XML is markup language used to store, transport & structure data. Markup languages uses tag to describe what data is, it’s structured and how should it appear. Extensible means that you can create your own tag & define your own structure for storing data based on your needs In HTML you must use predefined tag like <p>,<div>,<img>,<br> But in xml you can create tag like <student> <name>Riya</name> <dept>CSE</dept> </student>
users can create their own custom tags according to application requirements. <student> <name>Rahul</name> <rollNo>101</rollNo> </student> Platform Independent XML documents can be created on one operating system and used on another without modification. It works with different programming languages and platforms (Windows, Linux, macOS, etc.).
rules, such as having one root element, properly nested tags, and closing all tags. Valid XML: In addition to being well-formed, it follows rules defined in a DTD (Document Type Definition) or XML Schema (XSD). Easily Readable and Editable XML is a text-based format, making it easy for both humans and computers to read. It can be edited using any text editor, such as Notepad, VS Code, or XML editors. Supports metadata via attribute XML allows additional information (metadata) to be stored using attributes within elements. <book id="B101" category="Programming"> <title>XML Basics</title> </book>
hierarchical tree structure using element & tags. It is designed to be both human-readable and machine readable. The fundamental construct in an XML document is the element An element is simply a pair of matching start and end tag and all the text that appears between them. <bookstore> <book> <title>Advance Database Engineering</title> <author>S. Sudarshan</author> <year>2004</year> </book> <book> <title>Advance Java Programming</title> <author>Kanika Lakhani</author> <year>2004</year> </book> </bookstore>
must have a single root element that include all other elements in document Example <bookstore> <book> <title>Advance Database Engineering</title> <author>S. Sudarshan</author> <year>2004</year> </book> <book> <title>Advance Java Programming</title> <author>Kanika Lakhani</author> <year>2004</year> </book> </bookstore> In this example <bookstore> element forms the root element. Every XML document must have exactly one root element that contains all other element. Nested Element -<title>,<author>,<year>
in opening &closing tag. Example <title>Advance Database Engineering</title> 3. Attributes elements can have attribute that provide additional information about elements, usually metadata or properties. Example <account> <account_type =“Checking”> <account_no>SBI12956344</account_no> <branch_name>Mumbai</branch_name> </account_type> </account> 4.Text content elements can contain text or data 5. Namespace An XML namespace is way to uniquely identify element or attribute names by associated them with URL
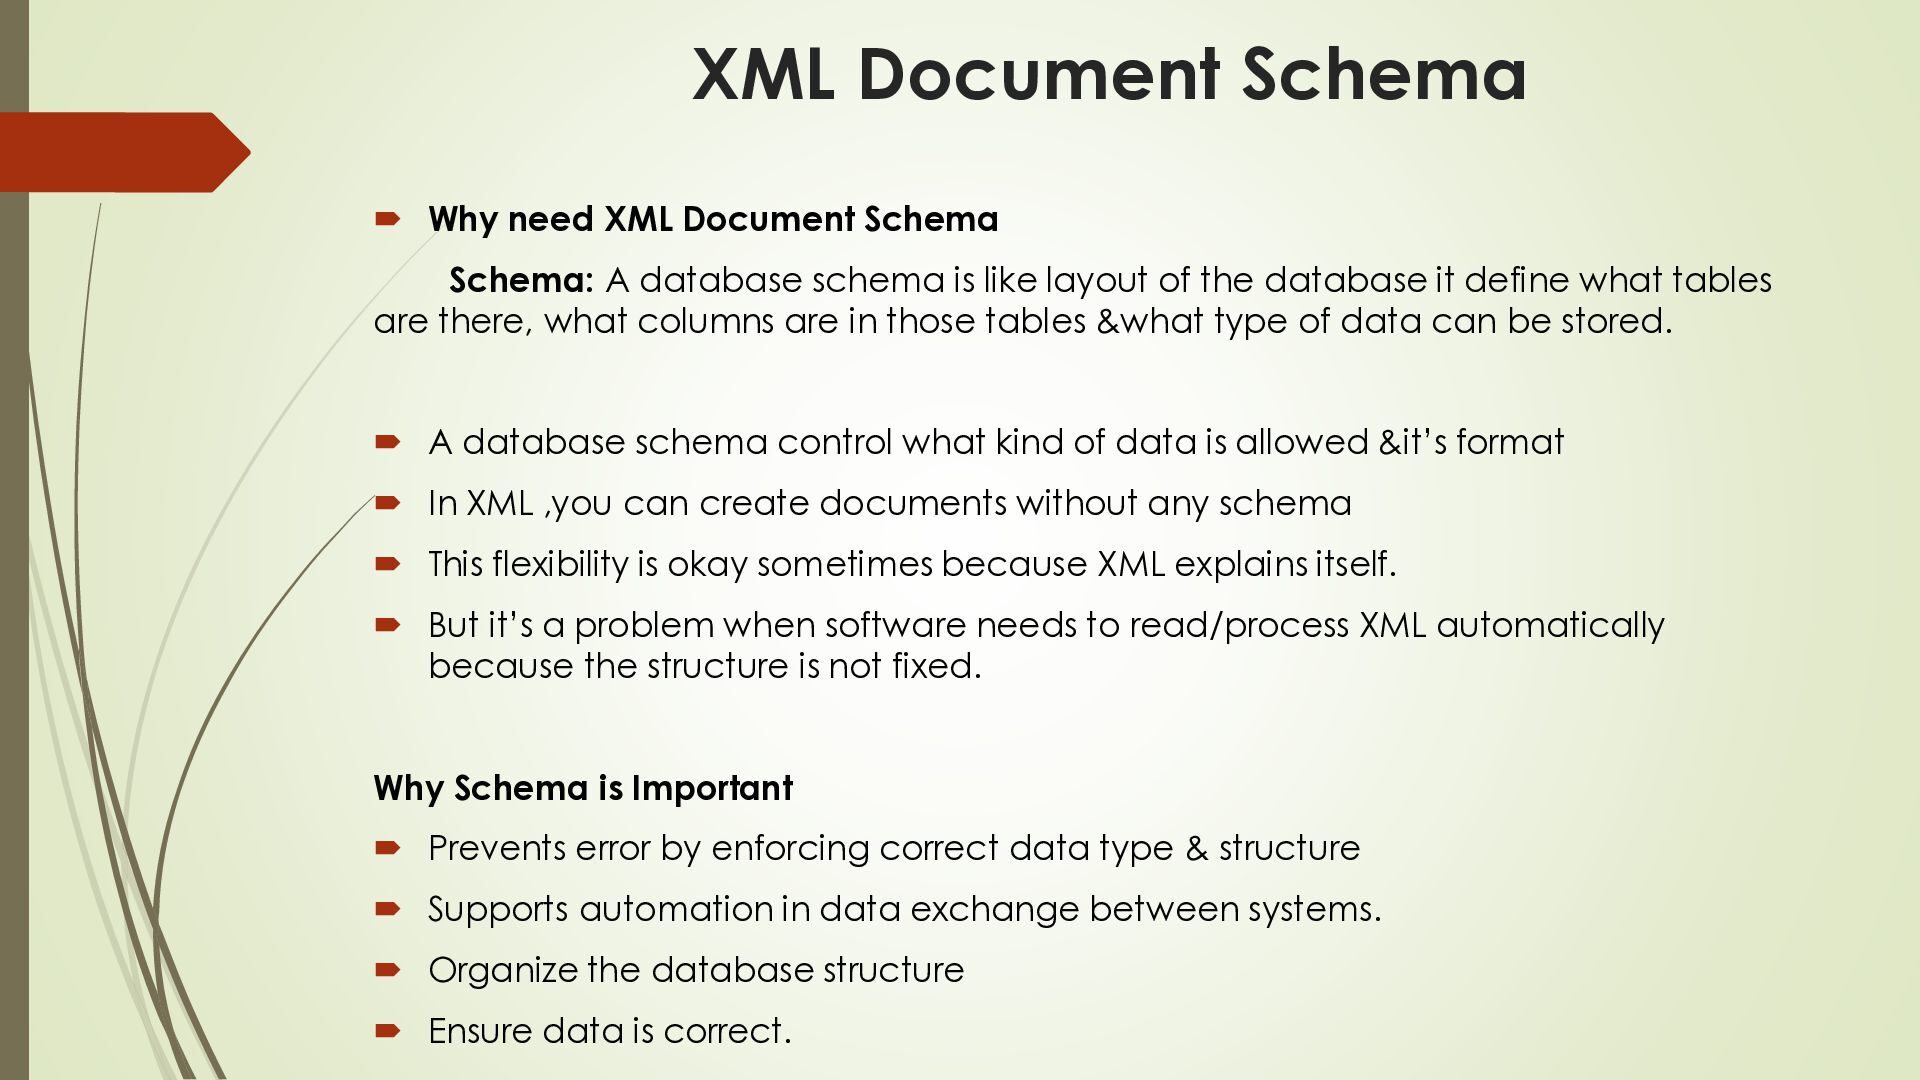
A database schema is like layout of the database it define what tables are there, what columns are in those tables &what type of data can be stored. A database schema control what kind of data is allowed &it’s format In XML ,you can create documents without any schema This flexibility is okay sometimes because XML explains itself. But it’s a problem when software needs to read/process XML automatically because the structure is not fixed. Why Schema is Important Prevents error by enforcing correct data type & structure Supports automation in data exchange between systems. Organize the database structure Ensure data is correct.
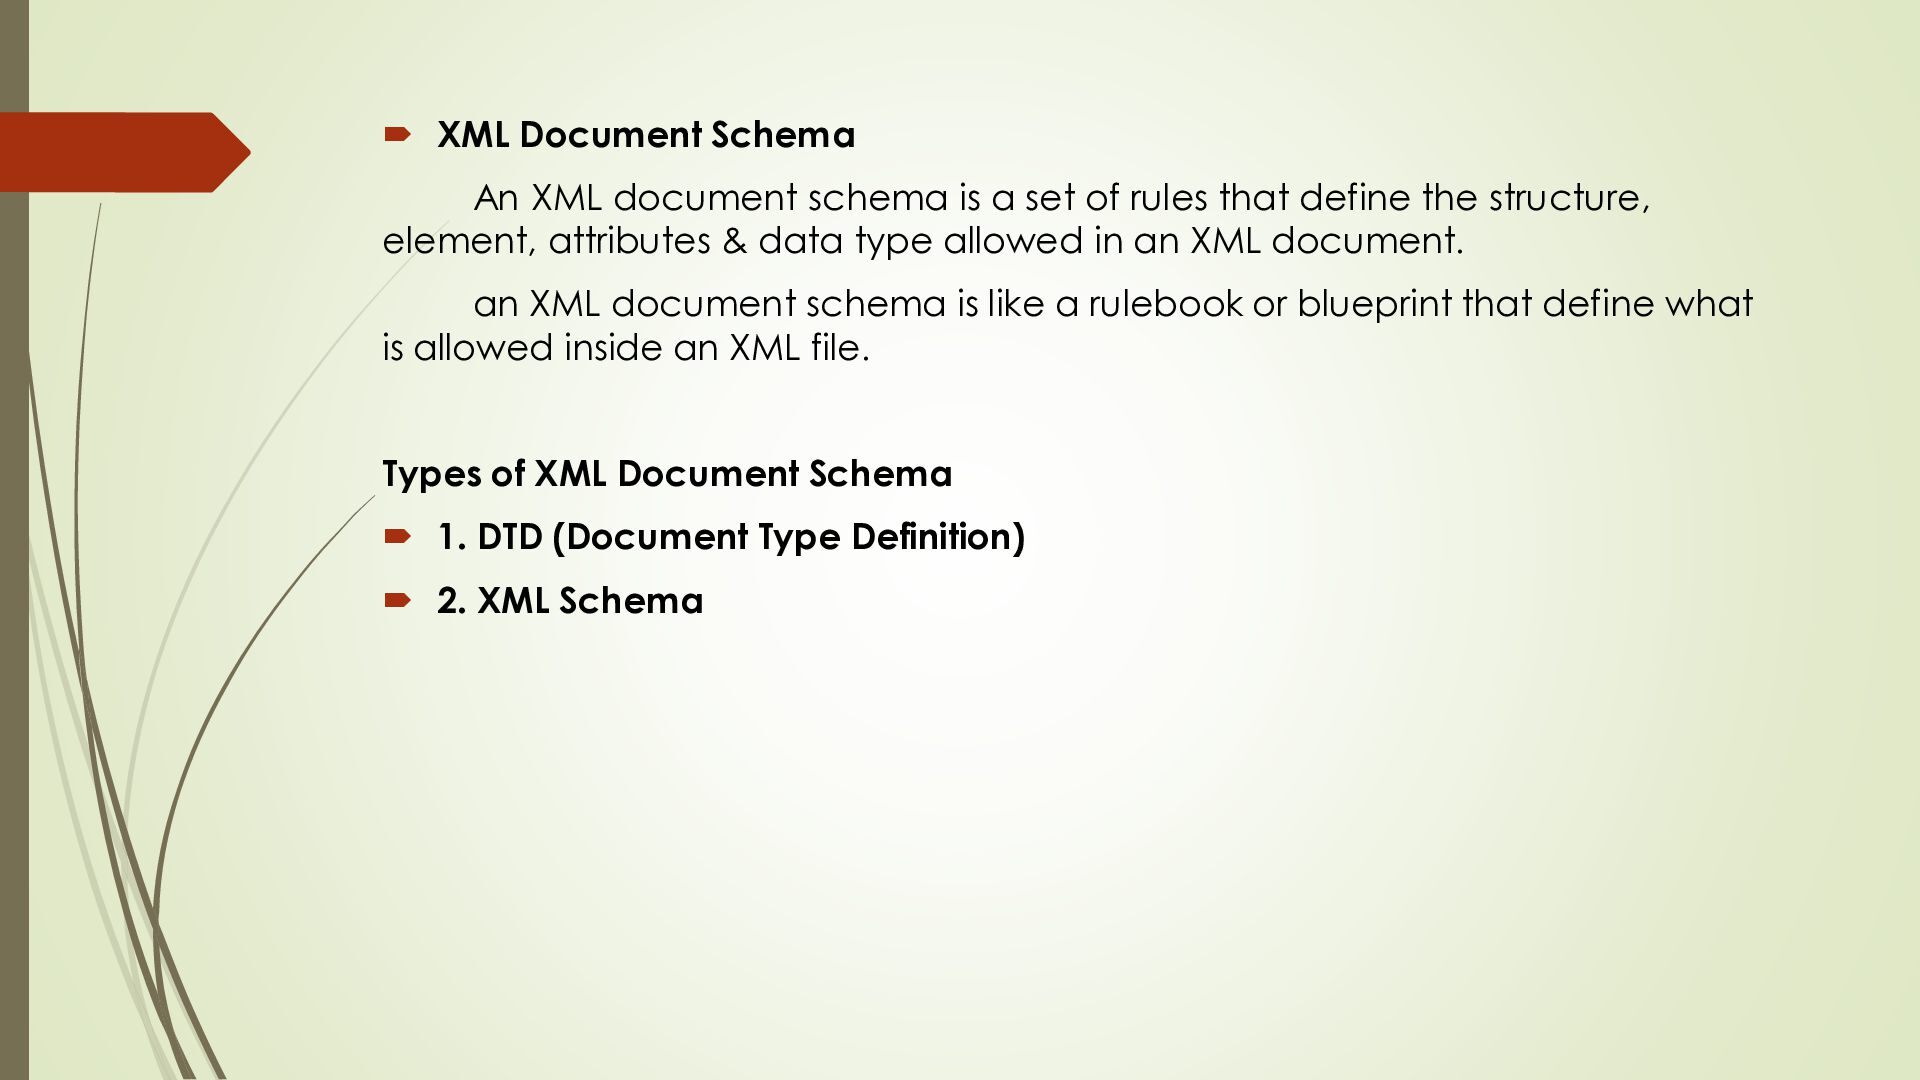
set of rules that define the structure, element, attributes & data type allowed in an XML document. an XML document schema is like a rulebook or blueprint that define what is allowed inside an XML file. Types of XML Document Schema 1. DTD (Document Type Definition) 2. XML Schema
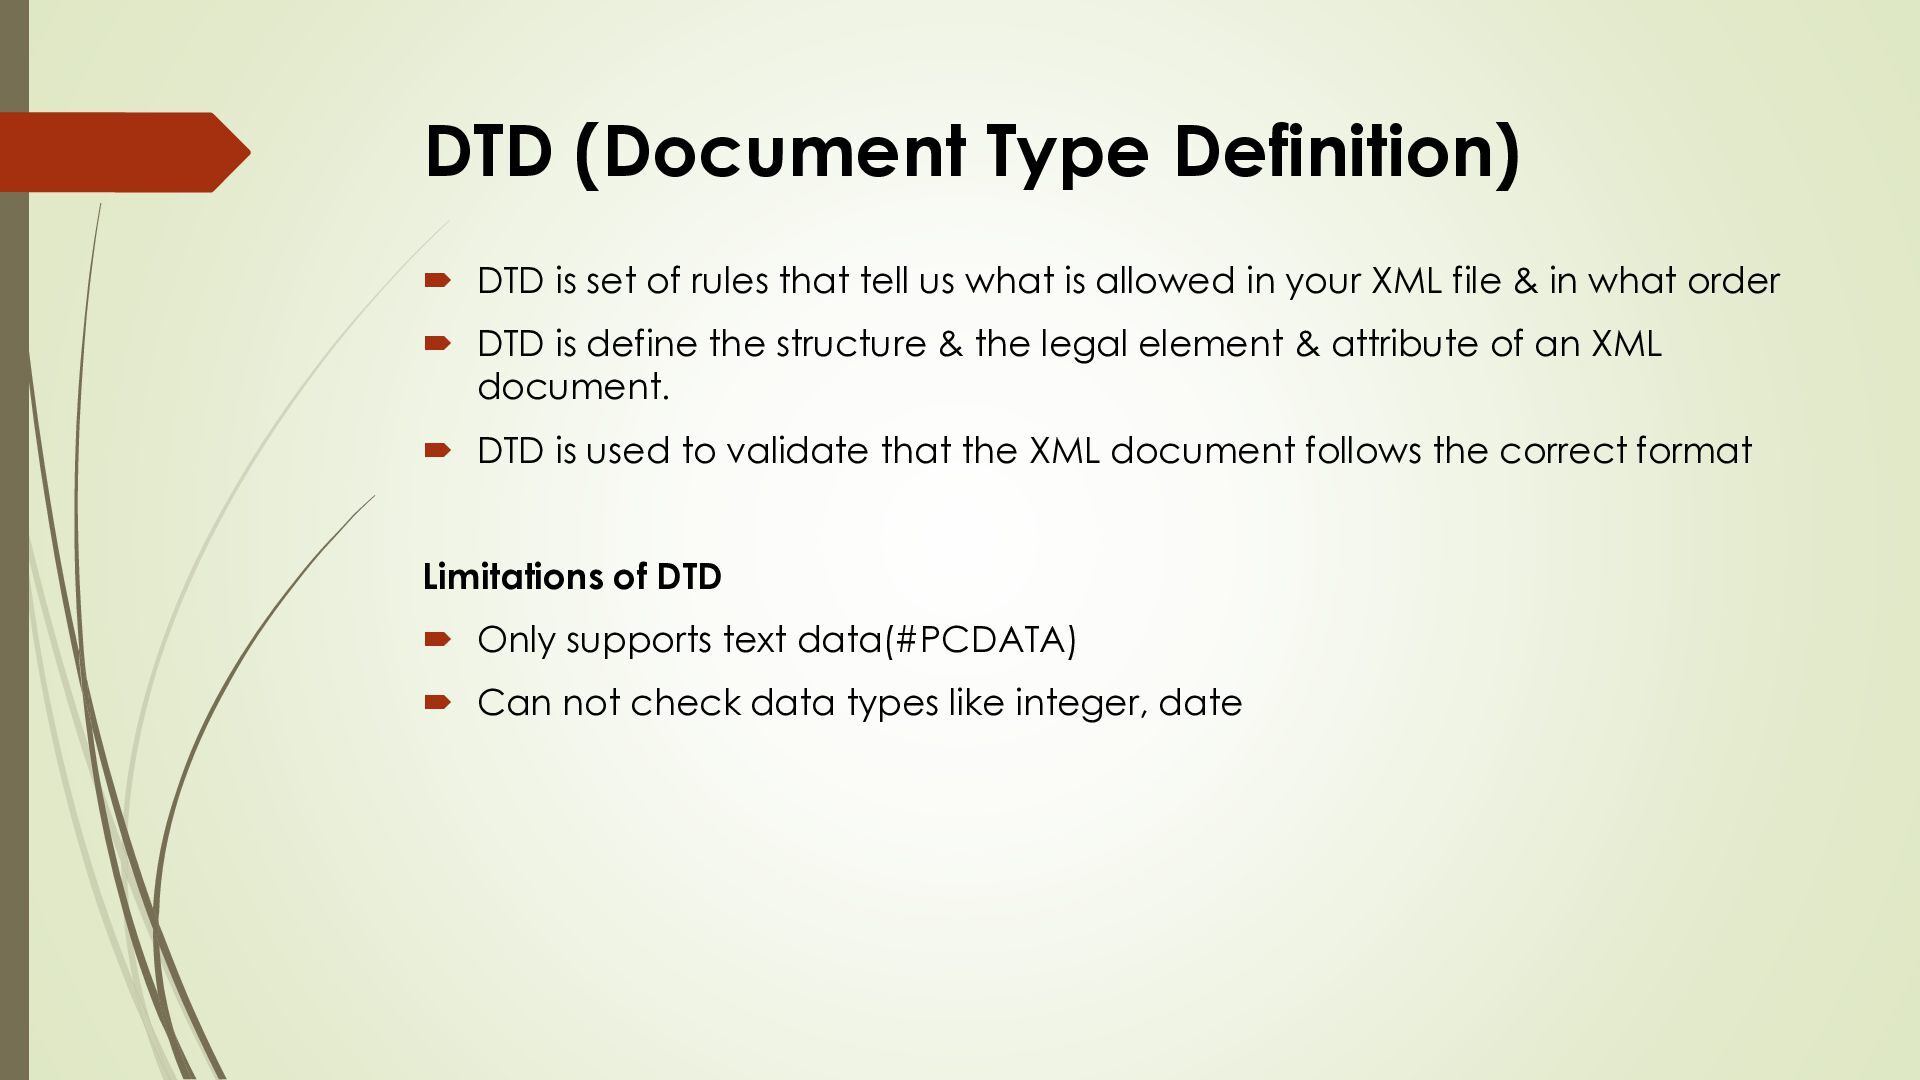
that tell us what is allowed in your XML file & in what order DTD is define the structure & the legal element & attribute of an XML document. DTD is used to validate that the XML document follows the correct format Limitations of DTD Only supports text data(#PCDATA) Can not check data types like integer, date
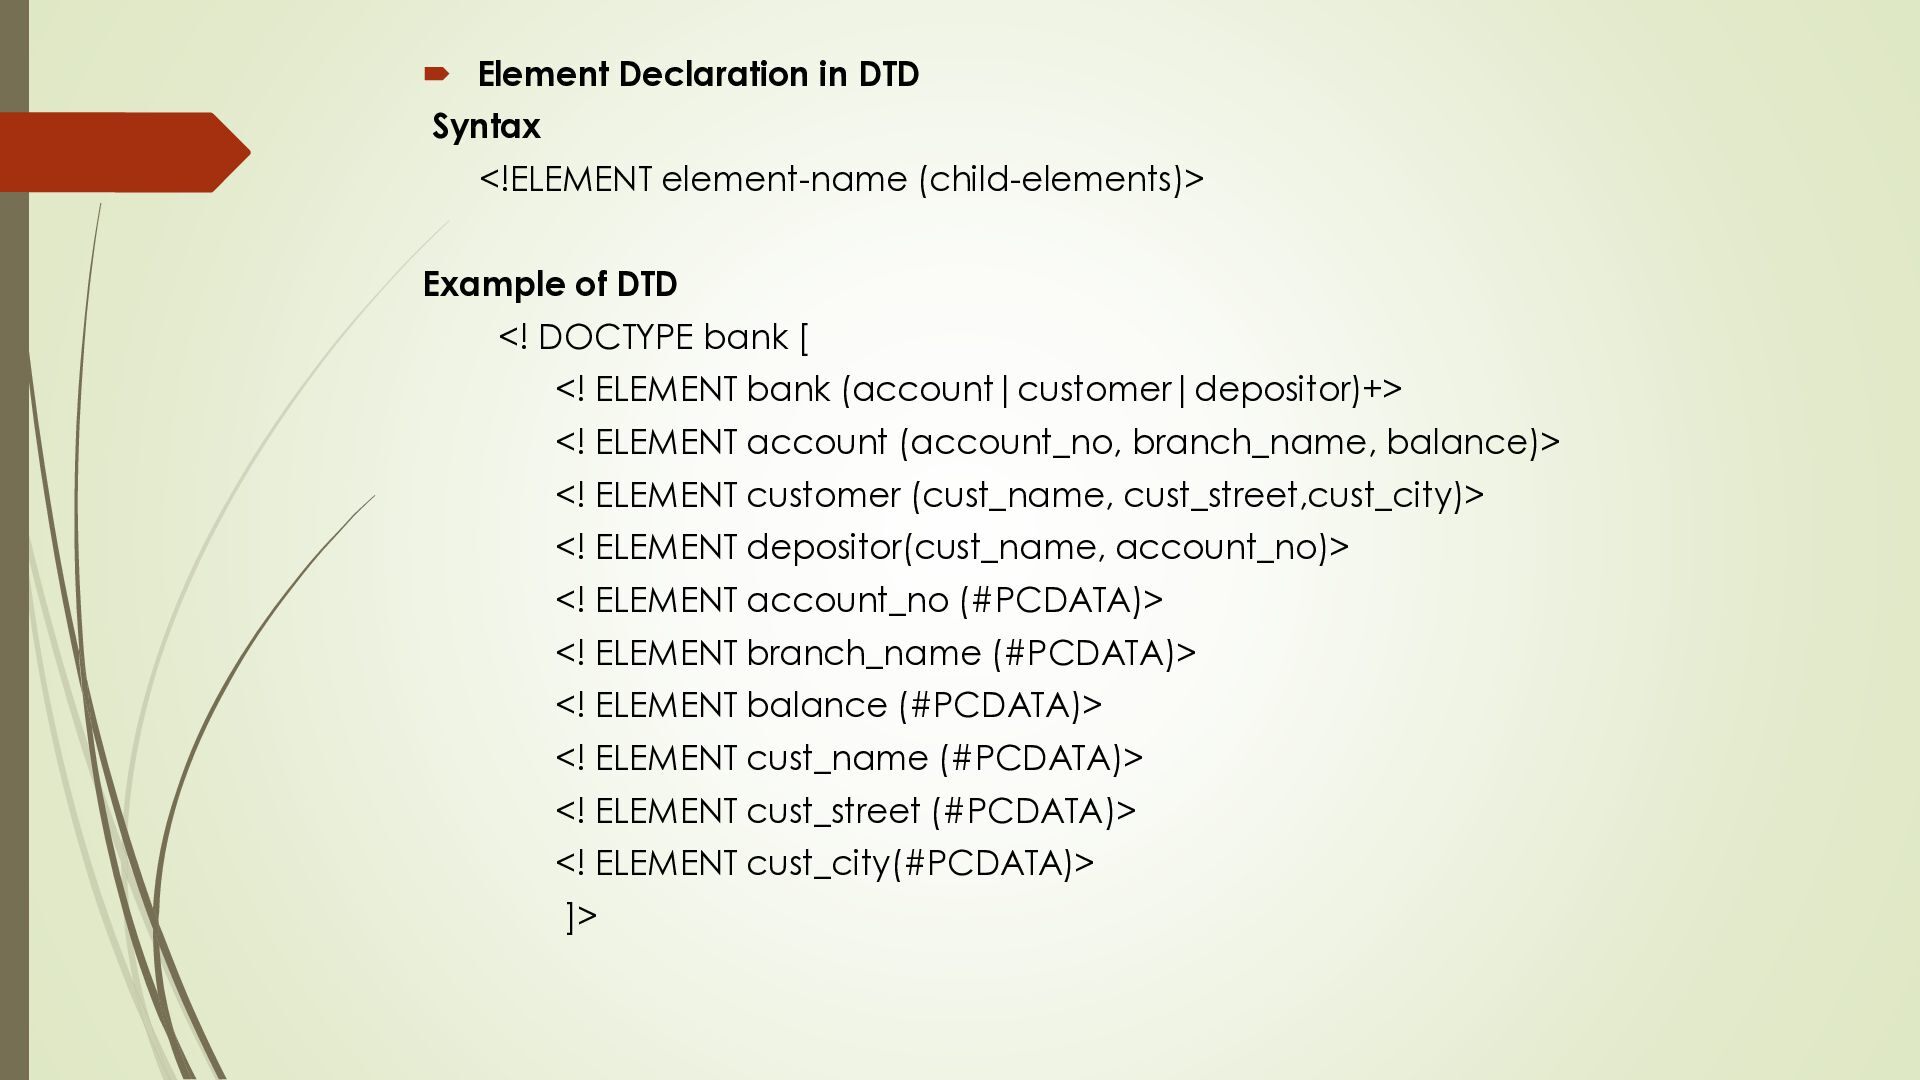
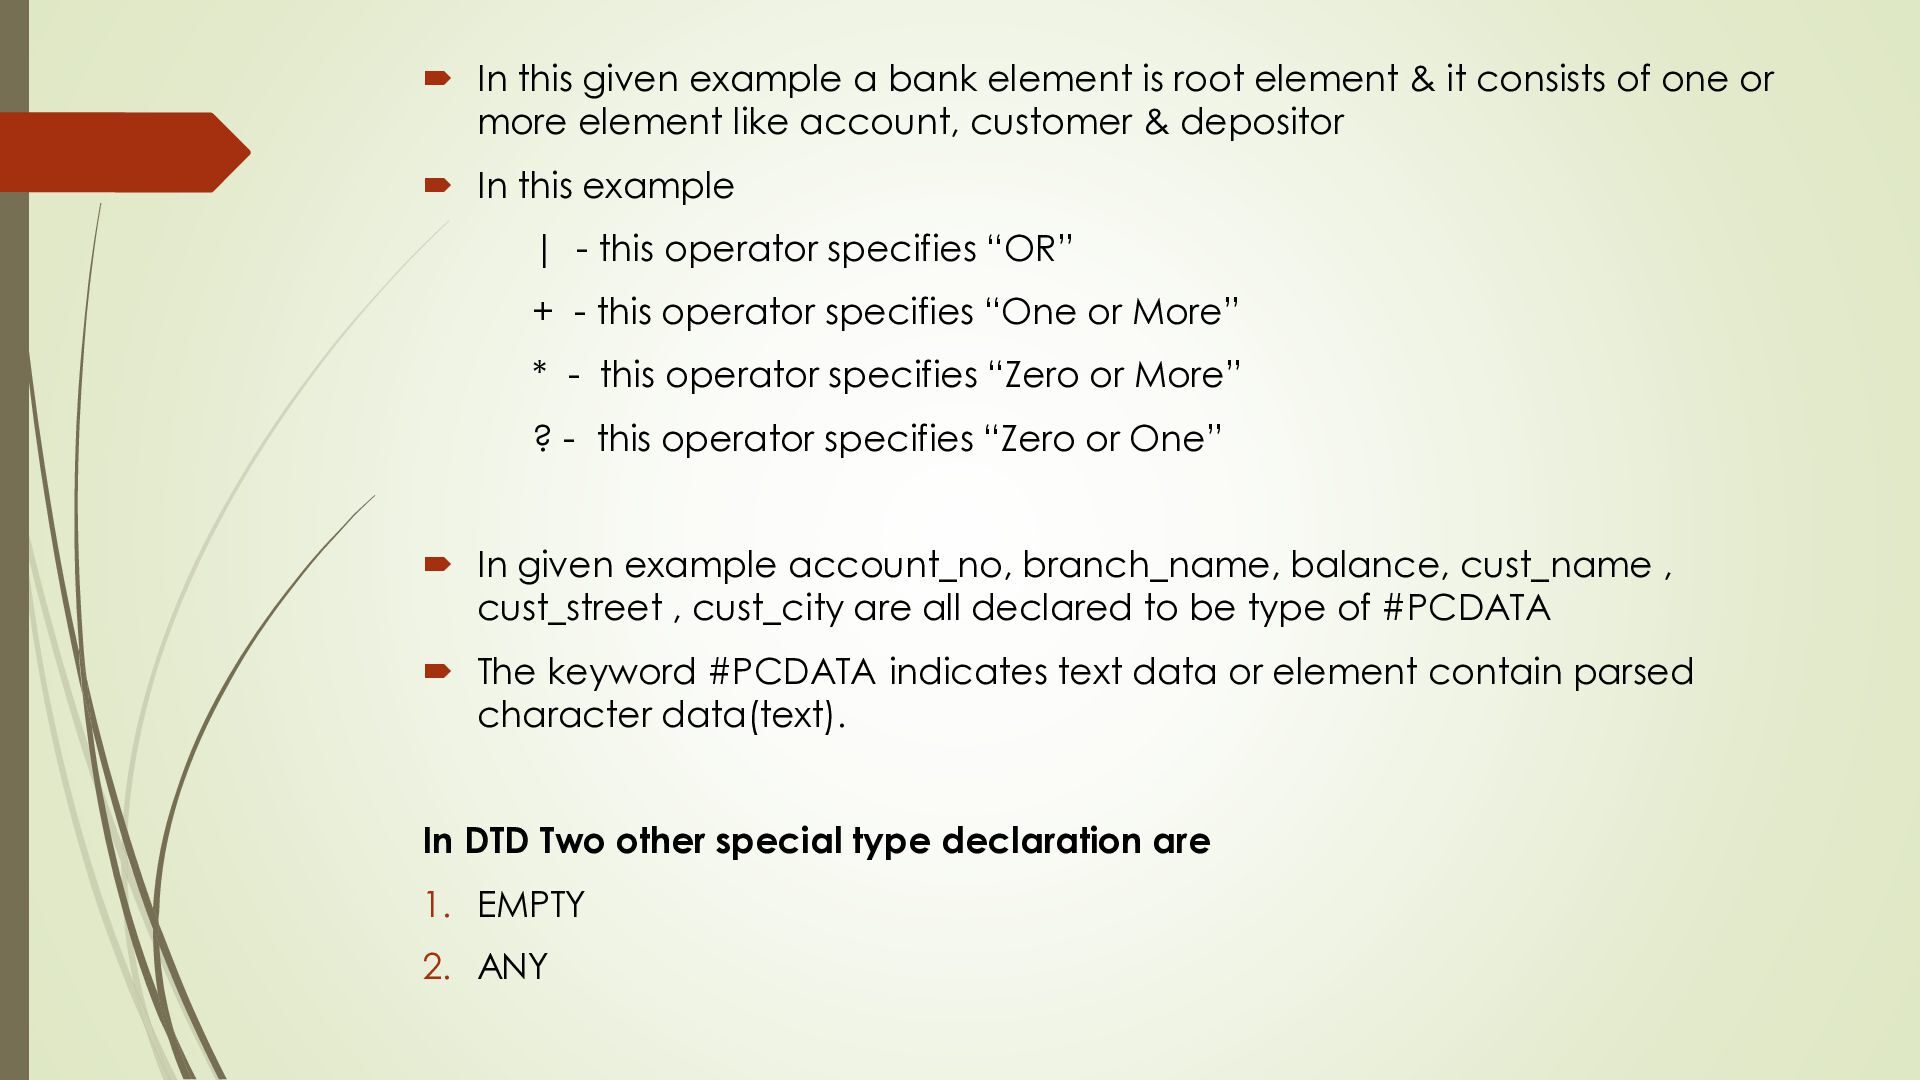
of DTD <! DOCTYPE bank [ <! ELEMENT bank (account|customer|depositor)+> <! ELEMENT account (account_no, branch_name, balance)> <! ELEMENT customer (cust_name, cust_street,cust_city)> <! ELEMENT depositor(cust_name, account_no)> <! ELEMENT account_no (#PCDATA)> <! ELEMENT branch_name (#PCDATA)> <! ELEMENT balance (#PCDATA)> <! ELEMENT cust_name (#PCDATA)> <! ELEMENT cust_street (#PCDATA)> <! ELEMENT cust_city(#PCDATA)> ]>
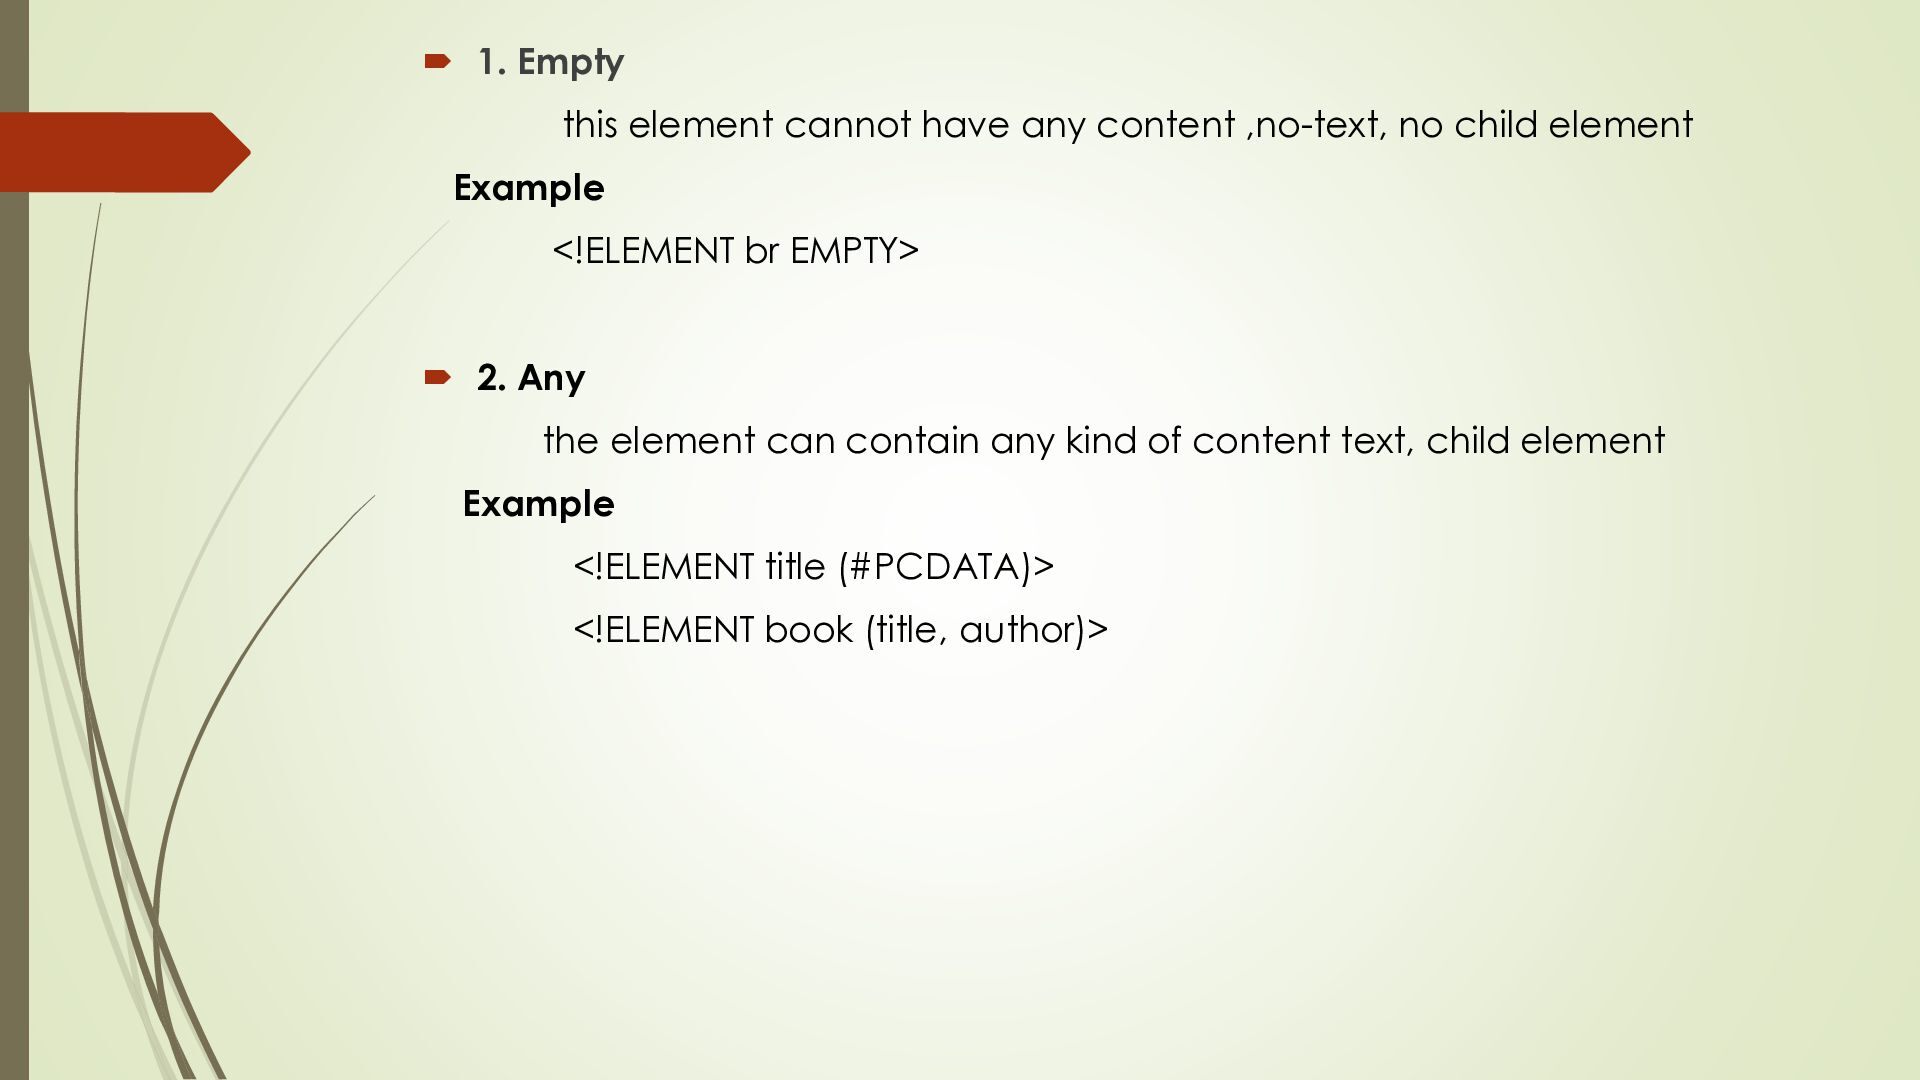
element & it consists of one or more element like account, customer & depositor In this example | - this operator specifies “OR” + - this operator specifies “One or More” * - this operator specifies “Zero or More” ? - this operator specifies “Zero or One” In given example account_no, branch_name, balance, cust_name , cust_street , cust_city are all declared to be type of #PCDATA The keyword #PCDATA indicates text data or element contain parsed character data(text). In DTD Two other special type declaration are 1. EMPTY 2. ANY
no child element Example <!ELEMENT br EMPTY> 2. Any the element can contain any kind of content text, child element Example <!ELEMENT title (#PCDATA)> <!ELEMENT book (title, author)>
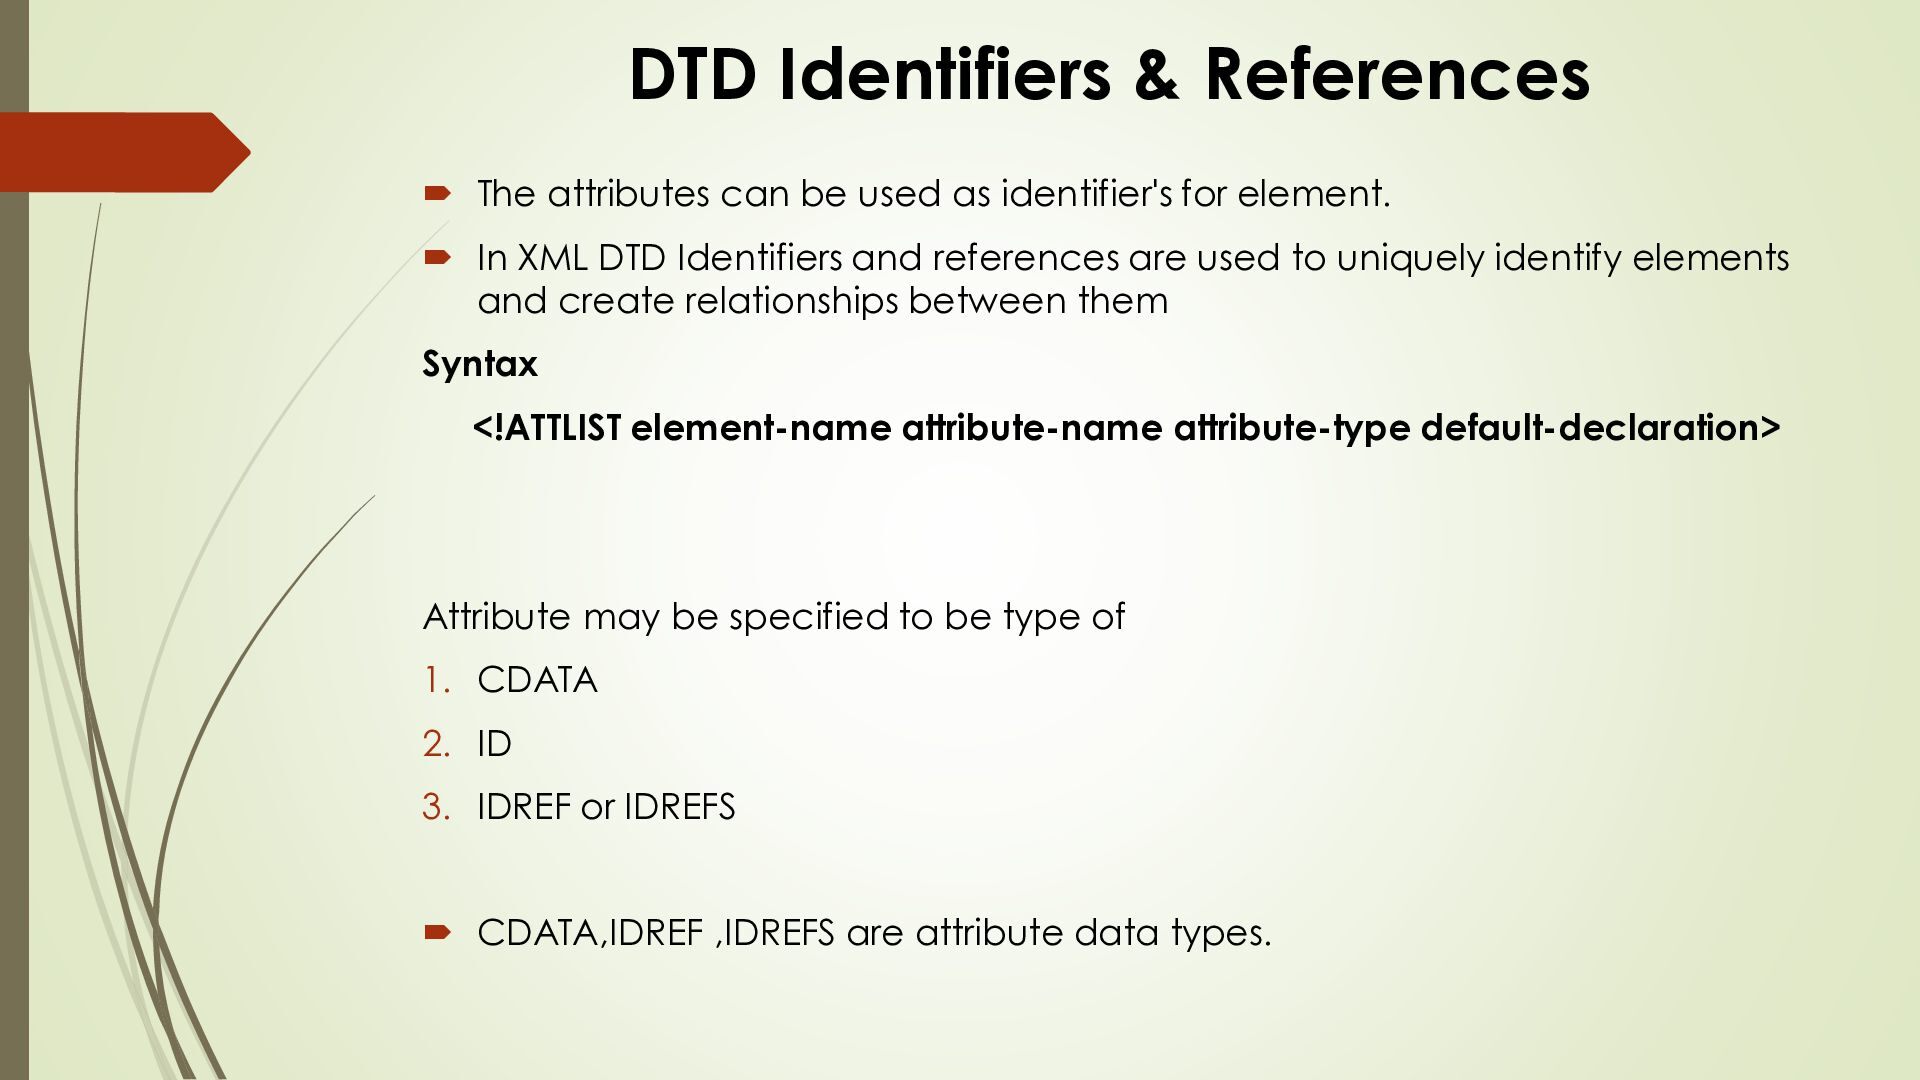
as identifier's for element. In XML DTD Identifiers and references are used to uniquely identify elements and create relationships between them Syntax <!ATTLIST element-name attribute-name attribute-type default-declaration> Attribute may be specified to be type of 1. CDATA 2. ID 3. IDREF or IDREFS CDATA,IDREF ,IDREFS are attribute data types.
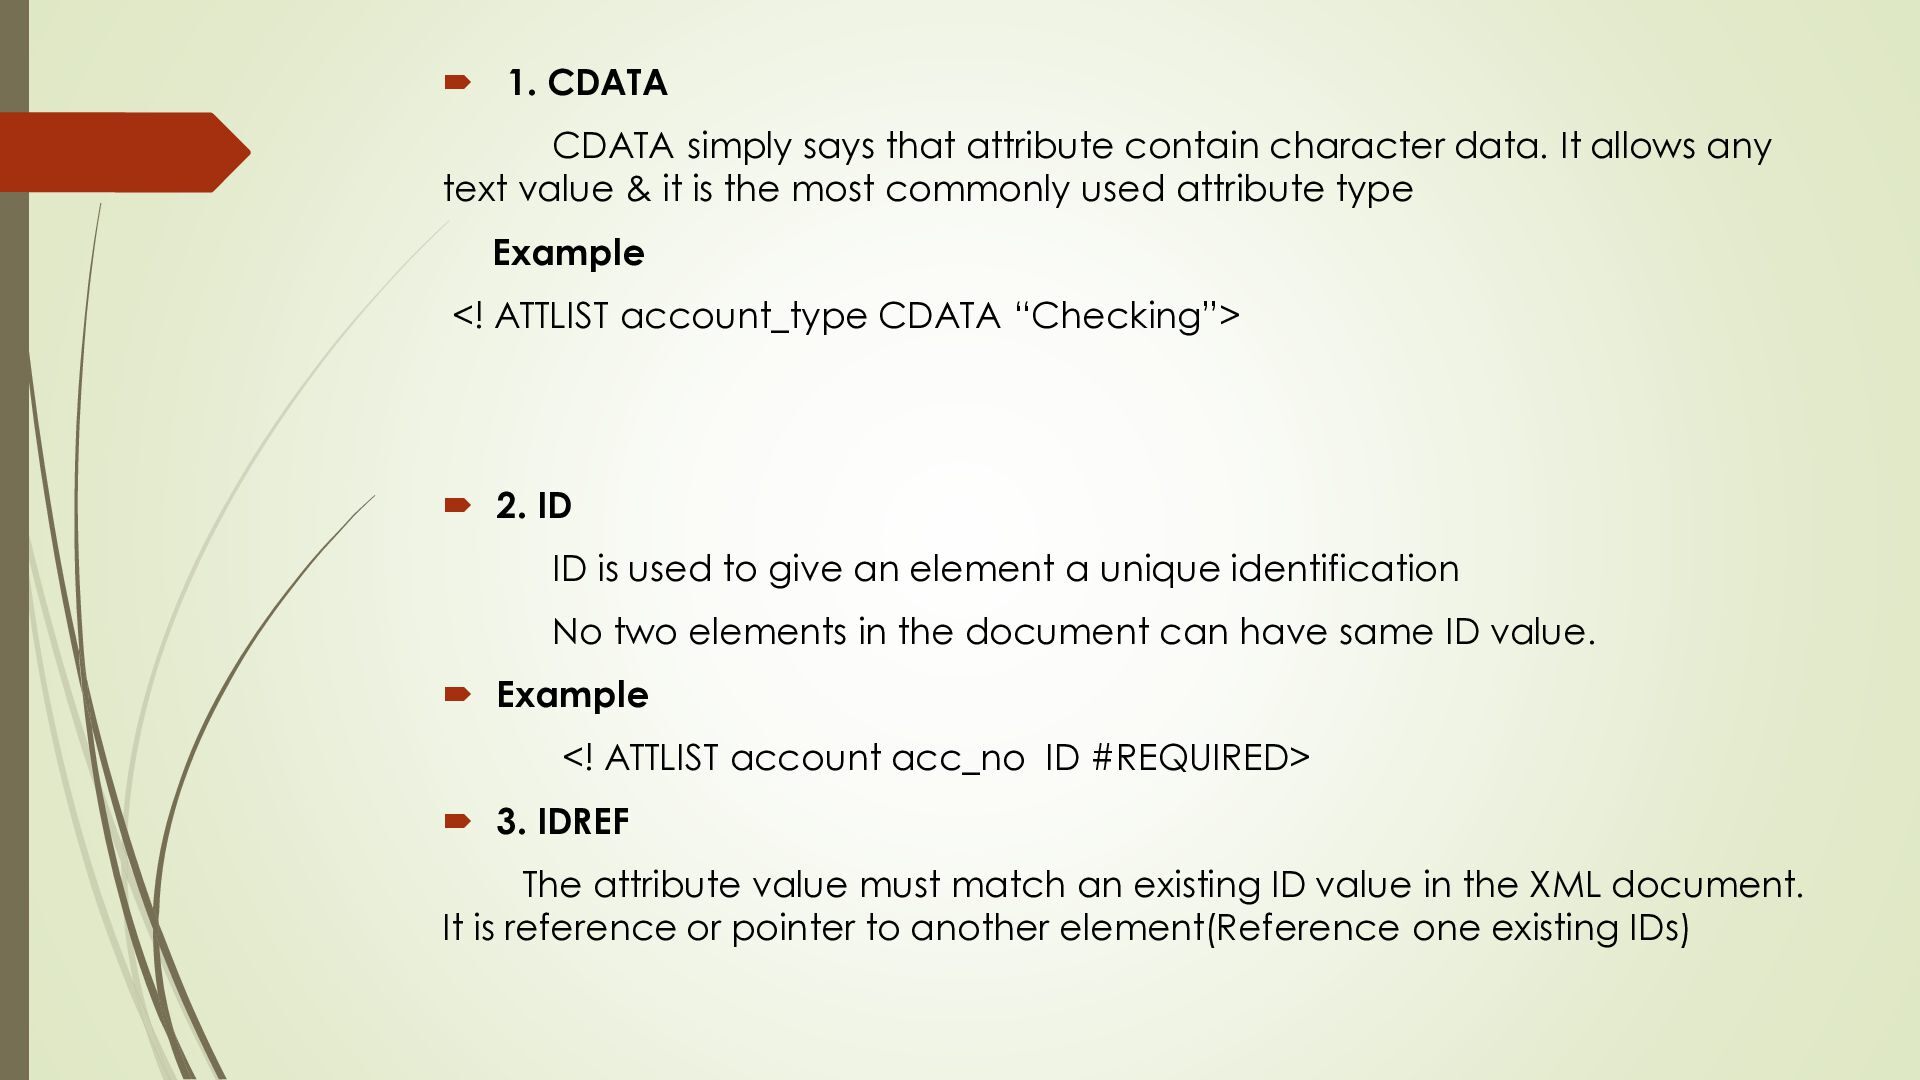
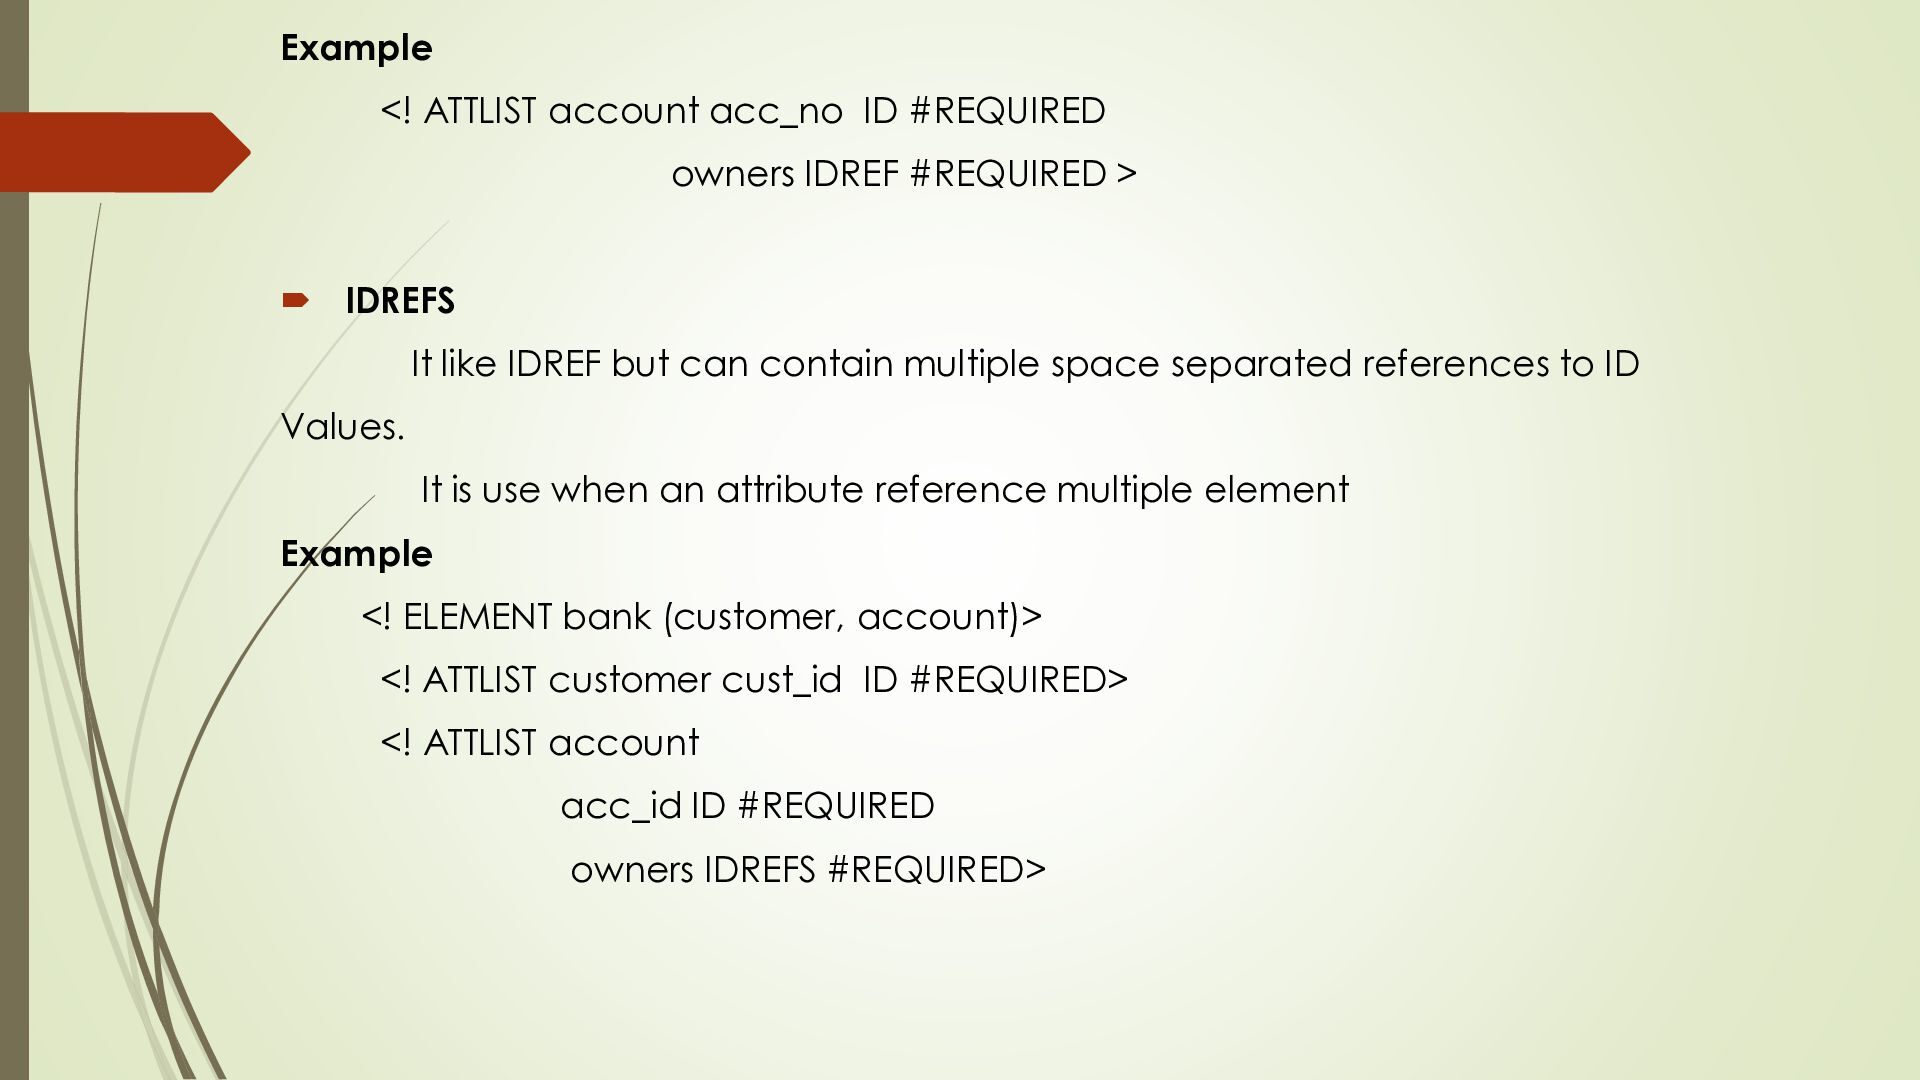
data. It allows any text value & it is the most commonly used attribute type Example <! ATTLIST account_type CDATA “Checking”> 2. ID ID is used to give an element a unique identification No two elements in the document can have same ID value. Example <! ATTLIST account acc_no ID #REQUIRED> 3. IDREF The attribute value must match an existing ID value in the XML document. It is reference or pointer to another element(Reference one existing IDs)
> IDREFS It like IDREF but can contain multiple space separated references to ID Values. It is use when an attribute reference multiple element Example <! ELEMENT bank (customer, account)> <! ATTLIST customer cust_id ID #REQUIRED> <! ATTLIST account acc_id ID #REQUIRED owners IDREFS #REQUIRED>
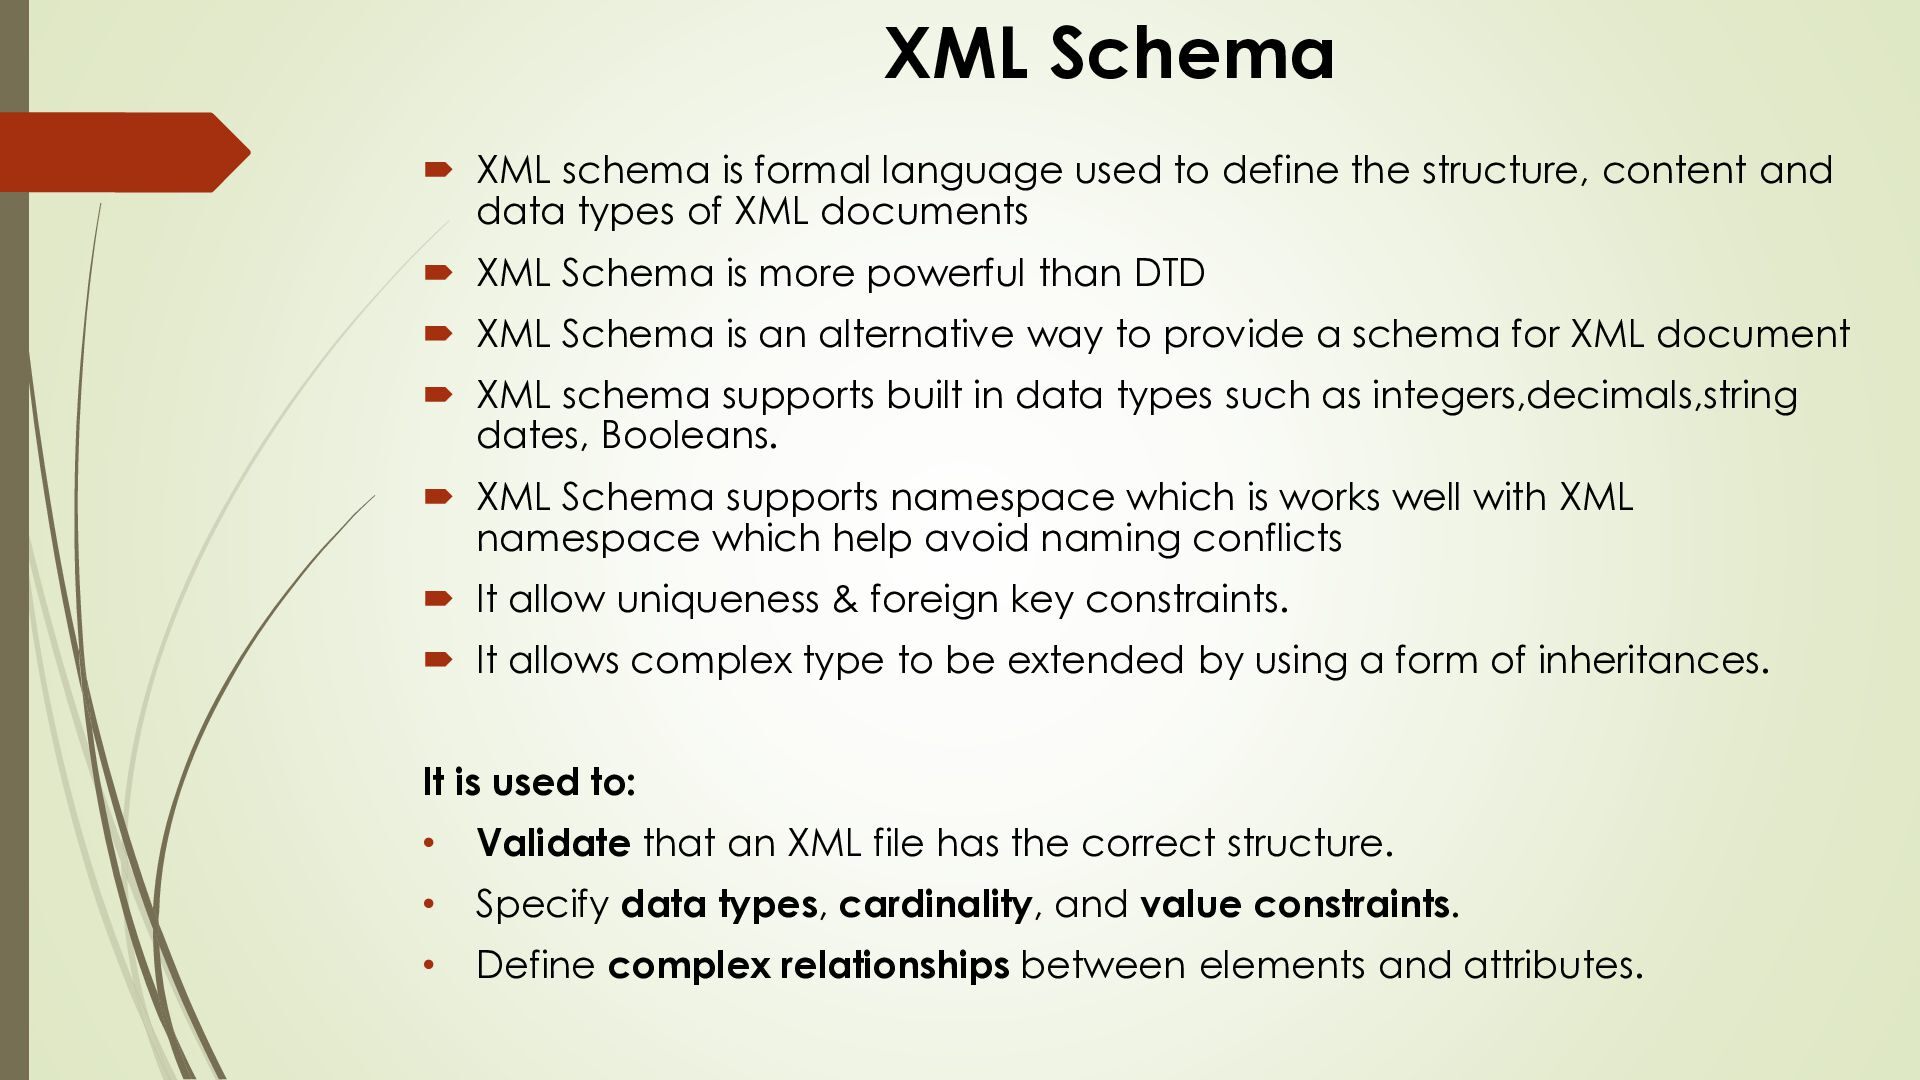
define the structure, content and data types of XML documents XML Schema is more powerful than DTD XML Schema is an alternative way to provide a schema for XML document XML schema supports built in data types such as integers,decimals,string dates, Booleans. XML Schema supports namespace which is works well with XML namespace which help avoid naming conflicts It allow uniqueness & foreign key constraints. It allows complex type to be extended by using a form of inheritances. It is used to: • Validate that an XML file has the correct structure. • Specify data types, cardinality, and value constraints. • Define complex relationships between elements and attributes.
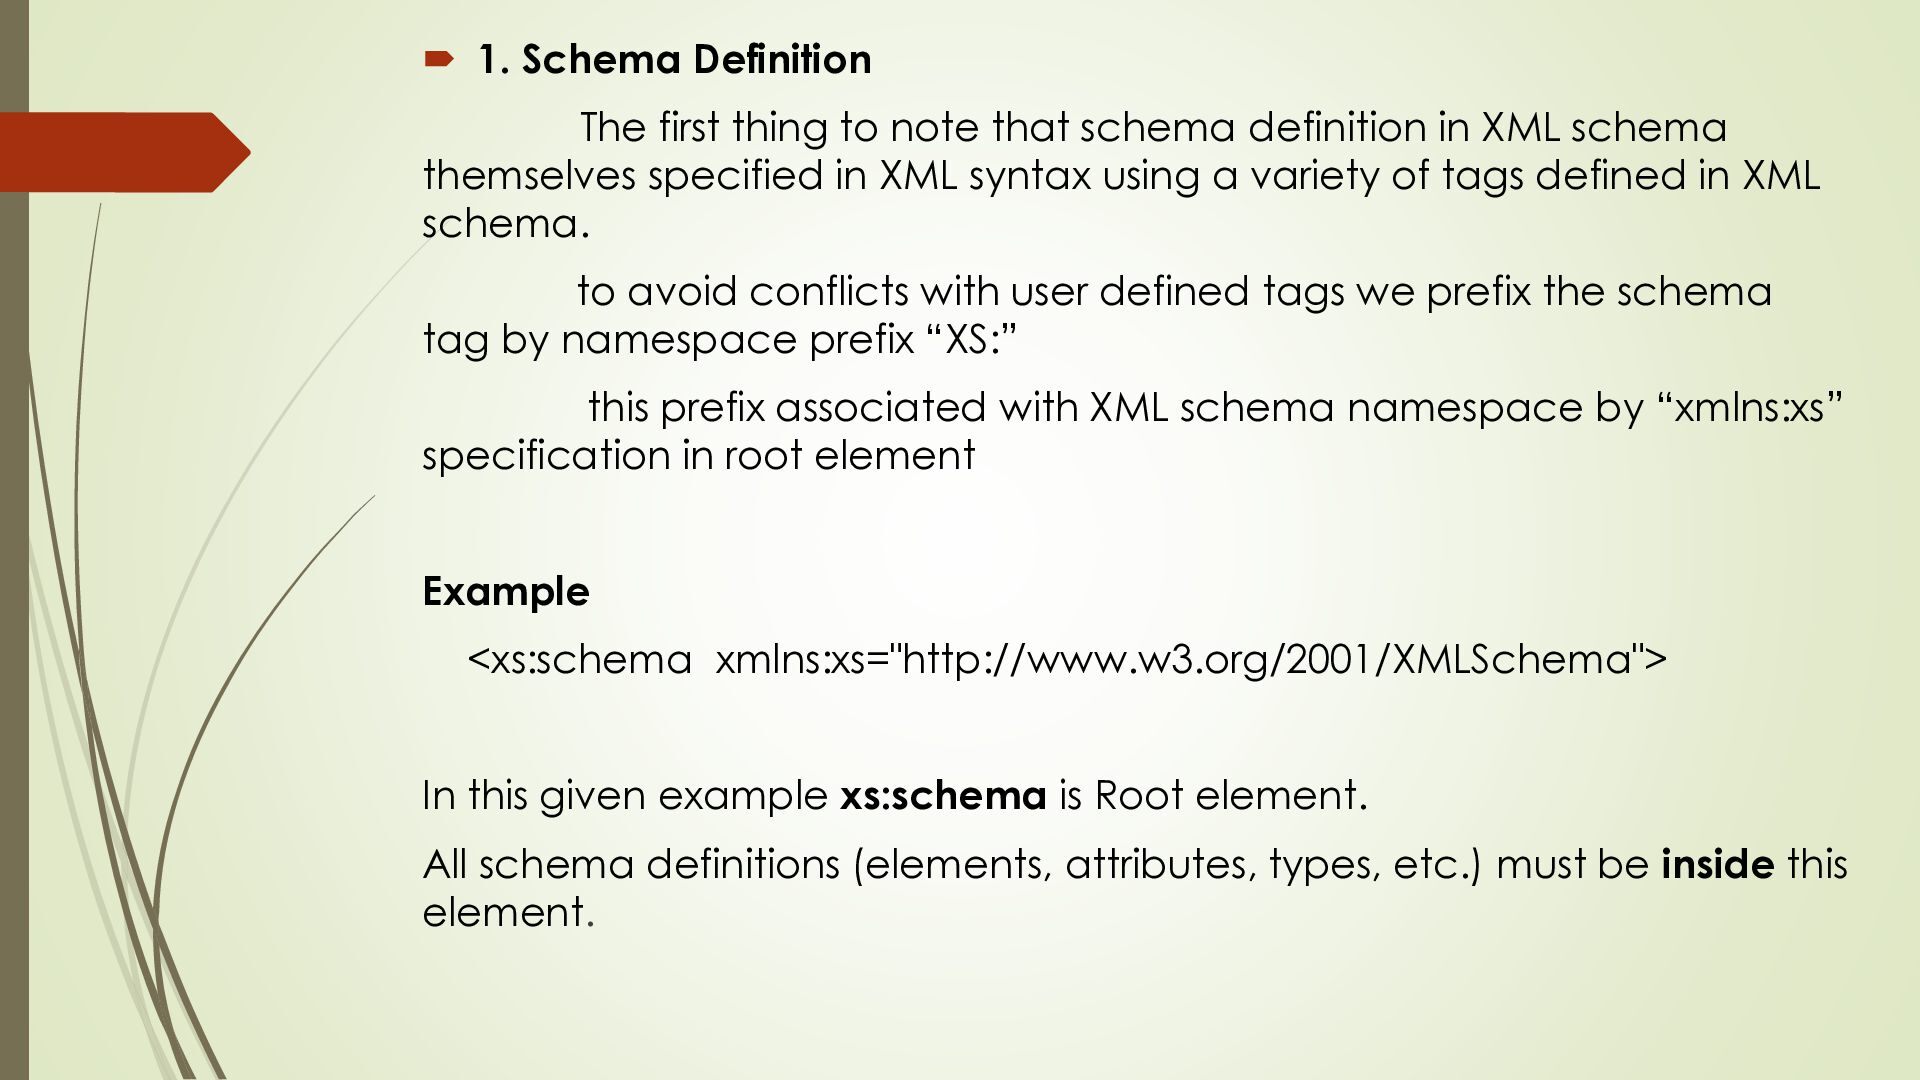
schema definition in XML schema themselves specified in XML syntax using a variety of tags defined in XML schema. to avoid conflicts with user defined tags we prefix the schema tag by namespace prefix “XS:” this prefix associated with XML schema namespace by “xmlns:xs” specification in root element Example <xs:schema xmlns:xs="http://www.w3.org/2001/XMLSchema"> In this given example xs:schema is Root element. All schema definitions (elements, attributes, types, etc.) must be inside this element.
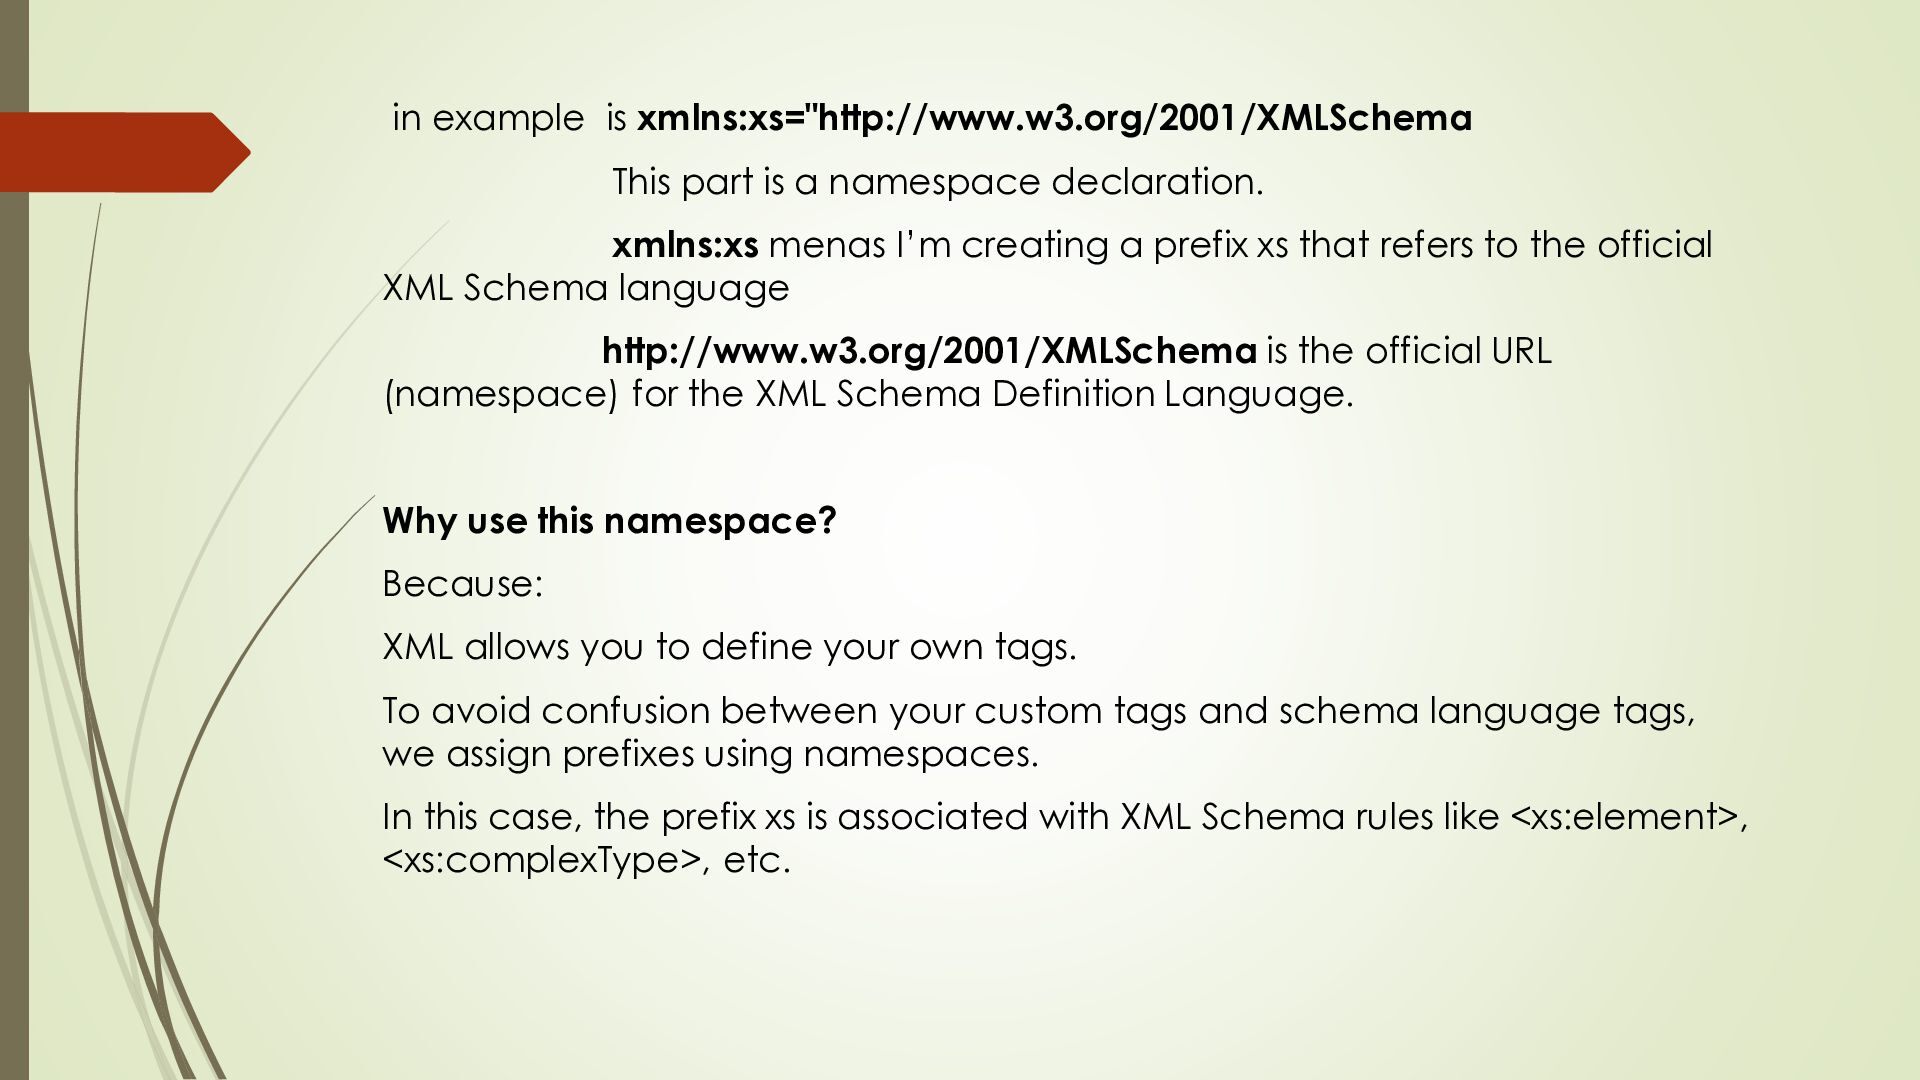
xmlns:xs menas I’m creating a prefix xs that refers to the official XML Schema language http://www.w3.org/2001/XMLSchema is the official URL (namespace) for the XML Schema Definition Language. Why use this namespace? Because: XML allows you to define your own tags. To avoid confusion between your custom tags and schema language tags, we assign prefixes using namespaces. In this case, the prefix xs is associated with XML Schema rules like <xs:element>, <xs:complexType>, etc.
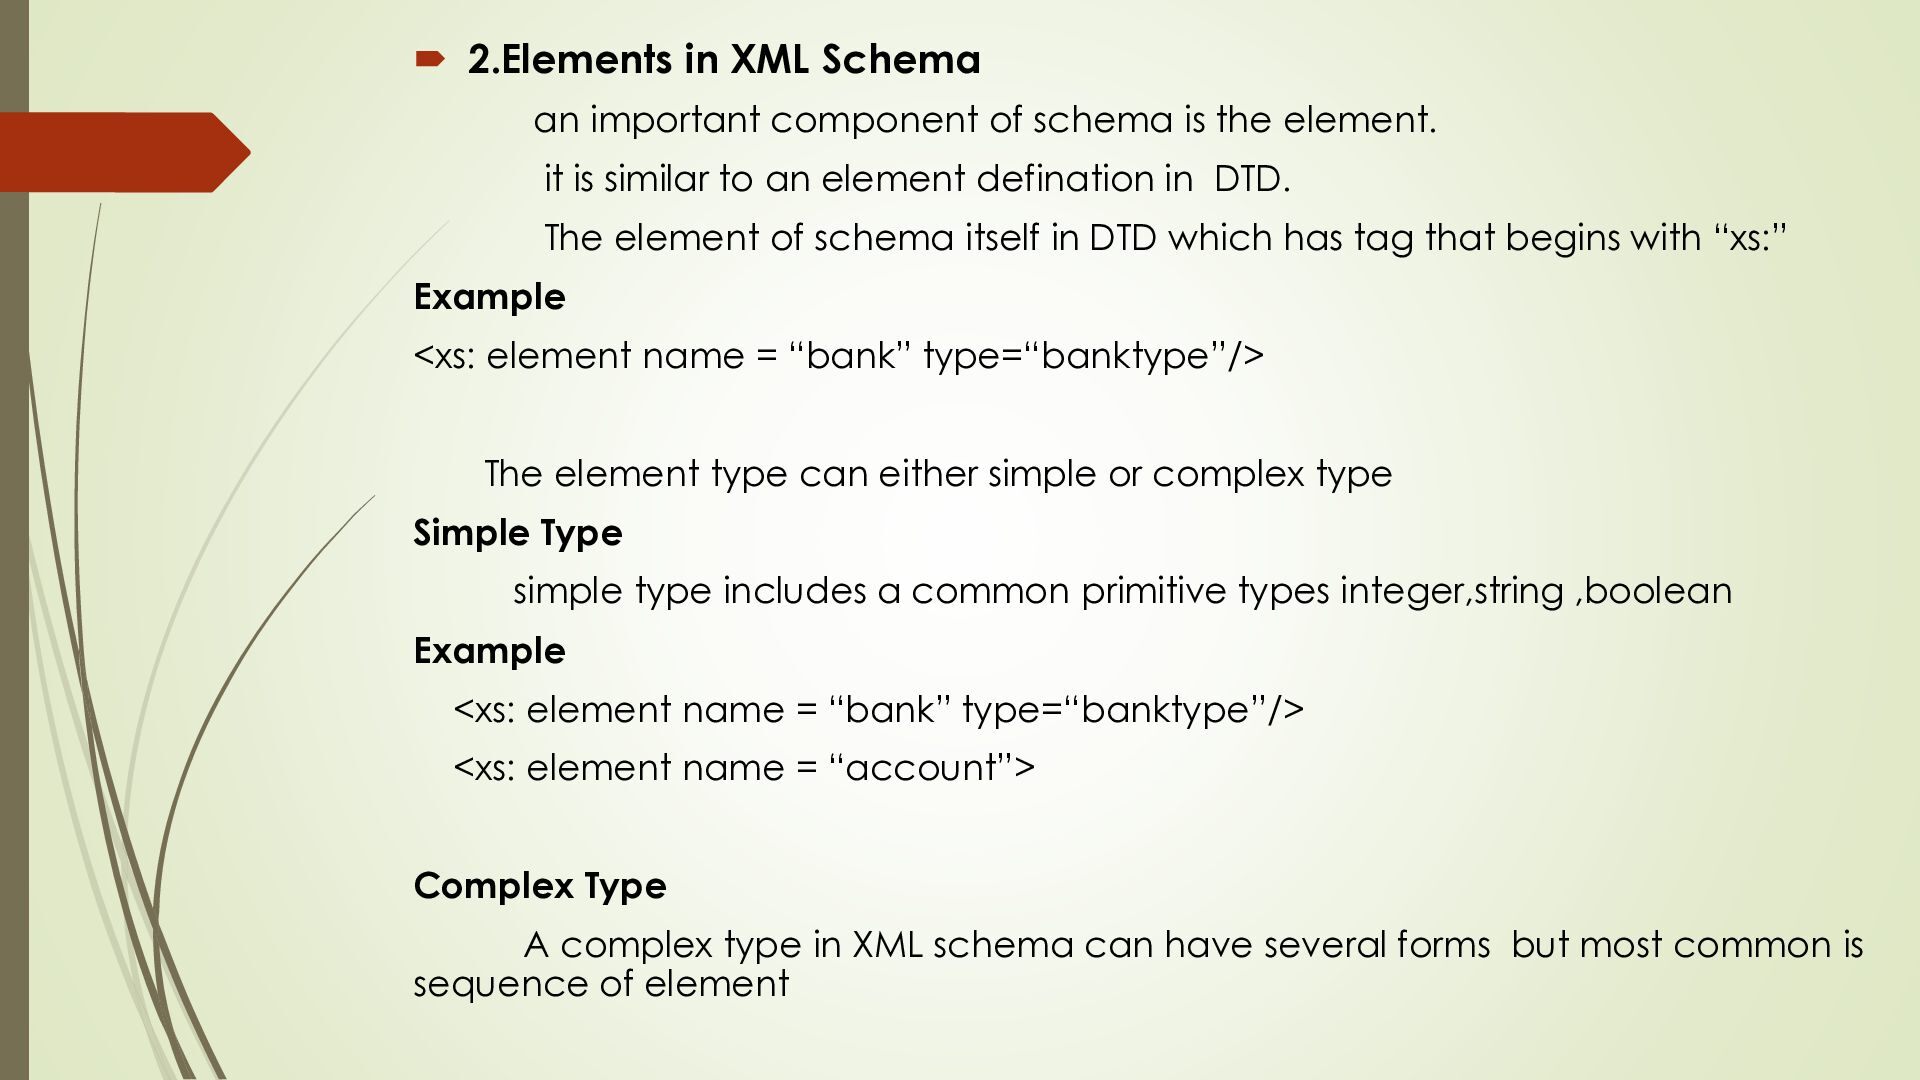
is the element. it is similar to an element defination in DTD. The element of schema itself in DTD which has tag that begins with “xs:” Example <xs: element name = “bank” type=“banktype”/> The element type can either simple or complex type Simple Type simple type includes a common primitive types integer,string ,boolean Example <xs: element name = “bank” type=“banktype”/> <xs: element name = “account”> Complex Type A complex type in XML schema can have several forms but most common is sequence of element
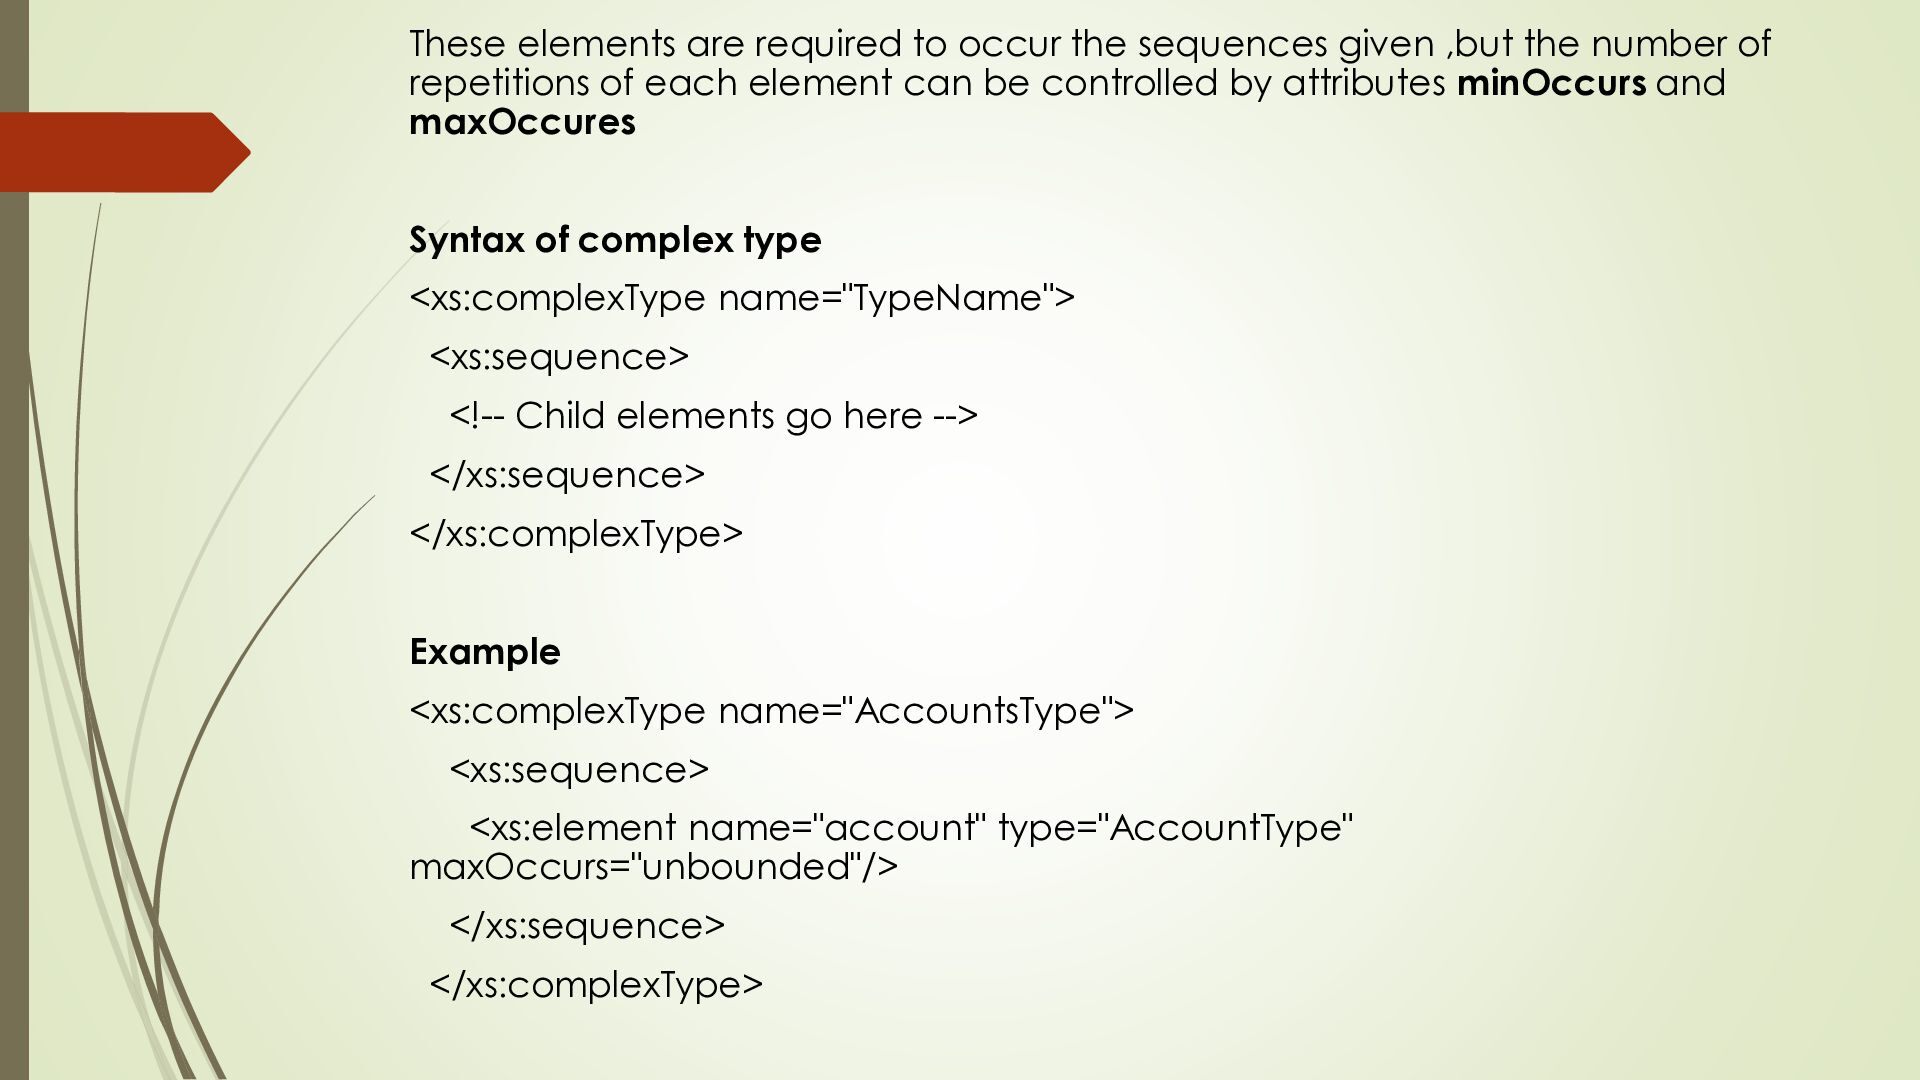
the number of repetitions of each element can be controlled by attributes minOccurs and maxOccures Syntax of complex type <xs:complexType name="TypeName"> <xs:sequence> <!-- Child elements go here --> </xs:sequence> </xs:complexType> Example <xs:complexType name="AccountsType"> <xs:sequence> <xs:element name="account" type="AccountType" maxOccurs="unbounded"/> </xs:sequence> </xs:complexType>
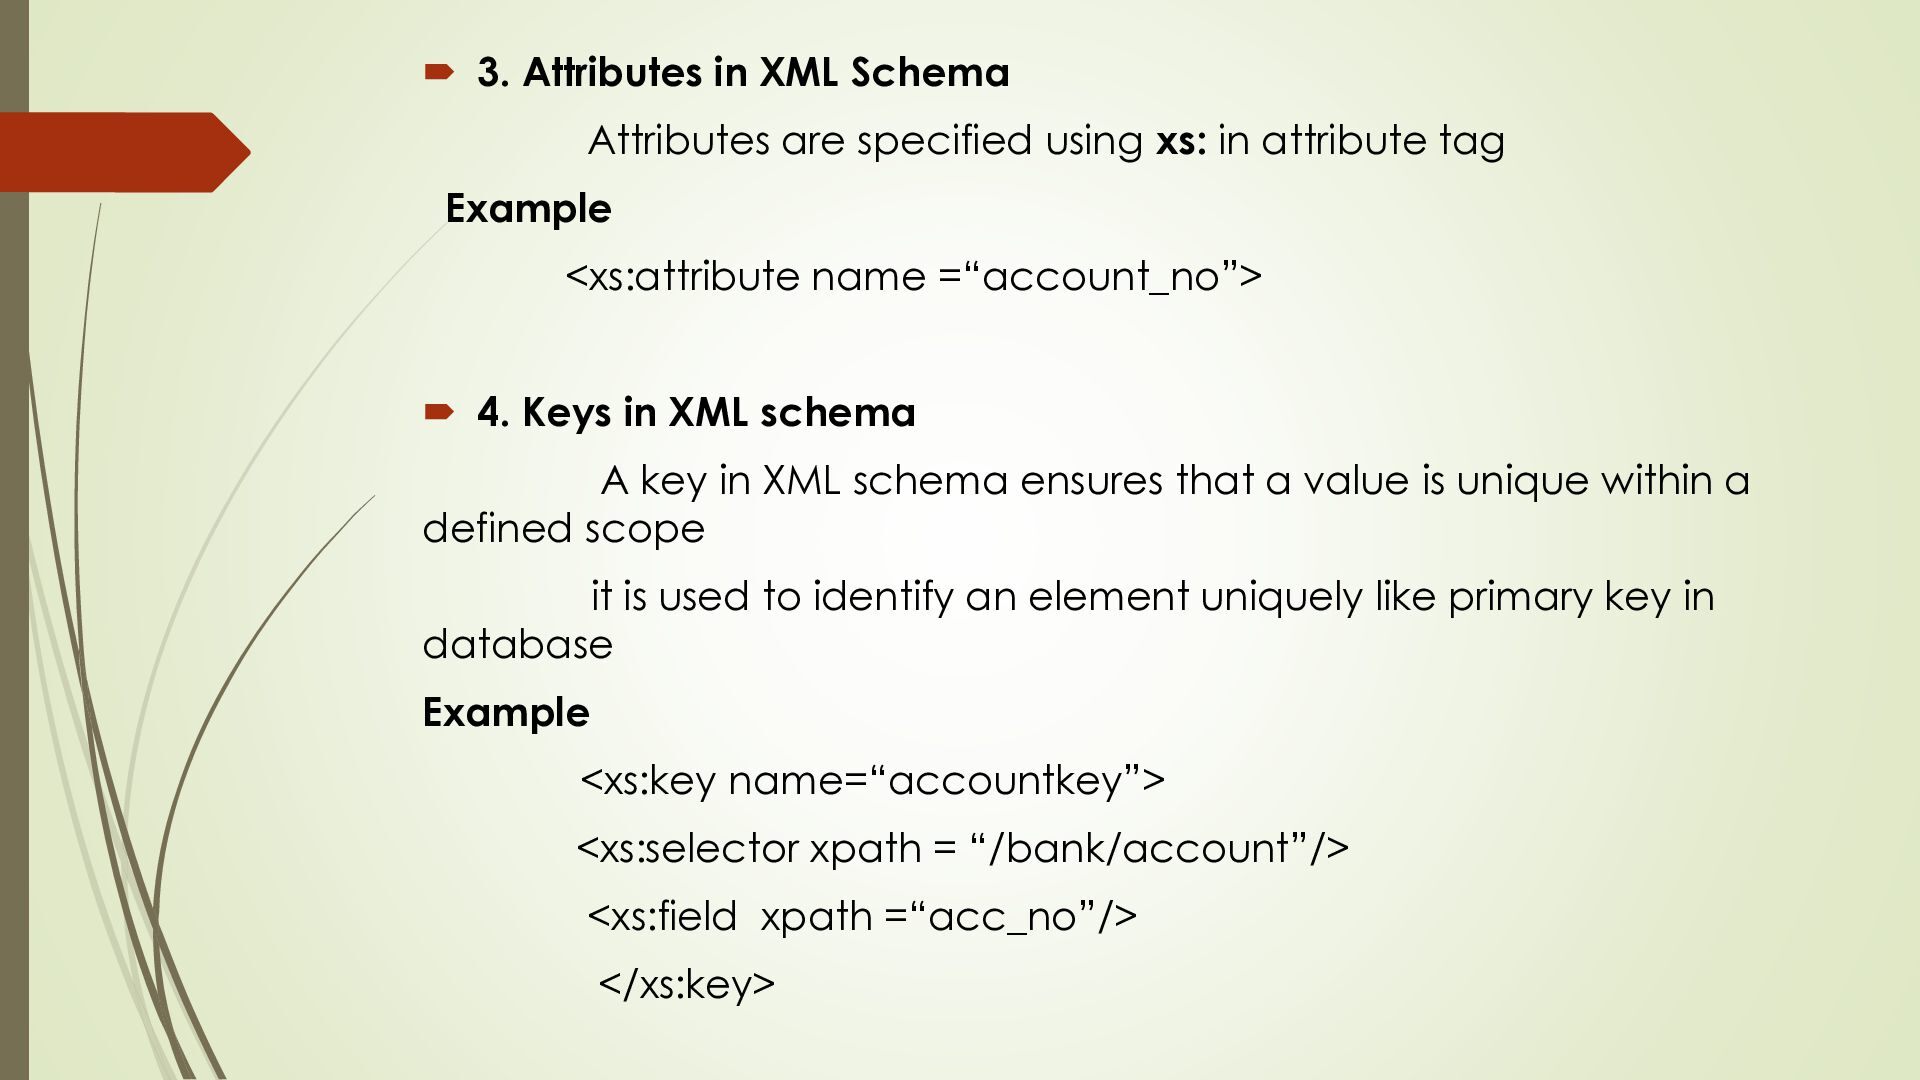
xs: in attribute tag Example <xs:attribute name =“account_no”> 4. Keys in XML schema A key in XML schema ensures that a value is unique within a defined scope it is used to identify an element uniquely like primary key in database Example <xs:key name=“accountkey”> <xs:selector xpath = “/bank/account”/> <xs:field xpath =“acc_no”/> </xs:key>
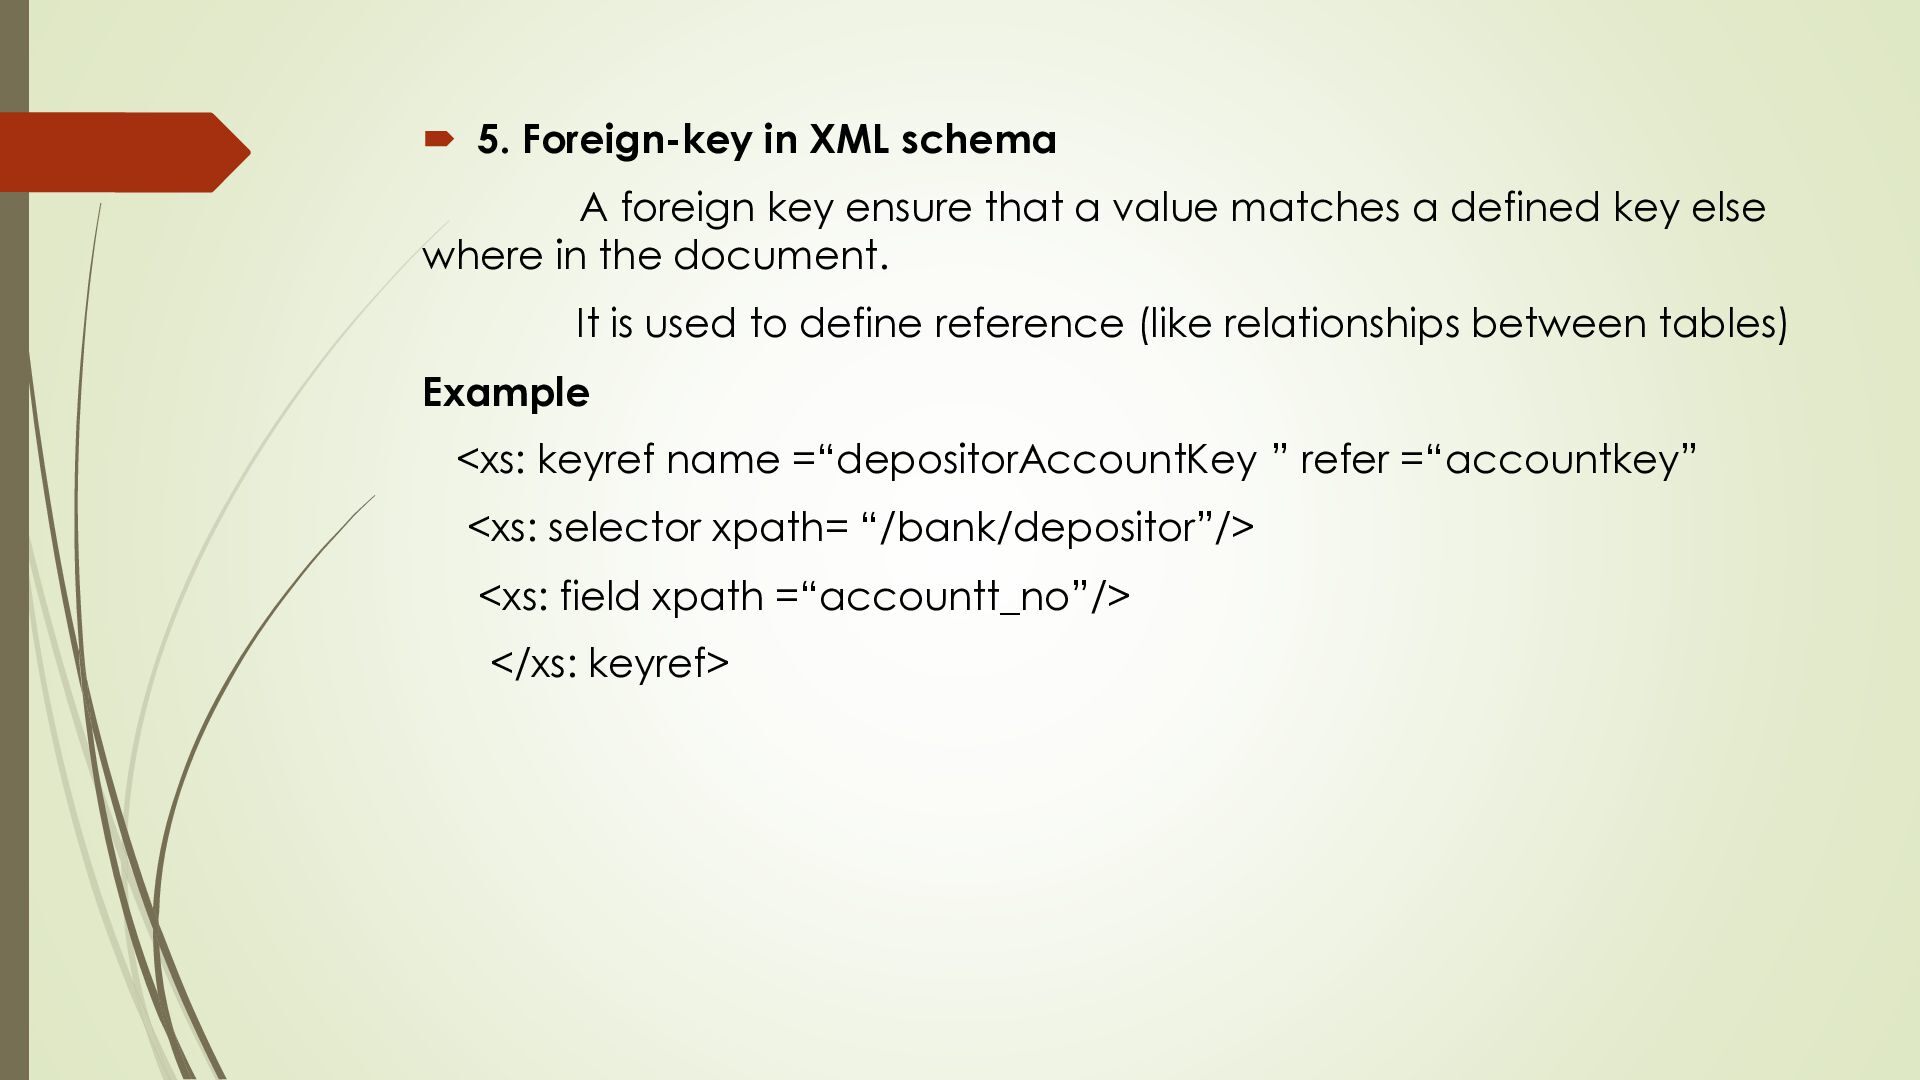
that a value matches a defined key else where in the document. It is used to define reference (like relationships between tables) Example <xs: keyref name =“depositorAccountKey ” refer =“accountkey” <xs: selector xpath= “/bank/depositor”/> <xs: field xpath =“accountt_no”/> </xs: keyref>
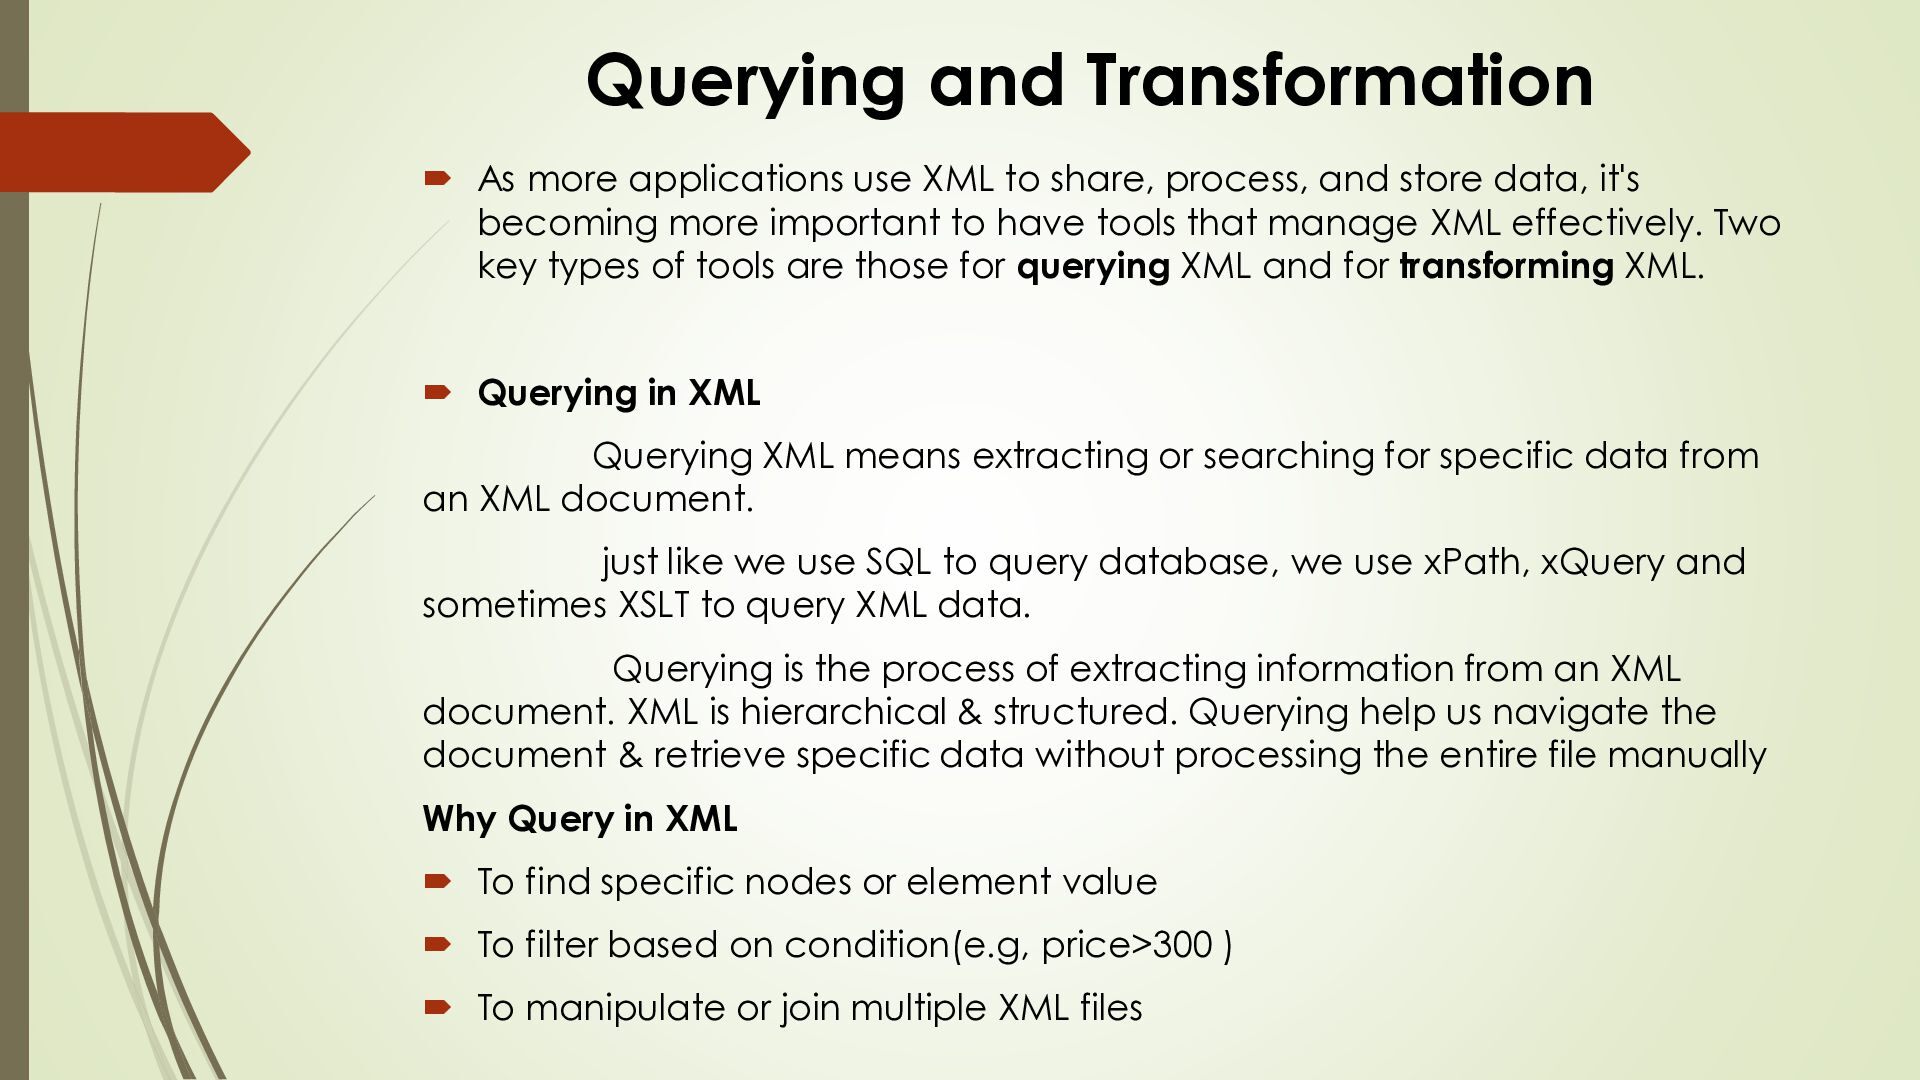
share, process, and store data, it's becoming more important to have tools that manage XML effectively. Two key types of tools are those for querying XML and for transforming XML. Querying in XML Querying XML means extracting or searching for specific data from an XML document. just like we use SQL to query database, we use xPath, xQuery and sometimes XSLT to query XML data. Querying is the process of extracting information from an XML document. XML is hierarchical & structured. Querying help us navigate the document & retrieve specific data without processing the entire file manually Why Query in XML To find specific nodes or element value To filter based on condition(e.g, price>300 ) To manipulate or join multiple XML files
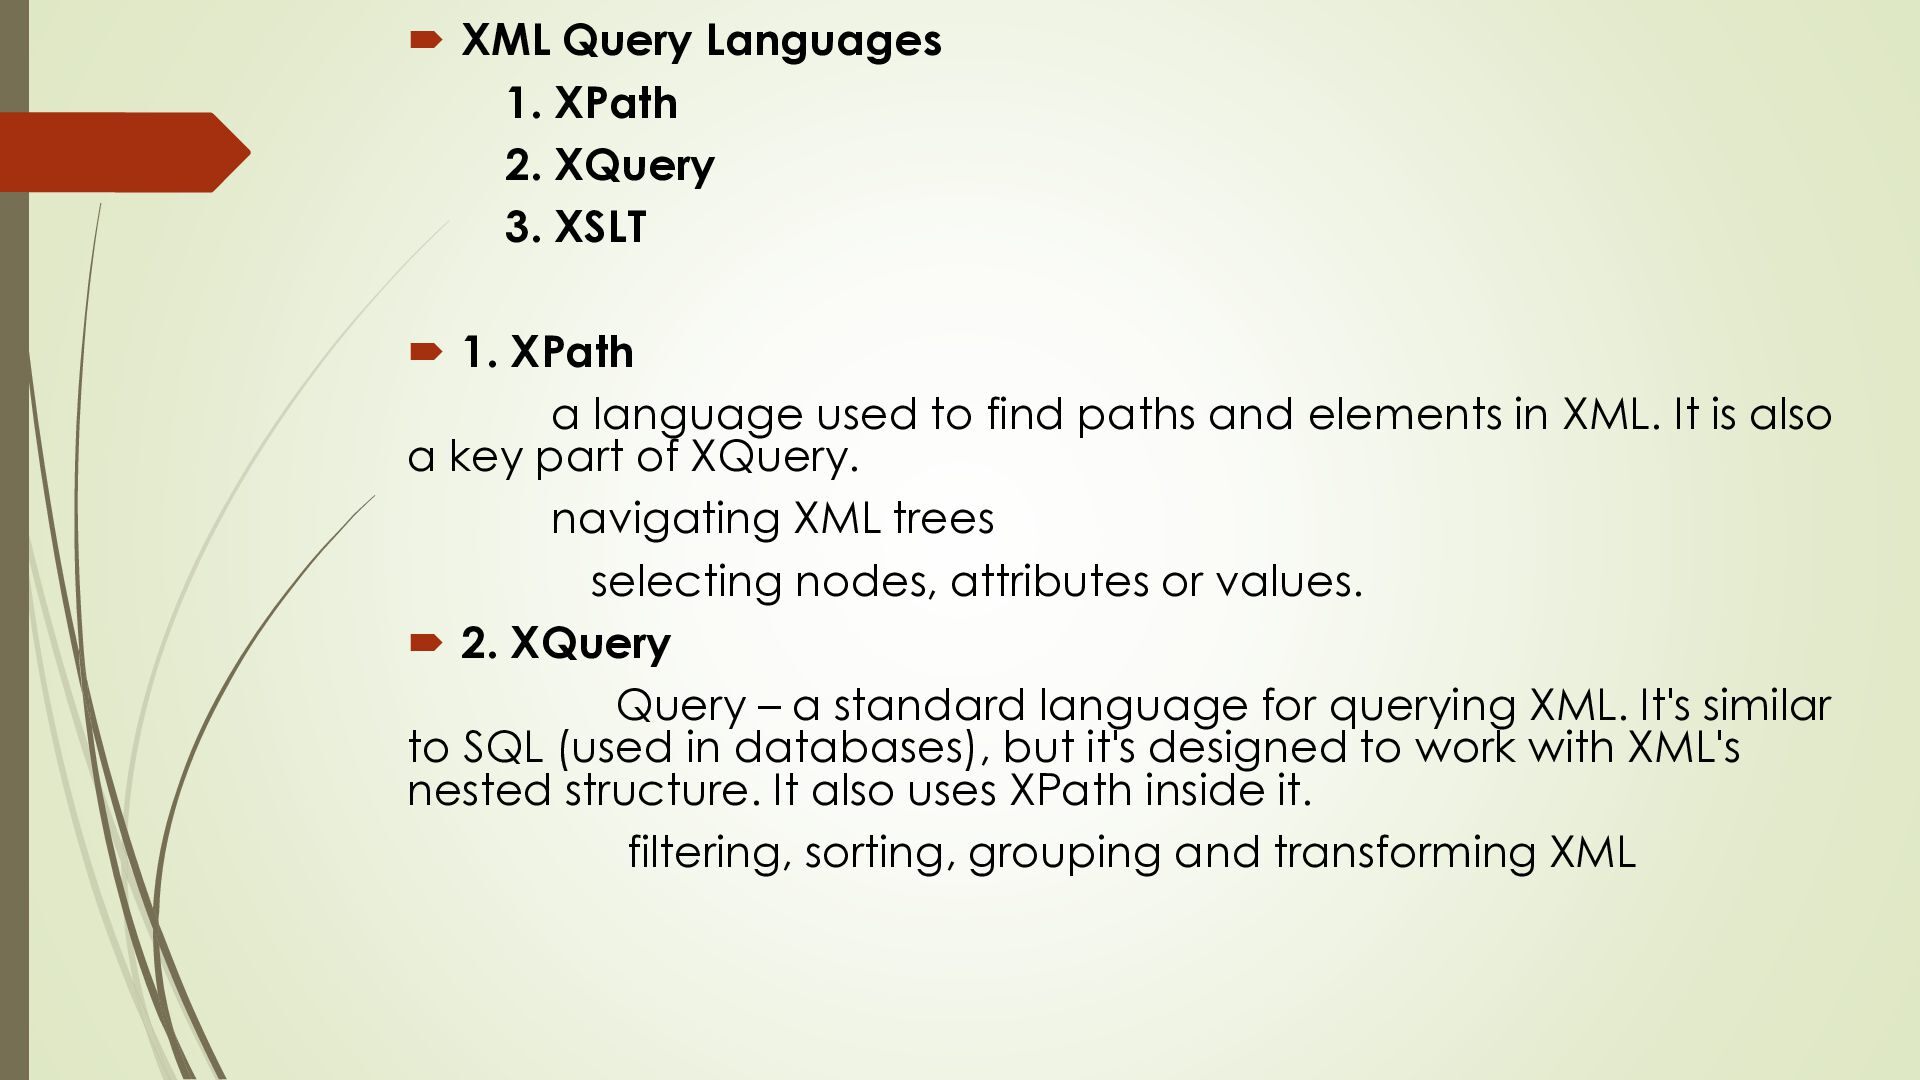
1. XPath a language used to find paths and elements in XML. It is also a key part of XQuery. navigating XML trees selecting nodes, attributes or values. 2. XQuery Query – a standard language for querying XML. It's similar to SQL (used in databases), but it's designed to work with XML's nested structure. It also uses XPath inside it. filtering, sorting, grouping and transforming XML
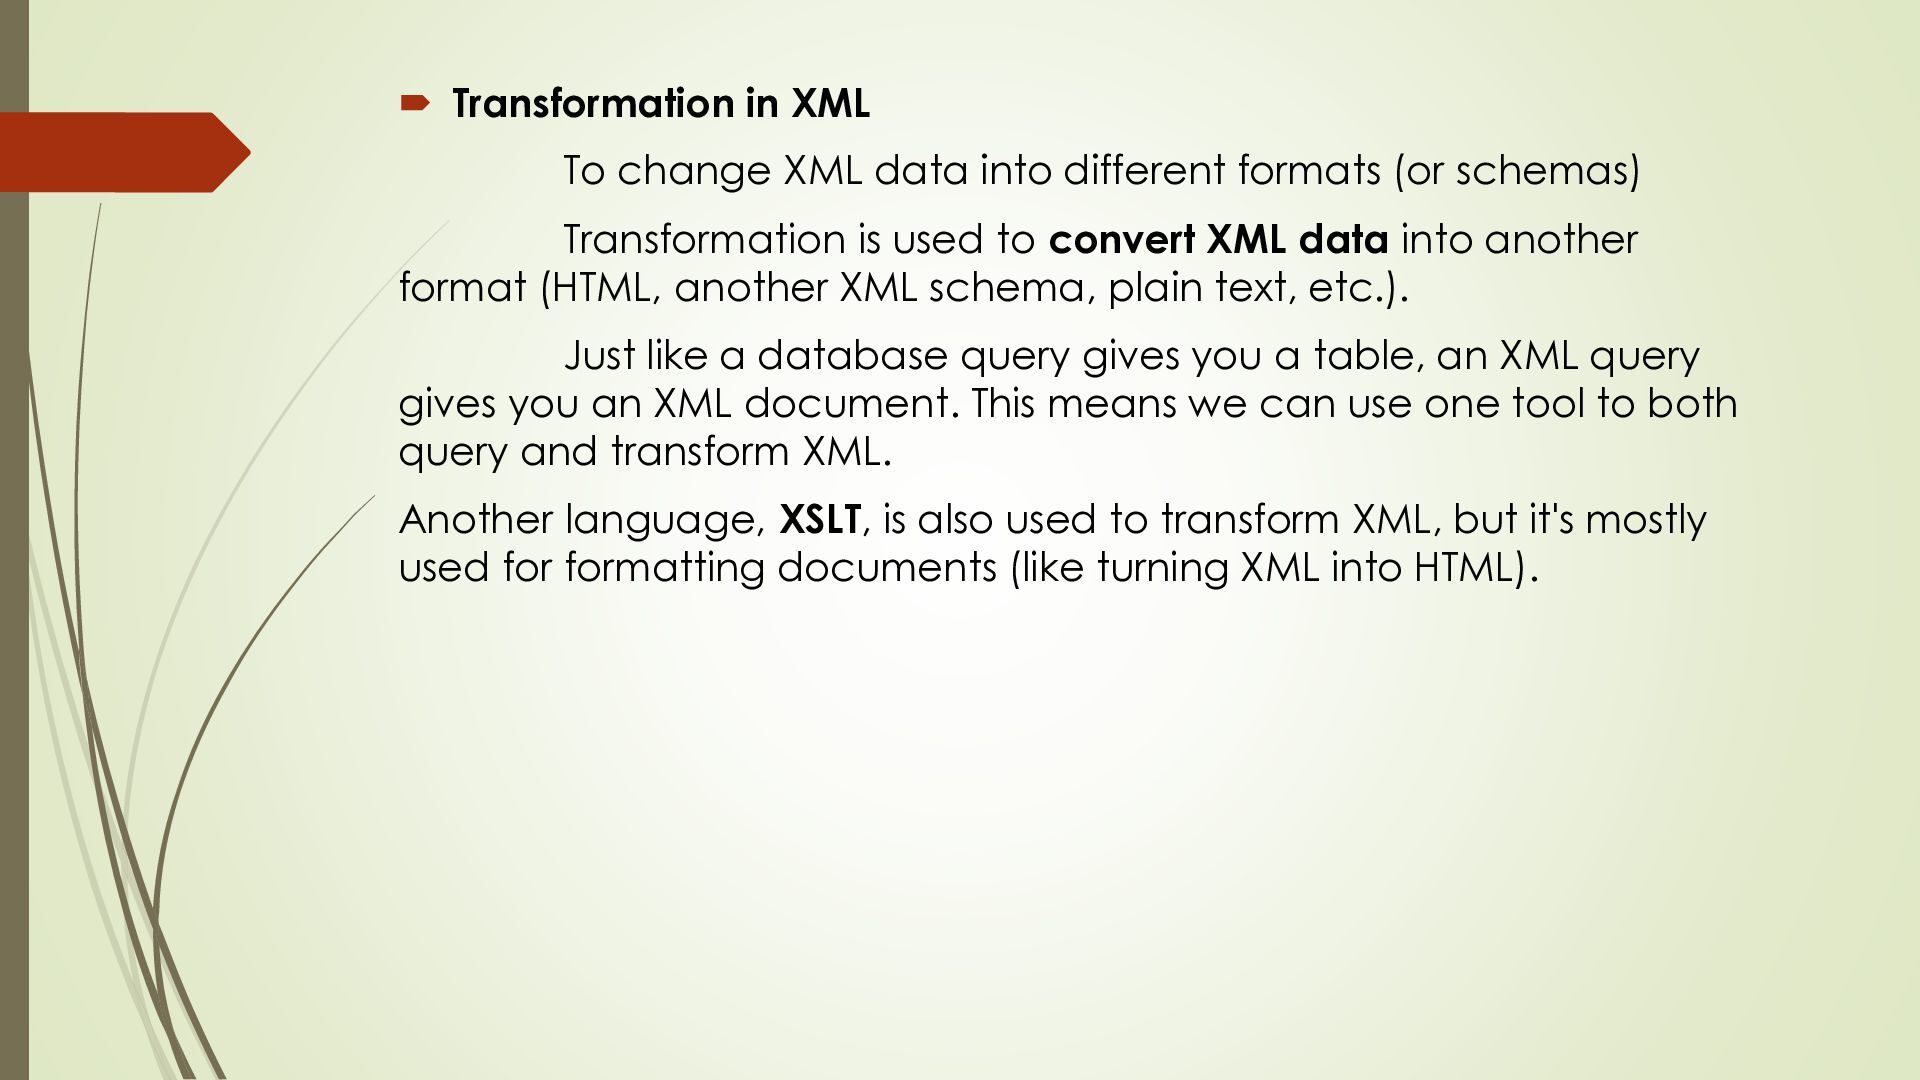
formats (or schemas) Transformation is used to convert XML data into another format (HTML, another XML schema, plain text, etc.). Just like a database query gives you a table, an XML query gives you an XML document. This means we can use one tool to both query and transform XML. Another language, XSLT, is also used to transform XML, but it's mostly used for formatting documents (like turning XML into HTML).
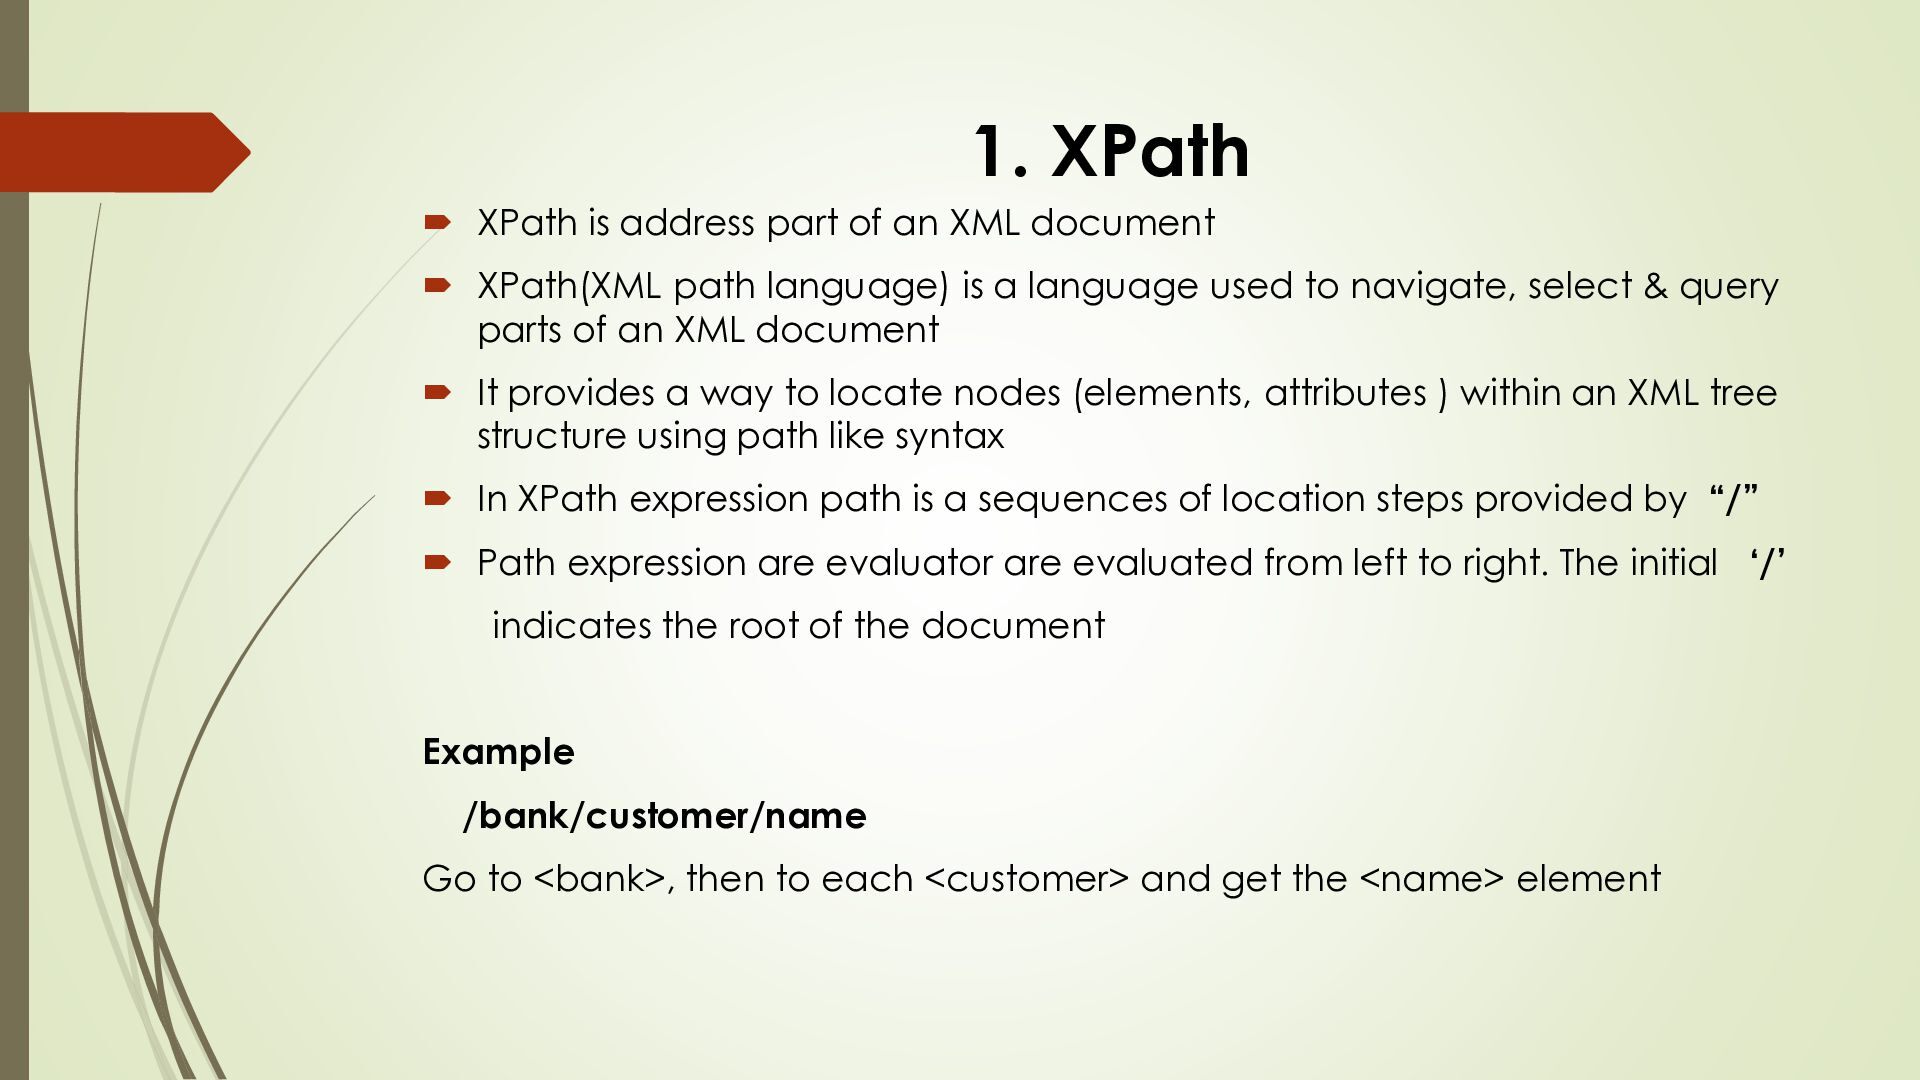
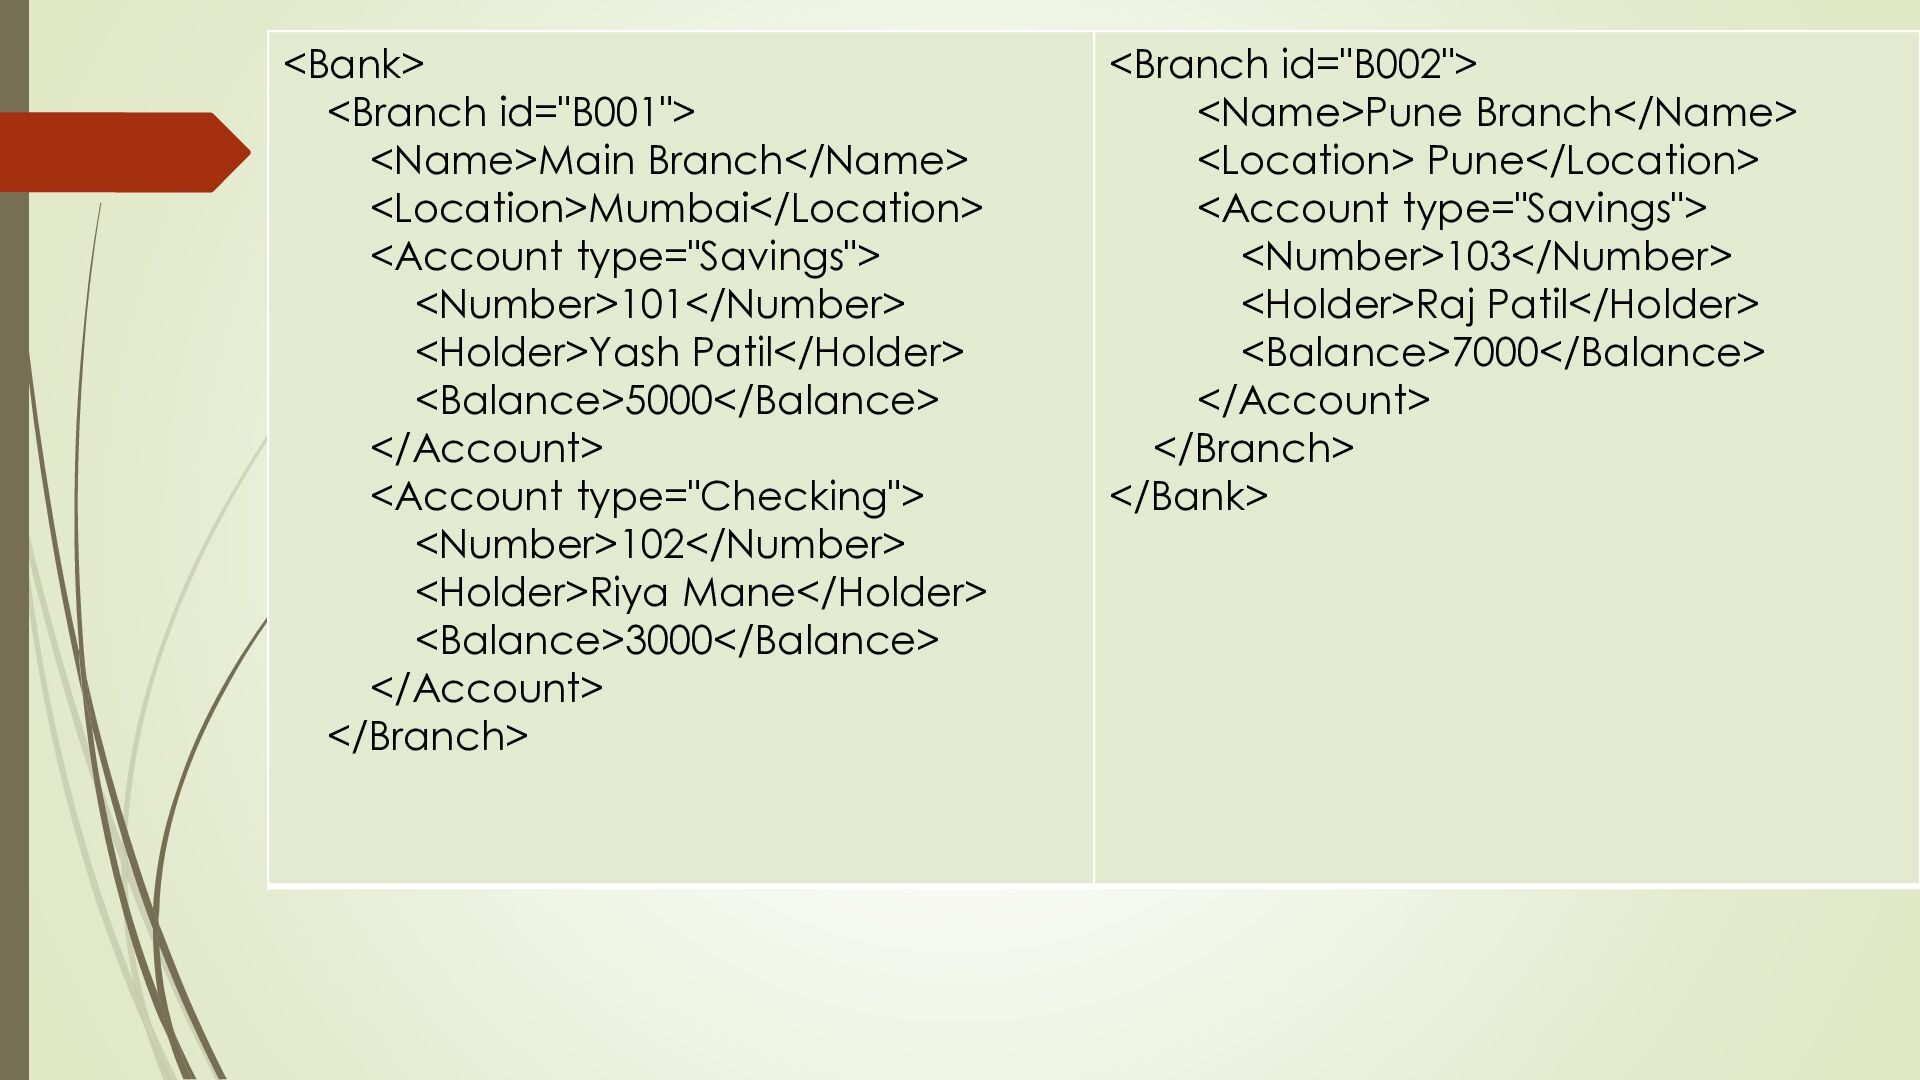
document XPath(XML path language) is a language used to navigate, select & query parts of an XML document It provides a way to locate nodes (elements, attributes ) within an XML tree structure using path like syntax In XPath expression path is a sequences of location steps provided by “/” Path expression are evaluator are evaluated from left to right. The initial ‘/’ indicates the root of the document Example /bank/customer/name Go to <bank>, then to each <customer> and get the <name> element
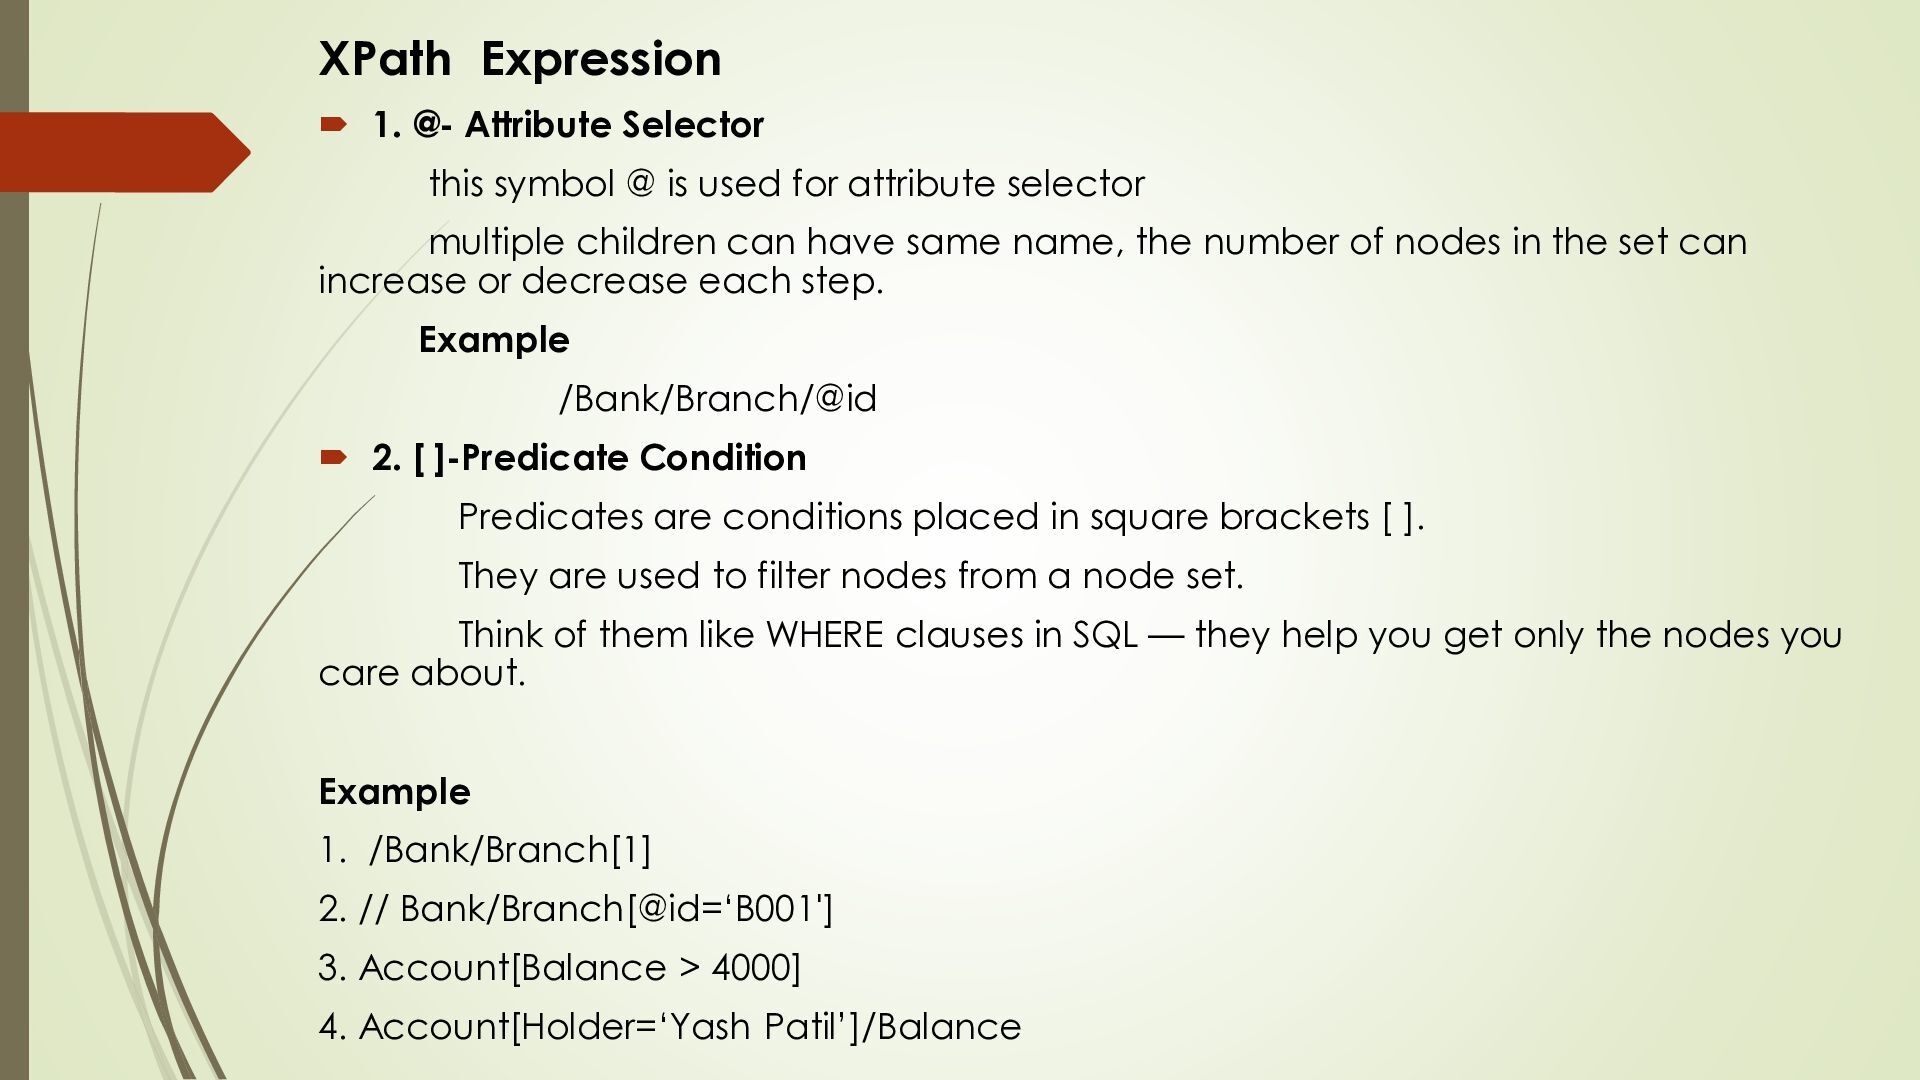
is used for attribute selector multiple children can have same name, the number of nodes in the set can increase or decrease each step. Example /Bank/Branch/@id 2. [ ]-Predicate Condition Predicates are conditions placed in square brackets [ ]. They are used to filter nodes from a node set. Think of them like WHERE clauses in SQL — they help you get only the nodes you care about. Example 1. /Bank/Branch[1] 2. // Bank/Branch[@id=‘B001'] 3. Account[Balance > 4000] 4. Account[Holder=‘Yash Patil’]/Balance
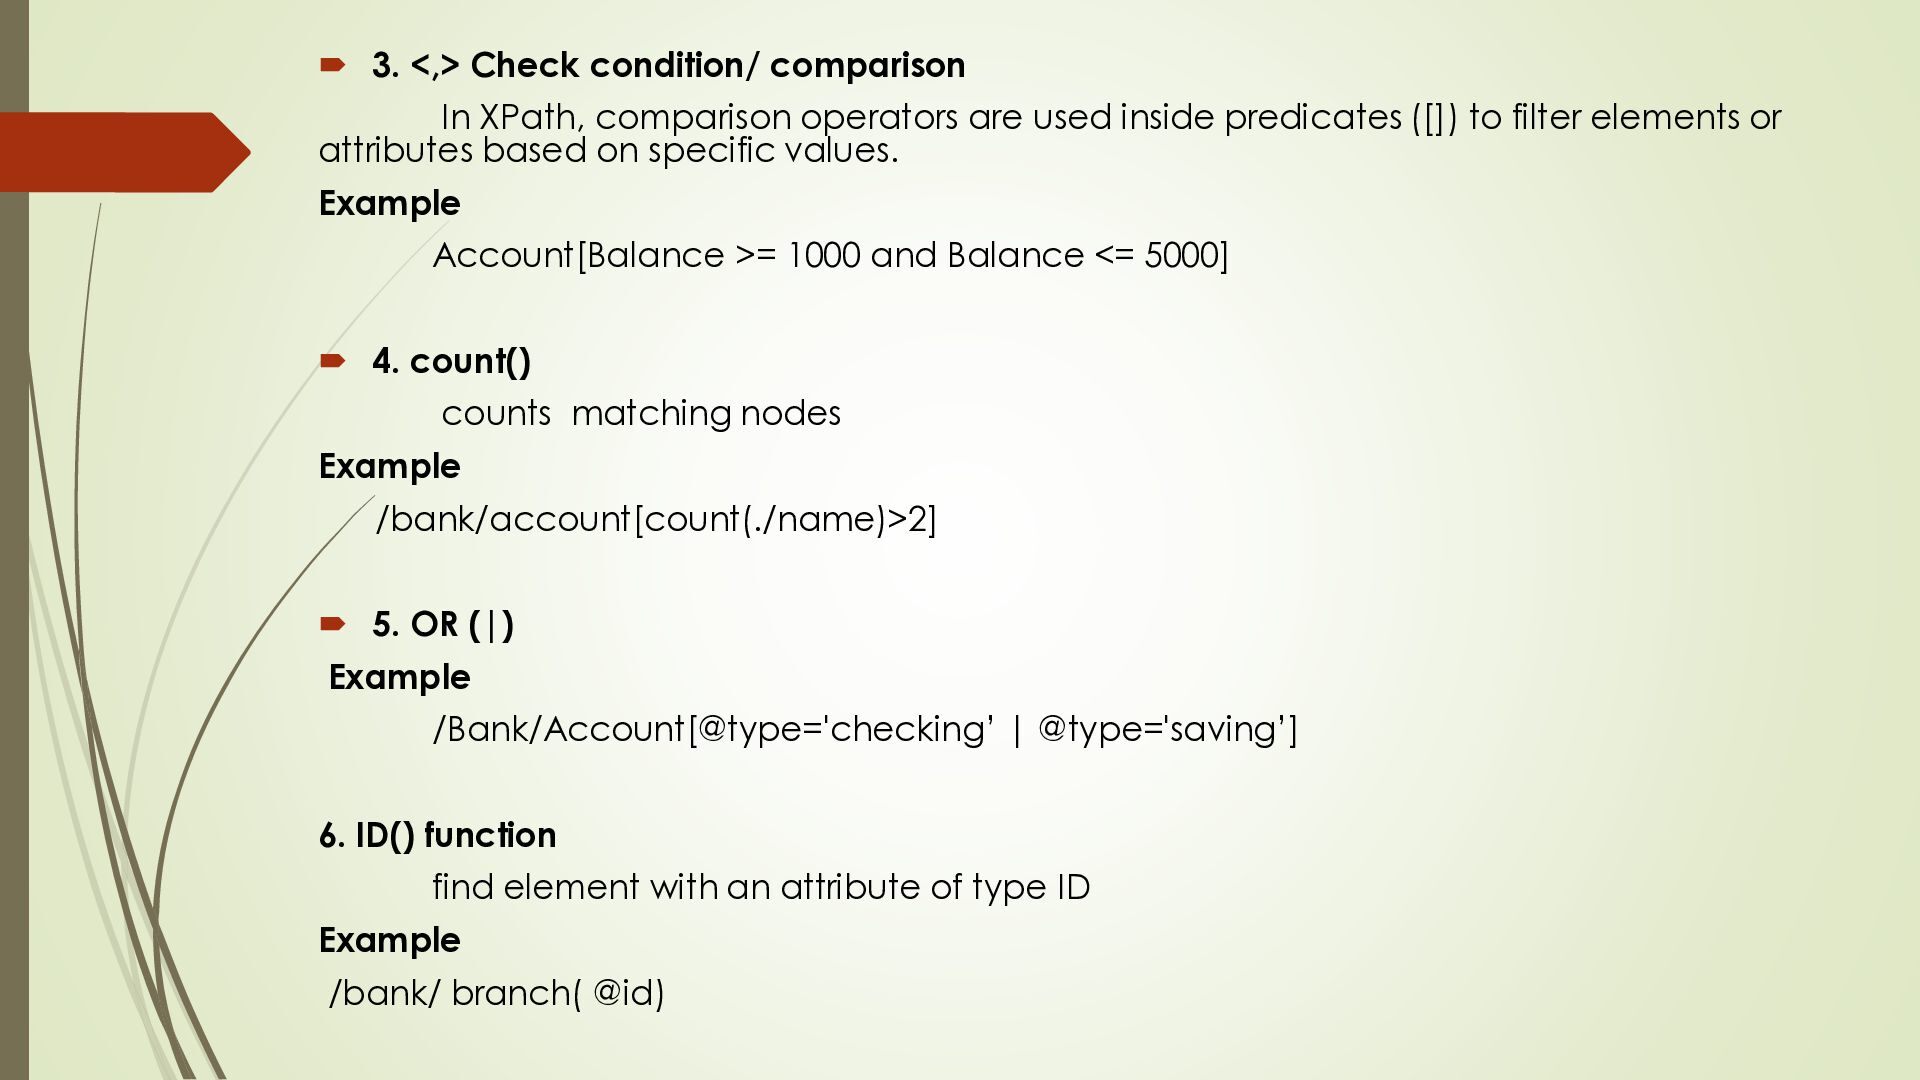
are used inside predicates ([]) to filter elements or attributes based on specific values. Example Account[Balance >= 1000 and Balance <= 5000] 4. count() counts matching nodes Example /bank/account[count(./name)>2] 5. OR (|) Example /Bank/Account[@type='checking’ | @type='saving’] 6. ID() function find element with an attribute of type ID Example /bank/ branch( @id)
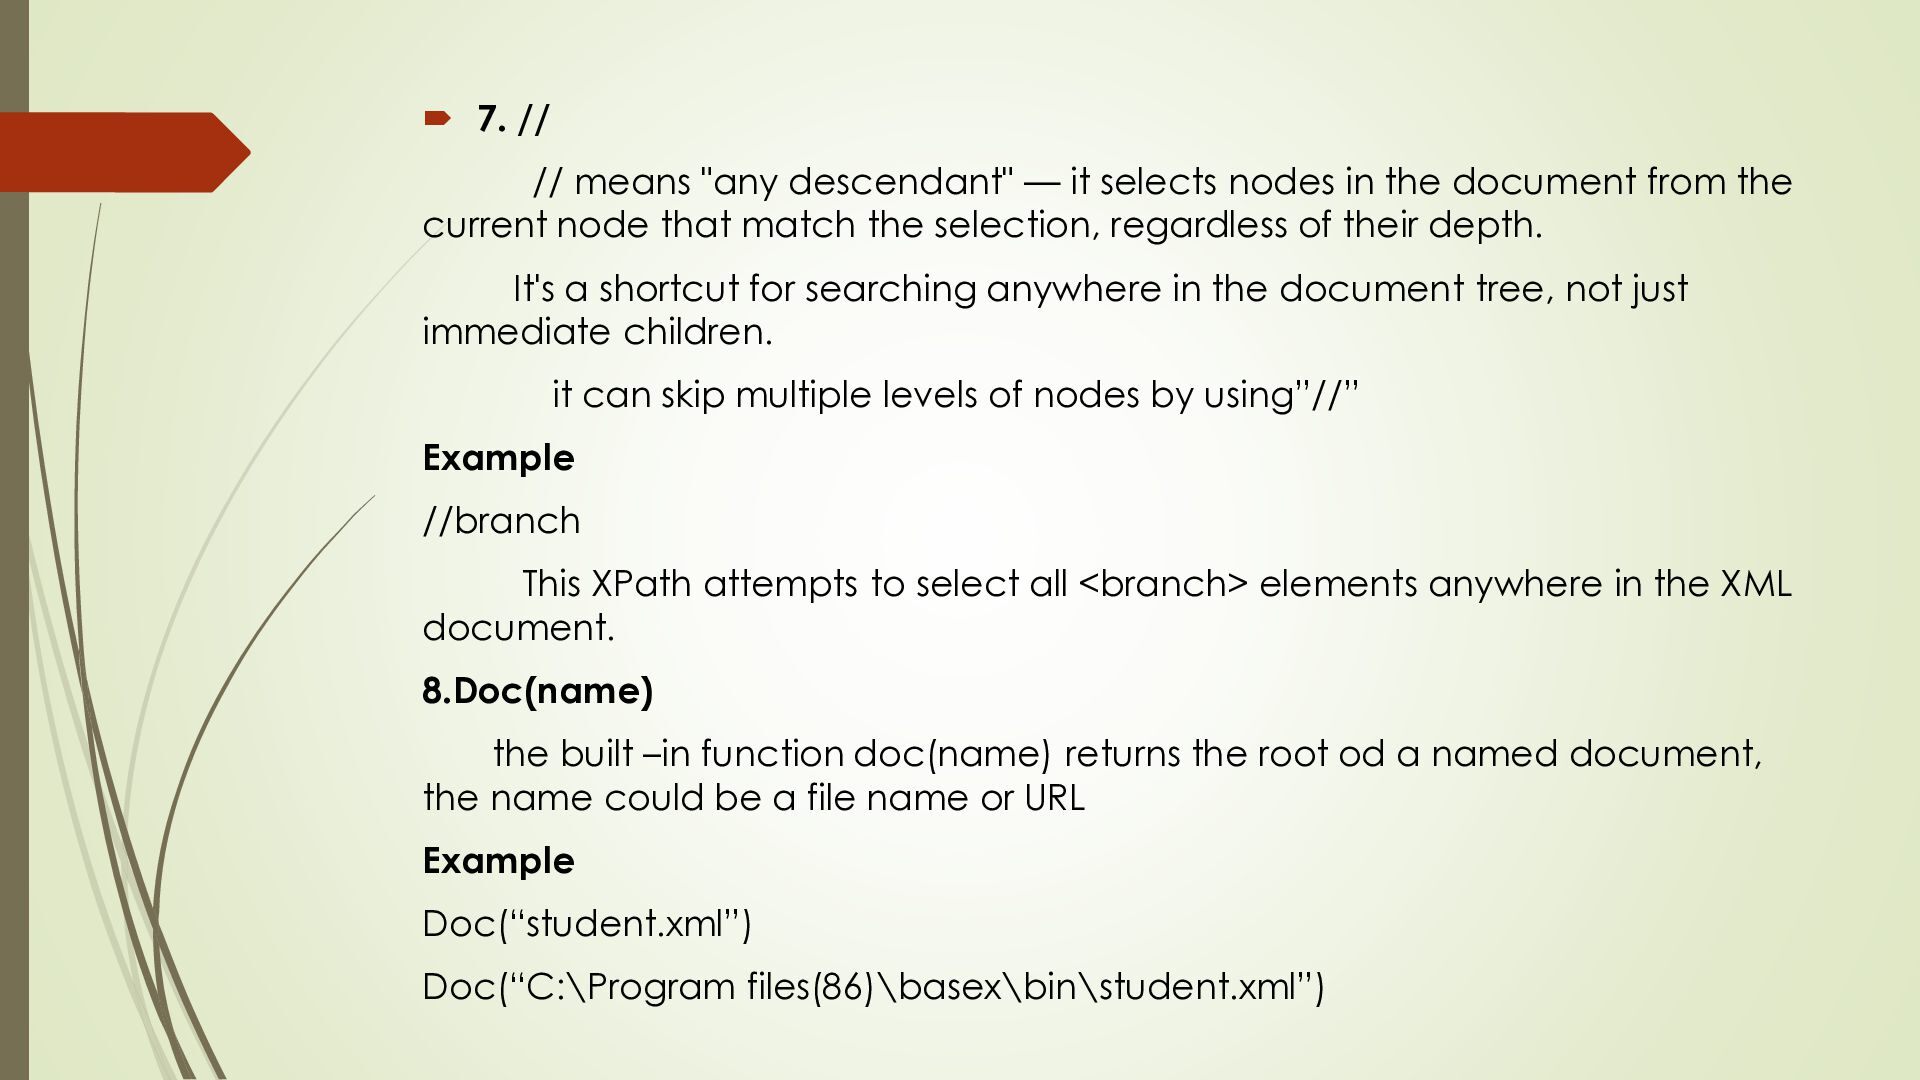
nodes in the document from the current node that match the selection, regardless of their depth. It's a shortcut for searching anywhere in the document tree, not just immediate children. it can skip multiple levels of nodes by using”//” Example //branch This XPath attempts to select all <branch> elements anywhere in the XML document. 8.Doc(name) the built –in function doc(name) returns the root od a named document, the name could be a file name or URL Example Doc(“student.xml”) Doc(“C:\Program files(86)\basex\bin\student.xml”)
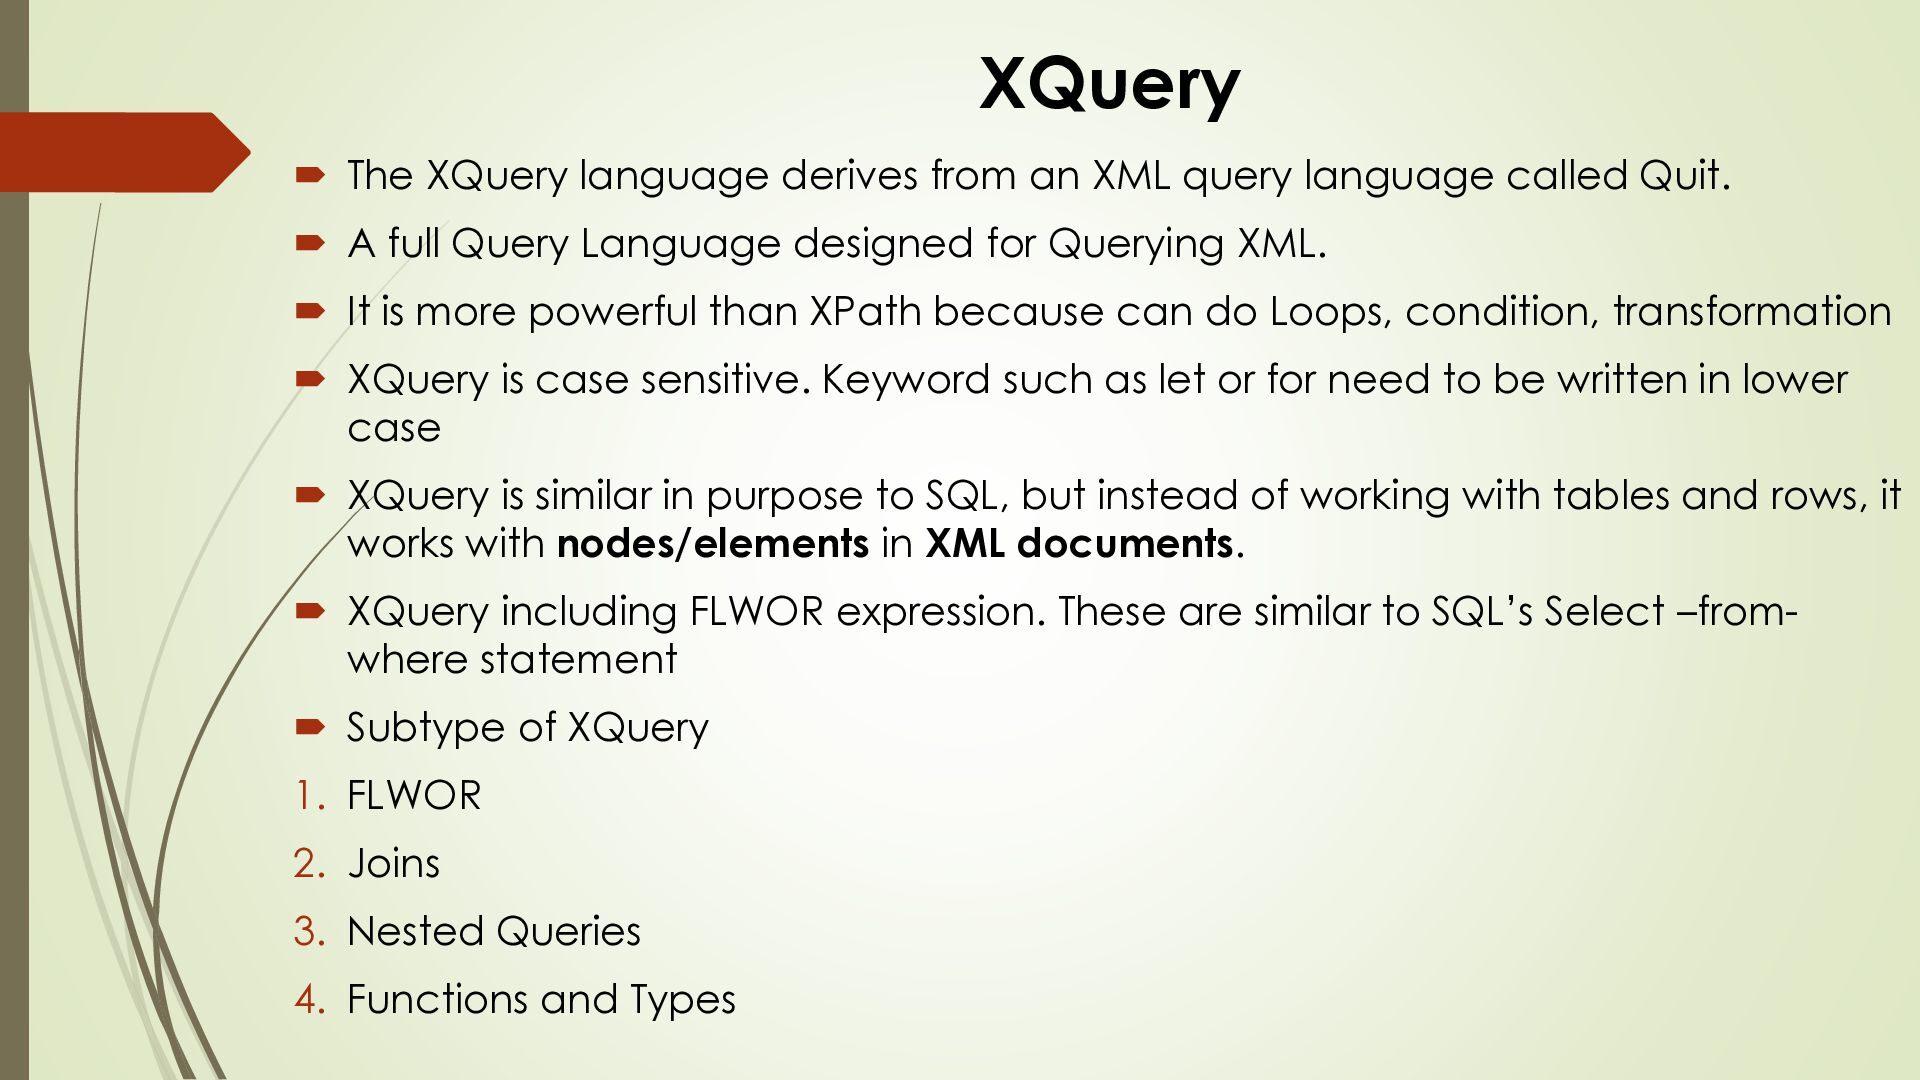
language called Quit. A full Query Language designed for Querying XML. It is more powerful than XPath because can do Loops, condition, transformation XQuery is case sensitive. Keyword such as let or for need to be written in lower case XQuery is similar in purpose to SQL, but instead of working with tables and rows, it works with nodes/elements in XML documents. XQuery including FLWOR expression. These are similar to SQL’s Select –fromwhere statement Subtype of XQuery 1. FLWOR 2. Joins 3. Nested Queries 4. Functions and Types
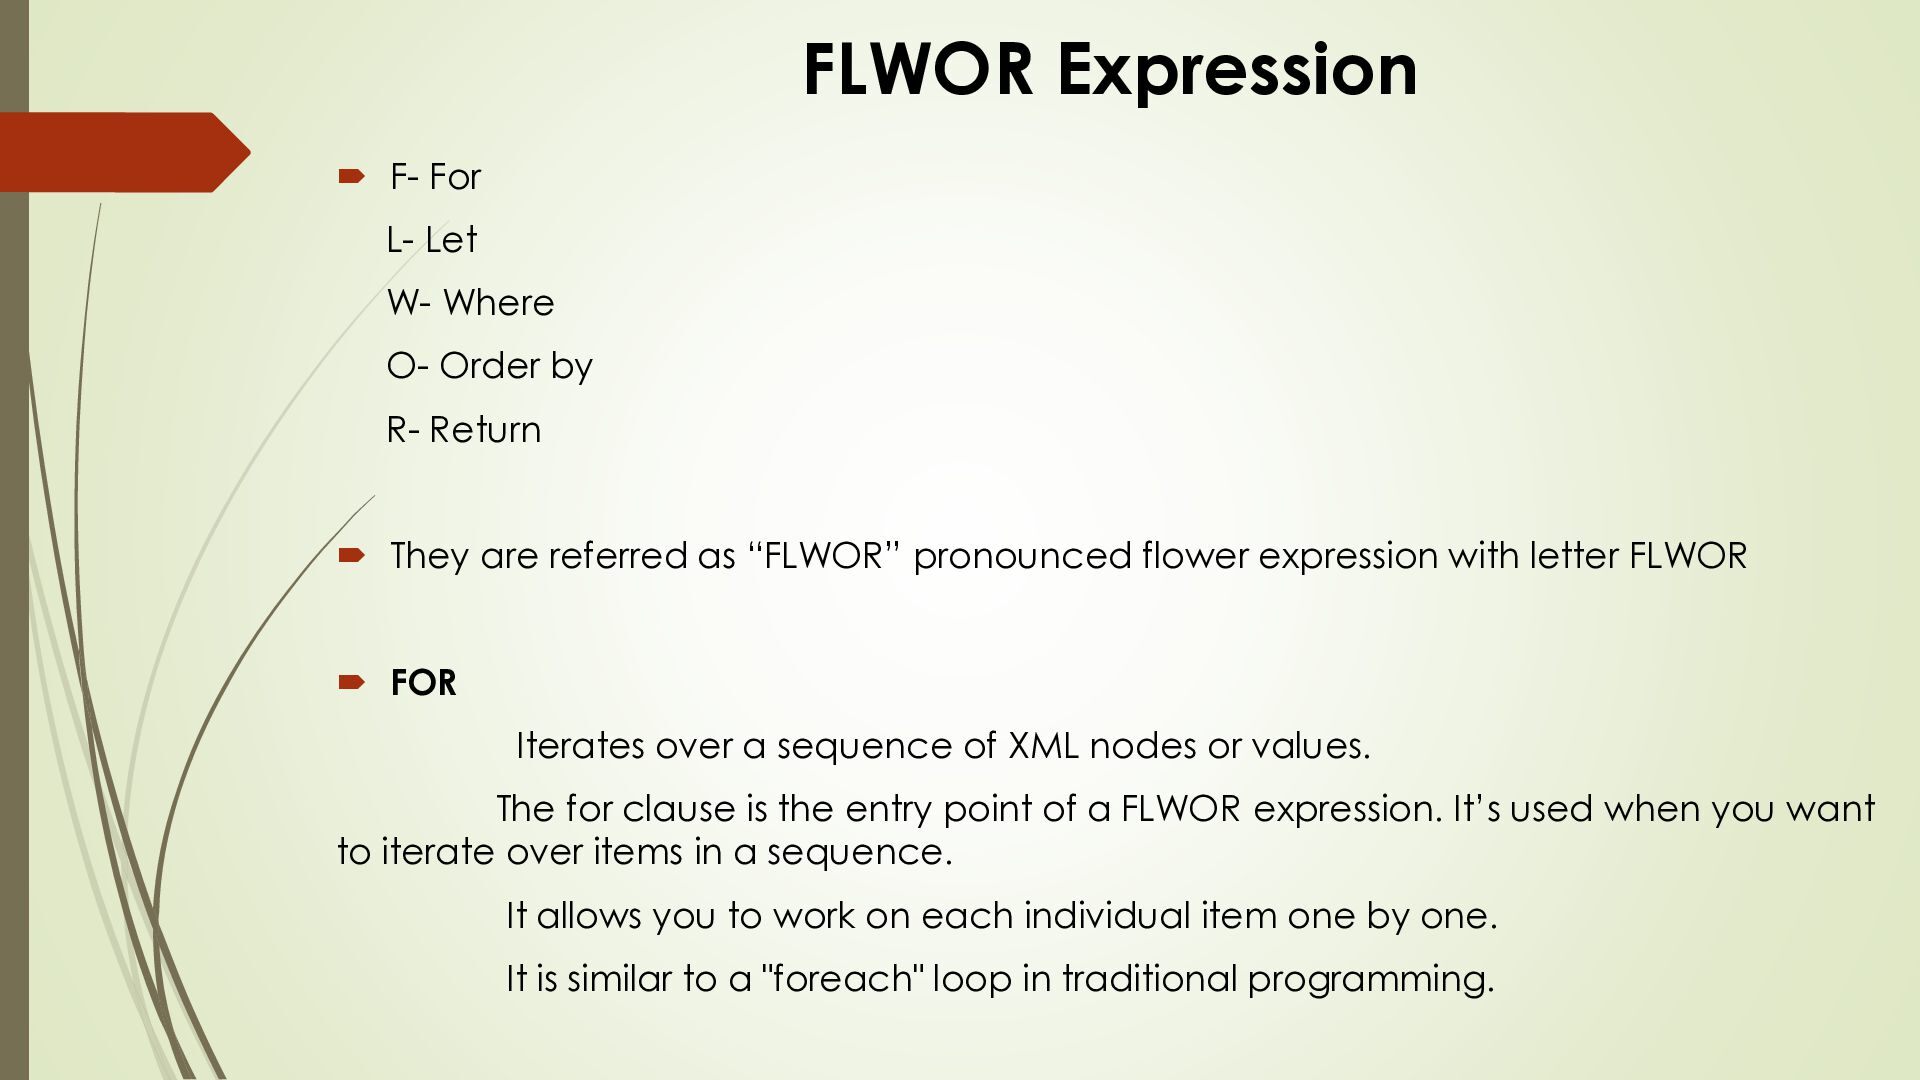
Order by R- Return They are referred as “FLWOR” pronounced flower expression with letter FLWOR FOR Iterates over a sequence of XML nodes or values. The for clause is the entry point of a FLWOR expression. It’s used when you want to iterate over items in a sequence. It allows you to work on each individual item one by one. It is similar to a "foreach" loop in traditional programming.
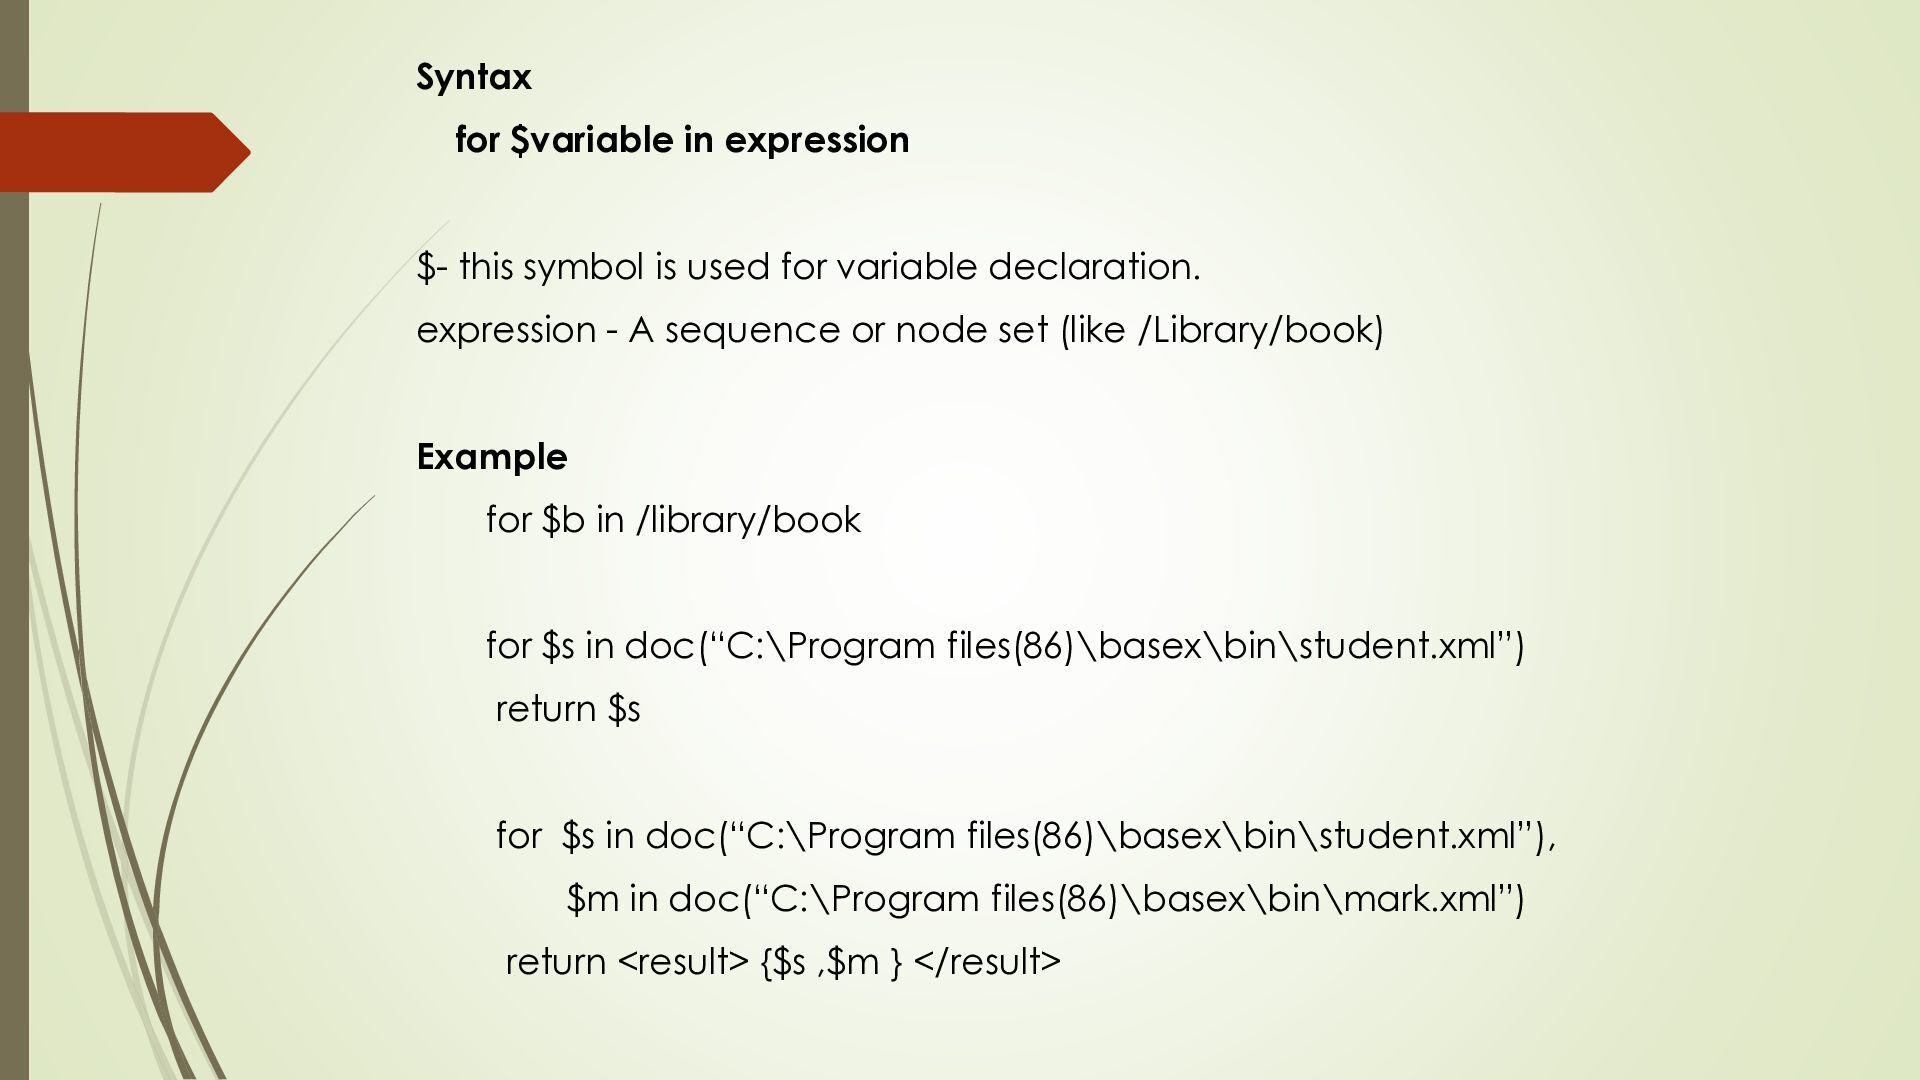
for variable declaration. expression - A sequence or node set (like /Library/book) Example for $b in /library/book for $s in doc(“C:\Program files(86)\basex\bin\student.xml”) return $s for $s in doc(“C:\Program files(86)\basex\bin\student.xml”), $m in doc(“C:\Program files(86)\basex\bin\mark.xml”) return <result> {$s ,$m } </result>
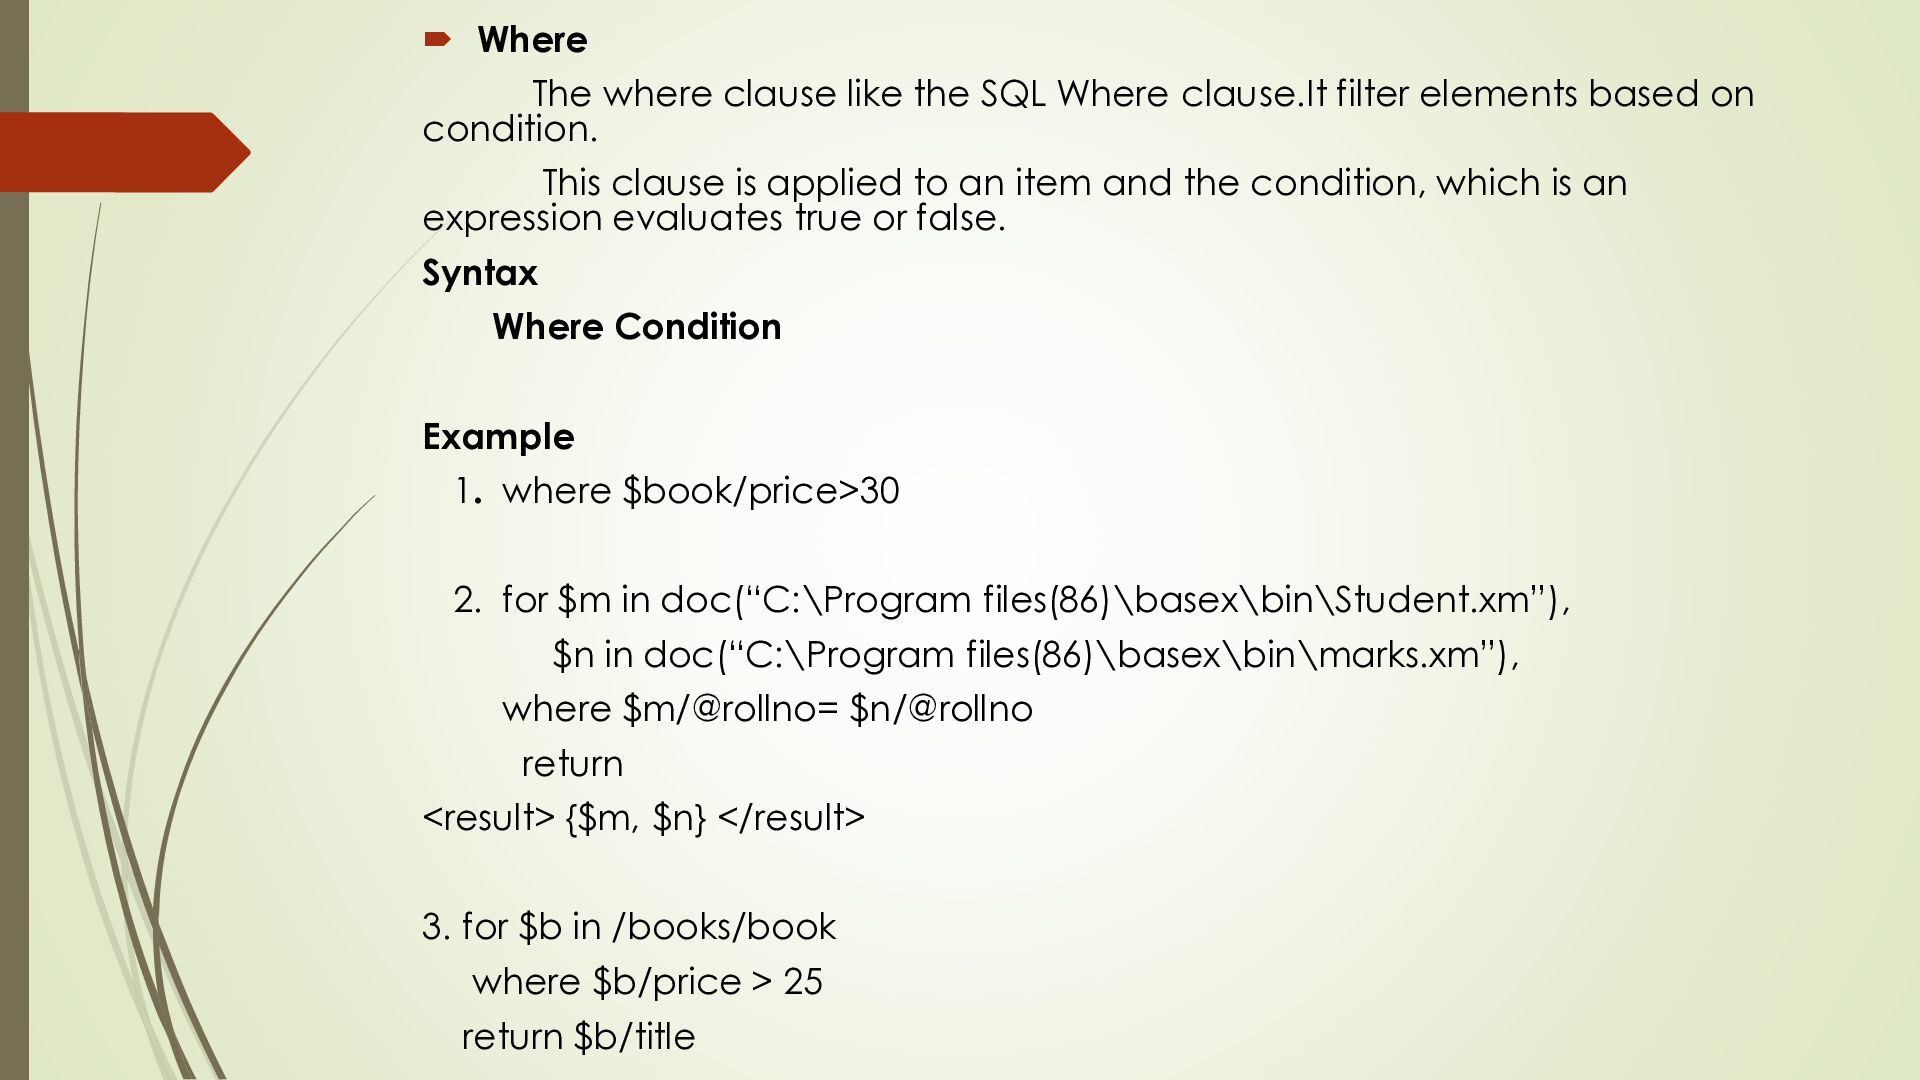
filter elements based on condition. This clause is applied to an item and the condition, which is an expression evaluates true or false. Syntax Where Condition Example 1. where $book/price>30 2. for $m in doc(“C:\Program files(86)\basex\bin\Student.xm”), $n in doc(“C:\Program files(86)\basex\bin\marks.xm”), where $m/@rollno= $n/@rollno return <result> {$m, $n} </result> 3. for $b in /books/book where $b/price > 25 return $b/title
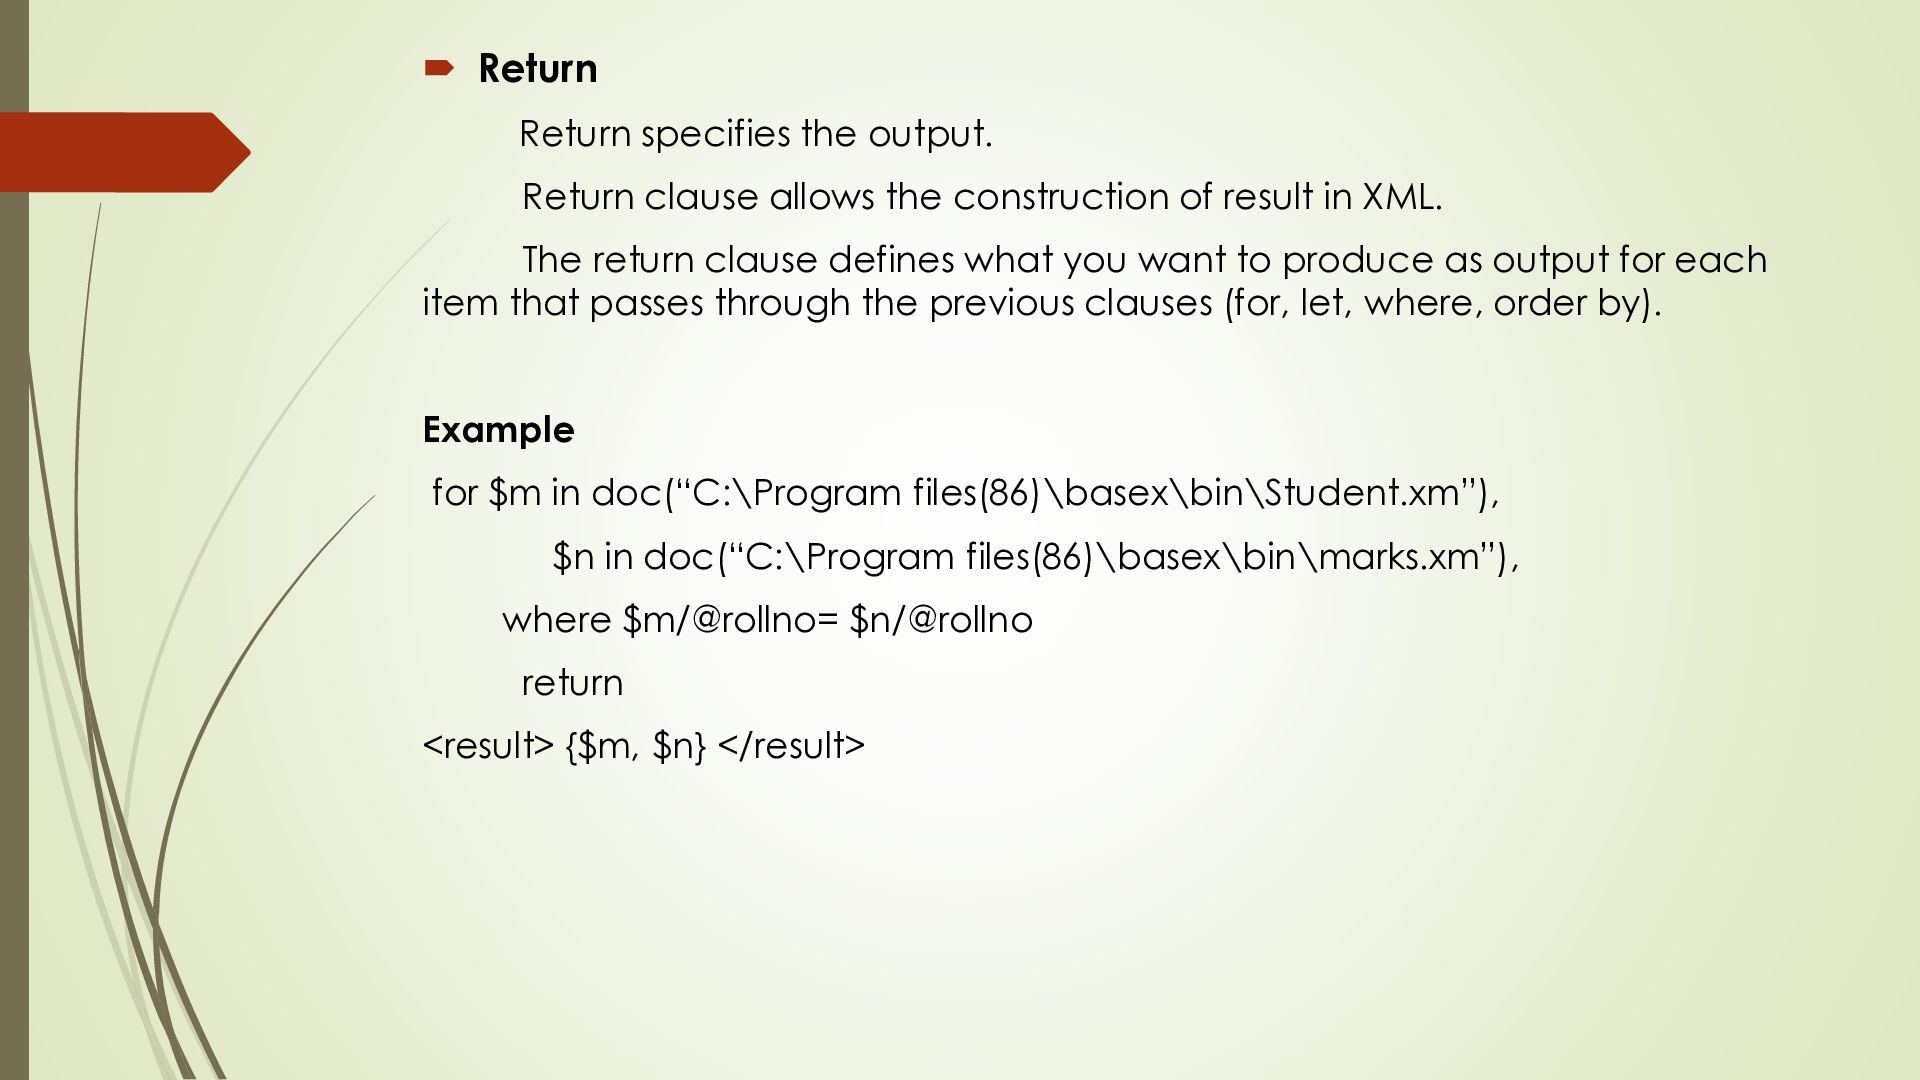
construction of result in XML. The return clause defines what you want to produce as output for each item that passes through the previous clauses (for, let, where, order by). Example for $m in doc(“C:\Program files(86)\basex\bin\Student.xm”), $n in doc(“C:\Program files(86)\basex\bin\marks.xm”), where $m/@rollno= $n/@rollno return <result> {$m, $n} </result>
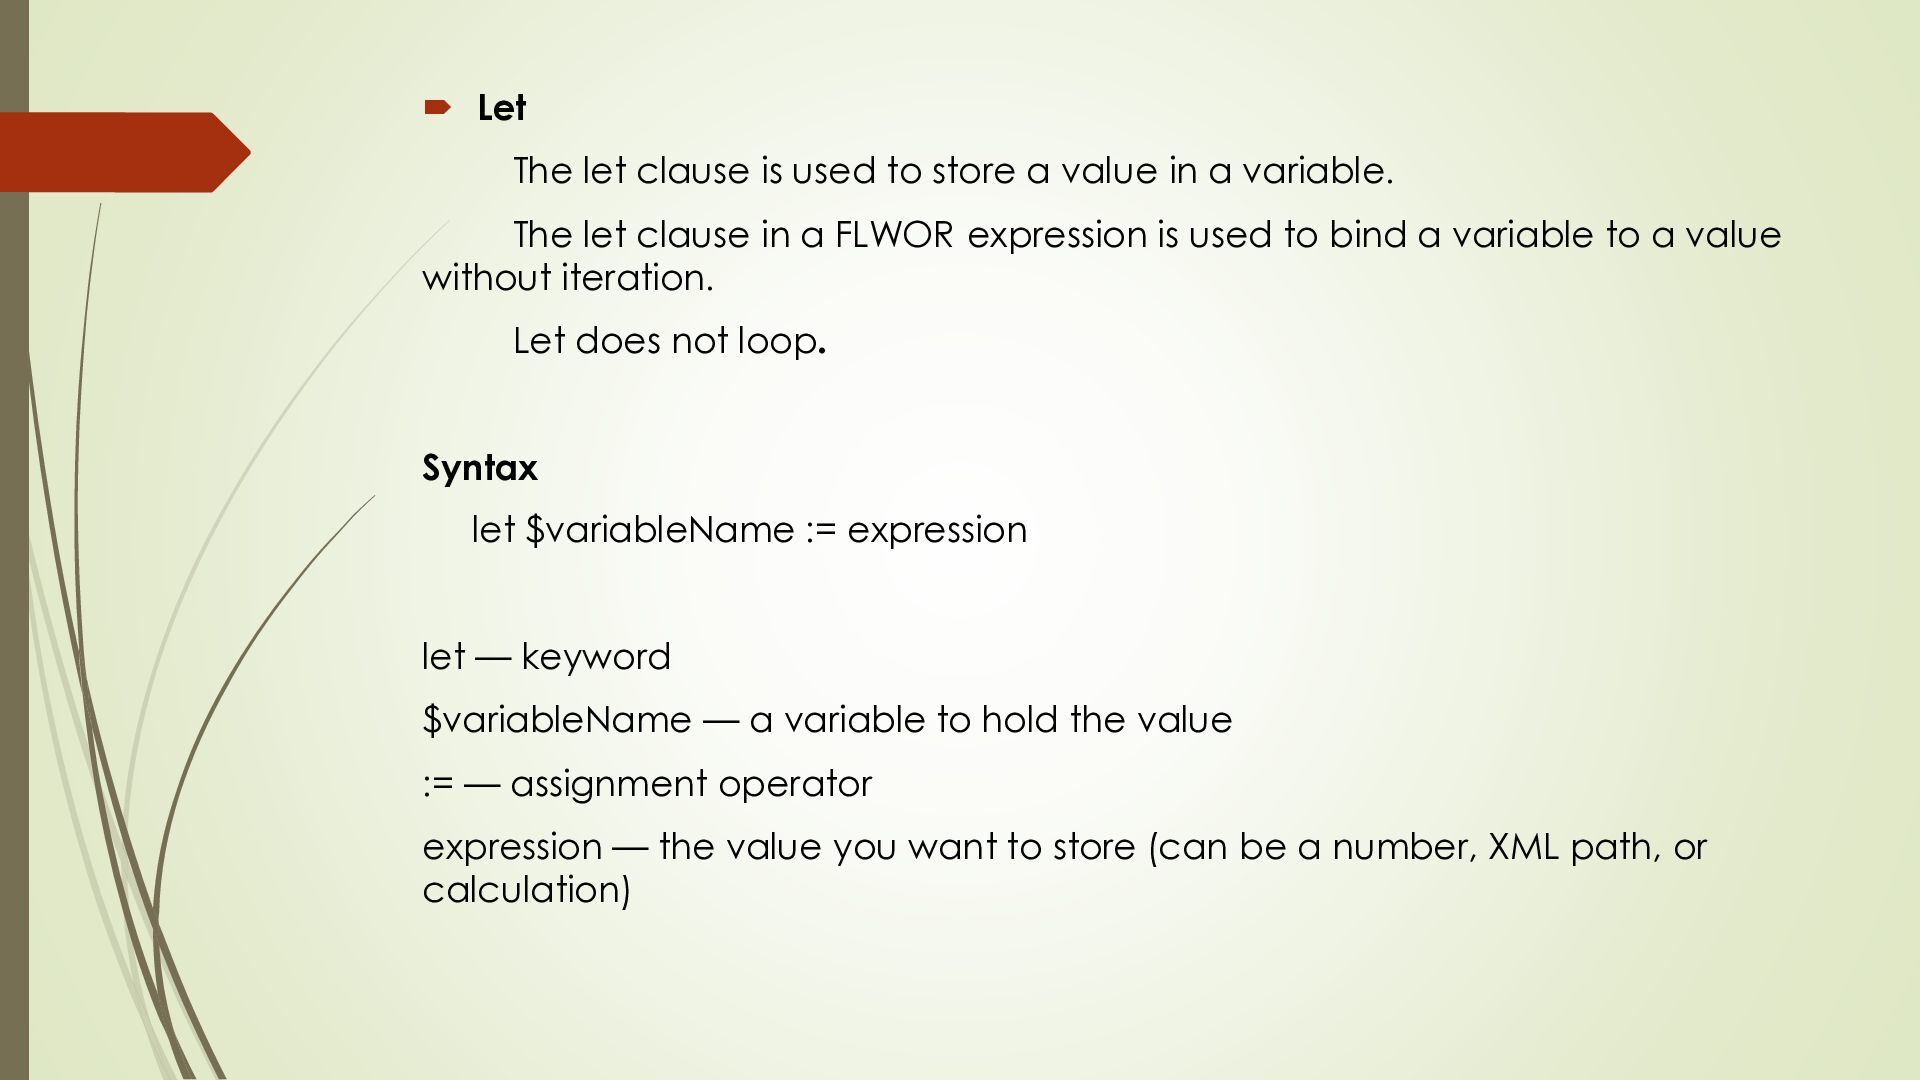
value in a variable. The let clause in a FLWOR expression is used to bind a variable to a value without iteration. Let does not loop. Syntax let $variableName := expression let — keyword $variableName — a variable to hold the value := — assignment operator expression — the value you want to store (can be a number, XML path, or calculation)
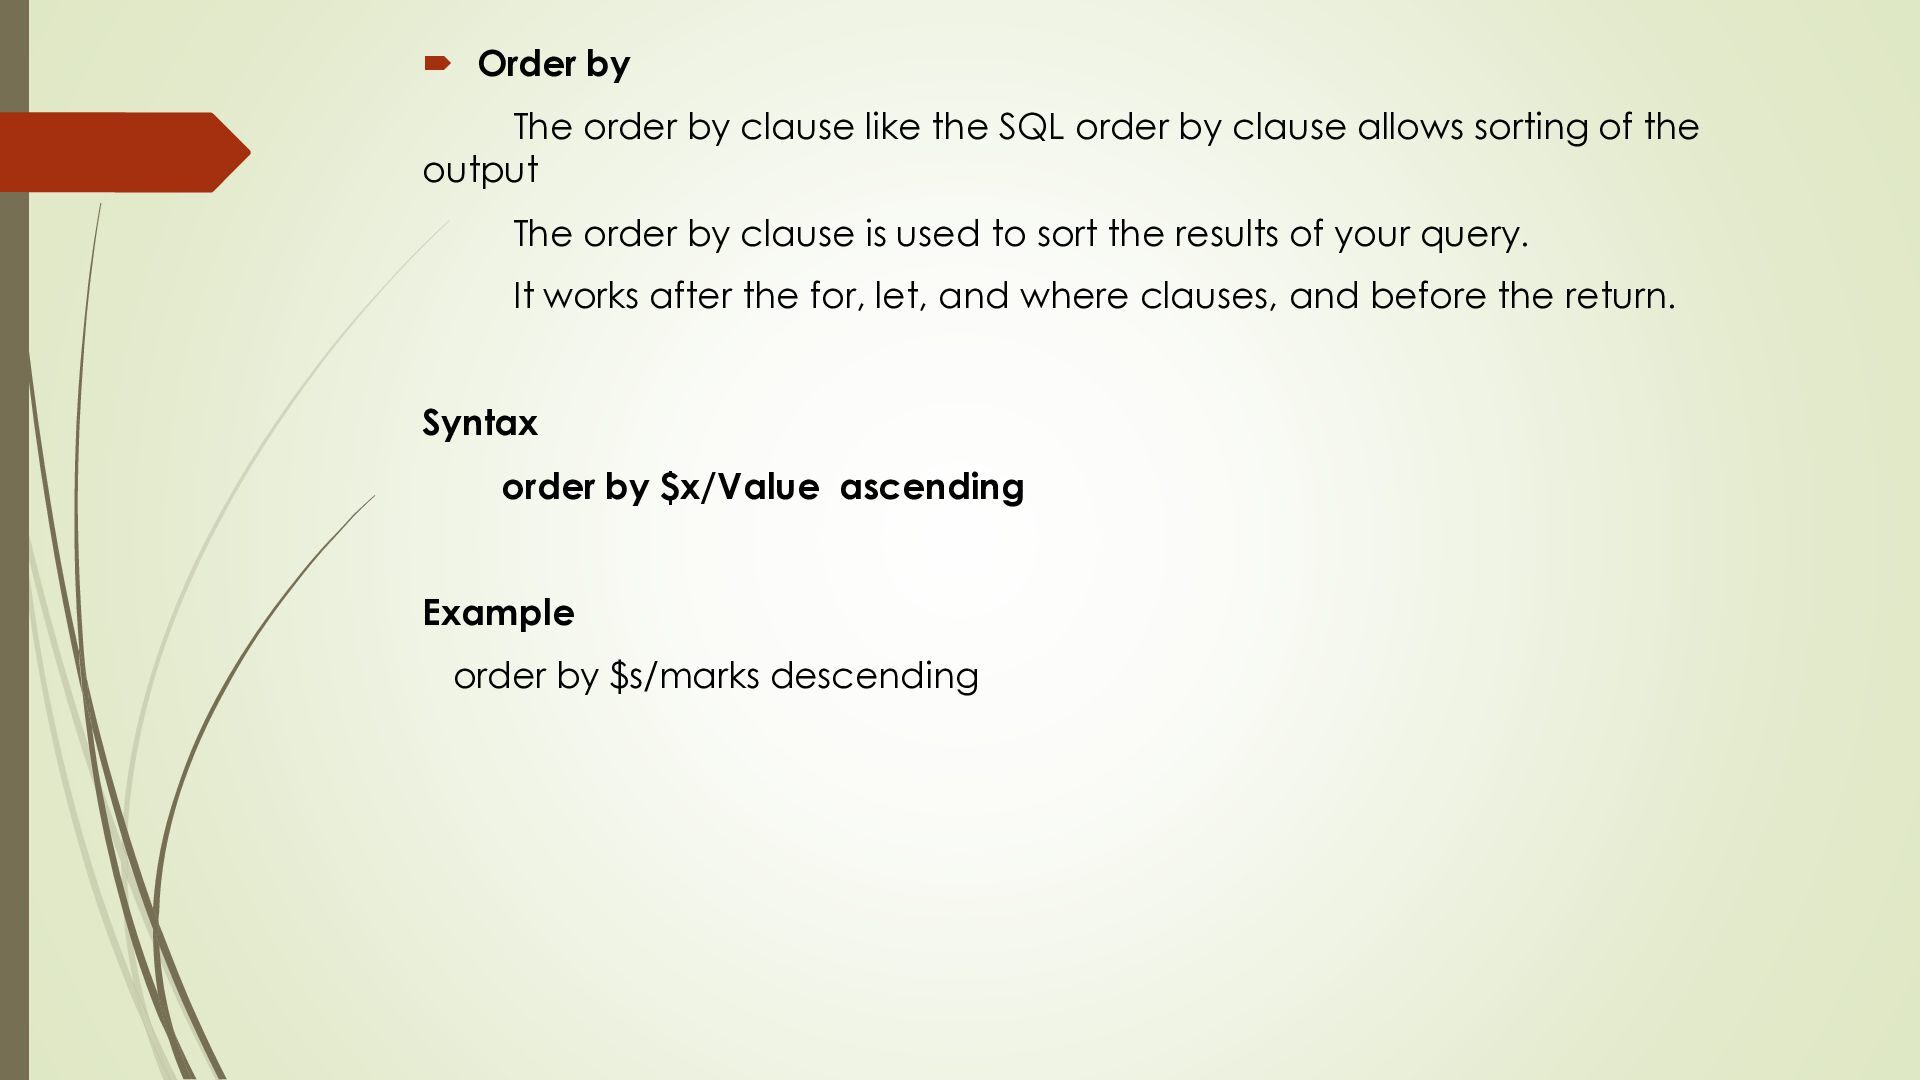
order by clause allows sorting of the output The order by clause is used to sort the results of your query. It works after the for, let, and where clauses, and before the return. Syntax order by $x/Value ascending Example order by $s/marks descending
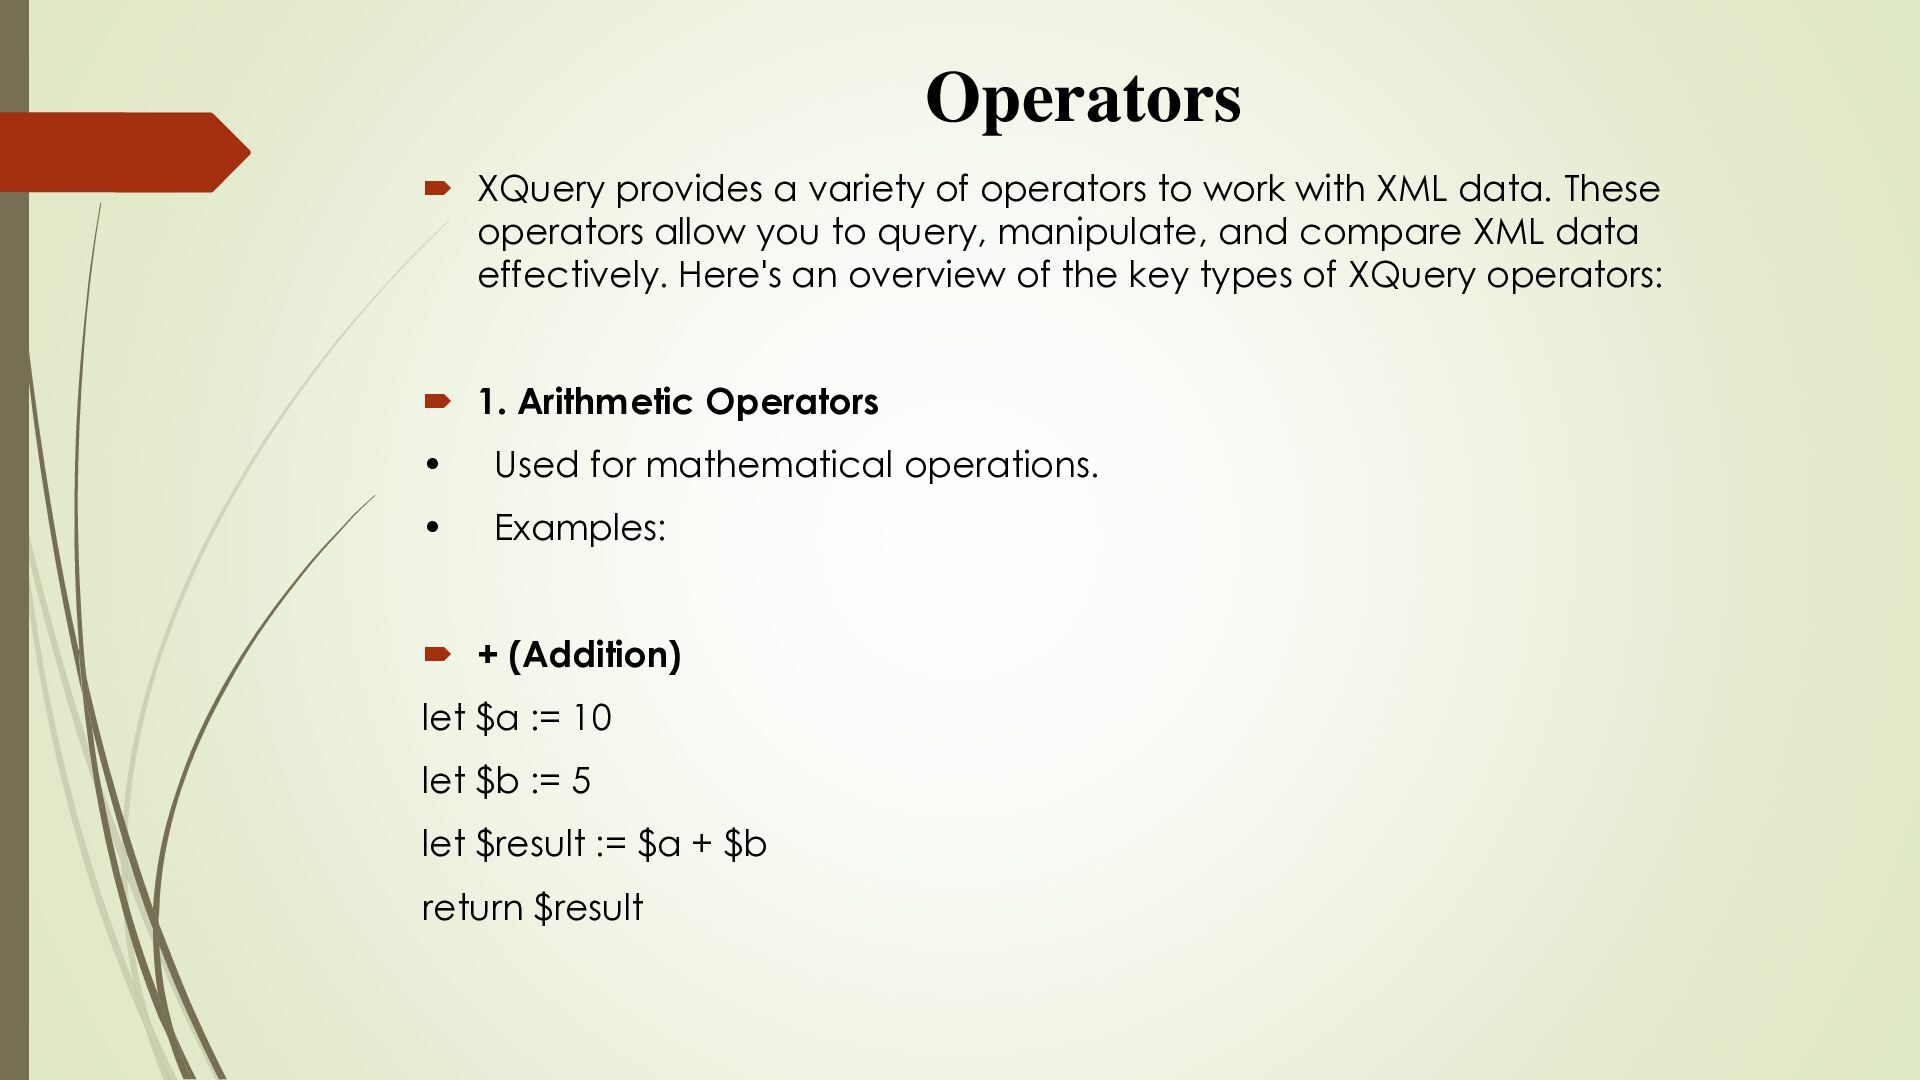
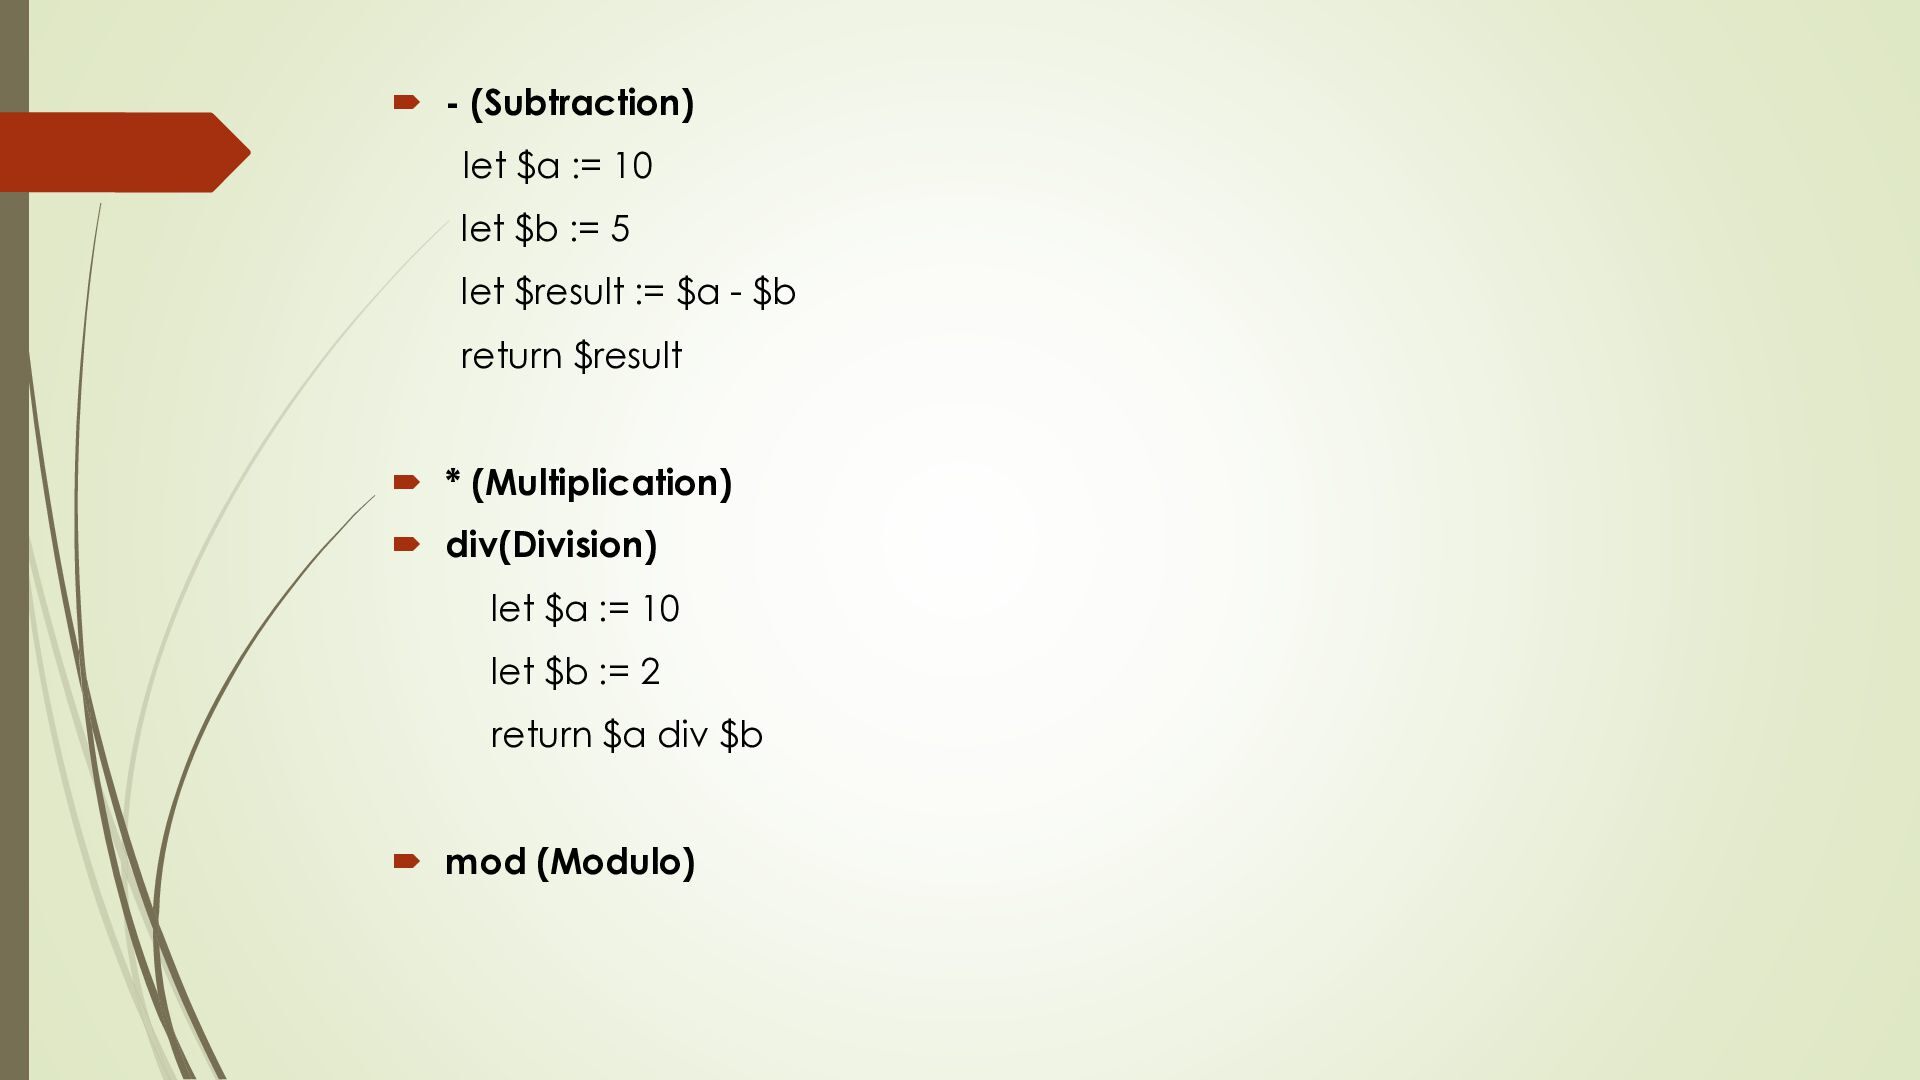
with XML data. These operators allow you to query, manipulate, and compare XML data effectively. Here's an overview of the key types of XQuery operators: 1. Arithmetic Operators • Used for mathematical operations. • Examples: + (Addition) let $a := 10 let $b := 5 let $result := $a + $b return $result
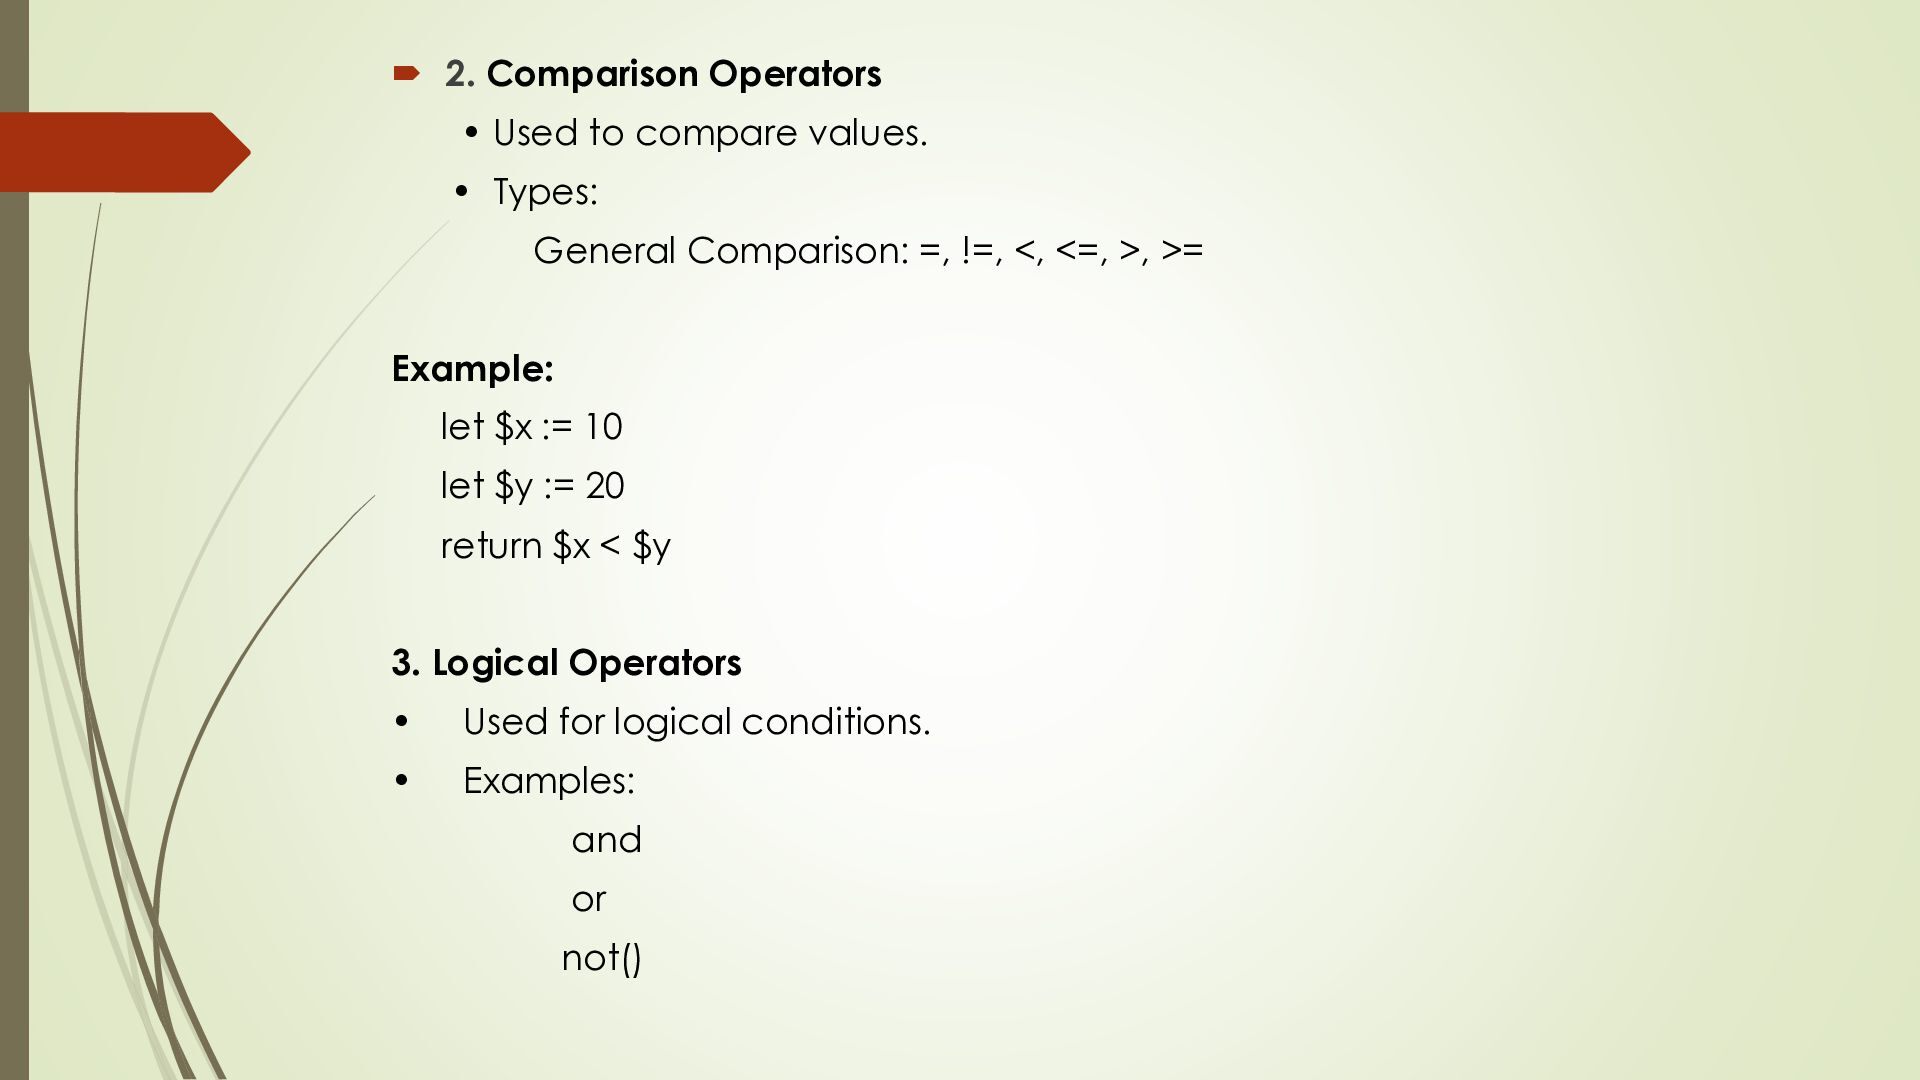
Types: General Comparison: =, !=, <, <=, >, >= Example: let $x := 10 let $y := 20 return $x < $y 3. Logical Operators • Used for logical conditions. • Examples: and or not()
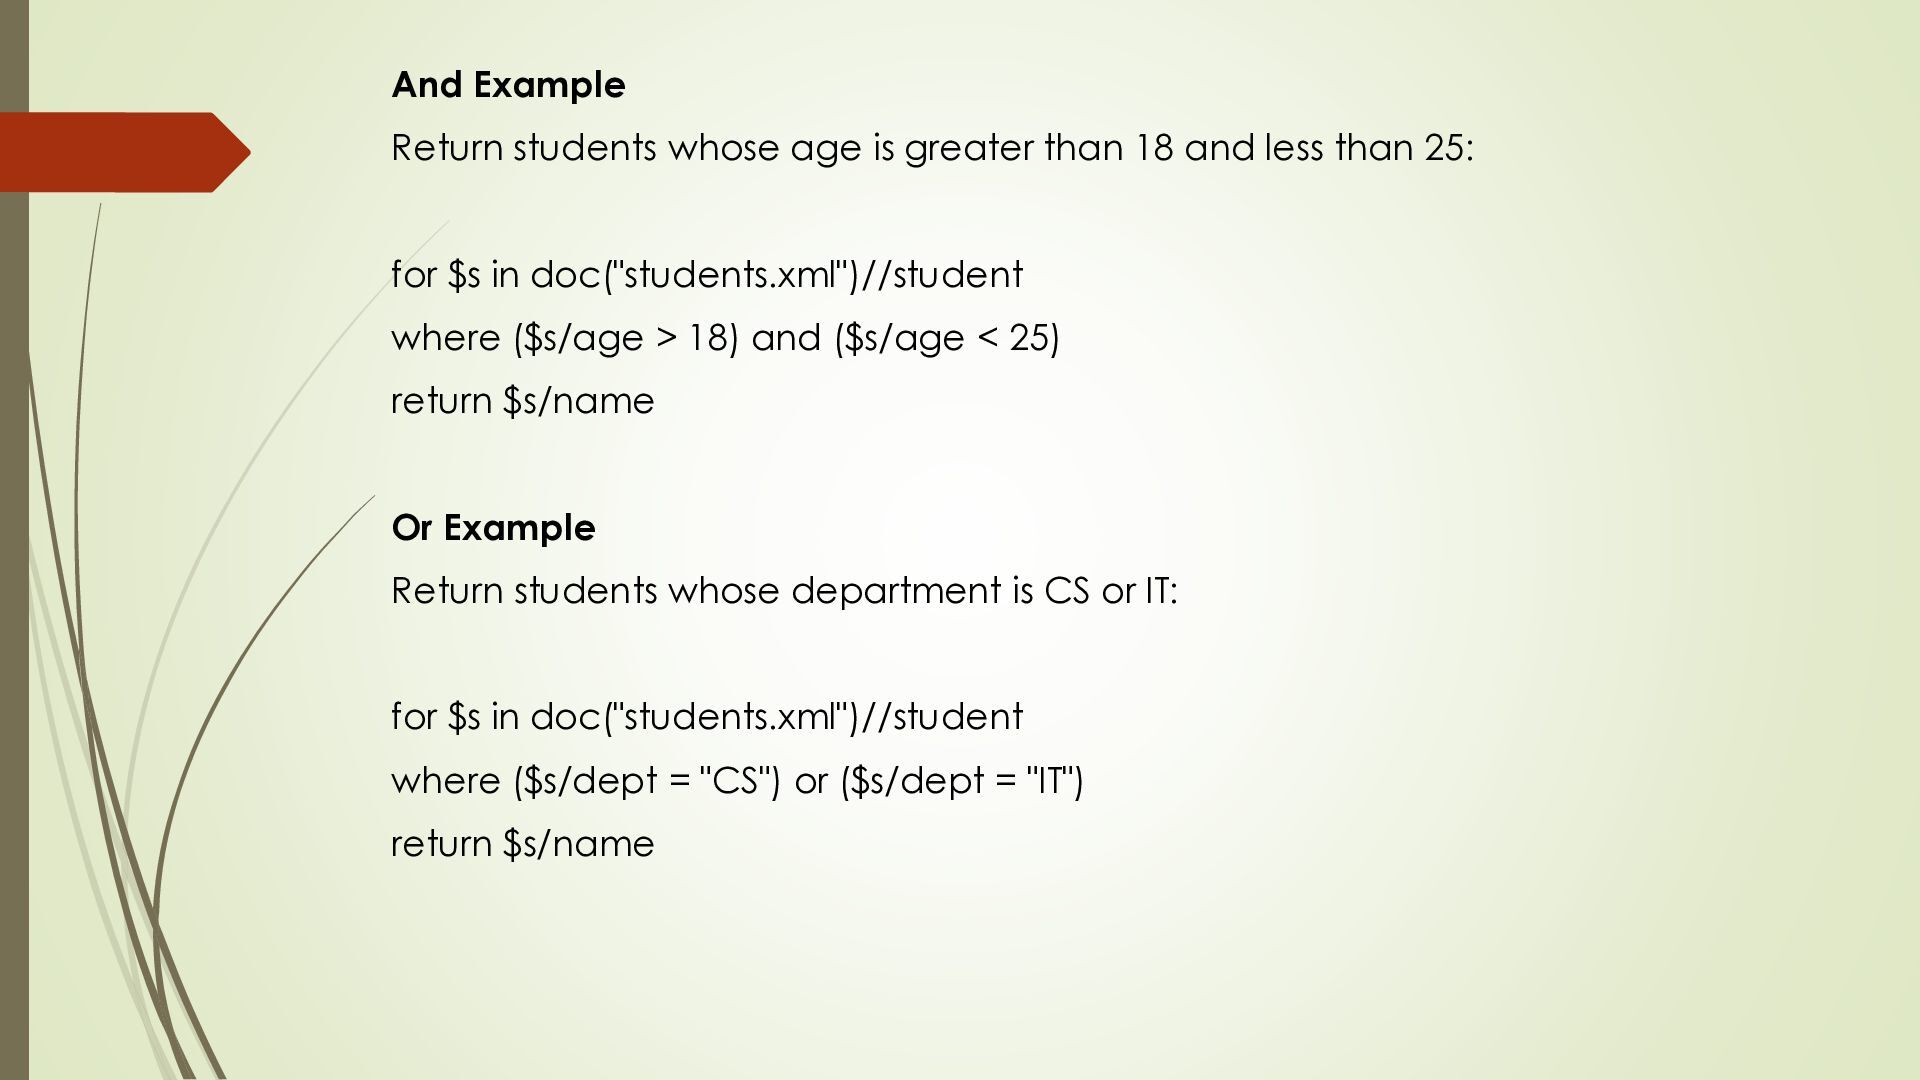
and less than 25: for $s in doc("students.xml")//student where ($s/age > 18) and ($s/age < 25) return $s/name Or Example Return students whose department is CS or IT: for $s in doc("students.xml")//student where ($s/dept = "CS") or ($s/dept = "IT") return $s/name
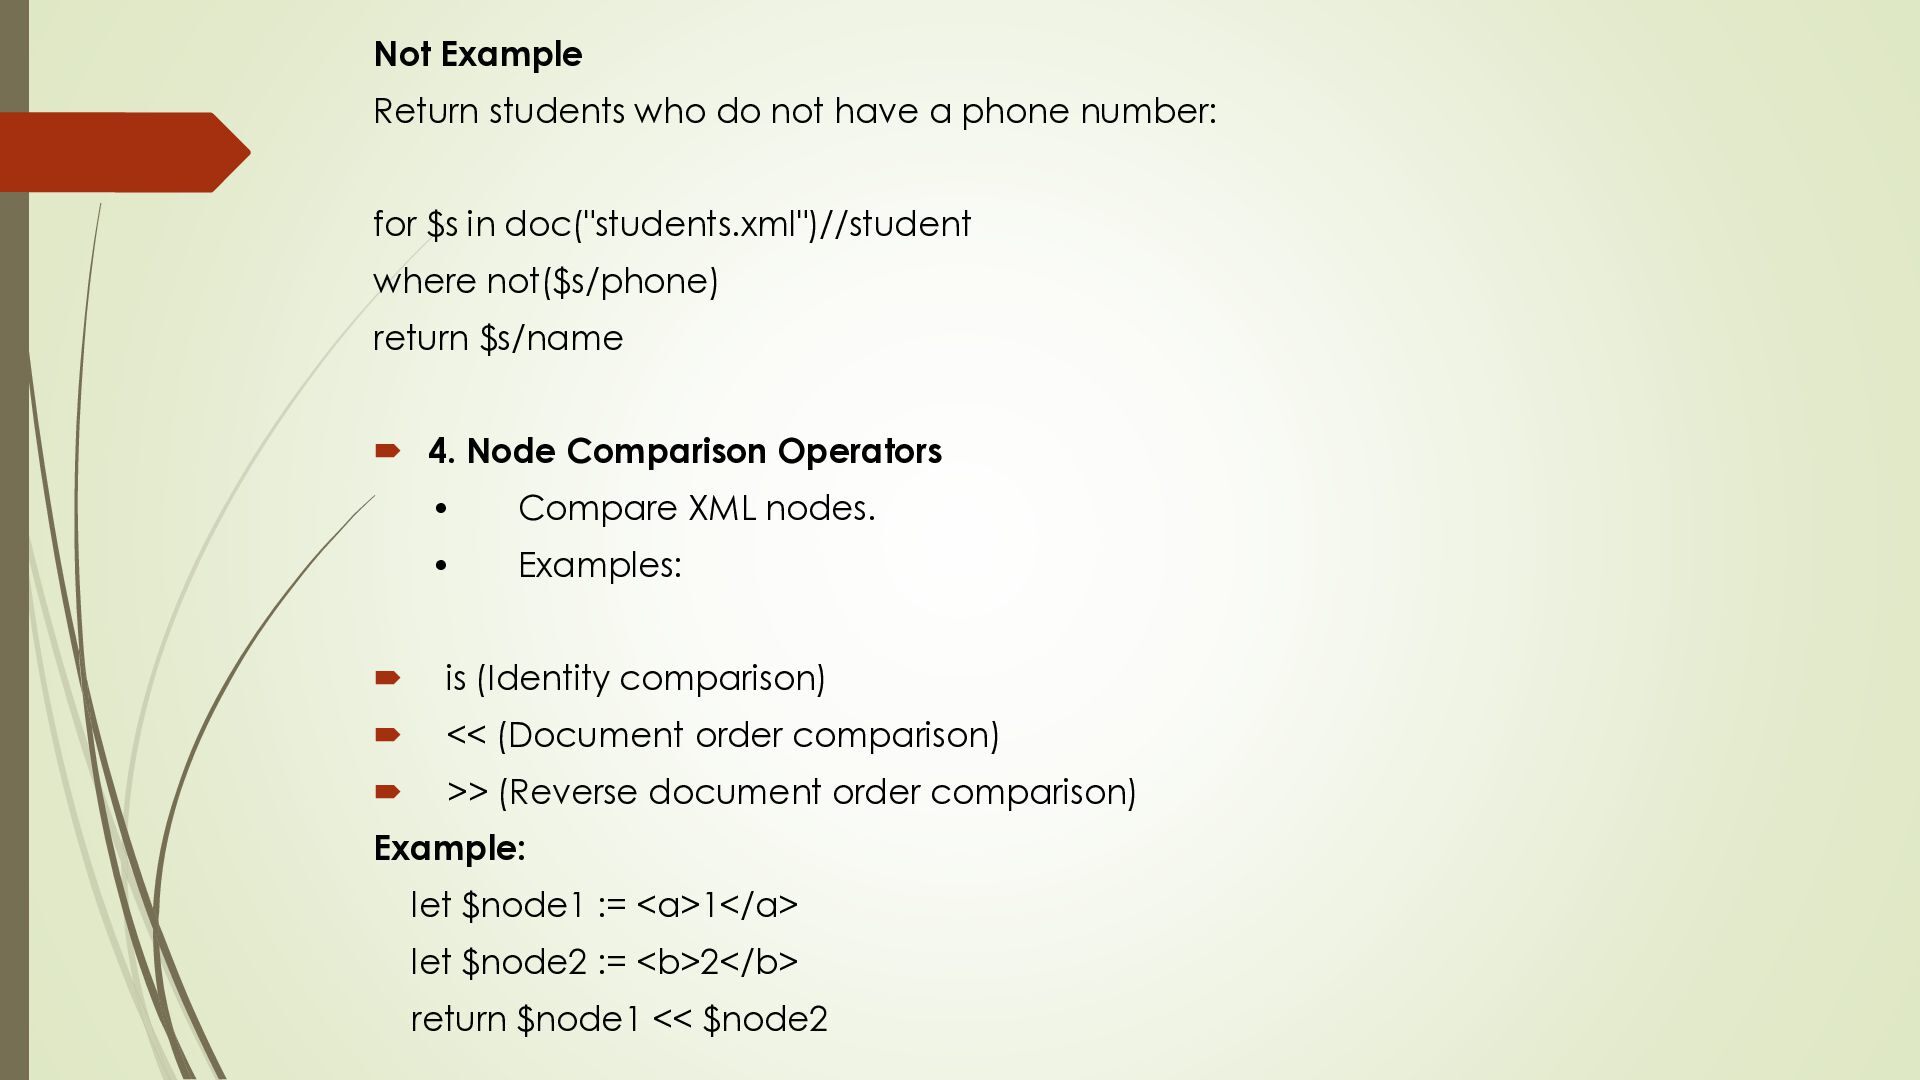
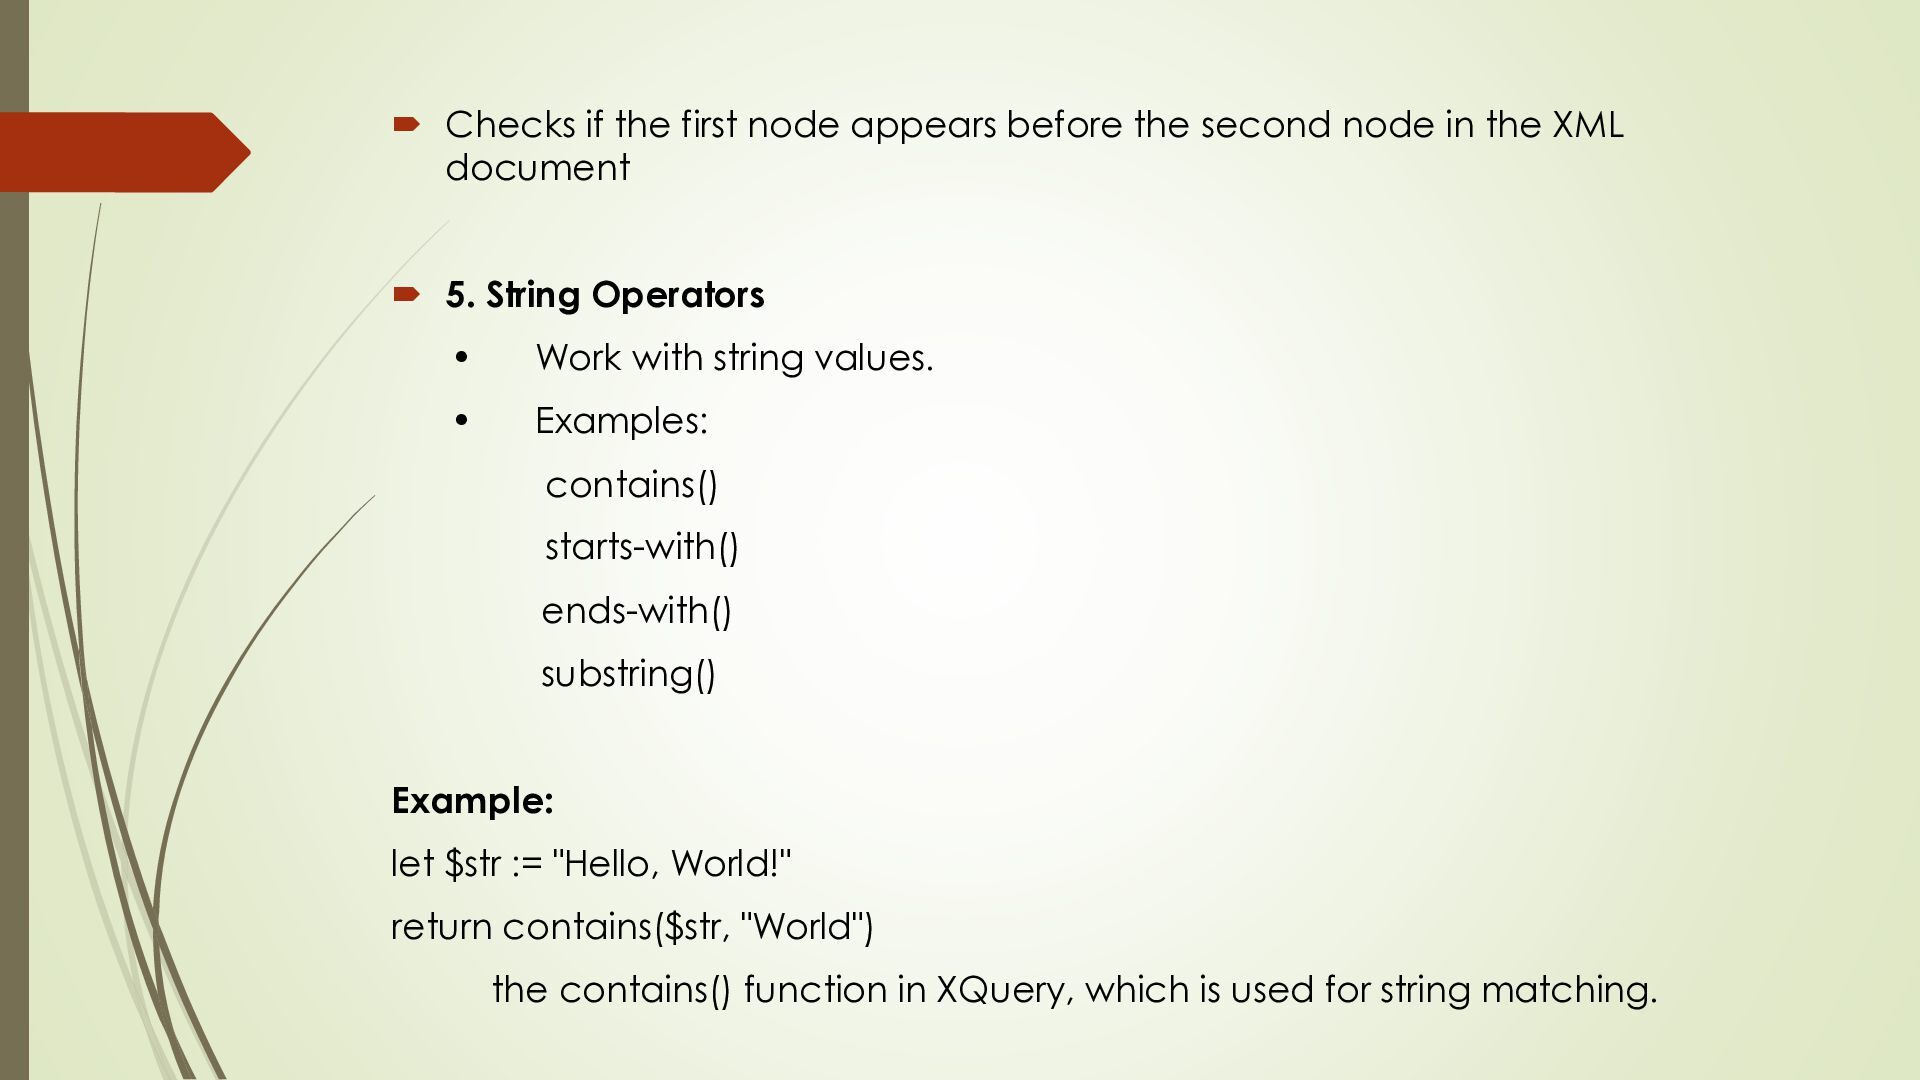
node in the XML document 5. String Operators • Work with string values. • Examples: contains() starts-with() ends-with() substring() Example: let $str := "Hello, World!" return contains($str, "World") the contains() function in XQuery, which is used for string matching.
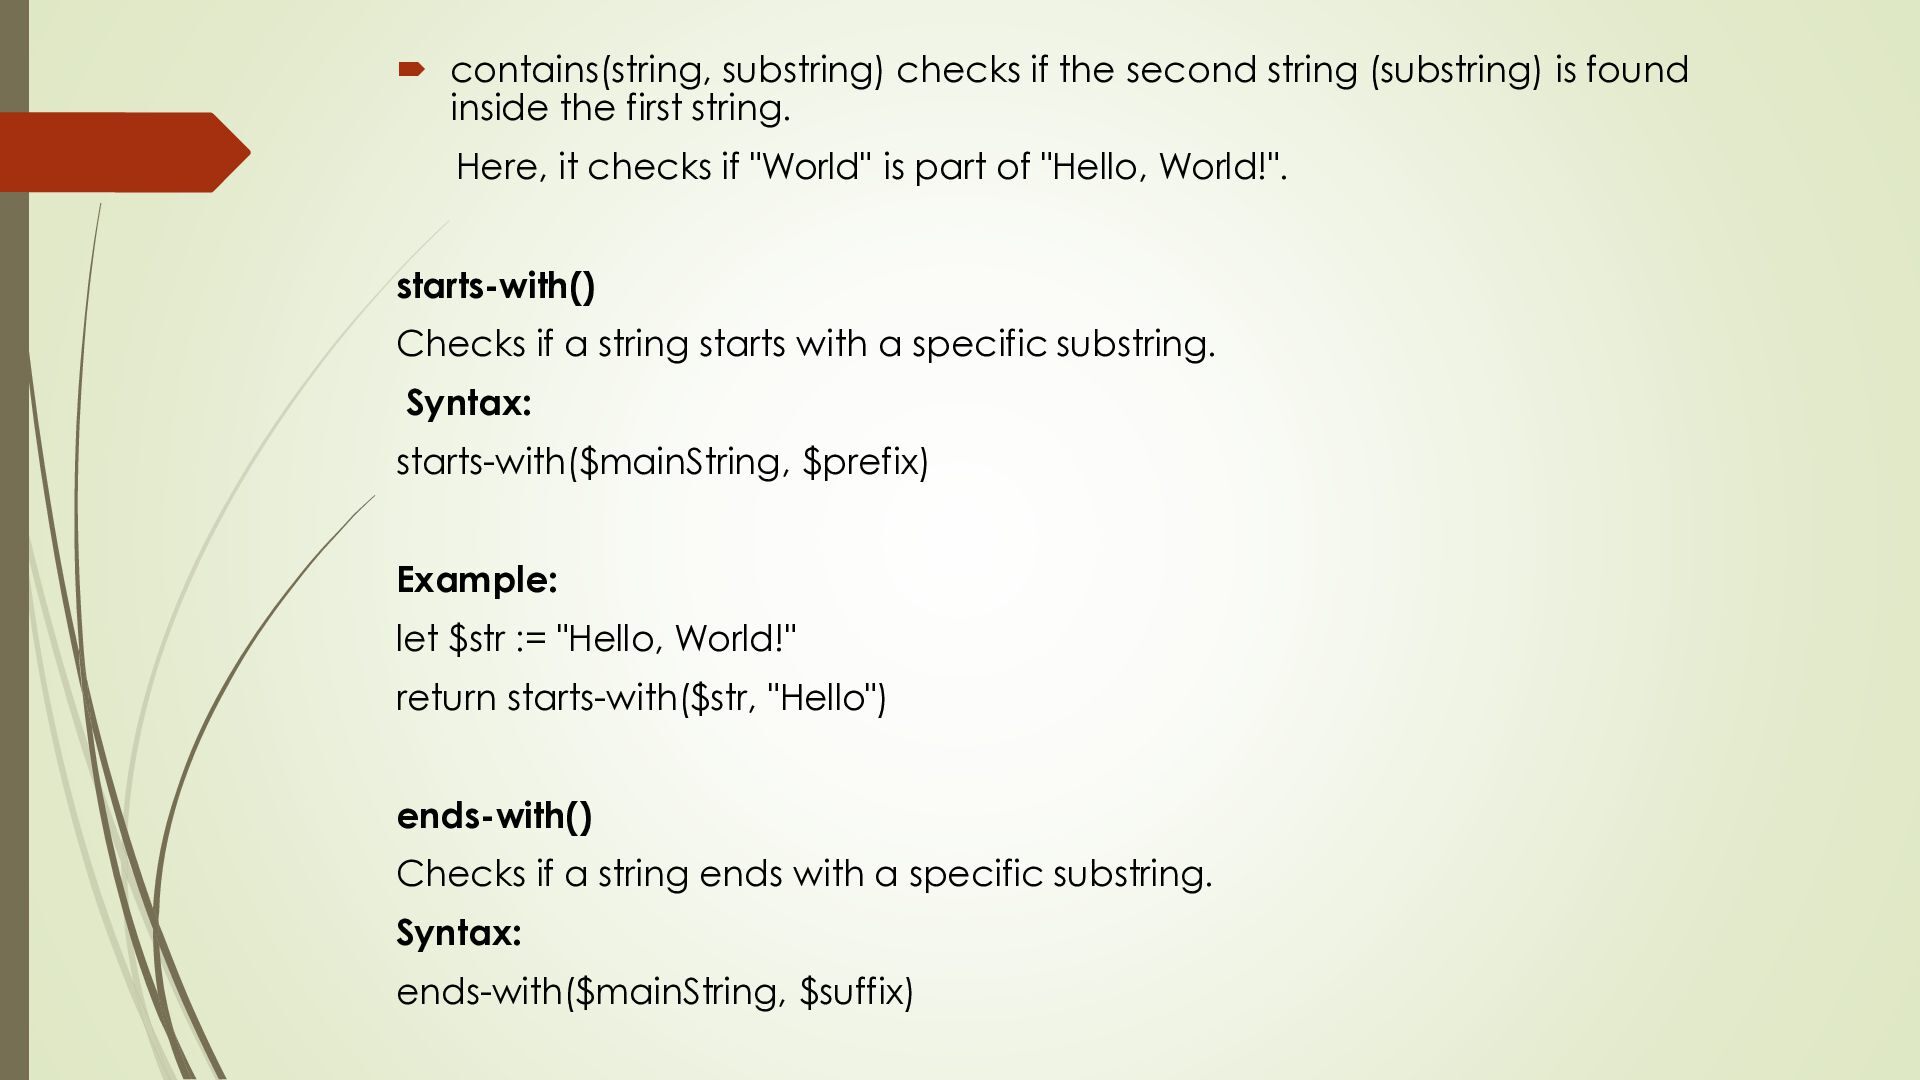
found inside the first string. Here, it checks if "World" is part of "Hello, World!". starts-with() Checks if a string starts with a specific substring. Syntax: starts-with($mainString, $prefix) Example: let $str := "Hello, World!" return starts-with($str, "Hello") ends-with() Checks if a string ends with a specific substring. Syntax: ends-with($mainString, $suffix)
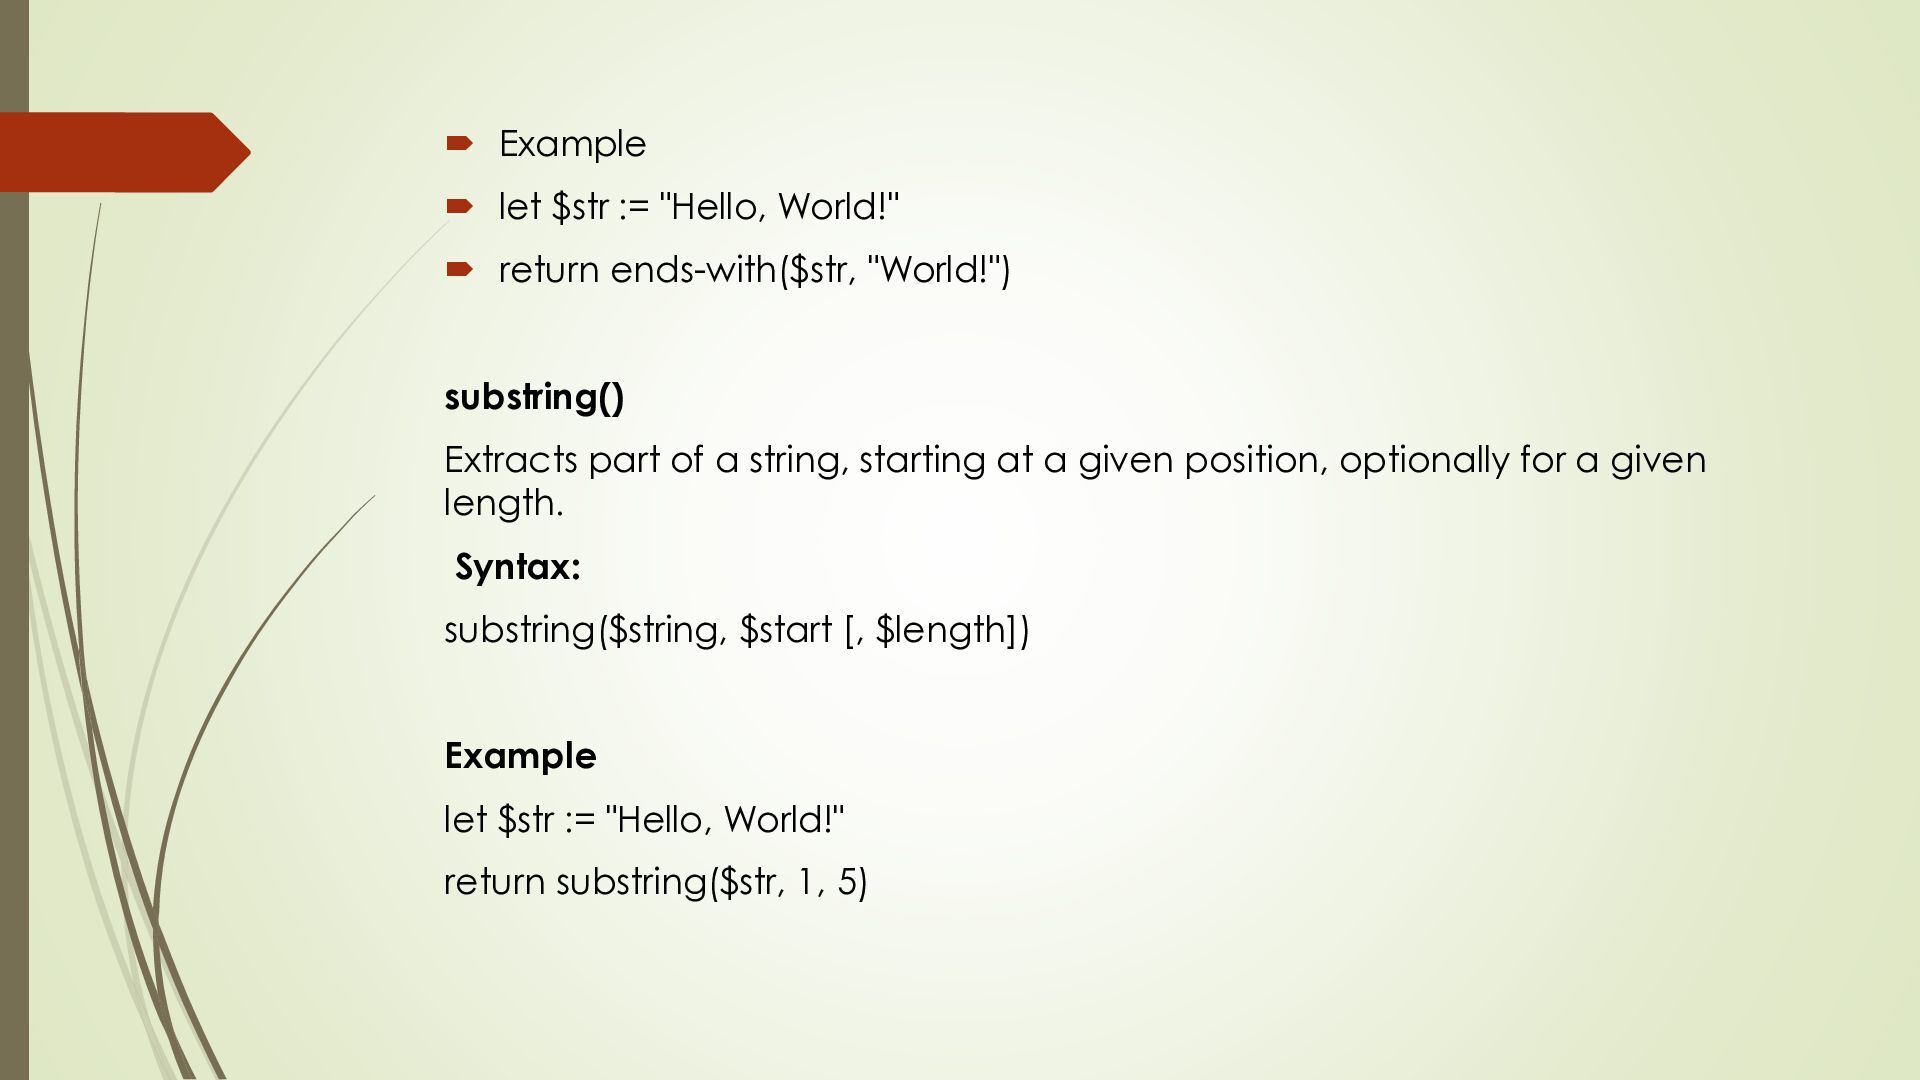
ends-with($str, "World!") substring() Extracts part of a string, starting at a given position, optionally for a given length. Syntax: substring($string, $start [, $length]) Example let $str := "Hello, World!" return substring($str, 1, 5)
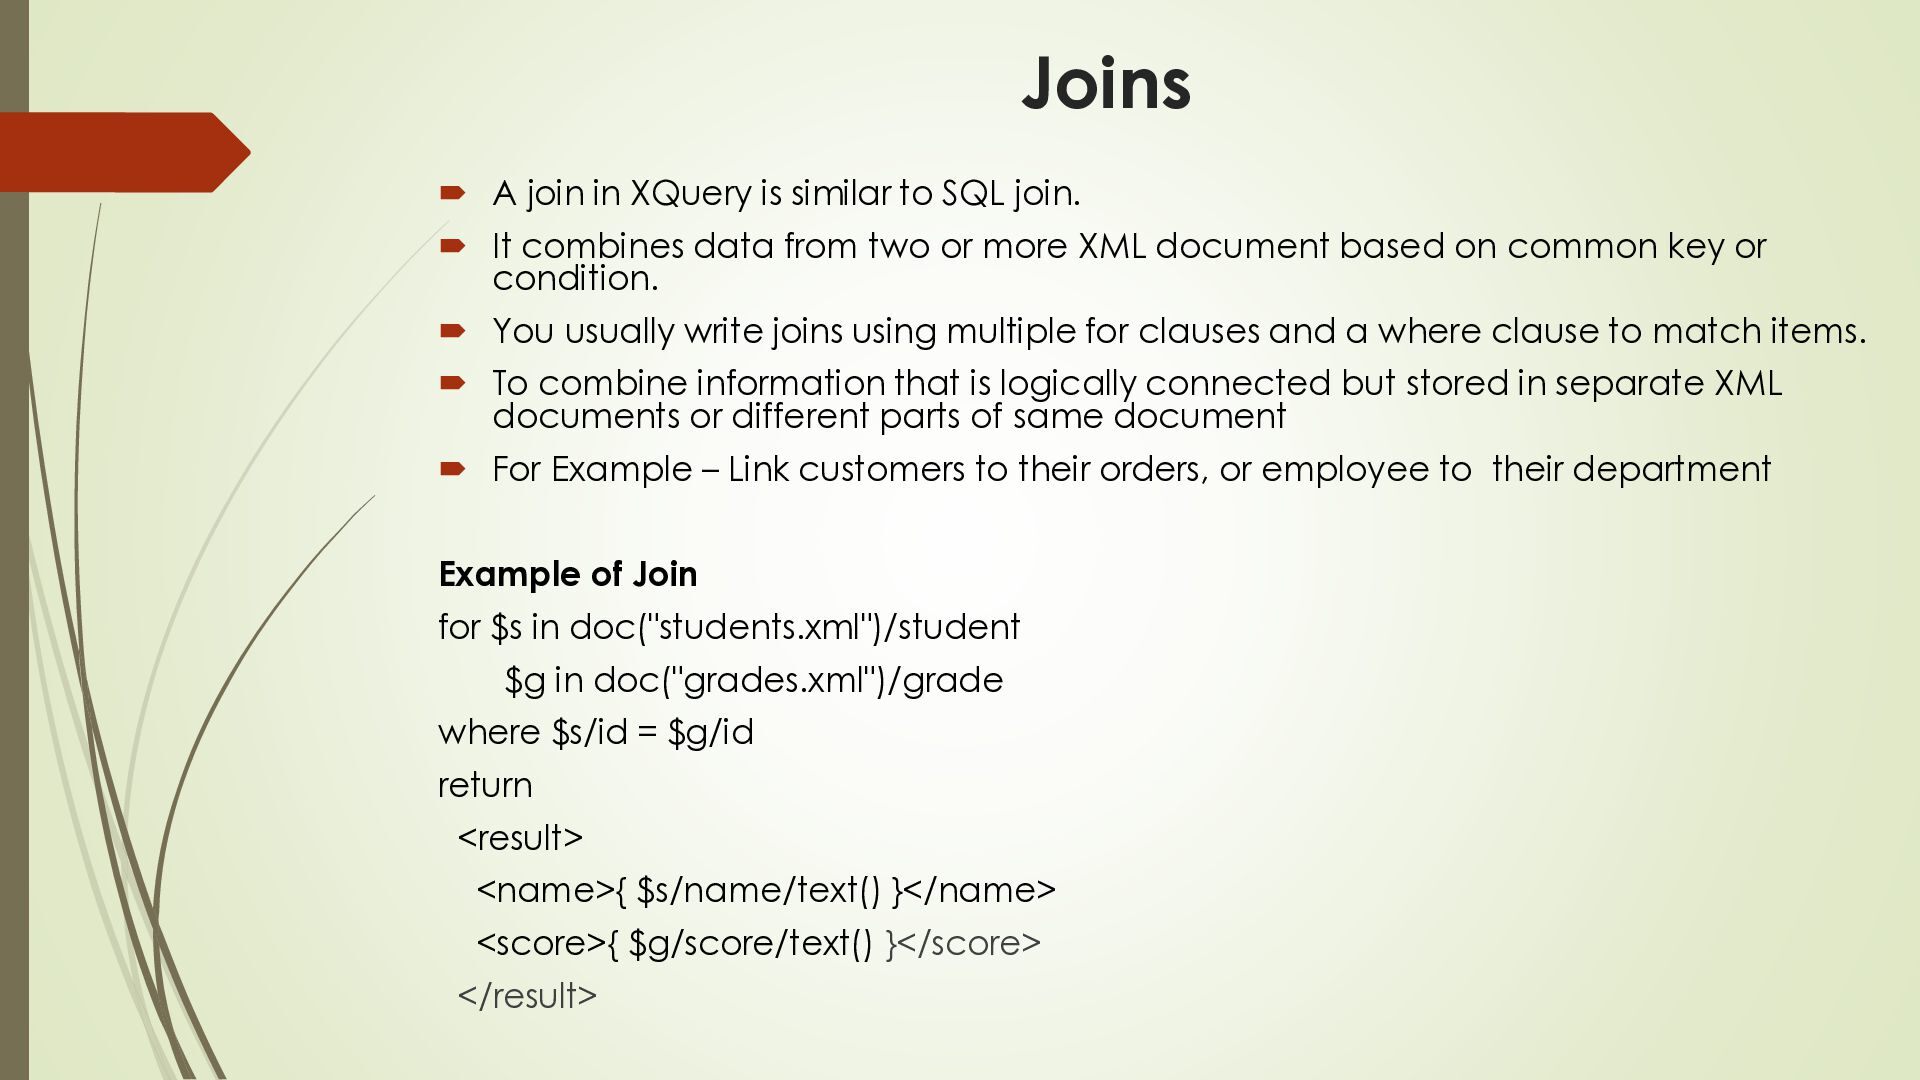
join. It combines data from two or more XML document based on common key or condition. You usually write joins using multiple for clauses and a where clause to match items. To combine information that is logically connected but stored in separate XML documents or different parts of same document For Example – Link customers to their orders, or employee to their department Example of Join for $s in doc("students.xml")/student $g in doc("grades.xml")/grade where $s/id = $g/id return <result> <name>{ $s/name/text() }</name> <score>{ $g/score/text() }</score> </result>
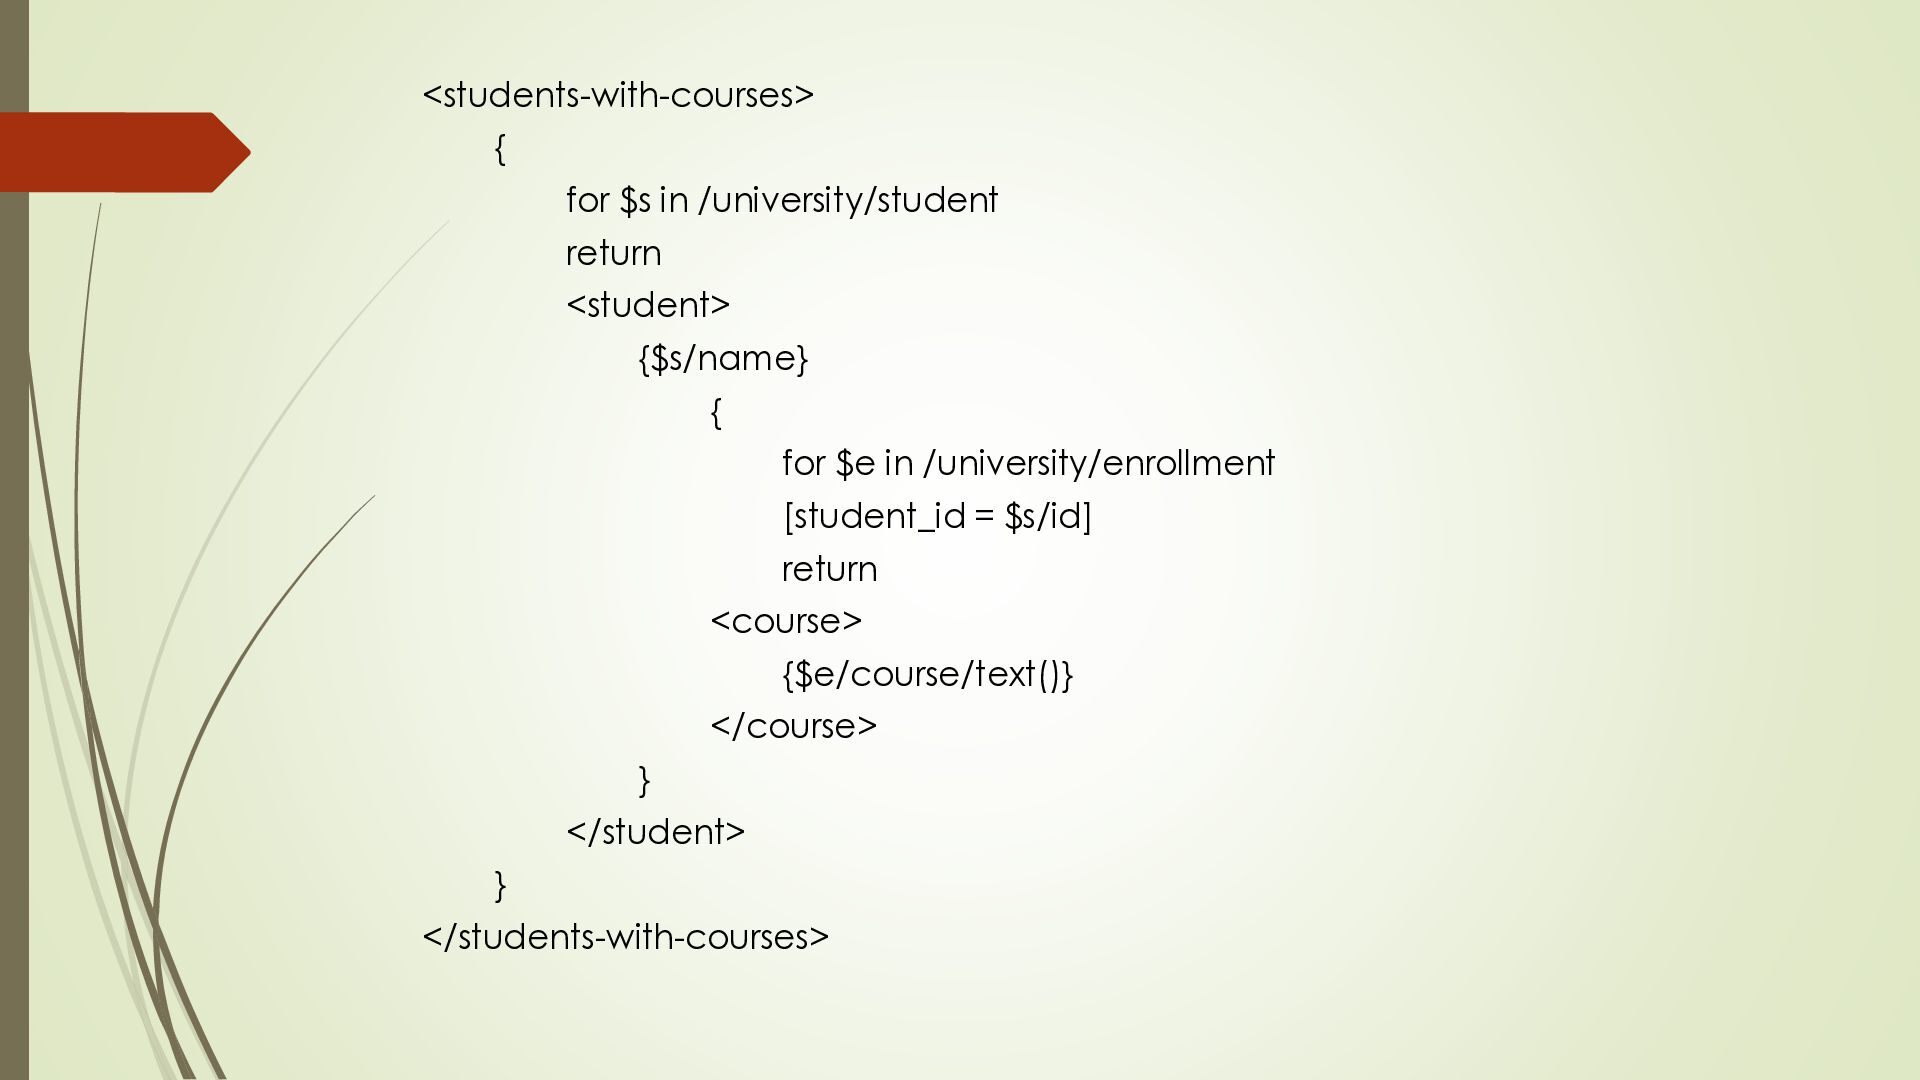
inside another. The inner query runs first & it’s results are used by the outer query This is similar to subqueries in SQL. Nested queries help in filtering, computing or transformation data based on some intermediate result. They allow breaking down complex problems into simpler parts XQuery FLWOR expression can be nested in the return clause in order to generate element nesting that do not appear in the source document. This features is similar to nested subqueries in the from clause of SQL Queries. Example
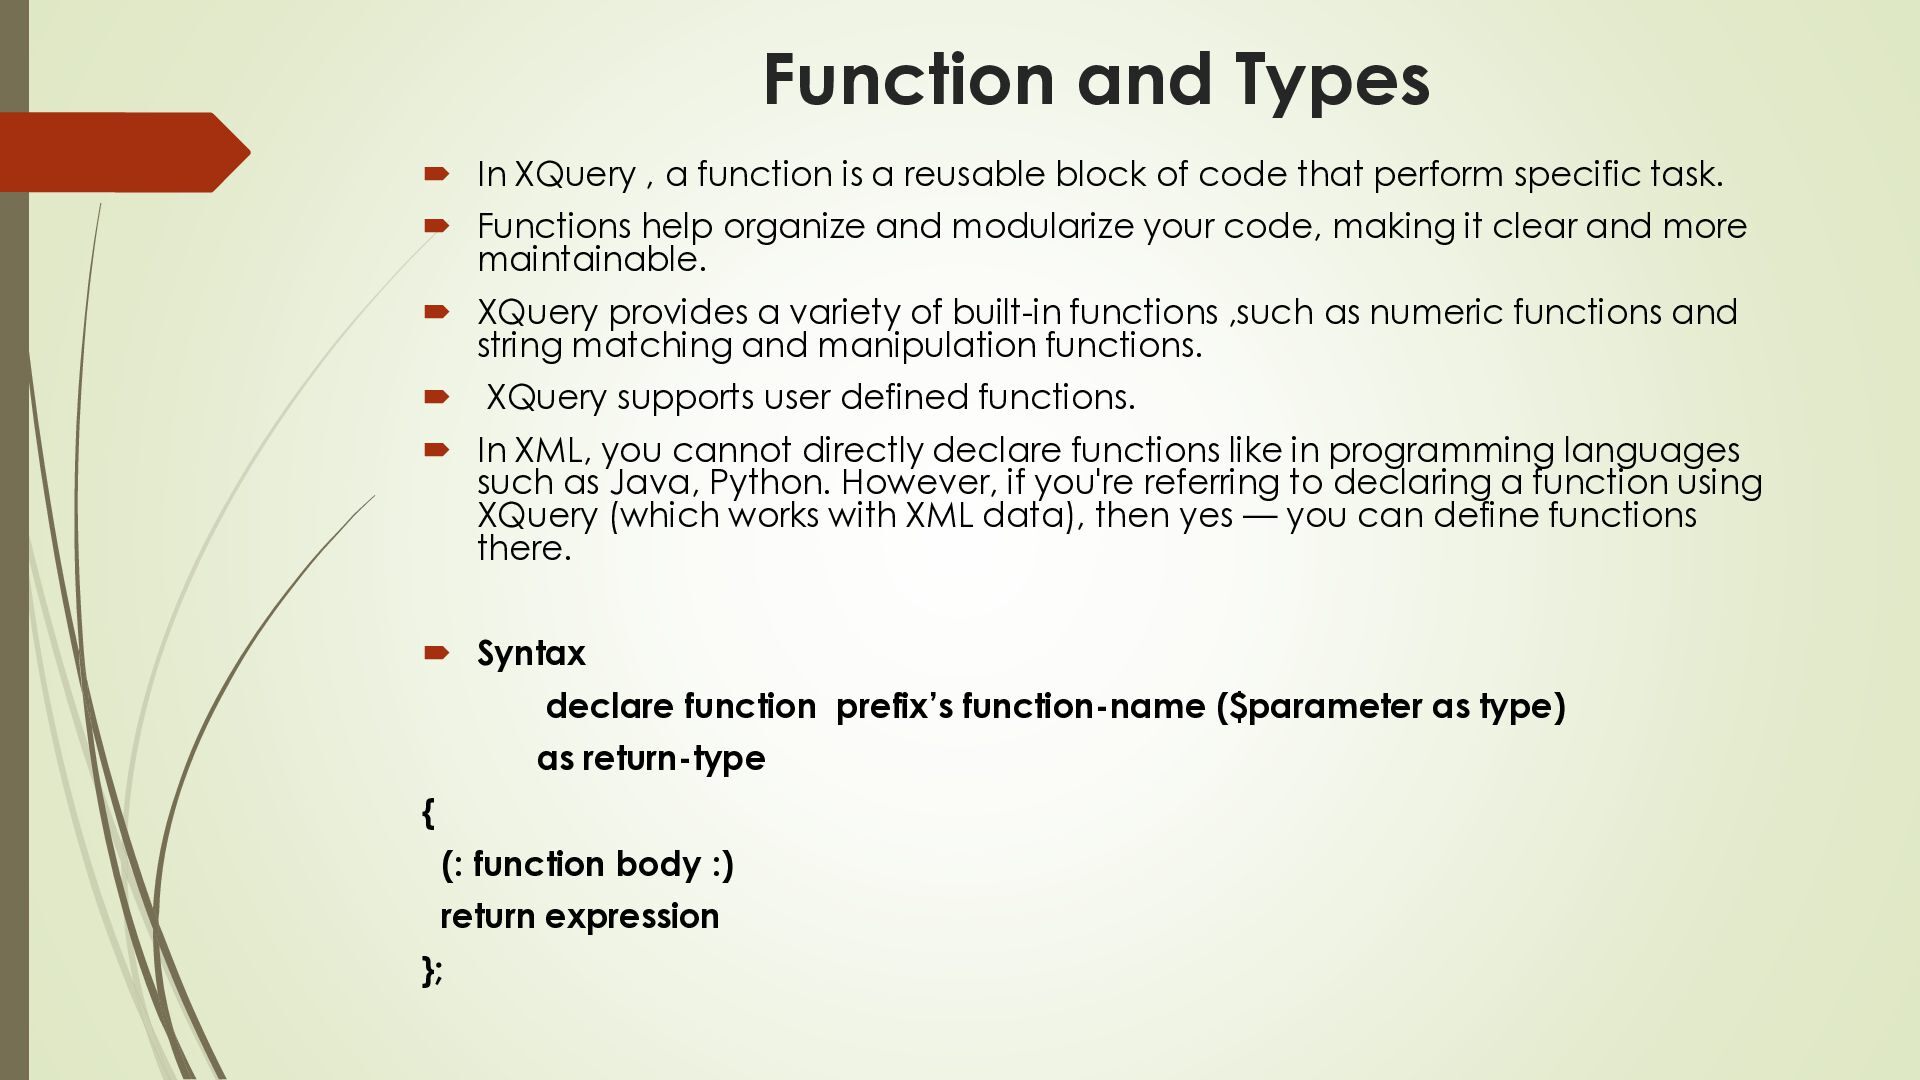
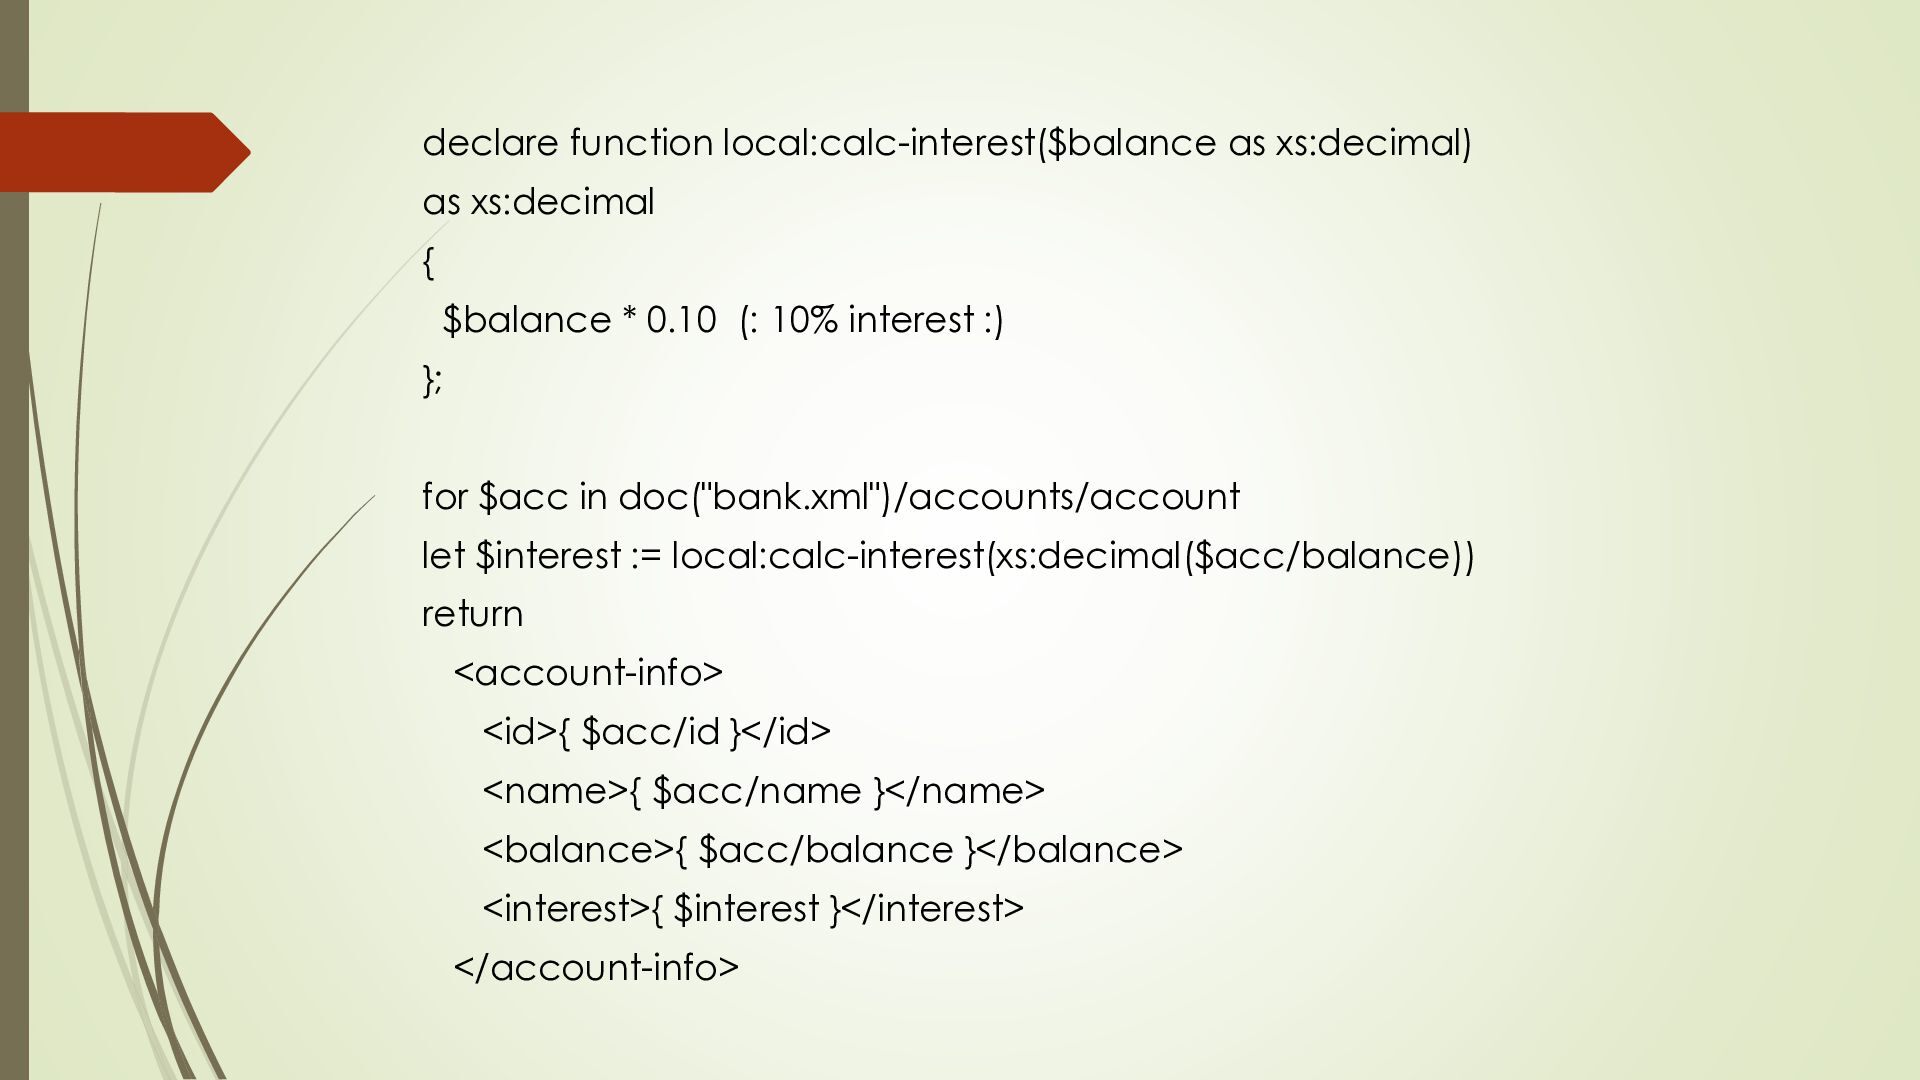
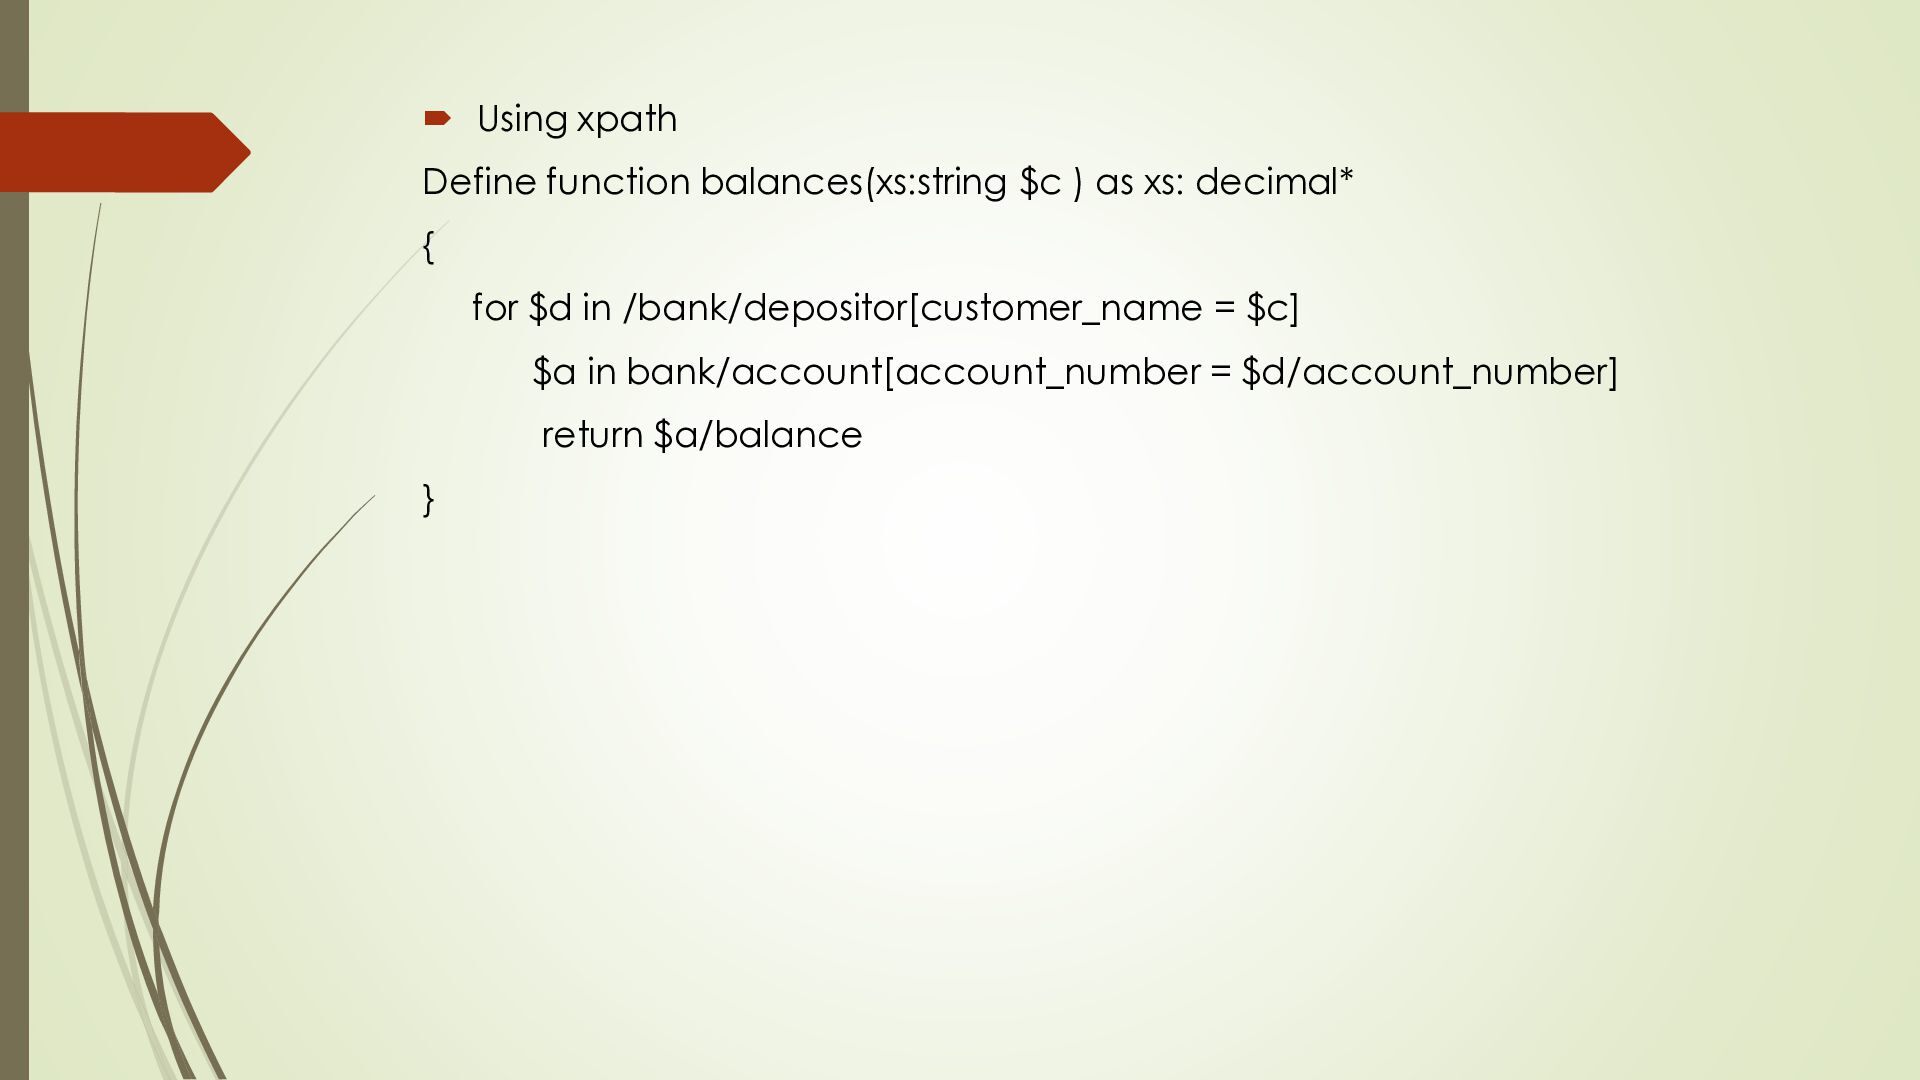
a reusable block of code that perform specific task. Functions help organize and modularize your code, making it clear and more maintainable. XQuery provides a variety of built-in functions ,such as numeric functions and string matching and manipulation functions. XQuery supports user defined functions. In XML, you cannot directly declare functions like in programming languages such as Java, Python. However, if you're referring to declaring a function using XQuery (which works with XML data), then yes — you can define functions there. Syntax declare function prefix’s function-name ($parameter as type) as return-type { (: function body :) return expression };
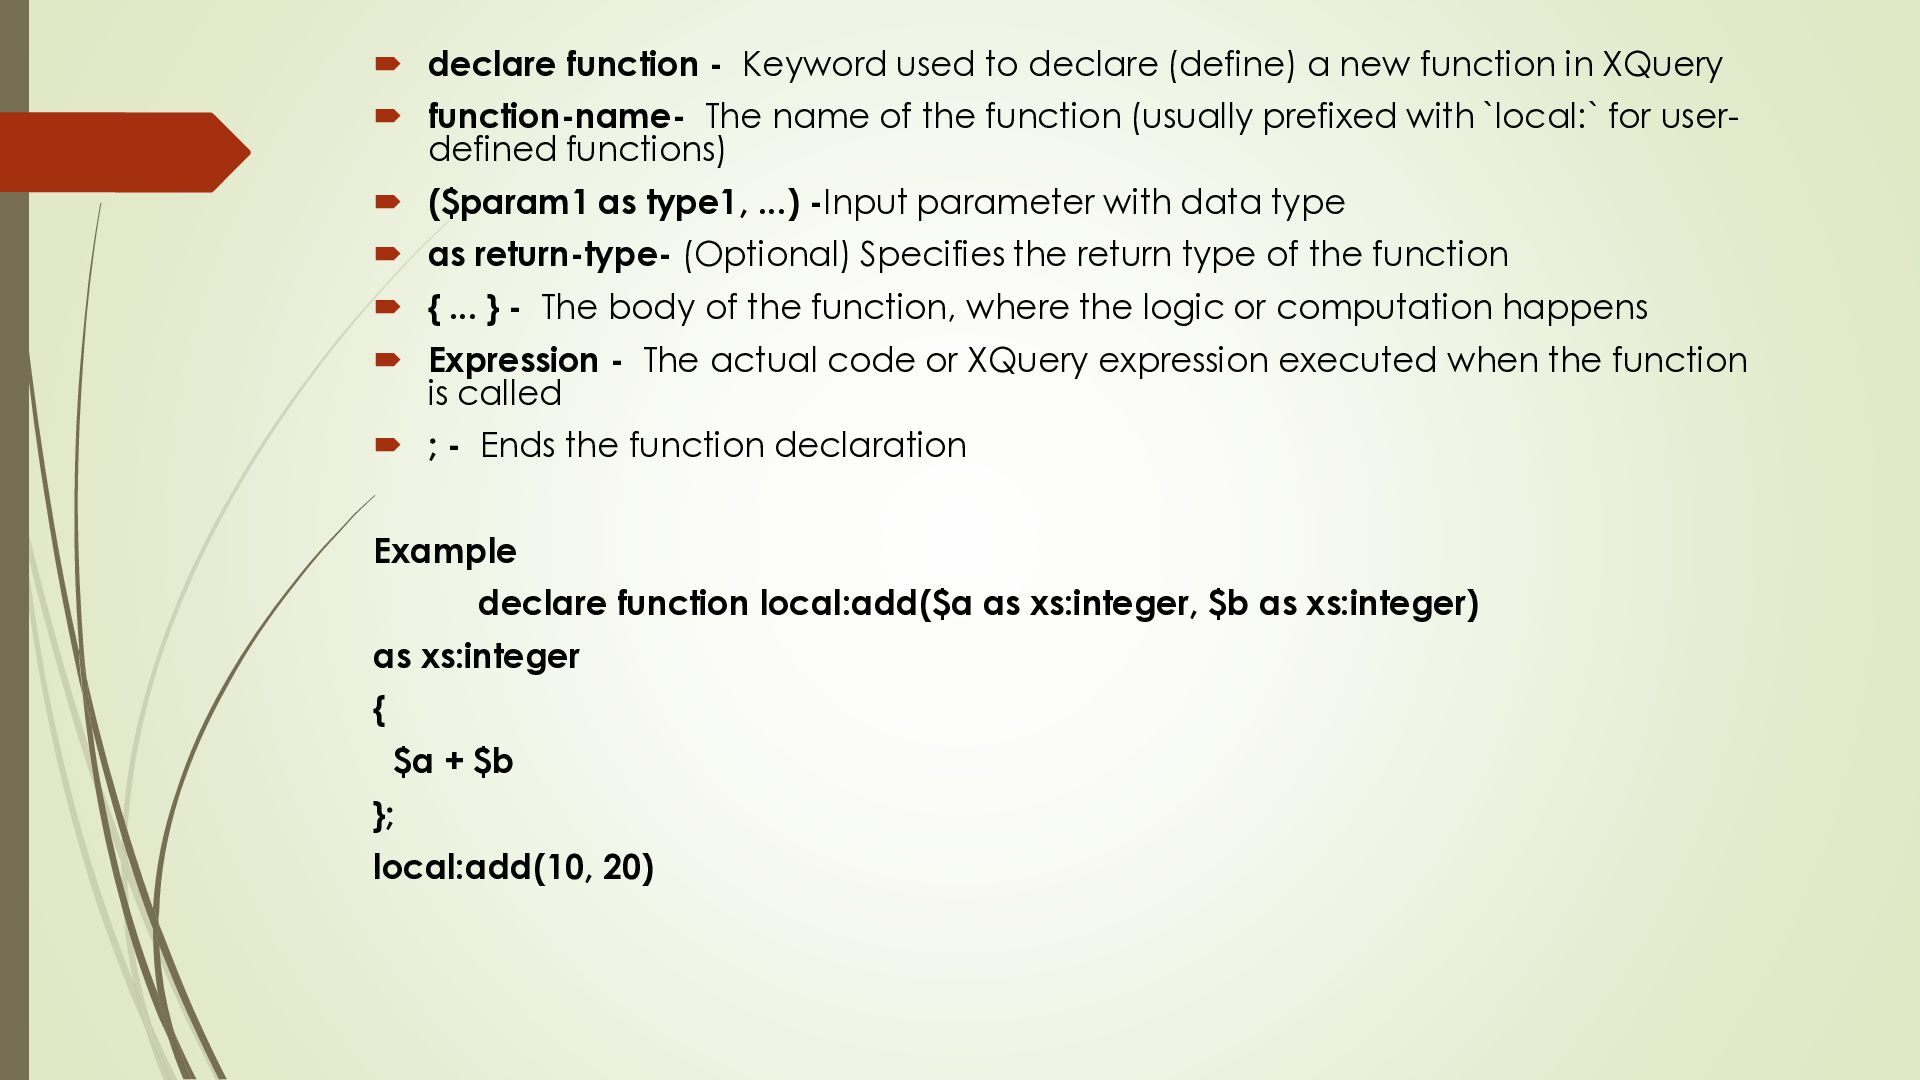
new function in XQuery function-name- The name of the function (usually prefixed with `local:` for userdefined functions) ($param1 as type1, ...) -Input parameter with data type as return-type- (Optional) Specifies the return type of the function { ... } - The body of the function, where the logic or computation happens Expression - The actual code or XQuery expression executed when the function is called ; - Ends the function declaration Example declare function local:add($a as xs:integer, $b as xs:integer) as xs:integer { $a + $b }; local:add(10, 20)
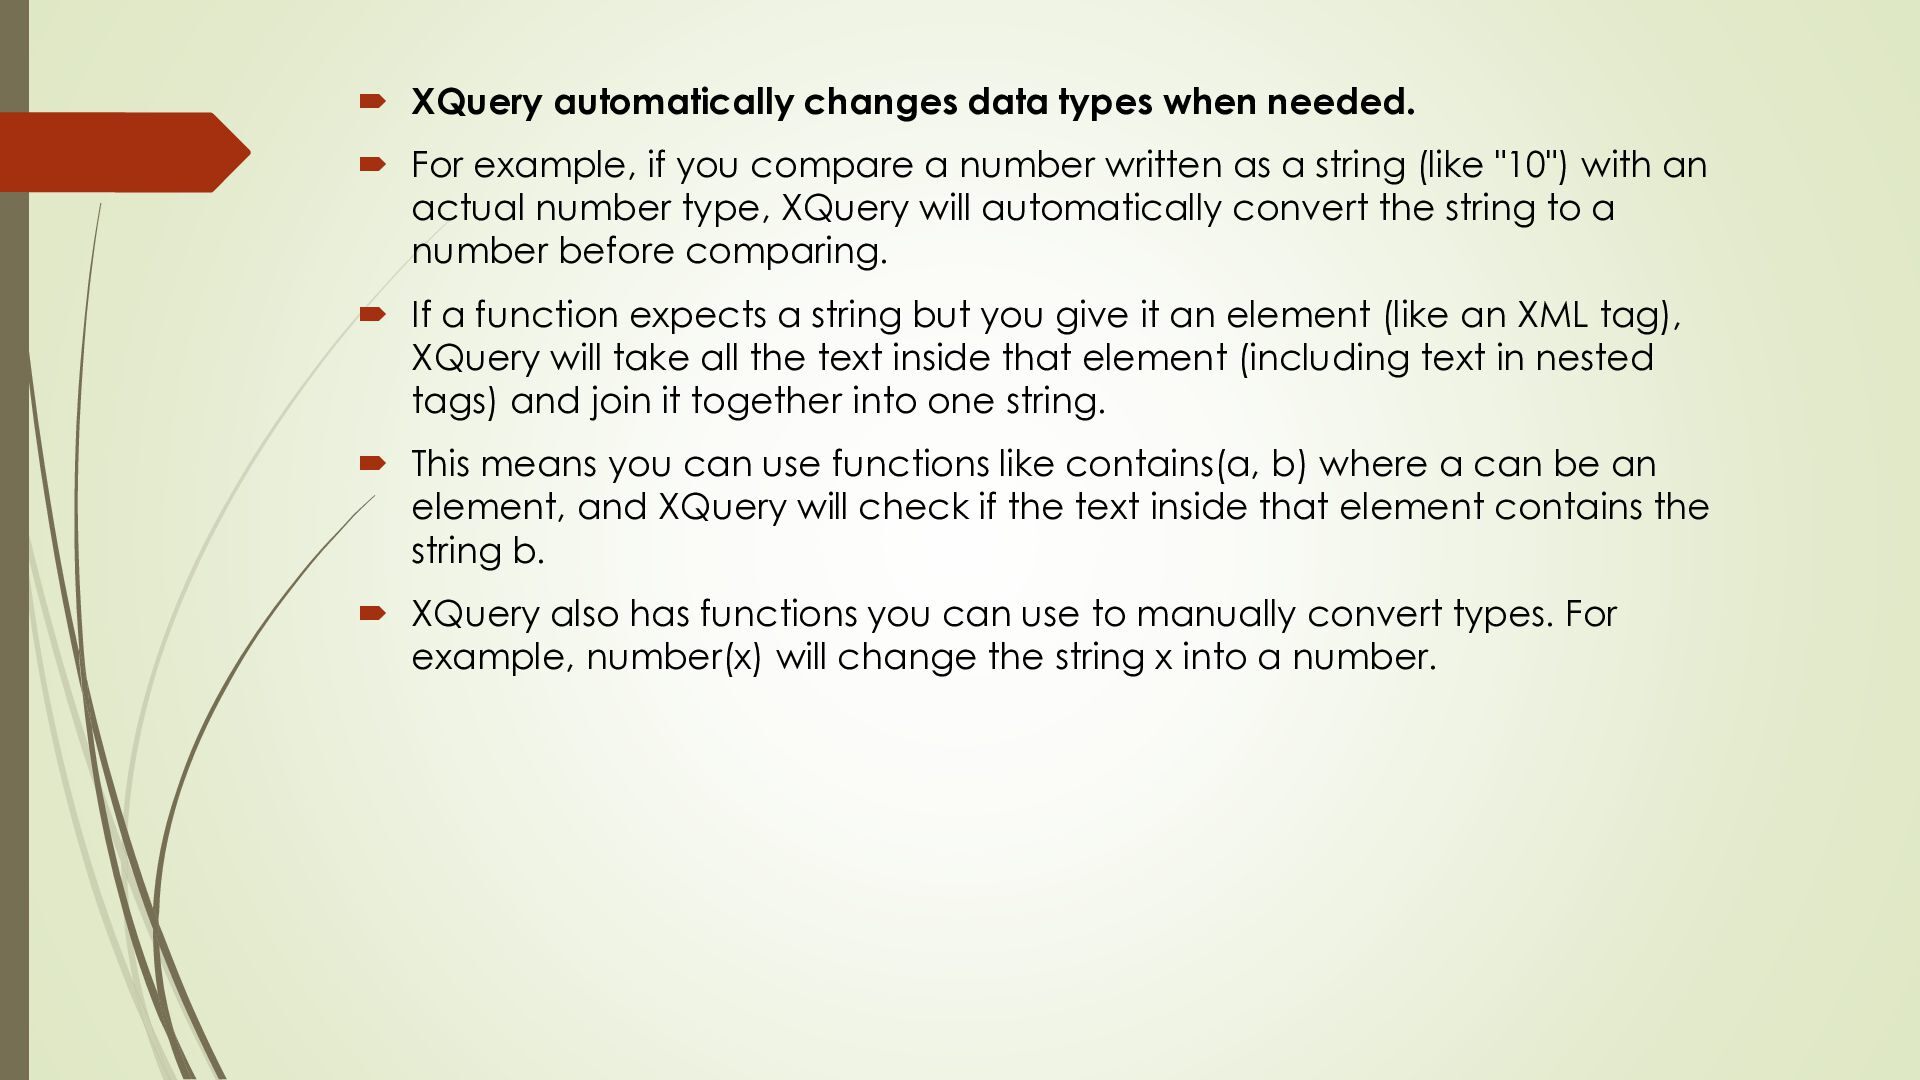
example, if you compare a number written as a string (like "10") with an actual number type, XQuery will automatically convert the string to a number before comparing. If a function expects a string but you give it an element (like an XML tag), XQuery will take all the text inside that element (including text in nested tags) and join it together into one string. This means you can use functions like contains(a, b) where a can be an element, and XQuery will check if the text inside that element contains the string b. XQuery also has functions you can use to manually convert types. For example, number(x) will change the string x into a number.
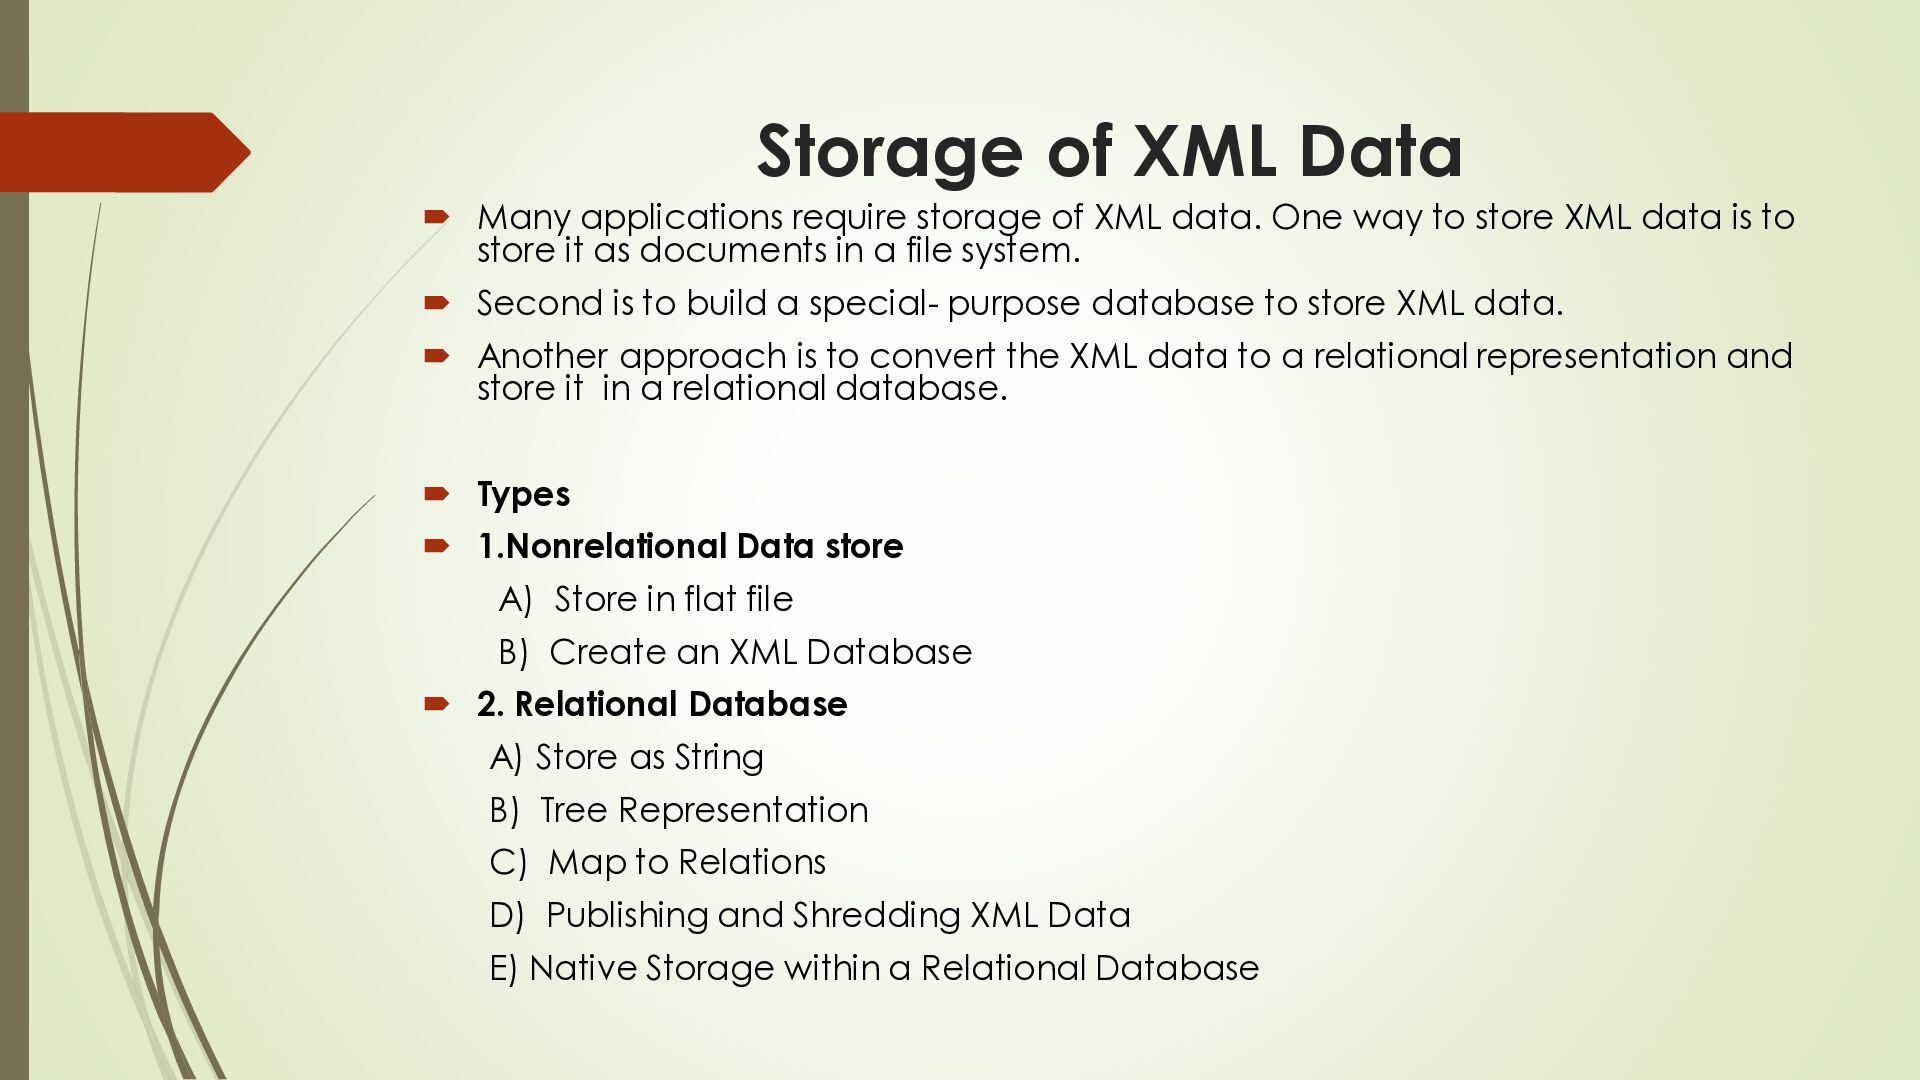
XML data. One way to store XML data is to store it as documents in a file system. Second is to build a special- purpose database to store XML data. Another approach is to convert the XML data to a relational representation and store it in a relational database. Types 1.Nonrelational Data store A) Store in flat file B) Create an XML Database 2. Relational Database A) Store as String B) Tree Representation C) Map to Relations D) Publishing and Shredding XML Data E) Native Storage within a Relational Database
storing XML data in non relational data storage systems. A) Store in Flat System Since XML is primarily a file format, a natural storage mechanism is simply a flat file. XML data is saved as .XML files on disk suitable for small-scale applications , configurations files or when XML is mostly used as a data interchange format. security. In flat files it lacks data isolation, atomicity, concurrent access & This storage format may be sufficient for some application. Or Suitable for simple applications or document storage. it is Simple but Poor search and transaction support
use XML as their basic data model. Use a native XML database designed to handle XML data (like BaseX, eXist-db). Early XML databases implemented the Document Object Model on a C++-based object-oriented database. This allows much of the object-oriented database infrastructure to be reused, while providing a standard XML interface Stores XML in a tree-like structure. Supports XML-specific queries using XPath/XQuery. Good for handling complex or nested XML. Great for querying and managing XML structure May lack features of full relational databases
applications, there is a great benefit to be had in storing XML data in relational databases, so that the data can be accessed from existing applications. Converting XML data into a relational database is usually easy if the XML was originally created from a database structure and is just used to share data. But in many cases, XML data doesn’t come from a database, so changing it to fit into tables can be tricky. This is especially true when the XML has nested parts or repeating elements, which are harder to store in a table format. There are different ways to handle this problem which is describe below A). Store as String The entire XML document is stored in a single column as a string (e.g., VARCHAR, TEXT, or CLOB).
text (CLOB) value in one row of a relational database table. For larger XML documents, especially when the top-level element has many child elements, you can store each child element separately as its own text entry in different rows. For Example <student> <name>Riya</name> <age>22</age> </student> The data store as <student><name>Riya</name><age>22</age></student> Difficult to query specific parts of XML (e.g., name or age). Poor performance for search or manipulation.
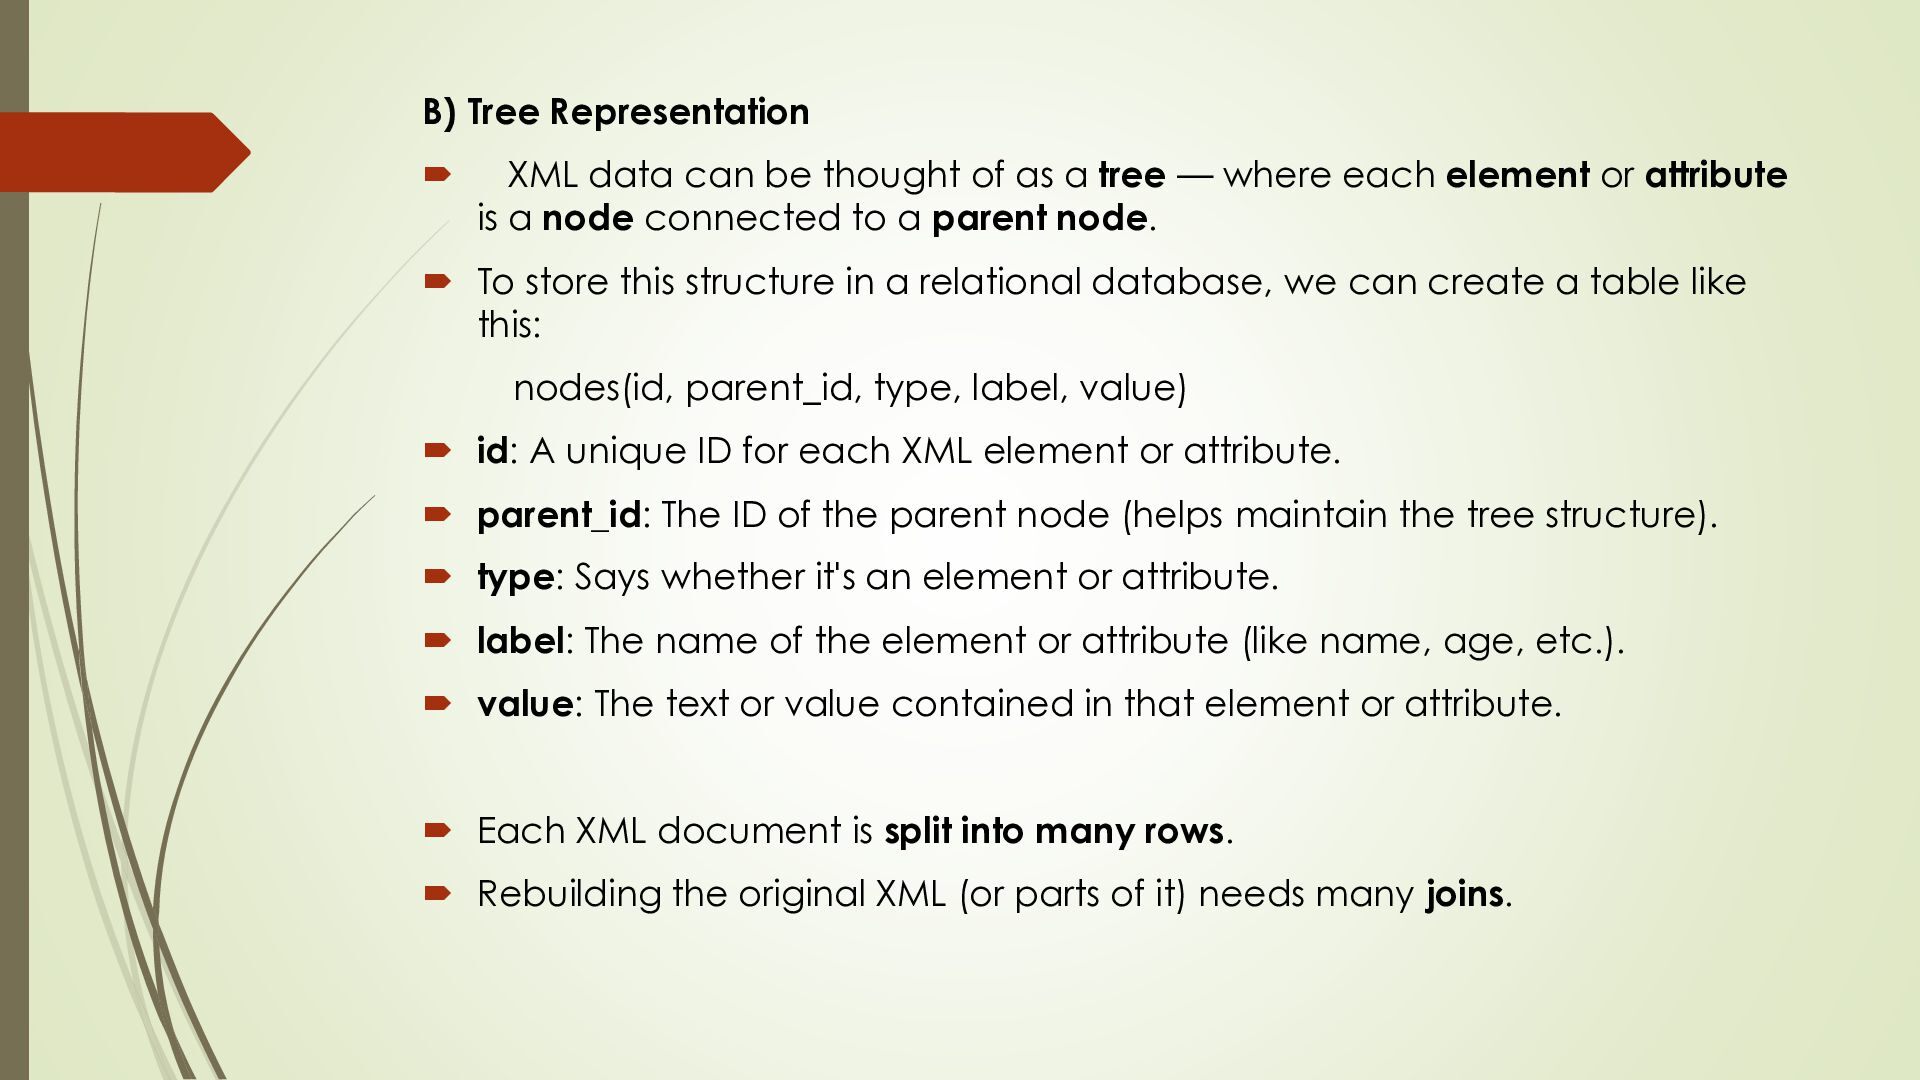
as a tree — where each element or attribute is a node connected to a parent node. To store this structure in a relational database, we can create a table like this: nodes(id, parent_id, type, label, value) id: A unique ID for each XML element or attribute. parent_id: The ID of the parent node (helps maintain the tree structure). type: Says whether it's an element or attribute. label: The name of the element or attribute (like name, age, etc.). value: The text or value contained in that element or attribute. Each XML document is split into many rows. Rebuilding the original XML (or parts of it) needs many joins.
schema is known are mapped to relations and attributes. Elements whose schema is unknown are stored as strings or as a tree. A relation is created for each element type (including subelements) whose schema is known and whose type is a complex type(that is,contains attributes or subelements). Advantages Efficient querying with SQL. Data normalization possible. Disadvantages Loss of original XML structure. Complex mapping for deeply nested XML.
into XML format to be sent to other systems or Data in relational databases must be published, that is, converted to XML form, for export to other applications. Incoming data must be shredded, that is, converted back from XML to normalized relation form and stored in a relational database. While application code can perform the publishing and shredding operations, the operations are so common that the conversions should be done automatically, without writing application code, where possible. The mapping used for publishing data may be simple or complex. A simple relation to XML mapping might create an XML element for every row of a table, and make each column in that row a subelement of the XML element. Example: Publishing: Convert Employee(Name=John) row into <Employee><Name>John</Name></Employee>. Shredding: Parse <Employee><Name>John</Name></Employee> and insert into Employee table.
databases can store XML data directly without changing it into regular tables. They save XML either as text strings or in a special binary format that is faster to handle. These databases use a special data type called xml to represent XML data. A table can have a column of type xml to hold many XML documents — each row stores one XML document. The database creates special indexes to make searching this XML data faster. Many modern databases support this native XML storage. They let you run XQuery commands inside regular SQL queries. This means you can run an XQuery on a single XML document or on a whole collection of XML documents stored in different rows.
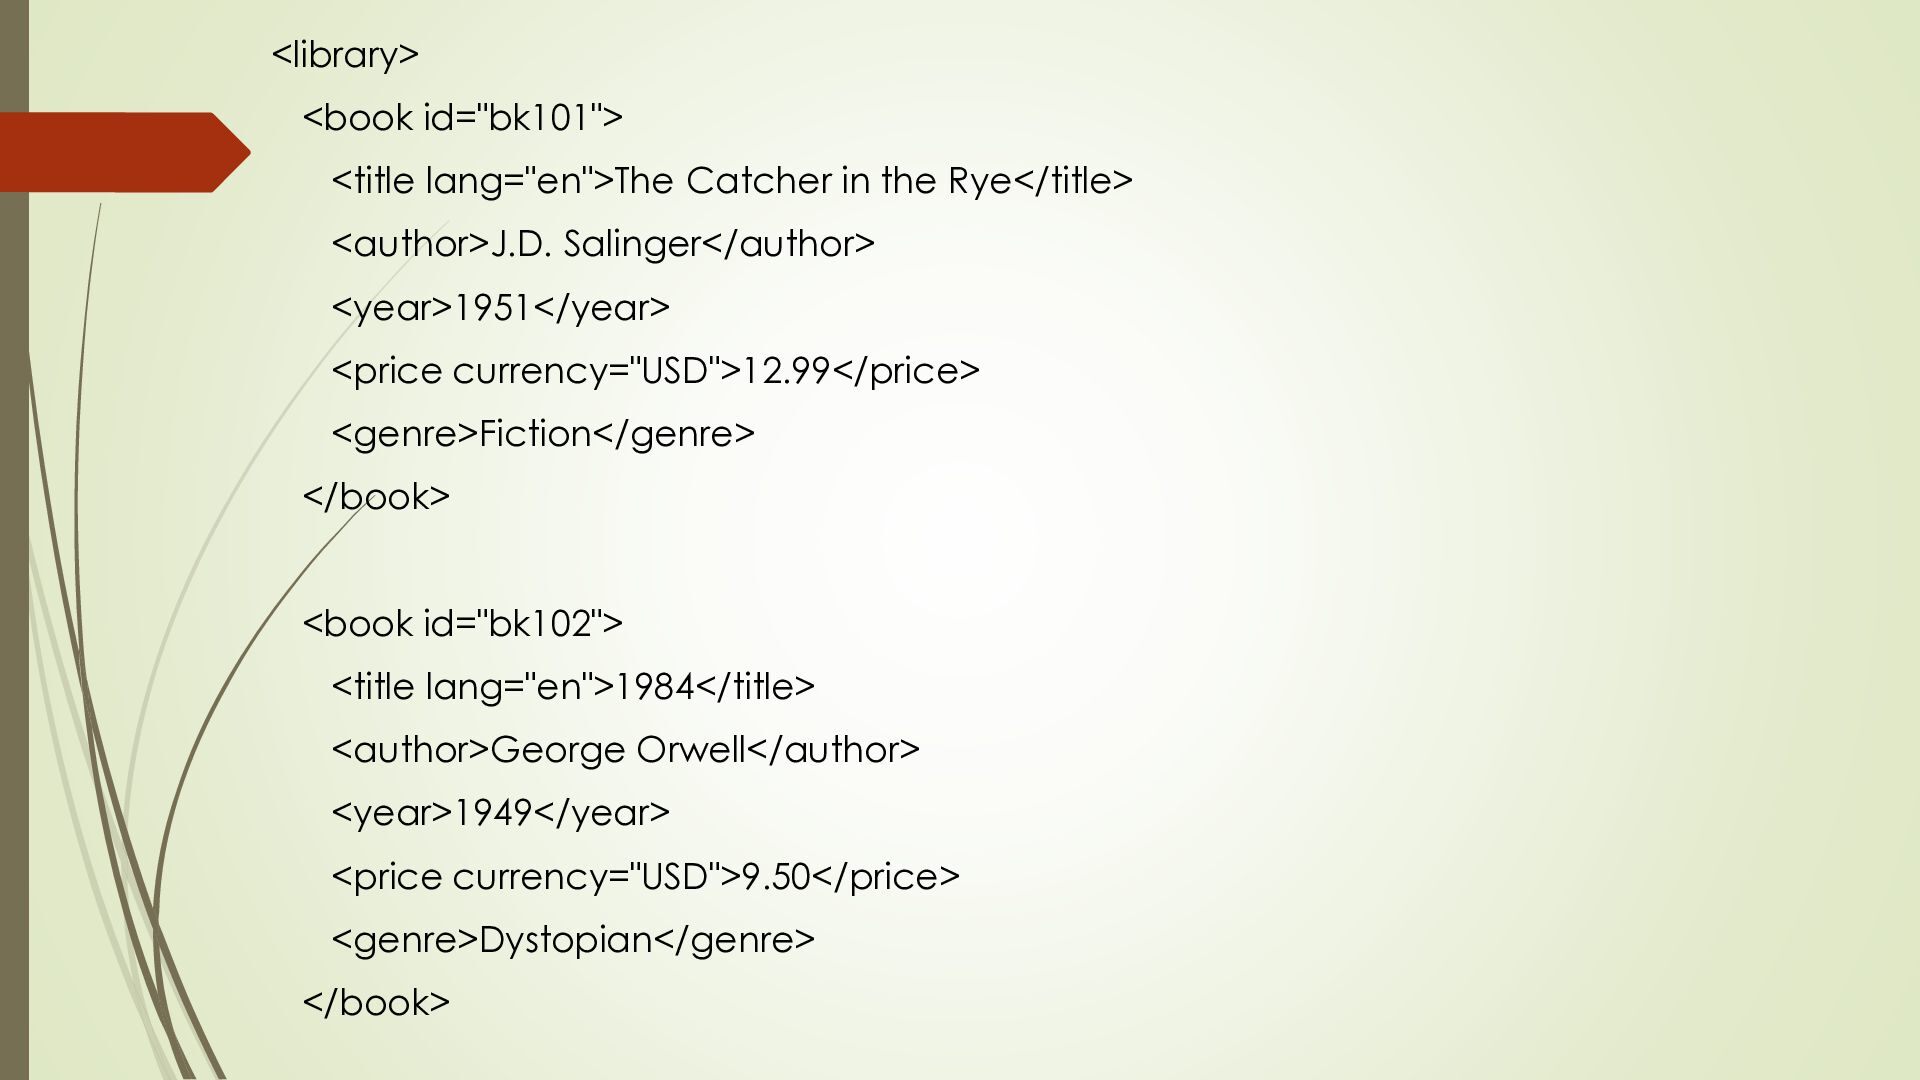
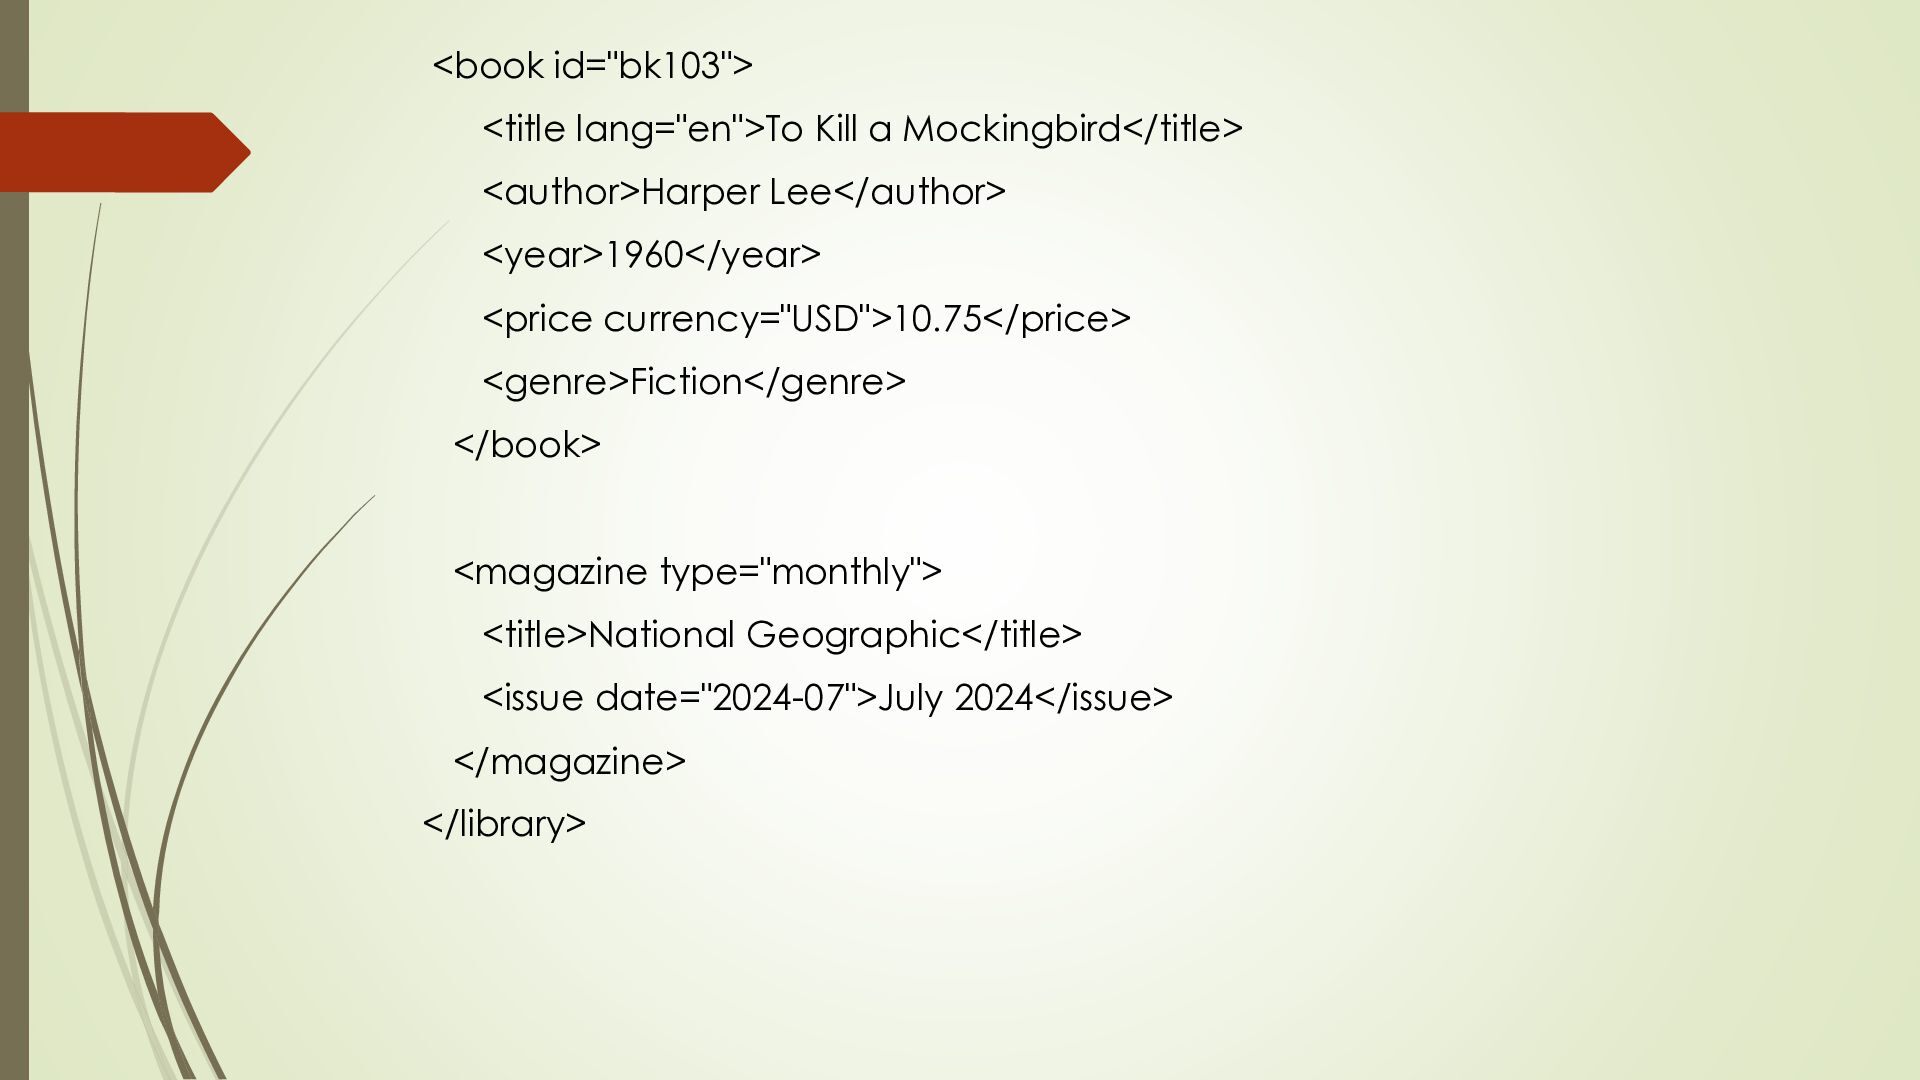
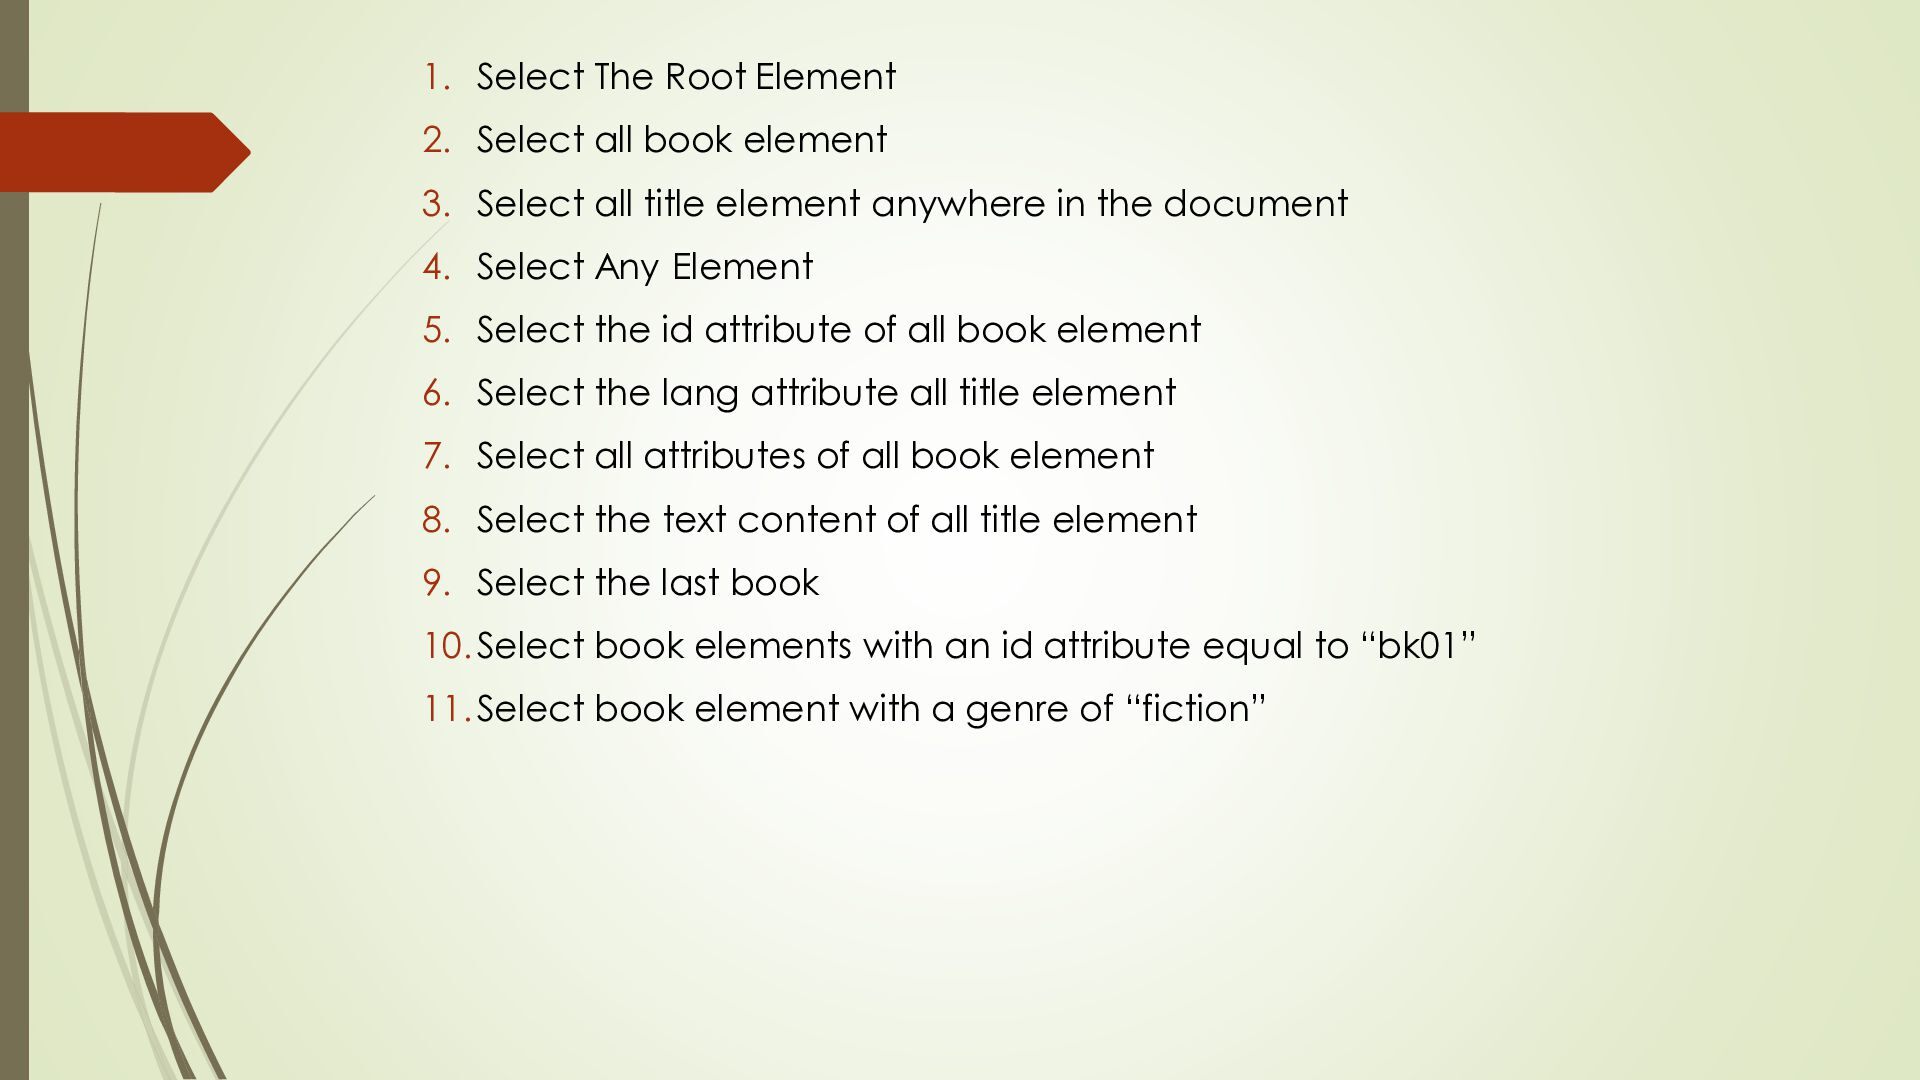
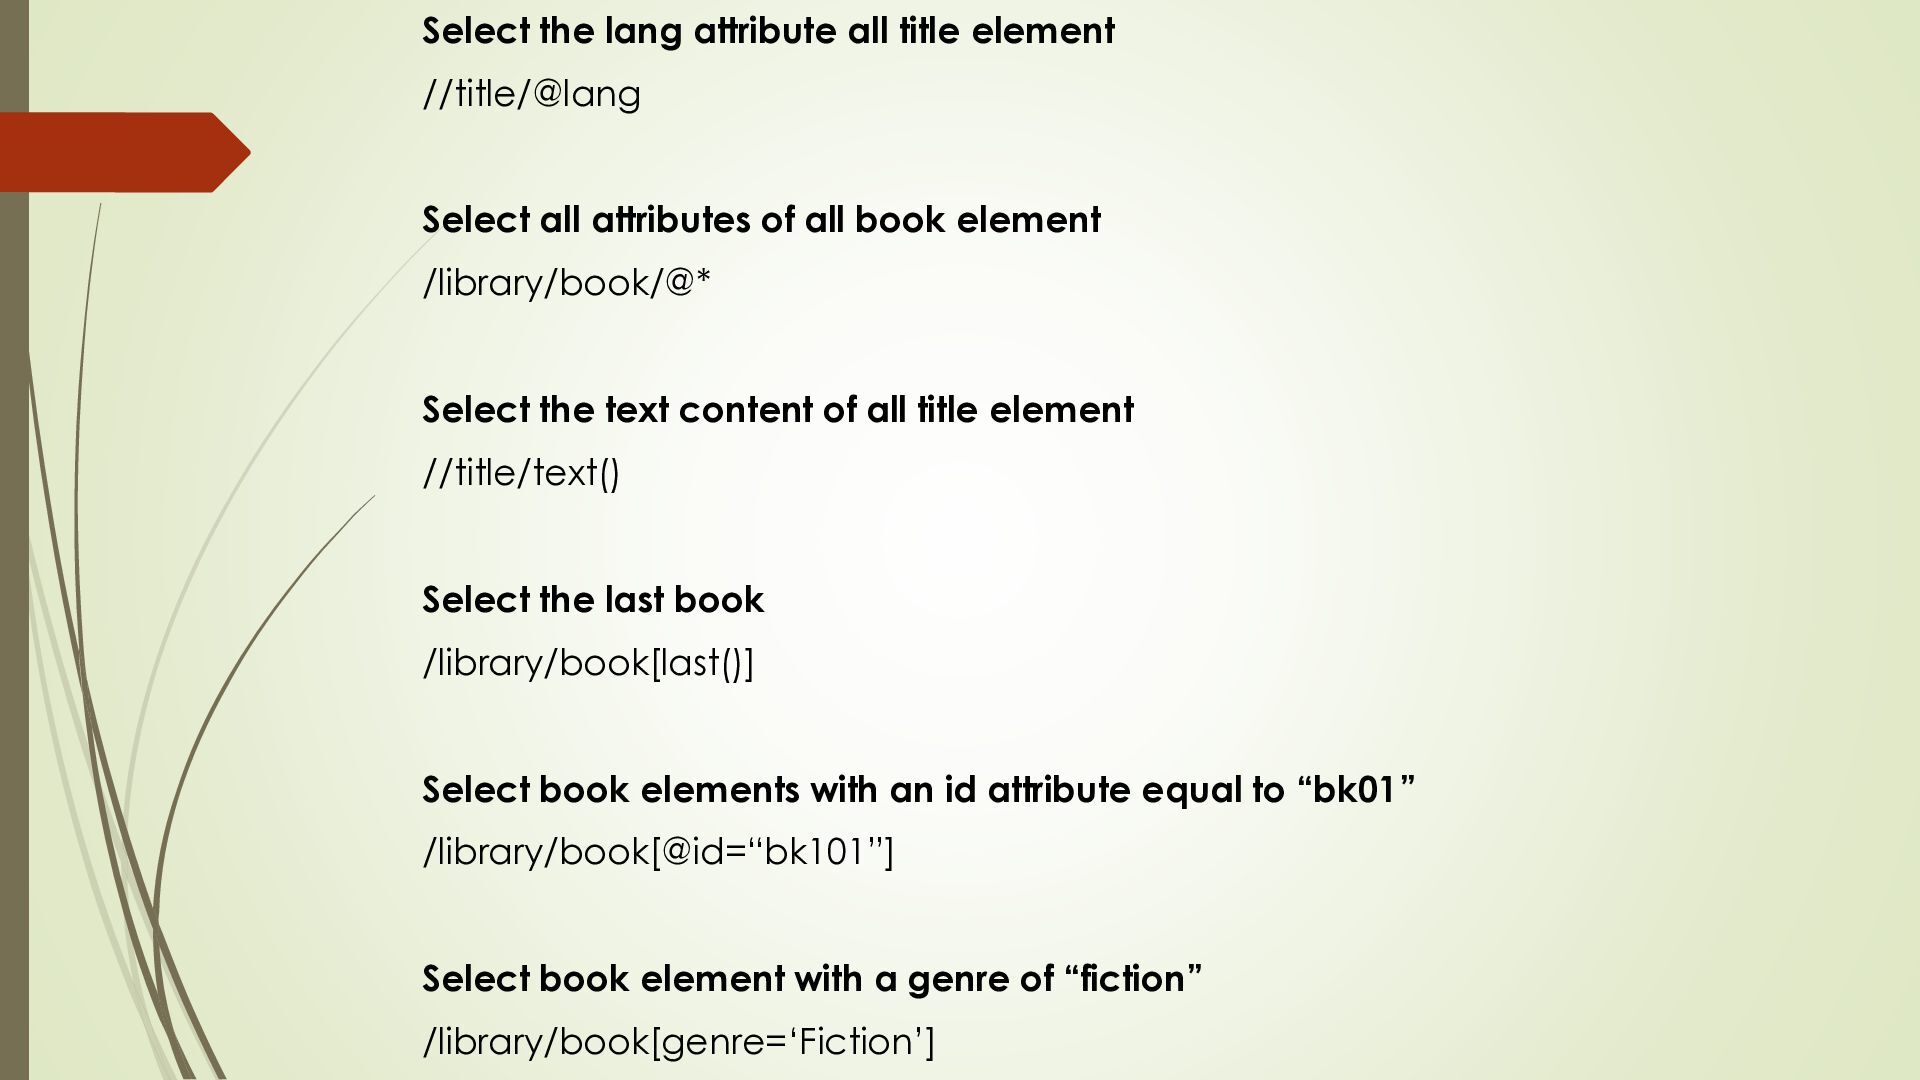
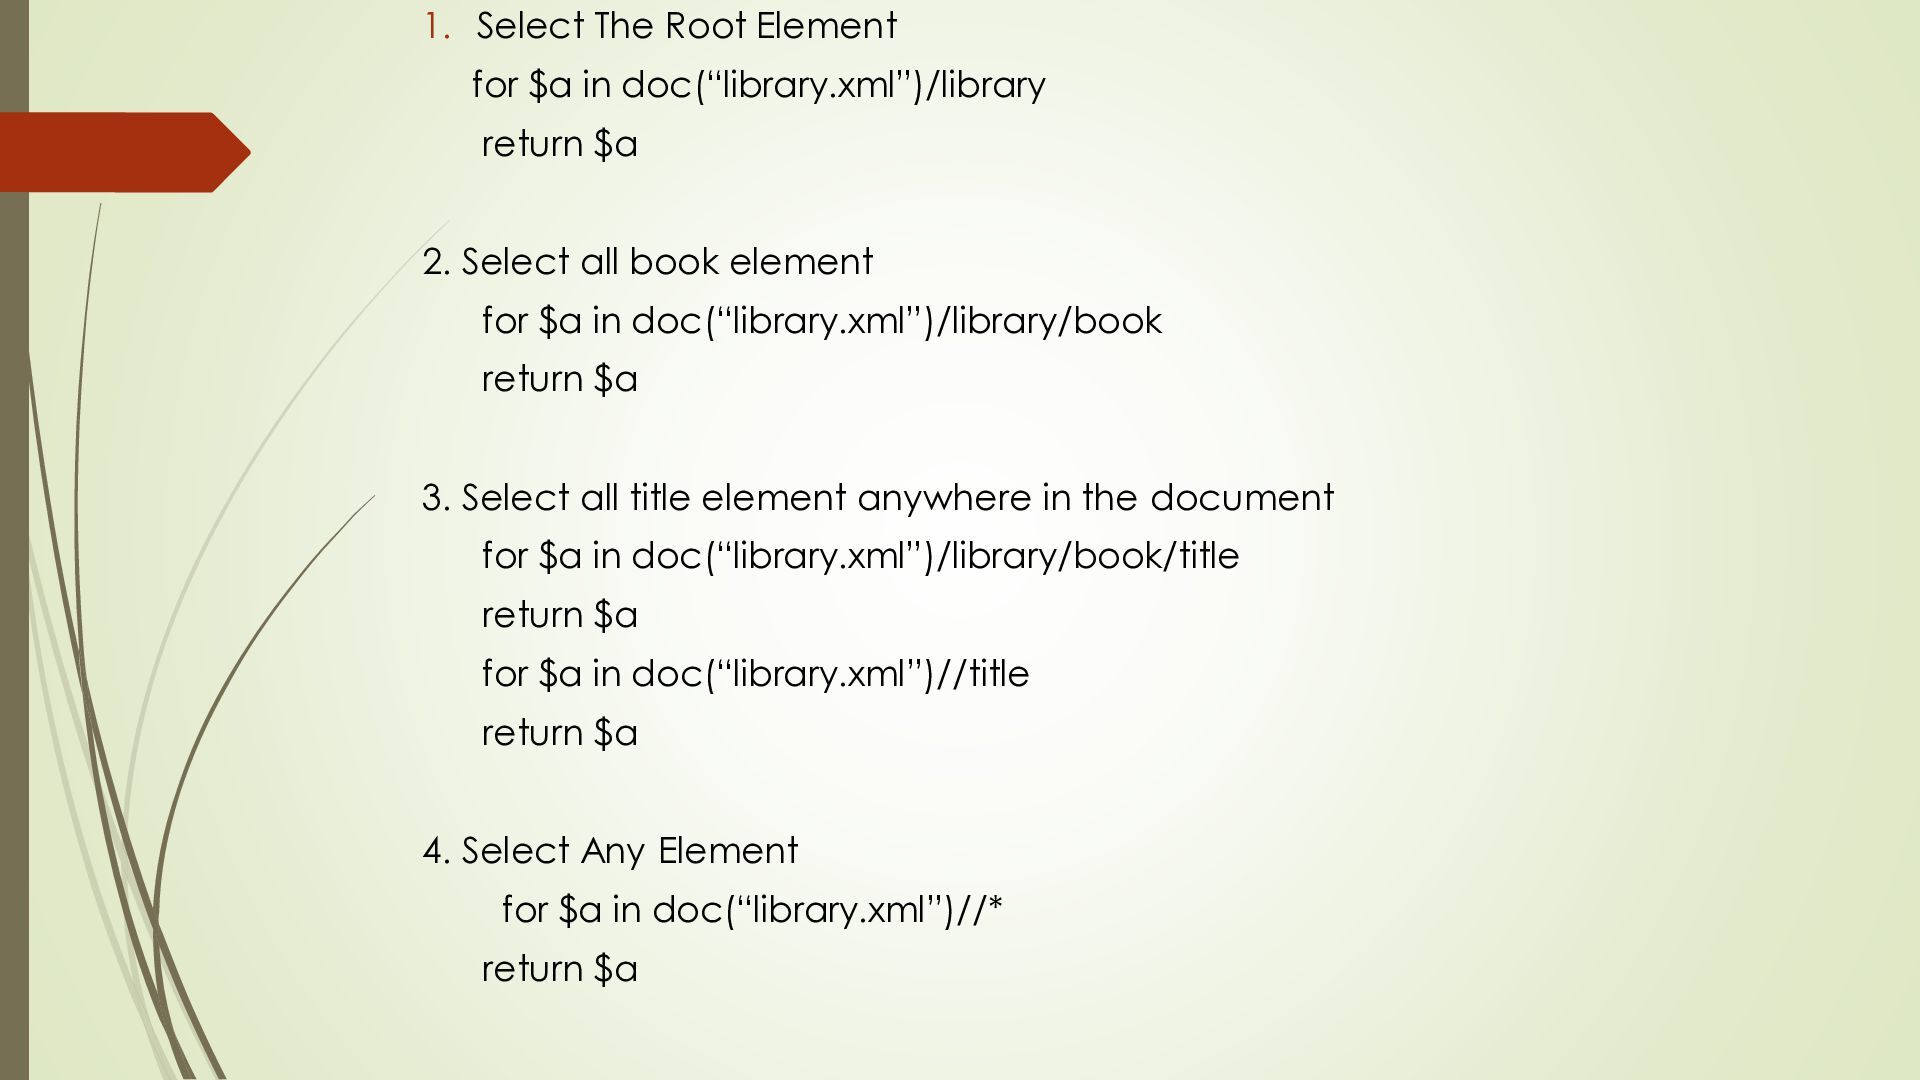
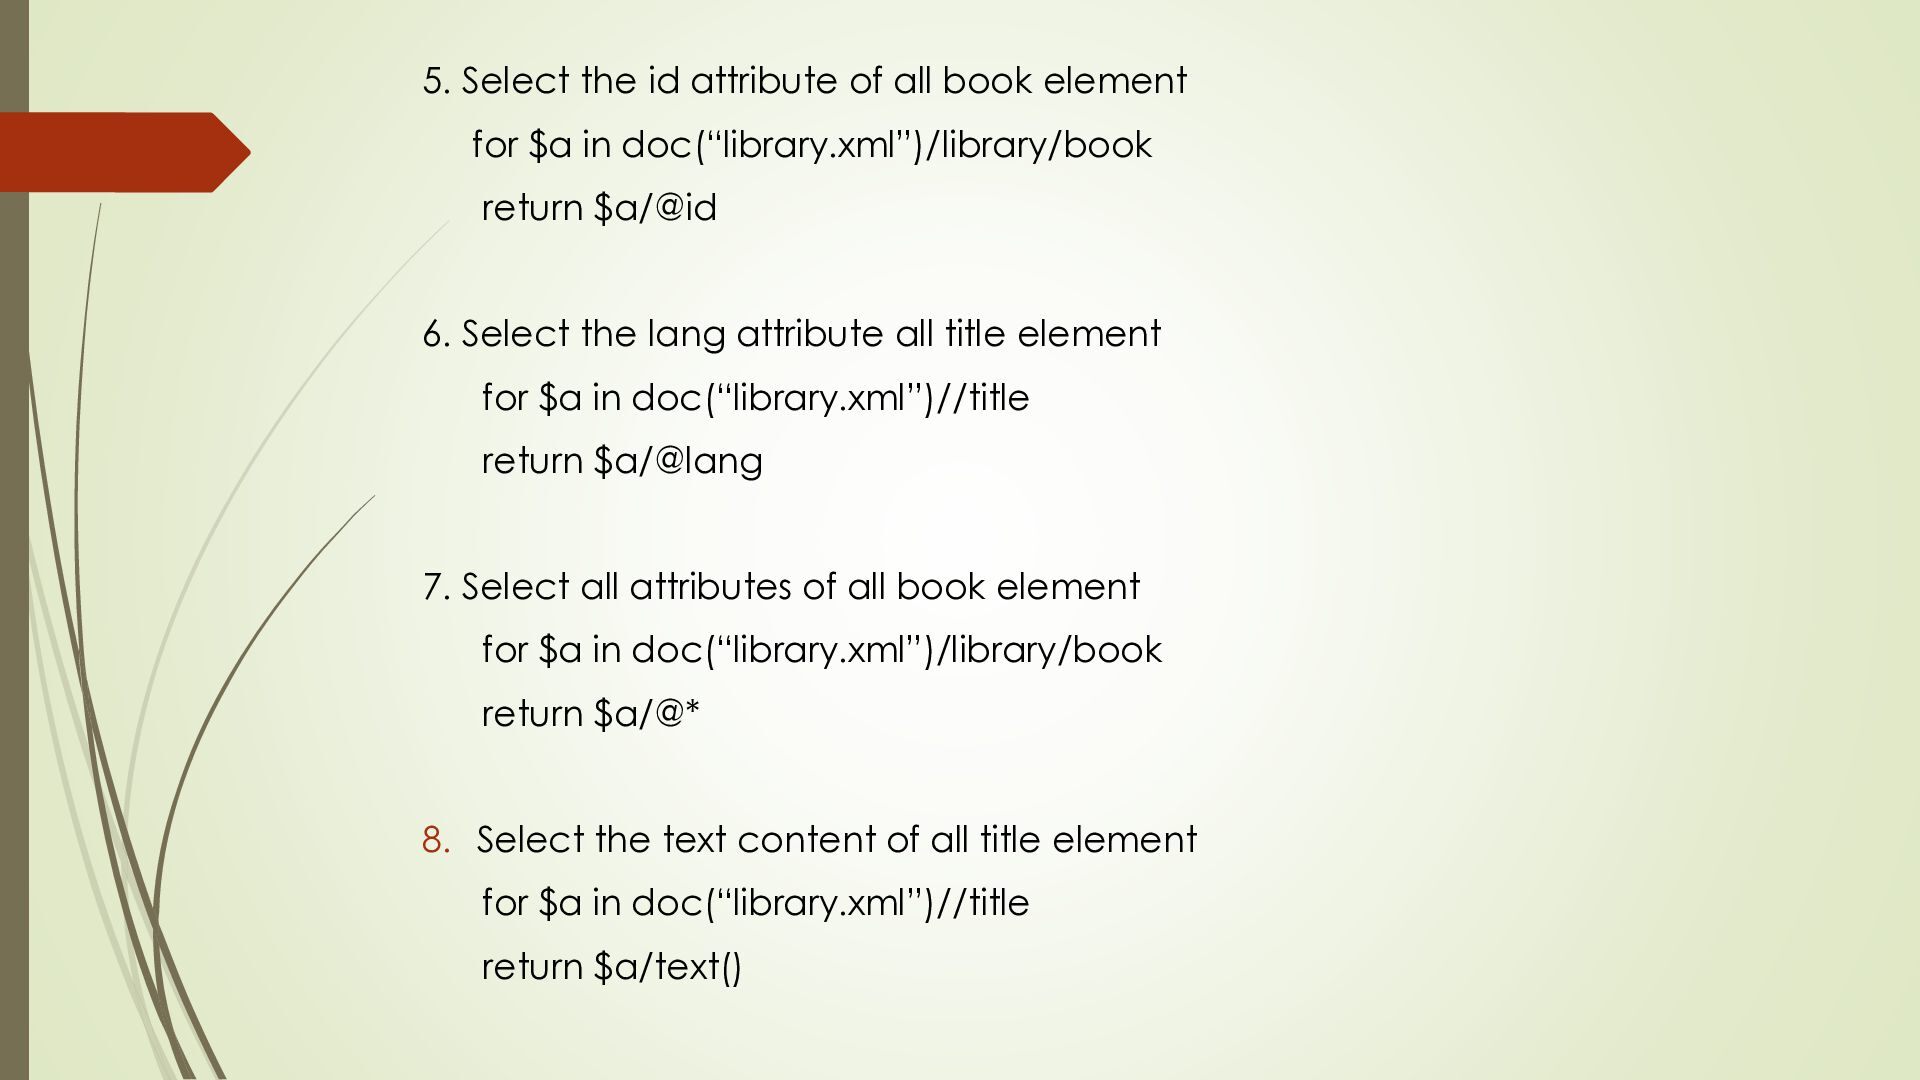
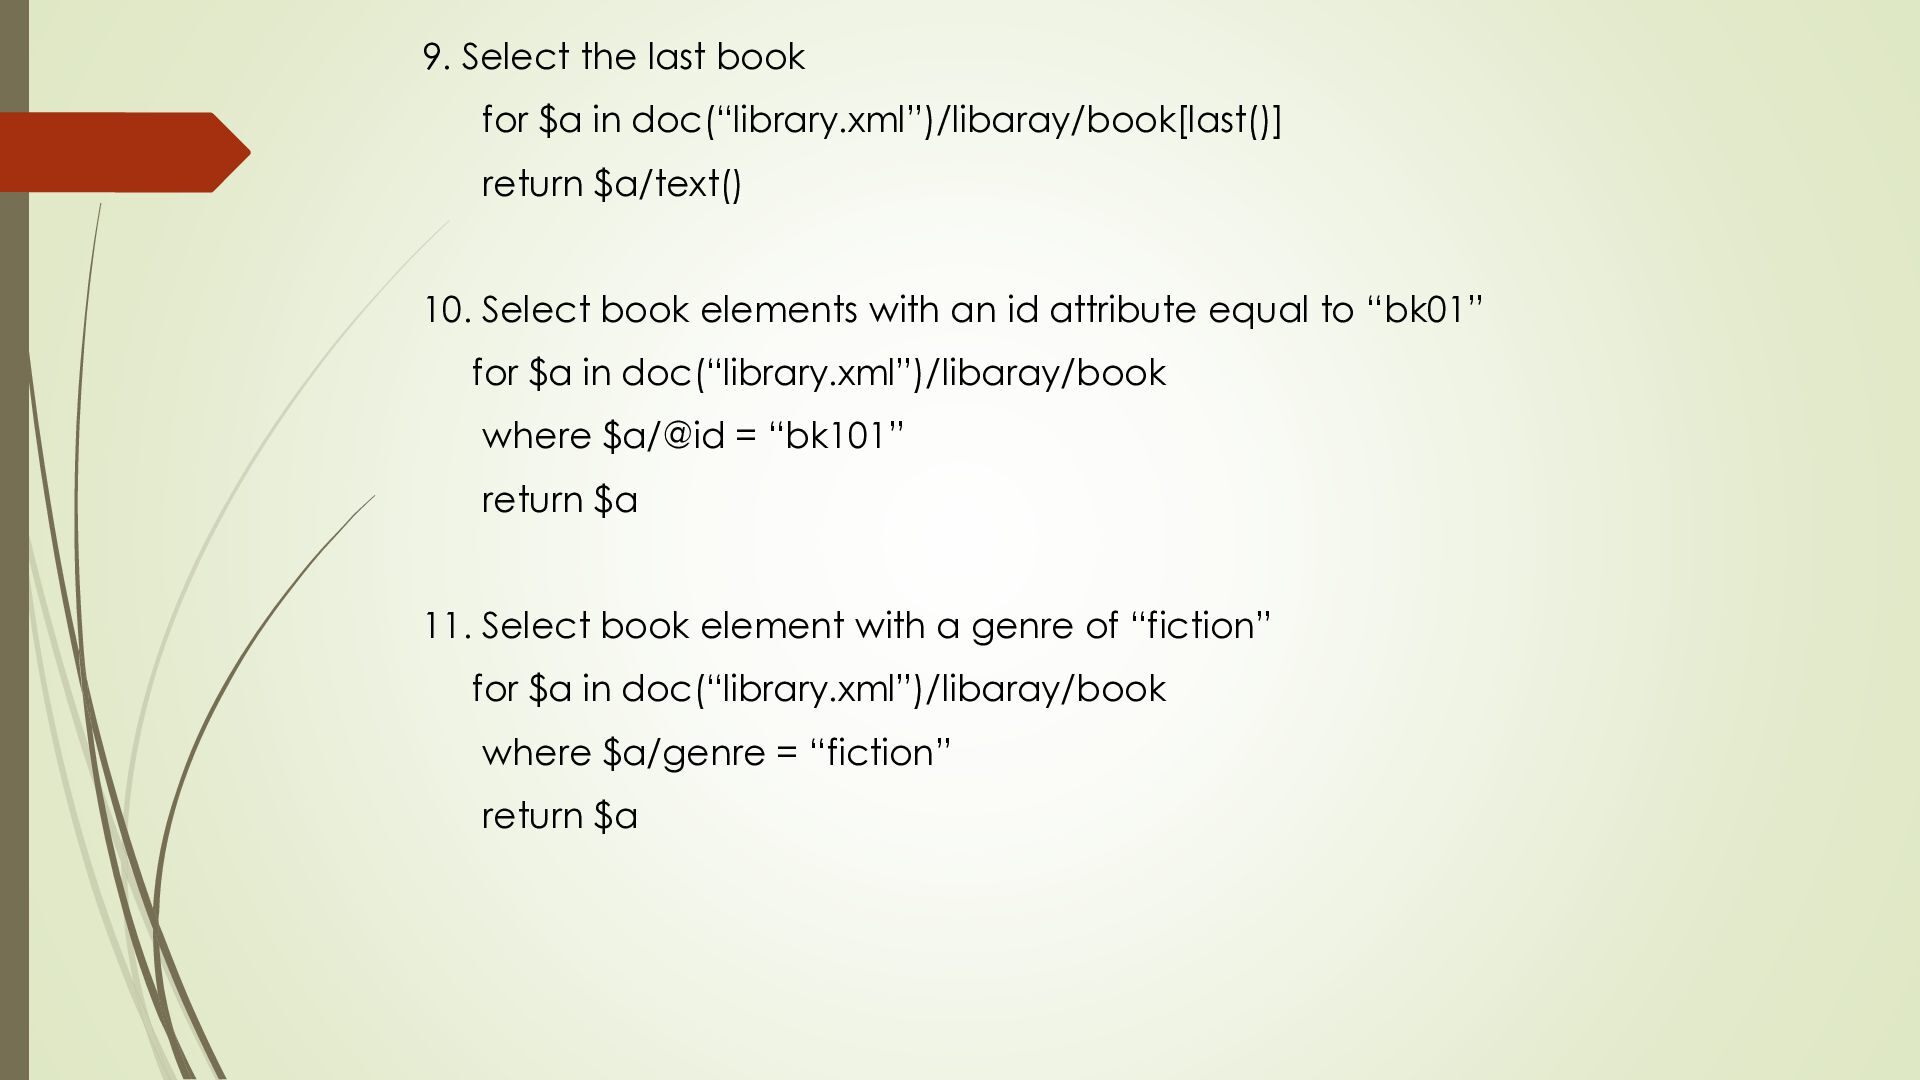
3. Select all title element anywhere in the document 4. Select Any Element 5. Select the id attribute of all book element 6. Select the lang attribute all title element 7. Select all attributes of all book element 8. Select the text content of all title element 9. Select the last book 10. Select book elements with an id attribute equal to “bk01” 11. Select book element with a genre of “fiction”
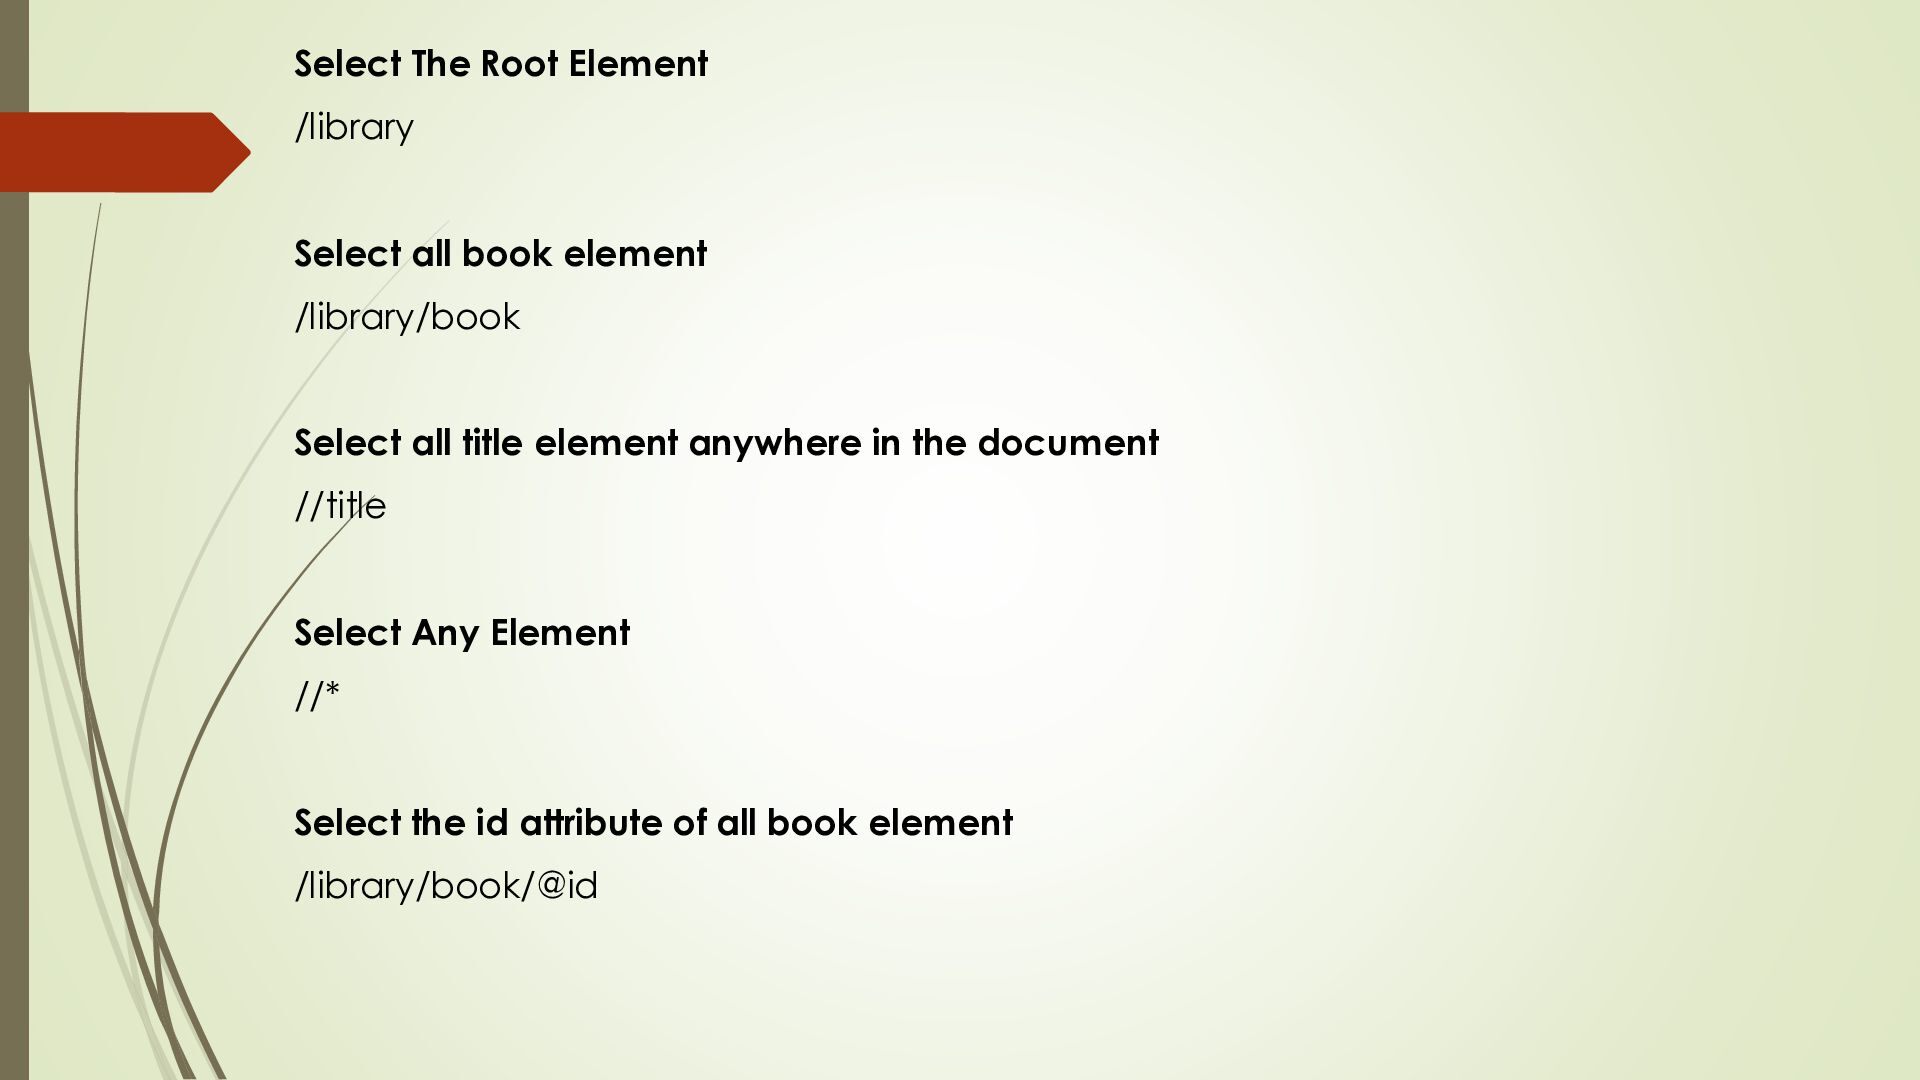
attributes of all book element /library/book/@* Select the text content of all title element //title/text() Select the last book /library/book[last()] Select book elements with an id attribute equal to “bk01” /library/book[@id=“bk101”] Select book element with a genre of “fiction” /library/book[genre=‘Fiction’]
$a 2. Select all book element for $a in doc(“library.xml”)/library/book return $a 3. Select all title element anywhere in the document for $a in doc(“library.xml”)/library/book/title return $a for $a in doc(“library.xml”)//title return $a 4. Select Any Element for $a in doc(“library.xml”)//* return $a
$a in doc(“library.xml”)/library/book return $a/@id 6. Select the lang attribute all title element for $a in doc(“library.xml”)//title return $a/@lang 7. Select all attributes of all book element for $a in doc(“library.xml”)/library/book return $a/@* 8. Select the text content of all title element for $a in doc(“library.xml”)//title return $a/text()
$a/text() 10. Select book elements with an id attribute equal to “bk01” for $a in doc(“library.xml”)/libaray/book where $a/@id = “bk101” return $a 11. Select book element with a genre of “fiction” for $a in doc(“library.xml”)/libaray/book where $a/genre = “fiction” return $a


 bhagyashripattankude29
 lara
 mojombo
 maltzj
 marktimemedia
 soudai
 gurzu
 keavy
 twada
 kimpetersen
 tammyeverts
 leimatthew05
 holman