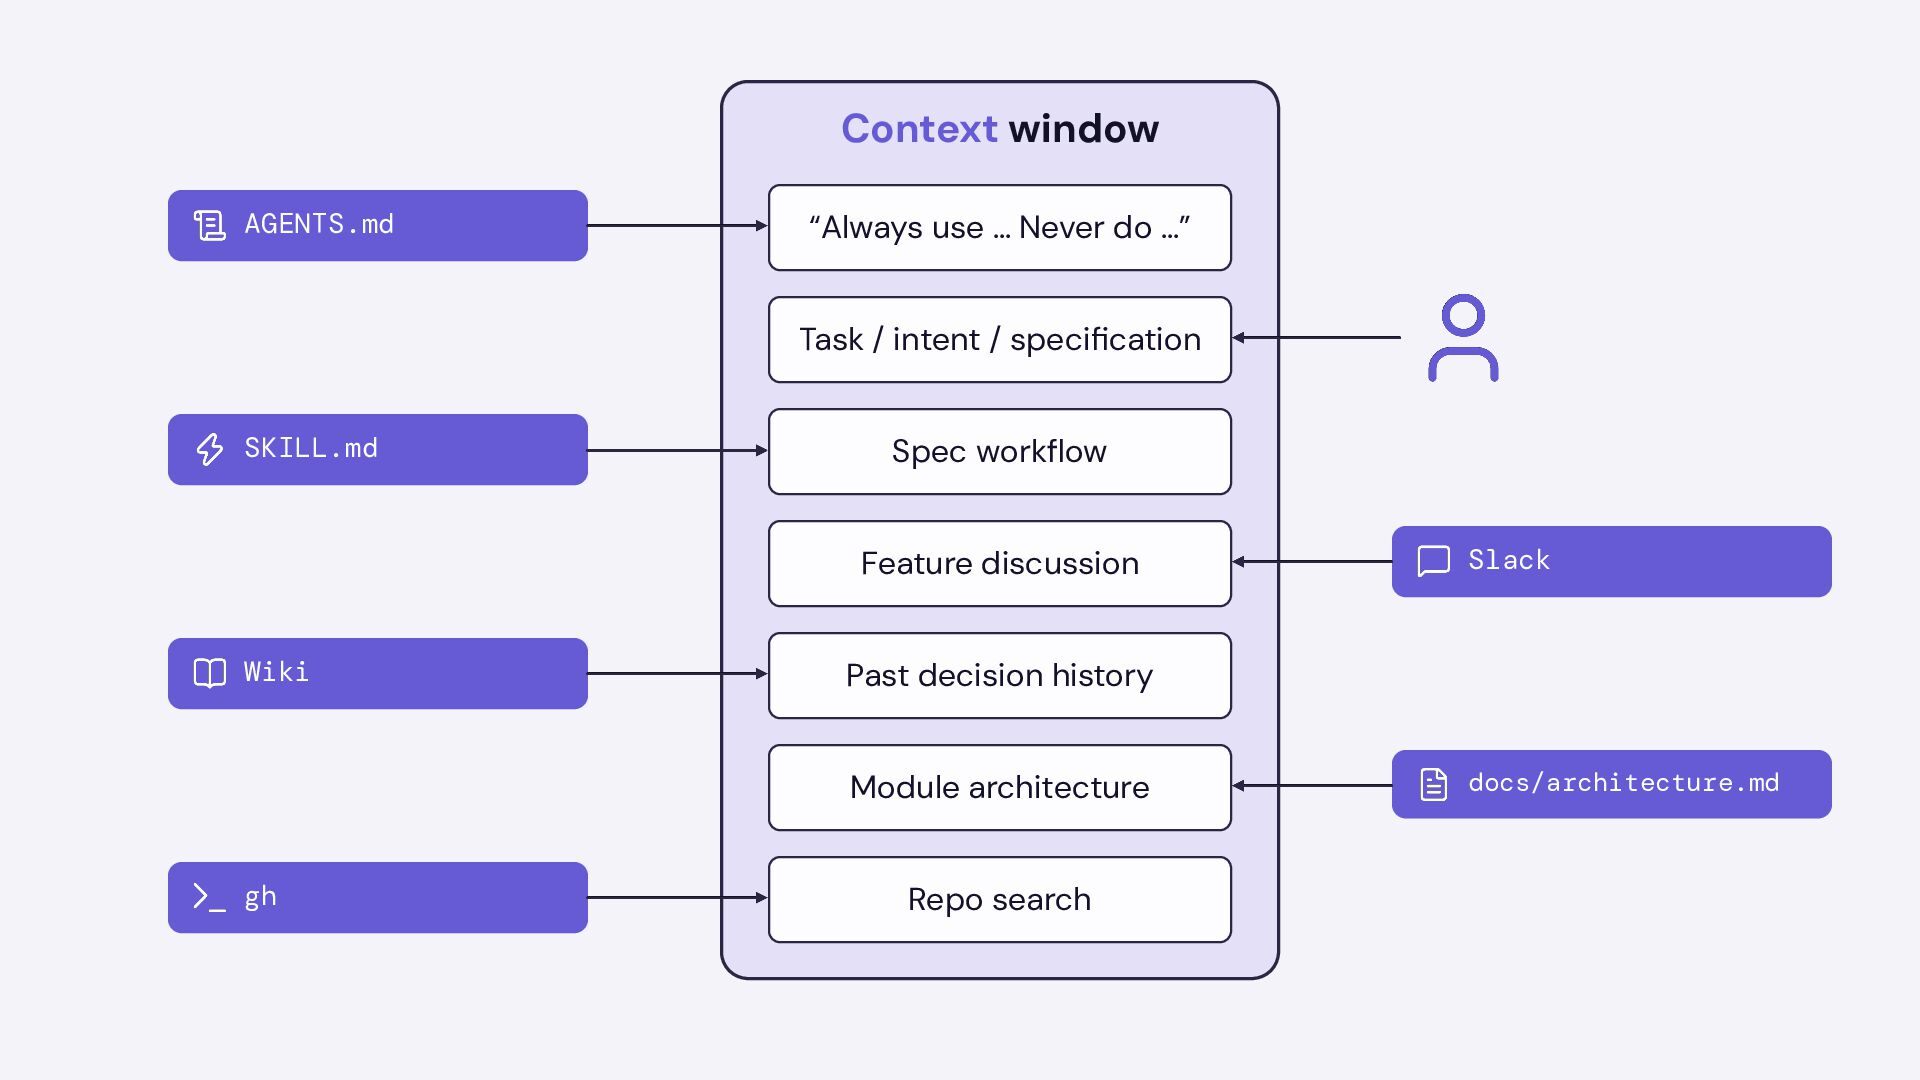
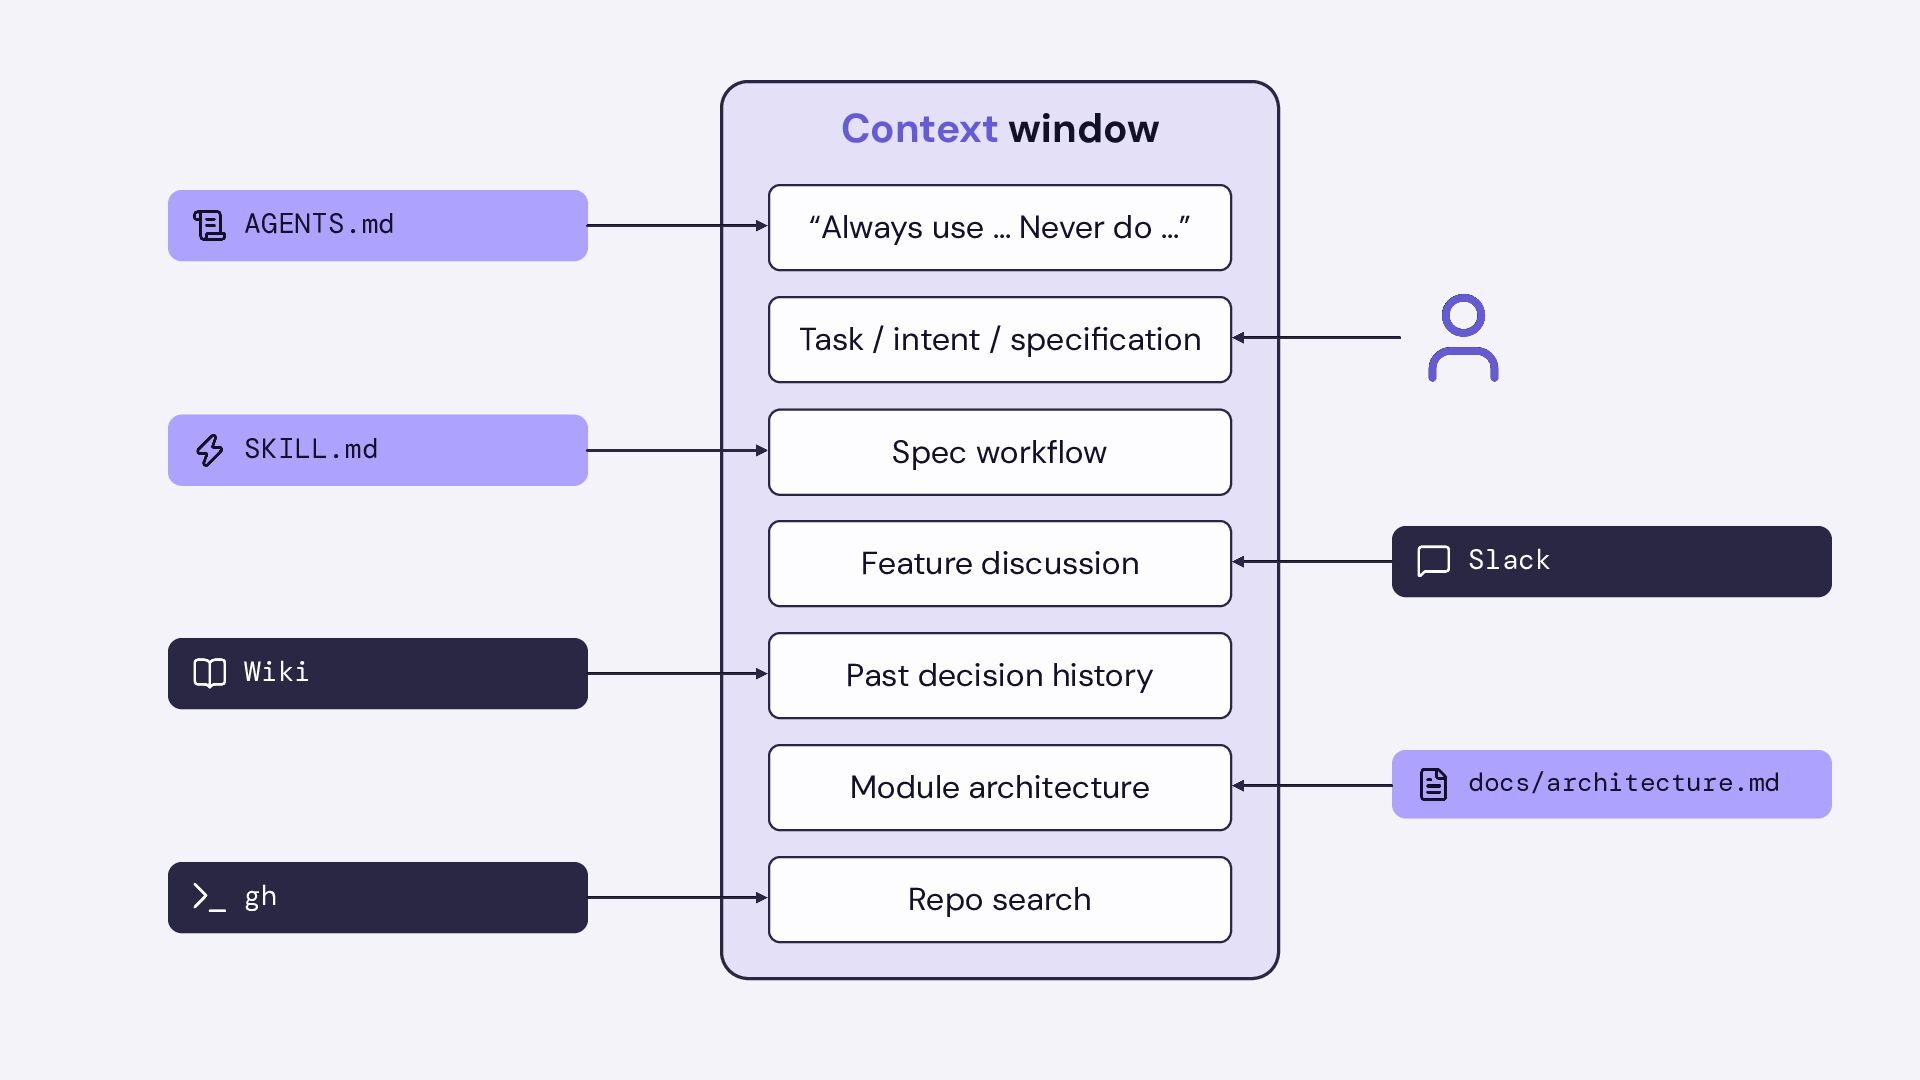
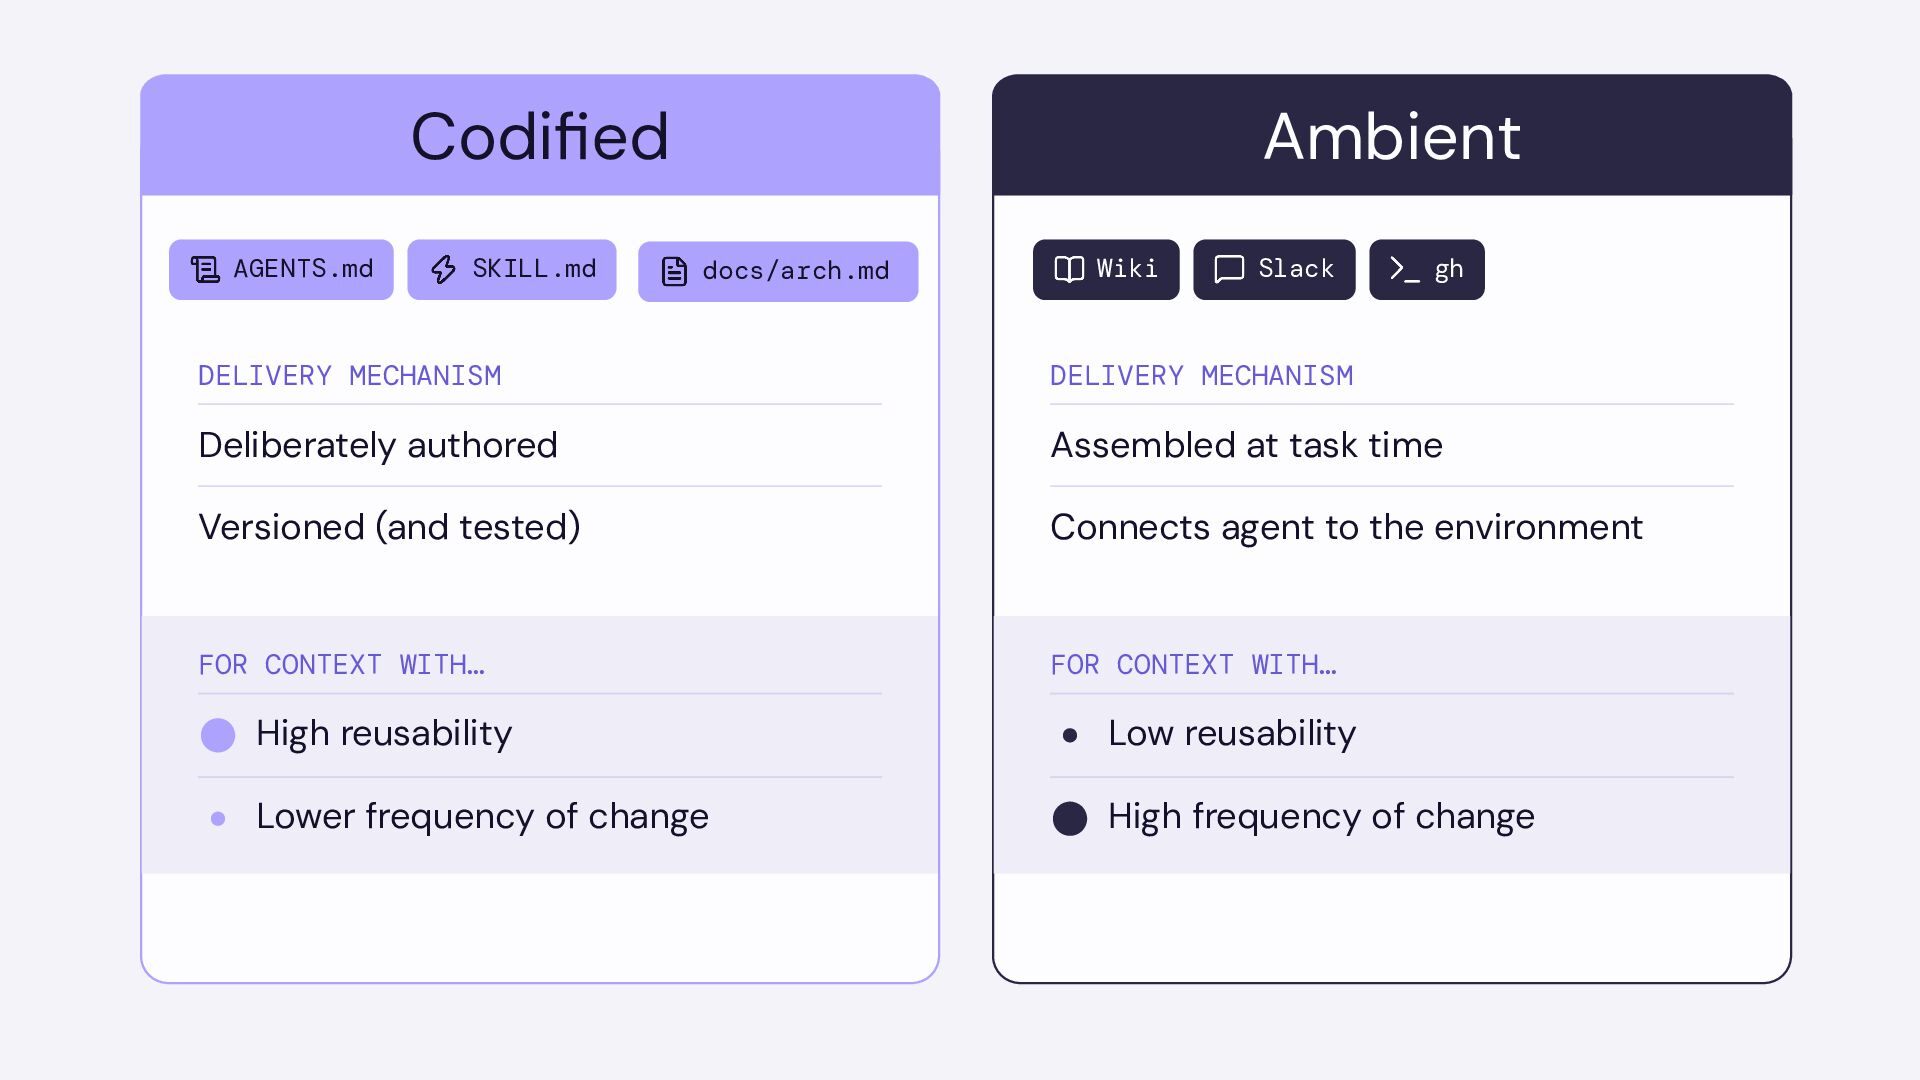
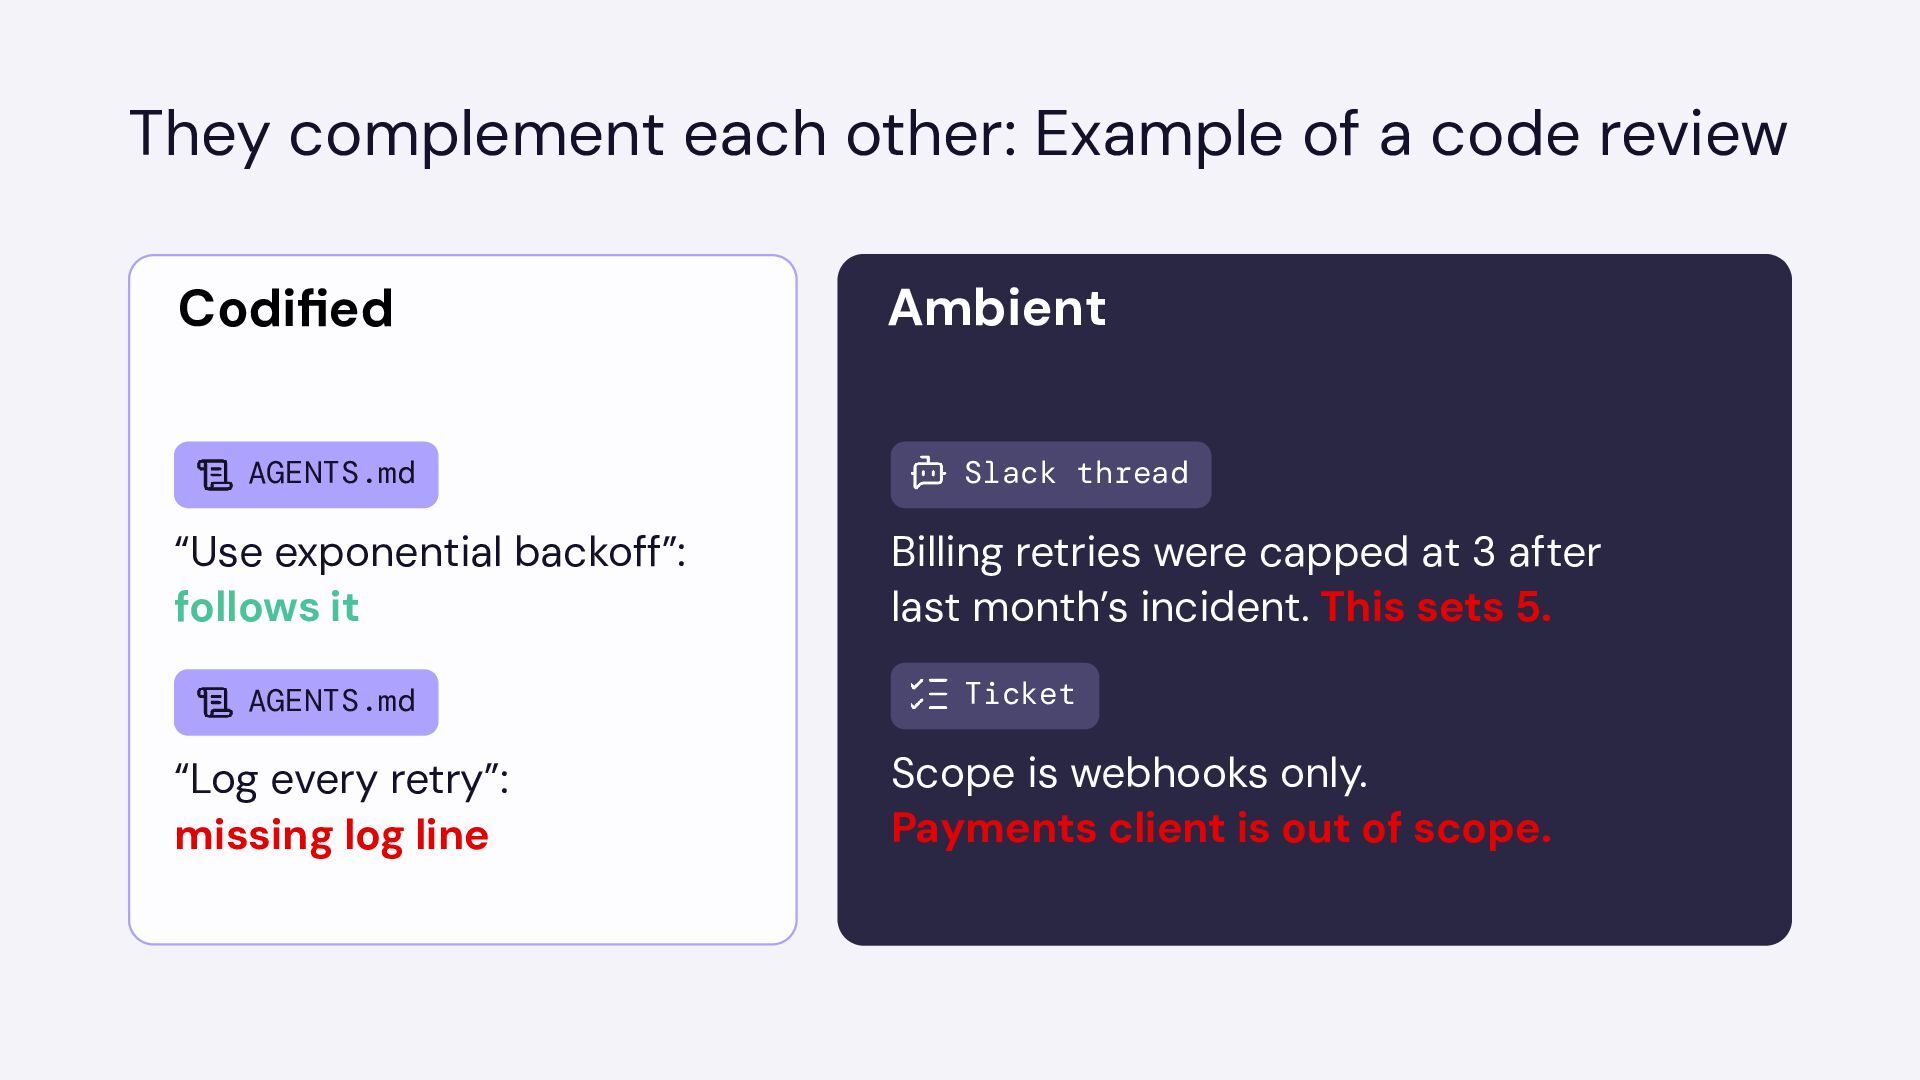
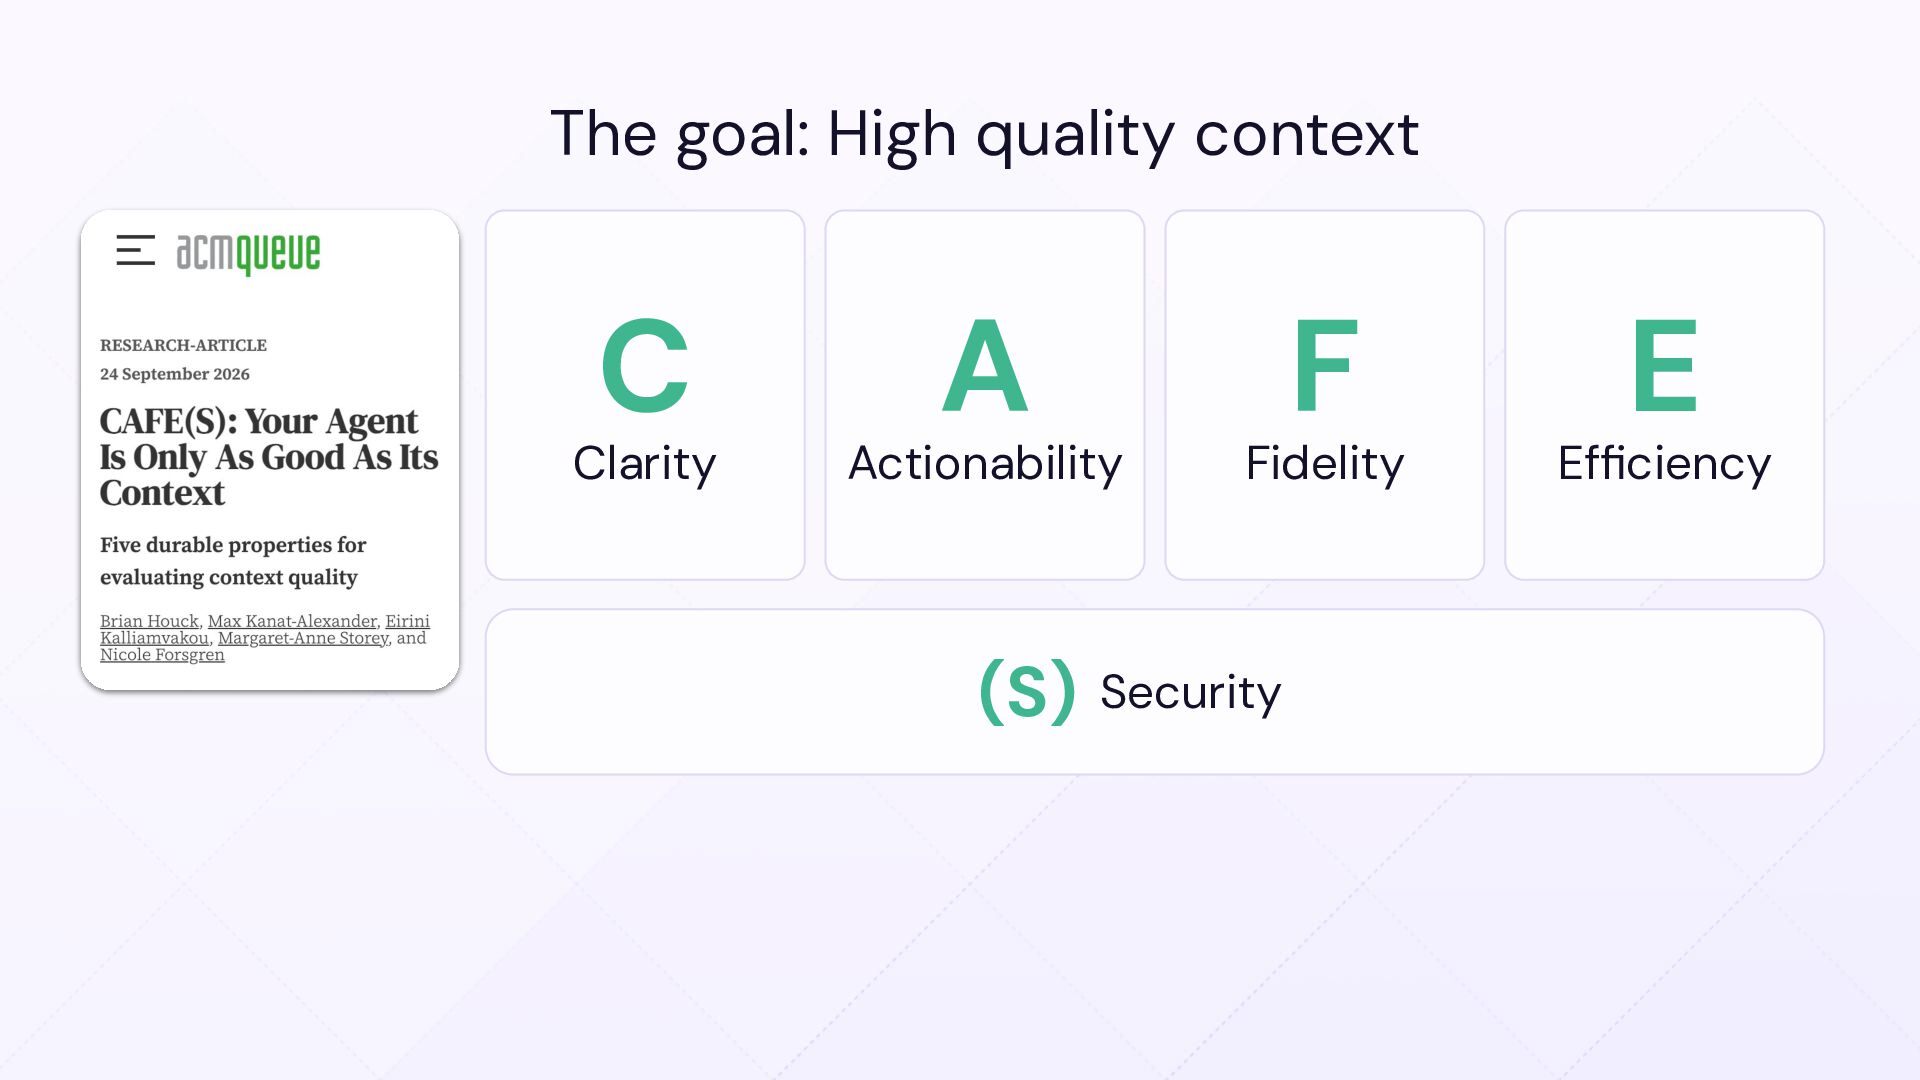
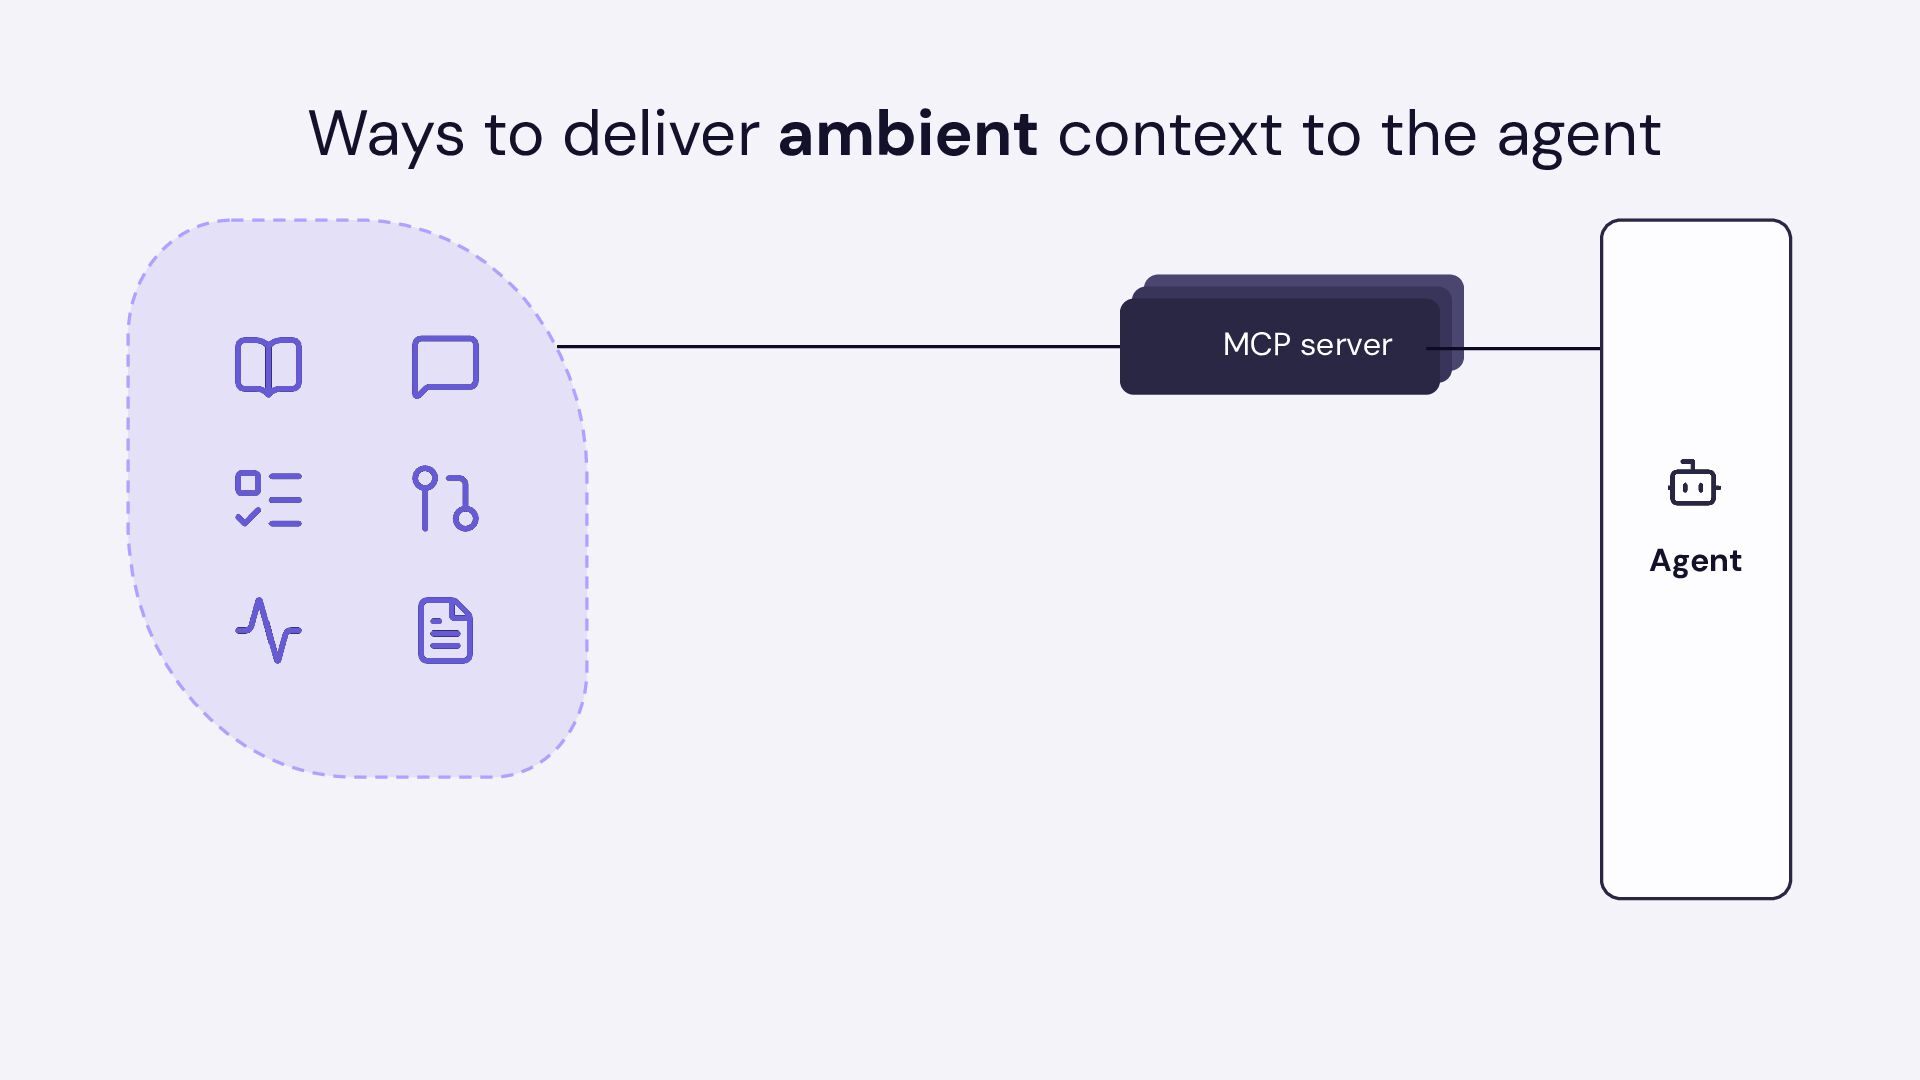
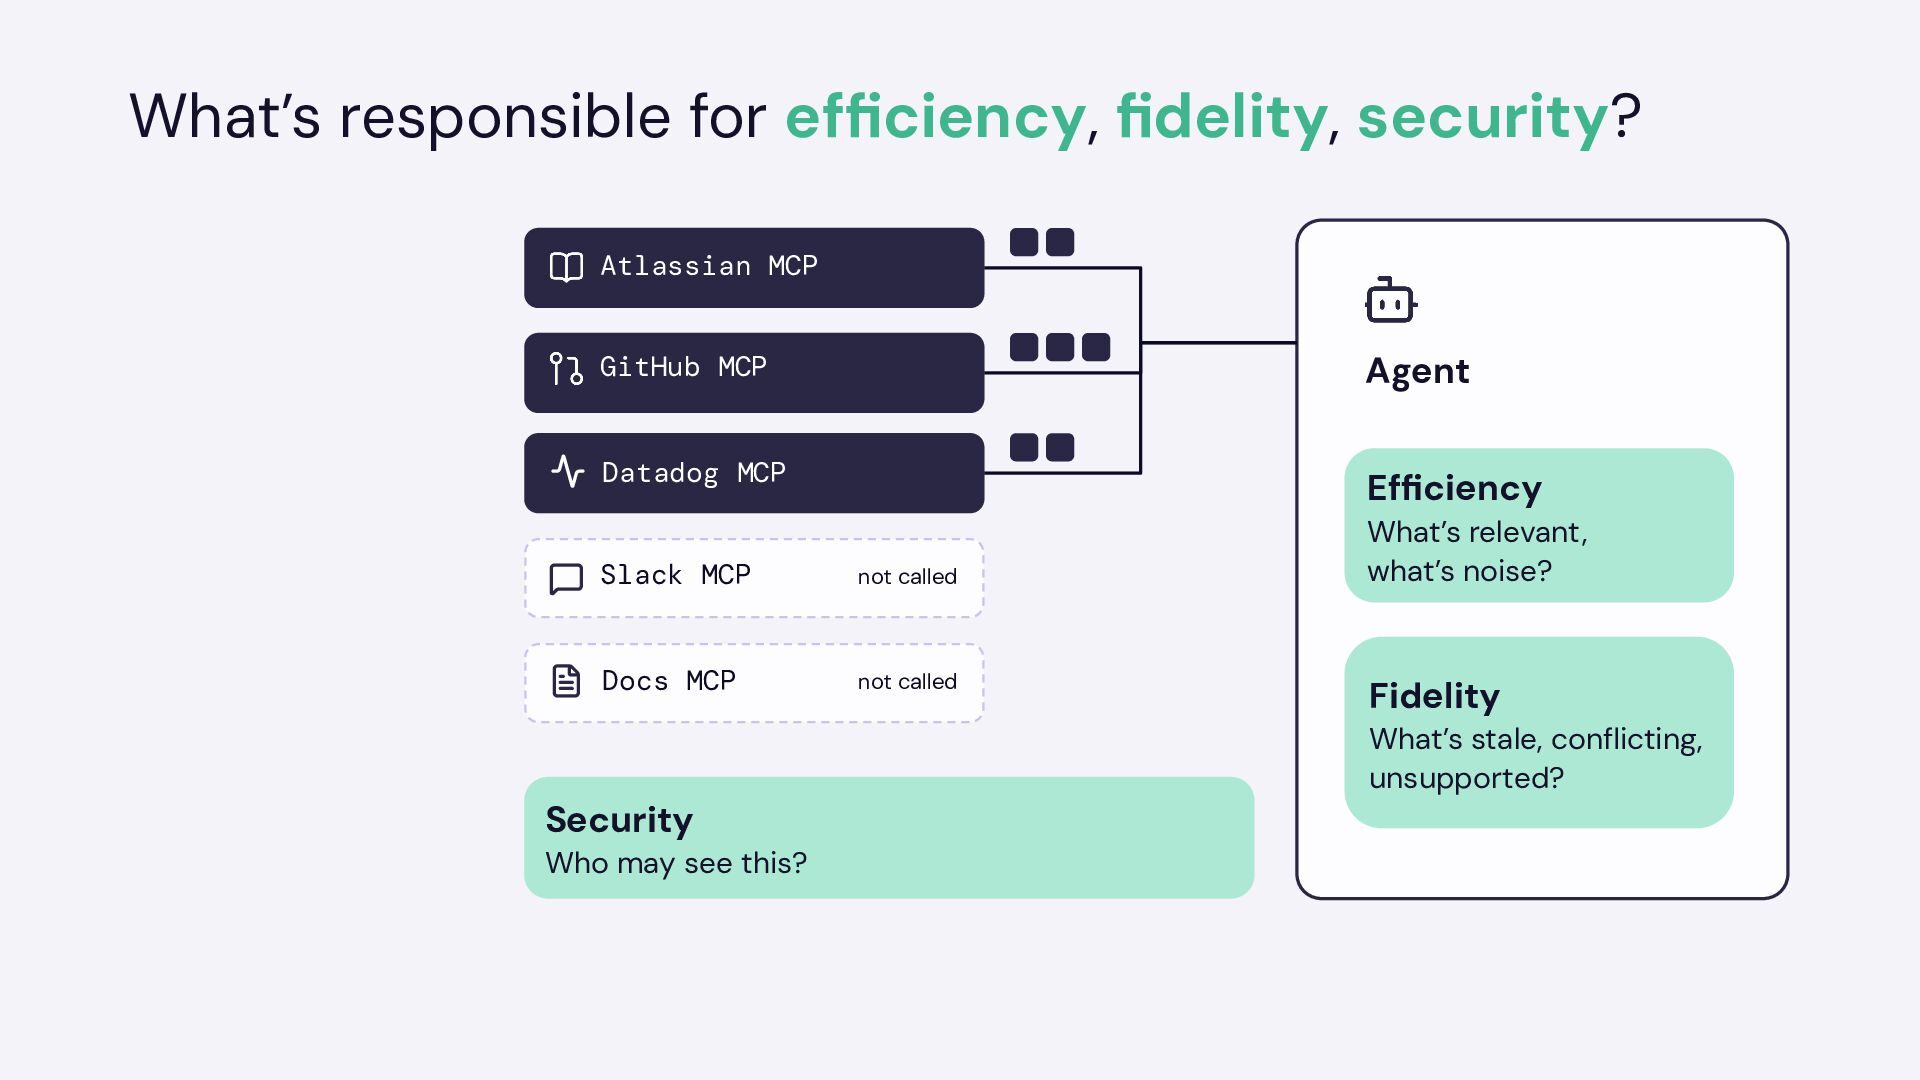
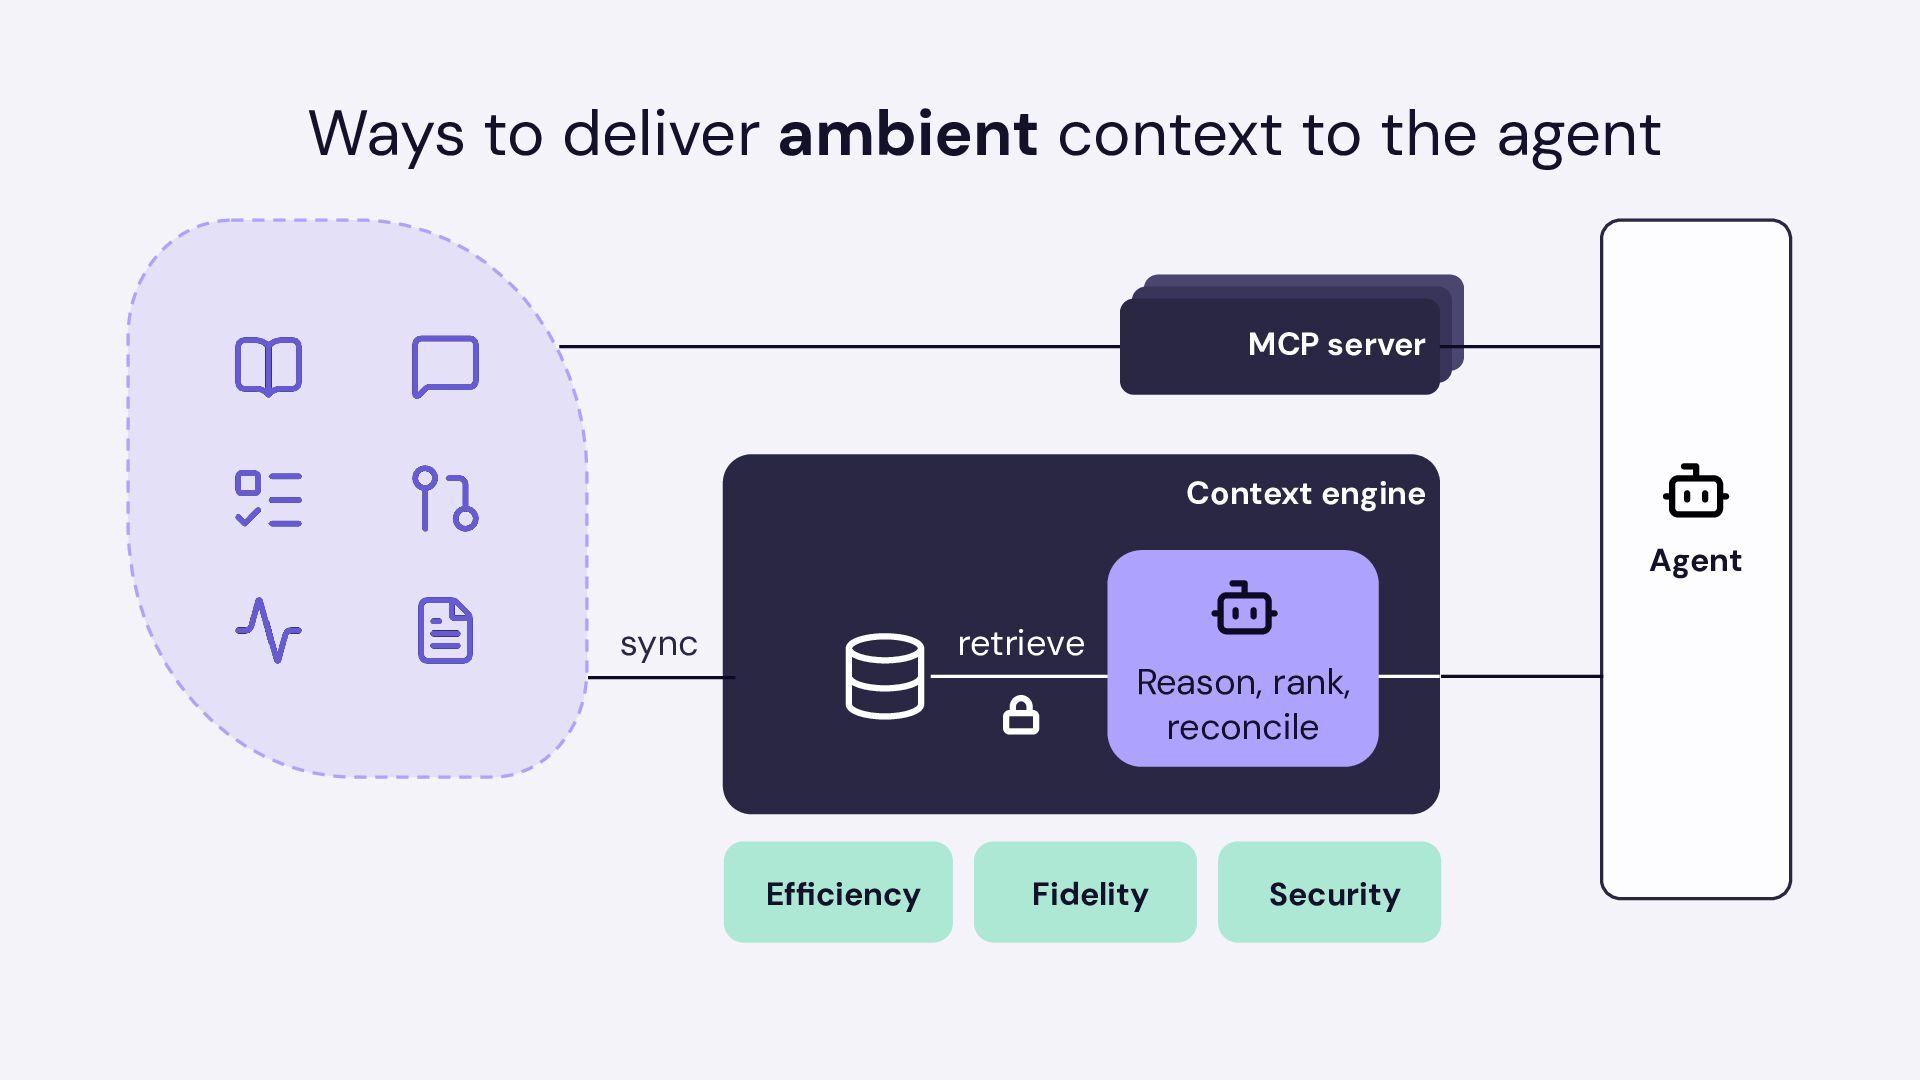
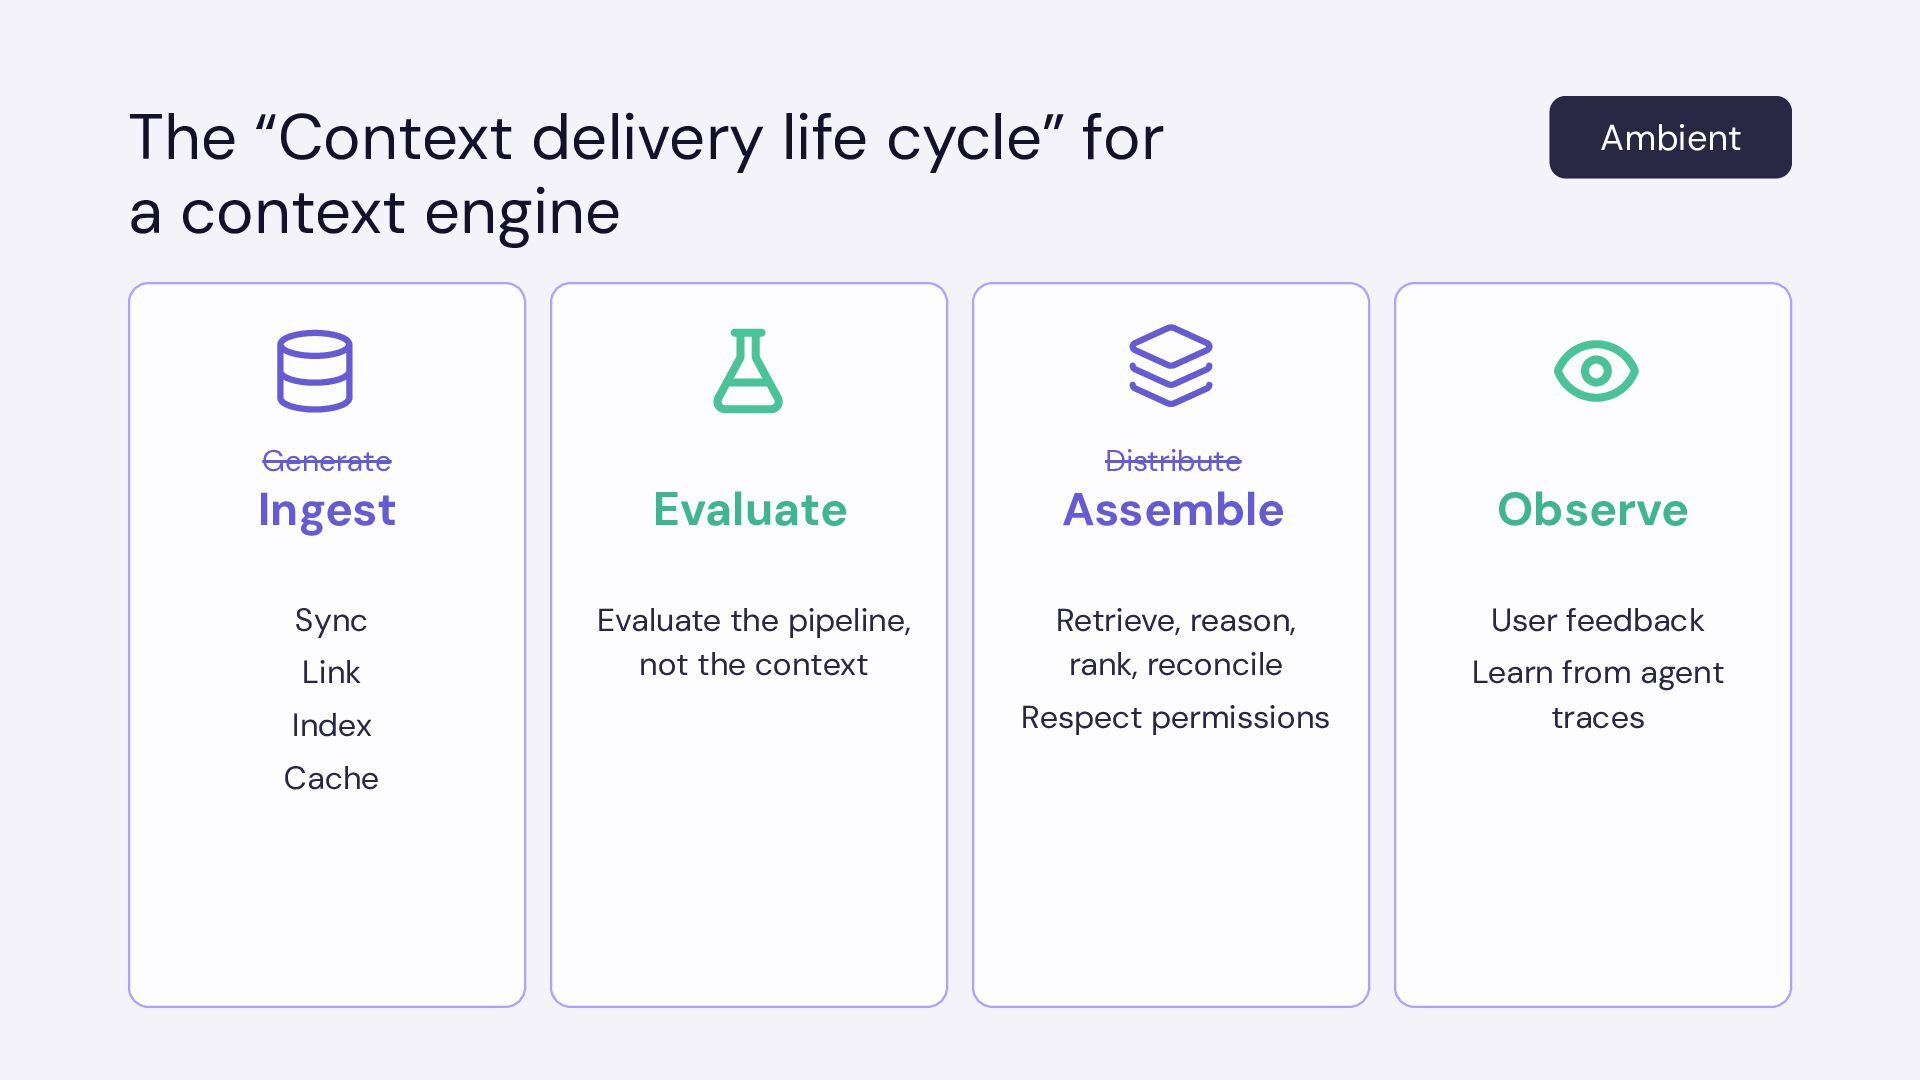
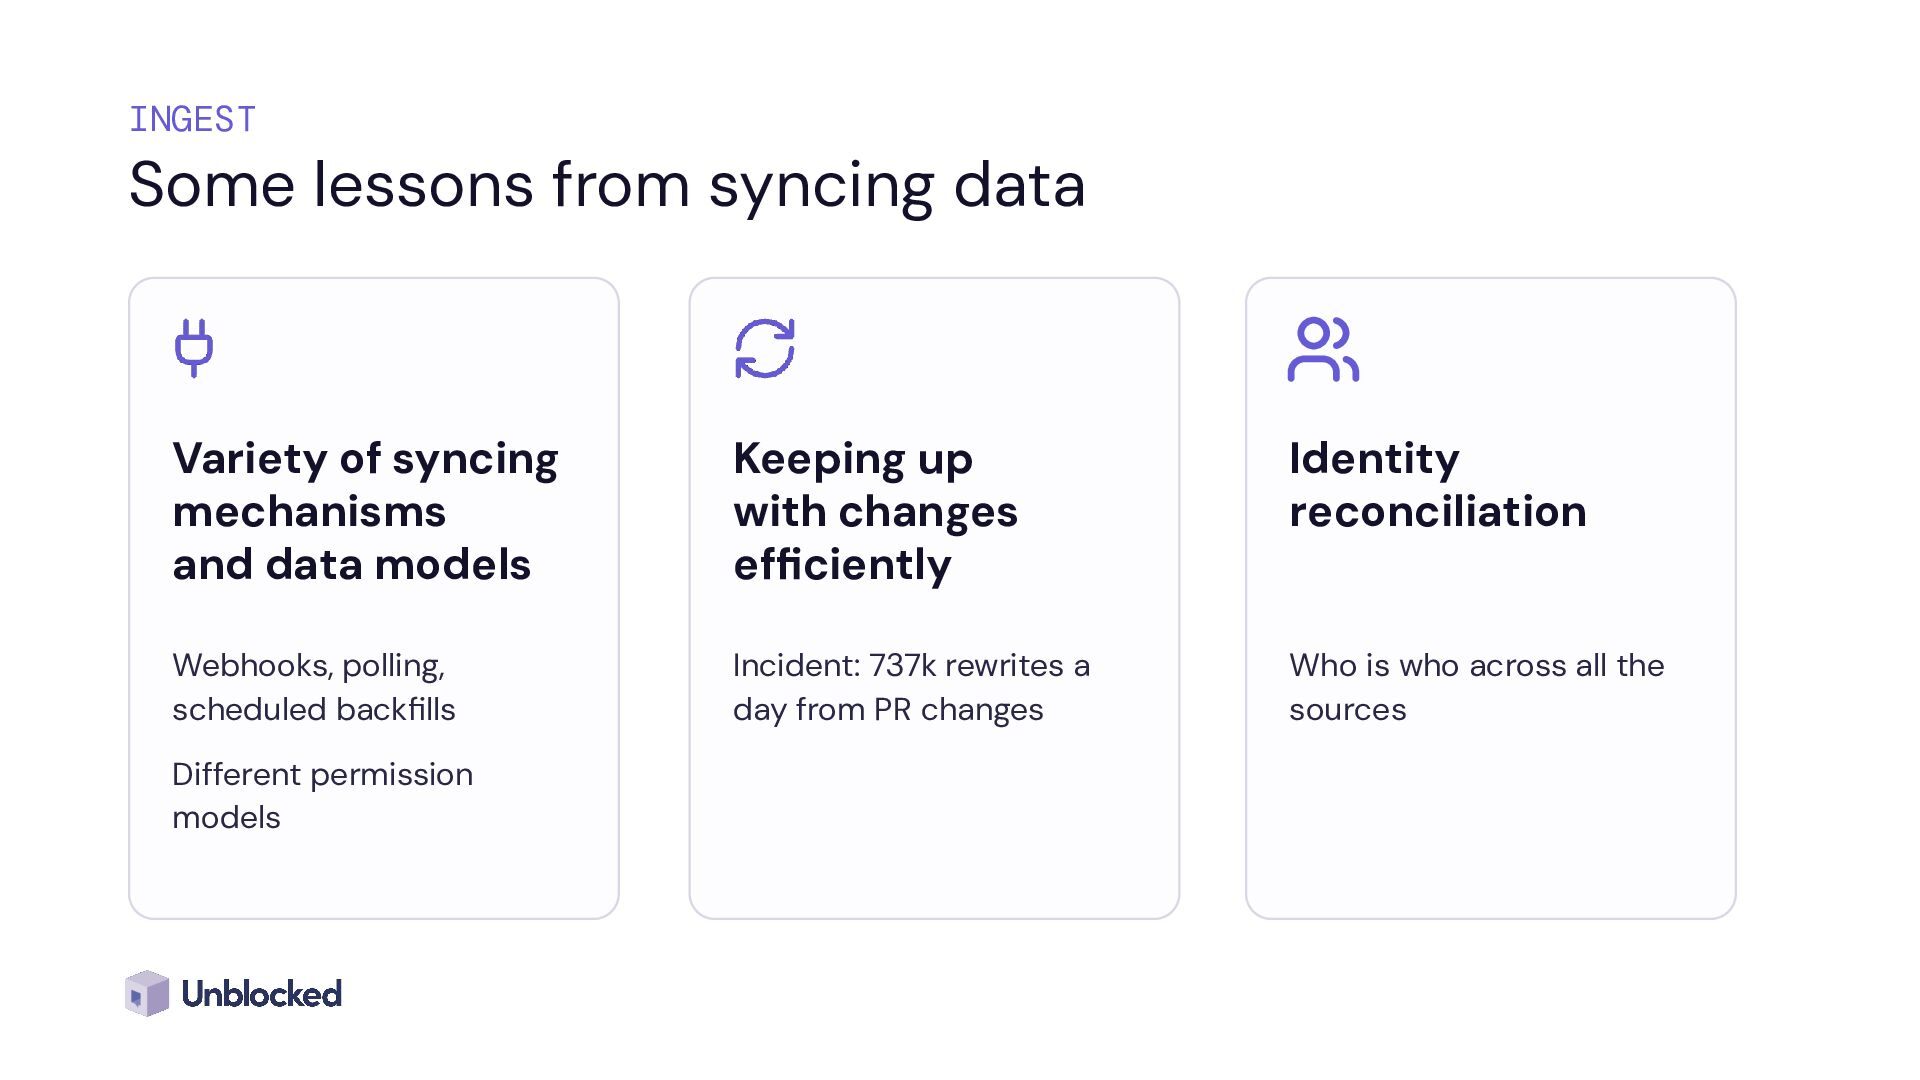
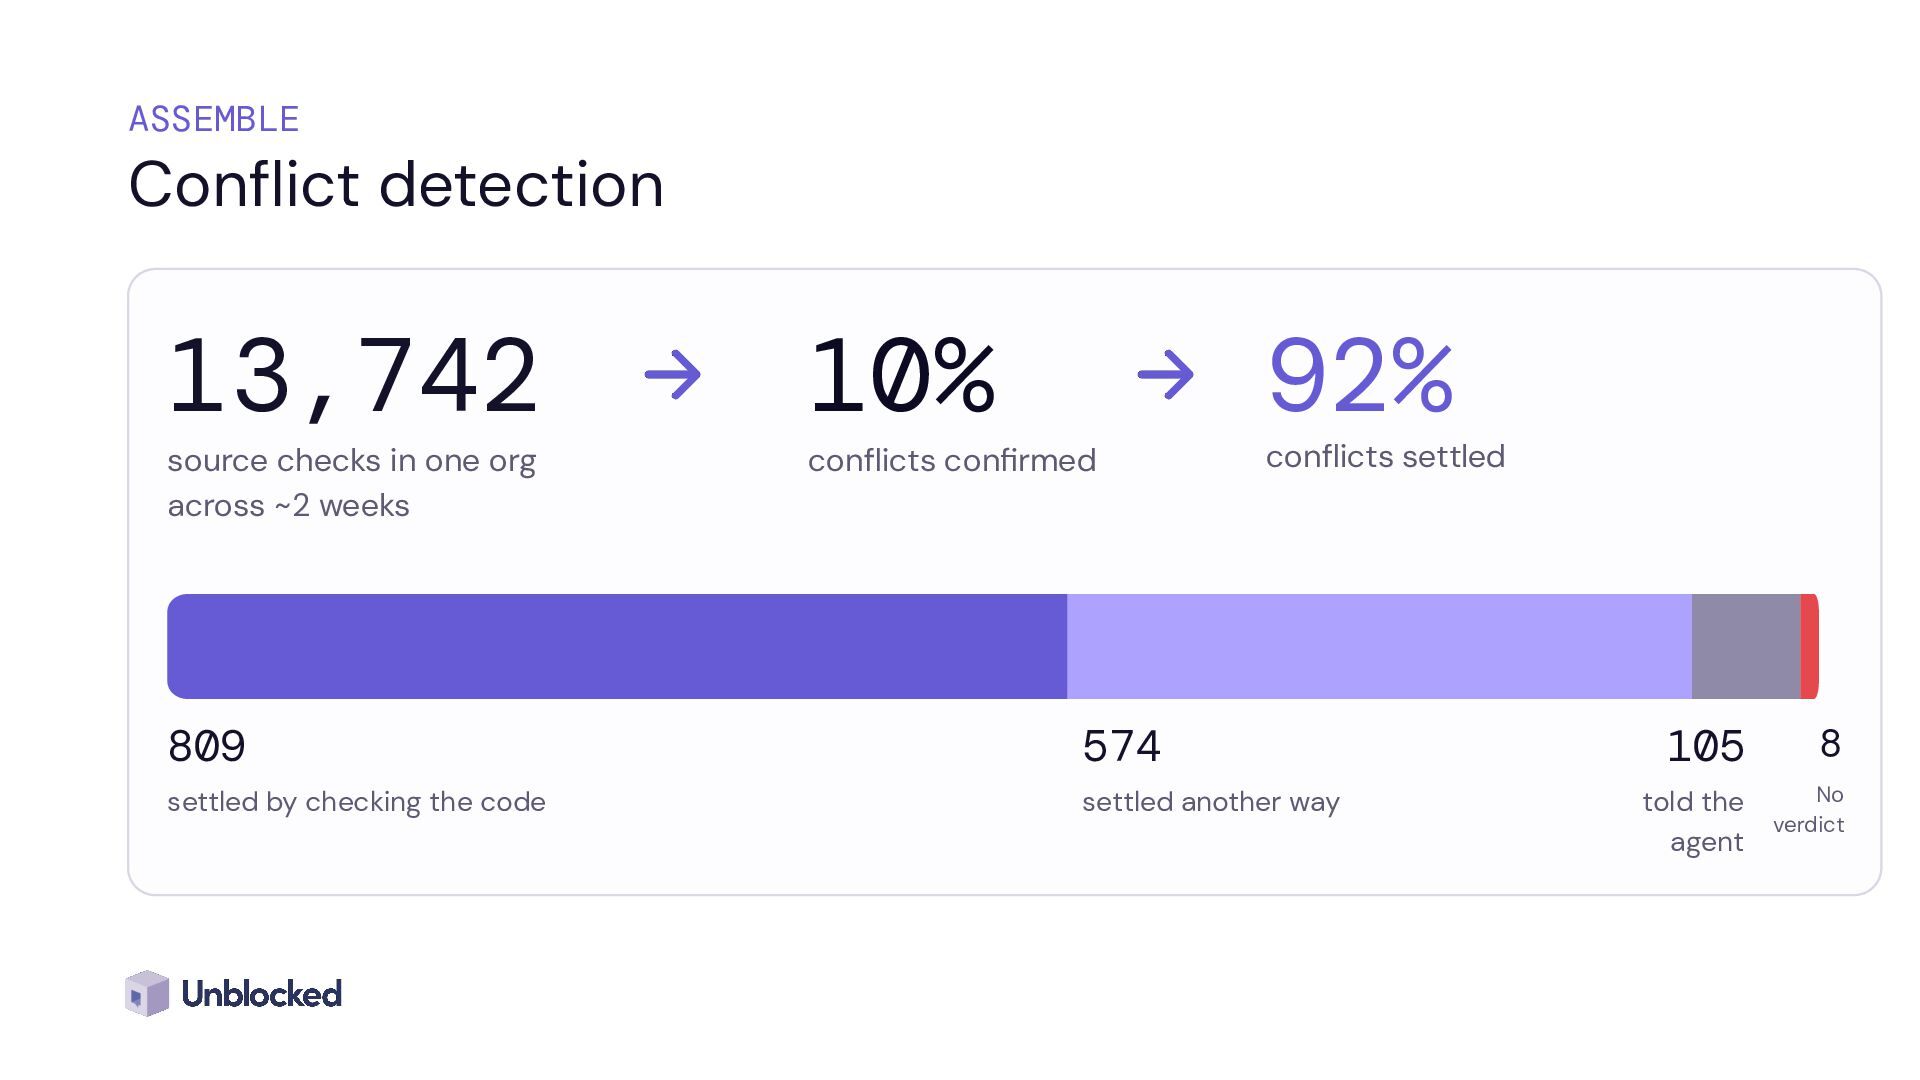
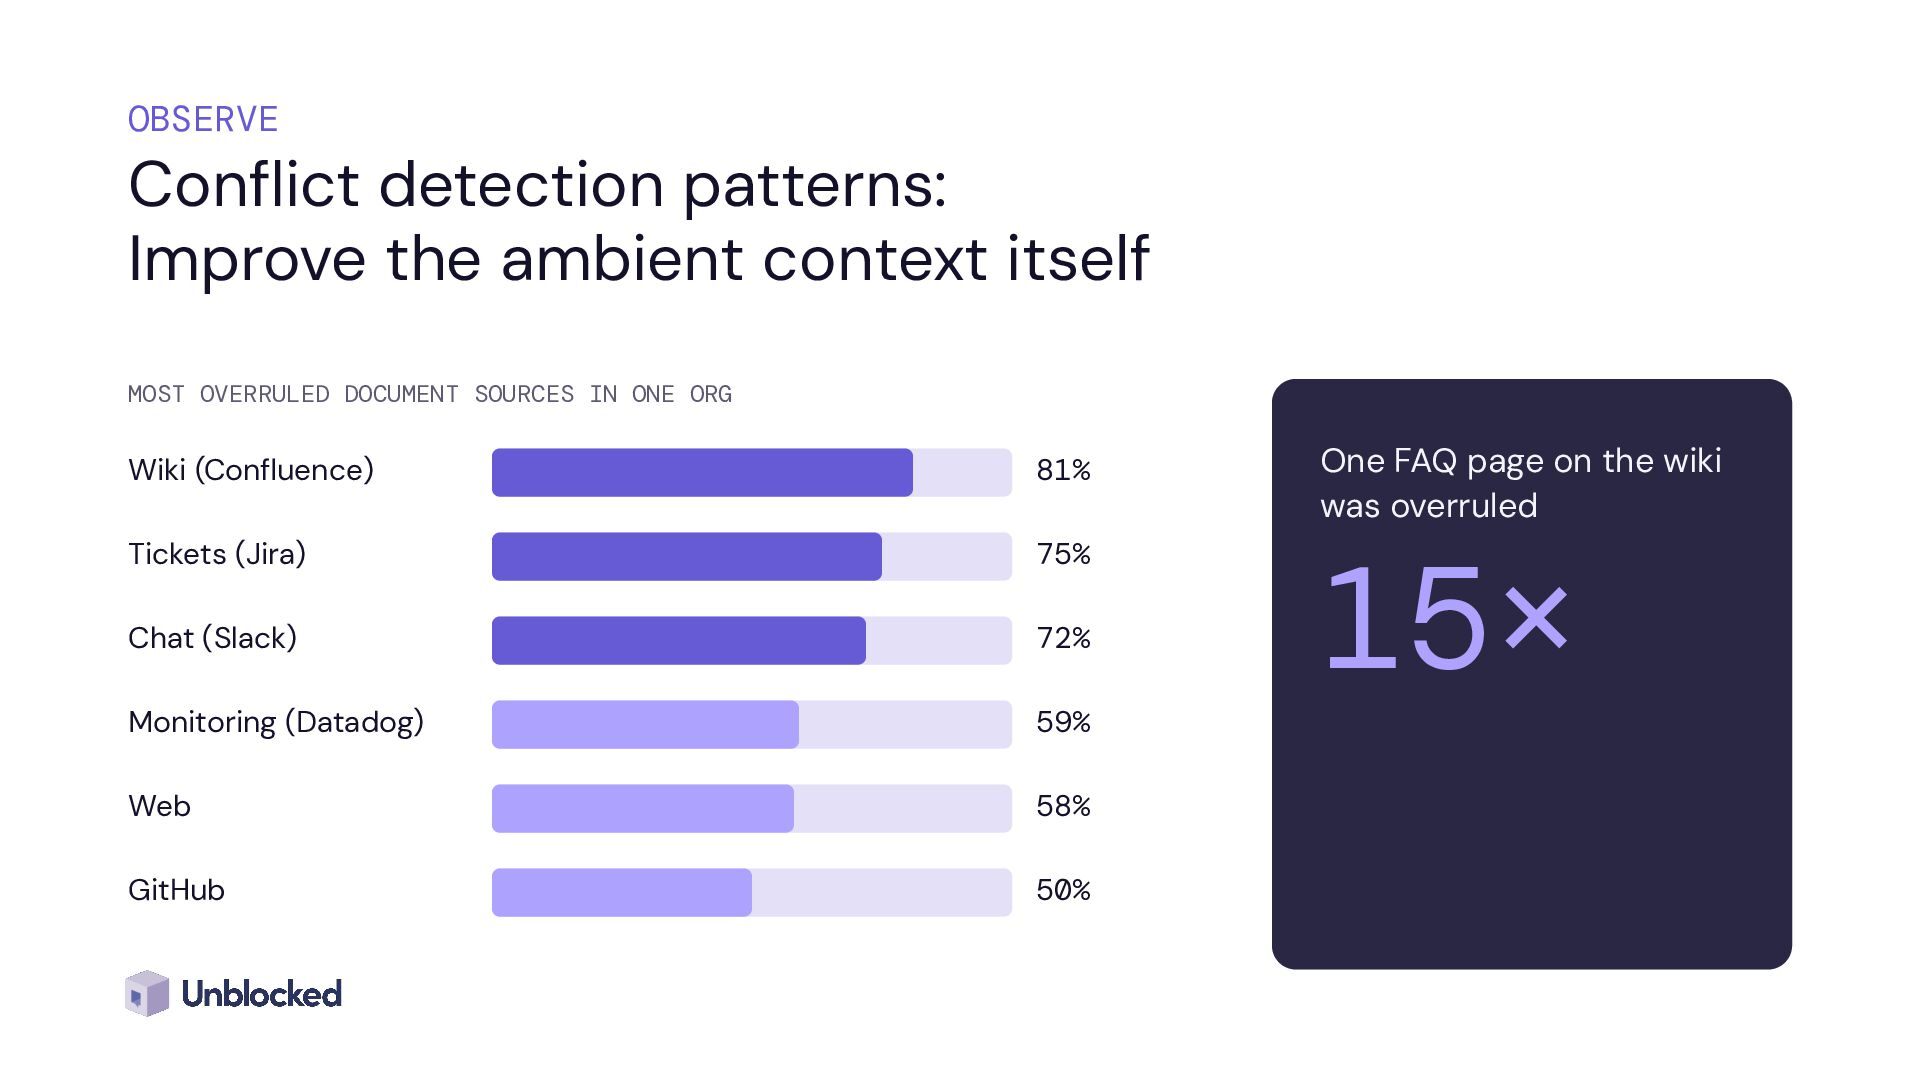
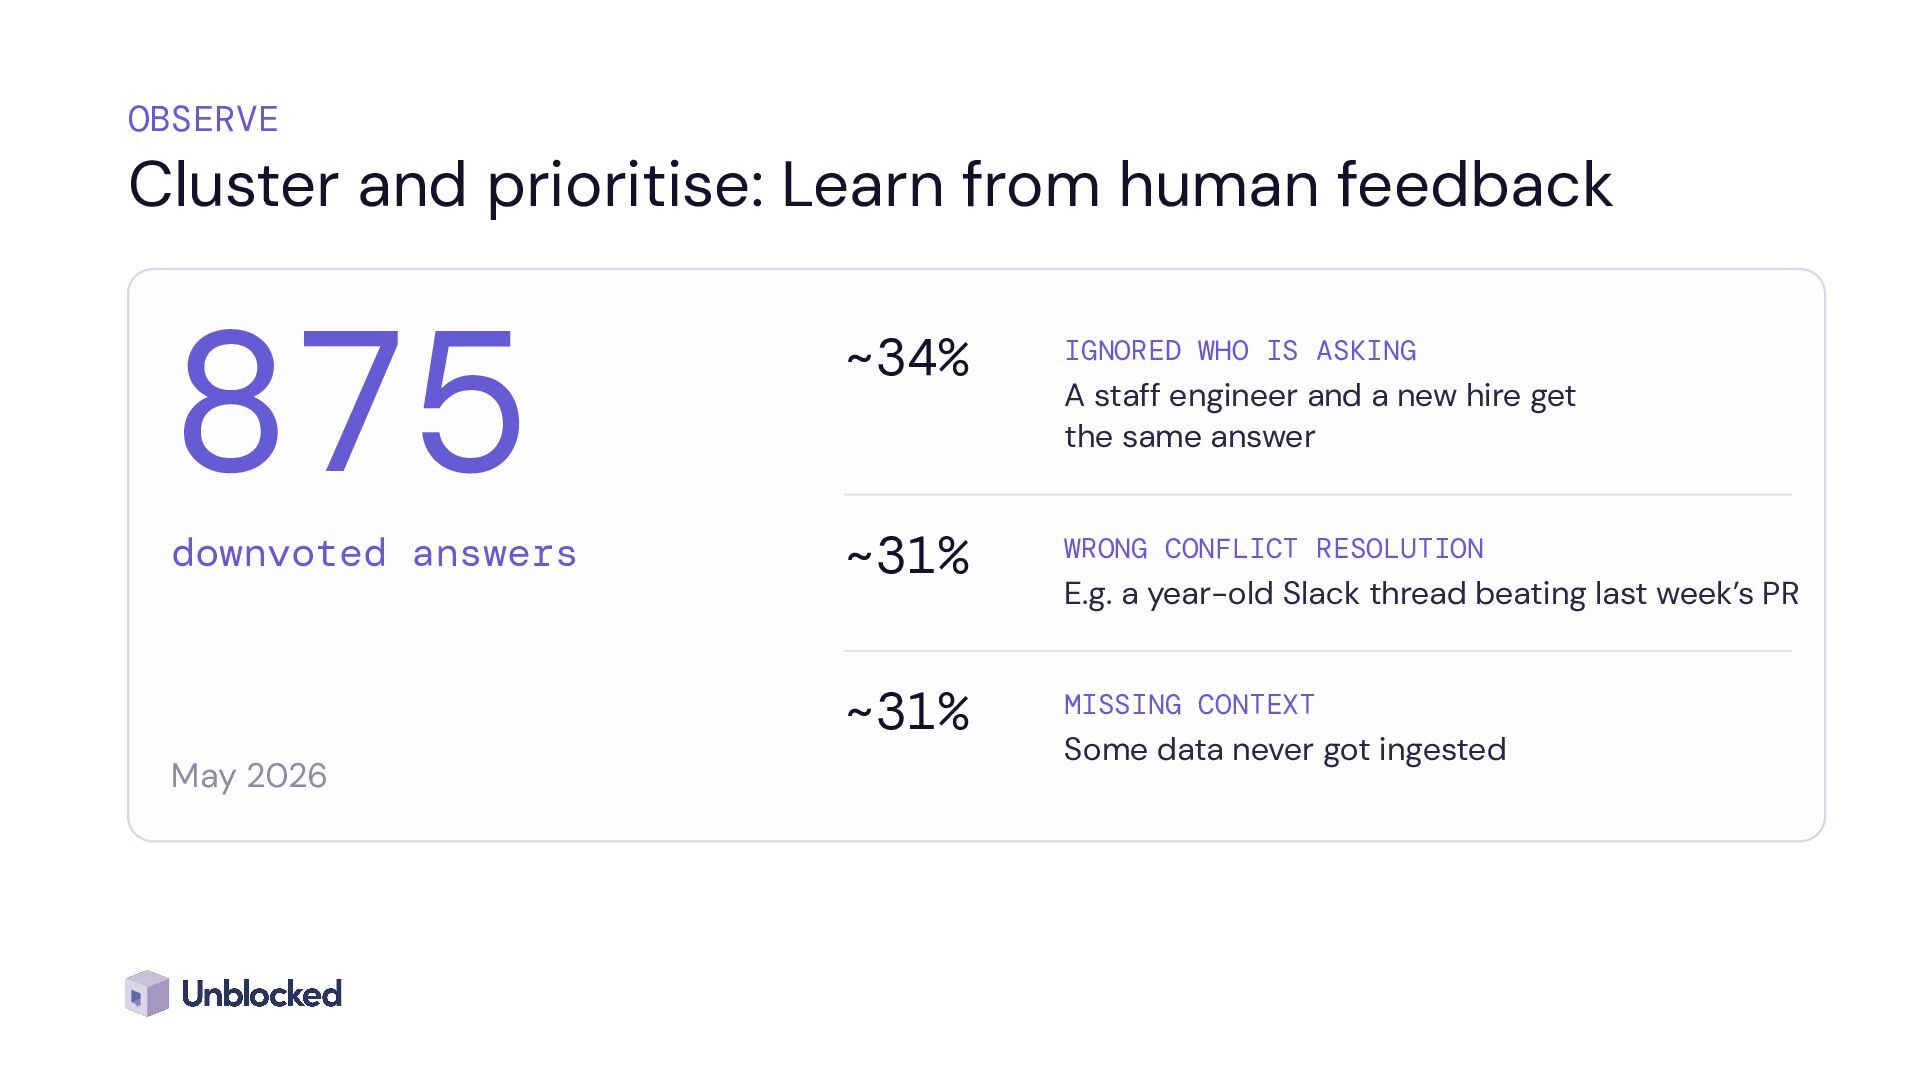
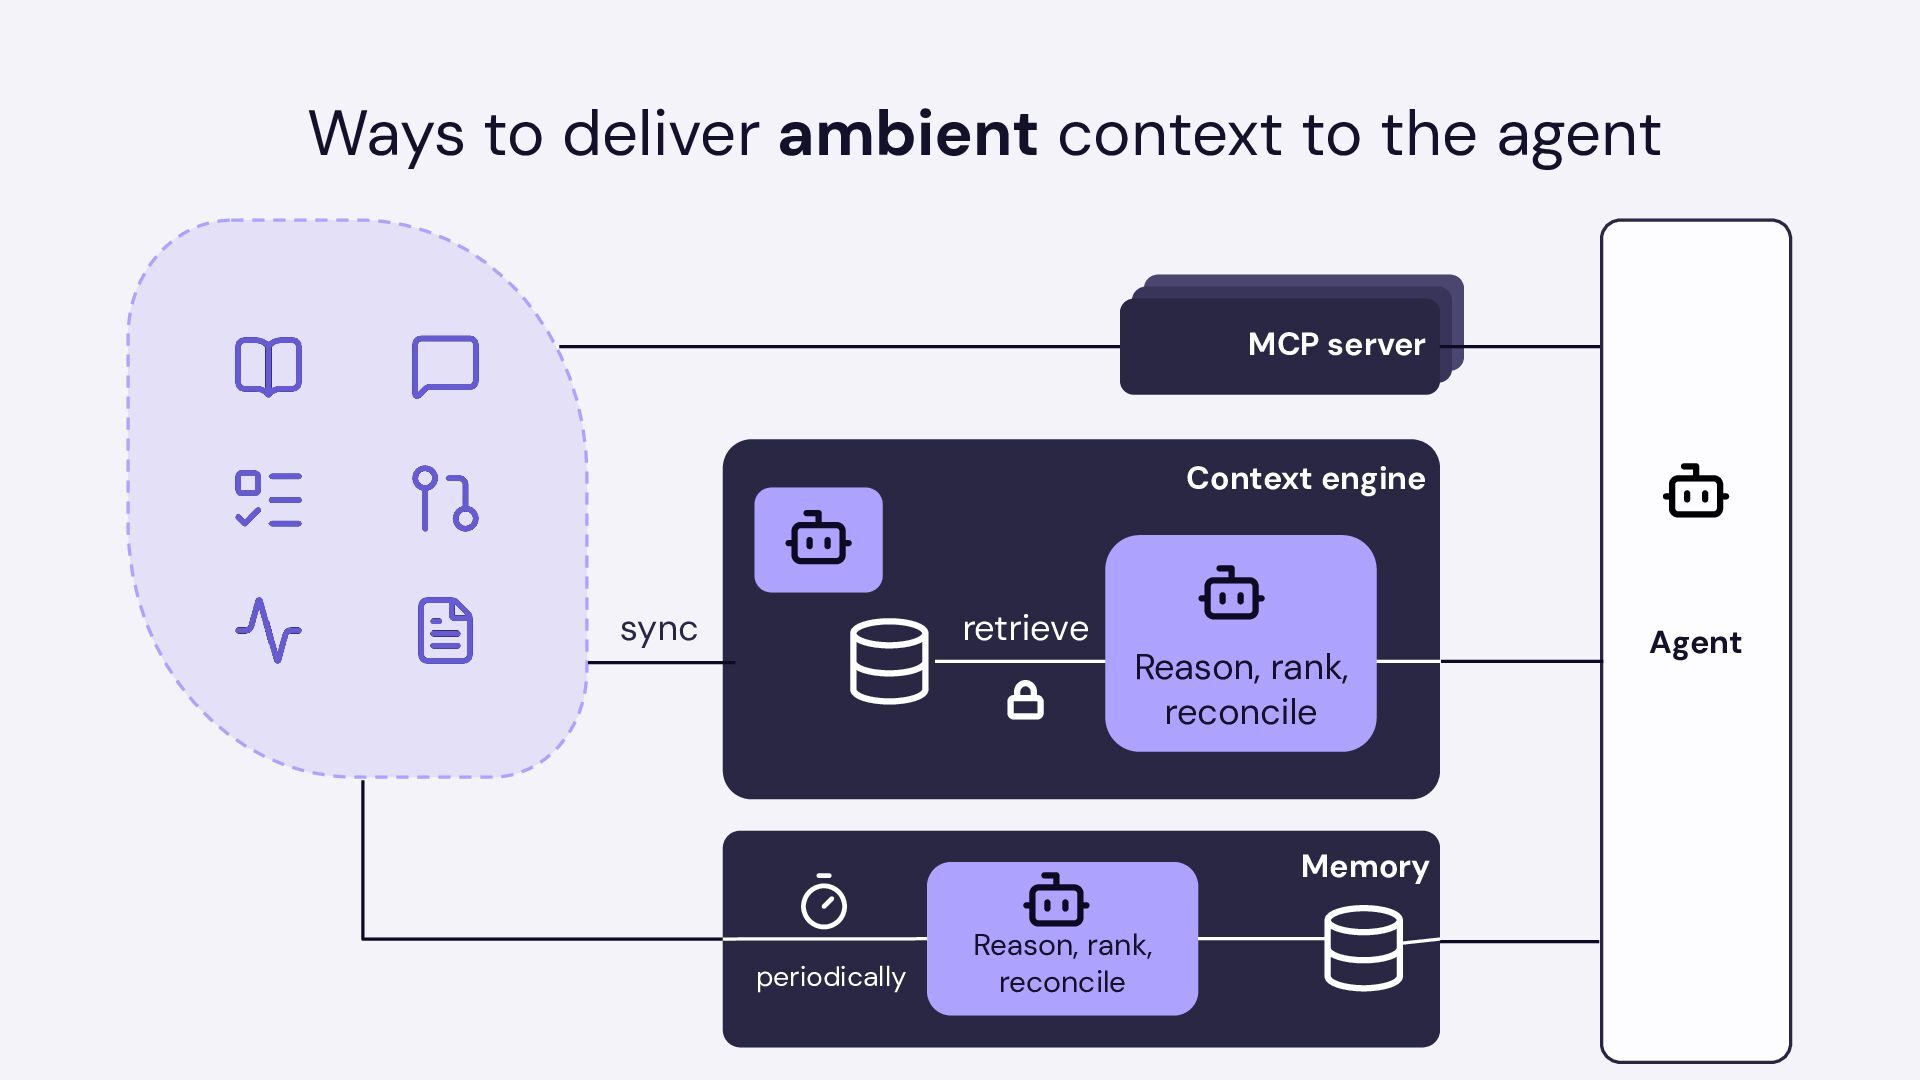
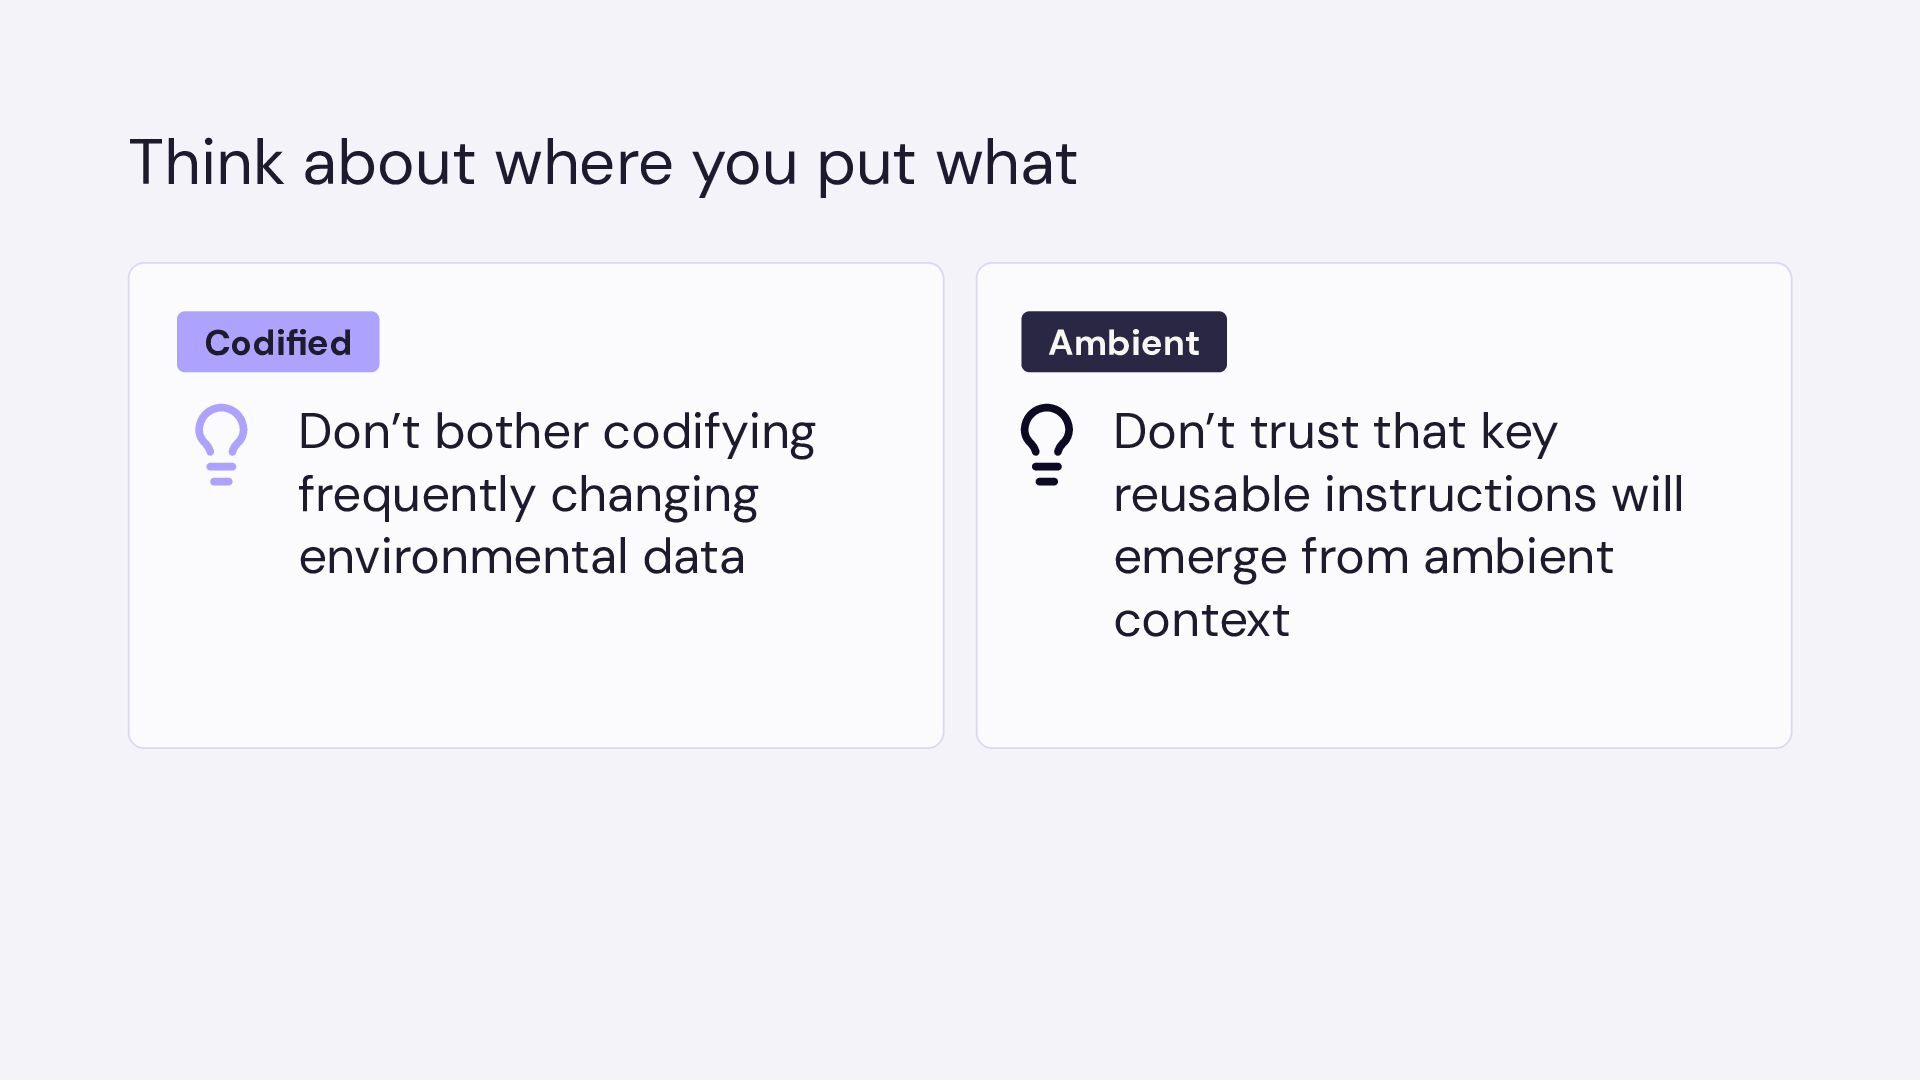
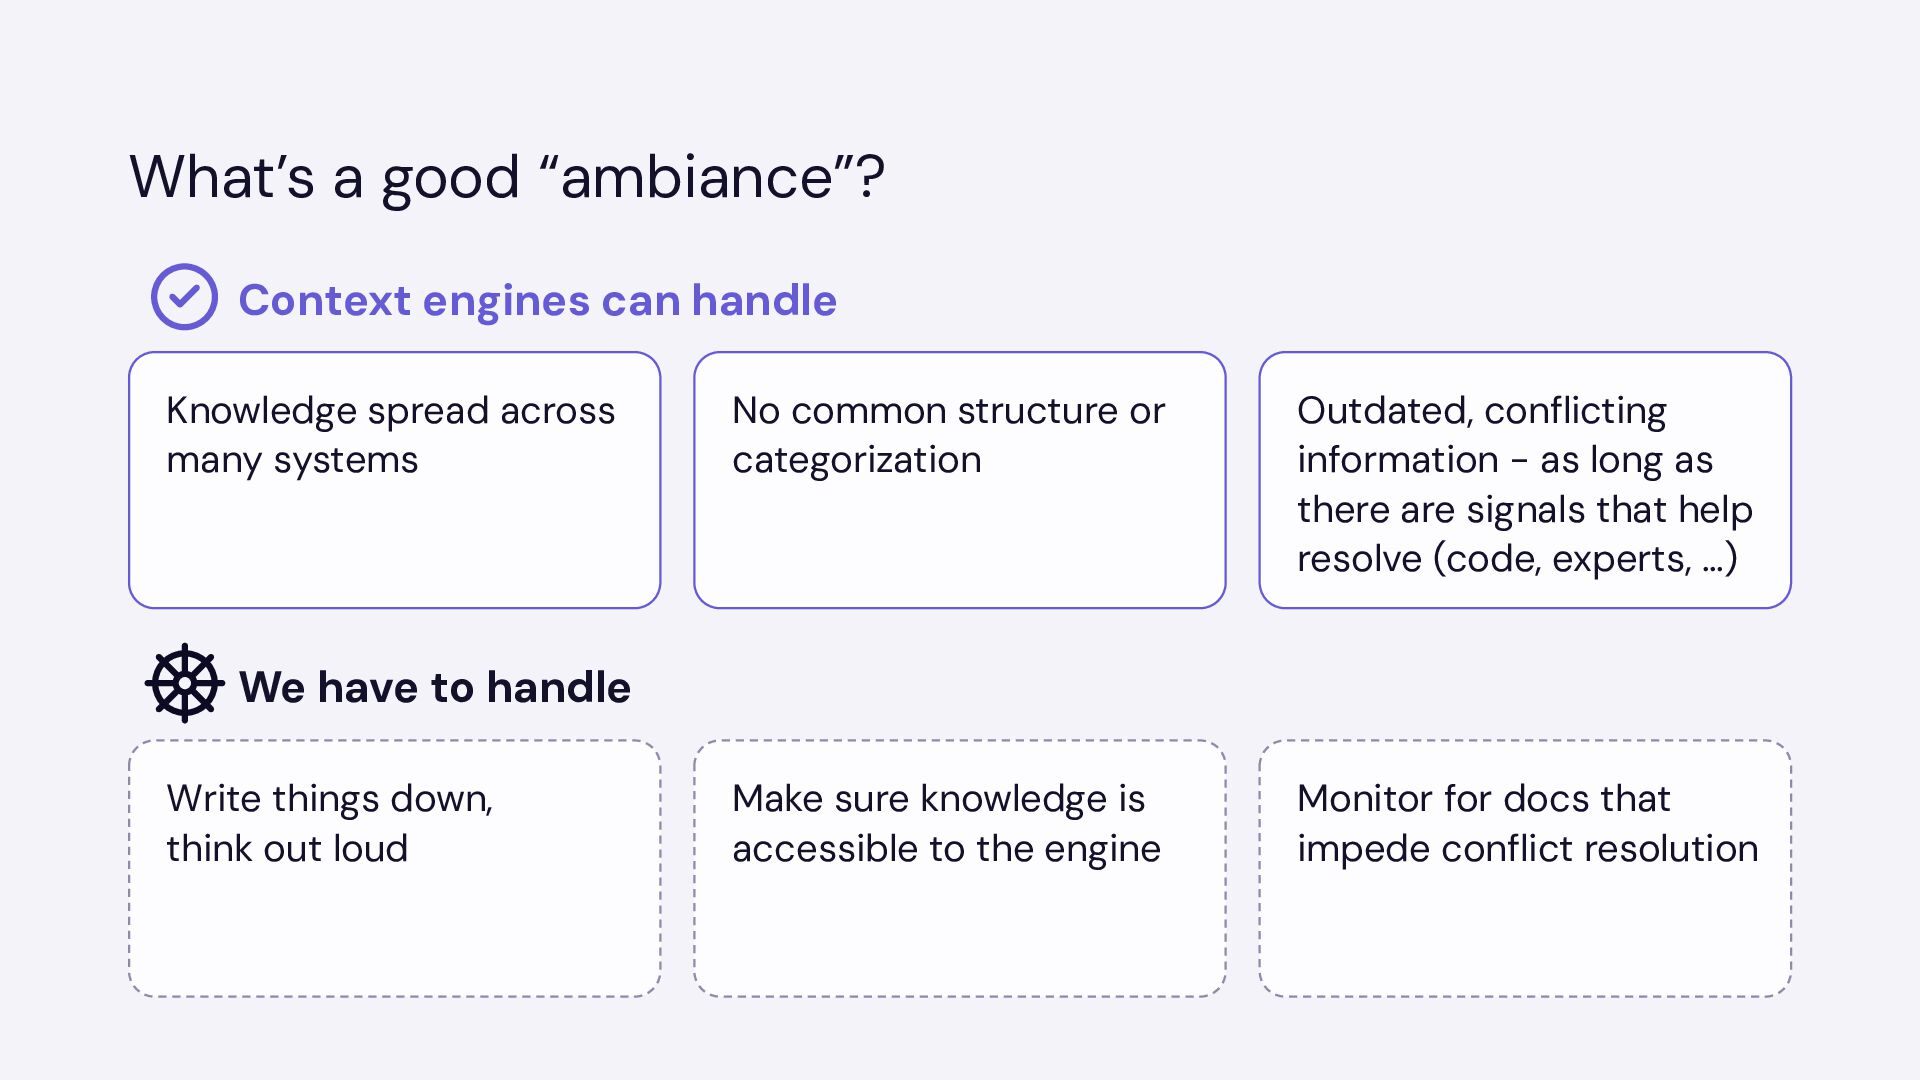
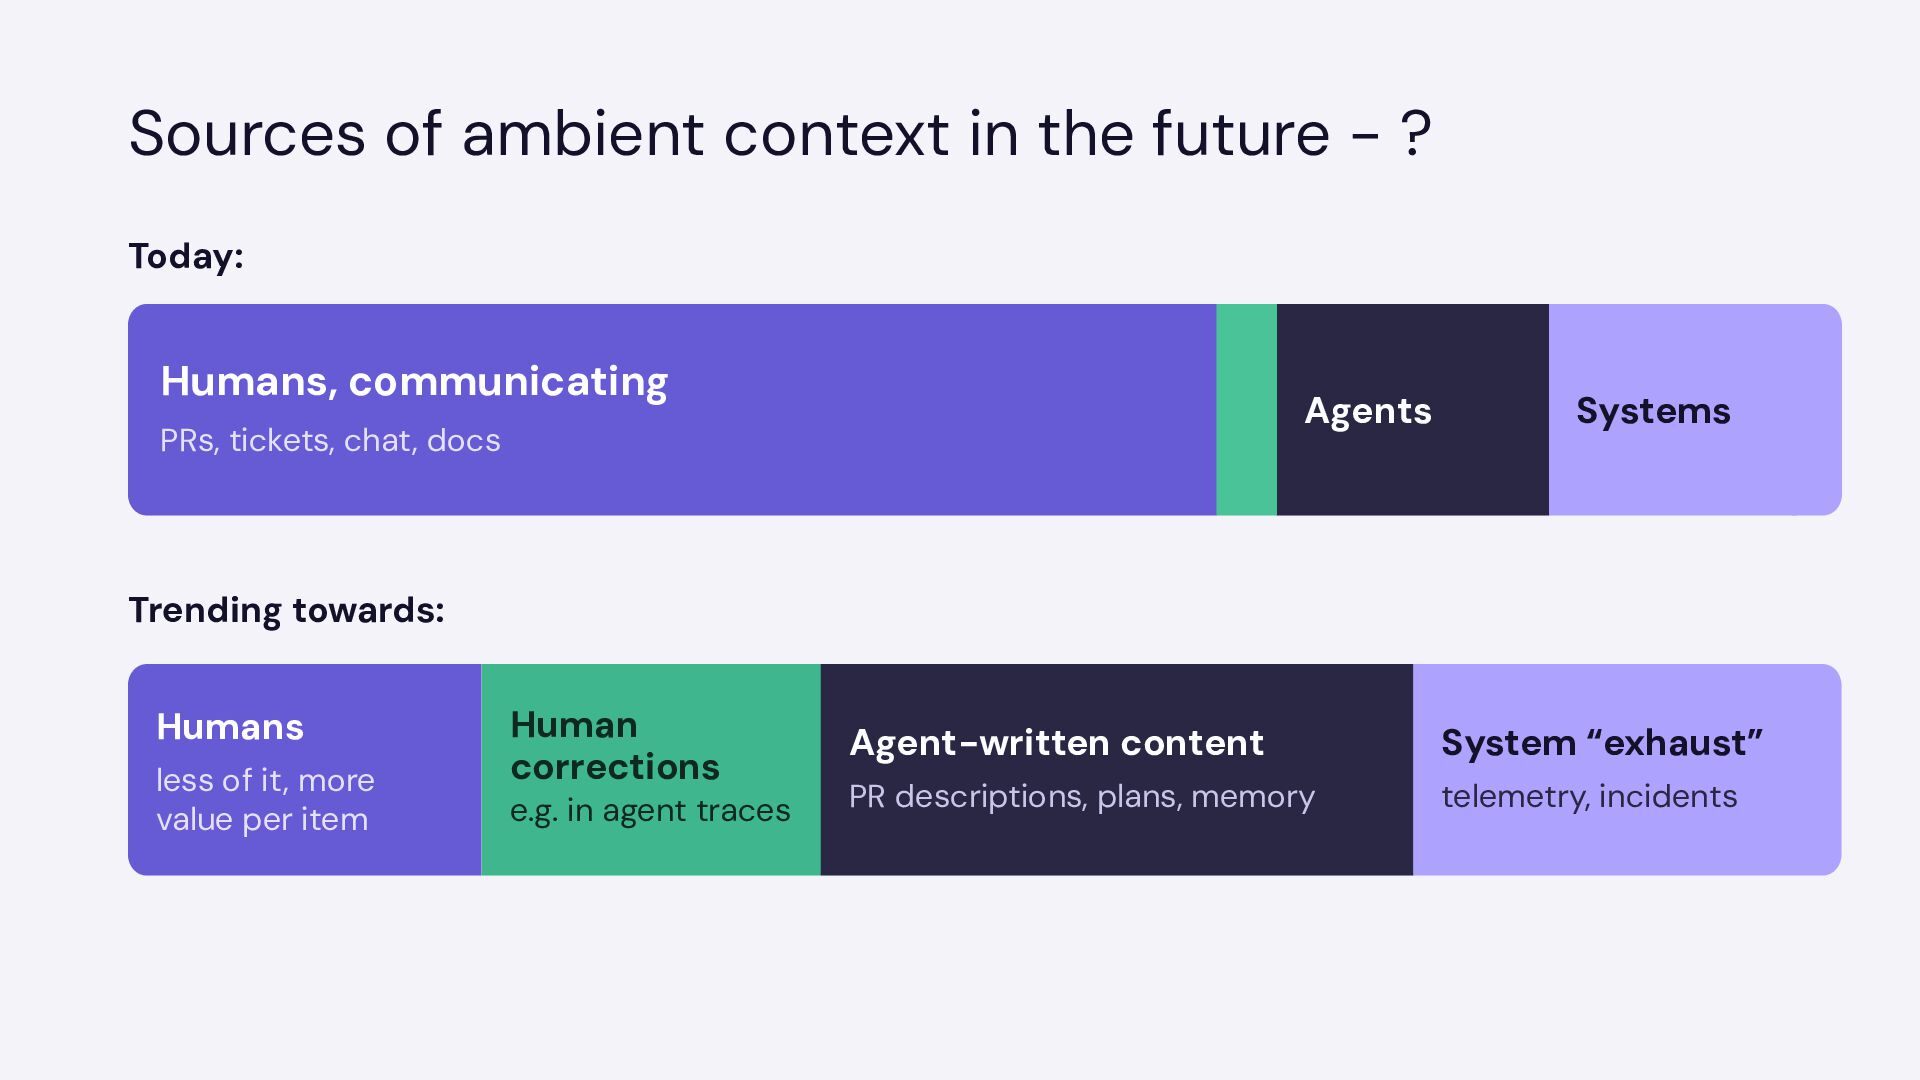
Workflow instructions, coding conventions, tickets, wiki pages, and observability data all end up in the same context window, and we call all of it "context." To the model, it's tokens shaping the next prediction. For the people who write, maintain, and rely on context, these tokens differ a lot in where they come from, how much authority they carry, and how they can go wrong. Some are deliberately authored and quality assured. Others emerge as a byproduct of work and are dynamically retrieved and reconciled from organizational systems.
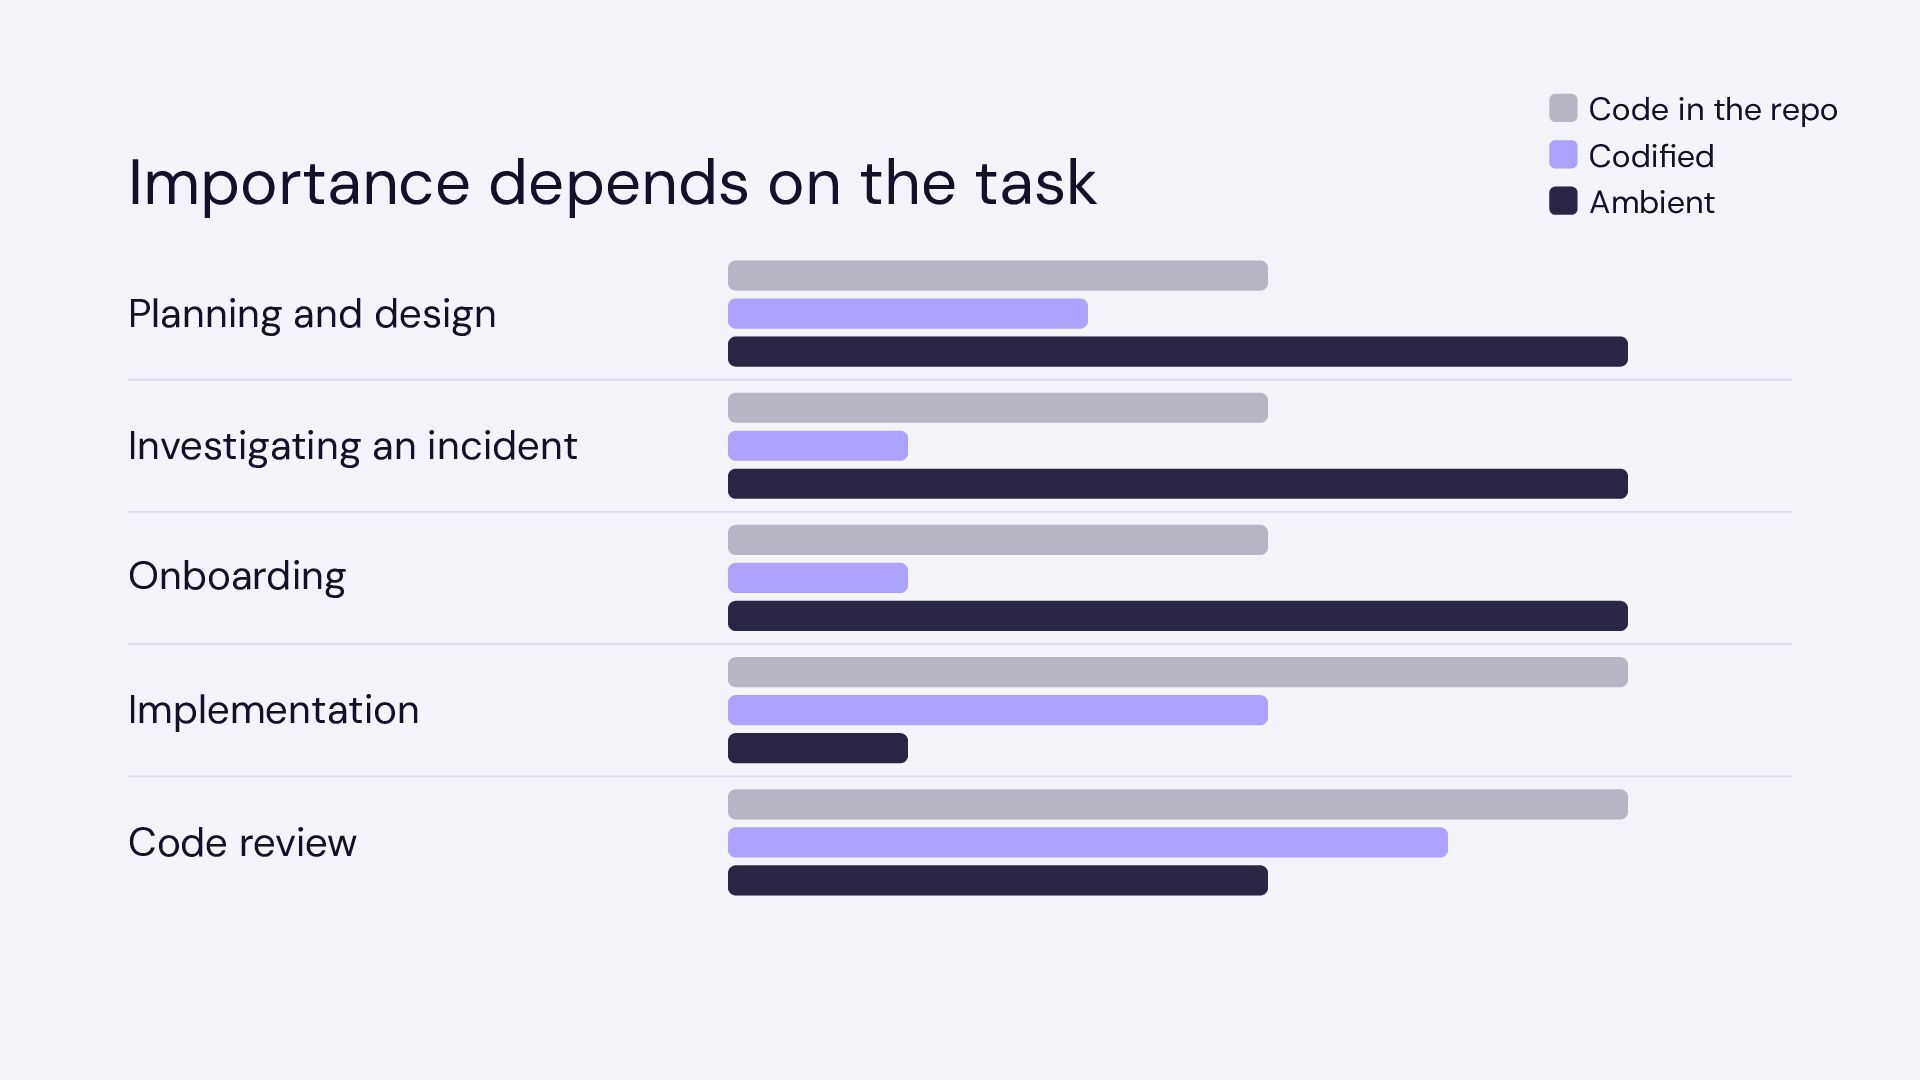
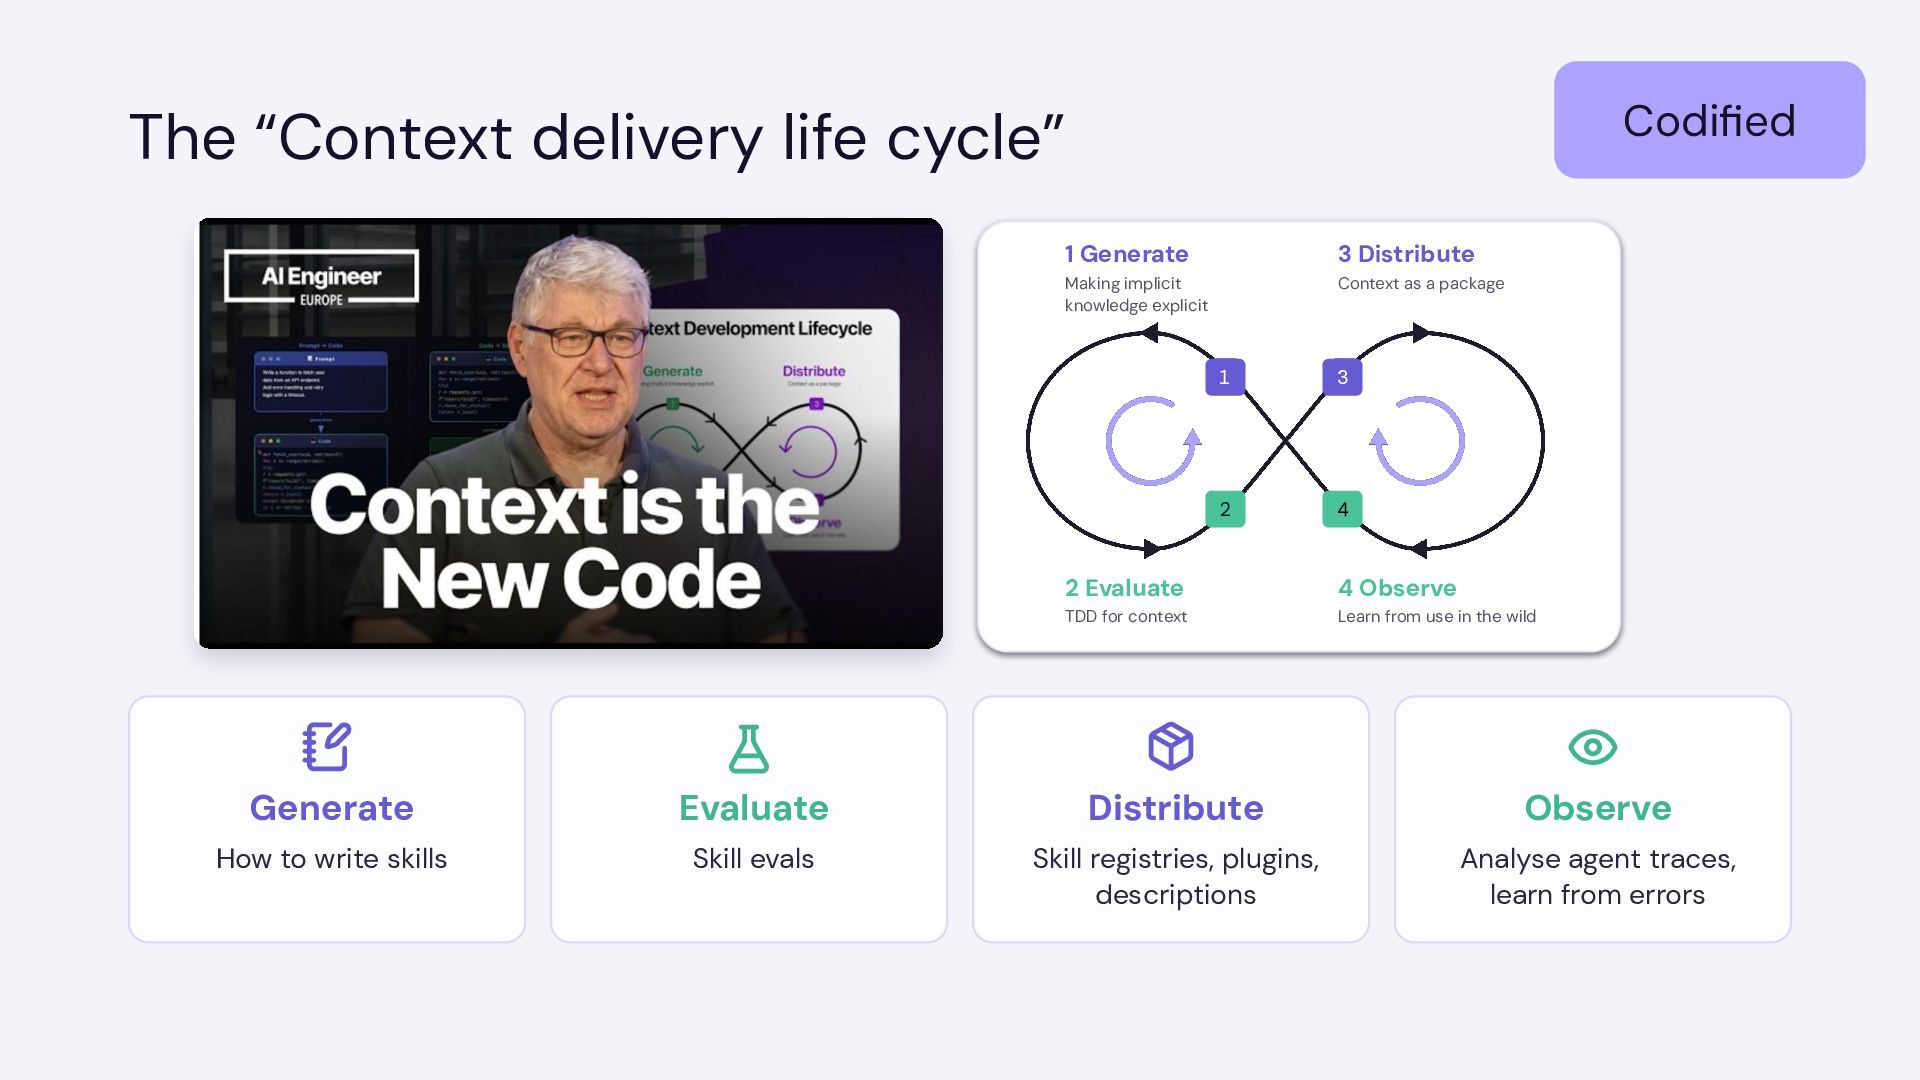
This talk discusses how these differences change the ways that each kind is created, checked, and delivered to the agent, and that treating them alike can lead to using unsuitable tools and processes. You will leave with a clearer idea of the types of context you have available for your coding agents, and the techniques to maintain and distribute them.


 birgitta410
 cdataj
 oidfj
 inariku
 keio_smilab
 optim
 yoshidashingo
 kintotechdev
 nealle
 muziyoshiz
 akuwano
 masu_mi
 kentosuzuki
 apolaine
 frankvandijk
 rasmusluckow
 bluesmoon
 bkeepers
 danielanewman
 cargoodrich
 takai
 jct
 letsgokoyo
 aleyda
 cassininazir