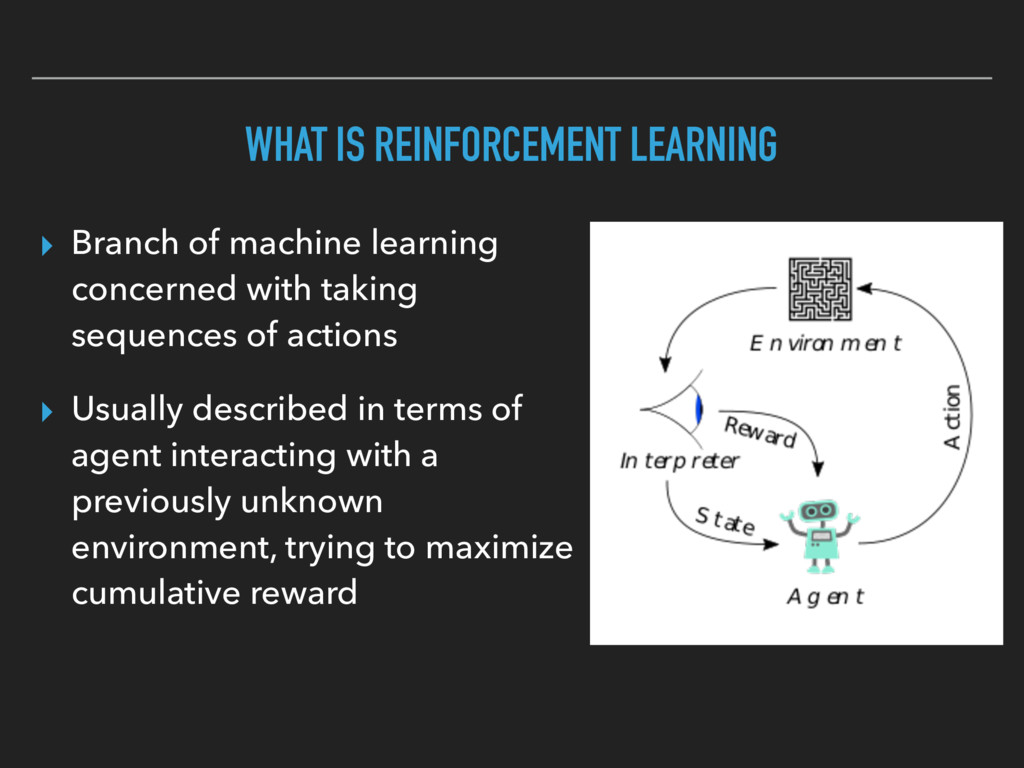
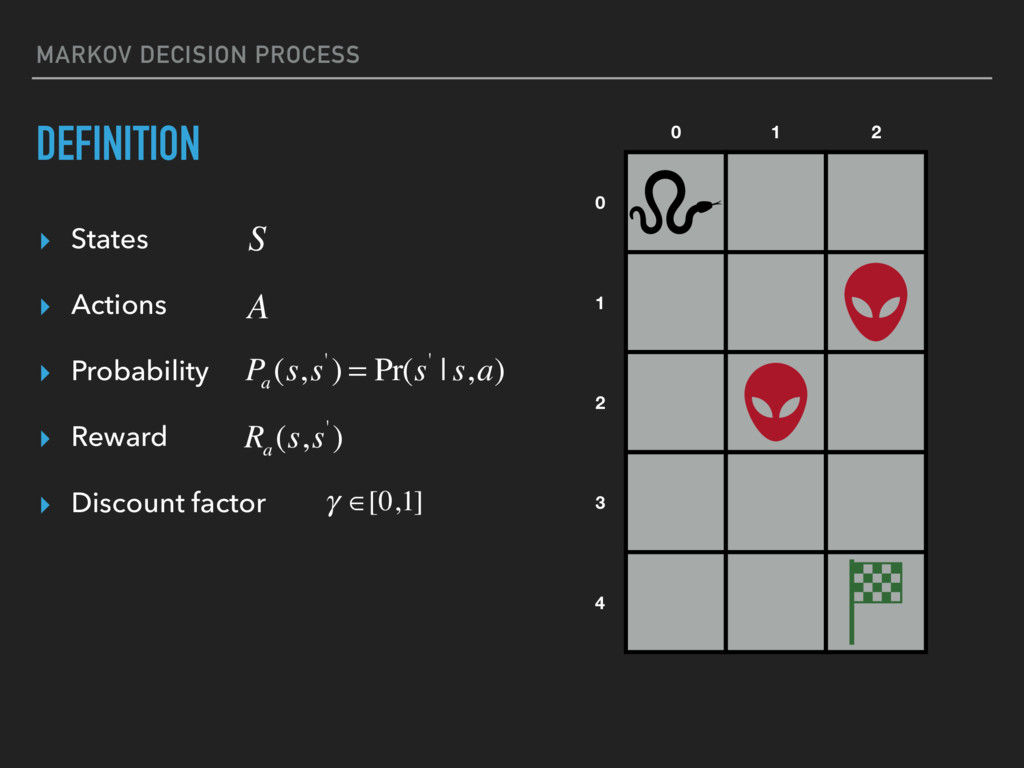
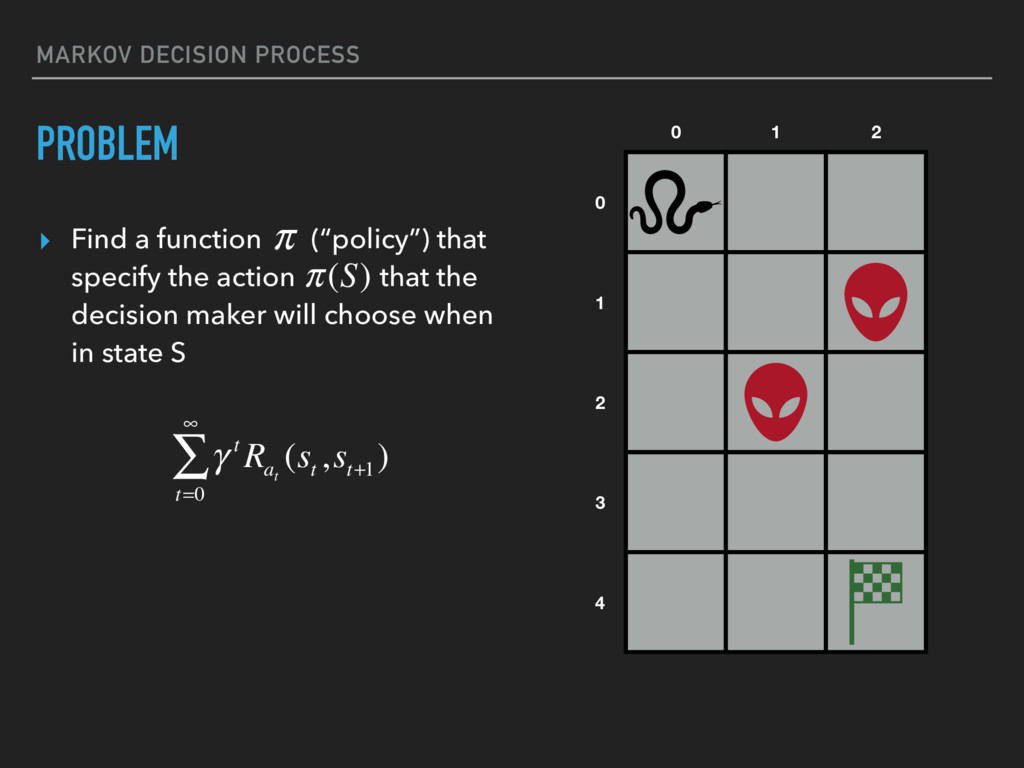
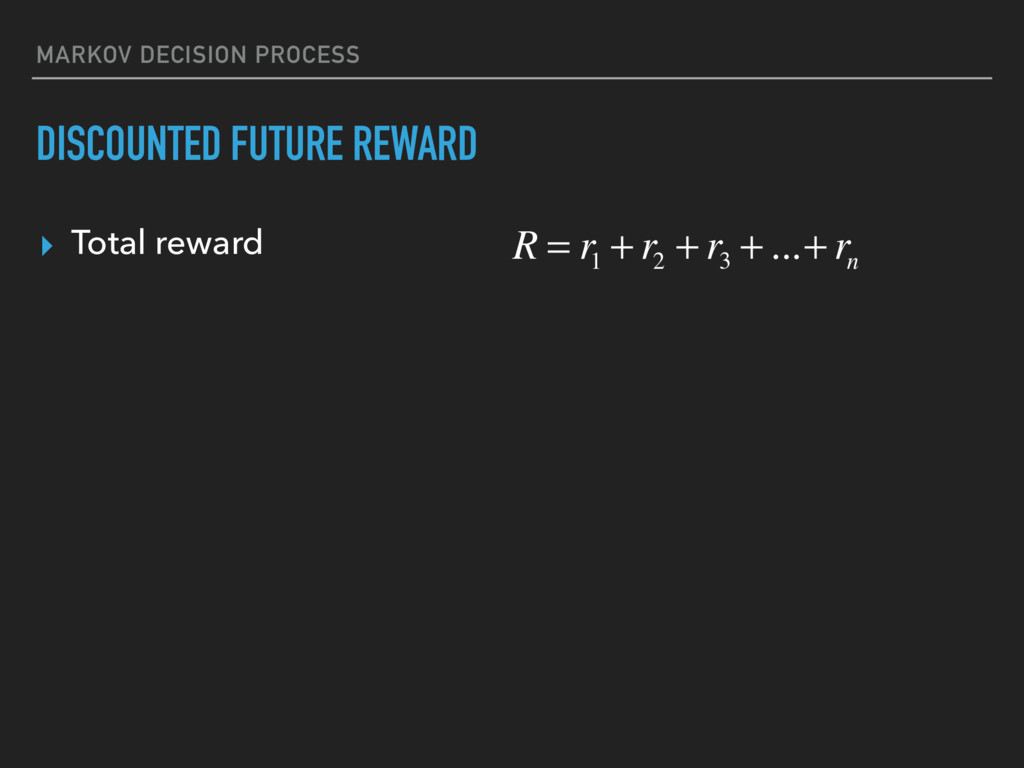
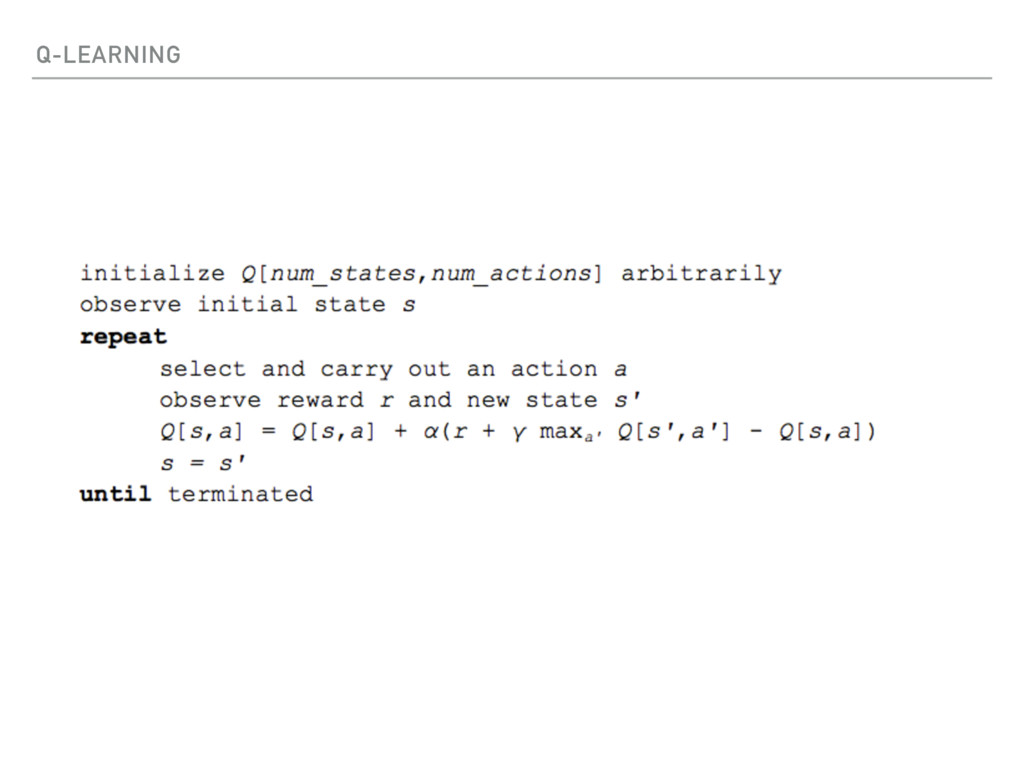
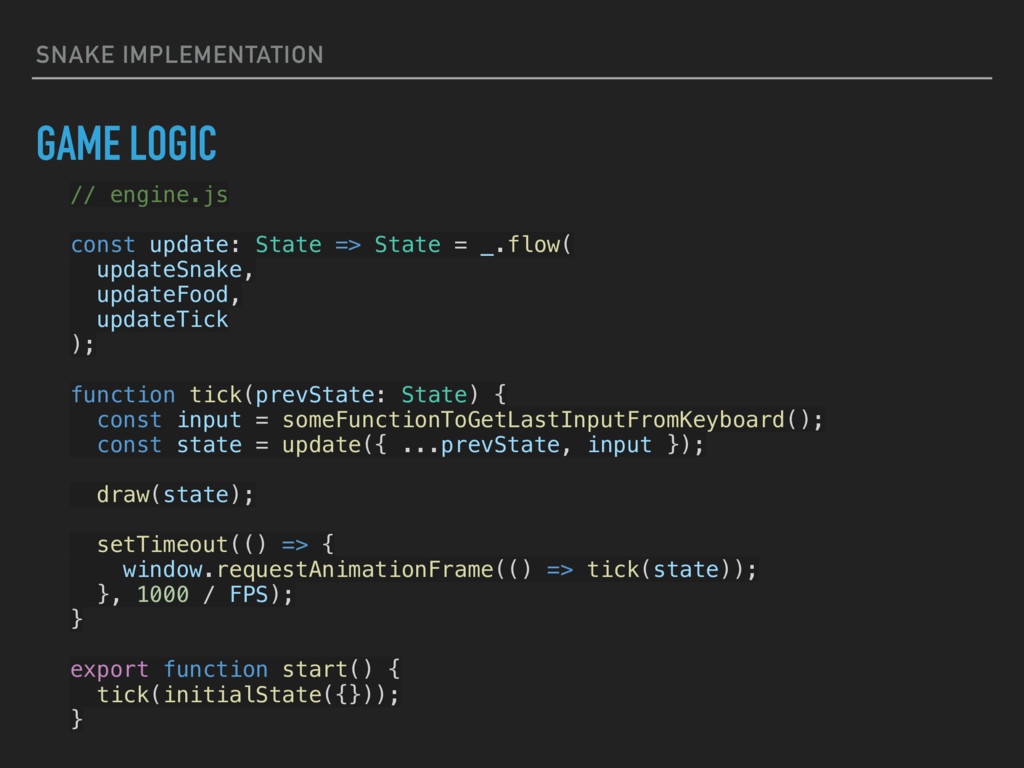
with taking sequences of actions ▸ Usually described in terms of agent interacting with a previously unknown environment, trying to maximize cumulative reward
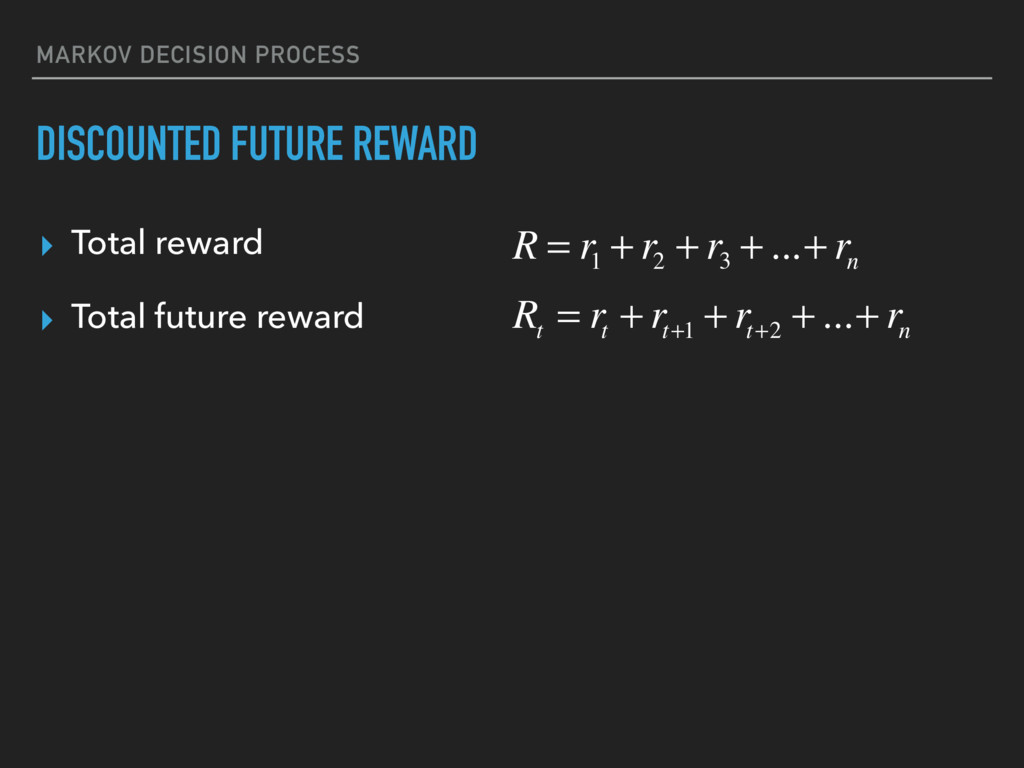
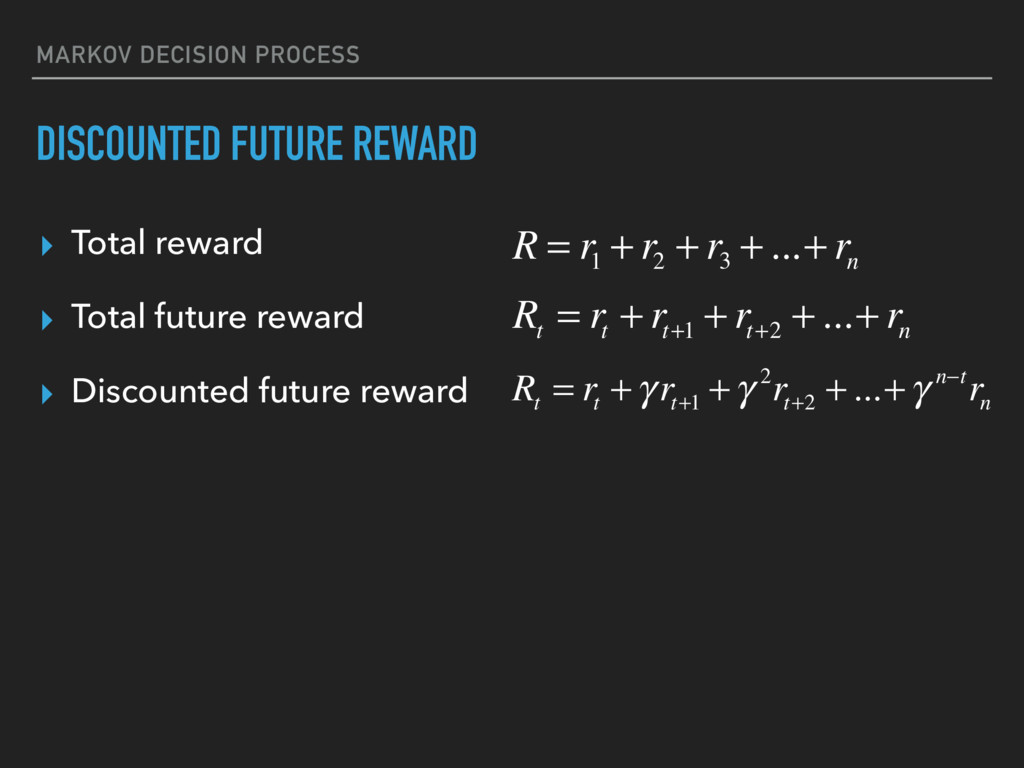
Total future reward ▸ Discounted future reward R t = r t +γ r t+1 +γ 2r t+2 +...+γ n−tr n R t = r t + r t+1 + r t+2 +...+ r n R = r 1 + r 2 + r 3 +...+ r n
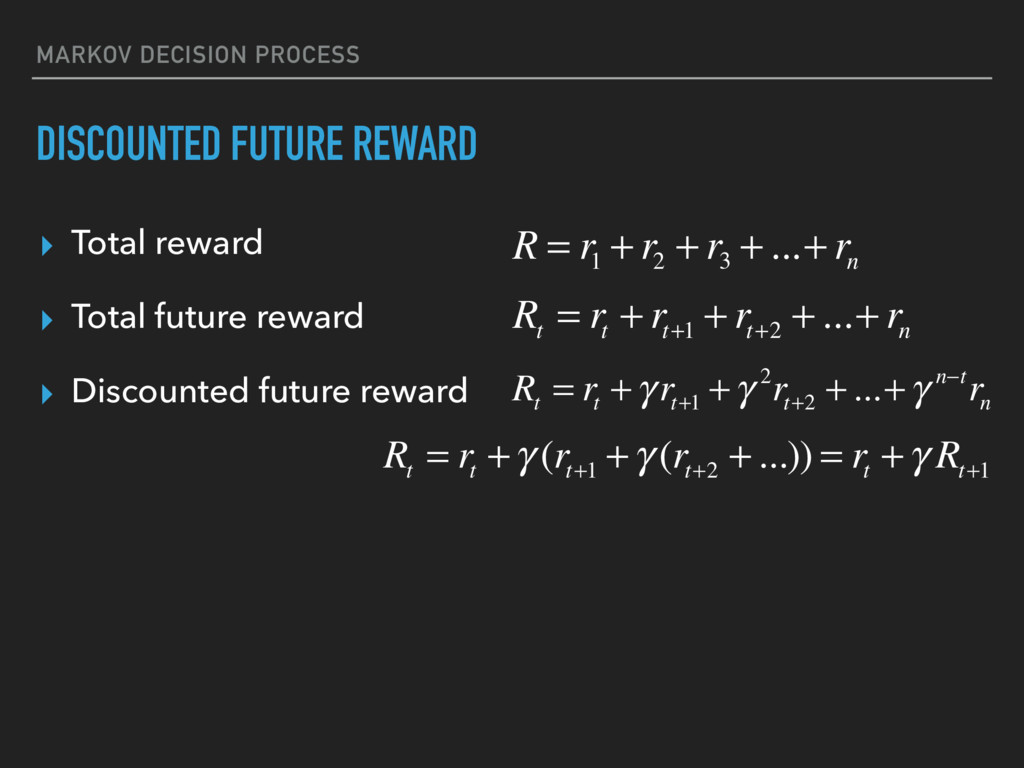
Total future reward ▸ Discounted future reward R t = r t +γ (r t+1 +γ (r t+2 + ...)) = r t +γ R t+1 R t = r t +γ r t+1 +γ 2r t+2 +...+γ n−tr n R t = r t + r t+1 + r t+2 +...+ r n R = r 1 + r 2 + r 3 +...+ r n
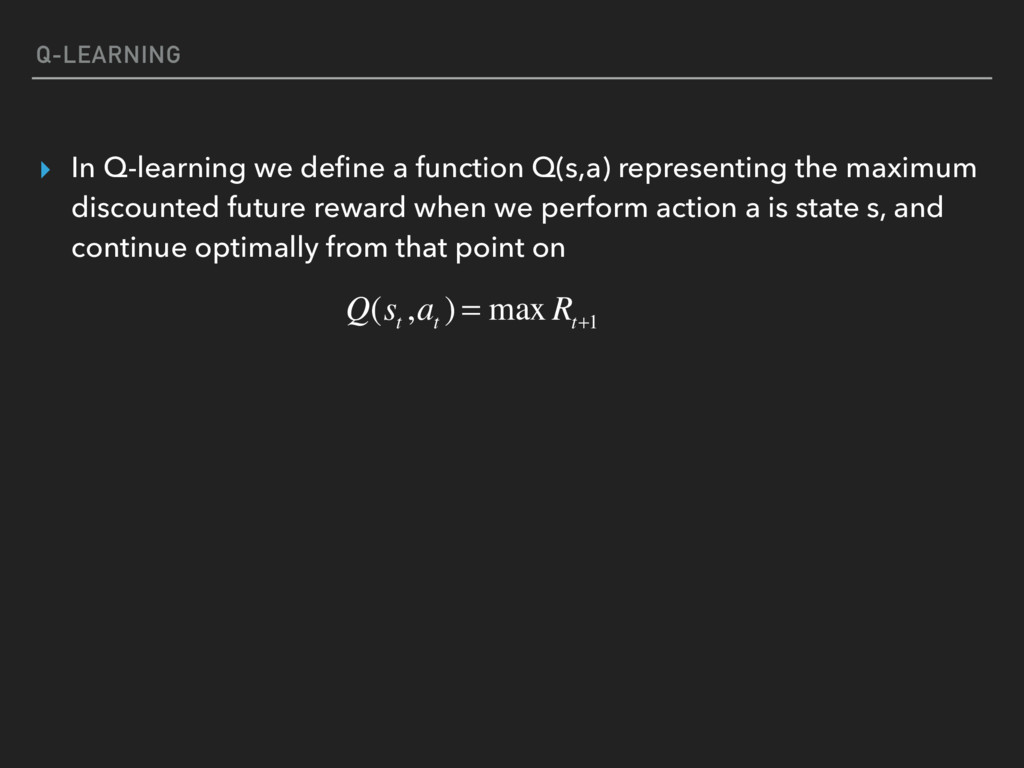
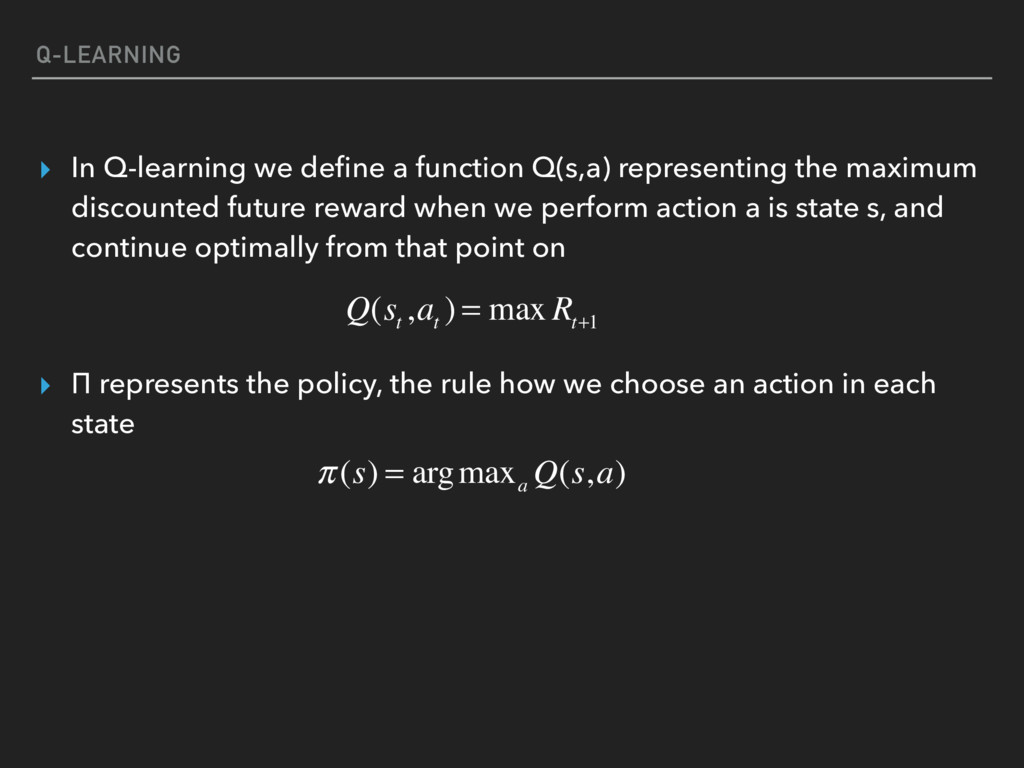
the maximum discounted future reward when we perform action a is state s, and continue optimally from that point on ▸ П represents the policy, the rule how we choose an action in each state Q(s t ,a t ) = max R t+1 π(s) = argmax a Q(s,a)
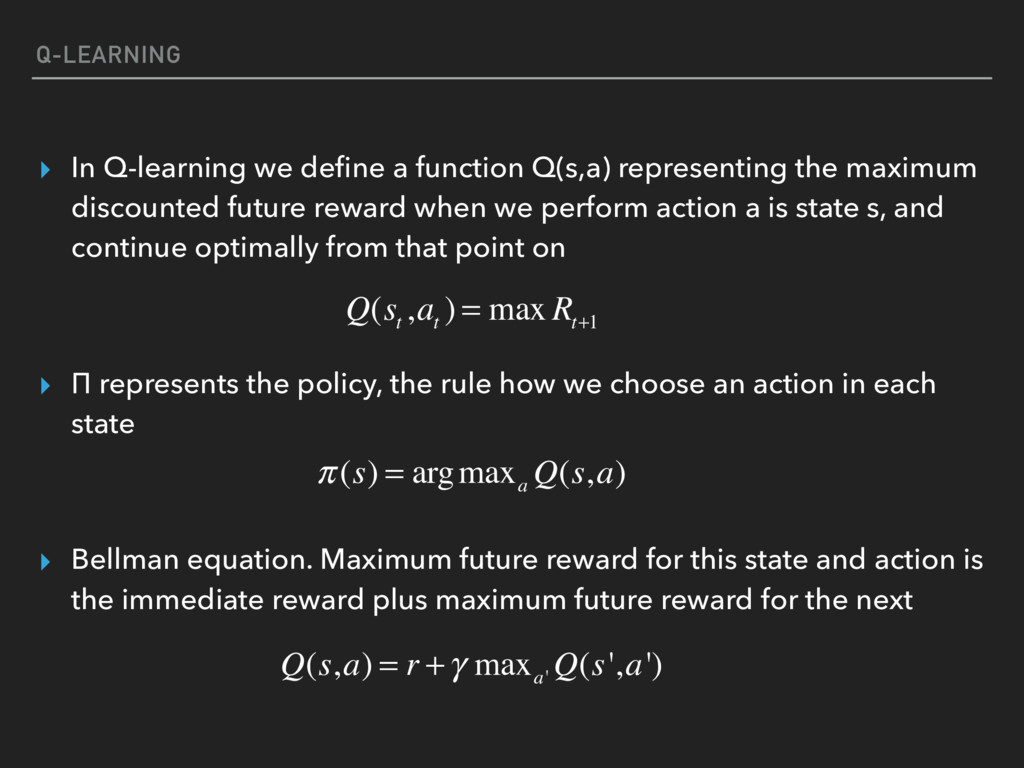
the maximum discounted future reward when we perform action a is state s, and continue optimally from that point on ▸ П represents the policy, the rule how we choose an action in each state ▸ Bellman equation. Maximum future reward for this state and action is the immediate reward plus maximum future reward for the next Q(s t ,a t ) = max R t+1 π(s) = argmax a Q(s,a) Q(s,a) = r +γ max a' Q(s',a')
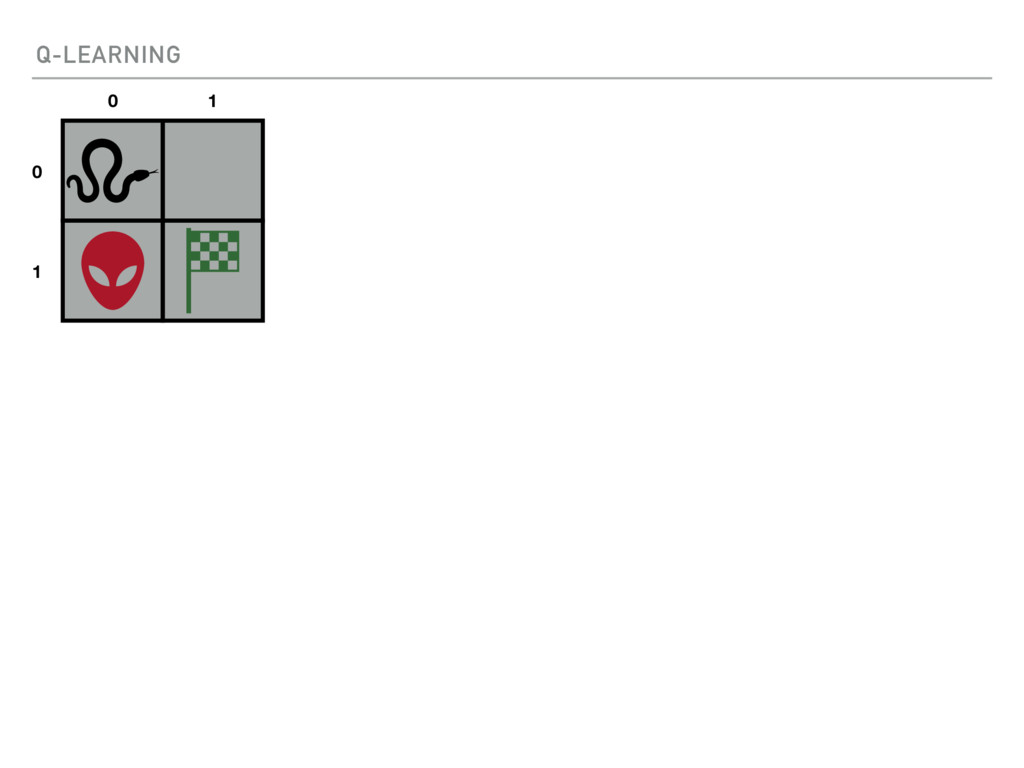
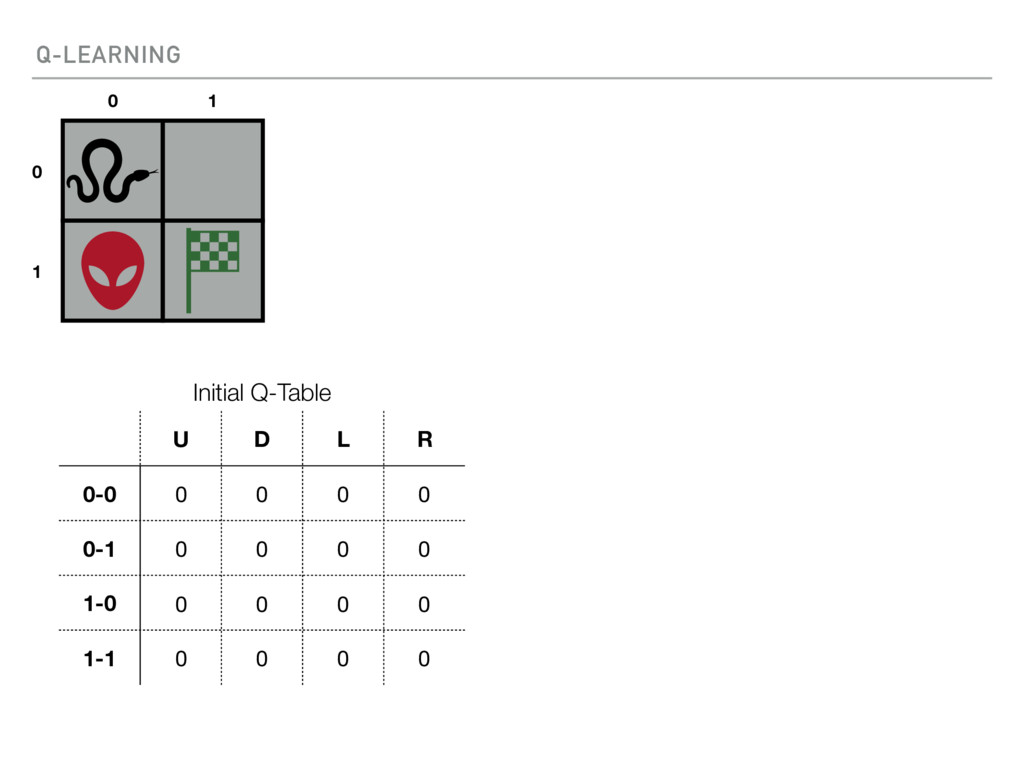
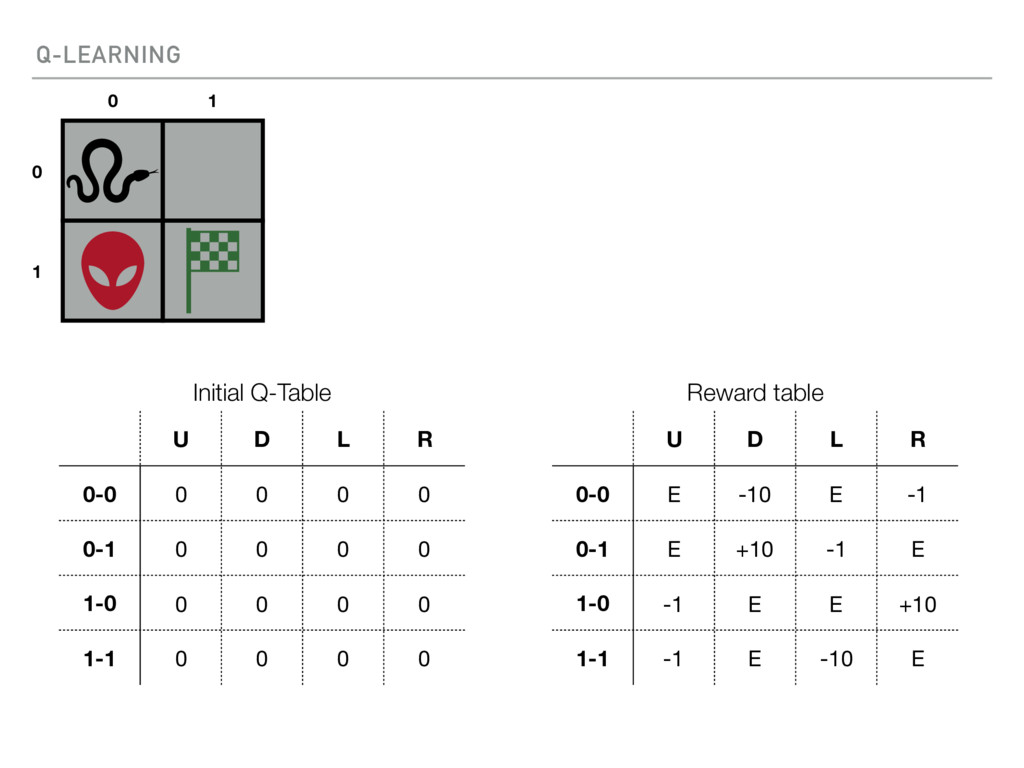
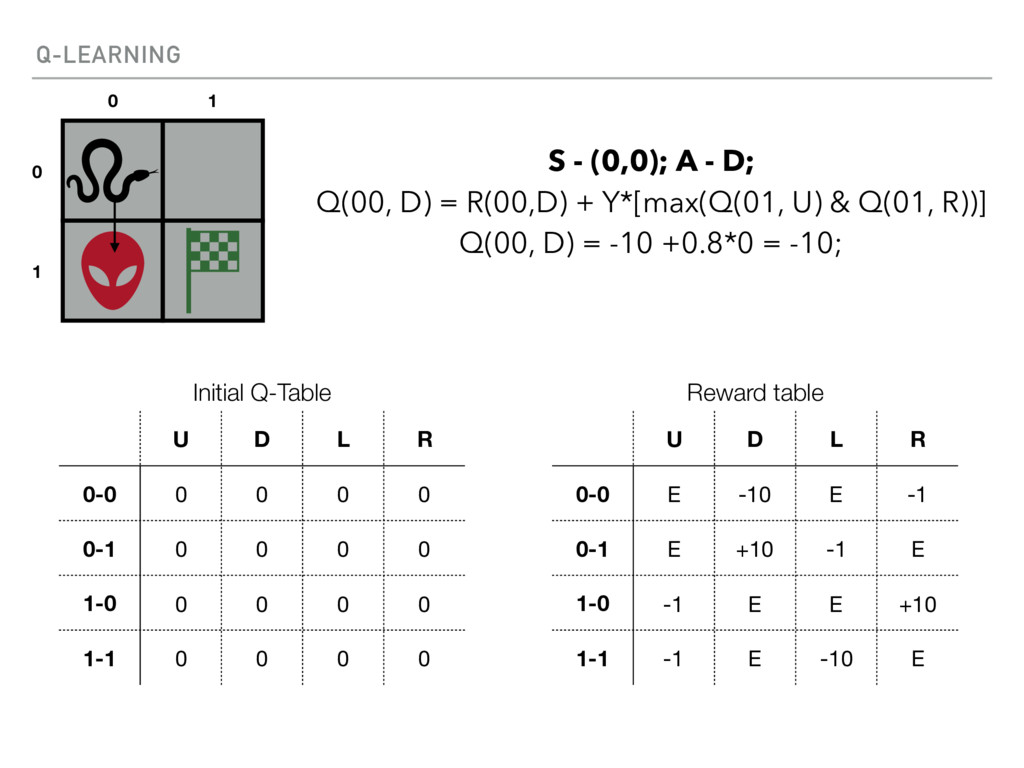
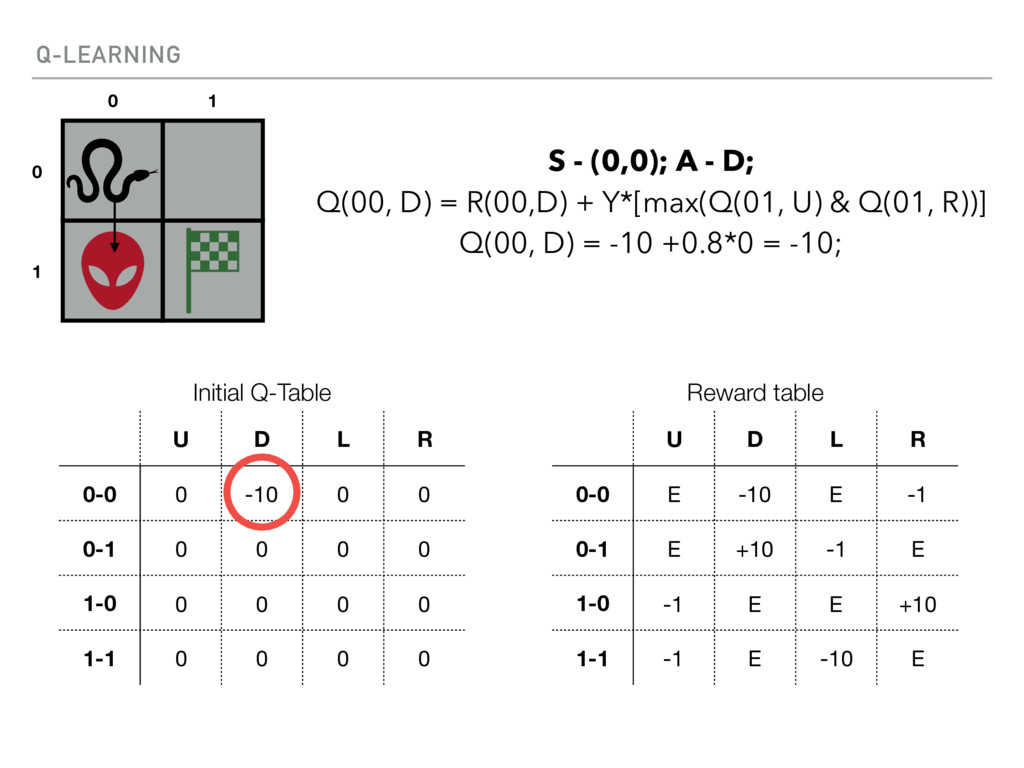
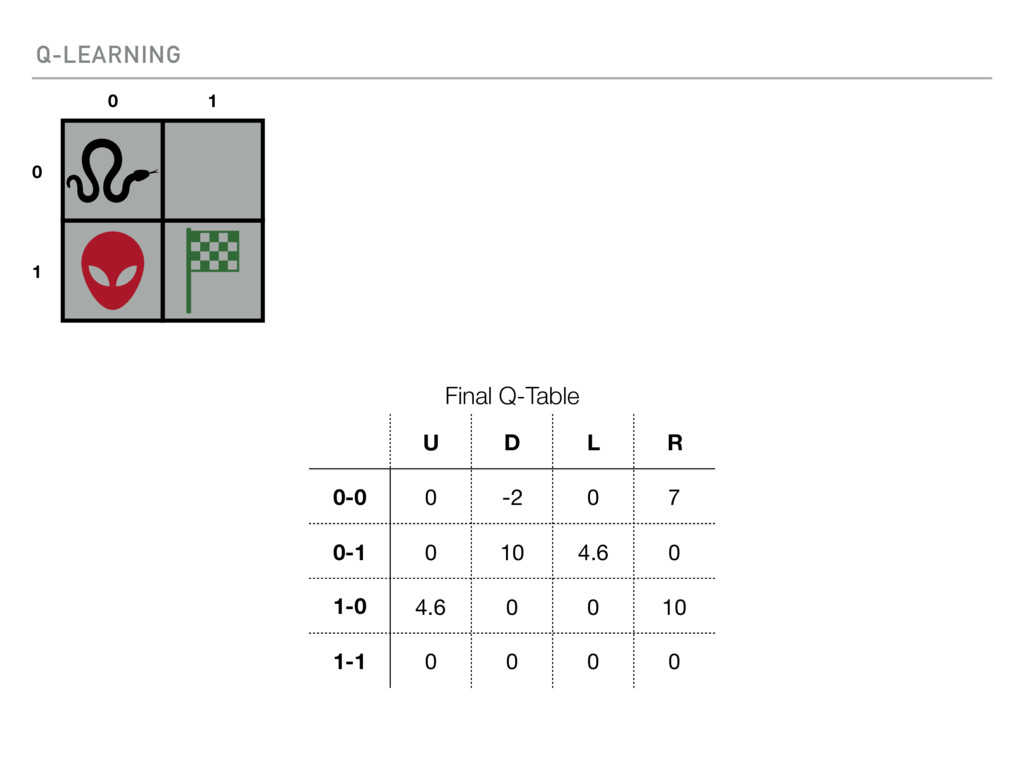
0 0 0-1 0 0 0 0 1-0 0 0 0 0 1-1 0 0 0 0 Reward table U D L R 0-0 E -10 E -1 0-1 E +10 -1 E 1-0 -1 E E +10 1-1 -1 E -10 E S - (0,0); A - D; Q(00, D) = R(00,D) + Y*[max(Q(01, U) & Q(01, R))] Q(00, D) = -10 +0.8*0 = -10; 0 1 0 1
0 0 0-1 0 0 0 0 1-0 0 0 0 0 1-1 0 0 0 0 Reward table U D L R 0-0 E -10 E -1 0-1 E +10 -1 E 1-0 -1 E E +10 1-1 -1 E -10 E S - (0,0); A - D; Q(00, D) = R(00,D) + Y*[max(Q(01, U) & Q(01, R))] Q(00, D) = -10 +0.8*0 = -10; 0 1 0 1
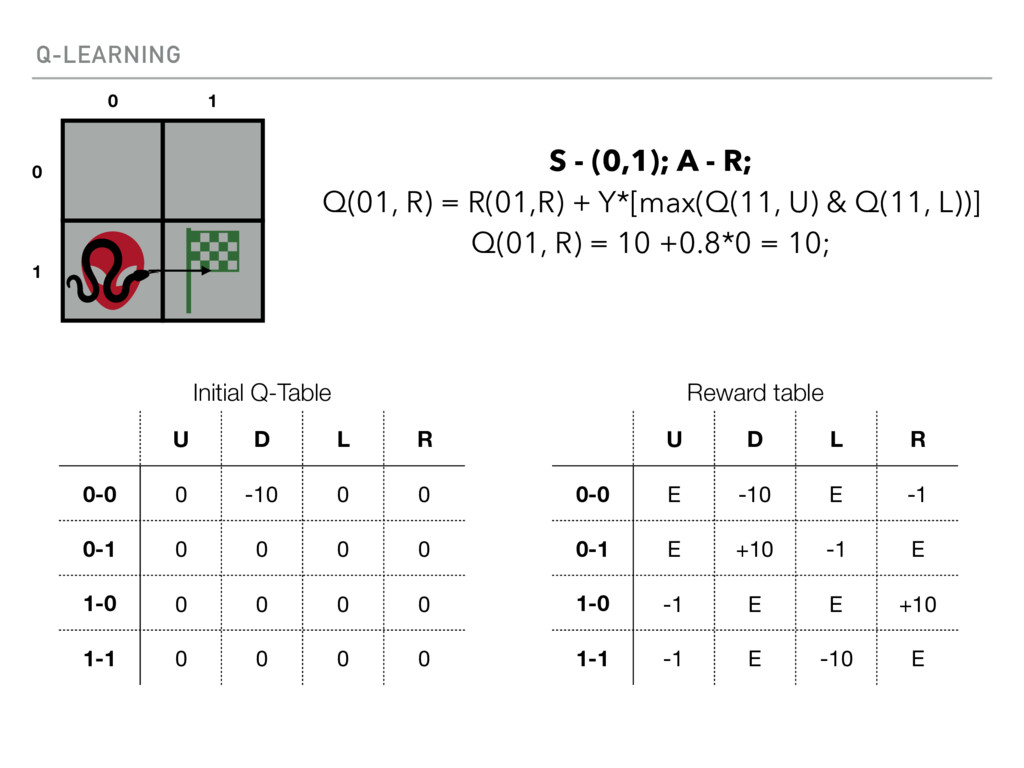
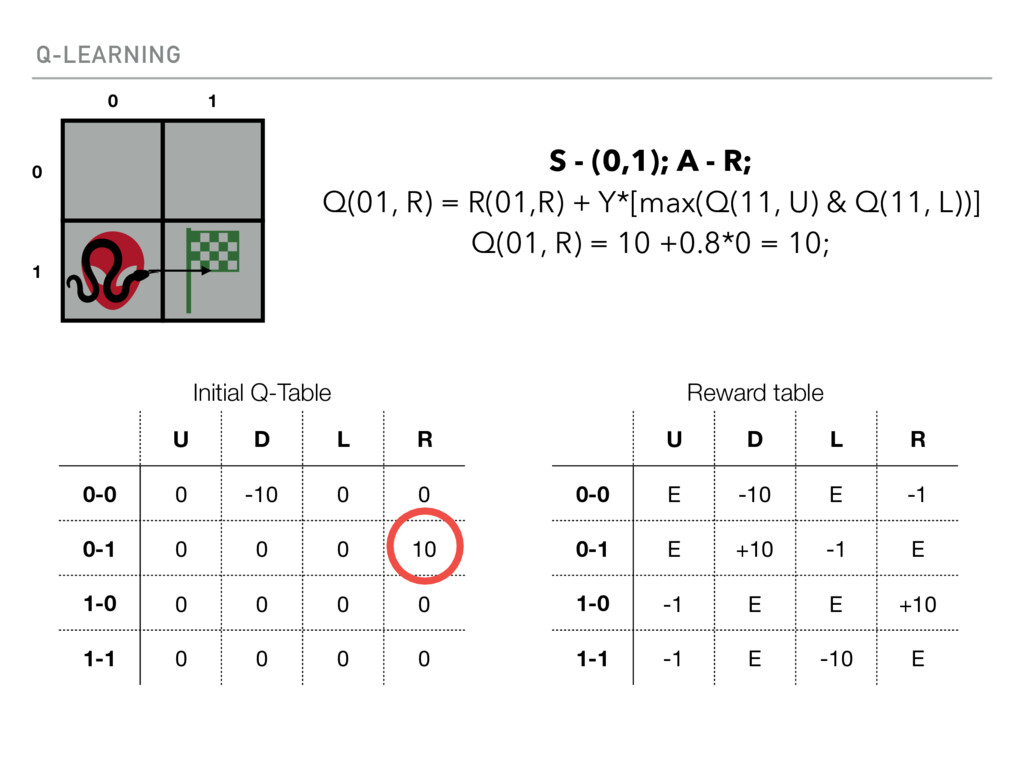
0 0 0-1 0 0 0 0 1-0 0 0 0 0 1-1 0 0 0 0 Reward table U D L R 0-0 E -10 E -1 0-1 E +10 -1 E 1-0 -1 E E +10 1-1 -1 E -10 E S - (0,1); A - R; Q(01, R) = R(01,R) + Y*[max(Q(11, U) & Q(11, L))] Q(01, R) = 10 +0.8*0 = 10; 0 1 0 1
0 0 0-1 0 0 0 10 1-0 0 0 0 0 1-1 0 0 0 0 Reward table U D L R 0-0 E -10 E -1 0-1 E +10 -1 E 1-0 -1 E E +10 1-1 -1 E -10 E S - (0,1); A - R; Q(01, R) = R(01,R) + Y*[max(Q(11, U) & Q(11, L))] Q(01, R) = 10 +0.8*0 = 10; 0 1 0 1
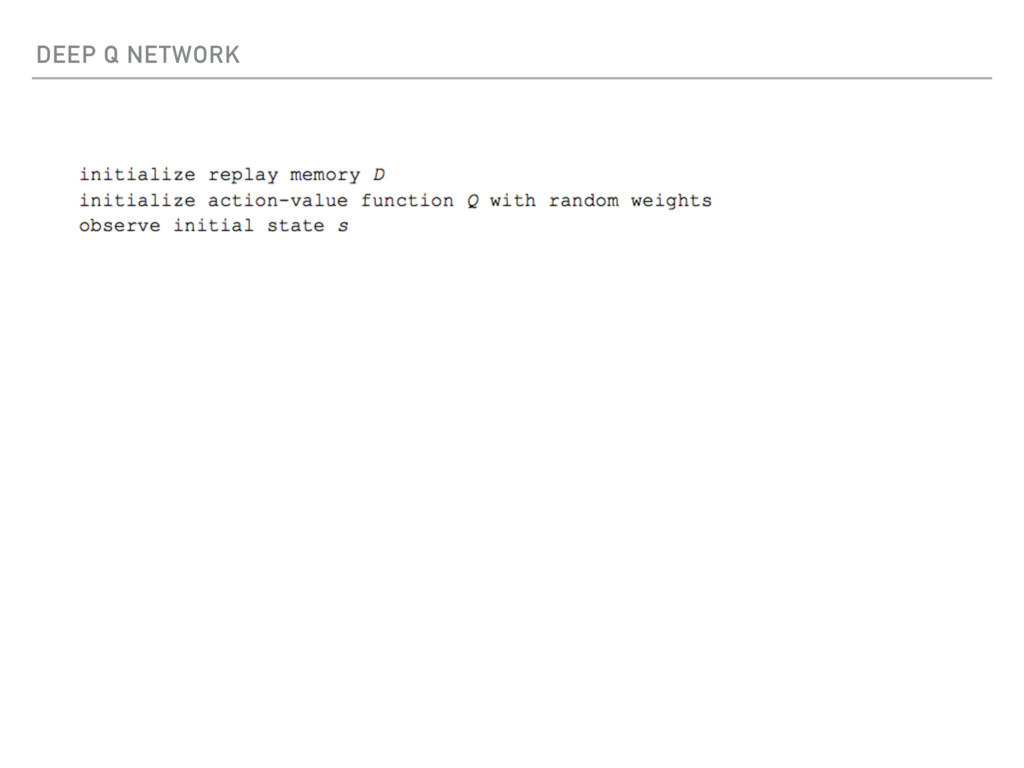
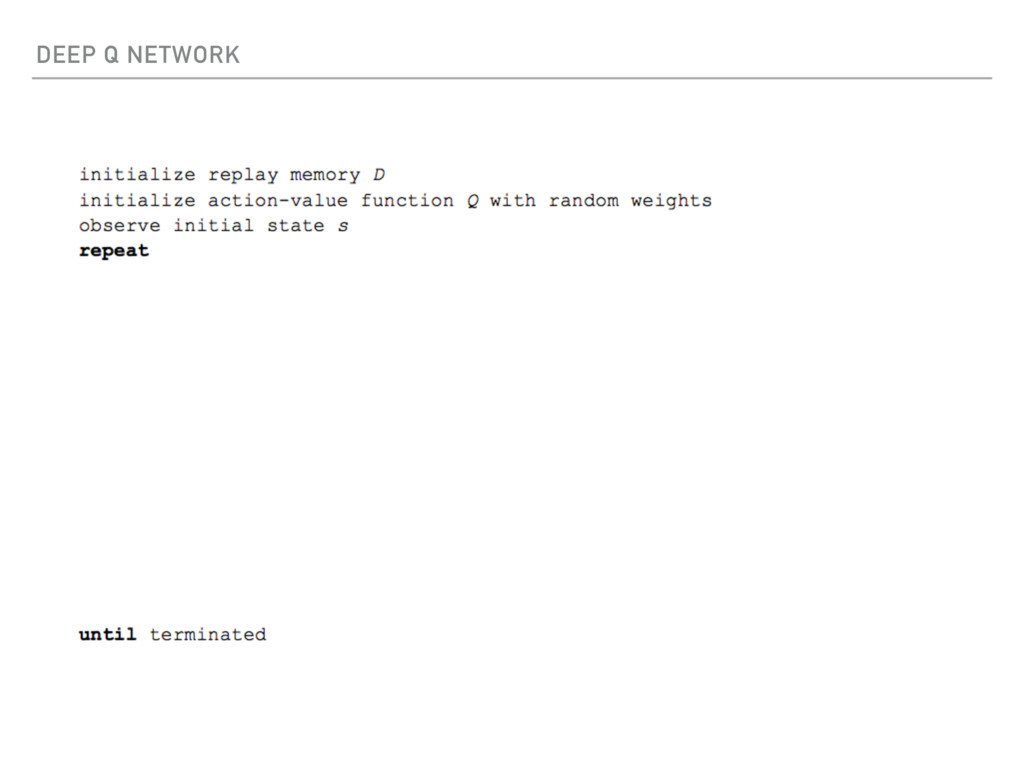
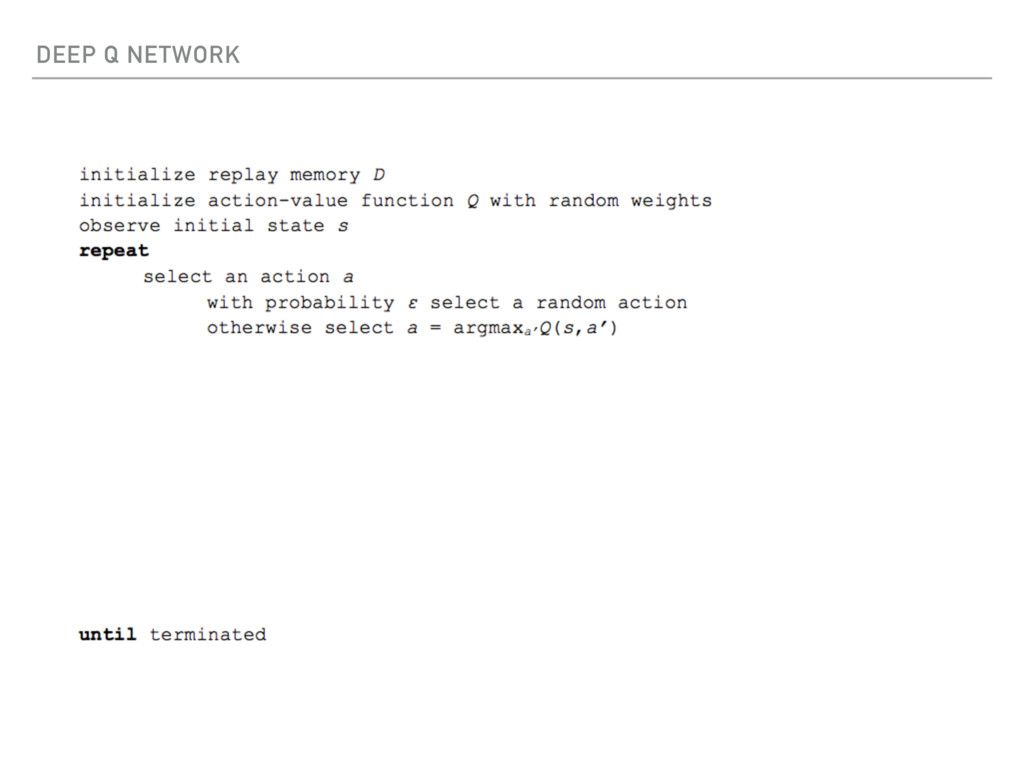
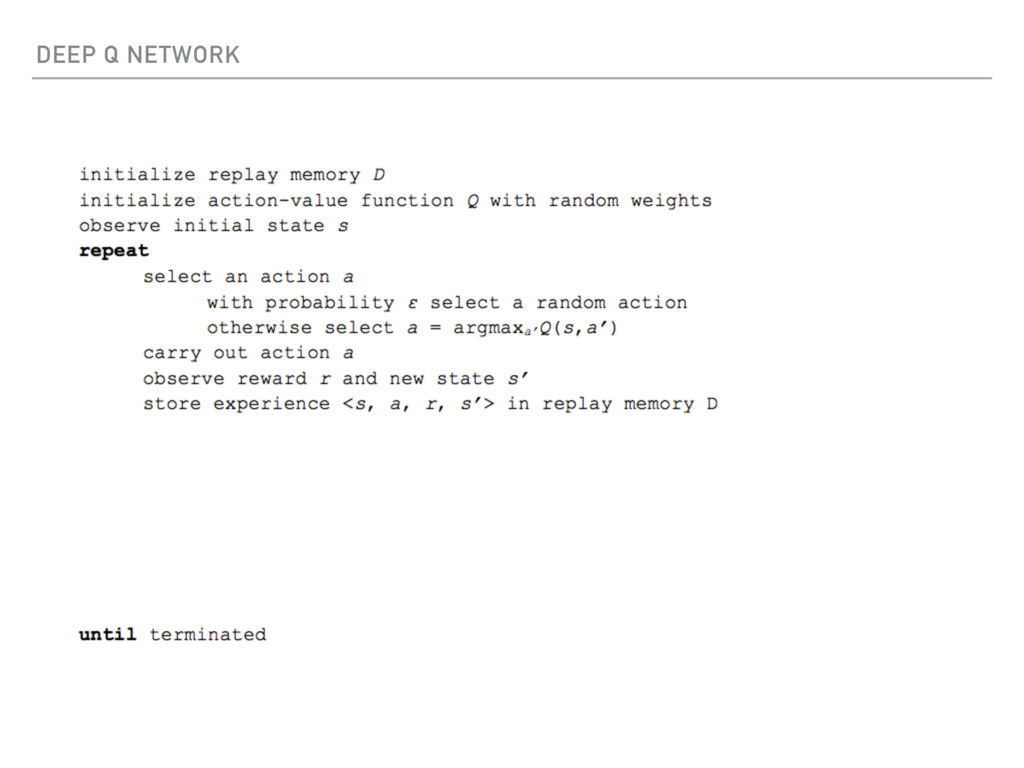
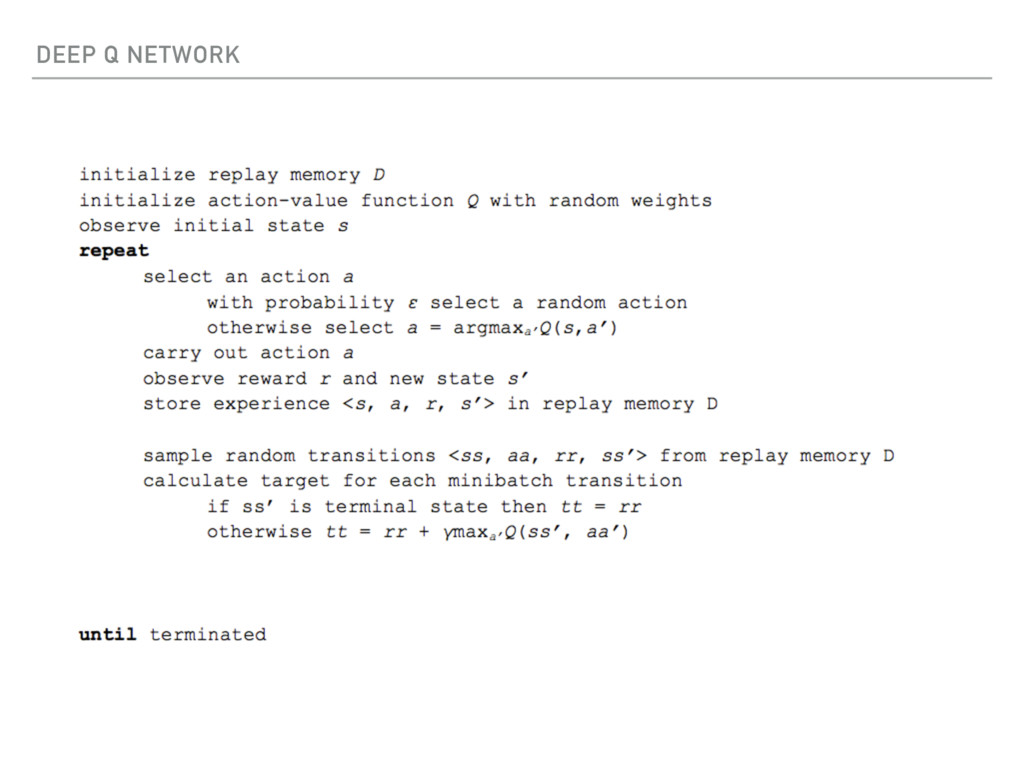
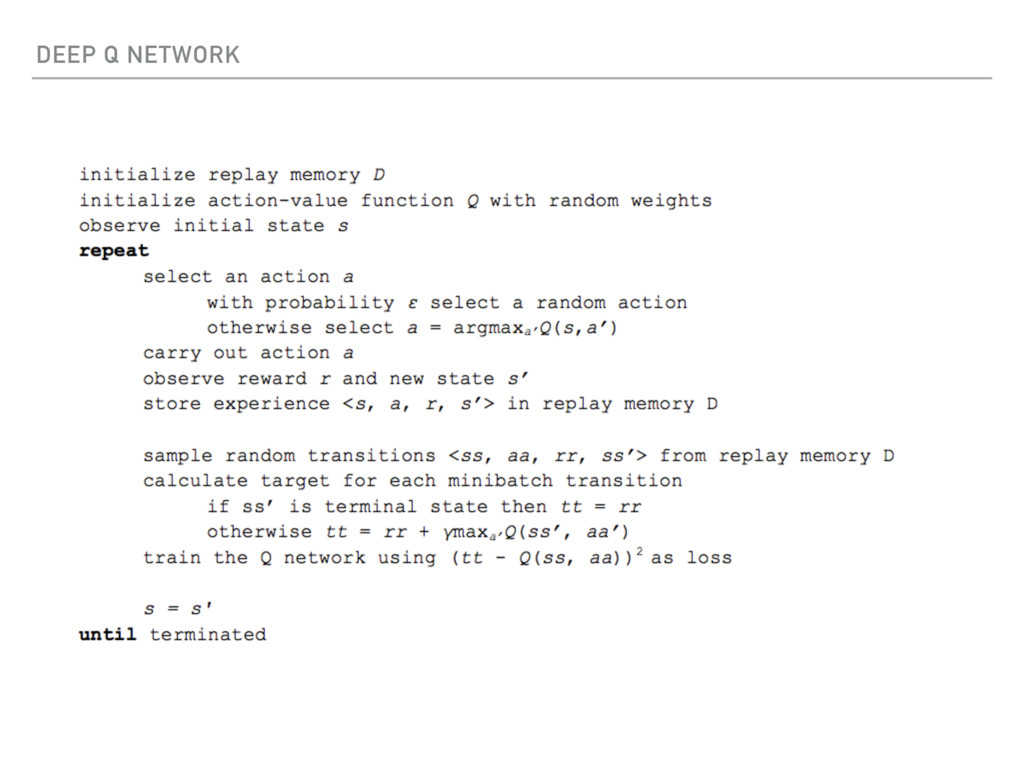
the experiences <s,a,r,s’> are stored in a replay memory ▸ when training the network, random minibatches from the replay memory are used instead of the most recent transition ▸ Exploration - Exploitation ▸ e-greed policy - with probability e choose a random action, otherwise go with the “greedy” action with the highest Q-value
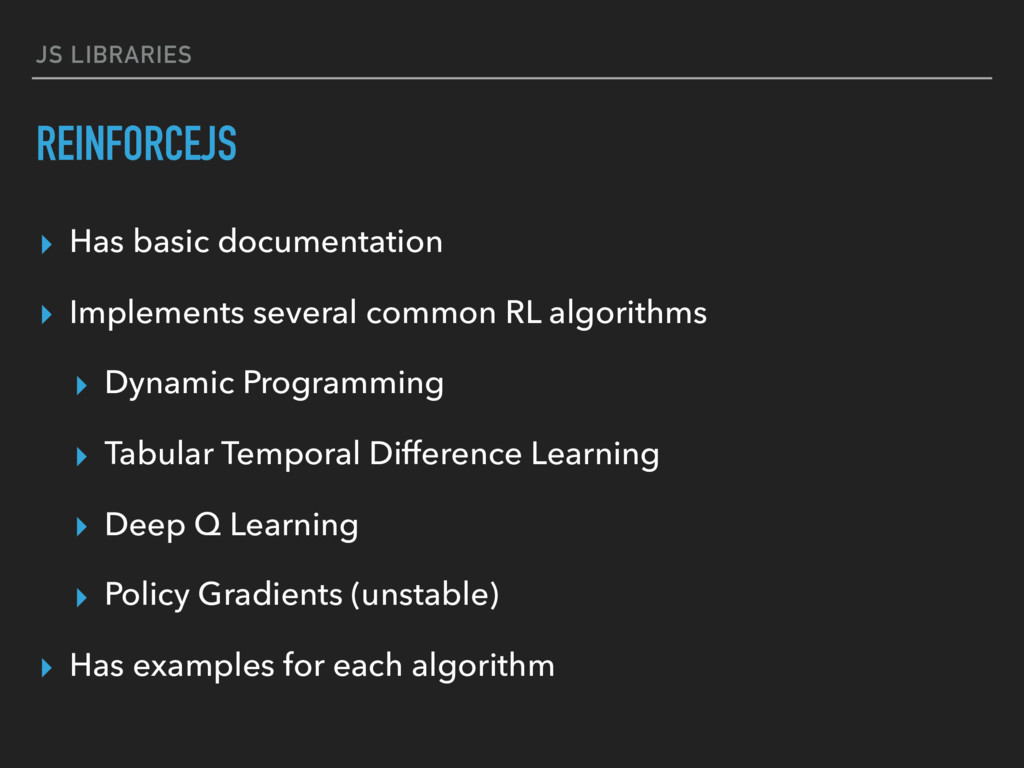
and reinforcement learning library. ▸ ReinforceJS - https://github.com/karpathy/reinforcejs A javascript reinforcement learning library that implements several common RL algorithms, all with web demos.
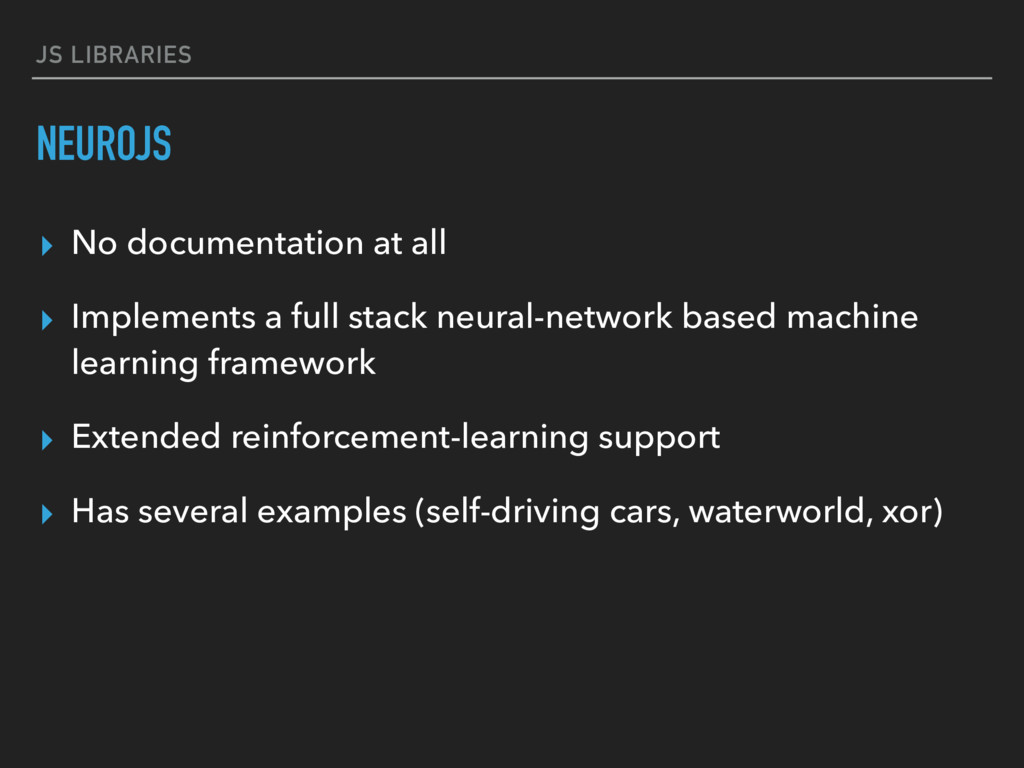
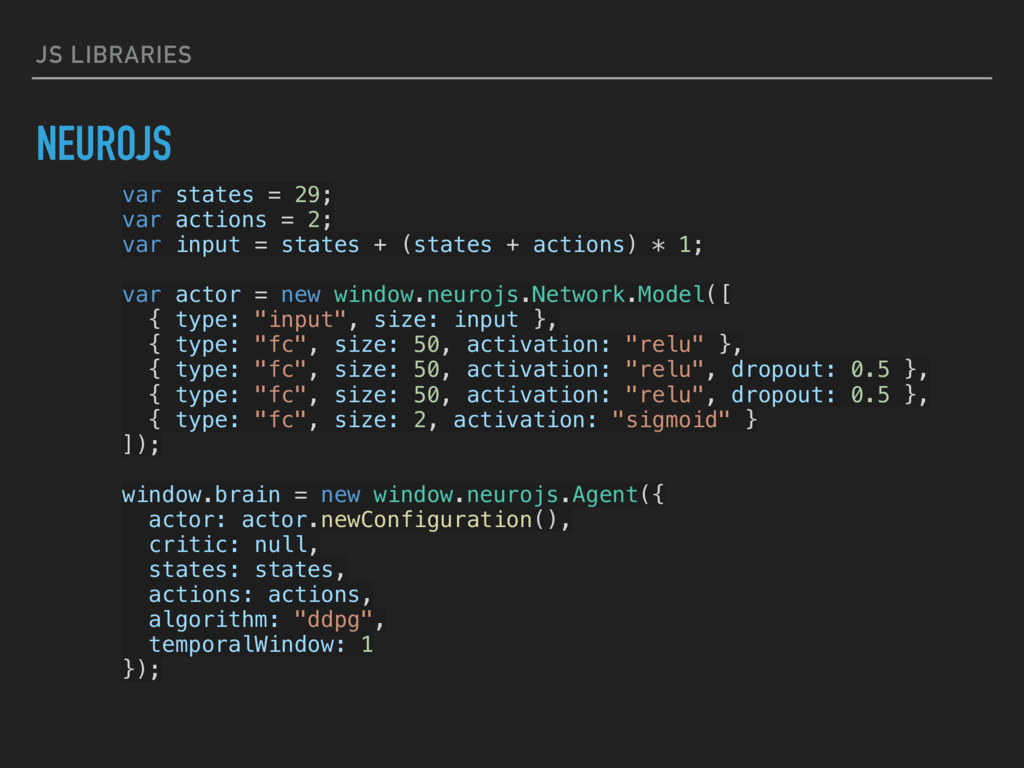
a full stack neural-network based machine learning framework ▸ Extended reinforcement-learning support ▸ Has several examples (self-driving cars, waterworld, xor)
common RL algorithms ▸ Dynamic Programming ▸ Tabular Temporal Difference Learning ▸ Deep Q Learning ▸ Policy Gradients (unstable) ▸ Has examples for each algorithm
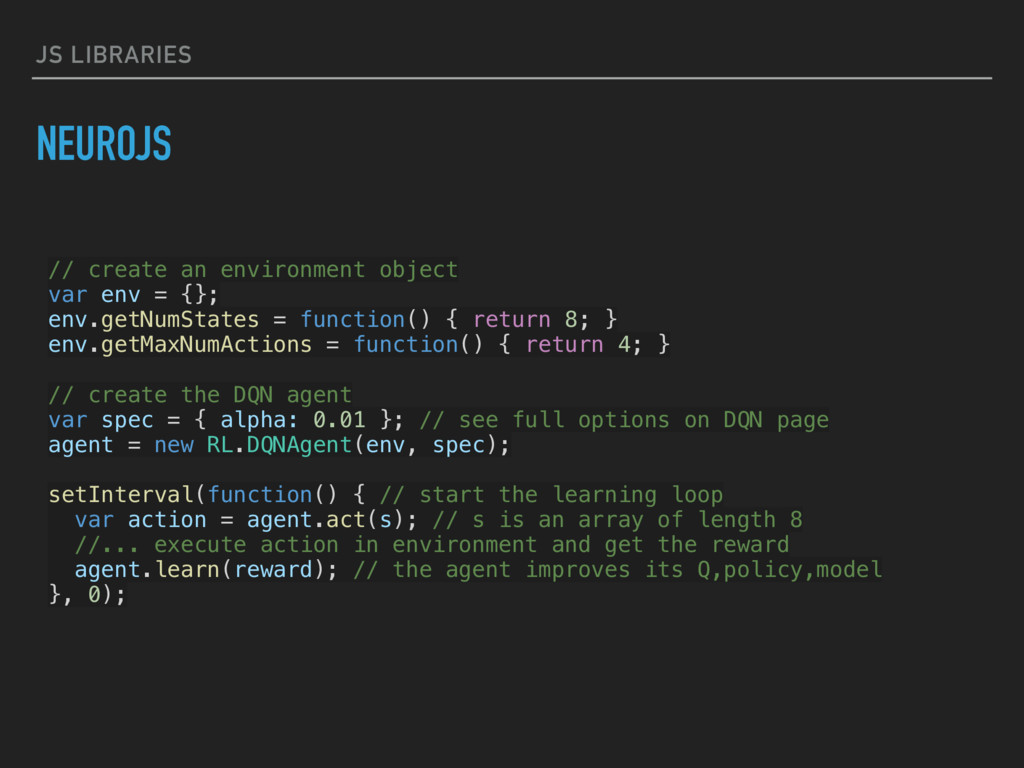
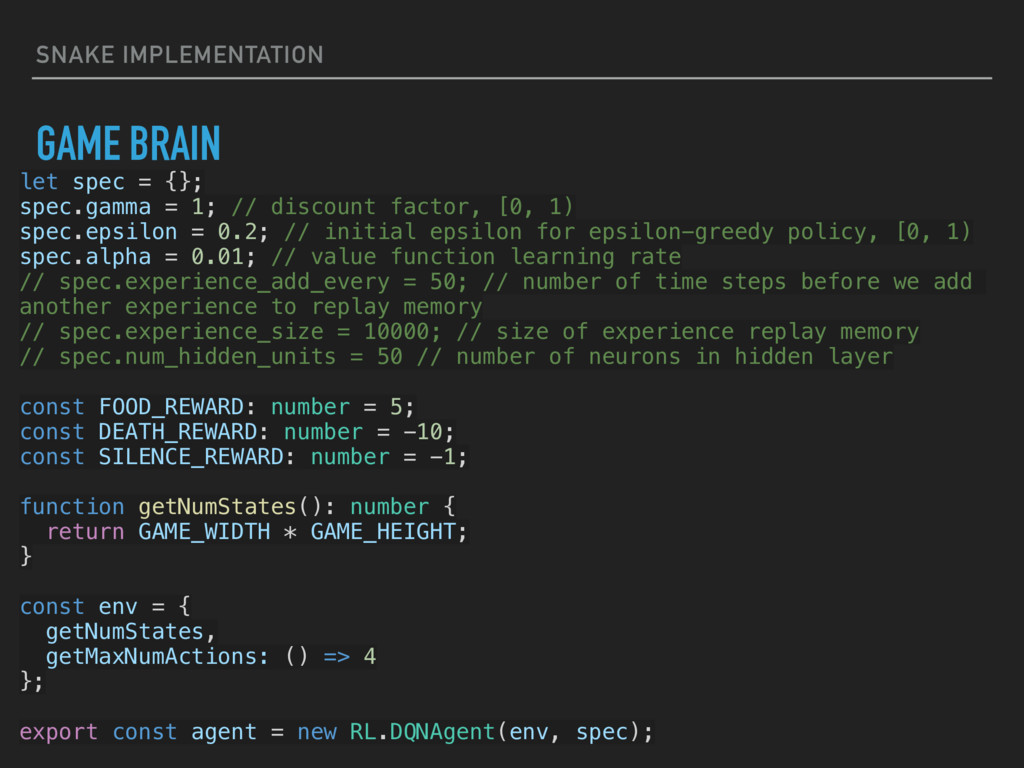
= {}; env.getNumStates = function() { return 8; } env.getMaxNumActions = function() { return 4; } // create the DQN agent var spec = { alpha: 0.01 }; // see full options on DQN page agent = new RL.DQNAgent(env, spec); setInterval(function() { // start the learning loop var action = agent.act(s); // s is an array of length 8 //... execute action in environment and get the reward agent.learn(reward); // the agent improves its Q,policy,model }, 0);
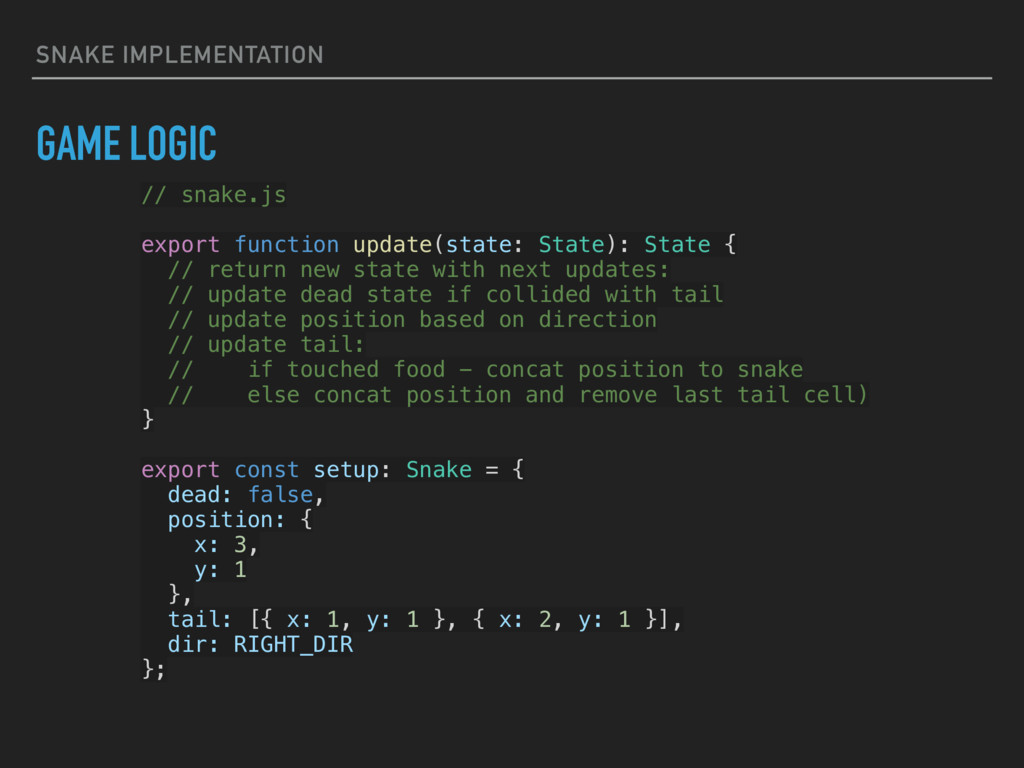
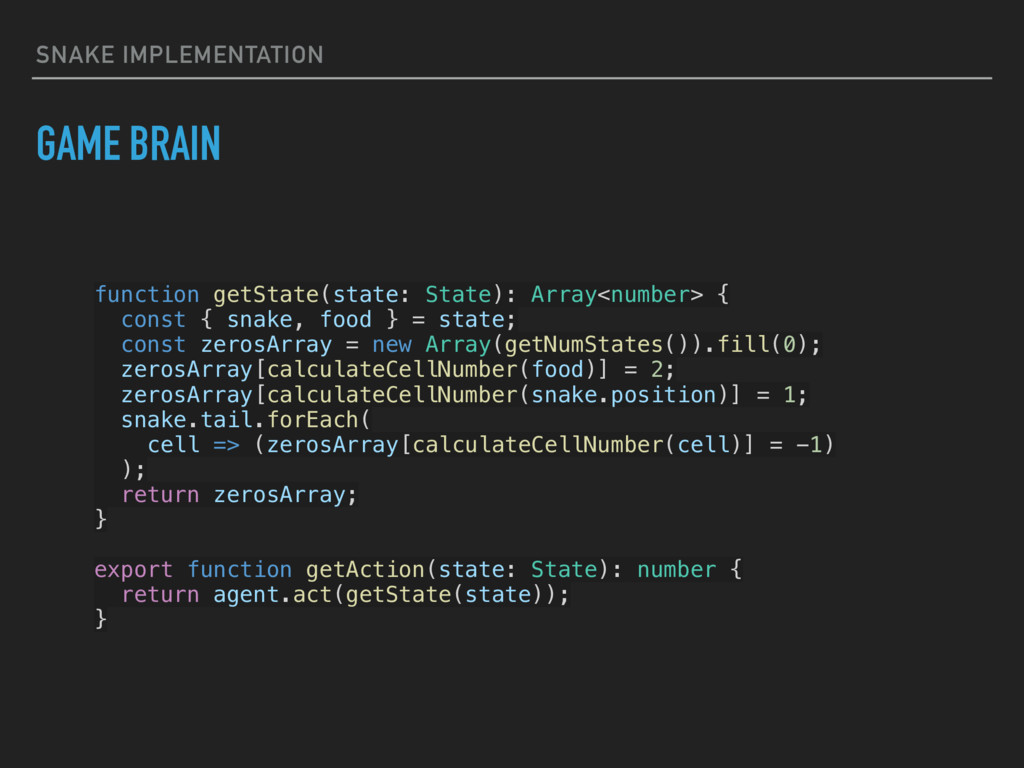
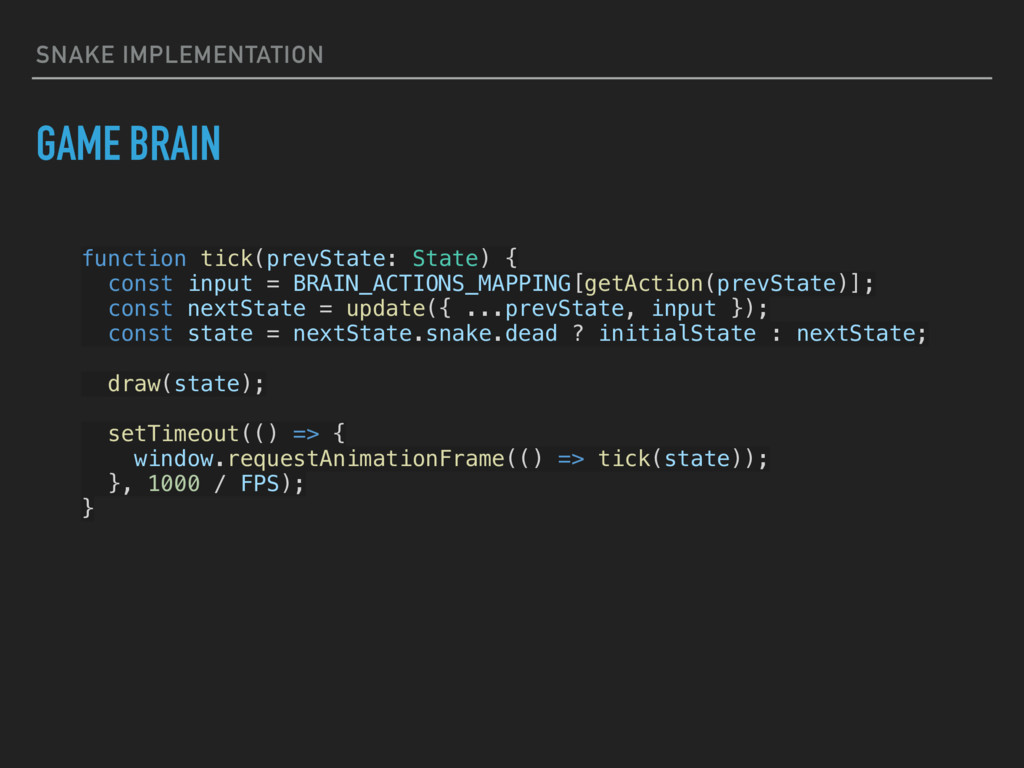
State { // return new state with next updates: // update dead state if collided with tail // update position based on direction // update tail: // if touched food - concat position to snake // else concat position and remove last tail cell) } export const setup: Snake = { dead: false, position: { x: 3, y: 1 }, tail: [{ x: 1, y: 1 }, { x: 2, y: 1 }], dir: RIGHT_DIR };
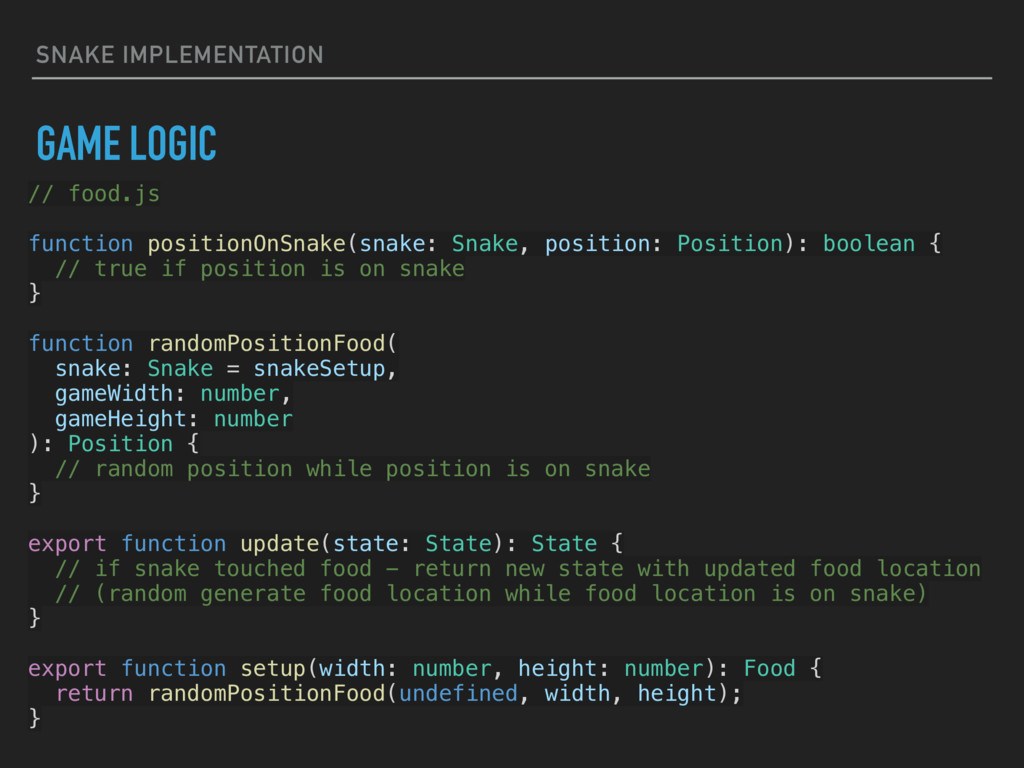
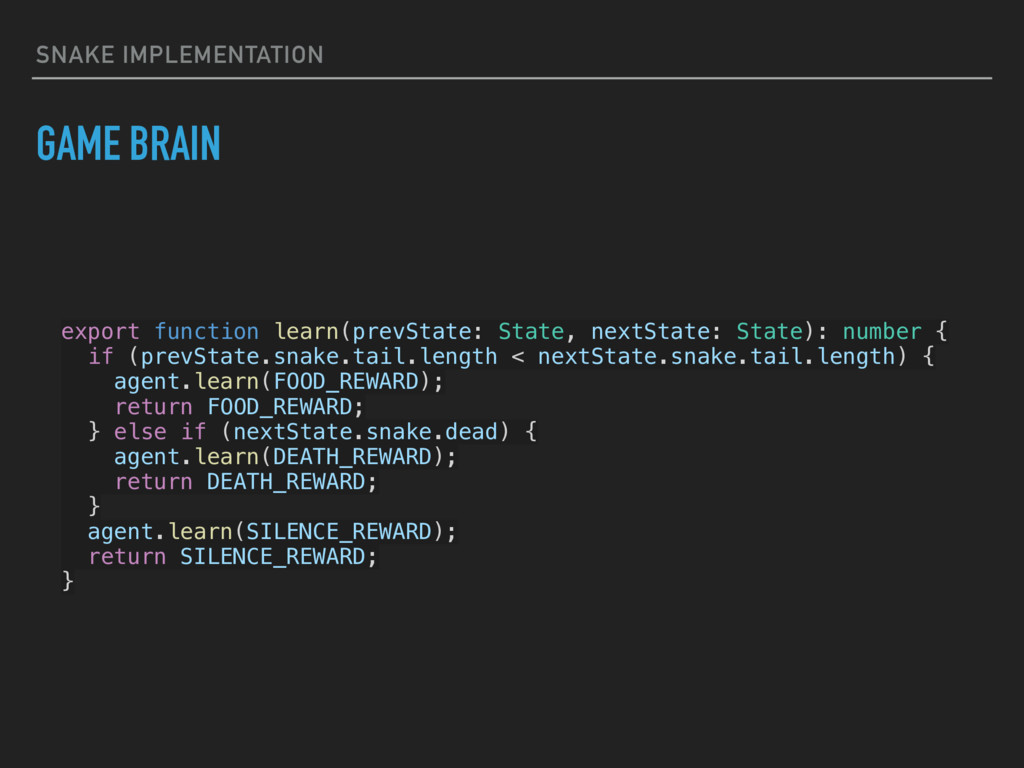
Position): boolean { // true if position is on snake } function randomPositionFood( snake: Snake = snakeSetup, gameWidth: number, gameHeight: number ): Position { // random position while position is on snake } export function update(state: State): State { // if snake touched food - return new state with updated food location // (random generate food location while food location is on snake) } export function setup(width: number, height: number): Food { return randomPositionFood(undefined, width, height); }


 shumpei777
 takusamar
 tagtag
 gkazunii
 voginip
 akasan
 trycycle
 x_ttyszk
 konakalab
 livdayseo
 akademiya2063
 skipperchong
 erikaheidi
 akosma
 trishagee
 coloredviolet
 scottboms
 jakevdp
 codingconduct
 keithpitt
 yeseniaperezcruz