Share
Embed
Open Source building blocks for scalable, reproducible science with Jupyter
How Jupyter, JupyterHub, and Binder bring reproducible, sharable science closer to reality.
Chris Holdgraf
April 07, 2018
Transcript
71 slides
-
Open source building blocks with Jupyter How Jupyter, JupyterHub, and
Binder bring reproducible, sharable science closer to reality Chris Holdgraf, Project Jupyter -
The science is the code An article about computational science
in a scientific publication is not the scholarship itself, it is merely advertising of the scholarship. The actual scholarship is the complete software development environment and the complete set of instructions which generated the figures. Buckheit and Donoho (paraphrasing John Claerbout) WaveLab and Reproducible Research, 1995 -
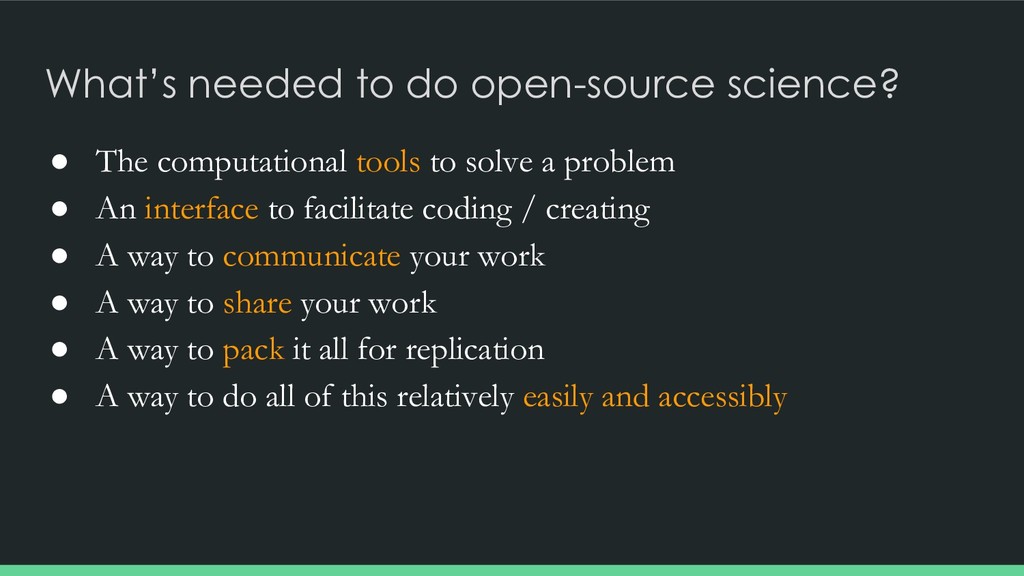
What’s needed to do open-source science? • The computational tools
to solve a problem • An interface to facilitate coding / creating • A way to communicate your work • A way to share your work • A way to pack it all for replication • A way to do all of this relatively easily and accessibly -
These pieces are the raw material How can we… ◦
Facilitate the use of open-source tools? ◦ Make it easier to use, share, and reproduce? ◦ Make connections between languages or tools? ◦ Make them more accessible to the world? -
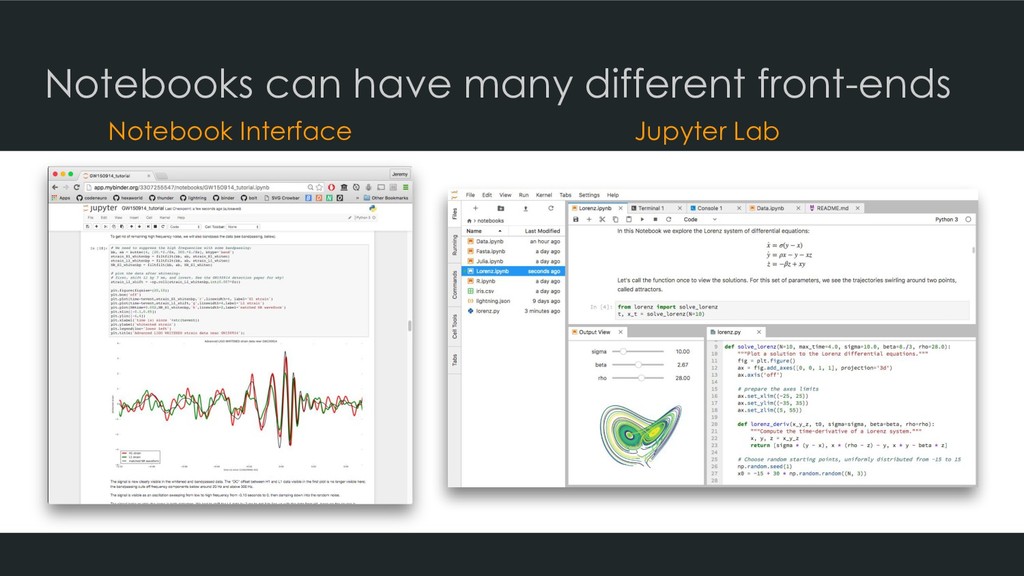
Document specifications organize narrative + code Jupyter Notebooks • Structured
document specification • Organize work into “cells” • Blend code and narrative • Attach arbitrary metadata -
This is *actually* the notebook {"metadata" : { "kernel_info": {
"name" : "my awesome kernel" }, "language_info": { "name" : "python3", "version": "0.1"} }, "nbformat": 4, "nbformat_minor": 0, "cells" : [ <list-of-cell-dictionaries> ]} Notebook metadata [ {'cell_type': 'markdown', 'metadata': {}, 'source': '# Hi there'}, {'cell_type': 'code', 'execution_count': 10, 'metadata': {}, 'outputs': [{'name': 'stdout', 'output_type': 'stream', 'text': '[-0.61023336 -0.35754269 -0.18629438 0.84355958 -0.14921895]\n'}], 'source': 'import numpy as np\ndata = np.random.randn(5)\nprint(data)'}, {'cell_type': 'markdown', 'metadata': {}, 'source': 'Look at those numbers!'} ] Cell Data -
Online communities let us share our work… ...but this is
usually in a static form -
Container specifications let us package and run our code docker
run -it -p 7001:7001 mpacer/procbuild -
What do you need to do open-source science? • The
computational tools to solve a problem • An interface to facilitate coding / creating • A way to communicate your work • A way to share your work • A way to pack it all for replication A way to do all of this relatively easily and accessibly? -
The cloud has come a long way • You can
ask, then throw away resources at will • User-friendly interfaces • More stability and flexibility -
Building blocks for working in the cloud • What core
infrastructure is needed to facilitate people working in the cloud? • Full-stack solutions are too rigid, don’t generalize well • Fully-generic solutions are too complex to expect adoption • It needs to be open-source so that others can build on this work. -
Kubernetes is... • A platform for managing resources in the
cloud • Built with containers in mind • A tool for defining/maintaining a state of cloud resources • Also known as “k8s” -
“Scalable” Works well for large (several thousand active users) &
small (10-50 users) installations Doesn’t need constant human operator intervention Increase or decrease cloud resources automatically or manually -
Abstracts away the provider Abstracts away most detail of underlying
cloud providers / hardware Declarative high level primitives that allow you to be as high level or low level as needed Utilize features of underlying hardware when you want (GPUs, SSDs, etc) easily -
Strong, welcoming, diverse community Not controlled by one single commercial
entity Fast paced releases that miraculously keep backwards compatibility Has worked to foster a warm, welcoming environment for contributors and users -
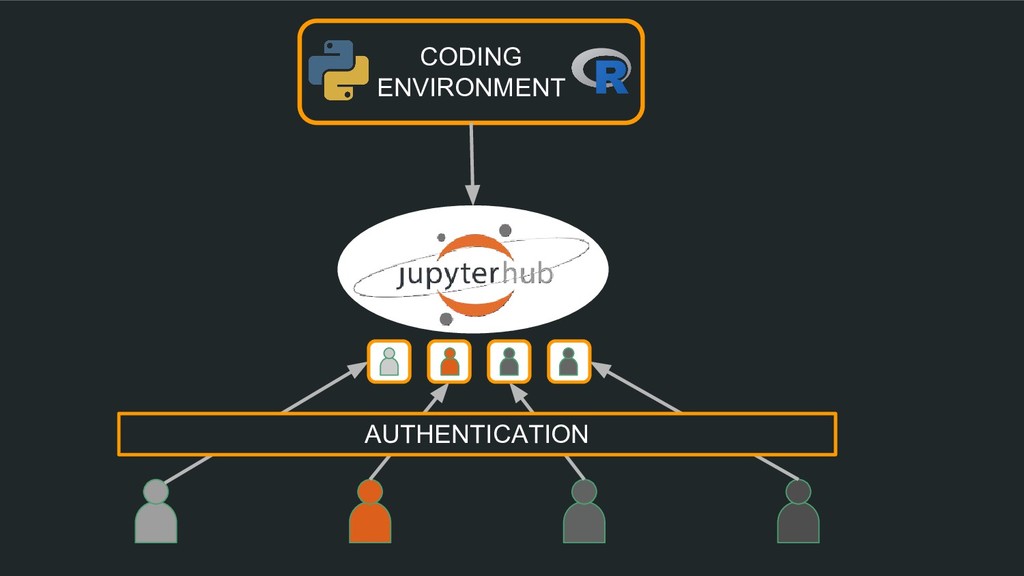
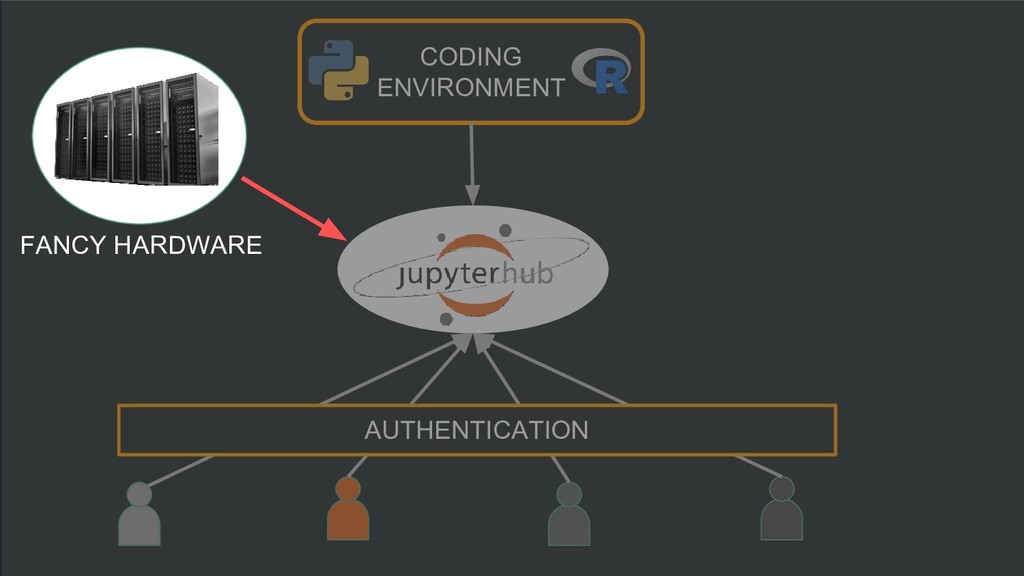
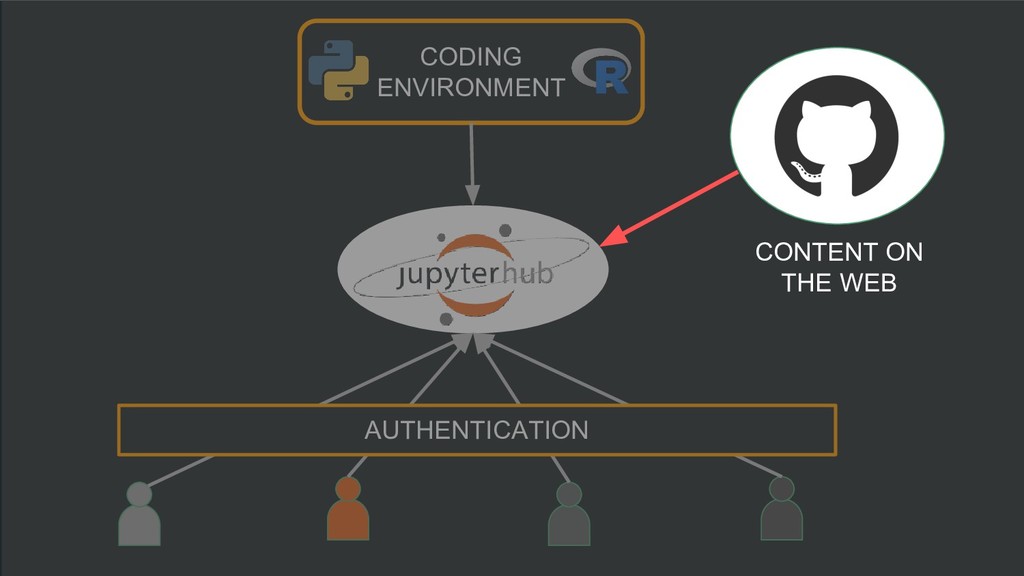
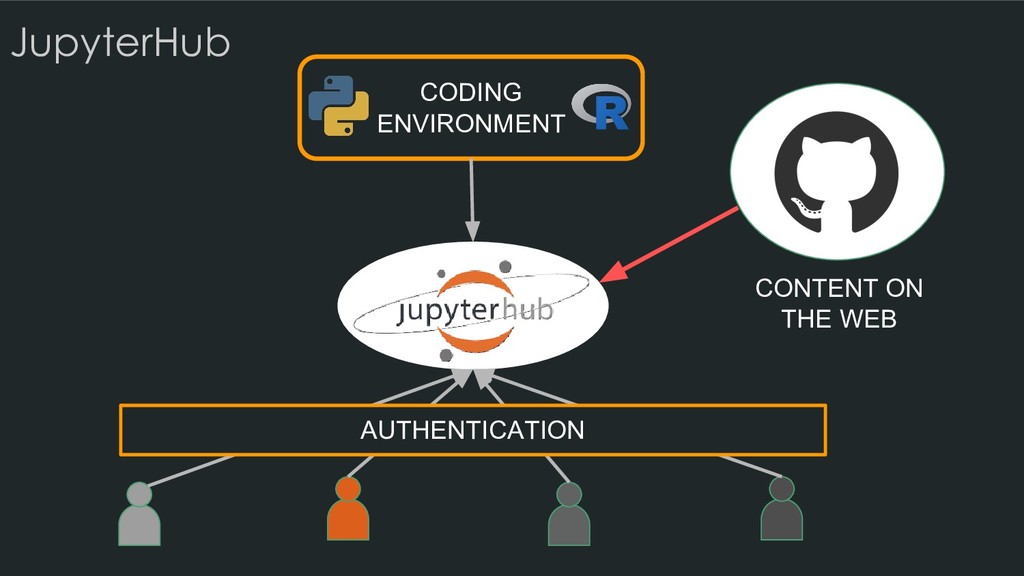
Flexibly connects users to a computational environment you provide. Removes
accidental complexity around accessing computational resources. What does JupyterHub do? -
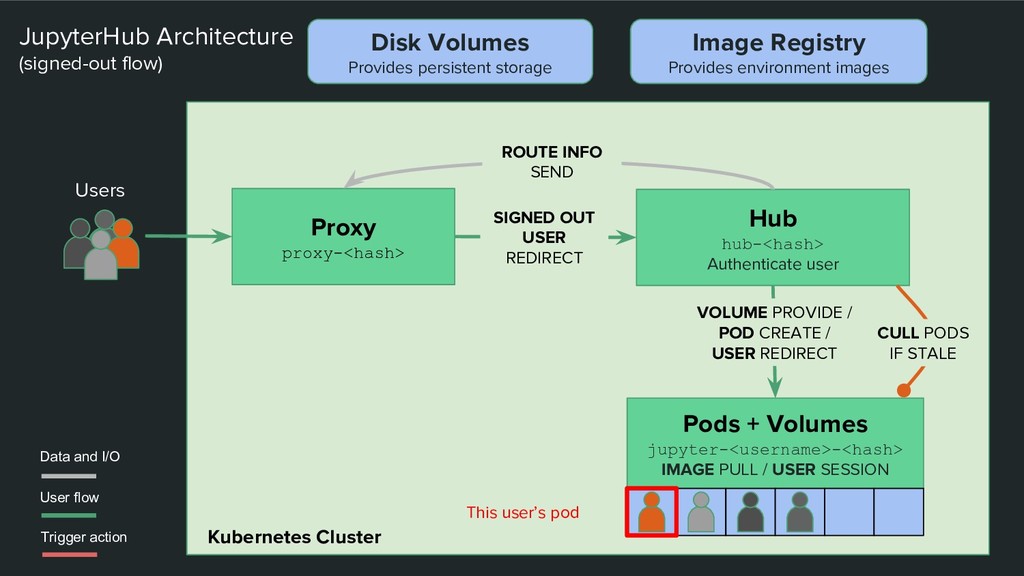
Proxy proxy-<hash> Hub hub-<hash> Authenticate user Kubernetes Cluster VOLUME PROVIDE
/ POD CREATE / USER REDIRECT JupyterHub Architecture (signed-out flow) SIGNED OUT USER REDIRECT ROUTE INFO SEND Data and I/O User flow Users Pods + Volumes jupyter-<username>-<hash> IMAGE PULL / USER SESSION This user’s pod Disk Volumes Provides persistent storage Image Registry Provides environment images CULL PODS IF STALE Trigger action -
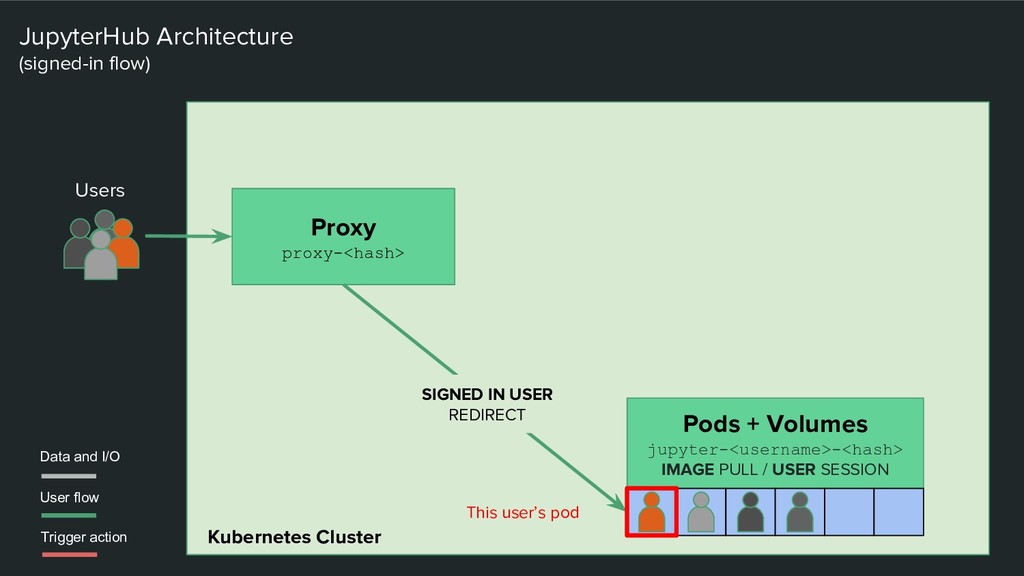
Proxy proxy-<hash> Kubernetes Cluster JupyterHub Architecture (signed-in flow) SIGNED IN
USER REDIRECT Data and I/O User flow Users Pods + Volumes jupyter-<username>-<hash> IMAGE PULL / USER SESSION This user’s pod Trigger action -
What does this mean for science + education? • Can
utilize… ◦ ...shared hardware/compute for running code ◦ ...shared data storage for big datasets ◦ ...shared environments for doing work ◦ ...shared workflows, ideas, and results -
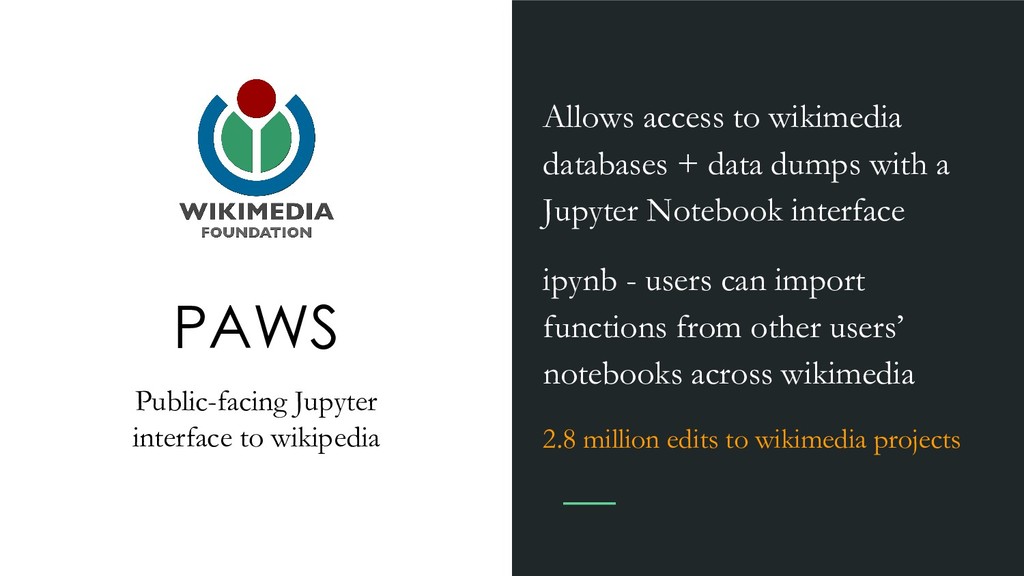
PAWS Public-facing Jupyter interface to wikipedia Allows access to wikimedia
databases + data dumps with a Jupyter Notebook interface ipynb - users can import functions from other users’ notebooks across wikimedia 2.8 million edits to wikimedia projects -
Can we deploy this without lots of custom work? •
PAWS required a lot of manual one-off customization • We can’t assume that researchers will spend this much time deploying JupyterHub • Fortunately...Kubernetes has a solution to this! -
The JupyterHub helm chart • Makes JupyterHub easily-deployable on Kubernetes
• Spend less time maintaining, more time customizing+extending • Runs on many cloud platforms or your hardware -
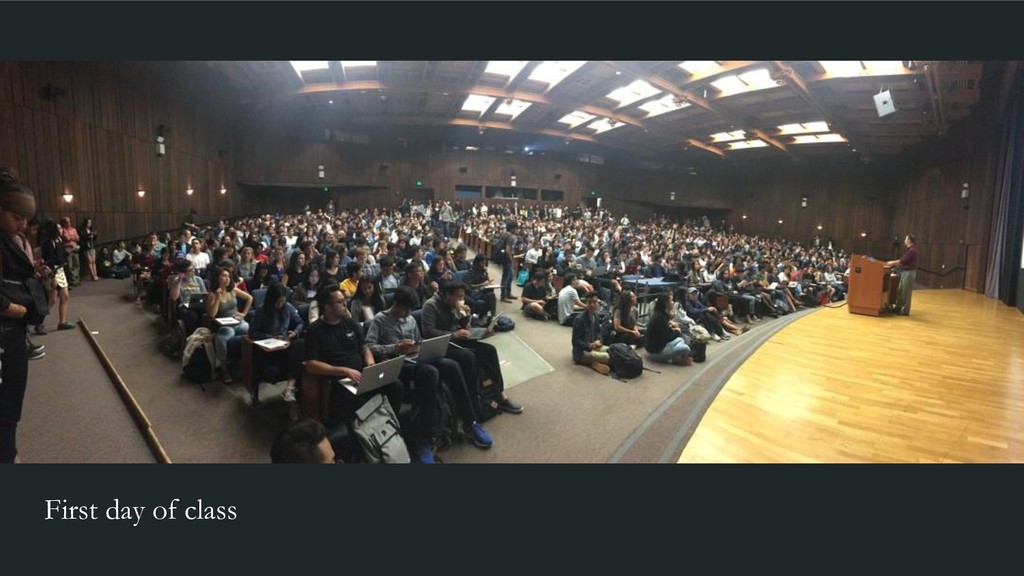
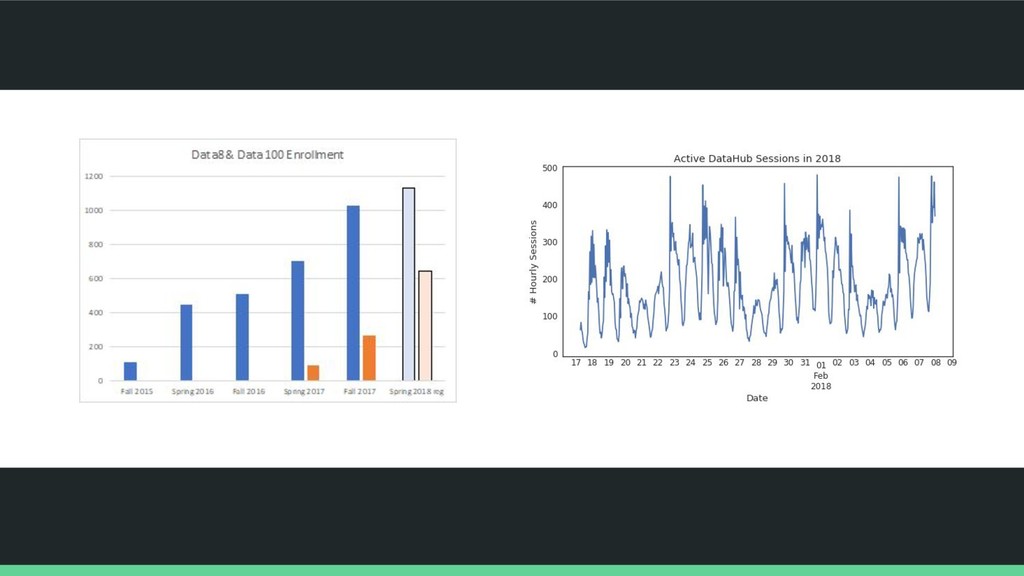
DataHub datahub.berkeley.edu Supporting 2,500+ users Being used for Data 8,
as well as several other courses Requires @berkeley.edu to access Running on Azure with almost zero maintenance -
Chris Is Trying A Live Demo Hopefully he doesn’t embarrass
himself too badly. -
Building a Docker image is a barrier to entry JupyterHub
needs a pre-built Docker image. Creating the image can be hard to learn, debug, etc Most languages already have a way to specify dependencies Could we programmatically generate an environment? -
repo2docker deterministically build a docker image from a repository. Parse
a repo for “configuration files” Use them to build the environment needed to run the code -
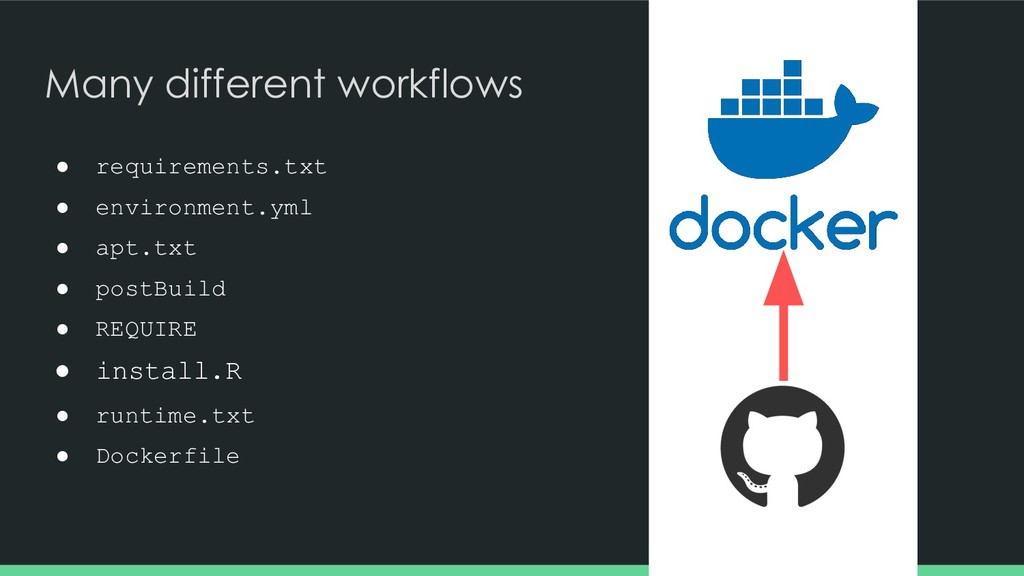
Many different workflows • requirements.txt • environment.yml • apt.txt •
postBuild • REQUIRE • install.R • runtime.txt • Dockerfile -
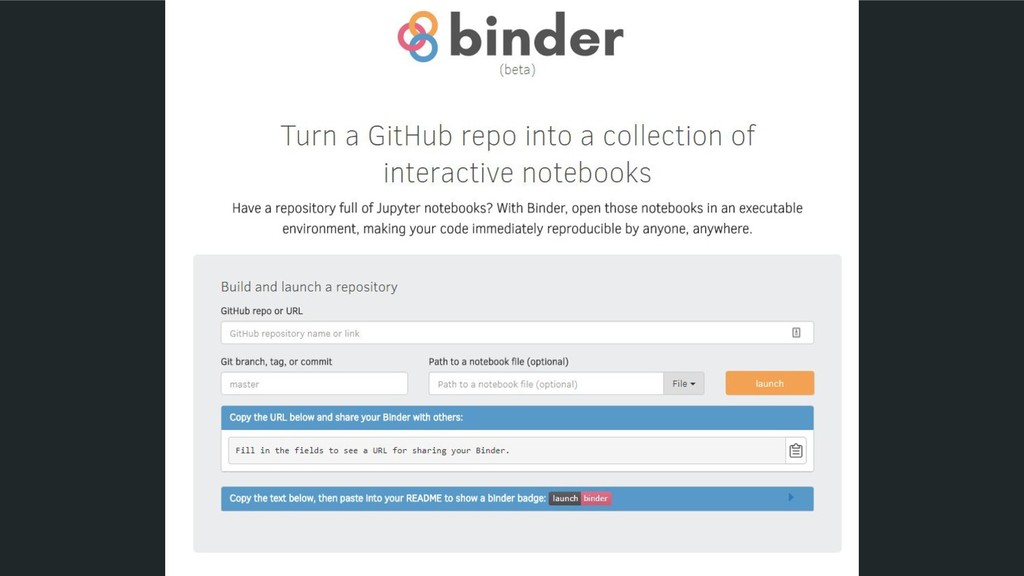
Binder sharable computational environments JupyterHub + repo2docker + some glue
Quickly generate interactive, reproducible, sharable computational environments -
Chris Is Trying A Live Demo Hopefully he doesn’t embarrass
himself too badly. -
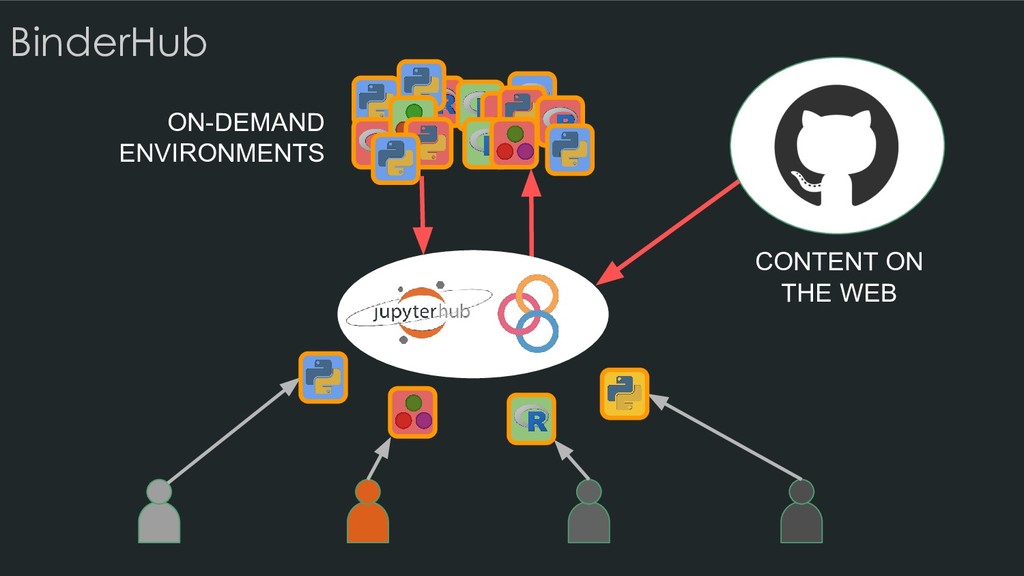
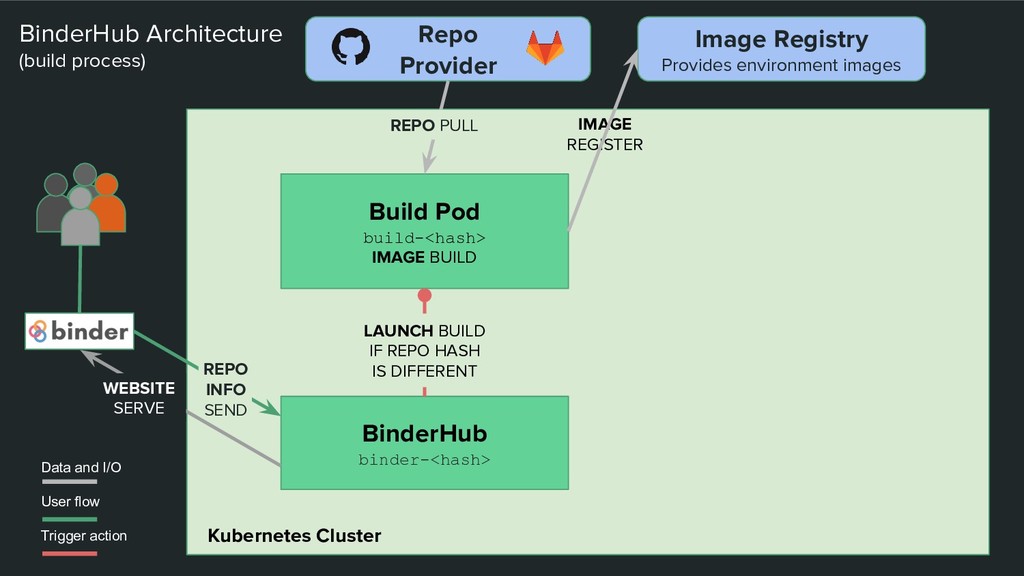
BinderHub binder-<hash> Kubernetes Cluster Repo Provider BinderHub Architecture (build process)
Build Pod build-<hash> IMAGE BUILD REPO PULL LAUNCH BUILD IF REPO HASH IS DIFFERENT Users Data and I/O User flow Trigger action Image Registry Provides environment images REPO INFO SEND IMAGE REGISTER WEBSITE SERVE -
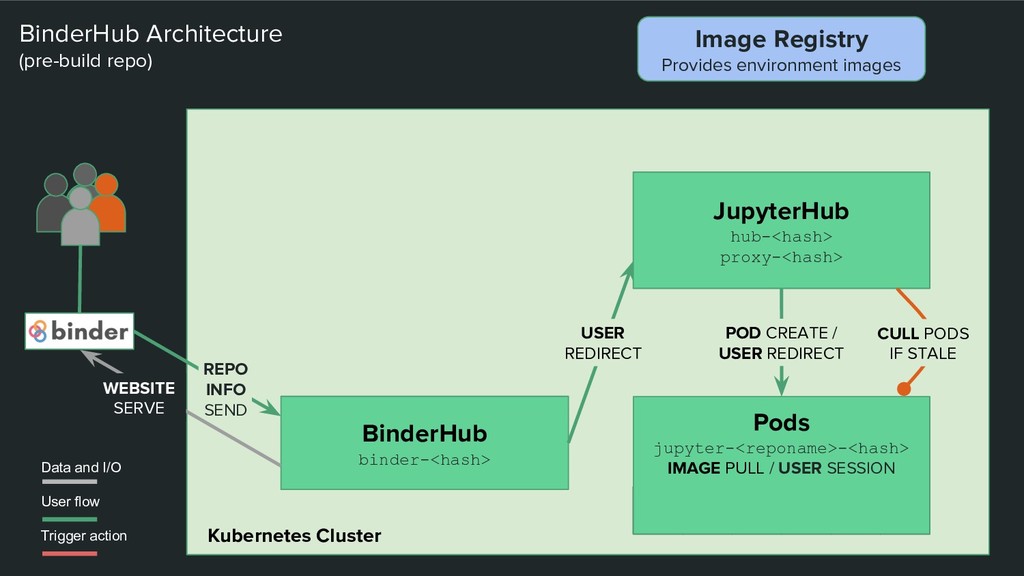
BinderHub binder-<hash> Kubernetes Cluster POD CREATE / USER REDIRECT BinderHub
Architecture (pre-build repo) USER REDIRECT Users Data and I/O User flow Trigger action Image Registry Provides environment images JupyterHub hub-<hash> proxy-<hash> REPO INFO SEND WEBSITE SERVE CULL PODS IF STALE Pods jupyter-<reponame>-<hash> IMAGE PULL / USER SESSION -
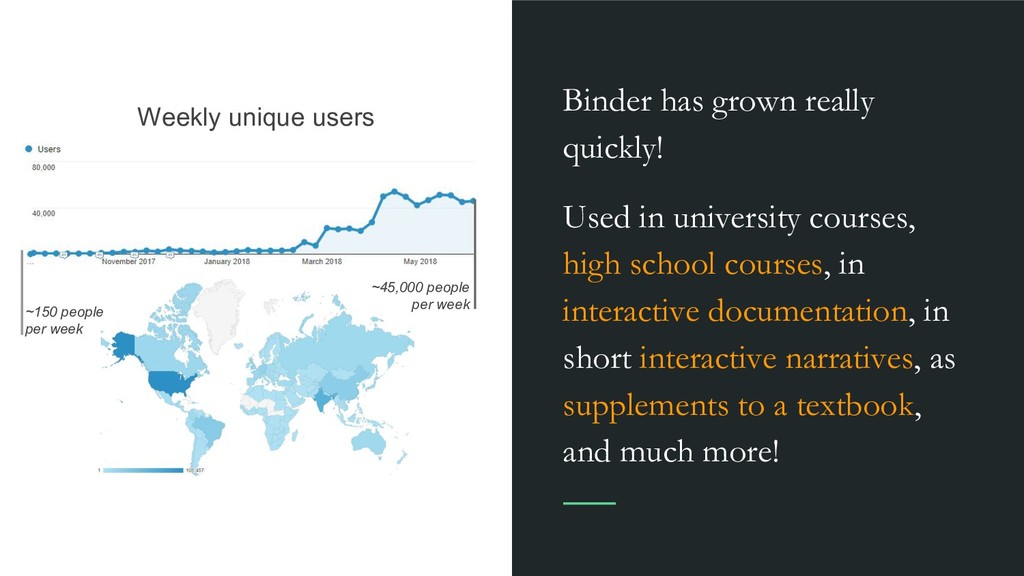
Binder has grown really quickly! Used in university courses, high
school courses, in interactive documentation, in short interactive narratives, as supplements to a textbook, and much more! Weekly unique users ~150 people per week ~45,000 people per week -
The full stack of computational science • The computational tools
to solve a problem • An interface to facilitate coding / creating • A way to communicate your work • A way to share your work • A way to pack it all for replication • A way to do all of this relatively easily and accessibly -
The full stack of computational science • The computational tools
to solve a problem • An interface to facilitate coding / creating • A way to communicate your work • A way to share your work • A way to pack it all for replication • A way to do all of this relatively easily and accessibly • A bunch of other cool stuff... -
Portable Learning Environments Scaling OUT More students, more diverse course
material, more universities Still need to solve the grading problem How to serve the non-R1 schools? (community colleges, K-12, etc) -
Portable Research Environments Scaling UP Different needs than teaching Data
is still an open question Use shared, fancier hardware More projects moving to k8s (daskernetes) (spark on k8s) -
Cloud Resources for Science • West and South big data
hubs • Academic-facing kubernetes deployments • Federated models for computation -
Interactive Webpages minrk.github.io/thebelab nbinteract.com Interact with arbitrary HTML, powered by
a jupyter kernel Binder can be used to request kernels on-demand, destroy them as needed Widgets, dashboards, interactive narratives, etc -
Communities of practice Teachers: How to use cloud tools to
facilitate teaching? What’s different when you’re in the cloud? Researchers: How to efficiently collaborate via the cloud? Communicators: How to convey more complex information or reach new audiences? -
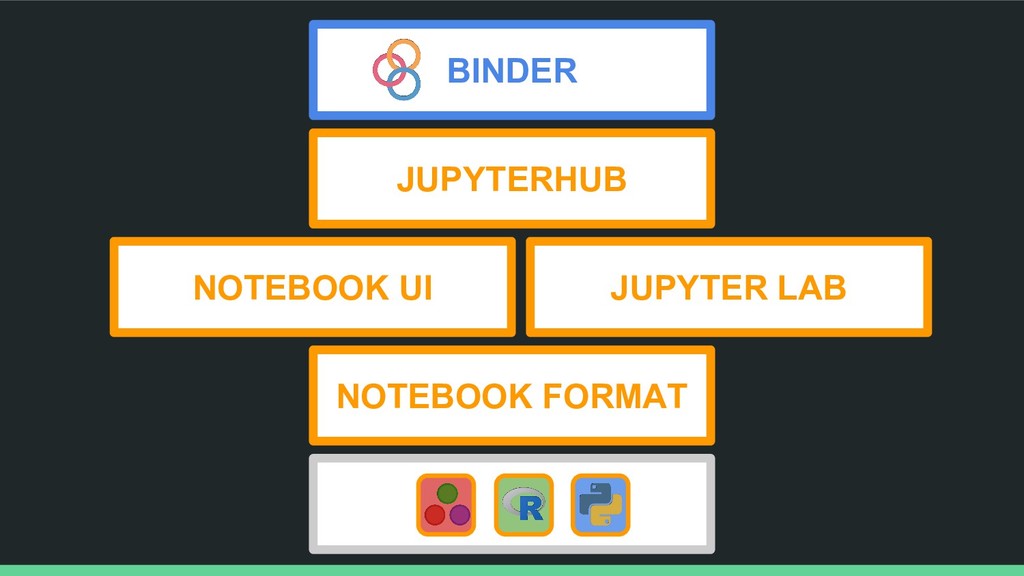
In summary... • The open-source/open-science ecosystem is mature and awesome
• Jupyter makes connections between open-source tools • The Notebook format interweaves narrative, code, and results • The Notebook Interface and JupyterLab presents your work in a readable and interactive way • JupyterHub lets you serve multiple notebook sessions in the cloud • Binder lets you create sharable, interactive code repositories -
Get involved (and thank you) Gitter Chat gitter.im/jupyterhub/jupyterhub gitter.im/jupyterhub/binder Mailing
list groups.google.com/forum/#!forum/jupyter groups.google.com/forum/#!forum/binderhub Deploy your own JupyterHub z2jh.jupyter.org Deploy your own BinderHub binderhub.readthedocs.io