Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
KubernetesでGPUを使おう
Search
Sponsored
·
Your Podcast. Everywhere. Effortlessly.
Share. Educate. Inspire. Entertain. You do you. We'll handle the rest.
→
Dodai-Dodai
February 27, 2025
Programming
670
0
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
KubernetesでGPUを使おう
大阪工業大学 ネットワークデザイン学科 LT大会 2025v1 で発表した資料です
Dodai-Dodai
February 27, 2025
Other Decks in Programming
See All in Programming
ChromeでローカルLLM
ryu1013
0
140
npm との違いを手がかりにGo の依存管理を理解したい
optim
0
340
[Dev Group Paris Octobre 26] Agentforce, SIforce, Claudeforce, Slackbot… on s'y retrouve ?
nabondance
0
110
最近”作らせてる” ローカルAIアプリの話
akit37
0
470
ActionController meets Protocol Buffers
sorah
0
520
S3 TablesのIcebergデータに、AIエージェントからアクセスしてみた / 20261016developersio2026joetsu-accessing-iceberg-in-s3tables-via-agent
kasacchiful
PRO
0
150
[ハンズオン]AIへの指示だけで「五目並べ」を作ってみよう
satoshi256kbyte
1
380
Web Framework Benchmark Battle 2026, Any%
a_matsuda
2
2.1k
Vue Fes Japan の “作る側”に関わってみて
naokihaba
0
160
Railsのためのパスキー実践入門 〜マルチテナントSaaSでの意思決定〜
utakaha
2
560
ハーネス設計入門 〜 基礎知識の整理から実務へのステップアップ 〜
kinopeee
28
32k
Starting & Sustaining Code-Based E2E Testing for Non-Coding QA Teams( #jasstniigata )
teyamagu
PRO
1
1k
Featured
See All Featured
No one is an island. Learnings from fostering a developers community.
thoeni
21
3.9k
Collaborative Software Design: How to facilitate domain modelling decisions
baasie
1
340
A better future with KSS
kneath
240
18k
Testing 201, or: Great Expectations
jmmastey
46
8.3k
A brief & incomplete history of UX Design for the World Wide Web: 1989–2019
jct
2
530
Statistics for Hackers
jakevdp
799
230k
How Software Deployment tools have changed in the past 20 years
geshan
2
35k
AI Search: Where Are We & What Can We Do About It?
aleyda
0
8.1k
The Anti-SEO Checklist Checklist. Pubcon Cyber Week
ryanjones
0
270
The Illustrated Guide to Node.js - THAT Conference 2024
reverentgeek
1
570
Breaking role norms: Why Content Design is so much more than writing copy - Taylor Woolridge
uxyall
1
450
Put a Button on it: Removing Barriers to Going Fast.
kastner
60
4.6k
Transcript
KubernetesでGPUを使おう ⼤阪⼯業⼤学 Dodai-Dodai
⾃⼰紹介 • Dodai-Dodai • ⼤阪⼯業⼤学 情報科学部 ネットワークデザイン学科4年 • 通信⽅式研究室 •
ネットワークやサーバーをいじってます • JANOG 55 NOC運営/ICTSC2024 運営
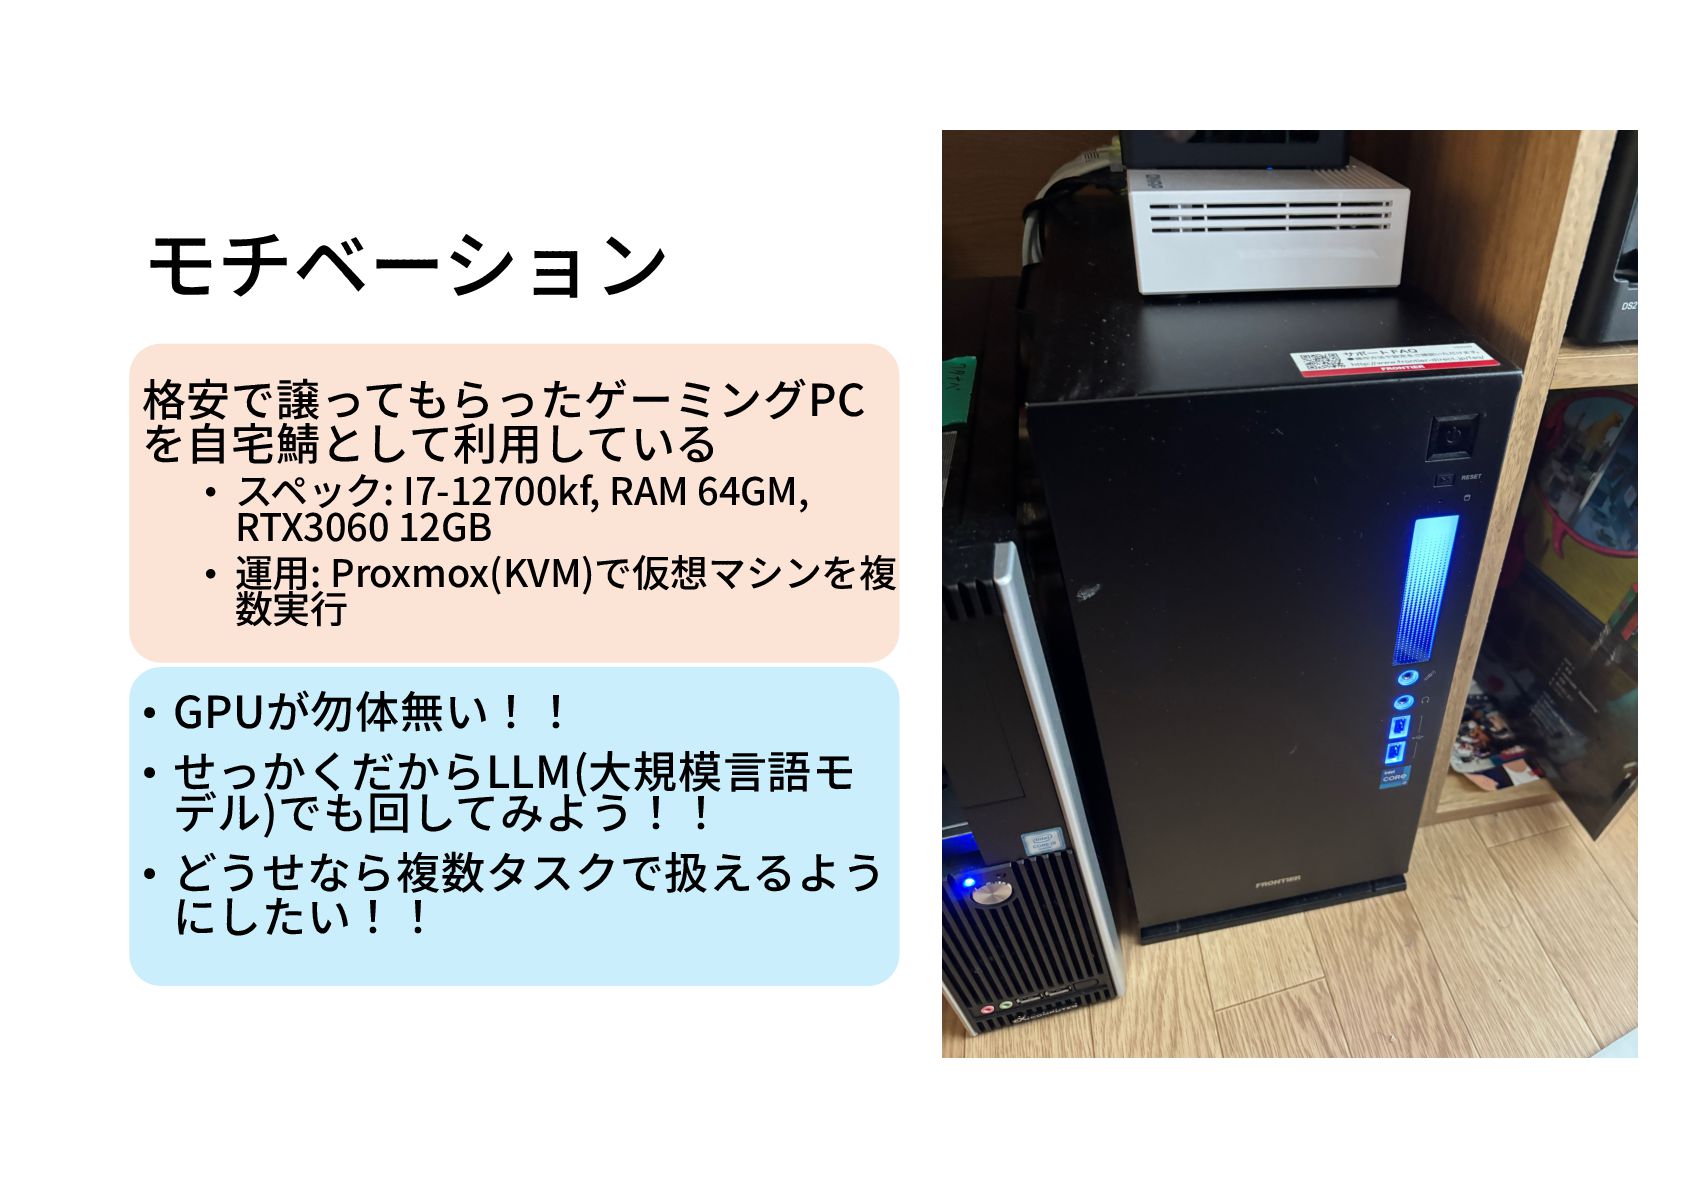
モチベーション 格安で譲ってもらったゲーミングPC を⾃宅鯖として利⽤している • スペック: I7-12700kf, RAM 64GM, RTX3060 12GB
• 運⽤: Proxmox(KVM)で仮想マシンを複 数実⾏ • GPUが勿体無い!! • せっかくだからLLM(⼤規模⾔語モ デル)でも回してみよう!! • どうせなら複数タスクで扱えるよう にしたい!!
仮想マシンでGPUを使う… • GeforceシリーズのGPUは、複数の仮想マシンで共有できな い。 • 1台のVMにしかパススルーできないため、リソースが固定される • これでは効率的にGPUを利⽤できない • NVIDIA
Container Toolkit & k8s-device-plugin がある • コンテナ単位でGPUを利⽤可能にするツール • DockerなどからGPUを利⽤可能となる • 加えてKubernetesを使えば、GPUを効率的に分配できる!
Kubernetesって? • 軽量な仮想マシン(コンテナ)を操作す るためのツール • コンテナの起動や停⽌、負荷分散や障 害からの復旧を⾃動で⾏う
環境構築 • Kubernetesには様々なディストリビューションがある • Kubeadm • Minikube • MicroK8s •
などなど 基本的にはこれらを構築した上で NVIDIAのGPUを利⽤する設定を⾏う
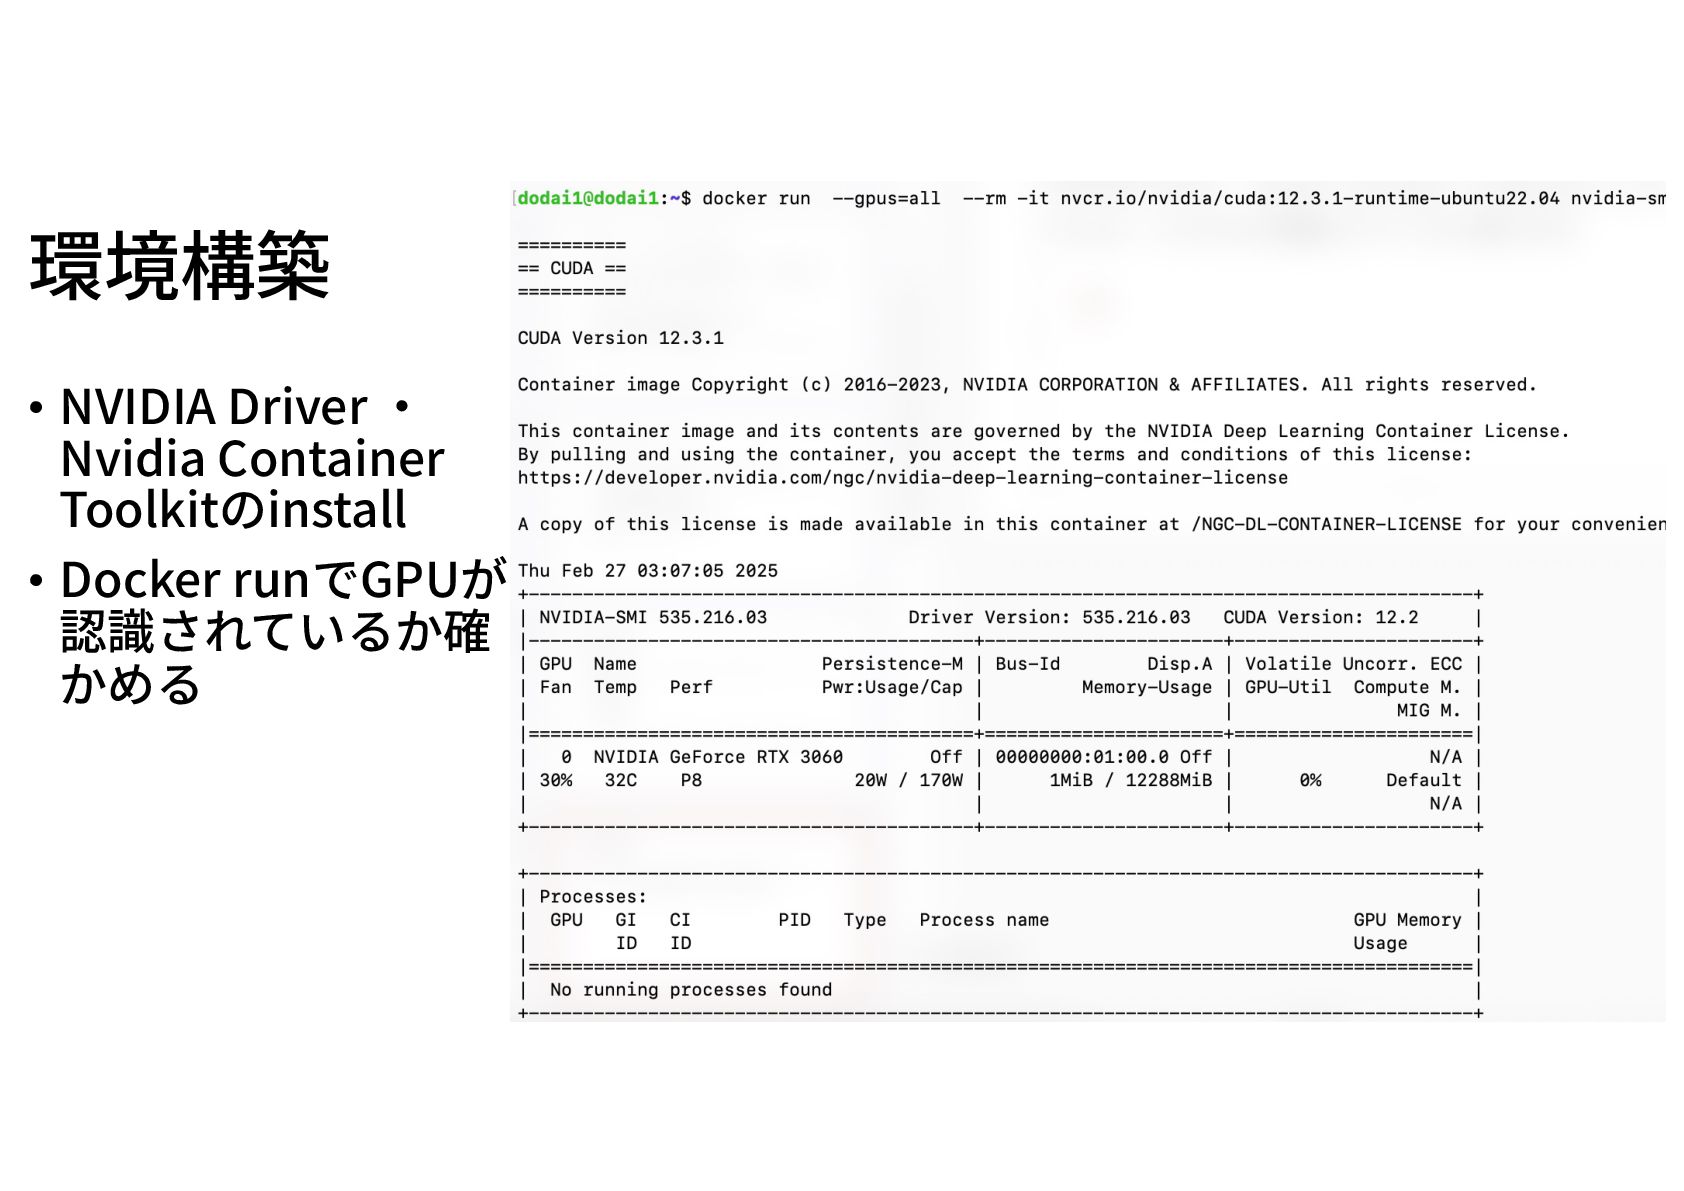
環境構築 • NVIDIA Driver ‧ Nvidia Container Toolkitのinstall • Docker
runでGPUが 認識されているか確 かめる
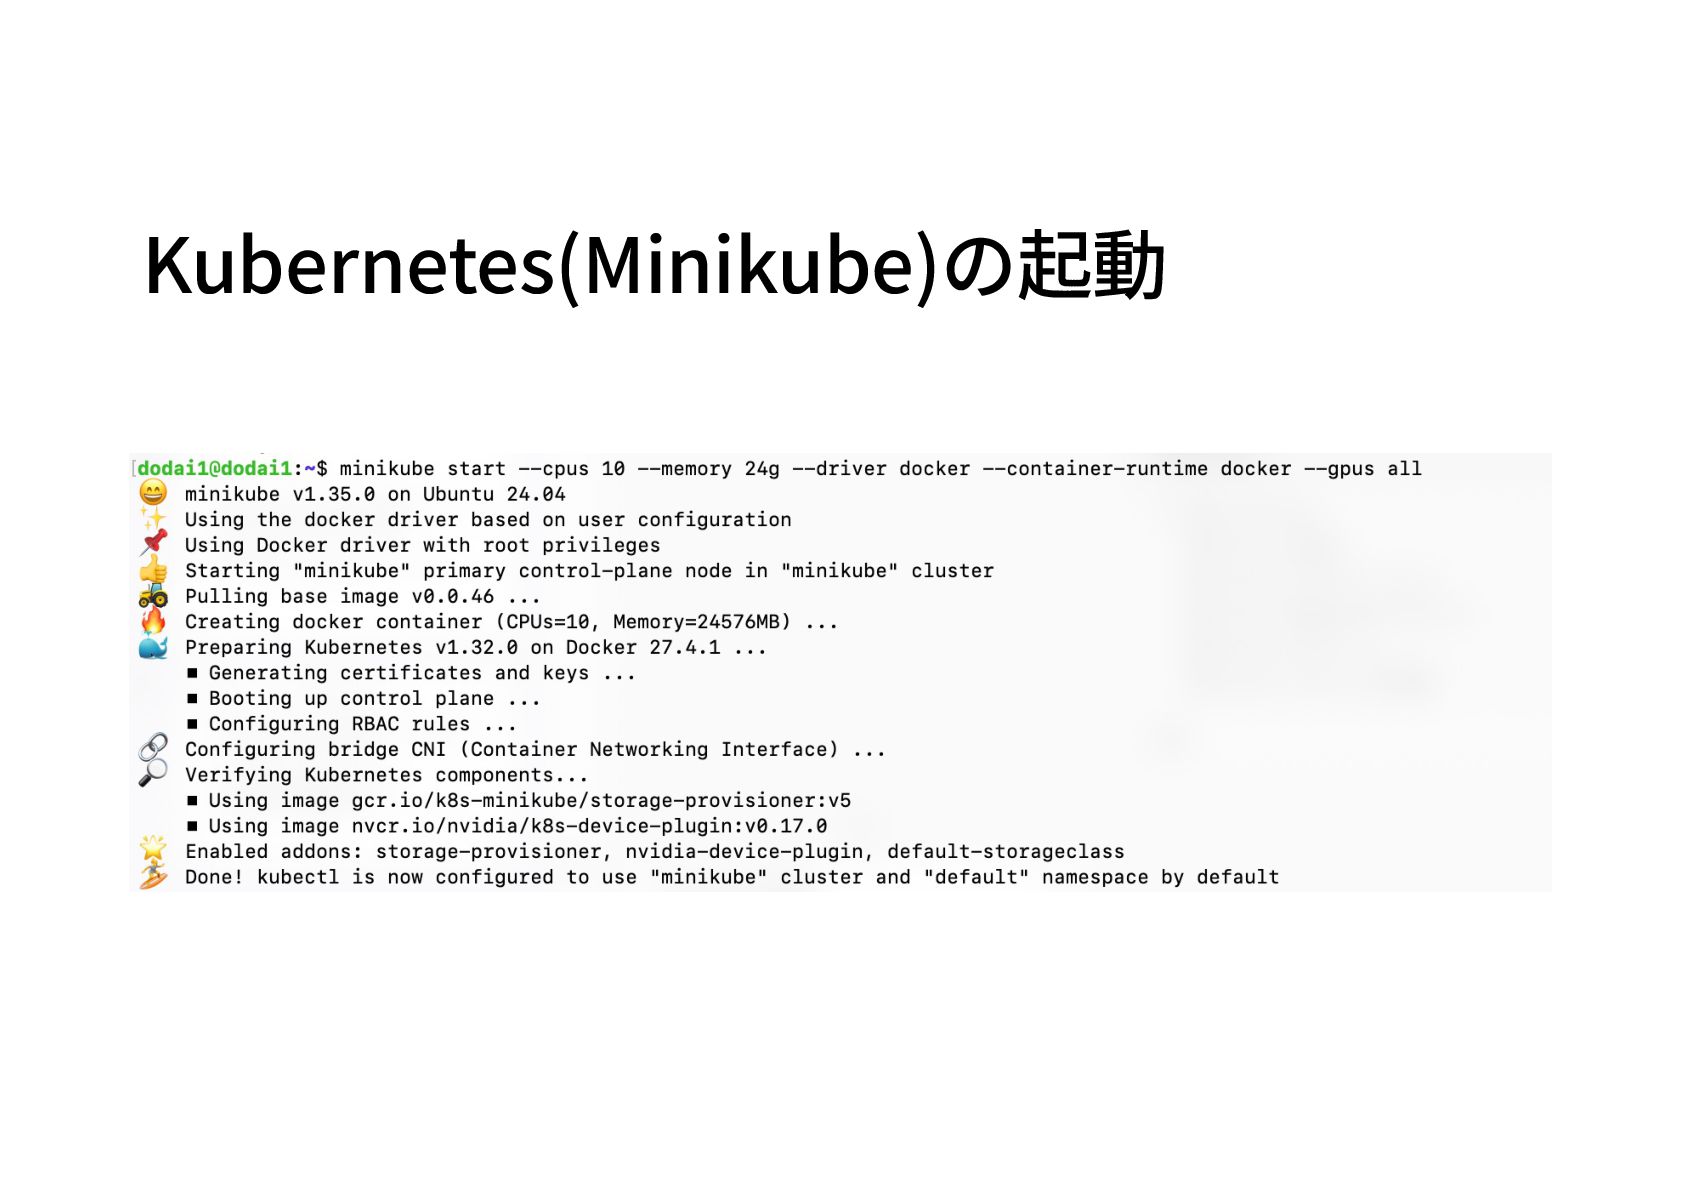
Kubernetes(Minikube)の起動
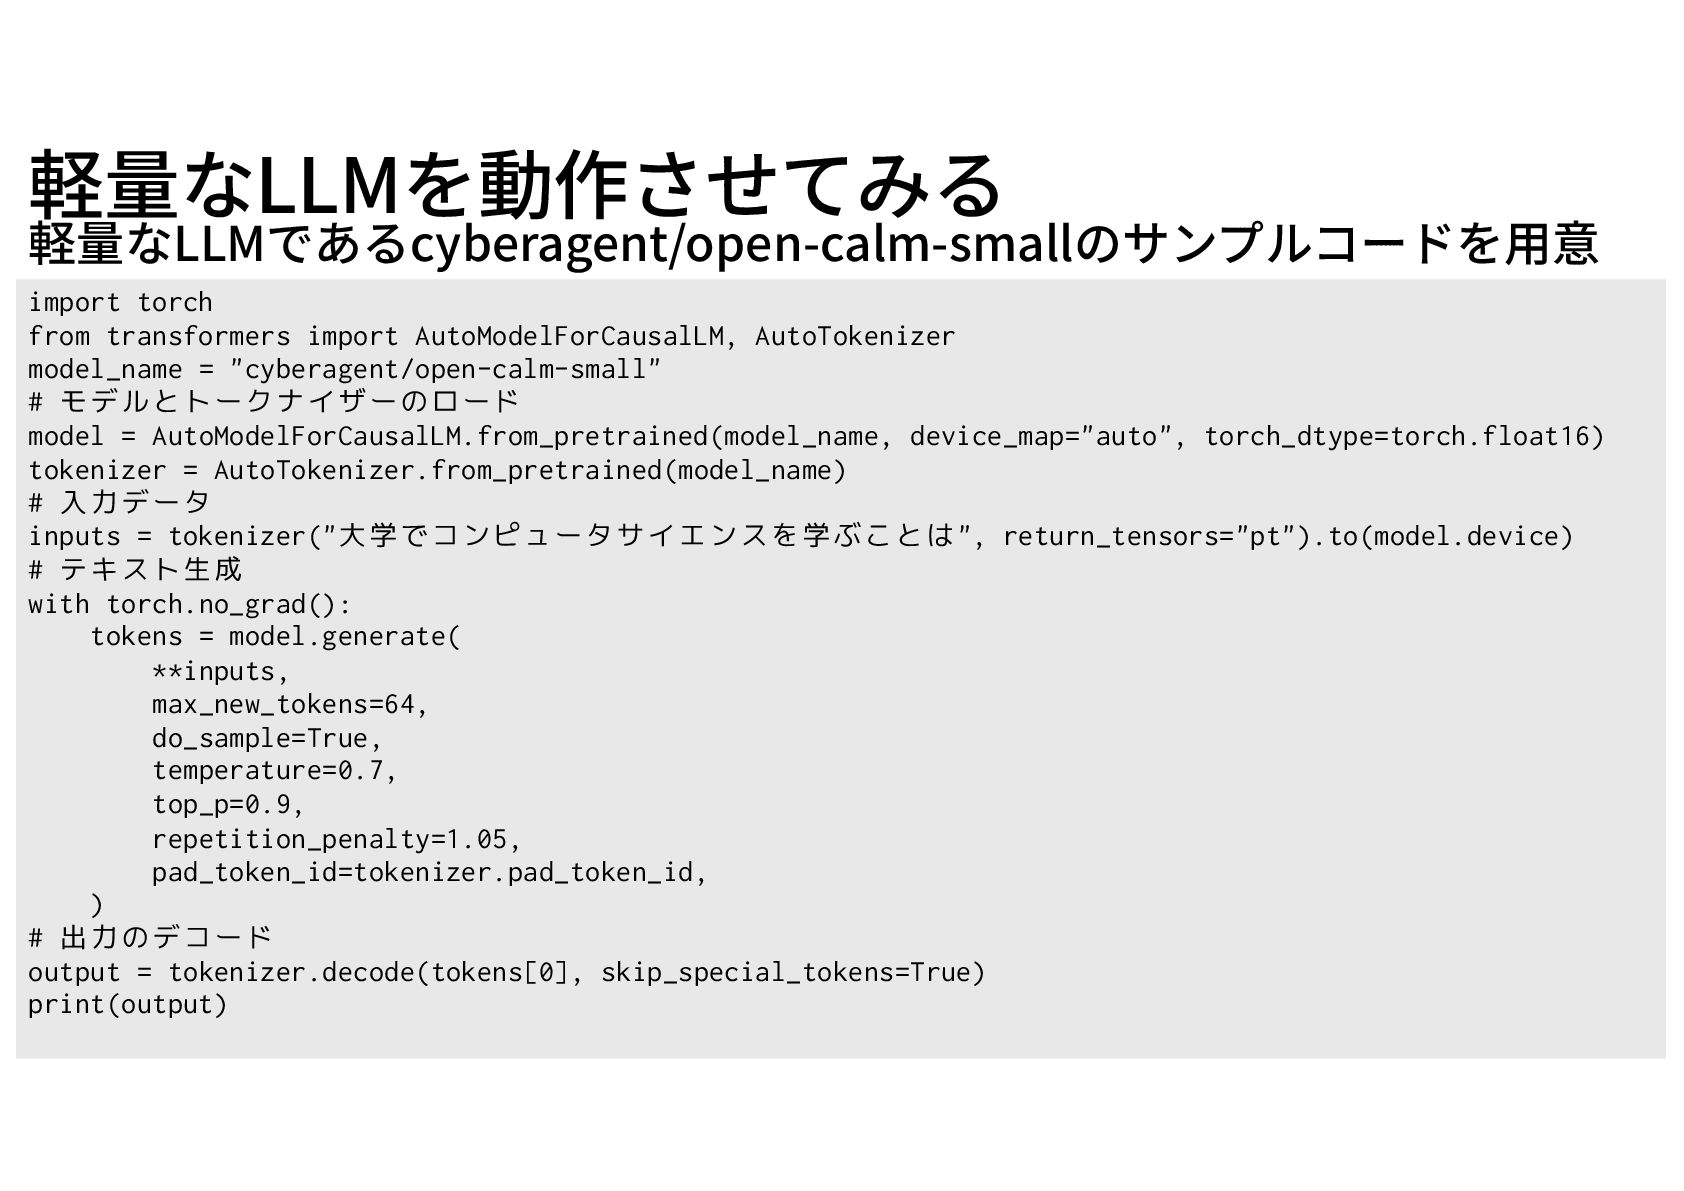
軽量なLLMを動作させてみる 軽量なLLMであるcyberagent/open-calm-smallのサンプルコードを⽤意 import torch from transformers import AutoModelForCausalLM, AutoTokenizer model_name
= "cyberagent/open-calm-small" # モデルとトークナイザーのロード model = AutoModelForCausalLM.from_pretrained(model_name, device_map="auto", torch_dtype=torch.float16) tokenizer = AutoTokenizer.from_pretrained(model_name) # 入力データ inputs = tokenizer("大学でコンピュータサイエンスを学ぶことは", return_tensors="pt").to(model.device) # テキスト生成 with torch.no_grad(): tokens = model.generate( **inputs, max_new_tokens=64, do_sample=True, temperature=0.7, top_p=0.9, repetition_penalty=1.05, pad_token_id=tokenizer.pad_token_id, ) # 出力のデコード output = tokenizer.decode(tokens[0], skip_special_tokens=True) print(output)
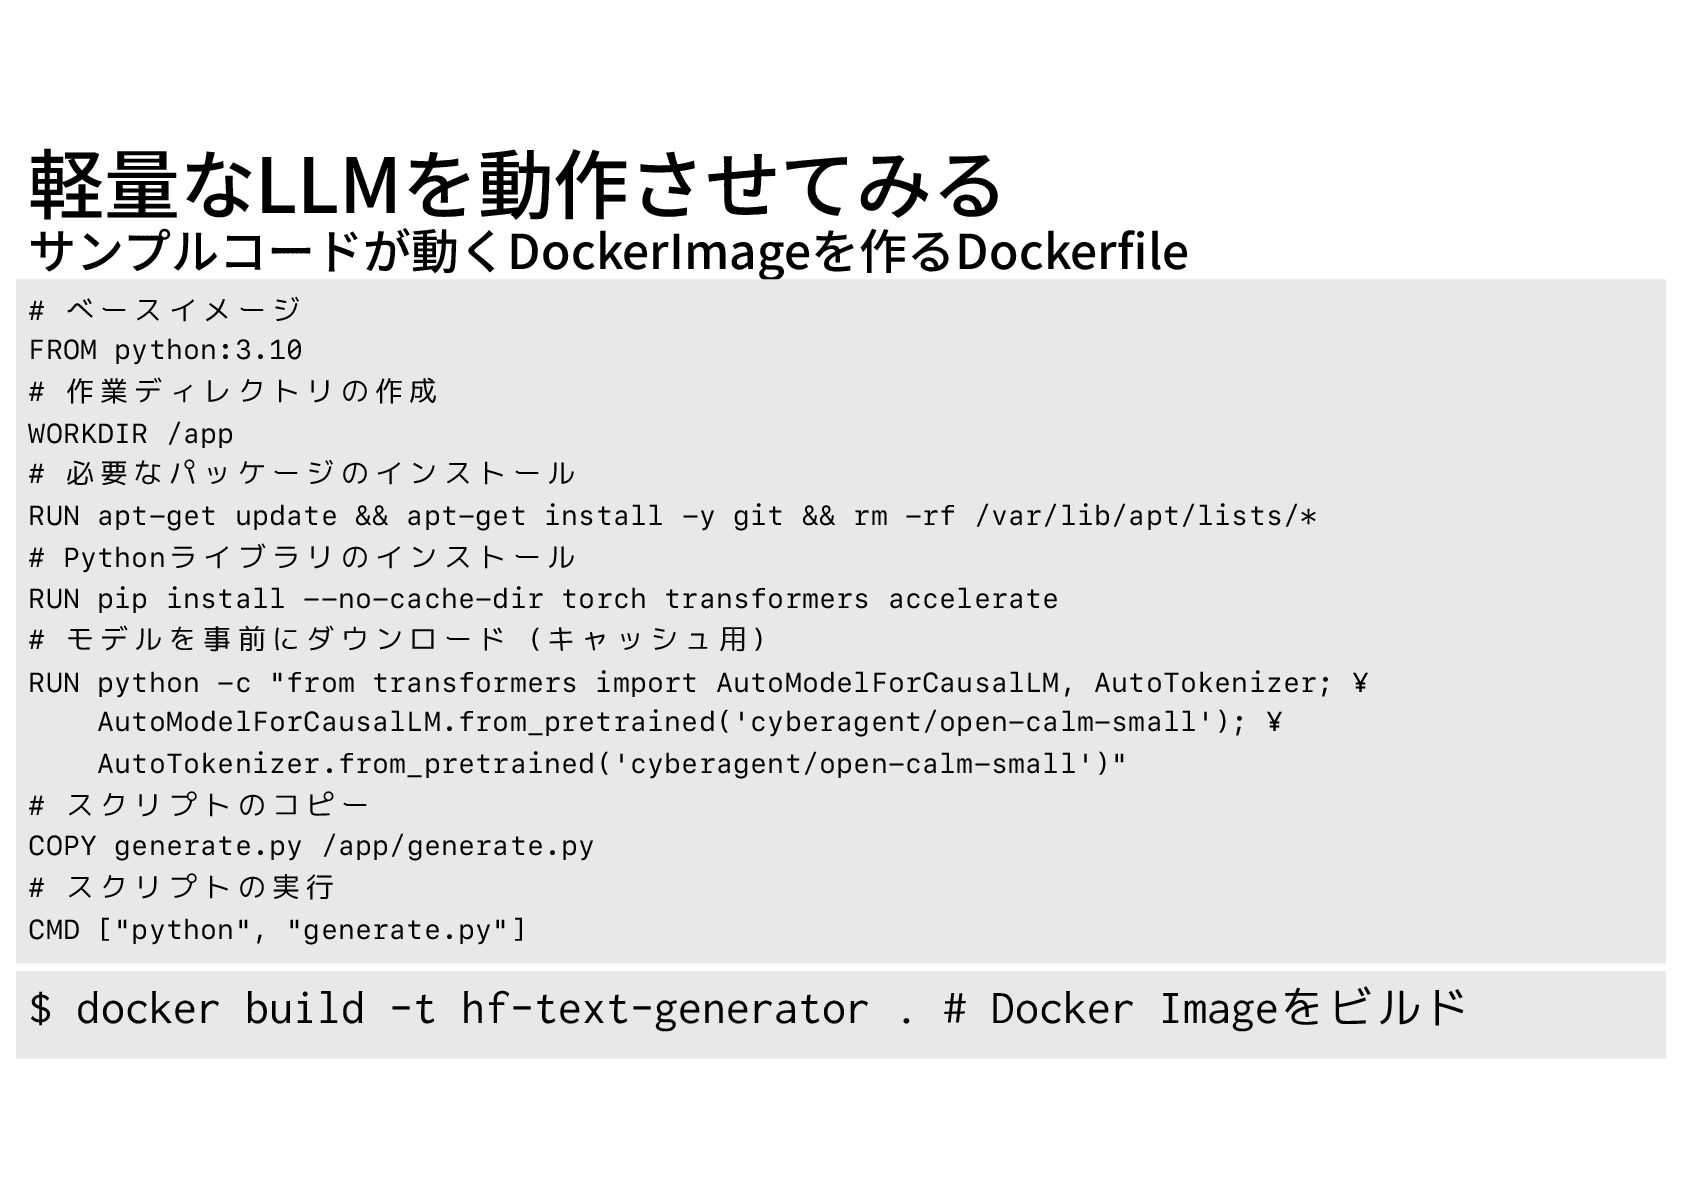
軽量なLLMを動作させてみる サンプルコードが動くDockerImageを作るDockerfile # ベースイメージ FROM python:3.10 # 作業ディレクトリの作成 WORKDIR /app
# 必要なパッケージのインストール RUN apt-get update && apt-get install -y git && rm -rf /var/lib/apt/lists/* # Pythonライブラリのインストール RUN pip install --no-cache-dir torch transformers accelerate # モデルを事前にダウンロード(キャッシュ用) RUN python -c "from transformers import AutoModelForCausalLM, AutoTokenizer; ¥ AutoModelForCausalLM.from_pretrained('cyberagent/open-calm-small'); ¥ AutoTokenizer.from_pretrained('cyberagent/open-calm-small')" # スクリプトのコピー COPY generate.py /app/generate.py # スクリプトの実行 CMD ["python", "generate.py"] $ docker build -t hf-text-generator . # Docker Imageをビルド
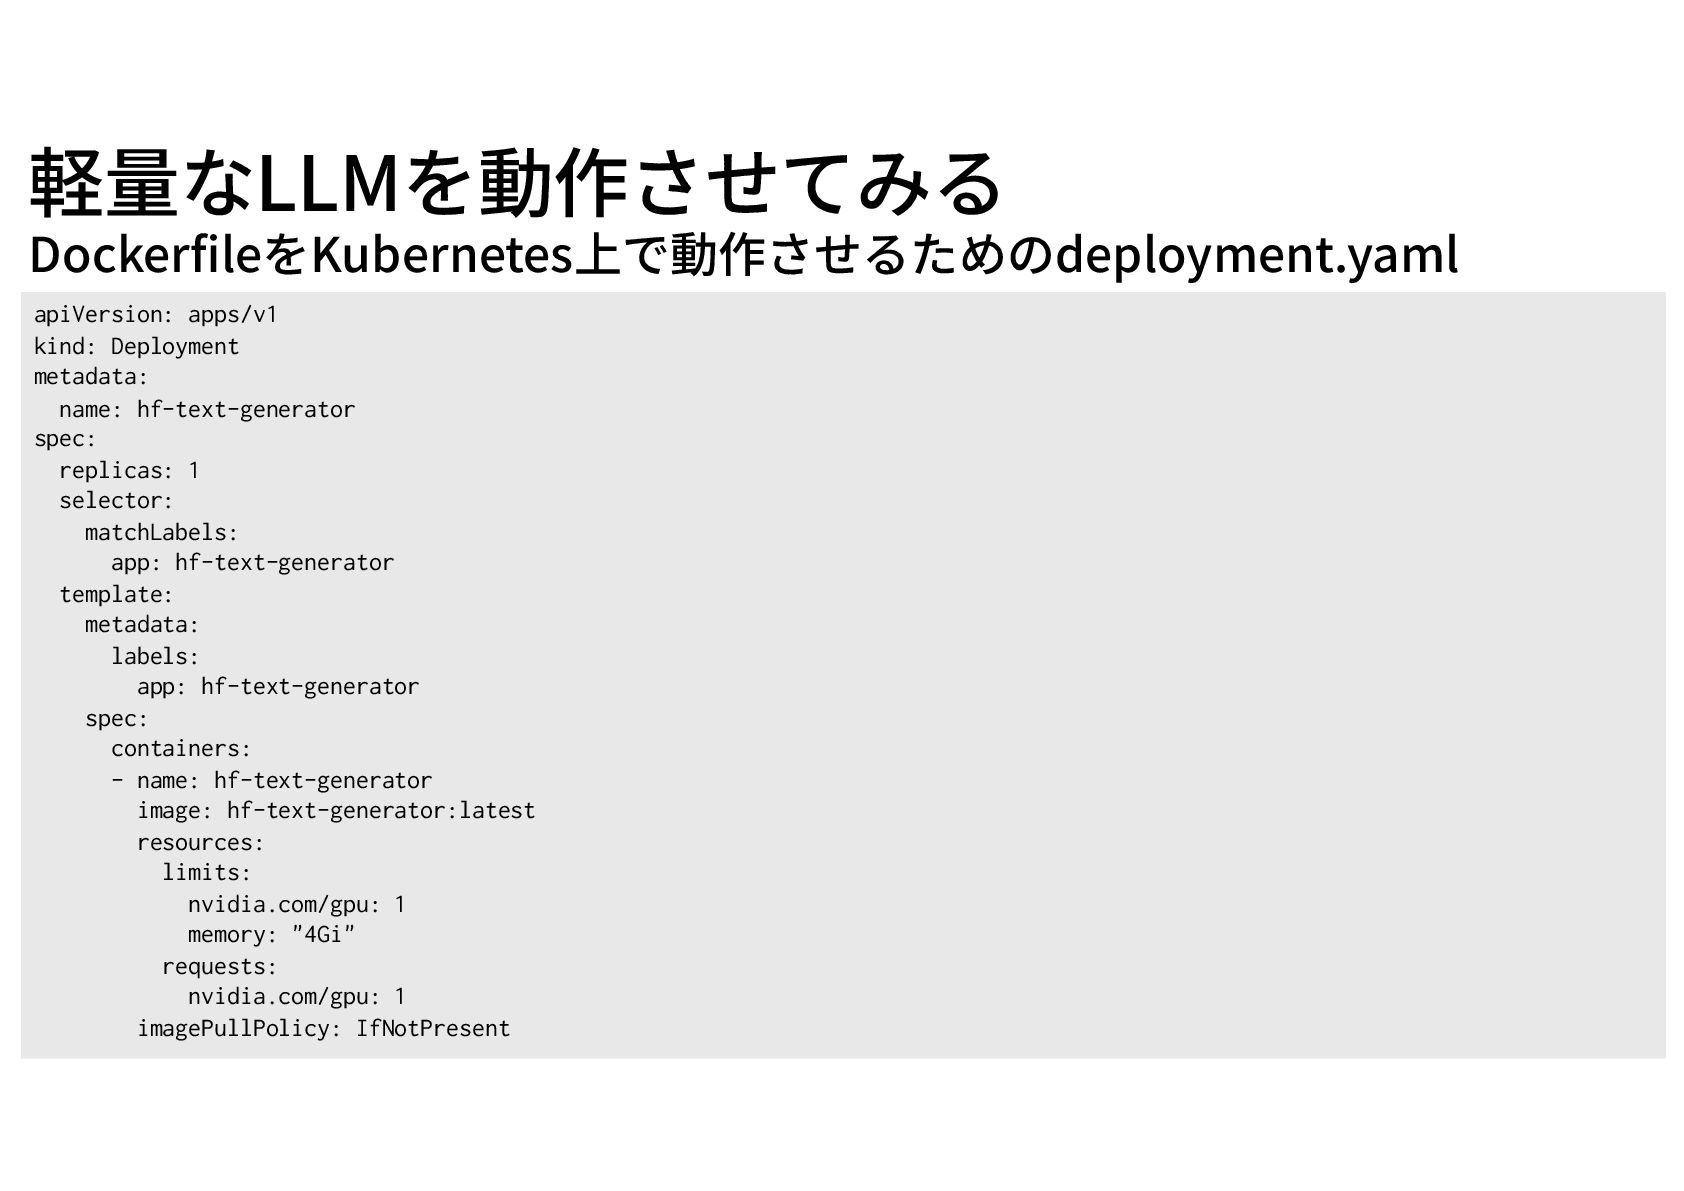
軽量なLLMを動作させてみる DockerfileをKubernetes上で動作させるためのdeployment.yaml apiVersion: apps/v1 kind: Deployment metadata: name: hf-text-generator spec:
replicas: 1 selector: matchLabels: app: hf-text-generator template: metadata: labels: app: hf-text-generator spec: containers: - name: hf-text-generator image: hf-text-generator:latest resources: limits: nvidia.com/gpu: 1 memory: "4Gi" requests: nvidia.com/gpu: 1 imagePullPolicy: IfNotPresent
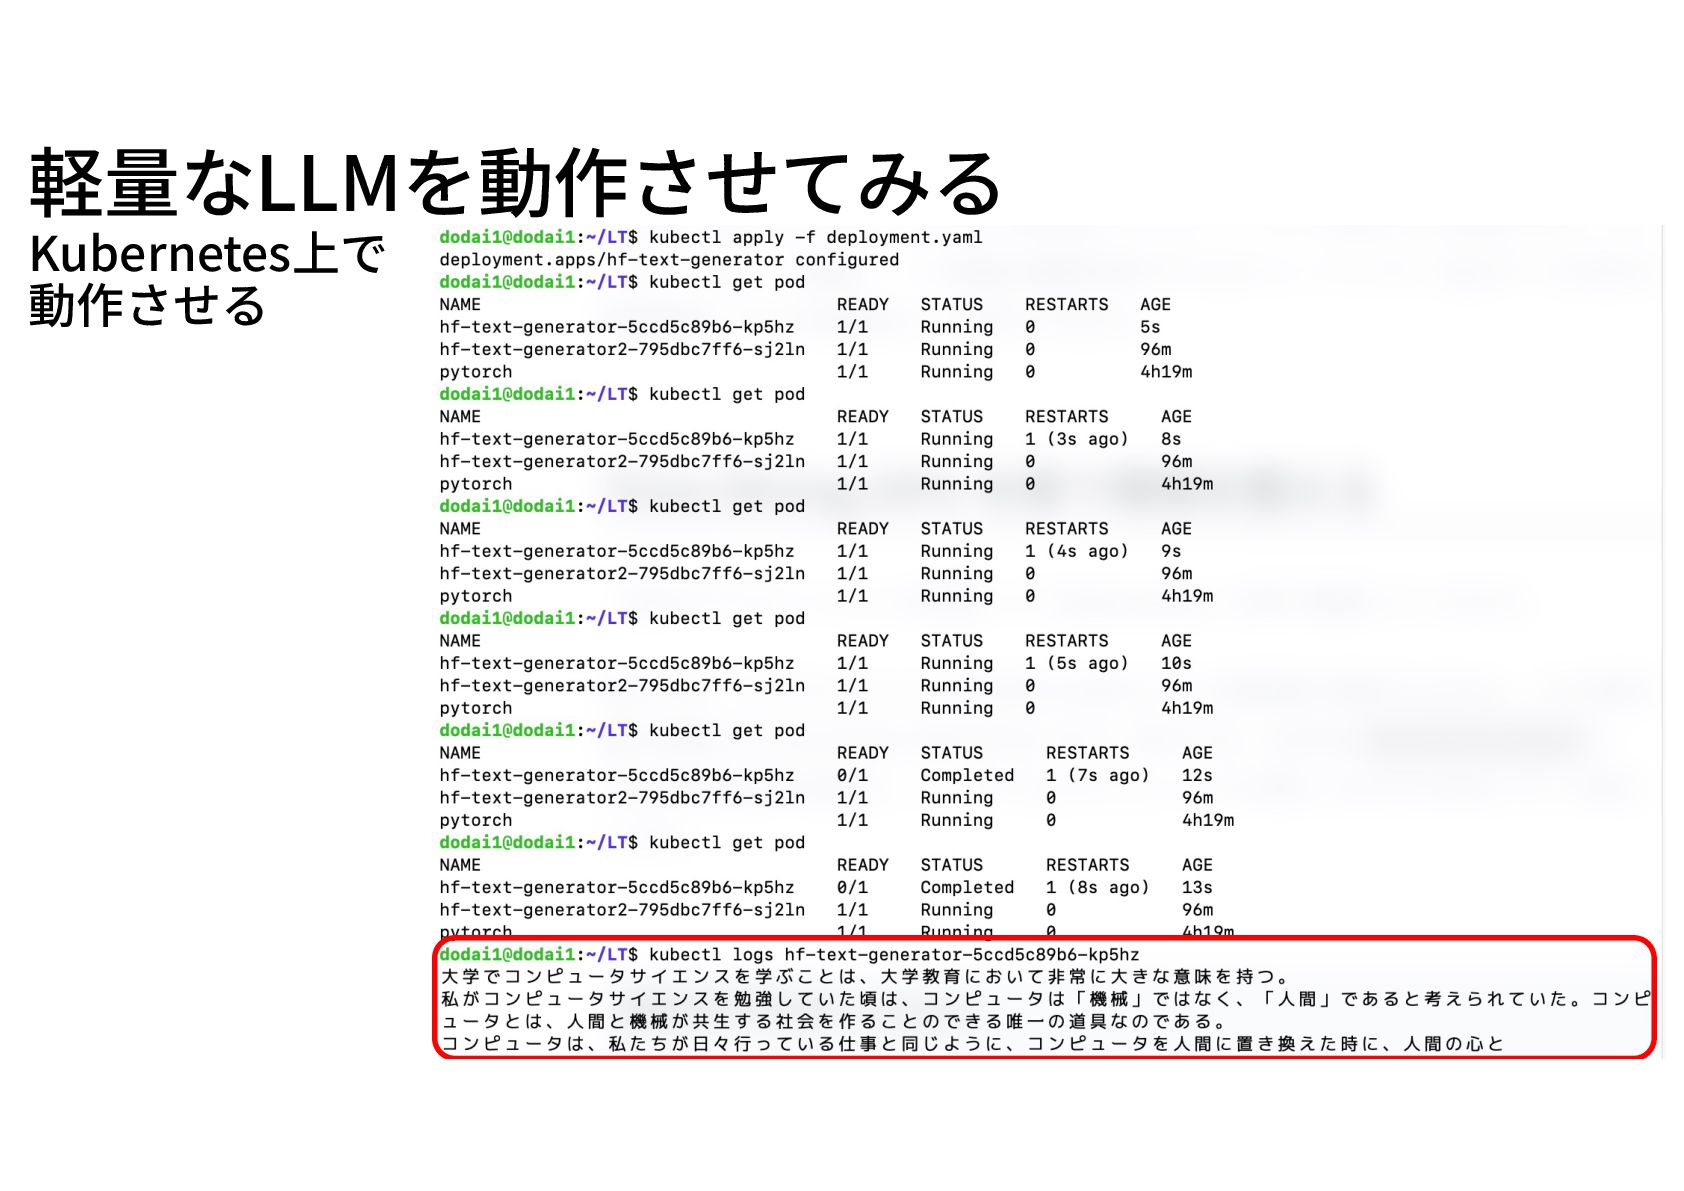
軽量なLLMを動作させてみる Kubernetes上で 動作させる
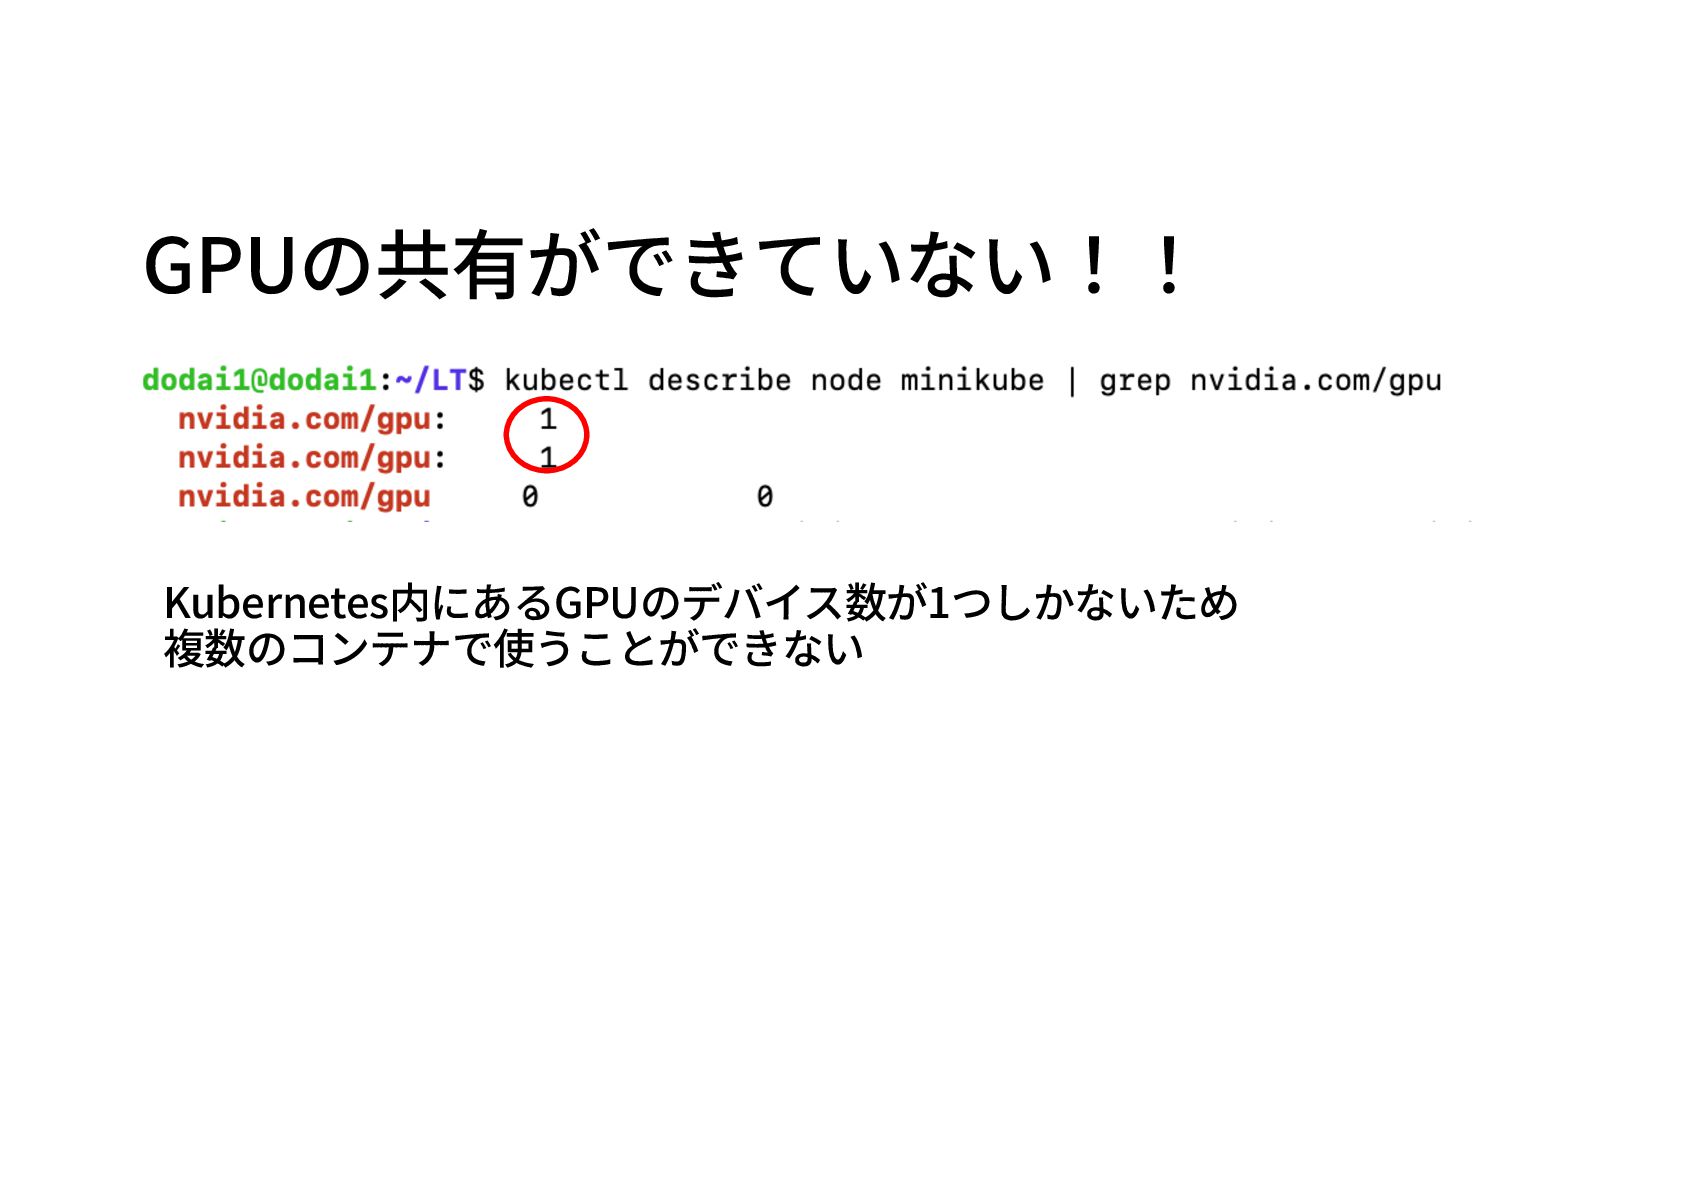
GPUの共有ができていない!! Kubernetes内にあるGPUのデバイス数が1つしかないため 複数のコンテナで使うことができない
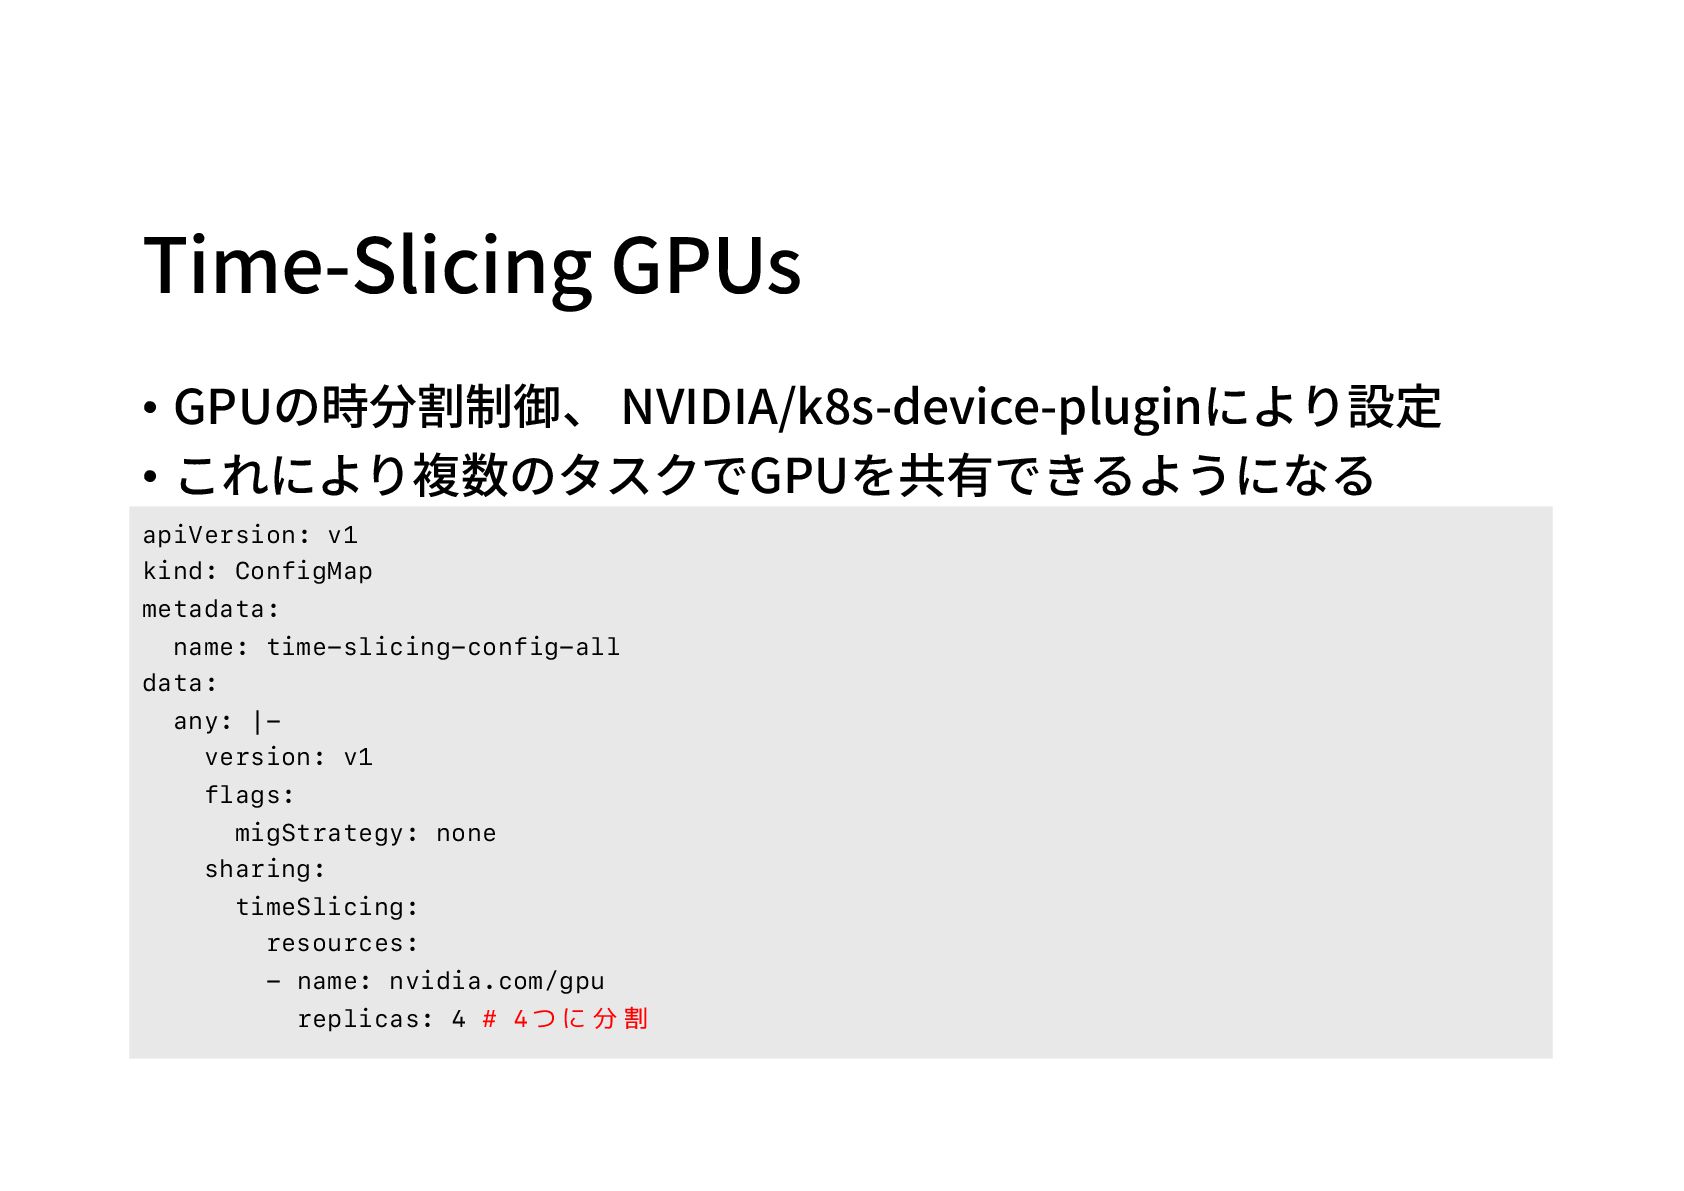
Time-Slicing GPUs • GPUの時分割制御、 NVIDIA/k8s-device-pluginにより設定 • これにより複数のタスクでGPUを共有できるようになる apiVersion: v1 kind:
ConfigMap metadata: name: time-slicing-config-all data: any: |- version: v1 flags: migStrategy: none sharing: timeSlicing: resources: - name: nvidia.com/gpu replicas: 4 # 4つに分割
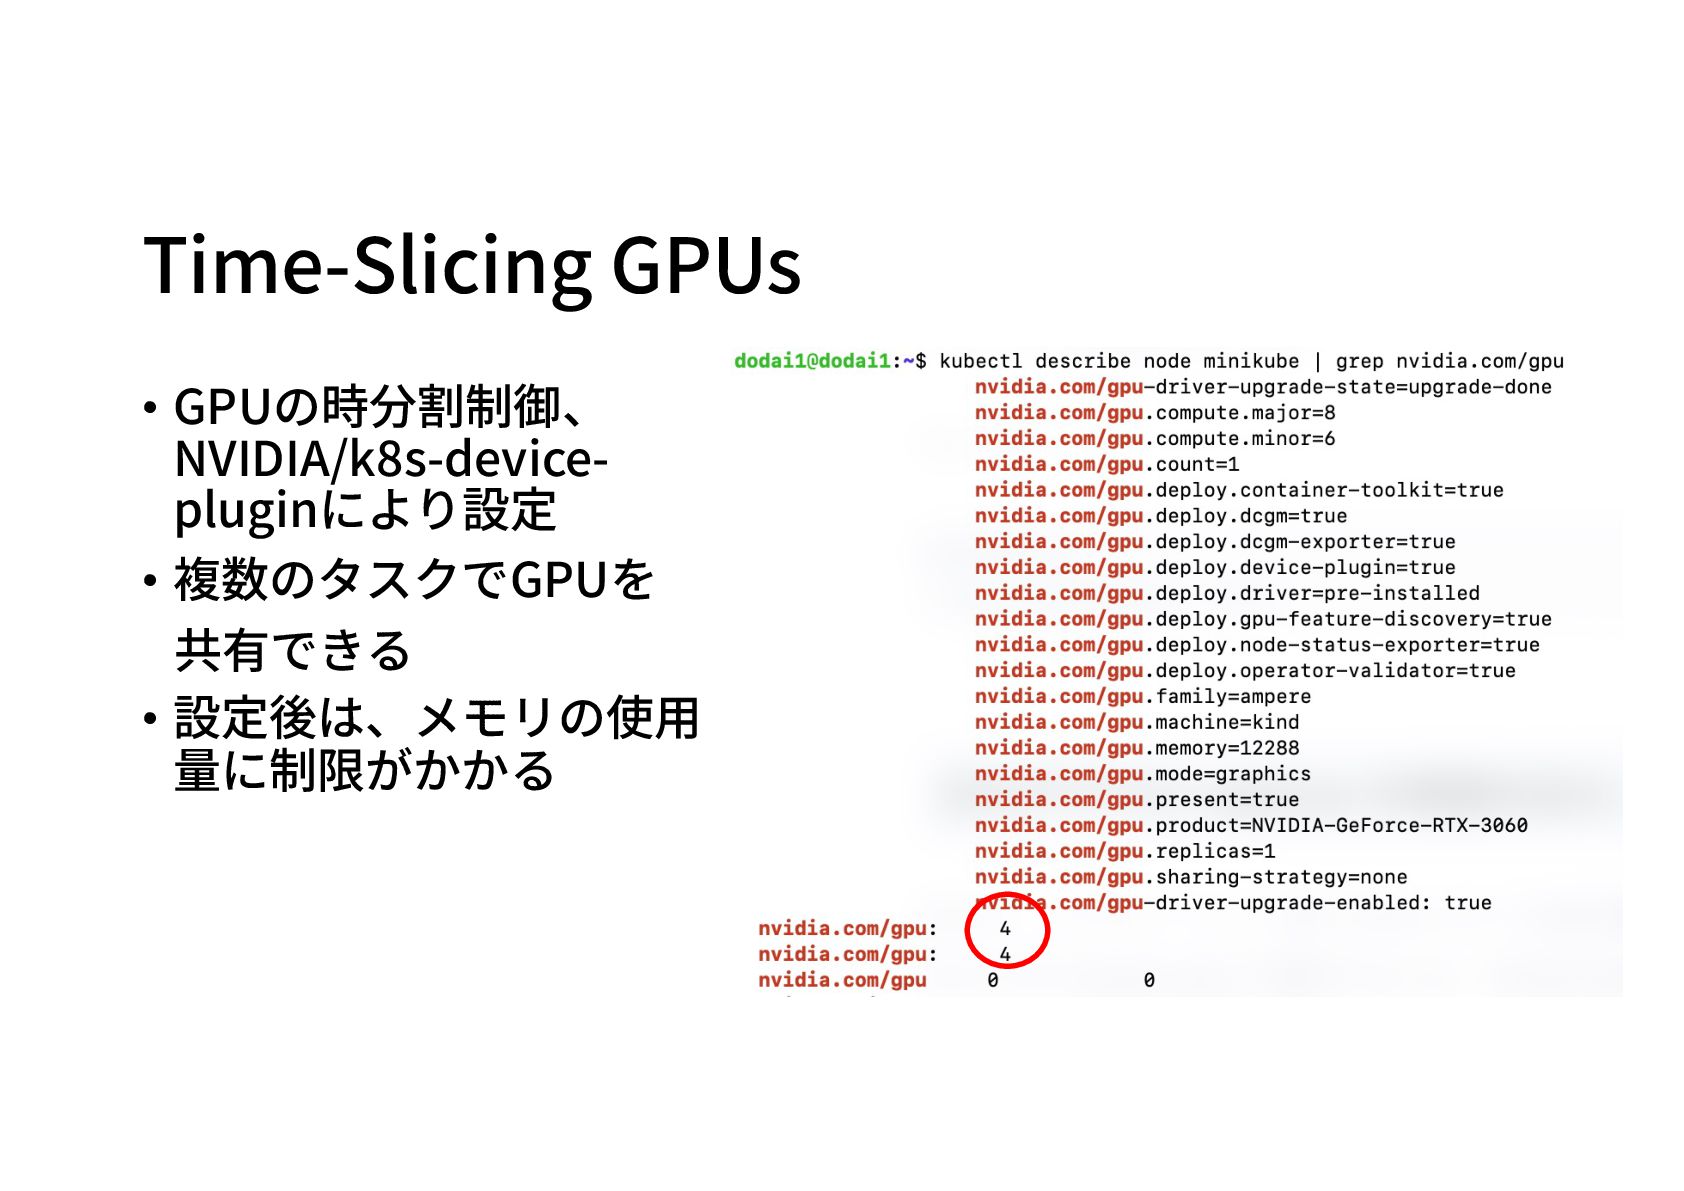
Time-Slicing GPUs • GPUの時分割制御、 NVIDIA/k8s-device- pluginにより設定 • 複数のタスクでGPUを 共有できる •
設定後は、メモリの使⽤ 量に制限がかかる
感想 • 業務⽤の⾼いGPUを調達することなく、GPUを複数タスクで共 有できる環境ができたのはよかったところ • (当然ながら)分割によりVRAMの制限が厳しくなるのでワーク ロードの向き不向きが出てしまうのは⽋点 • 結局、複数台のGPUがあることがベストプラクティスかも…


 ryu1013
 optim
 nabondance
 akit37
 sorah
 kasacchiful
 satoshi256kbyte
 a_matsuda
 naokihaba
 utakaha
 kinopeee
 teyamagu
 thoeni
 baasie
 kneath
 jmmastey
 jct
 jakevdp
 geshan
 aleyda
 ryanjones
 reverentgeek
 uxyall
 kastner