Share
Embed
Introducing mlflow
Databricks가 2018년 6월 발표한 기계학습 작업 관리 시스템, mlflow에 대한 소개.
2018년 8월, 비공개 그룹 발표.
Introduces mlflow, a Machine Learning task maintaining system developed, released & open sourced by Databricks in June 2018.
Presented in a non-public group in August 2018.
Slides: English. Presentation: Korean.
Lee Dongjin
August 17, 2018
Transcript
15 slides
-
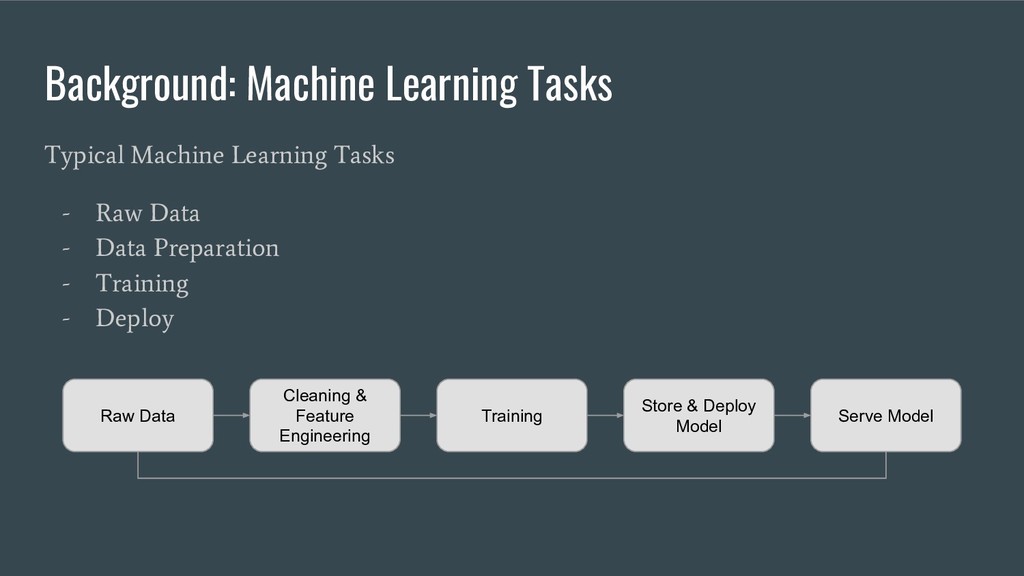
Background: Machine Learning Tasks Typical Machine Learning Tasks - Raw
Data - Data Preparation - Training - Deploy Cleaning & Feature Engineering Raw Data Training Serve Model Store & Deploy Model -
Problem: Continuous, Complex, and Difficult • Continuous ◦ Closely-coupled stages
◦ Repetitive • Complex ◦ Countless tools (tensorflow, scikit learn, spark, ...) ◦ Complex dependencies (tons of libraries ...) ◦ Complex model metadata: command, parameters, metrics, ... • Difficult ◦ Manually operated, one by one ◦ Hard to share & reproduce the results ◦ Hard to deploy - Scalability -
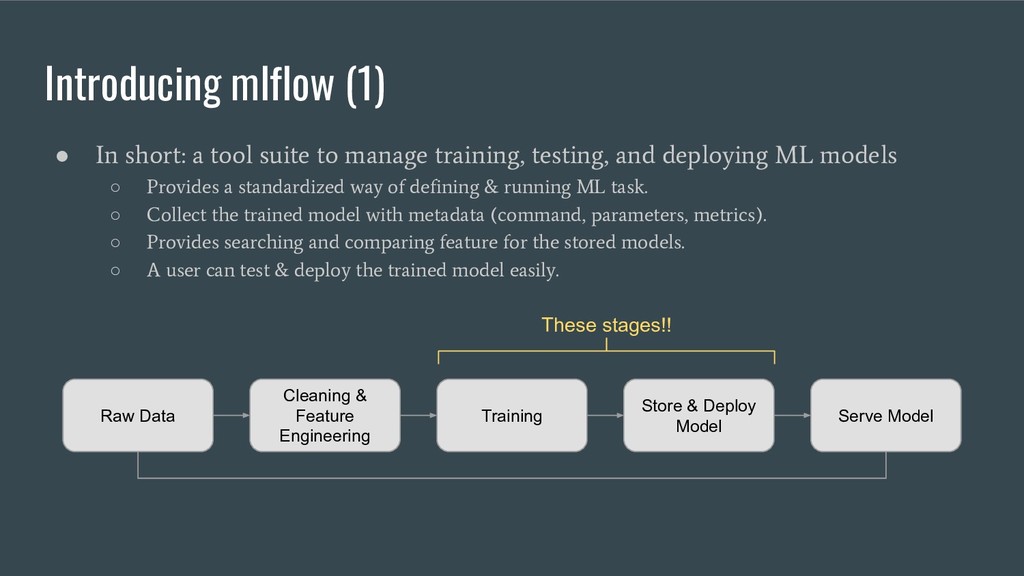
Introducing mlflow (1) • In short: a tool suite to
manage training, testing, and deploying ML models ◦ Provides a standardized way of defining & running ML task. ◦ Collect the trained model with metadata (command, parameters, metrics). ◦ Provides searching and comparing feature for the stored models. ◦ A user can test & deploy the trained model easily. Cleaning & Feature Engineering Raw Data Training Serve Model Store & Deploy Model These stages!! -
Introducing mlflow (2) • Overall ◦ Consists of Server &
Client ◦ Supports REST API & CLI ◦ Modular system: easy to integrate with into existing ML platforms & workflows • Server ◦ Stores trained model with metadata (command, parameters, metrics, ...) ◦ Provides functionality to search, compare & deploy trained model ◦ You can use hosted version: https://databricks.com/mlflow • Client ◦ Run Machine Learning task in standardized way (python code) ◦ Report metadata to Server -
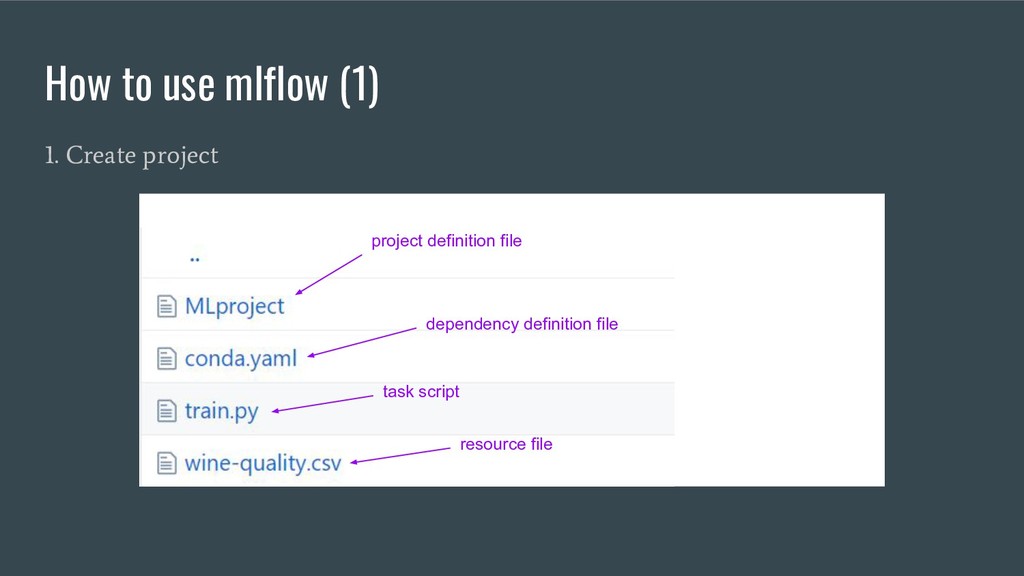
How to use mlflow (1) 1. Create project project definition
file dependency definition file resource file task script -
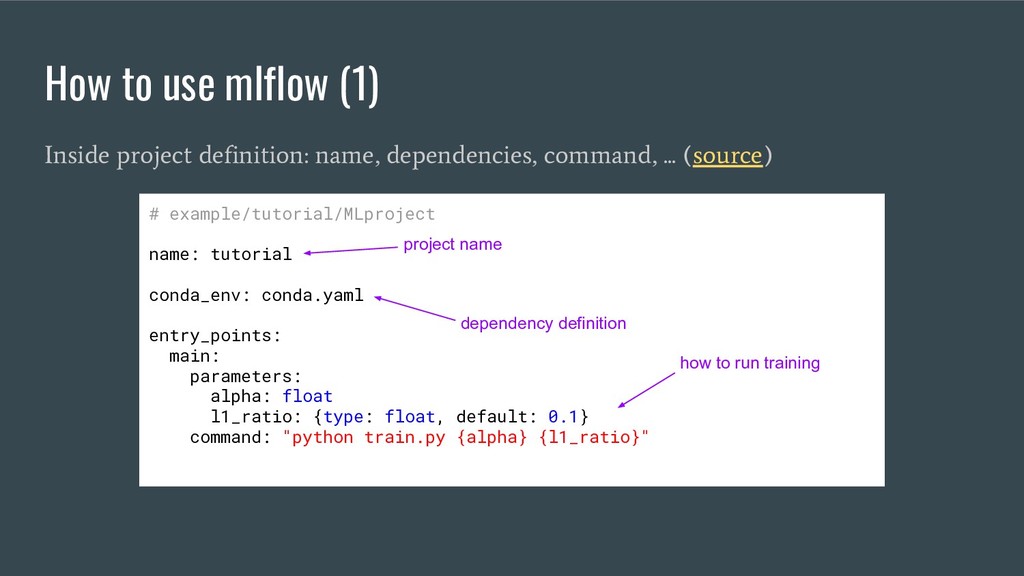
How to use mlflow (1) Inside project definition: name, dependencies,
command, ... (source) # example/tutorial/MLproject name: tutorial conda_env: conda.yaml entry_points: main: parameters: alpha: float l1_ratio: {type: float, default: 0.1} command: "python train.py {alpha} {l1_ratio}" project name dependency definition how to run training -
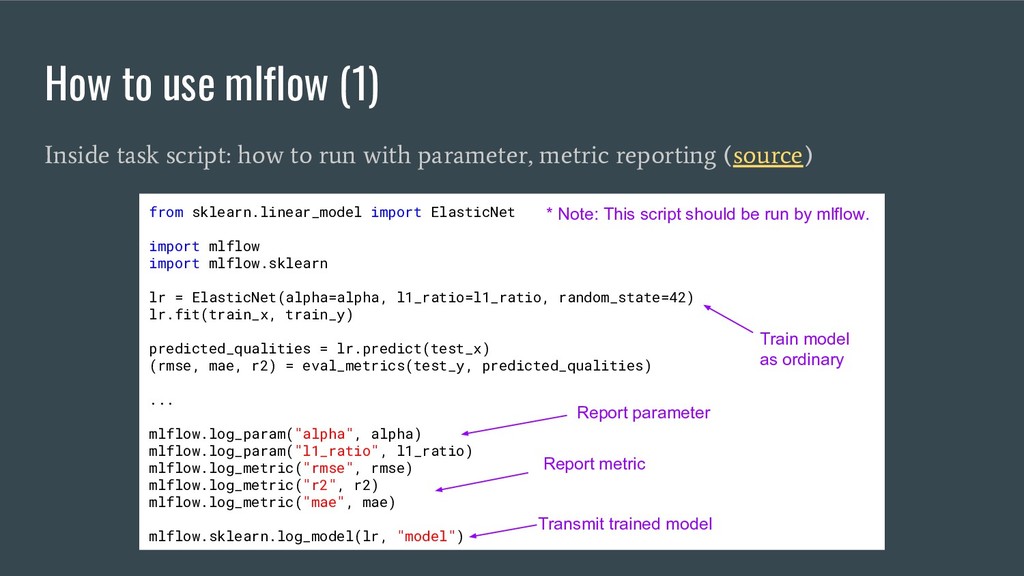
How to use mlflow (1) Inside task script: how to
run with parameter, metric reporting (source) from sklearn.linear_model import ElasticNet import mlflow import mlflow.sklearn lr = ElasticNet(alpha=alpha, l1_ratio=l1_ratio, random_state=42) lr.fit(train_x, train_y) predicted_qualities = lr.predict(test_x) (rmse, mae, r2) = eval_metrics(test_y, predicted_qualities) ... mlflow.log_param("alpha", alpha) mlflow.log_param("l1_ratio", l1_ratio) mlflow.log_metric("rmse", rmse) mlflow.log_metric("r2", r2) mlflow.log_metric("mae", mae) mlflow.sklearn.log_model(lr, "model") * Note: This script should be run by mlflow. Train model as ordinary Report parameter Report metric Transmit trained model -
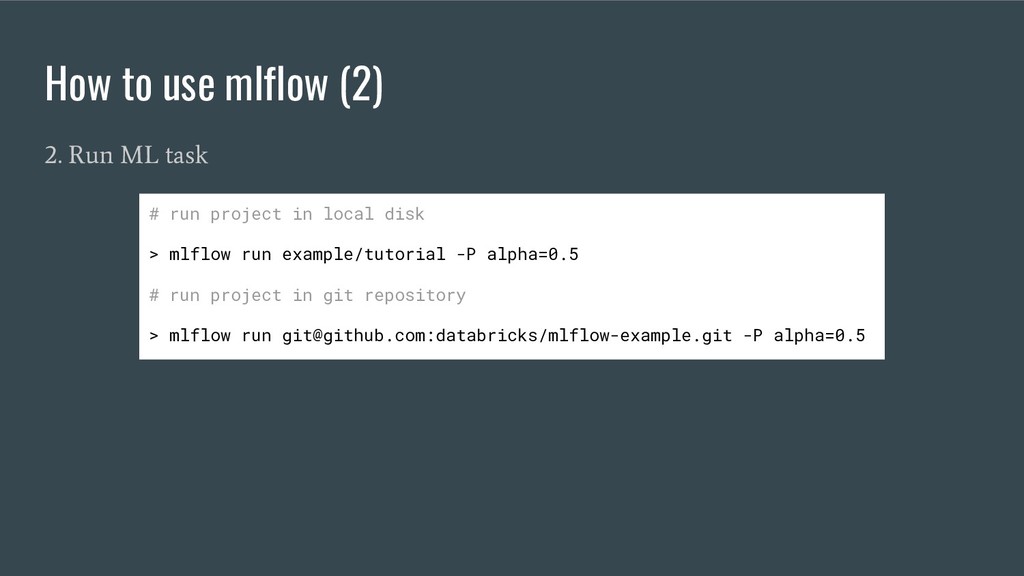
How to use mlflow (2) 2. Run ML task #
run project in local disk > mlflow run example/tutorial -P alpha=0.5 # run project in git repository > mlflow run [email protected]:databricks/mlflow-example.git -P alpha=0.5 -
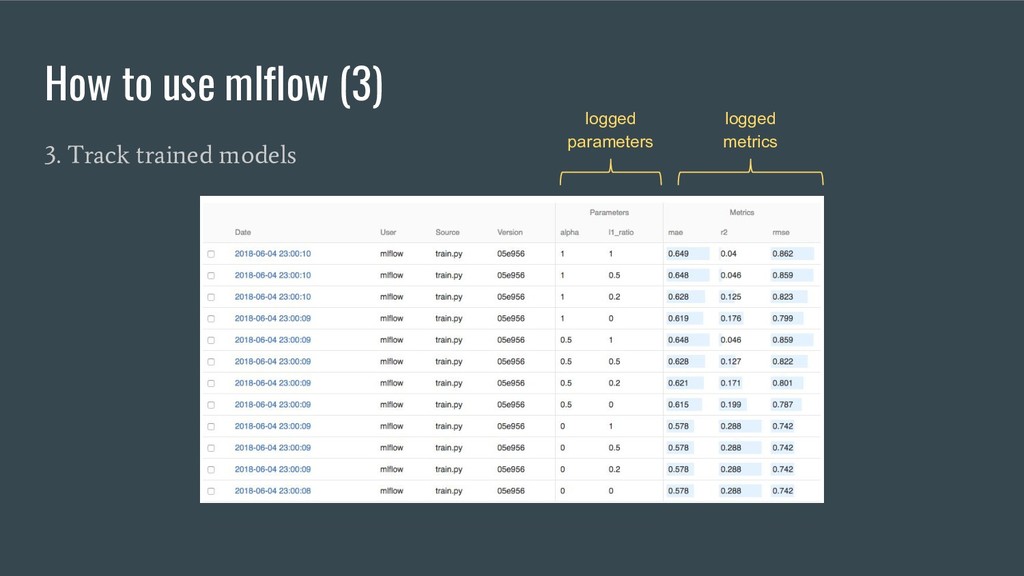
How to use mlflow (3) 3. Track trained models logged
parameters logged metrics -
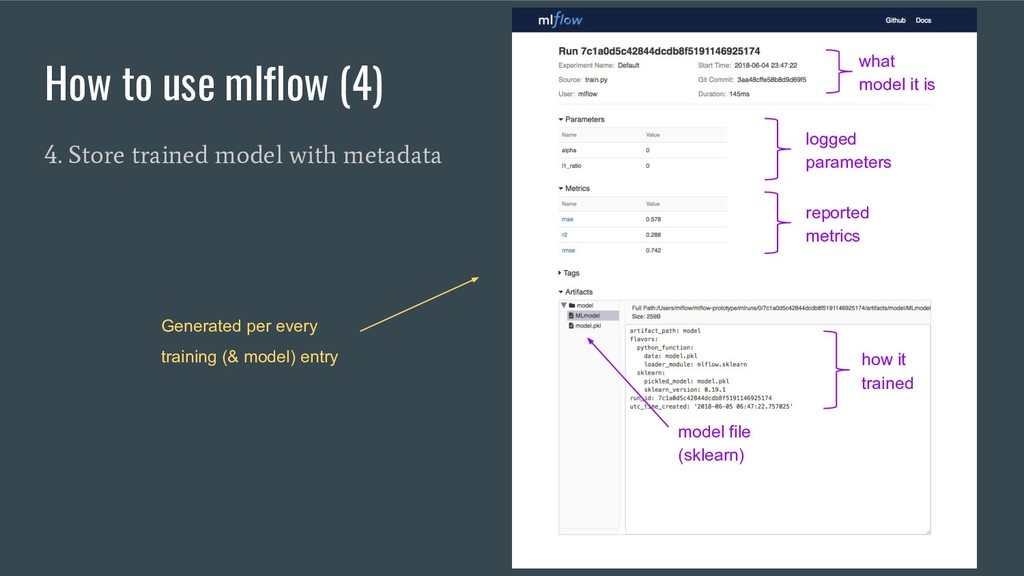
How to use mlflow (4) 4. Store trained model with
metadata what model it is logged parameters reported metrics how it trained model file (sklearn) Generated per every training (& model) entry -
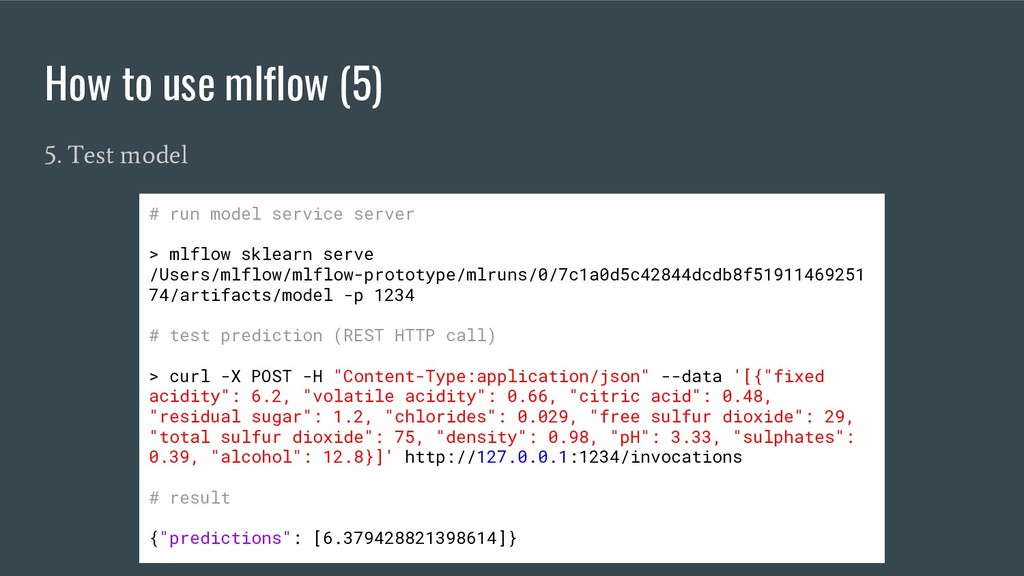
How to use mlflow (5) 5. Test model # run
model service server > mlflow sklearn serve /Users/mlflow/mlflow-prototype/mlruns/0/7c1a0d5c42844dcdb8f51911469251 74/artifacts/model -p 1234 # test prediction (REST HTTP call) > curl -X POST -H "Content-Type:application/json" --data '[{"fixed acidity": 6.2, "volatile acidity": 0.66, "citric acid": 0.48, "residual sugar": 1.2, "chlorides": 0.029, "free sulfur dioxide": 29, "total sulfur dioxide": 75, "density": 0.98, "pH": 3.33, "sulphates": 0.39, "alcohol": 12.8}]' http://127.0.0.1:1234/invocations # result {"predictions": [6.379428821398614]} -
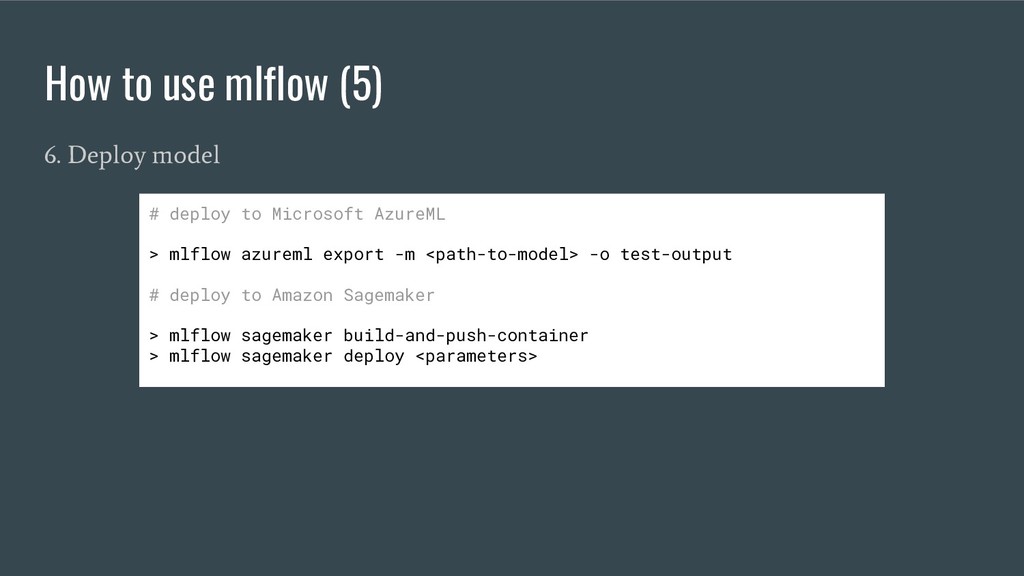
How to use mlflow (5) 6. Deploy model # deploy
to Microsoft AzureML > mlflow azureml export -m <path-to-model> -o test-output # deploy to Amazon Sagemaker > mlflow sagemaker build-and-push-container > mlflow sagemaker deploy <parameters> -
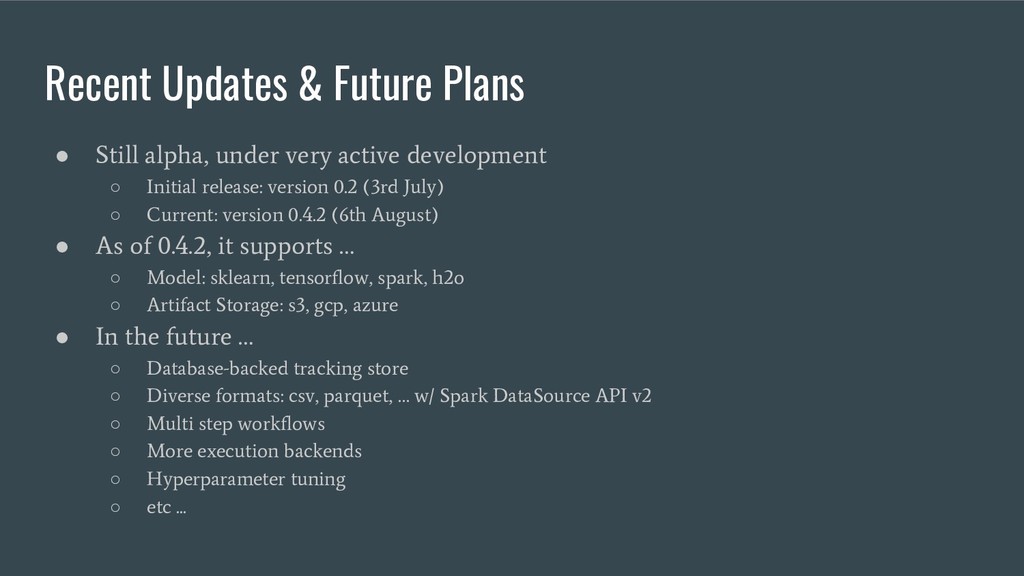
Recent Updates & Future Plans • Still alpha, under very
active development ◦ Initial release: version 0.2 (3rd July) ◦ Current: version 0.4.2 (6th August) • As of 0.4.2, it supports … ◦ Model: sklearn, tensorflow, spark, h2o ◦ Artifact Storage: s3, gcp, azure • In the future … ◦ Database-backed tracking store ◦ Diverse formats: csv, parquet, … w/ Spark DataSource API v2 ◦ Multi step workflows ◦ More execution backends ◦ Hyperparameter tuning ◦ etc ...