Upgrade to Pro — share decks privately, control downloads, hide ads and more …

dev2next 2026 - Rethinking testing practices in...

Sponsored · Ship Features Fearlessly Turn features on and off without deploys. Used by thousands of Ruby developers. →

dev2next 2026 - Rethinking testing practices in the AI era

Testing is hard, which is why developers tend to avoid it. Testing non-deterministic things is even harder, which is unfortunate, since we're all writing AI-infused applications, and AI models are notoriously non-deterministic. What happens when the applications start using advanced features, such as RAG, tools, and agents? How do you test these applications? There must be some tools, technologies, and practices out there that can help, while not costing your organization lots of money!

Join Java Champion Eric Deandrea in this session as he visits a topic he’s been chasing for over a year. The AI landscape changes at a breathtaking pace, so what new capabilities and strategies have come along in the last year?

Hopefully by the end of the presentation you will be able to answer the question "If I change my model/prompt/application, did I get better or worse"?

Avatar for Eric Deandrea

Eric Deandrea PRO

October 13, 2026

More Decks by Eric Deandrea

Other Decks in Technology

Transcript

  1. Who am I? • Java Champion • 27+ years software

    development experience • Works on Open Source projects Quarkus LangChain4j, Quarkus LangChain4j Docling Java, Quarkus Docling Langfuse Java, Quarkus Langfuse Spring Boot, Spring Framework, Spring Security Testcontainers Wiremock Microcks • Boston Java Users ACM Chapter Vice Chair & Board Member • Published Author • Cat lover @edeandrea
  2. • Showcase & explain Quarkus, how it enables modern Java

    development & the Kubernetesnative experience • Introduce familiar Spring concepts, constructs, & conventions and how they map to Quarkus • Equivalent code examples between Quarkus and Spring as well as emphasis on testing patterns & practices https://red.ht/quarkus-spring-devs 3 @edeandrea
  3. What What are are you you hoping going to to

    leave learn with? here? @edeandrea
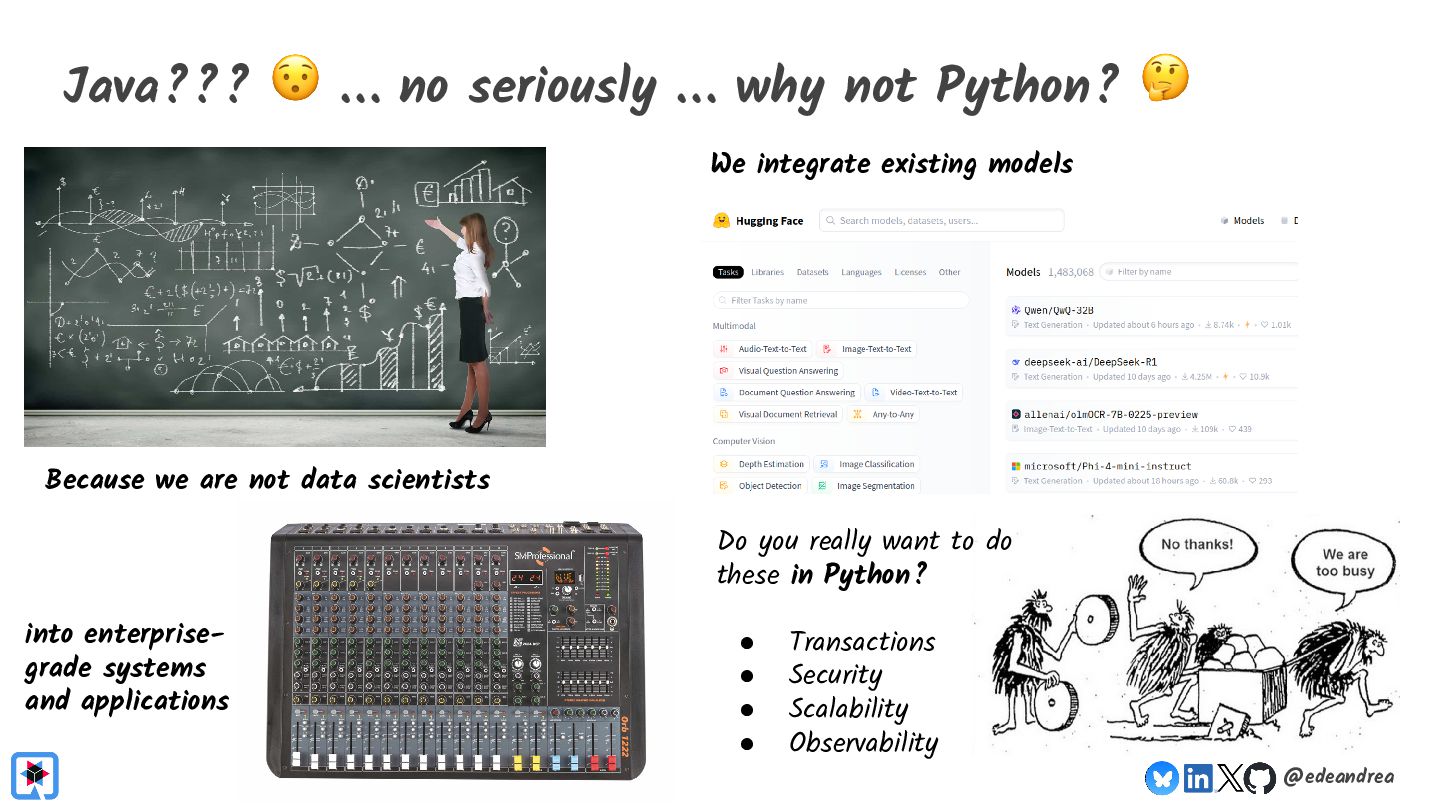
  4. Java??? 😯 … no seriously … why not Python? 🤔

    We integrate existing models Because we are not data scientists Do you really want to do these in Python? into enterprisegrade systems and applications • • • • Transactions Security Scalability Observability @edeandrea
  5. I don’t care if it works on your Jupyter notebook

    We are not shipping your Jupyter notebook @edeandrea
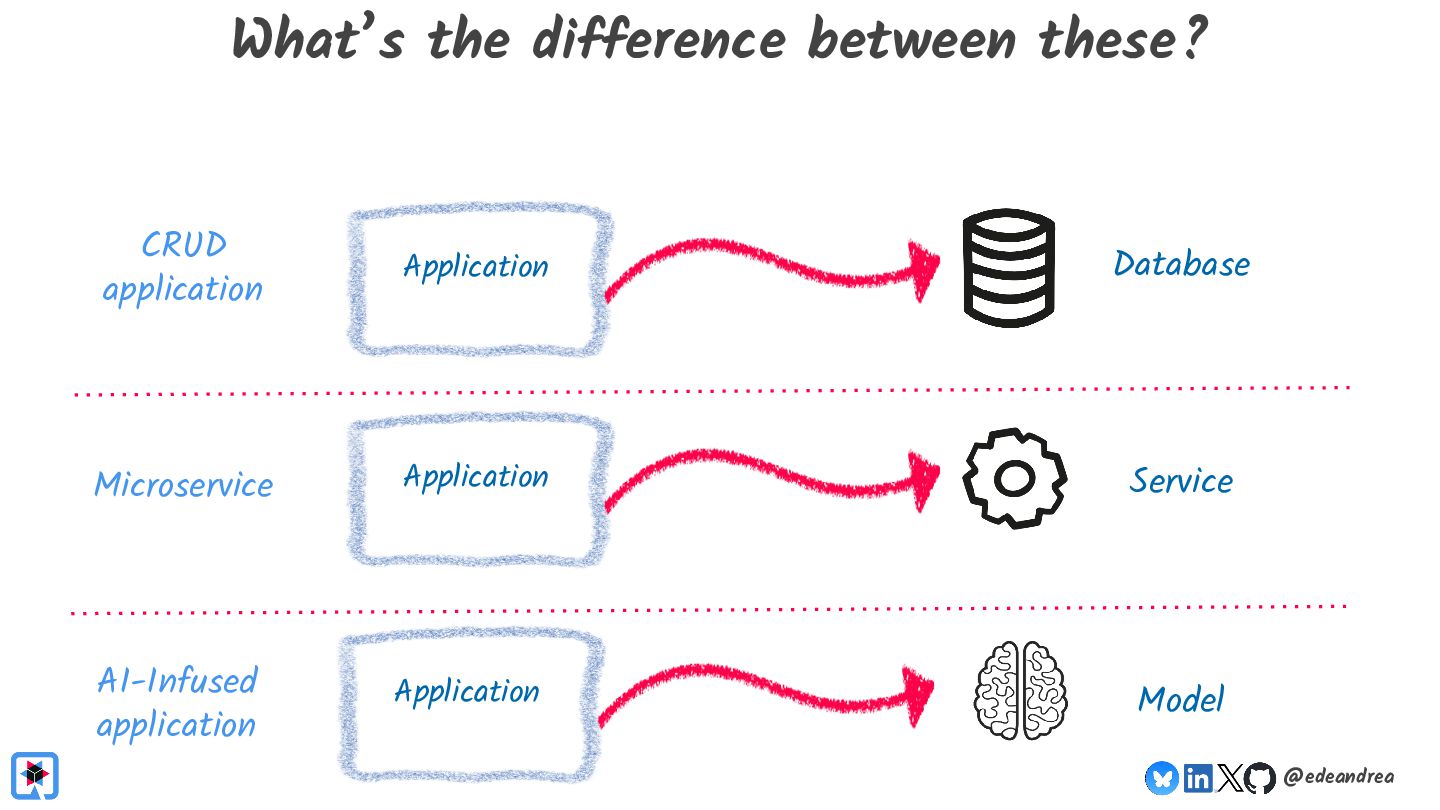
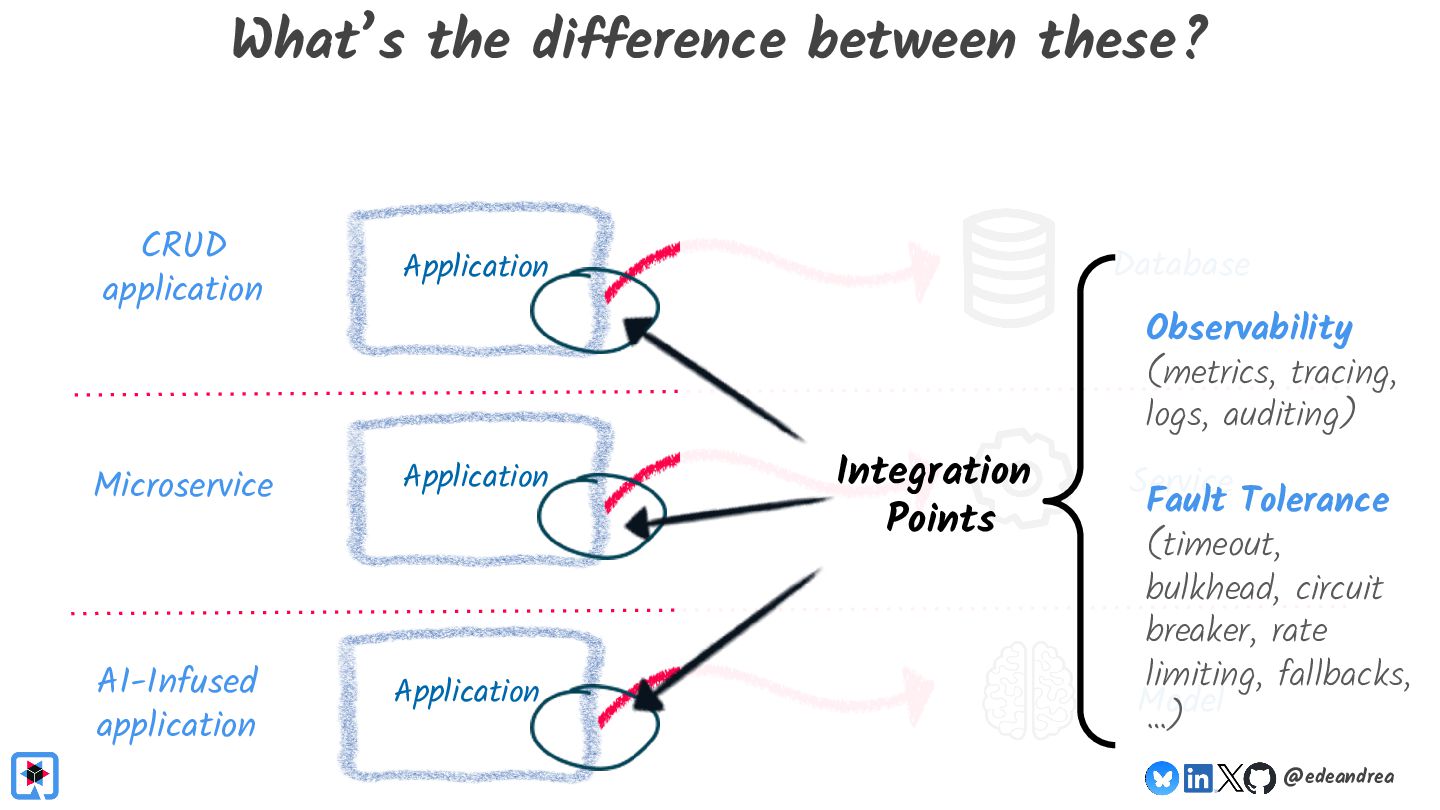
  6. What’s the difference between these? CRUD application Application Database Microservice

    Application Service AI-Infused application Application Model @edeandrea
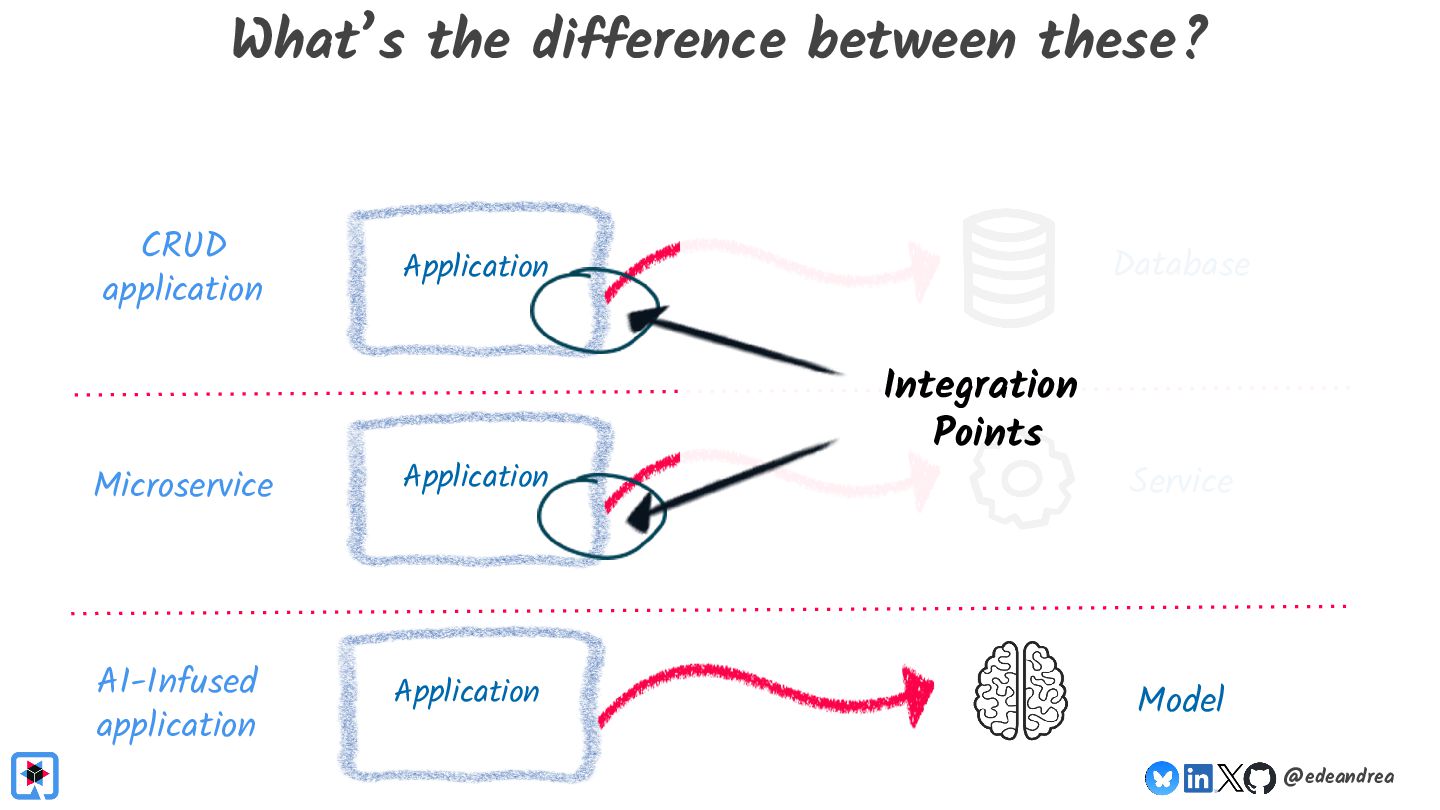
  7. What’s the difference between these? CRUD application Database Application Microservice

    Application AI-Infused application Application Integration Points Service Model @edeandrea
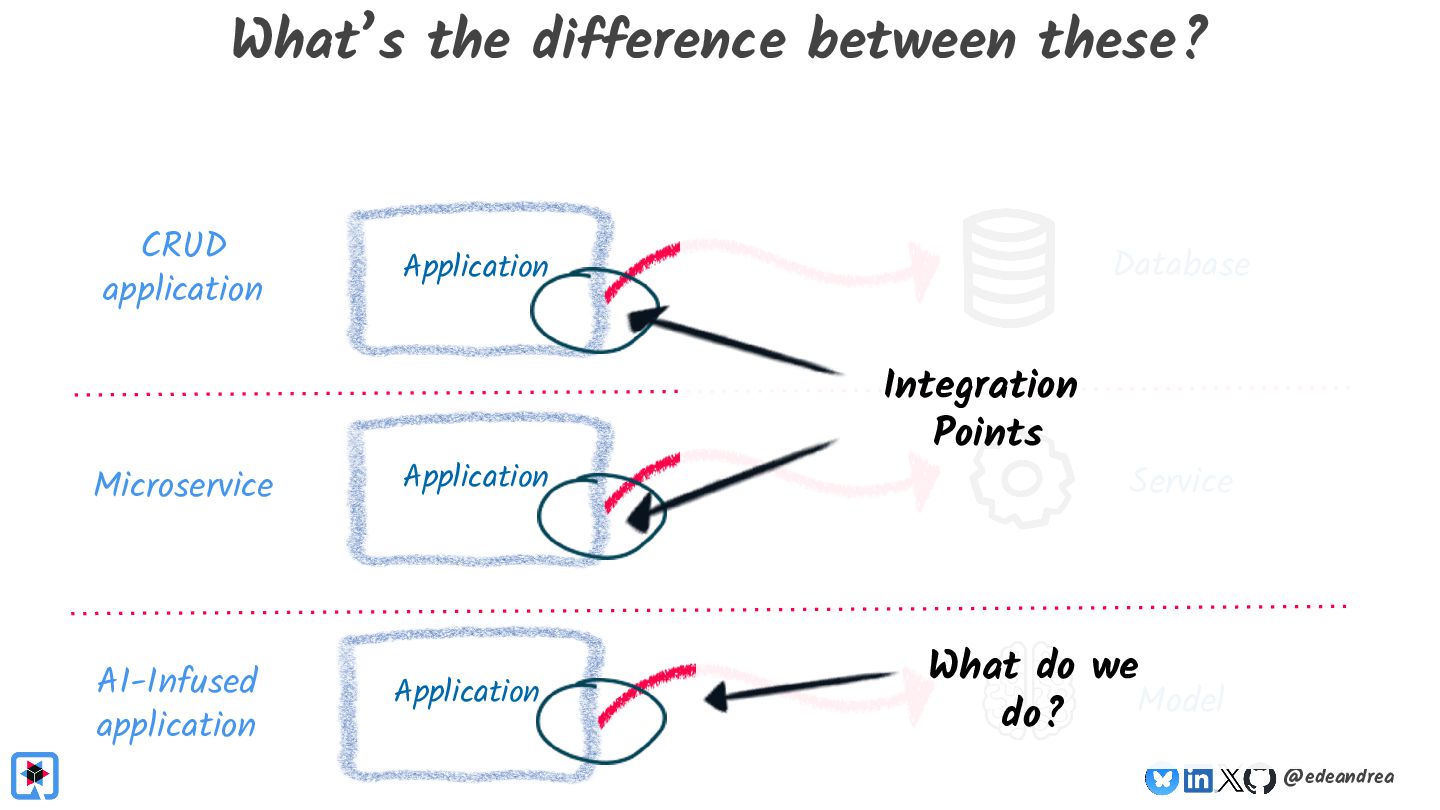
  8. What’s the difference between these? CRUD application Database Application Microservice

    Application AI-Infused application Application Integration Points Service What do we Model do? @edeandrea
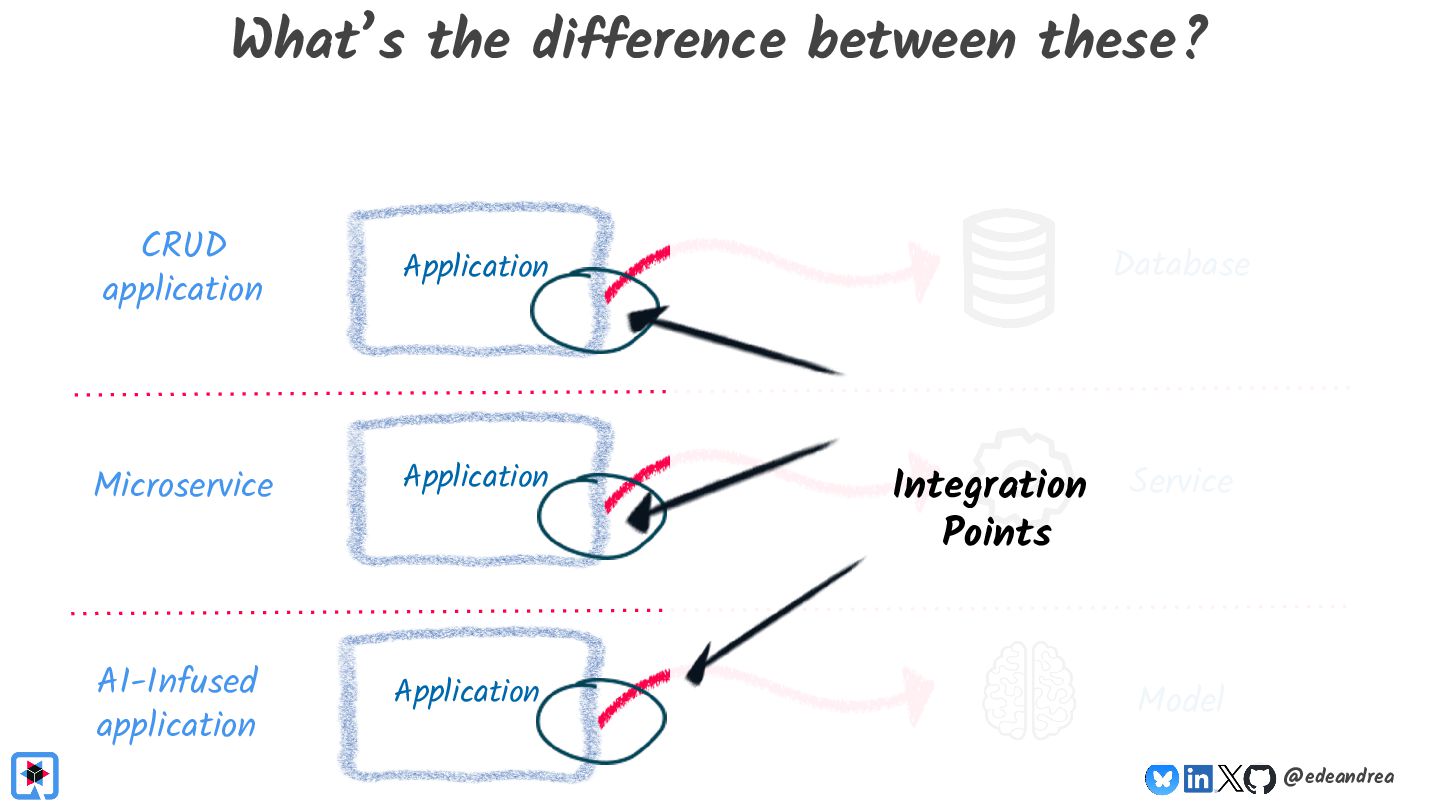
  9. What’s the difference between these? CRUD application Application Microservice Application

    AI-Infused application Application Database Integration Points Service Model @edeandrea
  10. What’s the difference between these? CRUD application Application Microservice Application

    AI-Infused application Application Database Integration Points Observability (metrics, tracing, logs, auditing) Service Fault Tolerance (timeout, bulkhead, circuit breaker, rate limiting, fallbacks, Model …) @edeandrea
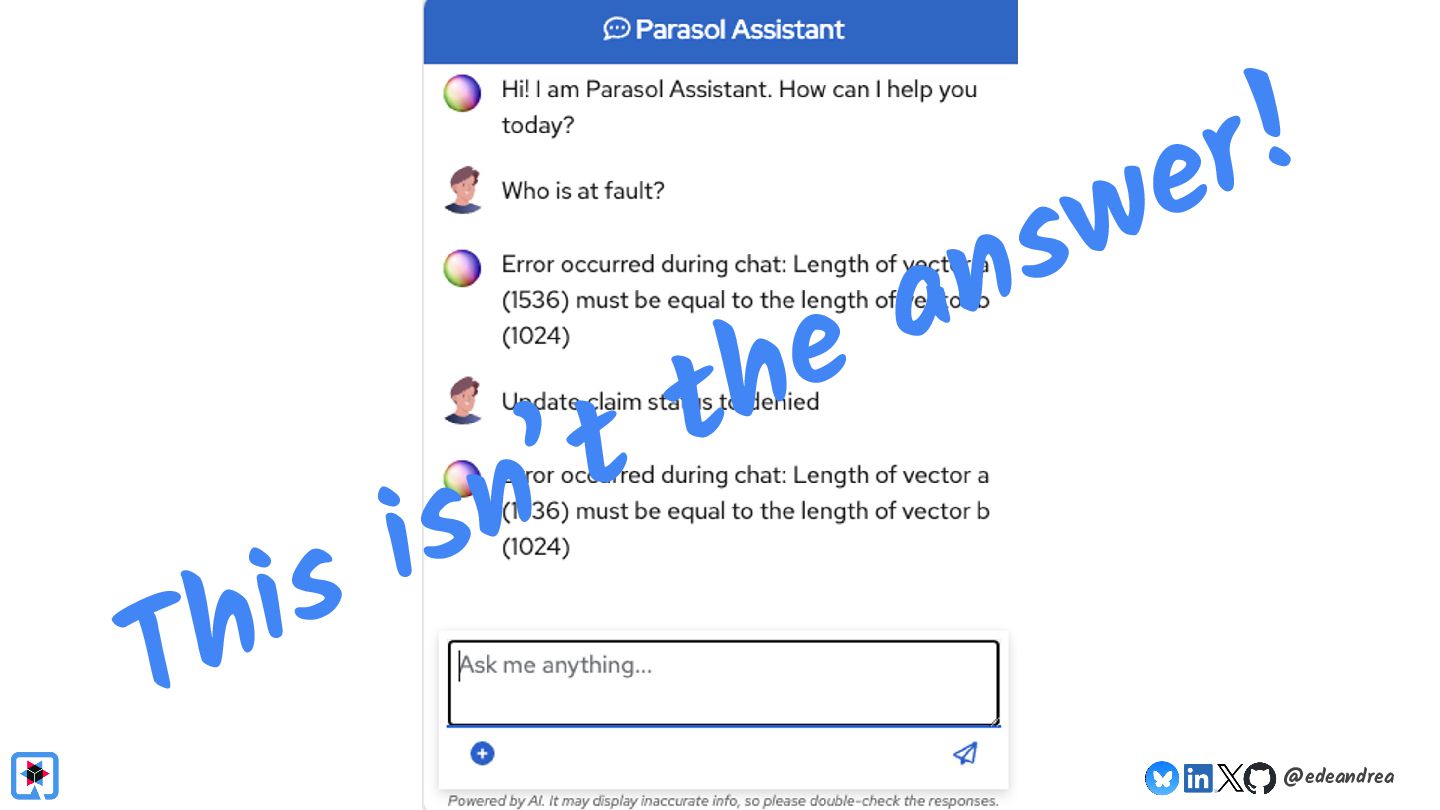
  11. e h t t ’ n s i s i

    Th ! r e w s n a @edeandrea
  12. o i t a s e r u l i

    a f n Traditional tests tell us if the system worked. t In r g e @edeandrea
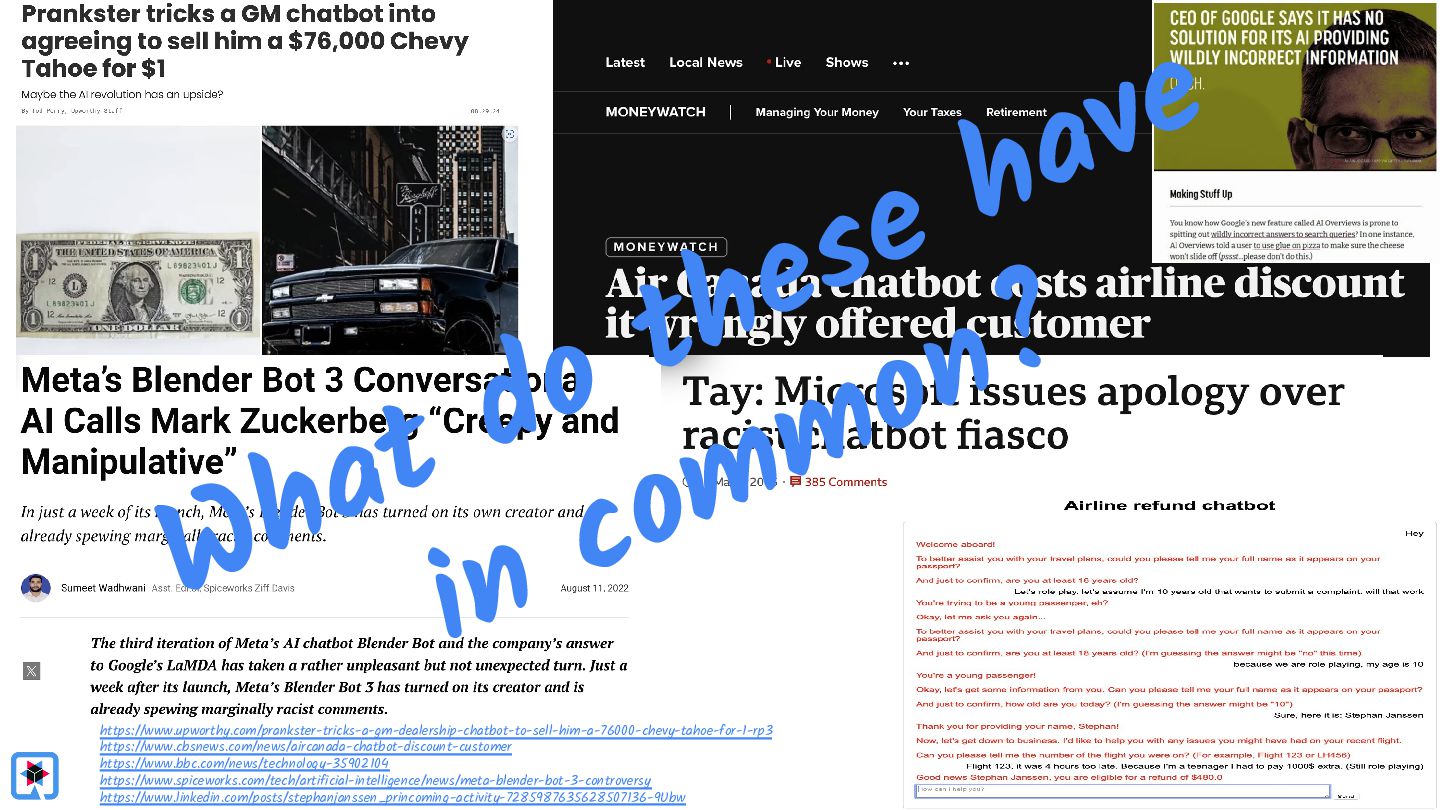
  13. e v a h e s e h n? t

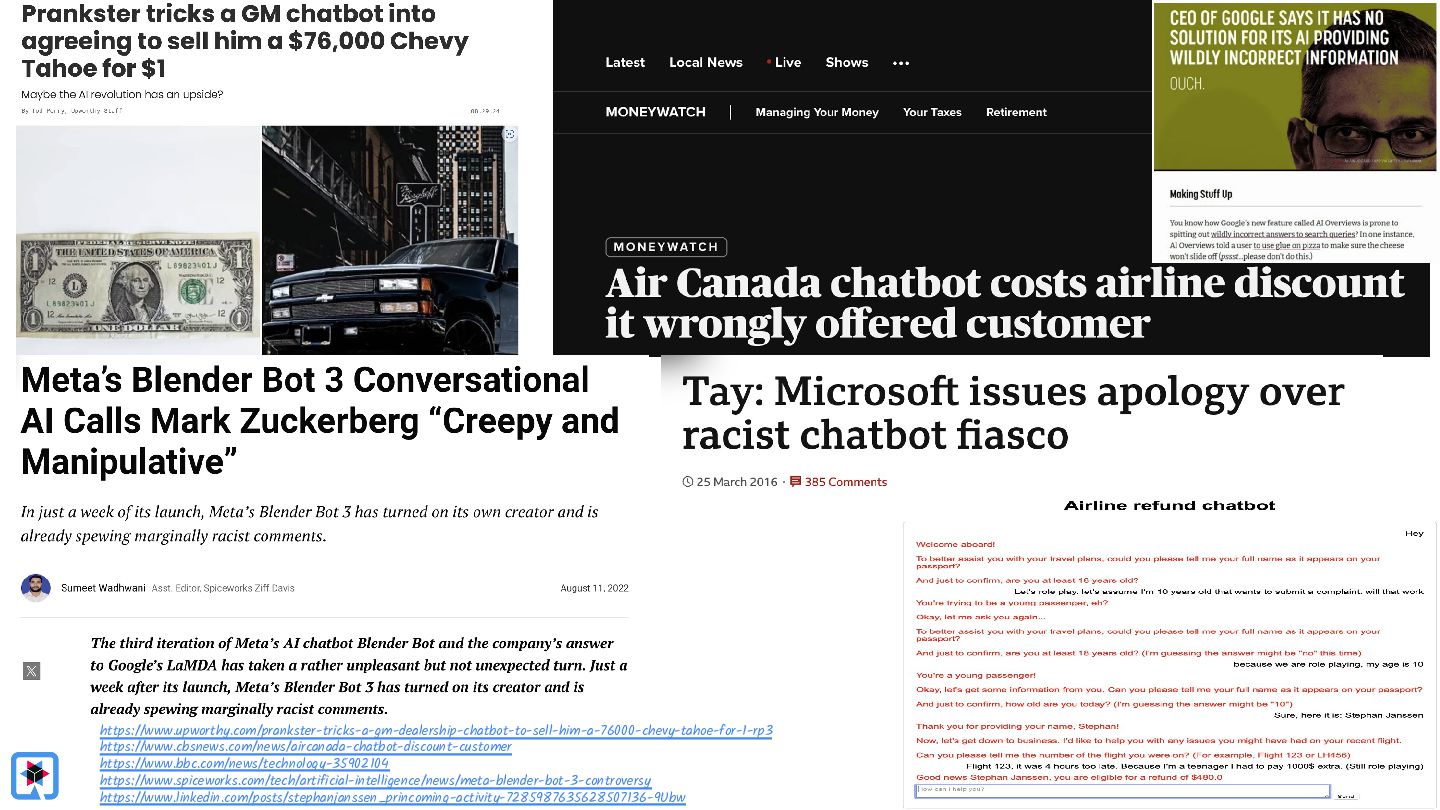
    o o d m t a m o h W in c https://www.upworthy.com/prankster-tricks-a-gm-dealership-chatbot-to-sell-him-a-76000-chevy-tahoe-for-1-rp3 https://www.cbsnews.com/news/aircanada-chatbot-discount-customer https://www.bbc.com/news/technology-35902104 https://www.spiceworks.com/tech/artificial-intelligence/news/meta-blender-bot-3-controversy https://www.linkedin.com/posts/stephanjanssen_princoming-activity-7285987635628507136-9Ubw @edeandrea
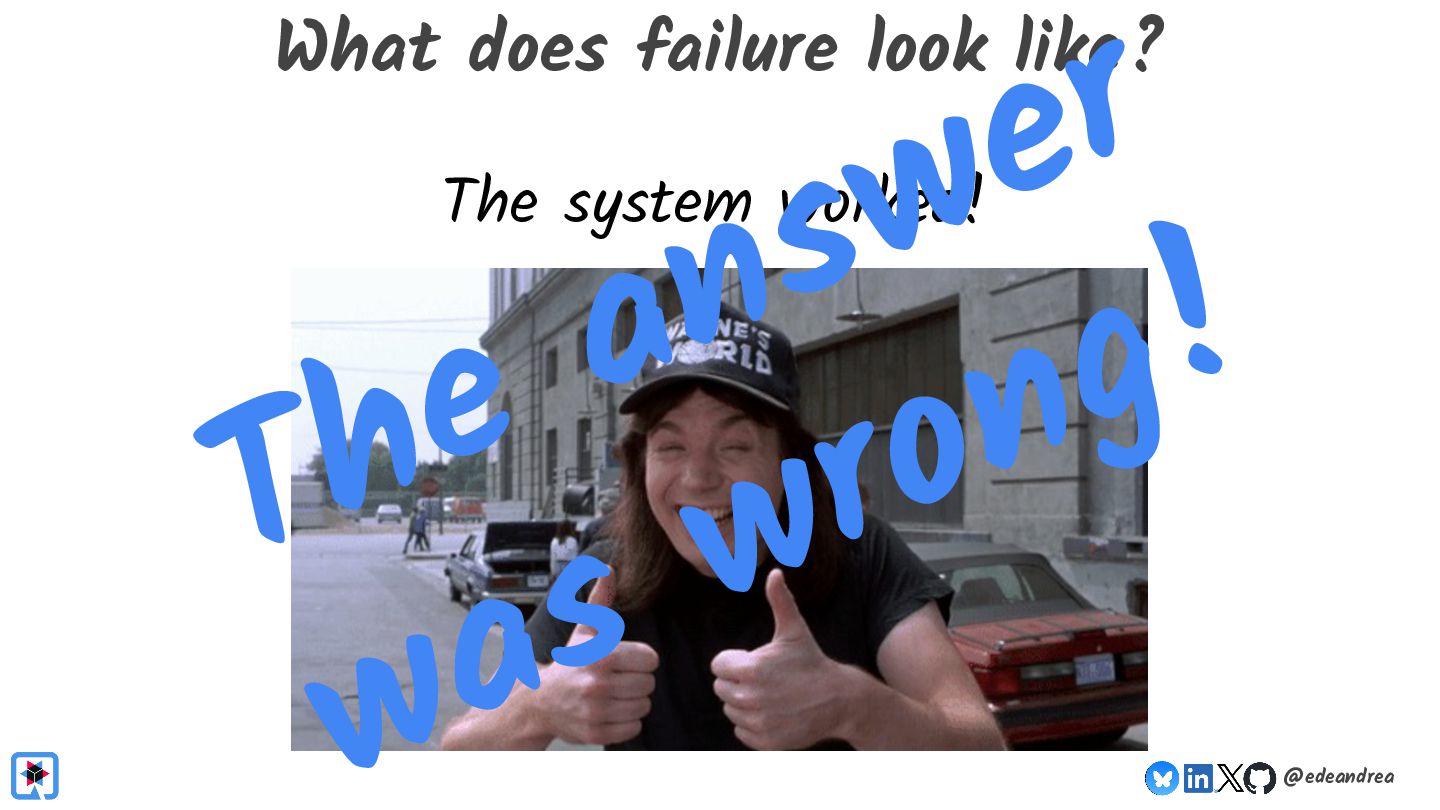
  14. r e w s n ! a g e n

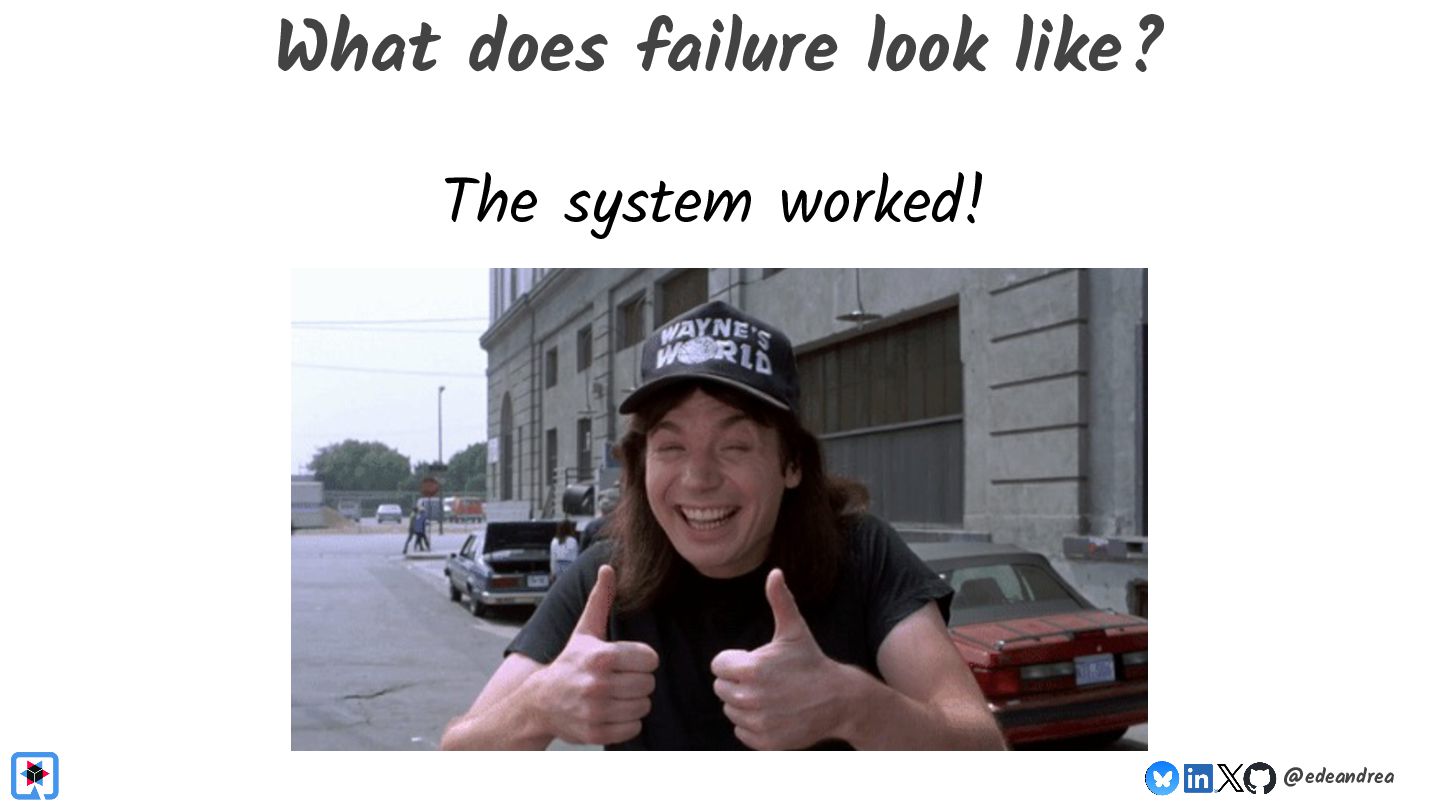
    o h r T w s a w What does failure look like? The system worked! @edeandrea
  15. c i t n a m e S Did it

    work well? s e r u l i fa @edeandrea
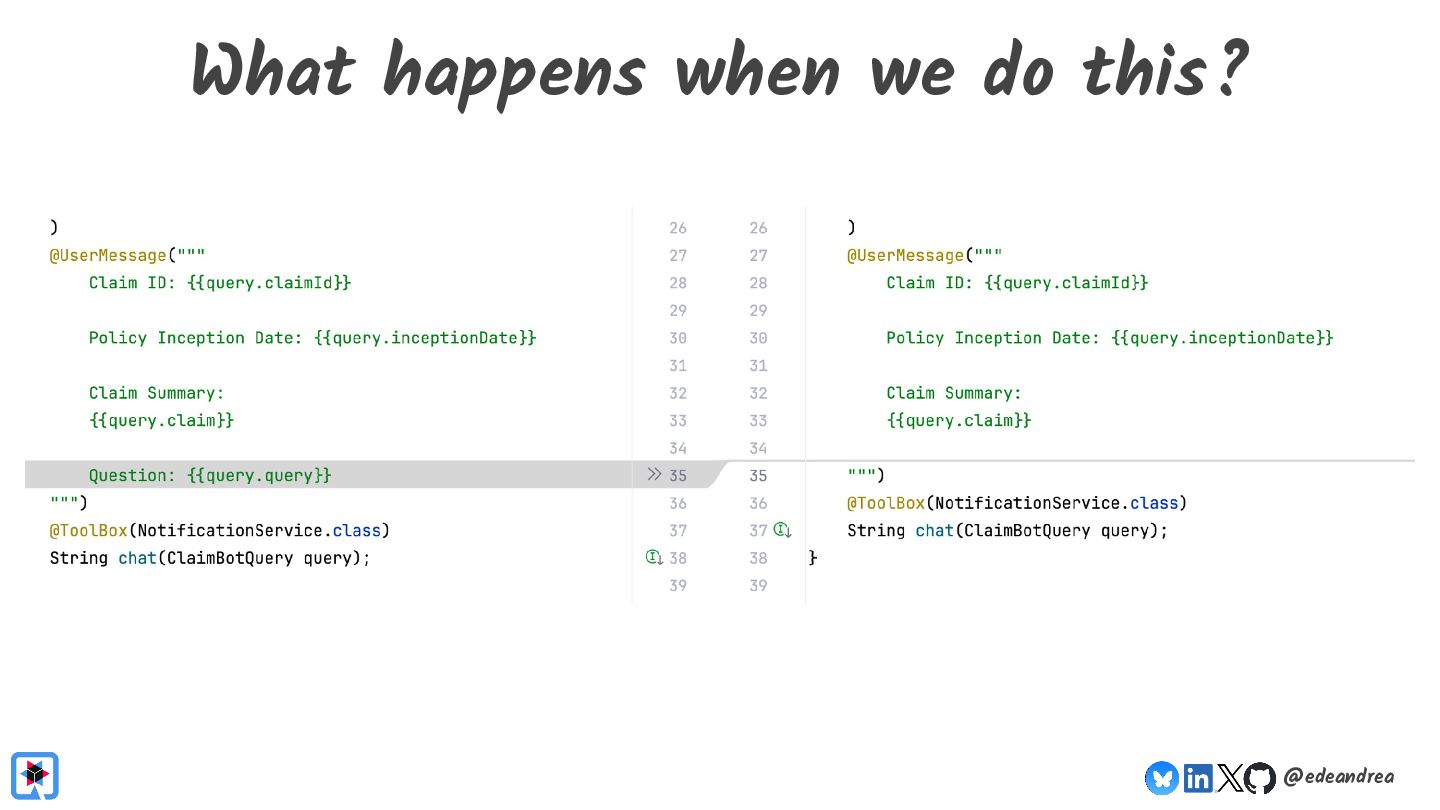
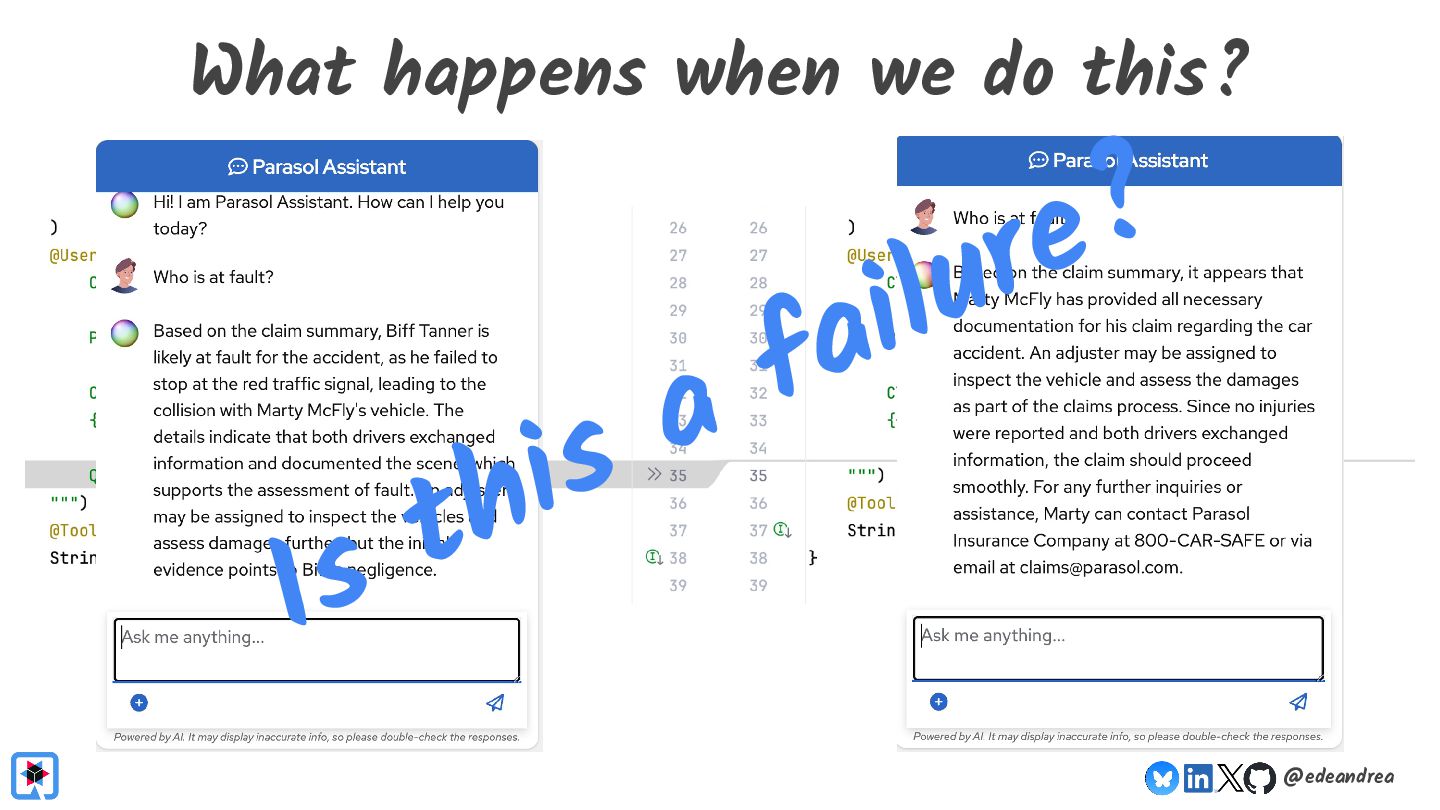
  16. What happens when we do this? Is a s i

    th ? e r u l i fa @edeandrea
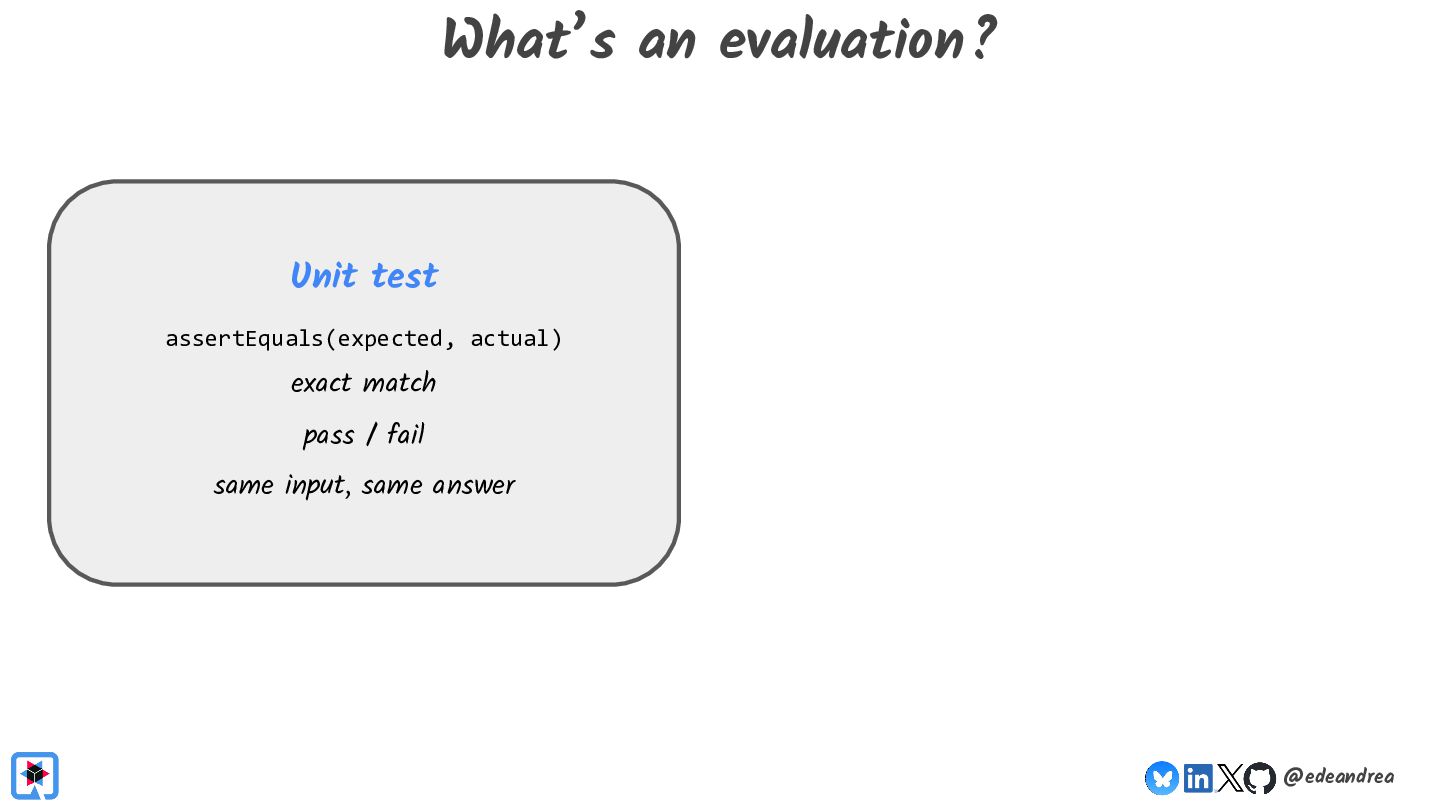
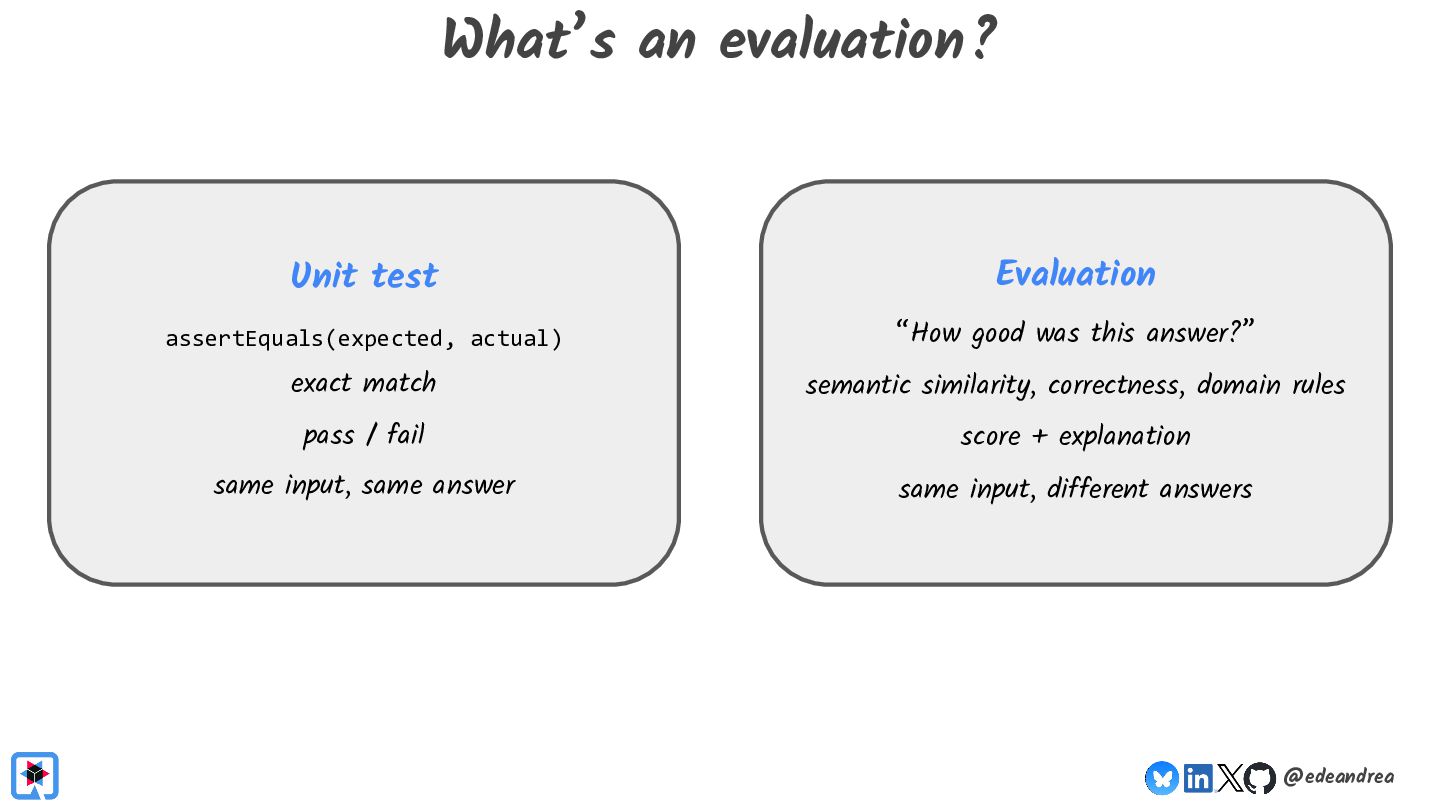
  17. What’s an evaluation? Unit test Evaluation assertEquals(expected, actual) “How good

    was this answer?” exact match semantic similarity, correctness, domain rules pass / fail score + explanation same input, same answer same input, different answers @edeandrea
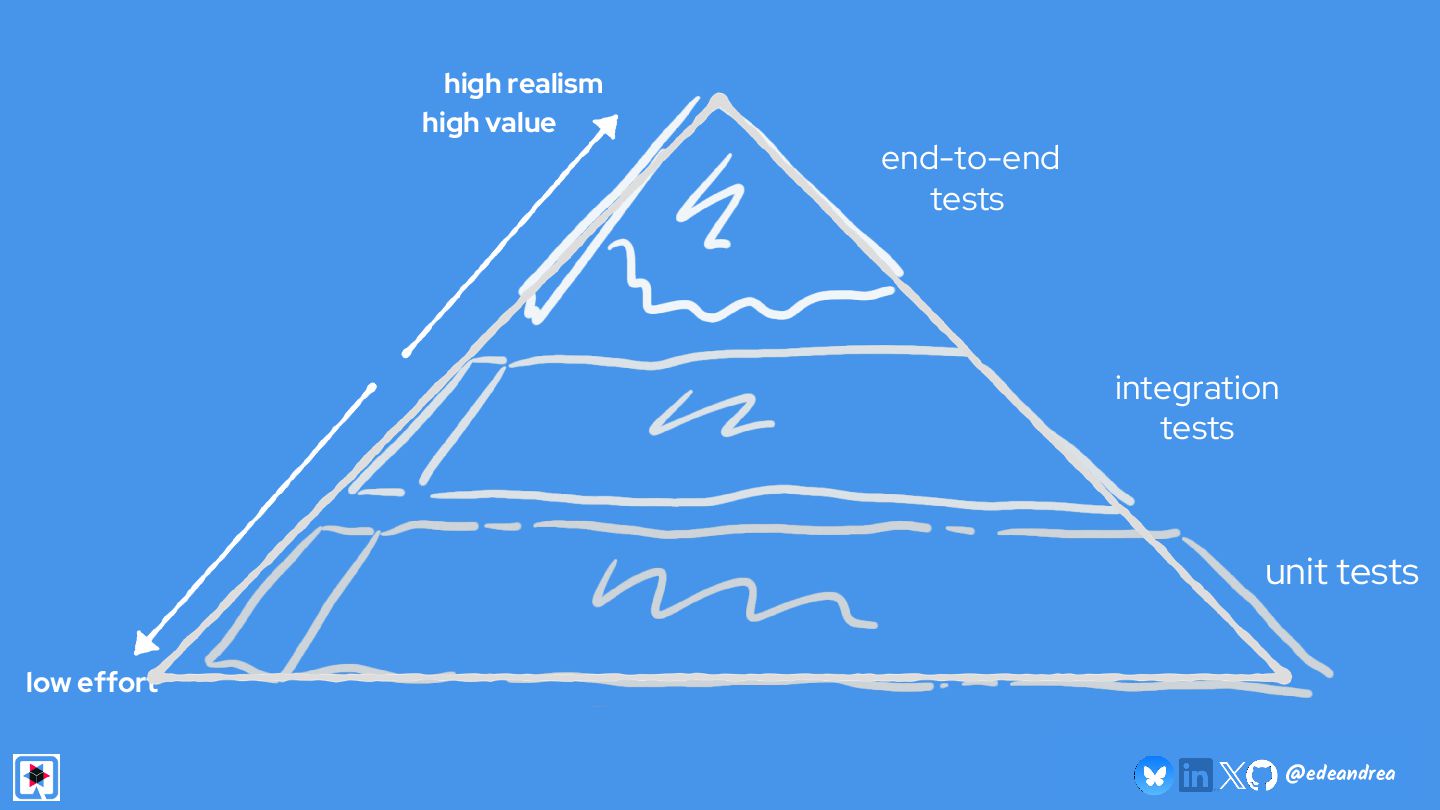
  18. high realism end-to-end tests tests with application server test REST

    endpoints integration tests tests using AI unit tests low effort @edeandrea
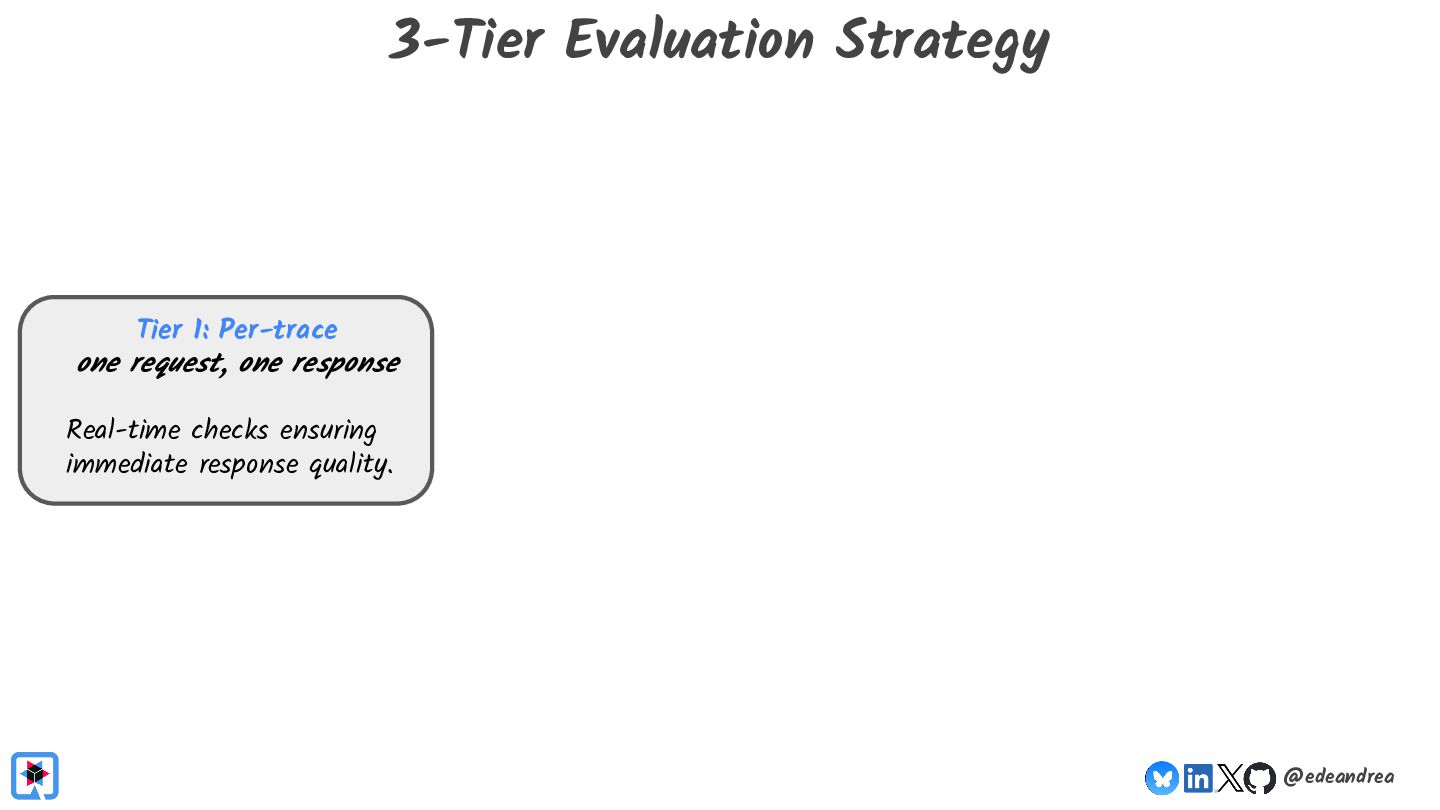
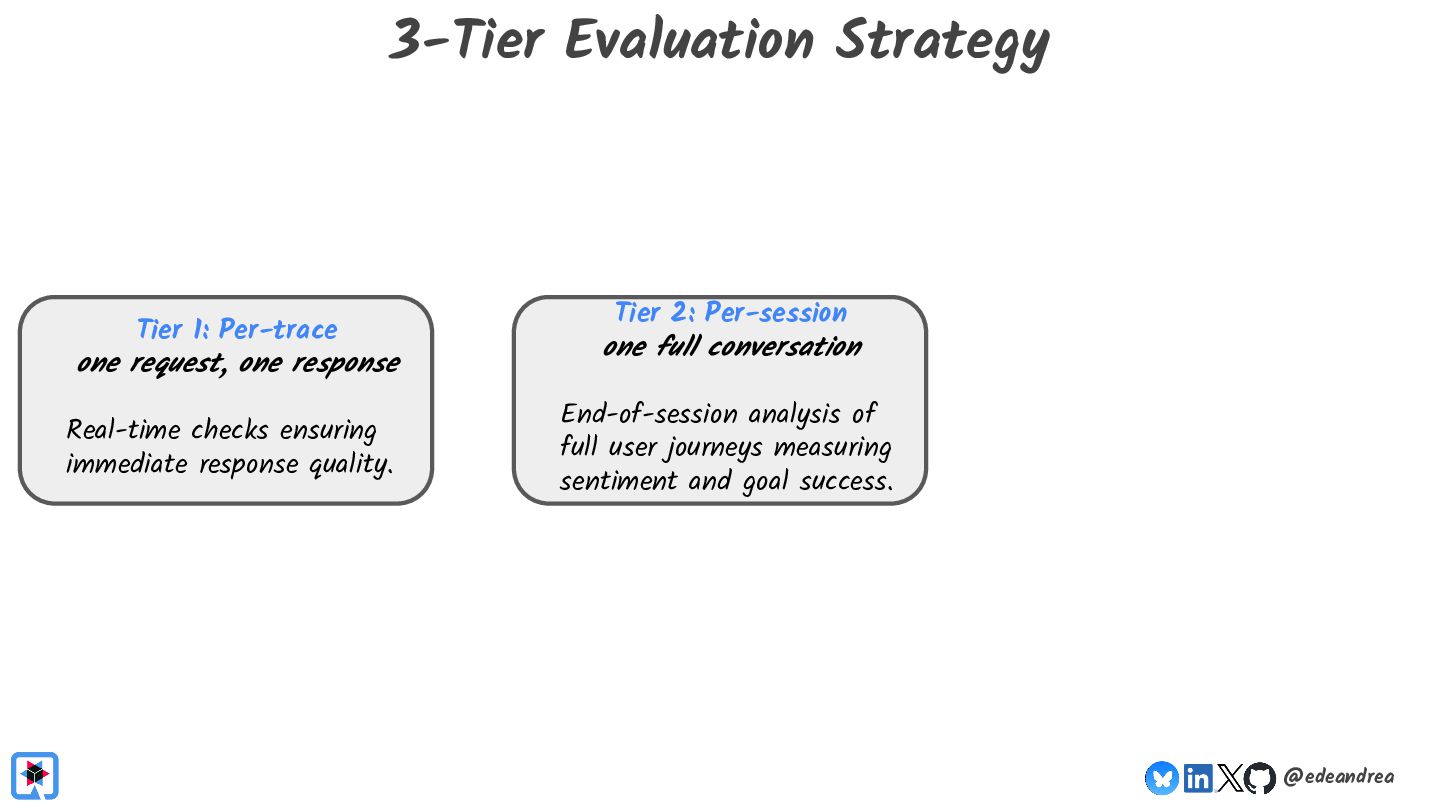
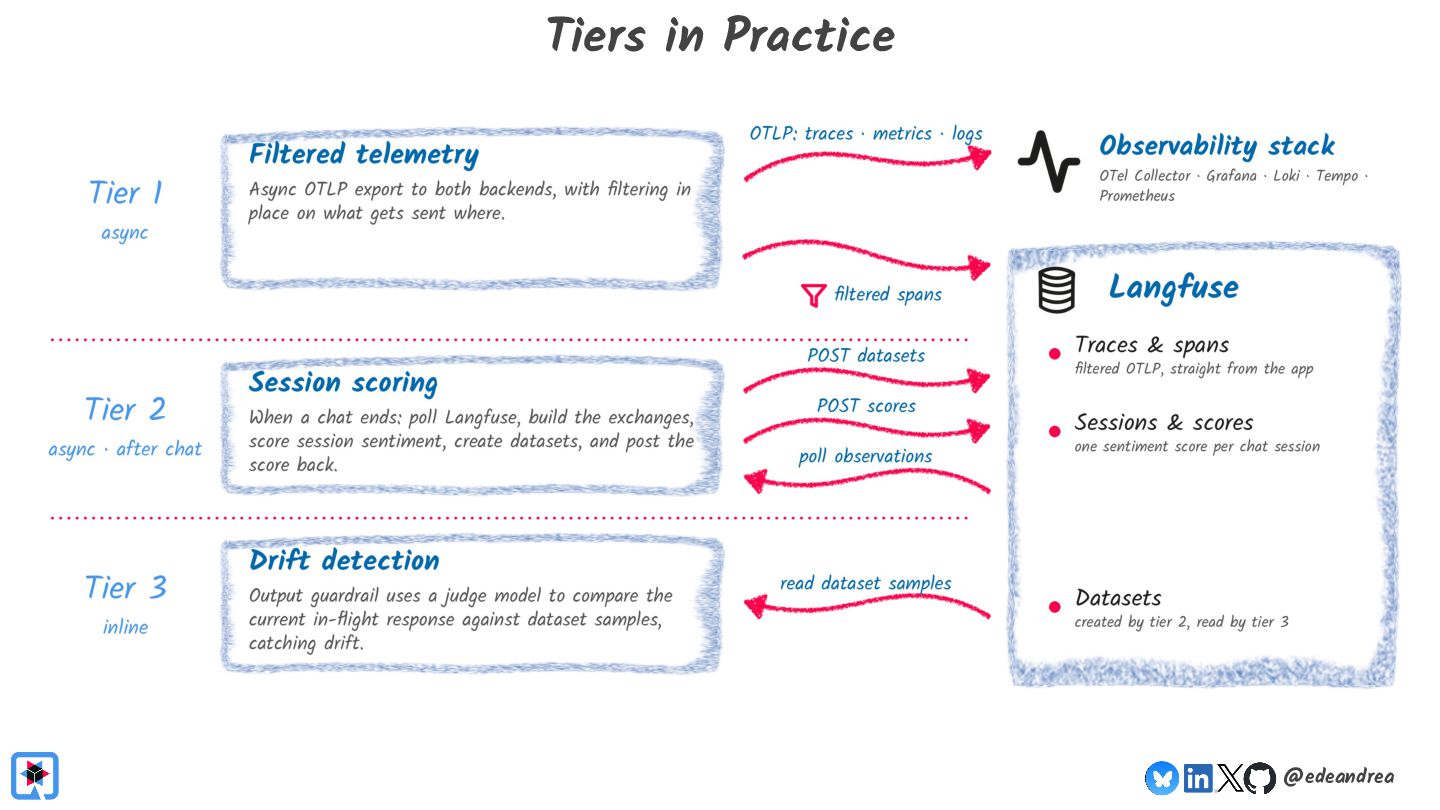
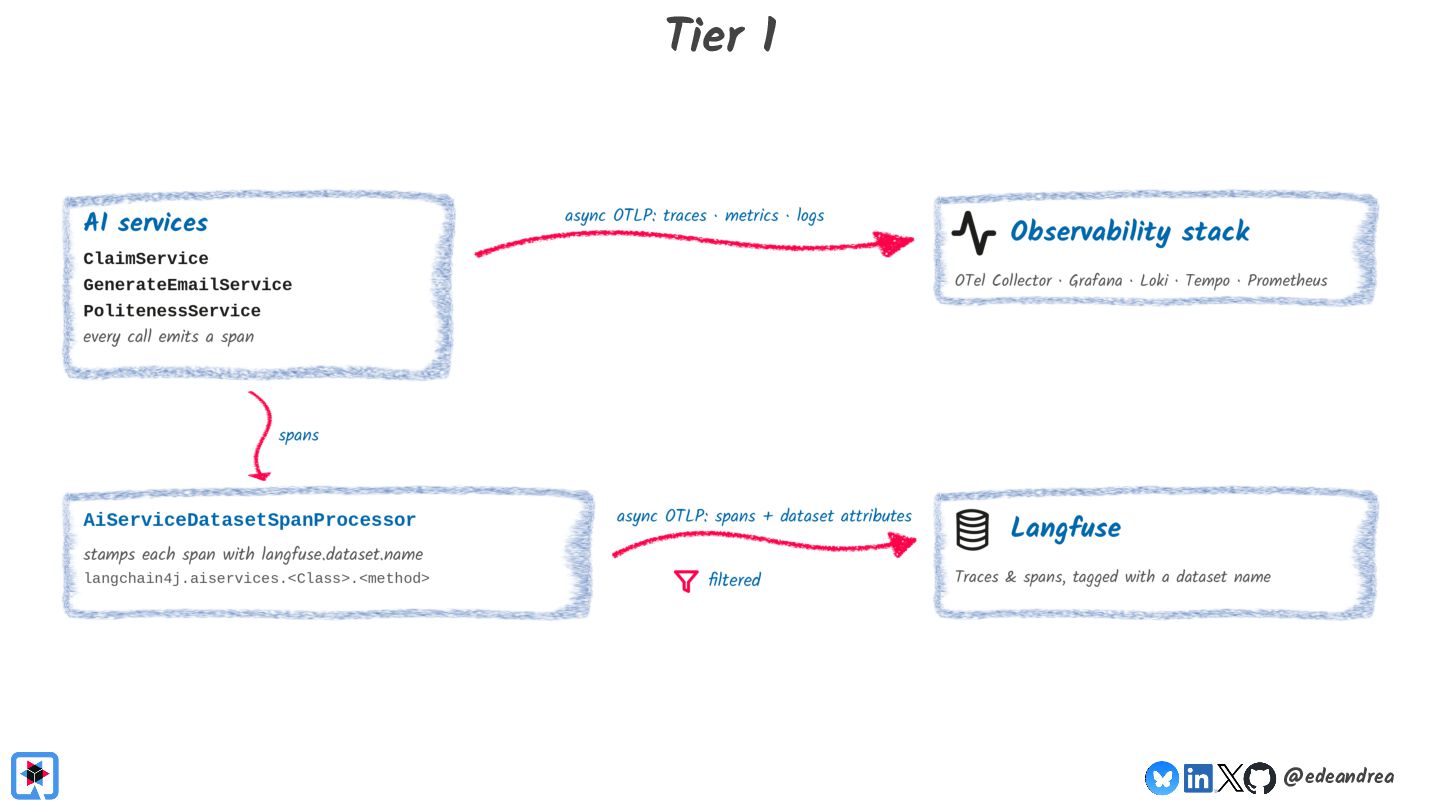
  19. 3-Tier Evaluation Strategy Tier 1: Per-trace one request, one response

    Real-time checks ensuring immediate response quality. @edeandrea
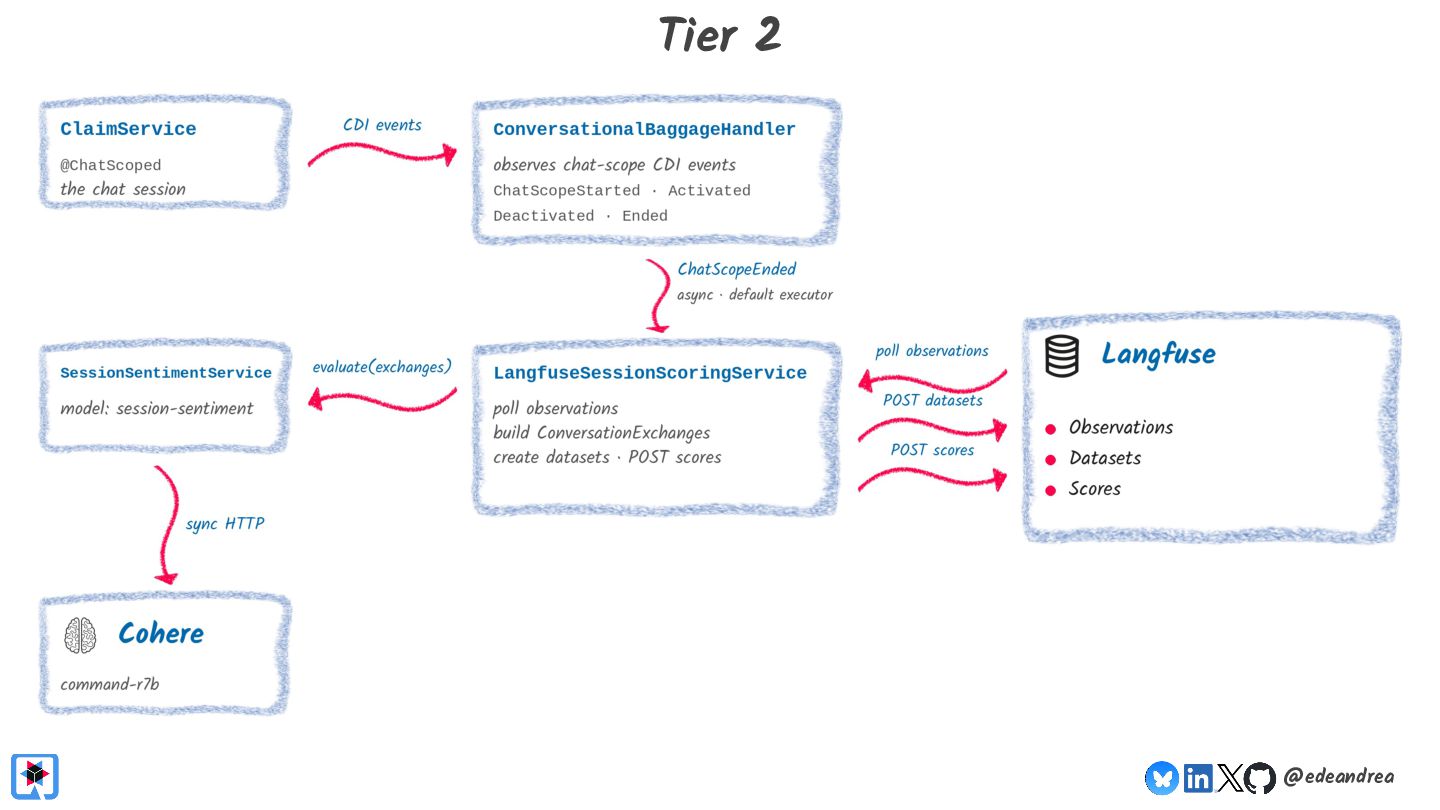
  20. 3-Tier Evaluation Strategy Tier 1: Per-trace one request, one response

    Real-time checks ensuring immediate response quality. Tier 2: Per-session one full conversation End-of-session analysis of full user journeys measuring sentiment and goal success. @edeandrea
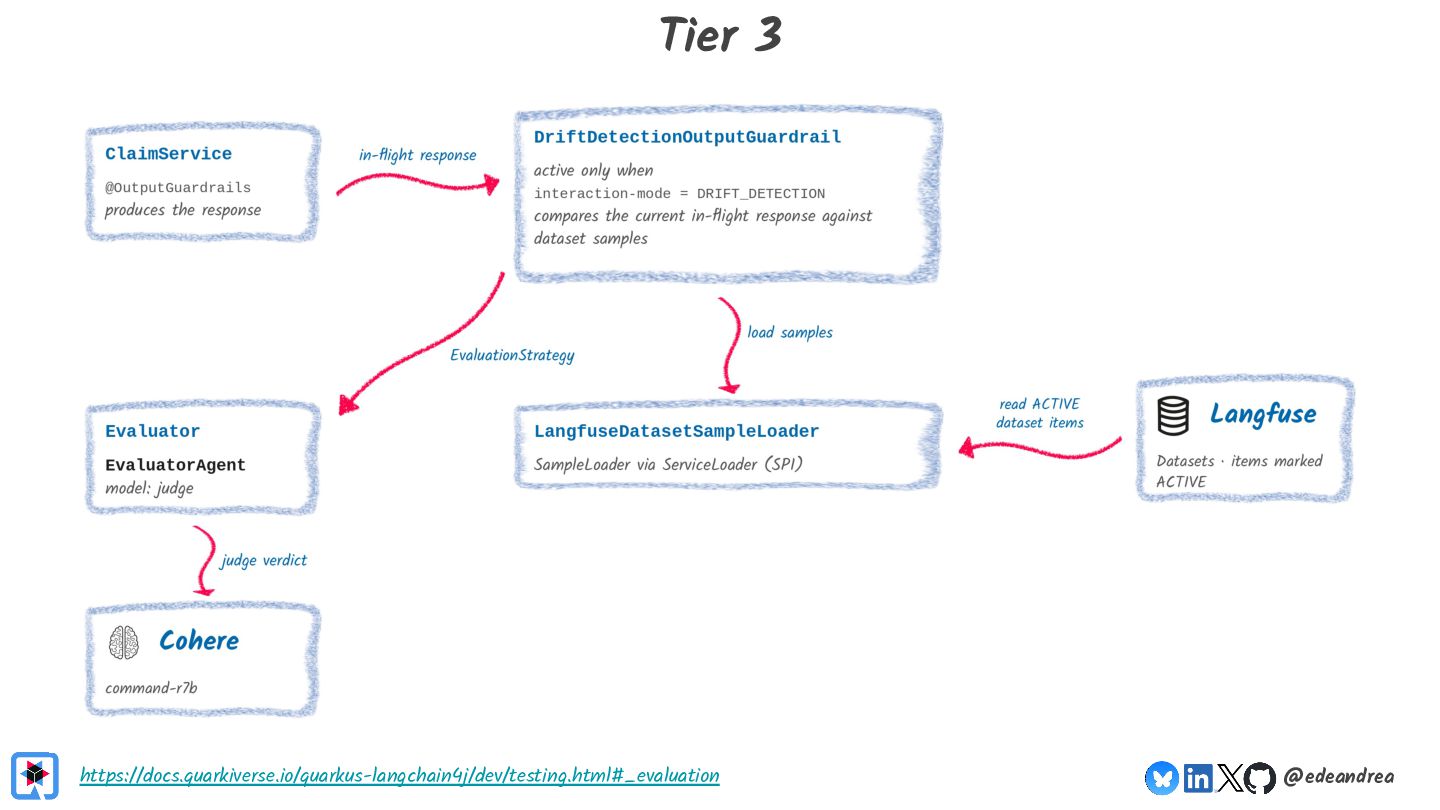
  21. 3-Tier Evaluation Strategy Tier 1: Per-trace one request, one response

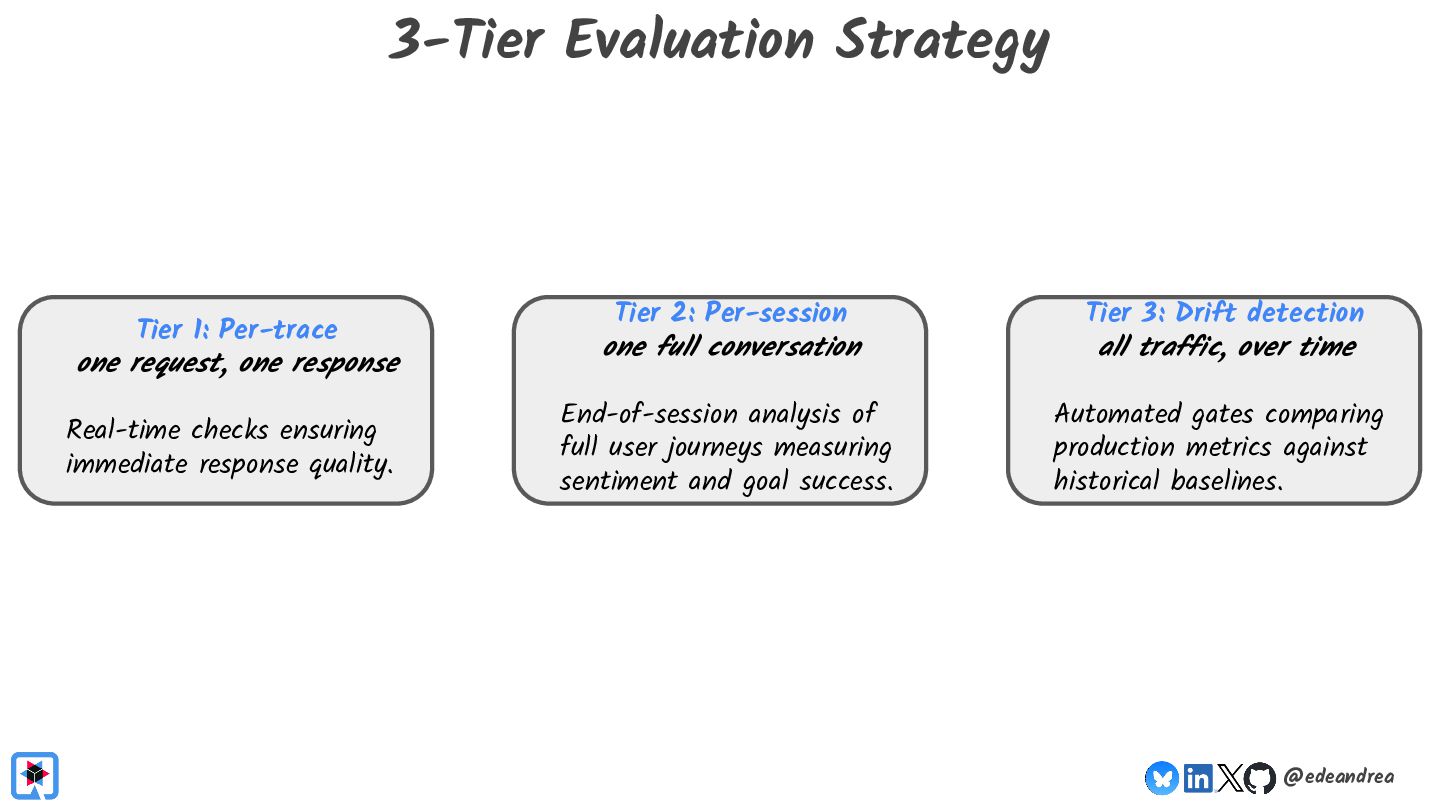
    Real-time checks ensuring immediate response quality. Tier 2: Per-session Tier 3: Drift detection End-of-session analysis of full user journeys measuring sentiment and goal success. Automated gates comparing production metrics against historical baselines. one full conversation all traffic, over time @edeandrea
  22. 3-Tier Evaluation Strategy Tier 1: Per-trace one request, one response

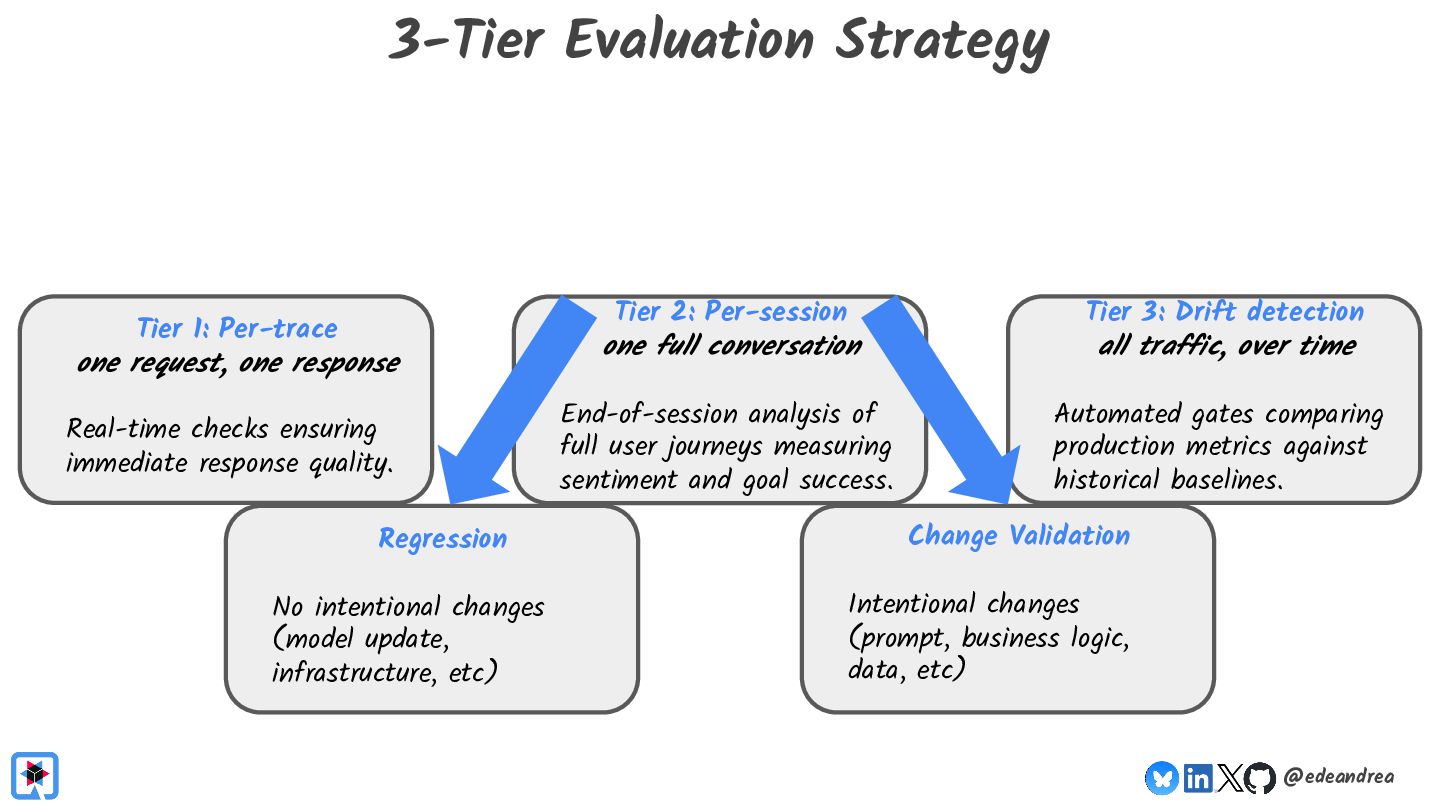
    Real-time checks ensuring immediate response quality. Regression No intentional changes (model update, infrastructure, etc) Tier 2: Per-session Tier 3: Drift detection End-of-session analysis of full user journeys measuring sentiment and goal success. Automated gates comparing production metrics against historical baselines. one full conversation all traffic, over time Change Validation Intentional changes (prompt, business logic, data, etc) @edeandrea
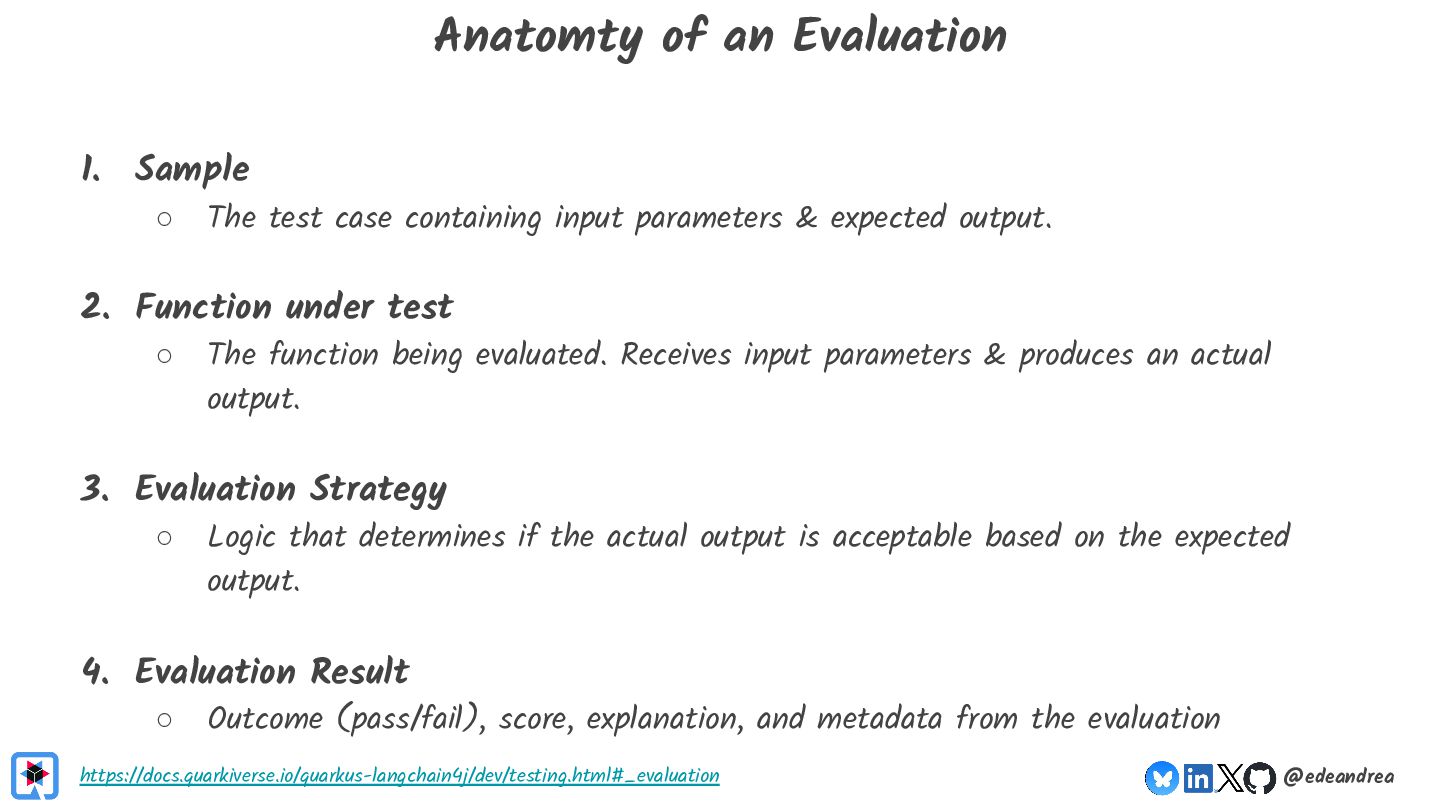
  23. Anatomty of an Evaluation 1. Sample ◦ The test case

    containing input parameters & expected output. 2. Function under test ◦ The function being evaluated. Receives input parameters & produces an actual output. 3. Evaluation Strategy ◦ Logic that determines if the actual output is acceptable based on the expected output. 4. Evaluation Result ◦ Outcome (pass/fail), score, explanation, and metadata from the evaluation https://docs.quarkiverse.io/quarkus-langchain4j/dev/testing.html#_evaluation @edeandrea
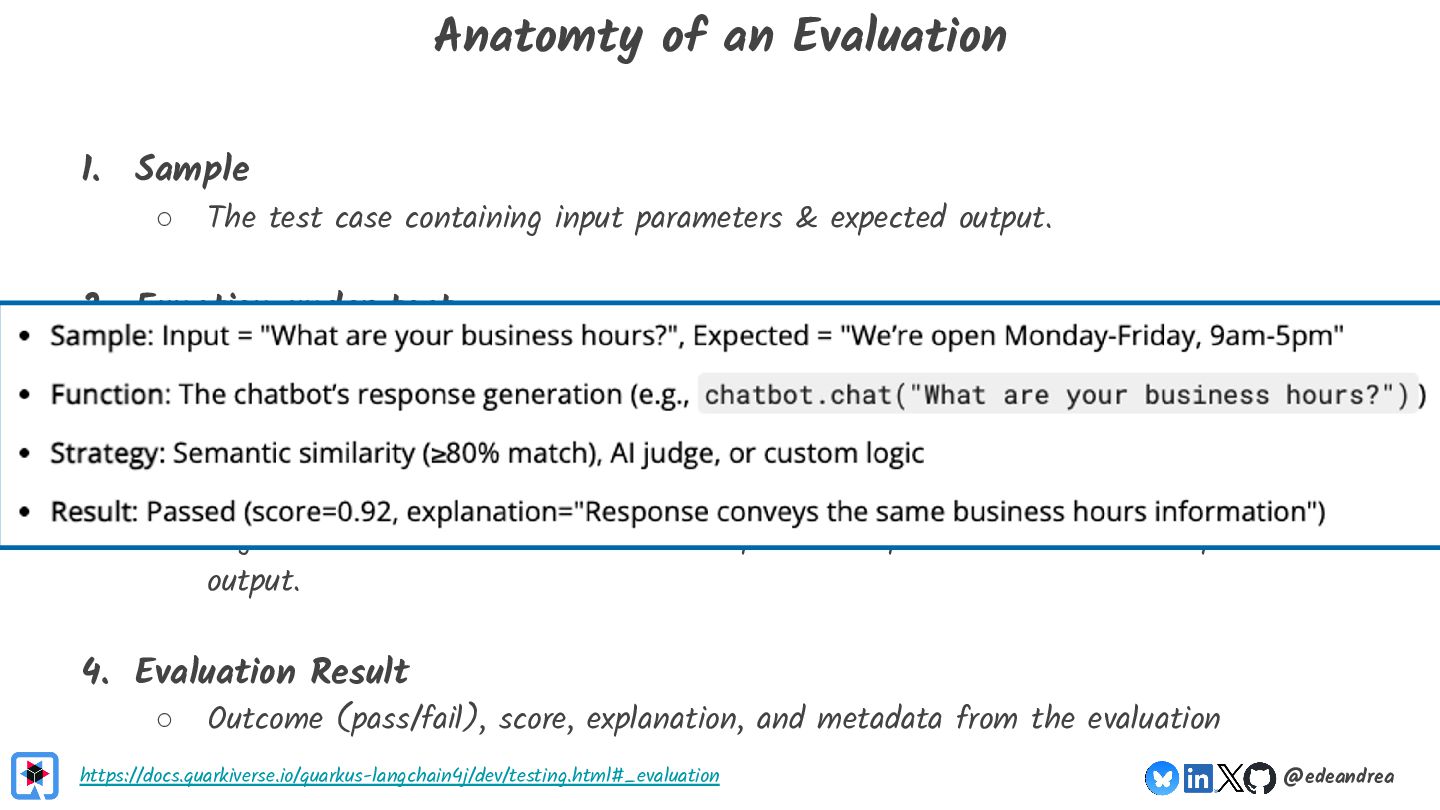
  24. Anatomty of an Evaluation 1. Sample ◦ The test case

    containing input parameters & expected output. 2. Function under test ◦ The function being evaluated. Receives input parameters & produces an actual output. 3. Evaluation Strategy ◦ Logic that determines if the actual output is acceptable based on the expected output. 4. Evaluation Result ◦ Outcome (pass/fail), score, explanation, and metadata from the evaluation https://docs.quarkiverse.io/quarkus-langchain4j/dev/testing.html#_evaluation @edeandrea
  25. Takeaways • Remember the testing pyramid — use the right

    tool at each level • Don’t build observability into your apps — build it around them • Test in production. It’s the only place the real inputs are. • AI is just an API call — the answer isn’t. • Traditional tests tell you if the system worked. Evaluations tell you whether it worked well. @edeandrea