Share
Embed

Transcript
109 slides
-
currently: building things at honeycomb.io Hi everyone! I'm Eben these
slides: speakerdeck.com/emfree/allocator-wrestling -
Why this talk - Go is a managed-memory language -
The runtime does a lot of sophisticated work on behalf of you, the programmer -
Why this talk - Go is a managed-memory language -
The runtime does a lot of sophisticated work on behalf of you, the programmer - And yet, dynamic memory allocation is not free - A program's allocation patterns can substantially affect its performance! -
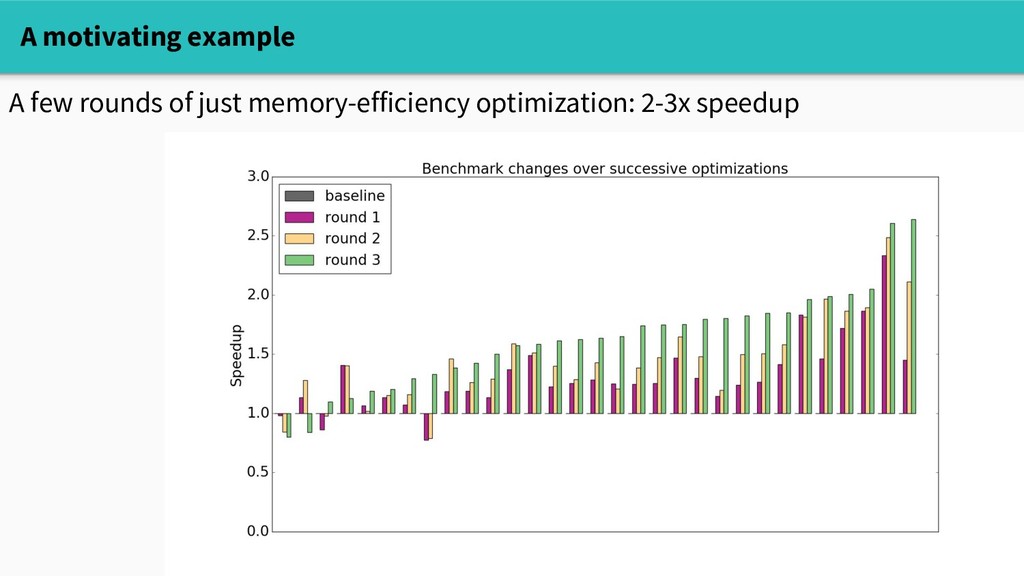
A motivating example Storage / query service at the day
job (Honeycomb): - goal: <5 second query latency - up to billions of rows per query - flexible queries, on-the-fly schema changes -
Why this talk - A program's allocation patterns can substantially
affect its performance! - However, those patterns are often syntactically opaque. - Equipped with understanding and the right set of tools, we can spend our time more wisely. -
Why this talk - A program's allocation patterns can substantially
affect its performance! - However, those patterns are often syntactically opaque. - Equipped with understanding and the right set of tools, we can spend our time more wisely. - Moreover, the runtime's internals are inherently interesting! -
Outline I. To tame the beast, you must first understand
its mind How do the allocator and garbage collector work? II. Bring your binoculars Tools for understanding allocation patterns III. Delicious treats for the ravenous allocator Strategies for improving memory efficiency -
This is a practitioner's perspective. The Go runtime authors are
much smarter than me, maybe even smarter than you! And they're always cooking up new stuff A Caveat The Go runtime team discusses the design of the garbage collector. -
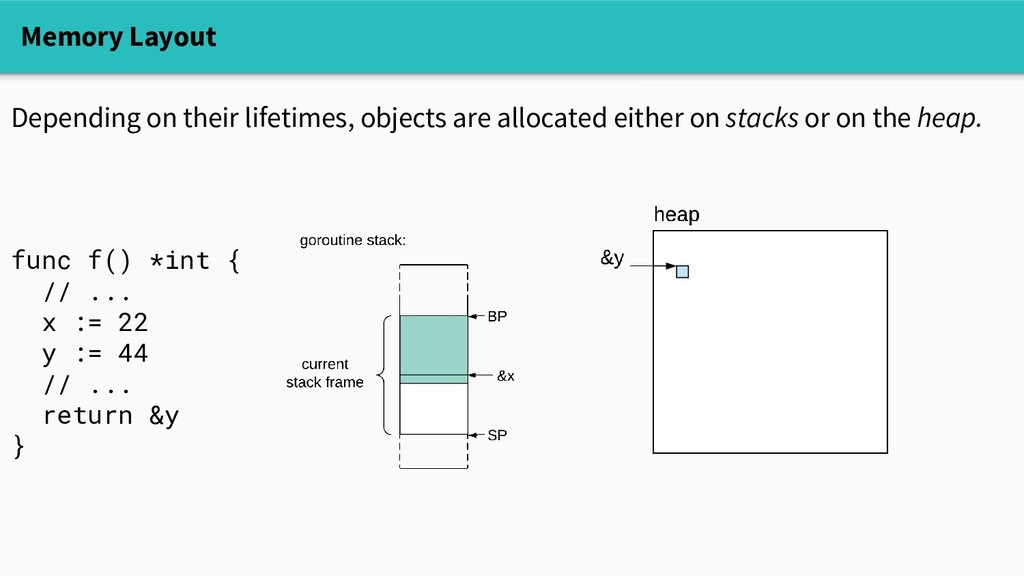
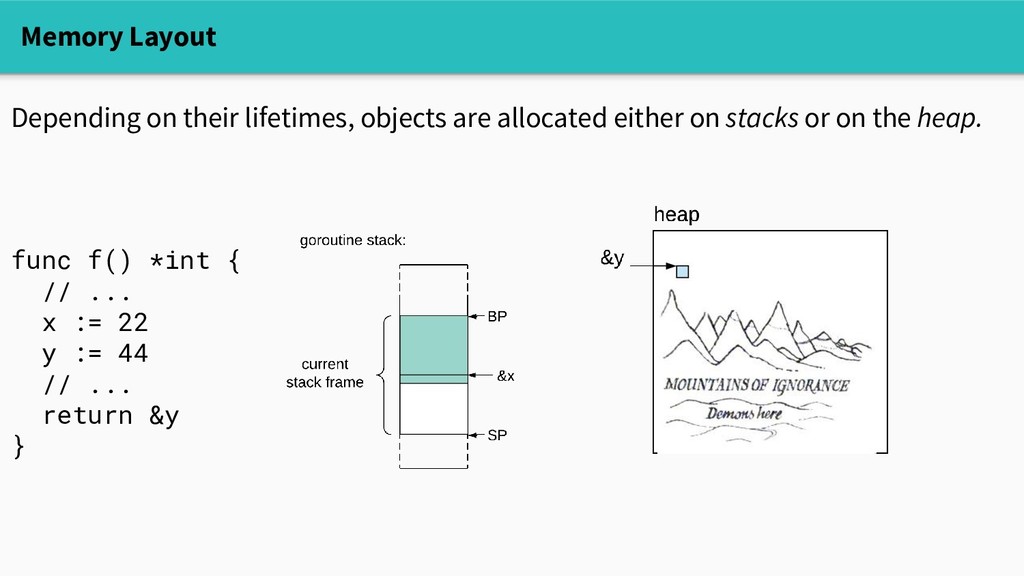
Memory Layout func f() *int { // ... x :=
22 y := 44 // ... return &y } Depending on their lifetimes, objects are allocated either on stacks or on the heap. -
Memory Layout func f() *int { // ... x :=
22 y := 44 // ... return &y } Depending on their lifetimes, objects are allocated either on stacks or on the heap. -
Memory Layout Design goals for an allocator: - Efficiently satisfy
allocations of a given size, but avoid fragmentation - Avoid locking in the common case - Efficiently reclaim freeable memory -
Memory Layout Design goals for an allocator: - Efficiently satisfy
allocations of a given size, but avoid fragmentation allocate like-sized objects in blocks - Avoid locking in the common case - Efficiently reclaim freeable memory -
Memory Layout Design goals for an allocator: - Efficiently satisfy
allocations of a given size, but avoid fragmentation allocate like-sized objects in blocks - Avoid locking in the common case maintain local caches - Efficiently reclaim freeable memory -
Memory Layout Design goals for an allocator: - Efficiently satisfy
allocations of a given size, but avoid fragmentation allocate like-sized objects in blocks - Avoid locking in the common case maintain local caches - Efficiently reclaim freeable memory use bitmaps for metadata, run GC concurrently -
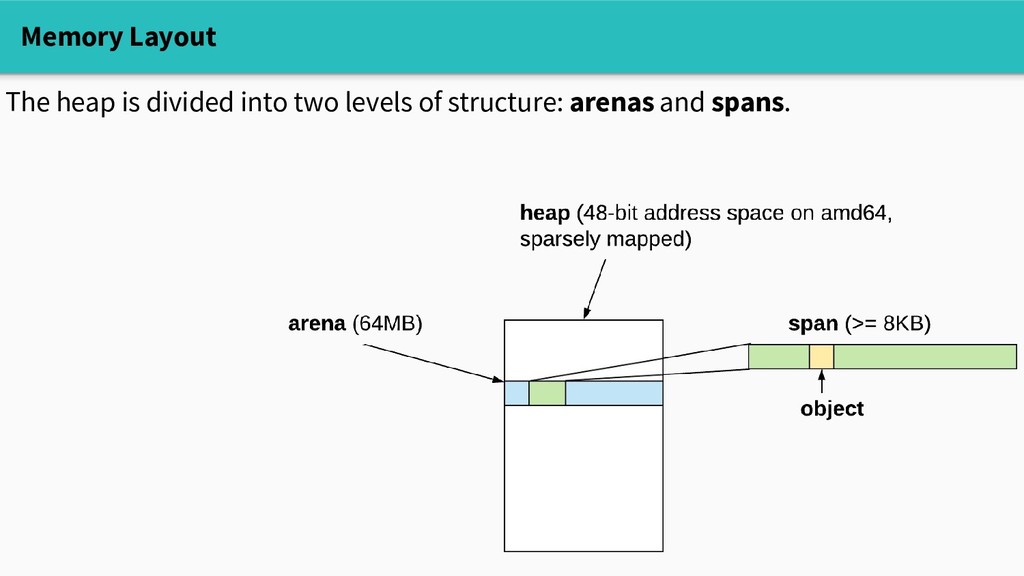
Memory Layout The heap is divided into two levels of
structure: arenas and spans. -
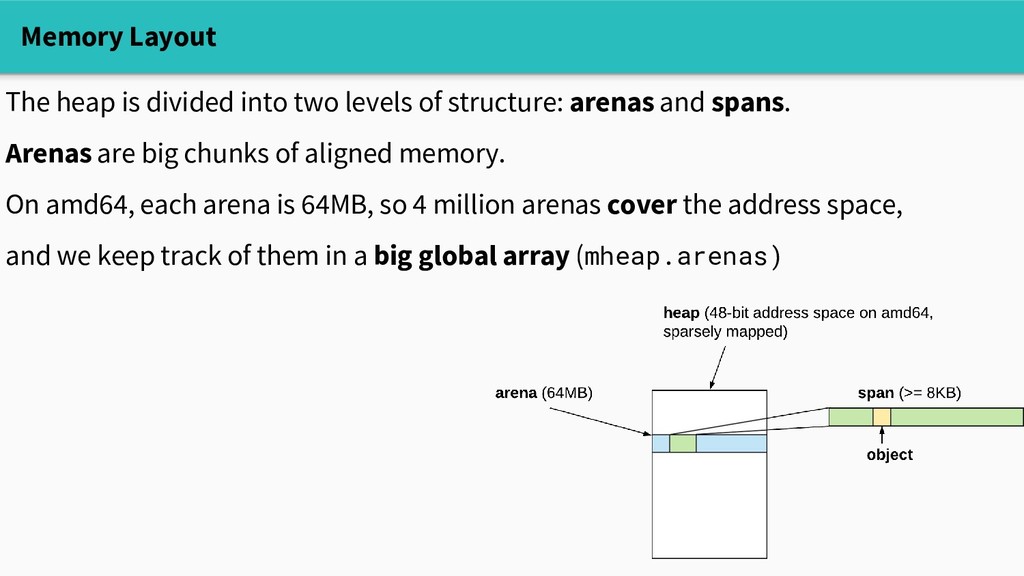
Memory Layout The heap is divided into two levels of
structure: arenas and spans. Arenas are big chunks of aligned memory. On amd64, each arena is 64MB, so 4 million arenas cover the address space, and we keep track of them in a big global array (mheap.arenas) -
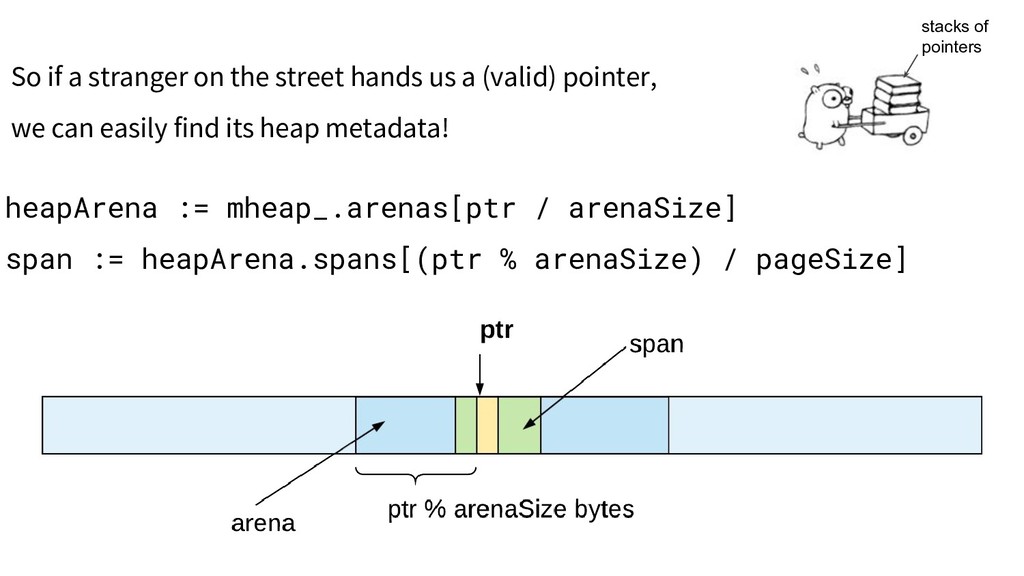
So if a stranger on the street hands us a
(valid) pointer, we can easily find its heap metadata! heapArena := mheap_.arenas[ptr / arenaSize] span := heapArena.spans[(ptr % arenaSize) / pageSize] stacks of pointers -
What's a span? Managing the heap at arena granularity isn't
practical, so heap objects live in spans. Small objects (<=32KB) live in spans of a fixed size class. type span struct { startAddr uintptr npages uintptr spanclass spanClass // allocated/free bitmap allocBits *gcBits // ... } -
What's a span? Managing the heap at arena granularity isn't
practical, so heap objects live in spans. Small objects (<=32KB) live in spans of a fixed size class. - There are ~70 size classes - Their spans are 8KB-64KB - So we can compactly allocate small objects with at most a few MB overhead -
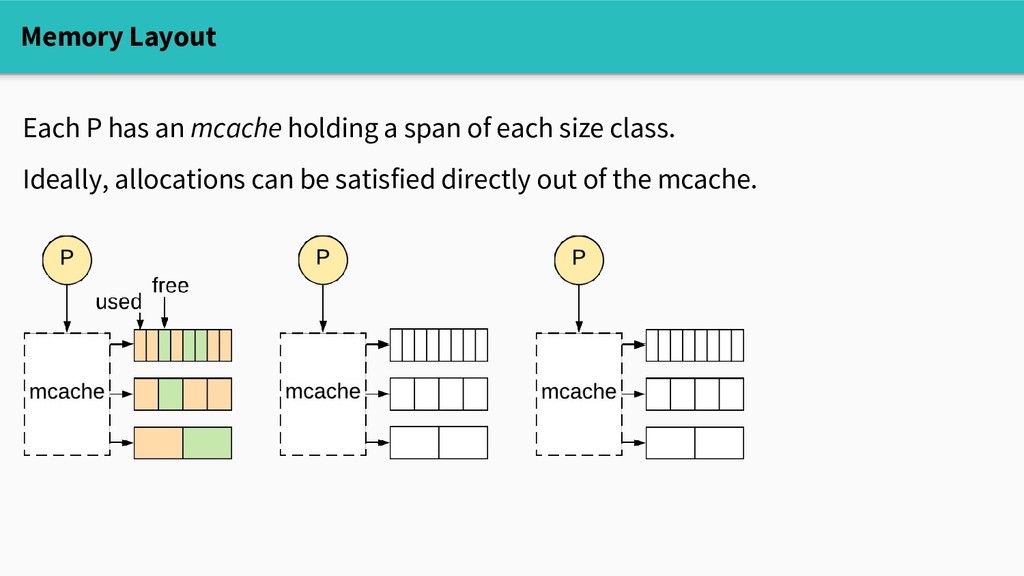
Memory Layout Each P has an mcache holding a span
of each size class. Ideally, allocations can be satisfied directly out of the mcache. -
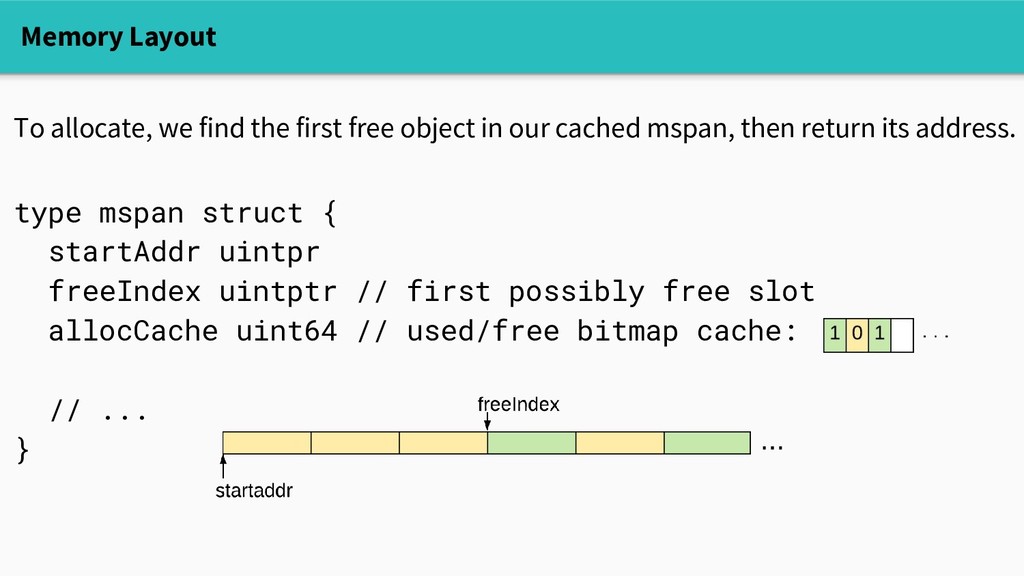
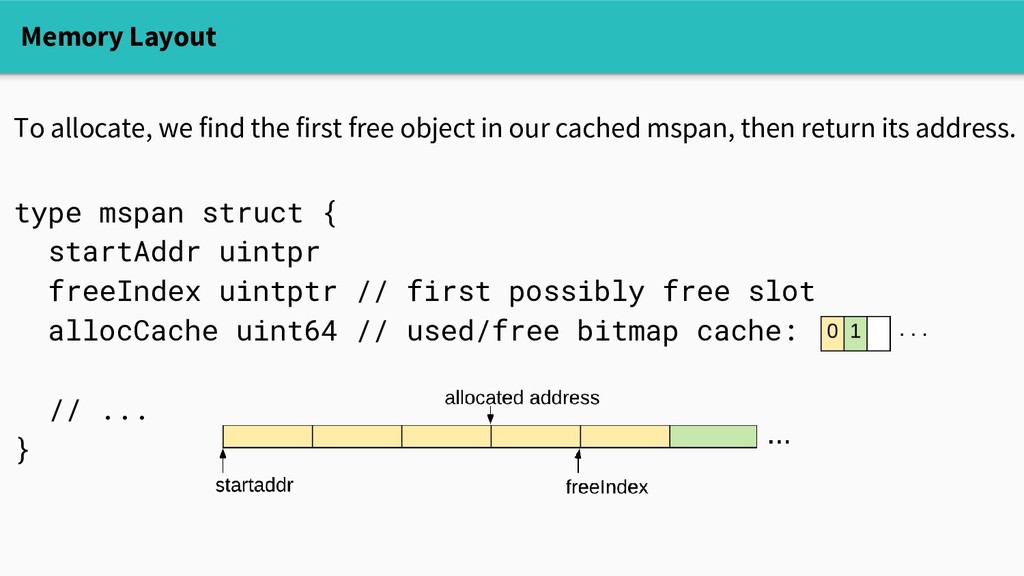
Memory Layout To allocate, we find the first free object
in our cached mspan, then return its address. type mspan struct { startAddr uintpr freeIndex uintptr // first possibly free slot allocCache uint64 // used/free bitmap cache: // ... } -
Memory Layout To allocate, we find the first free object
in our cached mspan, then return its address. type mspan struct { startAddr uintpr freeIndex uintptr // first possibly free slot allocCache uint64 // used/free bitmap cache: // ... } -
Memory Layout This means that "most" memory allocations are fast:
1. Find a cached span with the right size (mcache.mspan[sizeClass]) (if there's none, get a new span, cache it) 2. Find the next free object in the span 3. If necessary, update the heap bitmap (so the garbage collector knows which fields are pointers) and require no locking! -
Memory Layout What have we got so far? ✓ Efficiently
satisfy allocations of a given size, but avoid fragmentation allocate like-sized objects in blocks ✓ Avoid locking in the common case maintain local caches ? Efficiently reclaim free memory -
Memory Layout What have we got so far? ✓ Efficiently
satisfy allocations of a given size, but avoid fragmentation allocate like-sized objects in blocks ✓ Avoid locking in the common case maintain local caches ? Efficiently reclaim free memory What about garbage collection? -
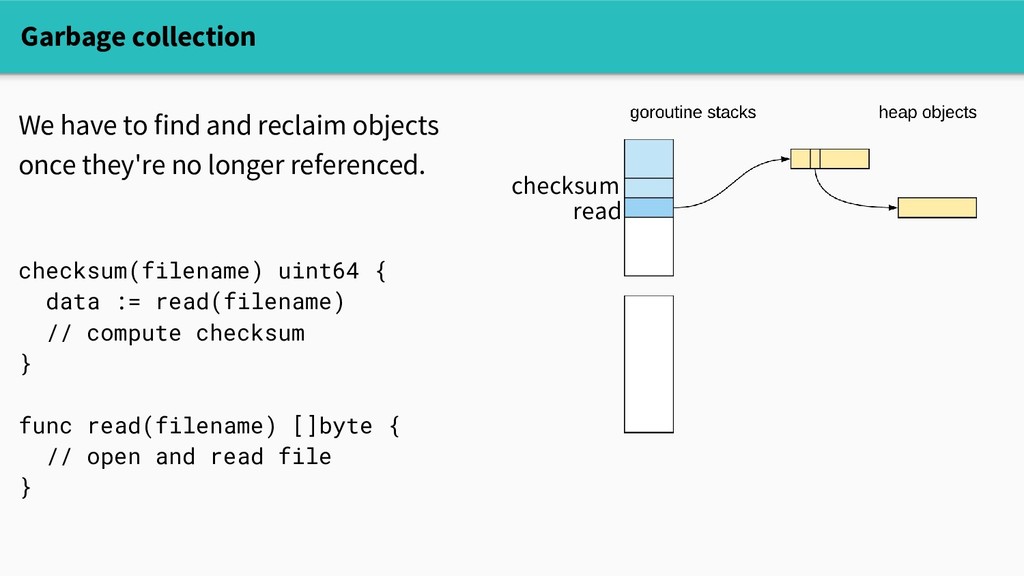
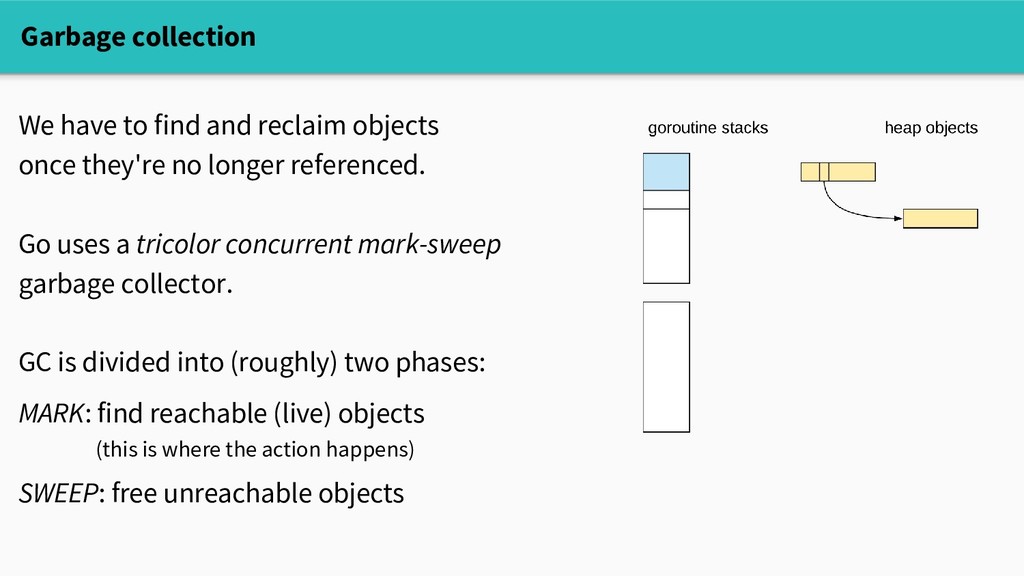
Garbage collection We have to find and reclaim objects once
they're no longer referenced. checksum(filename) uint64 { data := read(filename) // compute checksum } func read(filename) []byte { // open and read file } checksum read -
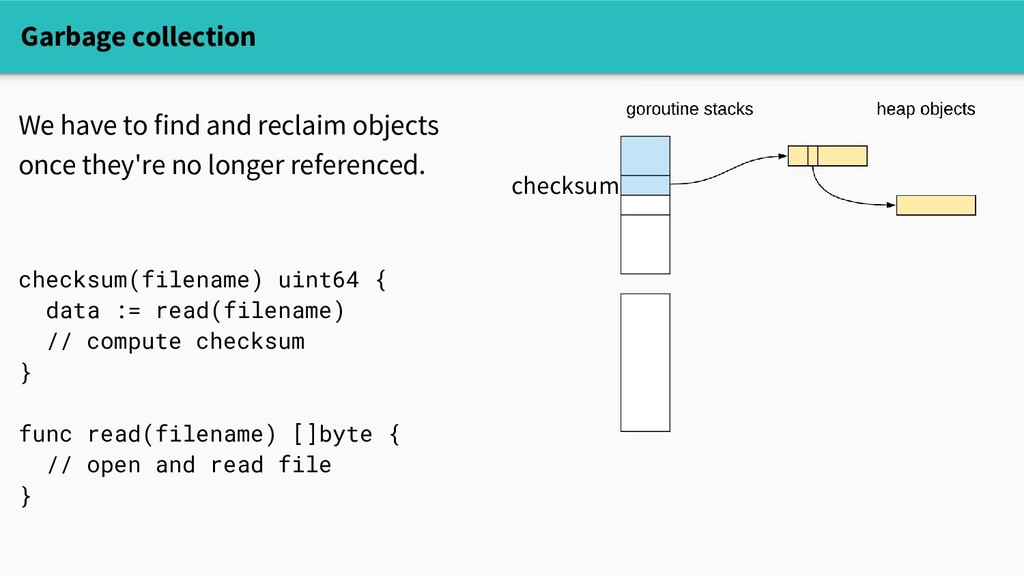
Garbage collection We have to find and reclaim objects once
they're no longer referenced. checksum(filename) uint64 { data := read(filename) // compute checksum } func read(filename) []byte { // open and read file } checksum -
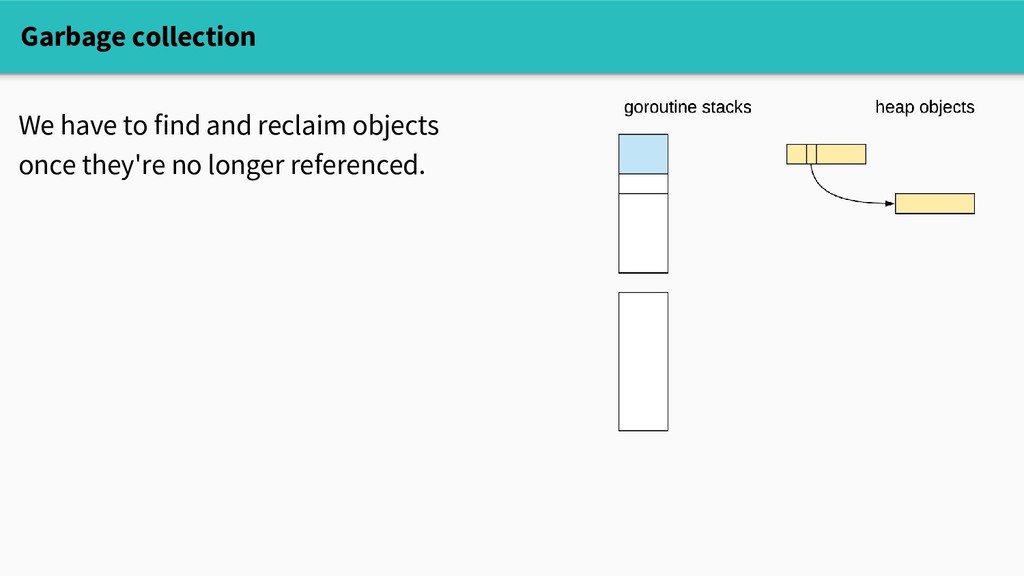
Garbage collection We have to find and reclaim objects once
they're no longer referenced. -
Garbage collection We have to find and reclaim objects once
they're no longer referenced. Go uses a tricolor concurrent mark-sweep garbage collector. -
Garbage collection We have to find and reclaim objects once
they're no longer referenced. Go uses a tricolor concurrent mark-sweep garbage collector. GC is divided into (roughly) two phases: MARK: find reachable (live) objects (this is where the action happens) SWEEP: free unreachable objects -
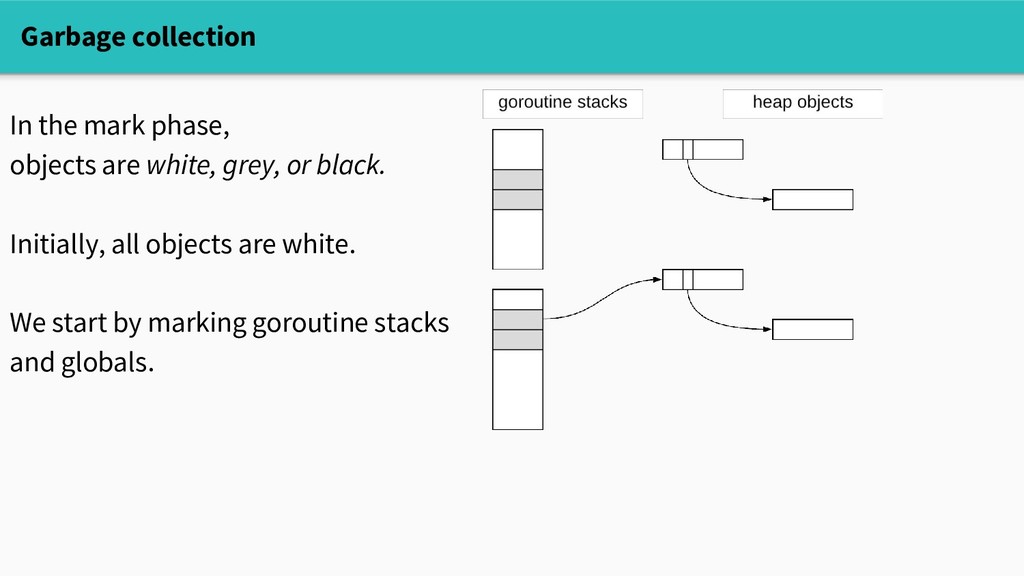
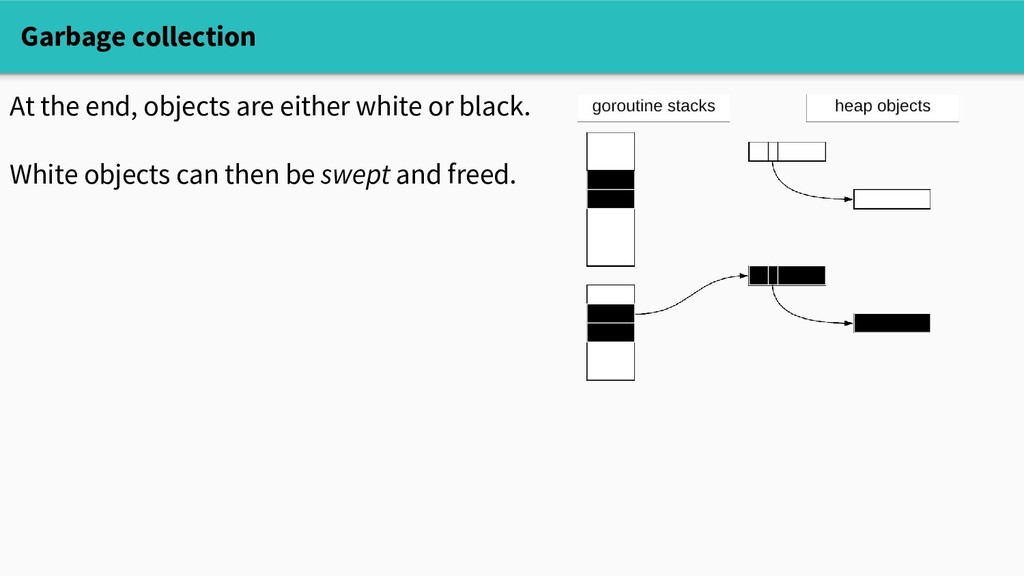
Garbage collection In the mark phase, objects are white, grey,
or black. Initially, all objects are white. We start by marking goroutine stacks and globals. -
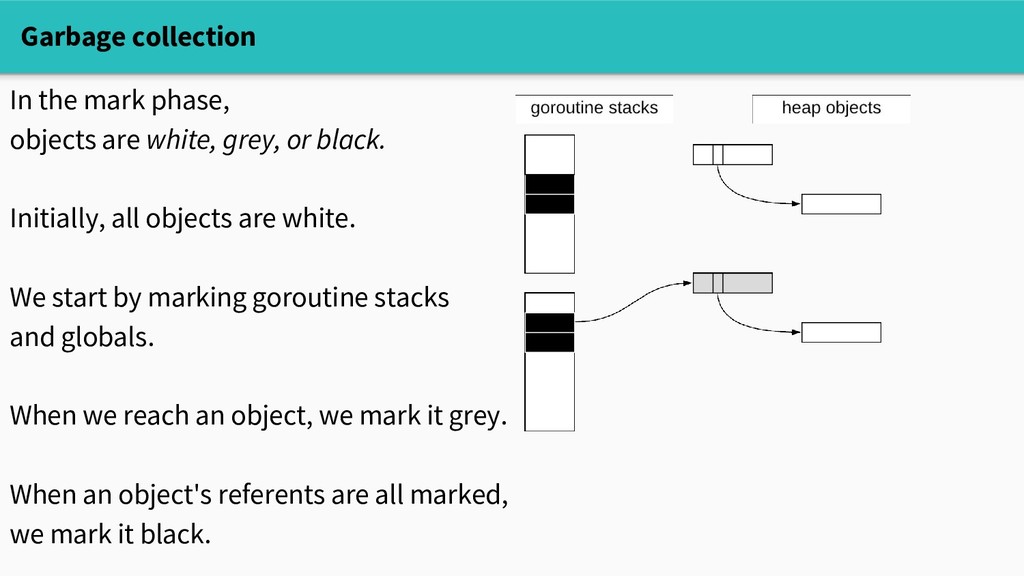
Garbage collection In the mark phase, objects are white, grey,
or black. Initially, all objects are white. We start by marking goroutine stacks and globals. When we reach an object, we mark it grey. -
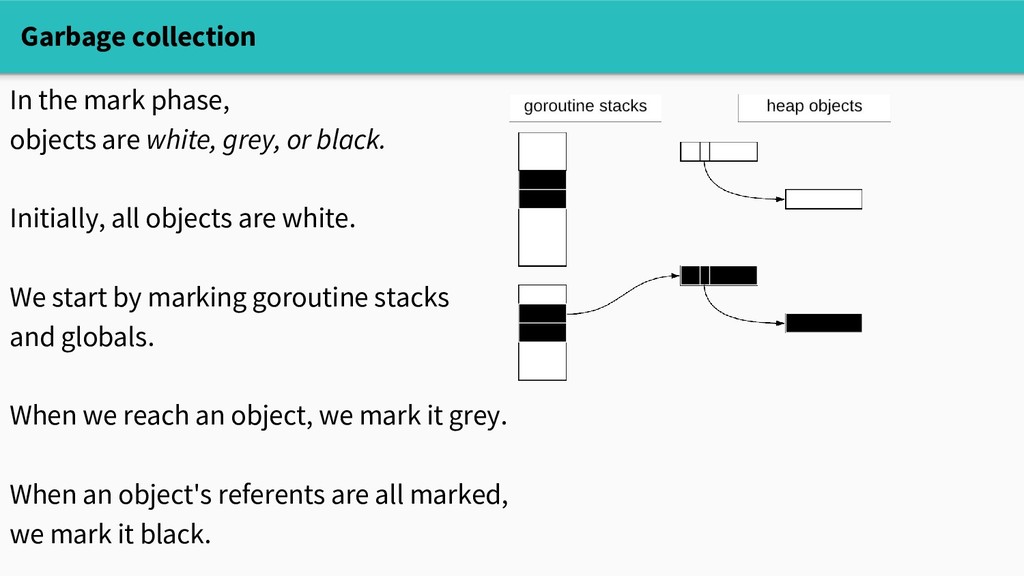
Garbage collection In the mark phase, objects are white, grey,
or black. Initially, all objects are white. We start by marking goroutine stacks and globals. When we reach an object, we mark it grey. When an object's referents are all marked, we mark it black. -
Garbage collection In the mark phase, objects are white, grey,
or black. Initially, all objects are white. We start by marking goroutine stacks and globals. When we reach an object, we mark it grey. When an object's referents are all marked, we mark it black. -
Garbage collection At the end, objects are either white or
black. White objects can then be swept and freed. -
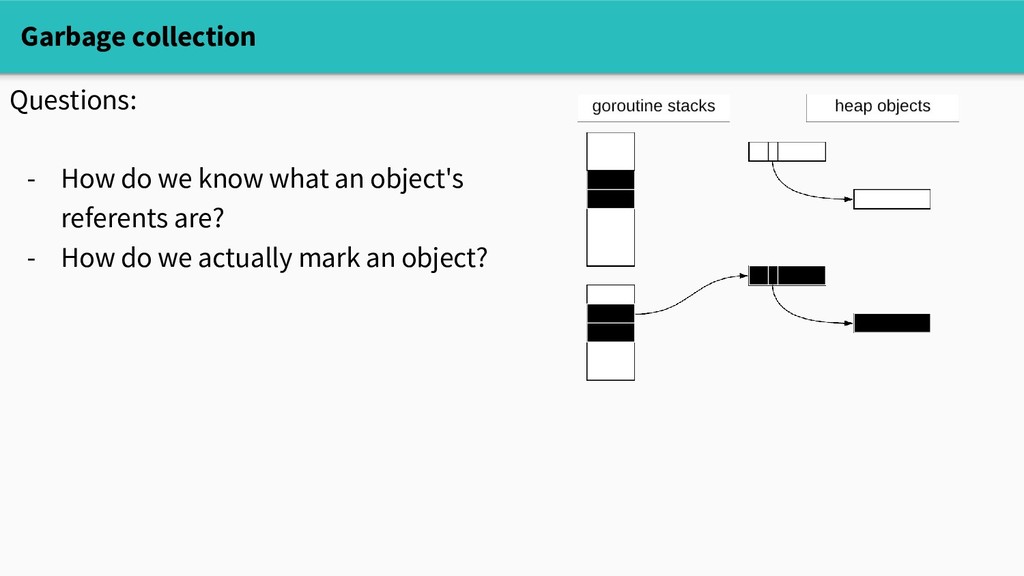
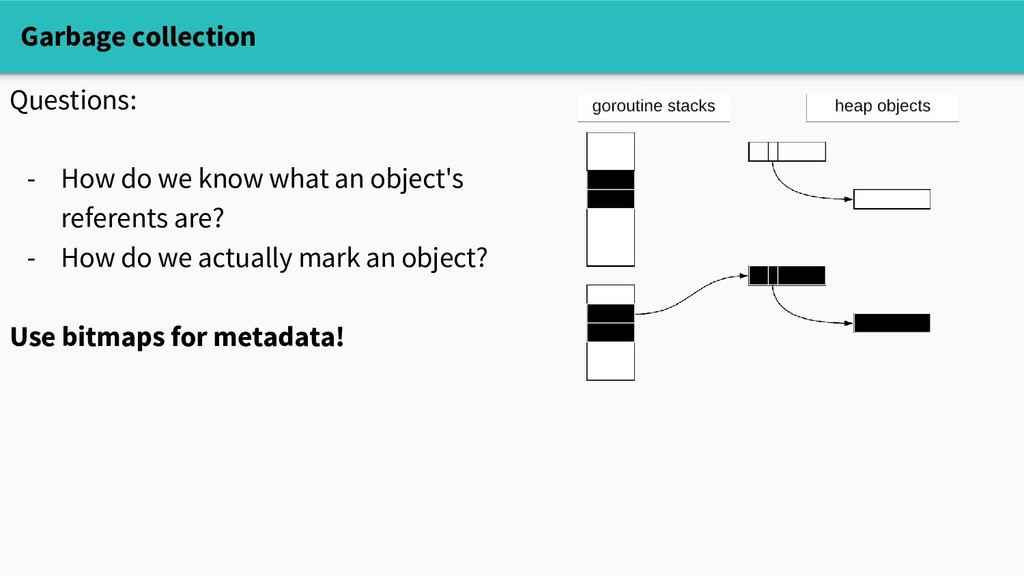
Garbage collection Questions: - How do we know what an
object's referents are? - How do we actually mark an object? -
Garbage collection Questions: - How do we know what an
object's referents are? - How do we actually mark an object? Use bitmaps for metadata! -
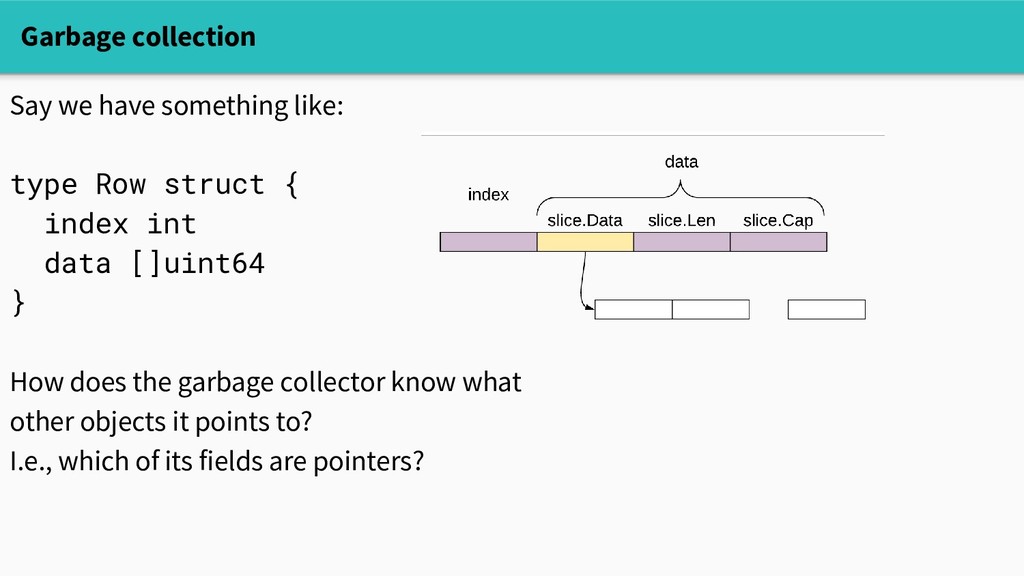
Garbage collection Say we have something like: type Row struct
{ index int data []uint64 } How does the garbage collector know what other objects it points to? I.e., which of its fields are pointers? -
Garbage collection Remember that this heap object is actually inside
an arena! The arena's bitmap tells us which of its words are pointers. -
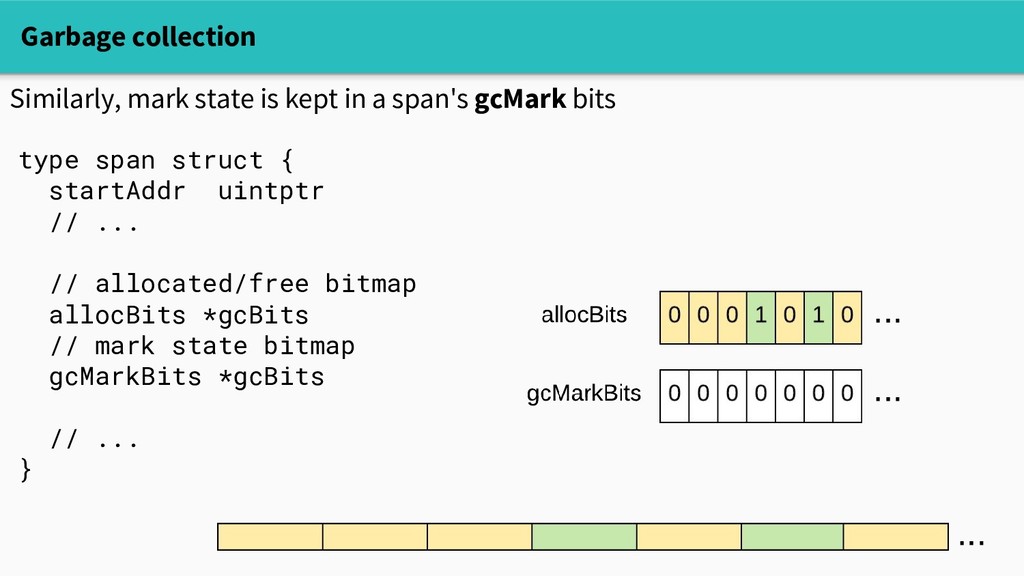
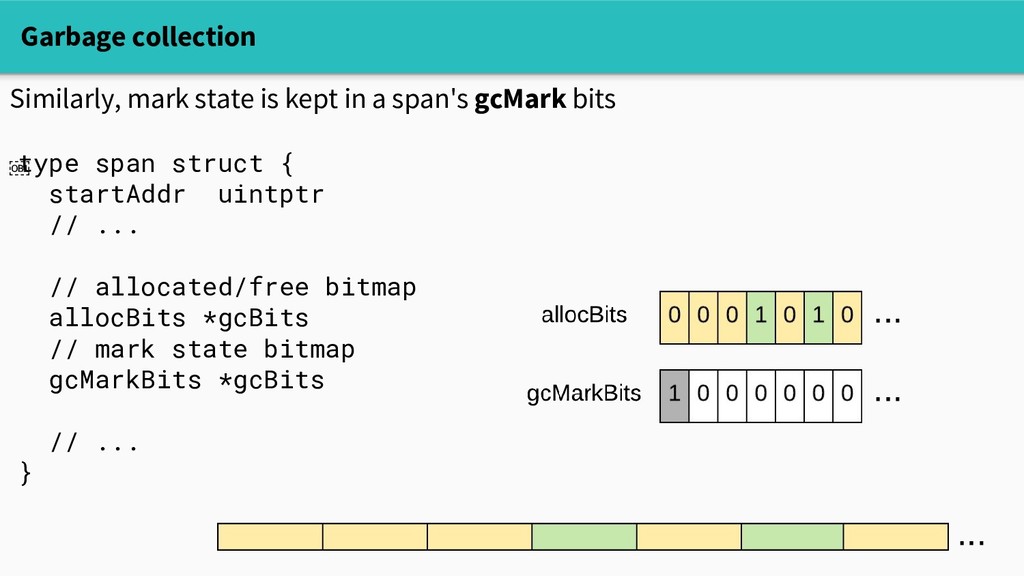
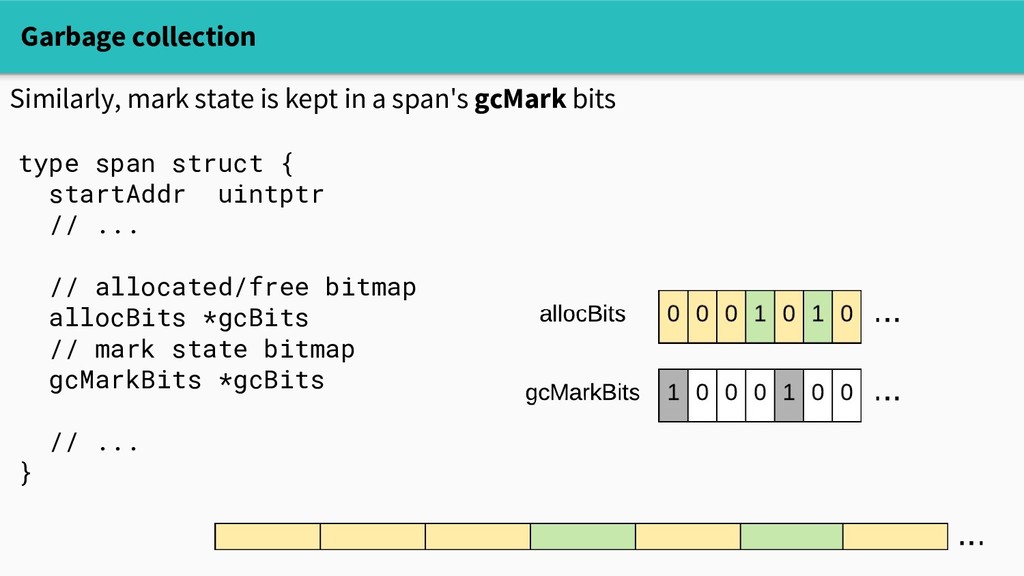
Garbage collection Similarly, mark state is kept in a span's
gcMark bits type span struct { startAddr uintptr // ... // allocated/free bitmap allocBits *gcBits // mark state bitmap gcMarkBits *gcBits // ... } -
Garbage collection Similarly, mark state is kept in a span's
gcMark bits type span struct { startAddr uintptr // ... // allocated/free bitmap allocBits *gcBits // mark state bitmap gcMarkBits *gcBits // ... }  -
Garbage collection Similarly, mark state is kept in a span's
gcMark bits type span struct { startAddr uintptr // ... // allocated/free bitmap allocBits *gcBits // mark state bitmap gcMarkBits *gcBits // ... } -
Garbage collection Similarly, mark state is kept in a span's
gcMark bits type span struct { startAddr uintptr // ... // allocated/free bitmap allocBits *gcBits // mark state bitmap gcMarkBits *gcBits // ... } -
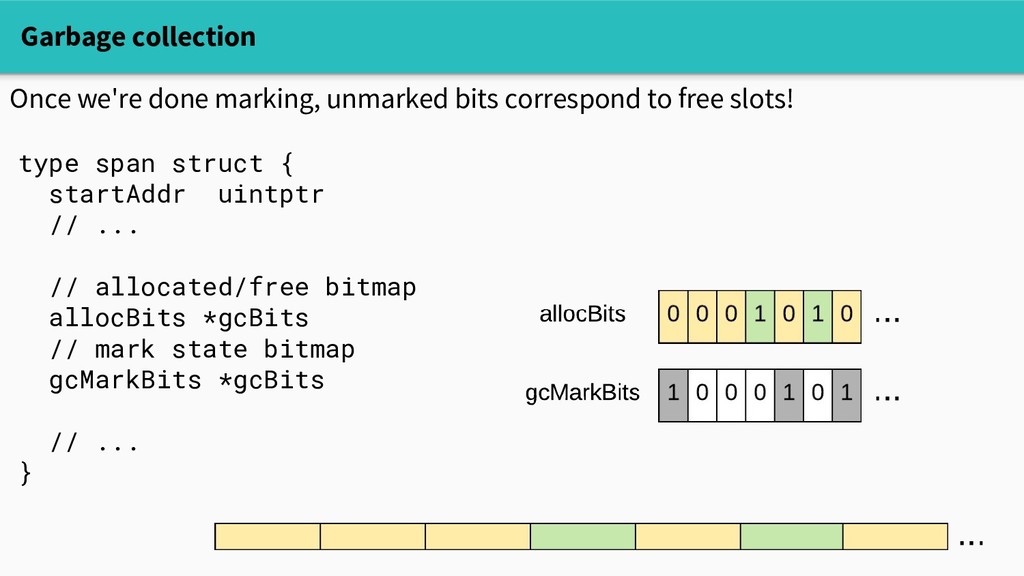
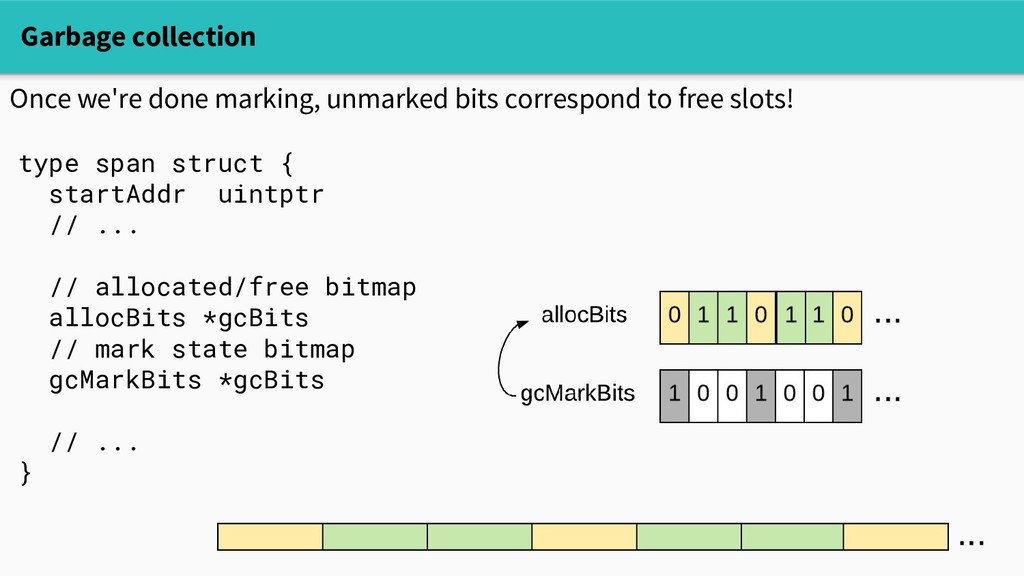
Garbage collection Once we're done marking, unmarked bits correspond to
free slots! type span struct { startAddr uintptr // ... // allocated/free bitmap allocBits *gcBits // mark state bitmap gcMarkBits *gcBits // ... } -
Garbage collection Once we're done marking, unmarked bits correspond to
free slots! type span struct { startAddr uintptr // ... // allocated/free bitmap allocBits *gcBits // mark state bitmap gcMarkBits *gcBits // ... } -
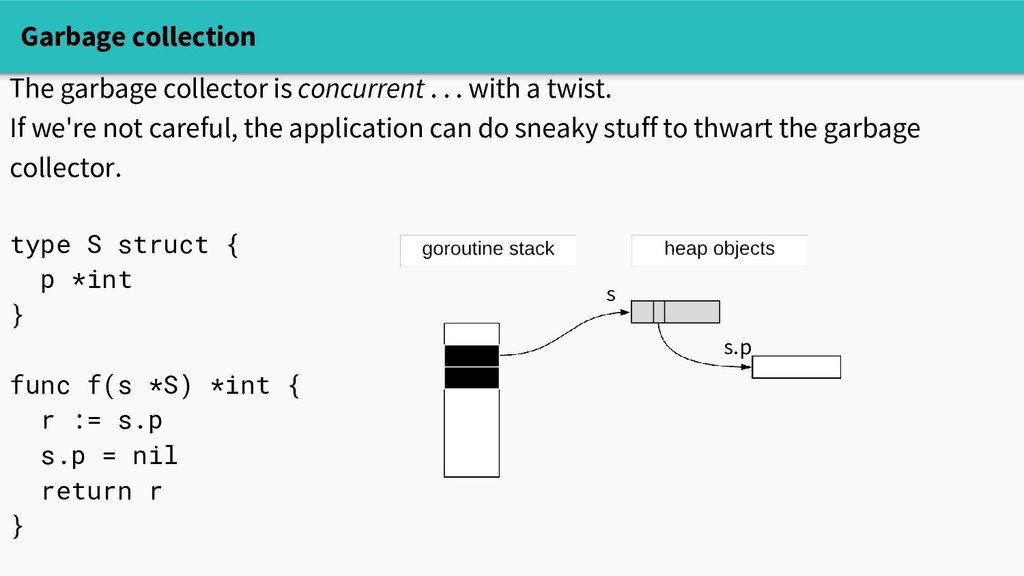
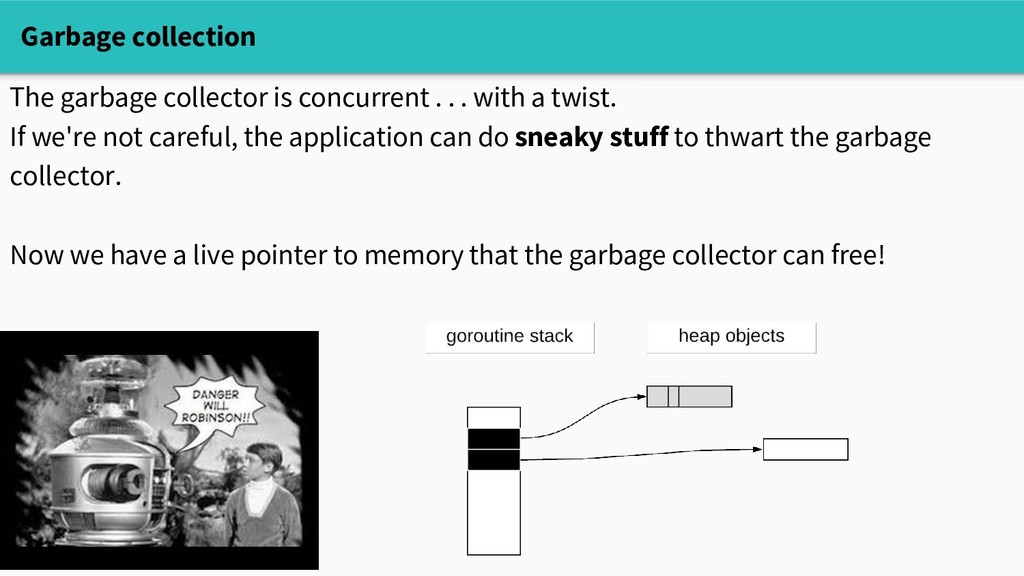
Garbage collection The garbage collector is concurrent . . .
with a twist. If we're not careful, the application can do sneaky stuff to thwart the garbage collector. type S struct { p *int } func f(s *S) *int { r := s.p s.p = nil return r } s s.p -
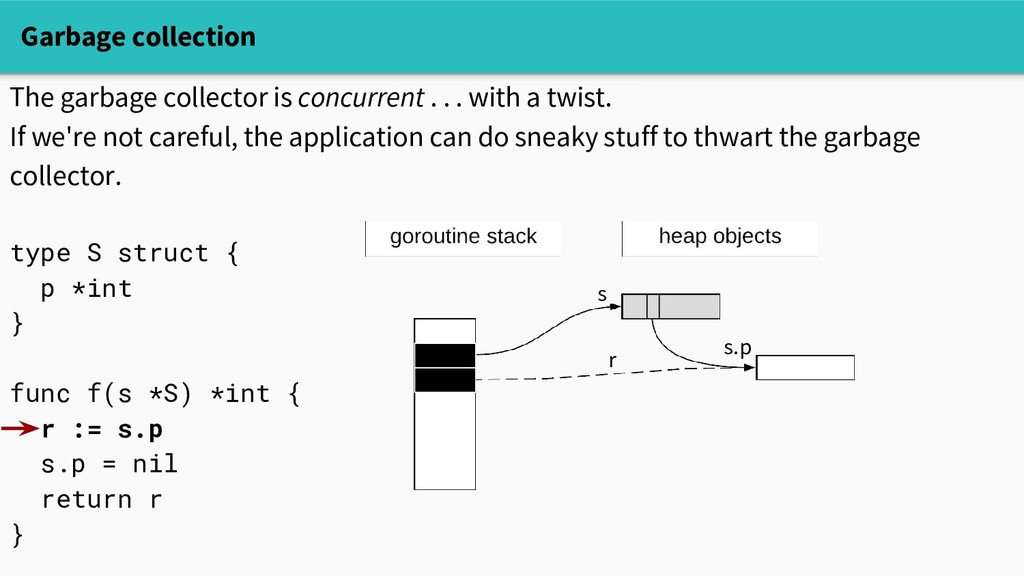
Garbage collection The garbage collector is concurrent . . .
with a twist. If we're not careful, the application can do sneaky stuff to thwart the garbage collector. type S struct { p *int } func f(s *S) *int { r := s.p s.p = nil return r } s s.p r -
Garbage collection The garbage collector is concurrent . . .
with a twist. If we're not careful, the application can do sneaky stuff to thwart the garbage collector. type S struct { p *int } func f(s *S) *int { r := s.p s.p = nil return r } s r -
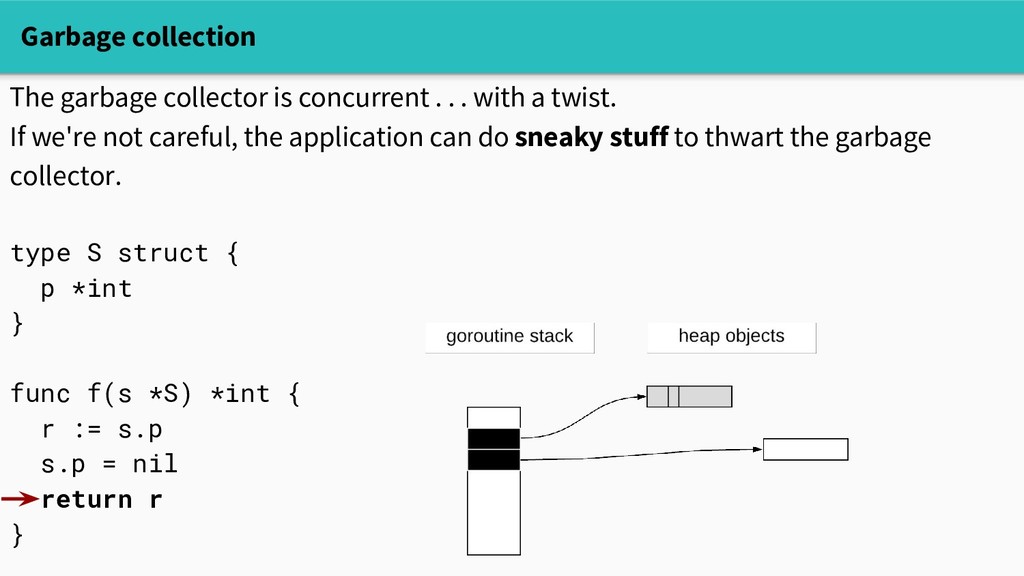
Garbage collection The garbage collector is concurrent . . .
with a twist. If we're not careful, the application can do sneaky stuff to thwart the garbage collector. type S struct { p *int } func f(s *S) *int { r := s.p s.p = nil return r } -
Garbage collection The garbage collector is concurrent . . .
with a twist. If we're not careful, the application can do sneaky stuff to thwart the garbage collector. Now we have a live pointer to memory that the garbage collector can free! -
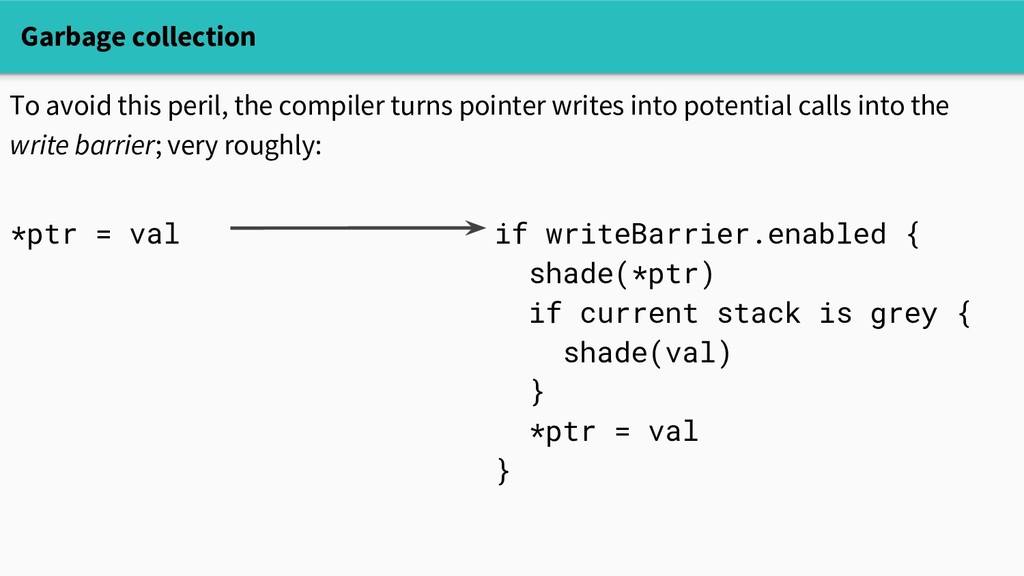
Garbage collection To avoid this peril, the compiler turns pointer
writes into potential calls into the write barrier; very roughly: if writeBarrier.enabled { shade(*ptr) if current stack is grey { shade(val) } *ptr = val } *ptr = val -
Garbage collection To avoid this peril, the compiler turns pointer
writes into potential calls into the write barrier; very roughly: if writeBarrier.enabled { shade(*ptr) if current stack is grey { shade(val) } *ptr = val } *ptr = val -
While the garbage collector is marking: - the write barrier
is on - marking consumes resources - background marking - GC assist Garbage collection -
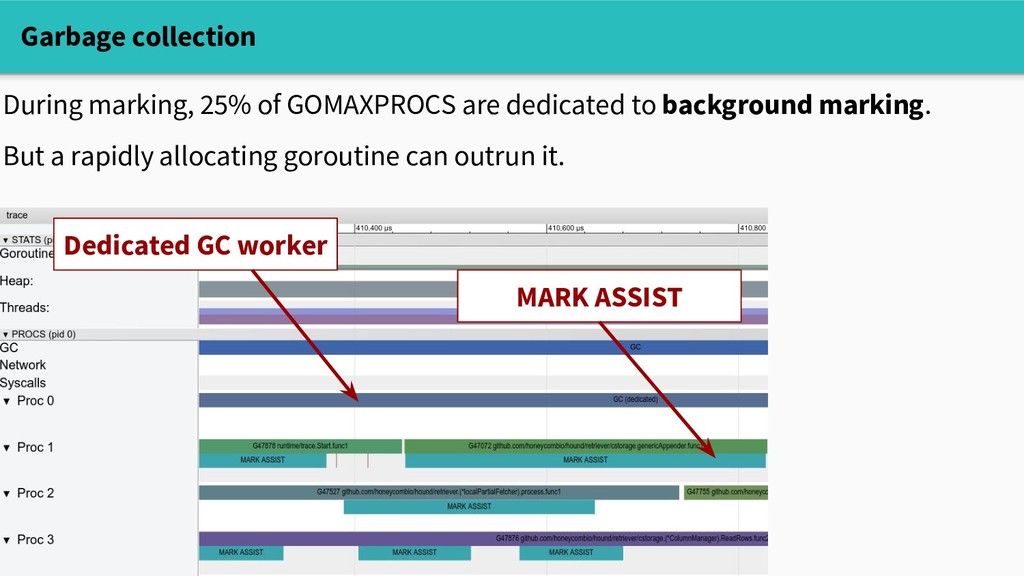
Garbage collection During marking, 25% of GOMAXPROCS are dedicated to
background marking. But a rapidly allocating goroutine can outrun it. Dedicated GC worker MARK ASSIST -
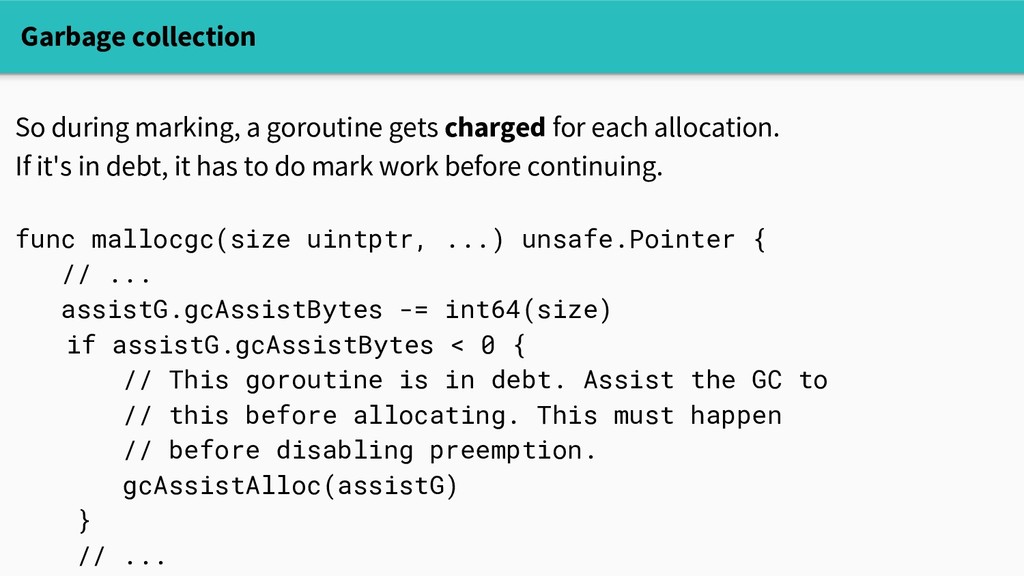
Garbage collection So during marking, a goroutine gets charged for
each allocation. If it's in debt, it has to do mark work before continuing. func mallocgc(size uintptr, ...) unsafe.Pointer { // ... assistG.gcAssistBytes -= int64(size) if assistG.gcAssistBytes < 0 { // This goroutine is in debt. Assist the GC to // this before allocating. This must happen // before disabling preemption. gcAssistAlloc(assistG) } // ... -
Garbage collection In summary: - The runtime allocates data in
spans to avoid fragmentation - Local caches speed up allocation, but the allocator still has to do some bookkeeping - GC is concurrent, but write barriers and mark assists can slow a program - GC work is proportional to scannable heap -
Question It seems like dynamic memory allocation has some cost.
Does this mean that reducing allocations will improve performance? -
Question It seems like dynamic memory allocation has some cost.
Does this mean that reducing allocations will improve performance? Well, it depends. -
Question It seems like dynamic memory allocation has some cost.
Does this mean that reducing allocations will improve performance? Well, it depends. The builtin memory profiler can tell us where we're allocating, but doesn't answer the causal question "will reducing allocations make a difference?" -
Question It seems like dynamic memory allocation has some cost.
Does this mean that reducing allocations will improve performance? Well, it depends. The builtin memory profiler can tell us where we're allocating, but doesn't answer the causal question "will reducing allocations make a difference?" Three tools to start with: - crude experimenting - sampling profiling with pprof - go tool trace -
Crude experimenting We think that the allocator and garbage collector
have some overhead, but we're not sure how much. Well . . . -
Crude experimenting We think that the allocator and garbage collector
have some overhead, but we're not sure how much. Well . . . -
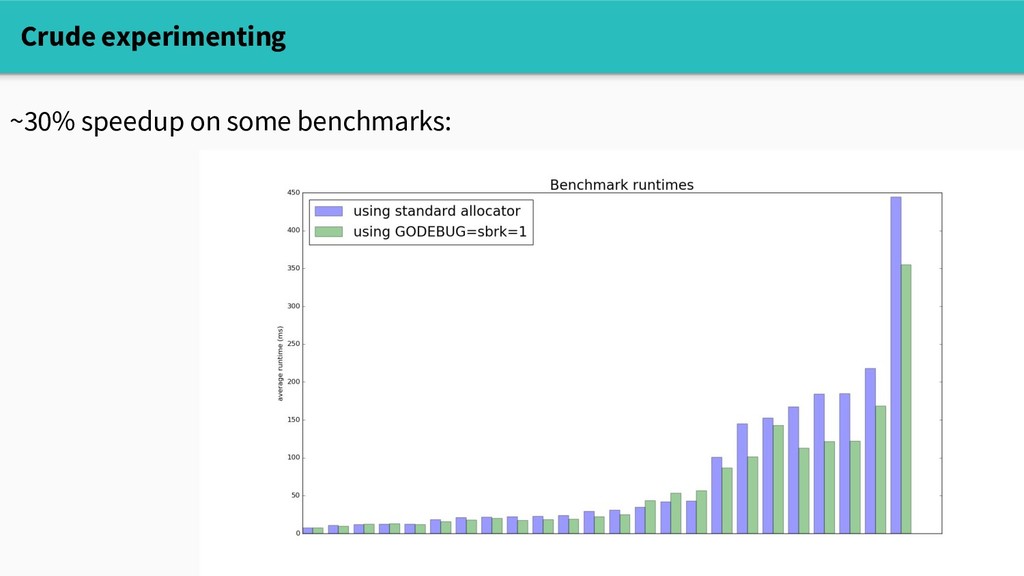
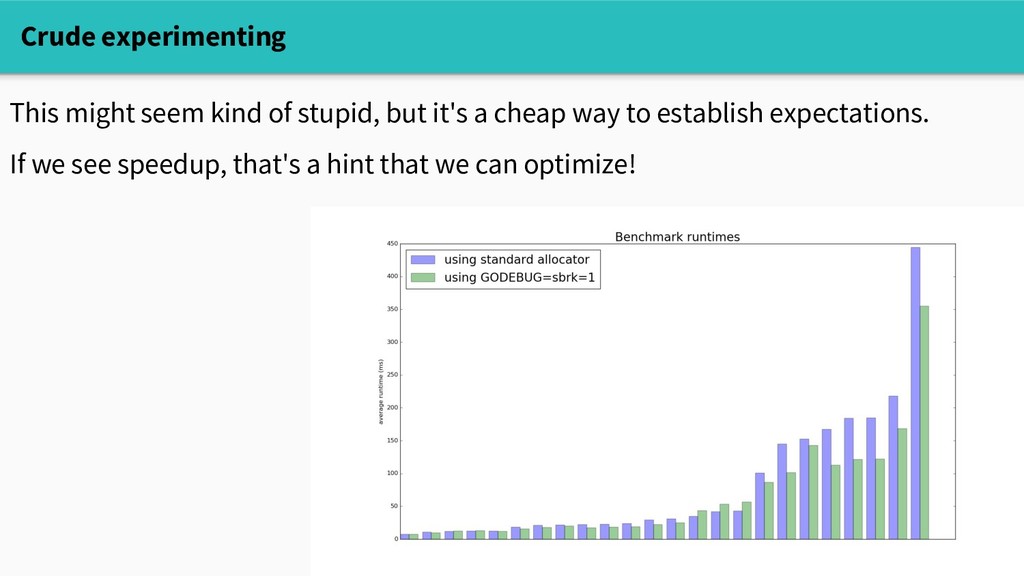
Crude experimenting Turn off the garbage collector or the allocator
with runtime flags: GOGC=off : Disables garbage collector GODEBUG=sbrk=1 : Replaces entire allocator with simple persistent allocator -
Crude experimenting This might seem kind of stupid, but it's
a cheap way to establish expectations. If we see speedup, that's a hint that we can optimize! -
This might seem kind of stupid, but it's a cheap
way to establish expectations. If we see speedup, that's a hint that we can optimize! Problems: - not viable in production: need synthetic benchmarks - persistent allocator isn't free either, so this doesn't fully reflect allocation cost Crude experimenting -
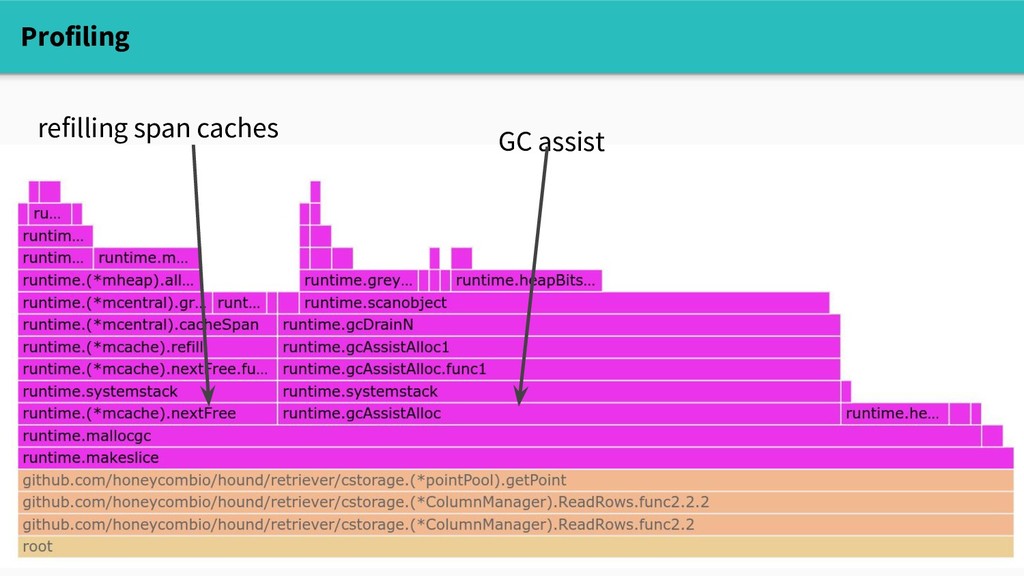
Profiling A pprof CPU profile can often show time spent
in runtime.mallocgc Tips: - Use the flamegraph viewer in the pprof web UI - If pprof isn't enabled in your binary, you can use Linux perf too -
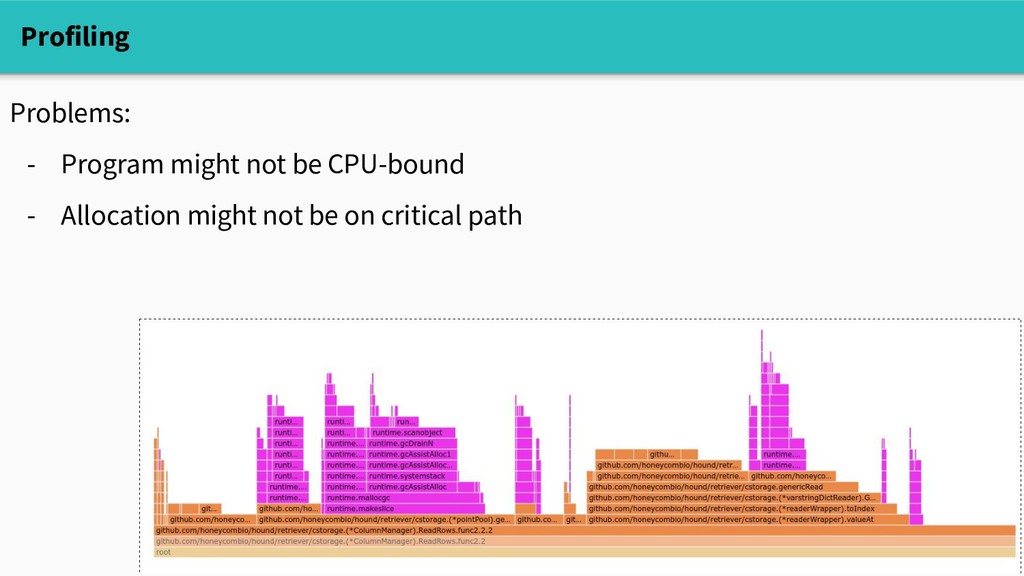
Profiling Problems: - Program might not be CPU-bound - Allocation
might not be on critical path -
go tool trace The execution tracer might be the best
tool at our disposal to understand the impact of allocating. The execution tracer captures very granular runtime events over a short time window: curl localhost:6060/debug/pprof/trace?seconds=5 > trace.out Which you can visualize in a web UI go tool trace trace.out -
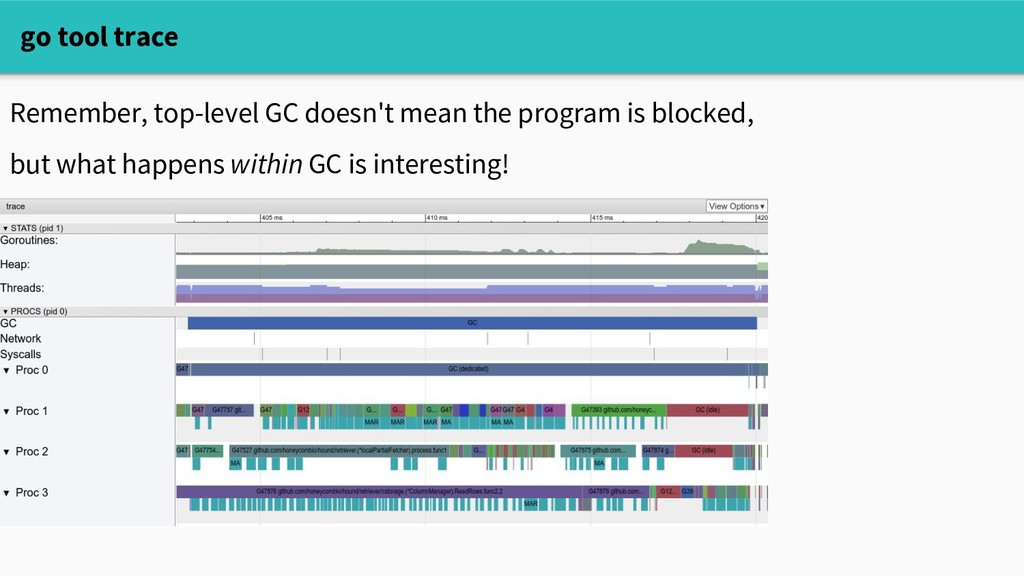
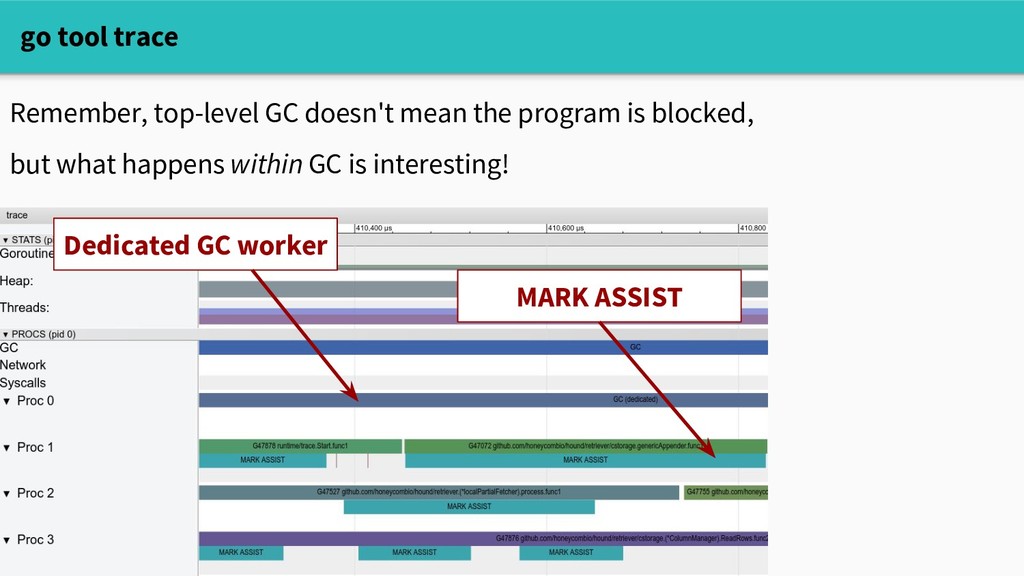
go tool trace Remember, top-level GC doesn't mean the program
is blocked, but what happens within GC is interesting! -
go tool trace Remember, top-level GC doesn't mean the program
is blocked, but what happens within GC is interesting! Dedicated GC worker MARK ASSIST -
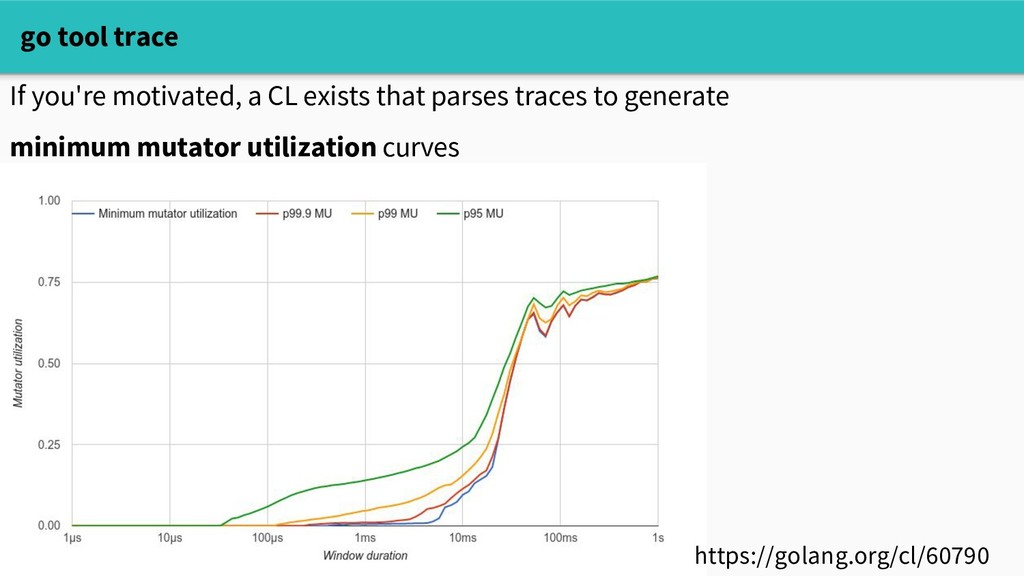
go tool trace If you're motivated, a CL exists that
parses traces to generate minimum mutator utilization curves https://golang.org/cl/60790 -
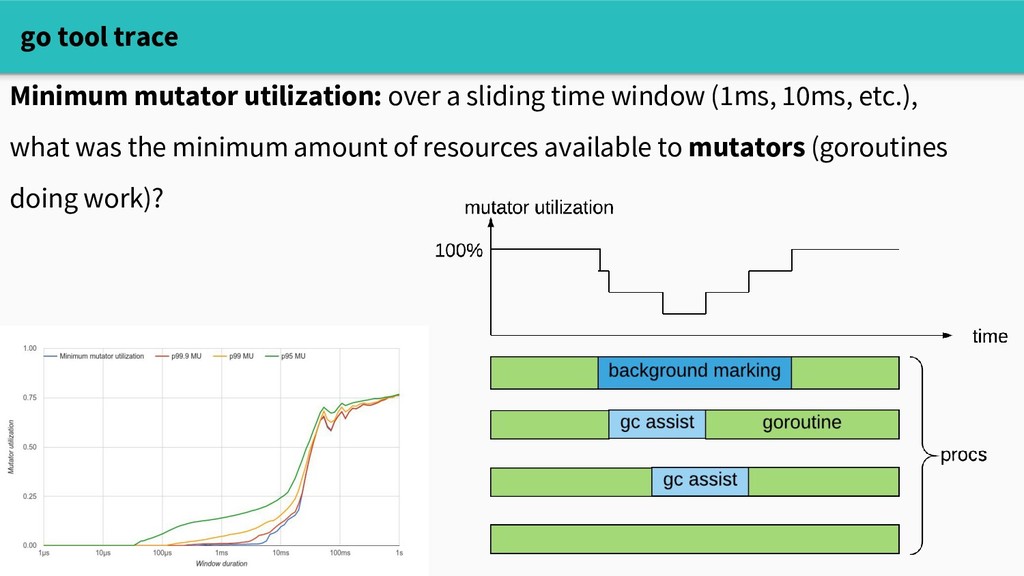
go tool trace Minimum mutator utilization: over a sliding time
window (1ms, 10ms, etc.), what was the minimum amount of resources available to mutators (goroutines doing work)? -
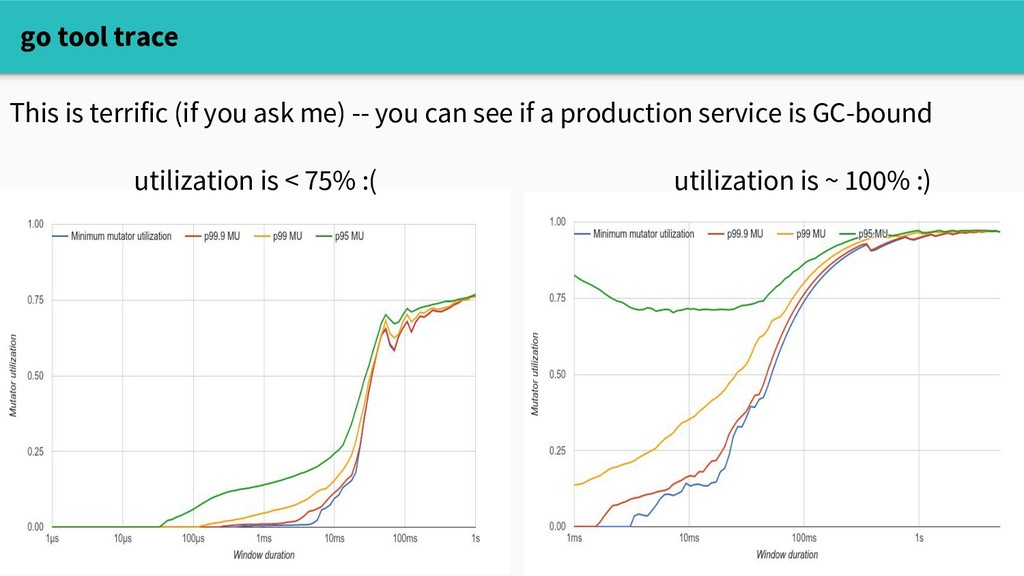
go tool trace This is terrific (if you ask me)
-- you can see if a production service is GC-bound utilization is < 75% :( utilization is ~ 100% :) -
In Summary Together, benchmarks with the allocator off, CPU profiles,
and execution traces give us a sense of: - whether allocation / GC are affecting performance - which call sites are spending a lot of time allocating - how throughput changes during GC. -
If we've concluded that allocations are a source of inefficiency,
what can we do? - Limit pointers - Allocate in batches - Try to recycle objects -
What about tuning GOGC? - Absolutely helps with throughput! However
. . . - If we want to optimize for throughput, GOGC doesn't express the real goal: "use all available memory, but no more" - Live heap size is generally (but not always) small - High GOGC makes avoiding OOMS harder But first -
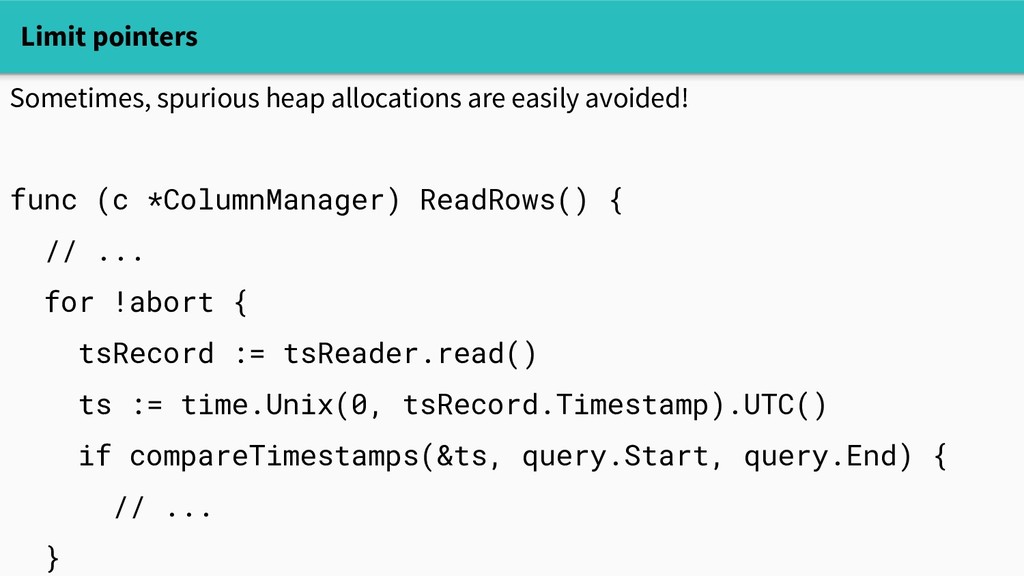
Limit pointers Sometimes, spurious heap allocations are easily avoided! func
(c *ColumnManager) ReadRows() { // ... for !abort { tsRecord := tsReader.read() ts := time.Unix(0, tsRecord.Timestamp).UTC() if compareTimestamps(&ts, query.Start, query.End) { // ... } -
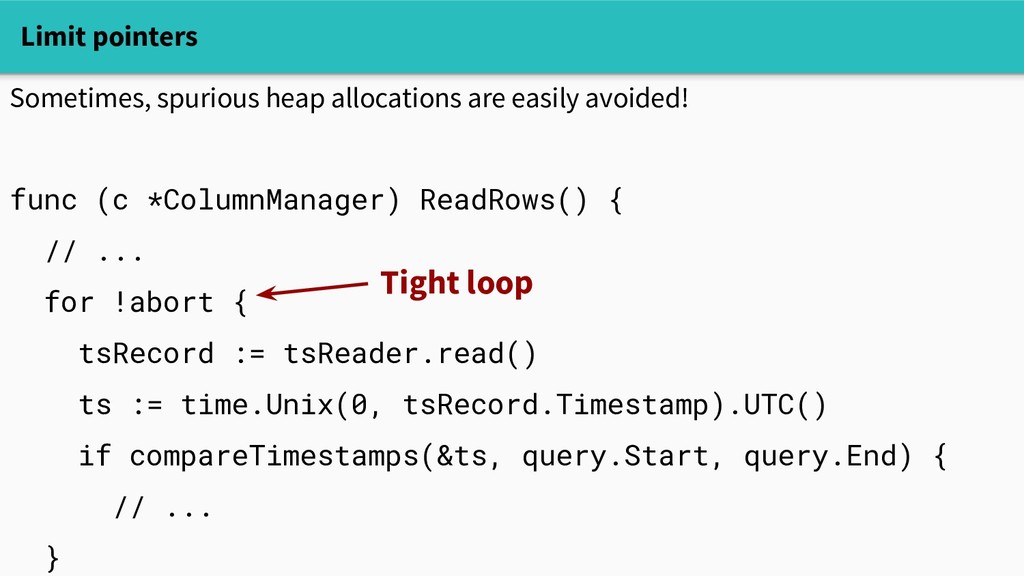
Limit pointers Sometimes, spurious heap allocations are easily avoided! func
(c *ColumnManager) ReadRows() { // ... for !abort { tsRecord := tsReader.read() ts := time.Unix(0, tsRecord.Timestamp).UTC() if compareTimestamps(&ts, query.Start, query.End) { // ... } Tight loop -
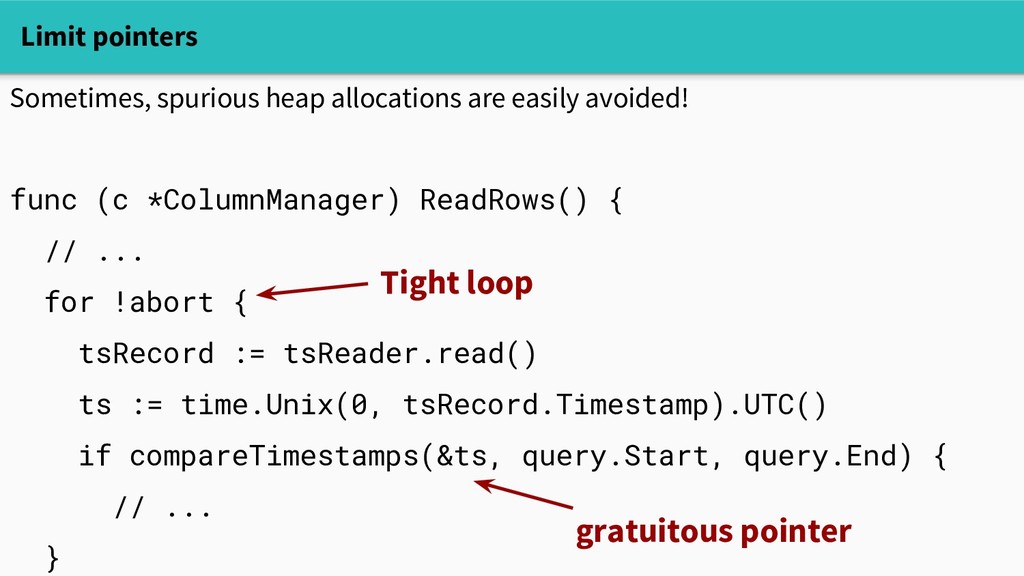
Limit pointers Sometimes, spurious heap allocations are easily avoided! func
(c *ColumnManager) ReadRows() { // ... for !abort { tsRecord := tsReader.read() ts := time.Unix(0, tsRecord.Timestamp).UTC() if compareTimestamps(&ts, query.Start, query.End) { // ... } Tight loop gratuitous pointer -
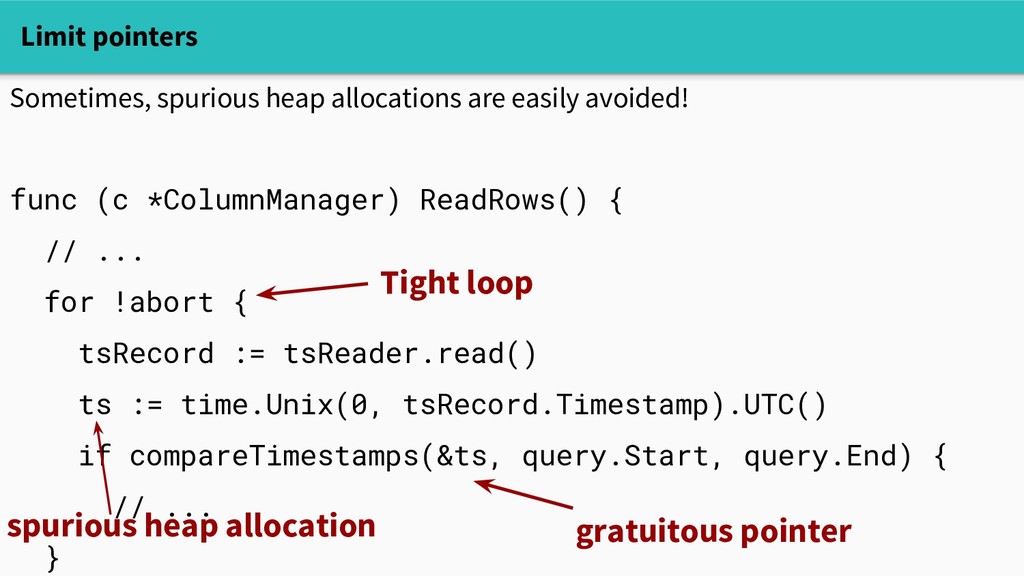
Limit pointers Sometimes, spurious heap allocations are easily avoided! func
(c *ColumnManager) ReadRows() { // ... for !abort { tsRecord := tsReader.read() ts := time.Unix(0, tsRecord.Timestamp).UTC() if compareTimestamps(&ts, query.Start, query.End) { // ... } Tight loop gratuitous pointer spurious heap allocation -
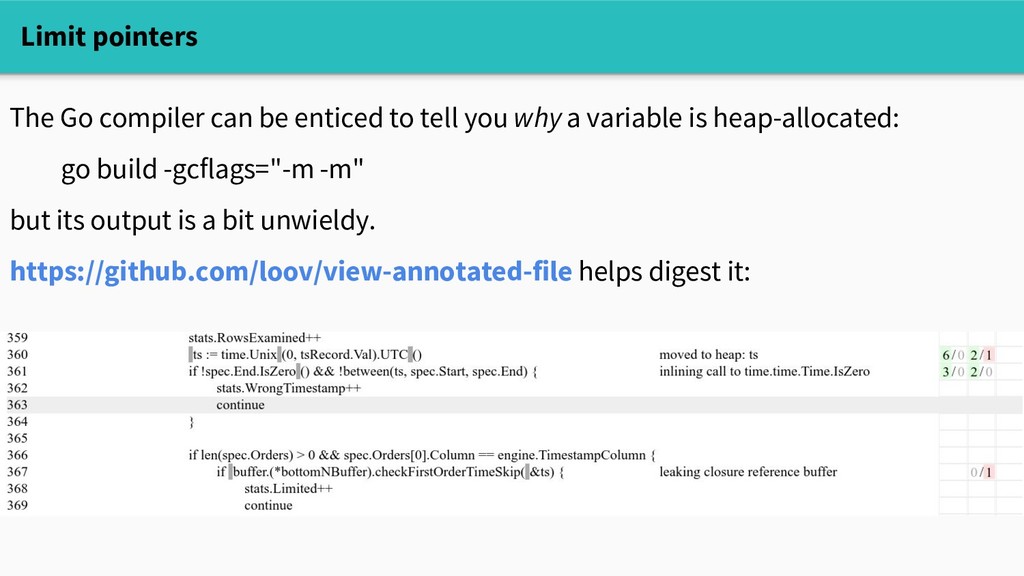
Limit pointers The Go compiler can be enticed to tell
you why a variable is heap-allocated: go build -gcflags="-m -m" but its output is a bit unwieldy. https://github.com/loov/view-annotated-file helps digest it: -
Limit pointers for !abort { tsRecord := tsReader.read() ts :=
time.Unix(0, tsRecord.Timestamp).UTC() // . . . } var ts time.Time var tsNanos uint64 -
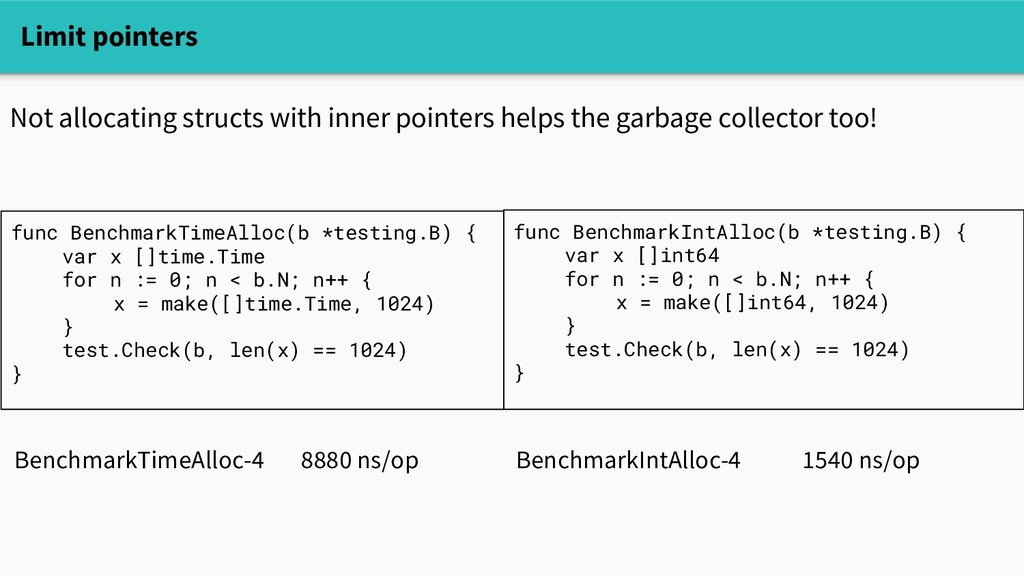
Limit pointers Not allocating structs with inner pointers helps the
garbage collector too! func BenchmarkTimeAlloc(b *testing.B) { var x []time.Time for n := 0; n < b.N; n++ { x = make([]time.Time, 1024) } test.Check(b, len(x) == 1024) } func BenchmarkIntAlloc(b *testing.B) { var x []int64 for n := 0; n < b.N; n++ { x = make([]int64, 1024) } test.Check(b, len(x) == 1024) } BenchmarkTimeAlloc-4 8880 ns/op BenchmarkIntAlloc-4 1540 ns/op -
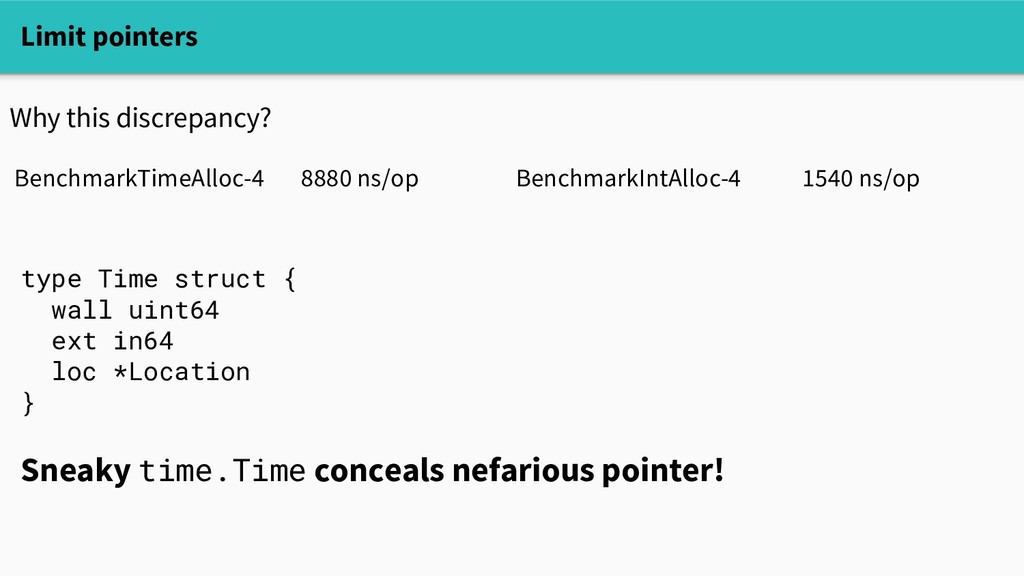
Limit pointers Why this discrepancy? BenchmarkTimeAlloc-4 8880 ns/op BenchmarkIntAlloc-4 1540
ns/op type Time struct { wall uint64 ext in64 loc *Location } Sneaky time.Time conceals nefarious pointer! -
Slab allocation Is it better to do one horse-sized allocation
or 100 duck-sized allocations? -
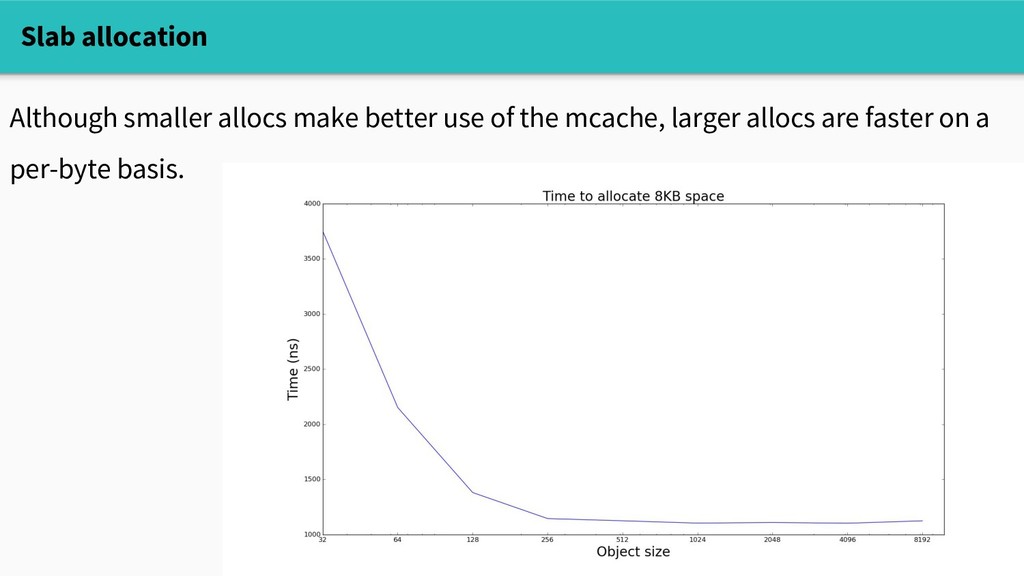
Slab allocation Although smaller allocs make better use of the
mcache, larger allocs are faster on a per-byte basis. -
Slab allocation Even though the fast path in the allocator
is very optimized, we still need to do some work on every allocation: - prevent ourselves from being preempted - check if we need to assist GC - compute the next free slot in the mcache - set heap bitmap bits - etc. -
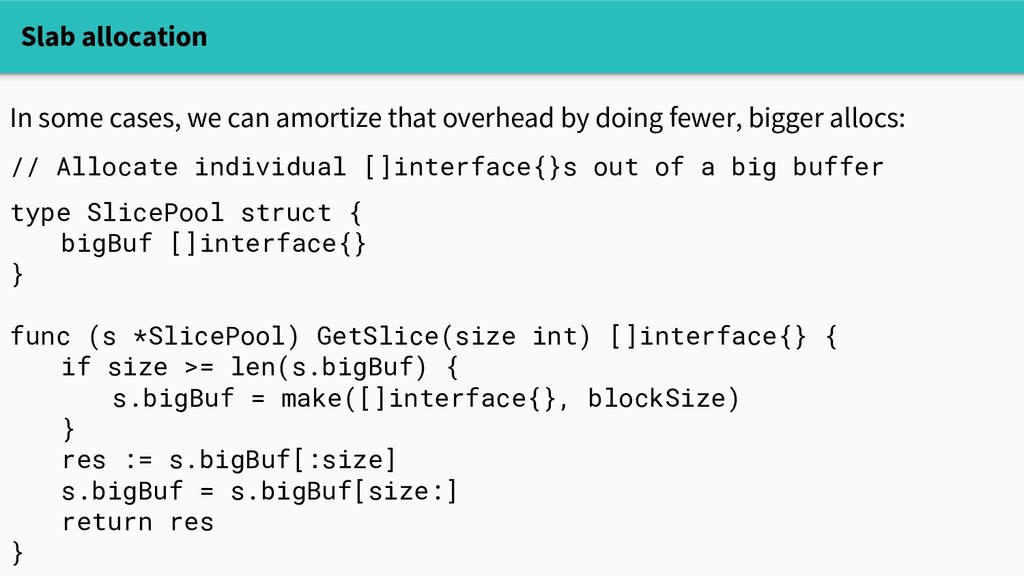
Slab allocation In some cases, we can amortize that overhead
by doing fewer, bigger allocs: // Allocate individual []interface{}s out of a big buffer type SlicePool struct { bigBuf []interface{} } func (s *SlicePool) GetSlice(size int) []interface{} { if size >= len(s.bigBuf) { s.bigBuf = make([]interface{}, blockSize) } res := s.bigBuf[:size] s.bigBuf = s.bigBuf[size:] return res } -
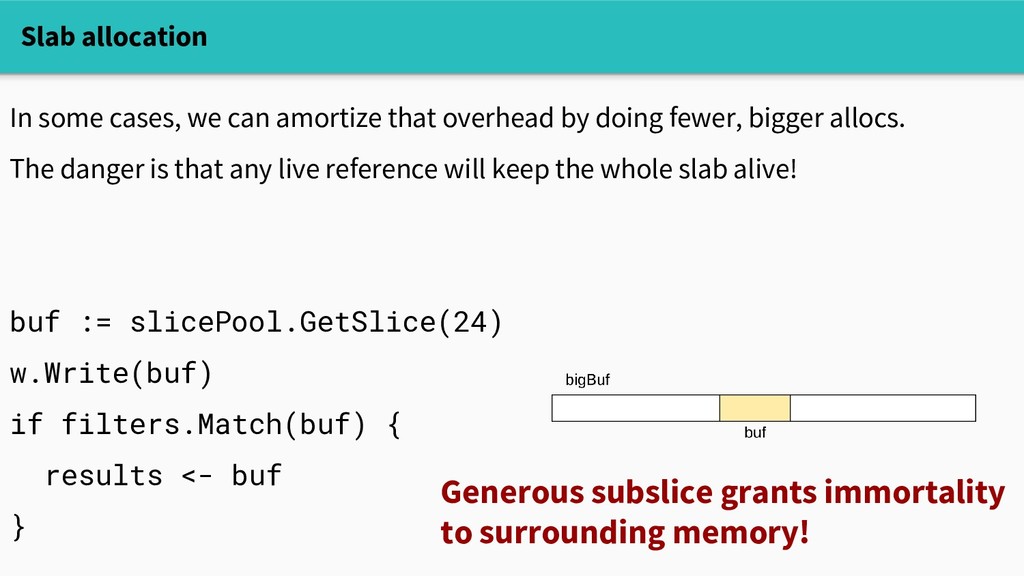
Slab allocation In some cases, we can amortize that overhead
by doing fewer, bigger allocs. The danger is that any live reference will keep the whole slab alive! buf := slicePool.GetSlice(24) w.Write(buf) if filters.Match(buf) { results <- buf } Generous subslice grants immortality to surrounding memory! -
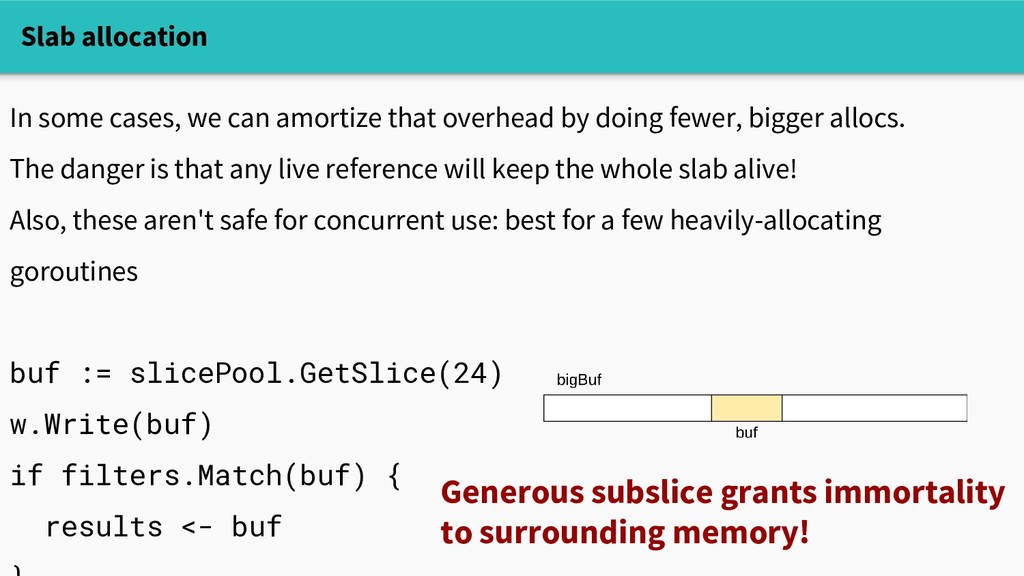
Slab allocation In some cases, we can amortize that overhead
by doing fewer, bigger allocs. The danger is that any live reference will keep the whole slab alive! Also, these aren't safe for concurrent use: best for a few heavily-allocating goroutines buf := slicePool.GetSlice(24) w.Write(buf) if filters.Match(buf) { results <- buf Generous subslice grants immortality to surrounding memory! -
Recycle allocations Optimization strategies: ✓ Avoid limit pointers, don't do
dumb stuff ✓ Amortize do fewer, larger allocations ? Reuse recycle allocated memory -
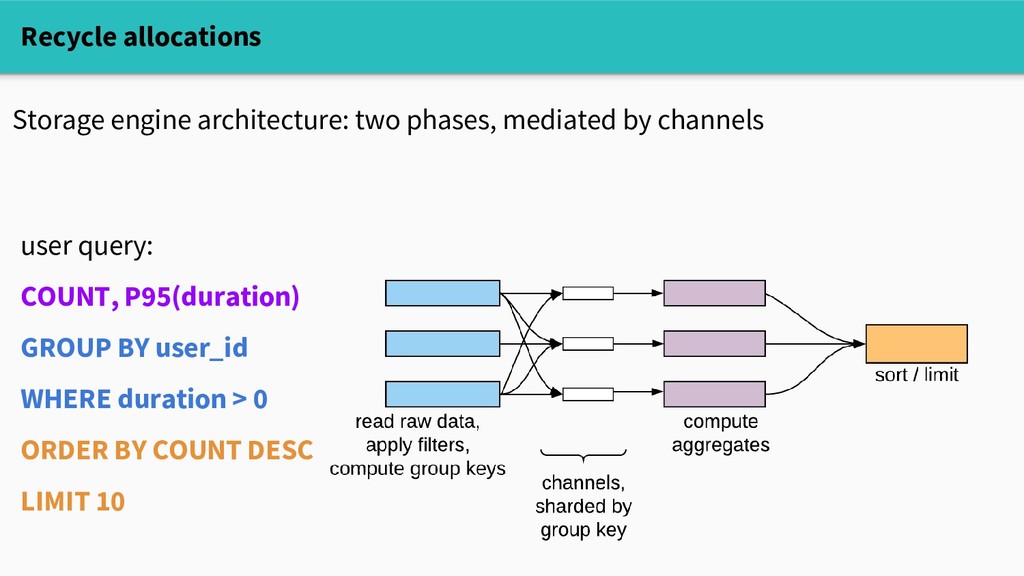
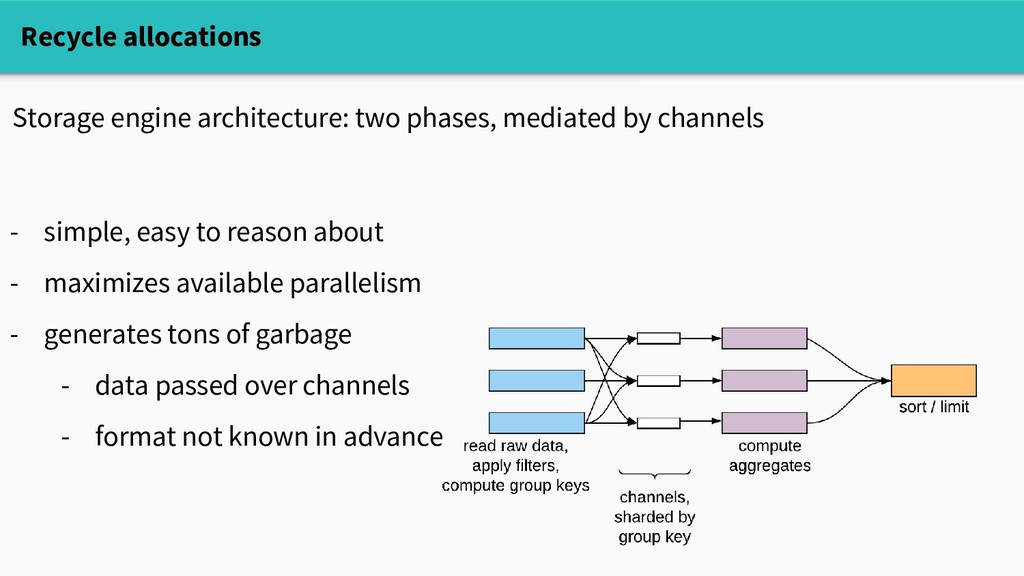
Storage engine architecture: two phases, mediated by channels Recycle allocations
user query: COUNT, P95(duration) GROUP BY user_id WHERE duration > 0 ORDER BY COUNT DESC LIMIT 10 -
Storage engine architecture: two phases, mediated by channels Recycle allocations
- simple, easy to reason about - maximizes available parallelism - generates tons of garbage - data passed over channels - format not known in advance -
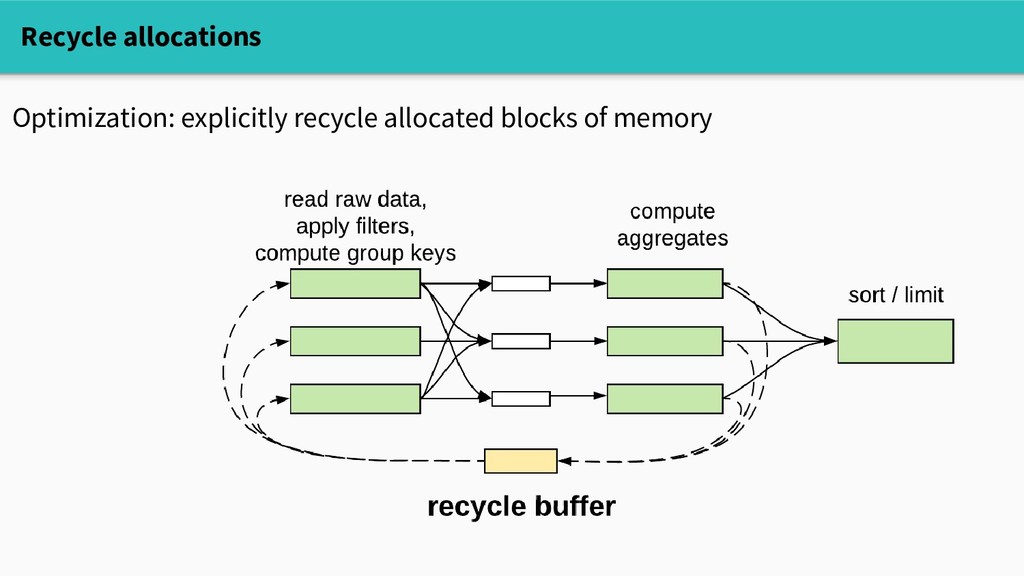
Optimization: explicitly recycle allocated blocks of memory Recycle allocations var
buf RowBuffer select { case buf = <-recycled: default: buf = NewRowBuffer() } -
A more sophisticated version: sync.Pool - maintains slices of recycled
objects, sharded by CPU (with runtime support) - allows lock-free get/put in the fast path - caveat: cleared on every GC Danger: - must be very careful to zero or overwrite recycled memory Recycle allocations -
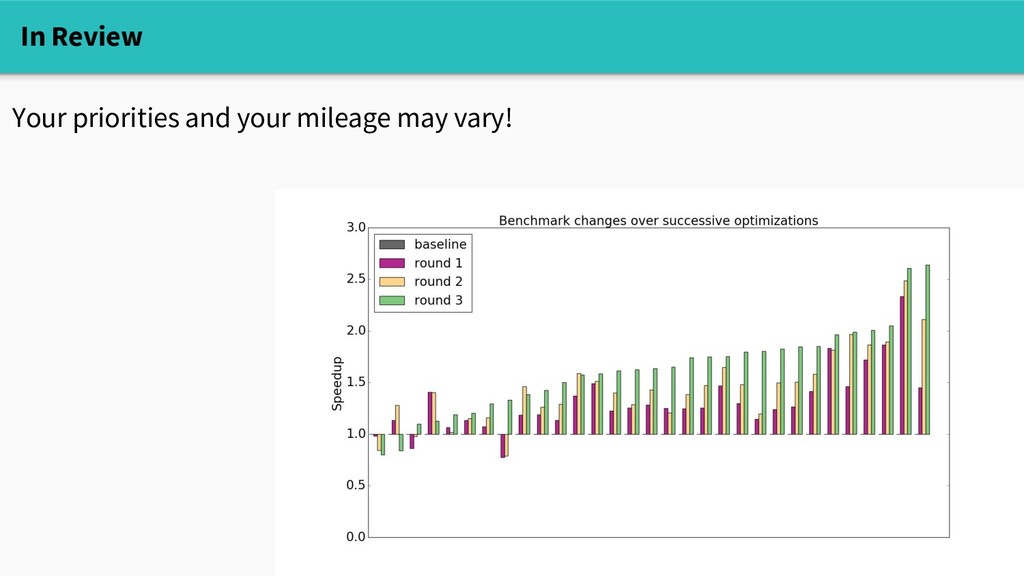
In Review - The allocator and garbage collector are pretty
ingenious! - Single allocations are fast but not free - The garbage collector can stop individual goroutines, even without STW - GC work depends on pointer density - Bring your toolbox: - benchmark with GC off - use CPU profiler to find hot allocations - use execution tracer to understand GC pattern - use escape analyzer to understand why allocations happen -
Thank you! Special credit to Ian Wilkes and many others
at Honeycomb: the true masterminds Suggested further reading: Allocation efficiency in high-performance Go services Achille Roussel / Rick Branson segment.com/blog/allocation-efficiency-in-high- performance-go-services/ Go 1.5 concurrent garbage collector pacing Austin Clements golang.org/s/go15gcpacing So You Wanna Go Fast Tyler Treat bravenewgeek.com/so-you-wanna-go-fast/ @_emfree_ -
- Optimizing for latency makes a lot of sense! Reliably
low-latency garbage collection is essential for many use cases: chat, streaming, lockservers, low-latency high-fanout services, etc. - For throughput-oriented use cases, Go's pauseless garbage collector may not be theoretically optimal. (But it might not be an existential burden either.) A Caveat
 emfree
 mkilby
 stephenakadiri
 bkeepers
 skoyamalab
 nwiizo
 jlugia
 erikaheidi
 garrettdimon
 jct
 axbom
 popppiees
 ammeep