Share
Embed
TMPA-2021: An approach to modules similarity definition based on the system logย analysis
An approach to modules similarity definition based on the system log analysis
TMPA is an annual International Conference on Software Testing, Machine Learning and Complex Process Analysis. The conference will focus on the application of modern methods of data science to the analysis of software quality.
To learn more about Exactpro, visit our website https://exactpro.com/
Follow us on
LinkedIn https://www.linkedin.com/company/exactpro-systems-llc
Twitter https://twitter.com/exactpro
Transcript
14 slides
-
1 25-27 NOVEMBER SOFTWARE TESTING, MACHINE LEARNING AND COMPLEX PROCESS
ANALYSIS An approach to modules similarity definition based on the system log analysis Ilya Samonenko, HSE Tamara Voznesenskaya, HSE Rostislav Yavorskiy, TPU -
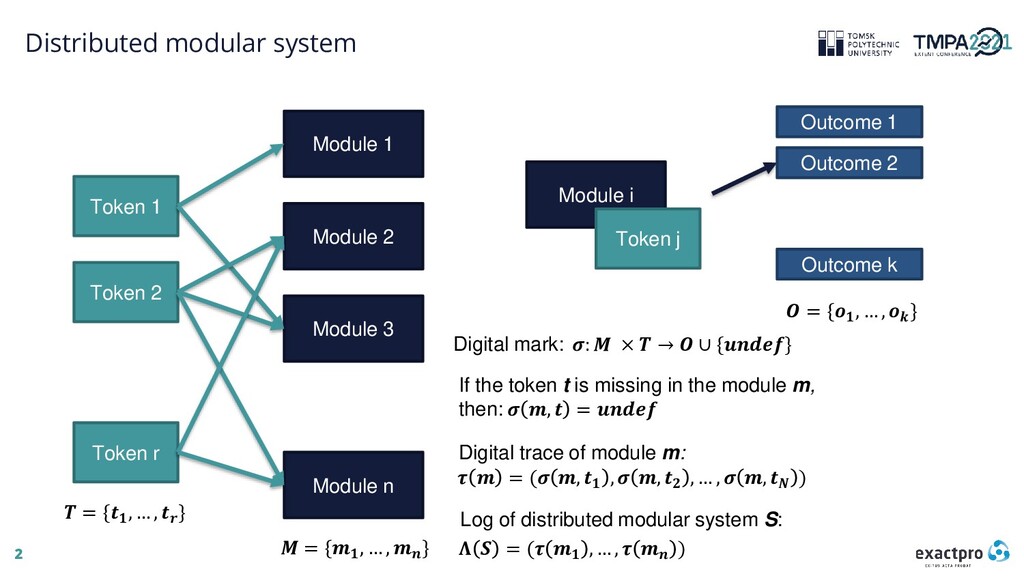
2 Distributed modular system Module 1 Module 2 Module 3
Module n Token 1 Token 2 Token r Module i Token j Outcome 1 Outcome 2 Outcome k ๐ป = {๐๐ , โฆ , ๐๐ } ๐ด = {๐๐ , โฆ , ๐๐ } ๐ถ = {๐๐ , โฆ , ๐๐ } ๐: ๐ด ร ๐ป โ ๐ถ โช {๐๐๐ ๐๐} Digital mark: ๐ ๐, ๐ = ๐๐๐ ๐๐ If the token t is missing in the module m, then: Digital trace of module m: ๐ ๐ = (๐ ๐, ๐๐ , ๐ ๐, ๐๐ , โฆ , ๐ ๐, ๐๐ต ) ๐ฒ ๐บ = (๐ ๐๐ , โฆ , ๐ ๐๐ ) Log of distributed modular system S: -
3 Comparable modules For similarity let Let s โ some
fixed natural number. Two modules m1 and m2 are comparable if there exist at least s tokens t, for which the both ฯ(m1 ,t) and ฯ(m2 ,t) are defined. Example: Let s = 3 m1 and m2 are comparable. Further we will consider only comparable pairs of modules. ๐ถ = {๐, ๐, ๐, ๐, โฆ , ๐} ๐ ๐๐ = (๐, ๐, ๐๐๐ ๐๐, ๐๐๐ ๐๐, ๐, ๐๐๐ ๐๐, ๐, ๐๐๐ ๐๐, ๐) ๐ ๐๐ = (๐, ๐๐๐ ๐๐, ๐, ๐๐๐ ๐๐, ๐, ๐๐๐ ๐๐, ๐, ๐๐๐ ๐๐, ๐๐๐ ๐๐) -
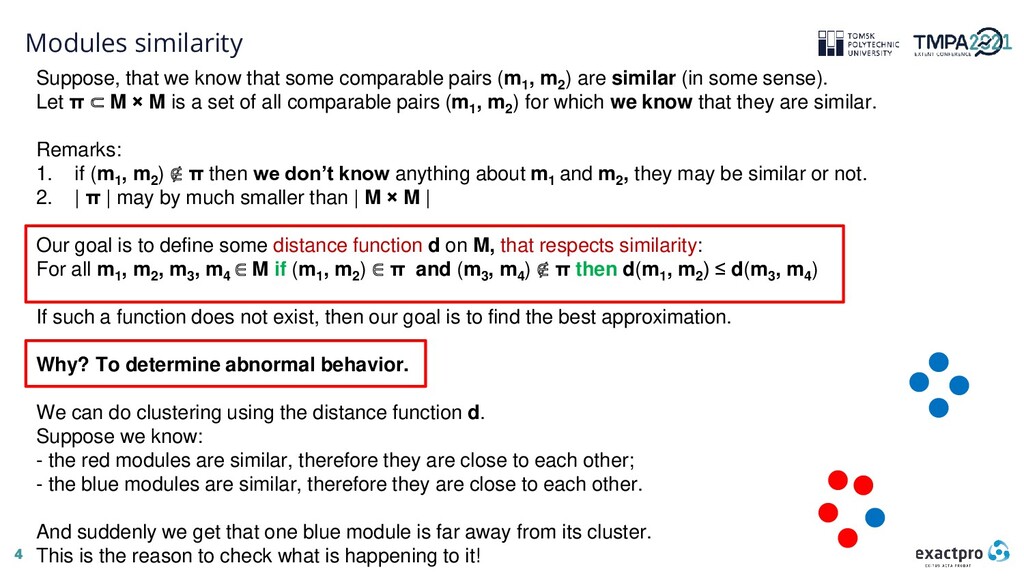
4 Modules similarity Suppose, that we know that some comparable
pairs (m1 , m2 ) are similar (in some sense). Let ฯ โ M ร M is a set of all comparable pairs (m1 , m2 ) for which we know that they are similar. Remarks: 1. if (m1 , m2 ) โ ฯ then we donโt know anything about m1 and m2 , they may be similar or not. 2. | ฯ | may by much smaller than | M ร M | Our goal is to define some distance function d on M, that respects similarity: For all m1 , m2 , m3 , m4 โ M if (m1 , m2 ) โ ฯ and (m3 , m4 ) โ ฯ then d(m1 , m2 ) โค d(m3 , m4 ) If such a function does not exist, then our goal is to find the best approximation. Why? To determine abnormal behavior. We can do clustering using the distance function d. Suppose we know: - the red modules are similar, therefore they are close to each other; - the blue modules are similar, therefore they are close to each other. And suddenly we get that one blue module is far away from its cluster. This is the reason to check what is happening to it! -
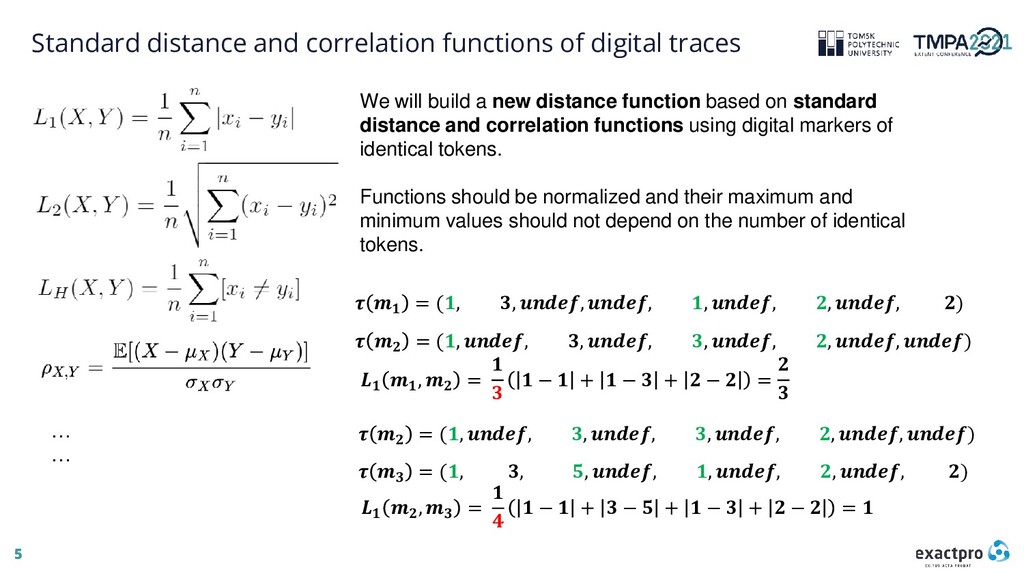
5 Standard distance and correlation functions of digital traces โฆ
โฆ ๐ ๐๐ = (๐, ๐, ๐๐๐ ๐๐, ๐๐๐ ๐๐, ๐, ๐๐๐ ๐๐, ๐, ๐๐๐ ๐๐, ๐) ๐ ๐๐ = (๐, ๐๐๐ ๐๐, ๐, ๐๐๐ ๐๐, ๐, ๐๐๐ ๐๐, ๐, ๐๐๐ ๐๐, ๐๐๐ ๐๐) ๐ณ๐ ๐๐ , ๐๐ = ๐ ๐ ๐ โ ๐ + ๐ โ ๐ + ๐ โ ๐ = ๐ ๐ We will build a new distance function based on standard distance and correlation functions using digital markers of identical tokens. Functions should be normalized and their maximum and minimum values should not depend on the number of identical tokens. ๐ ๐๐ = (๐, ๐, ๐, ๐๐๐ ๐๐, ๐, ๐๐๐ ๐๐, ๐, ๐๐๐ ๐๐, ๐) ๐ ๐๐ = (๐, ๐๐๐ ๐๐, ๐, ๐๐๐ ๐๐, ๐, ๐๐๐ ๐๐, ๐, ๐๐๐ ๐๐, ๐๐๐ ๐๐) ๐ณ๐ ๐๐ , ๐๐ = ๐ ๐ ๐ โ ๐ + ๐ โ ๐ + ๐ โ ๐ + ๐ โ ๐ = ๐ -
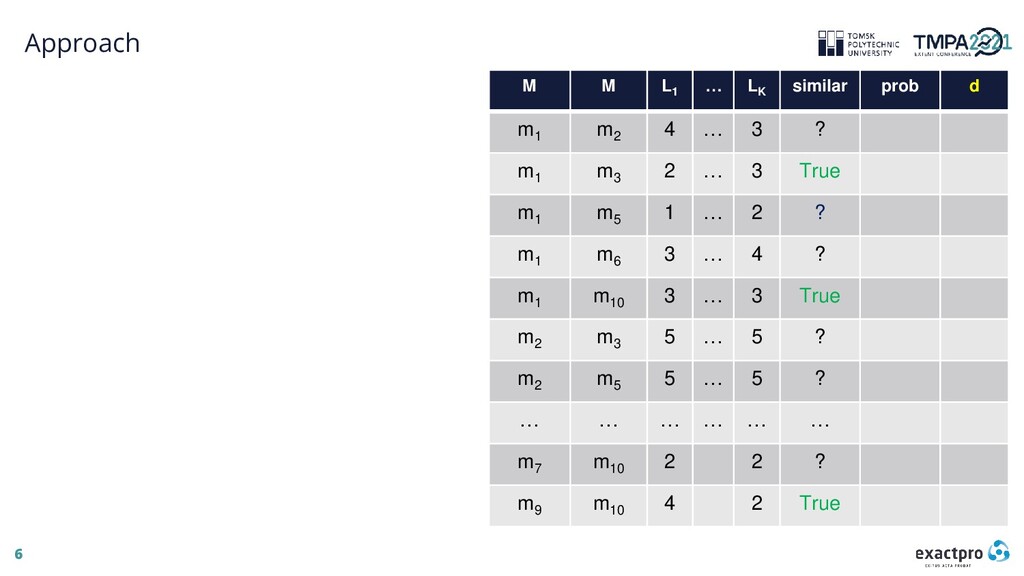
6 Approach M M L1 โฆ LK similar prob d
m1 m2 4 โฆ 3 ? m1 m3 2 โฆ 3 True m1 m5 1 โฆ 2 ? m1 m6 3 โฆ 4 ? m1 m10 3 โฆ 3 True m2 m3 5 โฆ 5 ? m2 m5 5 โฆ 5 ? โฆ โฆ โฆ โฆ โฆ โฆ m7 m10 2 2 ? m9 m10 4 2 True -
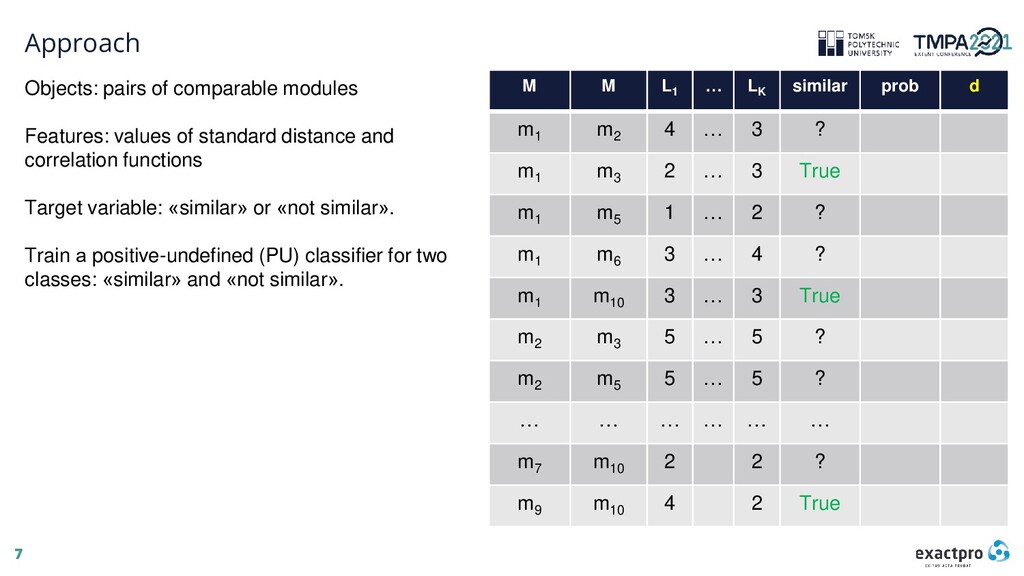
7 Approach Objects: pairs of comparable modules Features: values of
standard distance and correlation functions Target variable: ยซsimilarยป or ยซnot similarยป. Train ะฐ positive-undefined (PU) classifier for two classes: ยซsimilarยป and ยซnot similarยป. M M L1 โฆ LK similar prob d m1 m2 4 โฆ 3 ? m1 m3 2 โฆ 3 True m1 m5 1 โฆ 2 ? m1 m6 3 โฆ 4 ? m1 m10 3 โฆ 3 True m2 m3 5 โฆ 5 ? m2 m5 5 โฆ 5 ? โฆ โฆ โฆ โฆ โฆ โฆ m7 m10 2 2 ? m9 m10 4 2 True -
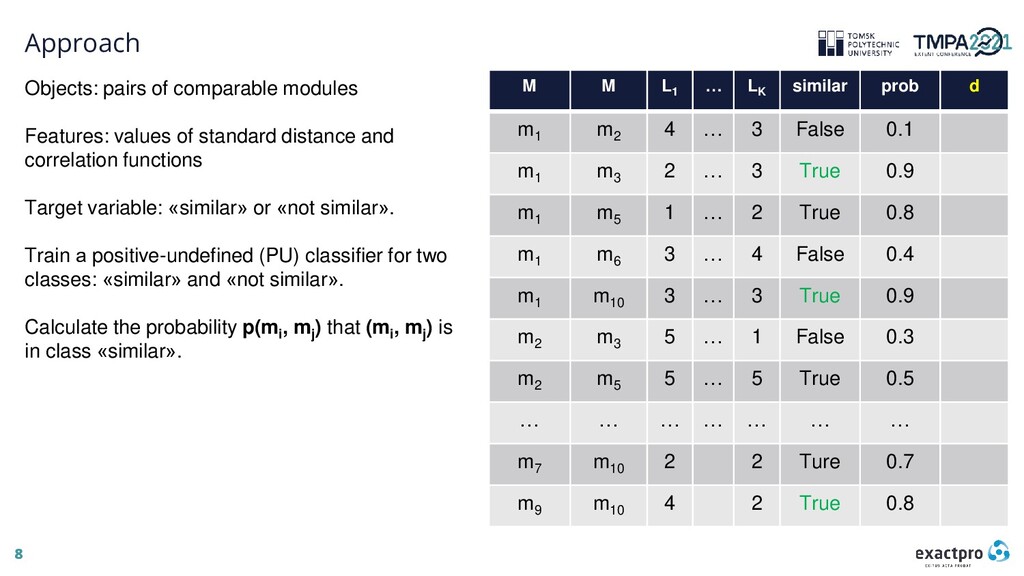
8 Approach M M L1 โฆ LK similar prob d
m1 m2 4 โฆ 3 False 0.1 m1 m3 2 โฆ 3 True 0.9 m1 m5 1 โฆ 2 True 0.8 m1 m6 3 โฆ 4 False 0.4 m1 m10 3 โฆ 3 True 0.9 m2 m3 5 โฆ 1 False 0.3 m2 m5 5 โฆ 5 True 0.5 โฆ โฆ โฆ โฆ โฆ โฆ โฆ m7 m10 2 2 Ture 0.7 m9 m10 4 2 True 0.8 Objects: pairs of comparable modules Features: values of standard distance and correlation functions Target variable: ยซsimilarยป or ยซnot similarยป. Train ะฐ positive-undefined (PU) classifier for two classes: ยซsimilarยป and ยซnot similarยป. Calculate the probability p(mi , mj ) that (mi , mj ) is in class ยซsimilarยป. -
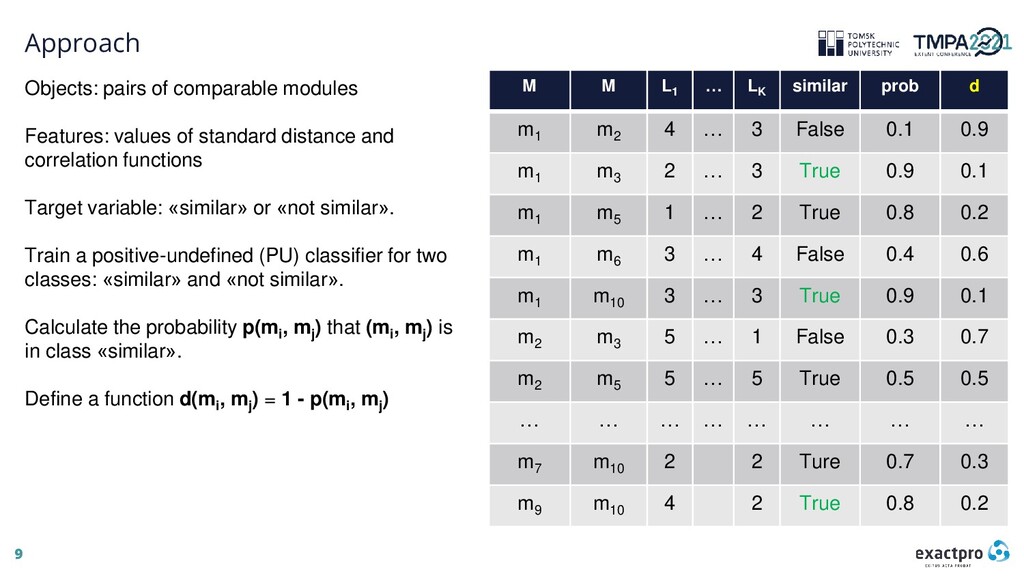
9 Approach M M L1 โฆ LK similar prob d
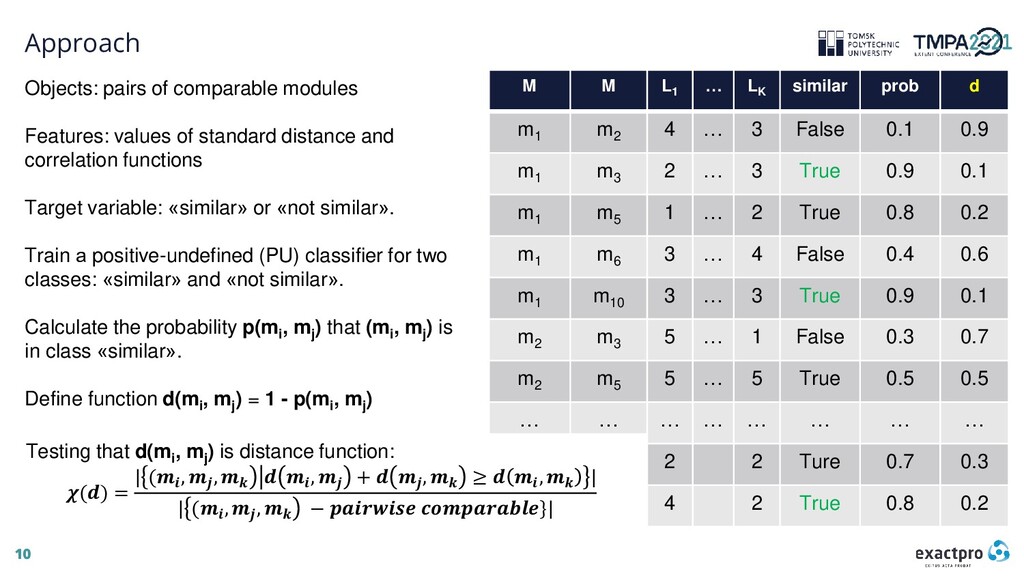
m1 m2 4 โฆ 3 False 0.1 0.9 m1 m3 2 โฆ 3 True 0.9 0.1 m1 m5 1 โฆ 2 True 0.8 0.2 m1 m6 3 โฆ 4 False 0.4 0.6 m1 m10 3 โฆ 3 True 0.9 0.1 m2 m3 5 โฆ 1 False 0.3 0.7 m2 m5 5 โฆ 5 True 0.5 0.5 โฆ โฆ โฆ โฆ โฆ โฆ โฆ โฆ m7 m10 2 2 Ture 0.7 0.3 m9 m10 4 2 True 0.8 0.2 Objects: pairs of comparable modules Features: values of standard distance and correlation functions Target variable: ยซsimilarยป or ยซnot similarยป. Train a positive-undefined (PU) classifier for two classes: ยซsimilarยป and ยซnot similarยป. Calculate the probability p(mi , mj ) that (mi , mj ) is in class ยซsimilarยป. Define a function d(mi , mj ) = 1 - p(mi , mj ) -
10 Approach M M L1 โฆ LK similar prob d
m1 m2 4 โฆ 3 False 0.1 0.9 m1 m3 2 โฆ 3 True 0.9 0.1 m1 m5 1 โฆ 2 True 0.8 0.2 m1 m6 3 โฆ 4 False 0.4 0.6 m1 m10 3 โฆ 3 True 0.9 0.1 m2 m3 5 โฆ 1 False 0.3 0.7 m2 m5 5 โฆ 5 True 0.5 0.5 โฆ โฆ โฆ โฆ โฆ โฆ โฆ โฆ m7 m10 2 2 Ture 0.7 0.3 m9 m10 4 2 True 0.8 0.2 Objects: pairs of comparable modules Features: values of standard distance and correlation functions Target variable: ยซsimilarยป or ยซnot similarยป. Train ะฐ positive-undefined (PU) classifier for two classes: ยซsimilarยป and ยซnot similarยป. Calculate the probability p(mi , mj ) that (mi , mj ) is in class ยซsimilarยป. Define function d(mi , mj ) = 1 - p(mi , mj ) Testing that d(mi , mj ) is distance function: ๐(๐ ) = | (๐๐ , ๐๐ , ๐๐ ๐ ๐๐ , ๐๐ + ๐ ๐๐ , ๐๐ โฅ ๐ ๐๐ , ๐๐ | | (๐๐ , ๐๐ , ๐๐ โ ๐๐๐๐๐๐๐๐ ๐๐๐๐๐๐๐๐๐๐}| -
11 Application Modules M: set of all disciplines of all
educational programs of the HSE in the period from 2017 to 2020. |M| = 54652 Tokens T: set of all students. Outcomes O: set of grades = {0,1, 2, 3, 4, 5, 6, 7, 8, 9, 10}. Digital mark: ๐(๐, ๐) โ the grade of student t for discipline m. Over 2,5 million grades. Digital trace: ๐(๐) โ all grades for discipline m. Disciplines m1 and m2 are comparable if at least 10 of the same students passed exams in this disciplines. Over 950 000 pairs of comparable disciplines. -
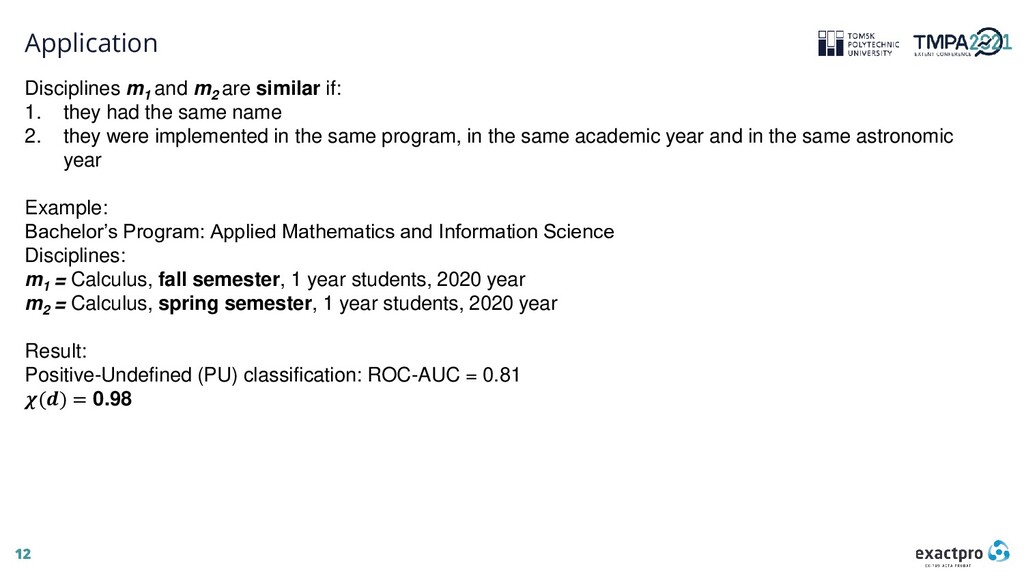
12 Application Disciplines m1 and m2 are similar if: 1.
they had the same name 2. they were implemented in the same program, in the same academic year and in the same astronomic year Example: Bachelorโs Program: Applied Mathematics and Information Science Disciplines: m1 = Calculus, fall semester, 1 year students, 2020 year m2 = Calculus, spring semester, 1 year students, 2020 year Result: Positive-Undefined (PU) classification: ROC-AUC = 0.81 ๐(๐ ) = 0.98 -
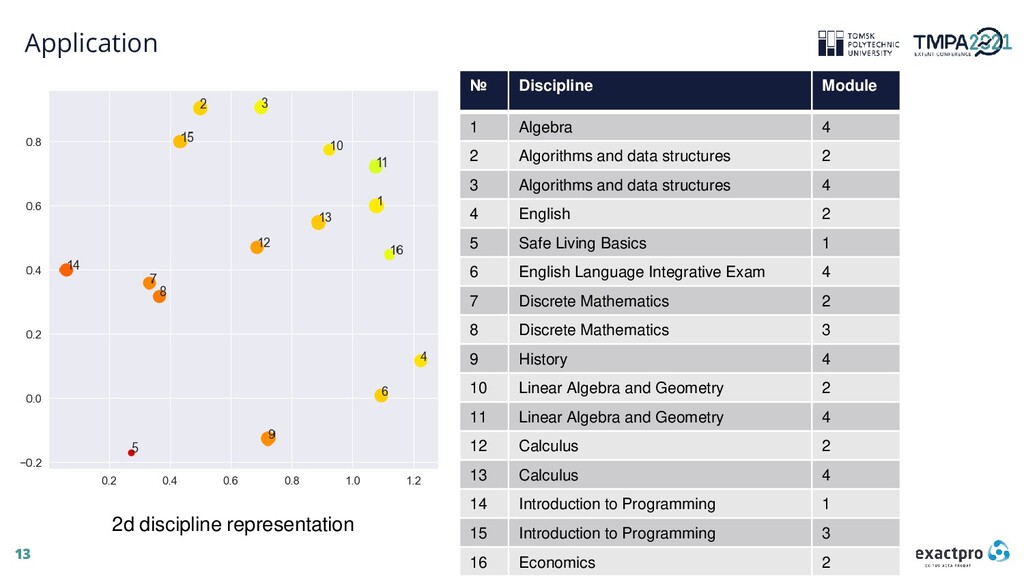
13 Application โ Discipline Module 1 Algebra 4 2 Algorithms
and data structures 2 3 Algorithms and data structures 4 4 English 2 5 Safe Living Basics 1 6 English Language Integrative Exam 4 7 Discrete Mathematics 2 8 Discrete Mathematics 3 9 History 4 10 Linear Algebra and Geometry 2 11 Linear Algebra and Geometry 4 12 Calculus 2 13 Calculus 4 14 Introduction to Programming 1 15 Introduction to Programming 3 16 Economics 2 2d discipline representation