Finding the right NoSQL DB for the job - The pa...

Share
Embed
Finding the right NoSQL DB for the job - The path to a non-RDBMS solution at Traackr
A walkthrough of Traackr's experience in choosing a NoSQL solution and how we ended up up switching from HBase to MongoDB. This deck goes through some in depth technical aspects, like schema design and our use of secondary indexes.

George P. Stathis
April 23, 2012
Transcript
137 slides
-
Finding the right NoSQL DB for the job
The path to a non-‐RDBMS solu>on at -
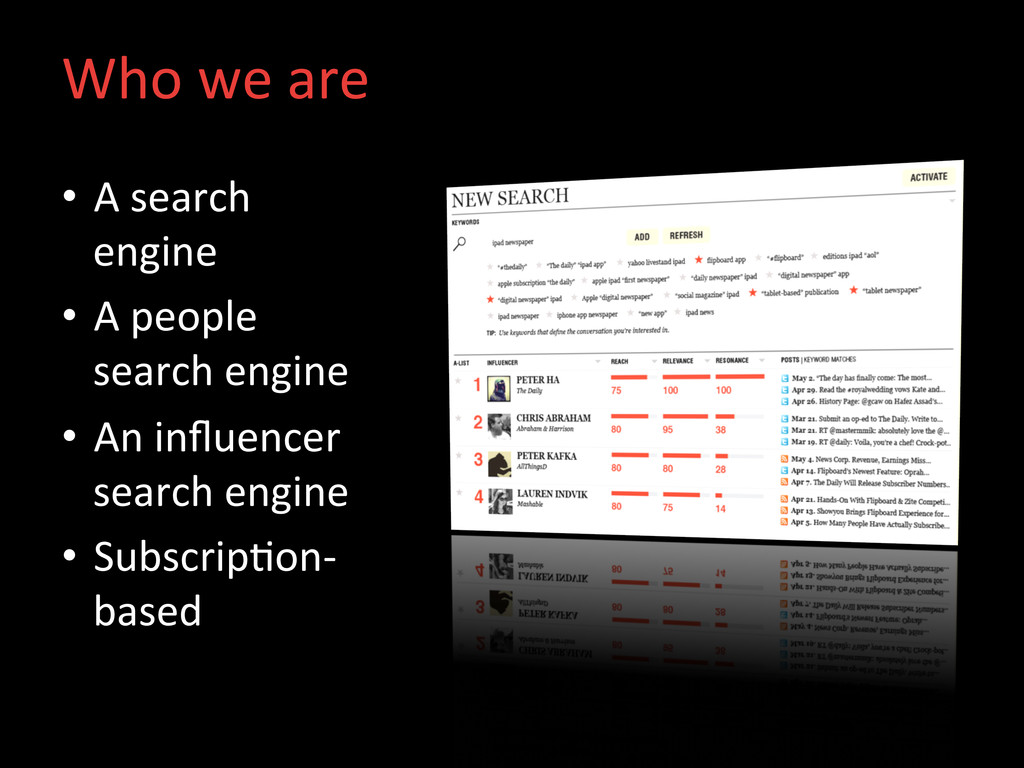
Who we are • A search engine
• A people search engine • An influencer search engine • Subscrip>on-‐ based -
George Stathis VP Engineering 14+ years of experience
building full-‐stack web soKware systems with a past focus on e-‐commerce and publishing. Currently responsible for building engineering capability to enable Traackr's growth goals. -
What’s this talk about? • Why we picked a
NoSQL database • How we picked a NoSQL database • My NoSQL does not do the job! What now?! • Nirvana = the right tool for the job -
There are some misconcep>ons around NoSQL only being appropriate
when one needs to achieve “Web Scale” -
• In terms of users/traffic? Do we fit the
“Web scale” profile? -
• In terms of users/traffic? • In terms of
the amount of data? Do we fit the “Web scale” profile? -
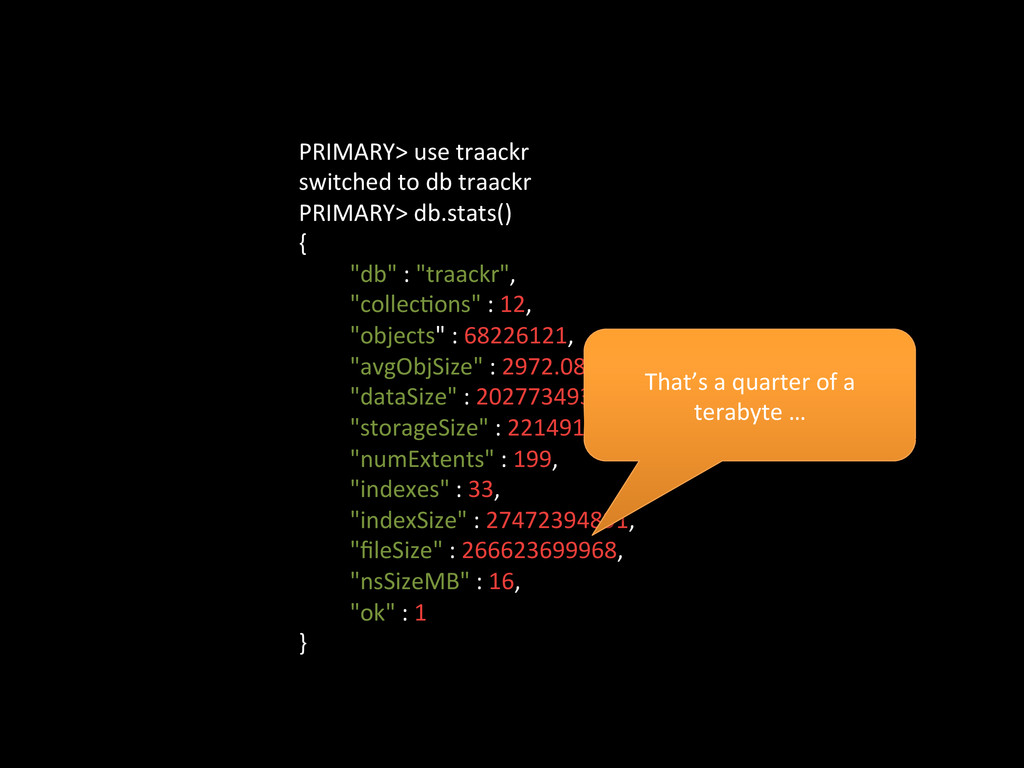
PRIMARY> use traackr switched to db traackr PRIMARY>
db.stats() { "db" : "traackr", "collec>ons" : 12, "objects" : 68226121, "avgObjSize" : 2972.0800625760330, "dataSize" : 202773493971, "storageSize" : 221491429671, "numExtents" : 199, "indexes" : 33, "indexSize" : 27472394891, "fileSize" : 266623699968, "nsSizeMB" : 16, "ok" : 1 } That’s a quarter of a terabyte … -
Wait! What? My Synology NAS at home can
hold 2TB! -
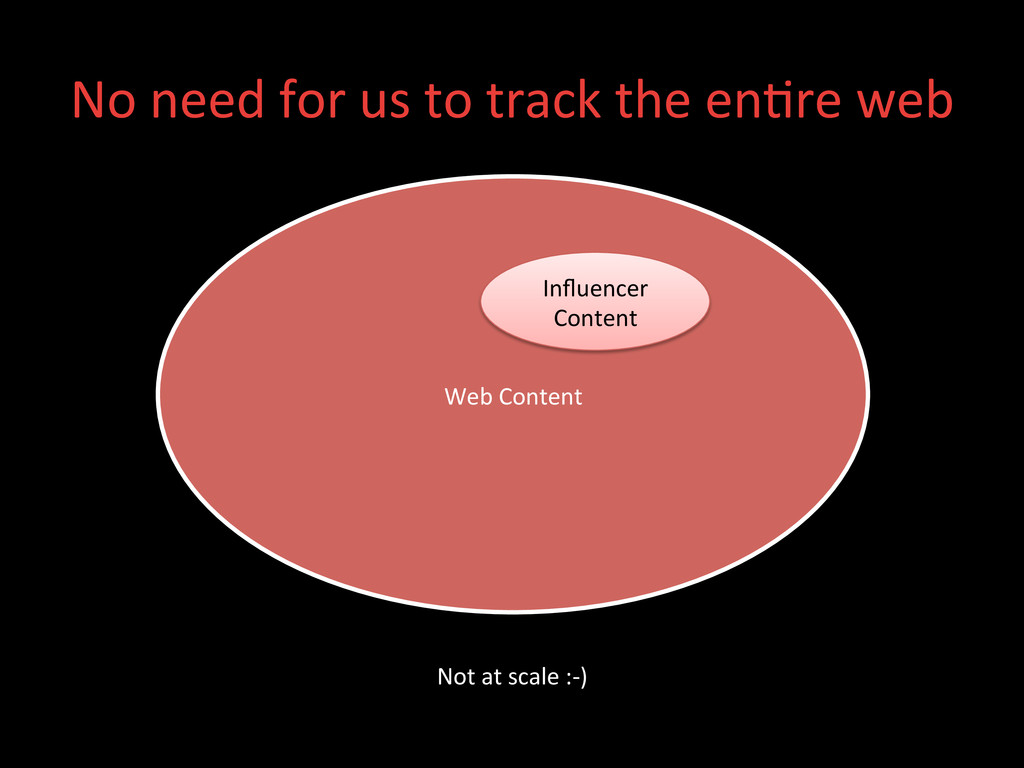
No need for us to track the en>re web
Web Content Influencer Content Not at scale :-‐) -
• In terms of users/traffic? • In terms of
the amount of data? Do we fit the “Web scale” profile? -
Alternate view of “Web Scale” Web data is:
Heterogeneous Unstructured (text) -
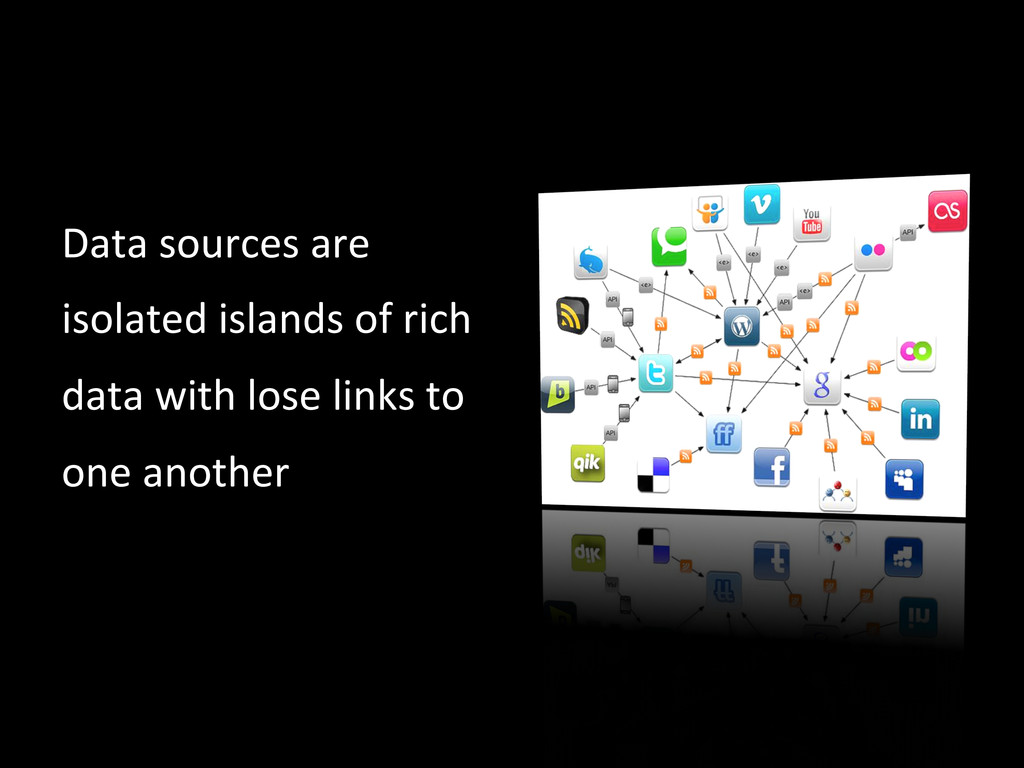
Data sources are isolated islands of rich data
with lose links to one another -
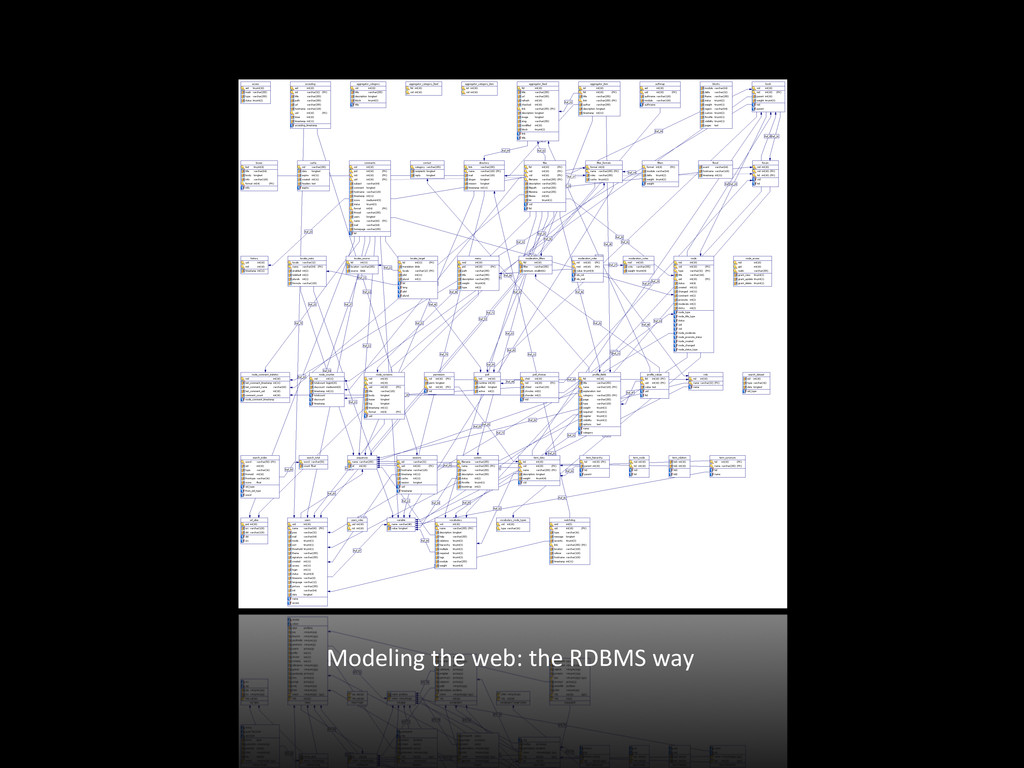
How do we build a database that models all
possible en>>es found on the web? -
{ "realName": "David Chancogne",
">tle": "CTO", "descrip>on": "Web. Geek.\r\nTraackr: hXp://traackr.com\r\nPropz: hXp://propz.me", "primaryAffilia>on": "Traackr", "email": "[email protected]", "loca>on": "Cambridge, MA, United States", "siteReferences": [ { "siteUrl": "hXp://twiXer.com/dchancogne", "metrics": [ { "value": 216, "name": "twiXer_followers_count" }, { "value": 2107, "name": "twiXer_statuses_count" } ] }, { "siteUrl": "hXp://traackr.com/blog/author/david", "metrics": [ { "value": 21, "name": "google_inbound_links" } ] } ] } Influencer data as JSON -
“In the old world of data analysis you knew
exactly which ques>ons you wanted to ask, which drove a very predictable collec>on and storage model. In the new world of data analysis your ques>ons are going to evolve and change over >me and as such you need to be able to collect, store and analyze data without being constrained by resources.” — Werner Vogels, CTO/VP Amazon.com -
• In terms of users/traffic? • In terms of
the amount of data? Do we fit the “Web scale” profile? -
• In terms of users/traffic? • In terms of
the amount of data? • In terms of the variety of the data Do we fit the “Web scale” profile? ✓ -
Traackr’s Datastore Requirements • Schema flexibility • Good
at storing lots of variable length text • Batch processing op>ons ✓ -
Requirement: text storage Variable text length: < big
variance < 140 character tweets mul>-‐page blog posts -
Requirement: text storage RDBMS’ answer to variable text length:
Plan ahead for largest value CLOB/BLOB -
Requirement: text storage Issues with CLOB/BLOG for us:
No clue what largest value is CLOB/BLOB for tweets = wasted space -
Requirement: text storage NoSQL solu>ons are great for text:
No length requirements (automated chunking) Limited space overhead -
Traackr’s Datastore Requirements • Schema flexibility • Good
at storing lots of variable length text • Batch processing op>ons ✓ ✓ -
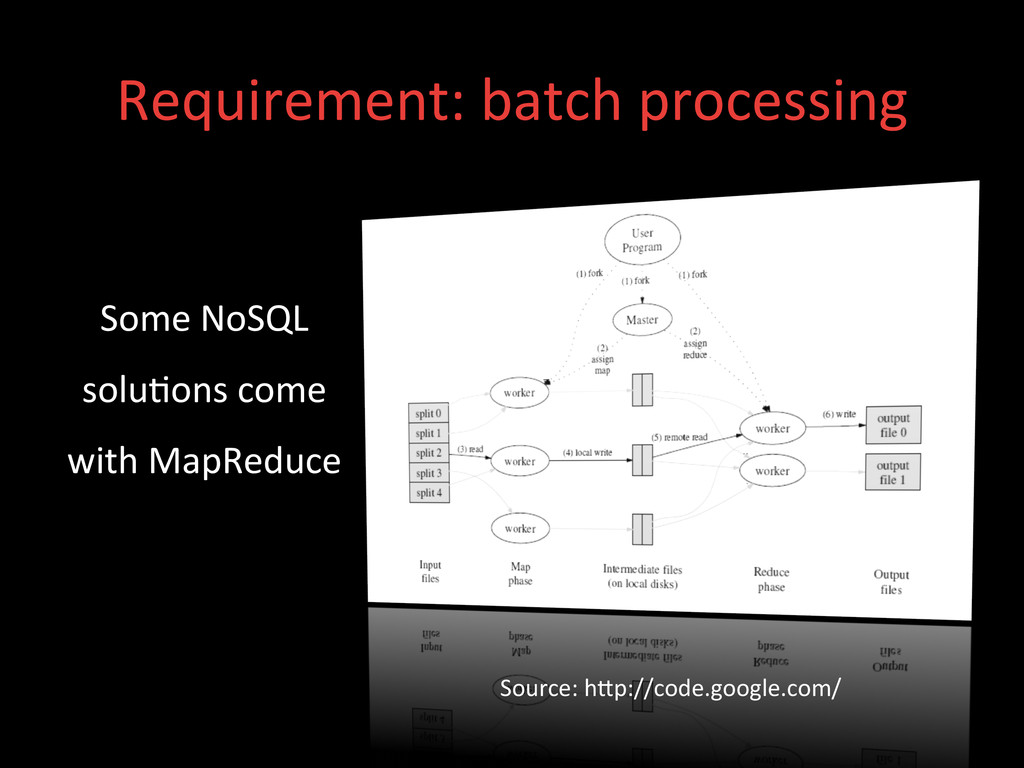
Requirement: batch processing Some NoSQL solu>ons come
with MapReduce Source: hXp://code.google.com/ -
Requirement: batch processing MapReduce + RDBMS: Possible but
proprietary solu>ons Usually involves expor>ng data from RDBMS into a NoSQL system anyway. Defeats data locality benefit of MR -
Traackr’s Datastore Requirements • Schema flexibility • Good
at storing lots of variable length text • Batch processing op>ons ✓ ✓ A NoSQL op>on is the right fit ✓ -
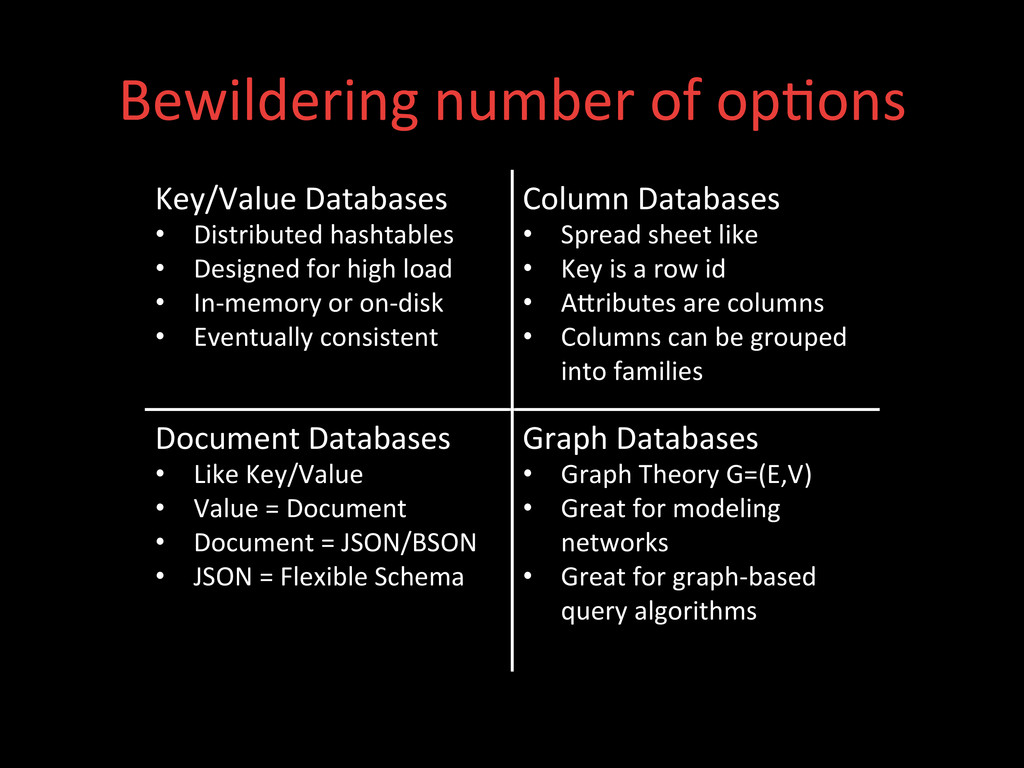
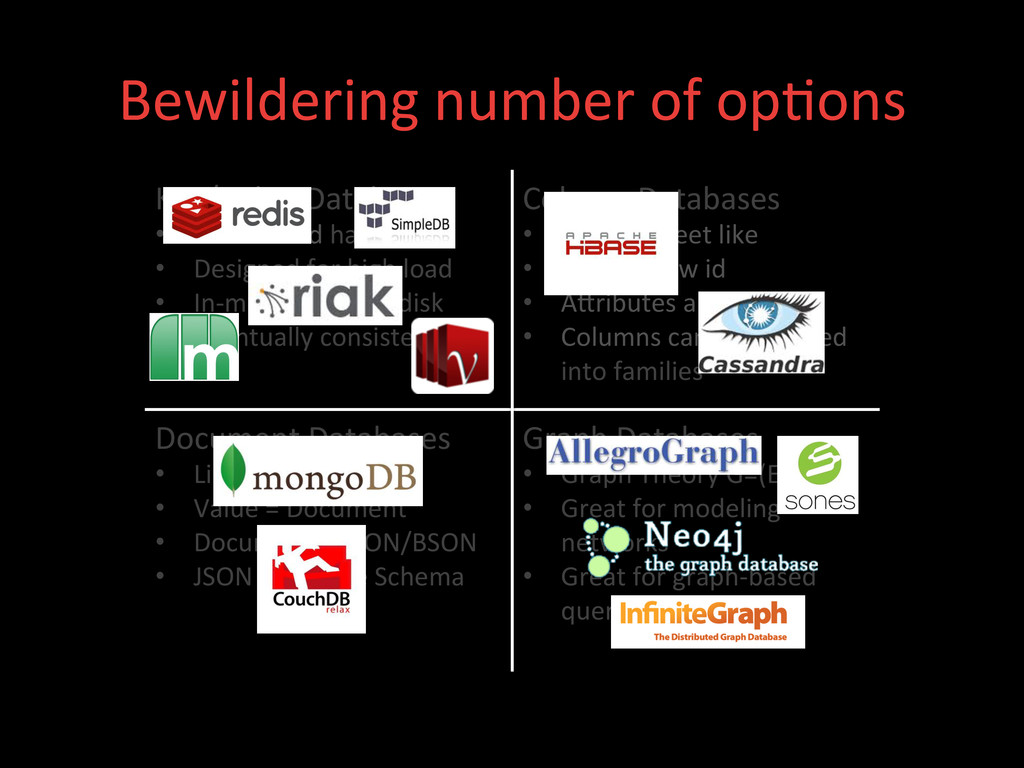
Bewildering number of op>ons Key/Value Databases • Distributed
hashtables • Designed for high load • In-‐memory or on-‐disk • Eventually consistent Column Databases • Spread sheet like • Key is a row id • AXributes are columns • Columns can be grouped into families Document Databases • Like Key/Value • Value = Document • Document = JSON/BSON • JSON = Flexible Schema Graph Databases • Graph Theory G=(E,V) • Great for modeling networks • Great for graph-‐based query algorithms -
Bewildering number of op>ons Key/Value Databases • Distributed
hashtables • Designed for high load • In-‐memory or on-‐disk • Eventually consistent Column Databases • Spread sheet like • Key is a row id • AXributes are columns • Columns can be grouped into families Document Databases • Like Key/Value • Value = Document • Document = JSON/BSON • JSON = Flexible Schema Graph Databases • Graph Theory G=(E,V) • Great for modeling networks • Great for graph-‐based query algorithms -
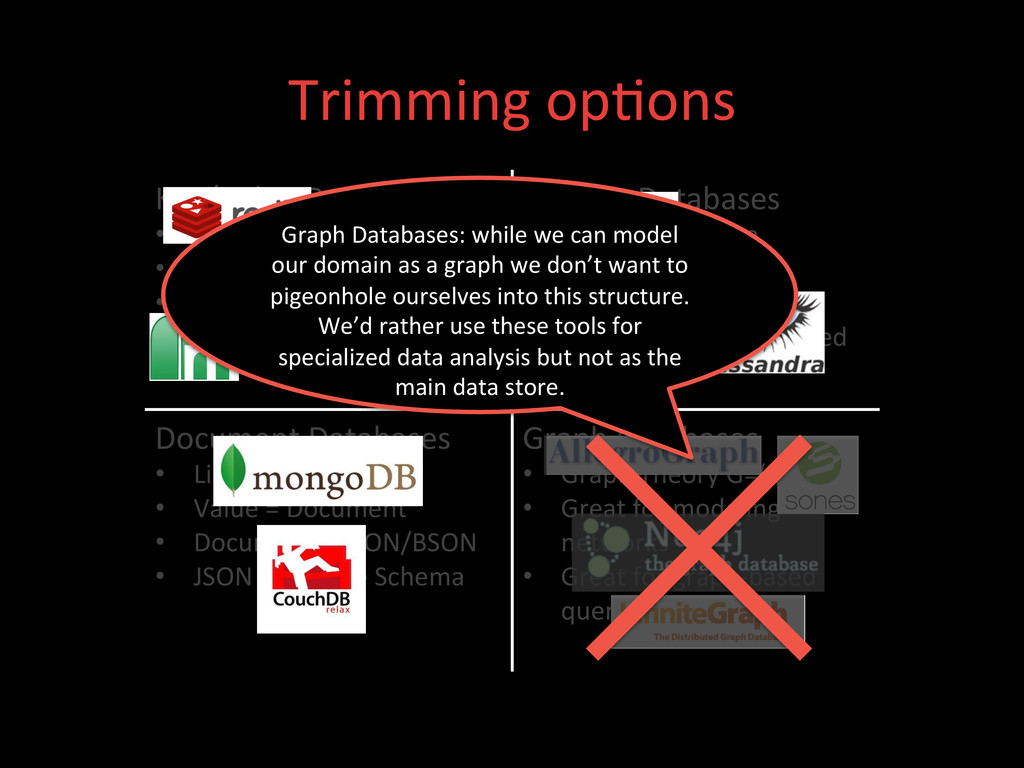
Trimming op>ons Key/Value Databases • Distributed hashtables
• Designed for high load • In-‐memory or on-‐disk • Eventually consistent Column Databases • Spread sheet like • Key is a row id • AXributes are columns • Columns can be grouped into families Document Databases • Like Key/Value • Value = Document • Document = JSON/BSON • JSON = Flexible Schema Graph Databases • Graph Theory G=(E,V) • Great for modeling networks • Great for graph-‐based query algorithms Graph Databases: while we can model our domain as a graph we don’t want to pigeonhole ourselves into this structure. We’d rather use these tools for specialized data analysis but not as the main data store. -
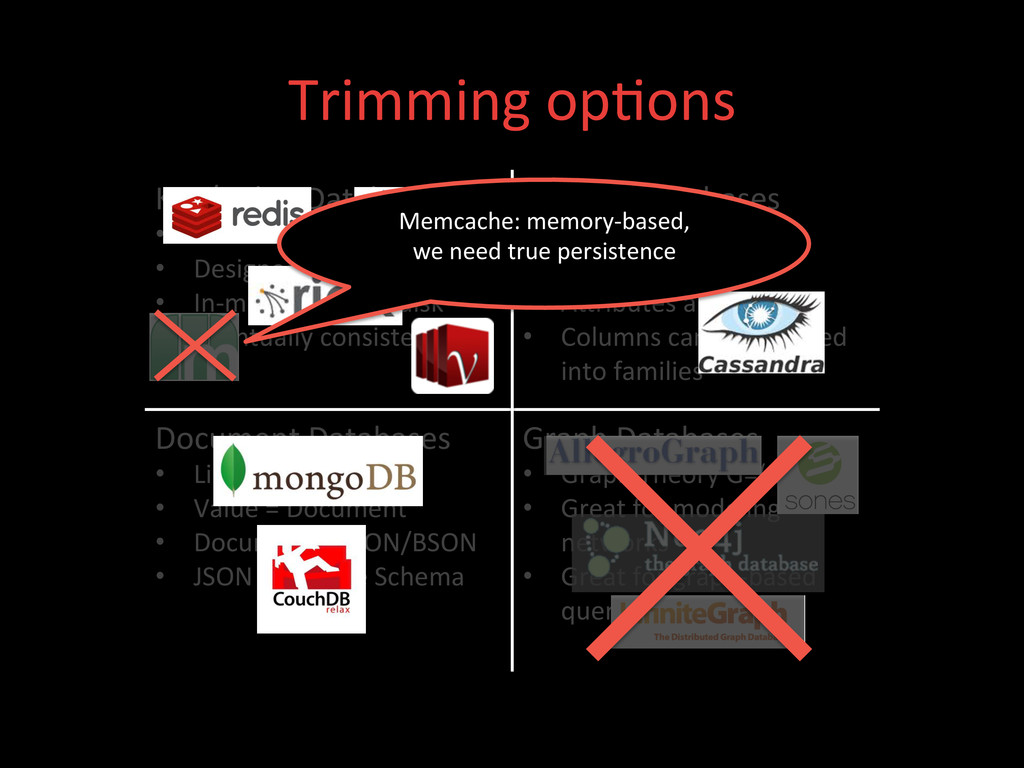
Trimming op>ons Key/Value Databases • Distributed hashtables
• Designed for high load • In-‐memory or on-‐disk • Eventually consistent Column Databases • Spread sheet like • Key is a row id • AXributes are columns • Columns can be grouped into families Document Databases • Like Key/Value • Value = Document • Document = JSON/BSON • JSON = Flexible Schema Graph Databases • Graph Theory G=(E,V) • Great for modeling networks • Great for graph-‐based query algorithms Memcache: memory-‐based, we need true persistence -
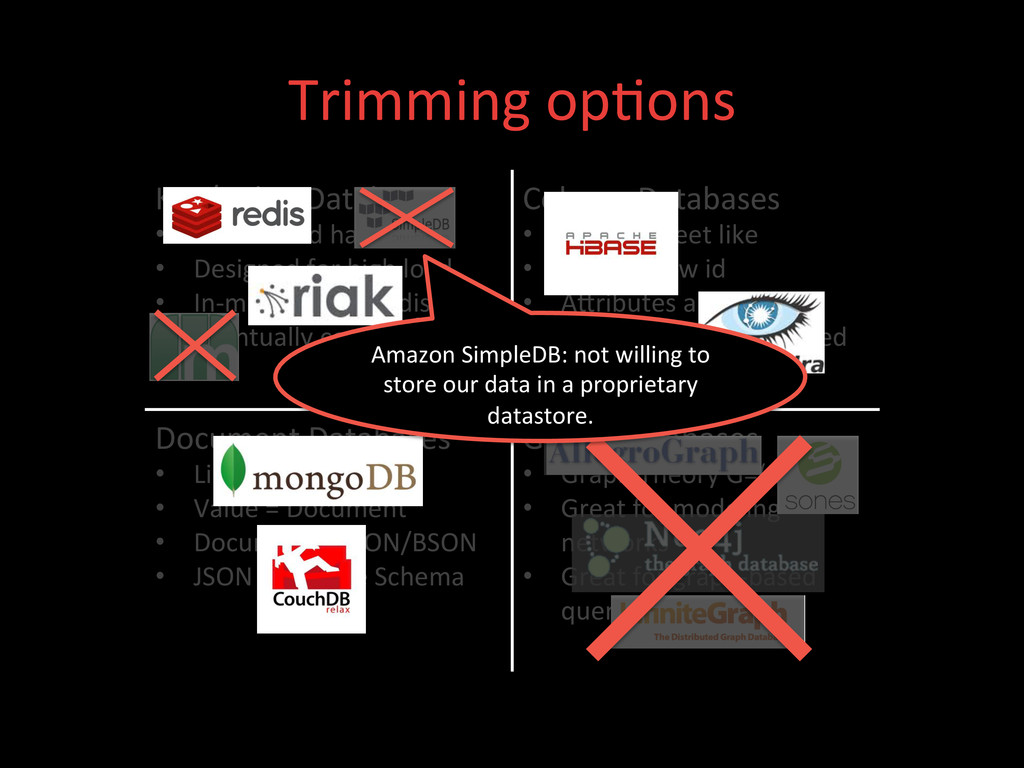
Trimming op>ons Key/Value Databases • Distributed hashtables
• Designed for high load • In-‐memory or on-‐disk • Eventually consistent Column Databases • Spread sheet like • Key is a row id • AXributes are columns • Columns can be grouped into families Document Databases • Like Key/Value • Value = Document • Document = JSON/BSON • JSON = Flexible Schema Graph Databases • Graph Theory G=(E,V) • Great for modeling networks • Great for graph-‐based query algorithms Amazon SimpleDB: not willing to store our data in a proprietary datastore. -
Trimming op>ons Key/Value Databases • Distributed hashtables
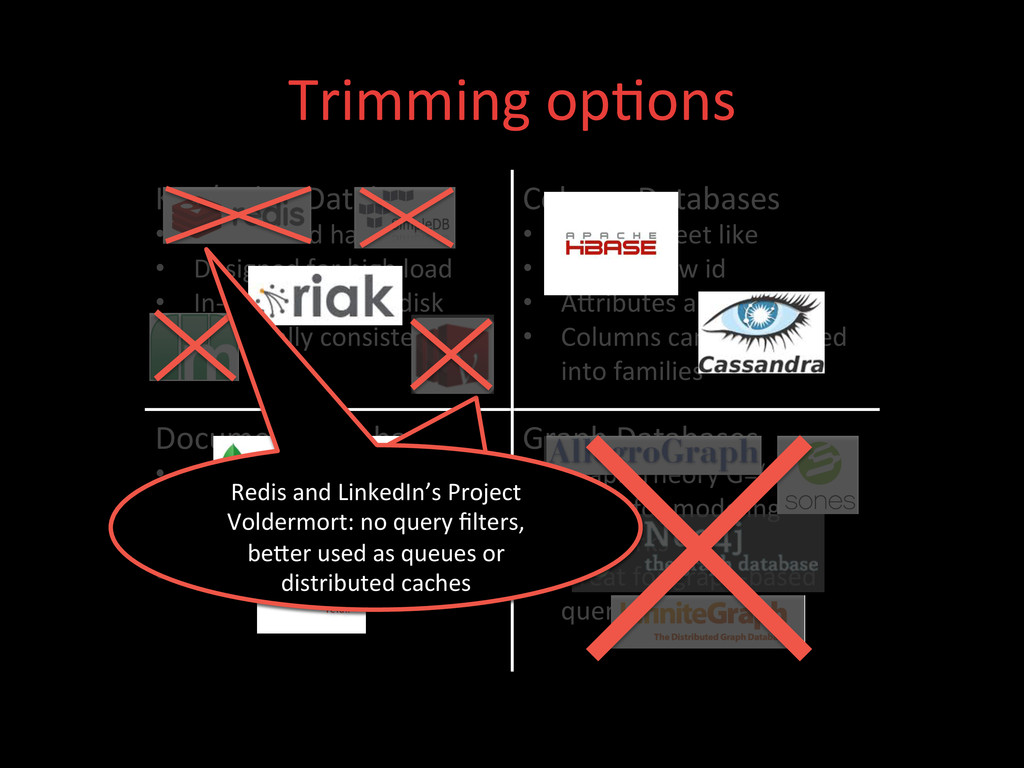
• Designed for high load • In-‐memory or on-‐disk • Eventually consistent Column Databases • Spread sheet like • Key is a row id • AXributes are columns • Columns can be grouped into families Document Databases • Like Key/Value • Value = Document • Document = JSON/BSON • JSON = Flexible Schema Graph Databases • Graph Theory G=(E,V) • Great for modeling networks • Great for graph-‐based query algorithms Not willing to store our data in a proprietary datastore. Redis and LinkedIn’s Project Voldermort: no query filters, beXer used as queues or distributed caches -
Trimming op>ons Key/Value Databases • Distributed hashtables
• Designed for high load • In-‐memory or on-‐disk • Eventually consistent Column Databases • Spread sheet like • Key is a row id • AXributes are columns • Columns can be grouped into families Document Databases • Like Key/Value • Value = Document • Document = JSON/BSON • JSON = Flexible Schema Graph Databases • Graph Theory G=(E,V) • Great for modeling networks • Great for graph-‐based query algorithms CouchDB: no ad-‐hoc queries; maturity in early 2010 made us shy away although we did try early prototypes. -
Trimming op>ons Key/Value Databases • Distributed hashtables
• Designed for high load • In-‐memory or on-‐disk • Eventually consistent Column Databases • Spread sheet like • Key is a row id • AXributes are columns • Columns can be grouped into families Document Databases • Like Key/Value • Value = Document • Document = JSON/BSON • JSON = Flexible Schema Graph Databases • Graph Theory G=(E,V) • Great for modeling networks • Great for graph-‐based query algorithms Cassandra: in early 2010, maturity ques>ons, no secondary indexes and no batch processing op>ons (came later on). -
Trimming op>ons Key/Value Databases • Distributed hashtables
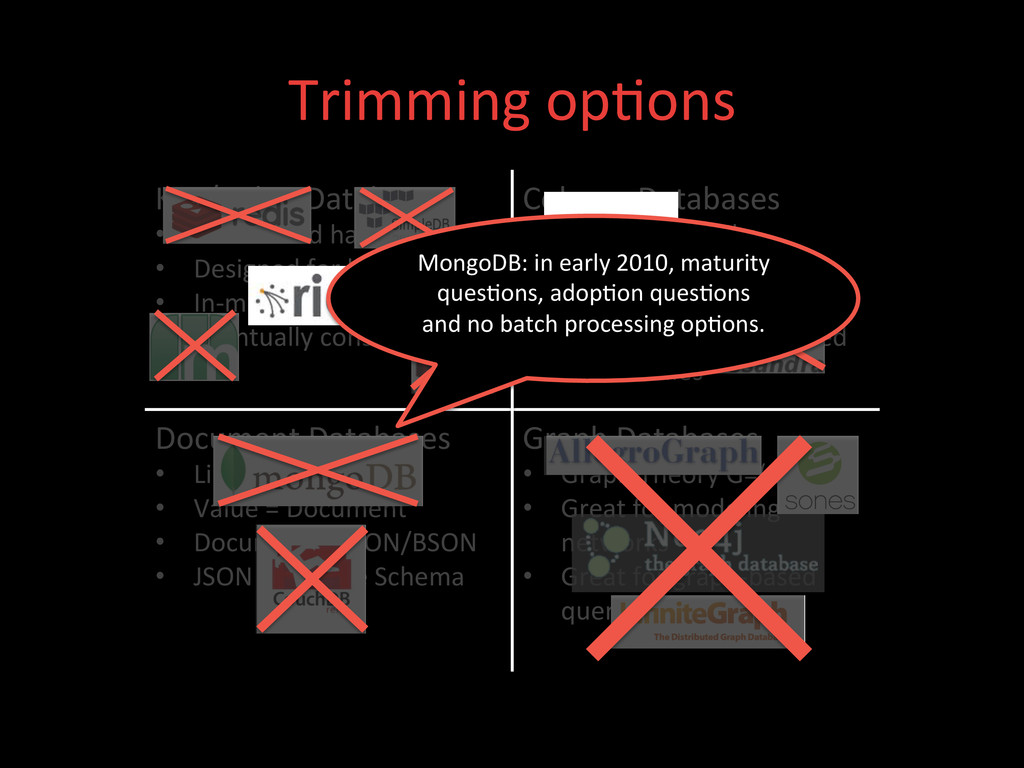
• Designed for high load • In-‐memory or on-‐disk • Eventually consistent Column Databases • Spread sheet like • Key is a row id • AXributes are columns • Columns can be grouped into families Document Databases • Like Key/Value • Value = Document • Document = JSON/BSON • JSON = Flexible Schema Graph Databases • Graph Theory G=(E,V) • Great for modeling networks • Great for graph-‐based query algorithms MongoDB: in early 2010, maturity ques>ons, adop>on ques>ons and no batch processing op>ons. -
Trimming op>ons Key/Value Databases • Distributed hashtables
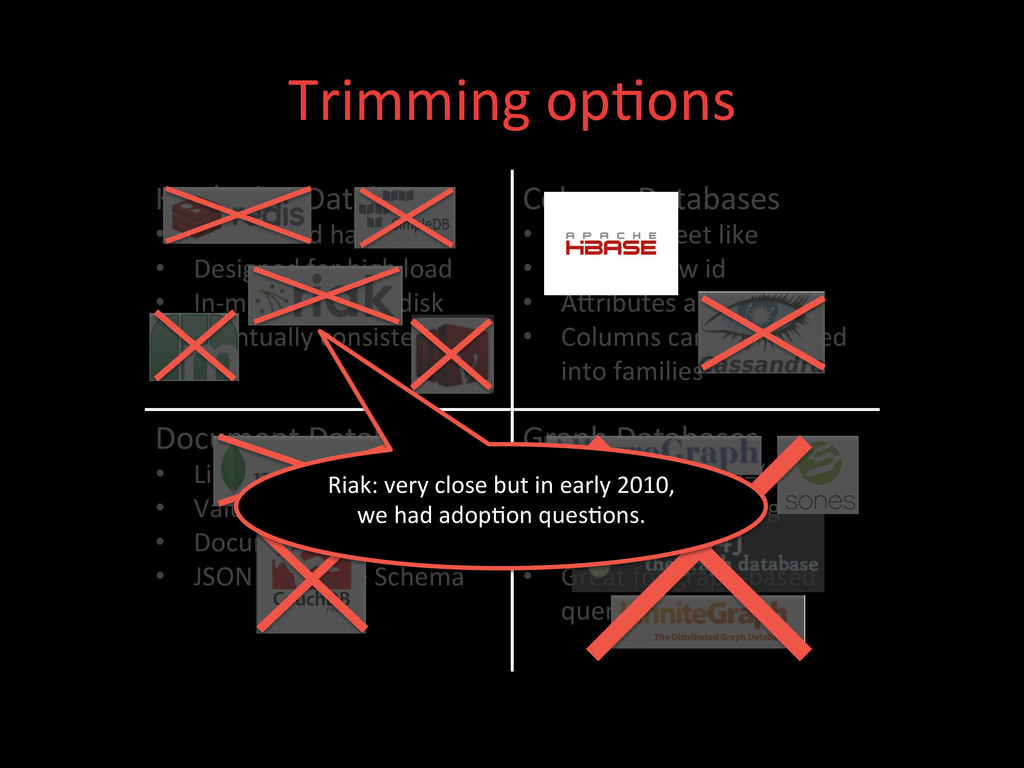
• Designed for high load • In-‐memory or on-‐disk • Eventually consistent Column Databases • Spread sheet like • Key is a row id • AXributes are columns • Columns can be grouped into families Document Databases • Like Key/Value • Value = Document • Document = JSON/BSON • JSON = Flexible Schema Graph Databases • Graph Theory G=(E,V) • Great for modeling networks • Great for graph-‐based query algorithms Riak: very close but in early 2010, we had adop>on ques>ons. -
Trimming op>ons Key/Value Databases • Distributed hashtables
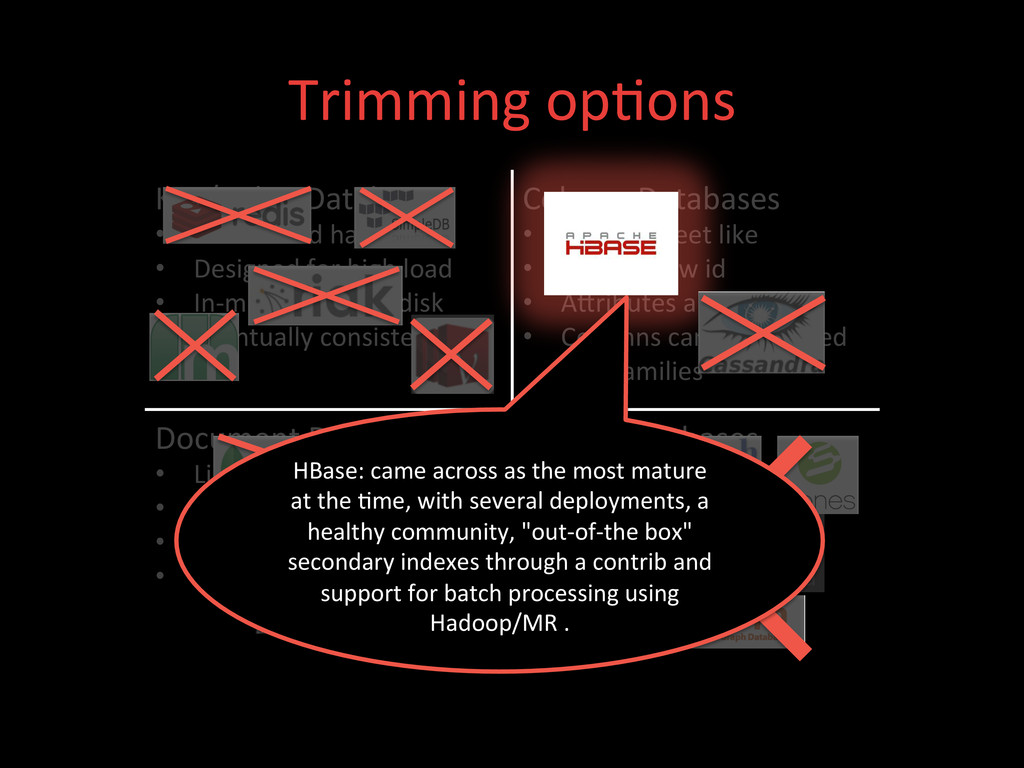
• Designed for high load • In-‐memory or on-‐disk • Eventually consistent Column Databases • Spread sheet like • Key is a row id • AXributes are columns • Columns can be grouped into families Document Databases • Like Key/Value • Value = Document • Document = JSON/BSON • JSON = Flexible Schema Graph Databases • Graph Theory G=(E,V) • Great for modeling networks • Great for graph-‐based query algorithms HBase: came across as the most mature at the >me, with several deployments, a healthy community, "out-‐of-‐the box" secondary indexes through a contrib and support for batch processing using Hadoop/MR . -
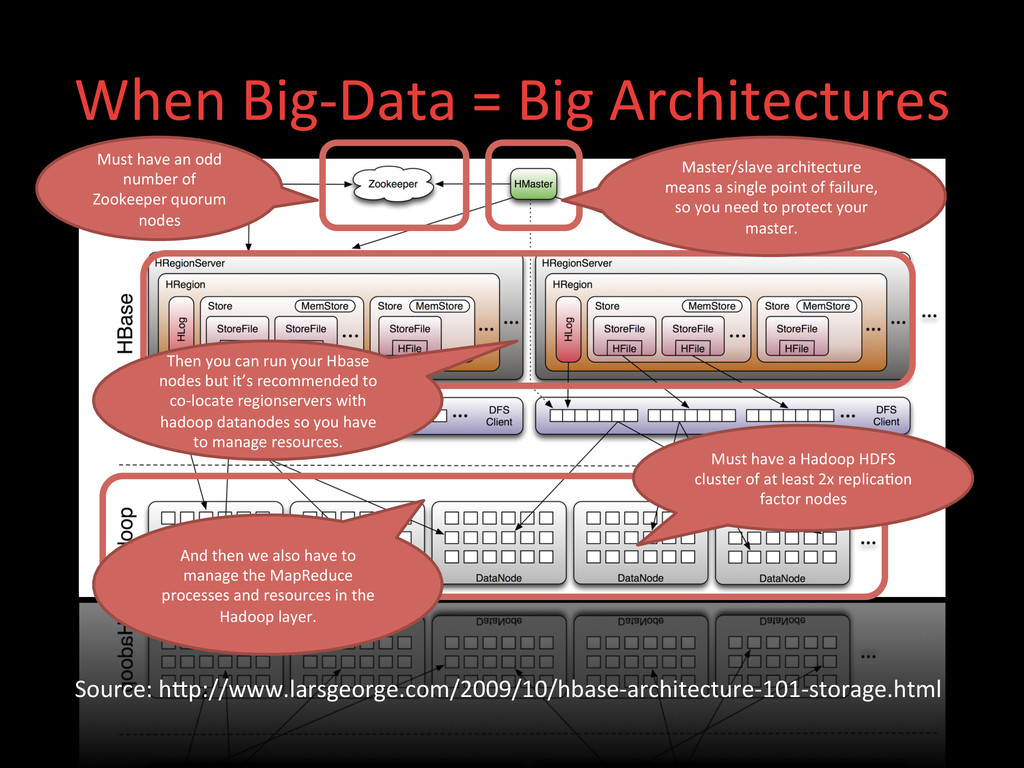
When Big-‐Data = Big Architectures Source: hXp://www.larsgeorge.com/2009/10/hbase-‐architecture-‐101-‐storage.html Must
have a Hadoop HDFS cluster of at least 2x replica>on factor nodes Must have an odd number of Zookeeper quorum nodes Then you can run your Hbase nodes but it’s recommended to co-‐locate regionservers with hadoop datanodes so you have to manage resources. Master/slave architecture means a single point of failure, so you need to protect your master. And then we also have to manage the MapReduce processes and resources in the Hadoop layer. -
To be expected • Hadoop/Hbase are designed to
move mountains • If you want to move big stuff, be prepared to some>mes use big equipment -
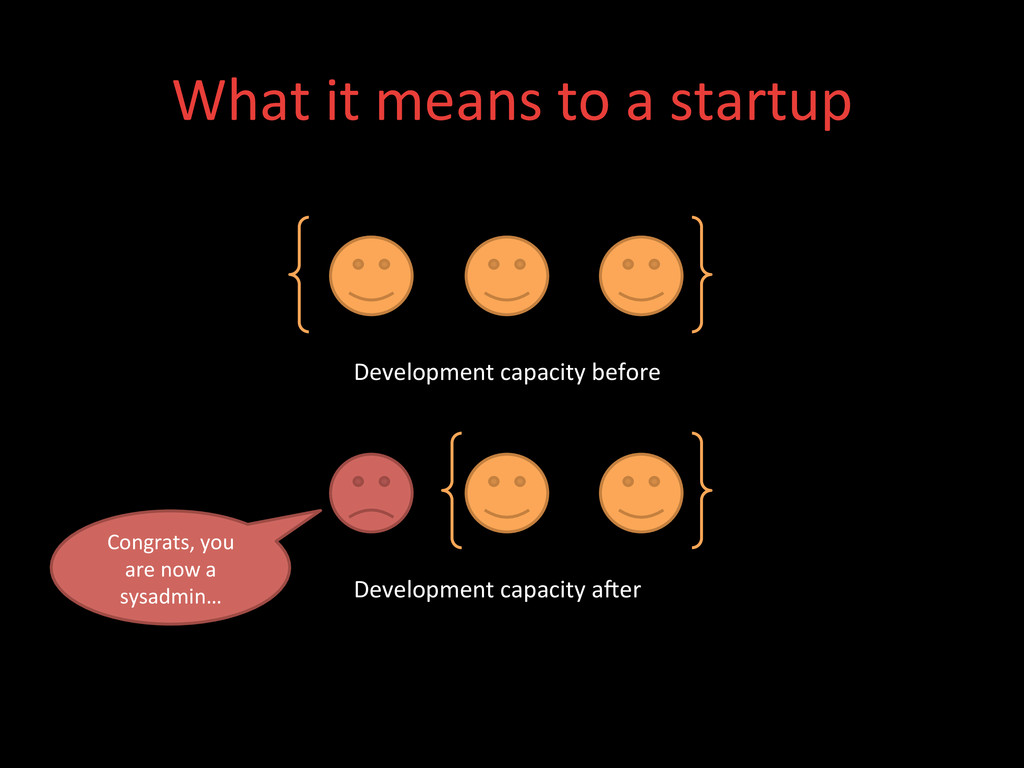
What it means to a startup Development capacity before
Development capacity aKer Congrats, you are now a sysadmin… -
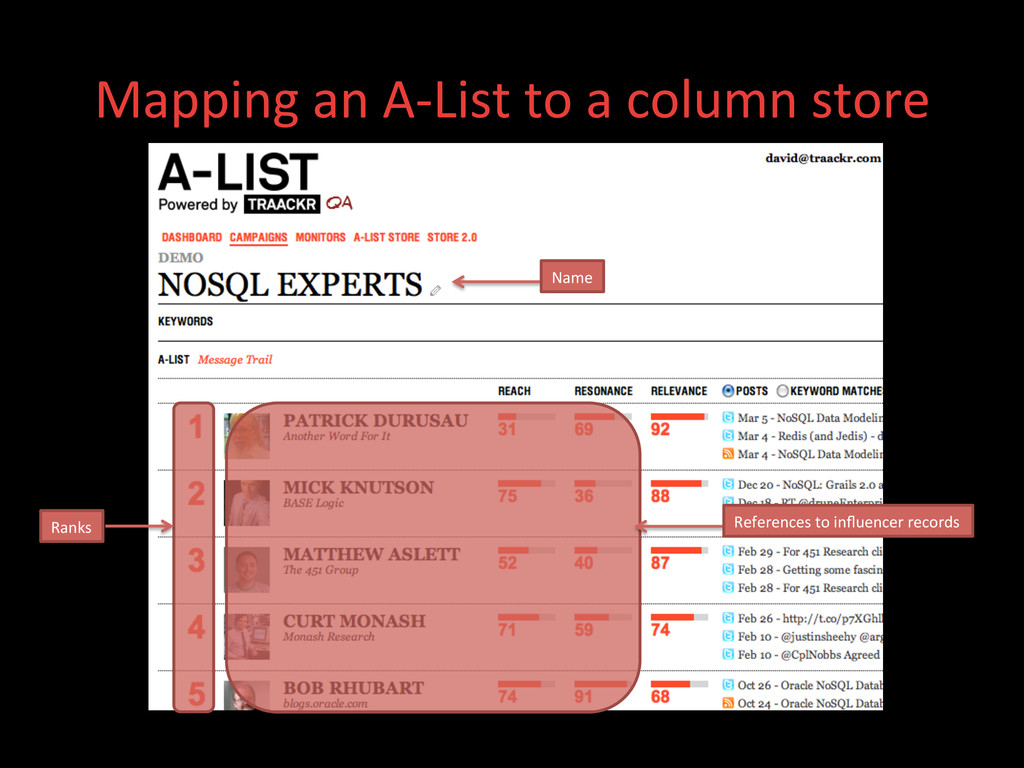
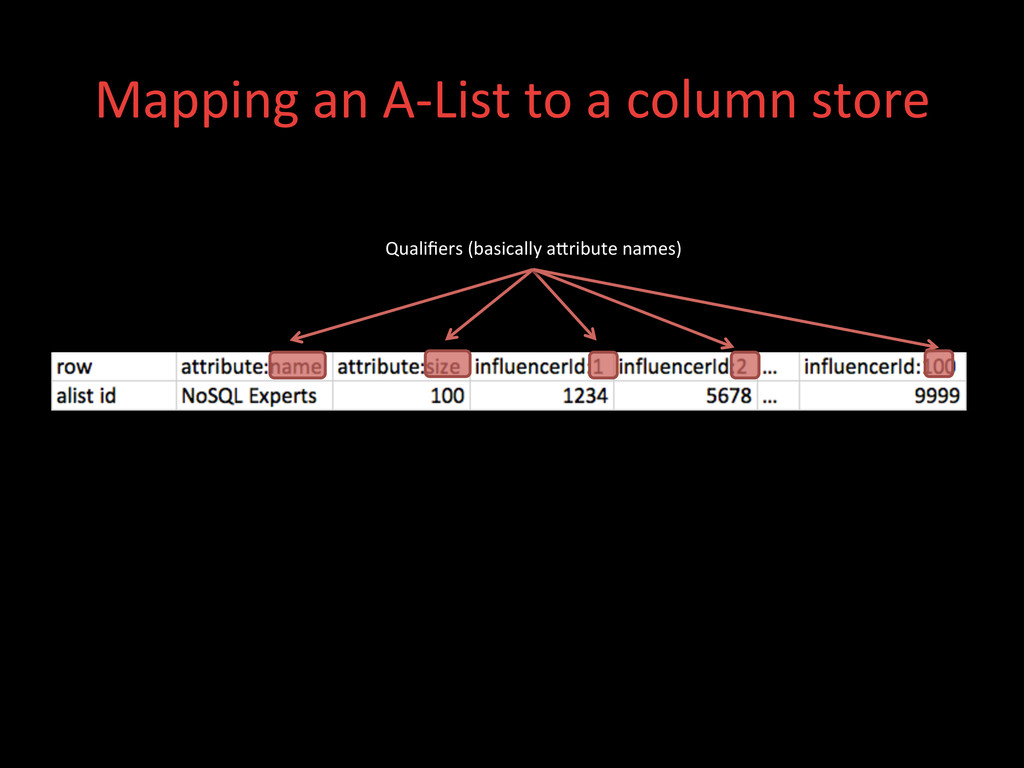
Mapping an A-‐List to a column store Name
Ranks References to influencer records -
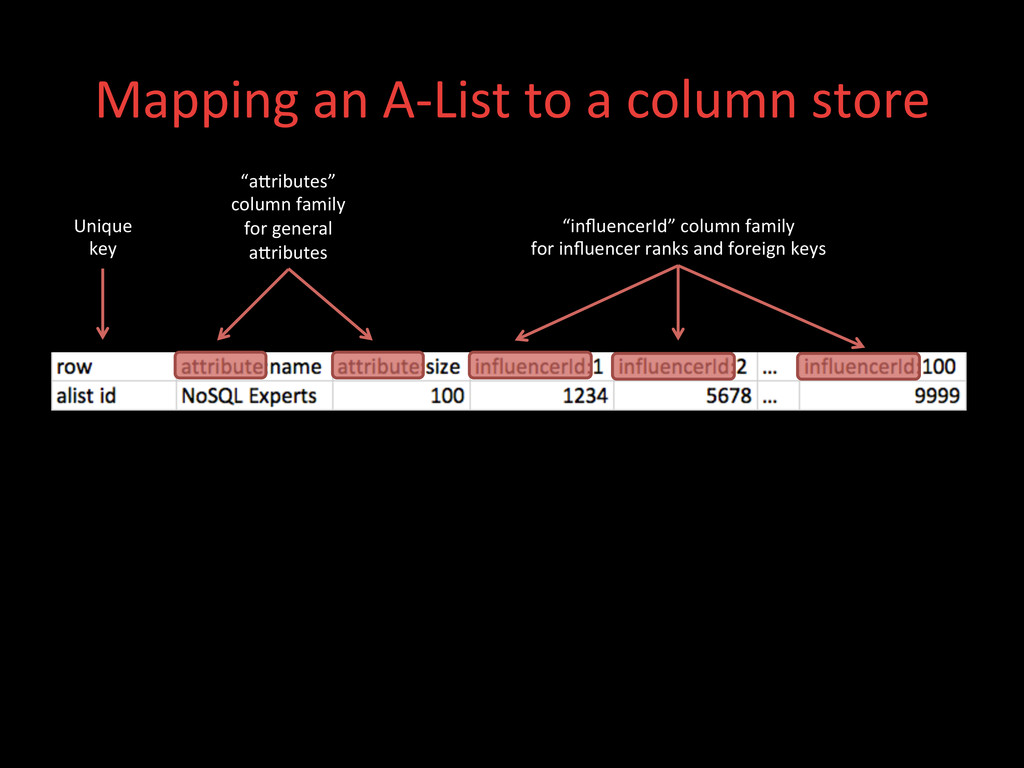
Mapping an A-‐List to a column store Unique
key “aXributes” column family for general aXributes “influencerId” column family for influencer ranks and foreign keys -
Mapping an A-‐List to a column store Qualifiers (basically
aXribute names) -
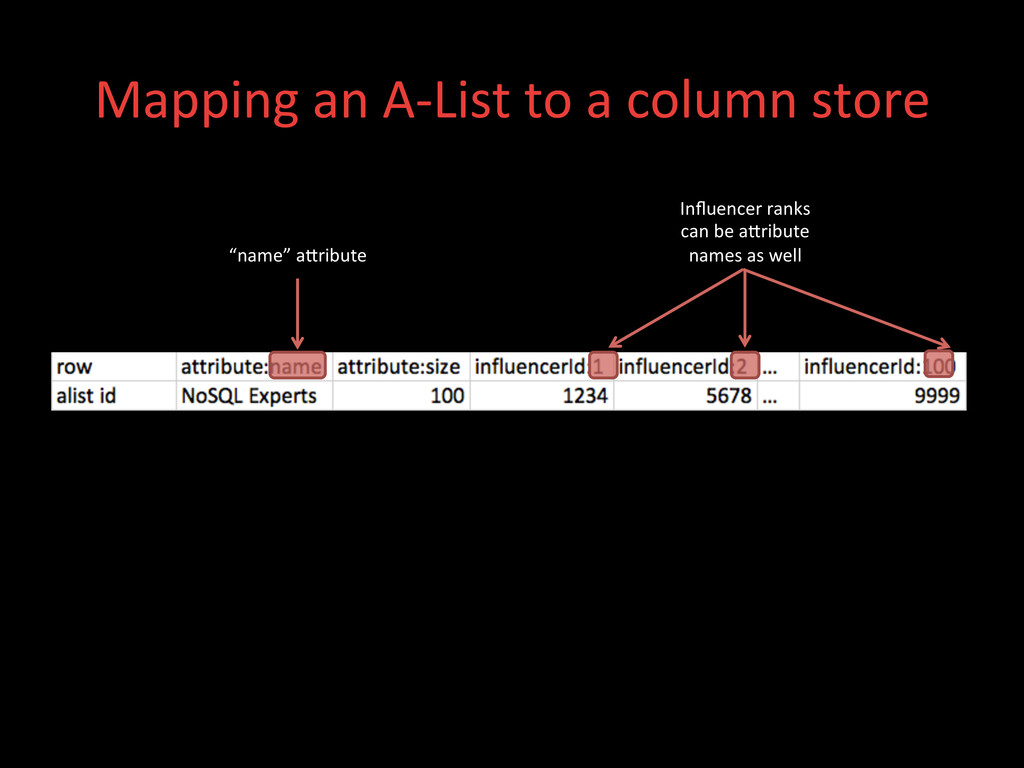
Mapping an A-‐List to a column store “name” aXribute
Influencer ranks can be aXribute names as well -
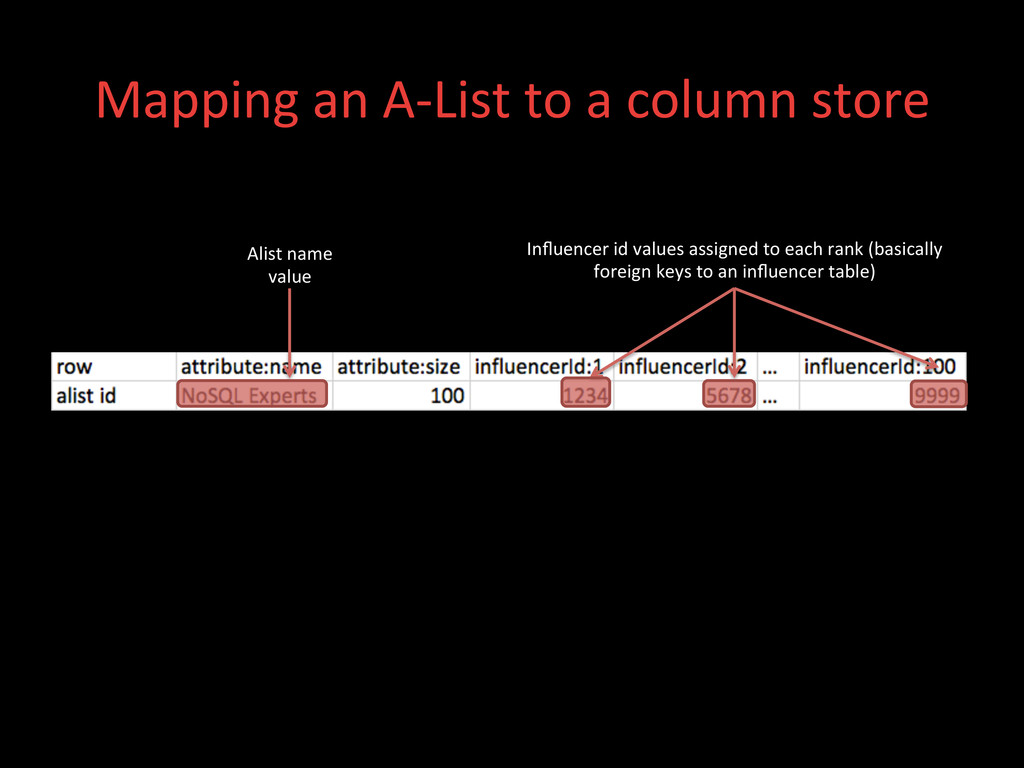
Mapping an A-‐List to a column store Alist name
value Influencer id values assigned to each rank (basically foreign keys to an influencer table) -
Mapping an A-‐List to a column store Can get
preXy long so needs indexing and pagina>on -
MapReduce for batch scoring • Need to re-‐score our
influencer database once a week • M/R cranked through it in 15 mins -
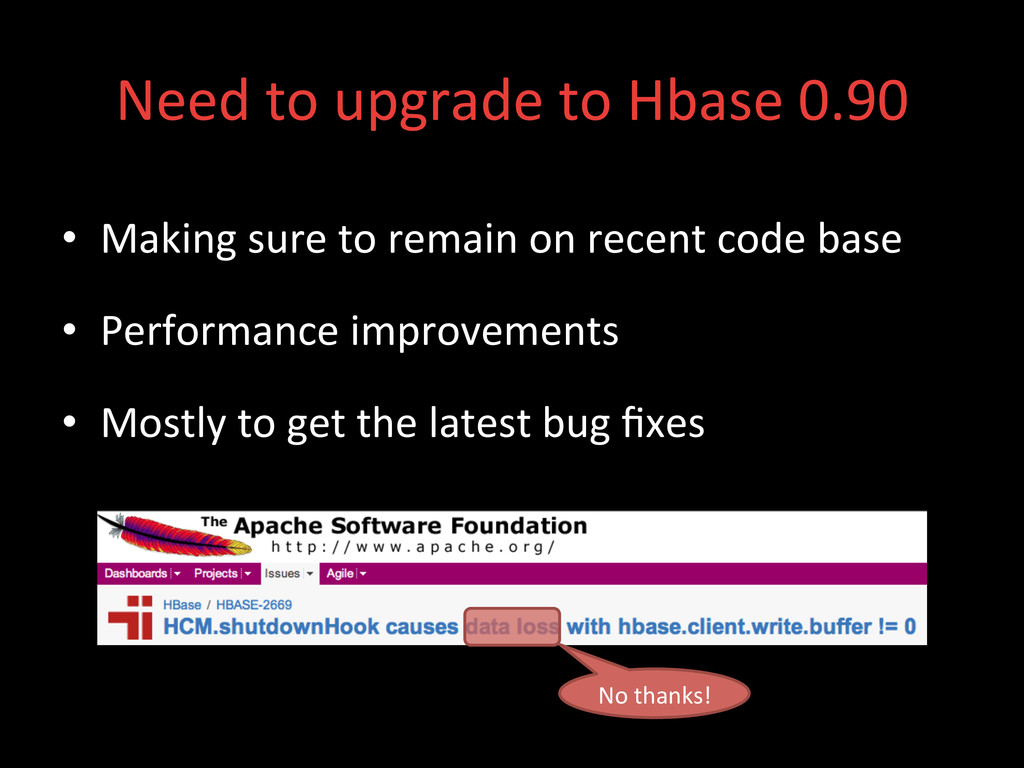
Need to upgrade to Hbase 0.90 • Making sure
to remain on recent code base • Performance improvements • Mostly to get the latest bug fixes No thanks! -
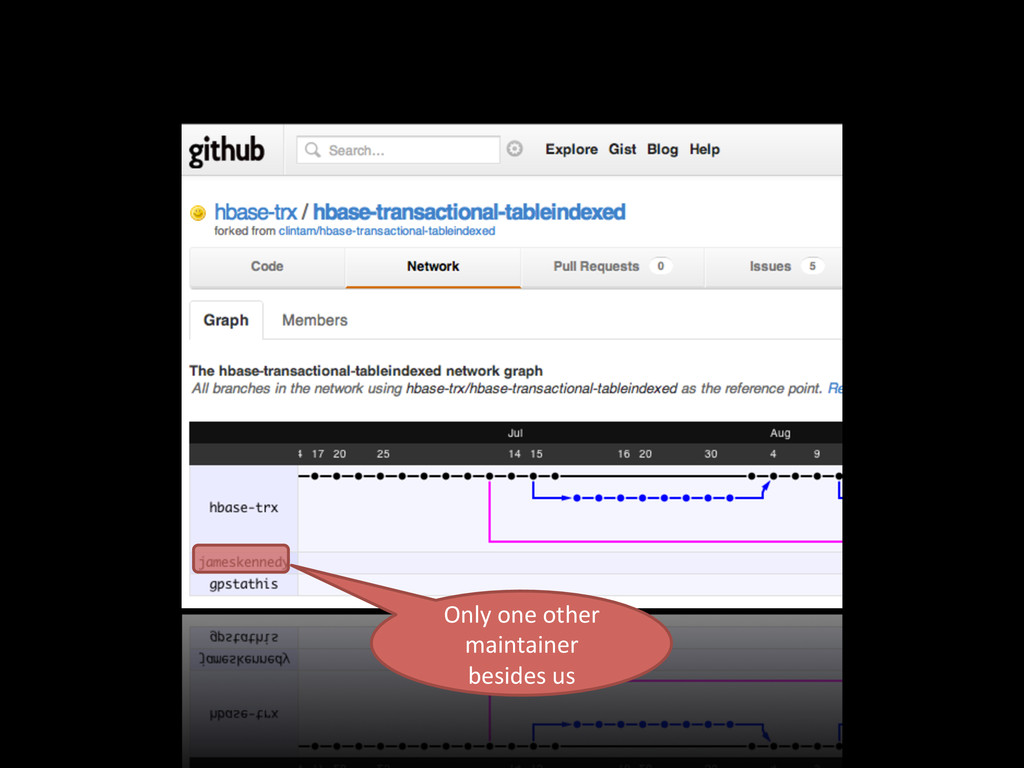
Let’s get this straight • Hbase no longer comes
with secondary indexing out-‐of-‐the-‐box • It’s been moved out of the trunk to GitHub • Where only one other company besides us seems to care about it -
What it means to a startup Development capacity
Congrats, you are now an hbase maintainer… -
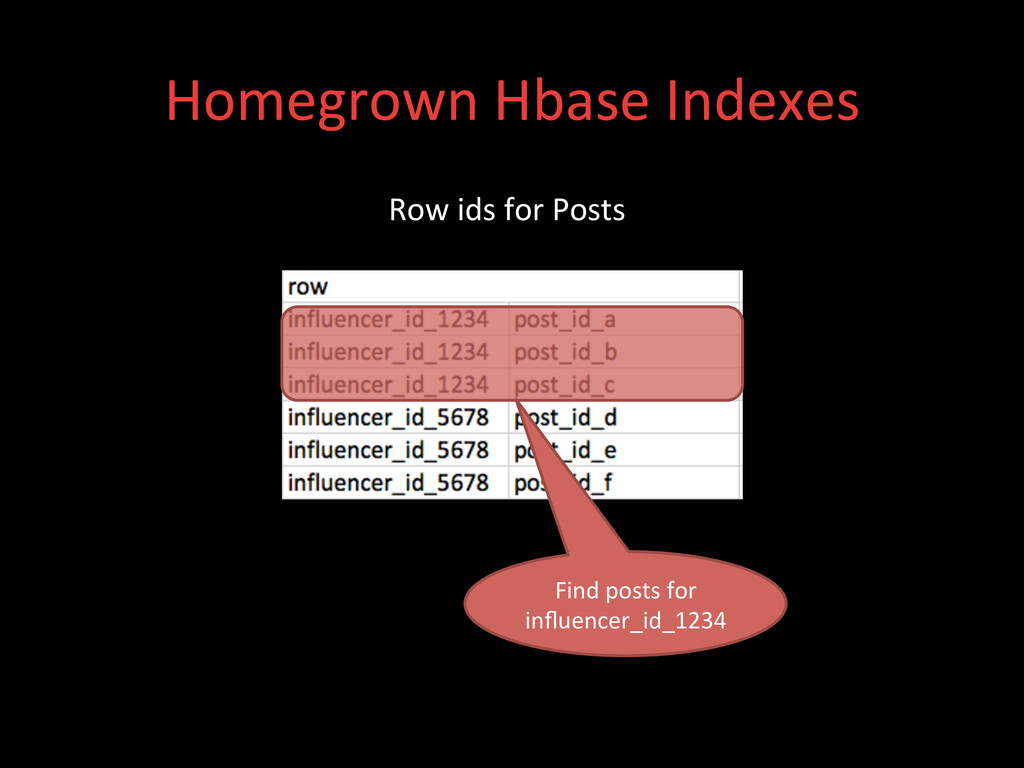
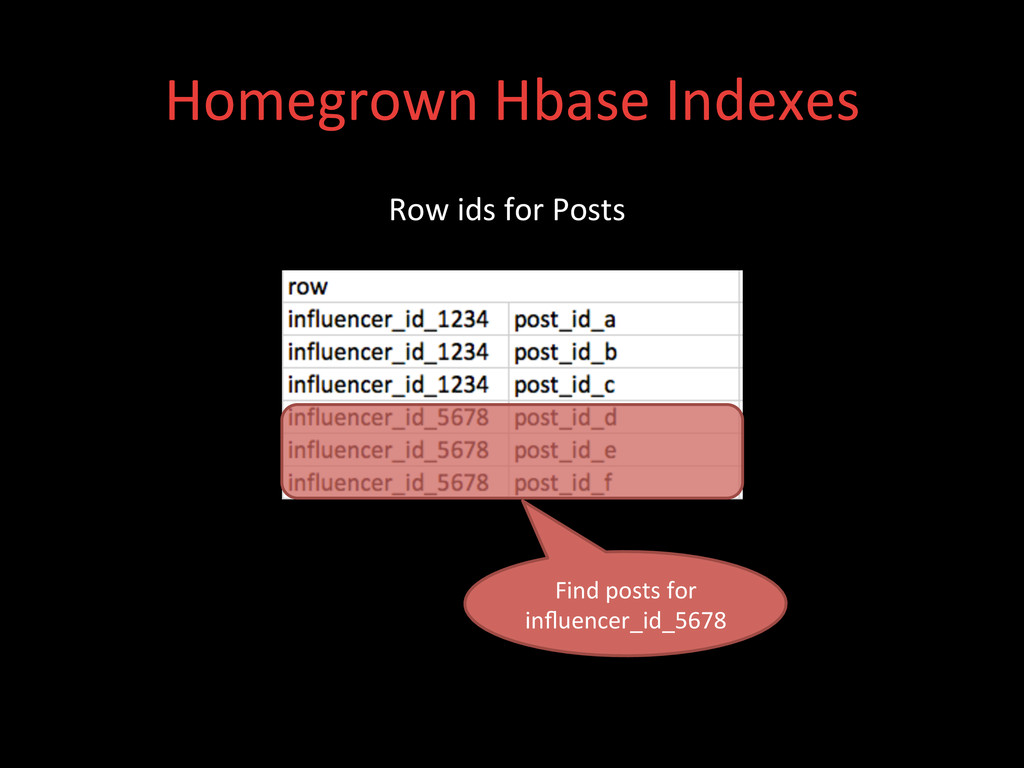
Homegrown Hbase Indexes Rows have id prefixes that can
be efficiently scanned using STARTROW and STOPROW filters Row ids for Posts -
Homegrown Hbase Indexes Find posts for influencer_id_1234
Row ids for Posts -
Homegrown Hbase Indexes Find posts for influencer_id_5678
Row ids for Posts -
Homegrown Hbase Indexes • No longer depending on
unmaintained code • Work with out-‐of-‐the-‐box Hbase installa>on -
What it means to a startup Development capacity
You are back but you s>ll need to maintain indexing logic -
Source: hXp://www.charliesheentshirts.info/ Applica>on layer indexes are slow and
briXle. The DB should be doing this, not us. Sort of… -
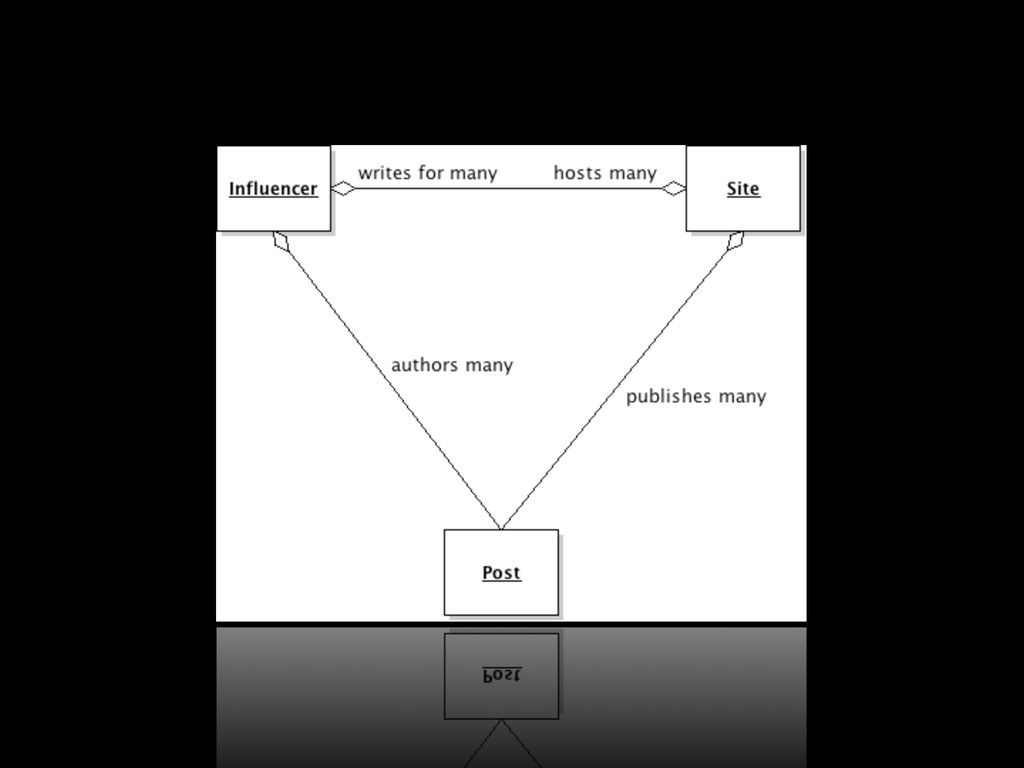
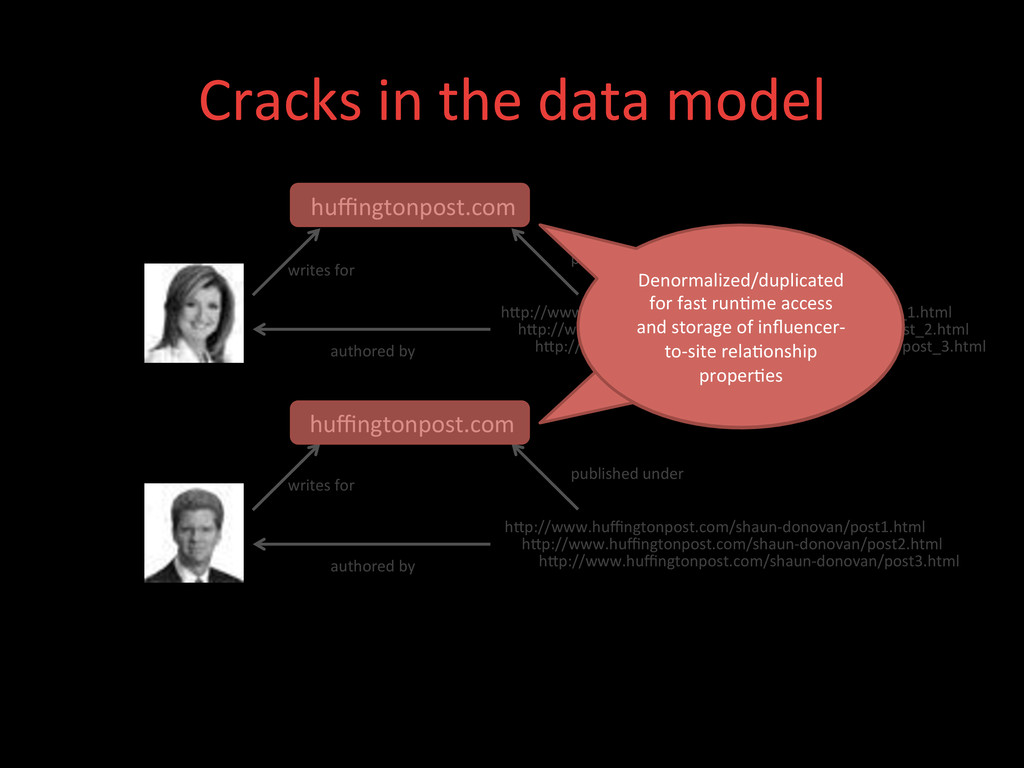
Cracks in the data model huffingtonpost.com huffingtonpost.com
hXp://www.huffingtonpost.com/arianna-‐huffington/post_1.html hXp://www.huffingtonpost.com/arianna-‐huffington/post_2.html hXp://www.huffingtonpost.com/arianna-‐huffington/post_3.html hXp://www.huffingtonpost.com/shaun-‐donovan/post1.html hXp://www.huffingtonpost.com/shaun-‐donovan/post2.html hXp://www.huffingtonpost.com/shaun-‐donovan/post3.html writes for authored by published under writes for authored by published under -
Cracks in the data model huffingtonpost.com huffingtonpost.com
hXp://www.huffingtonpost.com/arianna-‐huffington/post_1.html hXp://www.huffingtonpost.com/arianna-‐huffington/post_2.html hXp://www.huffingtonpost.com/arianna-‐huffington/post_3.html hXp://www.huffingtonpost.com/shaun-‐donovan/post1.html hXp://www.huffingtonpost.com/shaun-‐donovan/post2.html hXp://www.huffingtonpost.com/shaun-‐donovan/post3.html writes for authored by published under writes for authored by published under Denormalized/duplicated for fast run>me access and storage of influencer-‐ to-‐site rela>onship proper>es -
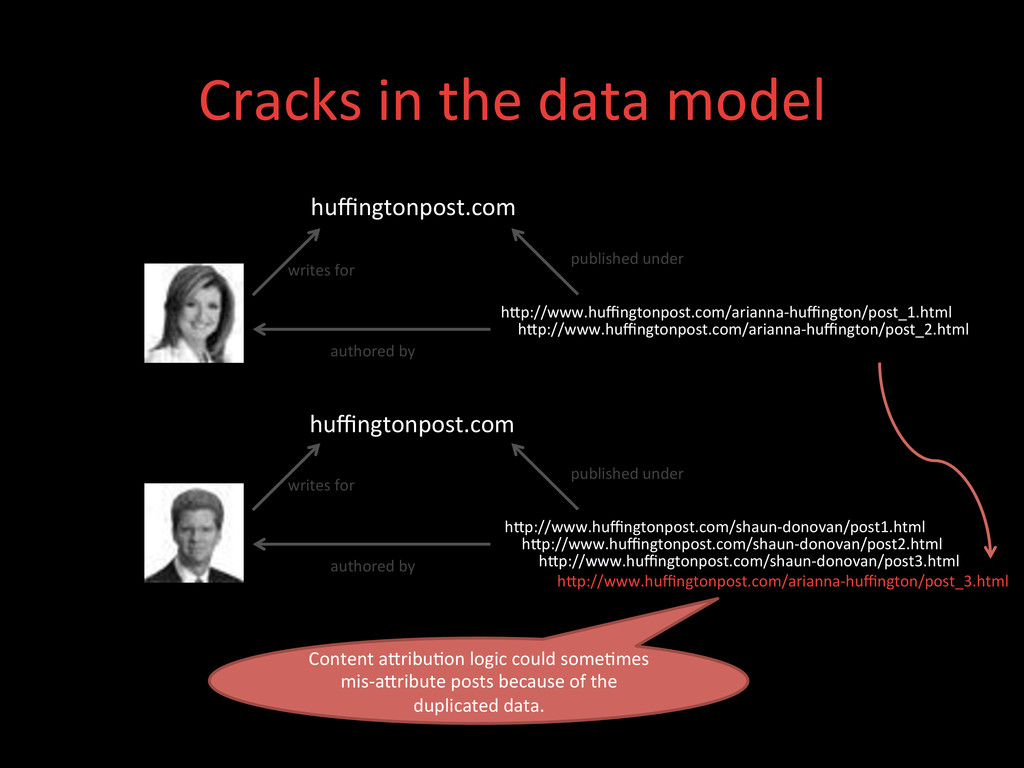
Cracks in the data model huffingtonpost.com huffingtonpost.com
hXp://www.huffingtonpost.com/arianna-‐huffington/post_1.html hXp://www.huffingtonpost.com/arianna-‐huffington/post_2.html hXp://www.huffingtonpost.com/arianna-‐huffington/post_3.html hXp://www.huffingtonpost.com/shaun-‐donovan/post1.html hXp://www.huffingtonpost.com/shaun-‐donovan/post2.html hXp://www.huffingtonpost.com/shaun-‐donovan/post3.html writes for authored by published under writes for authored by published under Content aXribu>on logic could some>mes mis-‐aXribute posts because of the duplicated data. -
Cracks in the data model huffingtonpost.com huffingtonpost.com
hXp://www.huffingtonpost.com/arianna-‐huffington/post_1.html hXp://www.huffingtonpost.com/arianna-‐huffington/post_2.html hXp://www.huffingtonpost.com/arianna-‐huffington/post_3.html hXp://www.huffingtonpost.com/shaun-‐donovan/post1.html hXp://www.huffingtonpost.com/shaun-‐donovan/post2.html hXp://www.huffingtonpost.com/shaun-‐donovan/post3.html writes for authored by published under writes for authored by published under Exacerbated when we started tracking people’s content on a daily basis in mid-‐2011 -
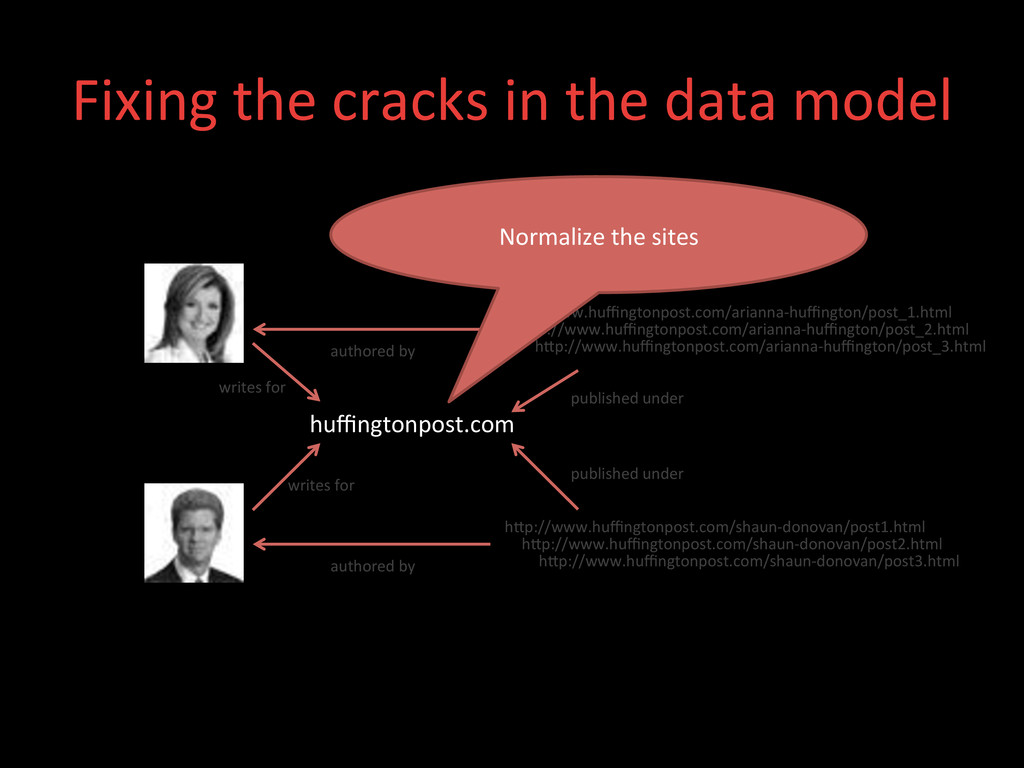
Fixing the cracks in the data model huffingtonpost.com
hXp://www.huffingtonpost.com/arianna-‐huffington/post_1.html hXp://www.huffingtonpost.com/arianna-‐huffington/post_2.html hXp://www.huffingtonpost.com/arianna-‐huffington/post_3.html hXp://www.huffingtonpost.com/shaun-‐donovan/post1.html hXp://www.huffingtonpost.com/shaun-‐donovan/post2.html hXp://www.huffingtonpost.com/shaun-‐donovan/post3.html writes for authored by published under writes for authored by published under -
Fixing the cracks in the data model huffingtonpost.com
hXp://www.huffingtonpost.com/arianna-‐huffington/post_1.html hXp://www.huffingtonpost.com/arianna-‐huffington/post_2.html hXp://www.huffingtonpost.com/arianna-‐huffington/post_3.html hXp://www.huffingtonpost.com/shaun-‐donovan/post1.html hXp://www.huffingtonpost.com/shaun-‐donovan/post2.html hXp://www.huffingtonpost.com/shaun-‐donovan/post3.html writes for authored by published under writes for authored by published under Normalize the sites -
Fixing the cracks in the data model • Normaliza>on
requires stronger secondary indexing • Our applica>on layer indexing would need revisi>ng…again! -
What it means to a startup Development capacity
Psych! You are back to wri>ng indexing code. -
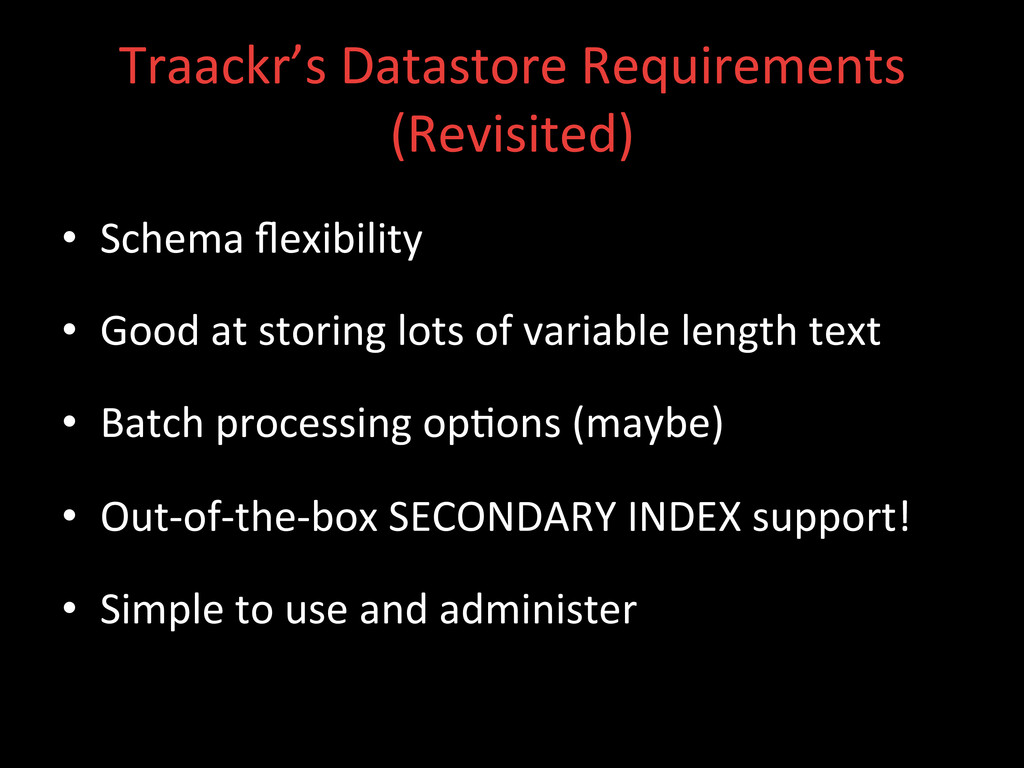
Traackr’s Datastore Requirements (Revisited) • Schema flexibility
• Good at storing lots of variable length text • Batch processing op>ons (maybe) • Out-‐of-‐the-‐box SECONDARY INDEX support! • Simple to use and administer -
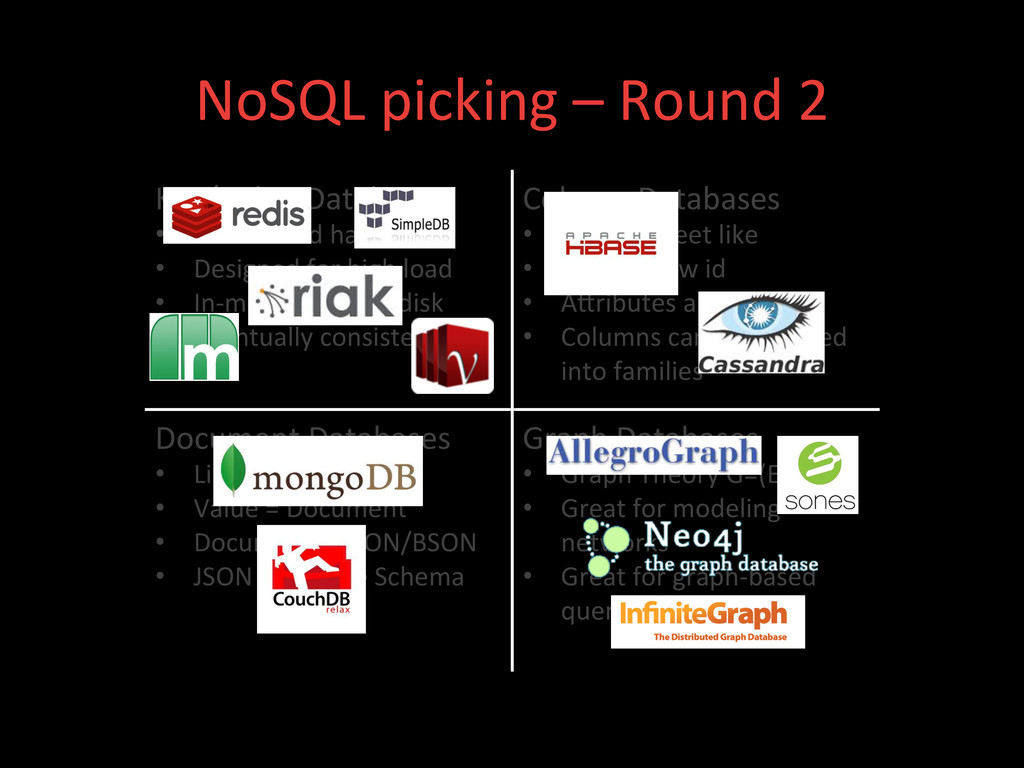
NoSQL picking – Round 2 Key/Value Databases •
Distributed hashtables • Designed for high load • In-‐memory or on-‐disk • Eventually consistent Column Databases • Spread sheet like • Key is a row id • AXributes are columns • Columns can be grouped into families Document Databases • Like Key/Value • Value = Document • Document = JSON/BSON • JSON = Flexible Schema Graph Databases • Graph Theory G=(E,V) • Great for modeling networks • Great for graph-‐based query algorithms -
NoSQL picking – Round 2 Key/Value Databases •
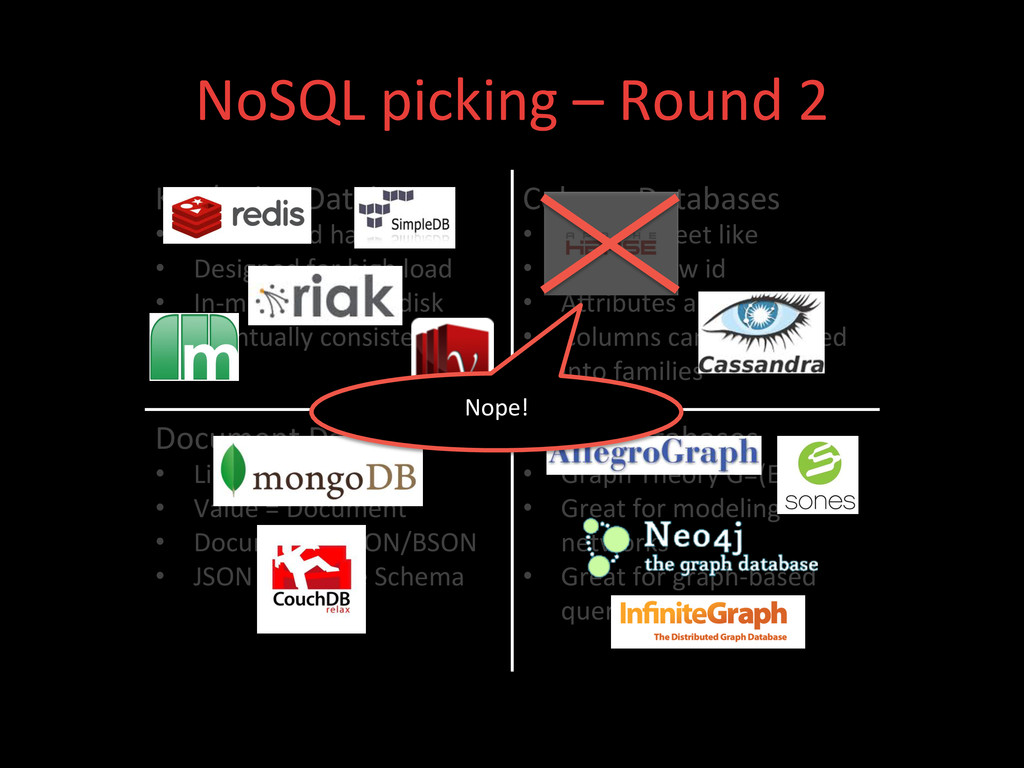
Distributed hashtables • Designed for high load • In-‐memory or on-‐disk • Eventually consistent Column Databases • Spread sheet like • Key is a row id • AXributes are columns • Columns can be grouped into families Document Databases • Like Key/Value • Value = Document • Document = JSON/BSON • JSON = Flexible Schema Graph Databases • Graph Theory G=(E,V) • Great for modeling networks • Great for graph-‐based query algorithms Nope! -
NoSQL picking – Round 2 Key/Value Databases •
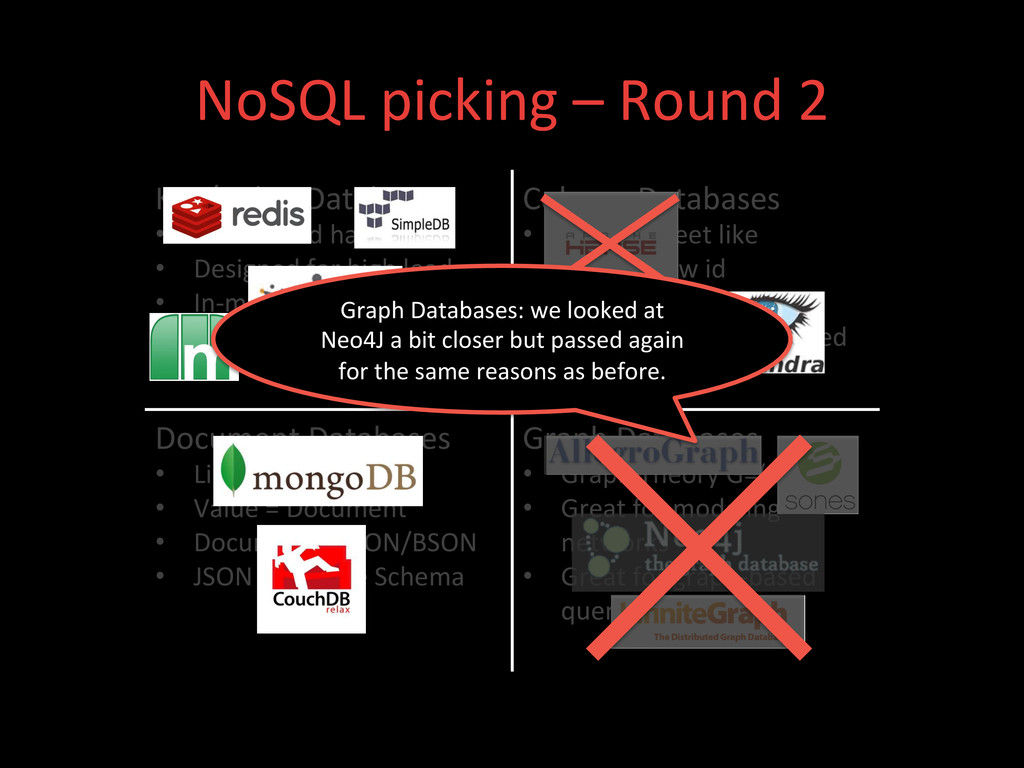
Distributed hashtables • Designed for high load • In-‐memory or on-‐disk • Eventually consistent Column Databases • Spread sheet like • Key is a row id • AXributes are columns • Columns can be grouped into families Document Databases • Like Key/Value • Value = Document • Document = JSON/BSON • JSON = Flexible Schema Graph Databases • Graph Theory G=(E,V) • Great for modeling networks • Great for graph-‐based query algorithms Graph Databases: we looked at Neo4J a bit closer but passed again for the same reasons as before. -
NoSQL picking – Round 2 Key/Value Databases •
Distributed hashtables • Designed for high load • In-‐memory or on-‐disk • Eventually consistent Column Databases • Spread sheet like • Key is a row id • AXributes are columns • Columns can be grouped into families Document Databases • Like Key/Value • Value = Document • Document = JSON/BSON • JSON = Flexible Schema Graph Databases • Graph Theory G=(E,V) • Great for modeling networks • Great for graph-‐based query algorithms Memcache: s>ll no -
NoSQL picking – Round 2 Key/Value Databases •
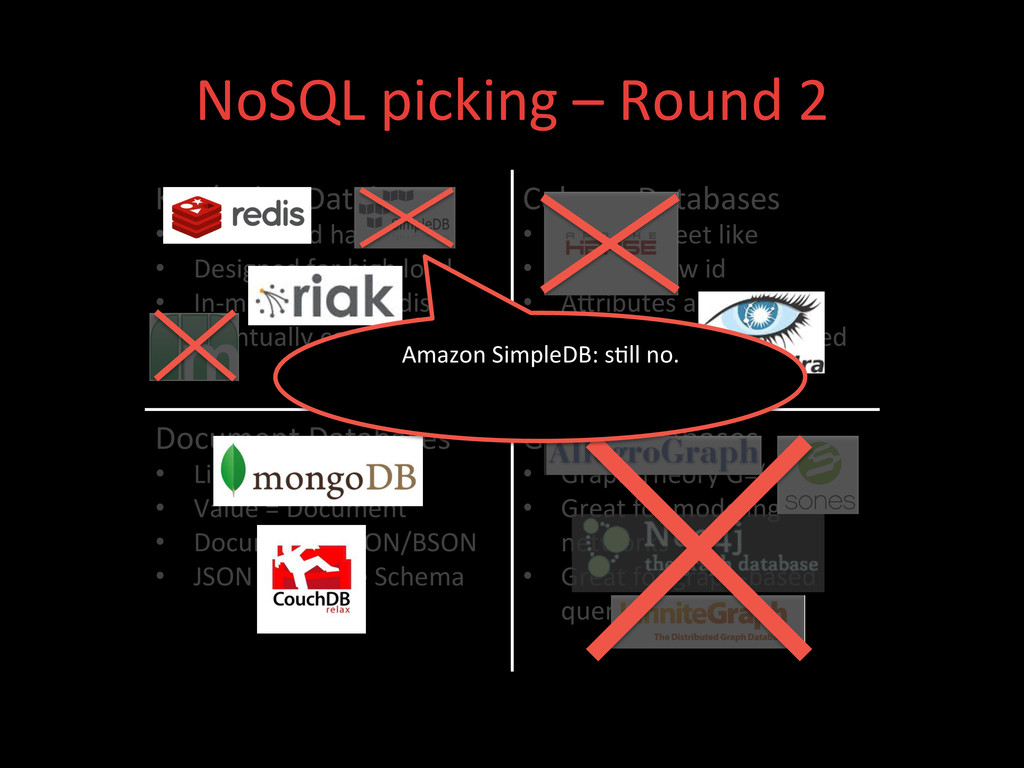
Distributed hashtables • Designed for high load • In-‐memory or on-‐disk • Eventually consistent Column Databases • Spread sheet like • Key is a row id • AXributes are columns • Columns can be grouped into families Document Databases • Like Key/Value • Value = Document • Document = JSON/BSON • JSON = Flexible Schema Graph Databases • Graph Theory G=(E,V) • Great for modeling networks • Great for graph-‐based query algorithms Amazon SimpleDB: s>ll no. -
NoSQL picking – Round 2 Key/Value Databases •
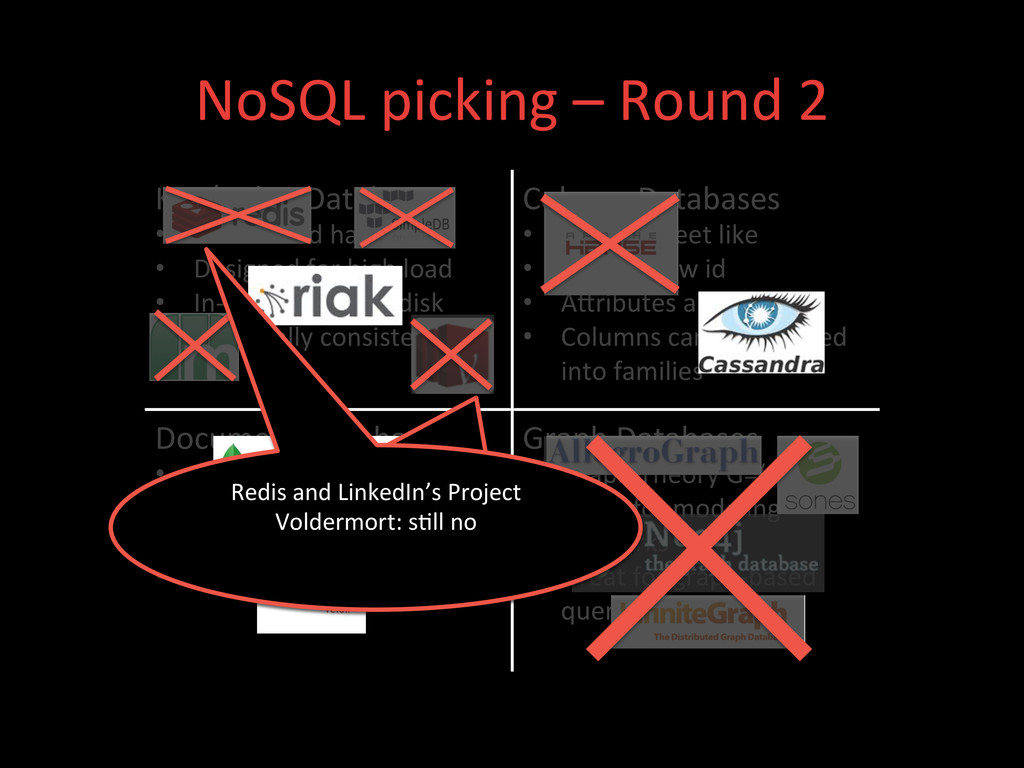
Distributed hashtables • Designed for high load • In-‐memory or on-‐disk • Eventually consistent Column Databases • Spread sheet like • Key is a row id • AXributes are columns • Columns can be grouped into families Document Databases • Like Key/Value • Value = Document • Document = JSON/BSON • JSON = Flexible Schema Graph Databases • Graph Theory G=(E,V) • Great for modeling networks • Great for graph-‐based query algorithms Not willing to store our data in a proprietary datastore. Redis and LinkedIn’s Project Voldermort: s>ll no -
NoSQL picking – Round 2 Key/Value Databases •
Distributed hashtables • Designed for high load • In-‐memory or on-‐disk • Eventually consistent Column Databases • Spread sheet like • Key is a row id • AXributes are columns • Columns can be grouped into families Document Databases • Like Key/Value • Value = Document • Document = JSON/BSON • JSON = Flexible Schema Graph Databases • Graph Theory G=(E,V) • Great for modeling networks • Great for graph-‐based query algorithms CouchDB: more mature but s>ll no ad-‐hoc queries. -
NoSQL picking – Round 2 Key/Value Databases •
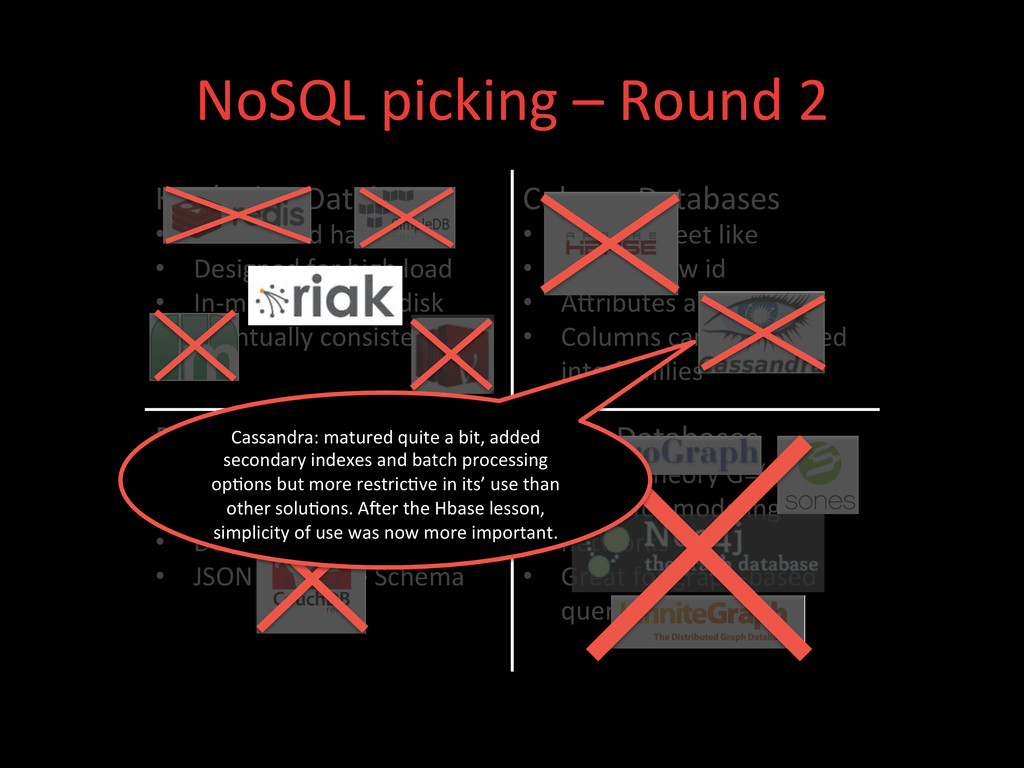
Distributed hashtables • Designed for high load • In-‐memory or on-‐disk • Eventually consistent Column Databases • Spread sheet like • Key is a row id • AXributes are columns • Columns can be grouped into families Document Databases • Like Key/Value • Value = Document • Document = JSON/BSON • JSON = Flexible Schema Graph Databases • Graph Theory G=(E,V) • Great for modeling networks • Great for graph-‐based query algorithms Cassandra: matured quite a bit, added secondary indexes and batch processing op>ons but more restric>ve in its’ use than other solu>ons. AKer the Hbase lesson, simplicity of use was now more important. -
NoSQL picking – Round 2 Key/Value Databases •
Distributed hashtables • Designed for high load • In-‐memory or on-‐disk • Eventually consistent Column Databases • Spread sheet like • Key is a row id • AXributes are columns • Columns can be grouped into families Document Databases • Like Key/Value • Value = Document • Document = JSON/BSON • JSON = Flexible Schema Graph Databases • Graph Theory G=(E,V) • Great for modeling networks • Great for graph-‐based query algorithms Riak: strong contender s>ll but adop>on ques>ons remained. -
NoSQL picking – Round 2 Key/Value Databases •
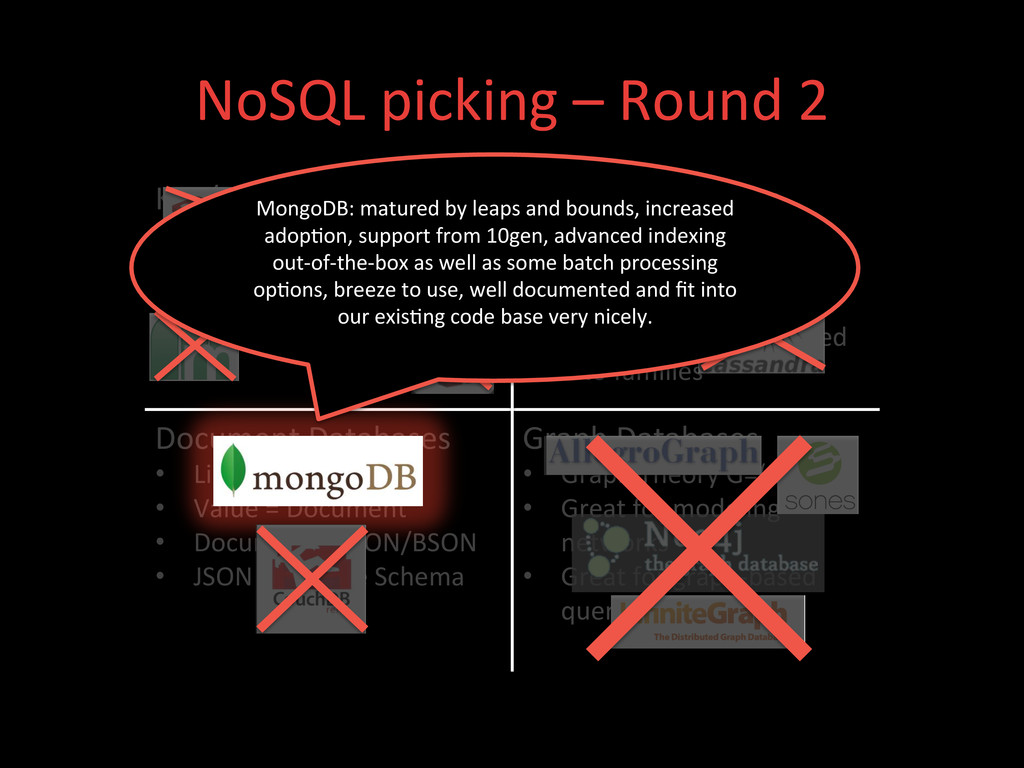
Distributed hashtables • Designed for high load • In-‐memory or on-‐disk • Eventually consistent Column Databases • Spread sheet like • Key is a row id • AXributes are columns • Columns can be grouped into families Document Databases • Like Key/Value • Value = Document • Document = JSON/BSON • JSON = Flexible Schema Graph Databases • Graph Theory G=(E,V) • Great for modeling networks • Great for graph-‐based query algorithms MongoDB: matured by leaps and bounds, increased adop>on, support from 10gen, advanced indexing out-‐of-‐the-‐box as well as some batch processing op>ons, breeze to use, well documented and fit into our exis>ng code base very nicely. -
Immediate Benefits • No more maintaining custom applica>on-‐layer
secondary indexing code -
What it means to a startup Development capacity
Yay! I’m back! -
Immediate Benefits • No more maintaining custom applica>on-‐layer
secondary indexing code • Single binary installa>on greatly simplifies administra>on -
What it means to a startup Development capacity
Honestly, I thought I’d never see you guys again! -
Immediate Benefits • No more maintaining custom applica>on-‐layer
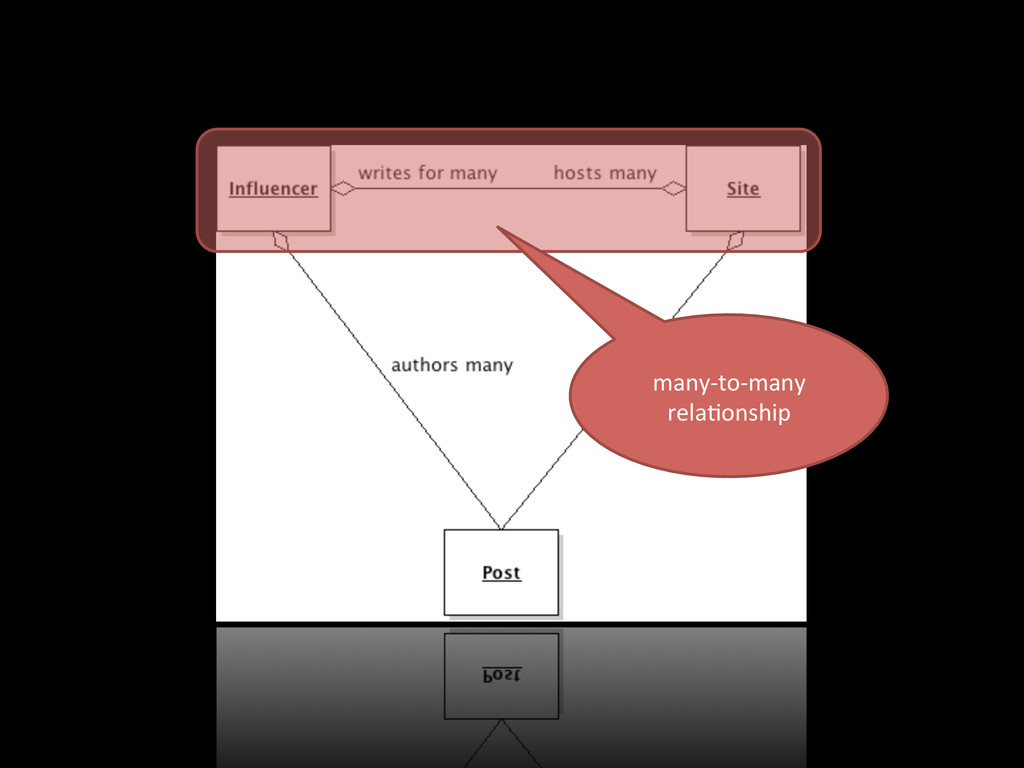
secondary indexing code • Single binary installa>on greatly simplifies administra>on • Our NoSQL could now support our domain model -
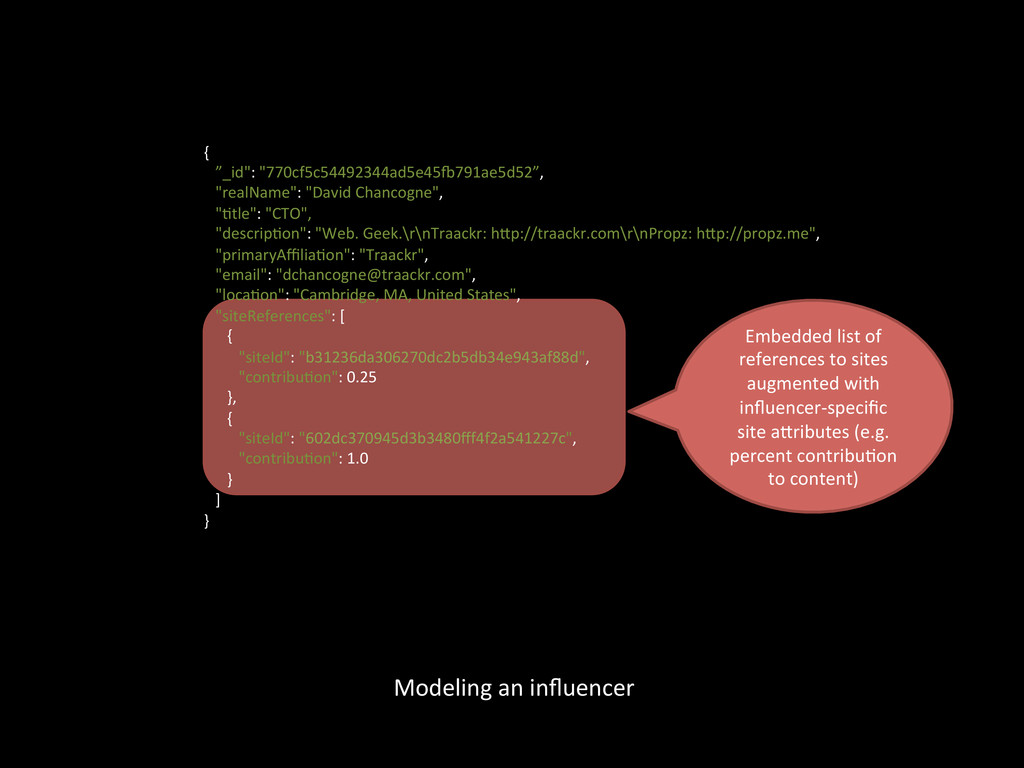
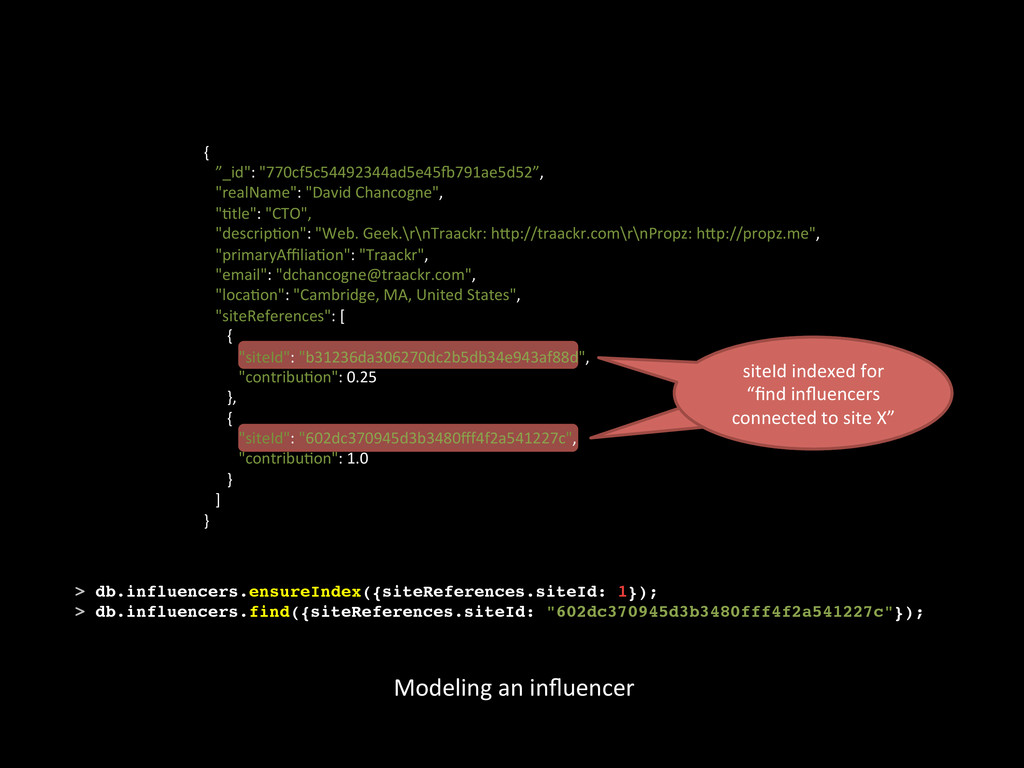
Modeling an influencer Embedded list of references to
sites augmented with influencer-‐specific site aXributes (e.g. percent contribu>on to content) { ”_id": "770cf5c54492344ad5e45„791ae5d52”, "realName": "David Chancogne", ">tle": "CTO", "descrip>on": "Web. Geek.\r\nTraackr: hXp://traackr.com\r\nPropz: hXp://propz.me", "primaryAffilia>on": "Traackr", "email": "[email protected]", "loca>on": "Cambridge, MA, United States", "siteReferences": [ { "siteId": "b31236da306270dc2b5db34e943af88d", "contribu>on": 0.25 }, { "siteId": "602dc370945d3b3480fff4f2a541227c", "contribu>on": 1.0 } ] } -
Modeling an influencer siteId indexed for “find influencers
connected to site X” > db.influencers.ensureIndex({siteReferences.siteId: 1});! > db.influencers.find({siteReferences.siteId: "602dc370945d3b3480fff4f2a541227c"});! { ”_id": "770cf5c54492344ad5e45„791ae5d52”, "realName": "David Chancogne", ">tle": "CTO", "descrip>on": "Web. Geek.\r\nTraackr: hXp://traackr.com\r\nPropz: hXp://propz.me", "primaryAffilia>on": "Traackr", "email": "[email protected]", "loca>on": "Cambridge, MA, United States", "siteReferences": [ { "siteId": "b31236da306270dc2b5db34e943af88d", "contribu>on": 0.25 }, { "siteId": "602dc370945d3b3480fff4f2a541227c", "contribu>on": 1.0 } ] } -
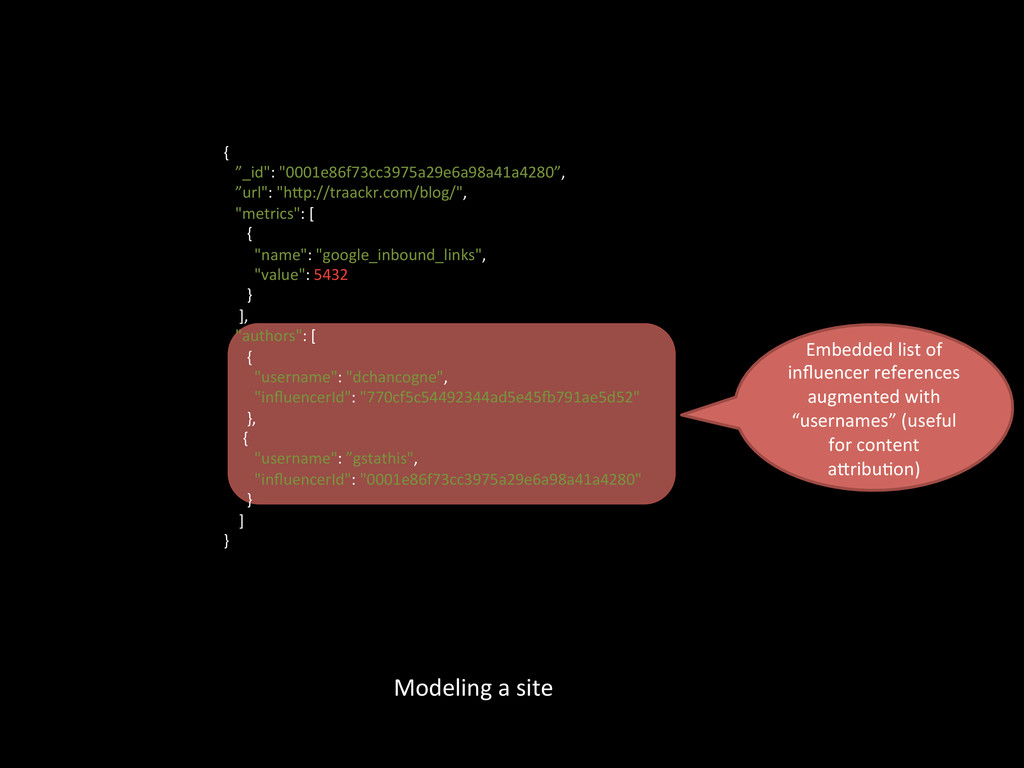
Embedded list of influencer references augmented with
“usernames” (useful for content aXribu>on) { ”_id": "0001e86f73cc3975a29e6a98a41a4280”, ”url": "hXp://traackr.com/blog/", "metrics": [ { "name": "google_inbound_links", "value": 5432 } ], "authors": [ { "username": "dchancogne", "influencerId": "770cf5c54492344ad5e45„791ae5d52" }, { "username": ”gstathis", "influencerId": "0001e86f73cc3975a29e6a98a41a4280" } ] } Modeling a site -
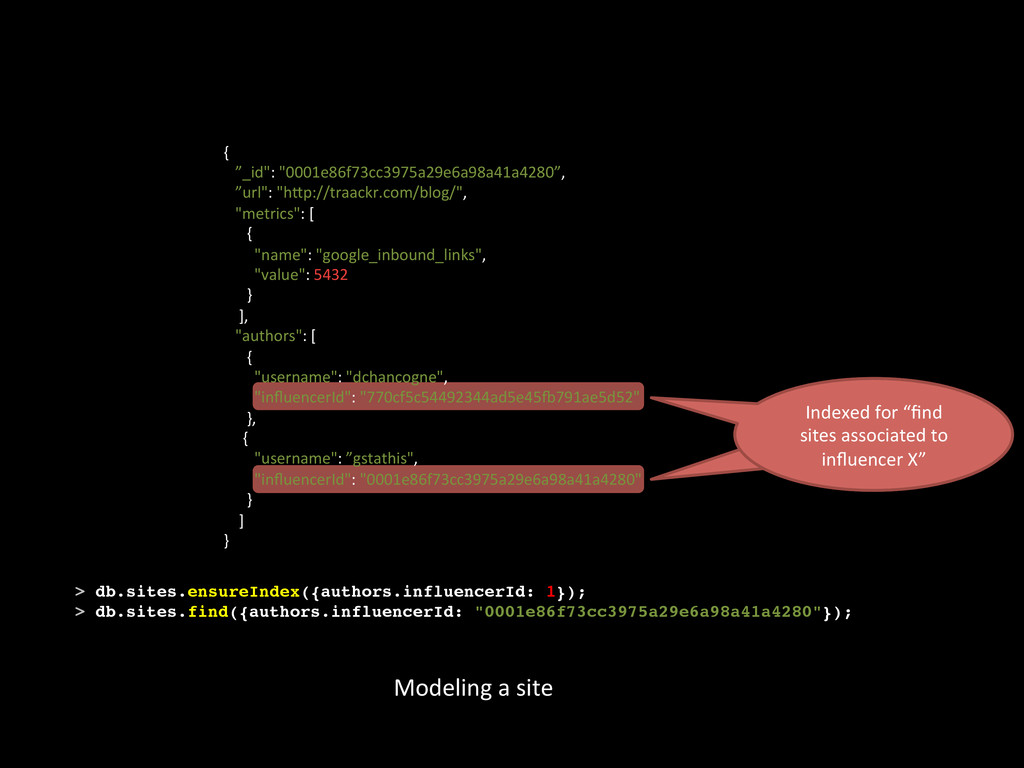
Modeling a site Indexed for “find sites associated
to influencer X” > db.sites.ensureIndex({authors.influencerId: 1});! > db.sites.find({authors.influencerId: "0001e86f73cc3975a29e6a98a41a4280"});! { ”_id": "0001e86f73cc3975a29e6a98a41a4280”, ”url": "hXp://traackr.com/blog/", "metrics": [ { "name": "google_inbound_links", "value": 5432 } ], "authors": [ { "username": "dchancogne", "influencerId": "770cf5c54492344ad5e45„791ae5d52" }, { "username": ”gstathis", "influencerId": "0001e86f73cc3975a29e6a98a41a4280" } ] } -
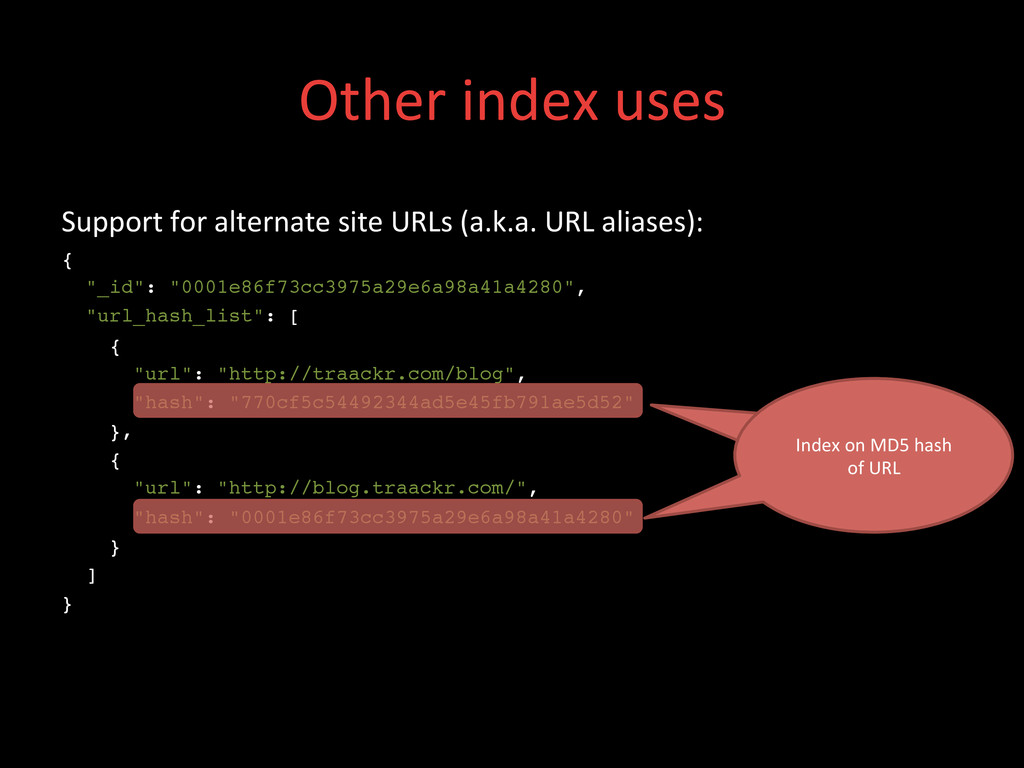
Other index uses Support for alternate site URLs (a.k.a.
URL aliases): {! "_id": "0001e86f73cc3975a29e6a98a41a4280",! "url_hash_list": [! {! "url": "http://traackr.com/blog",! "hash": "770cf5c54492344ad5e45fb791ae5d52"! },! {! "url": "http://blog.traackr.com/",! "hash": "0001e86f73cc3975a29e6a98a41a4280"! }! ]! }! Indexed for “find sites associated to influencer X” Index on MD5 hash of URL -
Other Benefits • Ad hoc queries and reports became
easier to write with JavaScript: no need for a Java developer to write map reduce code to extract the data in a usable form like it was needed with Hbase. -
Ad hoc report example // File Name: retweetTotal.js! //
Purpose: report the count of twitter URLs for which we have! // computed the the number of total retweets! print( "NUMBER OF TWITTER URLS where retweetTotal IS SET:" );! print( db.sites.find( { platformName: "twitter.com", ! retweetTotal: { $exists: true } } ).count() );! ! • Easy to execute JS report script remotely: ! > mongo <hostname>:<port>/traackr --quiet retweetTotal.js! ! • Run as a cron job, pipe the output to a file and email it out • Also, more complex MR-‐based reports are easily accessible to someone with some JavaScript knowledge -
Other Benefits (cont.) • Ad hoc queries and reports
became easier to write with JavaScript: no need for a Java developer to write map reduce code to extract the data in a usable form like it was needed with Hbase. • Simpler backups: Hbase mostly relied on HDFS redundancy; intra-‐ cluster replica>on is available but experimental and a lot more involved to setup. -
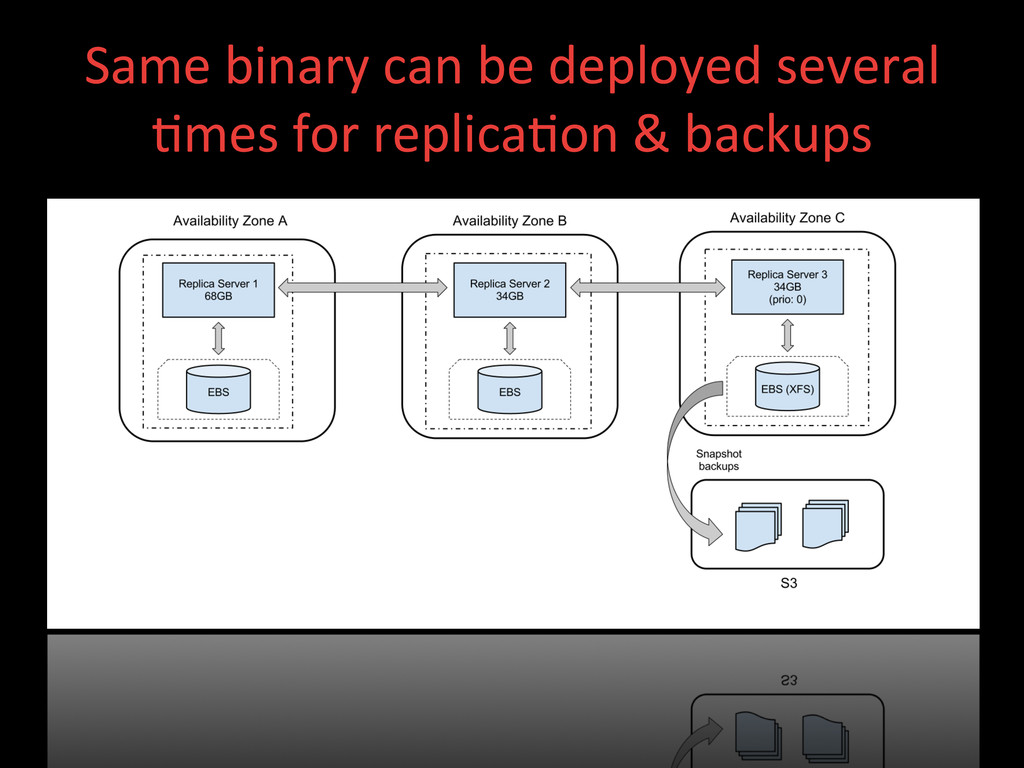
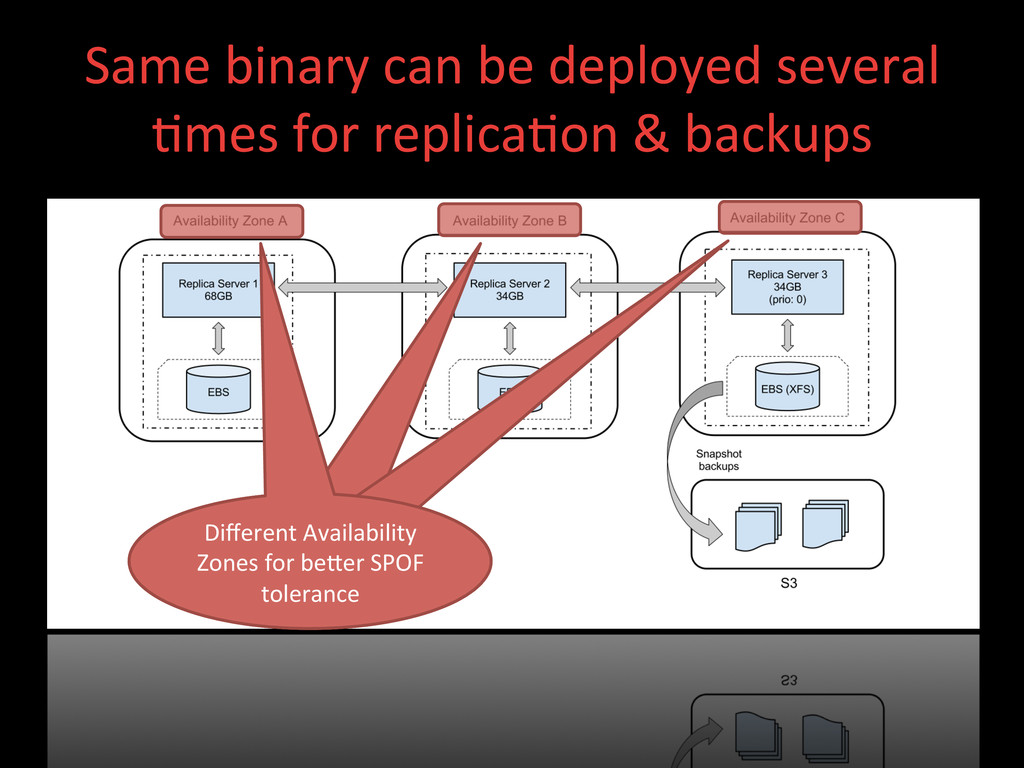
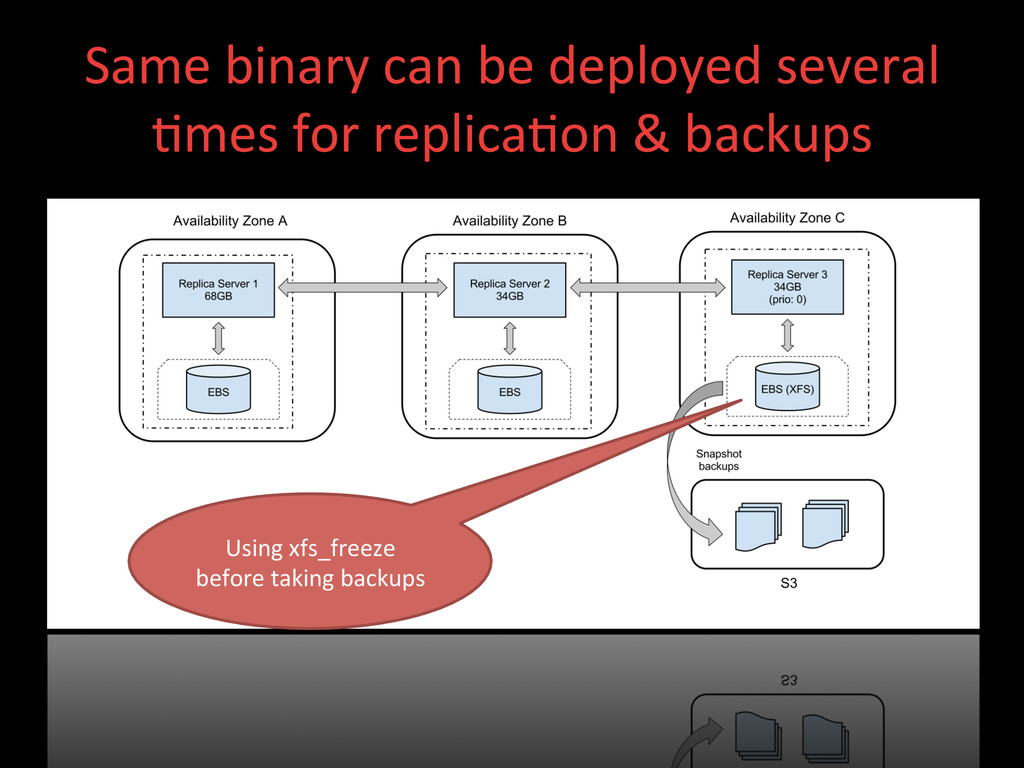
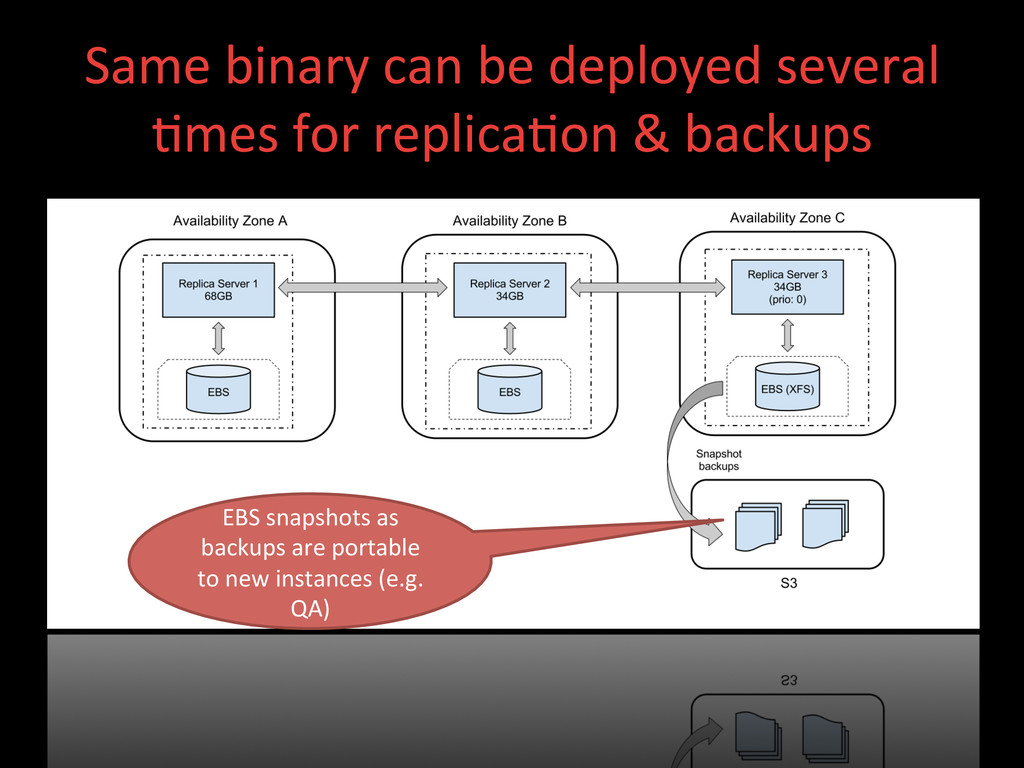
Same binary can be deployed several >mes for replica>on
& backups Different Availability Zones for beXer SPOF tolerance -
Same binary can be deployed several >mes for replica>on
& backups priority 0 for backup server so that it never gets elected as primary -
Same binary can be deployed several >mes for replica>on
& backups Using xfs_freeze before taking backups -
Same binary can be deployed several >mes for replica>on
& backups EBS snapshots as backups are portable to new instances (e.g. QA) -
Other Benefits (cont.) • Ad hoc queries and reports
became easier to write with JavaScript: no need for a Java developer to write map reduce code to extract the data in a usable form like it was needed with Hbase. • Simpler backups: Hbase mostly relied on HDFS redundancy; intra-‐ cluster replica>on is available but experimental and a lot more involved to setup. • Great documenta>on • Great adop>on and community -
Mongo cursors for batch scoring • Mongo is fast
enough for our data size to be able to serially score the DB faster than the MapReduce jobs did in parallel. • When we grow larger, MapReduce is s>ll available as an op>on -
Addi>onal takeaways • Fearless refactoring • Ease of
use and administra>on cannot be overstated for a small startup
 gstathis
 mikanichinose
 fj_yoshimura_kosuke
 torounit
 atalie2m
 bitkey
 kworkdev
 amarelo_n24
 tkito
 yappli_developers
 oracle4engineer
 oidfj
 ykimi
 csswizardry
 holman
 inesmontani
 427marketing
 ryanjones
 codingconduct
 aarron
 aleyda
 tapps
 mkilby
 stephaniewalter