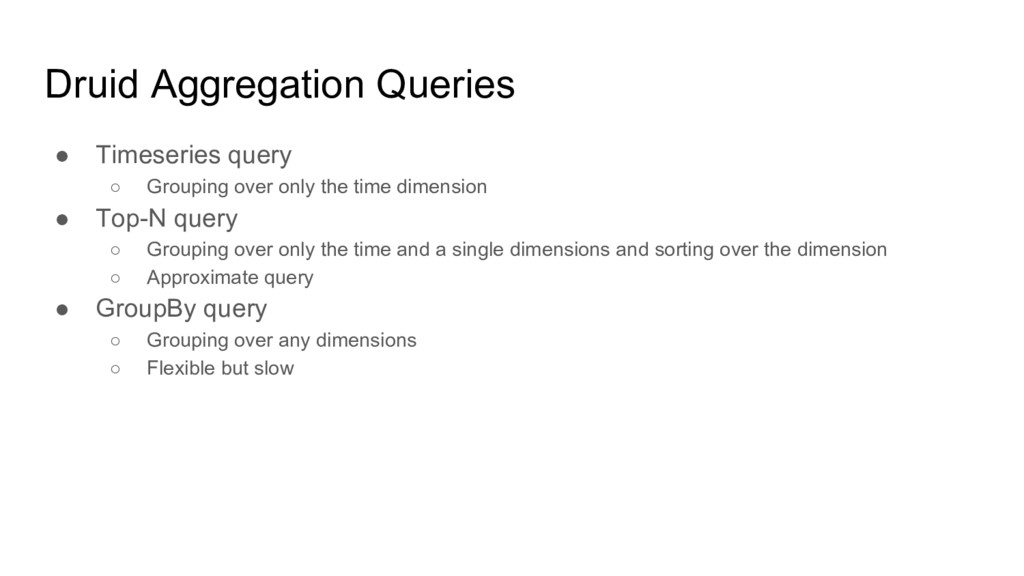
the time dimension • Top-N query ◦ Grouping over only the time and a single dimensions and sorting over the dimension ◦ Approximate query • GroupBy query ◦ Grouping over any dimensions ◦ Flexible but slow
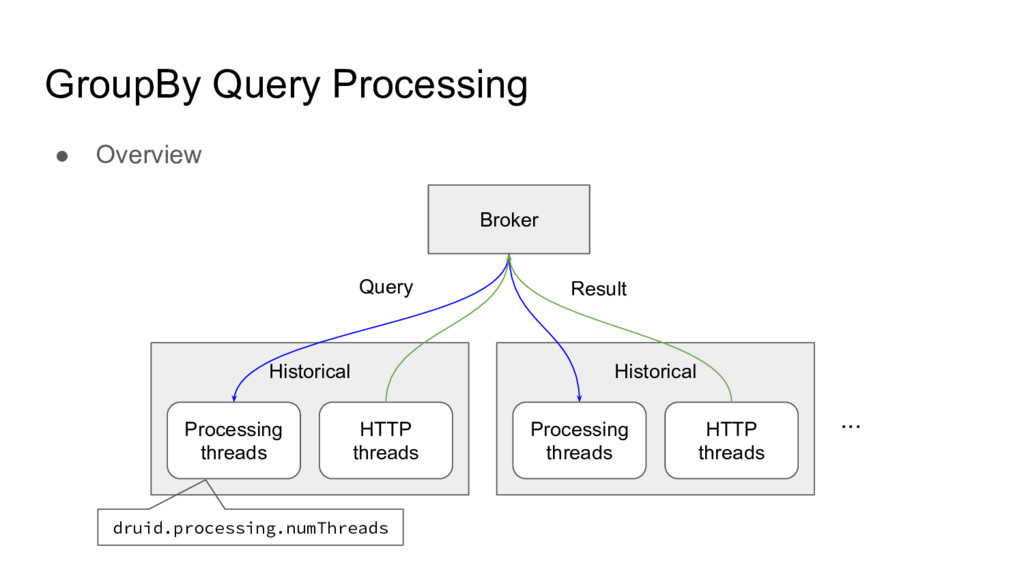
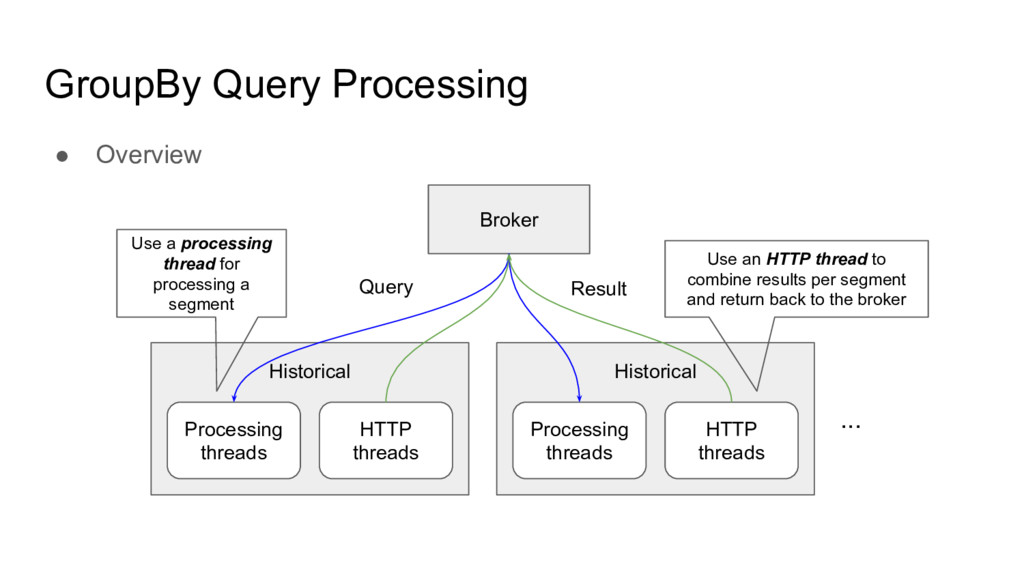
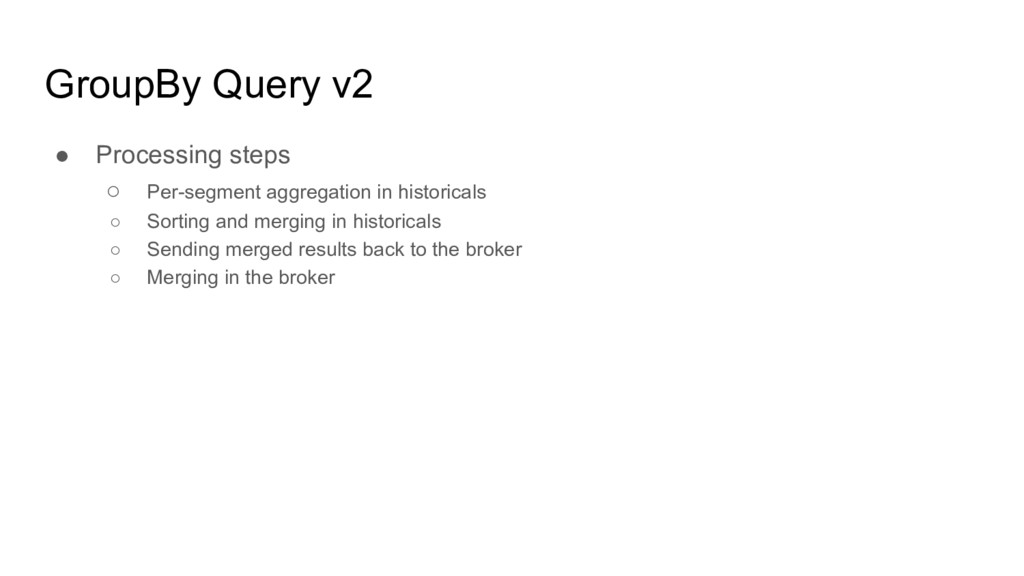
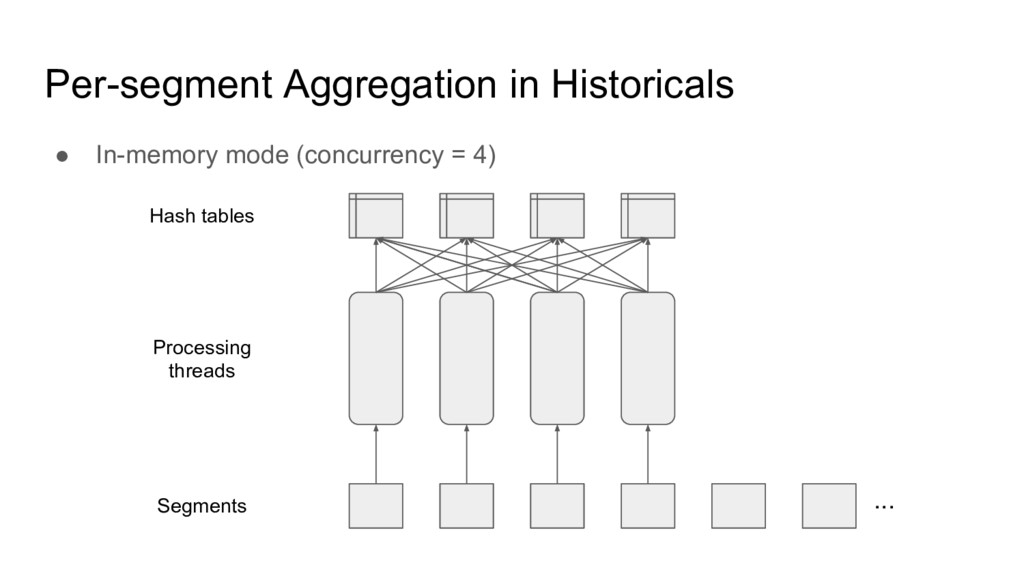
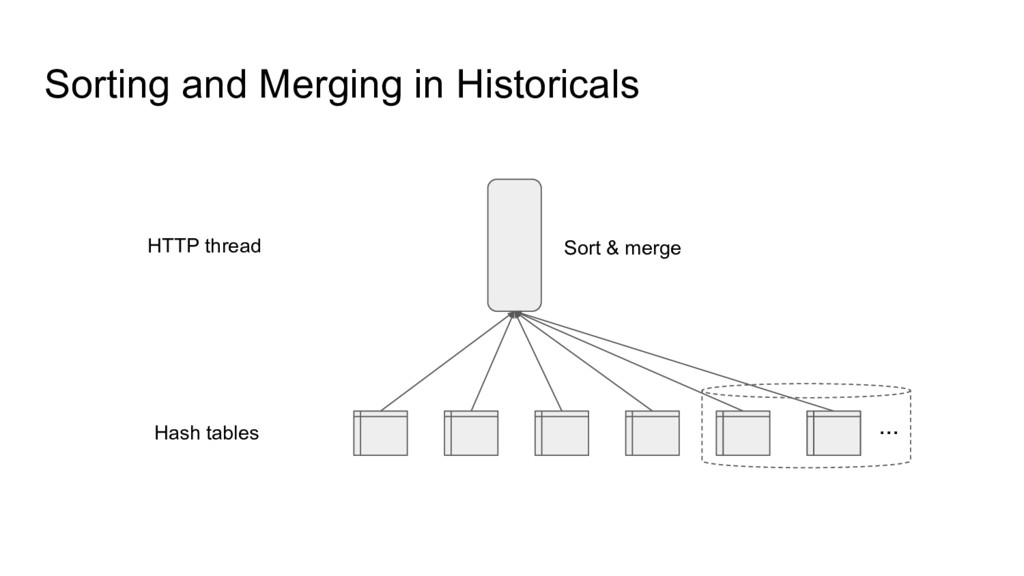
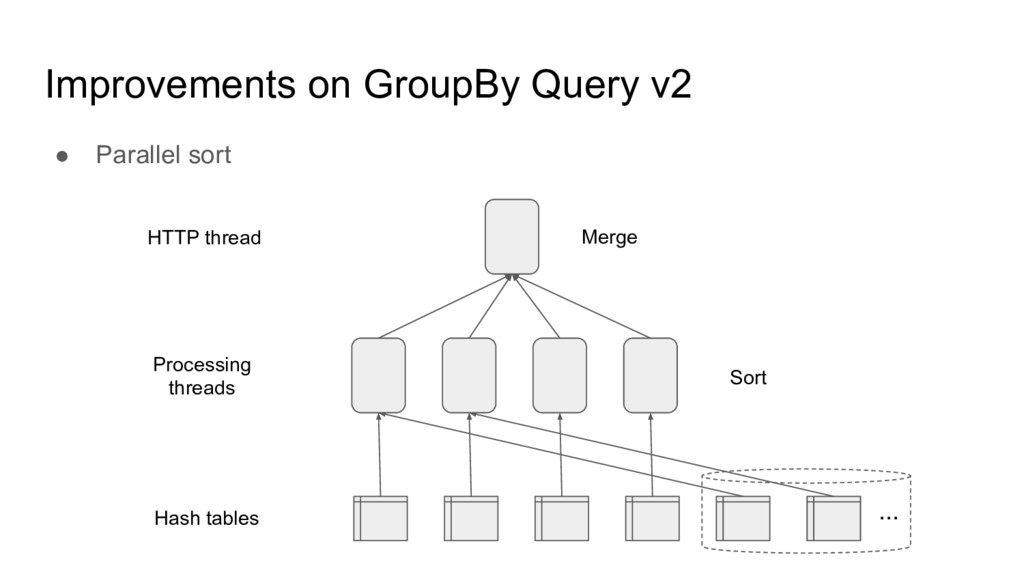
Historical Processing threads HTTP threads Historical ... Query Result Use a processing thread for processing a segment Use an HTTP thread to combine results per segment and return back to the broker
v2 ▪ Default strategy since 0.10.0 (added in 0.9.2) ▪ Hash aggregation using a fully off-heap map for per-segment result ▪ Sort-merge aggregation for merging per-segment results ▪ Better performance and memory management than v1 ◦ GroupBy v1 ▪ Legacy ▪ Hash aggregation using a map which is partially on-heap and partially off-heap for per-segment result ▪ Druid's indexing mechanism for merging per-segment results
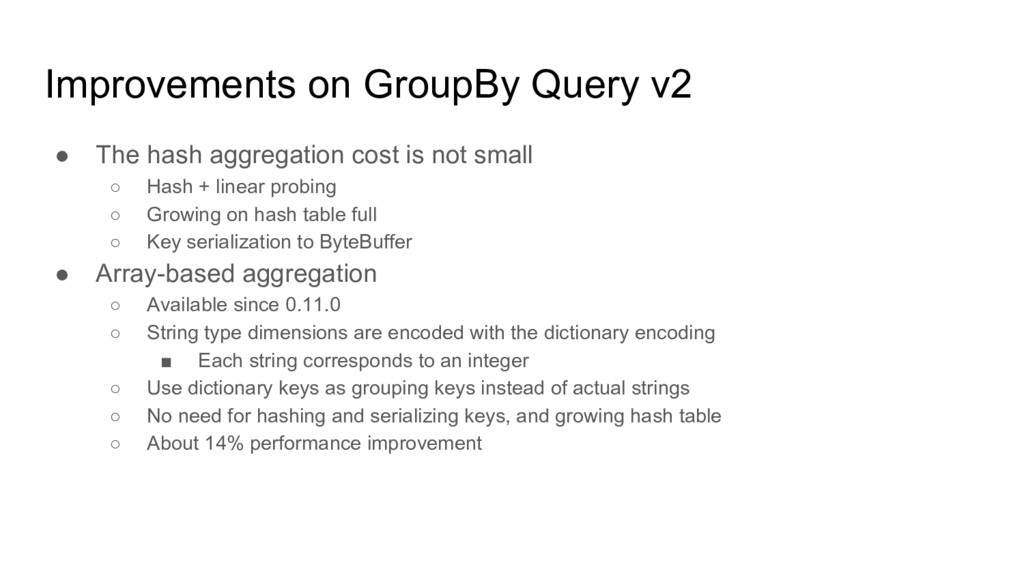
is not small ◦ Hash + linear probing ◦ Growing on hash table full ◦ Key serialization to ByteBuffer • Array-based aggregation ◦ Available since 0.11.0 ◦ String type dimensions are encoded with the dictionary encoding ▪ Each string corresponds to an integer ◦ Use dictionary keys as grouping keys instead of actual strings ◦ No need for hashing and serializing keys, and growing hash table ◦ About 14% performance improvement
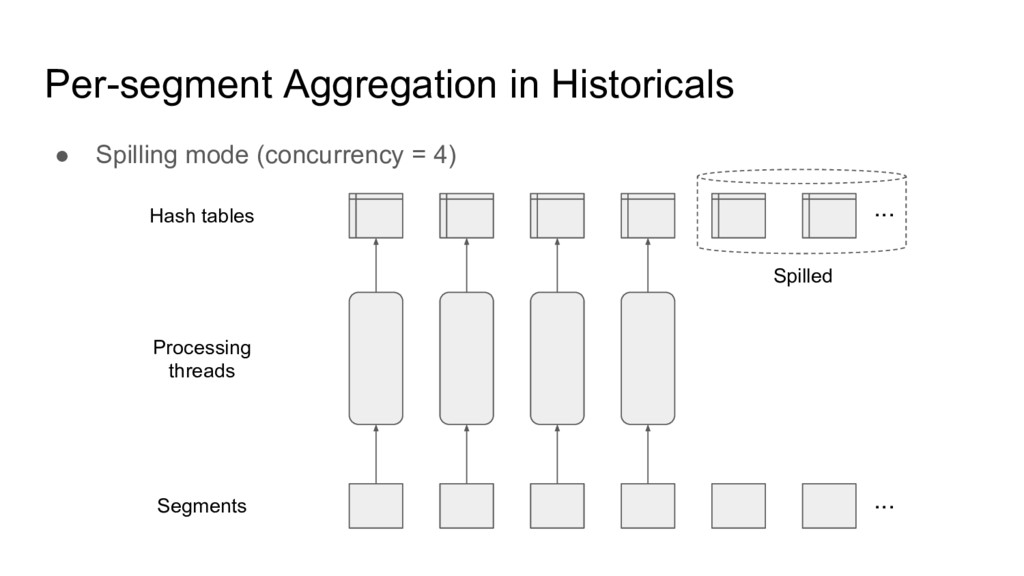
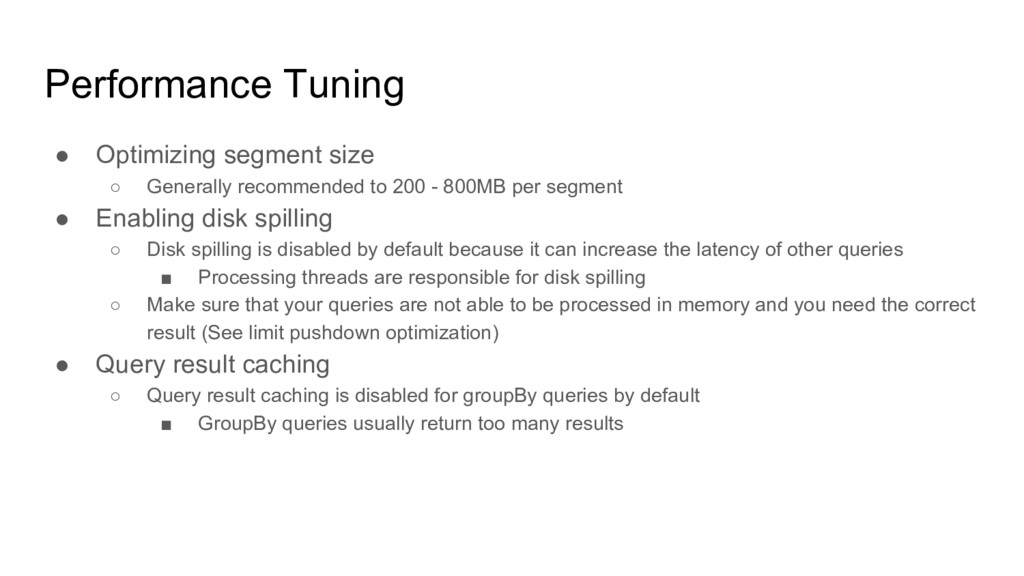
800MB per segment • Enabling disk spilling ◦ Disk spilling is disabled by default because it can increase the latency of other queries ▪ Processing threads are responsible for disk spilling ◦ Make sure that your queries are not able to be processed in memory and you need the correct result (See limit pushdown optimization) • Query result caching ◦ Query result caching is disabled for groupBy queries by default ▪ GroupBy queries usually return too many results Performance Tuning
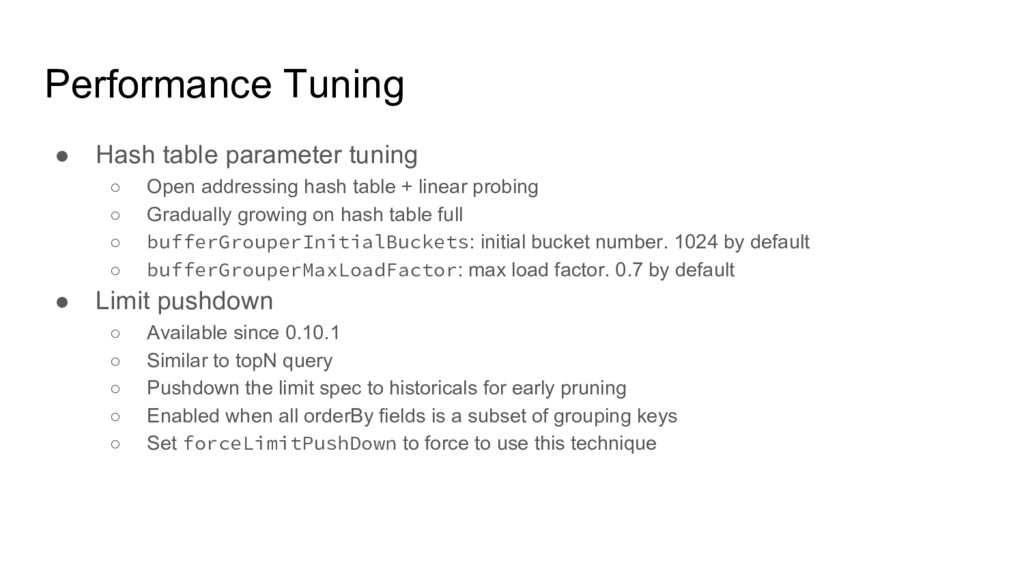
+ linear probing ◦ Gradually growing on hash table full ◦ bufferGrouperInitialBuckets: initial bucket number. 1024 by default ◦ bufferGrouperMaxLoadFactor: max load factor. 0.7 by default • Limit pushdown ◦ Available since 0.10.1 ◦ Similar to topN query ◦ Pushdown the limit spec to historicals for early pruning ◦ Enabled when all orderBy fields is a subset of grouping keys ◦ Set forceLimitPushDown to force to use this technique Performance Tuning
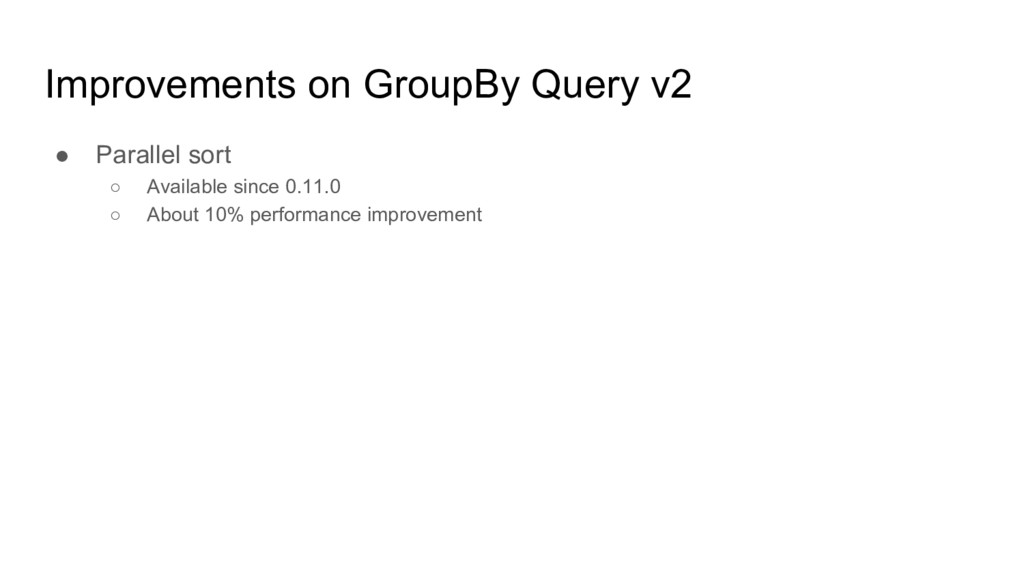
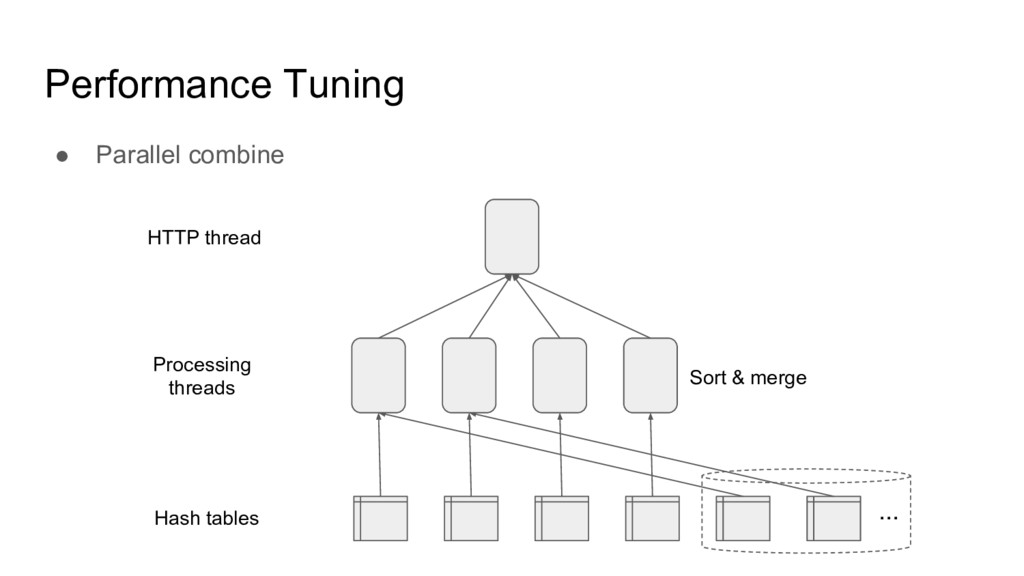
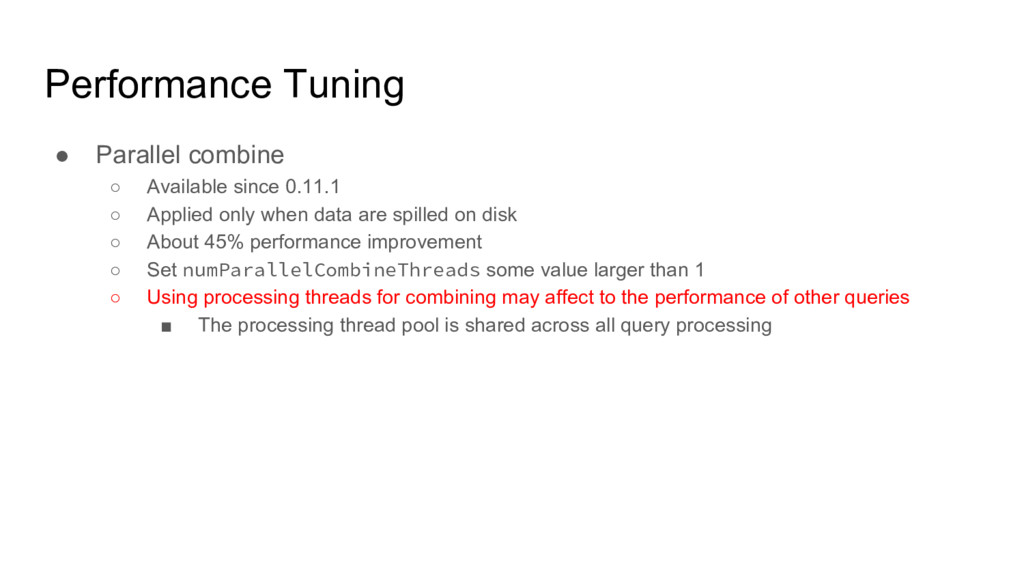
when data are spilled on disk ◦ About 45% performance improvement ◦ Set numParallelCombineThreads some value larger than 1 ◦ Using processing threads for combining may affect to the performance of other queries ▪ The processing thread pool is shared across all query processing Performance Tuning

 SiteGround - Reliable hosting with speed, security, and support you can count on.


 mohab1
 syuchimu
 masakiokuda
 ishikawa_satoru
 kaminashi
 kairim0
 genda
 persolserverworks
 kworkdev
 teamlab
 iktakahiro
 ivry_presentationmaterials
 katiecoart
 bethany
 keathley
 mfonobong
 lemiorhan
 tessaabrams
 sarafernandez
 techseoconnect
 yeseniaperezcruz
 marcelosomers
 ks91
 swwweet