Upgrade to Pro — share decks privately, control downloads, hide ads and more …

The Importance of Subword Embeddings in Sentenc...

Sponsored · Your Podcast. Everywhere. Effortlessly. Share. Educate. Inspire. Entertain. You do you. We'll handle the rest. →

The Importance of Subword Embeddings in Sentence Pair Modeling

文献紹介 勝田 哲弘

Avatar for katsutan

katsutan

July 24, 2018

More Decks by katsutan

Other Decks in Technology

Transcript

  1. 文献紹介: The Importance of Subword Embeddings in Sentence Pair Modeling

    Lan, Wuwei and Xu, Wei, Proceedings of the 2018 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies (NAACL-HLT) 2018/07/24 自然言語処理 修士1年 勝田 哲弘
  2. Abstract • Sentence pair modeling(換言、類似度、推論等) ◦ NLPタスクの中でも重要になっている • 様々な方法で文の意味を構築している ◦

    翻訳や言語モデルでのsubwordの有用性はよく知られている ◦ semantics, similarities等の影響は調査されていない • 提案するsubword modelsで事前訓練なしでstate-of-the-art を達成 2
  3. Introduction • 事前訓練された単語埋め込みを使用することによって、これら のタスクで最良の性能を達成した ◦ semantic similarity (Agirre et al.,

    2015) ◦ paraphrase identification (Dolan et al., 2004; Xu et al., 2015) ◦ natural language inference (Bowman et al., 2015), etc. • out-of-vocabularyの割合がしばしば20%を超えるソーシャル メディアドメインではカバレッジが悪い(Baldwin et al., 2013). 3
  4. Introduction • 文対ベクトル表現のためのsubword単位の有効性を調べた。 ◦ sister and sista, teach and teaches

    ◦ ware and war :誤る可能性がある • 以下の調査を行った。 ◦ subword unit ◦ composition function ◦ datasets of different characteristics 4
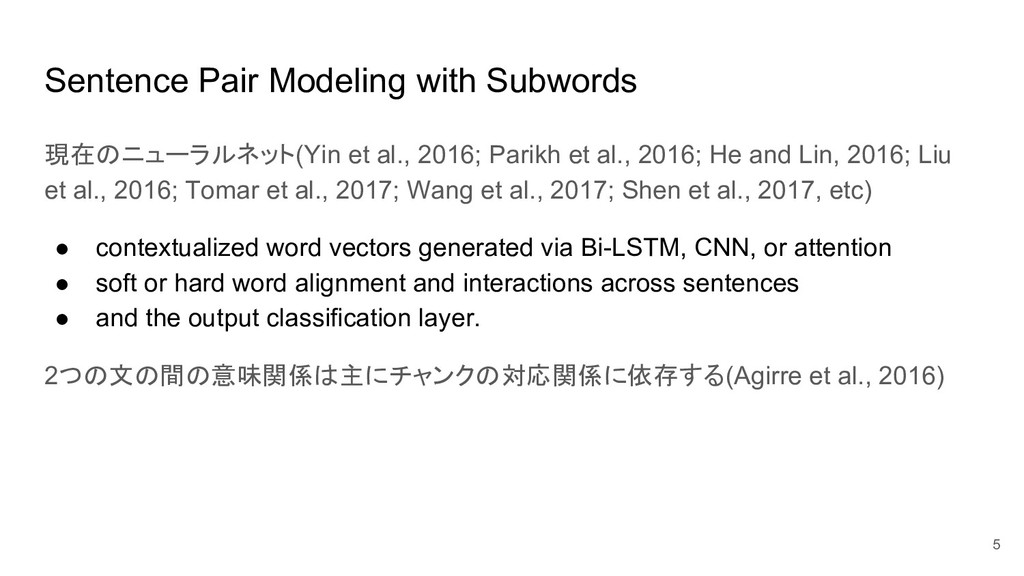
  5. Sentence Pair Modeling with Subwords 現在のニューラルネット(Yin et al., 2016; Parikh

    et al., 2016; He and Lin, 2016; Liu et al., 2016; Tomar et al., 2017; Wang et al., 2017; Shen et al., 2017, etc) • contextualized word vectors generated via Bi-LSTM, CNN, or attention • soft or hard word alignment and interactions across sentences • and the output classification layer. 2つの文の間の意味関係は主にチャンクの対応関係に依存する(Agirre et al., 2016) 5
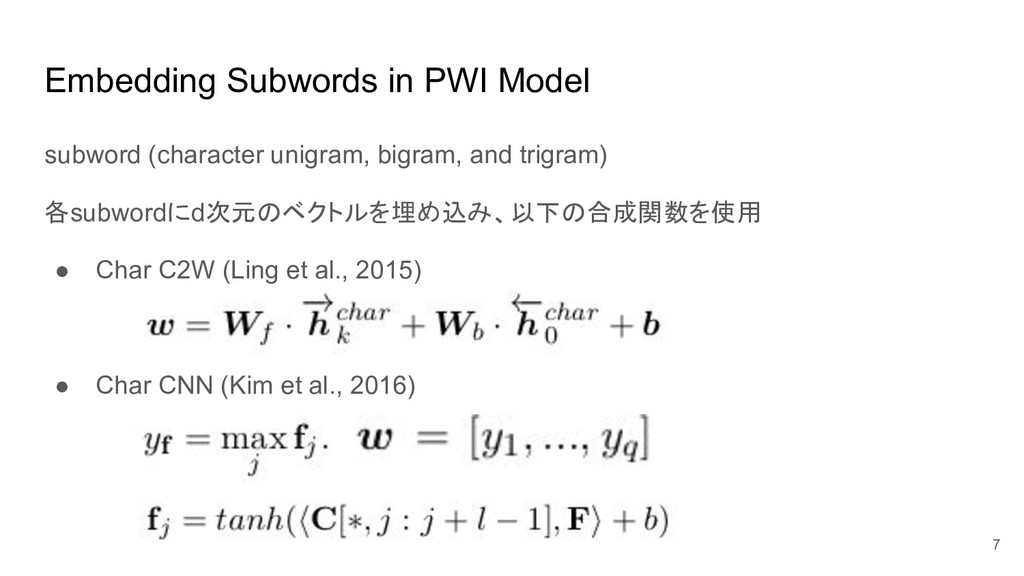
  6. Embedding Subwords in PWI Model 7 subword (character unigram, bigram,

    and trigram) 各subwordにd次元のベクトルを埋め込み、以下の合成関数を使用 • Char C2W (Ling et al., 2015) • Char CNN (Kim et al., 2016)
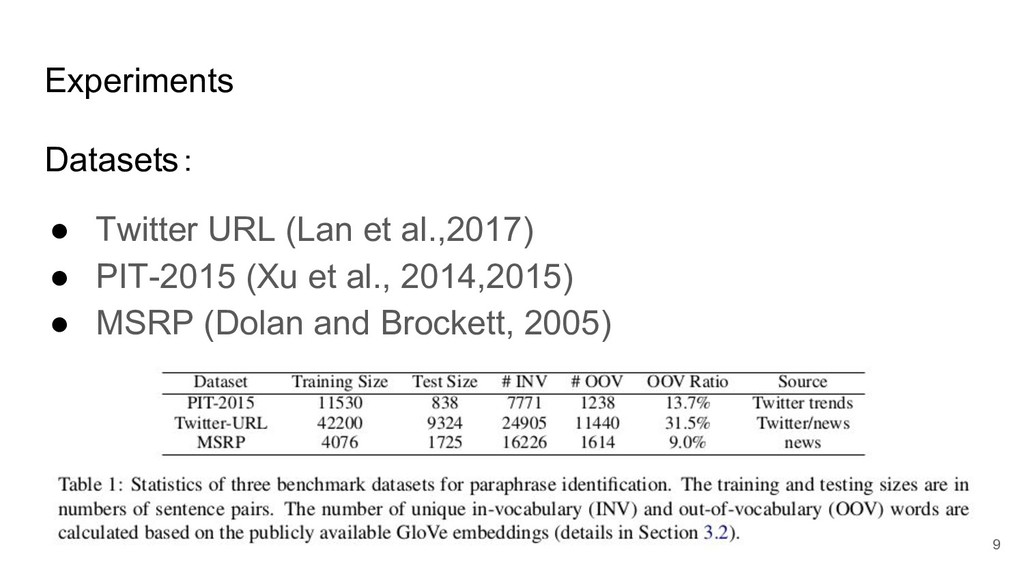
  7. Experiments Datasets: • Twitter URL (Lan et al.,2017) • PIT-2015

    (Xu et al., 2014,2015) • MSRP (Dolan and Brockett, 2005) 9
  8. Settings • フレームワーク ◦ PyTorch ◦ setups in (He and

    Lin, 2016) and (Lan et al., 2017) • Embedding ◦ 300-dimensional GloVe ◦ 27 billion words from Twitter (vocabulary size of 1.2 million words) ◦ without pretraining : random samples [0.05, 0.05] • 学習データ ◦ MSRP 840 billion words (vocabulary size of 2.2 million words) 10
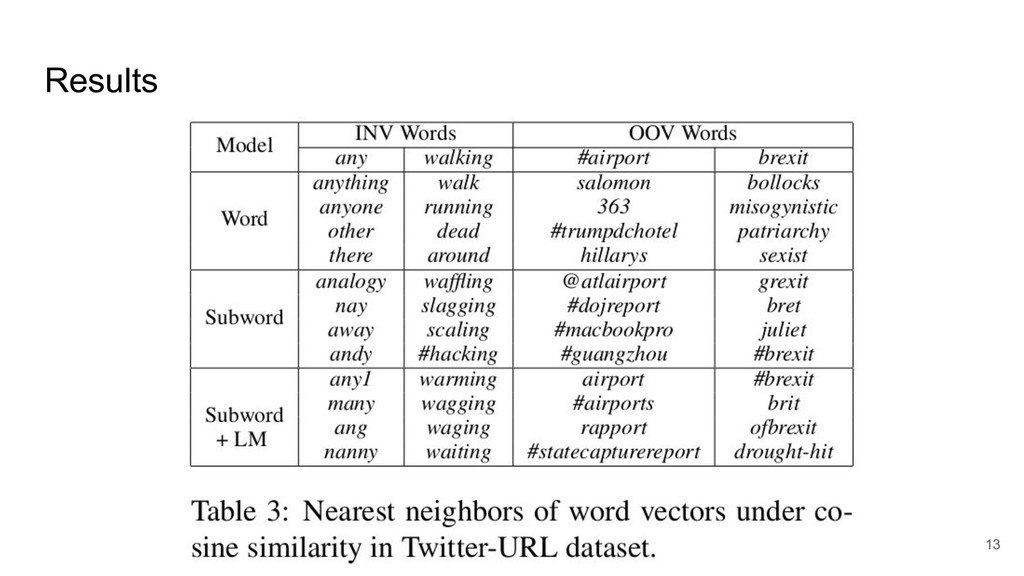
  9. Results • ランダムでも全体的に高い精度を出している。 ◦ n-gramの重複が意味の類似性を積極的に示すため • pretraining and fine-tuningが最終的に精度を上げる •

    Subword Modelで非常に競争力のある結果を達成することが できた • subwordはOOVにとって重要であり、言語モデルはより意味 的で構文的な互換性を保証する 12