Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
Improving Word Embeddings Using Kernel PCA
Search
Sponsored
·
Ship Features Fearlessly
Turn features on and off without deploys. Used by thousands of Ruby developers.
→
katsutan
September 17, 2019
Technology
250
0
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
Improving Word Embeddings Using Kernel PCA
文献紹介
https://www.aclweb.org/anthology/W19-4323
長岡技術科学大学
勝田 哲弘
katsutan
September 17, 2019
More Decks by katsutan
See All by katsutan
What does BERT learn about the structure of language?
katsutan
0
280
Simple and Effective Paraphrastic Similarity from Parallel Translations
katsutan
0
240
Simple task-specific bilingual word embeddings
katsutan
0
250
Retrofitting Contextualized Word Embeddings with Paraphrases
katsutan
0
300
Character Eyes: Seeing Language through Character-Level Taggers
katsutan
1
250
Better Word Embeddings by Disentangling Contextual n-Gram Information
katsutan
0
370
Rotational Unit of Memory: A Novel Representation Unit for RNNs with Scalable Applications
katsutan
0
300
A robust self-learning method for fully unsupervised cross-lingual mappings of word embeddings
katsutan
0
320
DSGAN: Generative Adversarial Training for Distant Supervision Relation Extraction
katsutan
0
310
Other Decks in Technology
See All in Technology
AI導入は済んだ。次は統制を作り替える番だ_AI×開発組織 Summit 2026
techtekt
PRO
0
390
Persisting Massive Data with Rails ~Designing for 60 billion rows, and fighting the bottlenecks~ Railsで挑む大量データ永続化 〜600億件を永続化するための設計とボトルネックとの戦い〜
occhi
0
740
オントロジーって 結局なにもの? AI エージェントに「意味」を渡す知識設計の話
greenmidori
0
240
自作バイナリを動かす「入口」8選
puhitaku
2
1.3k
ソフトウェア ファクトリー - 再現性のあるソフトウェアの工場づくり / Software factory
iktakahiro
7
5.1k
V8のArray.prototype.flatを最大約20倍速くするまでと、巨大OSSへの大規模コミットの道のり
riyaamemiya
0
310
Browser Spec: Testing Hotwire with Ruby
takahashim
1
130
M5Stackで作る BLEマウス GPSログの世界
tomokusaba
PRO
0
440
LLM-as-a-Judgeは本当に信頼できるのか――評価器を評価する話
taka_aki
1
430
フロントエンドカンファレンス関西2026 - 速すぎるUIに、待ち時間を
teamlab
PRO
0
200
CloudWatch Logsのコスト最適化:どこまでAIに任せてどこから人間が承認すべきか
yama3133
0
110
実践!Cloud Run ハンズオン!! / Cloud Run handson
y0hgi
2
300
Featured
See All Featured
Un-Boring Meetings
codingconduct
0
460
Exploring anti-patterns in Rails
aemeredith
4
540
DevOps and Value Stream Thinking: Enabling flow, efficiency and business value
helenjbeal
2
410
How To Speak Unicorn (iThemes Webinar)
marktimemedia
1
600
Winning Ecommerce Organic Search in an AI Era - #searchnstuff2025
aleyda
2
2.2k
Typedesign – Prime Four
hannesfritz
42
3.2k
Designing for Performance
lara
612
70k
We Have a Design System, Now What?
morganepeng
55
8.4k
Skip the Path - Find Your Career Trail
mkilby
1
260
Keith and Marios Guide to Fast Websites
keithpitt
413
23k
Fight the Zombie Pattern Library - RWD Summit 2016
marcelosomers
234
18k
Building Experiences: Design Systems, User Experience, and Full Site Editing
marktimemedia
1
630
Transcript
IMPROVING WORD EMBEDDINGS USING KERNEL PCA 文献紹介 長岡技術科学大学 勝田 哲弘
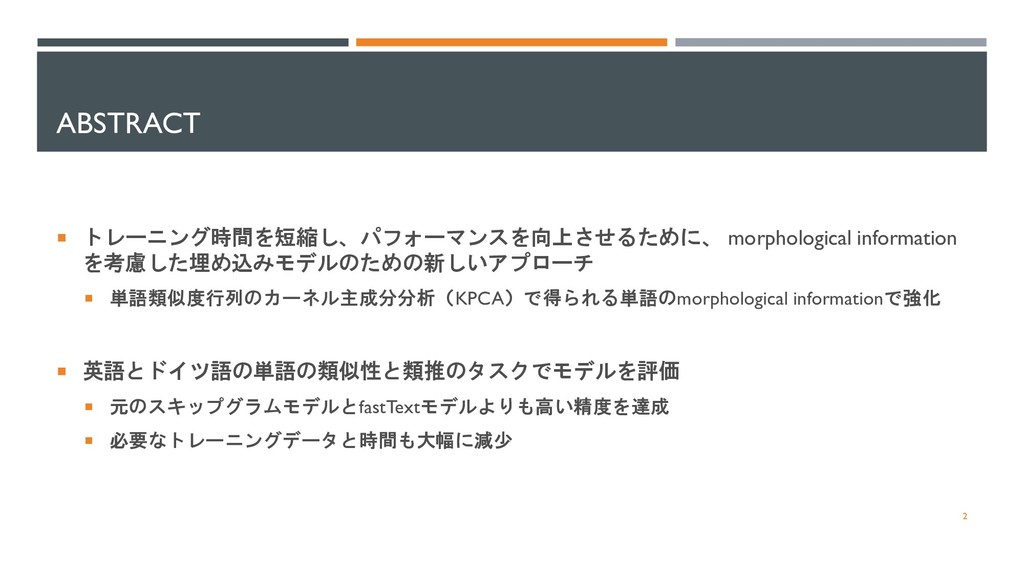
ABSTRACT トレーニング時間を短縮し、パフォーマンスを向上させるために、 morphological information を考慮した埋め込みモデルのための新しいアプローチ 単語類似度行列のカーネル主成分分析(KPCA)で得られる単語のmorphological informationで強化
英語とドイツ語の単語の類似性と類推のタスクでモデルを評価 元のスキップグラムモデルとfastTextモデルよりも高い精度を達成 必要なトレーニングデータと時間も大幅に減少 2
INTRODUCTION Word embeddingでよく用いられる手法 Word2vec-skipgram fastText fastTextはサブワードを考慮することで低頻度語をある程度改善できる
しかし、ニュースなどに出てくる新しい単語などは失敗する場合が多い 語彙が時間の経過で変化するデータセット内でうまく機能するアプローチの 提案 3
KPCA-BASED SKIP-GRAM AND FASTTEXT MODELS 単語類似度行列でKPCAを使用した埋め込み事前学習 語彙内の単語に対して文字列の類似度を計算し類似度行列を生成
単語、サブワード埋め込みをKPCAで初期化 意味的に類似した単語は、 roots, affixes, syllablesなどの一般的な形態素 をしばしば共有する morphologically richな言語で特に役立つ 4
KERNEL PCA ON STRING SIMILARITIES 語彙V内の単語w、文字列の類似度関数S(n-gram similarity)、非線形カーネル関 数K(ガウス)で単語類似度行列を計算
Kの列ベクトルkiはwiの| V |次元表現と見なすことができるため、V次元のwiの 単語の特徴空間表現が得られる PCAによって単語ベクトルを低次元空間に投影 最も高い固有値λ1からλdに対応するd個の固有ベクトルv1からvdを選択 5
MODELS WITH KPCA EMBEDDING 語彙Vを制限して、テキストコーパスの最も頻繁な単語のみを含める Vに含まれない単語snewは、カーネルベクトルを用いて計算 Semanticな情報を考慮するためword2vec、fastTextに組み込む
fastTextではサブワードのベクトル表現も同様に計算して使用 6
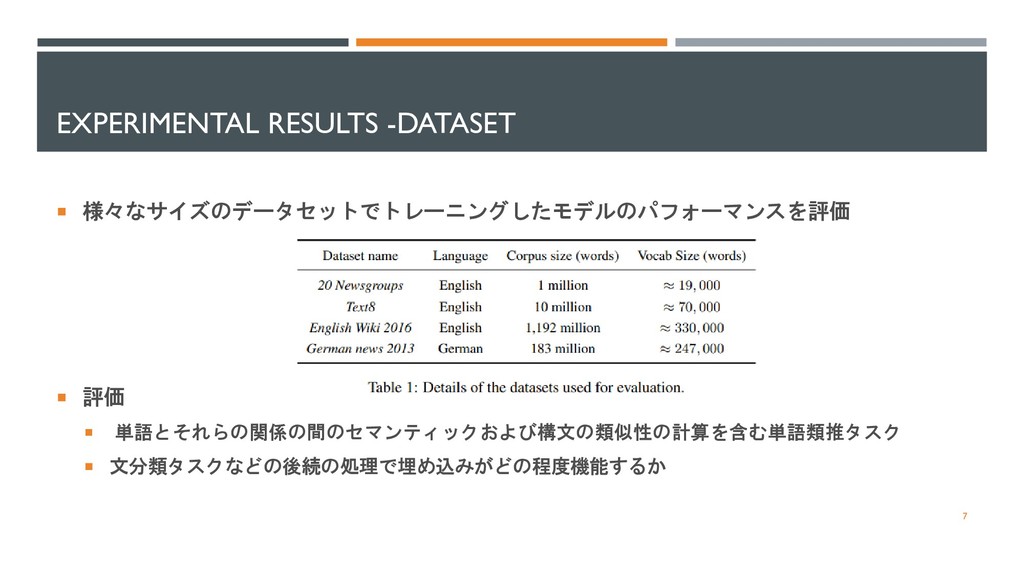
EXPERIMENTAL RESULTS -DATASET 様々なサイズのデータセットでトレーニングしたモデルのパフォーマンスを評価 評価 単語とそれらの関係の間のセマンティックおよび構文の類似性の計算を含む単語類推タスク
文分類タスクなどの後続の処理で埋め込みがどの程度機能するか 7
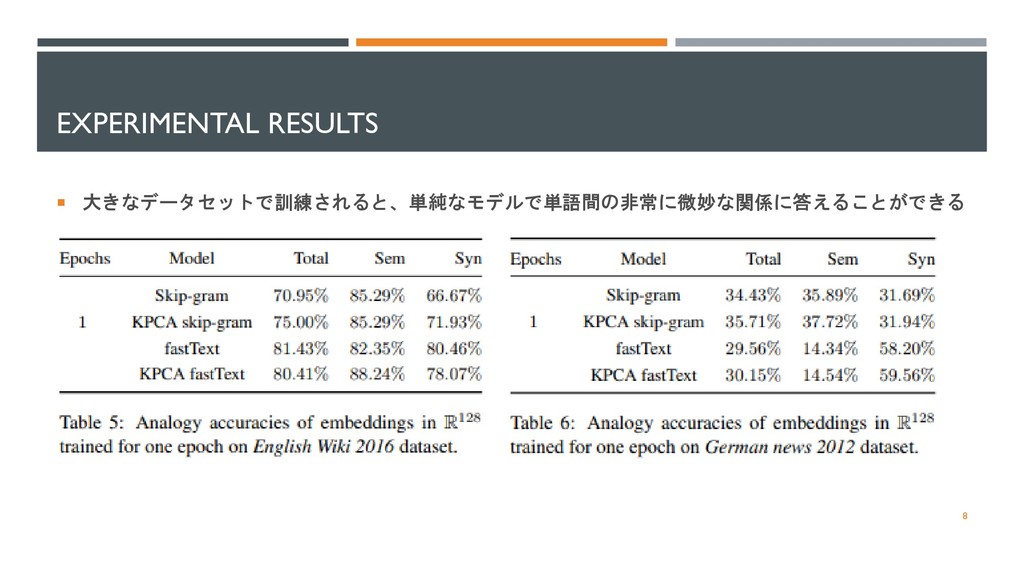
EXPERIMENTAL RESULTS 大きなデータセットで訓練されると、単純なモデルで単語間の非常に微妙な関係に答えることができる 8
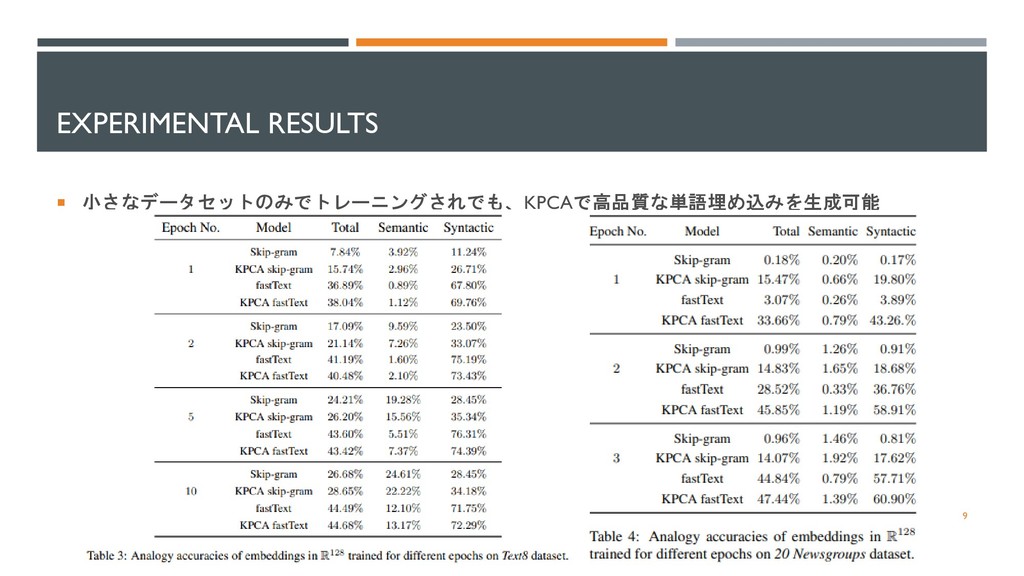
EXPERIMENTAL RESULTS 小さなデータセットのみでトレーニングされでも、KPCAで高品質な単語埋め込みを生成可能 9
EVALUATION OF PERFORMANCE ON DOWNSTREAM APPLICATIONS 埋め込みモデルから取得した埋め込みを使用してCNNを初期化、トレーニング中の埋め込み層を固定 10
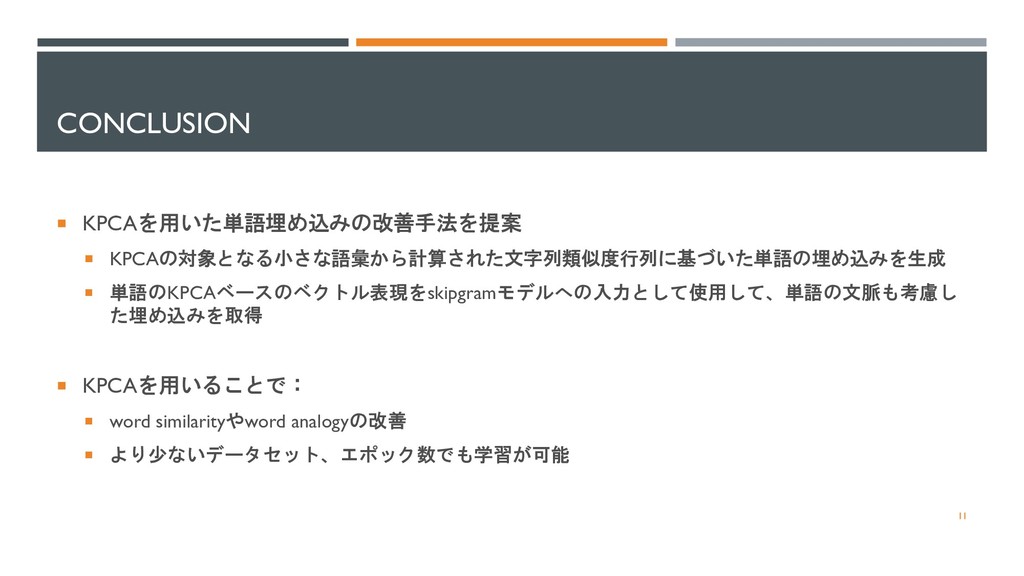
CONCLUSION KPCAを用いた単語埋め込みの改善手法を提案 KPCAの対象となる小さな語彙から計算された文字列類似度行列に基づいた単語の埋め込みを生成 単語のKPCAベースのベクトル表現をskipgramモデルへの入力として使用して、単語の文脈も考慮し た埋め込みを取得 KPCAを用いることで:
word similarityやword analogyの改善 より少ないデータセット、エポック数でも学習が可能 11


 katsutan
 techtekt
 occhi
 greenmidori
 puhitaku
 iktakahiro
 riyaamemiya
 takahashim
 tomokusaba
 taka_aki
 teamlab
 yama3133
 y0hgi
 codingconduct
 aemeredith
 helenjbeal
 marktimemedia
 aleyda
 hannesfritz
 lara
 morganepeng
 mkilby
 keithpitt
 marcelosomers