Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
Simple and Effective Paraphrastic Similarity fr...
Search
katsutan
January 27, 2020
Technology
240
0
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
Simple and Effective Paraphrastic Similarity from Parallel Translations
文献紹介
https://www.aclweb.org/anthology/P19-1453.pdf
長岡技術科学大学
勝田 哲弘
katsutan
January 27, 2020
More Decks by katsutan
See All by katsutan
What does BERT learn about the structure of language?
katsutan
0
280
Simple task-specific bilingual word embeddings
katsutan
0
250
Retrofitting Contextualized Word Embeddings with Paraphrases
katsutan
0
300
Character Eyes: Seeing Language through Character-Level Taggers
katsutan
1
250
Improving Word Embeddings Using Kernel PCA
katsutan
0
250
Better Word Embeddings by Disentangling Contextual n-Gram Information
katsutan
0
370
Rotational Unit of Memory: A Novel Representation Unit for RNNs with Scalable Applications
katsutan
0
300
A robust self-learning method for fully unsupervised cross-lingual mappings of word embeddings
katsutan
0
320
DSGAN: Generative Adversarial Training for Distant Supervision Relation Extraction
katsutan
0
310
Other Decks in Technology
See All in Technology
企業の現実世界をグラフで写し取る
sansantech
PRO
0
240
あなたの知らないAmazon VPC Route Server/Amazon VPC Route Server you don't know about
masakiokuda
2
200
The seven pitfalls of AI (revised version)
ufried
0
180
2026-10-01_MagicPod_QAハーネスエンジニアリングとQA組織の未来像
ynisqa1988
1
290
カンファレンスに参加した後の浮遊感とセルフケア
pauli
0
290
Codex概要
ymiya55
0
180
『GOエコノミー 』(相乗りサービス) におけるスペック駆動開発
mot_techtalk
1
170
OpenClawでAzure DevOpsのWiki更新を自動化する - クラウドAIだけでは届かない場所へ
yutakaosada
0
140
【Findyテック文化祭ワークショップ】新卒エンジニア&採用担当と作る、 なりたい姿と今やるべき一歩
dip_tech
PRO
0
150
Databricksメトリクスビューはじめてのもくもく会
taka_aki
0
150
【データ横丁主催】AI Agentがコンテキストを使って仕事をした後、何が残るのか― 組織の経験を次の判断に引き継ぐ「Agent Memory」
shisyu_gaku
2
310
10年欲しかった音楽管理アプリを、AIと一緒に作りはじめた
judau
1
200
Featured
See All Featured
Utilizing Notion as your number one productivity tool
mfonobong
4
610
Ruling the World: When Life Gets Gamed
codingconduct
0
380
Why Our Code Smells
bkeepers
PRO
340
58k
HTML-Aware ERB: The Path to Reactive Rendering @ RubyCon 2026, Rimini, Italy
marcoroth
5
750
Google's AI Overviews - The New Search
badams
0
1.6k
A brief & incomplete history of UX Design for the World Wide Web: 1989–2019
jct
2
520
Faster Mobile Websites
deanohume
310
32k
Deep Space Network (abreviated)
tonyrice
0
350
The B2B funnel & how to create a winning content strategy
katarinadahlin
PRO
1
550
ラッコキーワード サービス紹介資料
rakko
1
5.1M
Designing for Timeless Needs
cassininazir
1
510
Rails Girls Zürich Keynote
gr2m
96
14k
Transcript
Simple and Effective Paraphrastic Similarity from Parallel Translations 長岡技術科学大学 自然言語処理研究室
勝田 哲弘 文献紹介 Proceedings of the 57th Annual Meeting of the Association for Computational Linguistics, pages 4602–4608 Florence, Italy, July 28 - August 2, 2019
Abstract ➢言い換え文の埋め込みを学習するためのモデル ➢時間のかかる言い換えコーパスの作成ステップを削除 ➢bitextから直接学習 ➢結果 ➢このモデルは最先端の複雑なモデルよりも優れている ➢高速であり、クロスリンガルタスクに適用できる 2
Introduction ➢これまでの文の類似性 ➢言い換えフレーズのデータセットで学習 ➢大きなバイリンガルコーパスから言い換えデータセット を誘導する ➢本論文 ➢文の埋め込みをbitextで直接学習 ➢高速に文章をエンコードするシンプルなモデル 3
Learning Sentence Embeddings ➢Training ⚫ トレーニングデータ ⚫ それぞれソース言語とターゲット言語の一連の並列文 ペア (
, ) ⚫ ネガティブサンプリング ⚫ の翻訳ではないターゲット文′ をランダムに選択 ⚫ ( , )を( , ′ )よりもマージンδ近づける 4 目的関数 (; ): 各言語のパラメーターを持つ センテンスエンコーダー
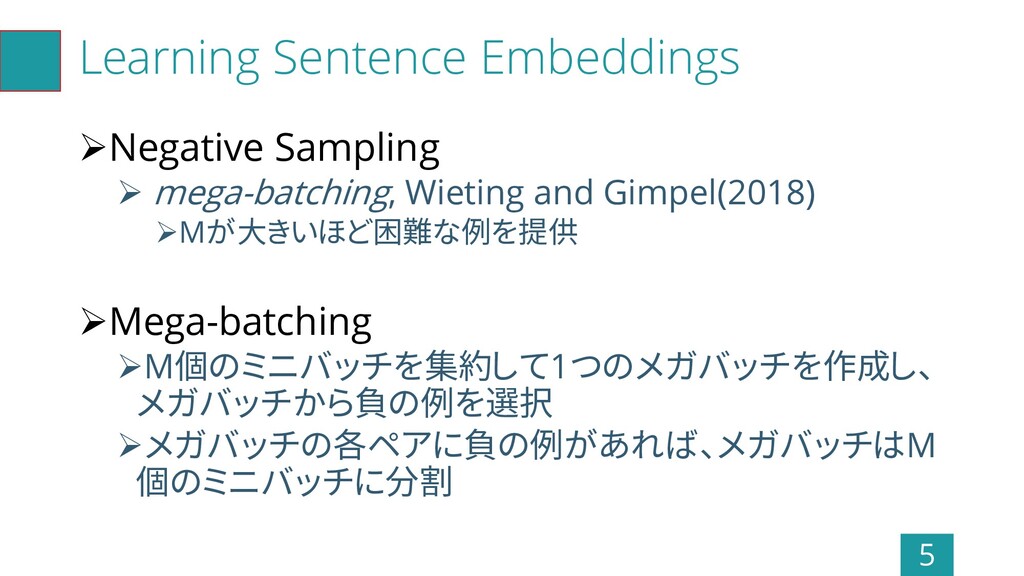
Learning Sentence Embeddings ➢Negative Sampling ➢ mega-batching, Wieting and Gimpel(2018)
➢Mが大きいほど困難な例を提供 ➢Mega-batching ➢M個のミニバッチを集約して1つのメガバッチを作成し、 メガバッチから負の例を選択 ➢メガバッチの各ペアに負の例があれば、メガバッチはM 個のミニバッチに分割 5
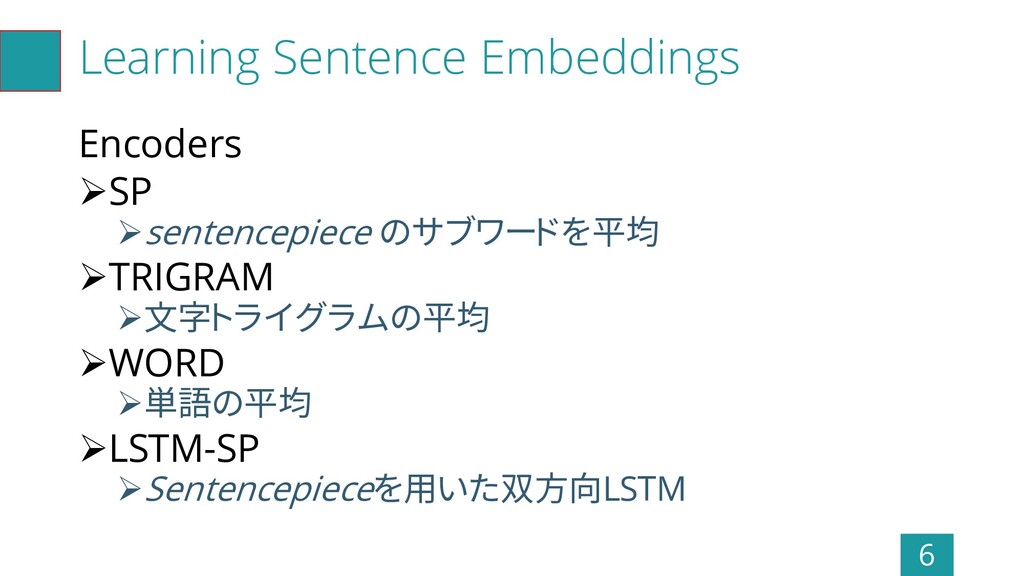
Learning Sentence Embeddings Encoders ➢SP ➢sentencepiece のサブワードを平均 ➢TRIGRAM ➢文字トライグラムの平均 ➢WORD
➢単語の平均 ➢LSTM-SP ➢Sentencepieceを用いた双方向LSTM 6
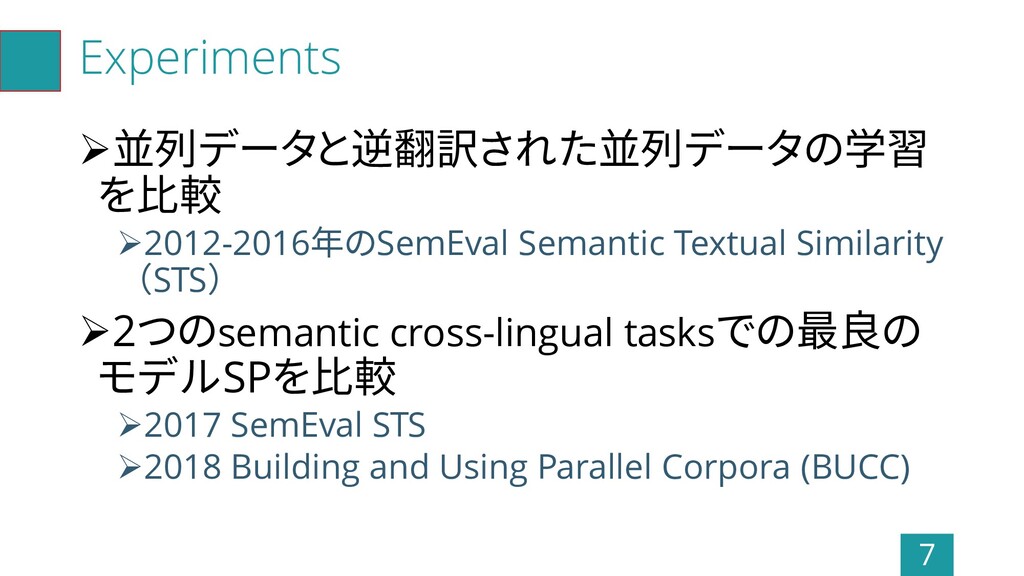
Experiments ➢並列データと逆翻訳された並列データの学習 を比較 ➢2012-2016年のSemEval Semantic Textual Similarity (STS) ➢2つのsemantic cross-lingual
tasksでの最良の モデルSPを比較 ➢2017 SemEval STS ➢2018 Building and Using Parallel Corpora (BUCC) 7
Back-Translated Text vs. Parallel Text ➢En-EnはEn-CS(1M) より、 SPを除いて高い相関 ➢同数の英文を用意すれば 同程度の性能
➢En-CS設定でSPは最高の パフォーマンスを発揮
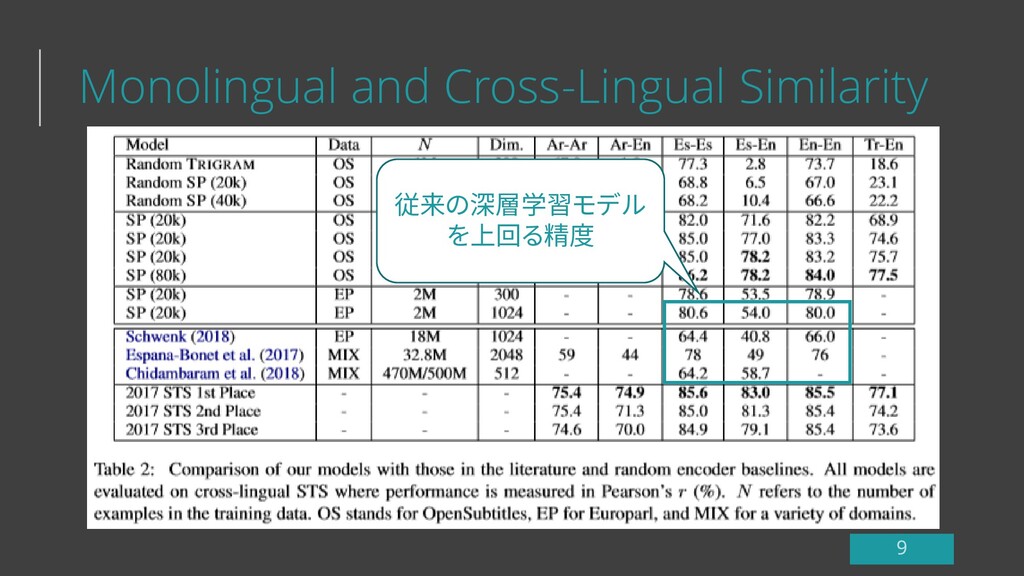
Monolingual and Cross-Lingual Similarity 従来の深層学習モデル を上回る精度
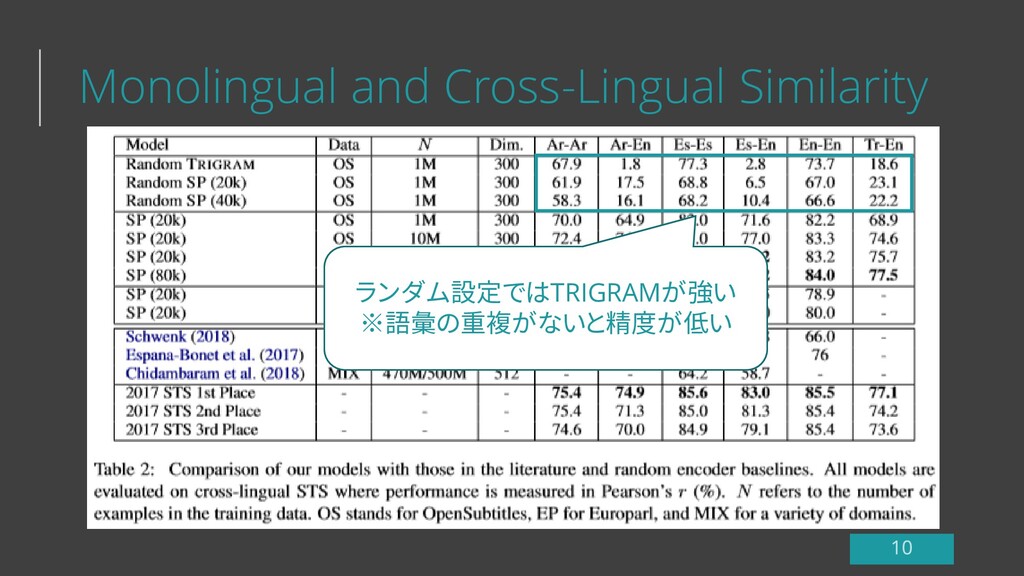
Monolingual and Cross-Lingual Similarity ランダム設定ではTRIGRAMが強い ※語彙の重複がないと精度が低い
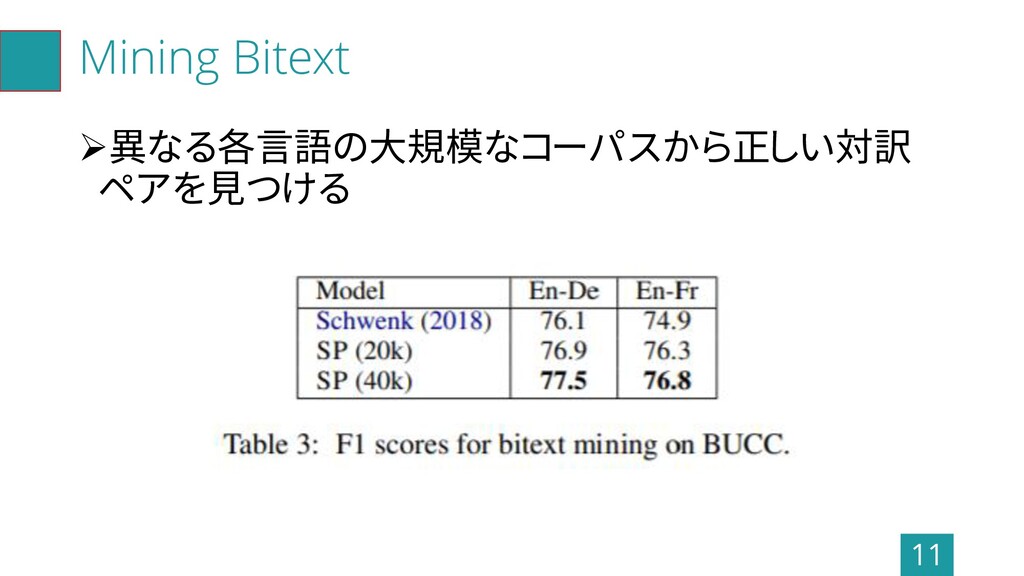
Mining Bitext ➢異なる各言語の大規模なコーパスから正しい対訳 ペアを見つける 11
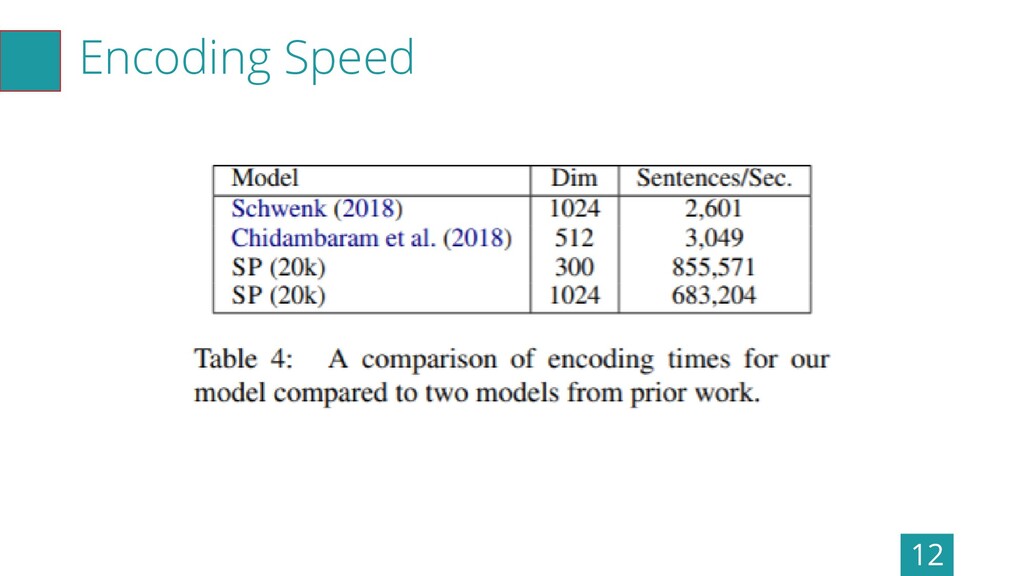
Encoding Speed 12
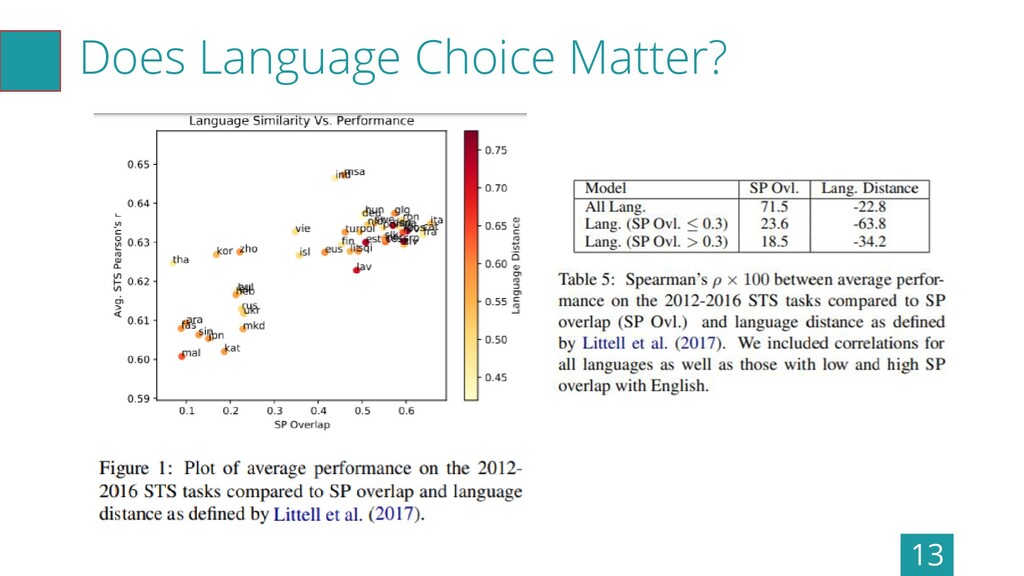
Does Language Choice Matter? 13
Conclusion ➢bitextを直接使用することにより精度の高い文の埋 め込みを作成 ➢ピボットや逆翻訳などを使用する必要がない ➢言語横断的表現が生成可能 ➢比較可能な従来の方法と比べて圧倒的に高速 14


 katsutan
 sansantech
 masakiokuda
 ufried
 ynisqa1988
 pauli
 ymiya55
 mot_techtalk
 yutakaosada
 dip_tech
 taka_aki
 shisyu_gaku
 judau
 mfonobong
 codingconduct
 bkeepers
 marcoroth
 badams
 jct
 deanohume
 tonyrice
 katarinadahlin
 rakko
 cassininazir
 gr2m