Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
[Journal Club]MultiMAE: Multi-modal Multi-task ...
Search
Semantic Machine Intelligence Lab., Keio Univ.
PRO
October 31, 2022
Technology
470
0
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
[Journal Club]MultiMAE: Multi-modal Multi-task Masked Autoencoders (ECCV22)
Semantic Machine Intelligence Lab., Keio Univ.
PRO
October 31, 2022
Transcript
18 slides
MultiMAE: Multi-modal Multi-task Masked Autoencoders 慶應義塾大学 杉浦孔明研究室 飯岡 雄偉 Roman
Bachmann, David Mizrahi, Andrei Atanov, Amir Zamir, Institute of Technology Lausanne (EPFL) Bachmann, R., Mizrahi, D., Atanov, A., & Zamir, A. (2022). MultiMAE: Multi-modal Multi-task Masked Autoencoders. In ECCV.
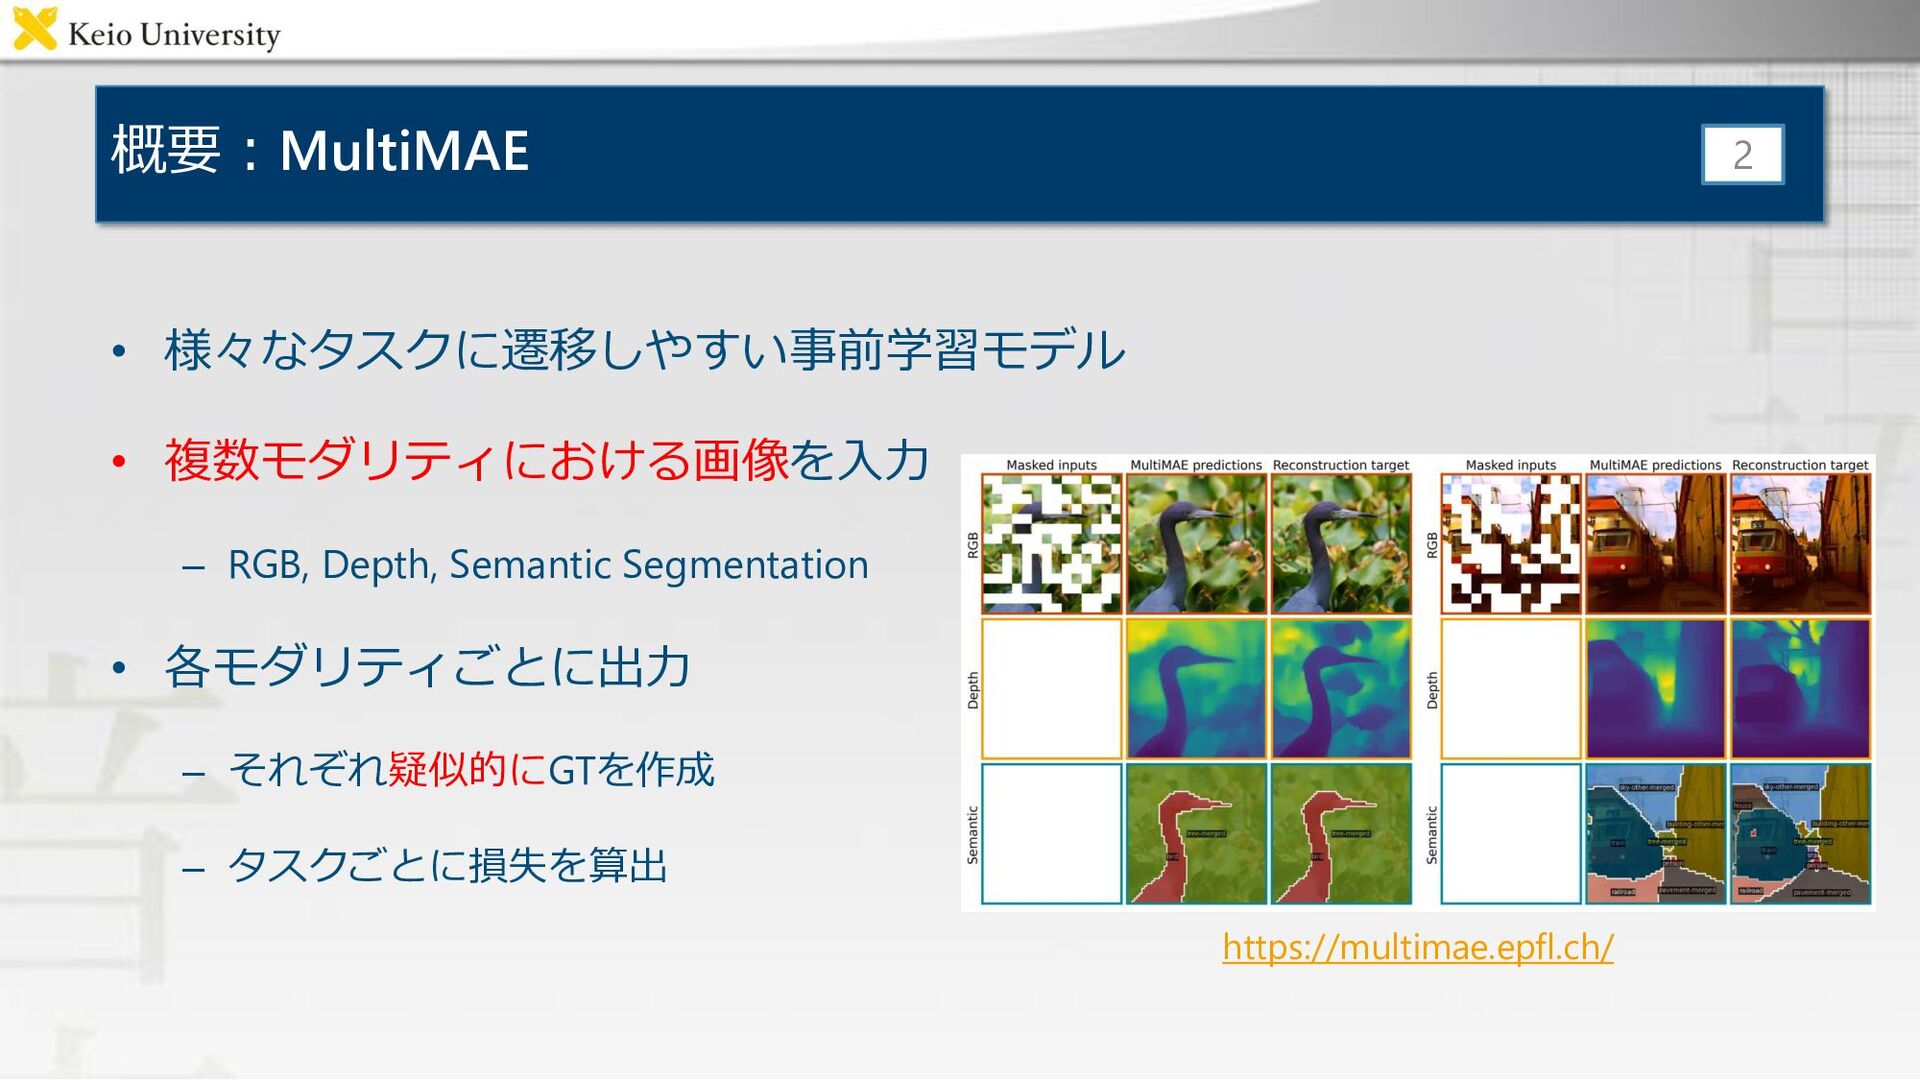
概要:MultiMAE 2 • 様々なタスクに遷移しやすい事前学習モデル • 複数モダリティにおける画像を入力 – RGB, Depth, Semantic
Segmentation • 各モダリティごとに出力 – それぞれ疑似的にGTを作成 – タスクごとに損失を算出 https://multimae.epfl.ch/
研究背景:扱いやすい画像特徴量の事前学習モデル • BERT[Jacob+, NAACL19] – 文をマスクして,予測 – 言語特徴量の事前学習モデルとしてbreak through •
Masked Autoencoders(MAE)[He +, CVPR22] – 画像をマスクして,予測 – RGBの画像のみで学習 -> 実際,Depth等が取れる状況は多いはず • MultiMAE – RGB, Depth, Semantic Segmentationにおける画像で学習 – より多様なタスクへの効率的な転移を目指す 3
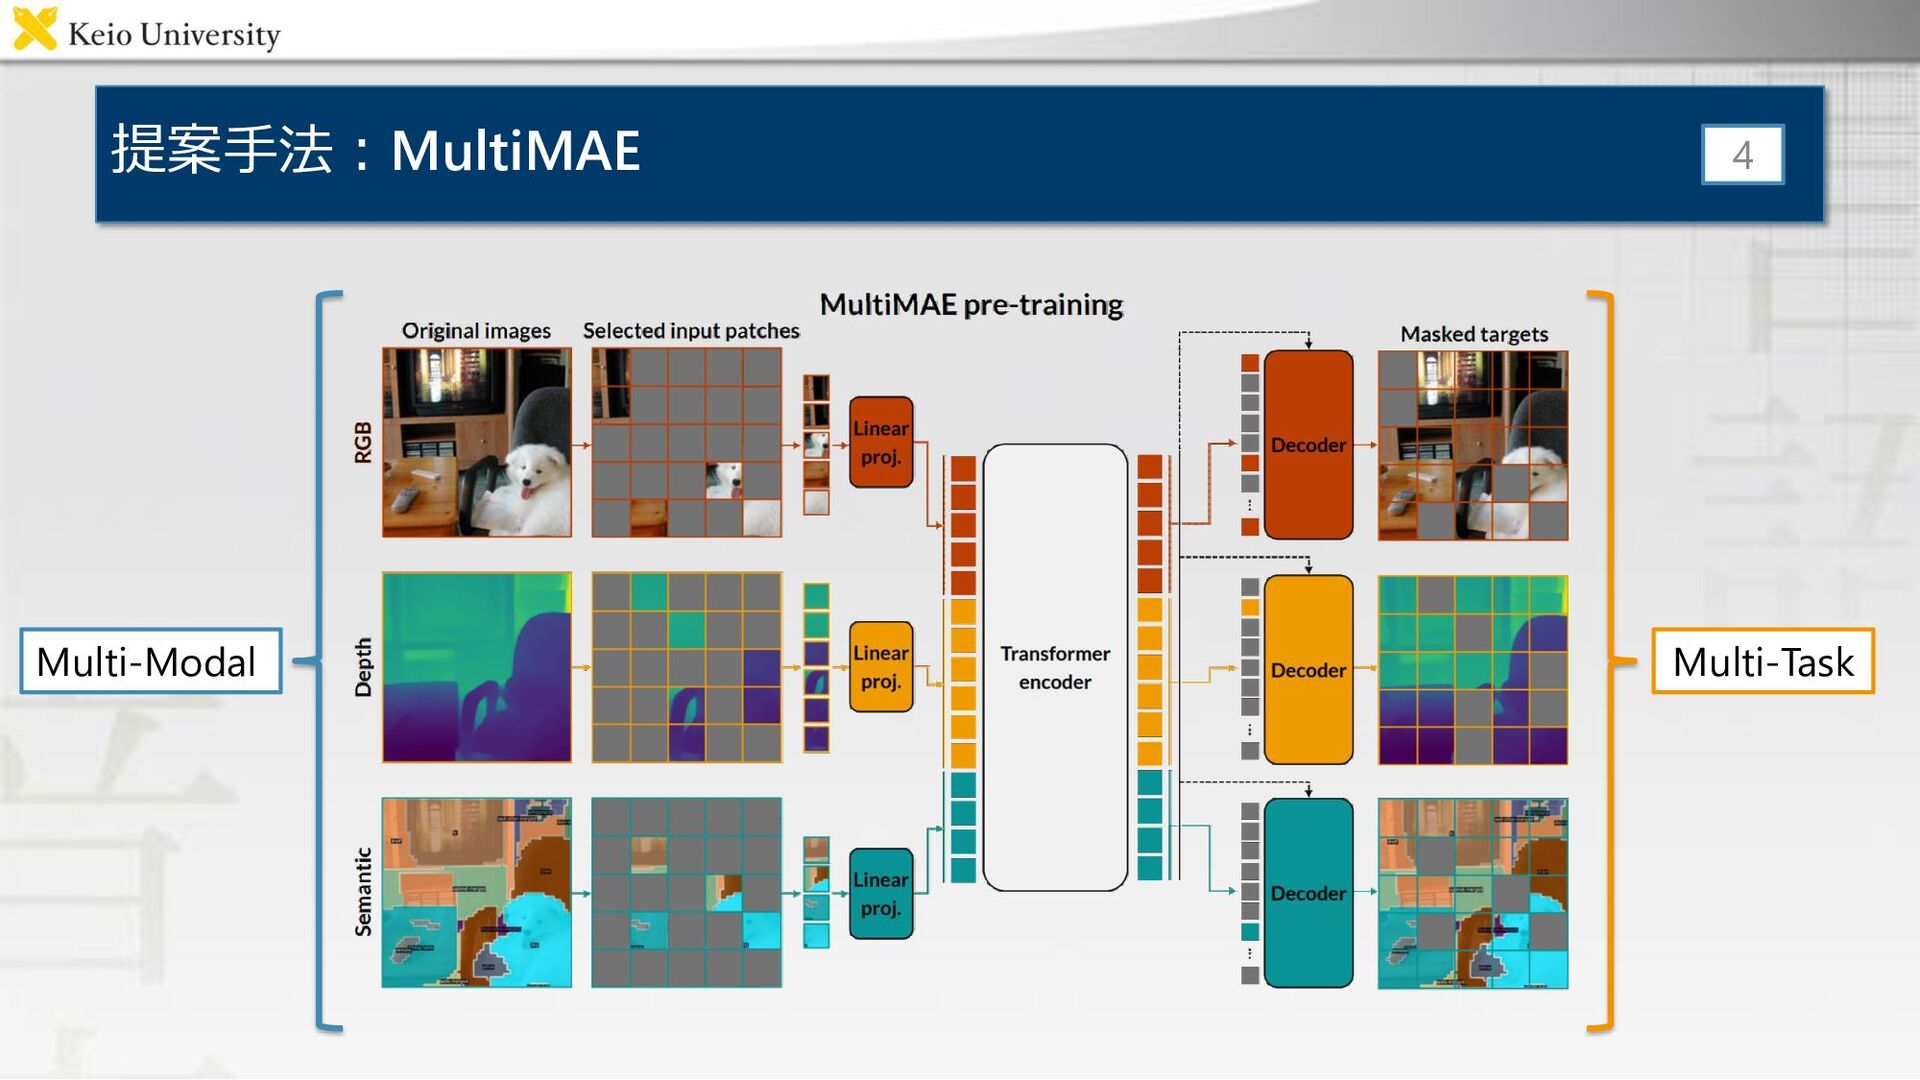
提案手法:MultiMAE 4 Multi-Modal Multi-Task
構造①:RGB画像から各モダリティの疑似画像を作成 • Depth – Omnidata[Ainaz+, ICCV21] で学習した DPT-Hybrid[Rene, ICCV21] で予測
• Semantic Segmentation – COCO[Tsung, ECCV14] で学習した Mask2Former[Bowen, CVPR22] で予測 5
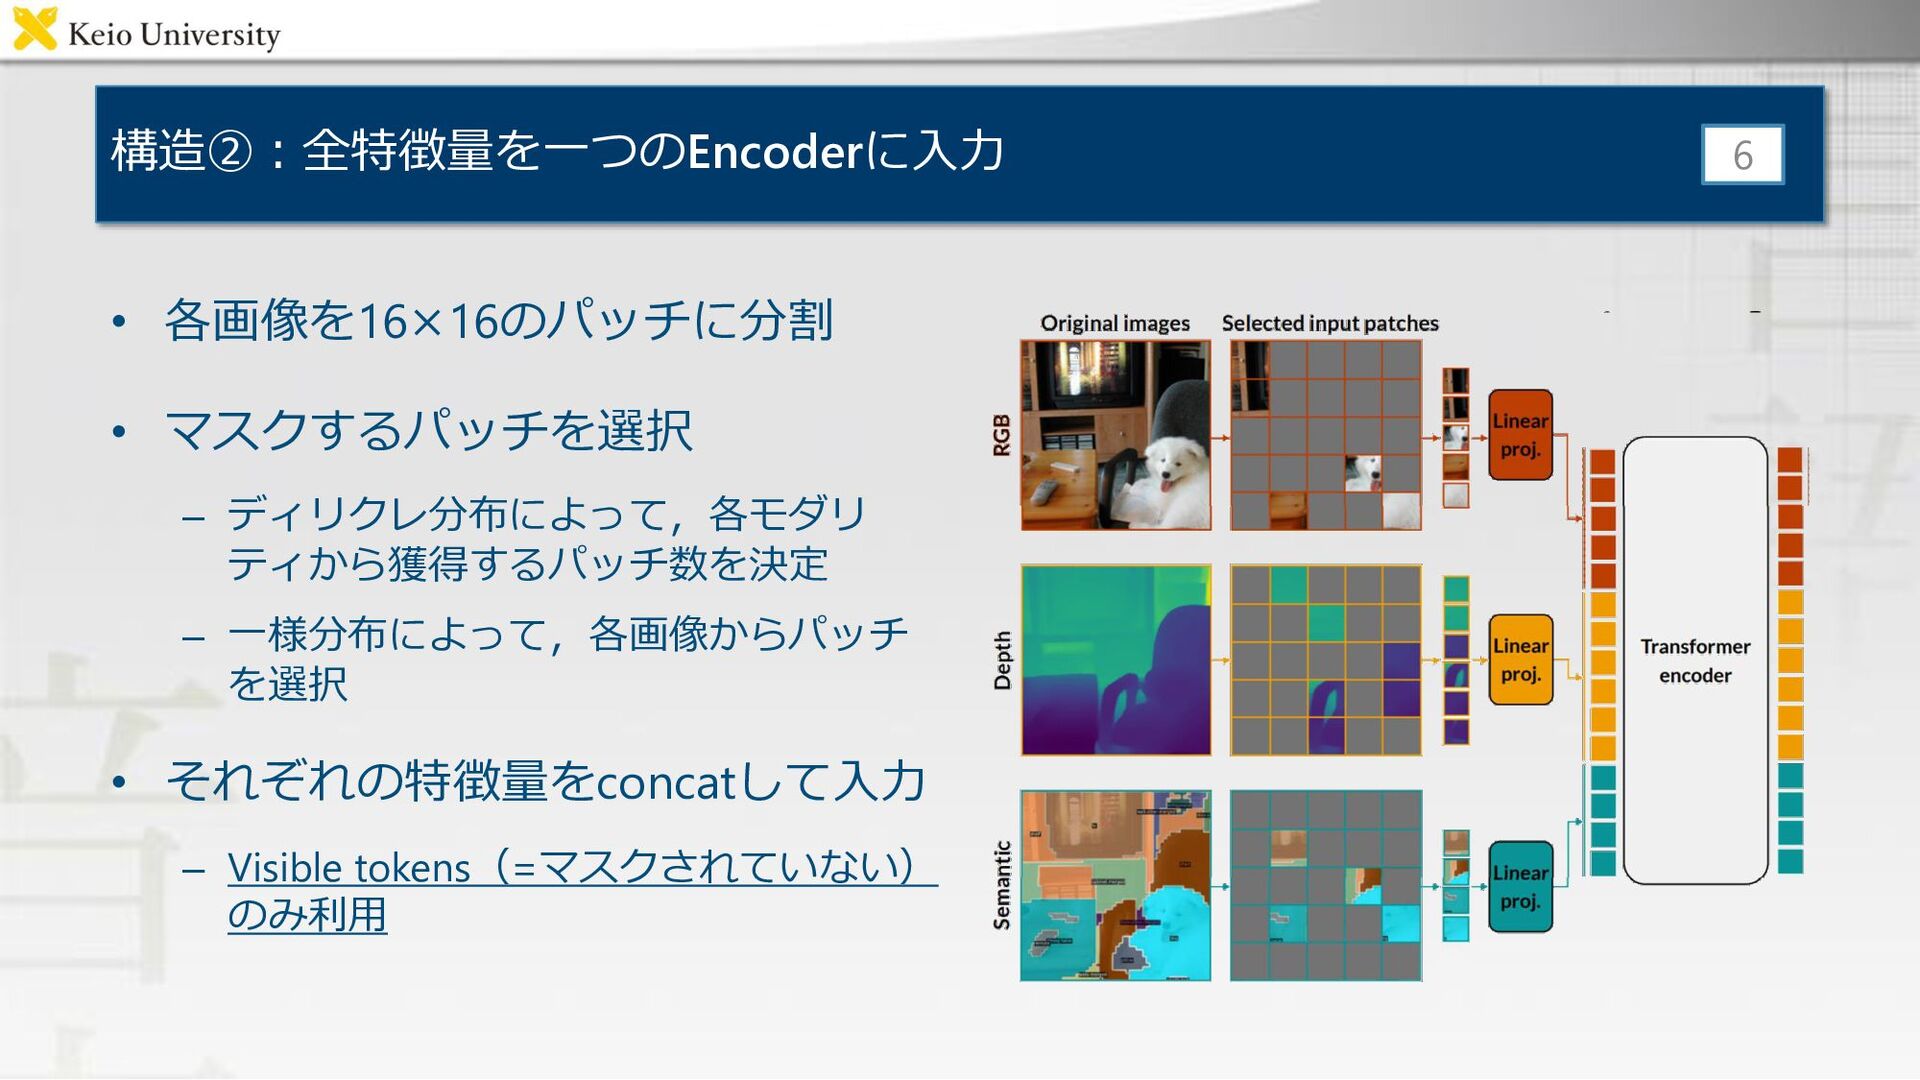
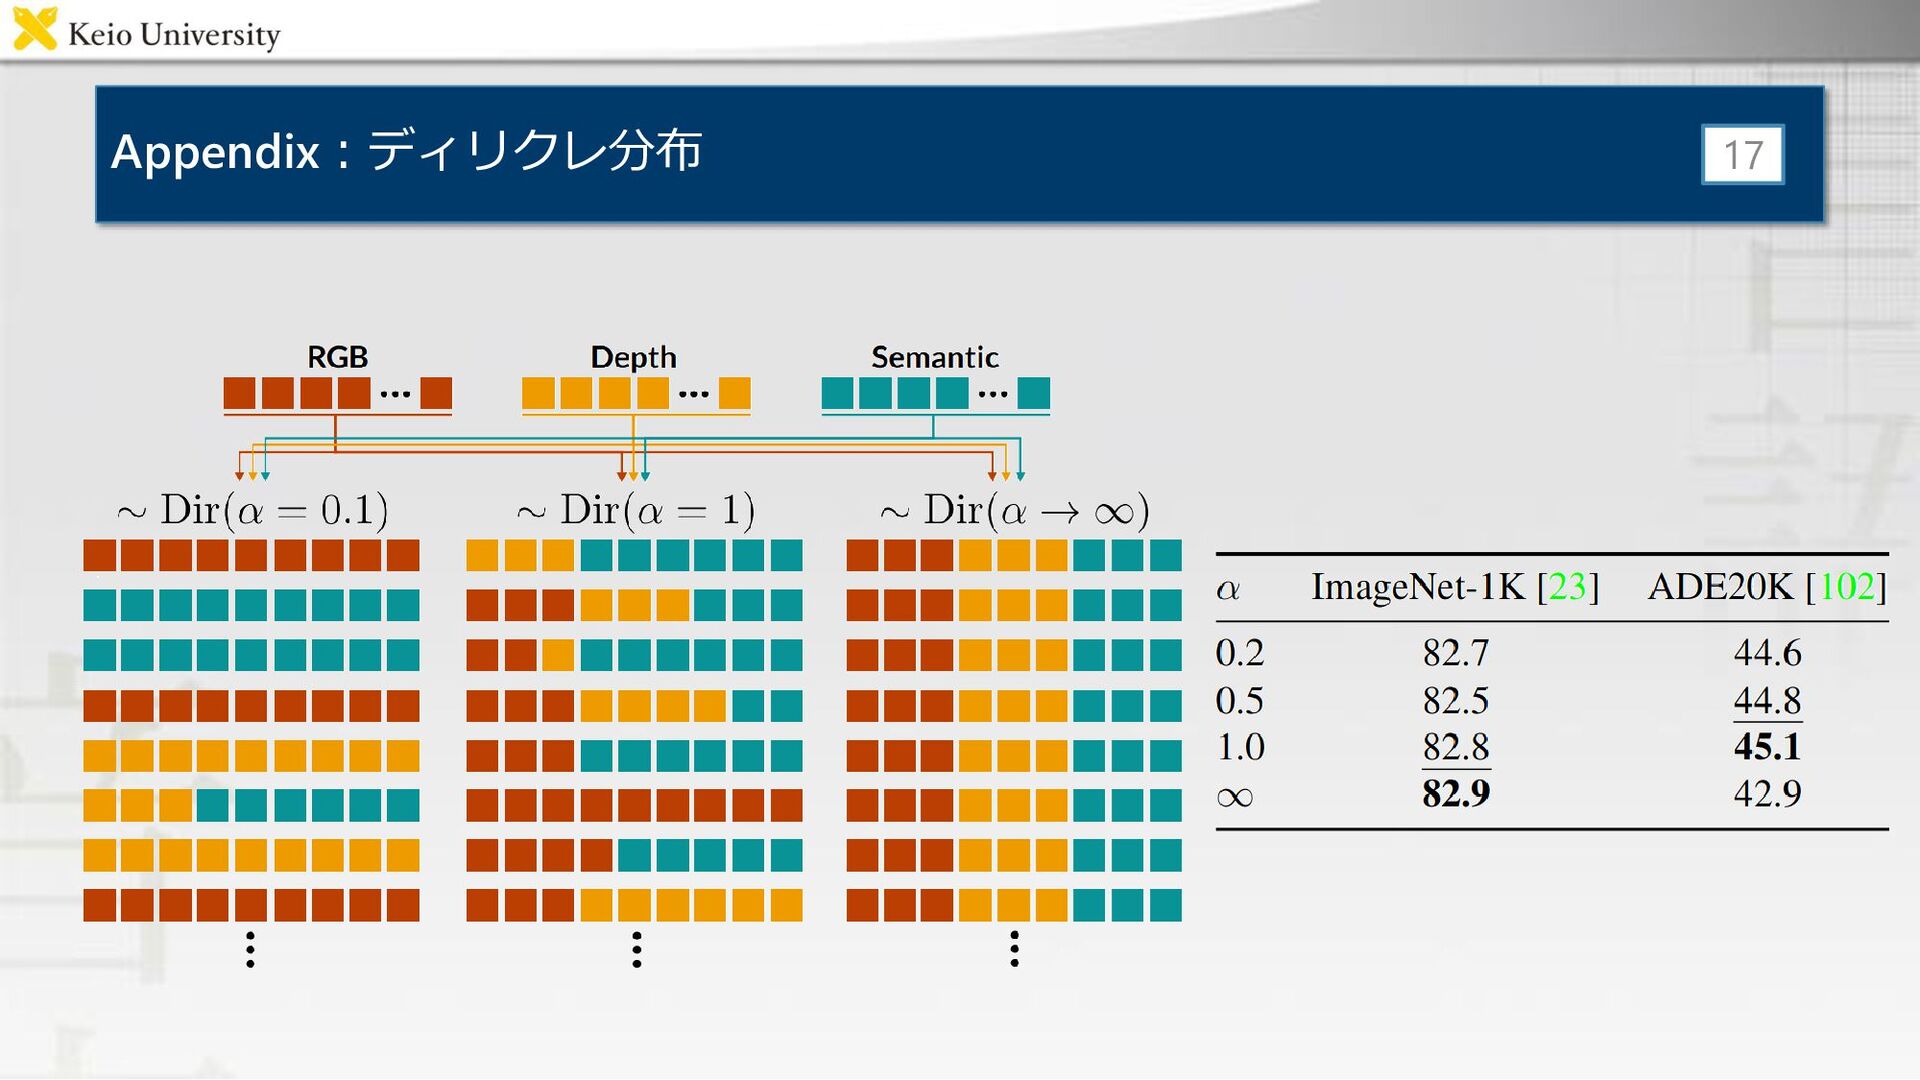
構造②:全特徴量を一つのEncoderに入力 • 各画像を16×16のパッチに分割 • マスクするパッチを選択 – ディリクレ分布によって,各モダリ ティから獲得するパッチ数を決定 – 一様分布によって,各画像からパッチ
を選択 • それぞれの特徴量をconcatして入力 – Visible tokens(=マスクされていない) のみ利用 6
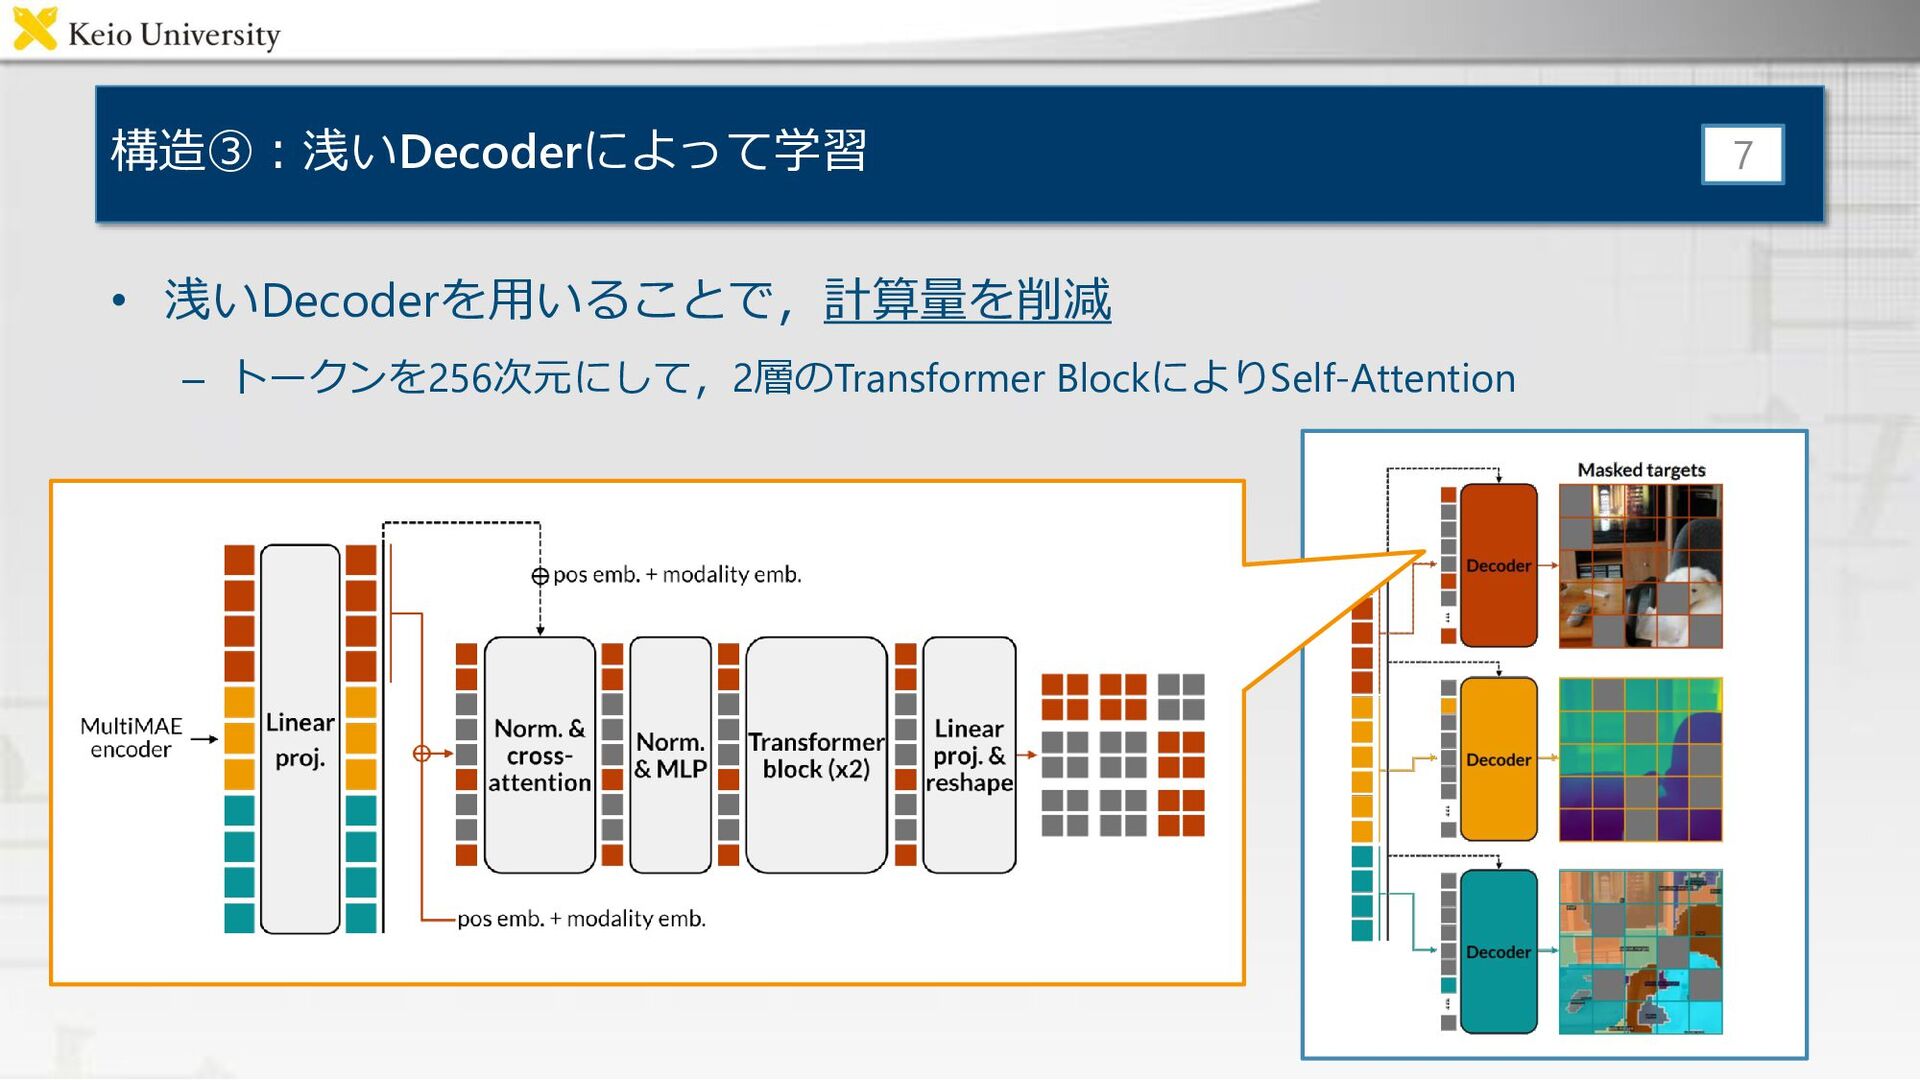
構造③:浅いDecoderによって学習 • 浅いDecoderを用いることで,計算量を削減 – トークンを256次元にして,2層のTransformer BlockによりSelf-Attention 7
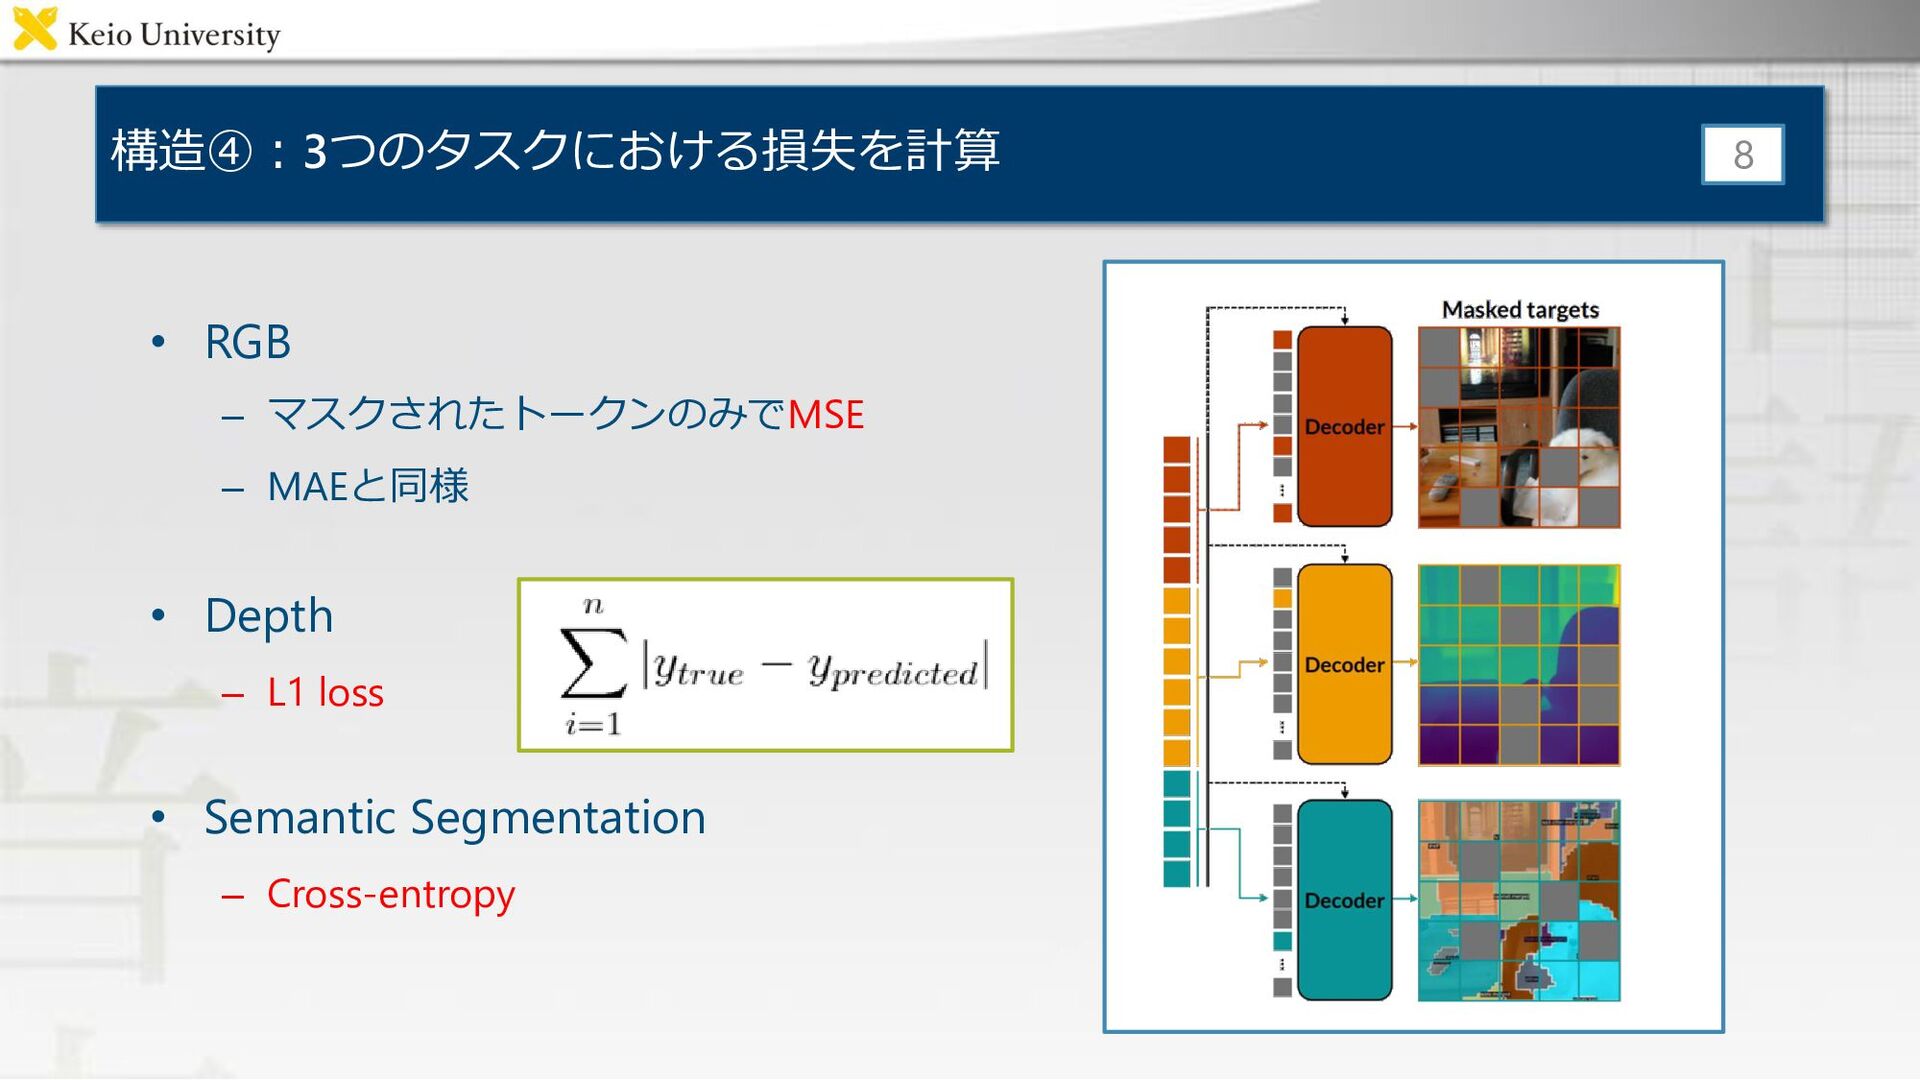
構造④:3つのタスクにおける損失を計算 • RGB – マスクされたトークンのみでMSE – MAEと同様 • Depth –
L1 loss • Semantic Segmentation – Cross-entropy 8
実験設定:3つの下流タスクで評価 1. Classification • Top-1 accuracyで評価 2. Semantic Segmentation •
mIoUで評価 3. Dense Regression Tasks • NYUv2データセットにおける𝛿1 で評価 • Depth値がthreshouldを下回るピクセル の割合(%) 9 今回は1.25 Fine-tuning用データセット – ImageNet-1K [Jia+, CVPR09] – ADE20K [Bolei+, CVPR17] – Hypersim [Mike+, ICCV21] – NYUv2 [Nathan+, ECCV12] – Taskonomy [Amir+, CVPR18] 事前学習 データセット:1.28M ImageNet GPU:8 A100 GPUs 学習時間:6.0 min / epoch
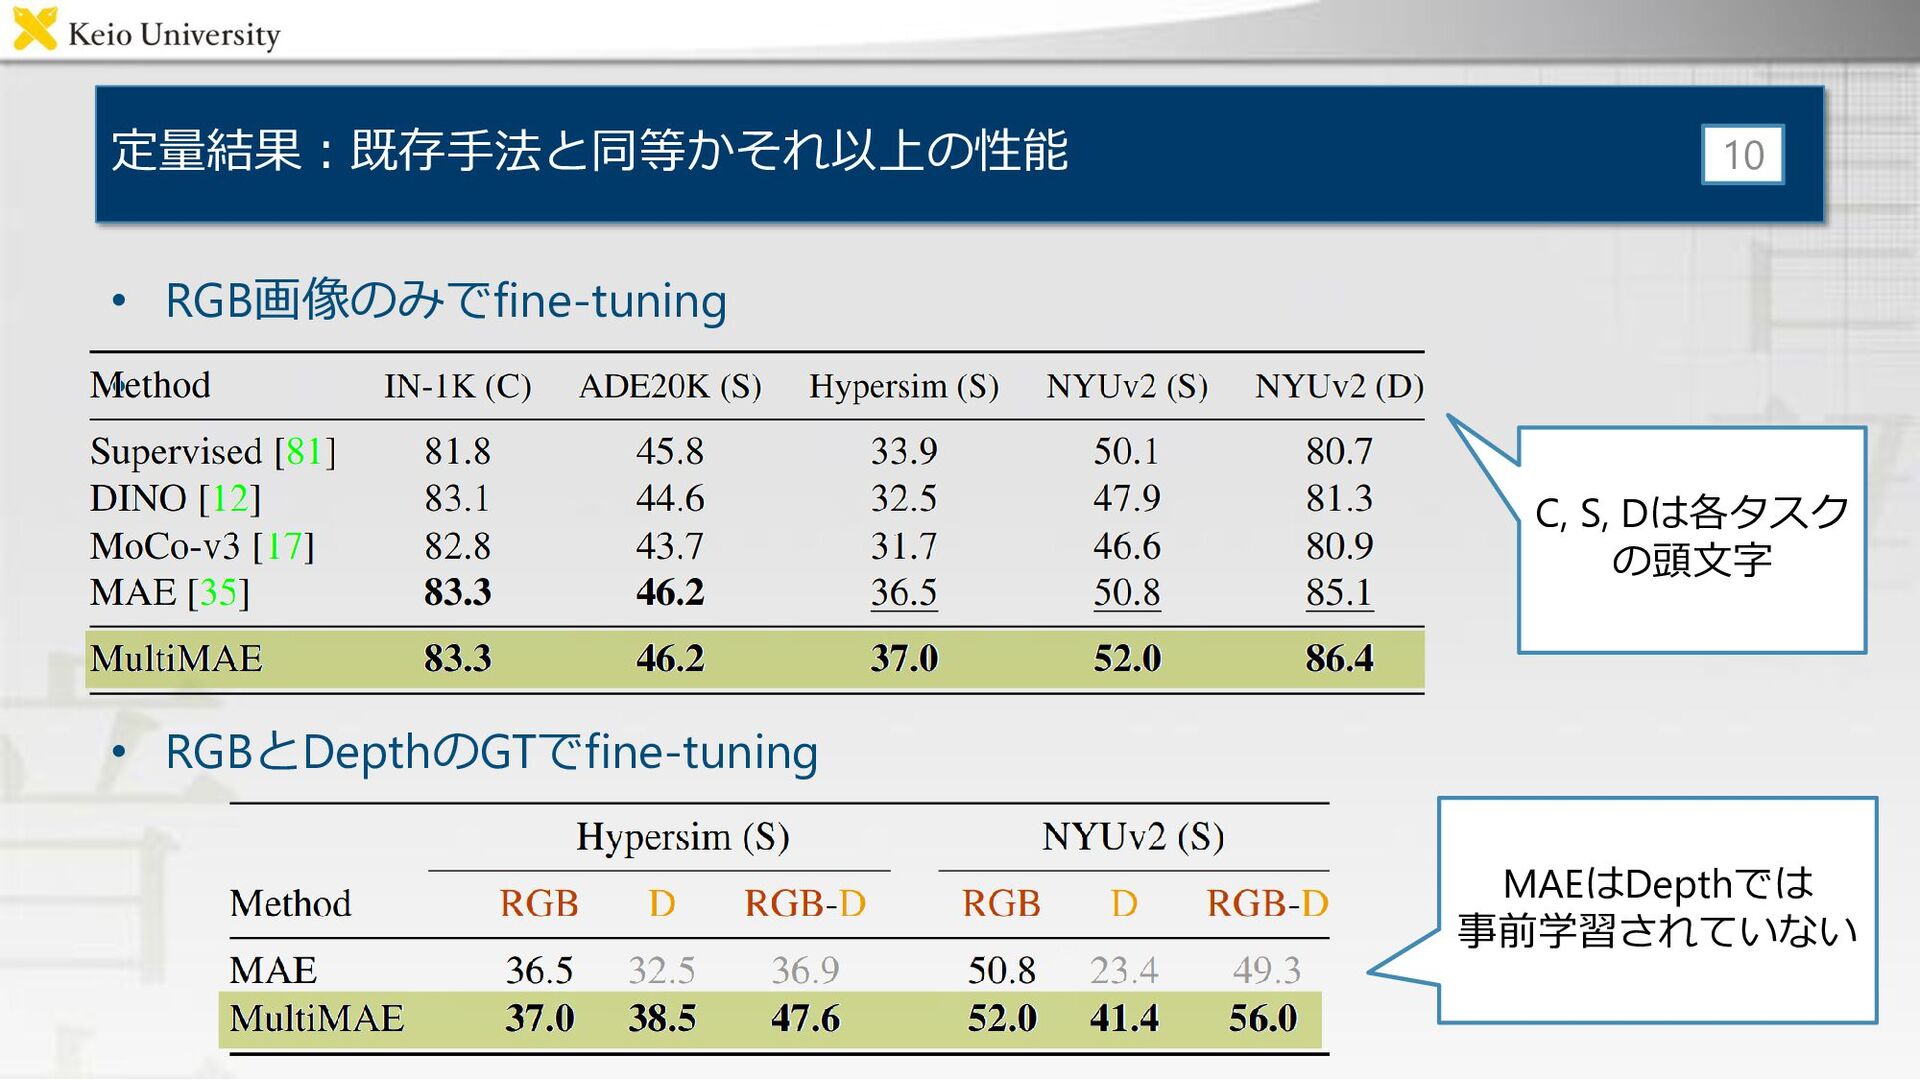
定量結果:既存手法と同等かそれ以上の性能 • RGB画像のみでfine-tuning • • RGBとDepthのGTでfine-tuning 10 C, S, Dは各タスク
の頭文字 MAEはDepthでは 事前学習されていない
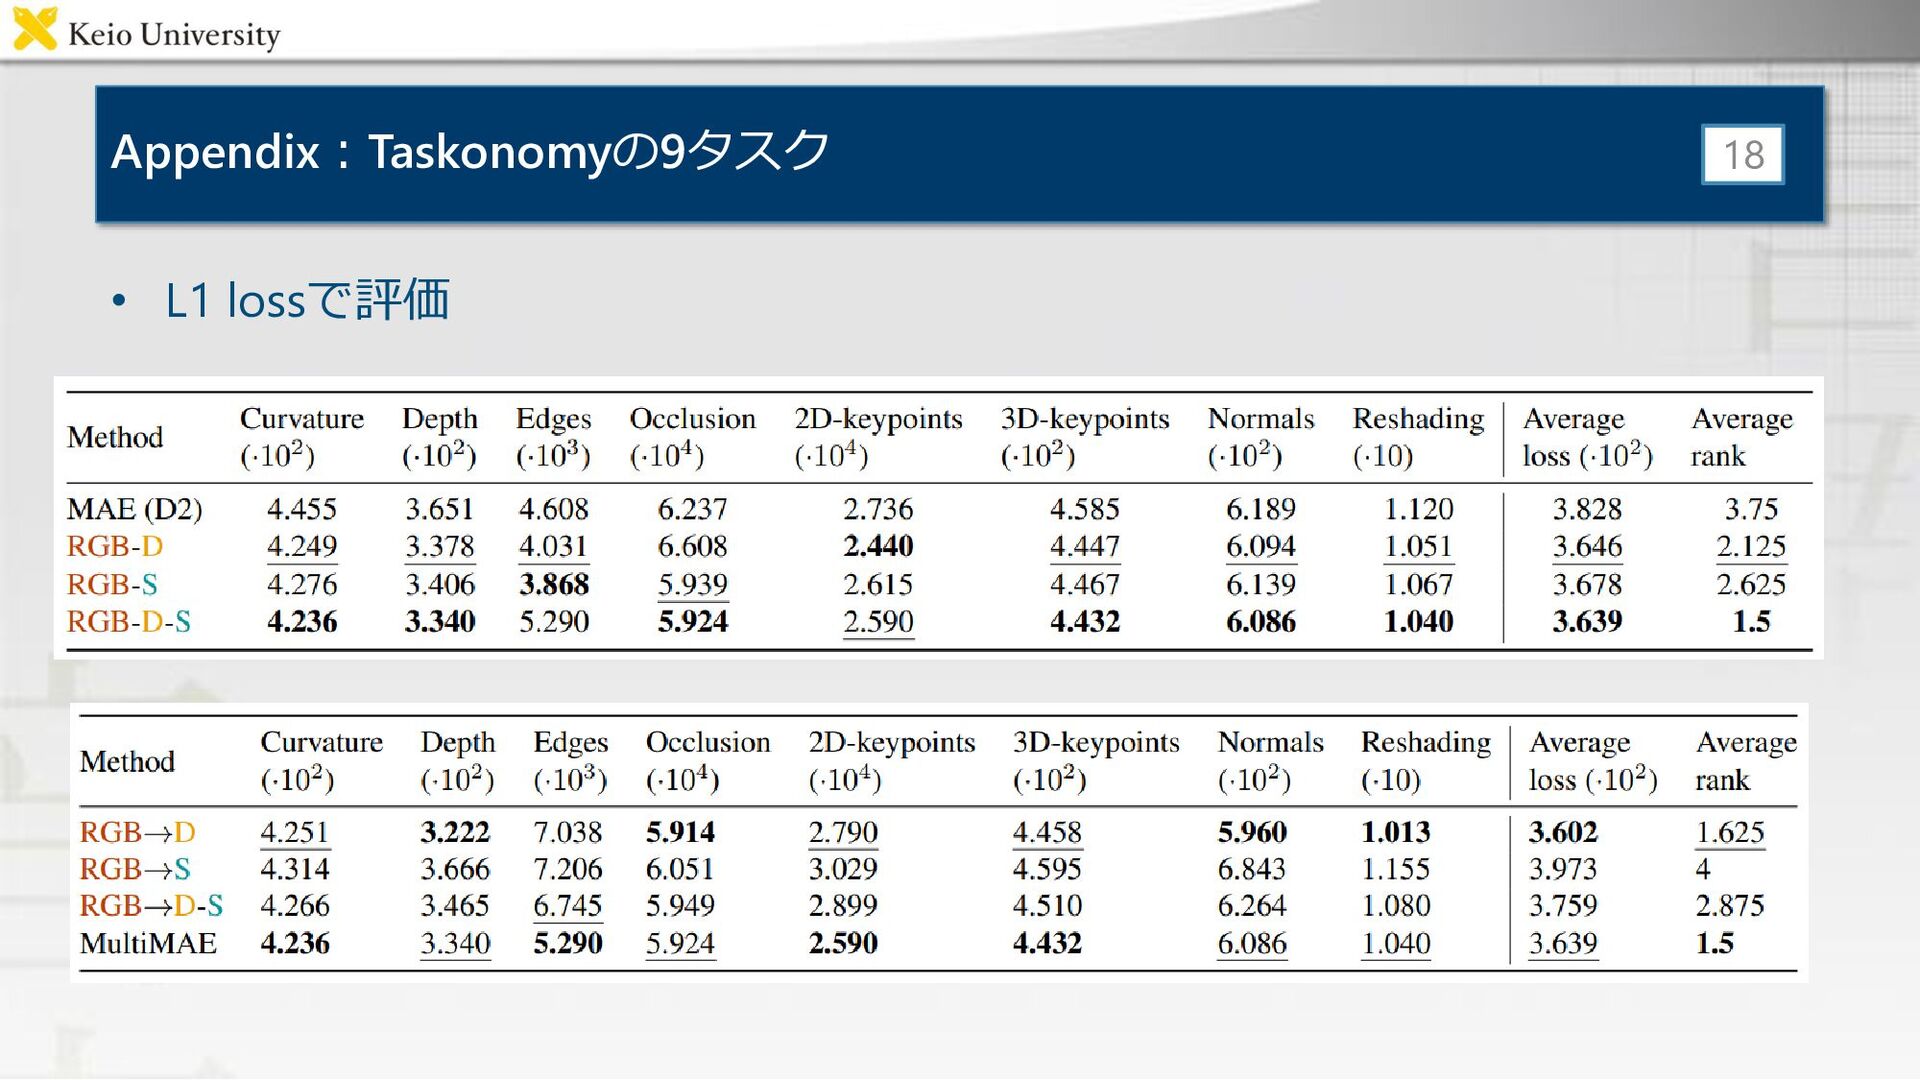
定量結果:既存手法と同等かそれ以上の性能 • 疑似ラベルの使用により性能上昇 • Taskonomy [Amir+, CVPR18] – 転移学習のしやすさを調べる –
評価は9タスクにおける評価のランキング 平均 11
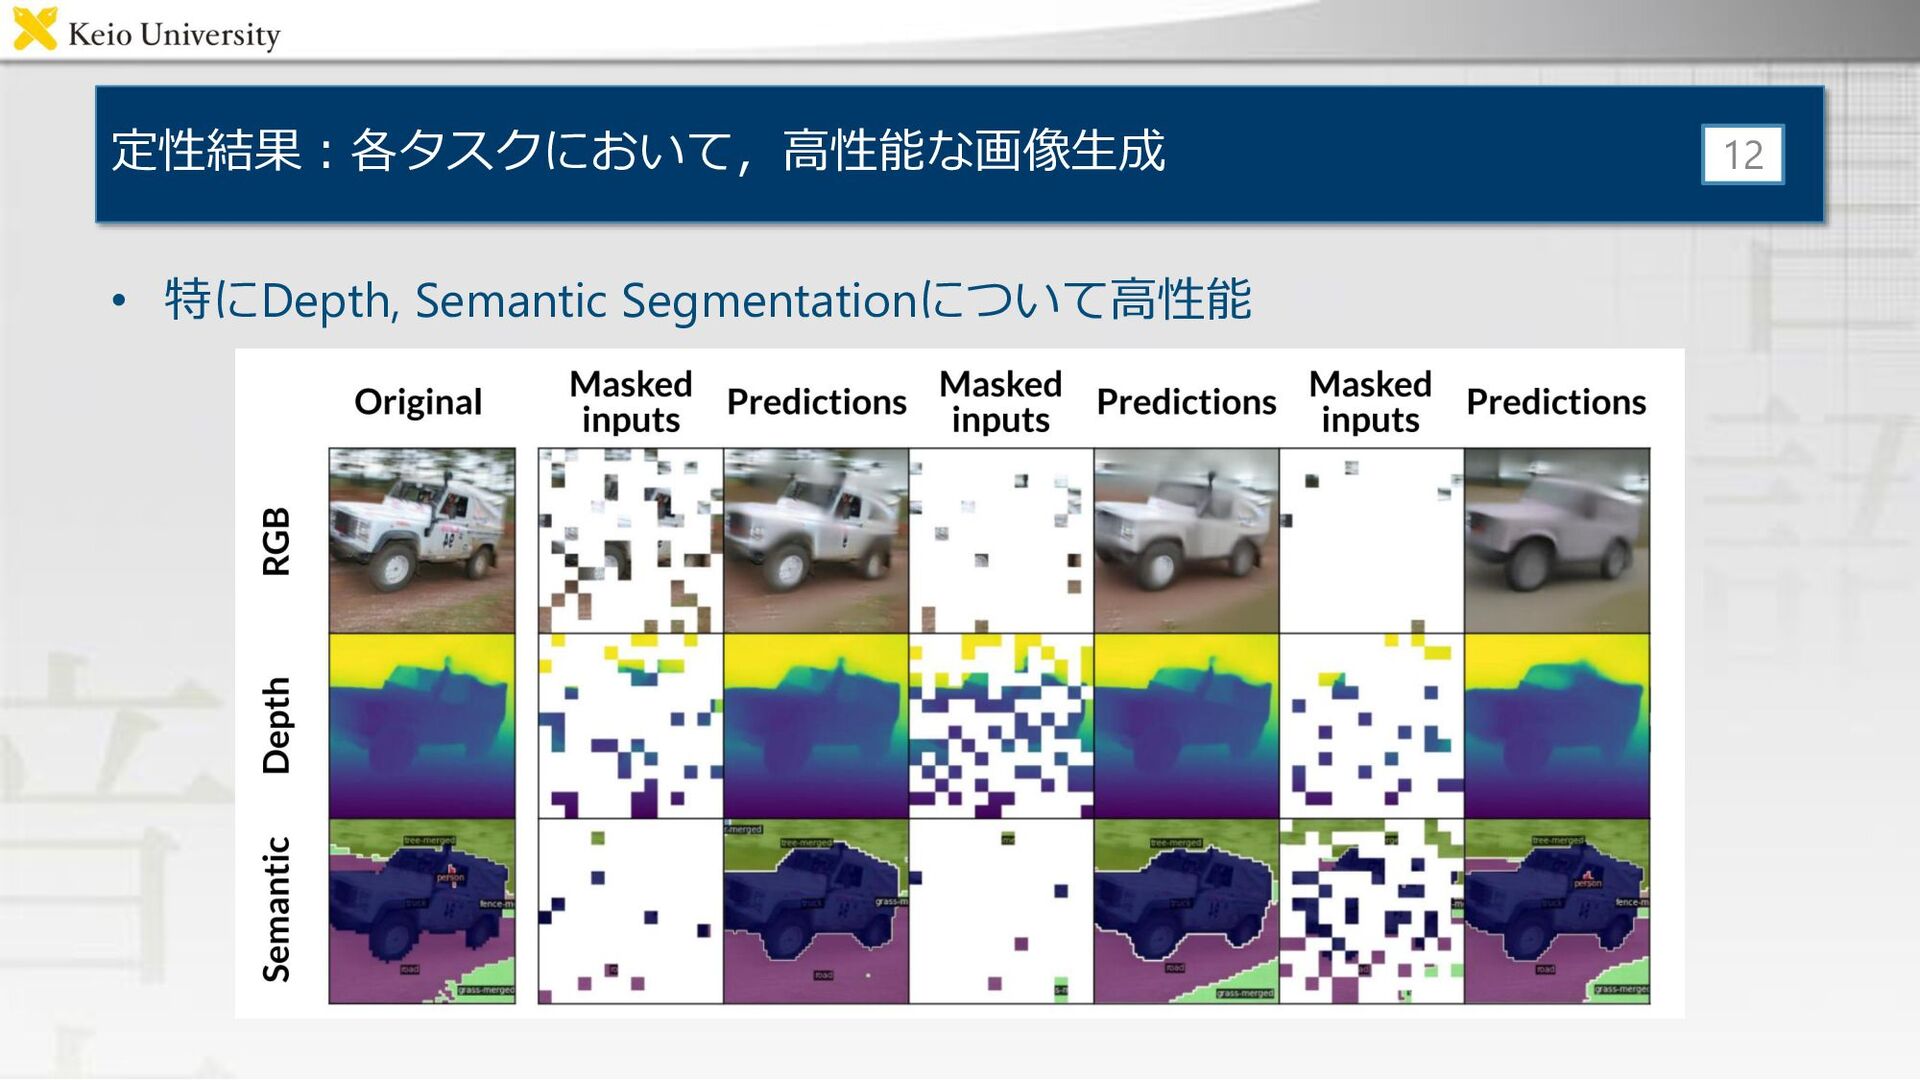
定性結果:各タスクにおいて,高性能な画像生成 • 特にDepth, Semantic Segmentationについて高性能 12
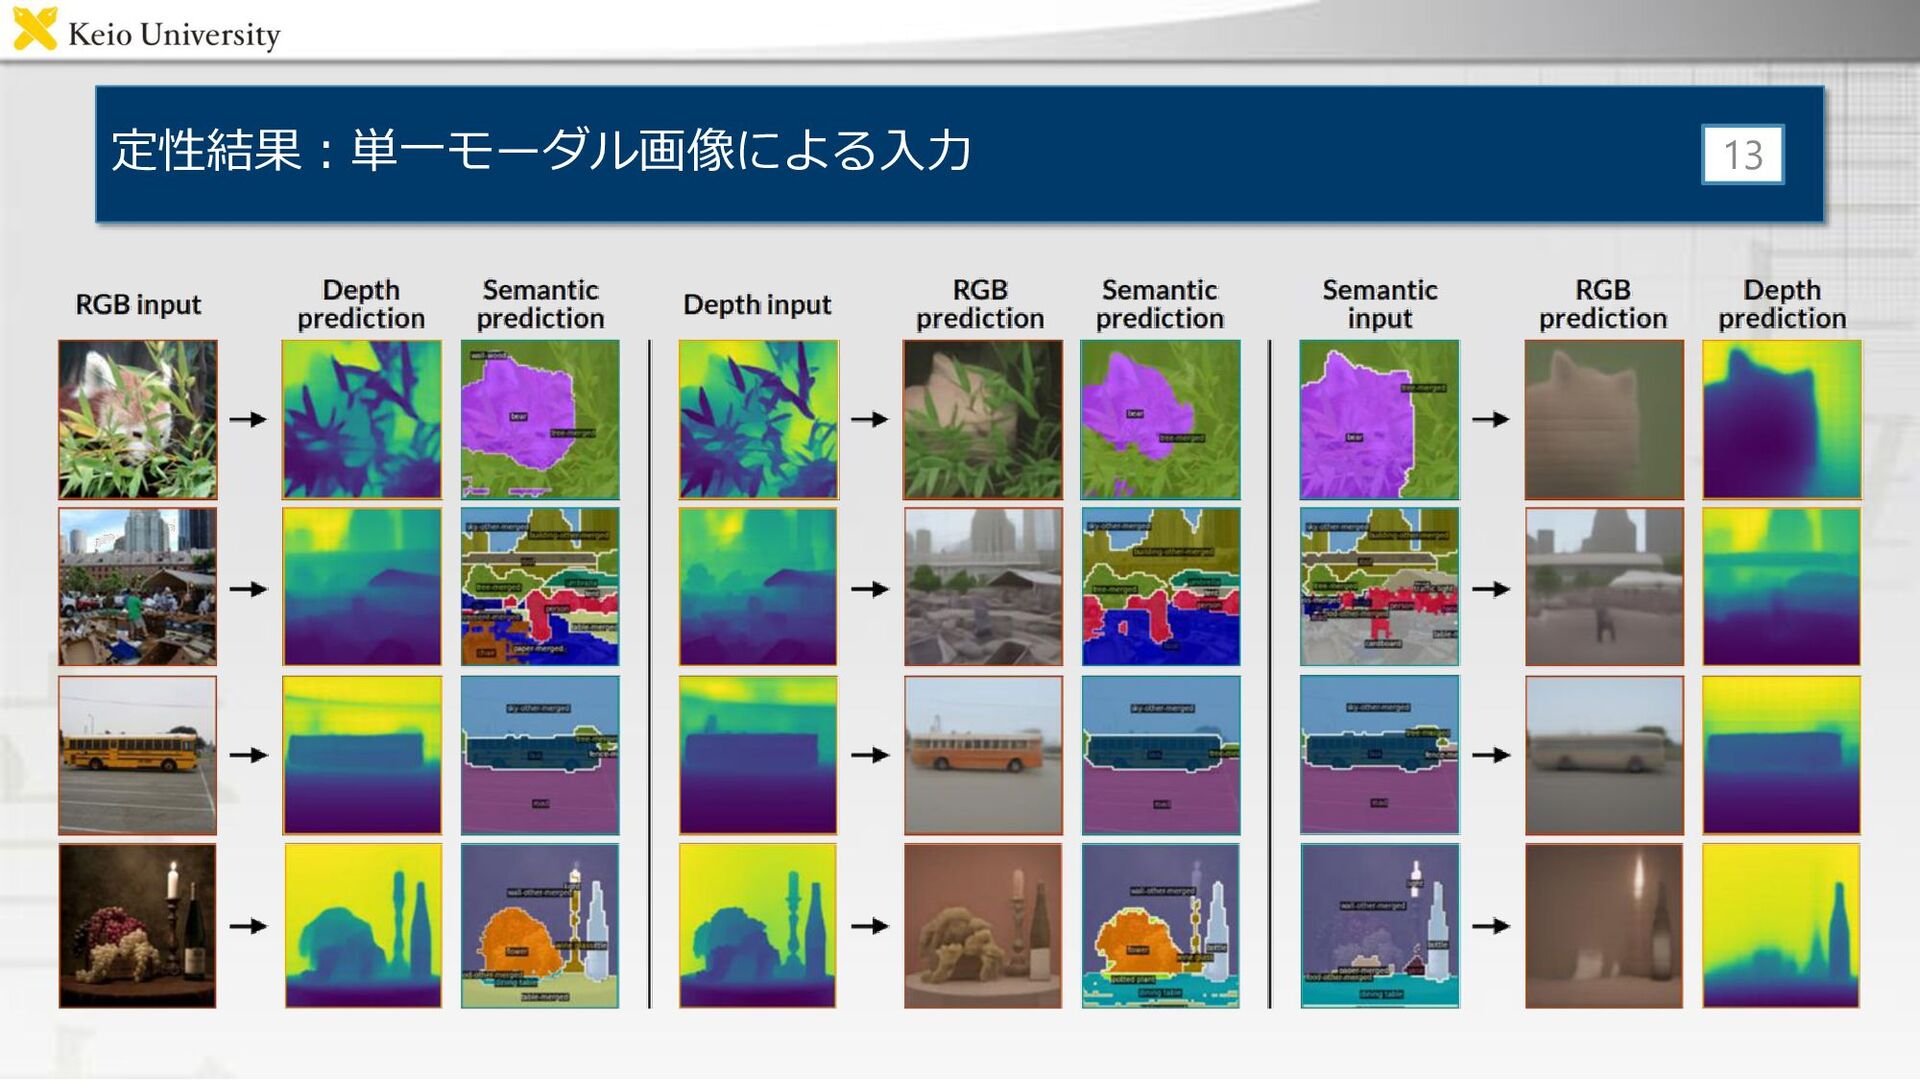
定性結果:単一モーダル画像による入力 13
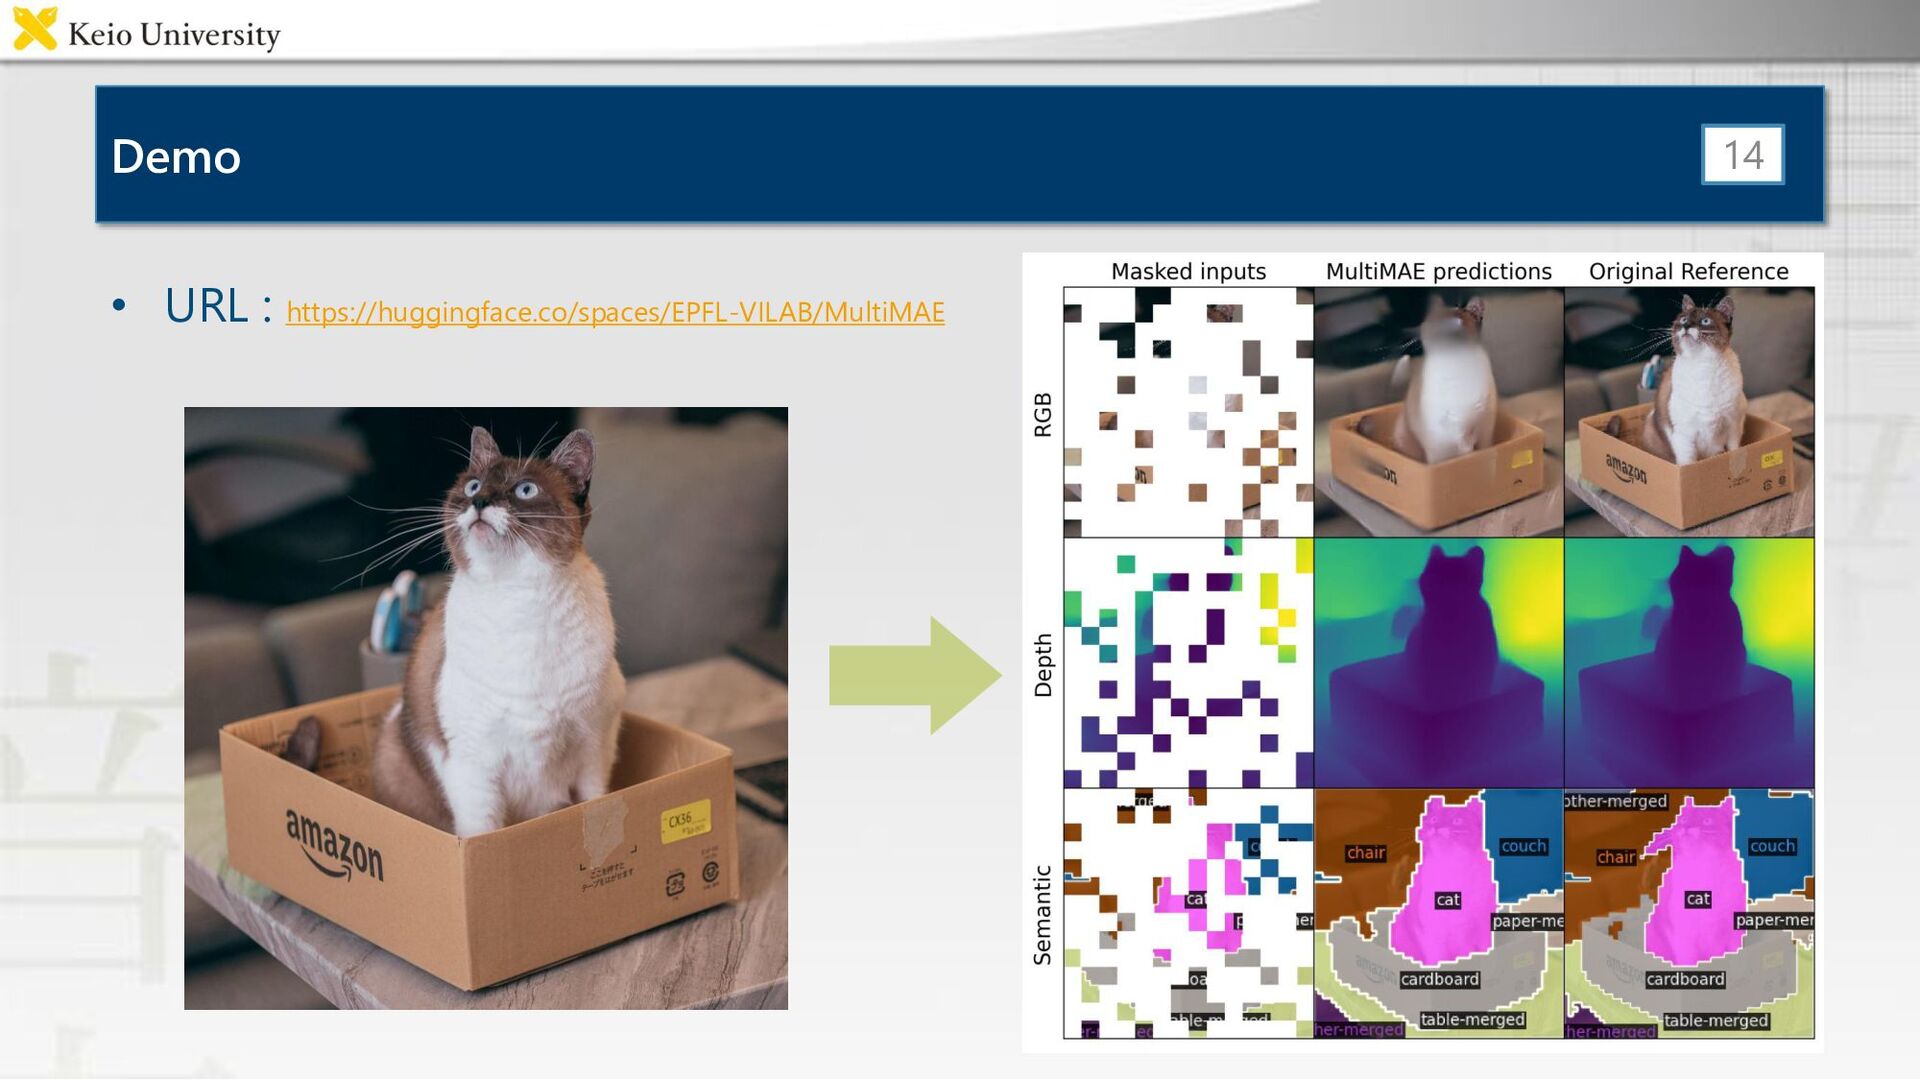
Demo • URL : https://huggingface.co/spaces/EPFL-VILAB/MultiMAE 14
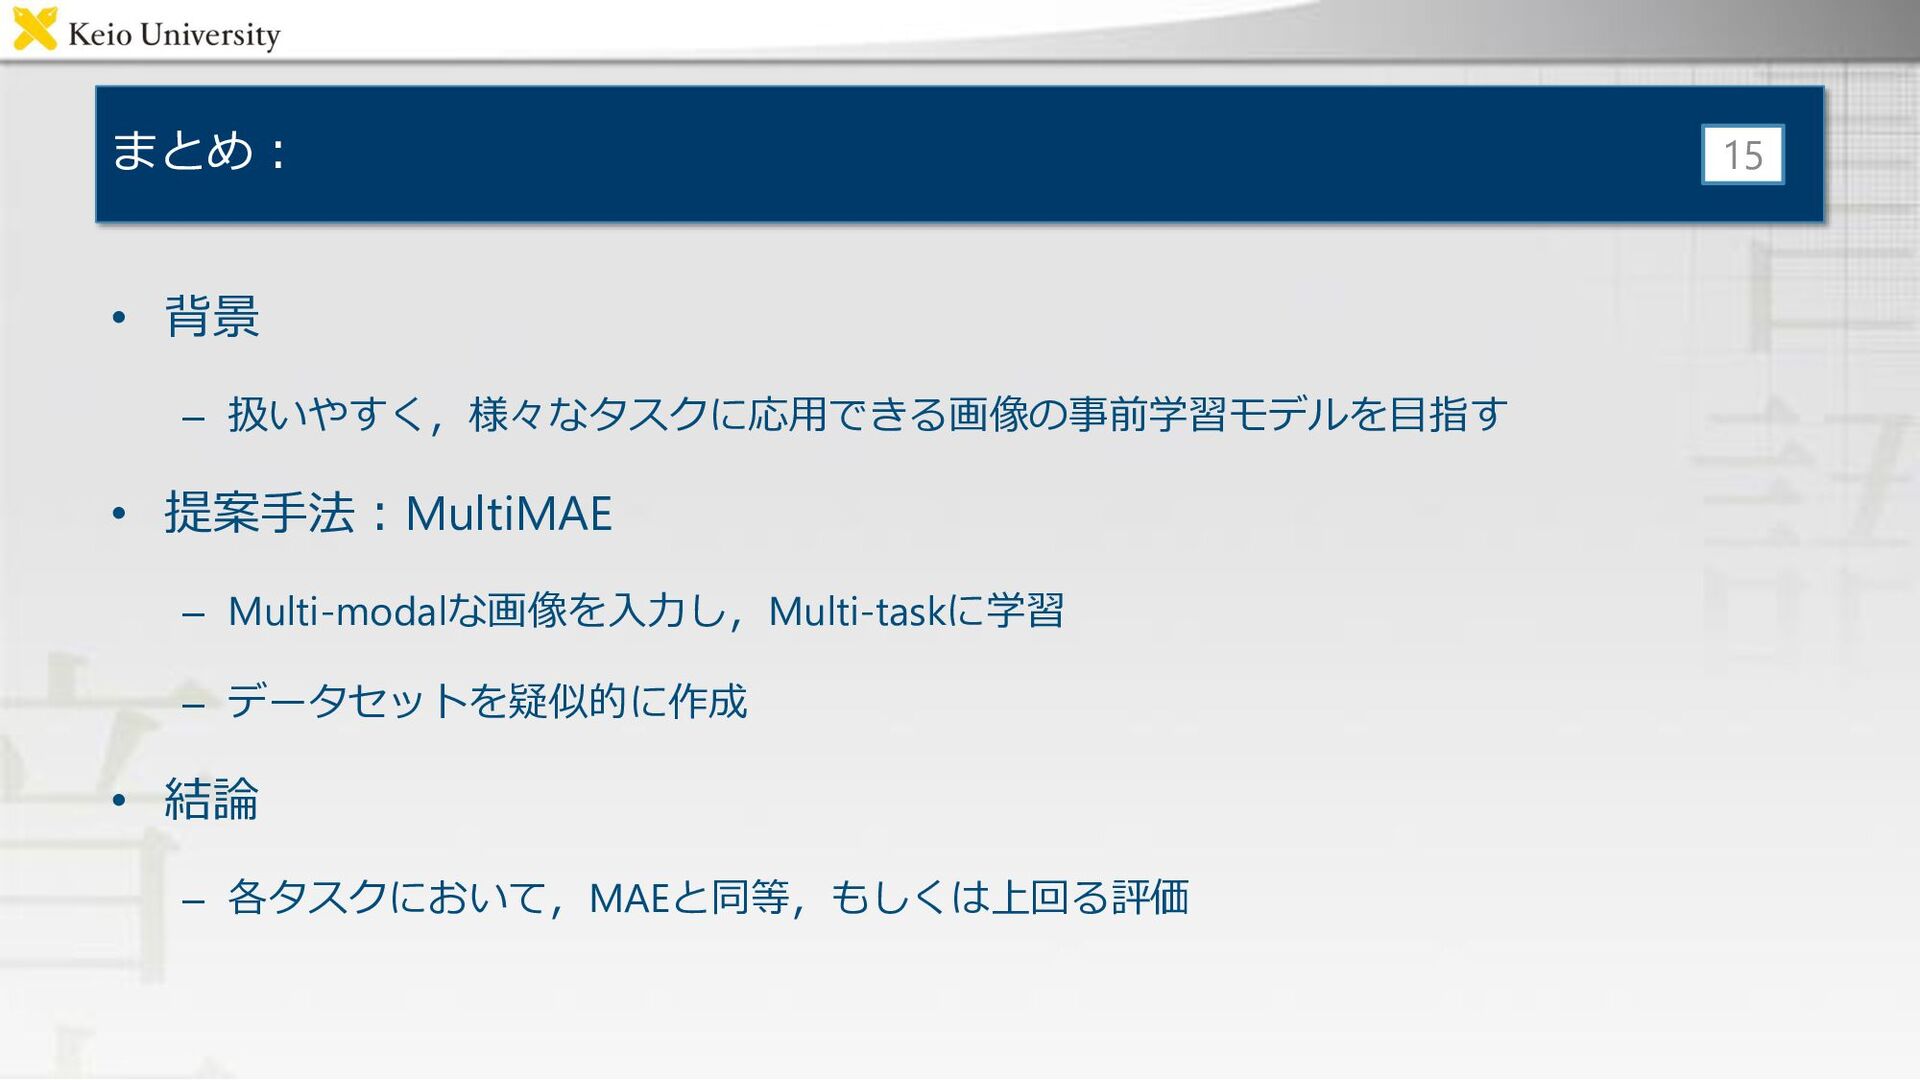
まとめ: • 背景 – 扱いやすく,様々なタスクに応用できる画像の事前学習モデルを目指す • 提案手法:MultiMAE – Multi-modalな画像を入力し,Multi-taskに学習 –
データセットを疑似的に作成 • 結論 – 各タスクにおいて,MAEと同等,もしくは上回る評価 15
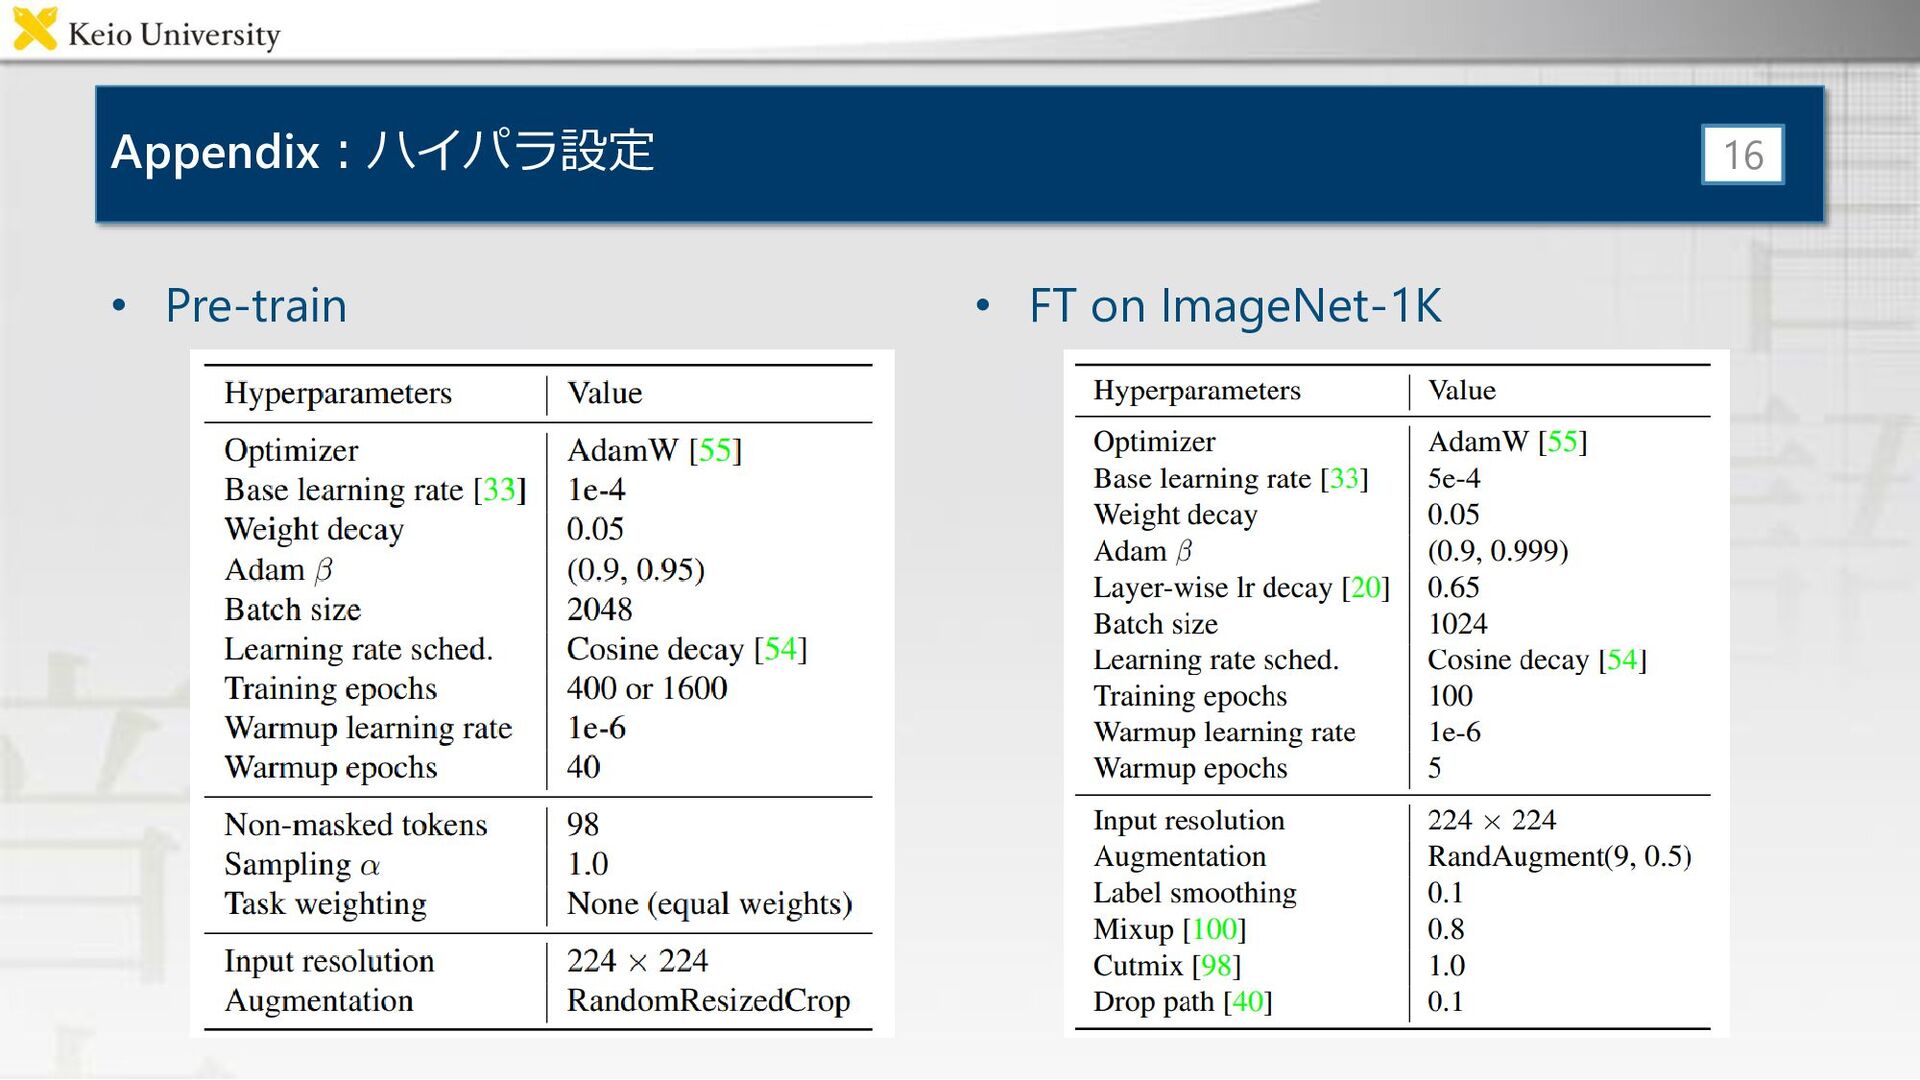
Appendix:ハイパラ設定 • Pre-train 16 • FT on ImageNet-1K
Appendix:ディリクレ分布 17
Appendix:Taskonomyの9タスク • L1 lossで評価 18
More Decks by Semantic Machine Intelligence Lab., Keio Univ.
See All by Semantic Machine Intelligence Lab., Keio Univ.
慶應義塾大学 AI実践05 論文執筆の仕組み化
keio_smilab
PRO
7
3.9k
[EMNLP26] RIGEL: Self-Distilled Score Adaptation for Image and Video Captioning Evaluation
keio_smilab
PRO
0
170
[RSJ26] Building a VLA Model Based on Self-Distilled Classification
keio_smilab
PRO
0
230
[RSJ26] AnoleVLA: Lightweight Vision-Language-Action Model with Deep State Space Models for Mobile Manipulation
keio_smilab
PRO
0
200
[RSJ26] NarrativeFlow: Flow-Based Vision-Language-Action Model Using Robot Velocity Fields
keio_smilab
PRO
0
270
[RSJ26] Flow as Flow: Modeling Robot Velocity Fields as Probability Velocity Fields
keio_smilab
PRO
1
300
[RSJ26] Hierarchy-Aware Multimodal Retrieval-Augmented Generation for Embodied Question Answering
keio_smilab
PRO
1
210
[MIRU26] Open-Vocabulary Intention-Guided Object Detection in Diverse Scenes
keio_smilab
PRO
0
260
[Journal club] Evo-1: Lightweight Vision-Language-Action Model with Preserved Semantic Alignment
keio_smilab
PRO
0
79
Other Decks in Technology
See All in Technology
Kiro CLI 入門 (ターミナルと CI で使う) | 目指せ Kiro マスター 03
inariku
PRO
2
140
複数システムが同居した 15 年物の AWS アカウントを解体するための考古学
wa6sn
3
150
E2E Test というハーネス — AI時代の自動テスト民主化
daishukojima
1
470
Ebitengine製iOSアプリ公開ボタンを押す会
eiei114
0
120
高品質と高スピードを支える品質のシフトレフトのアプローチ
goyoki
2
850
並列度を下げたら速くなった — go build の重複コンパイルを実測で見る
tomoaki25
2
1.2k
81天的 AI Agent 軟體開發團隊治理實務分享
regionbbs
0
160
Context Ontology Accelerator 入門 (業務データの意味を、AI エージェントに渡す)
inariku
PRO
3
670
An Introduction to Context Ontology Accelerator (teaching AI agents what your data means)
inariku
PRO
1
240
Go初心者のクラウドエンジニアが、デプロイを通して旨味を知っていく話
ryudai
1
200
人間+AIを「チーム」としてプロセスを再設計する
littlehands
1
1.4k
小さなエージェントから始めてみよう!実践コンテキストエンジニアリング
iwamot
PRO
0
120
Featured
See All Featured
Introduction to Domain-Driven Design and Collaborative software design
baasie
1
1.1k
Evolution of real-time – Irina Nazarova, EuRuKo, 2024
irinanazarova
9
1.7k
SEO for Brand Visibility & Recognition
aleyda
0
4.9k
The Director’s Chair: Orchestrating AI for Truly Effective Learning
tmiket
1
350
Crafting Experiences
bethany
1
440
4 Signs Your Business is Dying
shpigford
187
23k
Jamie Indigo - Trashchat’s Guide to Black Boxes: Technical SEO Tactics for LLMs
techseoconnect
PRO
0
750
Documentation Writing (for coders)
carmenintech
77
5.6k
Stewardship and Sustainability of Urban and Community Forests
pwiseman
0
590
Deep Space Network (abreviated)
tonyrice
0
410
"I'm Feeling Lucky" - Building Great Search Experiences for Today's Users (#IAC19)
danielanewman
230
23k
Principles of Awesome APIs and How to Build Them.
keavy
128
18k


 keio_smilab
 inariku
 wa6sn
 daishukojima
 eiei114
 goyoki
 tomoaki25
 regionbbs
 ryudai
 littlehands
 iwamot
 baasie
 irinanazarova
 aleyda
 tmiket
 bethany
 shpigford
 techseoconnect
 carmenintech
 pwiseman
 tonyrice
 danielanewman
 keavy