Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
第66回コンピュータビジョン勉強会@関東 Epona: Autoregressive Diff...
Search
Sponsored
·
Your Podcast. Everywhere. Effortlessly.
Share. Educate. Inspire. Entertain. You do you. We'll handle the rest.
→
Kento Sasaki
February 08, 2026
Research
810
0
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
第66回コンピュータビジョン勉強会@関東 Epona: Autoregressive Diffusion World Model for Autonomous Driving
Kento Sasaki
February 08, 2026
Transcript
29 slides
第66回コンピュータビジョン勉強会@関東 世界モデル論文読み会 Kento Sasaki 紹介する論文: Epona: Autoregressive Diffusion World Model
for Autonomous Driving (Zhang+, ICCV 2025) Feb. 8, 2026
⾃⼰紹介 佐々木謙人 (Kento Sasaki) • Research Engineer @ Turing Inc.
(April 2023~) • X account: @kento_sasaki1 • 自動運転VLAモデルの研究開発 • ICLR 2026, AAAI 2026 (Oral), WACV 2025 (Oral) 1
紹介する論⽂ https://kevin-thu.github.io/Epona/ 2
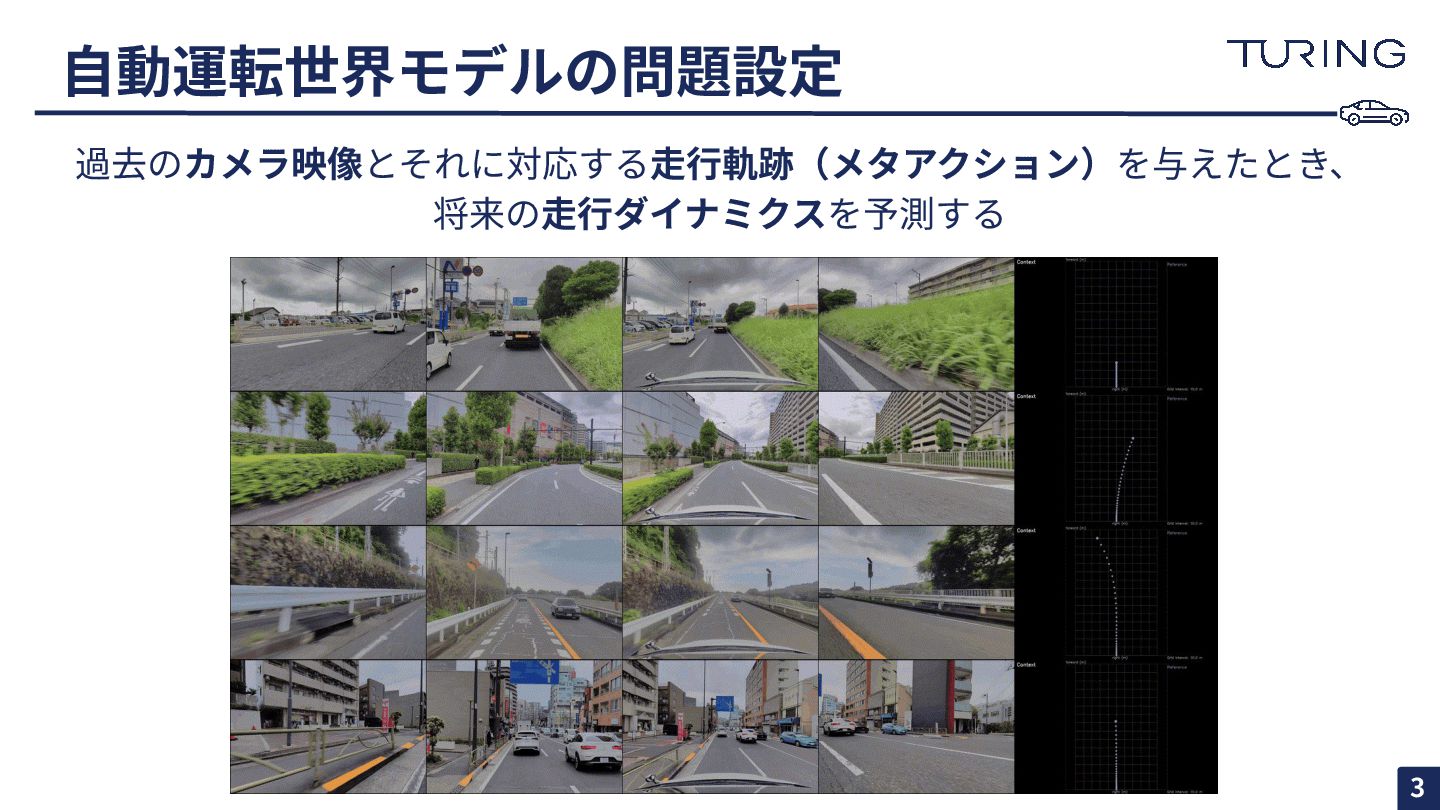
過去のカメラ映像とそれに対応する⾛⾏軌跡(メタアクション)を与えたとき、 将来の⾛⾏ダイナミクスを予測する ⾃動運転世界モデルの問題設定 3
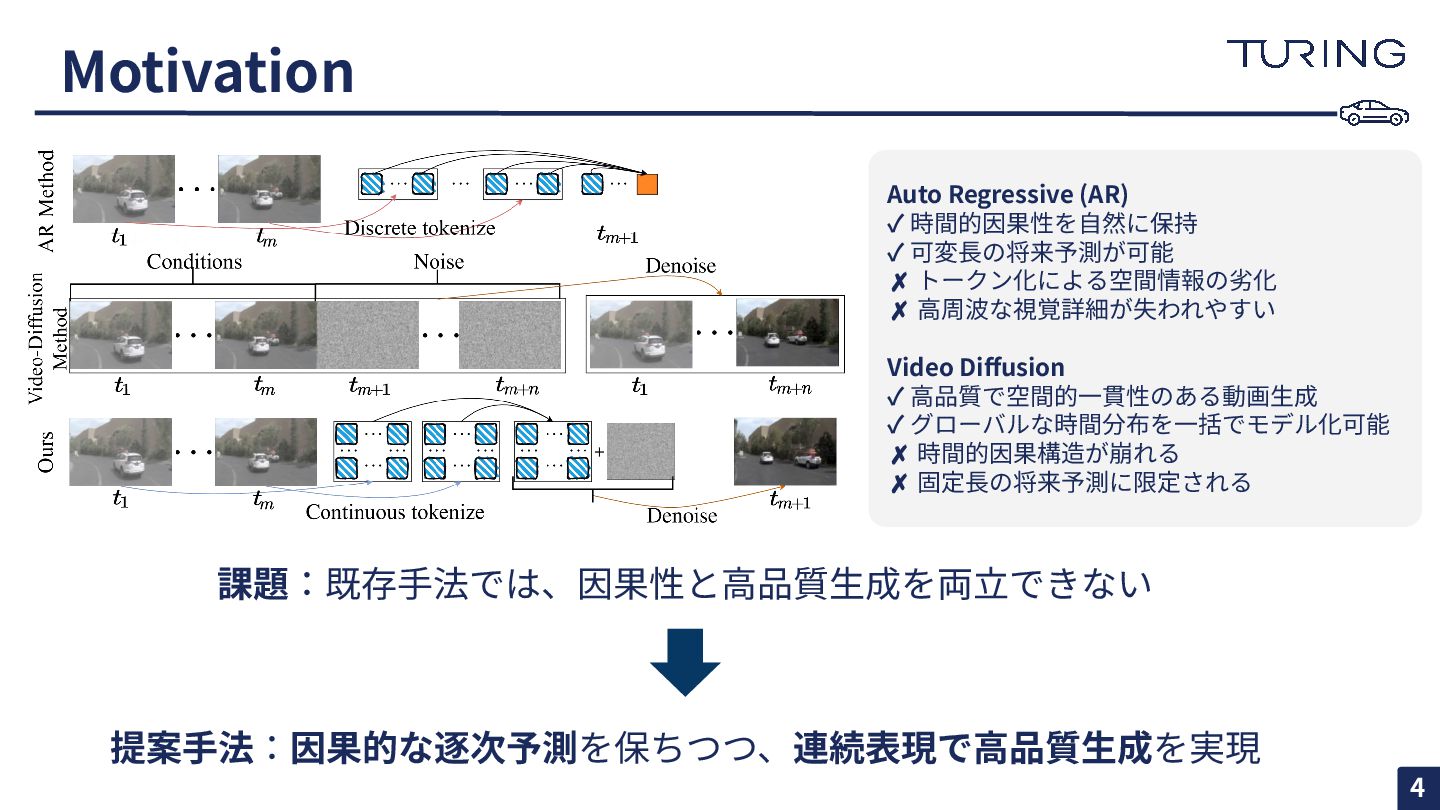
Motivation Auto Regressive (AR) ✓ 時間的因果性を⾃然に保持 ✓ 可変⻑の将来予測が可能 ✗ トークン化による空間情報の劣化
✗ ⾼周波な視覚詳細が失われやすい Video Diffusion ✓ ⾼品質で空間的⼀貫性のある動画⽣成 ✓ グローバルな時間分布を⼀括でモデル化可能 ✗ 時間的因果構造が崩れる ✗ 固定⻑の将来予測に限定される 課題:既存⼿法では、因果性と⾼品質⽣成を両⽴できない 提案⼿法:因果的な逐次予測を保ちつつ、連続表現で⾼品質⽣成を実現 4
Motivation 5
Method
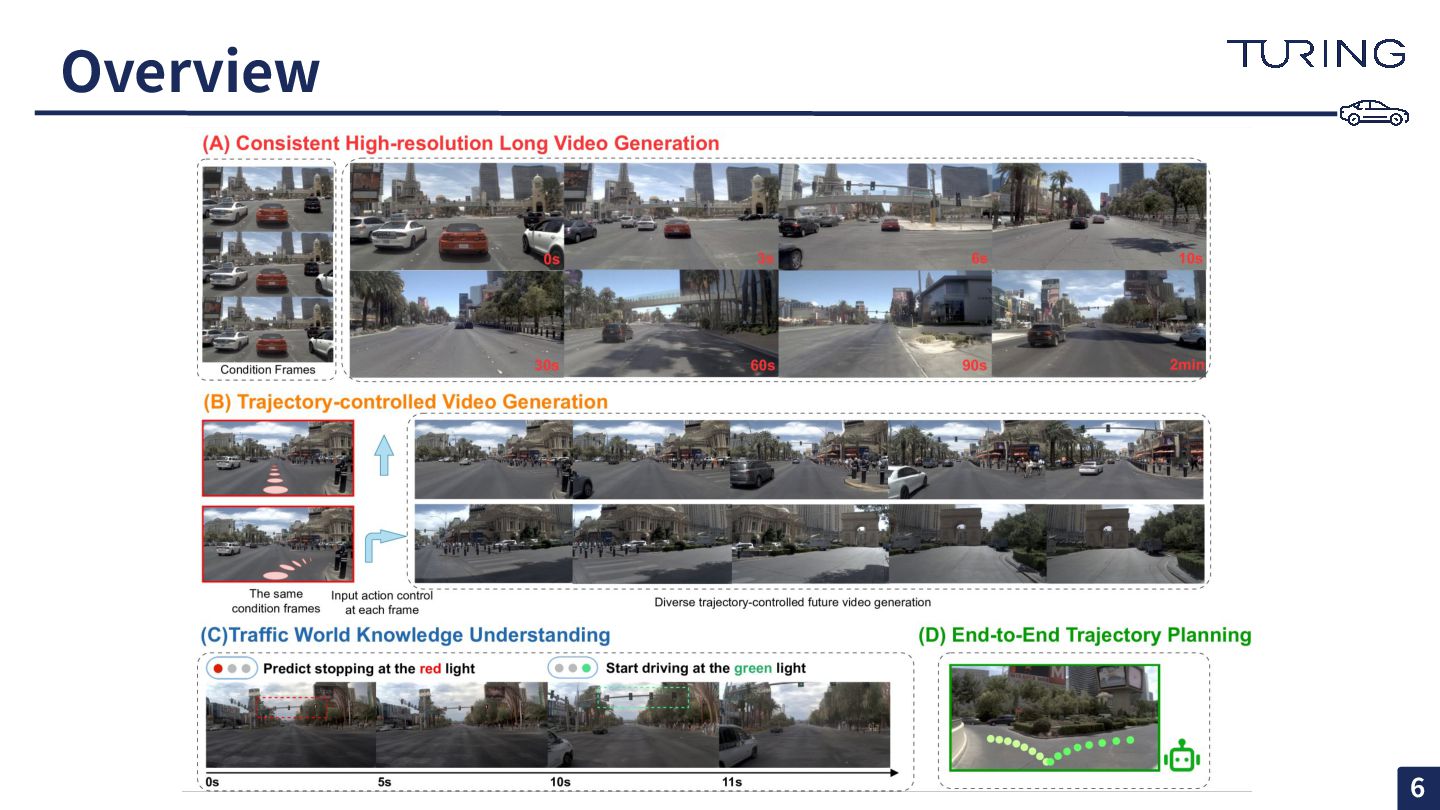
Overview 6
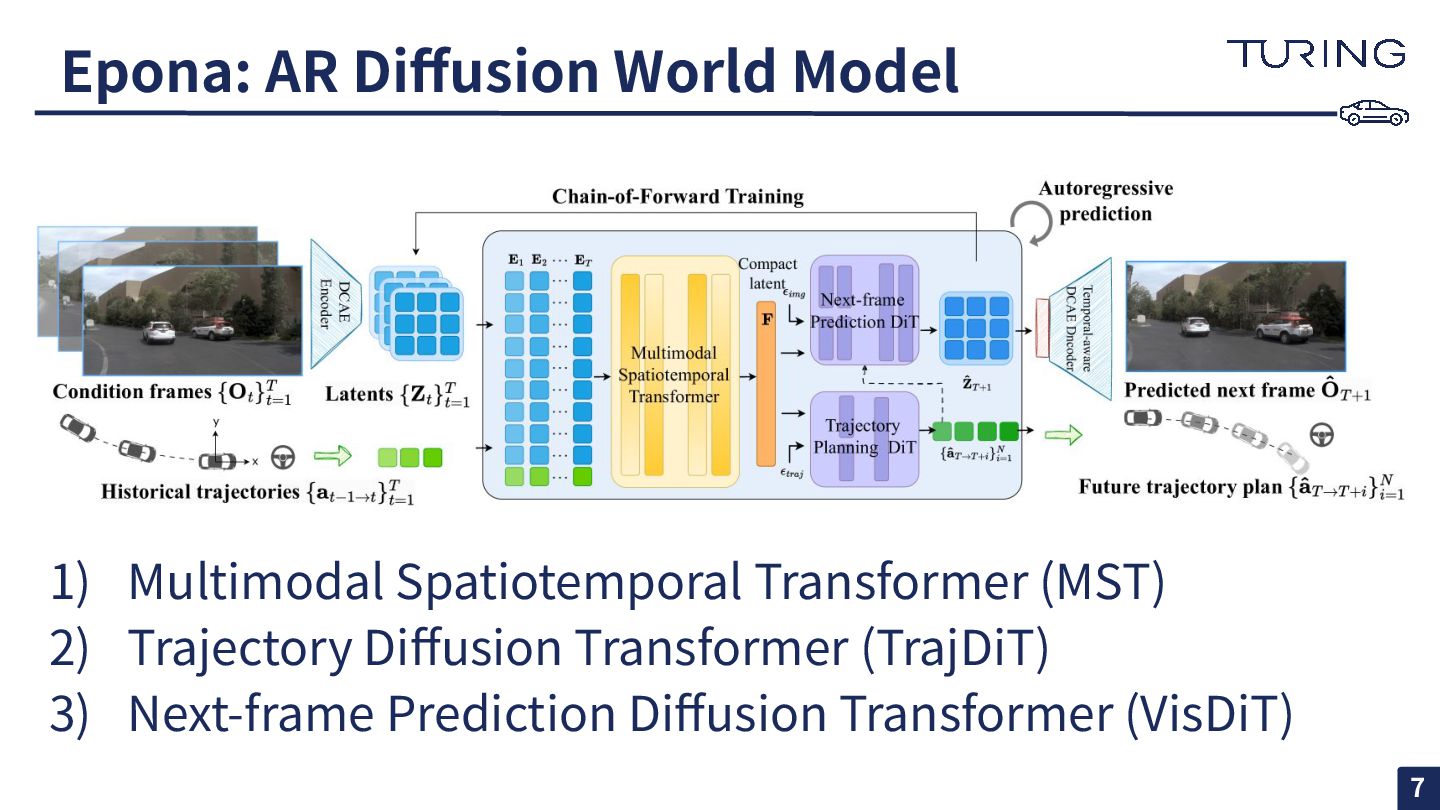
Epona: AR Diffusion World Model 1) Multimodal Spatiotemporal Transformer (MST)
2) Trajectory Diffusion Transformer (TrajDiT) 3) Next-frame Prediction Diffusion Transformer (VisDiT) 7
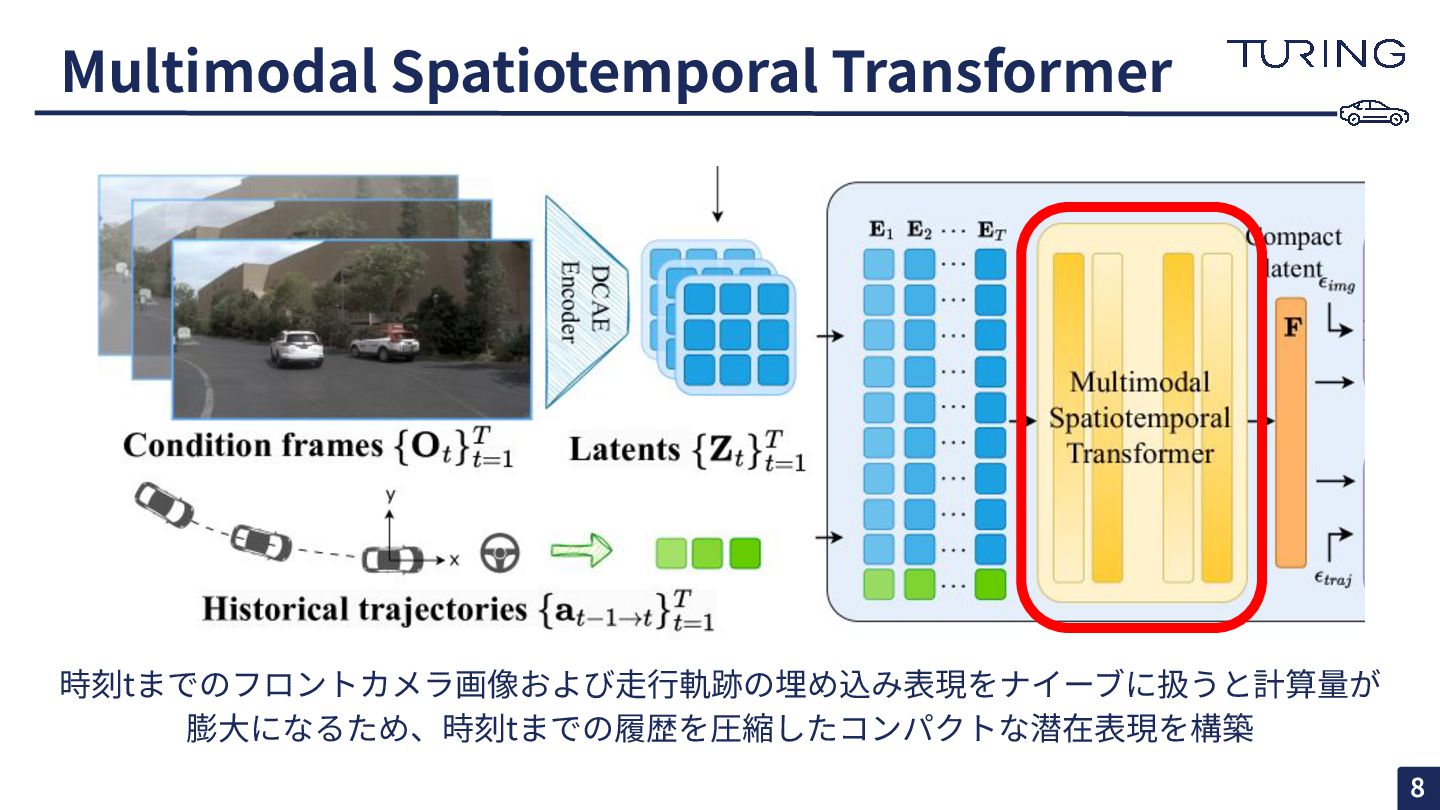
Multimodal Spatiotemporal Transformer 時刻tまでのフロントカメラ画像および⾛⾏軌跡の埋め込み表現をナイーブに扱うと計算量が 膨⼤になるため、時刻tまでの履歴を圧縮したコンパクトな潜在表現を構築 8
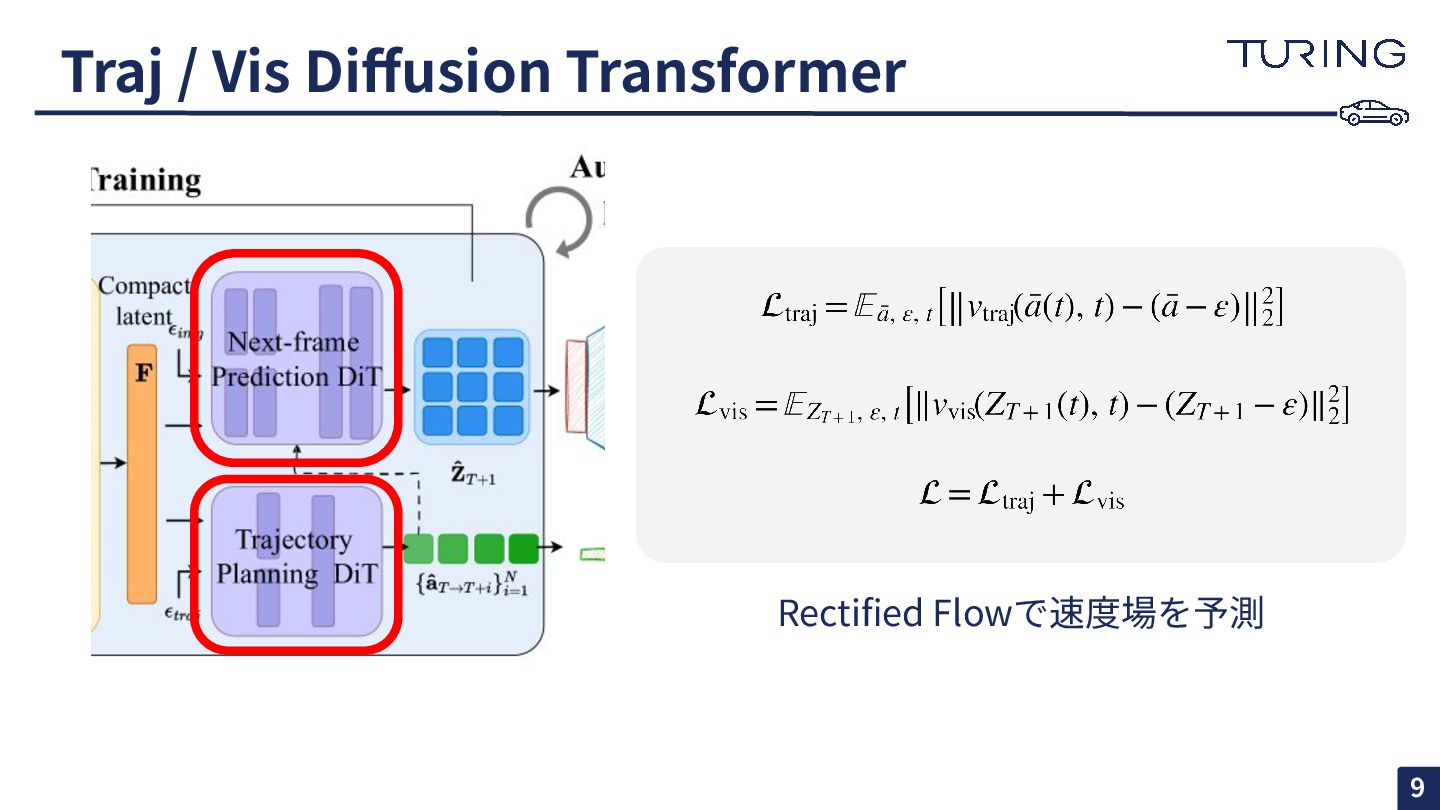
Traj / Vis Diffusion Transformer Rectified Flowで速度場を予測 9
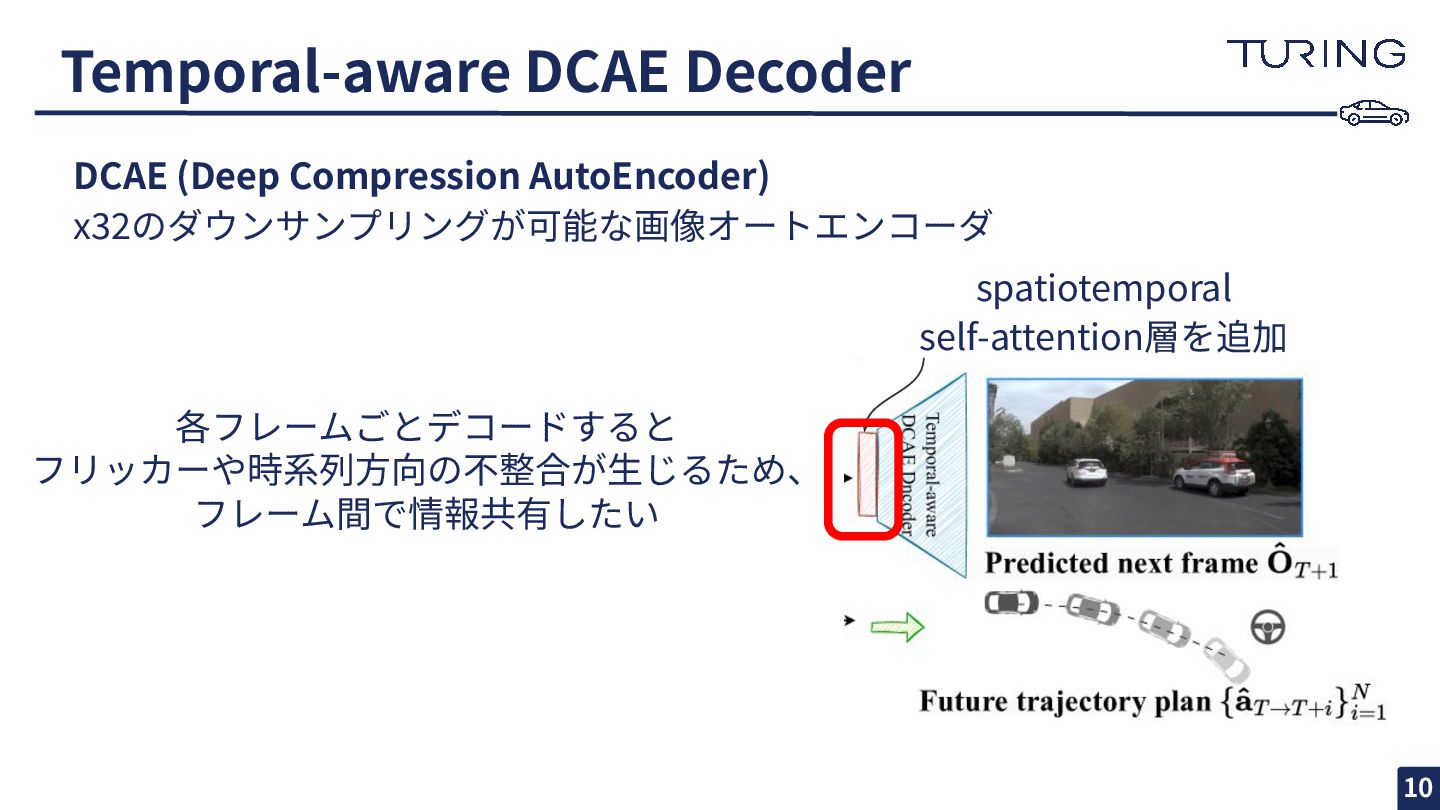
Temporal-aware DCAE Decoder spatiotemporal self-attention層を追加 各フレームごとデコードすると フリッカーや時系列⽅向の不整合が⽣じるため、 フレーム間で情報共有したい DCAE (Deep
Compression AutoEncoder) x32のダウンサンプリングが可能な画像オートエンコーダ 10
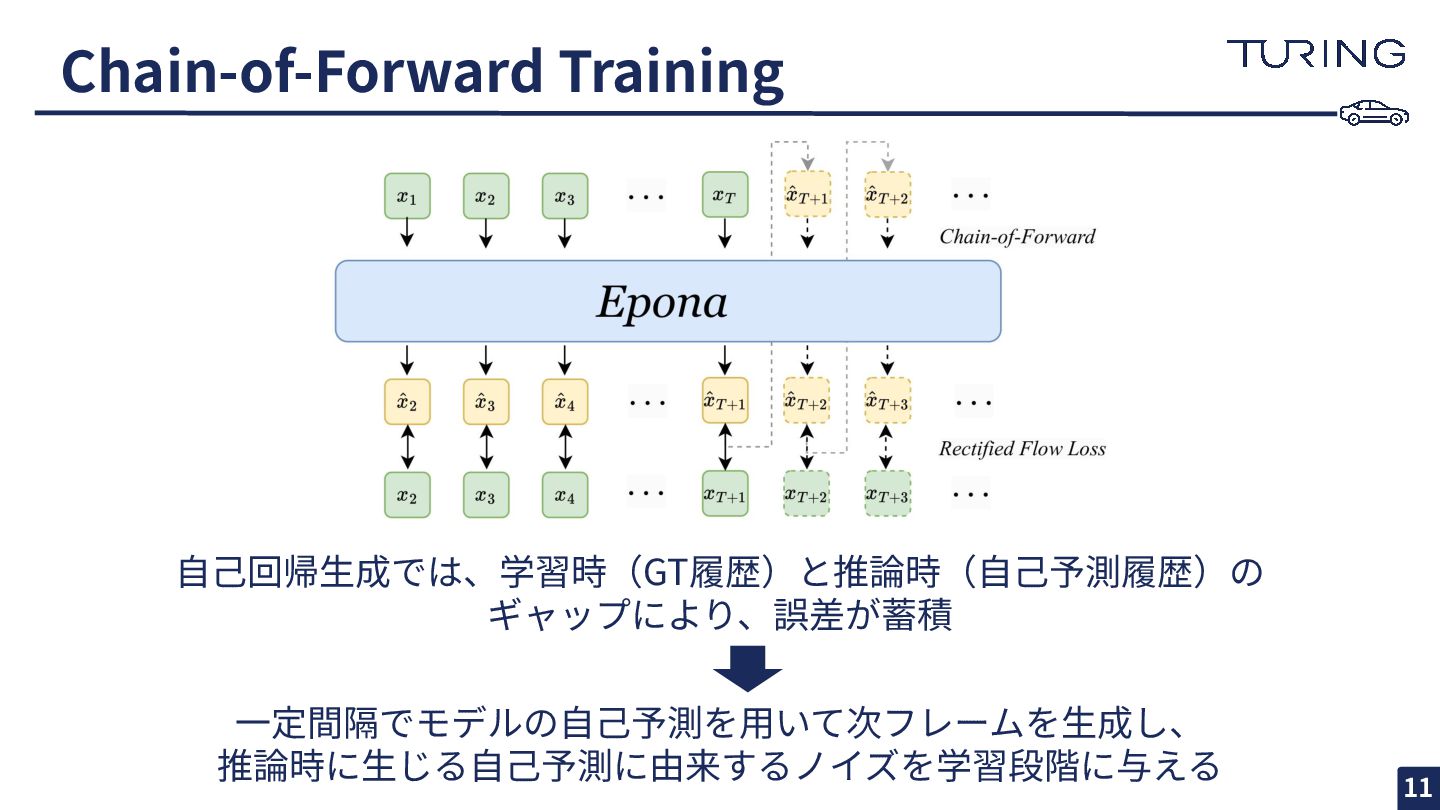
Chain-of-Forward Training ⾃⼰回帰⽣成では、学習時(GT履歴)と推論時(⾃⼰予測履歴)の ギャップにより、誤差が蓄積 ⼀定間隔でモデルの⾃⼰予測を⽤いて次フレームを⽣成し、 推論時に⽣じる⾃⼰予測に由来するノイズを学習段階に与える 11
Experiments
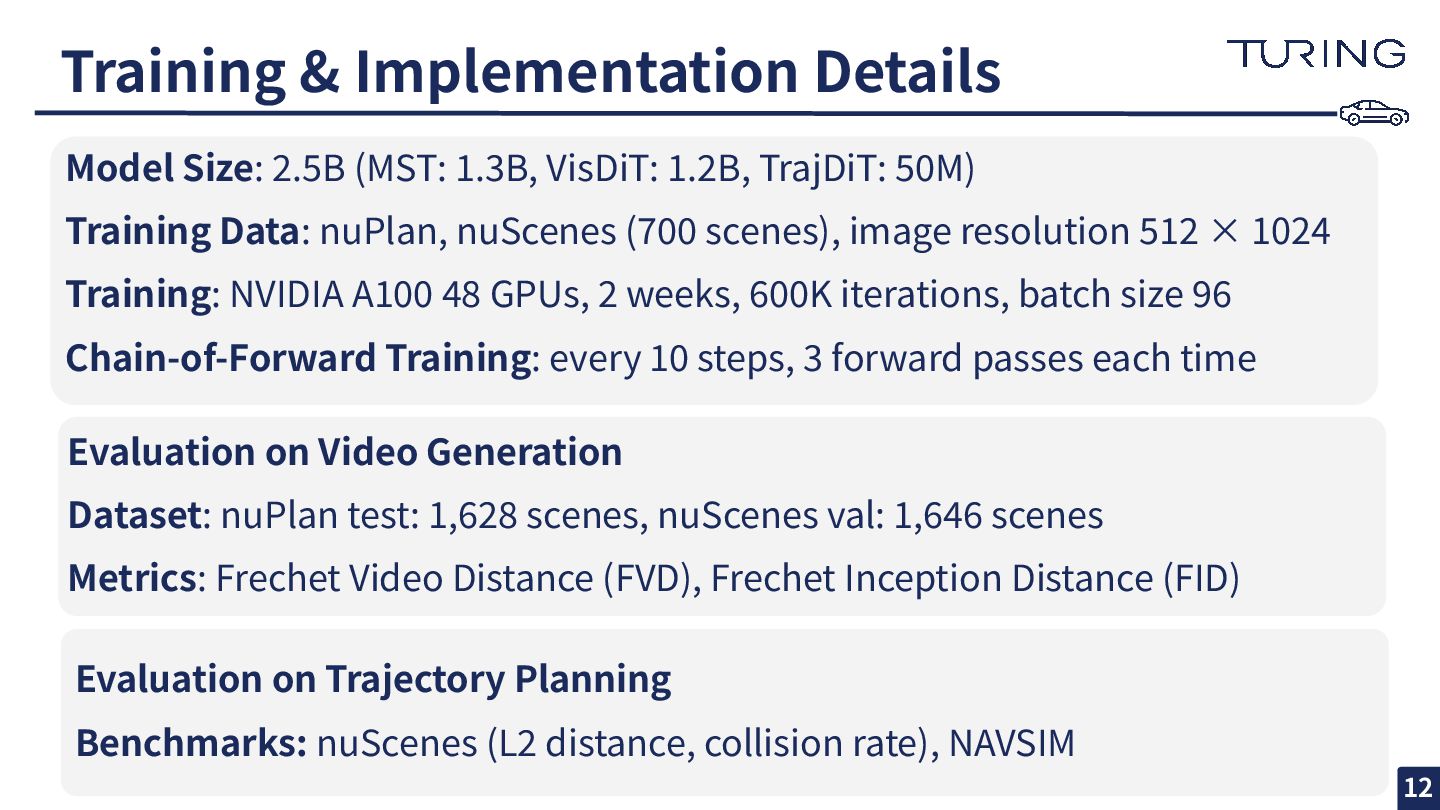
Model Size: 2.5B (MST: 1.3B, VisDiT: 1.2B, TrajDiT: 50M) Training
Data: nuPlan, nuScenes (700 scenes), image resolution 512 × 1024 Training: NVIDIA A100 48 GPUs, 2 weeks, 600K iterations, batch size 96 Chain-of-Forward Training: every 10 steps, 3 forward passes each time Training & Implementation Details Evaluation on Video Generation Dataset: nuPlan test: 1,628 scenes, nuScenes val: 1,646 scenes Metrics: Frechet Video Distance (FVD), Frechet Inception Distance (FID) Evaluation on Trajectory Planning Benchmarks: nuScenes (L2 distance, collision rate), NAVSIM 12
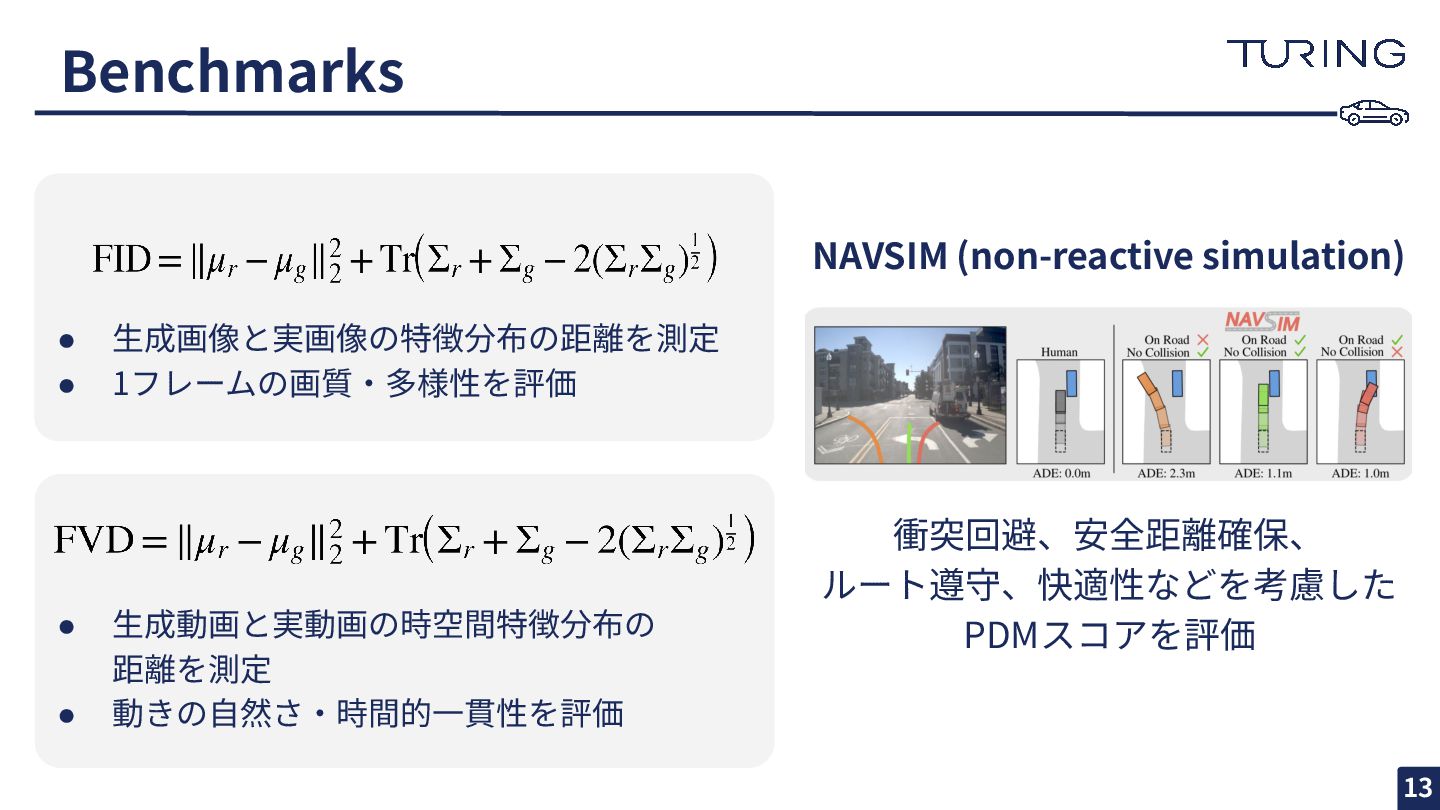
Benchmarks NAVSIM (non-reactive simulation) • ⽣成画像と実画像の特徴分布の距離を測定 • 1フレームの画質‧多様性を評価 • ⽣成動画と実動画の時空間特徴分布の
距離を測定 • 動きの⾃然さ‧時間的⼀貫性を評価 衝突回避、安全距離確保、 ルート遵守、快適性などを考慮した PDMスコアを評価 13
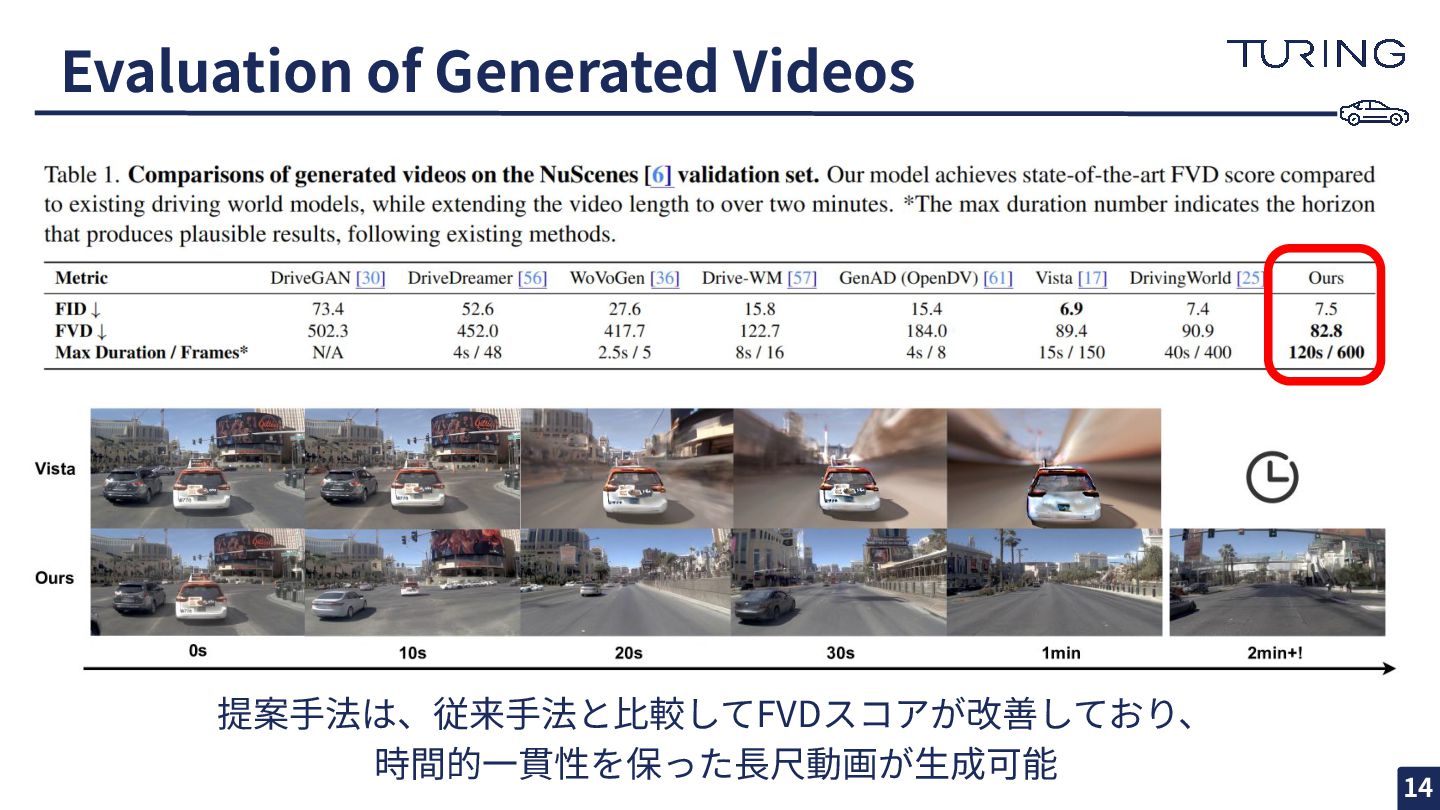
Evaluation of Generated Videos 提案⼿法は、従来⼿法と⽐較してFVDスコアが改善しており、 時間的⼀貫性を保った⻑尺動画が⽣成可能 14
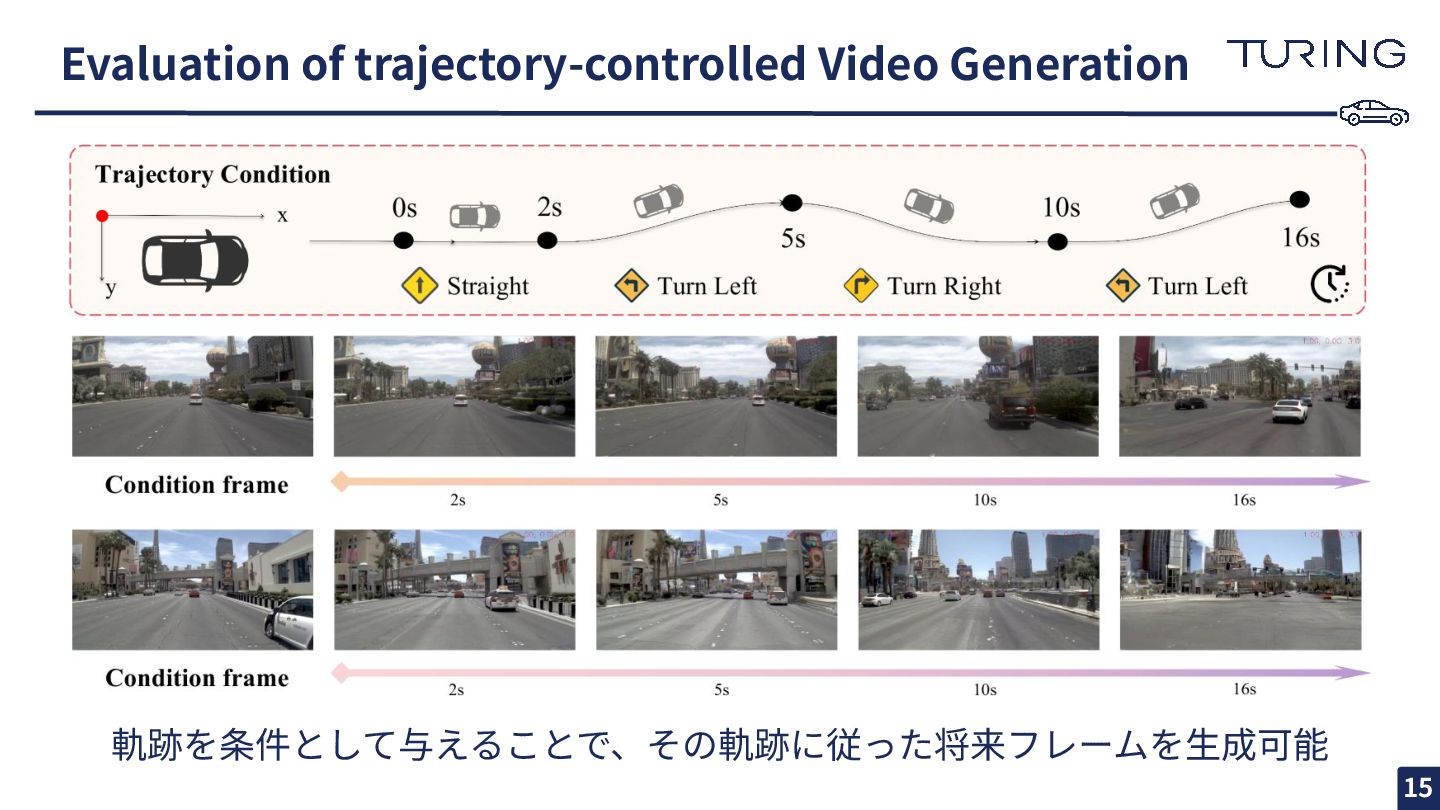
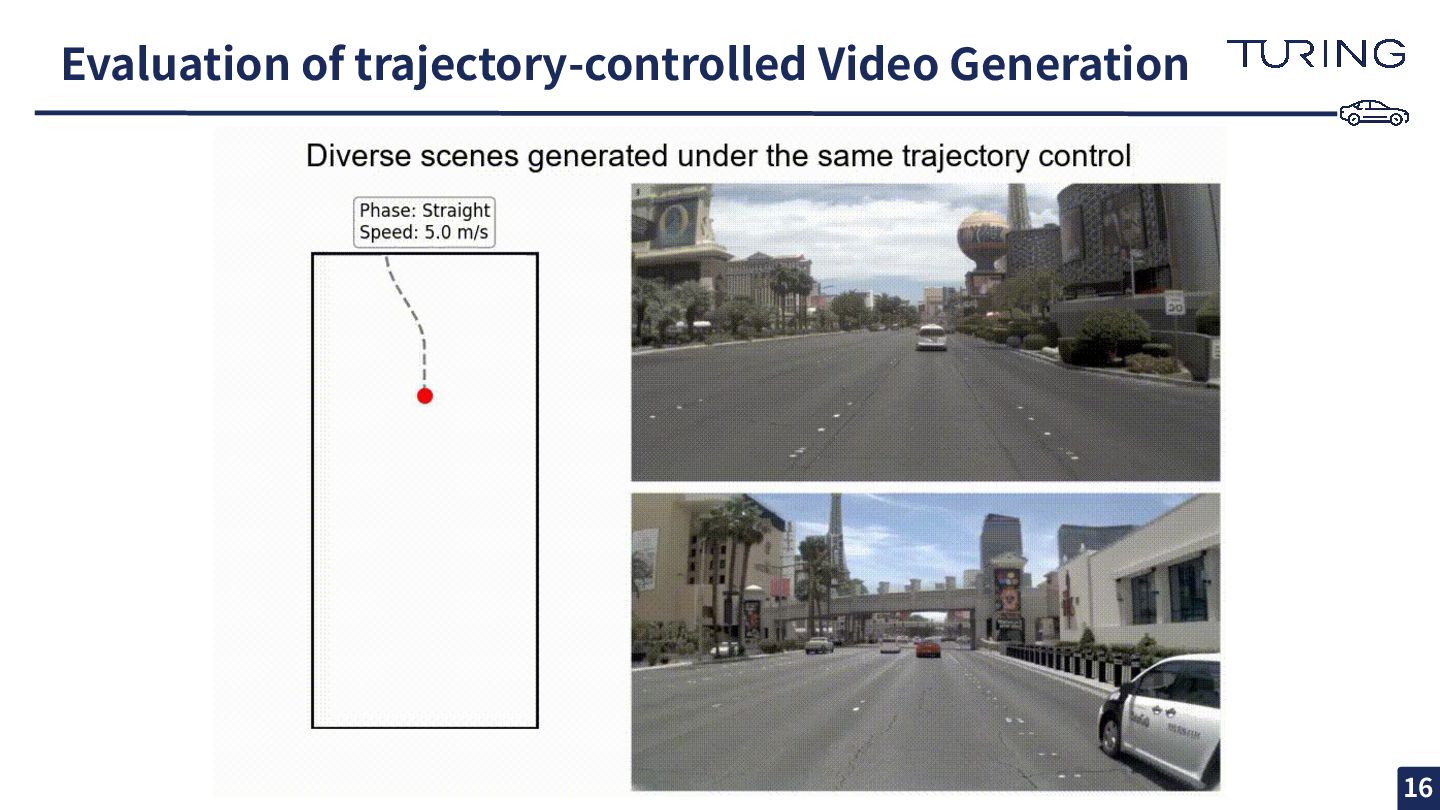
Evaluation of trajectory-controlled Video Generation 軌跡を条件として与えることで、その軌跡に従った将来フレームを⽣成可能 15
Evaluation of trajectory-controlled Video Generation 16
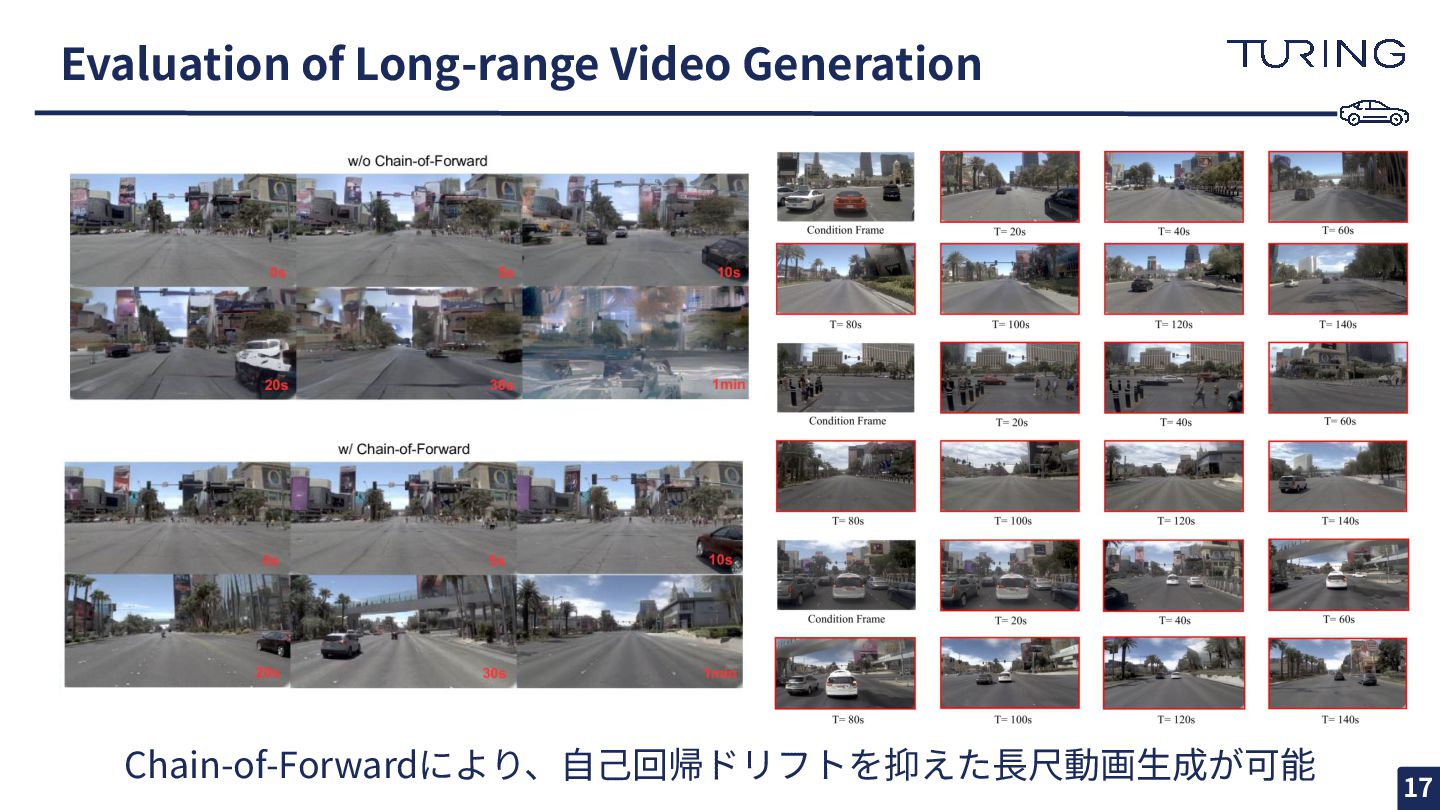
Chain-of-Forwardにより、⾃⼰回帰ドリフトを抑えた⻑尺動画⽣成が可能 Evaluation of Long-range Video Generation 17
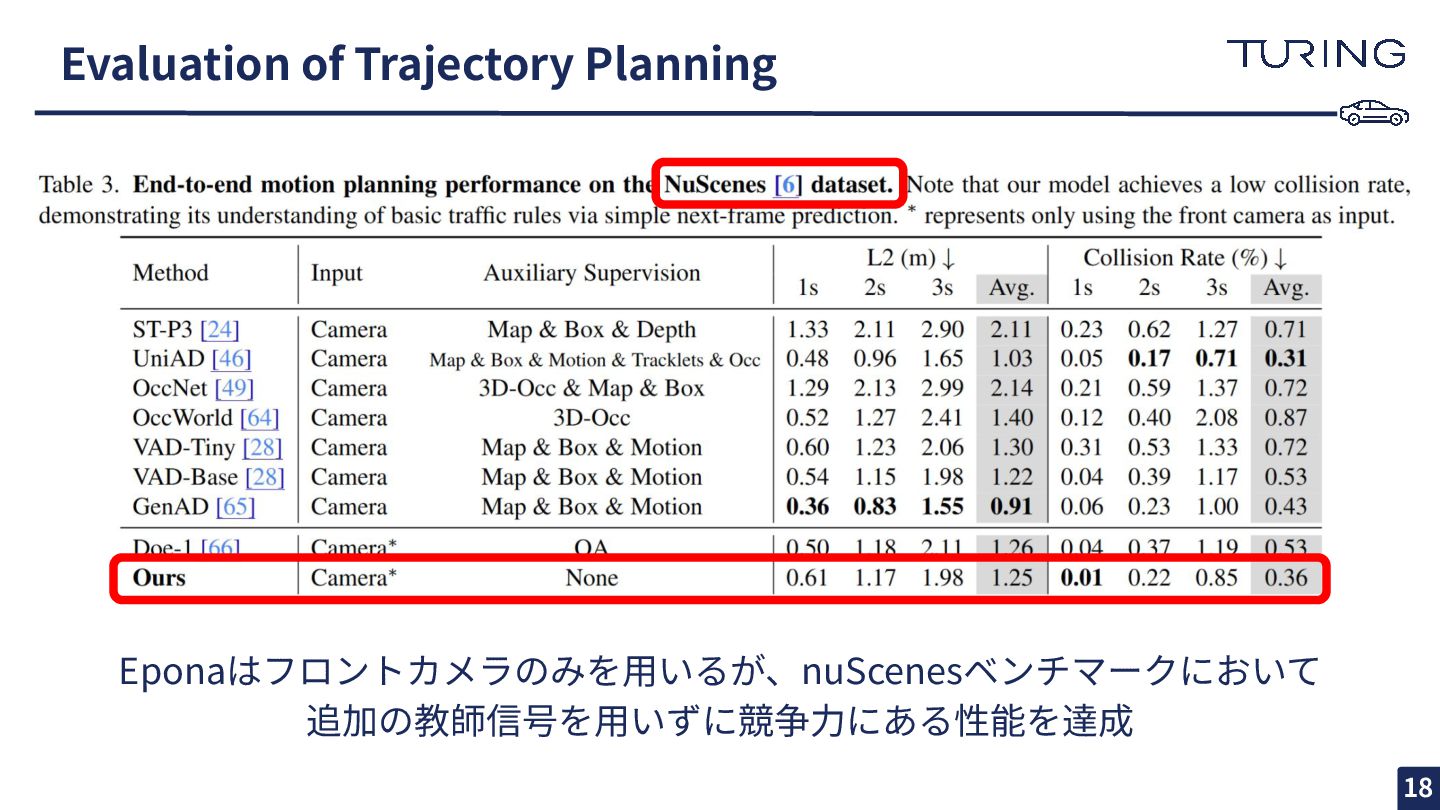
Evaluation of Trajectory Planning Eponaはフロントカメラのみを⽤いるが、nuScenesベンチマークにおいて 追加の教師信号を⽤いずに競争⼒にある性能を達成 18
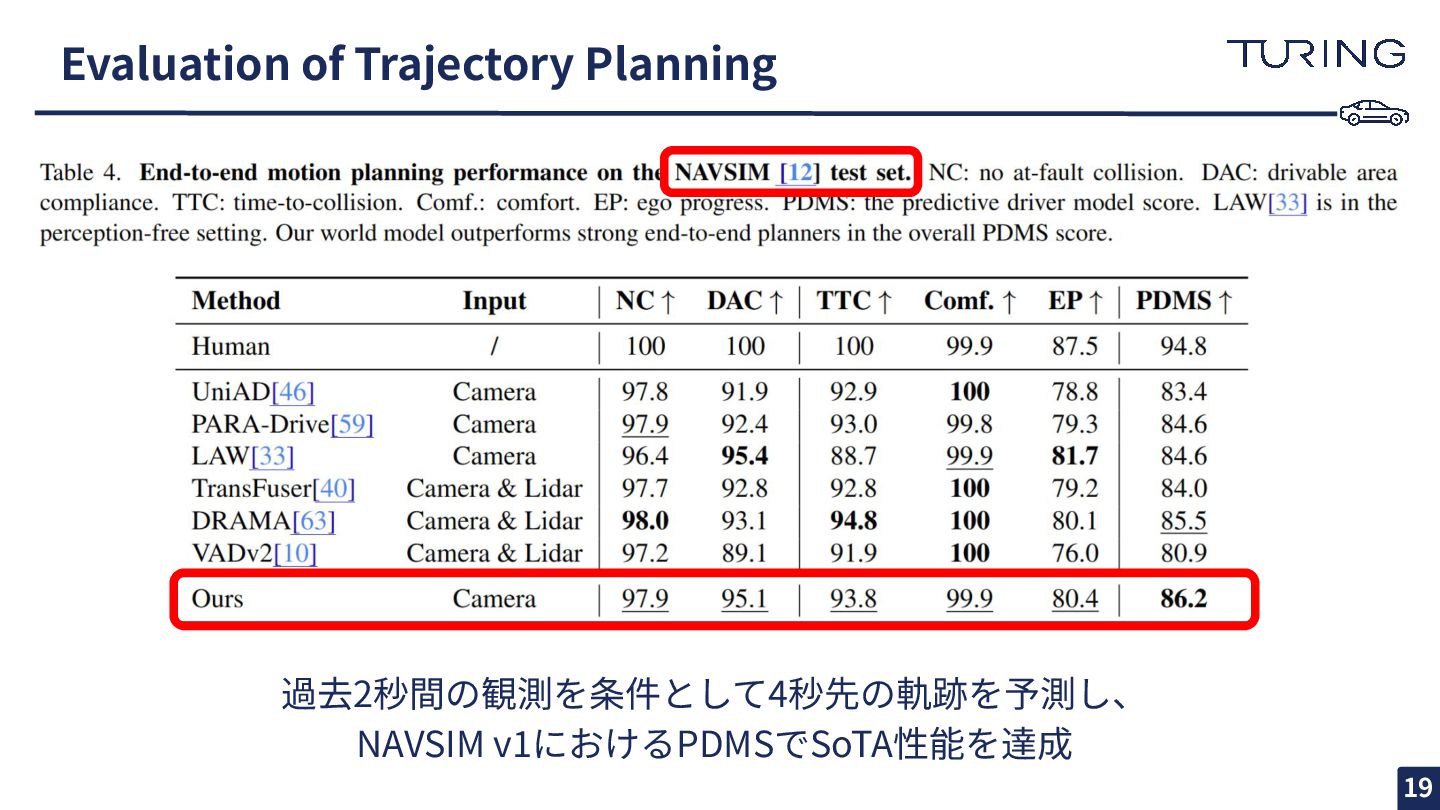
Evaluation of Trajectory Planning 過去2秒間の観測を条件として4秒先の軌跡を予測し、 NAVSIM v1におけるPDMSでSoTA性能を達成 19
Ablations
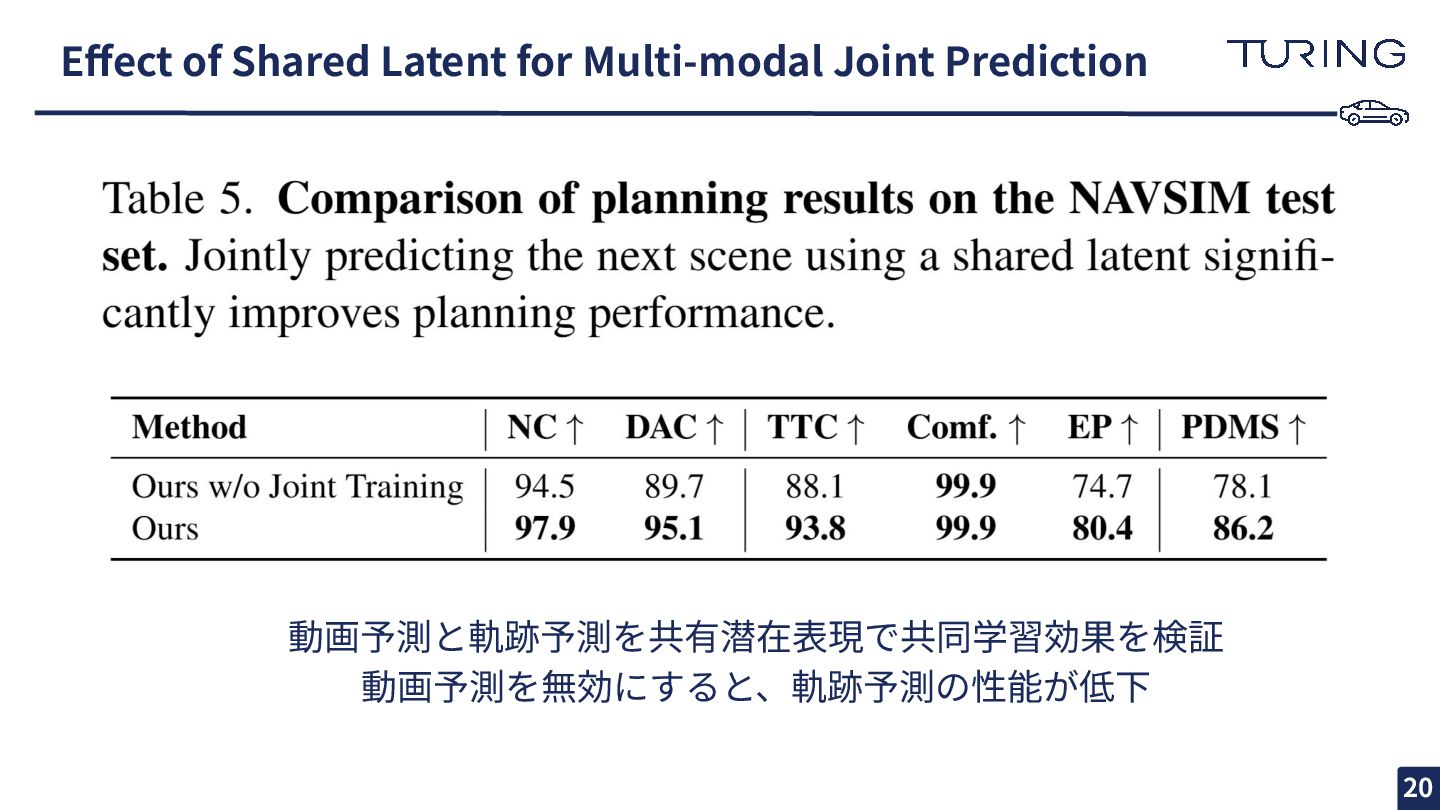
Effect of Shared Latent for Multi-modal Joint Prediction 動画予測と軌跡予測を共有潜在表現で共同学習効果を検証 動画予測を無効にすると、軌跡予測の性能が低下
20
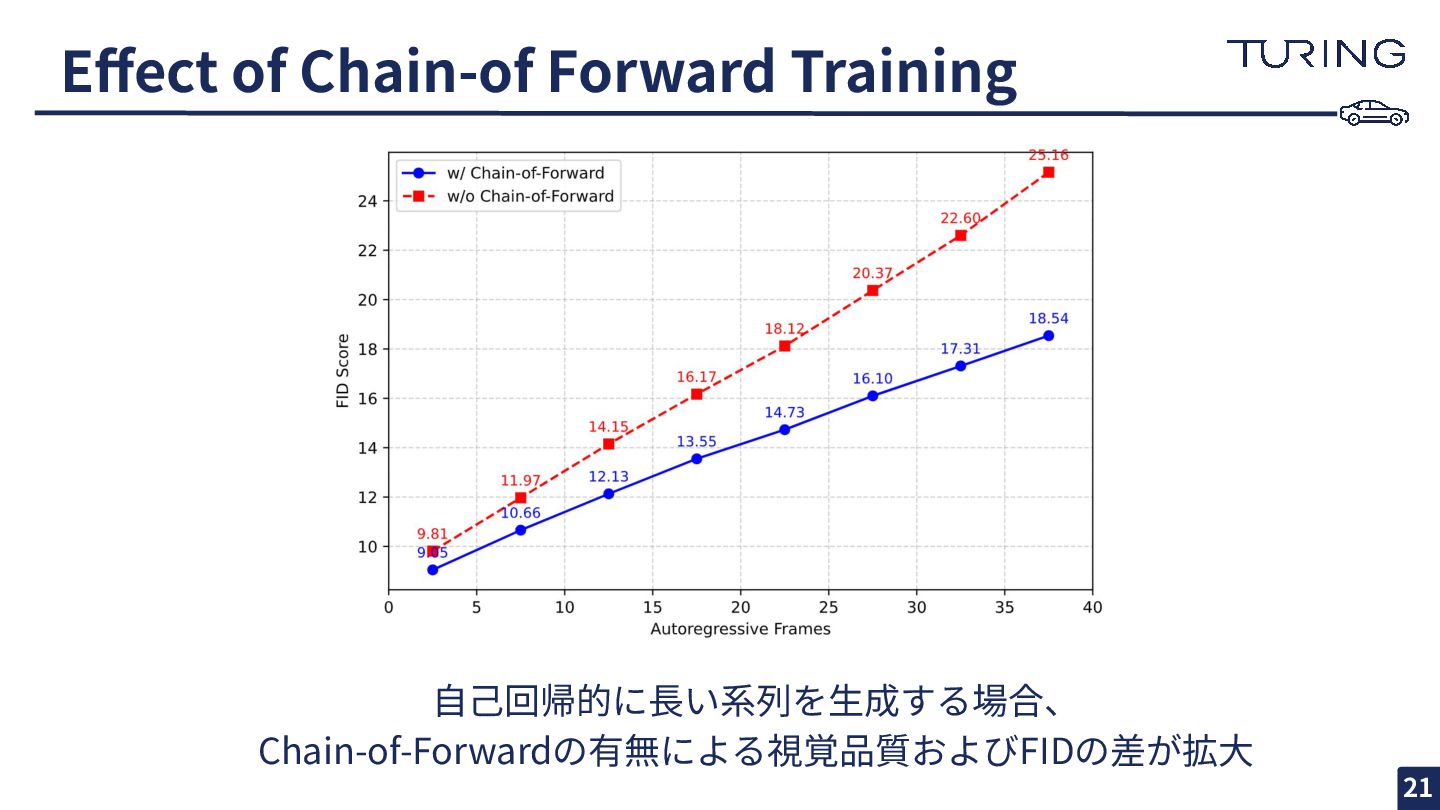
Effect of Chain-of Forward Training ⾃⼰回帰的に⻑い系列を⽣成する場合、 Chain-of-Forwardの有無による視覚品質およびFIDの差が拡⼤ 21
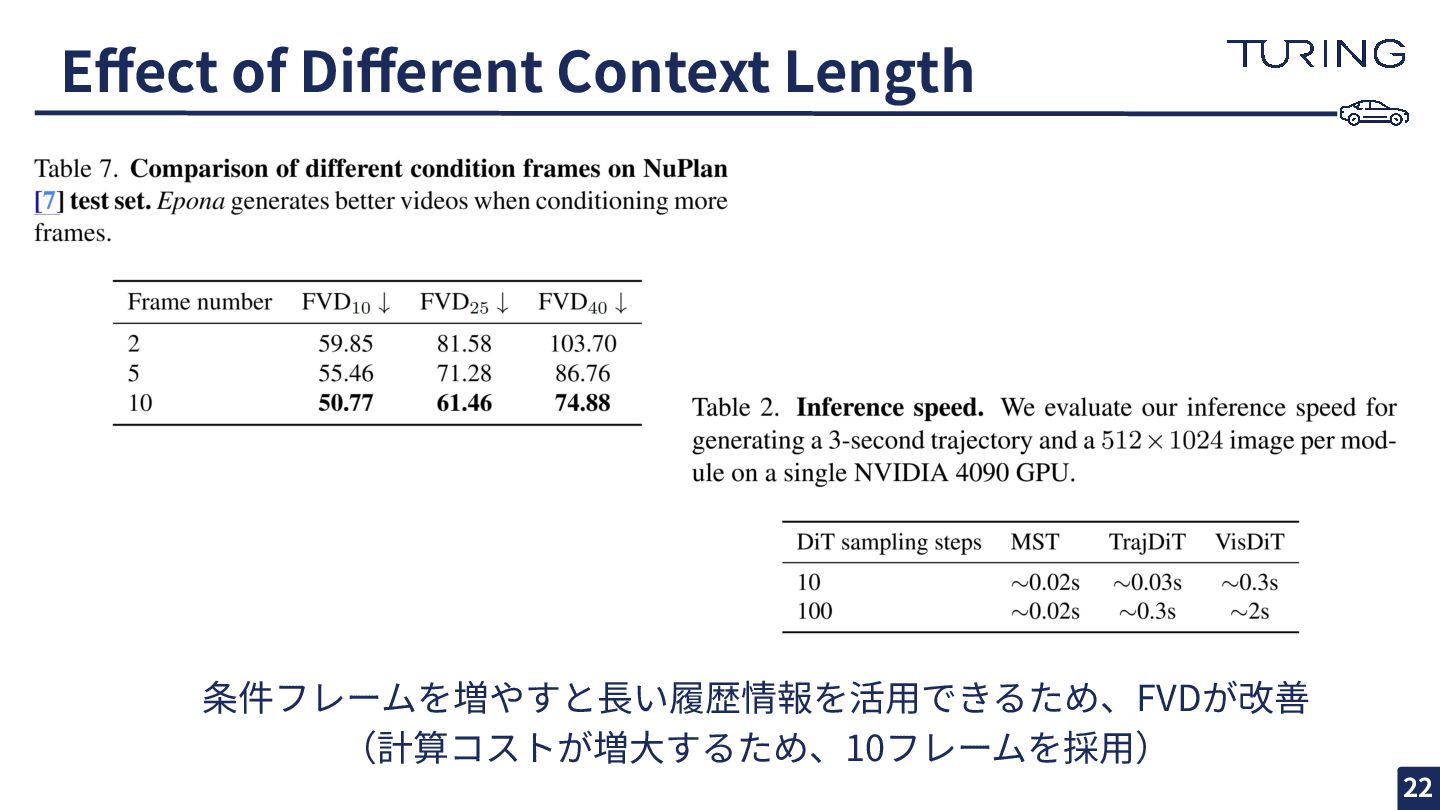
Effect of Different Context Length 条件フレームを増やすと⻑い履歴情報を活⽤できるため、FVDが改善 (計算コストが増⼤するため、10フレームを採⽤) 22
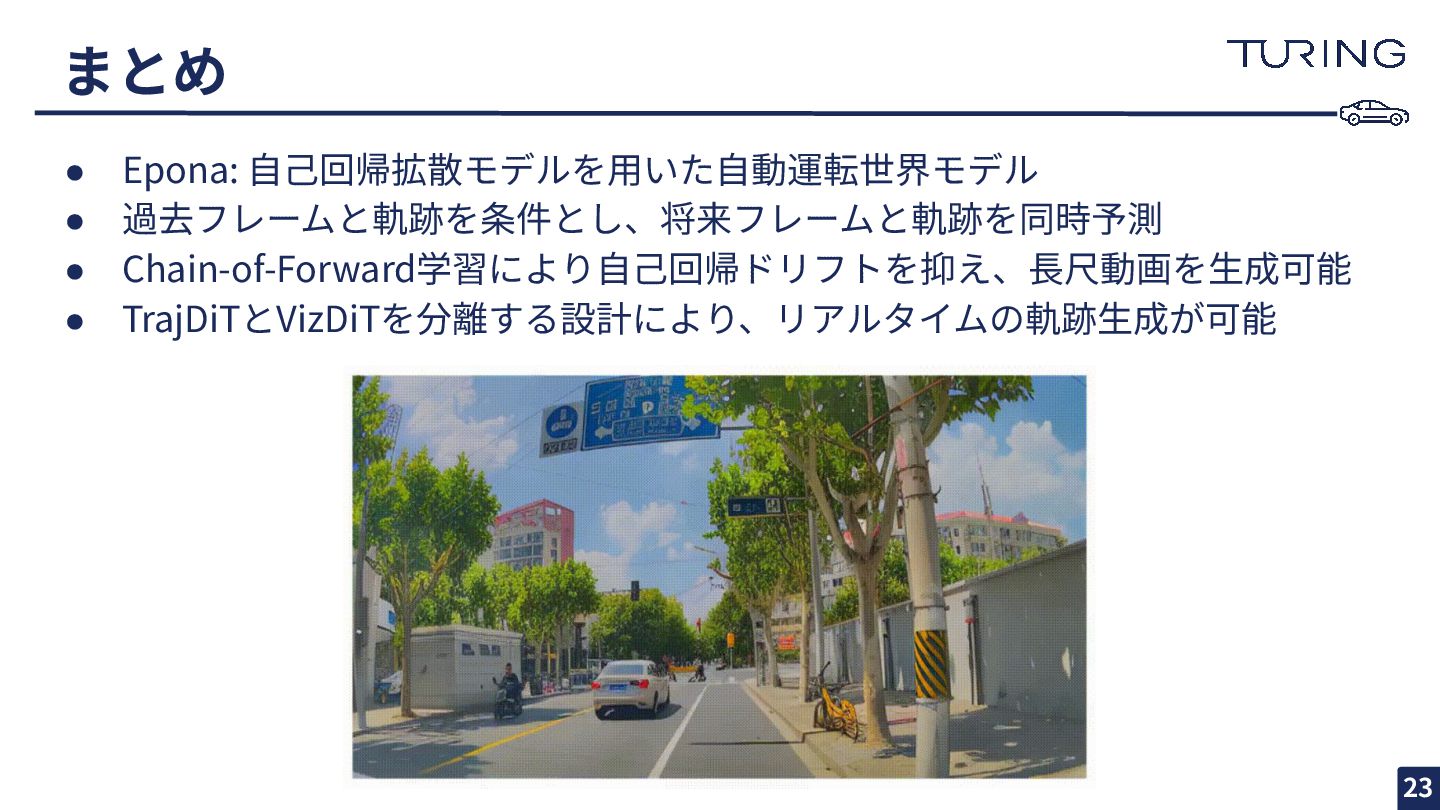
まとめ • Epona: ⾃⼰回帰拡散モデルを⽤いた⾃動運転世界モデル • 過去フレームと軌跡を条件とし、将来フレームと軌跡を同時予測 • Chain-of-Forward学習により⾃⼰回帰ドリフトを抑え、⻑尺動画を⽣成可能 • TrajDiTとVizDiTを分離する設計により、リアルタイムの軌跡⽣成が可能
23
None
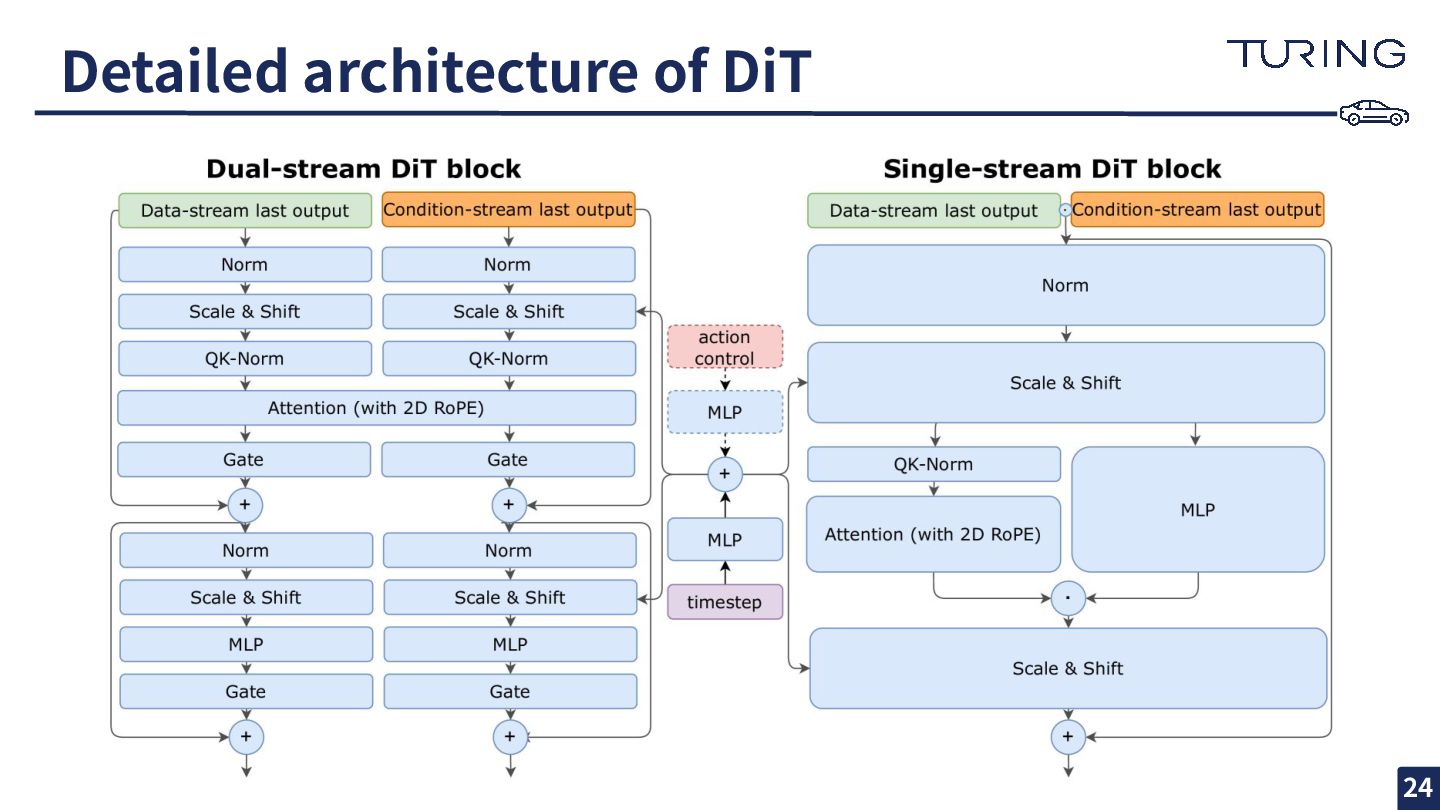
Detailed architecture of DiT 24
More Decks by Kento Sasaki
See All by Kento Sasaki
大規模言語モデルを用いた日本語視覚言語モデルの評価方法とベースラインモデルの提案 【MIRU 2024】
kentosasaki
3
930
Generative Predictive Model for Autonomous Driving 第61回 コンピュータビジョン勉強会@関東 (後編)
kentosasaki
0
410
Other Decks in Research
See All in Research
[UAI2026, Tutorial Talk] Tensor Networks for Density Estimation: The merits of low-rank structures, tractable inference, and uncertainty quantification
gkazunii
0
130
[webinaire du Ciirpo] Agnelages plein air : des éleveurs partagent leurs pratiques
institutdelelevage
PRO
0
350
Hitting the buffers
beale
0
420
Vers un système bovin allaitant multiperformant :leviers actionnés et trajectoire de réduction de l'empreinte carbone à travers 4 années d'expérimentation à FERM'INOV
institutdelelevage
PRO
0
150
Evaluation génomique des femelles laitières croisées : comprendre la méthode pour accompagner les éleveurs à son utilisation
institutdelelevage
PRO
0
230
論文読み会 SNLP2026 Tau2-Bench: Evaluating Conversational Agents in a Dual-Control Environment
s_mizuki_nlp
0
360
Karkada さんの論文 × 2 の紹介: (1) Closed-Form Training Dynamics Reveal Learned Features and Linear Structure in Word2Vec-like Models, (2) Symmetry in language statistics shapes the geometry of model representations
eumesy
PRO
2
2k
就労支援の現場での生成AI活用
enochan
0
220
ros2-perf-multihost: 分散システムにおける客観的なアーキテクチャ評価フレームワーク
takasehideki
0
360
ICAITD 2026 Oral Presentation
rikkabotan7
0
150
AI時代に学術情報をどう探し、どう使うか: 研究の様々な場面と一研究者の経験から
masao
0
240
L’albédo:levier d’atténuation du changement climatique dans les systèmes fourragers
institutdelelevage
PRO
0
170
Featured
See All Featured
Technical Leadership for Architectural Decision Making
baasie
4
660
Building a A Zero-Code AI SEO Workflow
portentint
PRO
0
850
Connecting the Dots Between Site Speed, User Experience & Your Business [WebExpo 2025]
tammyeverts
11
1.1k
AI in Enterprises - Java and Open Source to the Rescue
ivargrimstad
0
1.6k
職位にかかわらず全員がリーダーシップを発揮するチーム作り / Building a team where everyone can demonstrate leadership regardless of position
madoxten
70
69k
How to make the Groovebox
asonas
2
2.6k
Noah Learner - AI + Me: how we built a GSC Bulk Export data pipeline
techseoconnect
PRO
0
500
CoffeeScript is Beautiful & I Never Want to Write Plain JavaScript Again
sstephenson
162
16k
The Language of Interfaces
destraynor
162
27k
The AI Revolution Will Not Be Monopolized: How open-source beats economies of scale, even for LLMs
inesmontani
PRO
3
3.8k
The Myth of the Modular Monolith - Day 2 Keynote - Rails World 2024
eileencodes
28
3.8k
Reflections from 52 weeks, 52 projects
jeffersonlam
356
22k


 kentosasaki
 gkazunii
 institutdelelevage
 beale
 s_mizuki_nlp
 eumesy
 enochan
 takasehideki
 rikkabotan7
 masao
 baasie
 portentint
 tammyeverts
 ivargrimstad
 madoxten
 asonas
 techseoconnect
 sstephenson
 destraynor
 inesmontani
 eileencodes
 jeffersonlam