Share
Embed
Decaton: High performance task processing with Kafka
Haruki Okada
LINE Z Part Team Software Engineer
https://linedevday.linecorp.com/2020/ja/sessions/5340
https://linedevday.linecorp.com/2020/en/sessions/5340
LINE DevDay 2020
November 26, 2020
Transcript
61 slides
-
Speaker › Software engineer at LINE Z-Part team › Developing
company-wide Apache Kafka platform › Decaton maintainer › Haruki Okada -
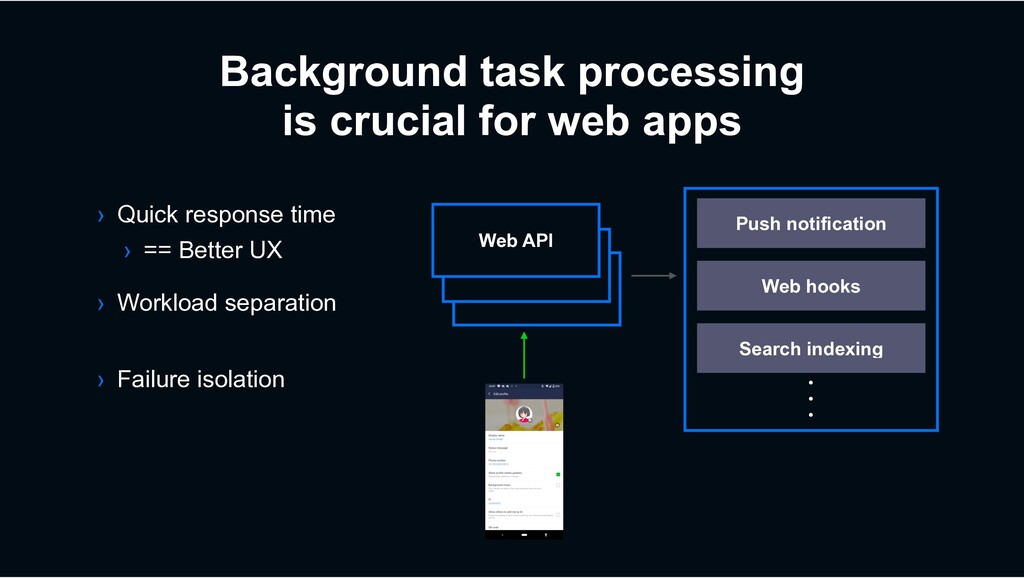
› Workload separation › Quick response time › == Better
UX Background task processing is crucial for web apps › Failure isolation Web API Web API Push notification Web hooks Search indexing ɾ ɾ ɾ -
Process massive background tasks At maximal resource utilization efficiency Without
spoiling task processing reliability Background task processing at scale is challenging -
Decaton is: › Decaton is battle tested in LINE service
development for years › “High performance” is the most important feature Decaton provides › Kafka consumer framework › Aimed to implement reliable task processing on it -
Agenda › Why we developed Decaton › How Decaton works
› Various engineering efforts we made › To make it high-performant -
Apache Kafka at LINE › Distributed streaming platform › One
of the most popular middleware in LINE › Over 90 services use company-wide Kafka platform developed by our team -
Typical use case of Kafka at LINE › Background task
processing Task processor Web API Web API Kafka Produce tasks including external I/O Process in background Storage -
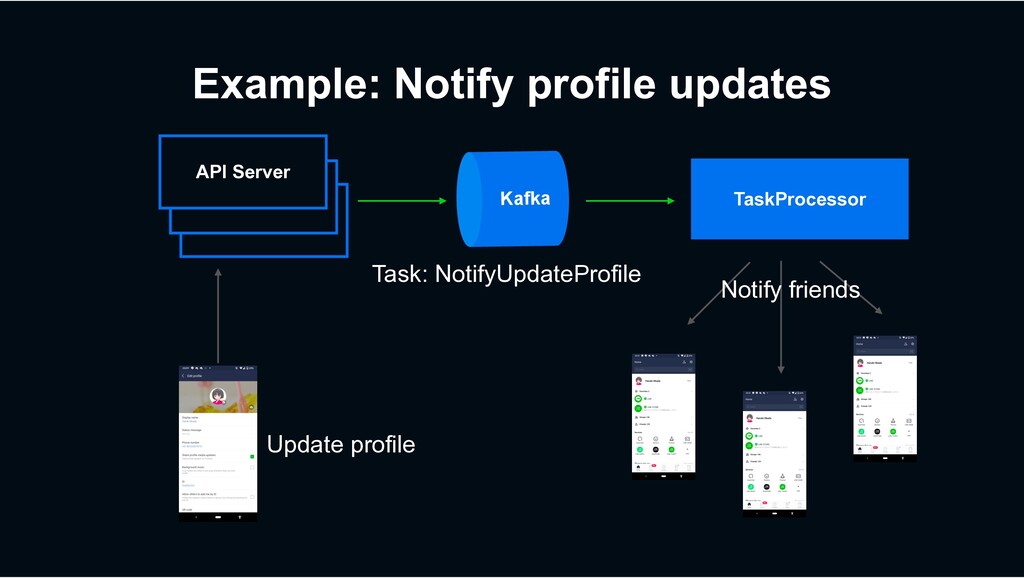
Example: Notify profile updates TaskProcessor Web API API Server Kafka
Update profile Notify friends Task: NotifyUpdateProfile -
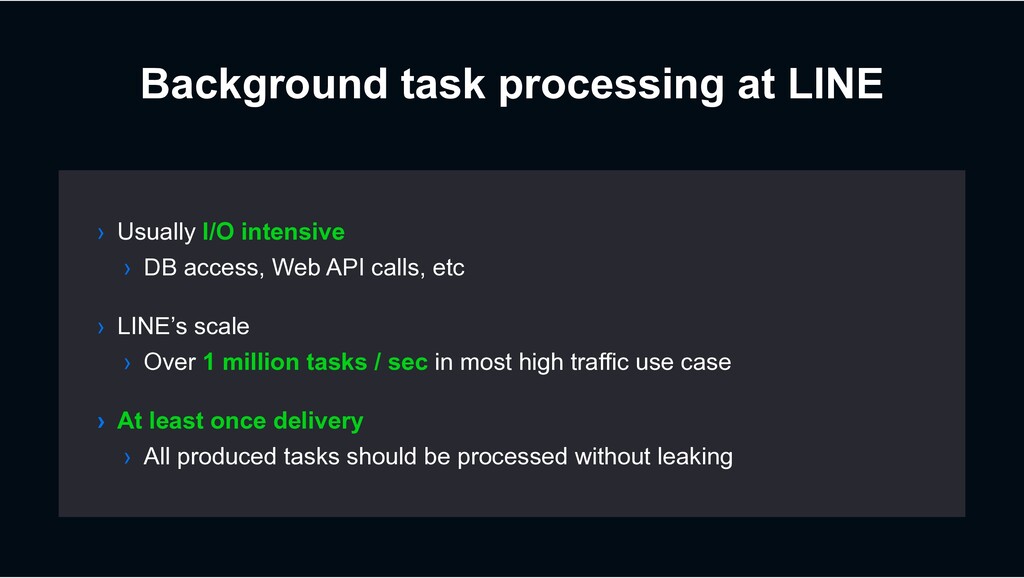
Background task processing at LINE › LINE’s scale › Over
1 million tasks / sec in most high traffic use case › At least once delivery › All produced tasks should be processed without leaking › Usually I/O intensive › DB access, Web API calls, etc -
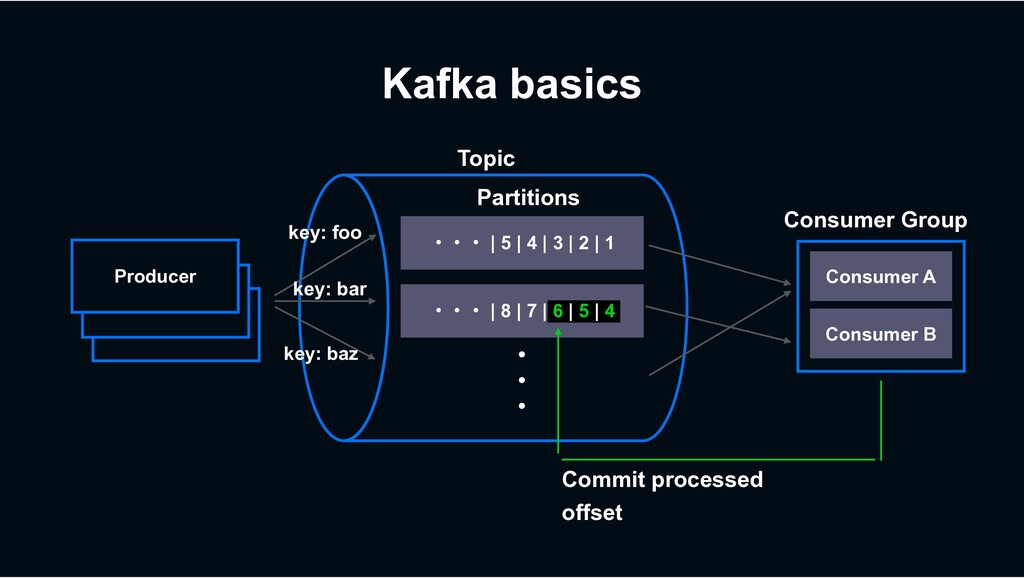
Kafka basics Topic ɾɾɾ | 5 | 4 | 3
| 2 | 1 ɾɾɾ | 8 | 7 | 6 | 5 | 4 ɾ ɾ ɾ Consumer A Consumer B Consumer Group Web API Producer Partitions Commit processed offset key: foo key: bar key: baz -
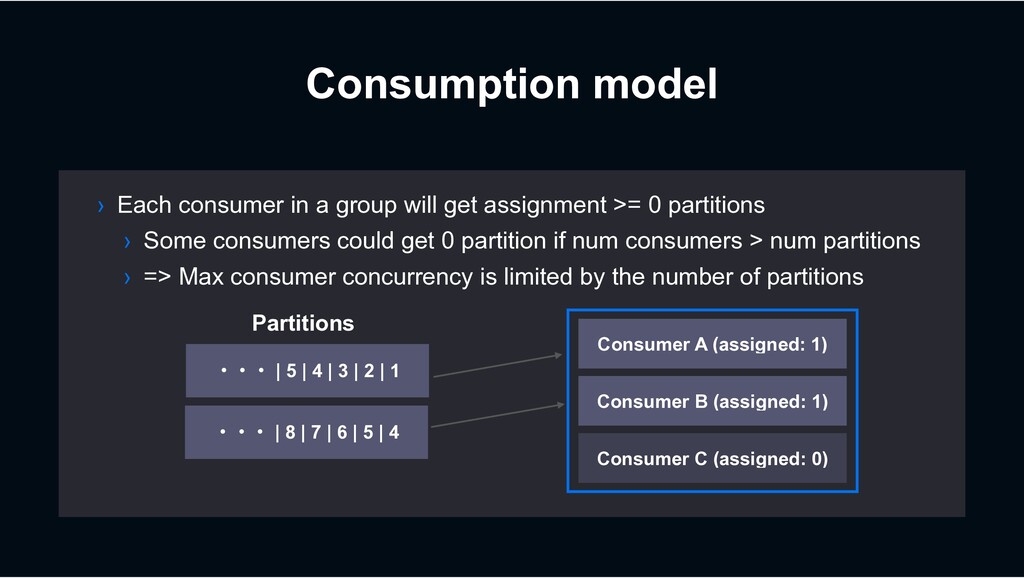
Consumption model › Each consumer in a group will get
assignment >= 0 partitions › Some consumers could get 0 partition if num consumers > num partitions › => Max consumer concurrency is limited by the number of partitions ɾɾɾ | 5 | 4 | 3 | 2 | 1 Consumer A (assigned: 1) Consumer B (assigned: 1) ɾɾɾ | 8 | 7 | 6 | 5 | 4 Consumer C (assigned: 0) Partitions -
Basic consumer impl ɾɾɾ | 5 | 4 | 3
| 2 | 1 Partition Consumer thread poll() loop -
ɾɾɾ | 5 | 4 | 3 | 2 |
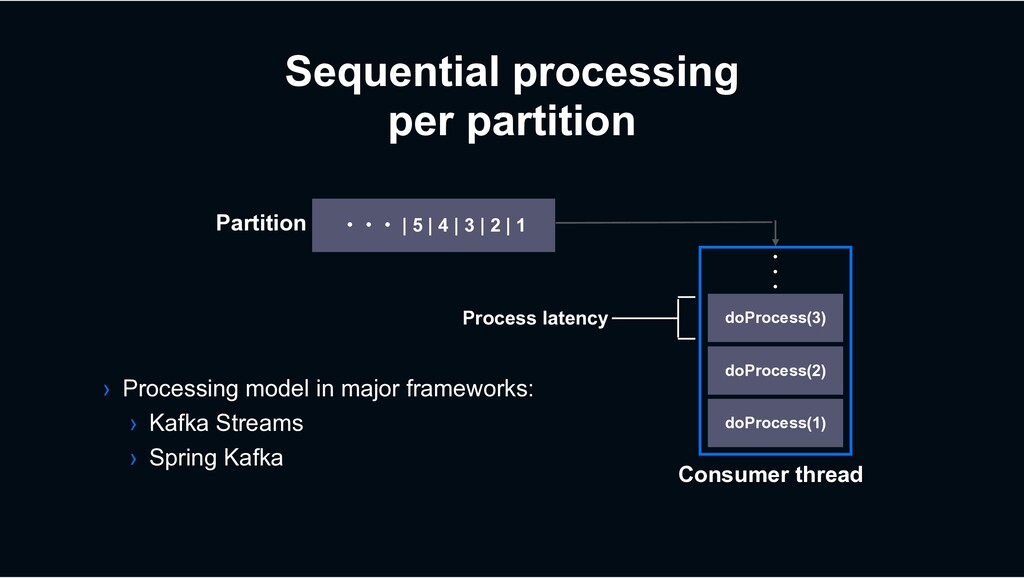
1 Partition doProcess(1) doProcess(2) doProcess(3) ɾ ɾ ɾ Consumer thread Process latency › Processing model in major frameworks: › Kafka Streams › Spring Kafka Sequential processing per partition -
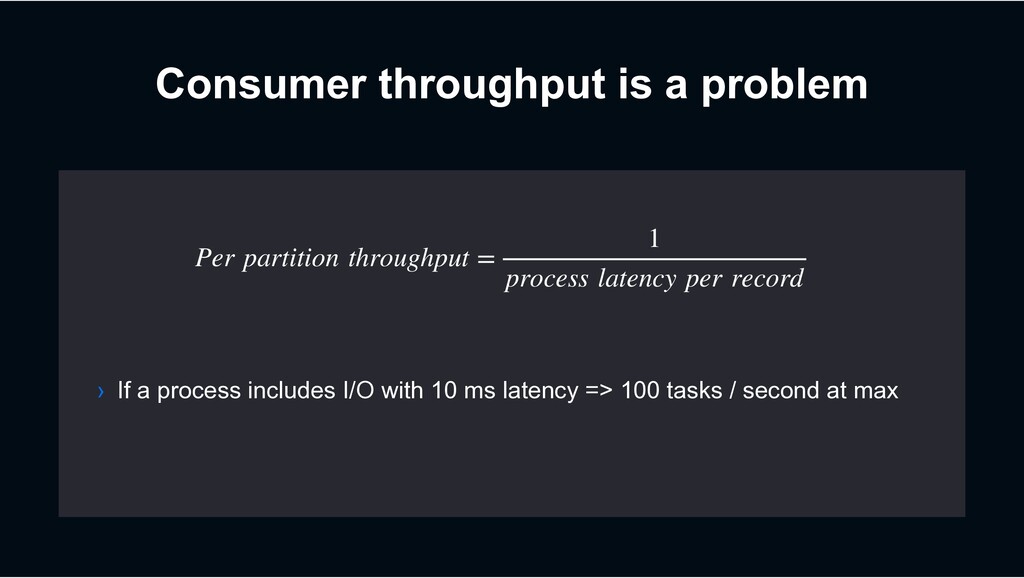
Consumer throughput is a problem Per partition throughput = 1
process latency per record › If a process includes I/O with 10 ms latency => 100 tasks / second at max -
Why not adding more partitions? › It’s difficult to estimate
required concurrency from the beginning › However, › Adding partitions often requires contacting cluster administrator › Adding partitions has side-effects › Message ordering breaks temporarily -
Why not adding more partitions? › Partitions are the unit
of consumer concurrency. At the same time: › The unit of producer batches => tends to generate smaller batches › Affects number of open file descriptors & mmapped files etc › Not preferable in LINE circumstance › Single, multi-tenant shared Kafka cluster -
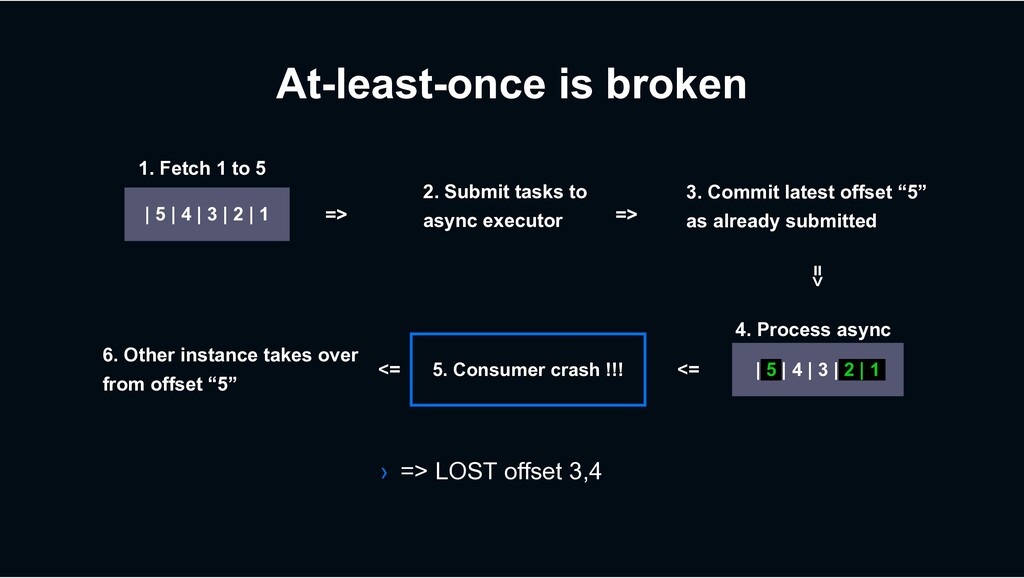
At-least-once is broken | 5 | 4 | 3 |
2 | 1 | 5 | 4 | 3 | 2 | 1 => 1. Fetch 1 to 5 2. Submit tasks to async executor => 3. Commit latest offset “5” as already submitted => 5. Consumer crash !!! => 6. Other instance takes over from offset “5” › => LOST offset 3,4 => 4. Process async -
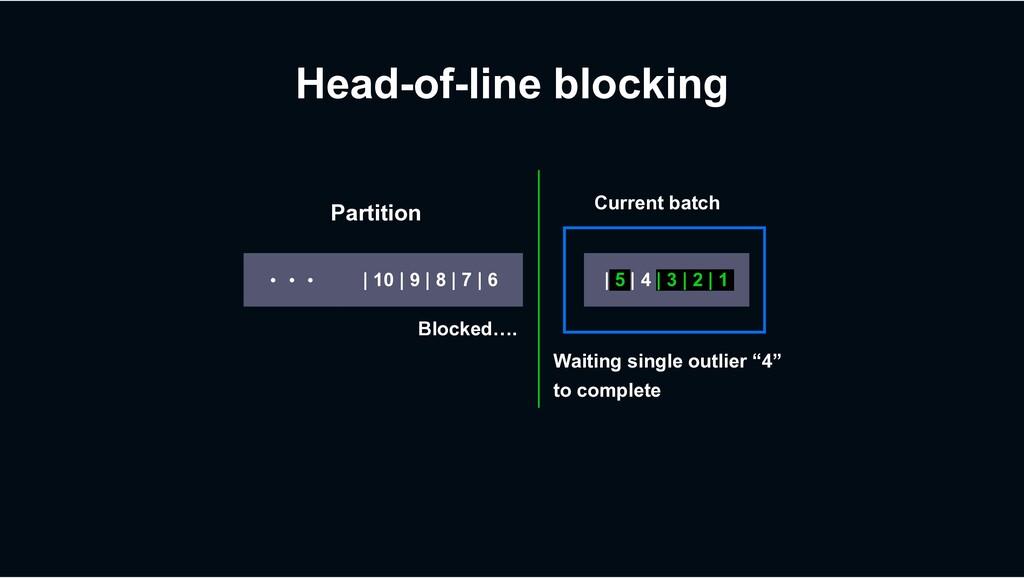
Head-of-line blocking | 5 | 4 | 3 | 2
| 1 | 10 | 9 | 8 | 7 | 6 ɾɾɾ Waiting single outlier “4” to complete Current batch Blocked…. Partition -
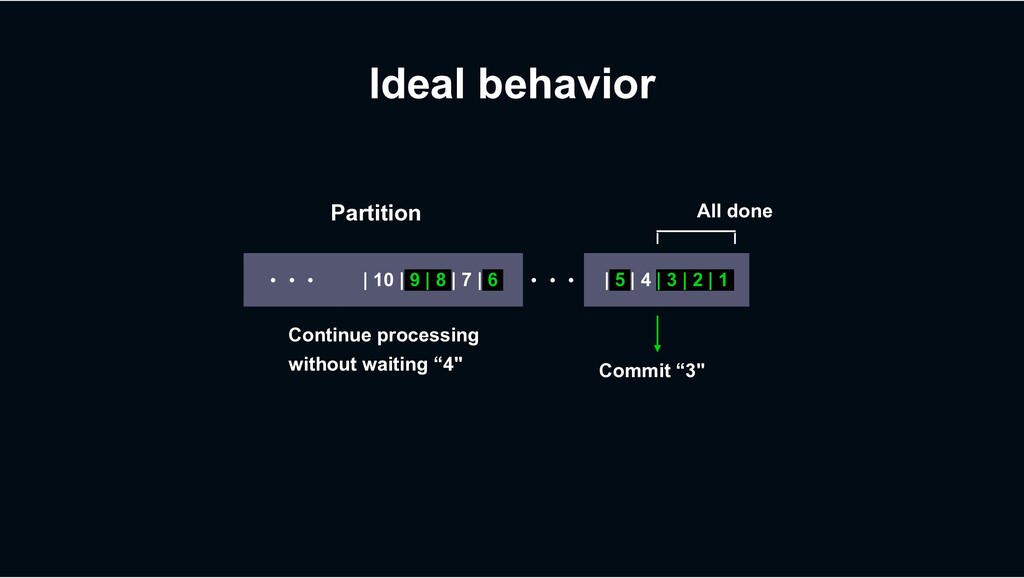
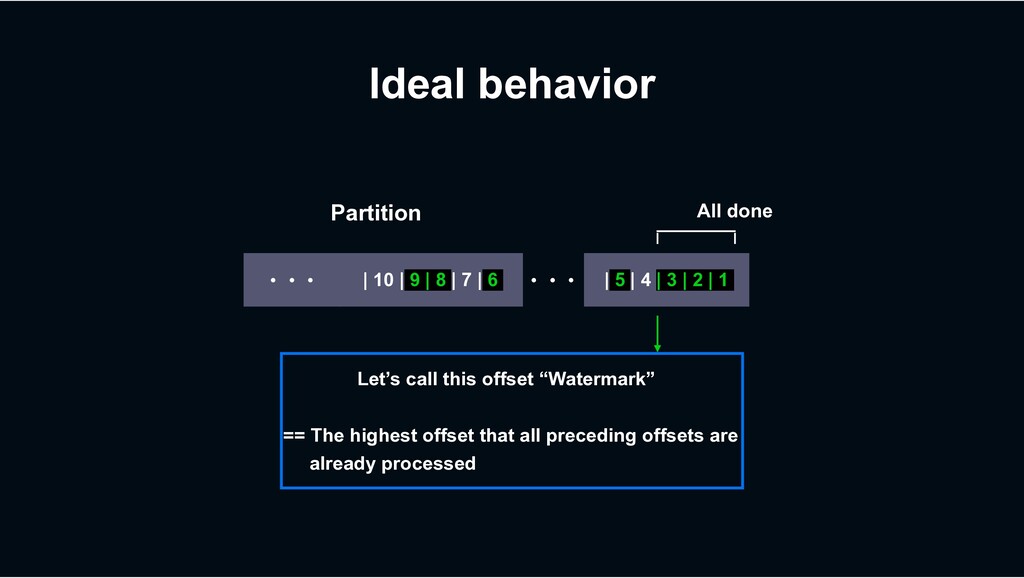
Ideal behavior | 5 | 4 | 3 | 2
| 1 | 10 | 9 | 8 | 7 | 6 ɾɾɾ Continue processing without waiting “4" Partition Commit “3" All done ɾɾɾ -
Ideal behavior | 5 | 4 | 3 | 2
| 1 | 10 | 9 | 8 | 7 | 6 ɾɾɾ Partition Let’s call this offset “Watermark” == The highest offset that all preceding offsets are already processed All done ɾɾɾ -
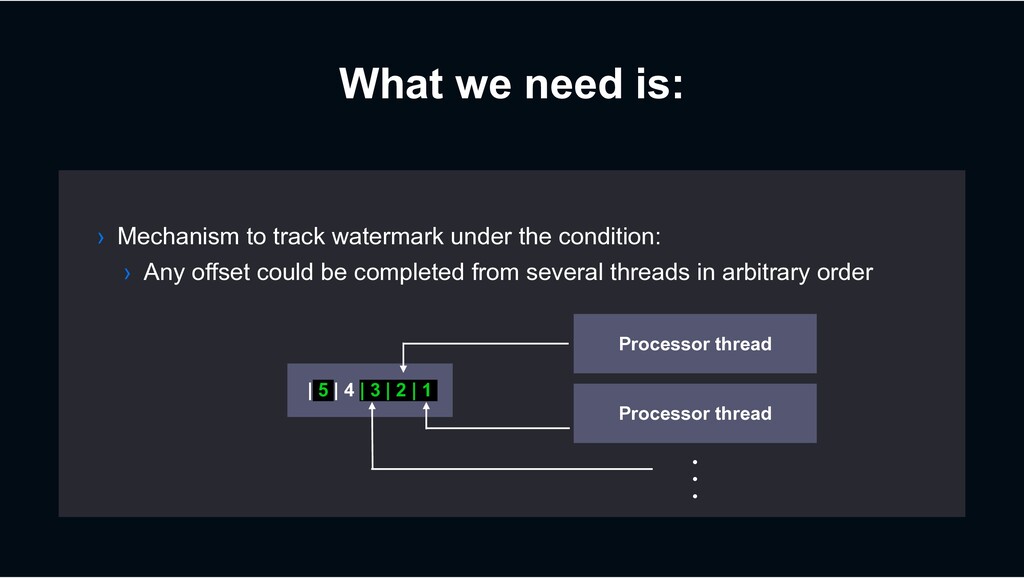
What we need is: › Mechanism to track watermark under
the condition: › Any offset could be completed from several threads in arbitrary order | 5 | 4 | 3 | 2 | 1 Processor thread Processor thread ɾ ɾ ɾ -
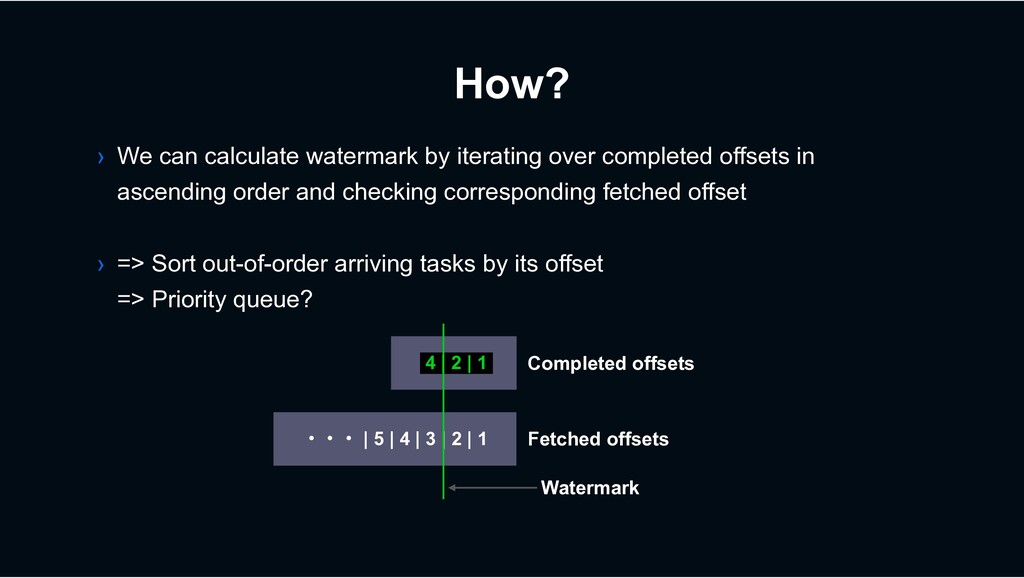
How? › We can calculate watermark by iterating over completed
offsets in ascending order and checking corresponding fetched offset › => Sort out-of-order arriving tasks by its offset => Priority queue? 4 | 2 | 1 ɾɾɾ | 5 | 4 | 3 | 2 | 1 Completed offsets Fetched offsets Watermark -
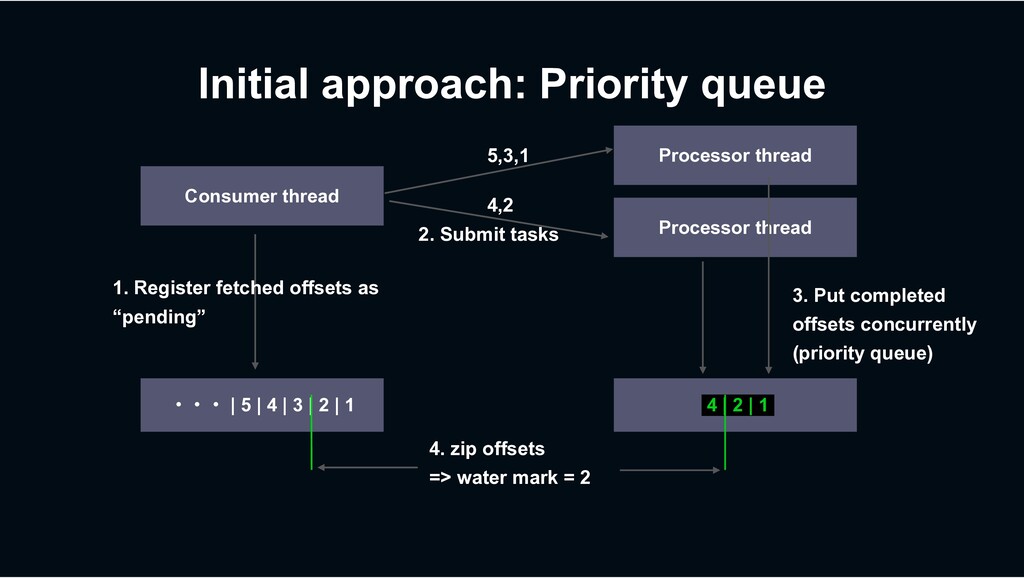
Initial approach: Priority queue 4 | 2 | 1 ɾɾɾ
| 5 | 4 | 3 | 2 | 1 Consumer thread 1. Register fetched offsets as “pending” Processor thread Processor thread 2. Submit tasks 5,3,1 4,2 3. Put completed offsets concurrently (priority queue) 4. zip offsets => water mark = 2 -
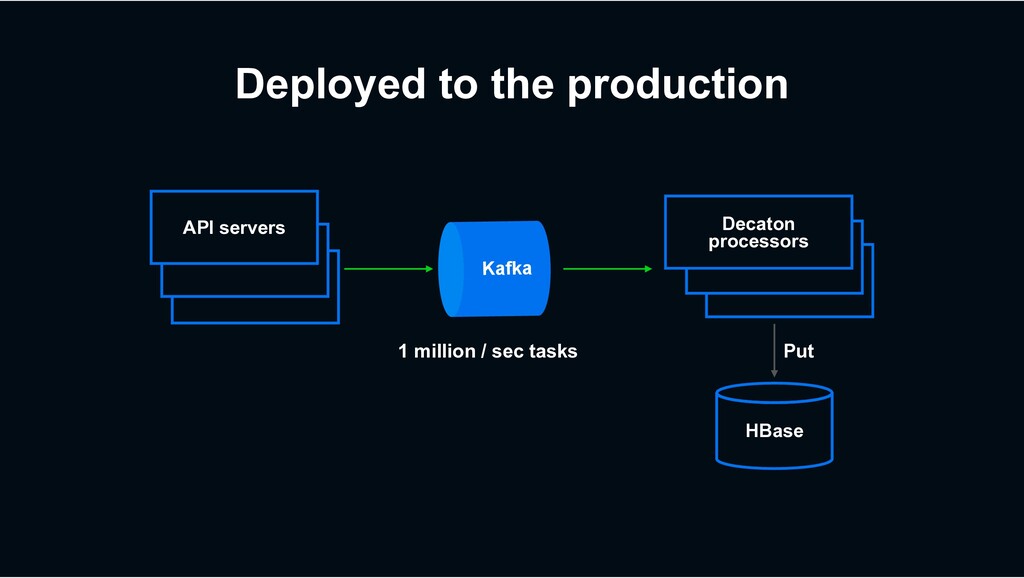
Deployed to the production Kafka Web API Decaton processors API
servers 1 million / sec tasks HBase Put -
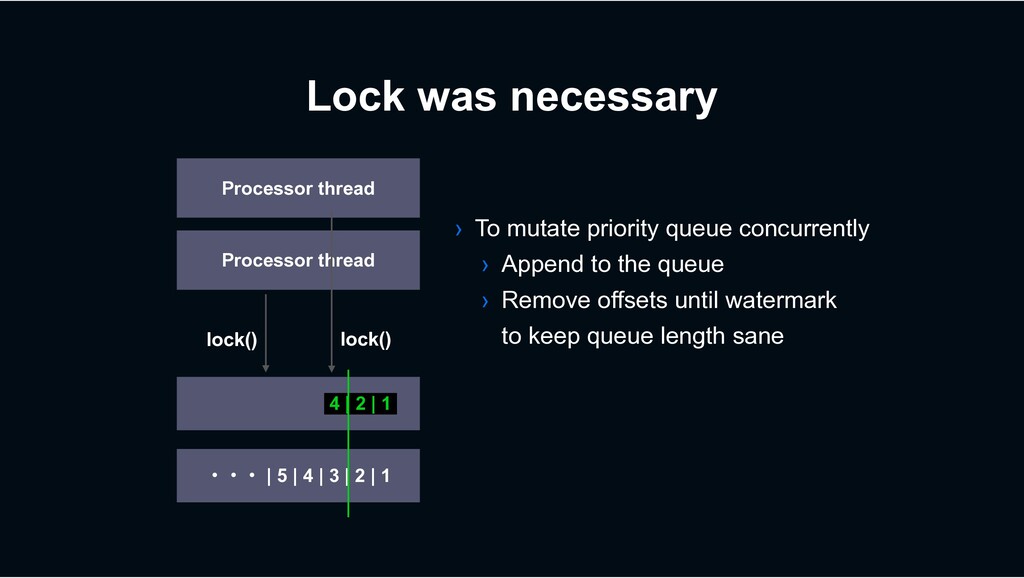
4 | 2 | 1 Processor thread Processor thread lock()
lock() › To mutate priority queue concurrently › Append to the queue › Remove offsets until watermark to keep queue length sane ɾɾɾ | 5 | 4 | 3 | 2 | 1 Lock was necessary -
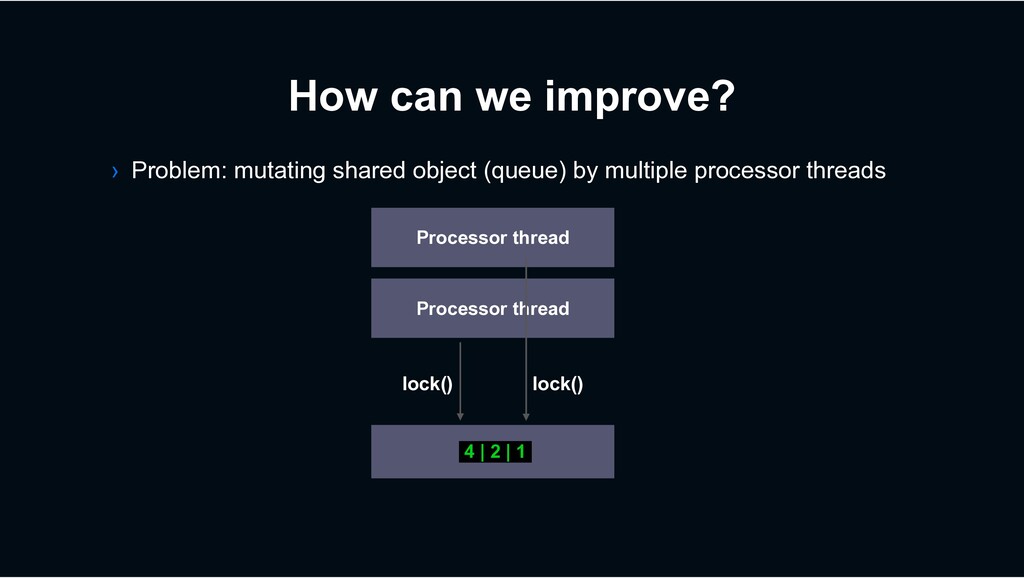
How can we improve? › Problem: mutating shared object (queue)
by multiple processor threads 4 | 2 | 1 Processor thread Processor thread lock() lock() -
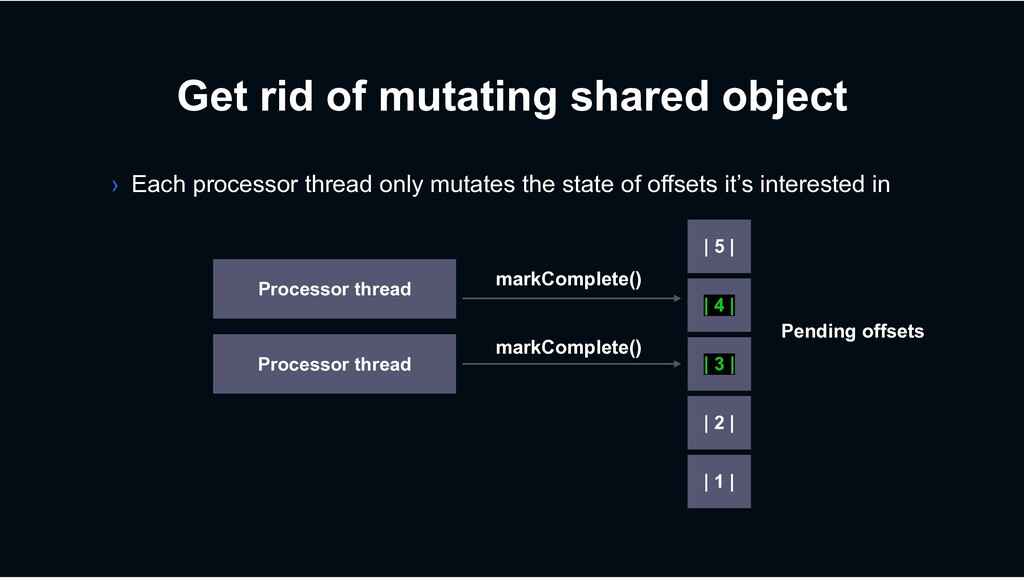
Get rid of mutating shared object › Each processor thread
only mutates the state of offsets it’s interested in Processor thread Processor thread | 1 | | 2 | | 4 | | 5 | | 3 | markComplete() markComplete() Pending offsets -
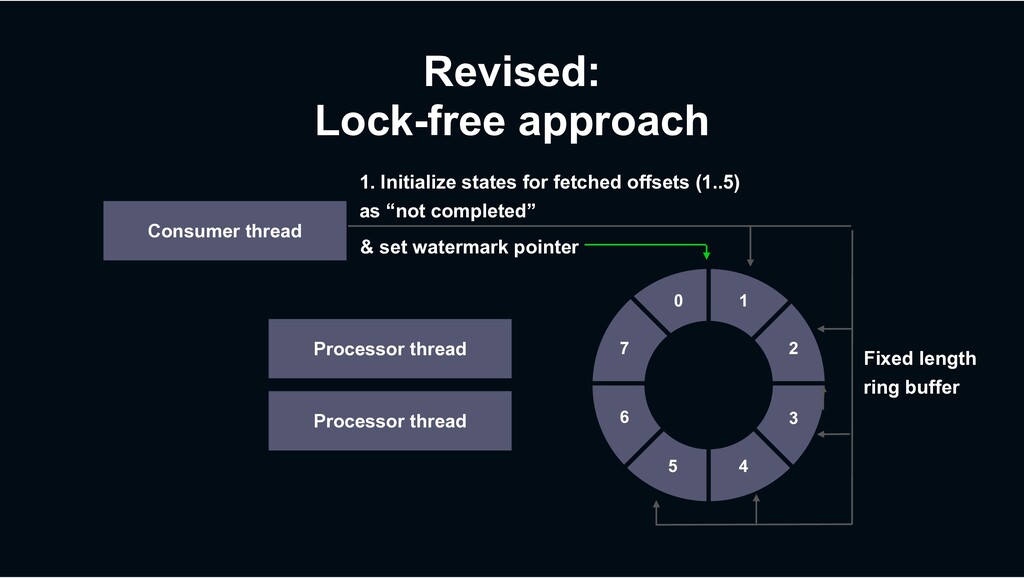
Revised: Lock-free approach Consumer thread Processor thread Processor thread Fixed
length ring buffer 1. Initialize states for fetched offsets (1..5) as “not completed” & set watermark pointer 0 1 2 3 4 5 6 7 -
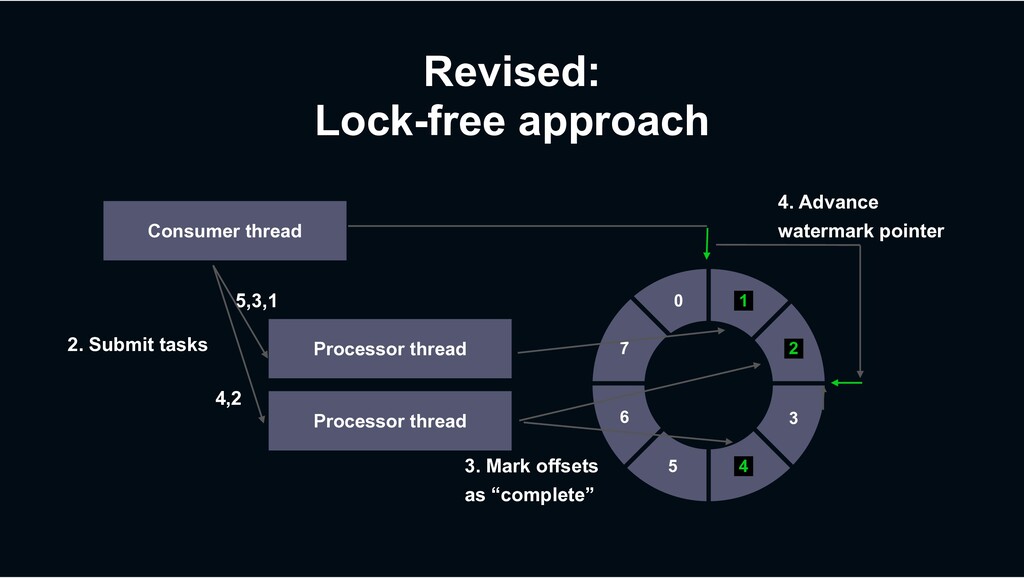
Revised: Lock-free approach Consumer thread 0 1 2 3 4
5 6 7 2. Submit tasks 5,3,1 4,2 4. Advance watermark pointer 3. Mark offsets as “complete” Processor thread Processor thread -
Now we have: › Mechanism to track watermark in a
optimized way › => The core of Decaton’s high performance asynchronous task processing -
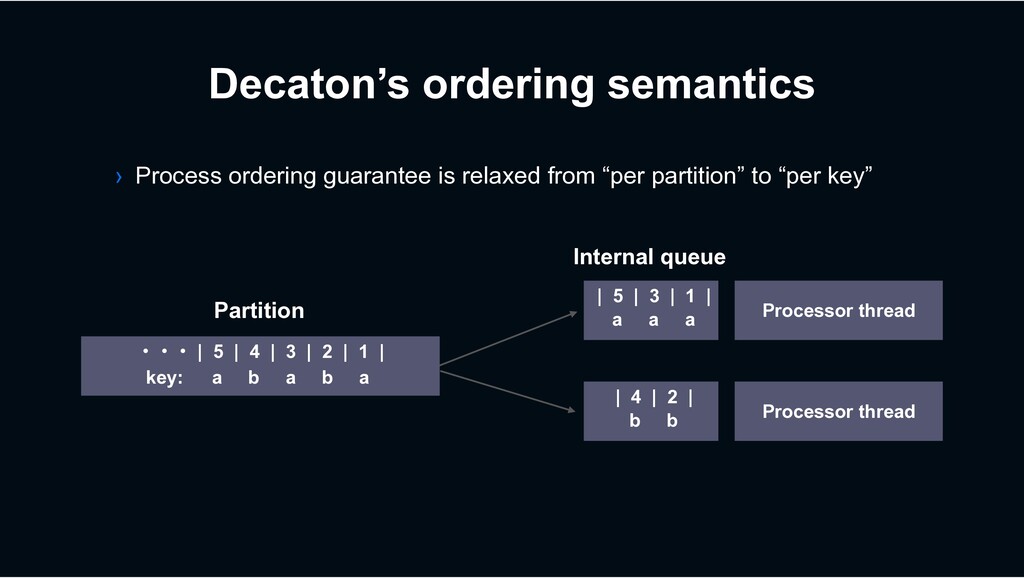
Decaton’s ordering semantics Processor thread Processor thread ɾɾɾ | 5
| 4 | 3 | 2 | 1 | a b a b a key: Partition | 5 | 3 | 1 | a a a Internal queue | 4 | 2 | b b › Process ordering guarantee is relaxed from “per partition” to “per key” -
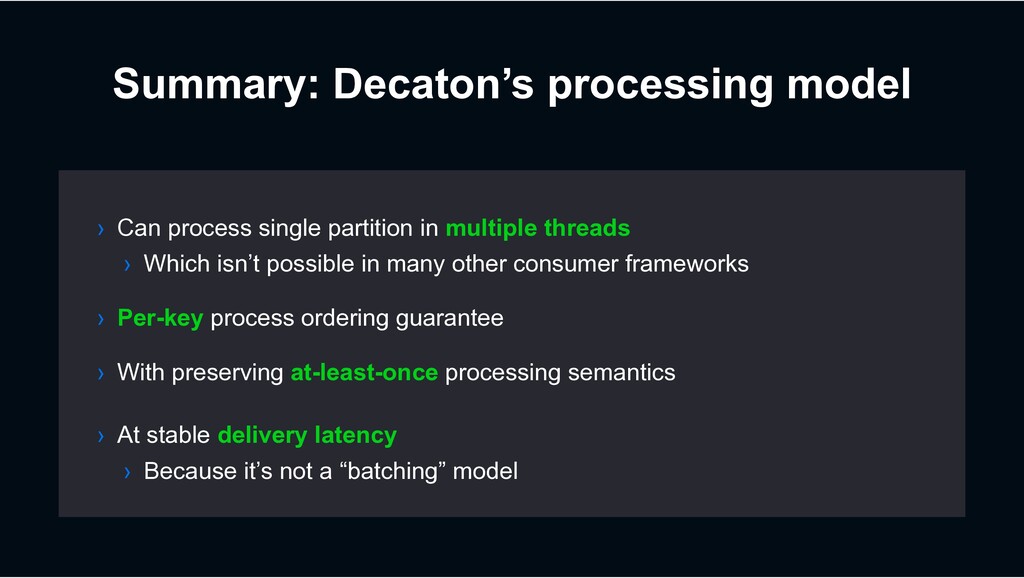
Summary: Decaton’s processing model › Can process single partition in
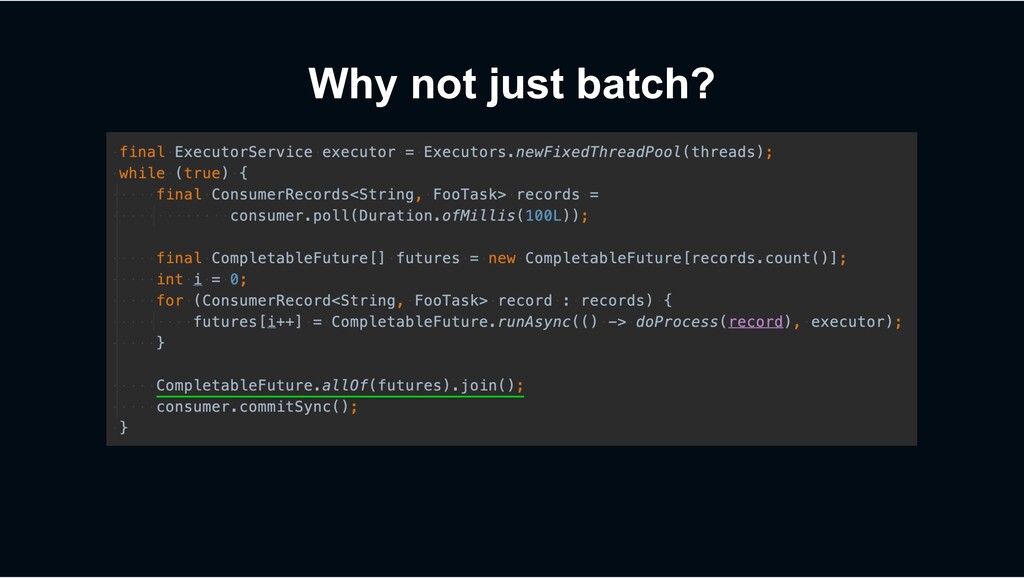
multiple threads › Which isn’t possible in many other consumer frameworks › With preserving at-least-once processing semantics › At stable delivery latency › Because it’s not a “batching” model › Per-key process ordering guarantee -
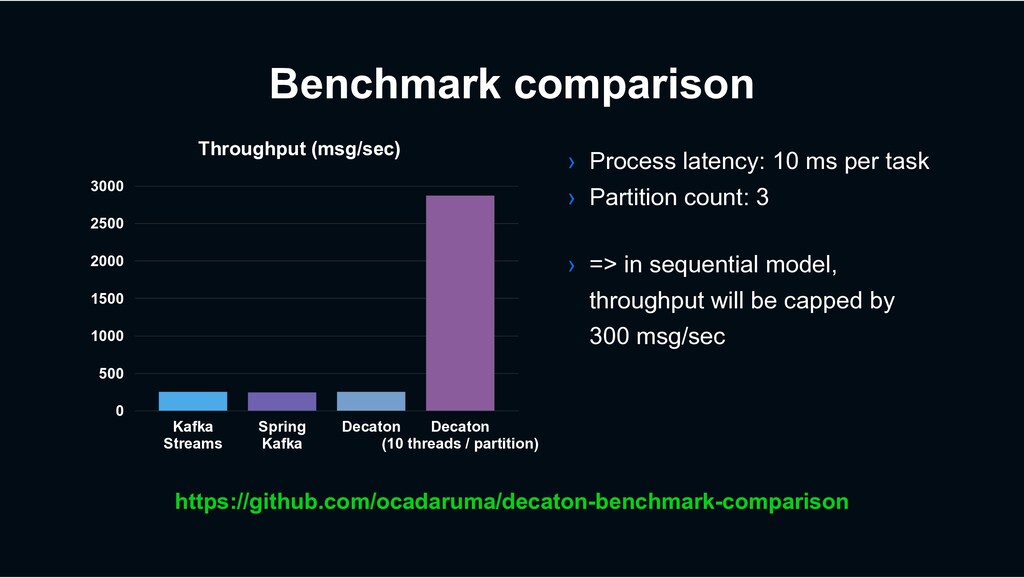
Benchmark comparison 0 500 1000 1500 2000 2500 3000 Kafka
Streams Spring Kafka Decaton Decaton (10 threads / partition) › Process latency: 10 ms per task › Partition count: 3 https://github.com/ocadaruma/decaton-benchmark-comparison Throughput (msg/sec) › => in sequential model, throughput will be capped by 300 msg/sec -
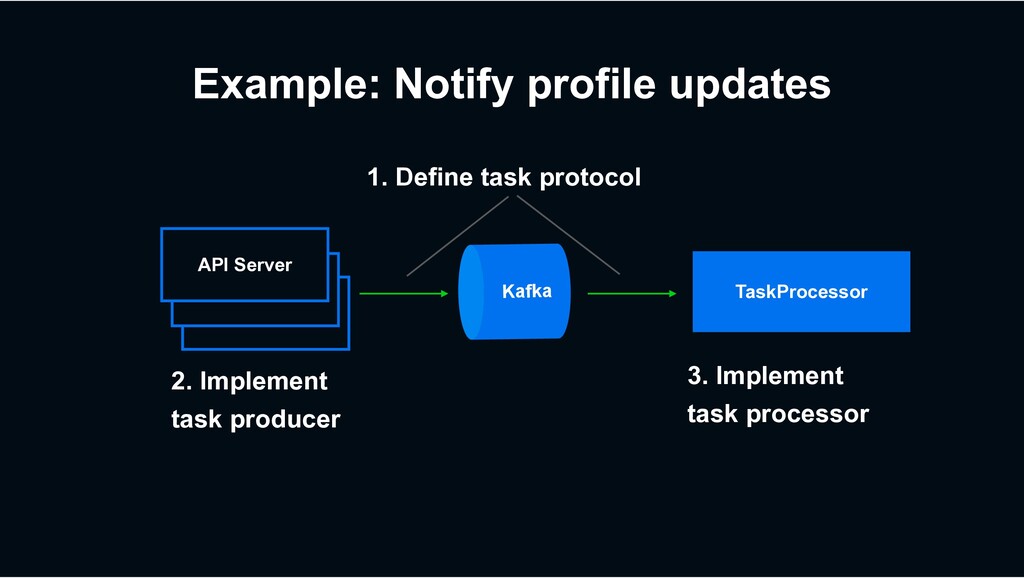
Example: Notify profile updates TaskProcessor Web API API Server Kafka
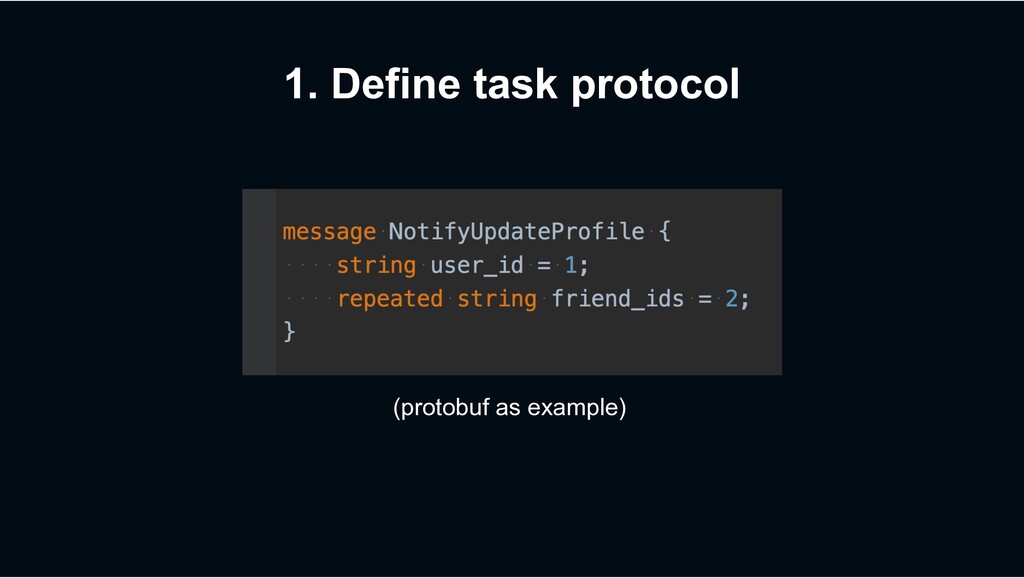
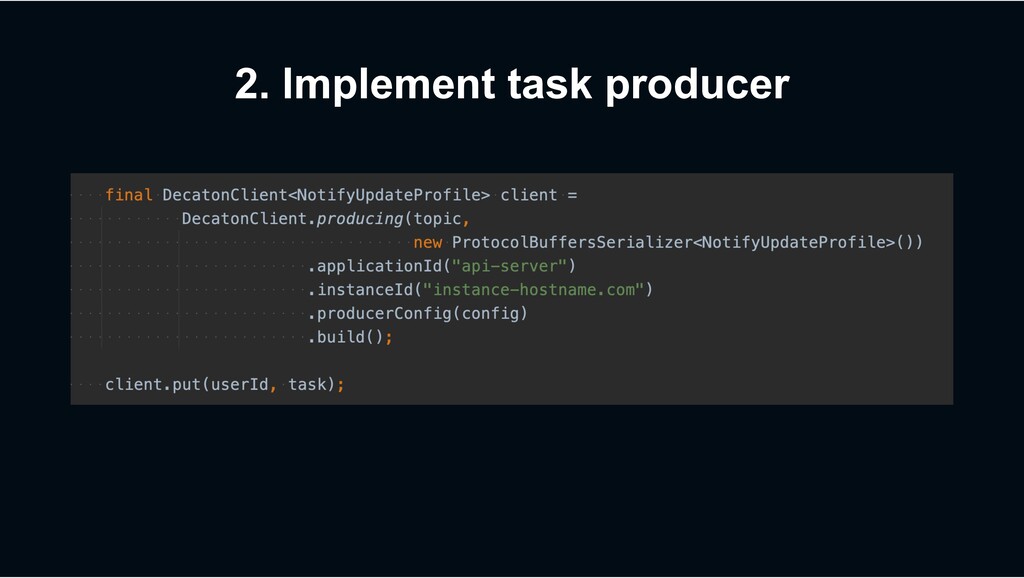
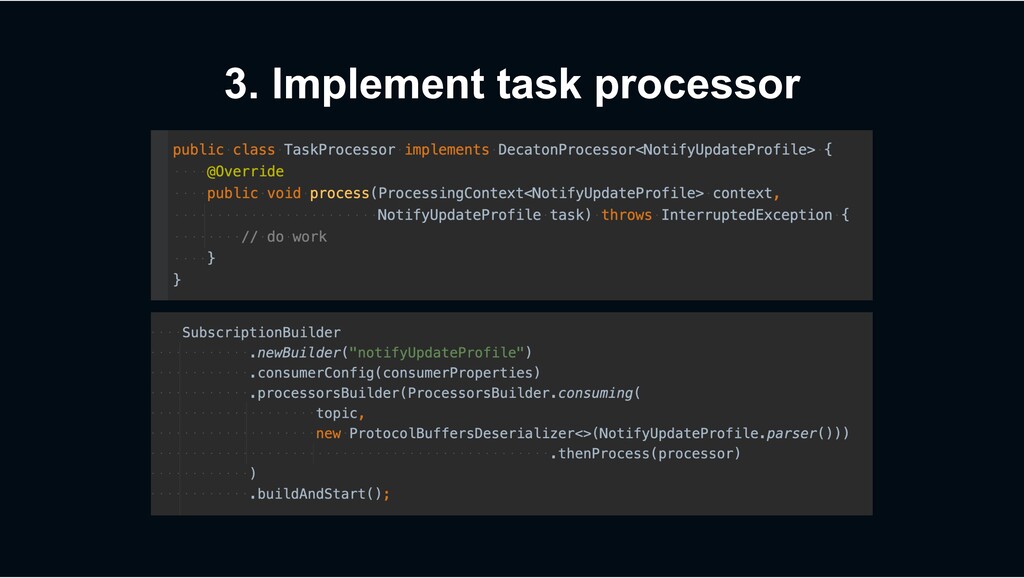
1. Define task protocol 2. Implement task producer 3. Implement task processor -
Decaton features › Decaton has various features useful for task
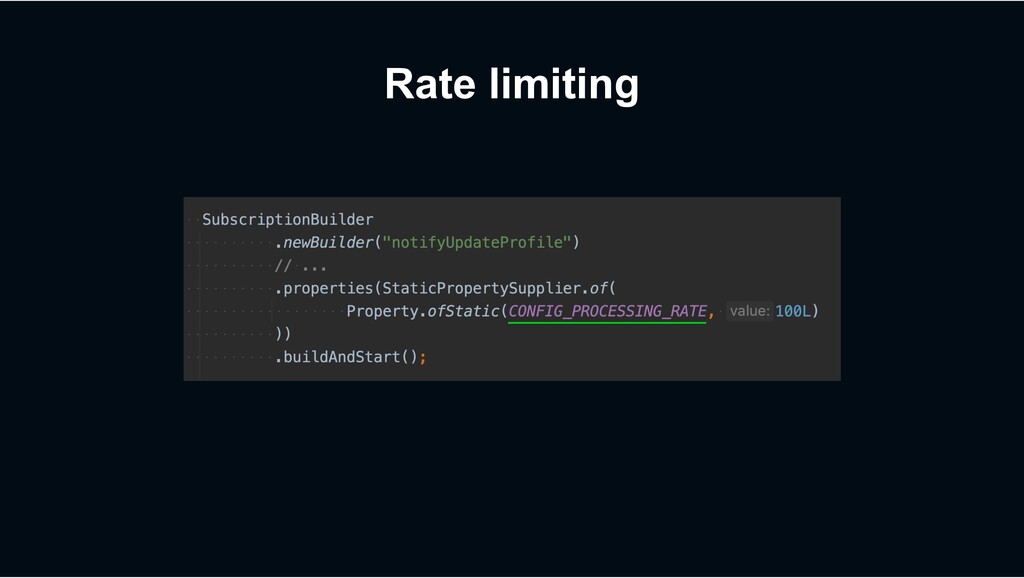
processing › From requirements for real-world LINE service development › Rate limiting › Retry queueing › And more… -
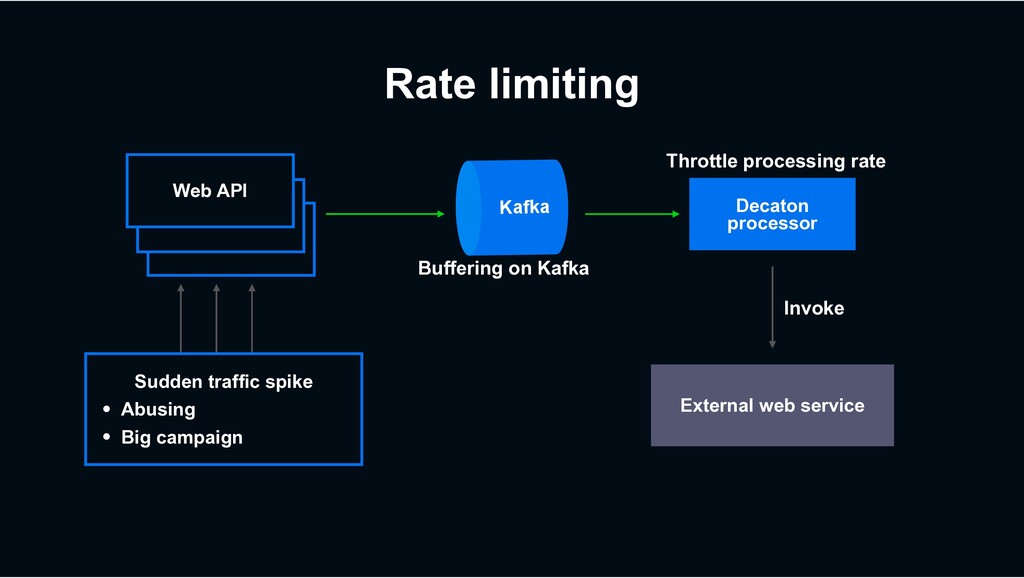
Rate limiting Decaton processor Web API Web API Kafka Sudden
traffic spike • Abusing • Big campaign External web service Invoke Throttle processing rate Buffering on Kafka -
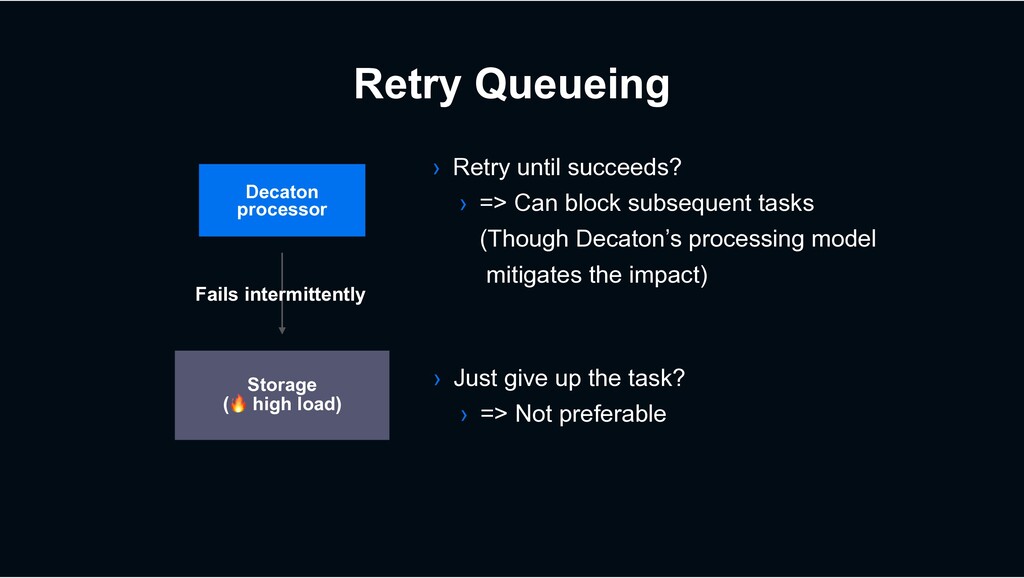
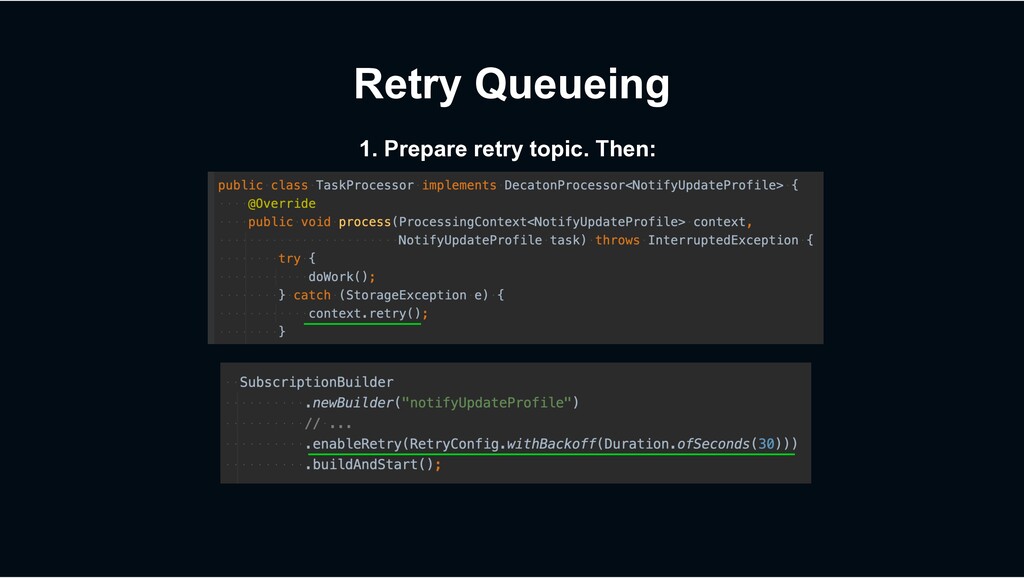
Retry Queueing Decaton processor Storage (! high load) Fails intermittently
› Retry until succeeds? › => Can block subsequent tasks (Though Decaton’s processing model mitigates the impact) › Just give up the task? › => Not preferable -
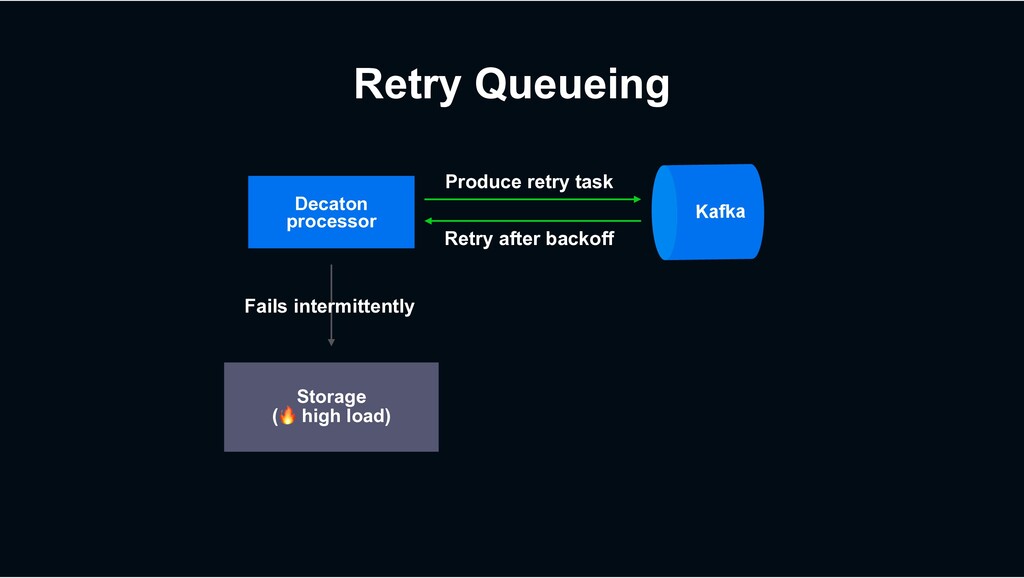
Retry Queueing Decaton processor Storage (! high load) Fails intermittently
Kafka Produce retry task Retry after backoff -
Ambition: Experimental WebAssembly support https://engineering.linecorp.com/en/blog/ › As of now Decaton
only supports JVM based language › If Decaton can support WebAssembly binary as a DecatonProcessor implementation, it unlocks supports for many programming languages ! › Adding experimental WebAssembly support to Decaton – Part 1, 2 -
Performance can be affected by: › Several factors: › Adding
new feature › Refactoring › Default configuration value changes › Update dependencies › kafka-clients › … -
What we need is: › Integrated benchmarking environment › Measures
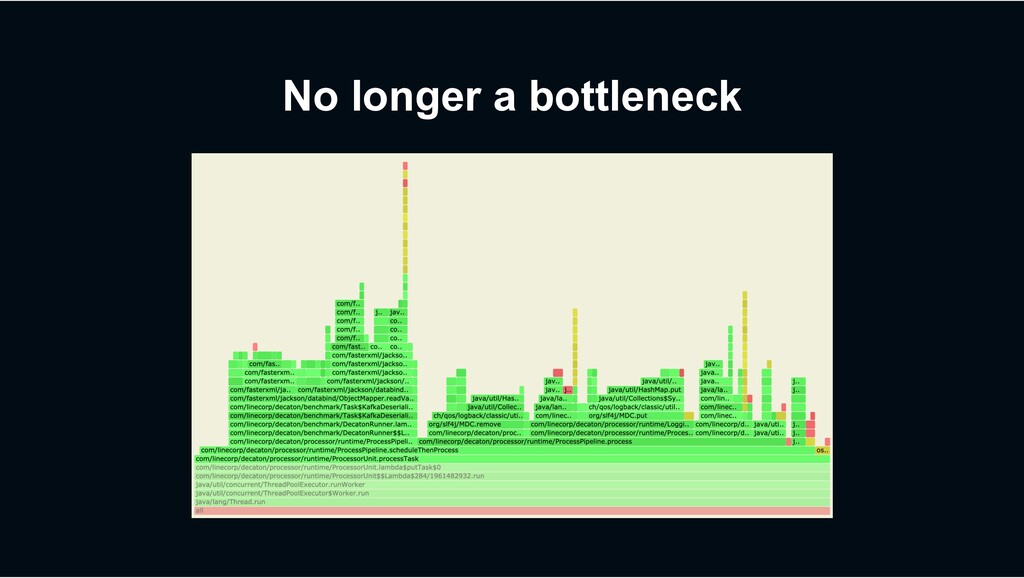
end-to-end processing performance › Rather than micro-benchmark for small portion of the code › Along with profiles to investigate bottleneck › Async-profiler › Linux taskstats › Measure performance transition per code changes -
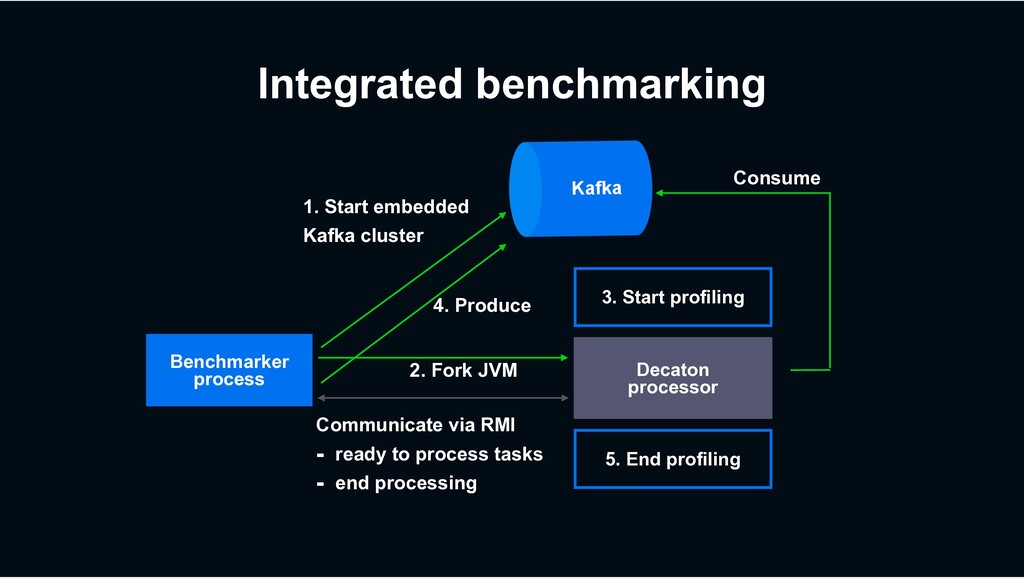
Integrated benchmarking Benchmarker process Kafka Decaton processor 1. Start embedded
Kafka cluster 3. Start profiling 5. End profiling 2. Fork JVM Consume 4. Produce Communicate via RMI - ready to process tasks - end processing -
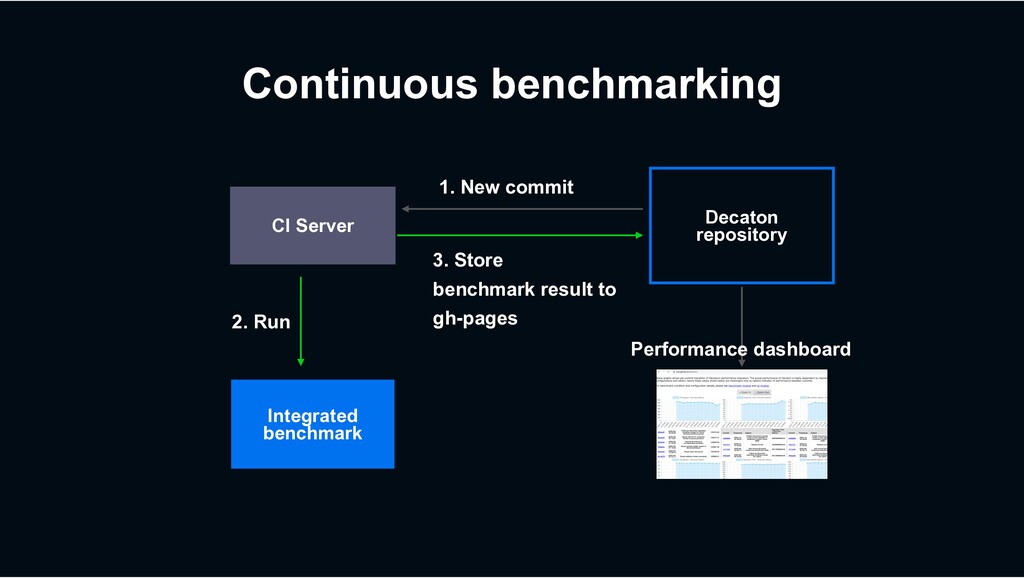
Continuous benchmarking › Run integrated benchmarking per every code changes
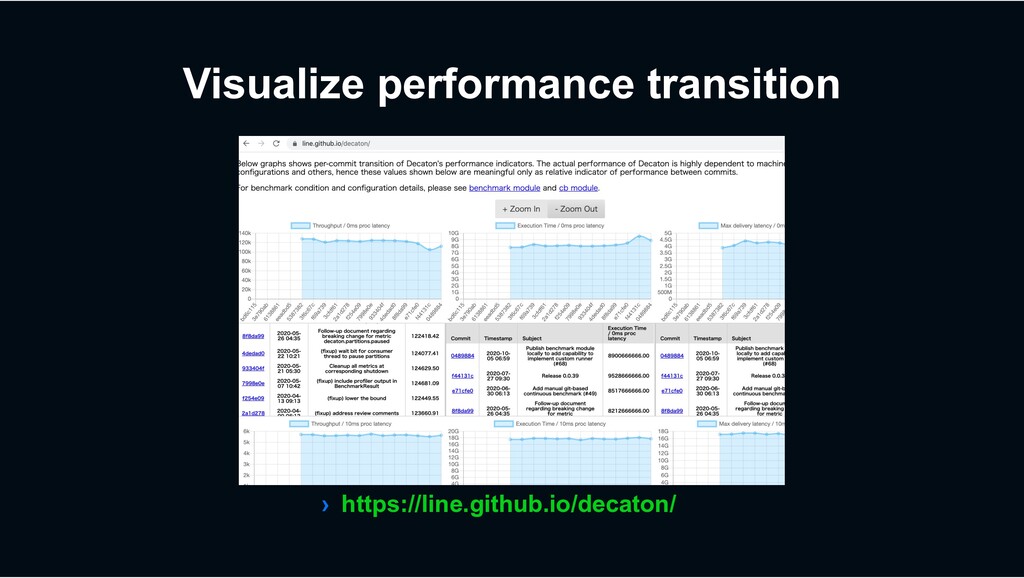
› As part of continuous integration › Store benchmark results › Visualize performance trend on a web UI -
Continuous benchmarking Integrated benchmark CI Server Decaton repository 2. Run
1. New commit 3. Store benchmark result to gh-pages Performance dashboard -
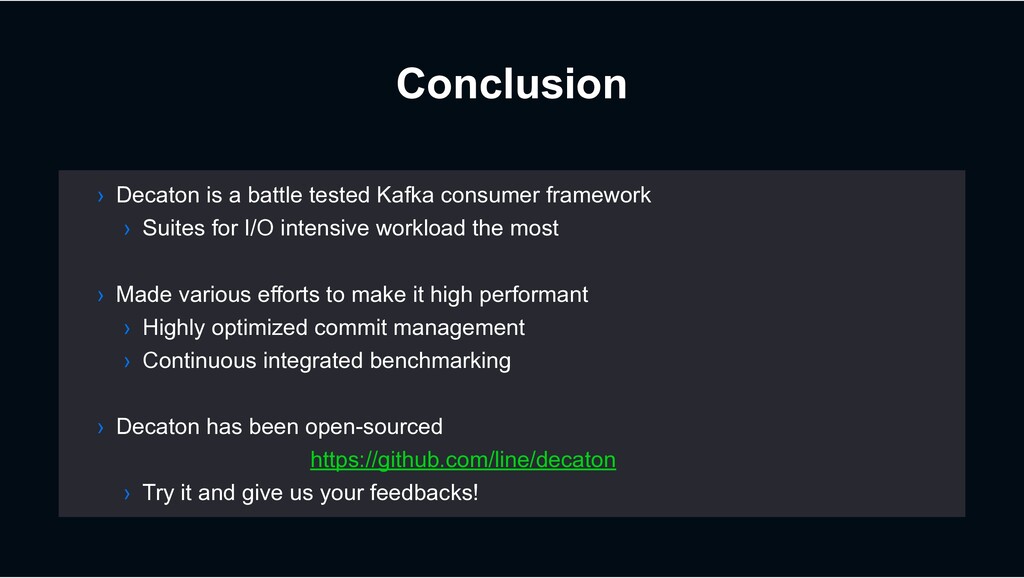
Conclusion › Decaton is a battle tested Kafka consumer framework
› Suites for I/O intensive workload the most › Made various efforts to make it high performant › Highly optimized commit management › Continuous integrated benchmarking › Decaton has been open-sourced https://github.com/line/decaton › Try it and give us your feedbacks!