Upgrade to Pro — share decks privately, control downloads, hide ads and more …

Get to know the Unicode monster and don’t let i...

Get to know the Unicode monster and don’t let it harm you - Jeremy Chan

Jeremy Chan's short talk to the London Java Community on 8th September 2020.

In this talk, Jeremy will give us a brief history of Unicode and discuss some of the common pitfalls he's come across.

Jeremy Chan is currently a VP at Goldman Sachs. He has previously worked at Credit Suisse and Barclays Investment Bank and has a Masters in Computer Science and Engineering.

London Java Community

September 08, 2020

Transcript

35 slides
  1. Basic Concept Ultimate goal of encoding: maps characters into bytes

    and vice versa 0x48 0x69 Hi Bytes Characters Encoding 4
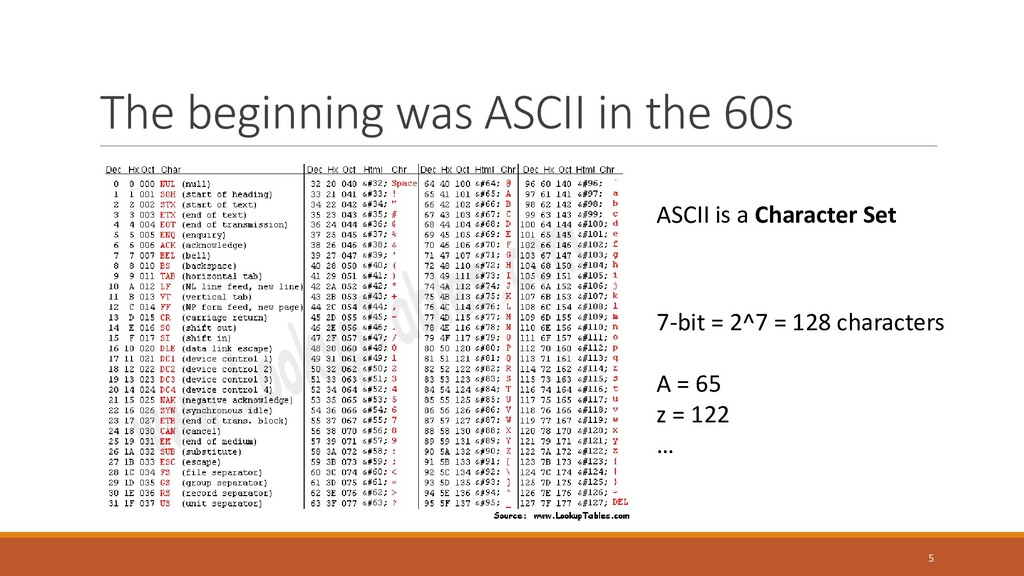
  2. The beginning was ASCII in the 60s ASCII is a

    Character Set 7-bit = 2^7 = 128 characters A = 65 z = 122 … 5
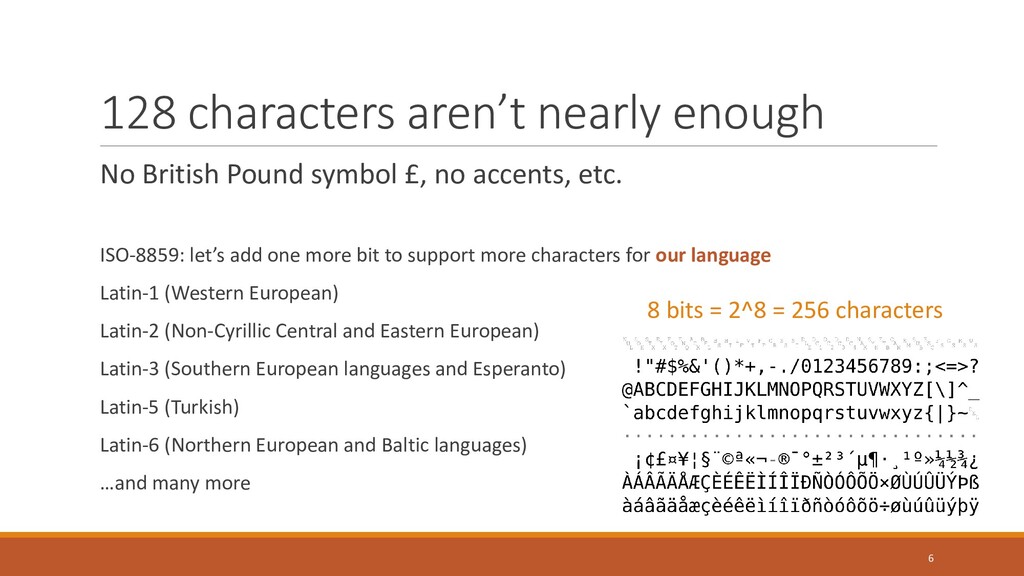
  3. 128 characters aren’t nearly enough No British Pound symbol £,

    no accents, etc. ISO-8859: let’s add one more bit to support more characters for our language Latin-1 (Western European) Latin-2 (Non-Cyrillic Central and Eastern European) Latin-3 (Southern European languages and Esperanto) Latin-5 (Turkish) Latin-6 (Northern European and Baltic languages) …and many more 8 bits = 2^8 = 256 characters 6
  4. 7

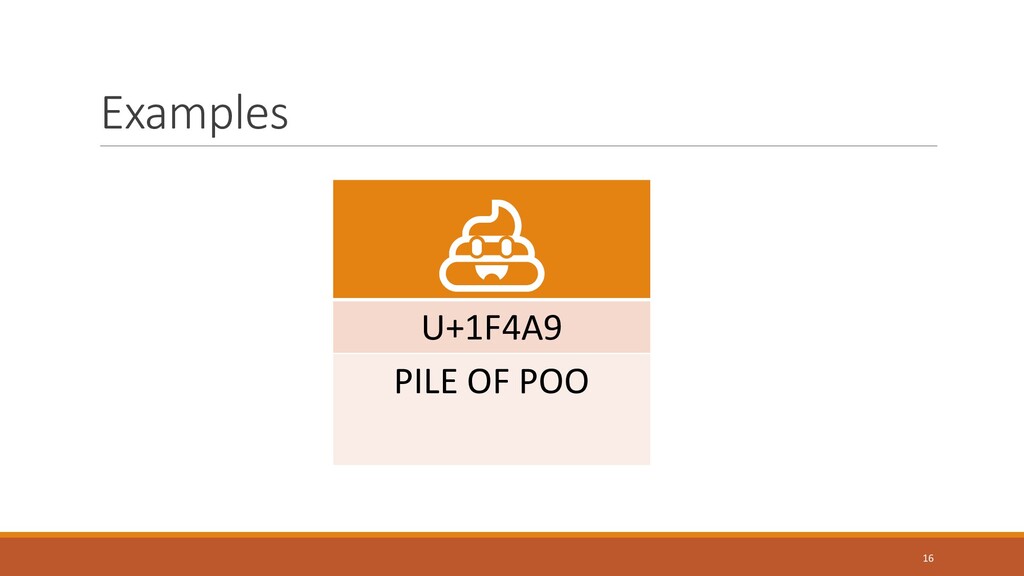
  5. Code point – layer of abstraction ? ? ? ?

    ? ? Hi Bytes U+0048 U+0069 U+1F4A9 Code point (A hex number) Characters Encoding 9
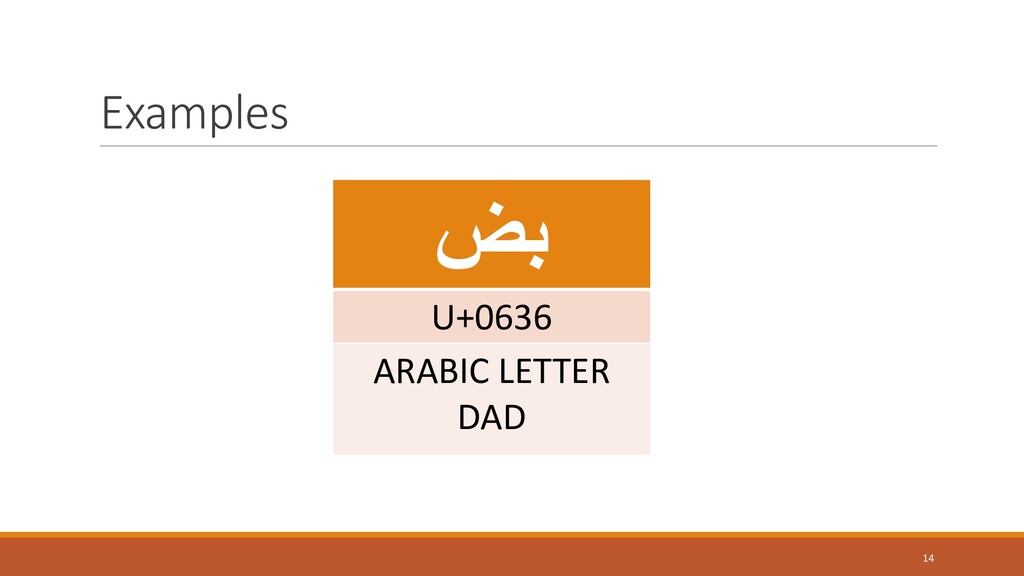
  6. How many code points? 10 Valid code points U+0000 –

    U+10FFFF (21 bits) 1,114,112 code points Currently about 143,859 (~13%) utilized ◦~ 1,000 characters for European languages ◦~ 75,000 characters for Chinese, Japanese and Korean ◦> 3,000 emojis
  7. Fancy adding your own? We did it! How a comment

    on HackerNews lead to 4 ½ new Unicode characters 17
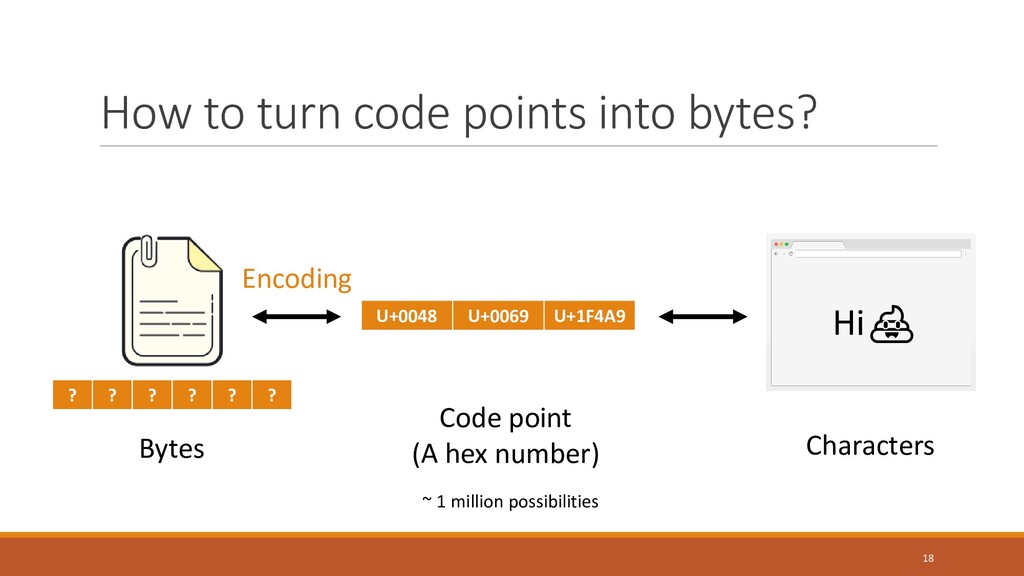
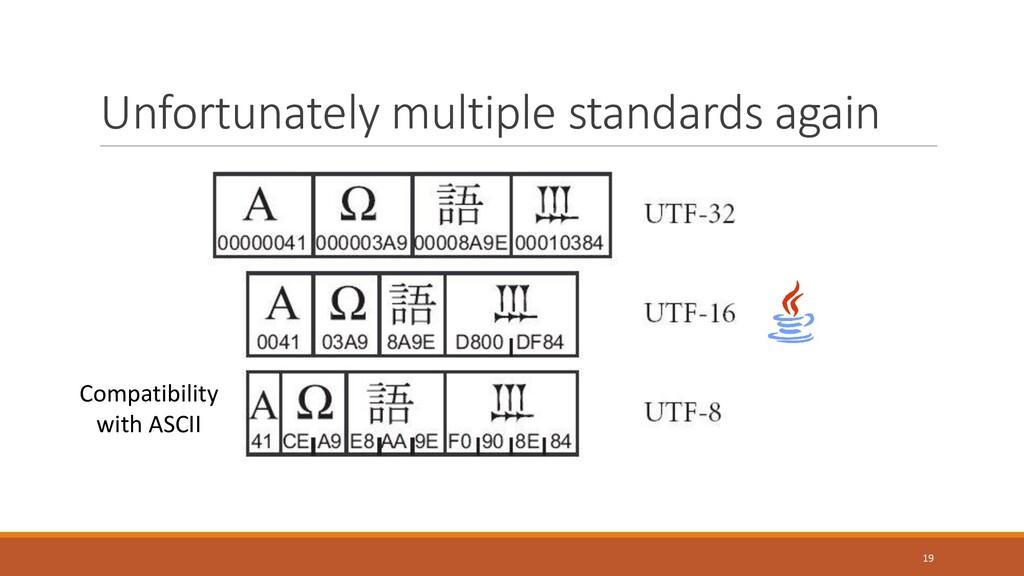
  8. How to turn code points into bytes? ? ? ?

    ? ? ? Hi Bytes U+0048 U+0069 U+1F4A9 Code point (A hex number) Characters Encoding 18 ~ 1 million possibilities
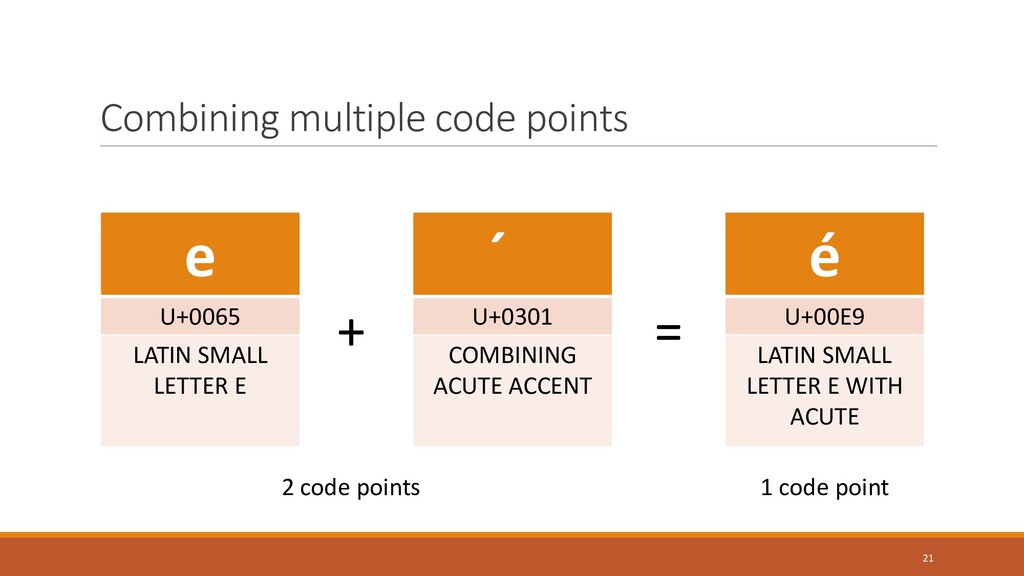
  9. Combining multiple code points 21 = e U+0065 LATIN SMALL

    LETTER E ́ U+0301 COMBINING ACUTE ACCENT é U+00E9 LATIN SMALL LETTER E WITH ACUTE + 2 code points 1 code point
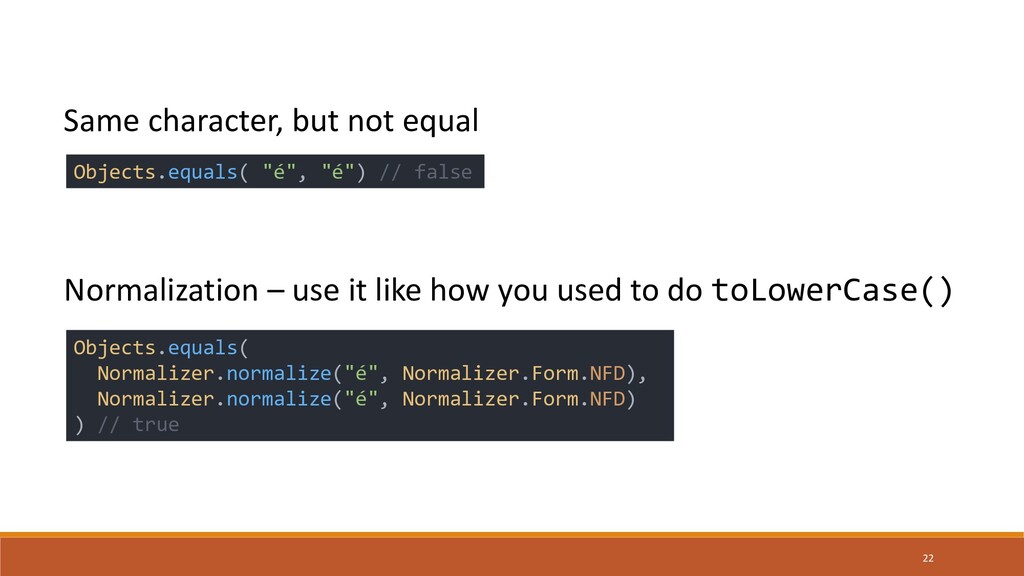
  10. 22 Objects.equals( "é", "é") // false Objects.equals( Normalizer.normalize("é", Normalizer.Form.NFD), Normalizer.normalize("é",

    Normalizer.Form.NFD) ) // true Normalization – use it like how you used to do toLowerCase() Same character, but not equal
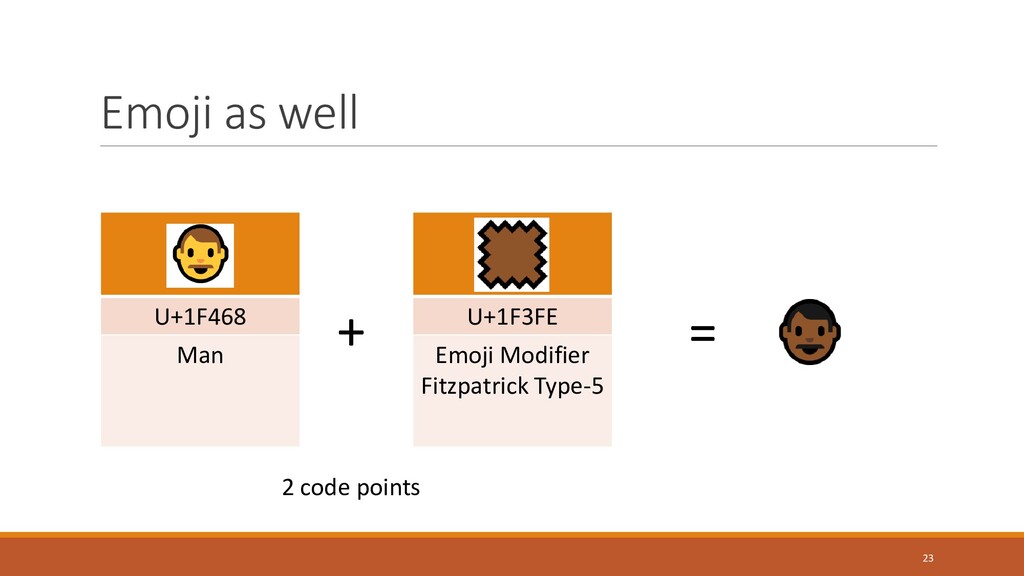
  11. Emoji as well 23 = U+1F468 Man U+1F3FE Emoji Modifier

    Fitzpatrick Type-5 + 2 code points
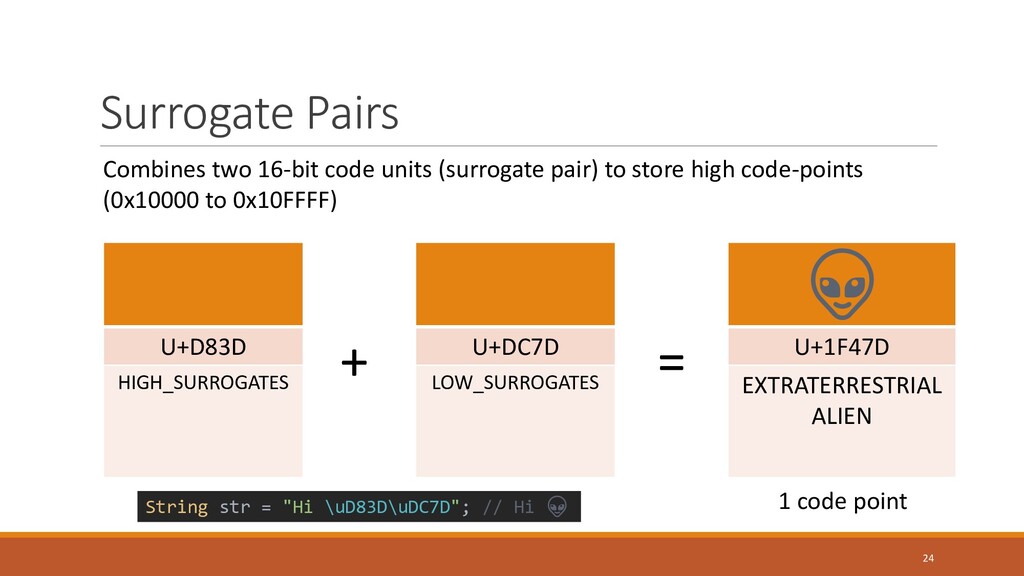
  12. Surrogate Pairs 24 = U+D83D HIGH_SURROGATES U+DC7D LOW_SURROGATES U+1F47D EXTRATERRESTRIAL

    ALIEN + Combines two 16-bit code units (surrogate pair) to store high code-points (0x10000 to 0x10FFFF) 1 code point String str = "Hi \uD83D\uDC7D"; // Hi
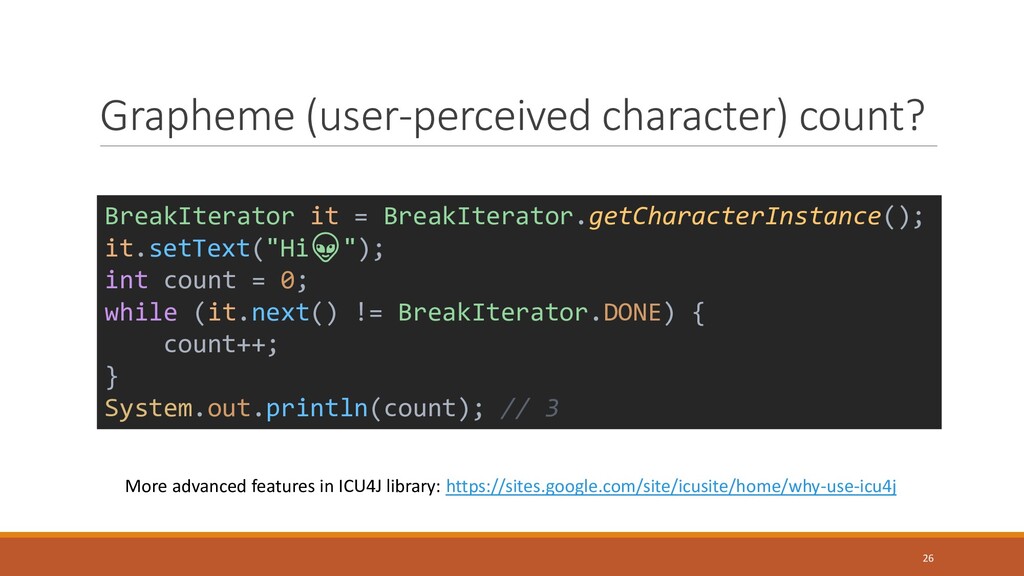
  13. Grapheme (user-perceived character) count? 26 BreakIterator it = BreakIterator.getCharacterInstance(); it.setText("Hi");

    int count = 0; while (it.next() != BreakIterator.DONE) { count++; } System.out.println(count); // 3 More advanced features in ICU4J library: https://sites.google.com/site/icusite/home/why-use-icu4j
  14. 27 String str = "Hi \uD83D\uDC7D"; // Hi for (char

    c: str.toCharArray()) { System.out.println(c); } H i ? ? Never use char again
  15. Iterate in code points (Java 8) 28 H i String

    s = "Hi \uD83D\uDC7D"; // Hi s.codePoints().forEach(c -> { System.out.println(Character.toChars(c)); });
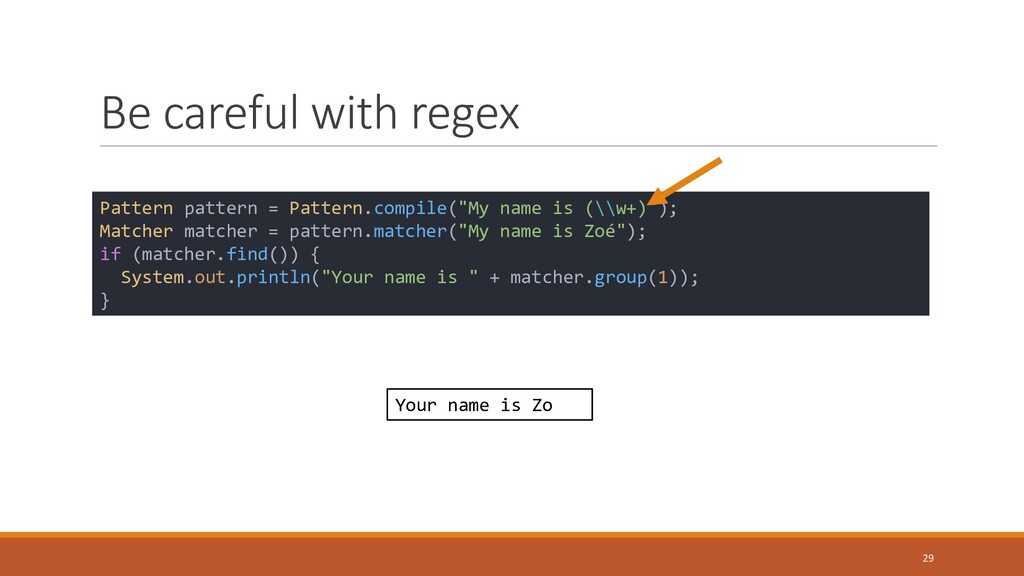
  16. Be careful with regex 29 Your name is Zo Pattern

    pattern = Pattern.compile("My name is (\\w+)"); Matcher matcher = pattern.matcher("My name is Zoé"); if (matcher.find()) { System.out.println("Your name is " + matcher.group(1)); }
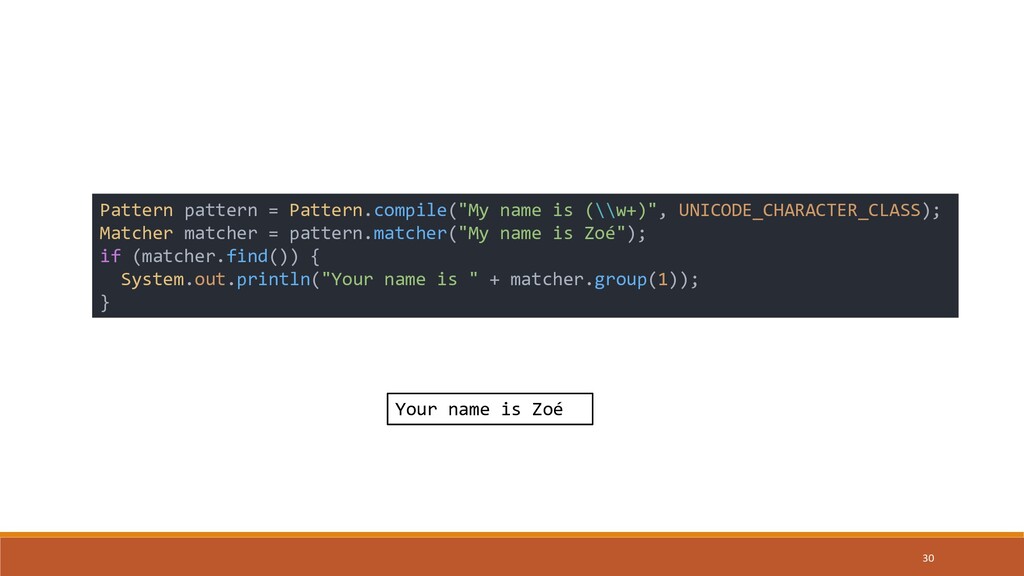
  17. 30 Pattern pattern = Pattern.compile("My name is (\\w+)", UNICODE_CHARACTER_CLASS); Matcher

    matcher = pattern.matcher("My name is Zoé"); if (matcher.find()) { System.out.println("Your name is " + matcher.group(1)); } Your name is Zoé
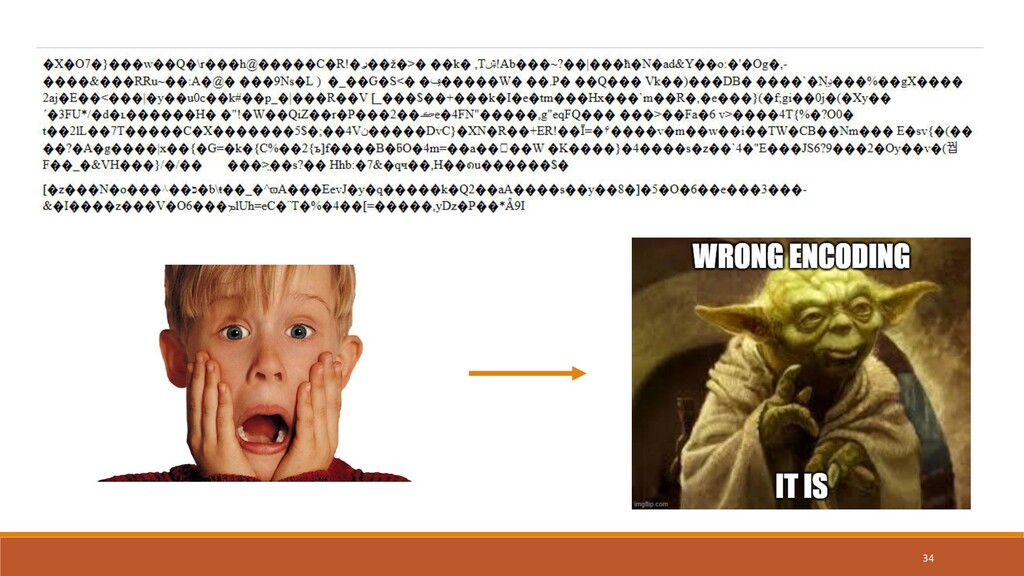
  18. 34

  19. Reference Must Read: https://www.joelonsoftware.com/2003/10/08/the-absolute-minimum-every-software- developer-absolutely-positively-must-know-about-unicode-and-character-sets-no-excuses/ History of unicode: https://www.translationroyale.com/the-history-of-unicode/ Some

    common pitfalls: http://unicode.org/faq/utf_bom.html Unicode hacks: https://speakerdeck.com/mathiasbynens/hacking-with-unicode Unicode regex pitfalls: http://www.guido-flohr.net/unicode-regex-pitfalls/ 35

More Decks by London Java Community

Other Decks in Programming