Upgrade to Pro — share decks privately, control downloads, hide ads and more …

10 insane things on Big Data

Luis Belloch
September 22, 2016

10 insane things on Big Data

Ten war stories while doing large-scale data management in Accudelta, and some approaches we took to survive the tsunami.

Luis Belloch

September 22, 2016

Transcript

21 slides
  1. Since 1991, ~100 employees Offices in Dublin, Boston, London, New

    York, Stockholm, Milan and Valencia. Valencia is an engineering office only Black Rock, Fidelity, J.P. Morgan US, M&G, Prudential, Charles Schwab, Schroders, State Street, Columbia Threadneedle, Canada Life, IFDS, New Ireland, ...
  2. #1 Wild Data So… is that a bunch of Excel

    and CSV files randomly piled up? - Day 1, MoneyMate developer “
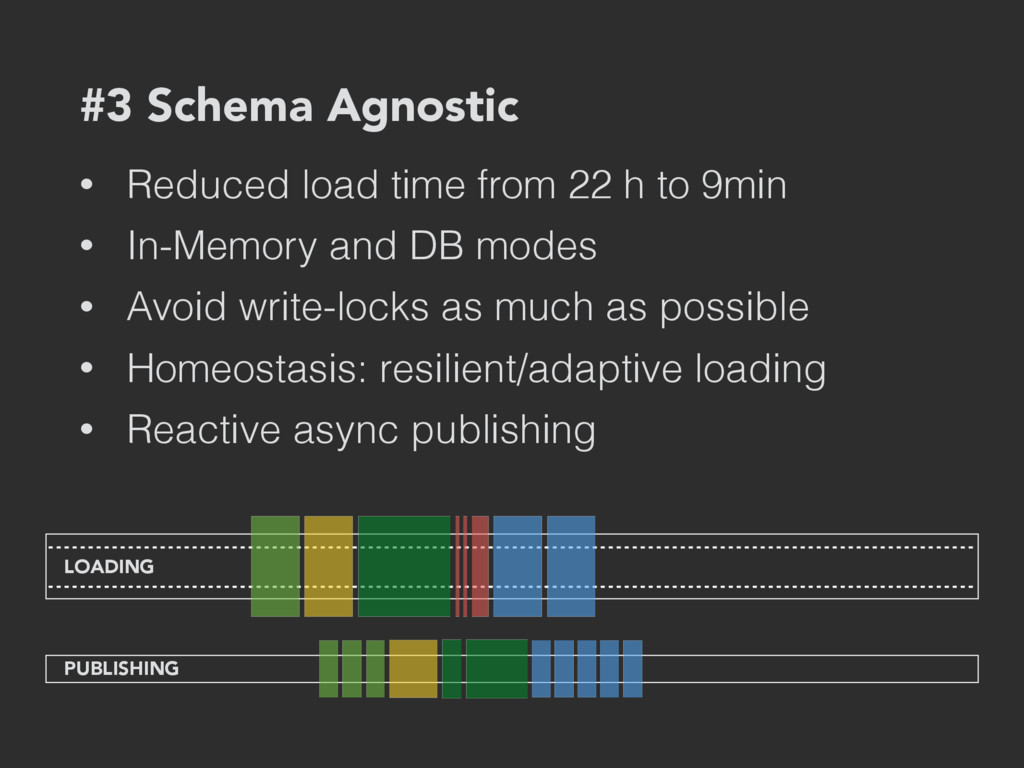
  3. #3 Schema Agnostic • Reduced load time from 22 h

    to 9min • In-Memory and DB modes • Avoid write-locks as much as possible • Homeostasis: resilient/adaptive loading • Reactive async publishing LOADING PUBLISHING
  4. #4 Parallel Testing Replay one-month events in the system,
 …

    using two software versions, 
 … then compare row-by-row, cell-by-cell.
  5. #5 Schema Evolutions • ~50MB of SQL, several more CSVs

    • VCS and code review friendly • Test-data & container migrations • Forward-only, no rollbacks • Exercised many times per day through CI builds • etcd distributed locks, coordination
  6. #6a Market Right after the Brexit, one of our clients

    started to load data in a daily-basis, instead of monthly.
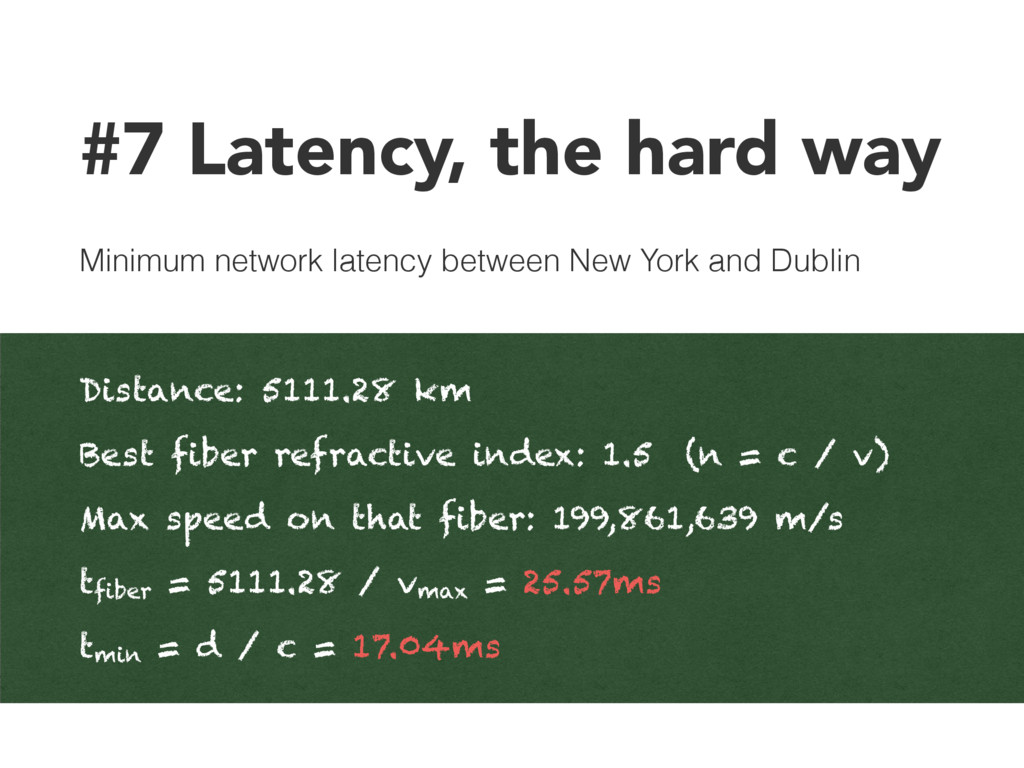
  7. #7 Latency, the hard way Minimum network latency between New

    York and Dublin
 Distance: 5111.28 km Best fiber refractive index: 1.5 (n = c / v) Max speed on that fiber: 199,861,639 m/s tfiber = 5111.28 / vmax = 25.57ms tmin = d / c = 17.04ms
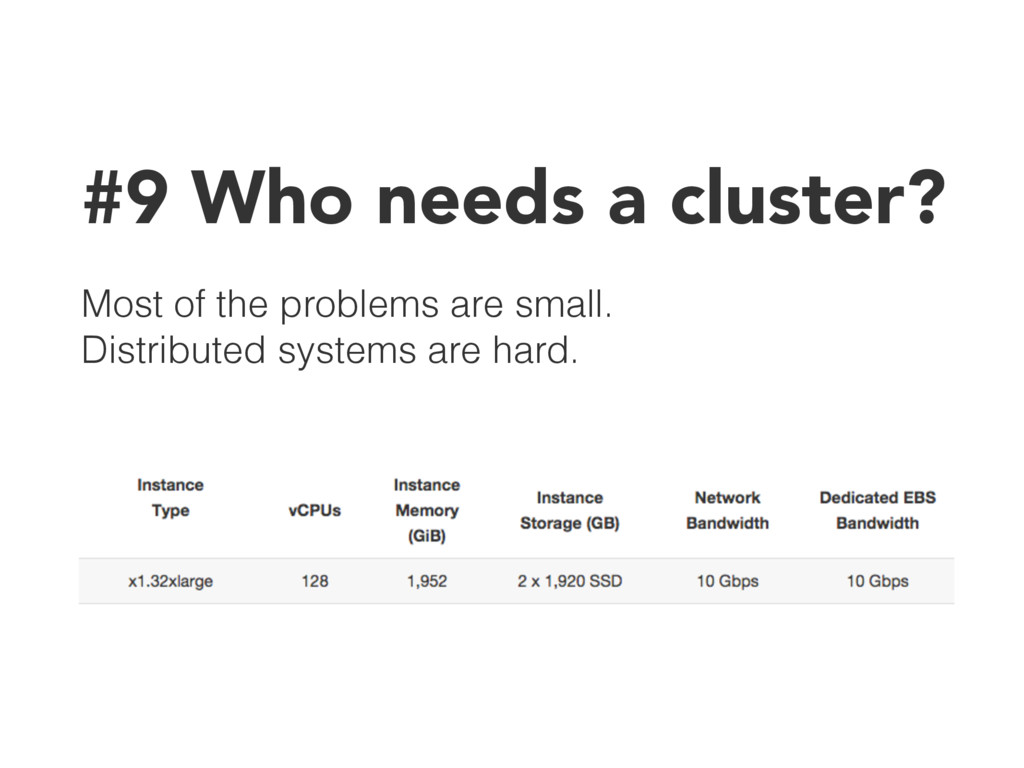
  8. #9 Who needs a cluster? Most of the problems are

    small.
 Distributed systems are hard.
  9. #10 Small Data Big data is an excuse,
 a catalyst

    improving the tools we have today

More Decks by Luis Belloch

Other Decks in Programming