Share
LINE Messaging: From Active-Standby to Active-Active Multi-DC Architecture
To further enhance business continuity, the LINE Messaging service is embarking on a transition toward a multi-datacenter Active-Active architecture. Implementing this architecture at LINE's immense scale and high-traffic volume presents unique and significant challenges for databases and distributed systems alike.
In this session, we will explore our journey through this architectural evolution. We will first discuss the current status and limitations of our existing Disaster Recovery (DR) framework, followed by the insights and reasoning behind adopting a multi-datacenter Active-Active setup. We will also share the technical hurdles we faced along the way and our vision for future challenges in keeping one of the world's largest messaging platforms resilient.
Additionally, we will introduce YugabyteDB as a key technology enabling this transition, detailing how we selected and integrate it into our messaging backend.
LINEヤフーTech (LY Corporation Tech) PRO
Transcript
69 slides
-
2026.06.29 LY Corporation LINE Messaging: From Active-Standby to Active-Active Multi-DC
Architecture Javier Luca de Tena | LINE Messaging Dev SBU Tsuruhara Tomu | LINE Messaging Dev SBU -
LINE Messaging at a Glance Current Architecture: Active-Standby & Why
We Need to Change The Challenge of Going Active-Active and solutions Why do we need a new DB to achieve Active-Active multi-DC? Case Study: DB selection for LINE Messenger Backend 01 03 02 04 05 Agenda 1st Part (Javier Luca de Tena) 2nd Part (Tsuruhara Tomu) -
One of the largest messaging platforms in Asia LINE Messaging
at a Glance Presence & Services Available across Japan, Taiwan, Thailand, Indonesia and more Text, voice, video calls, stickers, ... Mission Criticality Critical communication infrastructure. Reliability and speed for real time communication is paramount. LINE Messaging serves hundred millions of users globally and processes billions of interactions every day. -
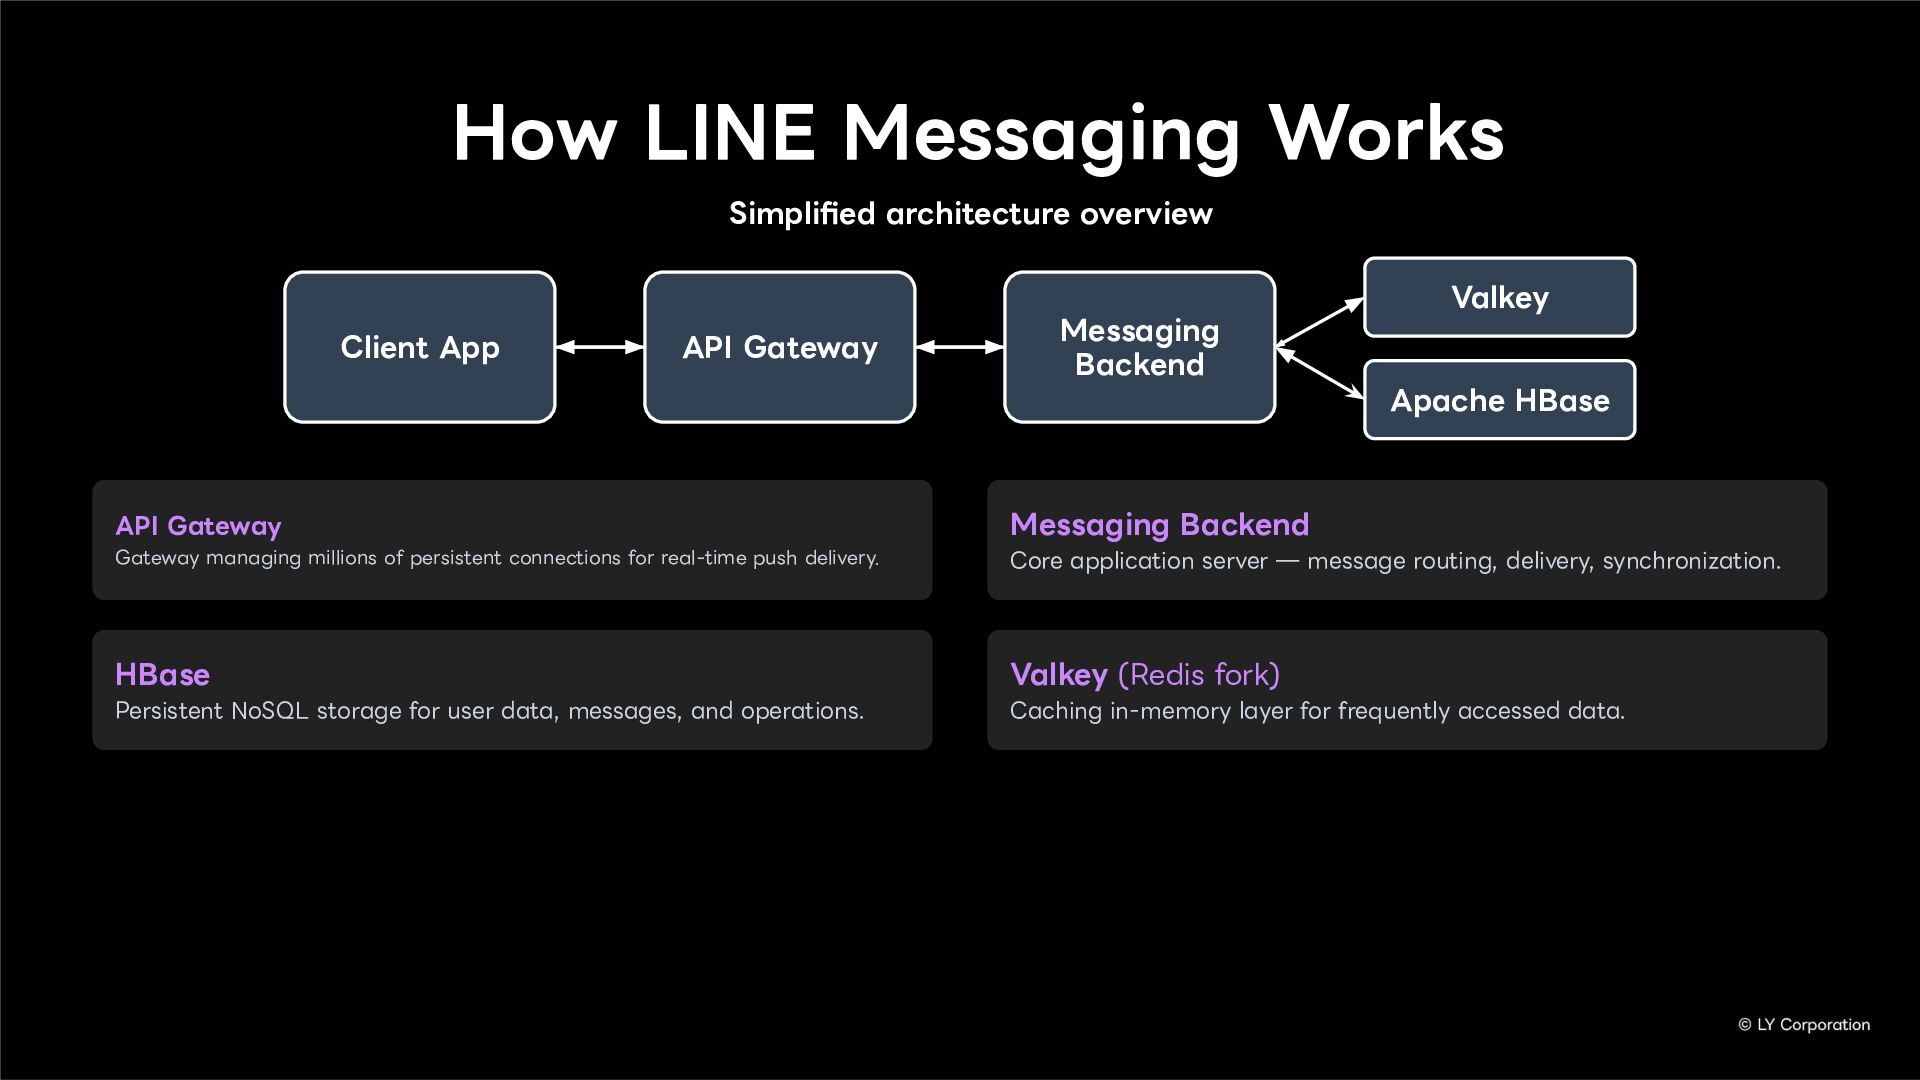
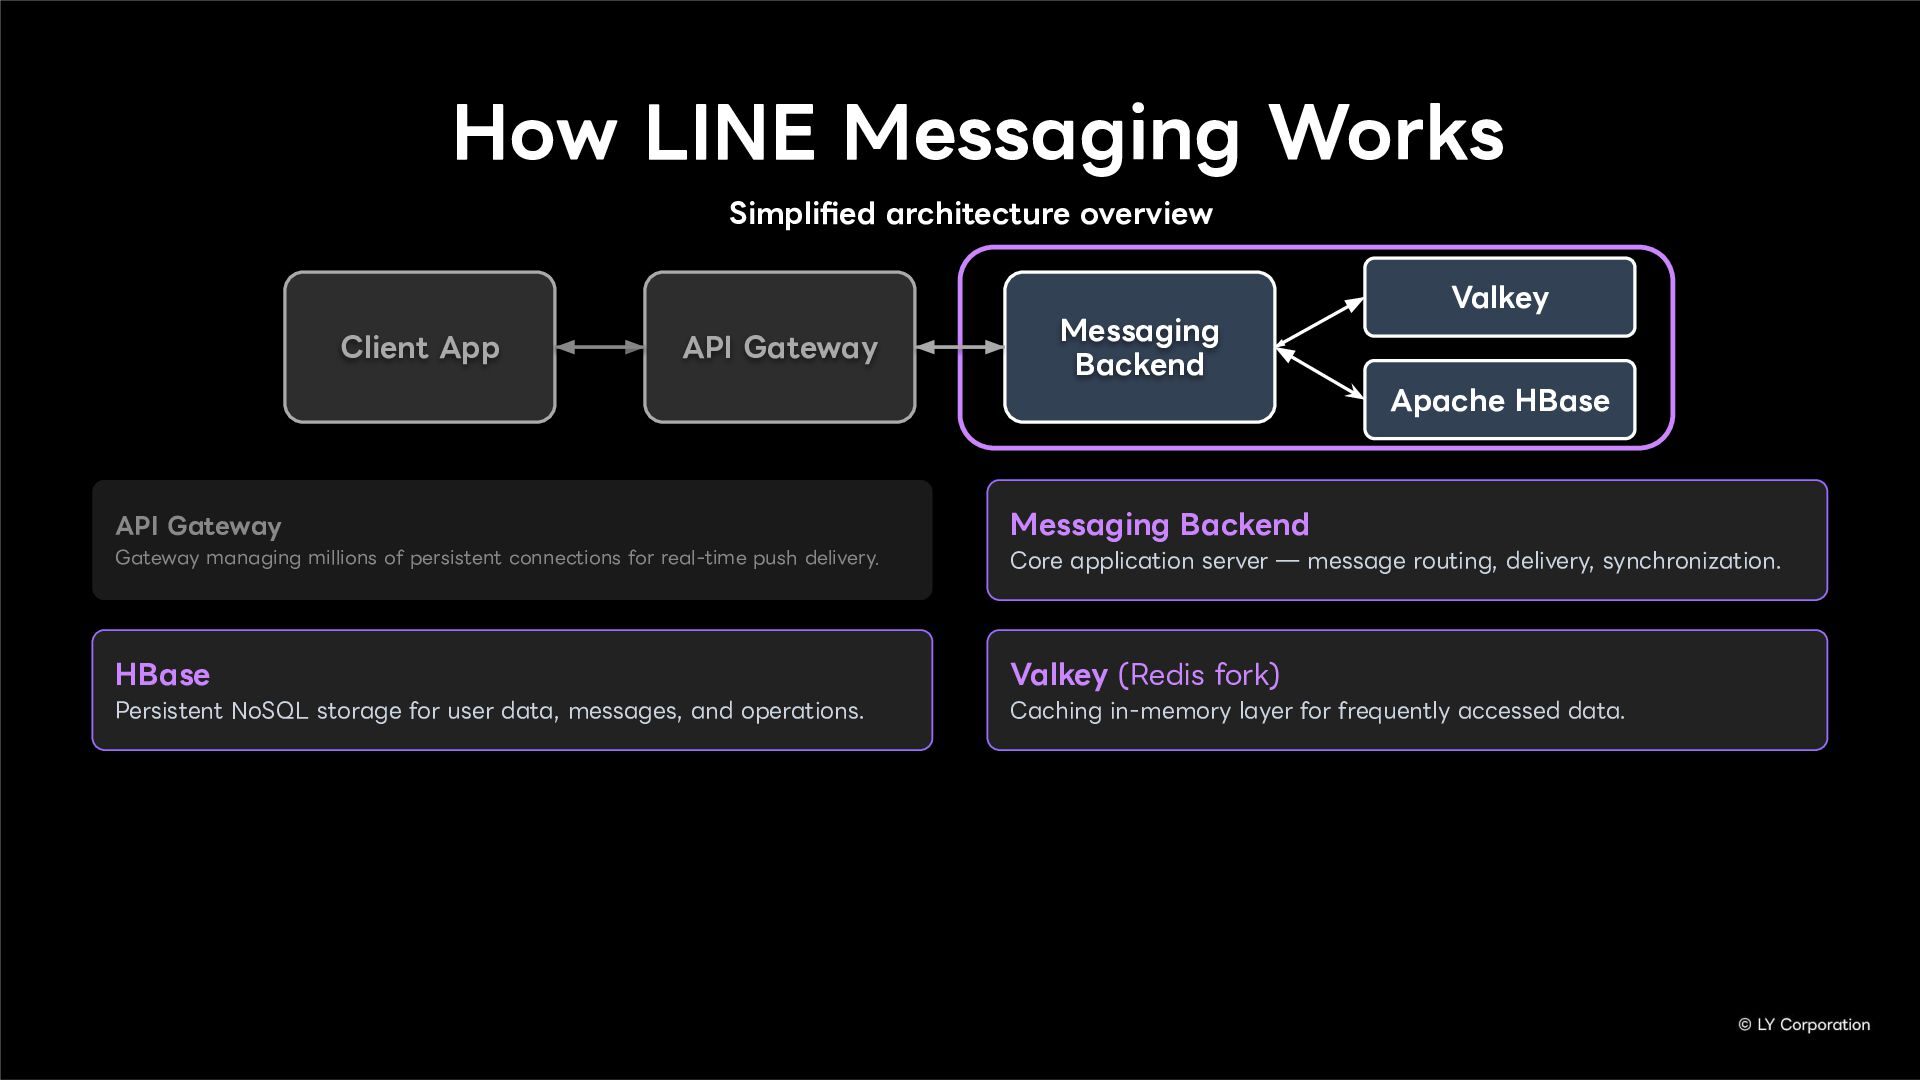
Simplified architecture overview How LINE Messaging Works Client App API
Gateway Messaging Backend Valkey API Gateway Gateway managing millions of persistent connections for real-time push delivery. Messaging Backend Core application server ̶ message routing, delivery, synchronization. HBase Persistent NoSQL storage for user data, messages, and operations. Valkey (Redis fork) Caching in-memory layer for frequently accessed data. Apache HBase -
Simplified architecture overview How LINE Messaging Works Client App API
Gateway Messaging Backend API Gateway Gateway managing millions of persistent connections for real-time push delivery. Messaging Backend Core application server ̶ message routing, delivery, synchronization. HBase Persistent NoSQL storage for user data, messages, and operations. Valkey (Redis fork) Caching in-memory layer for frequently accessed data. Valkey Apache HBase -
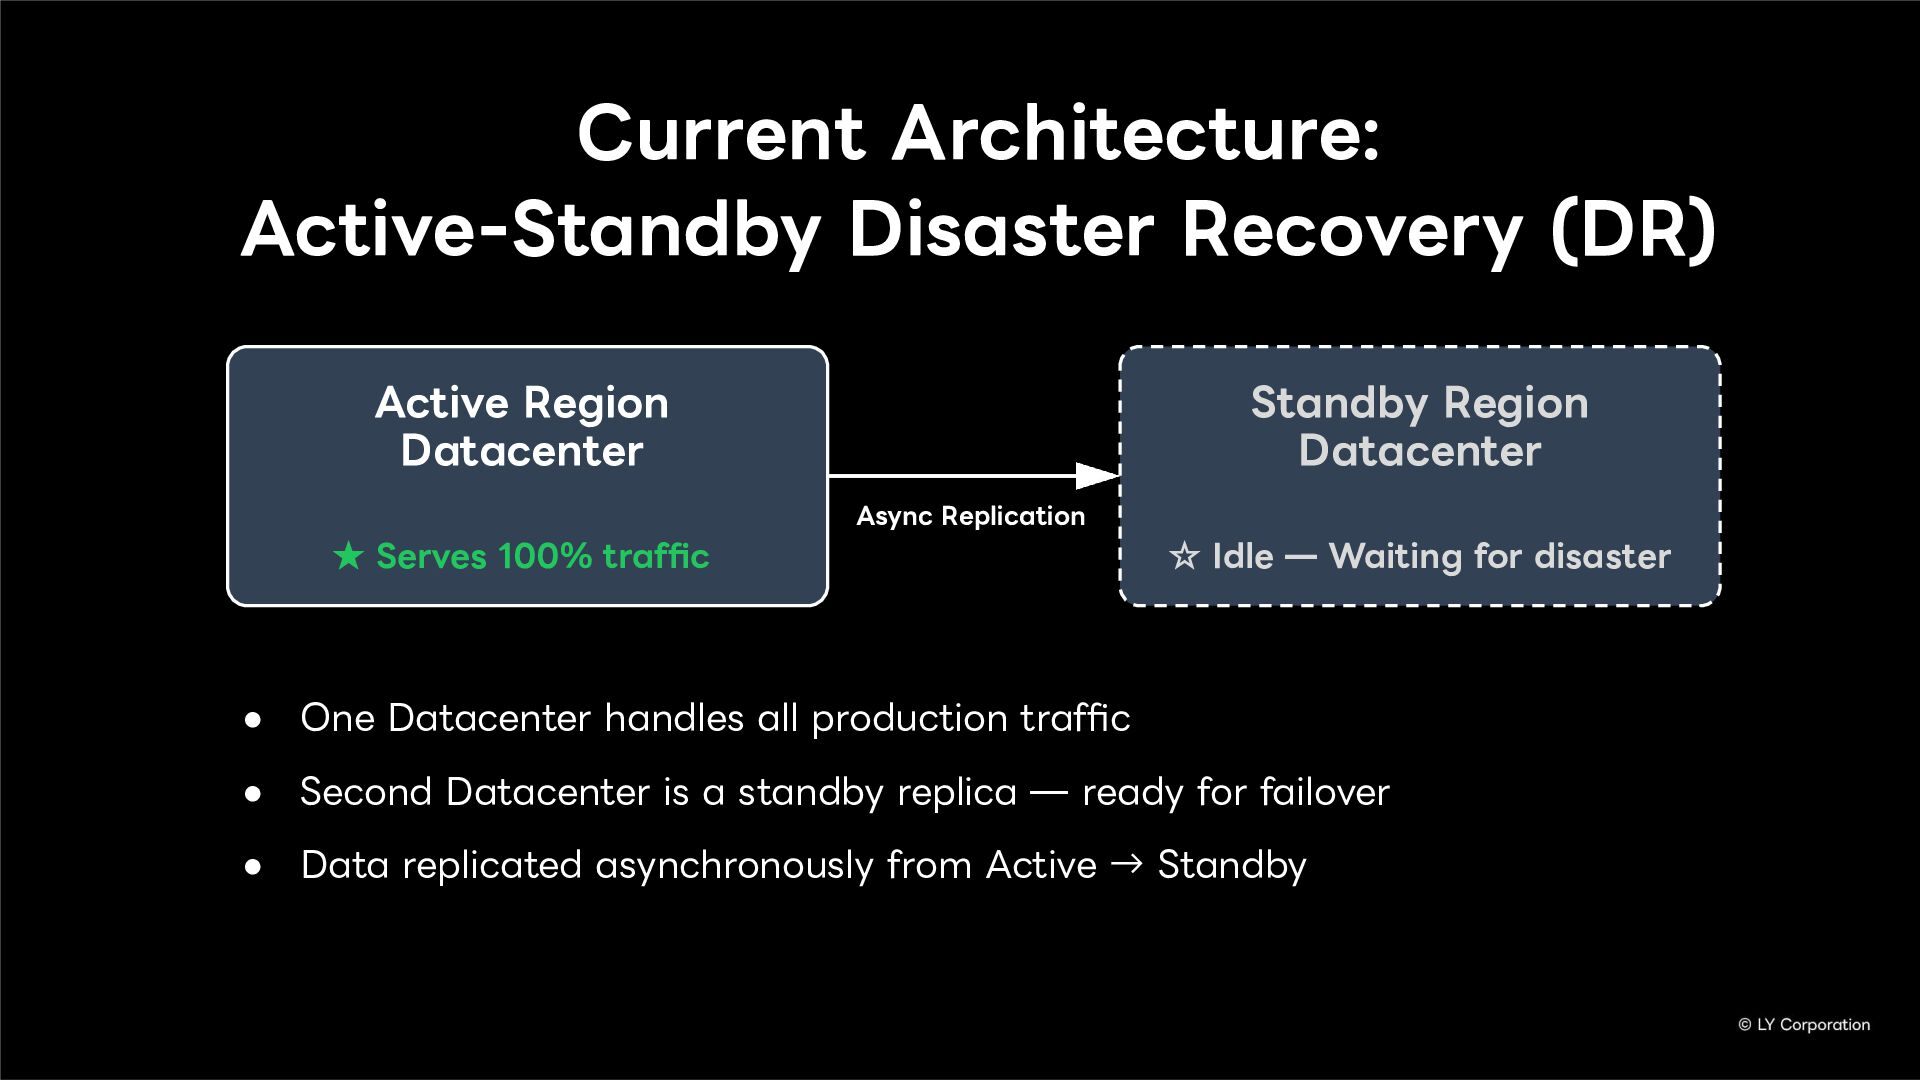
Current Architecture: Active-Standby Disaster Recovery (DR) • One Datacenter handles
all production traffic • Second Datacenter is a standby replica ̶ ready for failover • Data replicated asynchronously from Active → Standby Active Region Datacenter ★ Serves 100% traffic Async Replication Standby Region Datacenter ☆ Idle ̶ Waiting for disaster -
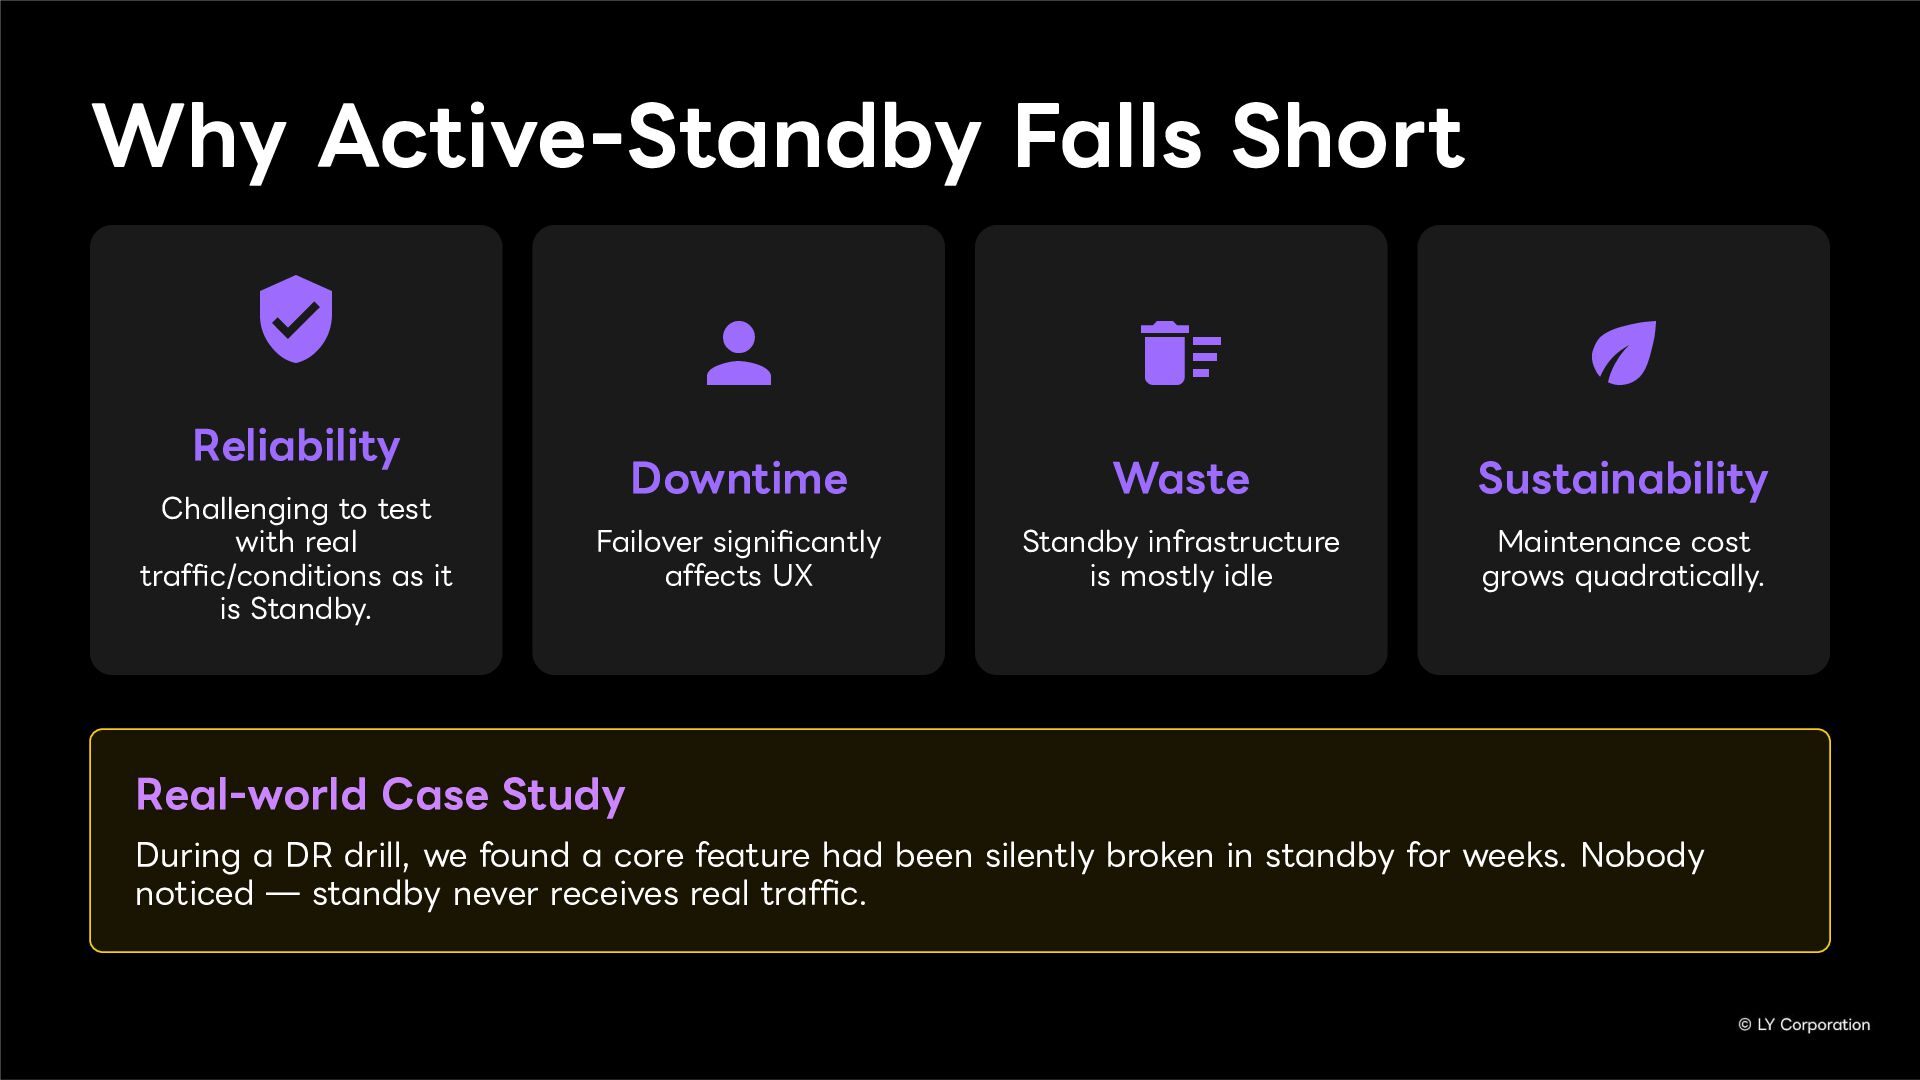
Why Active-Standby Falls Short Reliability Challenging to test with
real traffic/conditions as it is Standby. Downtime Failover significantly affects UX Waste Standby infrastructure is mostly idle Sustainability Maintenance cost grows quadratically. Real-world Case Study During a DR drill, we found a core feature had been silently broken in standby for weeks. Nobody noticed ̶ standby never receives real traffic. -
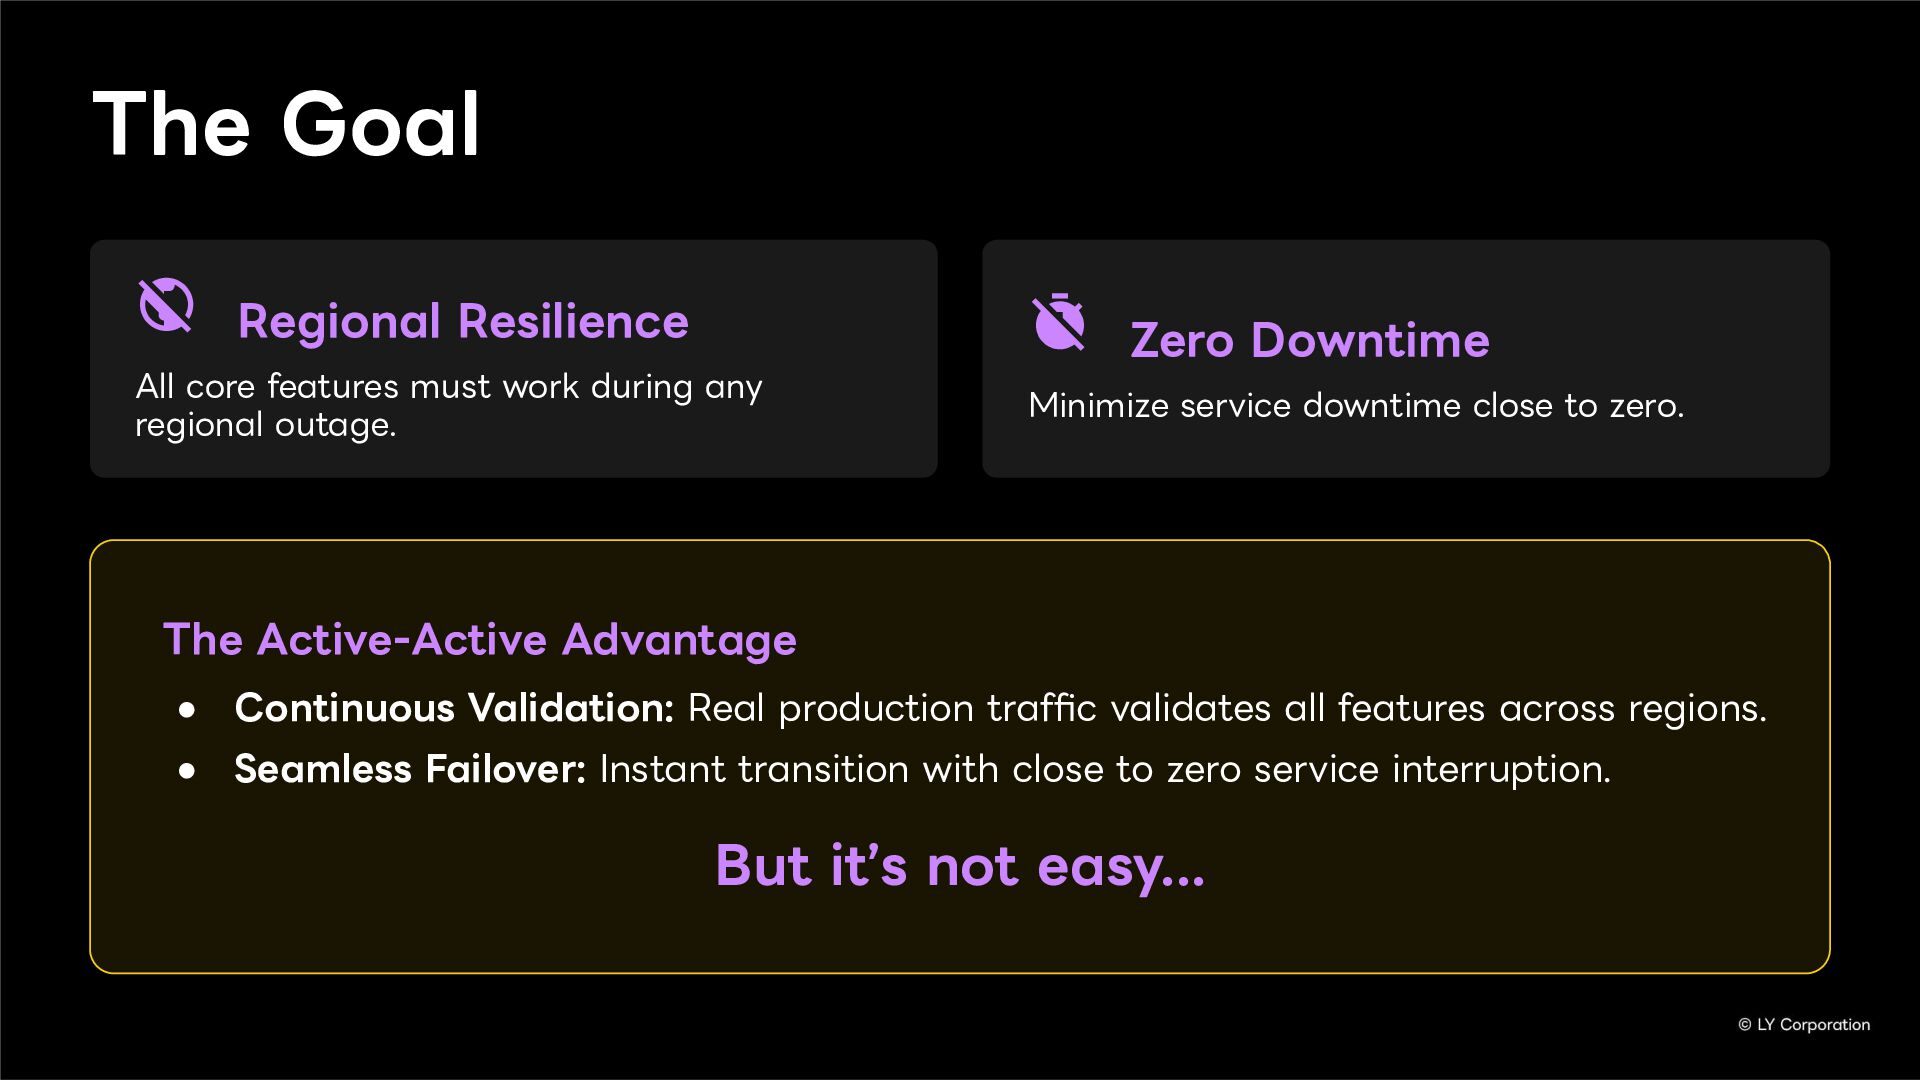
The Goal Regional Resilience All core features must work
during any regional outage. Zero Downtime Minimize service downtime close to zero. The Active-Active Advantage • Continuous Validation: Real production traffic validates all features across regions. • Seamless Failover: Instant transition with close to zero service interruption. But itʼs not easy... -
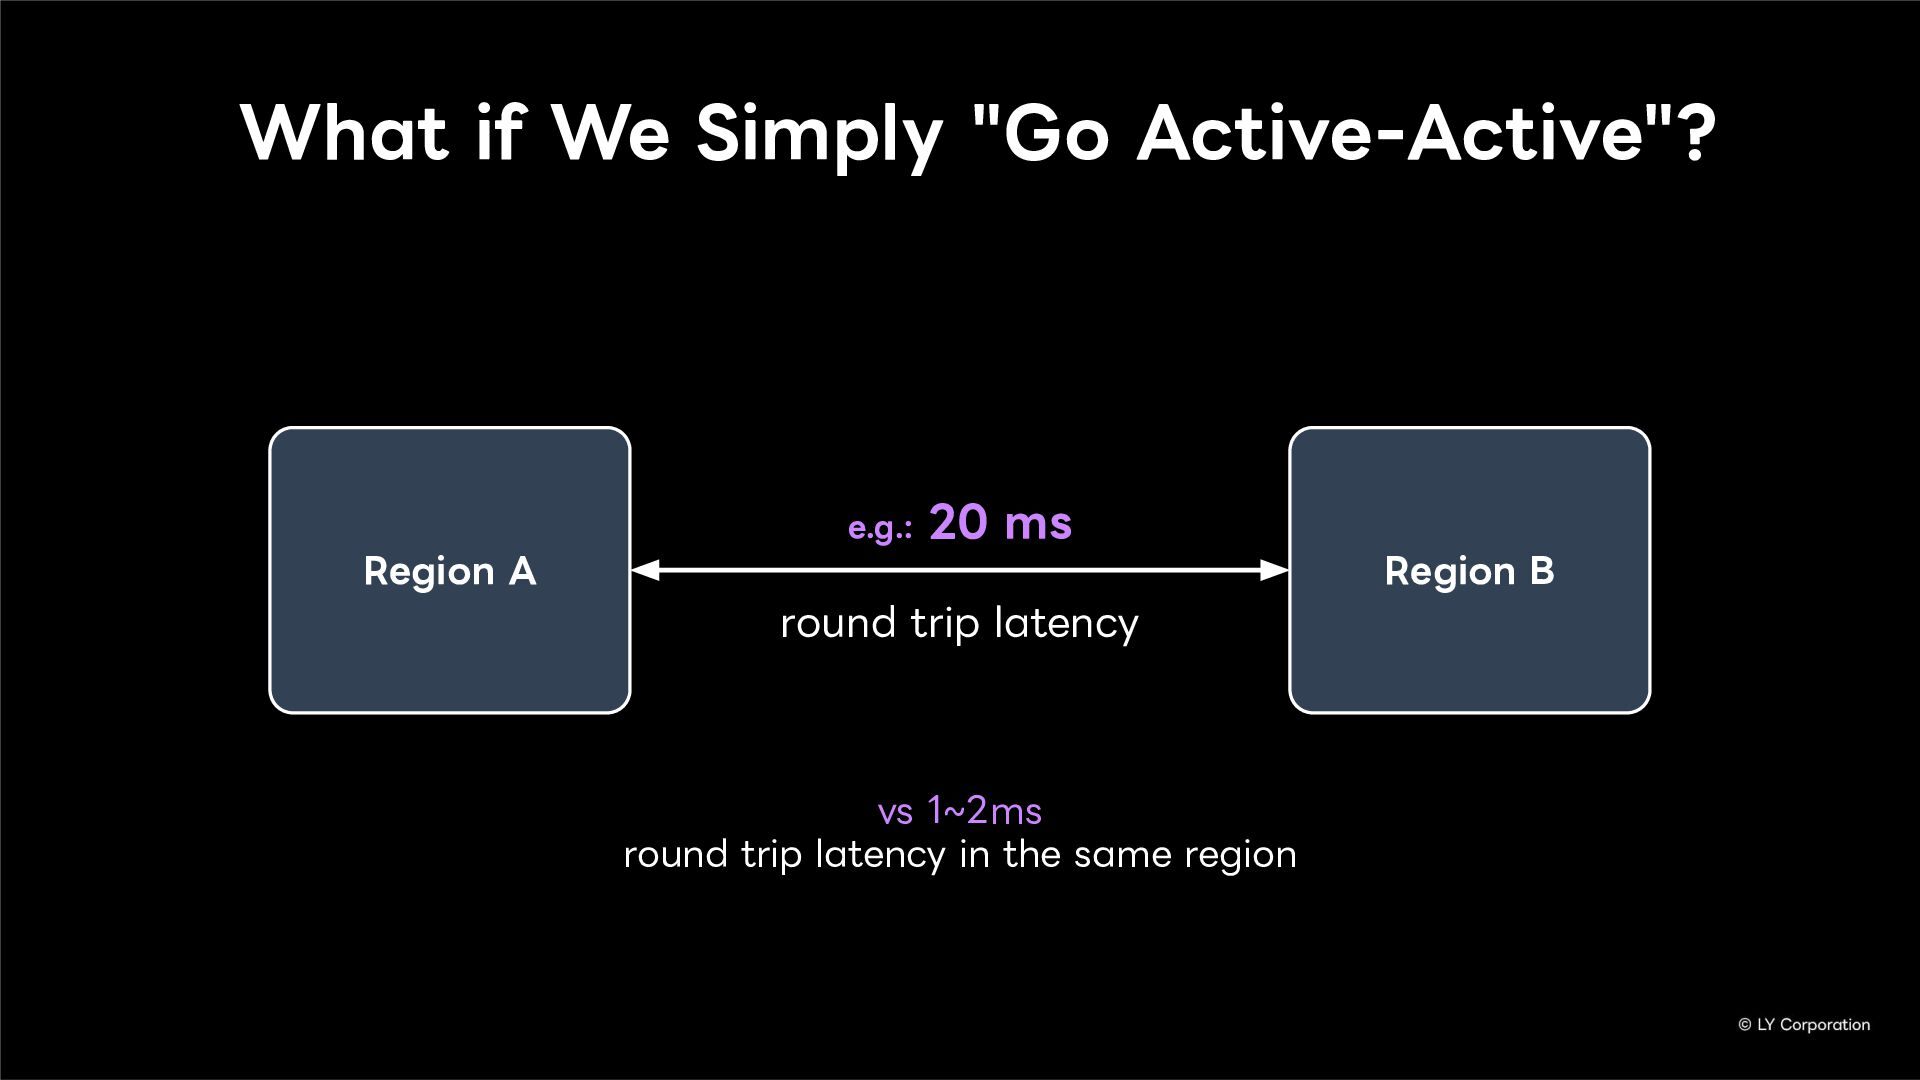
What if We Simply "Go Active-Active"? Region A Region B
e.g.: 20 ms round trip latency vs 1~2ms round trip latency in the same region -
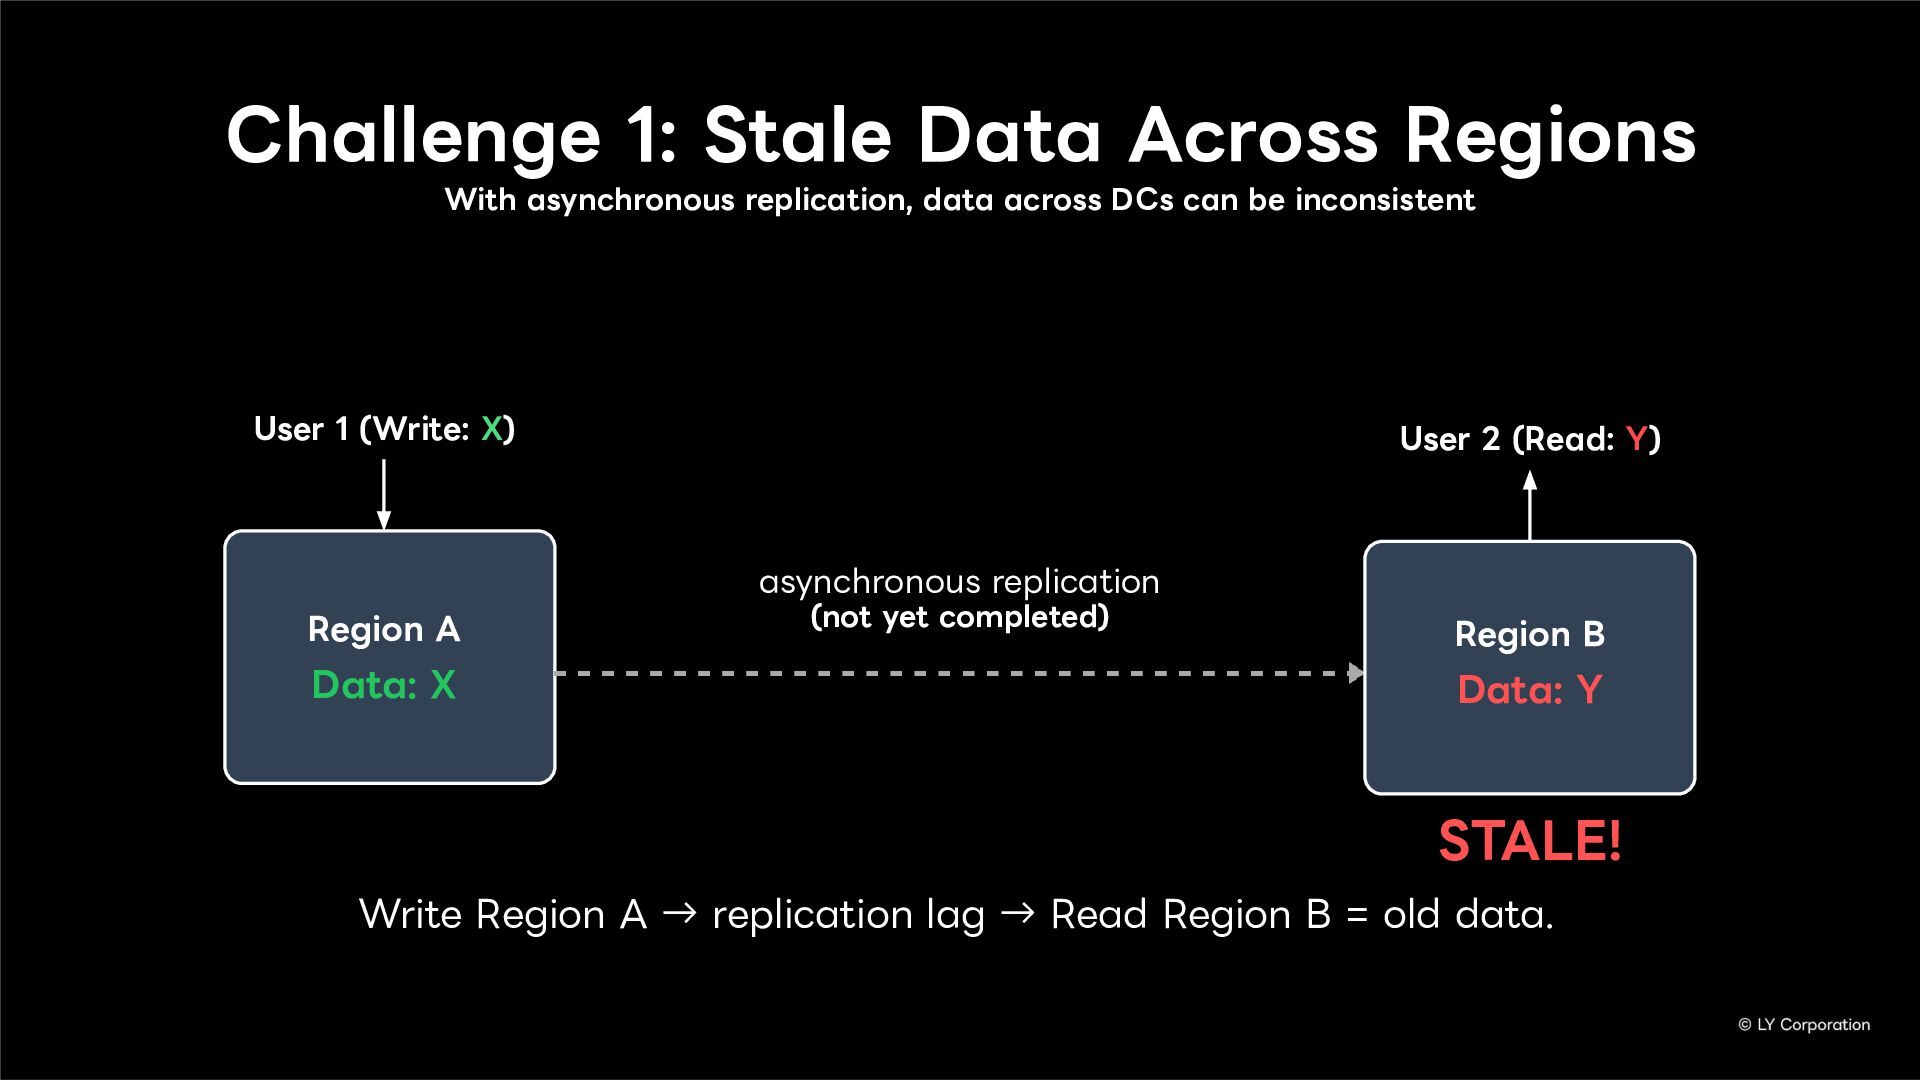
Challenge 1: Stale Data Across Regions With asynchronous replication, data
across DCs can be inconsistent Region A Data: X User 1 (Write: X) asynchronous replication (not yet completed) Region B Data: Y User 2 (Read: Y) STALE! Write Region A → replication lag → Read Region B = old data. -
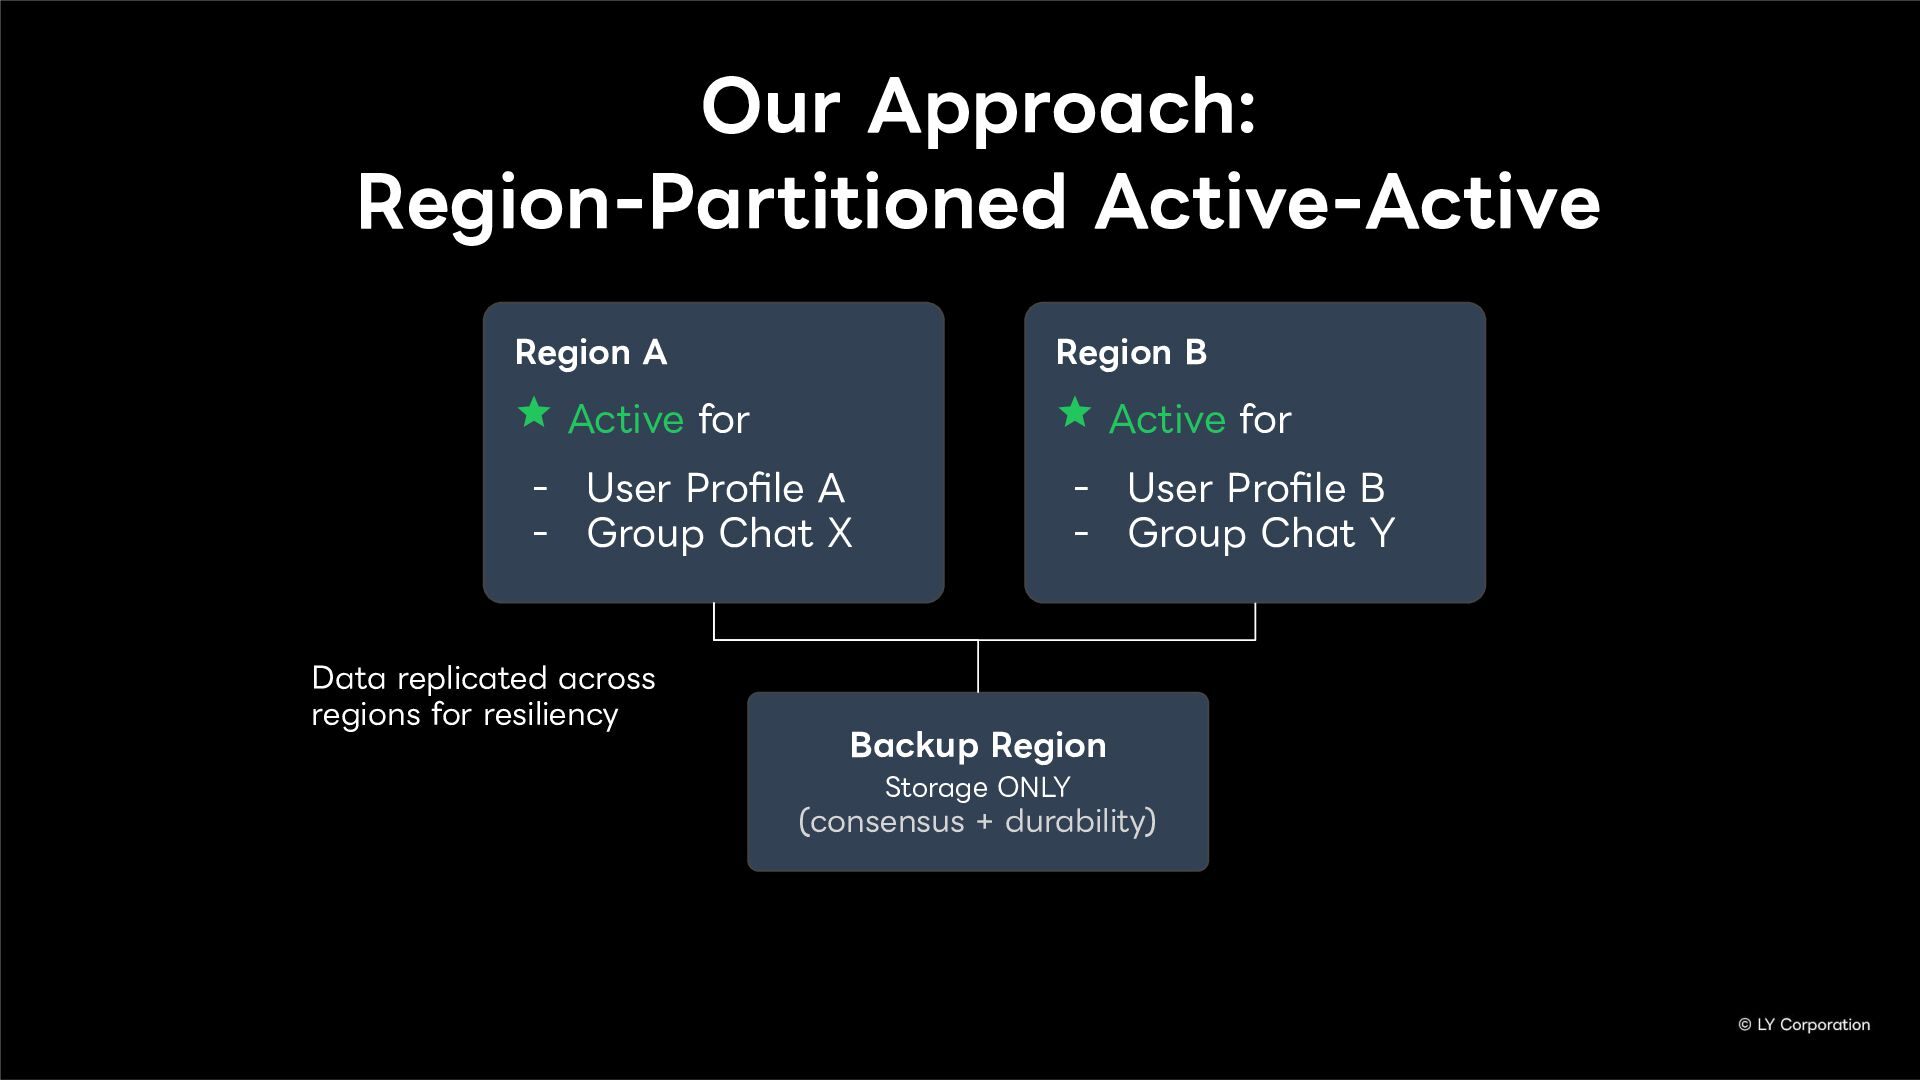
Our Approach: Region-Partitioned Active-Active Region A Active for -
User Profile A - Group Chat X Region B Active for - User Profile B - Group Chat Y Backup Region Storage ONLY (consensus + durability) Data replicated across regions for resiliency -
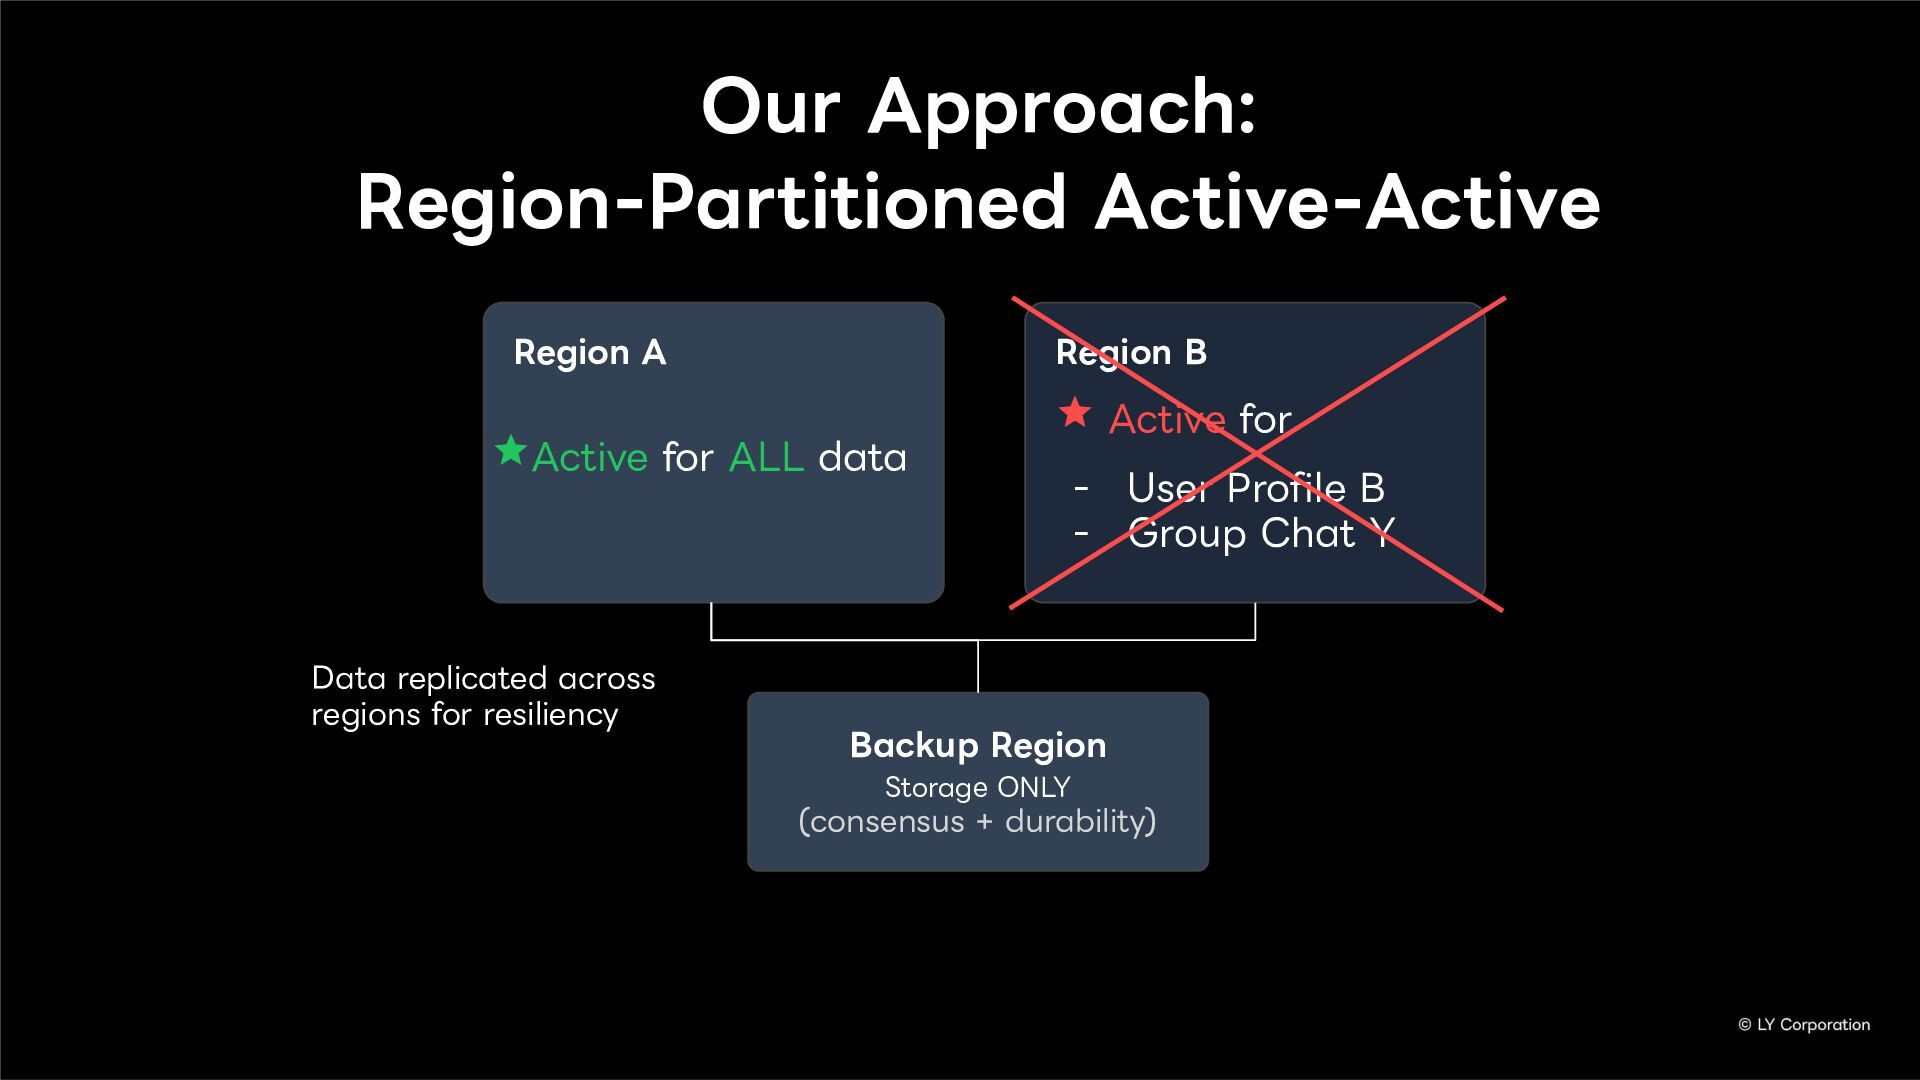
Region B Active for - User Profile B -
Group Chat Y Backup Region Storage ONLY (consensus + durability) Data replicated across regions for resiliency Region A Active for ALL data Our Approach: Region-Partitioned Active-Active -
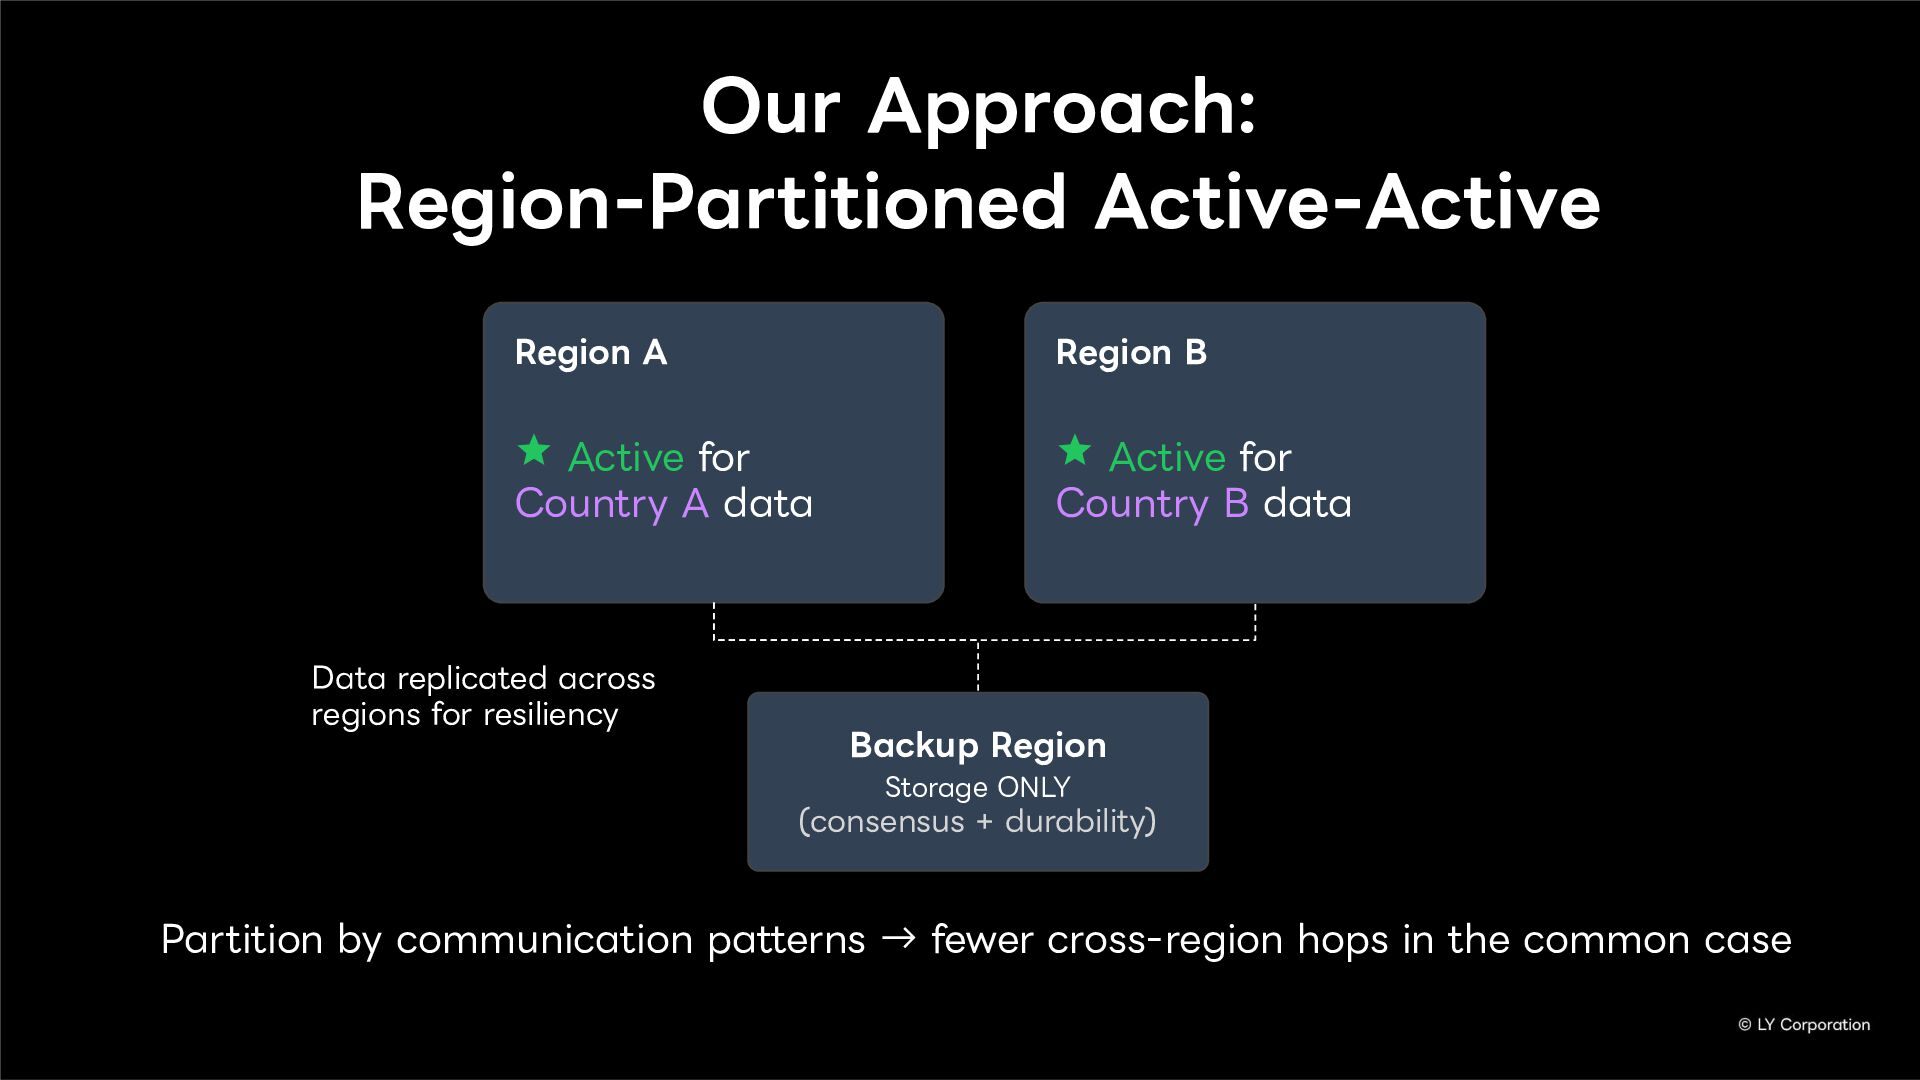
Region A Active for Country A data Region B
Active for Country B data Backup Region Storage ONLY (consensus + durability) Data replicated across regions for resiliency Our Approach: Region-Partitioned Active-Active Partition by communication patterns → fewer cross-region hops in the common case -
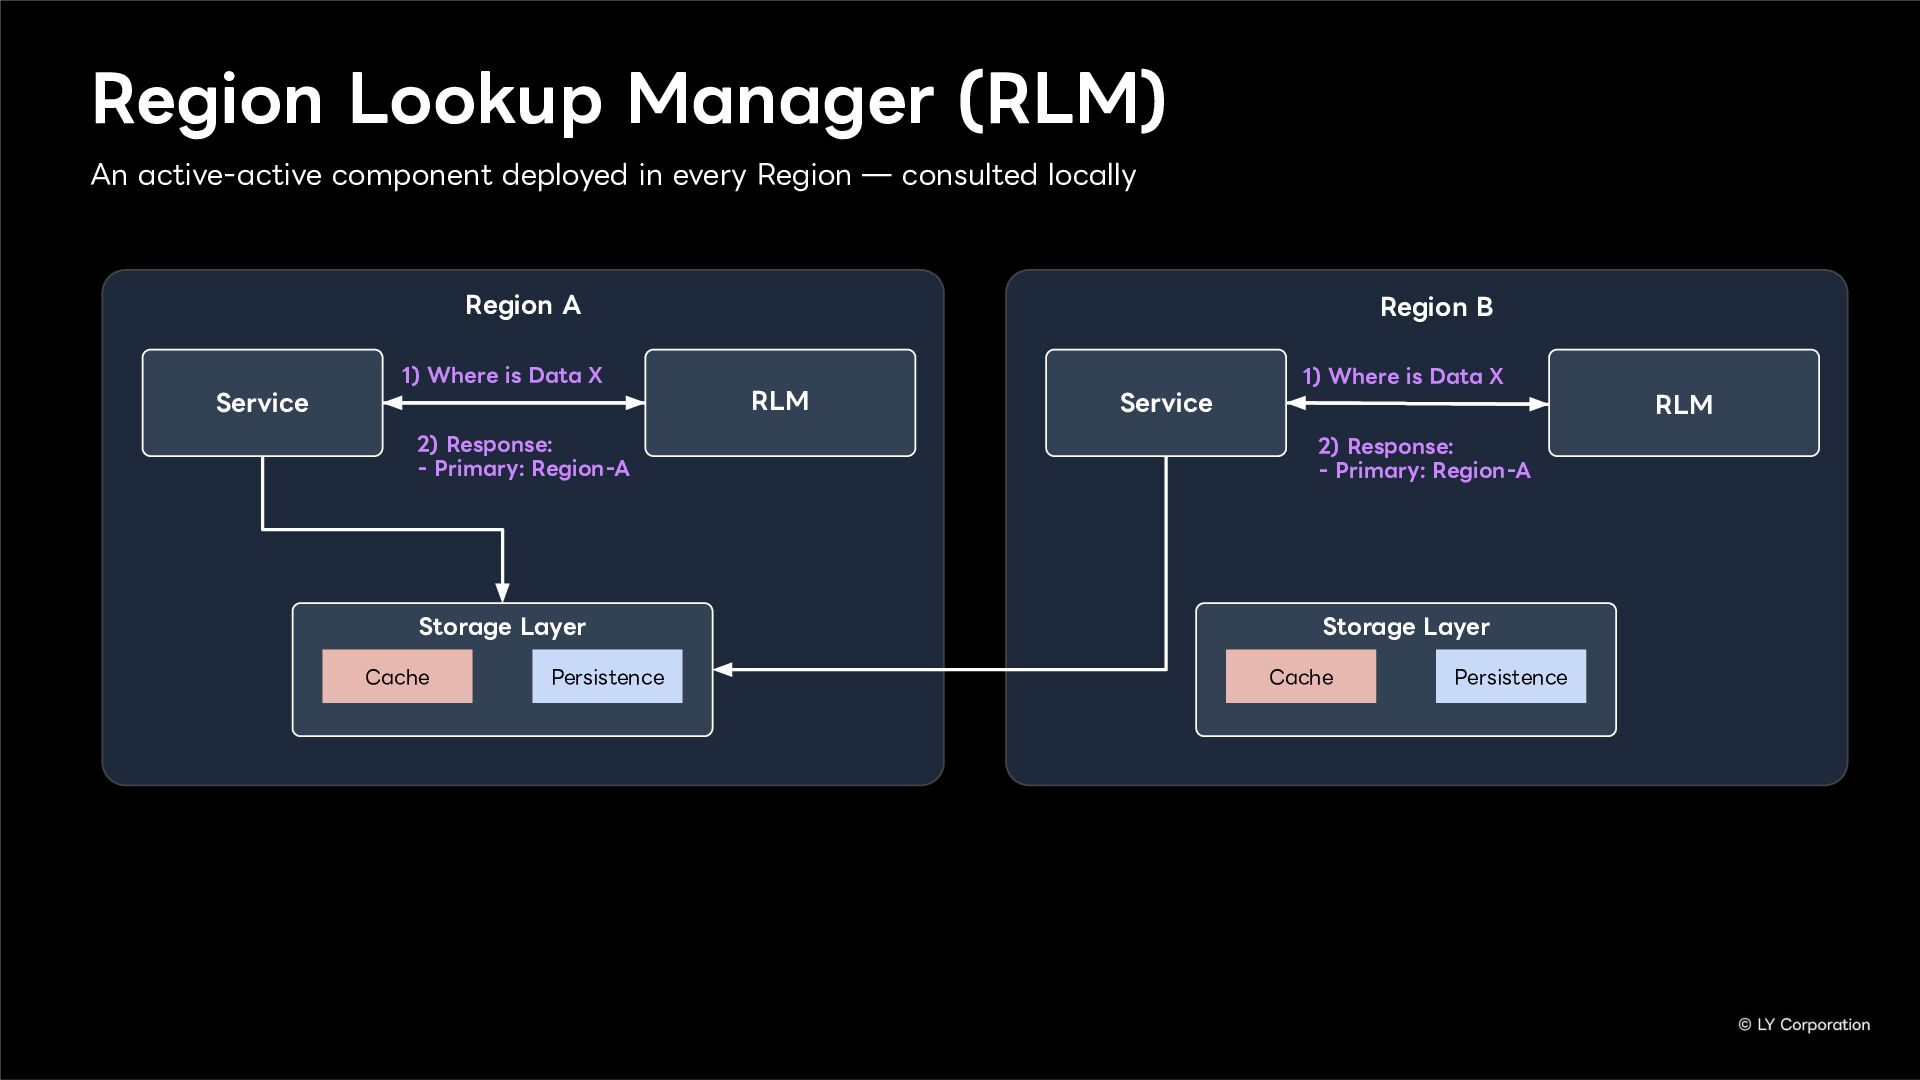
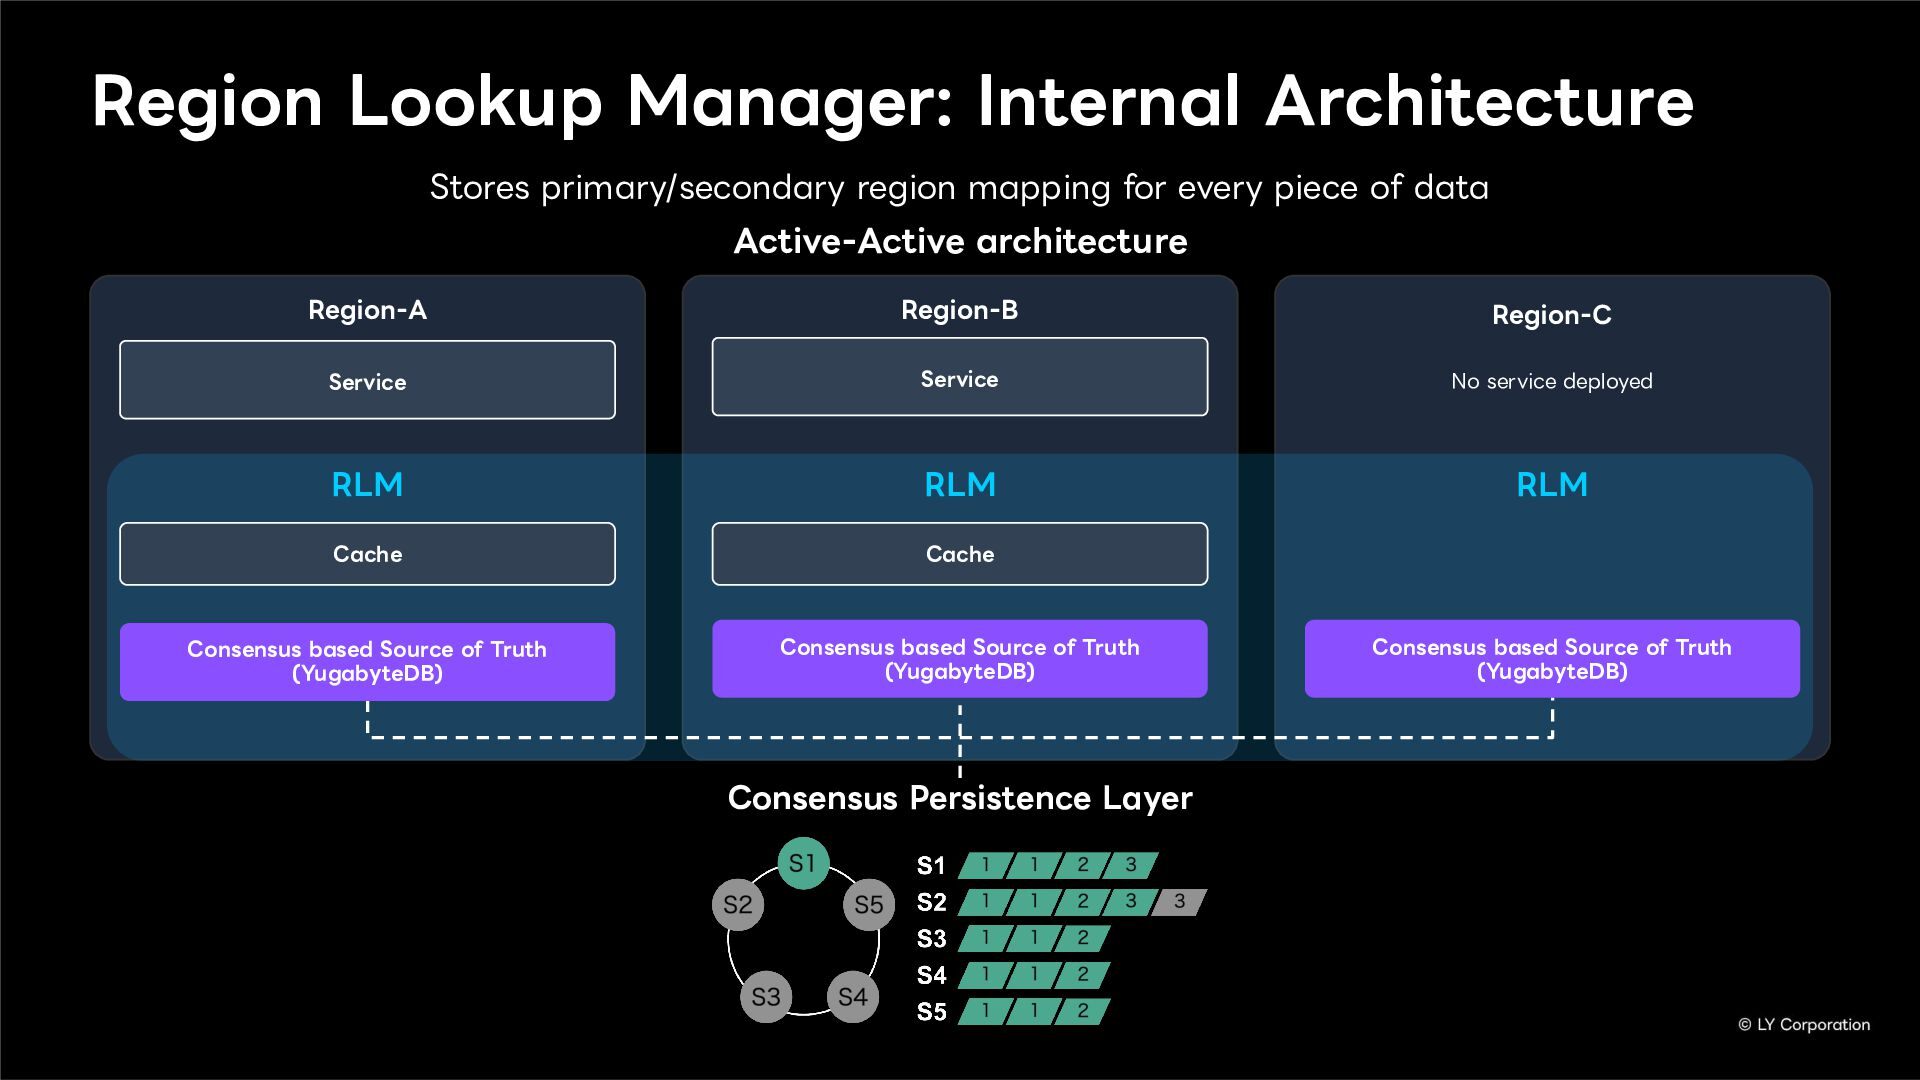
Region Lookup Manager (RLM) An active-active component deployed in every
Region ̶ consulted locally Service Storage Layer Cache Persistence 1) Where is Data X 2) Response: - Primary: Region-A Service Storage Layer Cache Persistence Region A Region B RLM RLM 1) Where is Data X 2) Response: - Primary: Region-A -
Stores primary/secondary region mapping for every piece of data Active-Active
architecture Region Lookup Manager: Internal Architecture Region-A Region-B No service deployed Service Service Region-C Cache Cache Consensus Persistence Layer Consensus based Source of Truth (YugabyteDB) RLM RLM RLM Consensus based Source of Truth (YugabyteDB) Consensus based Source of Truth (YugabyteDB) -
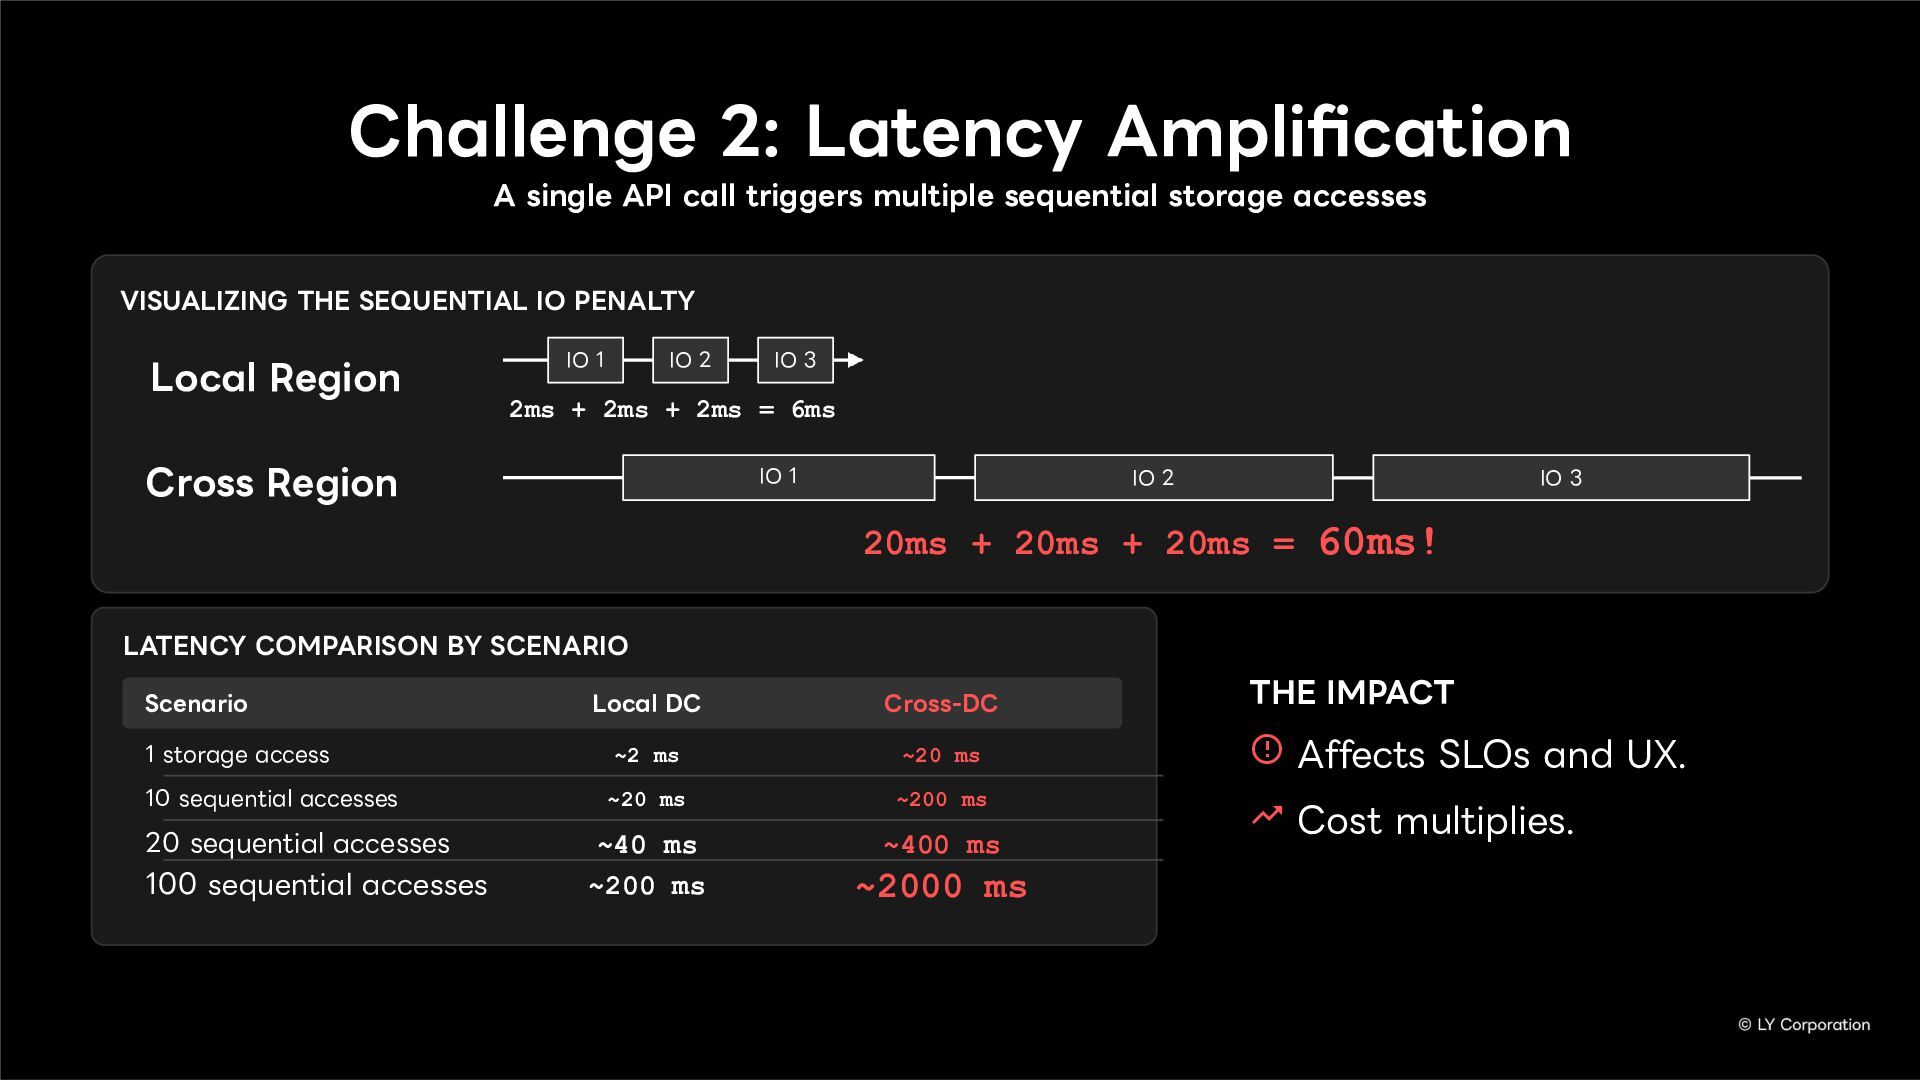
Challenge 2: Latency Amplification A single API call triggers multiple
sequential storage accesses VISUALIZING THE SEQUENTIAL IO PENALTY IO 1 IO 2 IO 3 2ms + 2ms + 2ms = 6ms IO 1 IO 2 IO 3 20ms + 20ms + 20ms = 60ms! LATENCY COMPARISON BY SCENARIO Scenario Local DC Cross-DC 1 storage access ~2 ms ~20 ms 10 sequential accesses ~20 ms ~200 ms 20 sequential accesses ~40 ms ~400 ms 100 sequential accesses ~200 ms ~2000 ms THE IMPACT Affects SLOs and UX. Cost multiplies. Local Region Cross Region -
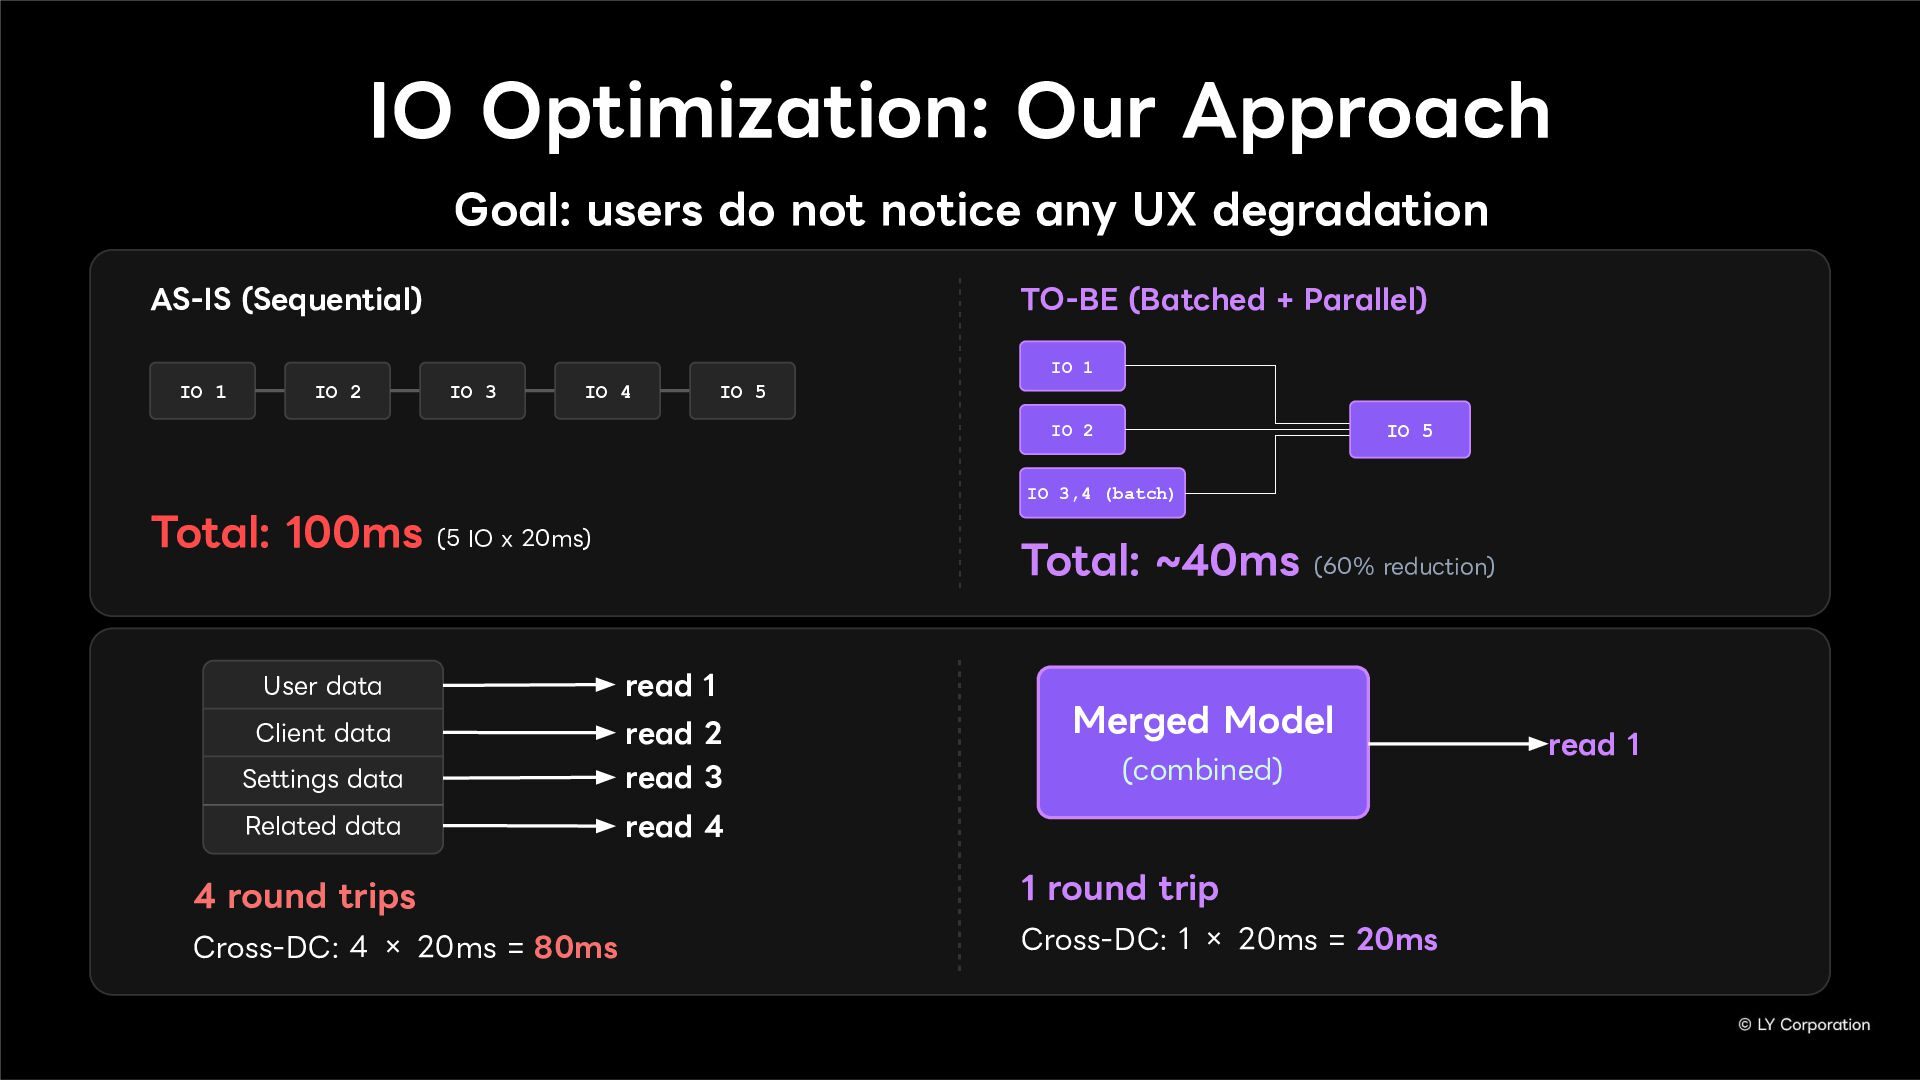
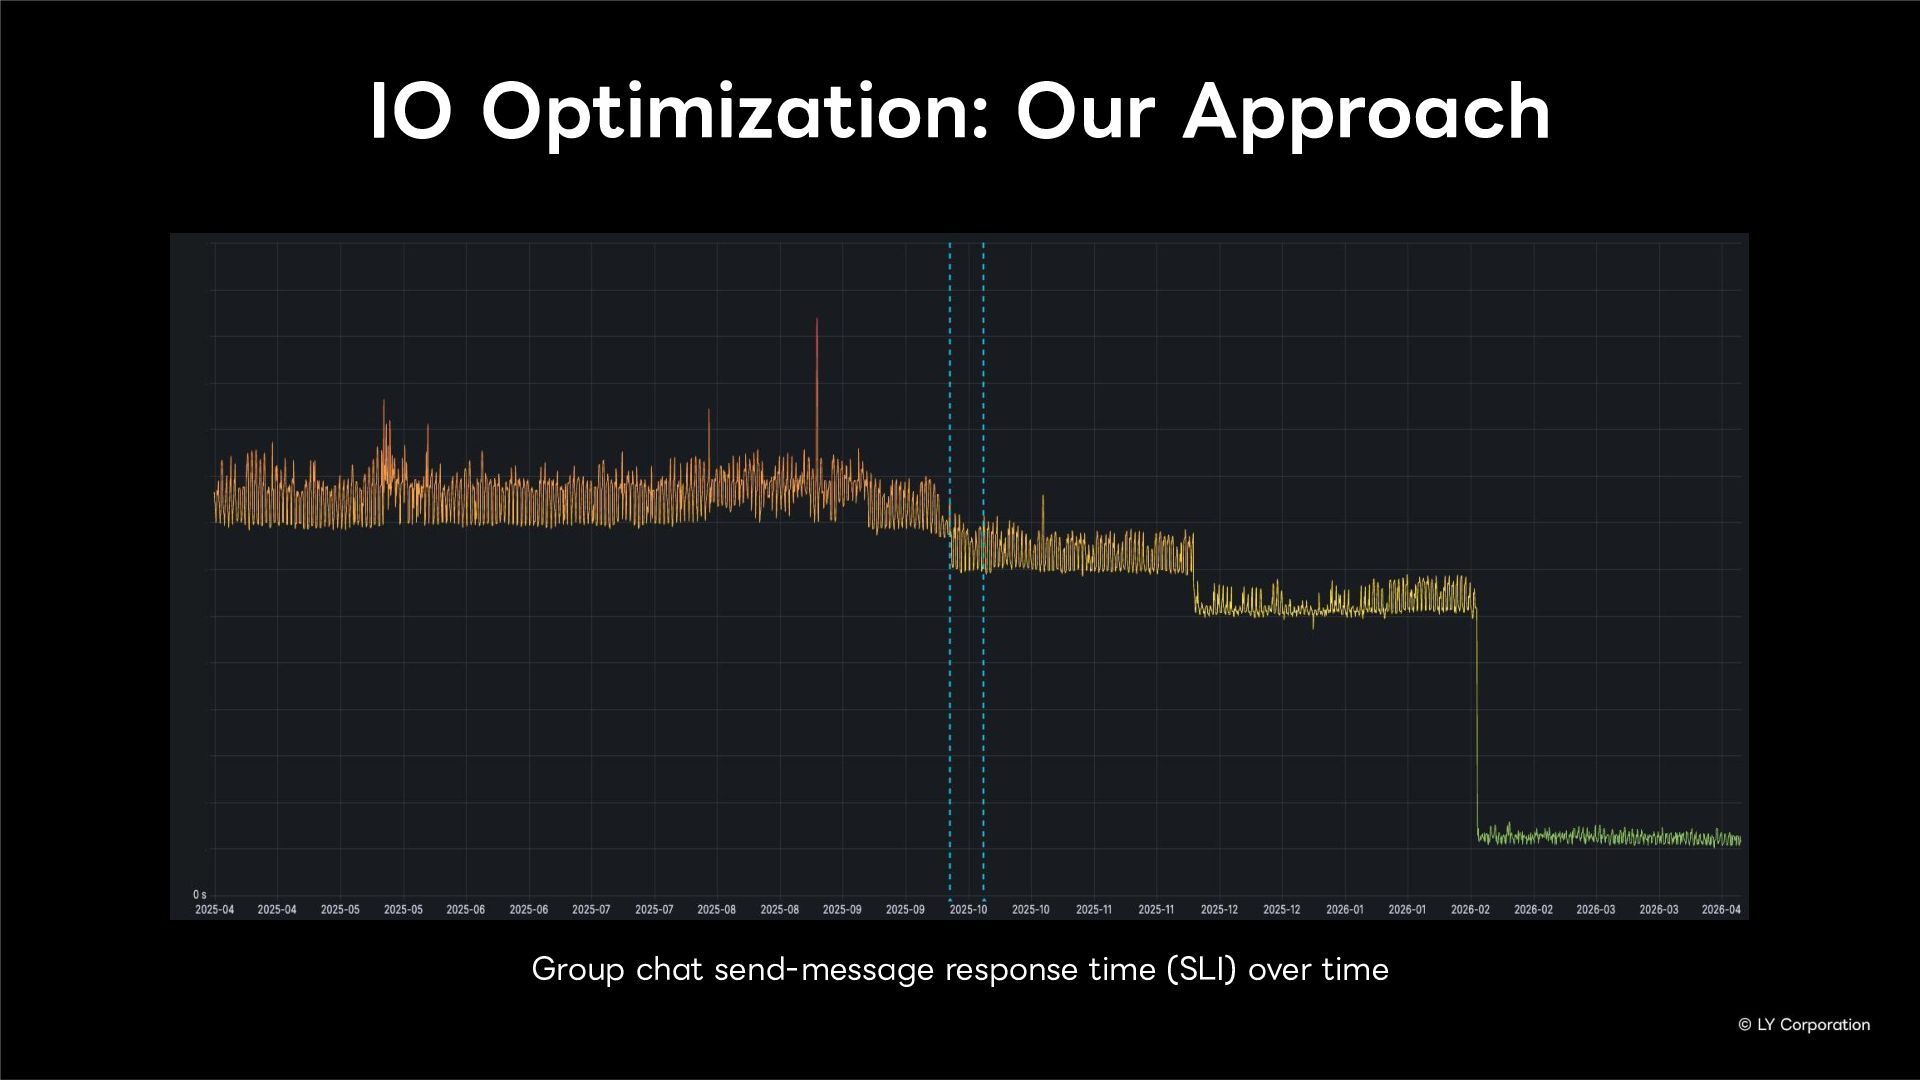
IO Optimization: Our Approach AS-IS (Sequential) TO-BE (Batched + Parallel)
IO 1 IO 2 IO 3 IO 4 IO 5 IO 1 IO 2 IO 3,4 (batch) IO 5 Total: 100ms (5 IO x 20ms) Total: ~40ms (60% reduction) Goal: users do not notice any UX degradation User data Client data Settings data read 1 4 round trips Cross-DC: 4 × 20ms = 80ms Merged Model (combined) read 1 1 round trip Cross-DC: 1 × 20ms = 20ms read 2 read 3 Related data read 4 -
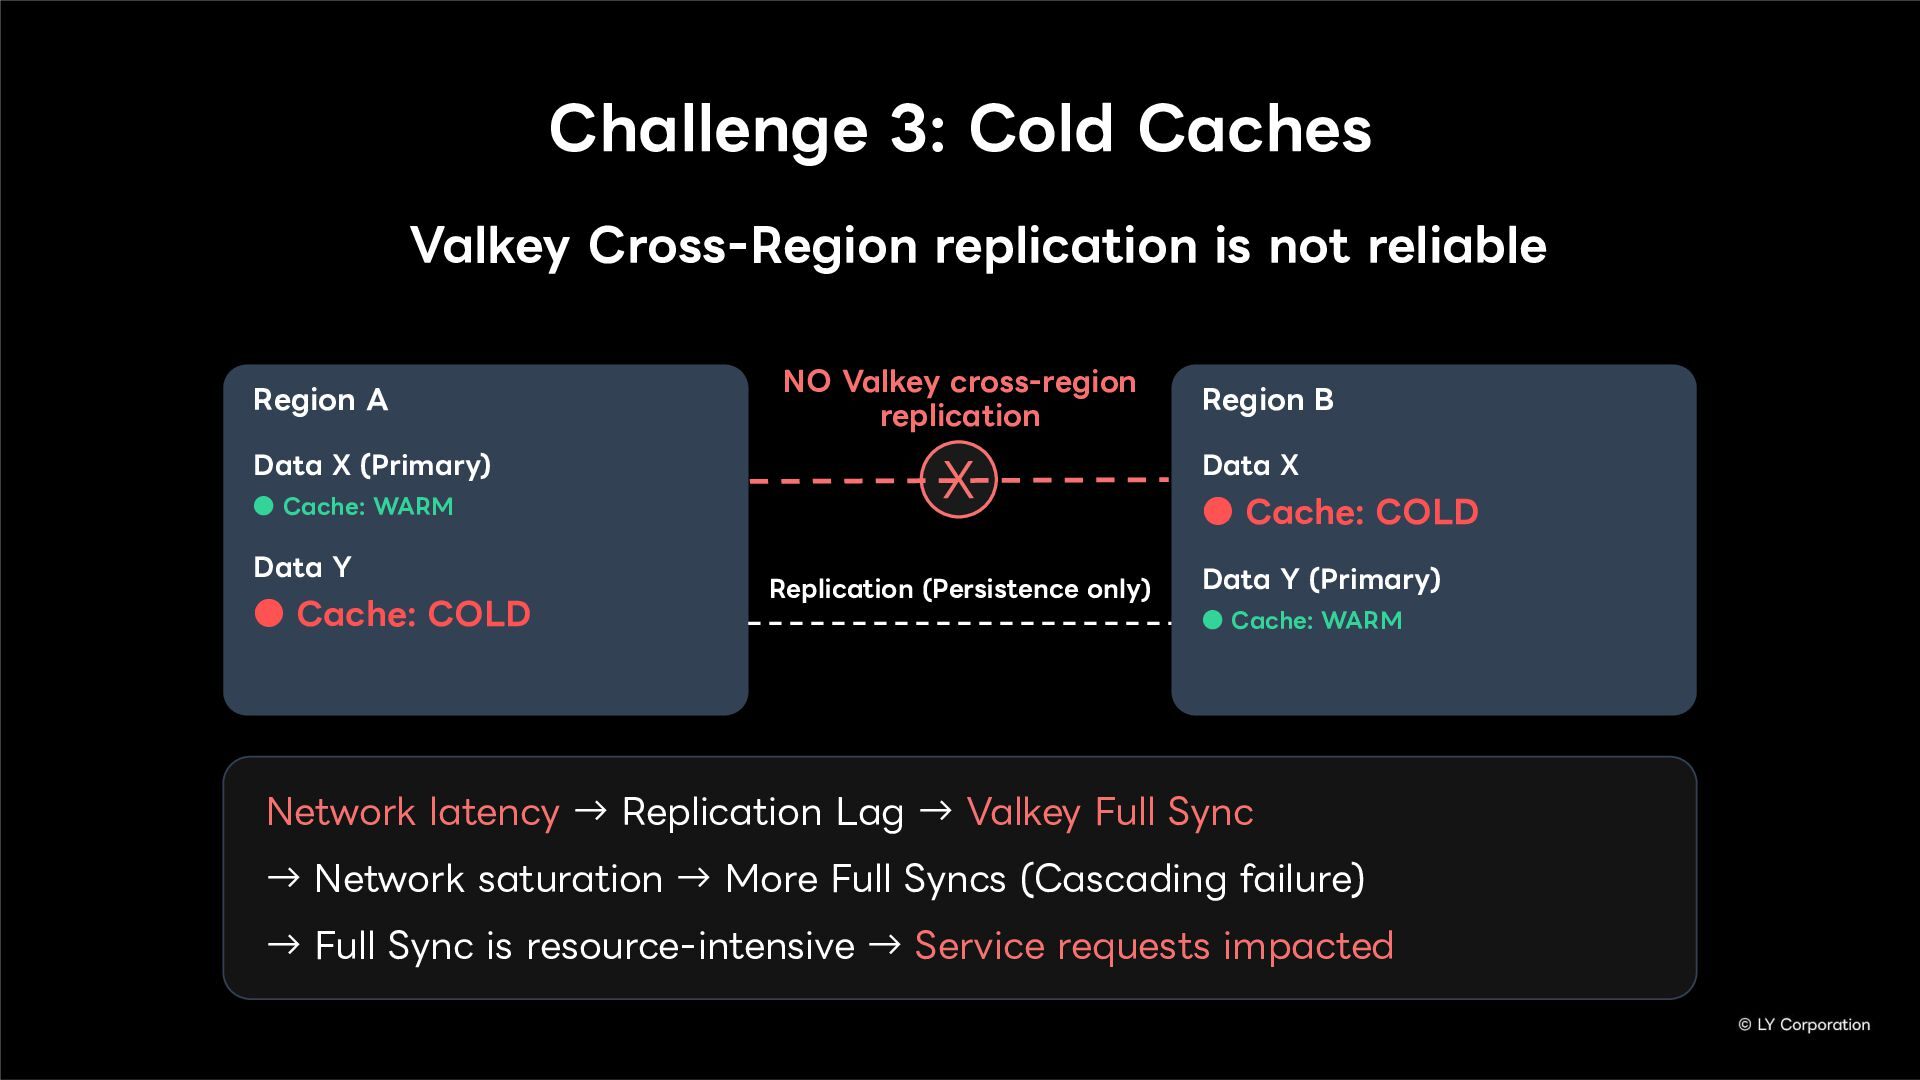
Valkey Cross-Region replication is not reliable Replication (Persistence only) X
Challenge 3: Cold Caches Network latency → Replication Lag → Valkey Full Sync → Network saturation → More Full Syncs (Cascading failure) → Full Sync is resource-intensive → Service requests impacted Region A Data X (Primary) • Cache: WARM Data Y • Cache: COLD Region B Data X • Cache: COLD Data Y (Primary) • Cache: WARM NO Valkey cross-region replication -
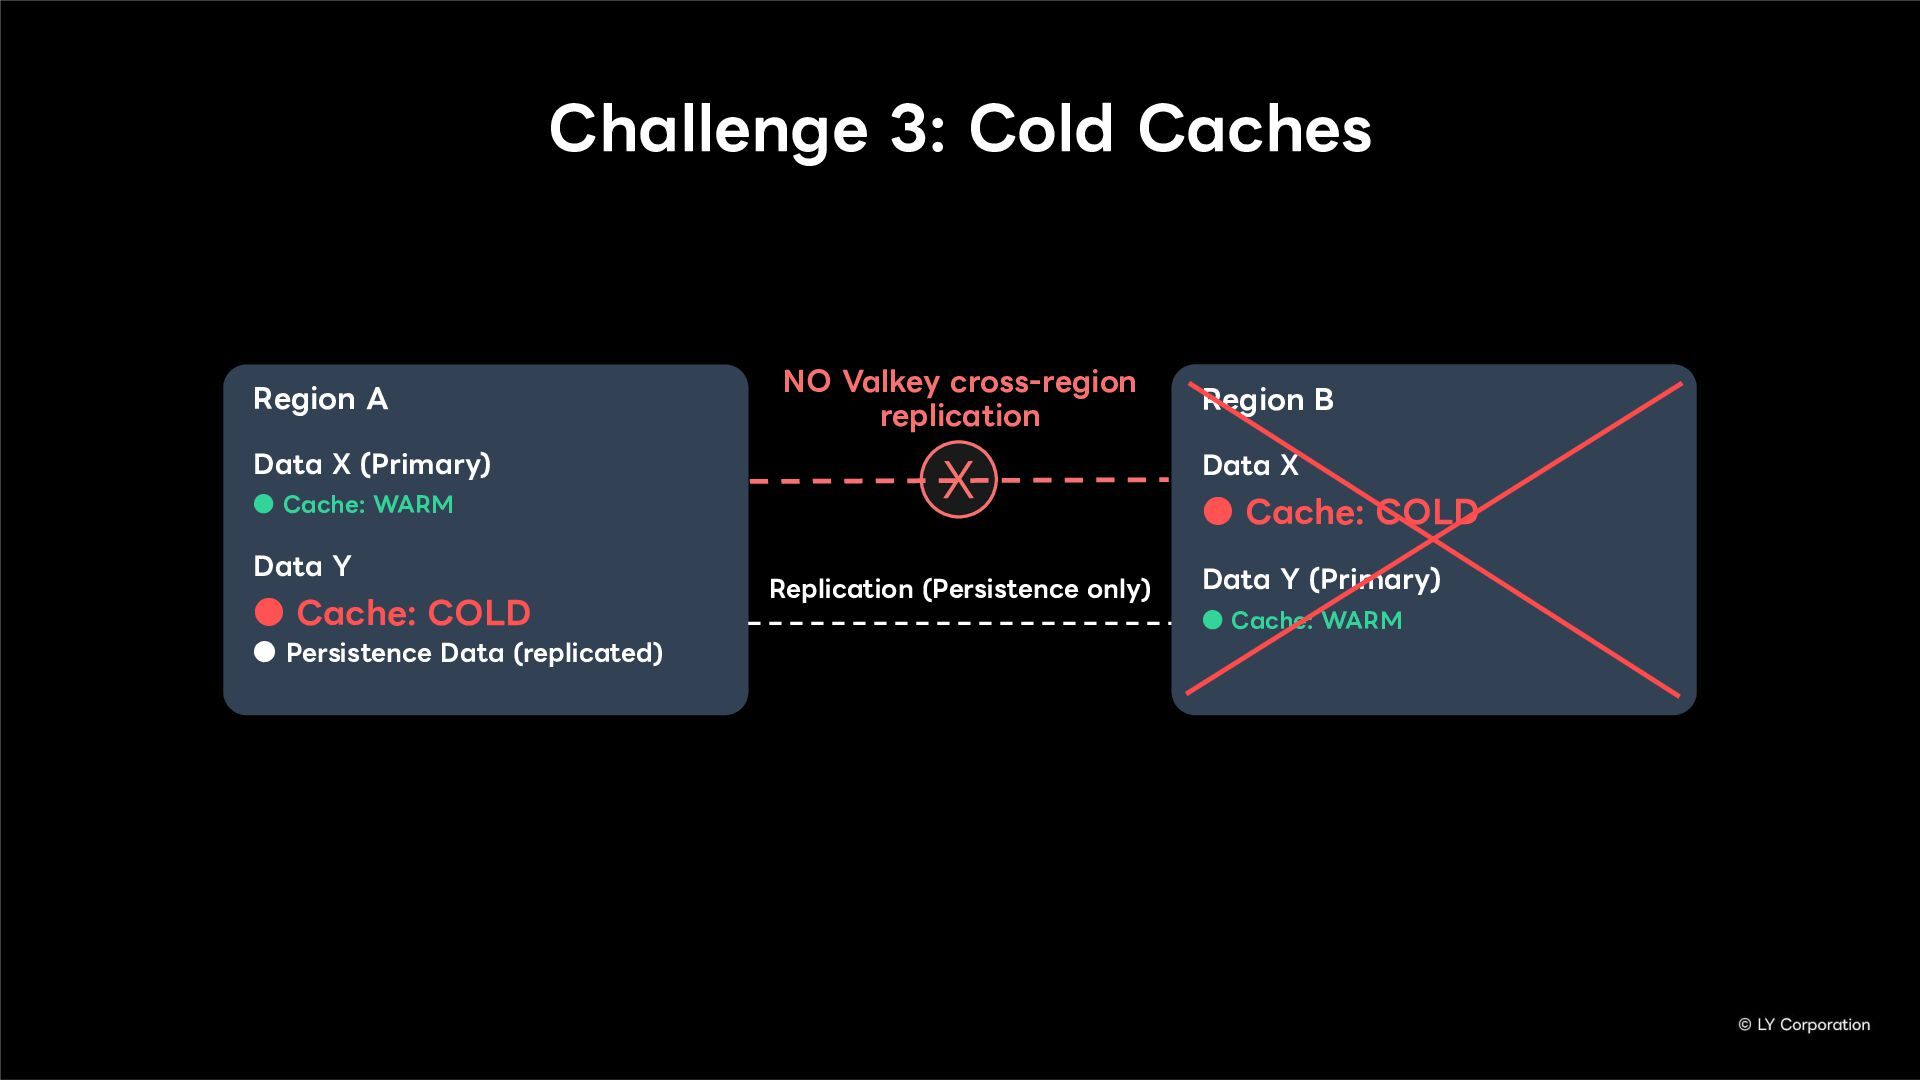
Region A Data X (Primary) • Cache: WARM Data Y
• Cache: COLD • Persistence Data (replicated) Replication (Persistence only) X Challenge 3: Cold Caches Region B Data X • Cache: COLD Data Y (Primary) • Cache: WARM NO Valkey cross-region replication -
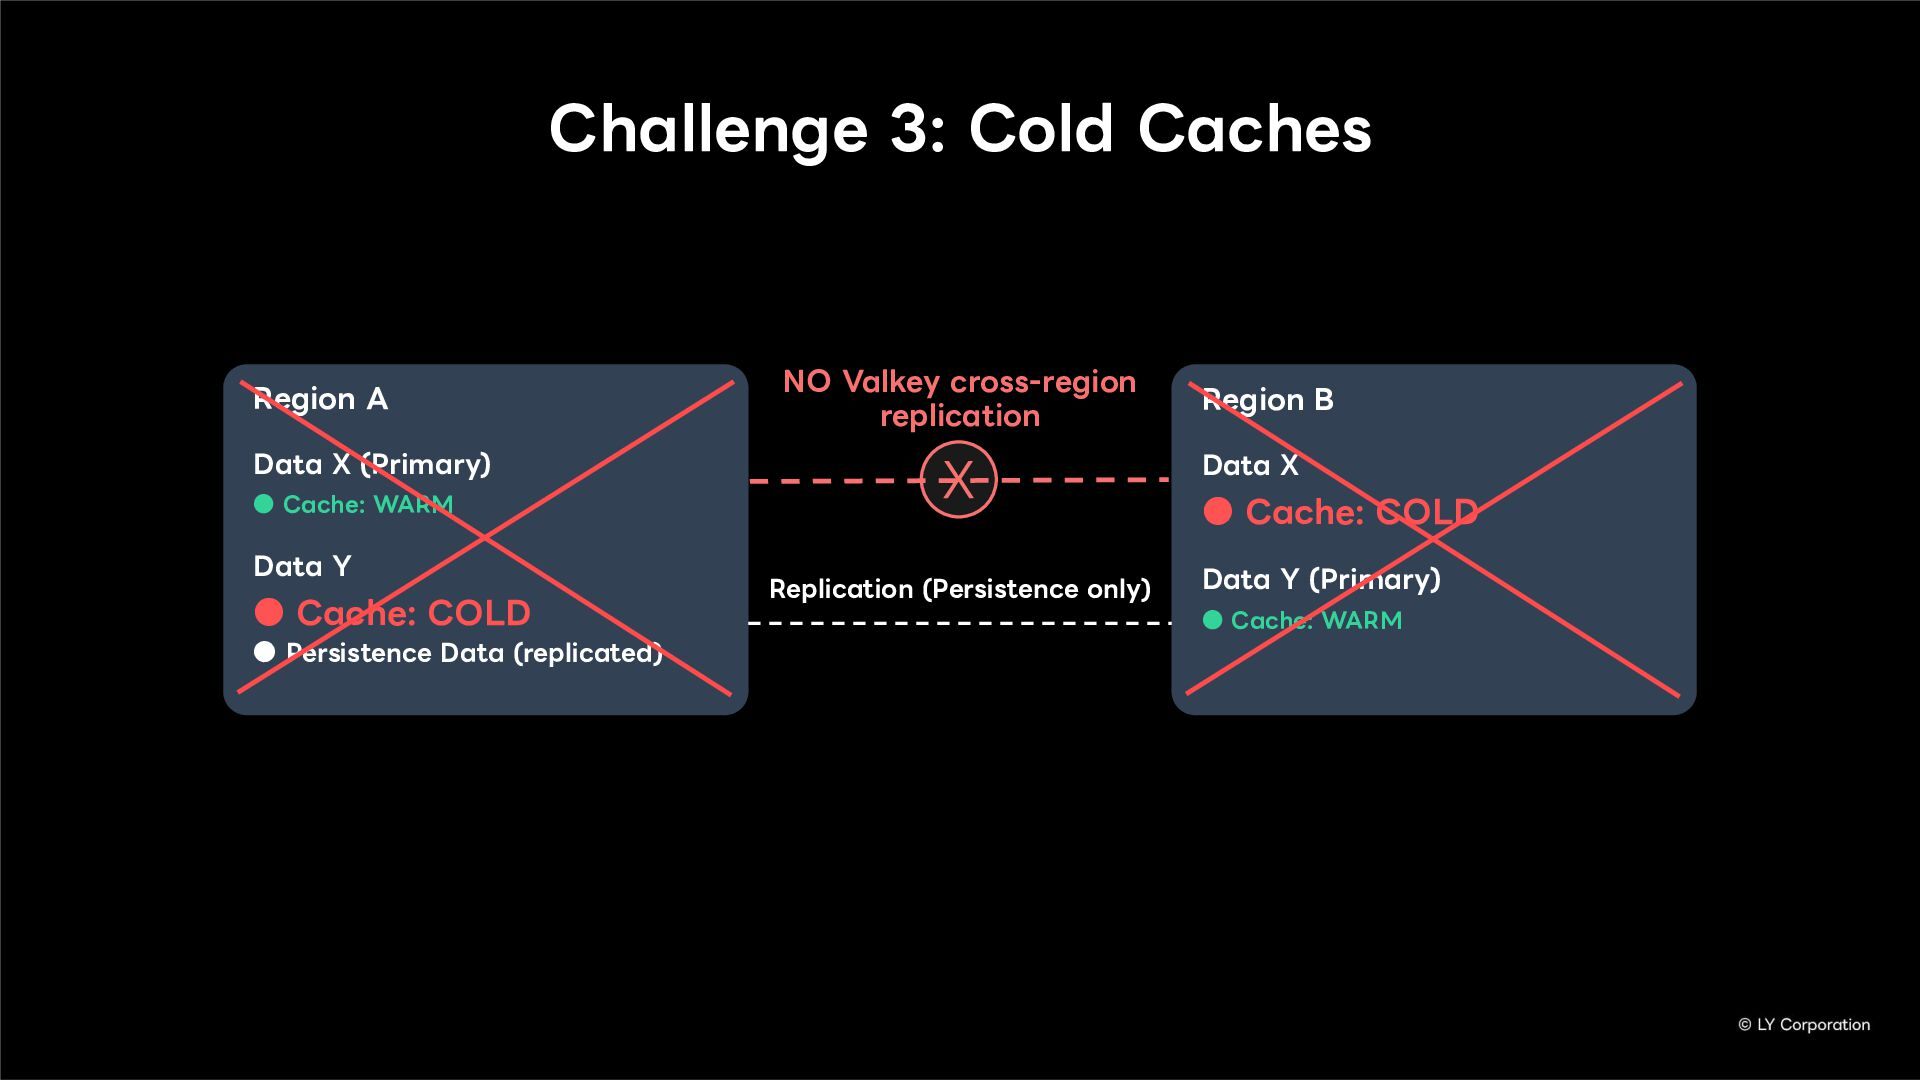
Region A Data X (Primary) • Cache: WARM Data Y
• Cache: COLD • Persistence Data (replicated) Replication (Persistence only) X Challenge 3: Cold Caches Region B Data X • Cache: COLD Data Y (Primary) • Cache: WARM NO Valkey cross-region replication -
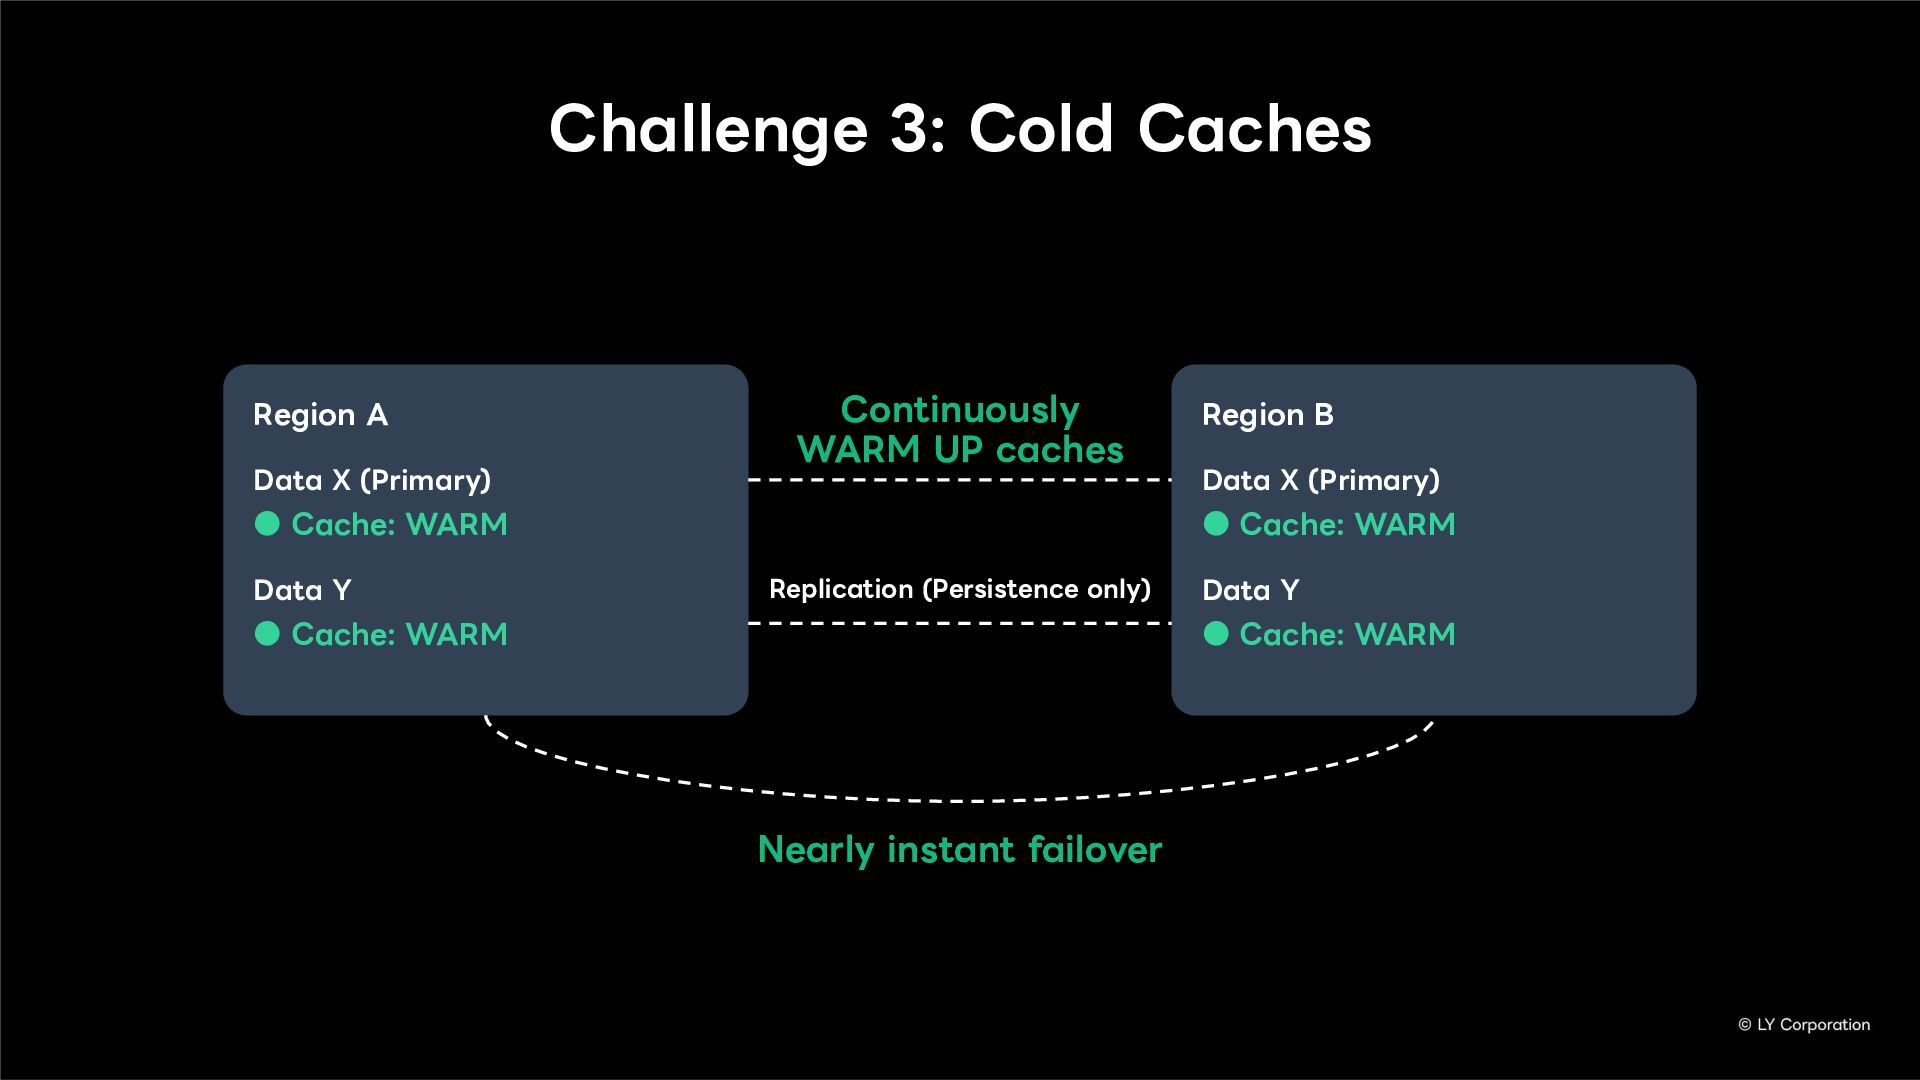
Region A Data X (Primary) • Cache: WARM Data Y
• Cache: WARM Region B Data X (Primary) • Cache: WARM Data Y • Cache: WARM Replication (Persistence only) Challenge 3: Cold Caches Continuously WARM UP caches Nearly instant failover -
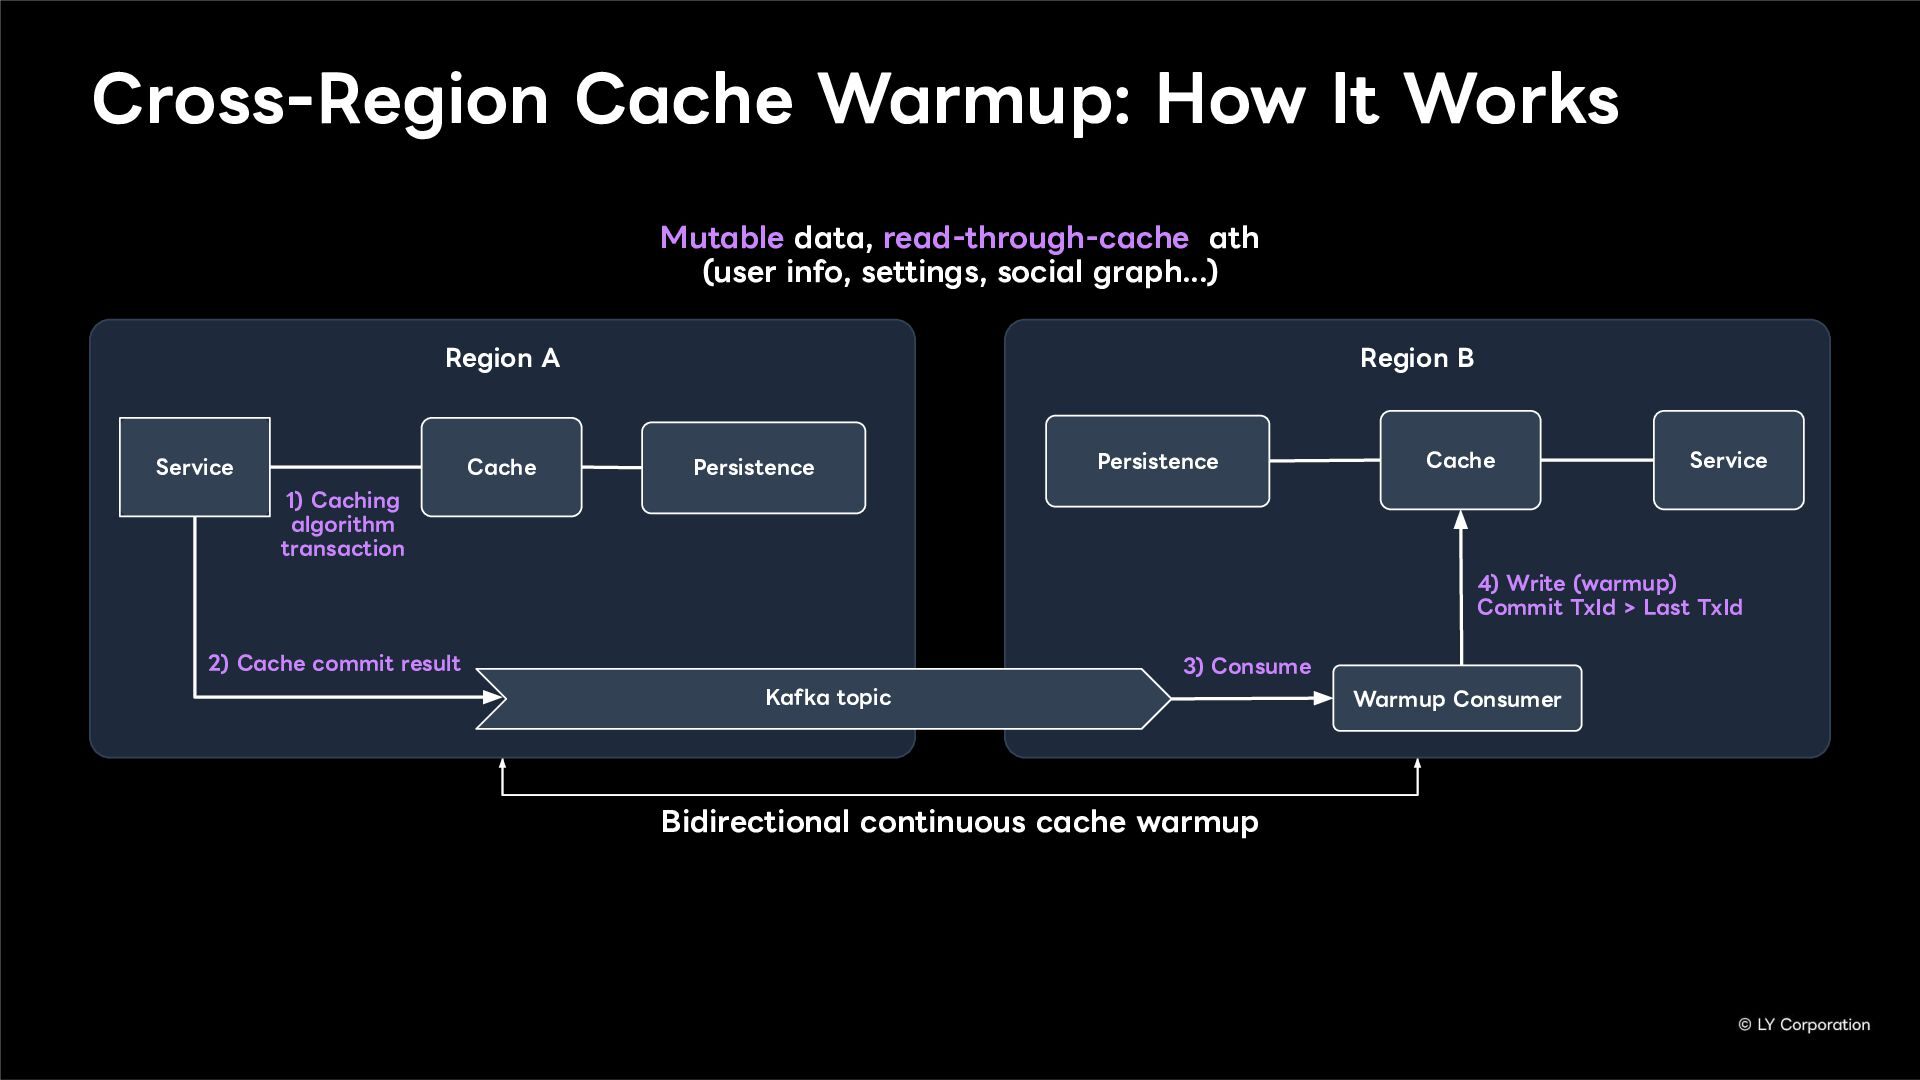
Cross-Region Cache Warmup: How It Works Bidirectional continuous cache warmup
Region A Region B Service Warmup Consumer Cache 1) Caching algorithm transaction 2) Cache commit result 3) Consume Persistence Cache Service 4) Write (warmup) Commit TxId > Last TxId Persistence Kafka topic Mutable data, read-through-cache ath (user info, settings, social graph...) -
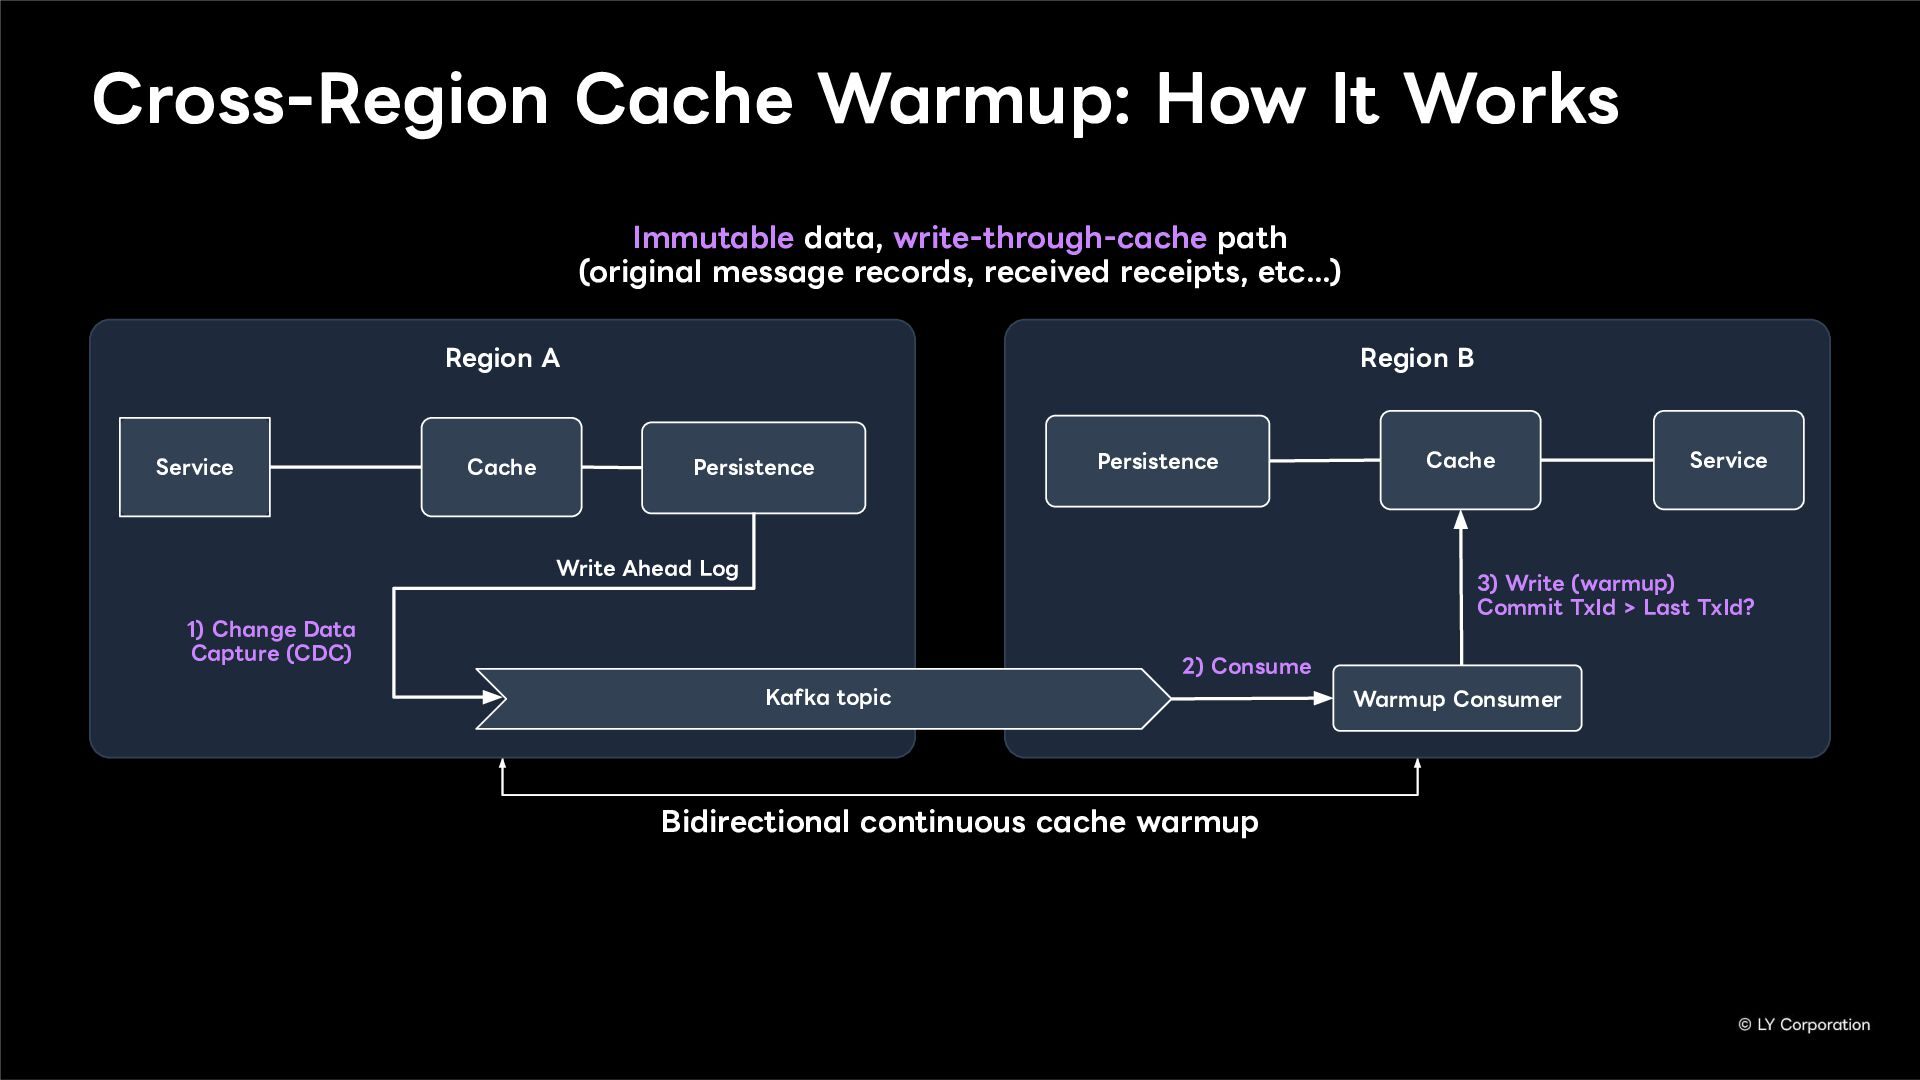
Cross-Region Cache Warmup: How It Works Bidirectional continuous cache warmup
Region A Region B Service Warmup Consumer Cache 2) Consume Persistence Cache Service 3) Write (warmup) Commit TxId > Last TxId? Persistence Kafka topic 1) Change Data Capture (CDC) Write Ahead Log Immutable data, write-through-cache path (original message records, received receipts, etc...) -
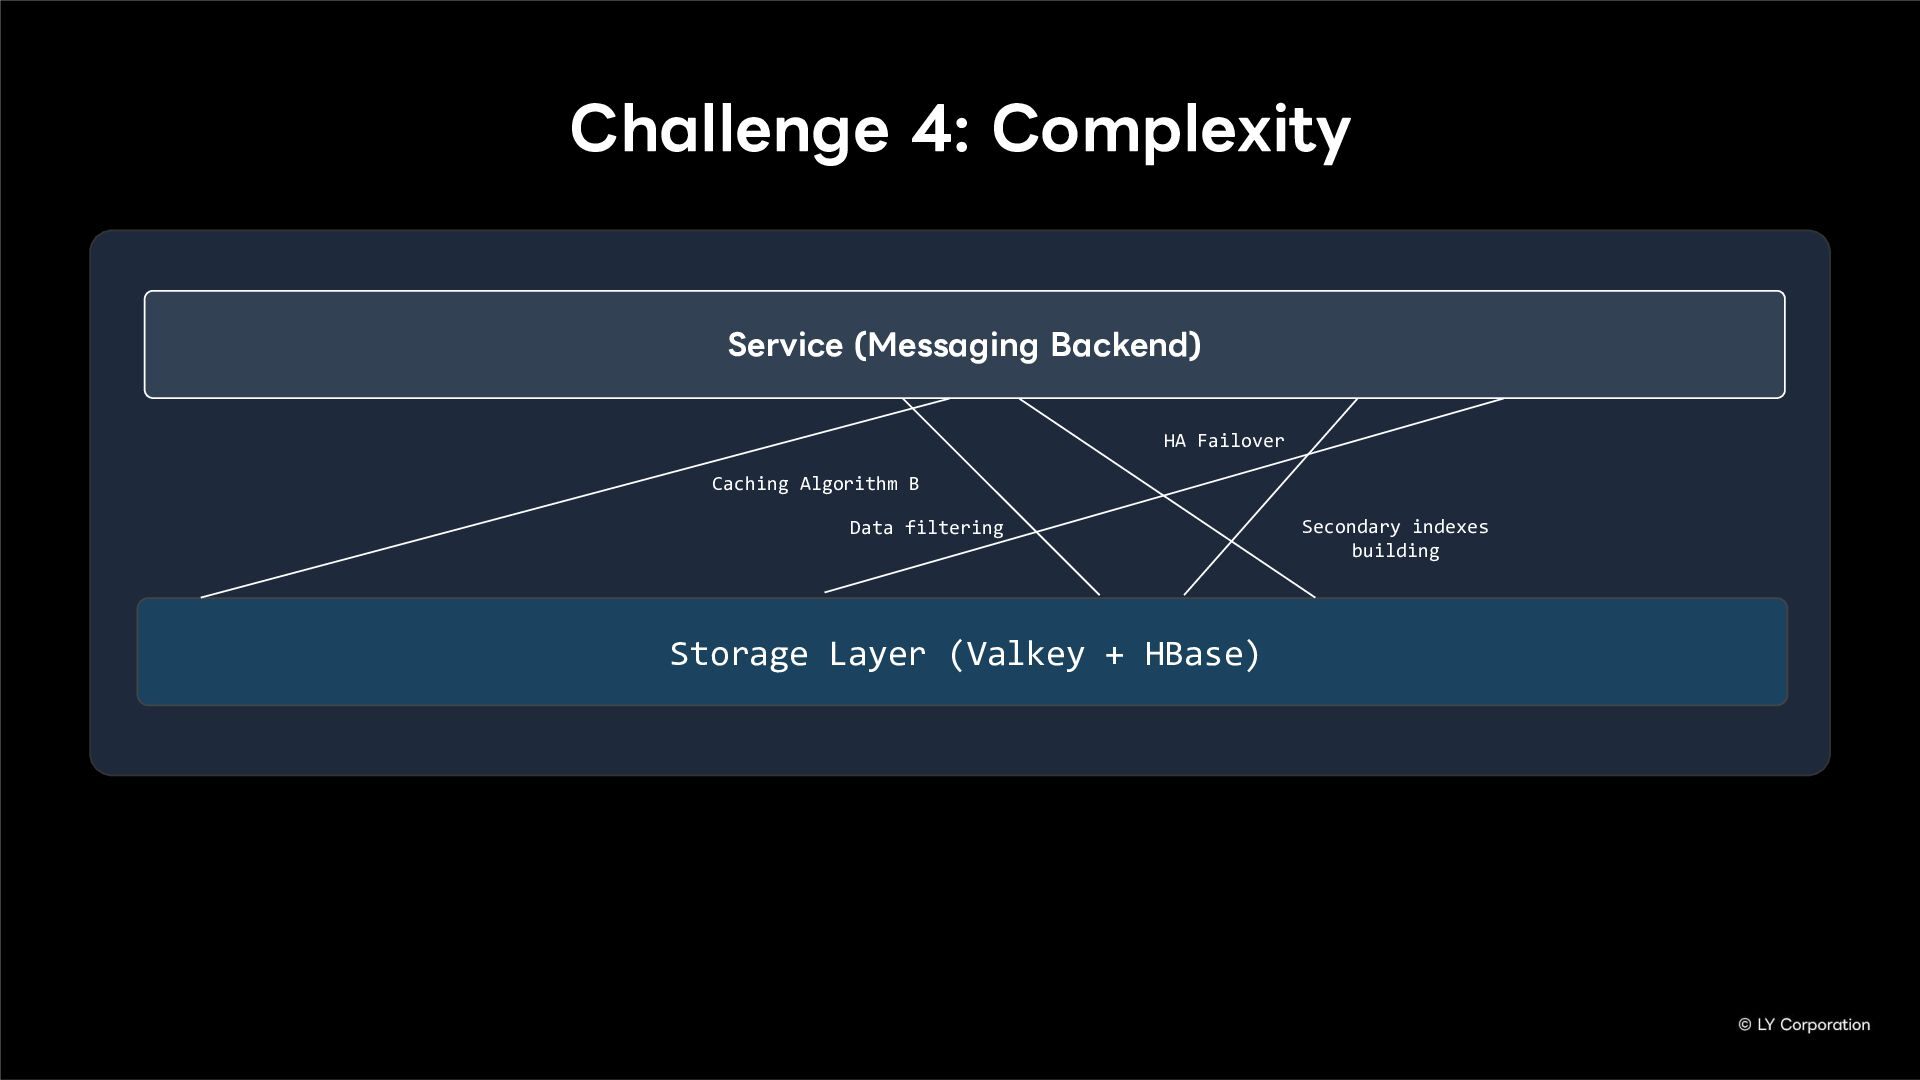
Caching Algorithm A Distributed locks Storage Layer (Valkey + HBase)
Service (Messaging Backend) HA Failover Caching Algorithm B Data filtering Secondary indexes building Challenge 4: Complexity -
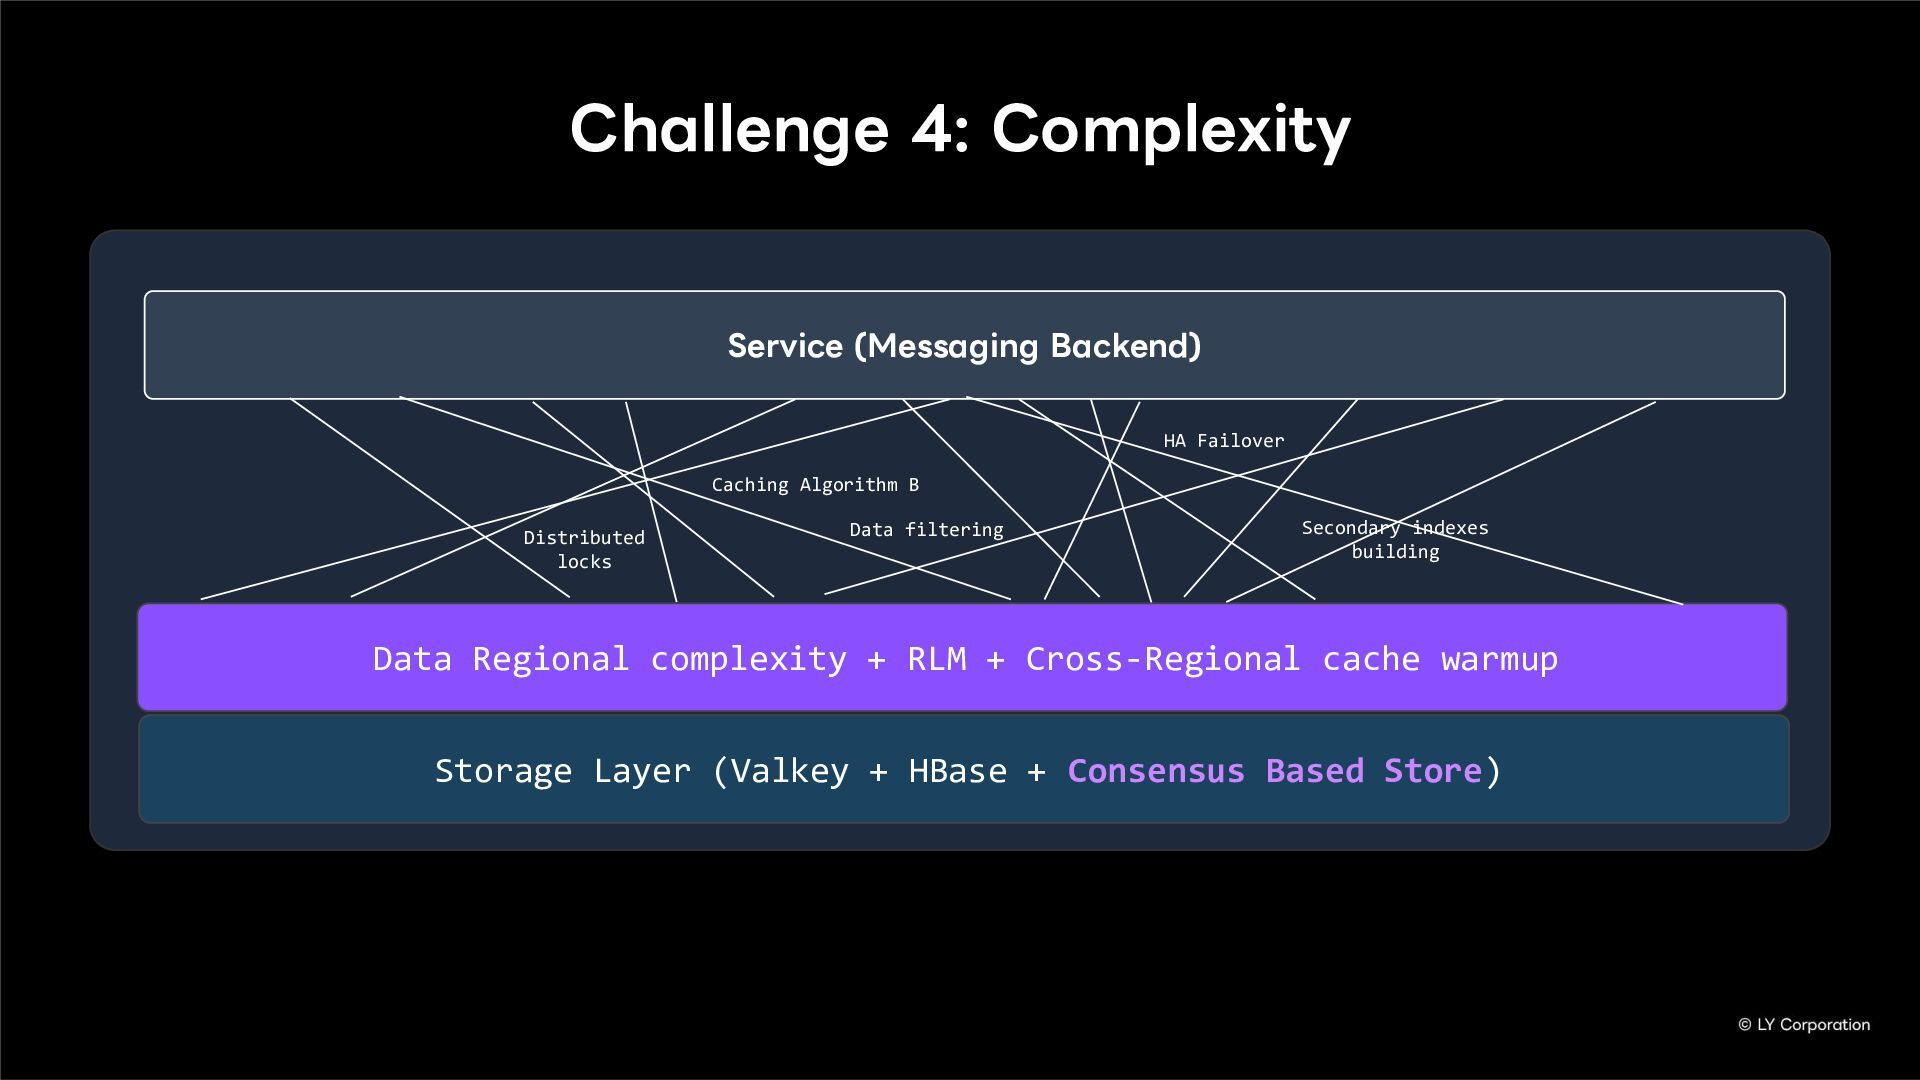
Caching Algorithm A Storage Layer (Valkey + HBase + Consensus
Based Store) Service (Messaging Backend) Distributed locks Data filtering Secondary indexes building Data Regional complexity + RLM + Cross-Regional cache warmup Caching Algorithm B HA Failover Challenge 4: Complexity -
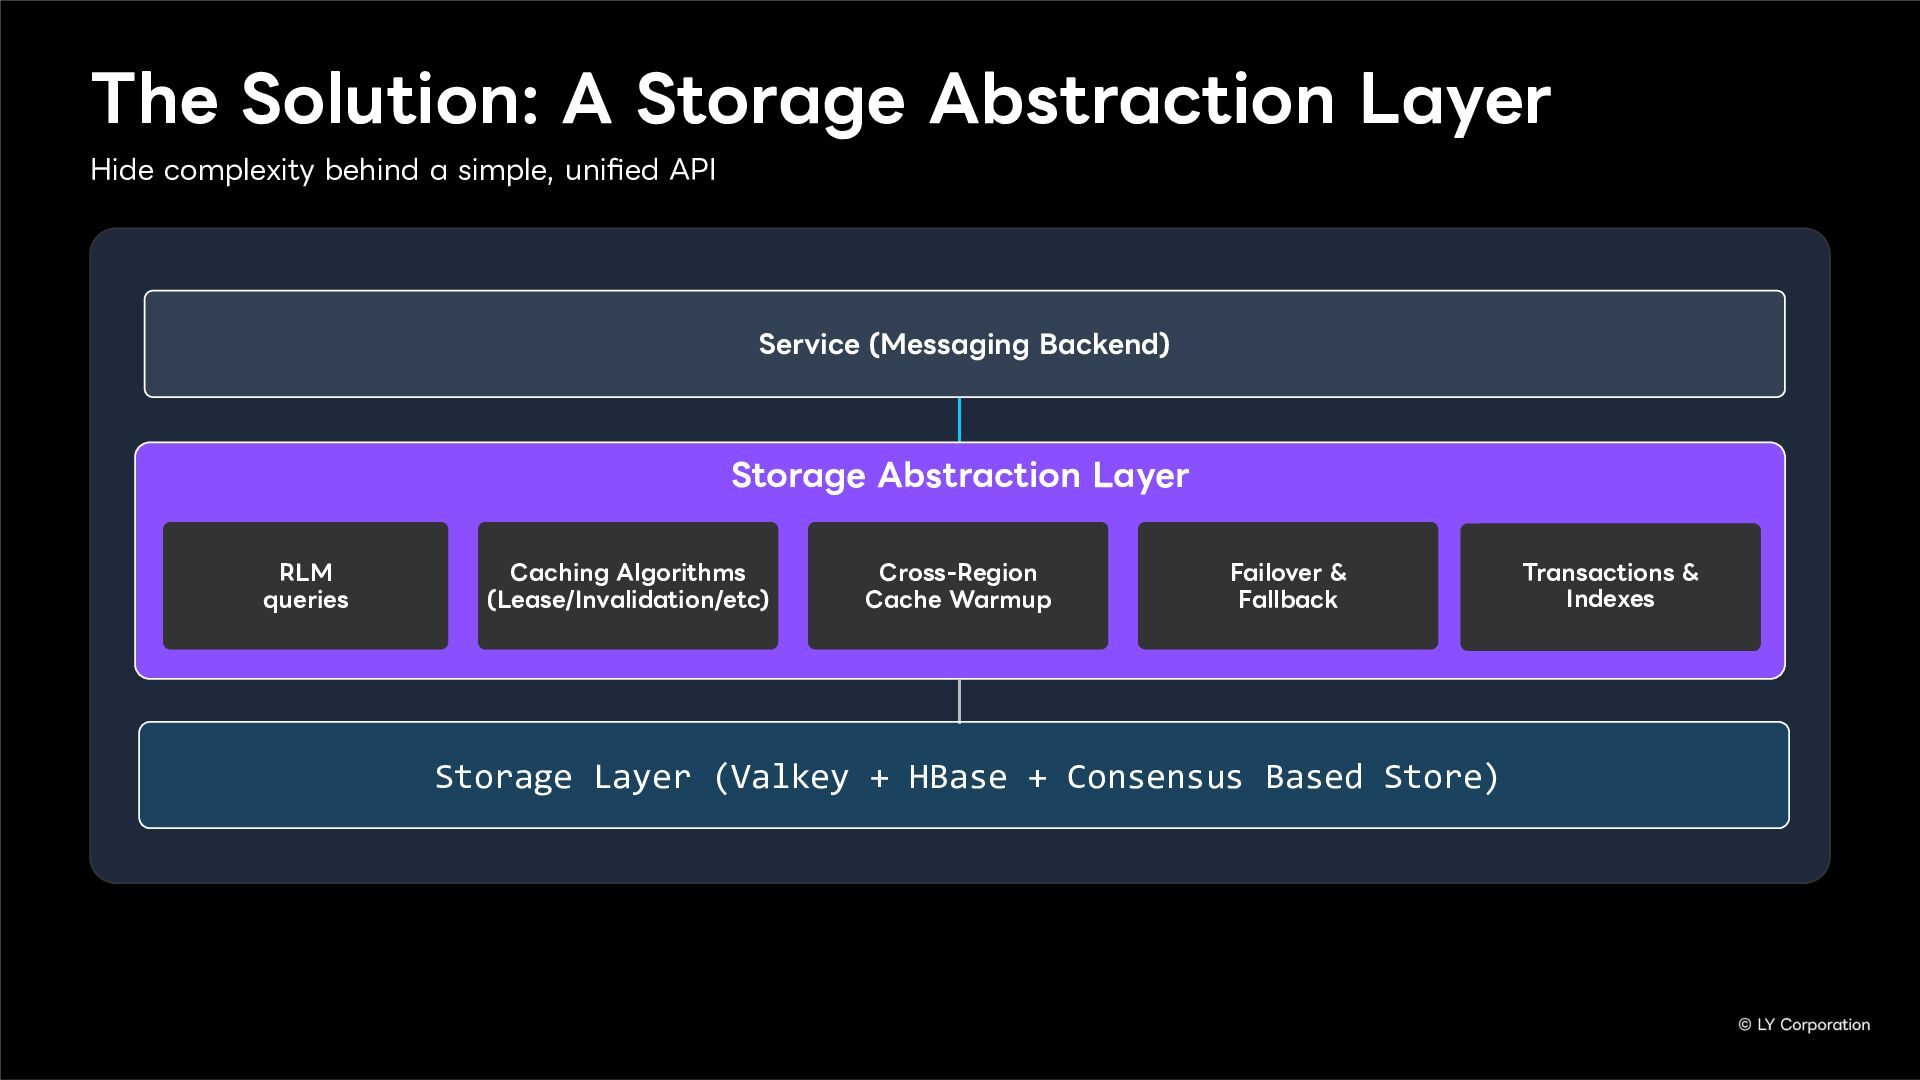
The Solution: A Storage Abstraction Layer Hide complexity behind a
simple, unified API Transactions, Locks & Indexes Region Routing (RLM) Storage Abstraction Layer Caching Algorithms (Lease/Invalidation/etc) Cross-Region Cache Warmup Failover & Fallback Storage Layer (Valkey + HBase + Consensus Based Store) Service (Messaging Backend) RLM queries Region Routing (RLM) Transactions & Indexes -
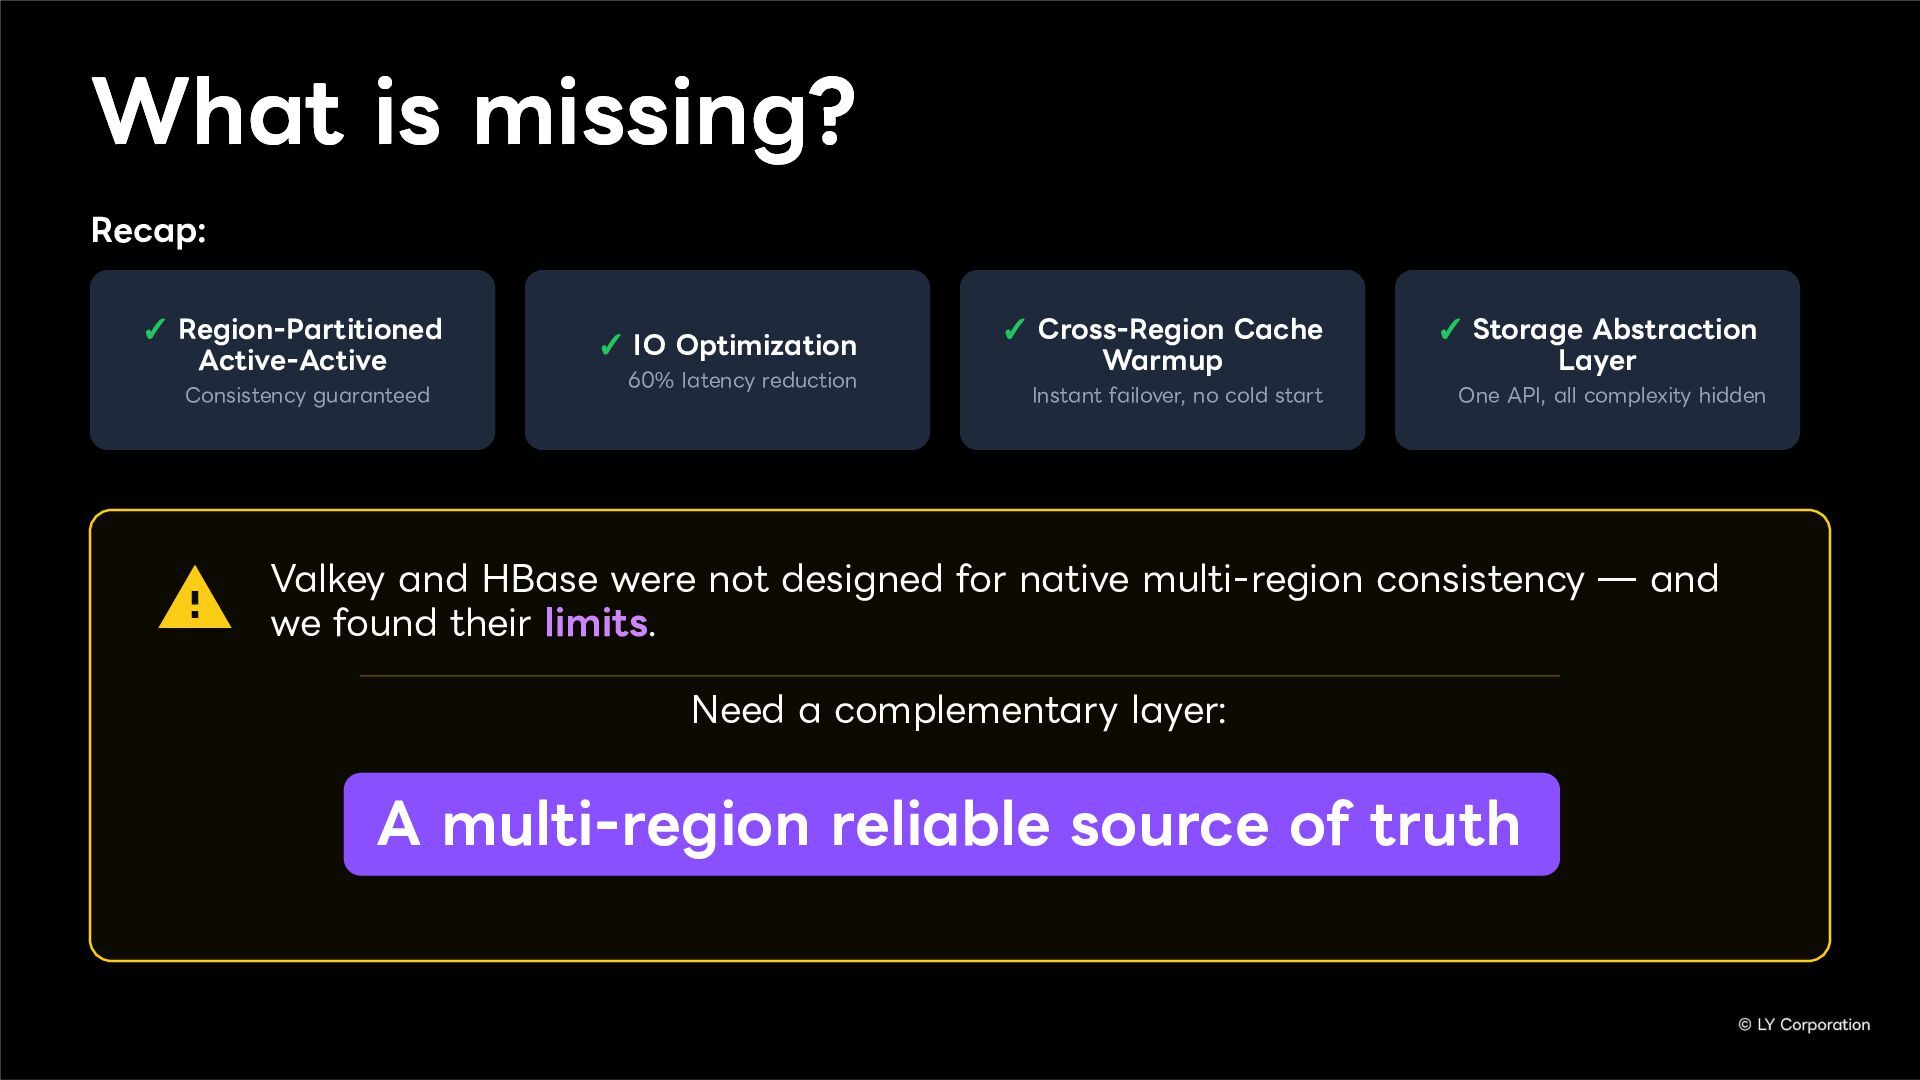
What is missing? What is missing? Recap: ✓ Region-Partitioned Active-Active
Consistency guaranteed ✓ IO Optimization 60% latency reduction ✓ Cross-Region Cache Warmup Instant failover, no cold start ✓ Storage Abstraction Layer One API, all complexity hidden Valkey and HBase were not designed for native multi-region consistency ̶ and we found their limits. Need a complementary layer: A multi-region reliable source of truth -
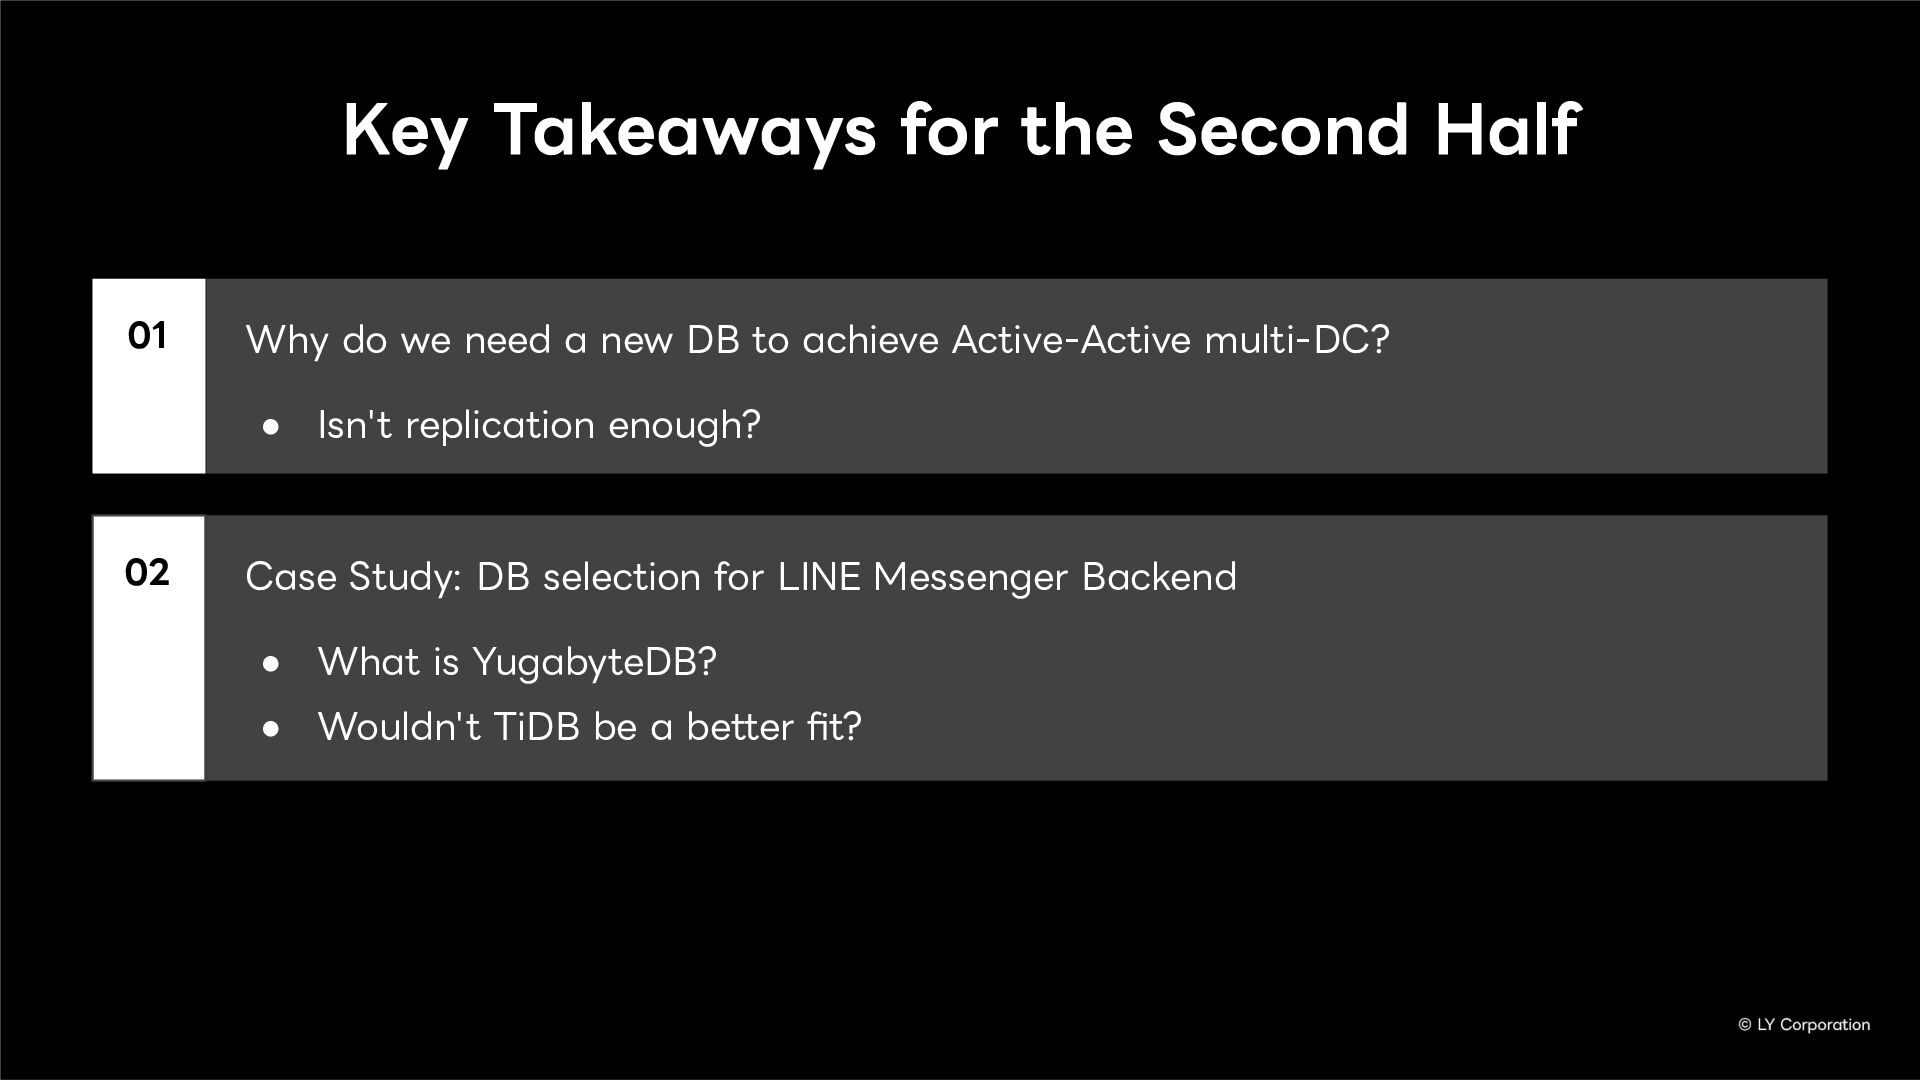
Why do we need a new DB to achieve Active-Active
multi-DC? • Isn't replication enough? Case Study: DB selection for LINE Messenger Backend • What is YugabyteDB? • Wouldn't TiDB be a better fit? 01 02 Key Takeaways for the Second Half -
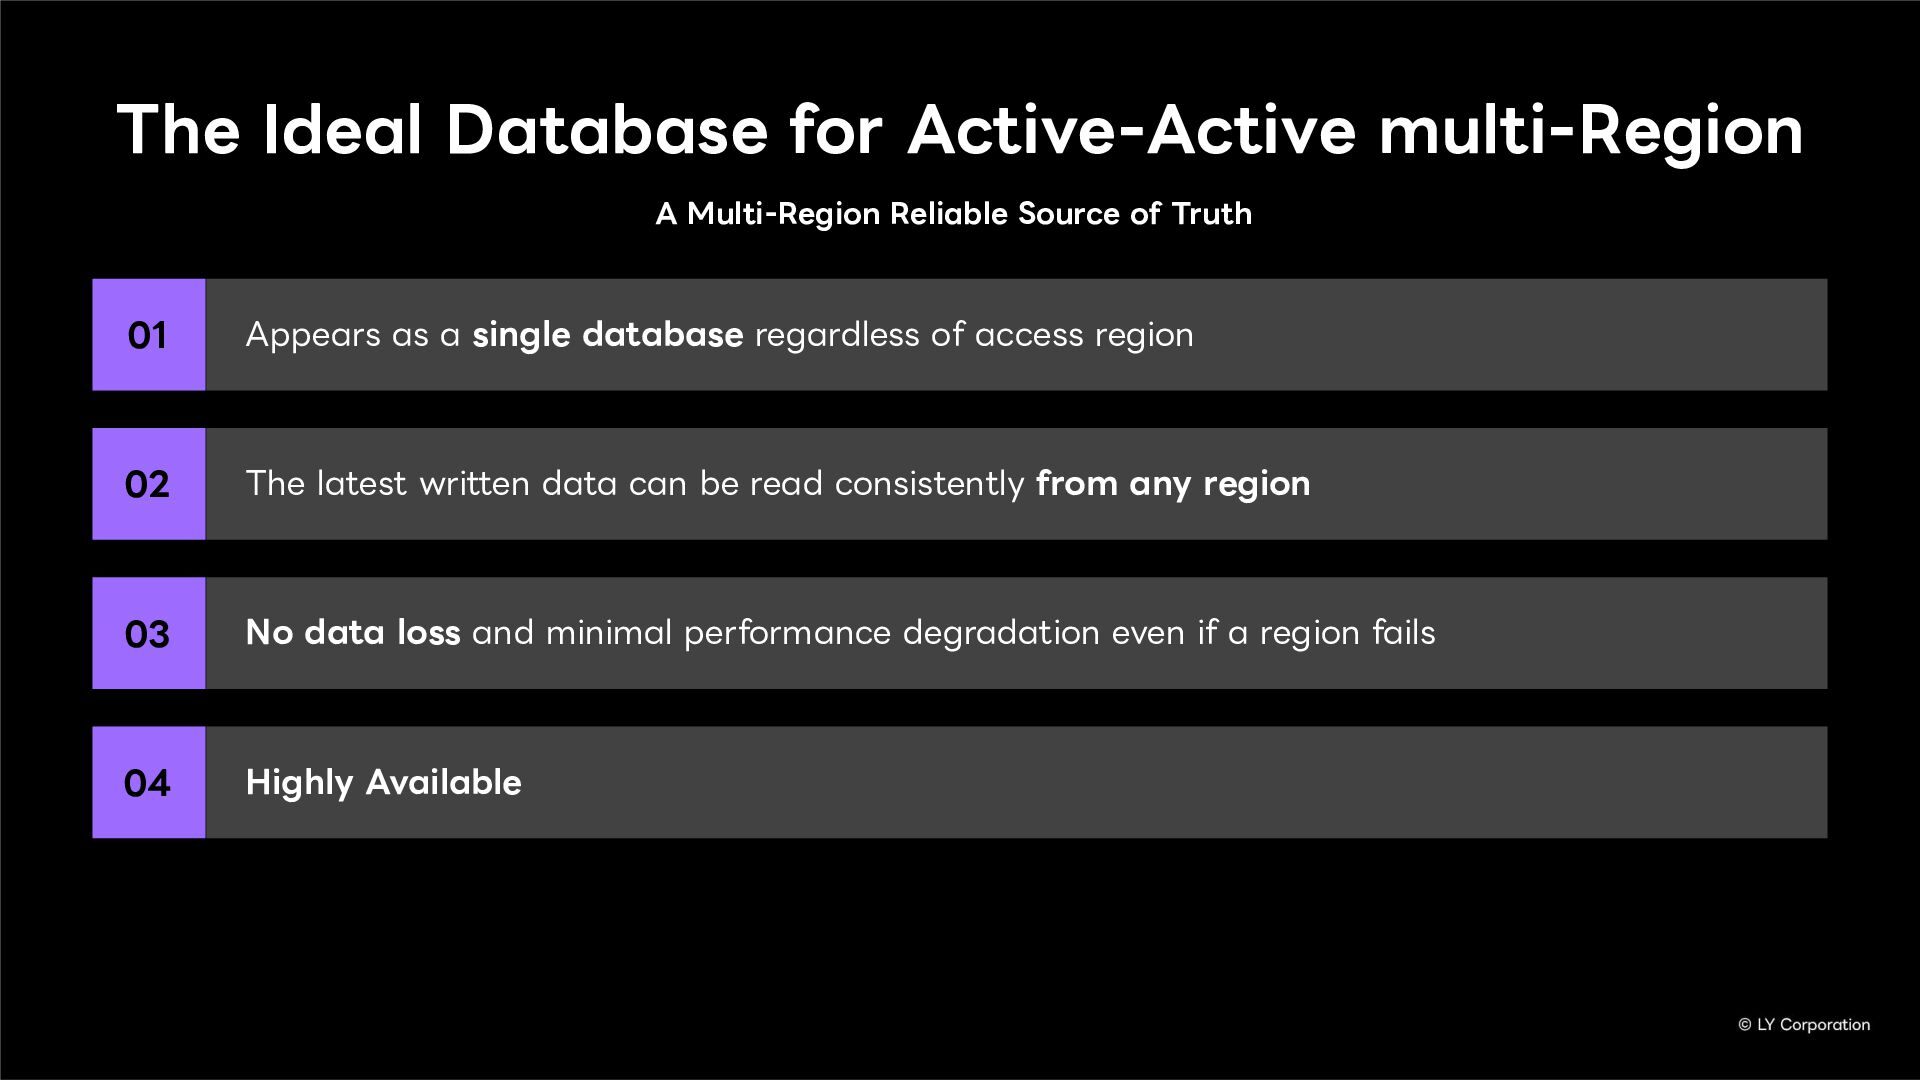
Appears as a single database regardless of access region The
latest written data can be read consistently from any region No data loss and minimal performance degradation even if a region fails Highly Available 01 03 02 04 The Ideal Database for Active-Active multi-Region A Multi-Region Reliable Source of Truth -
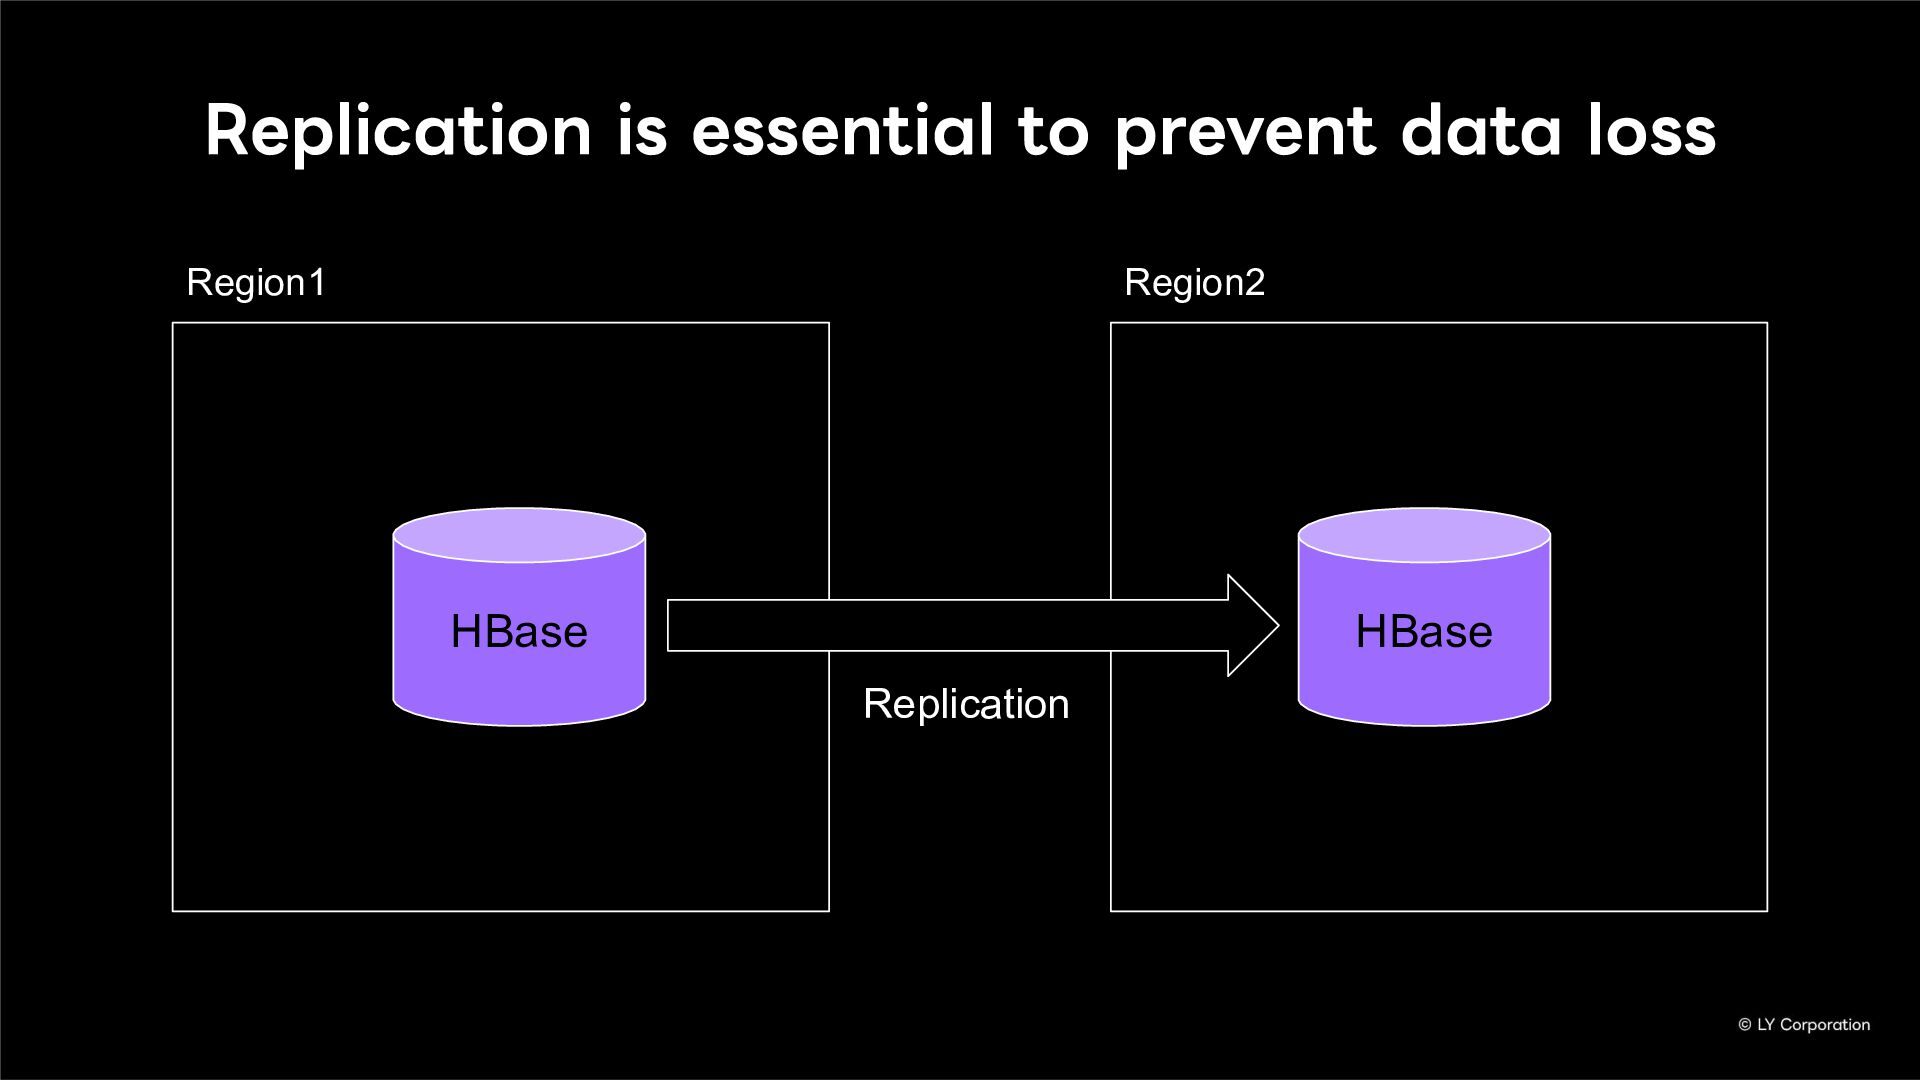
HBase Replication is essential to prevent data loss Region1 Region2
HBase Replication -
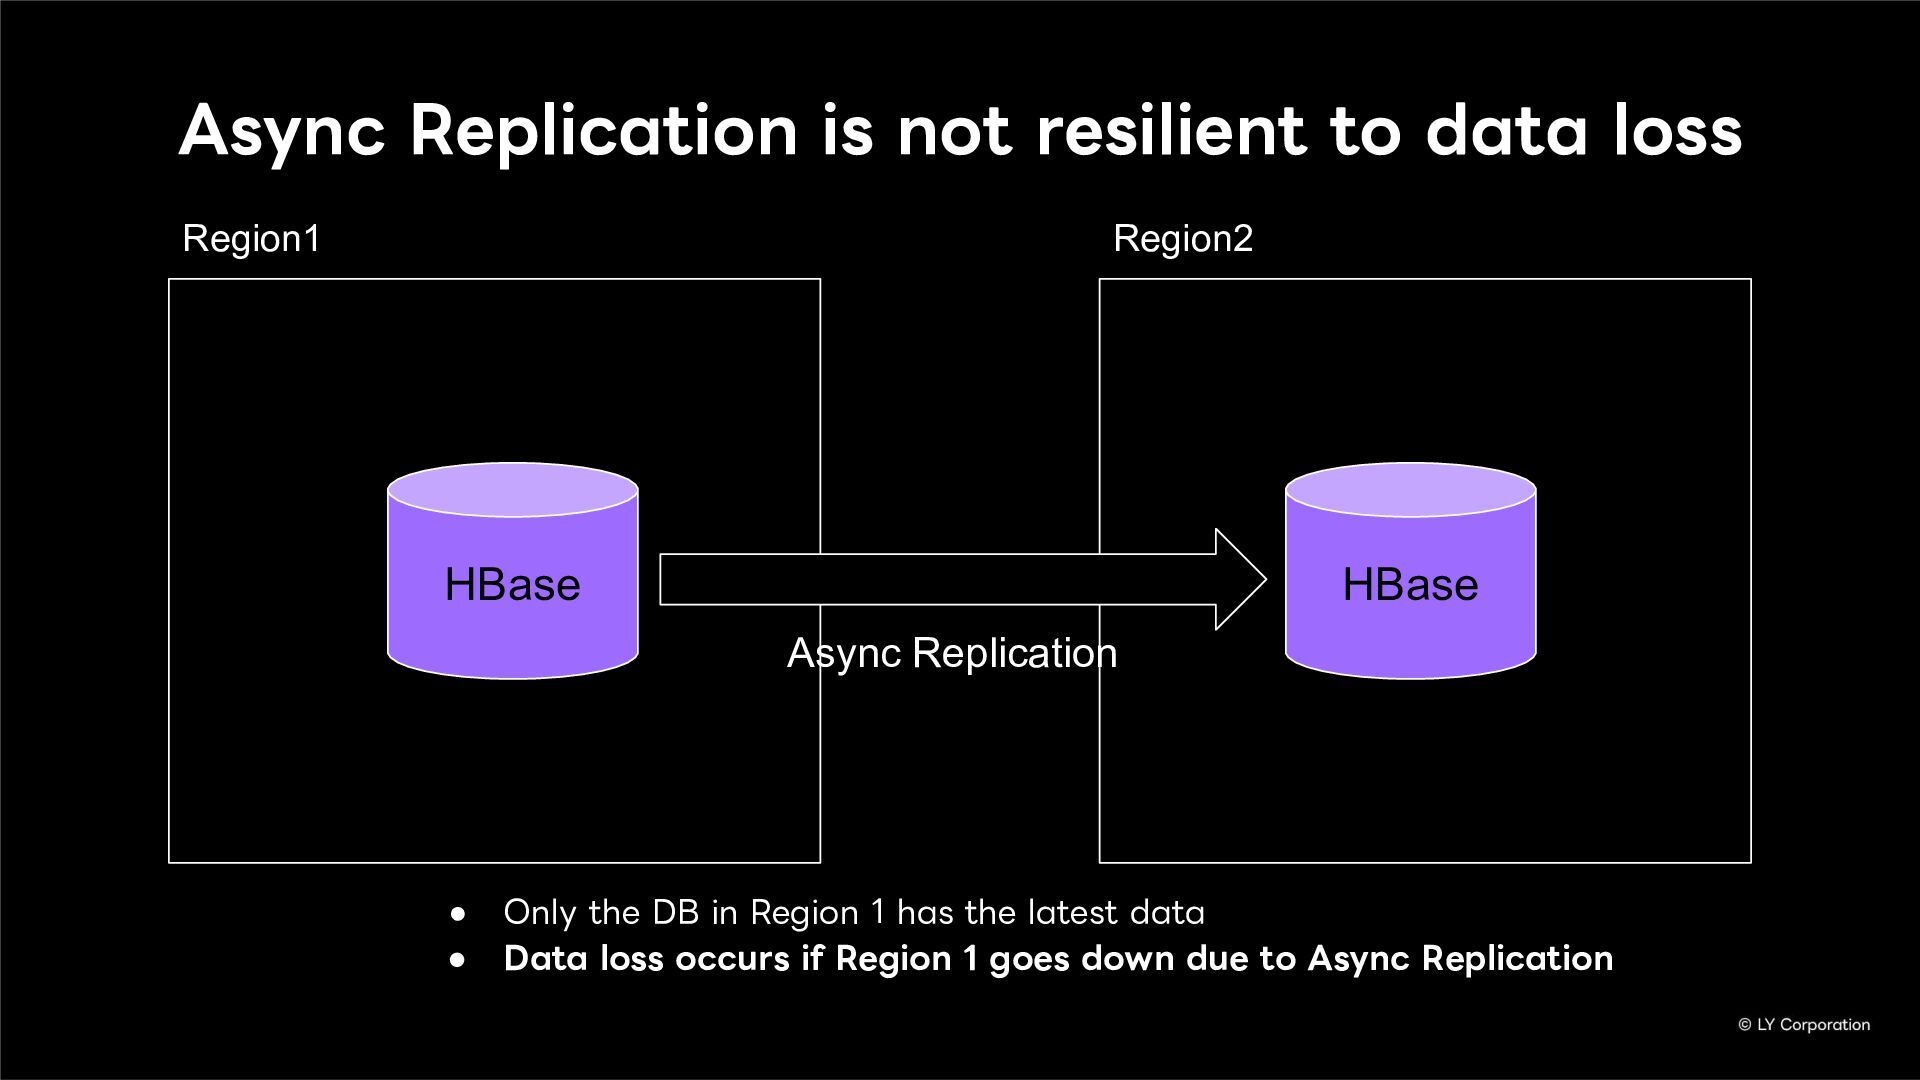
Async Replication is not resilient to data loss HBase Region1
Region2 HBase Async Replication • Only the DB in Region 1 has the latest data • Data loss occurs if Region 1 goes down due to Async Replication -
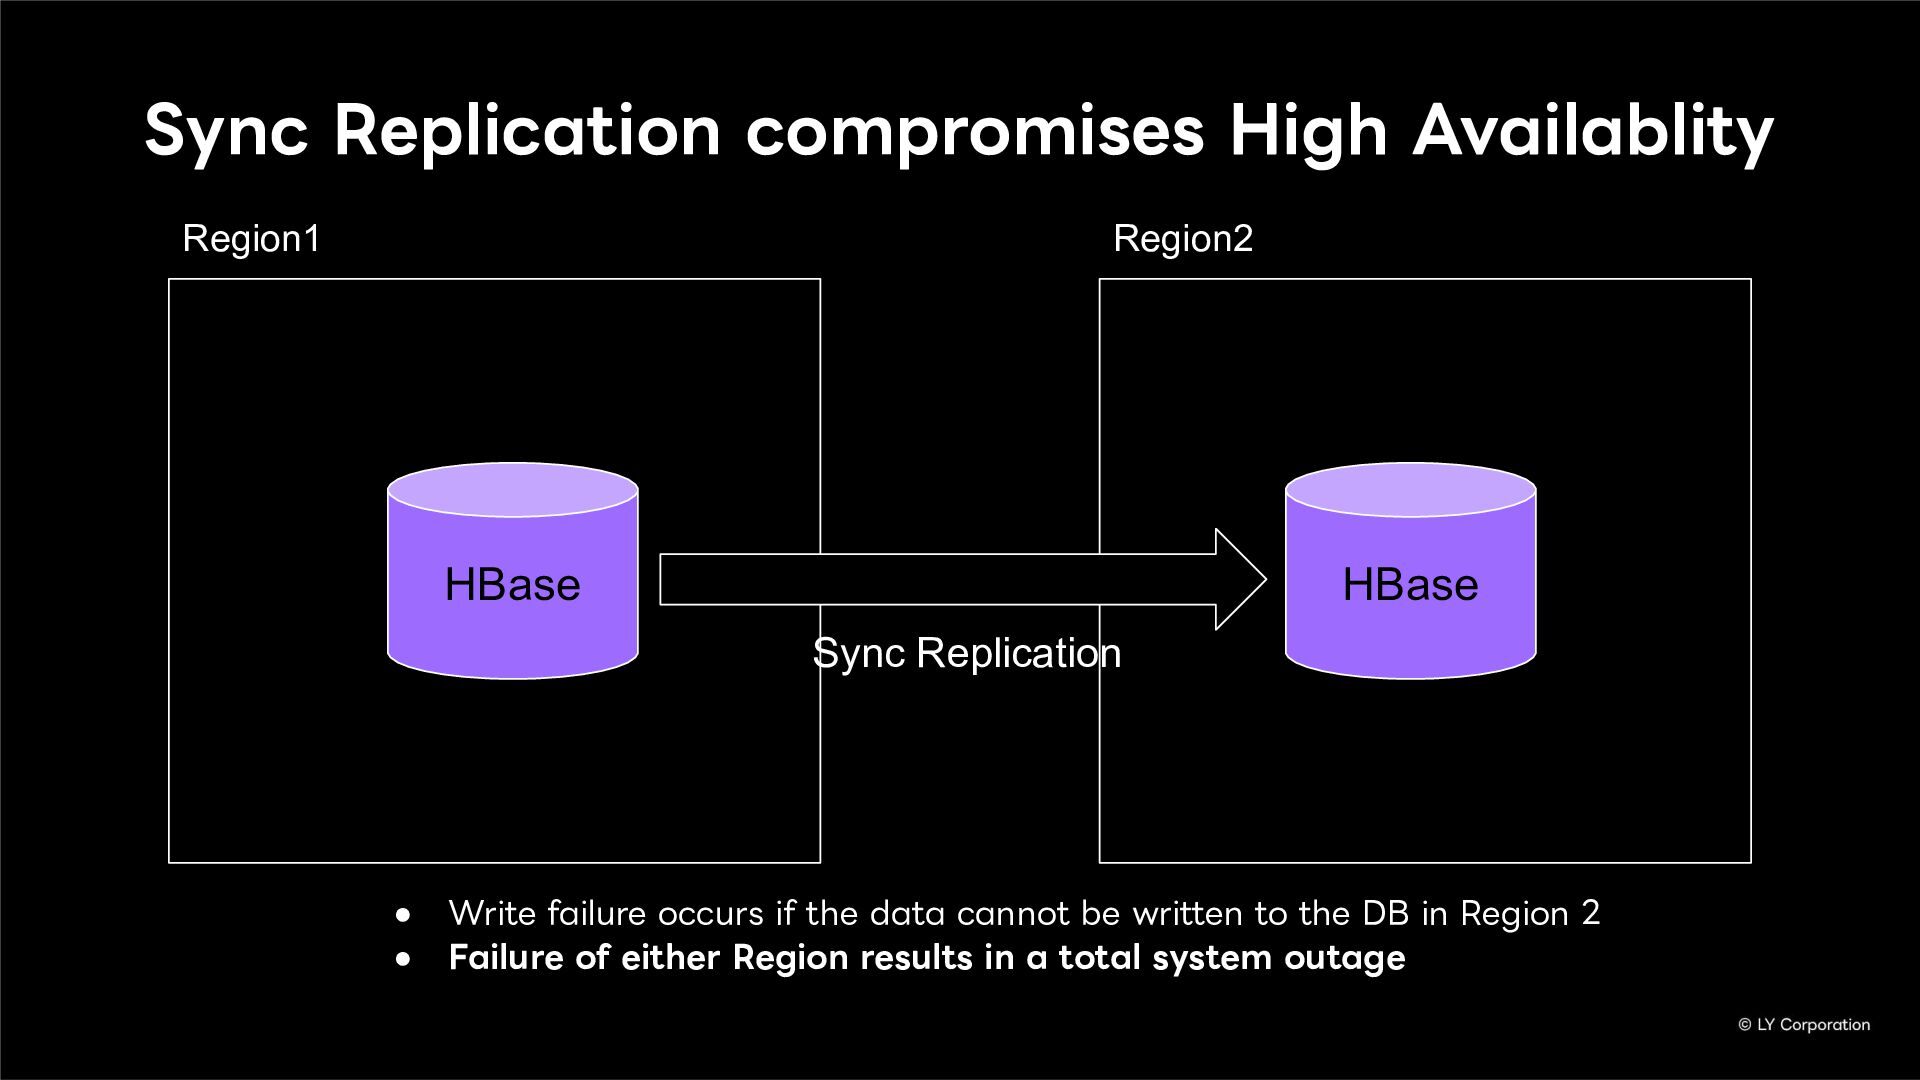
Sync Replication compromises High Availablity HBase Region1 Region2 HBase Sync
Replication • Write failure occurs if the data cannot be written to the DB in Region 2 • Failure of either Region results in a total system outage -
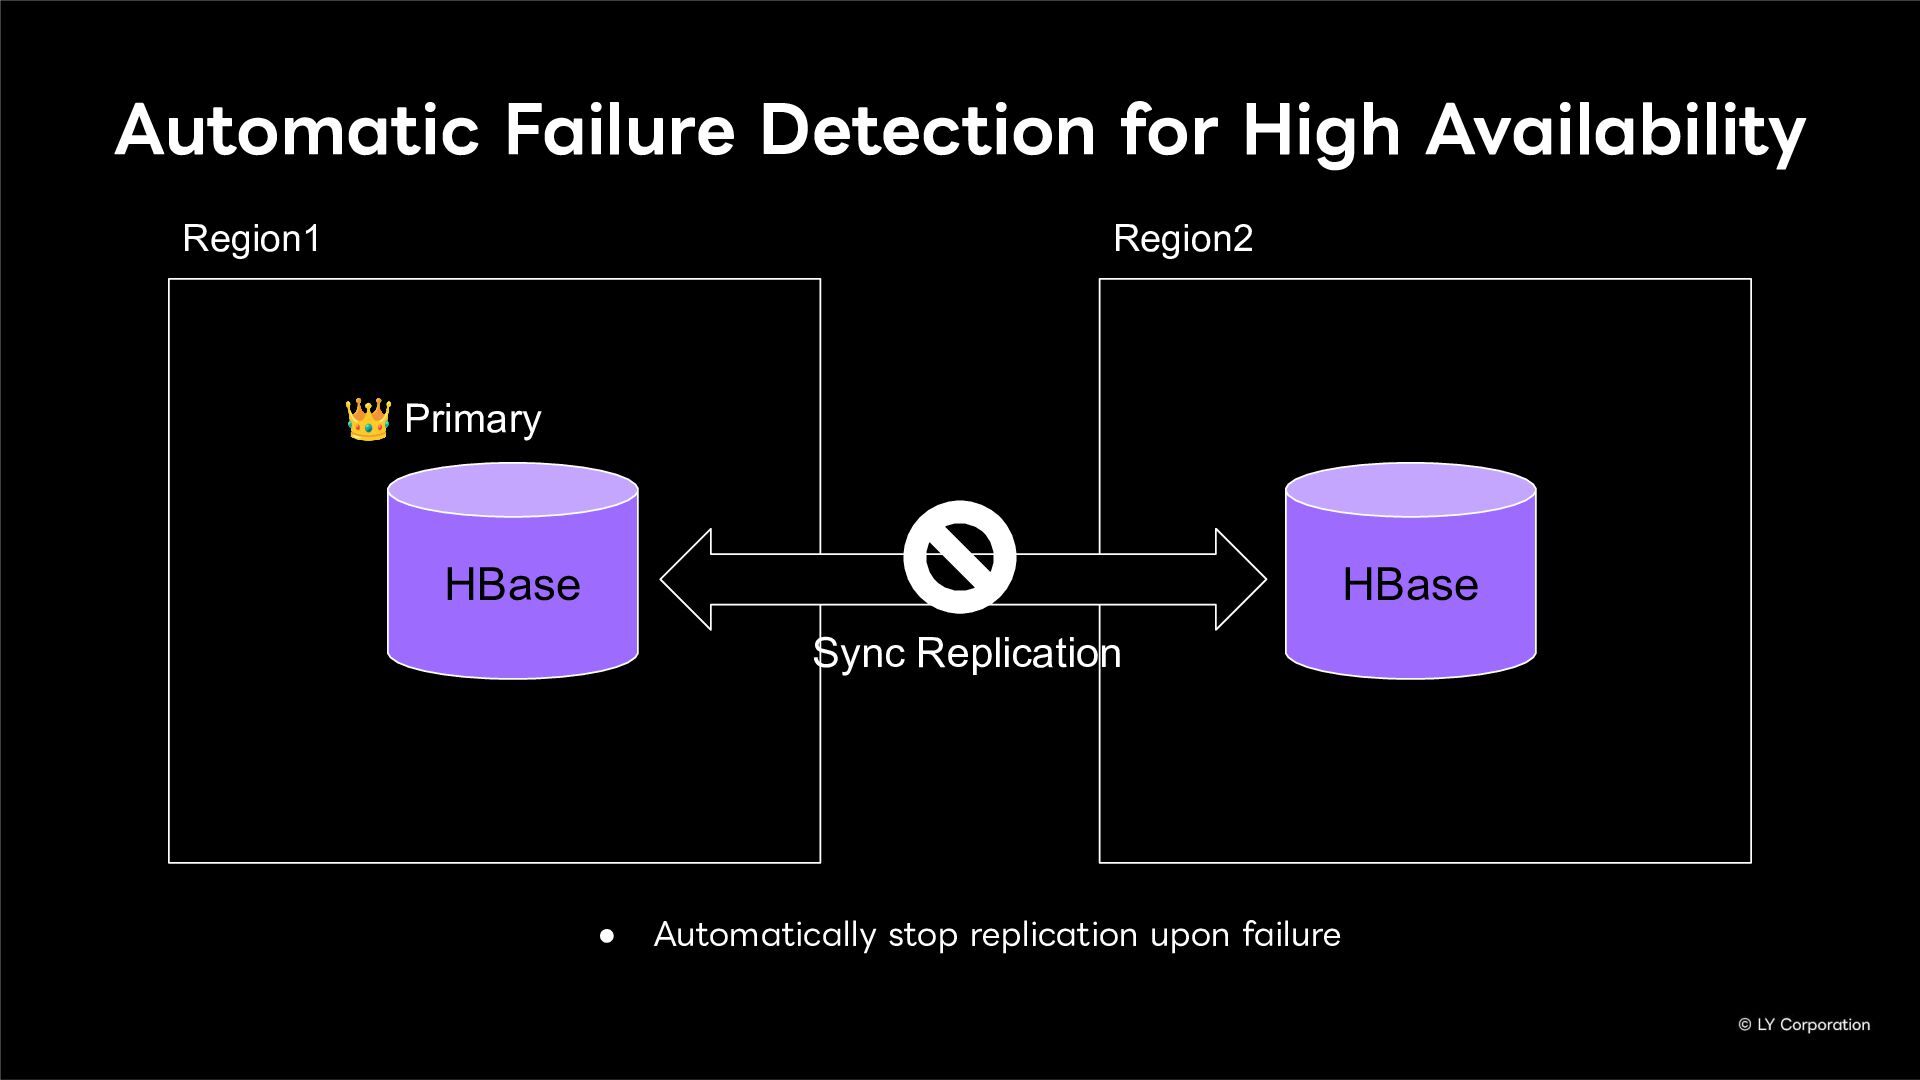
Automatic Failure Detection for High Availability HBase Region1 Region2 HBase
Sync Replication • Automatically stop replication upon failure 👑 Primary -
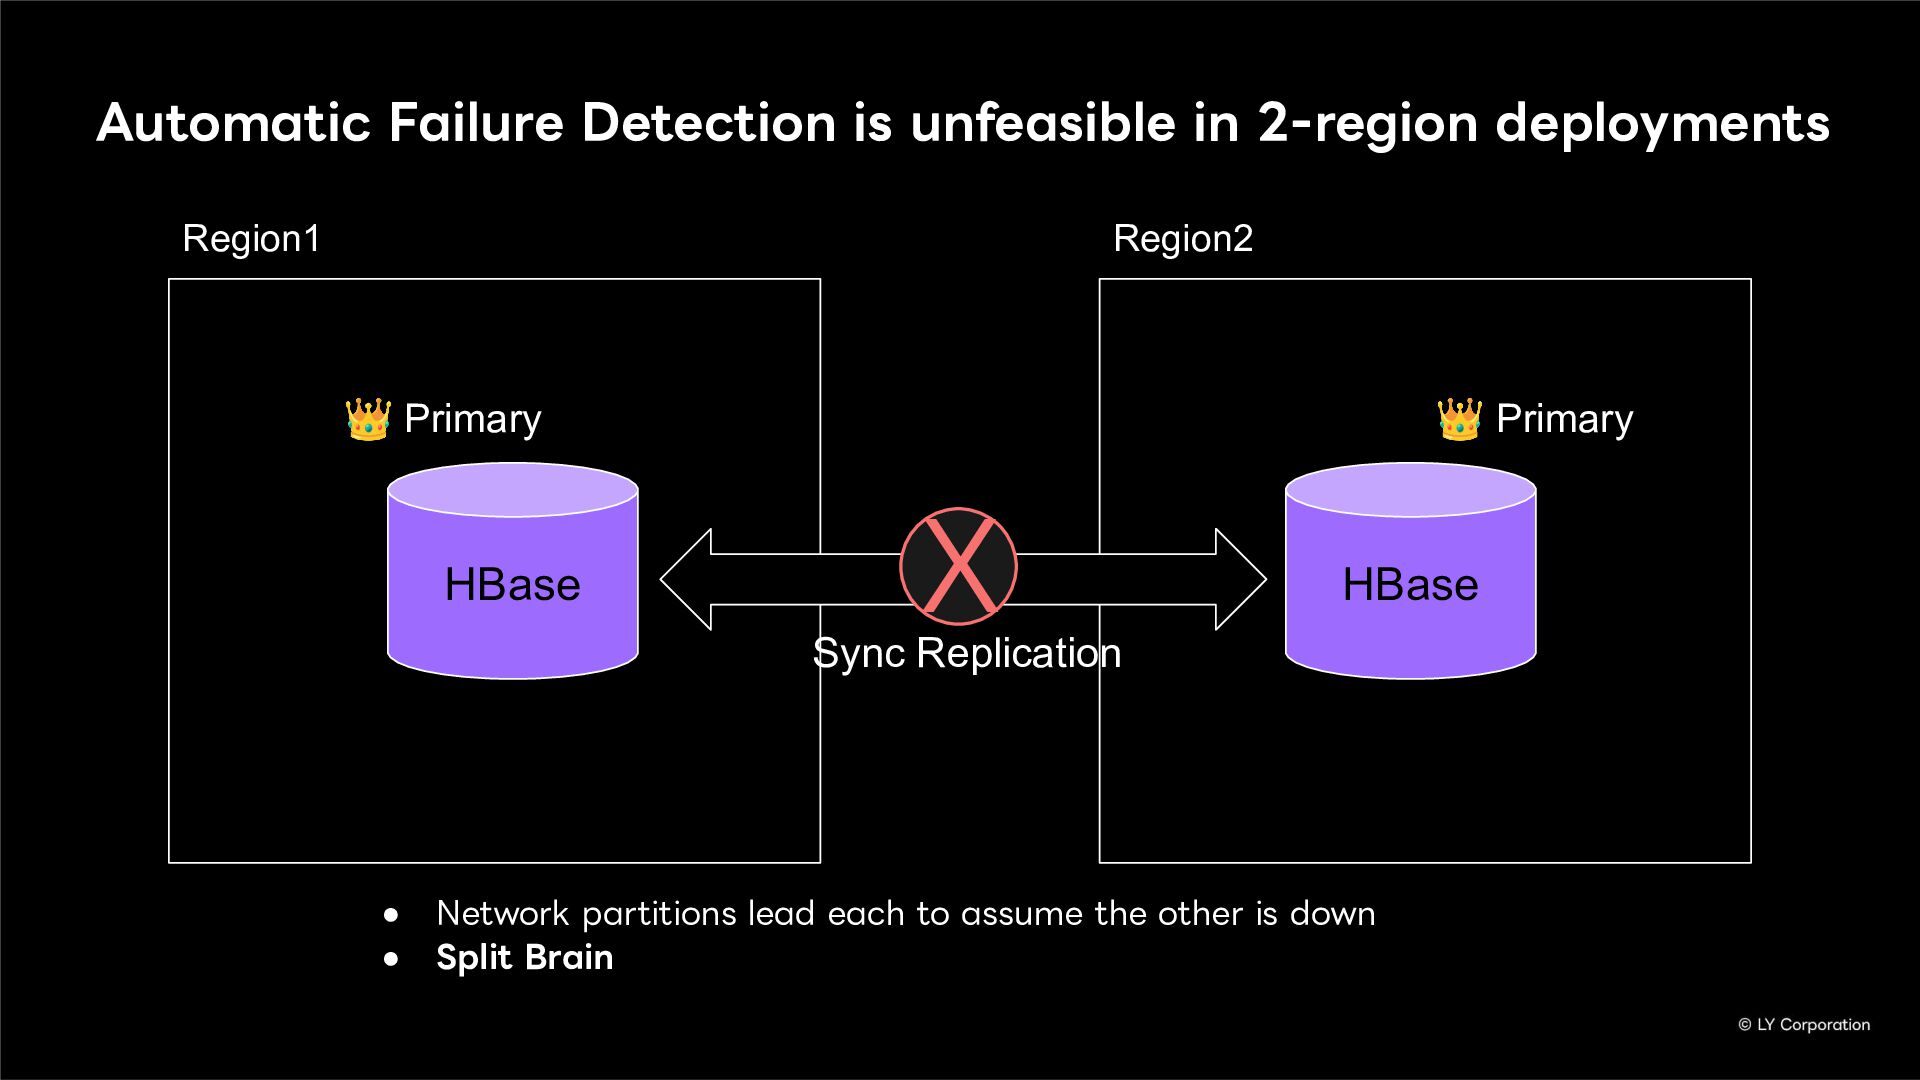
Automatic Failure Detection is unfeasible in 2-region deployments HBase Region1
Region2 HBase Sync Replication • Network partitions lead each to assume the other is down • Split Brain X 👑 Primary 👑 Primary -
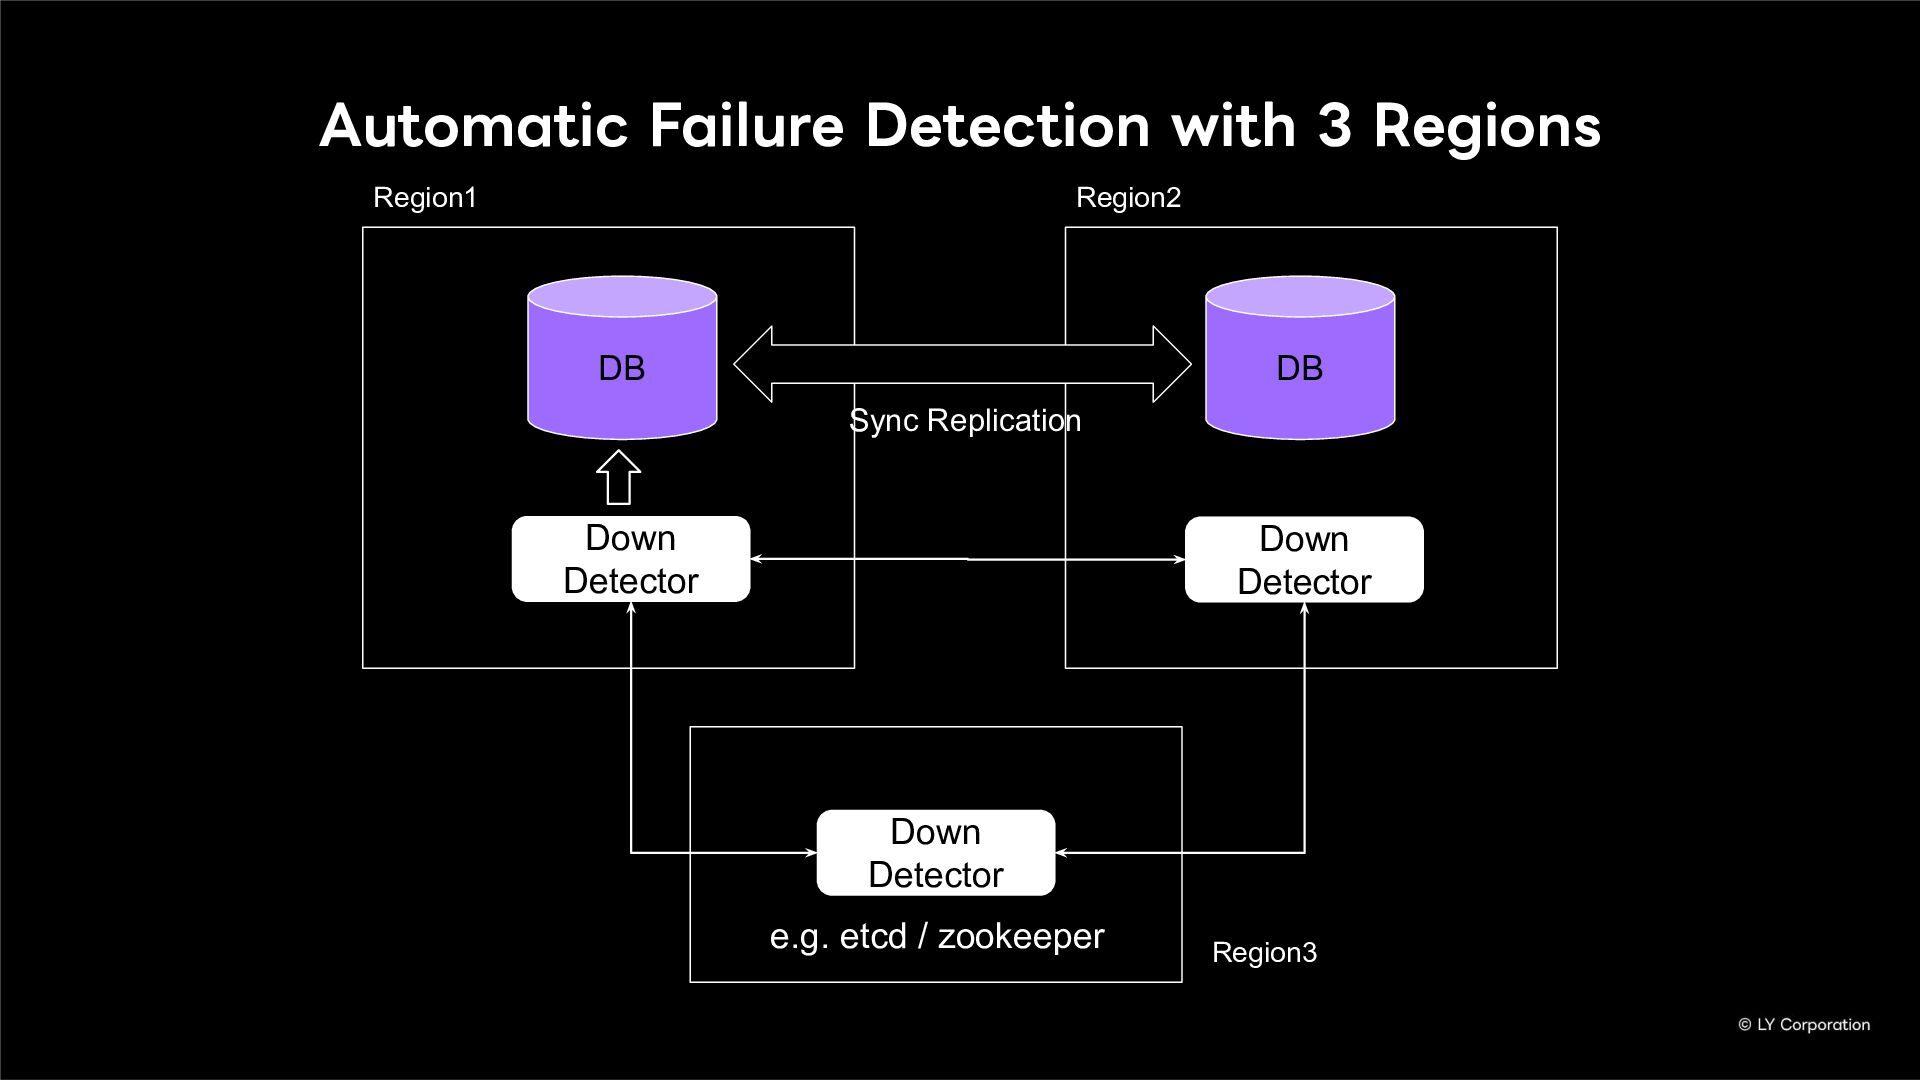
Automatic Failure Detection with 3 Regions DB Region1 Region2 DB
Sync Replication Region3 Down Detector Down Detector Down Detector e.g. etcd / zookeeper -
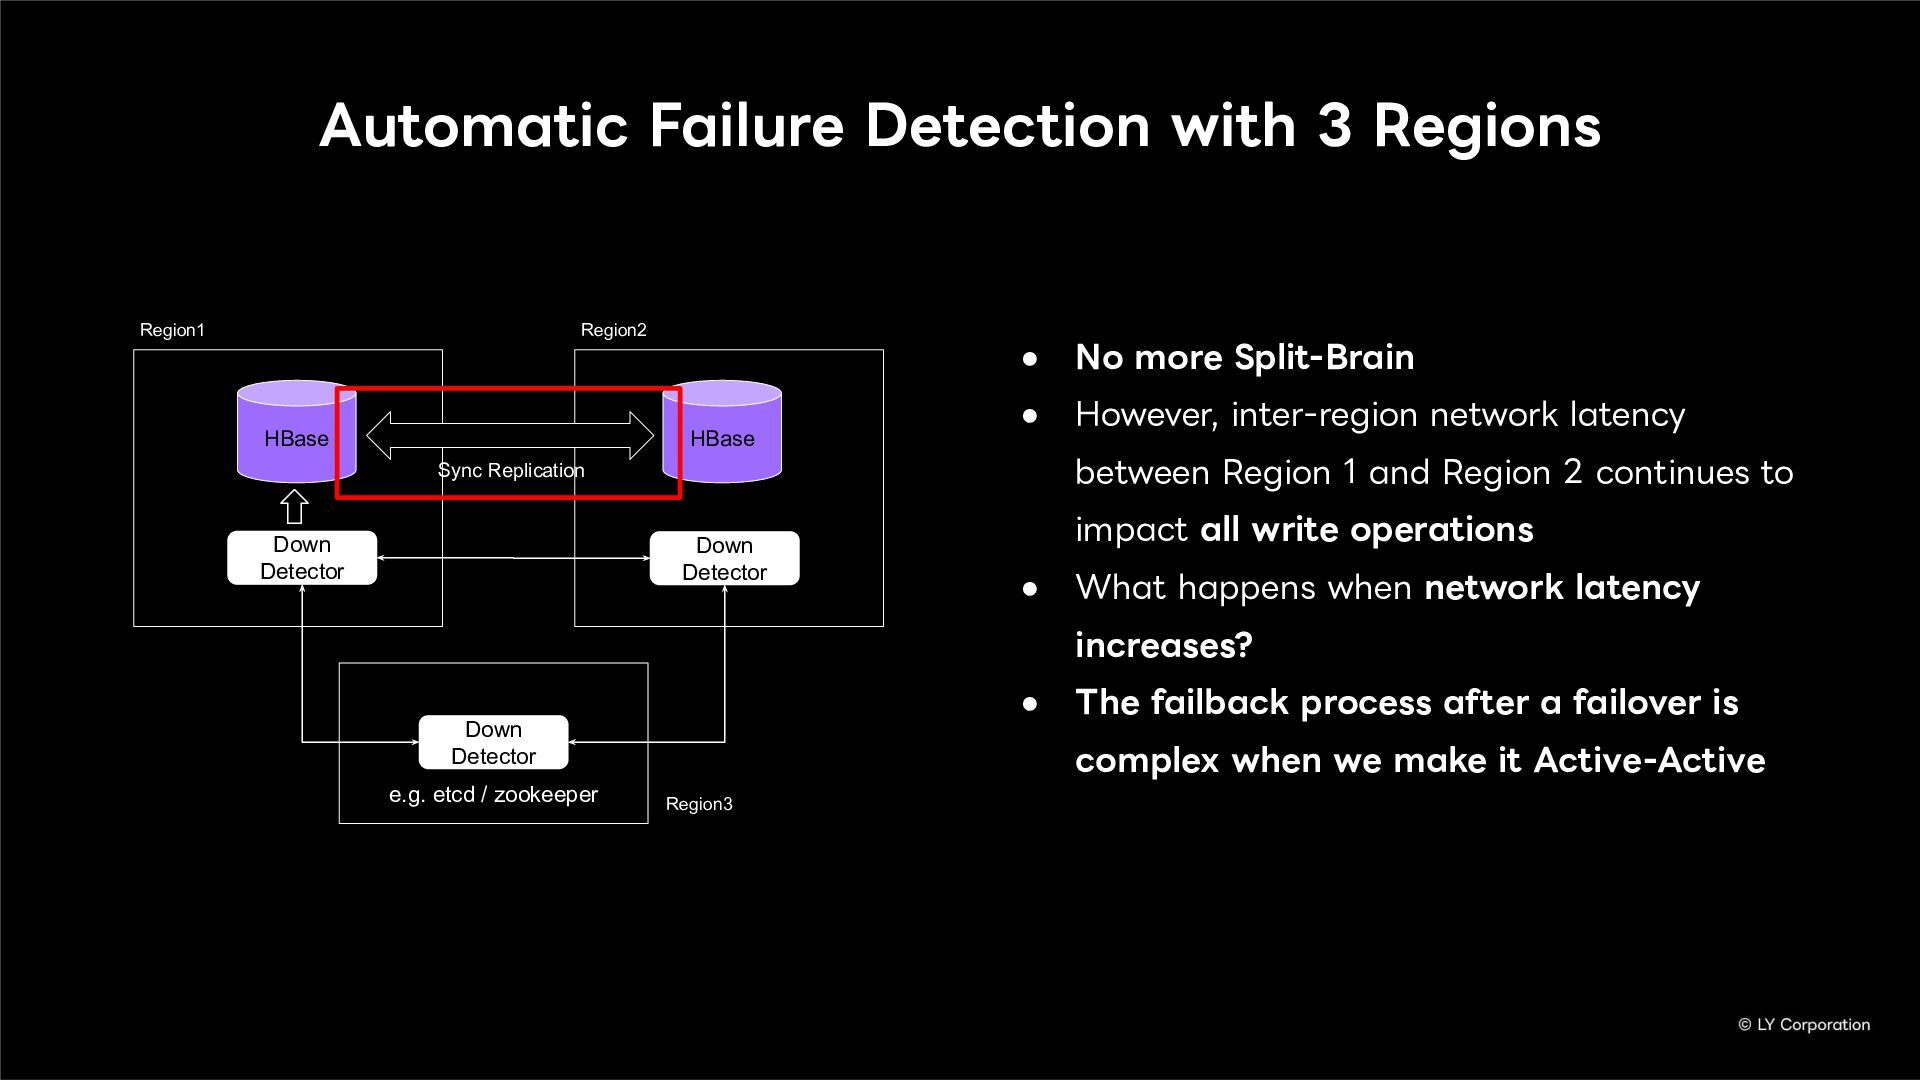
Automatic Failure Detection with 3 Regions HBase Region1 Region2 HBase
Sync Replication • No more Split-Brain • However, inter-region network latency between Region 1 and Region 2 continues to impact all write operations • What happens when network latency increases? • The failback process after a failover is complex when we make it Active-Active Region3 Down Detector Down Detector Down Detector e.g. etcd / zookeeper -
A: Active-Active multi-DC is Hard to achieve with Leader-Follower replication
and we need more sophisticated algorithm Q: Why do we need a new DB to achieve Active-Active multi-DC? -
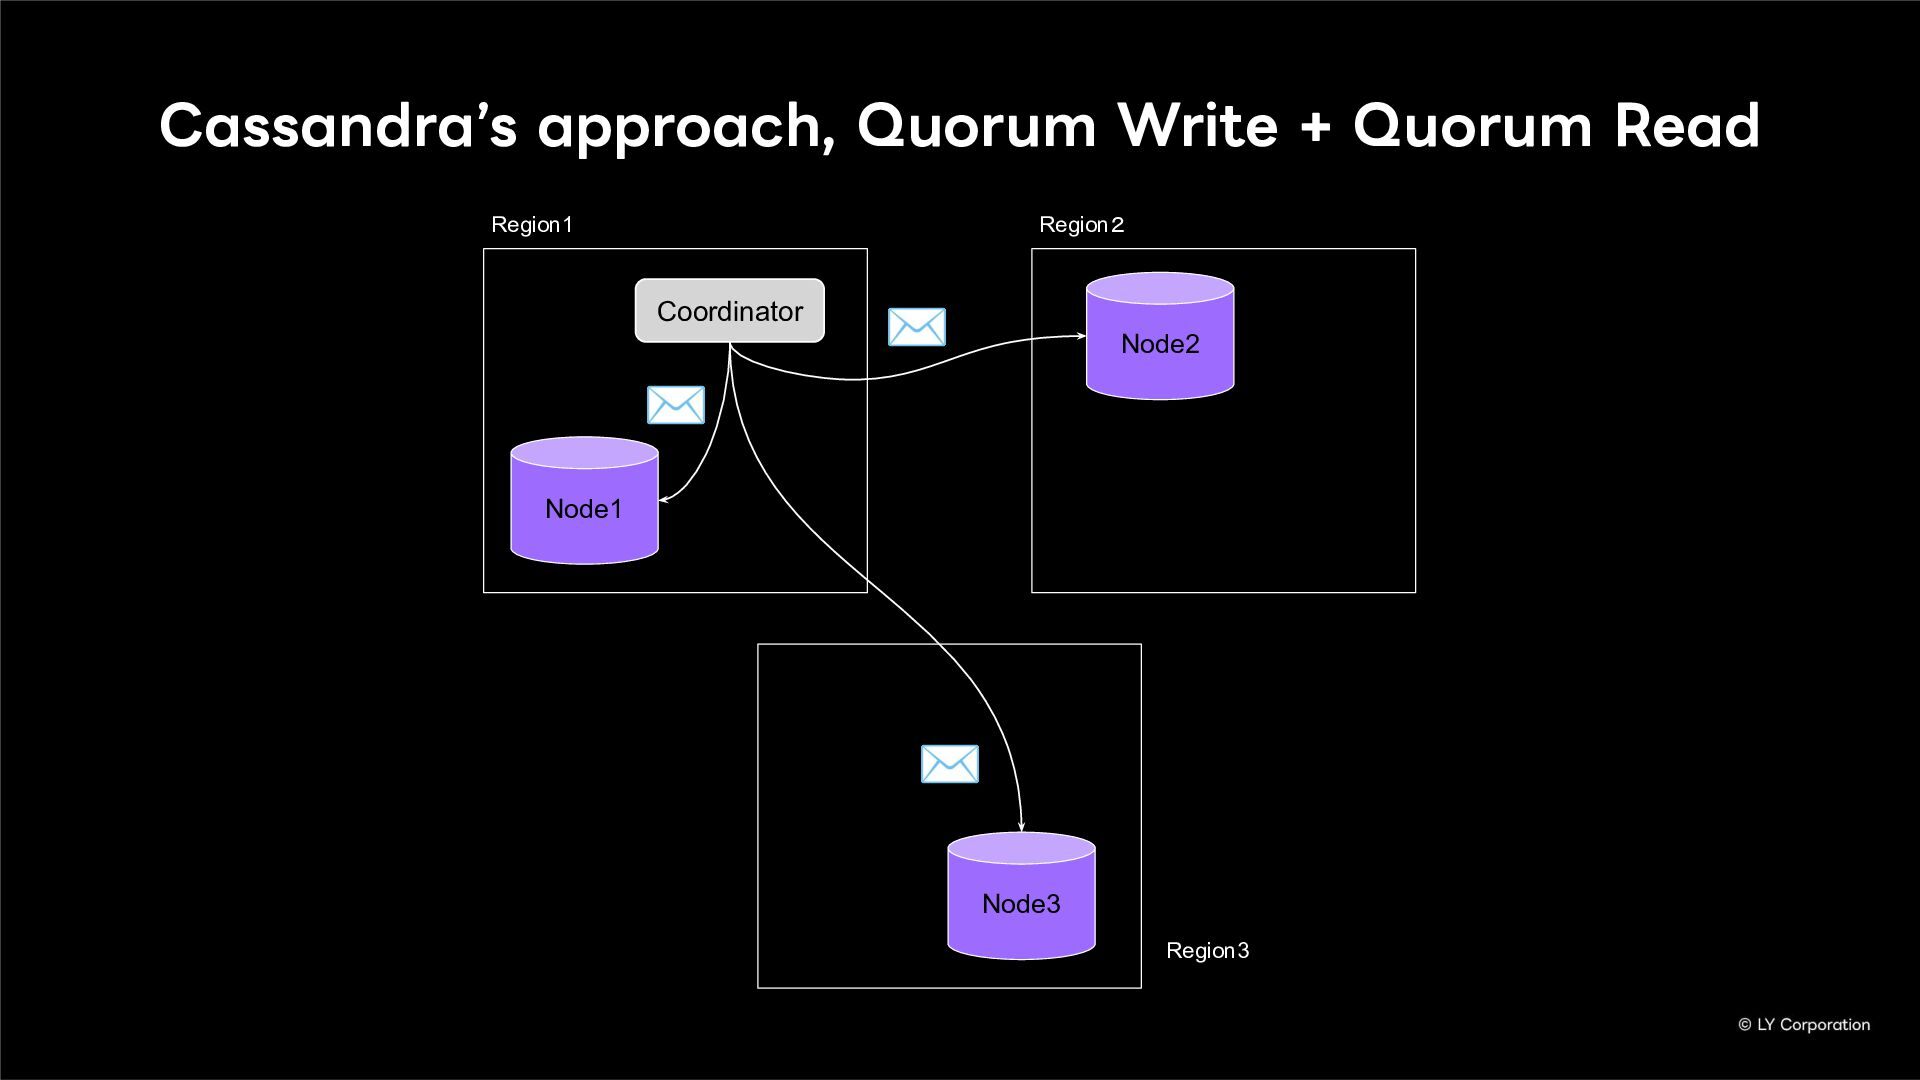
Cassandraʼs approach, Quorum Write + Quorum Read Node1 Region1 Region2
Node2 Node3 Region3 Coordinator ✉ ✉ ✉ -
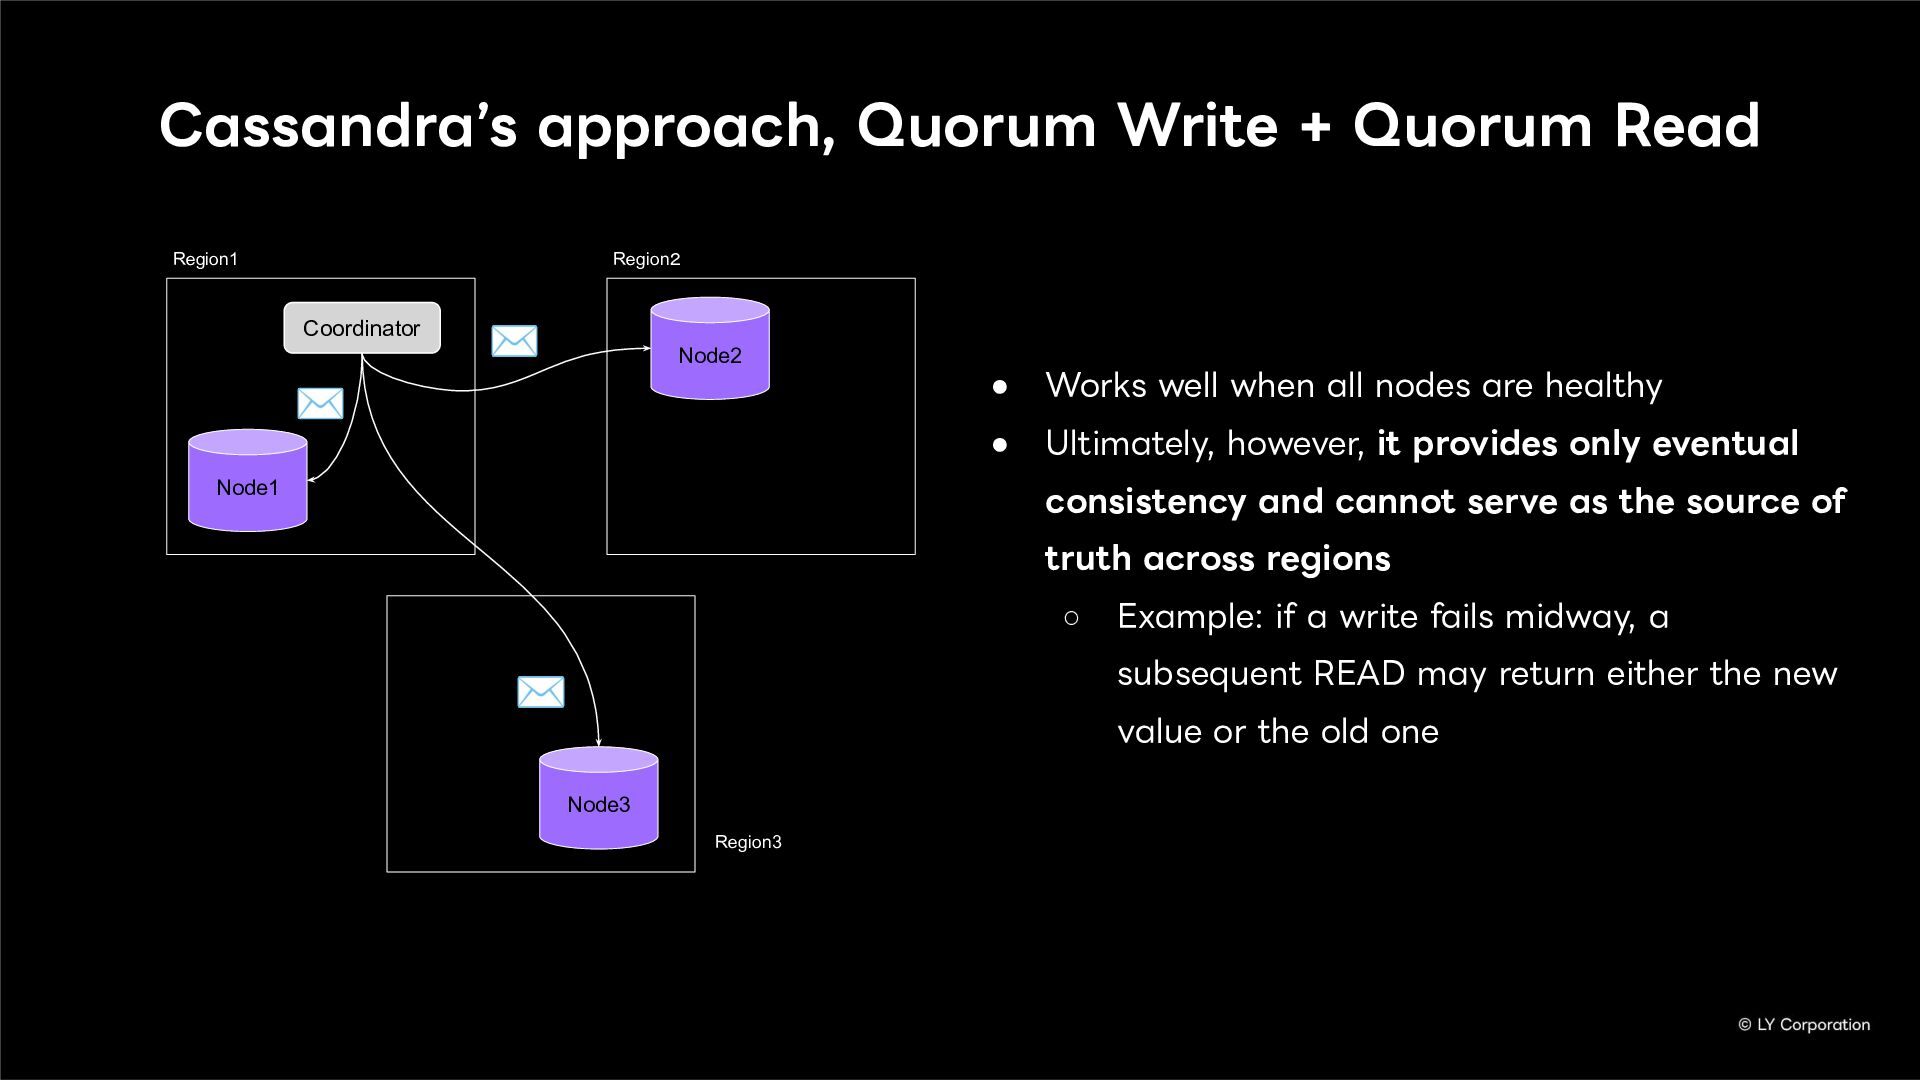
Cassandraʼs approach, Quorum Write + Quorum Read Node1 Region1 Region2
Node2 Node3 Region3 Coordinator ✉ ✉ ✉ • Works well when all nodes are healthy • Ultimately, however, it provides only eventual consistency and cannot serve as the source of truth across regions ◦ Example: if a write fails midway, a subsequent READ may return either the new value or the old one -
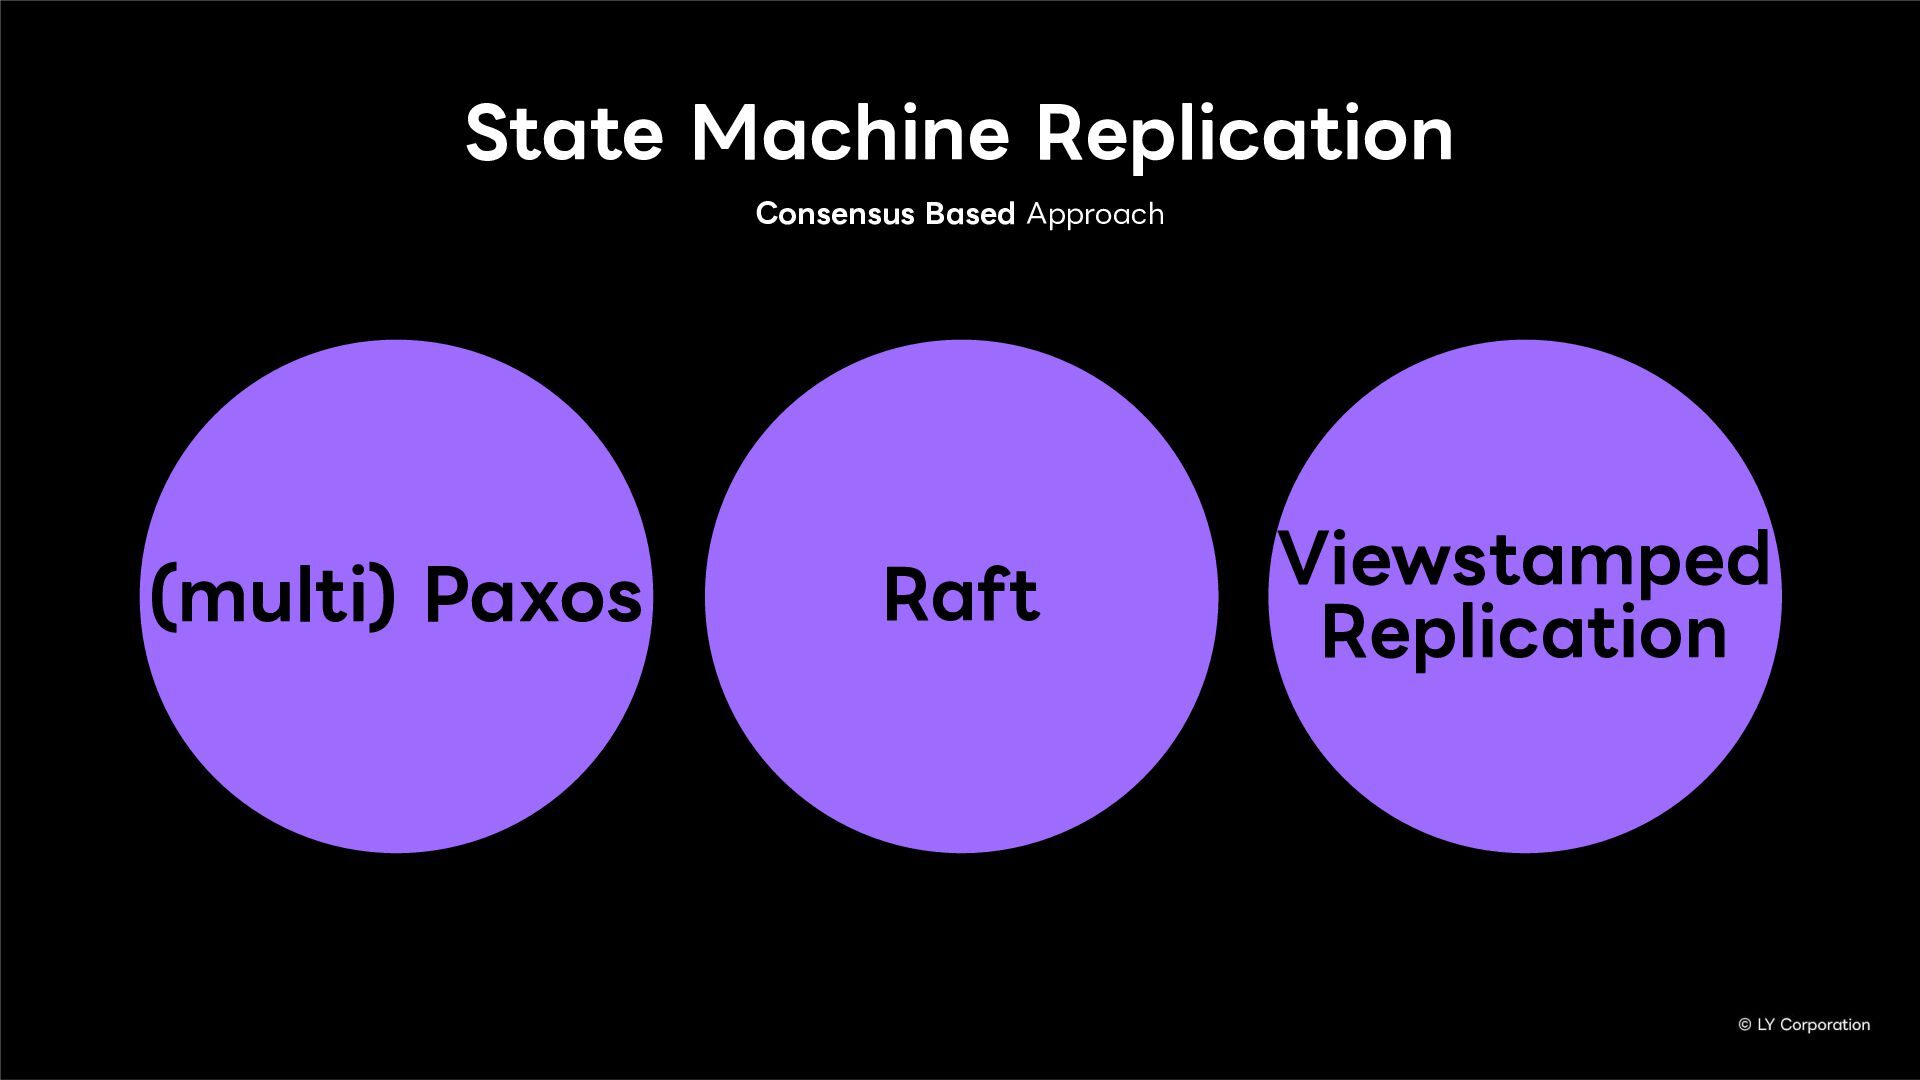
State Machine Replication Raft (multi) Paxos Viewstamped Replication State Machine
Replication Consensus Based Approach -
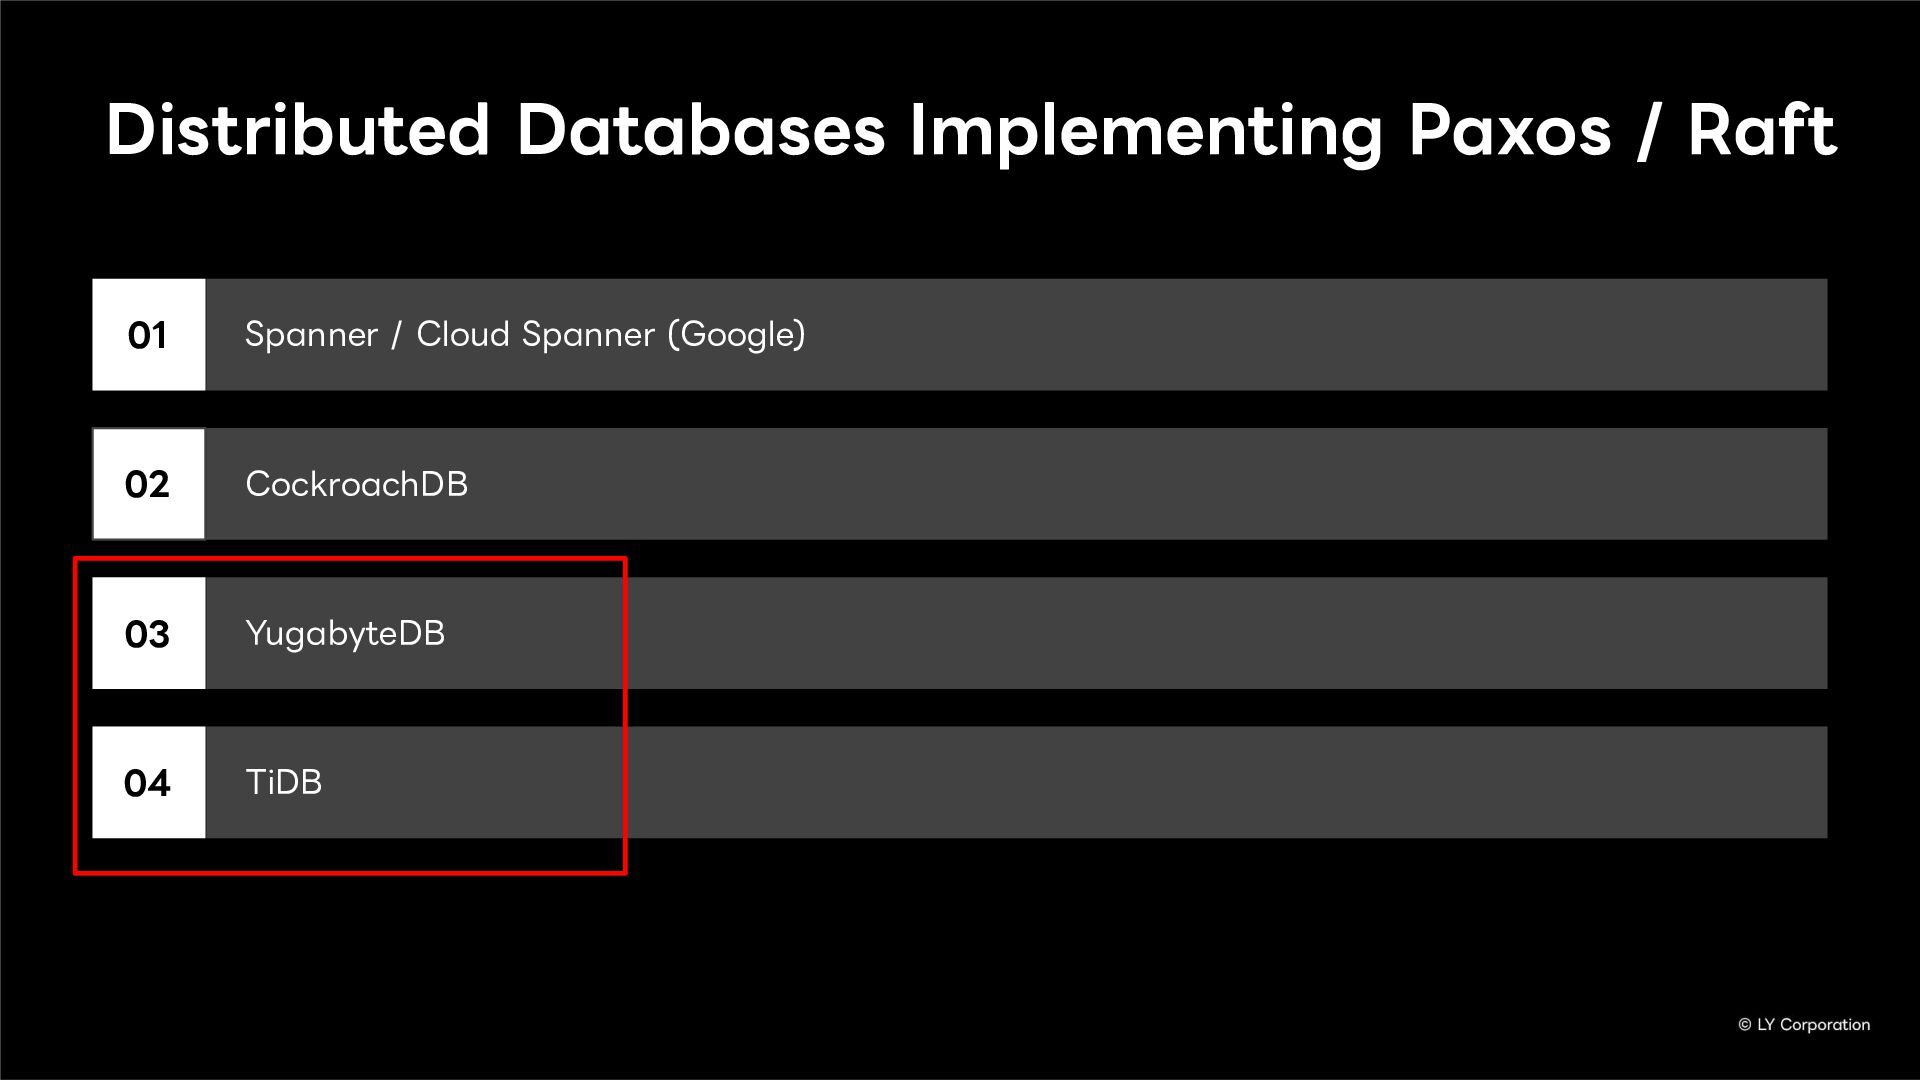
Spanner / Cloud Spanner (Google) CockroachDB YugabyteDB TiDB 01 03
02 04 Distributed Databases Implementing Paxos / Raft -
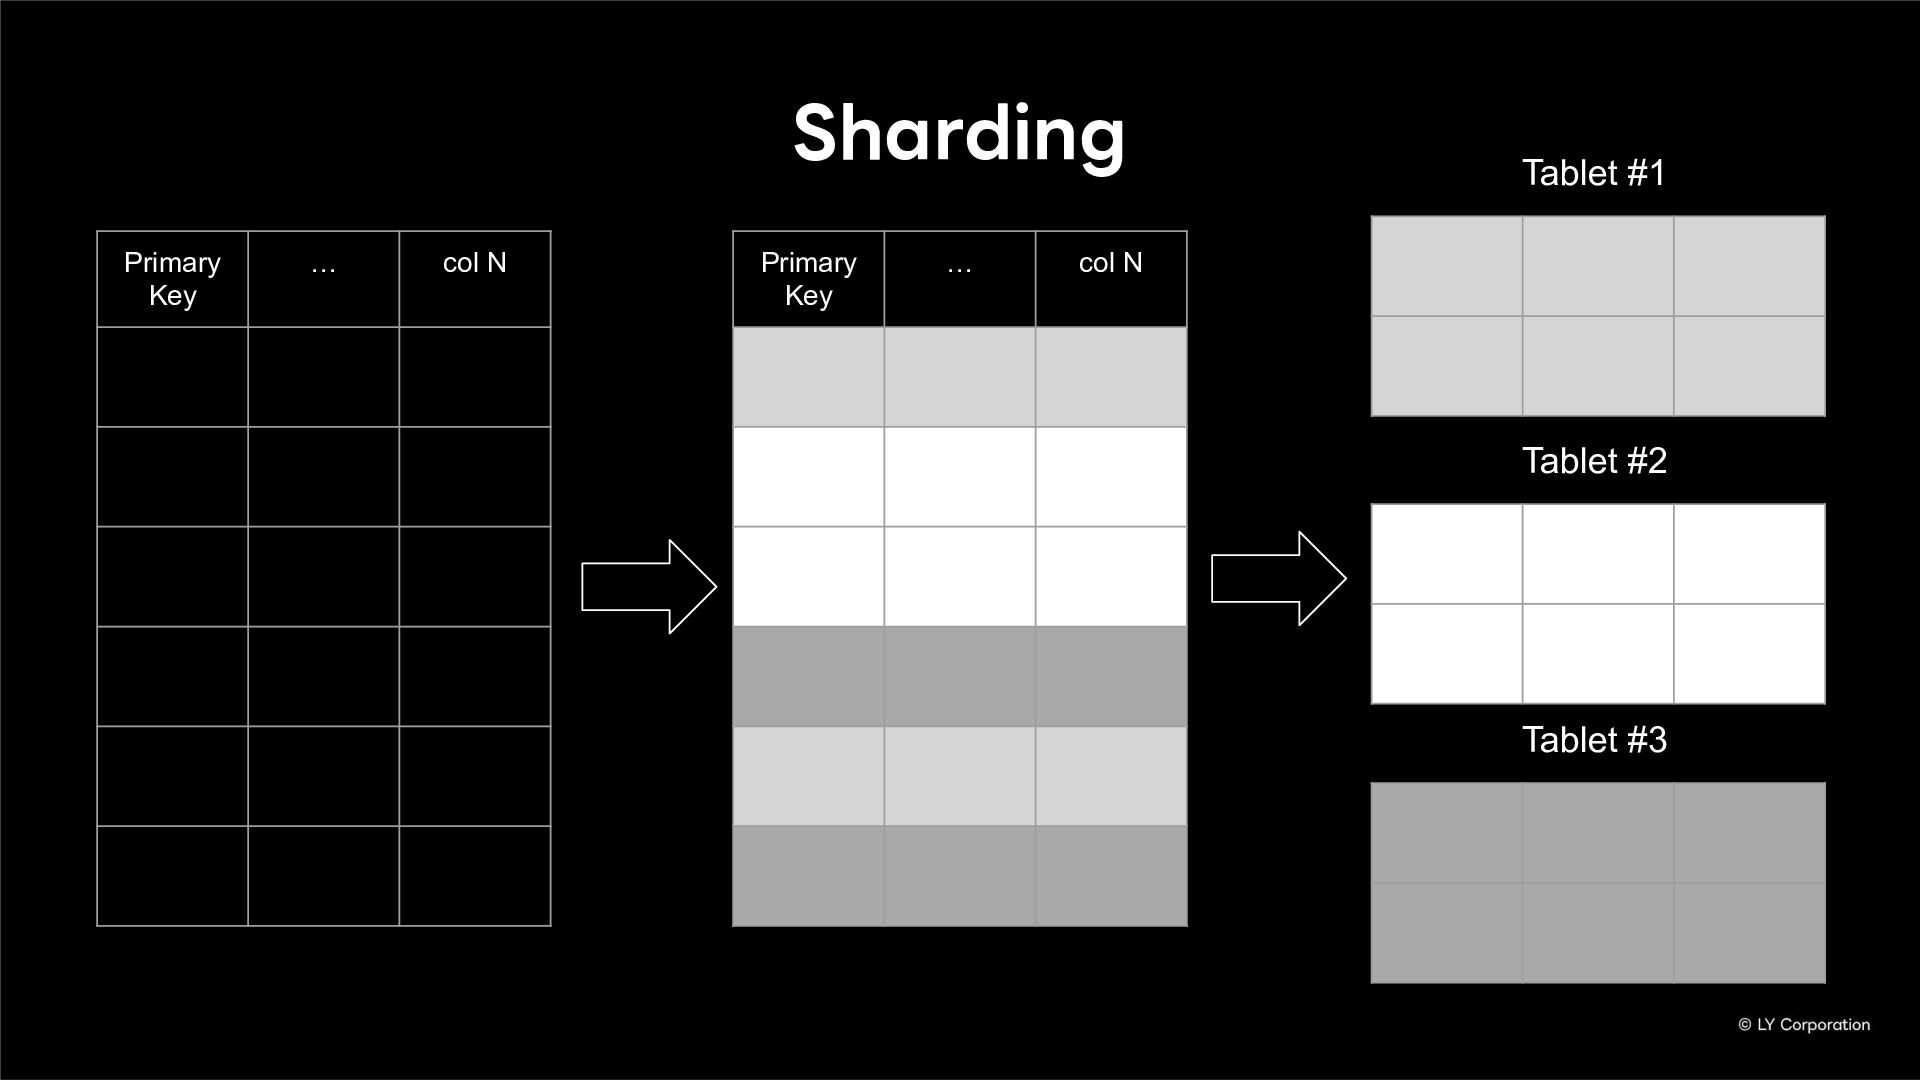
Sharding Primary Key … col N Primary Key … col
N Tablet #1 Tablet #2 Tablet #3 -
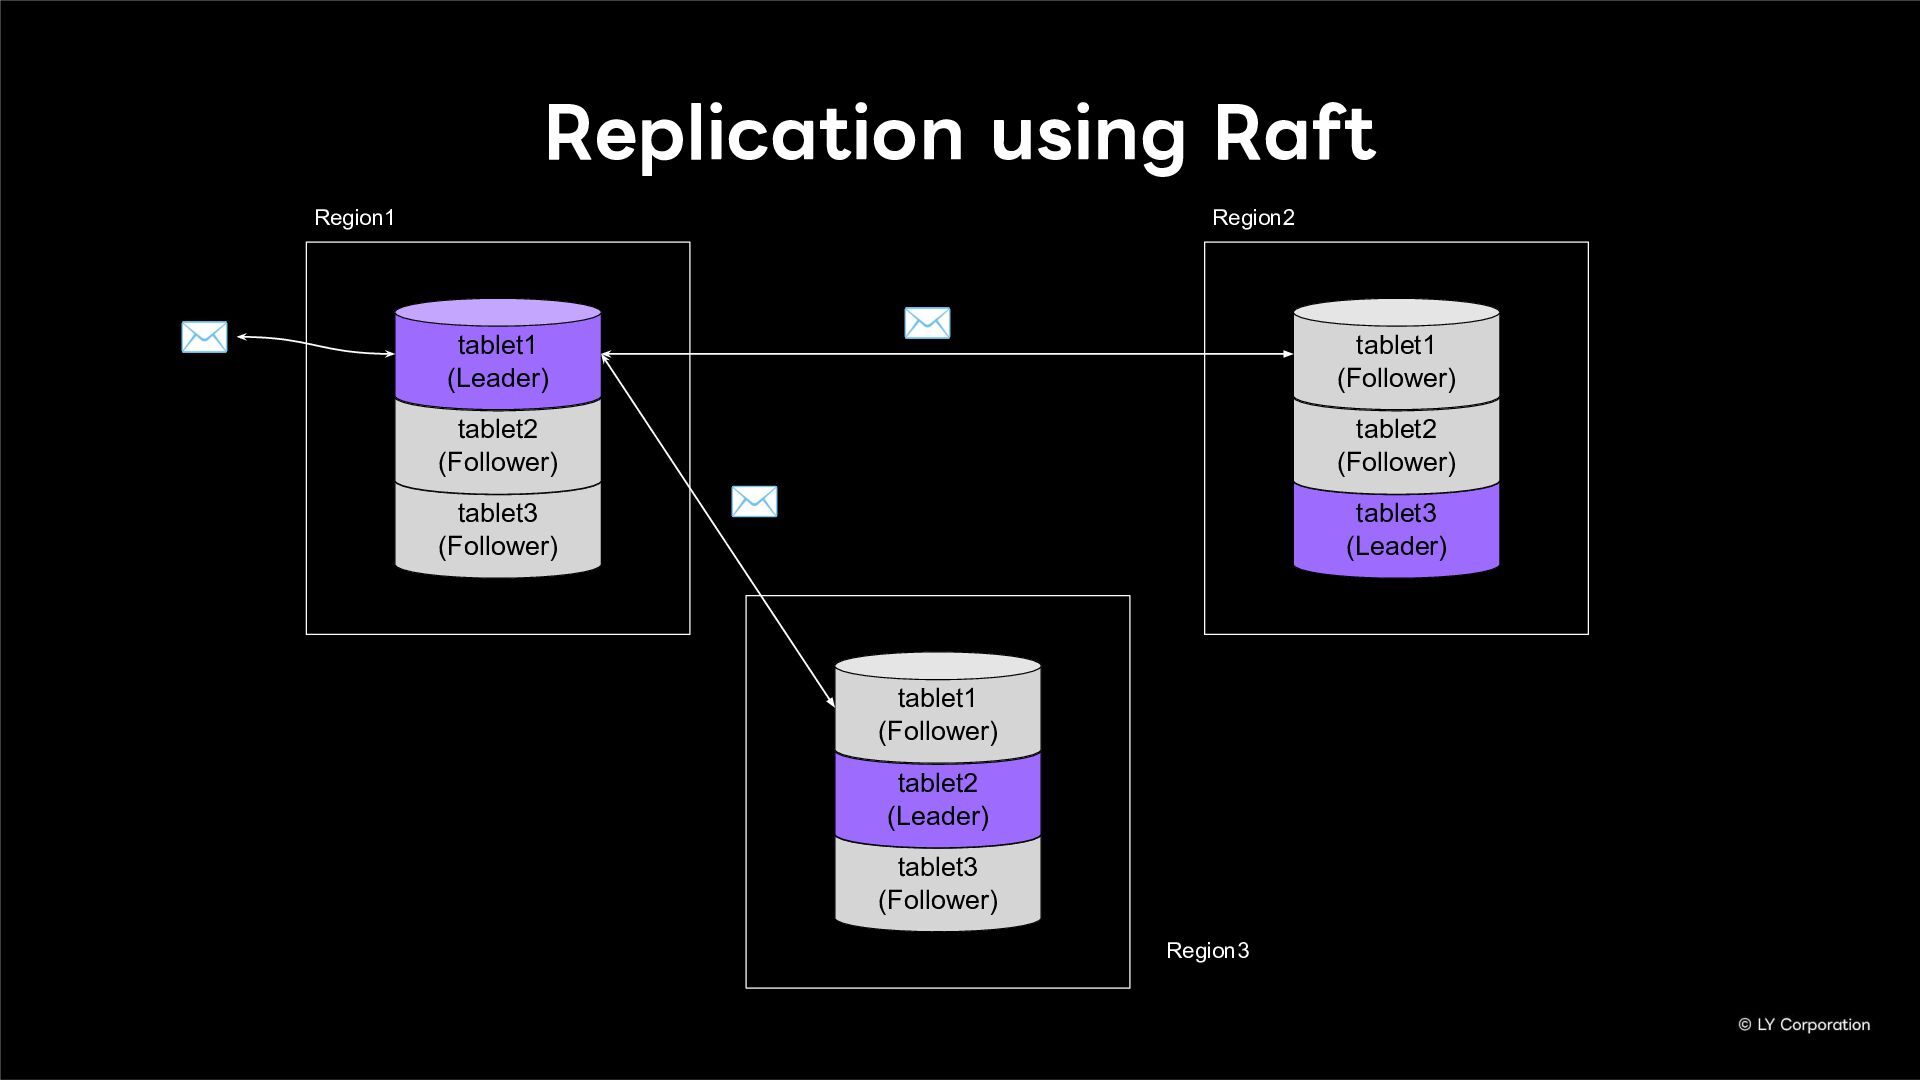
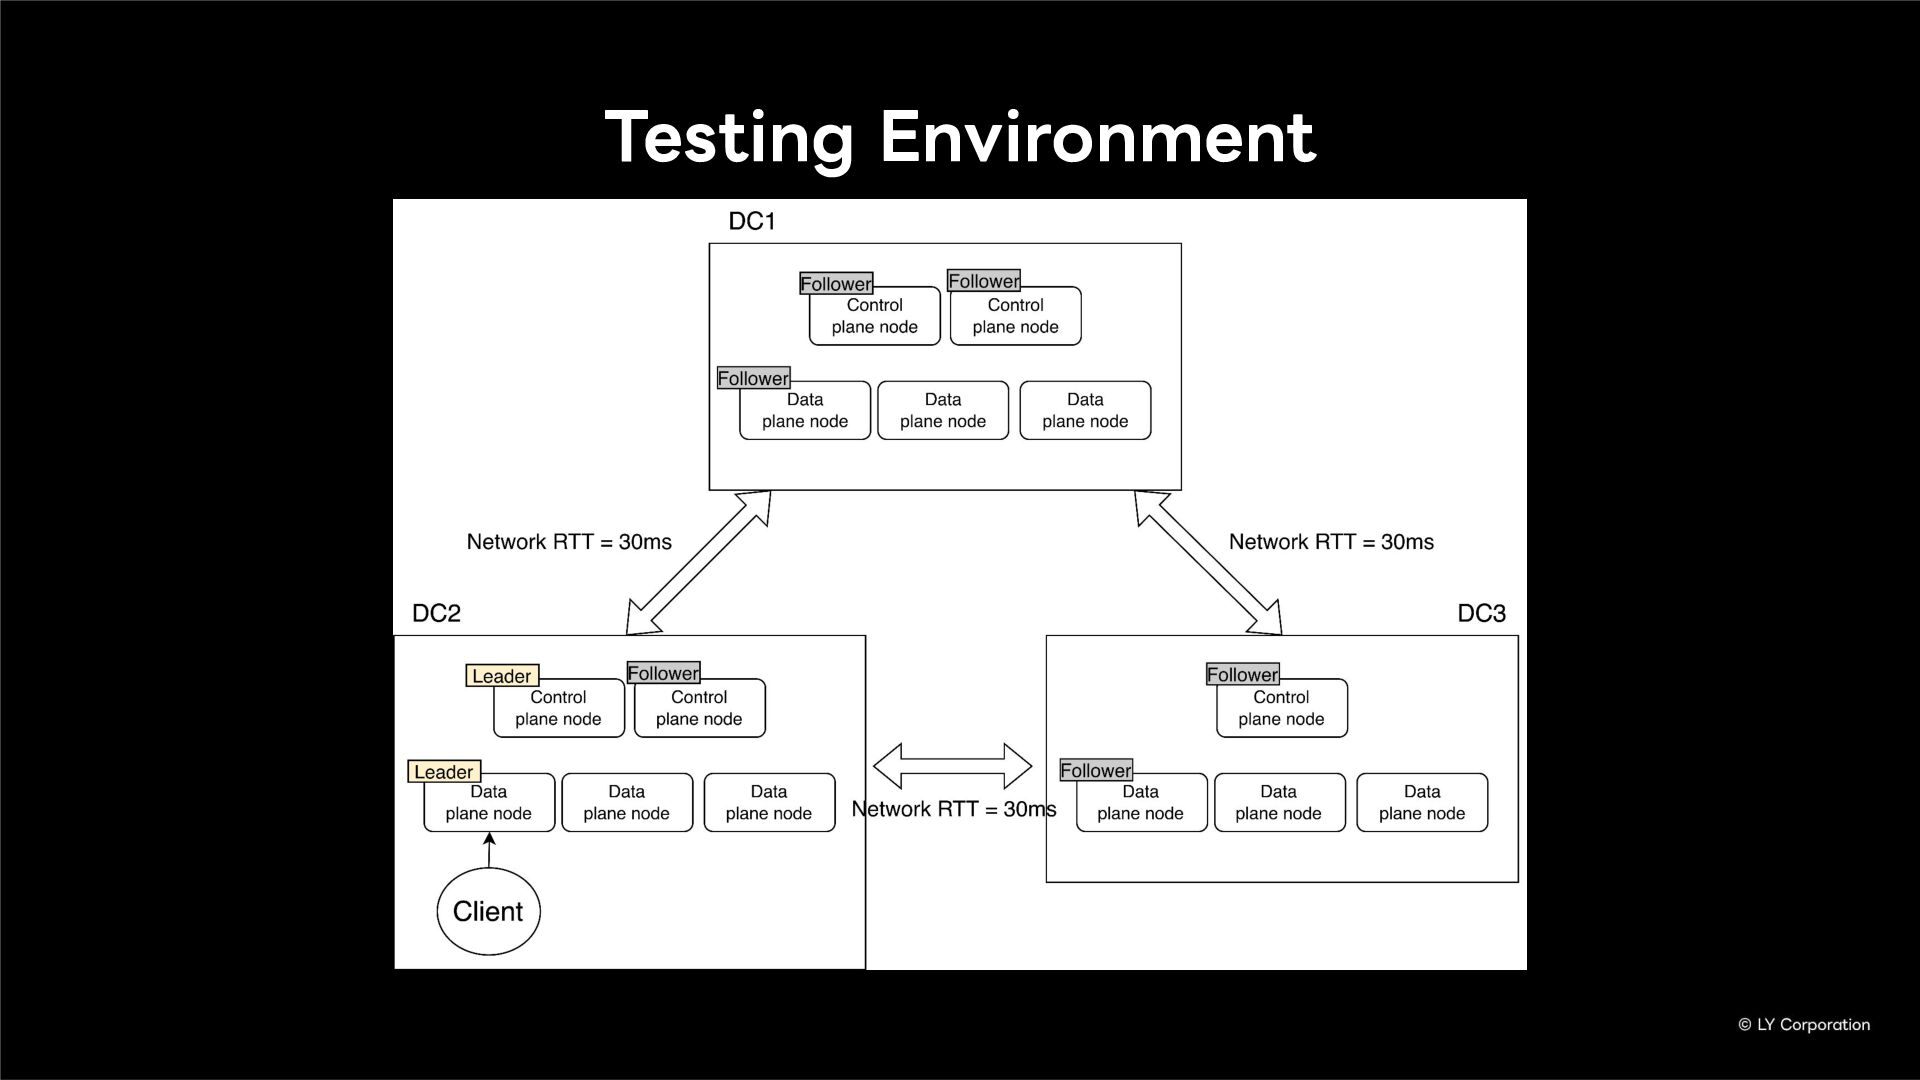
3 Replication using Raft Region1 Region3 tablet3 (Follower) tablet2 (Follower)
tablet1 (Leader) 3 tablet3 (Follower) tablet2 (Leader) tablet1 (Follower) 3 Region2 tablet3 (Leader) tablet2 (Follower) tablet1 (Follower) ✉ ✉ ✉ -
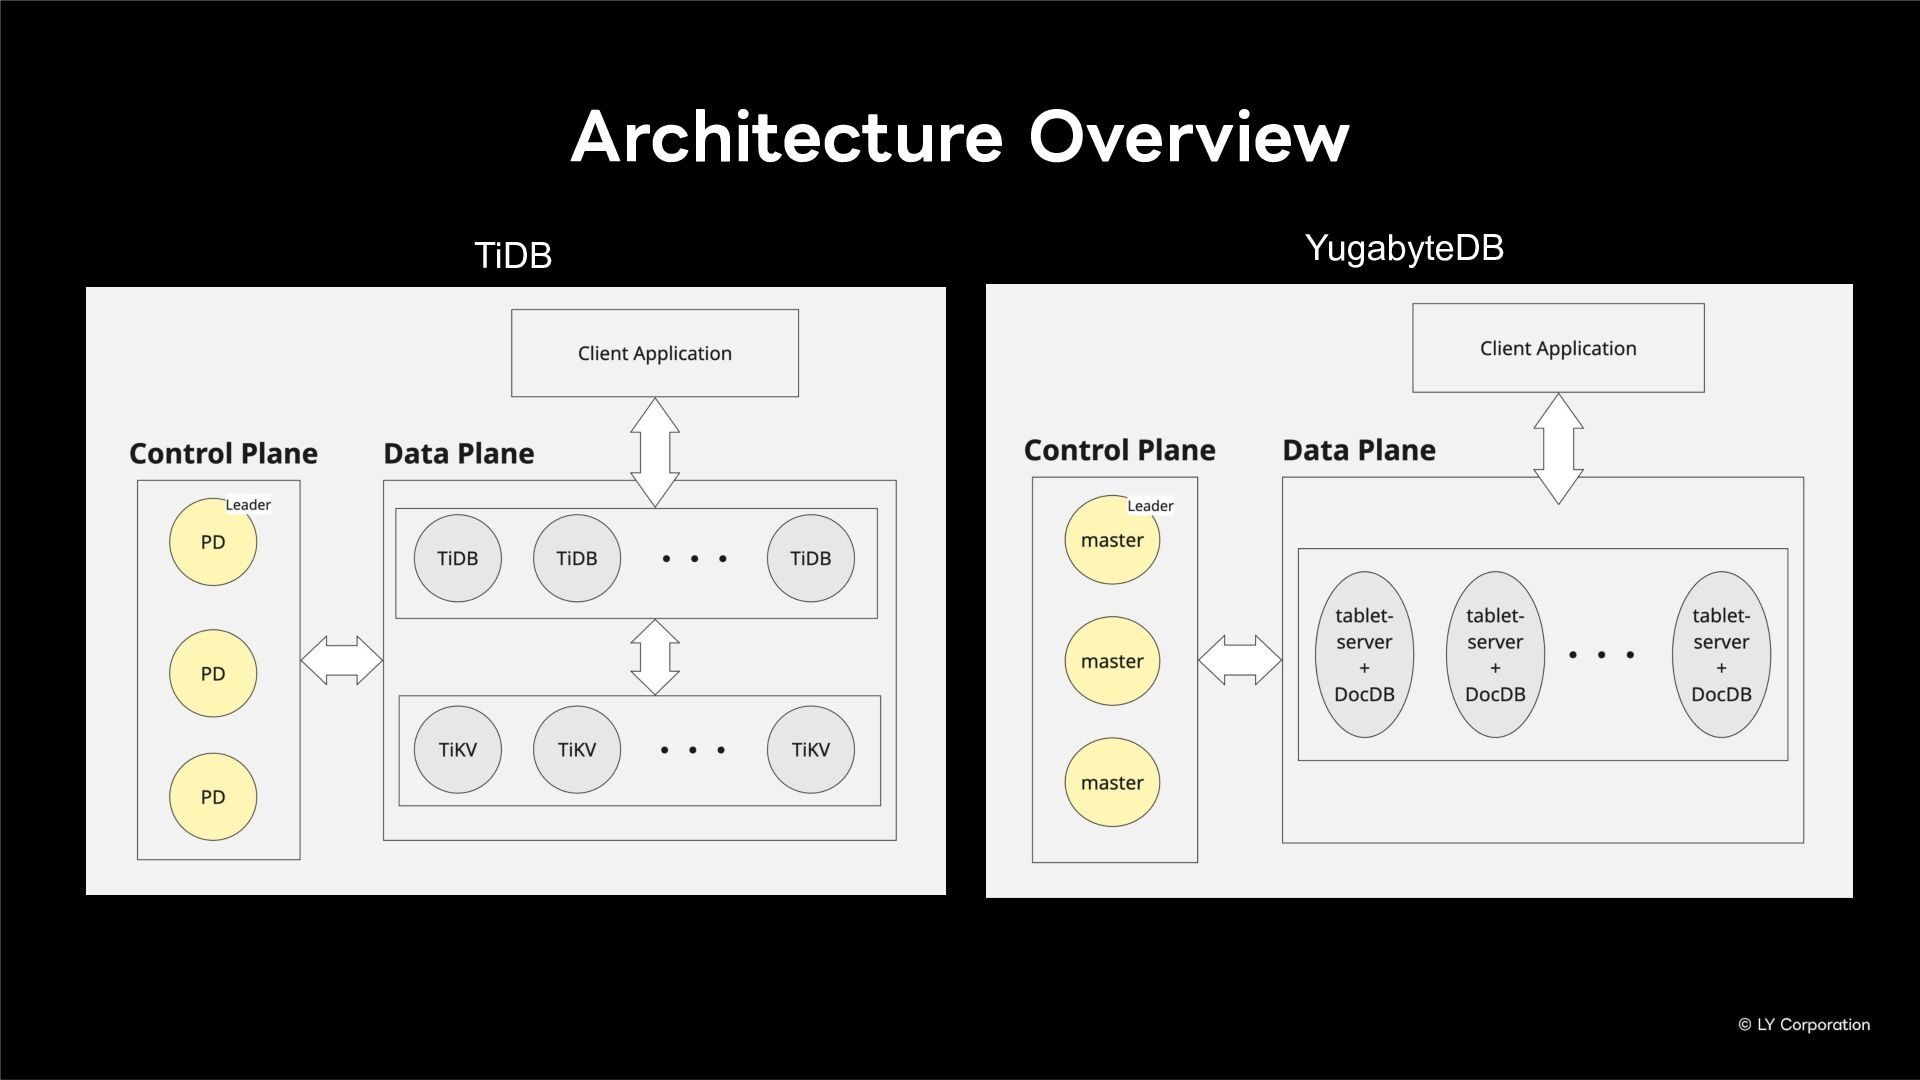
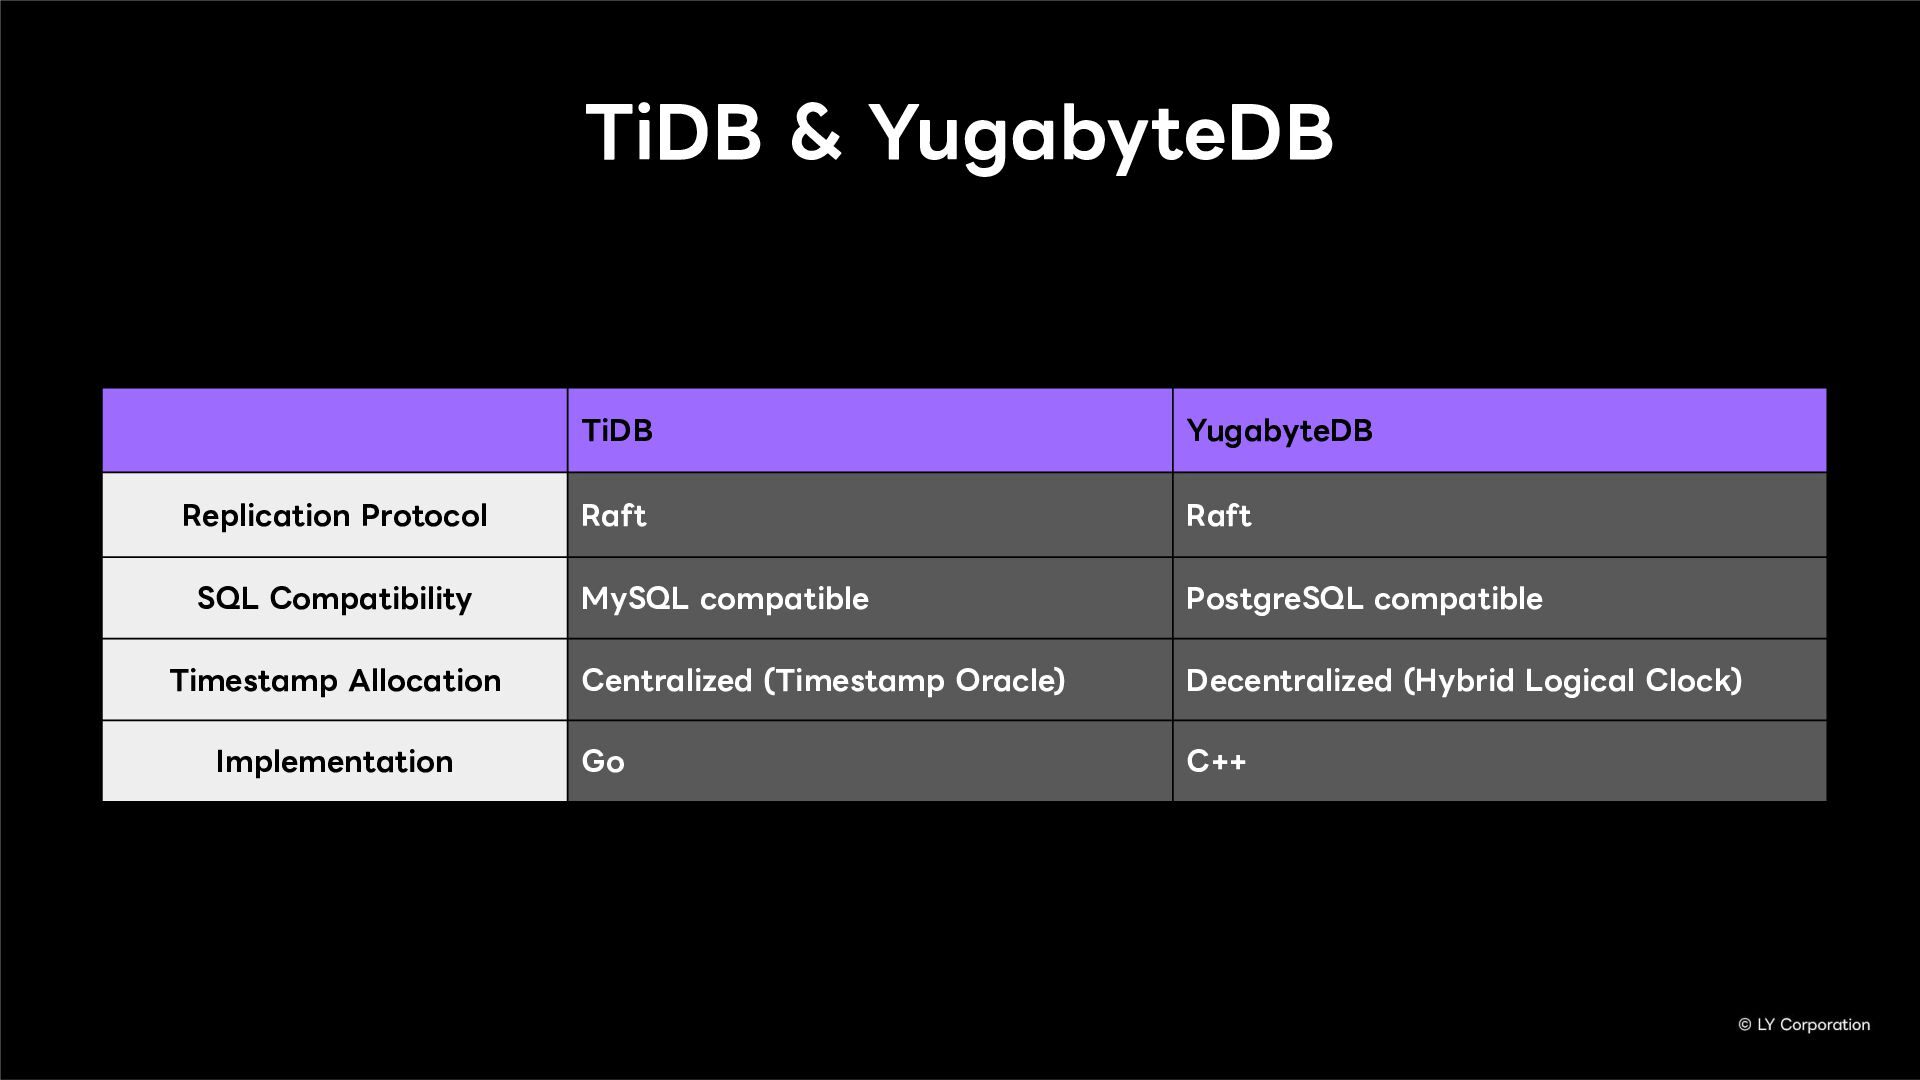
TiDB & YugabyteDB TiDB & YugabyteDB TiDB YugabyteDB Replication Protocol
Raft Raft SQL Compatibility MySQL compatible PostgreSQL compatible Timestamp Allocation Centralized (Timestamp Oracle) Decentralized (Hybrid Logical Clock) Implementation Go C++ -
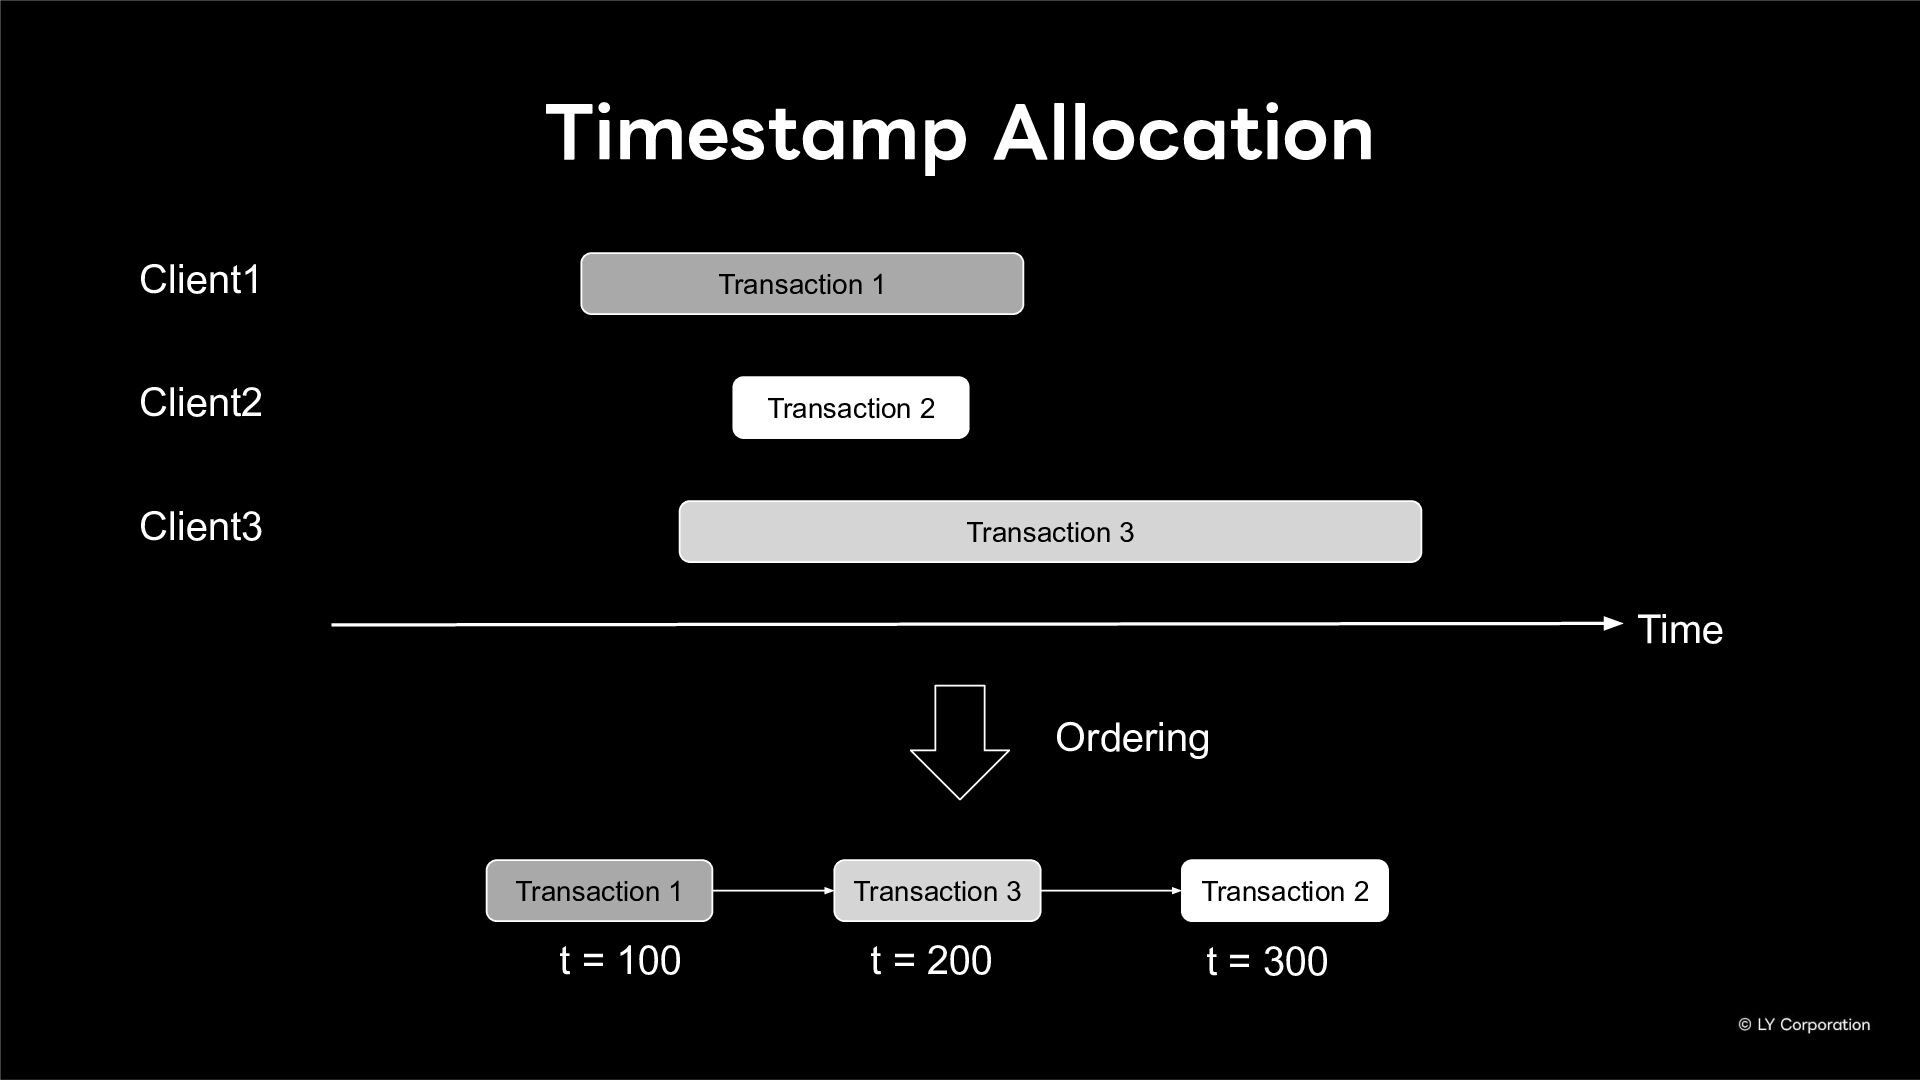
Timestamp Allocation Transaction 1 Transaction 2 Transaction 3 Time Client1
Client2 Client3 Transaction 1 Transaction 2 Transaction 3 Ordering t = 100 t = 200 t = 300 -
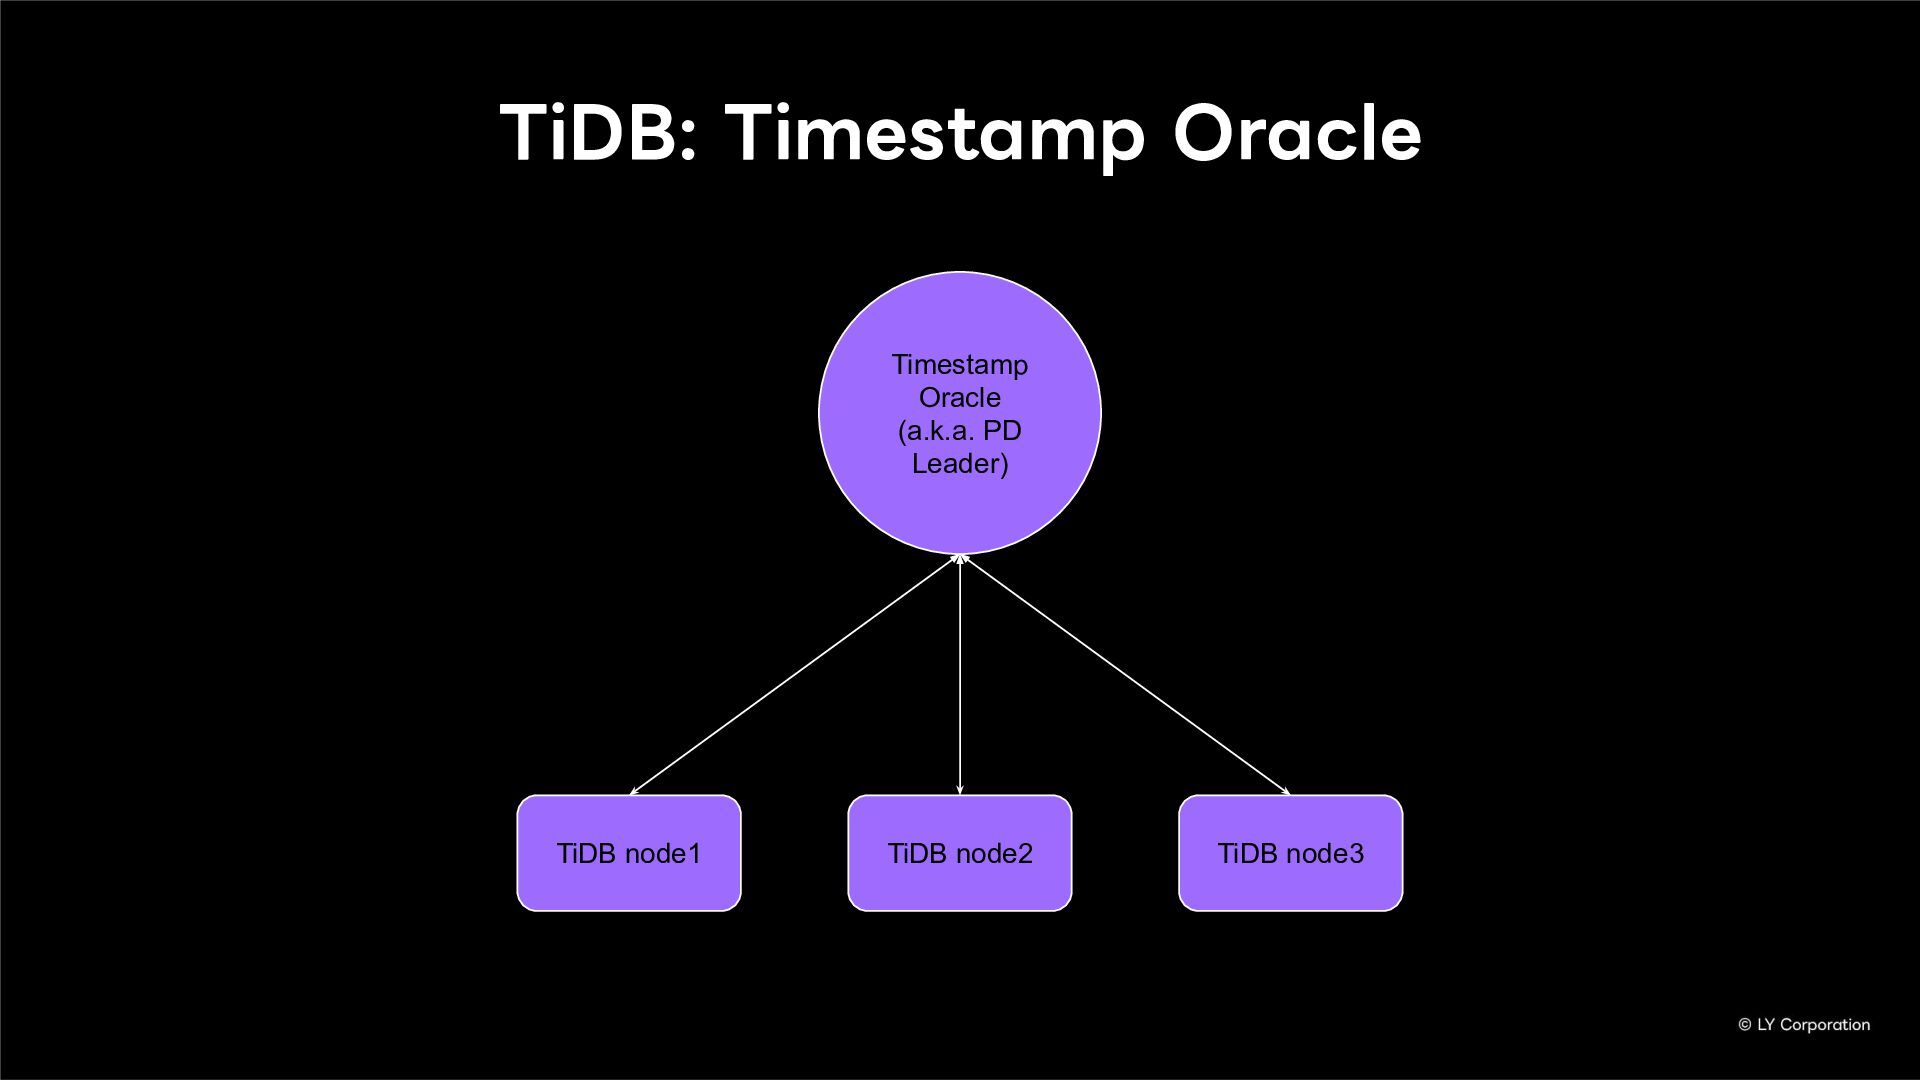
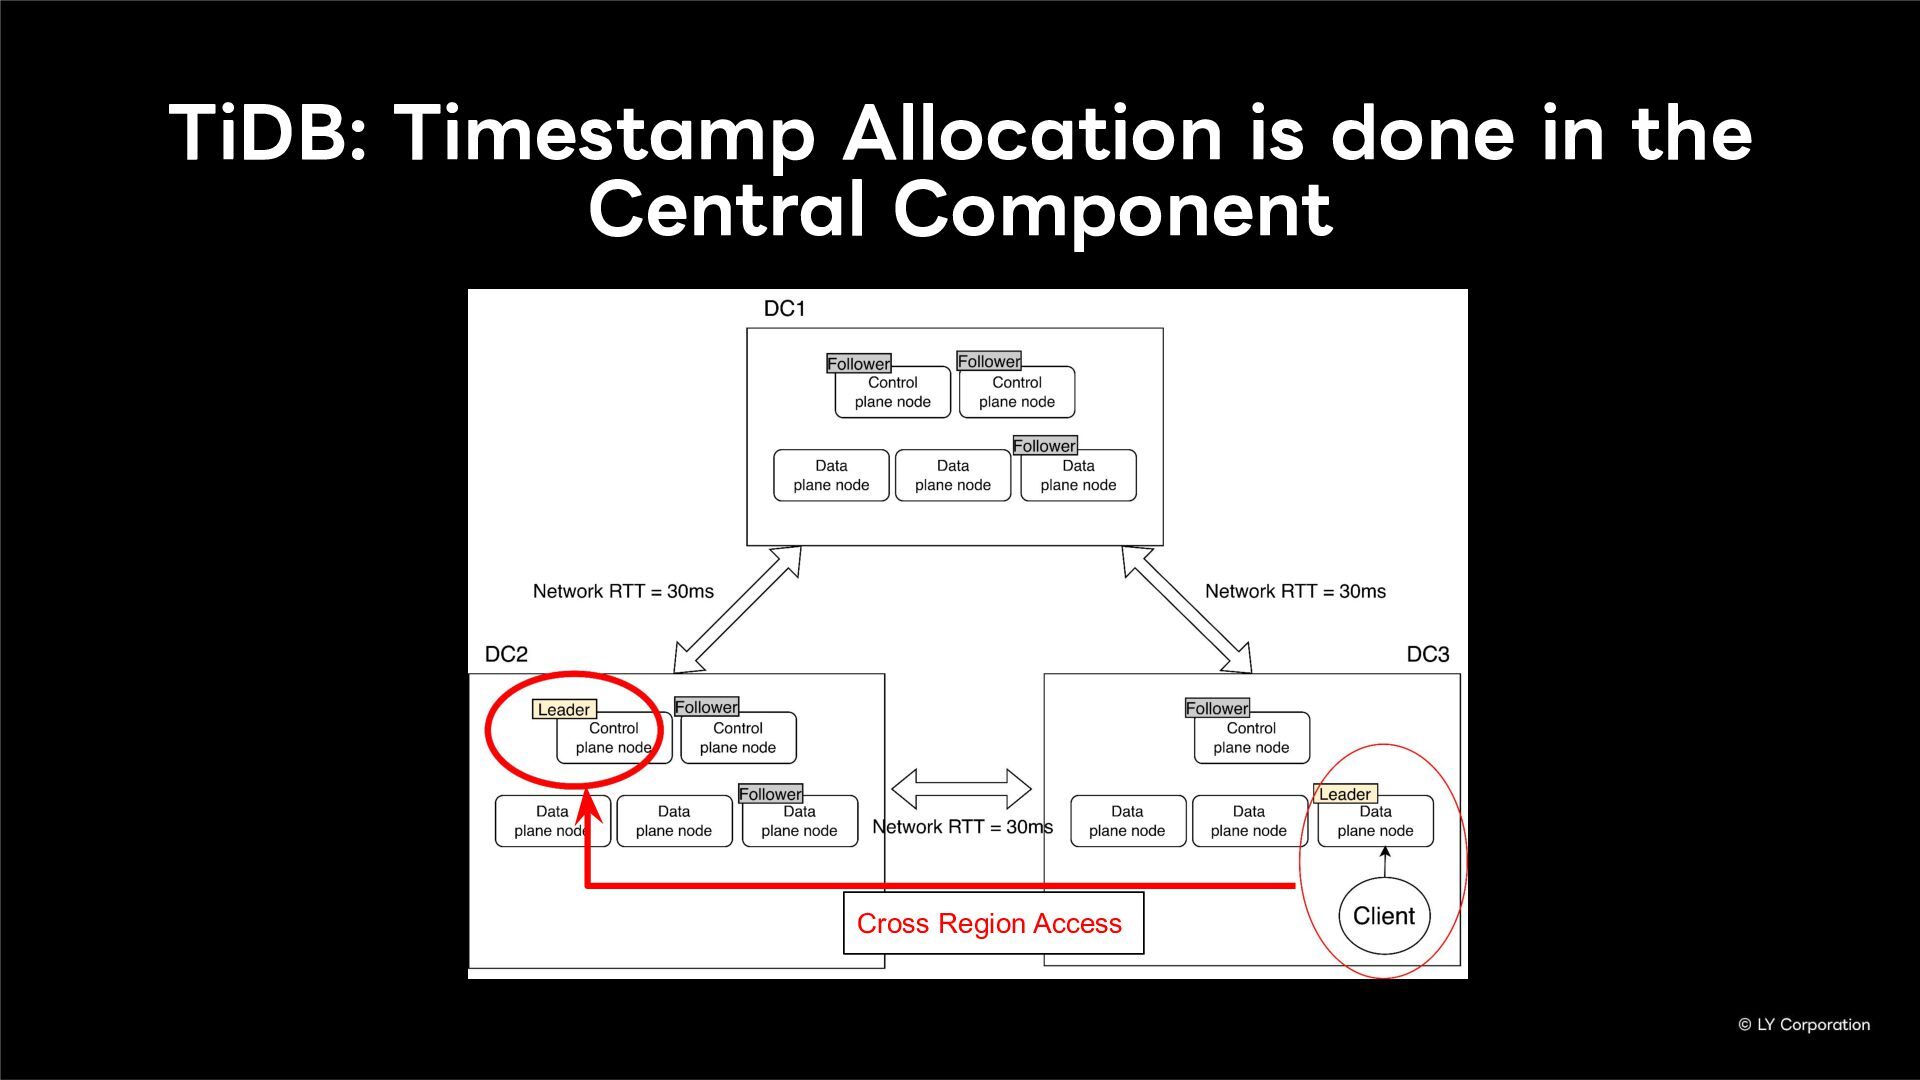
TiDB: Timestamp Oracle Timestamp Oracle (a.k.a. PD Leader) TiDB node1
TiDB node2 TiDB node3 -
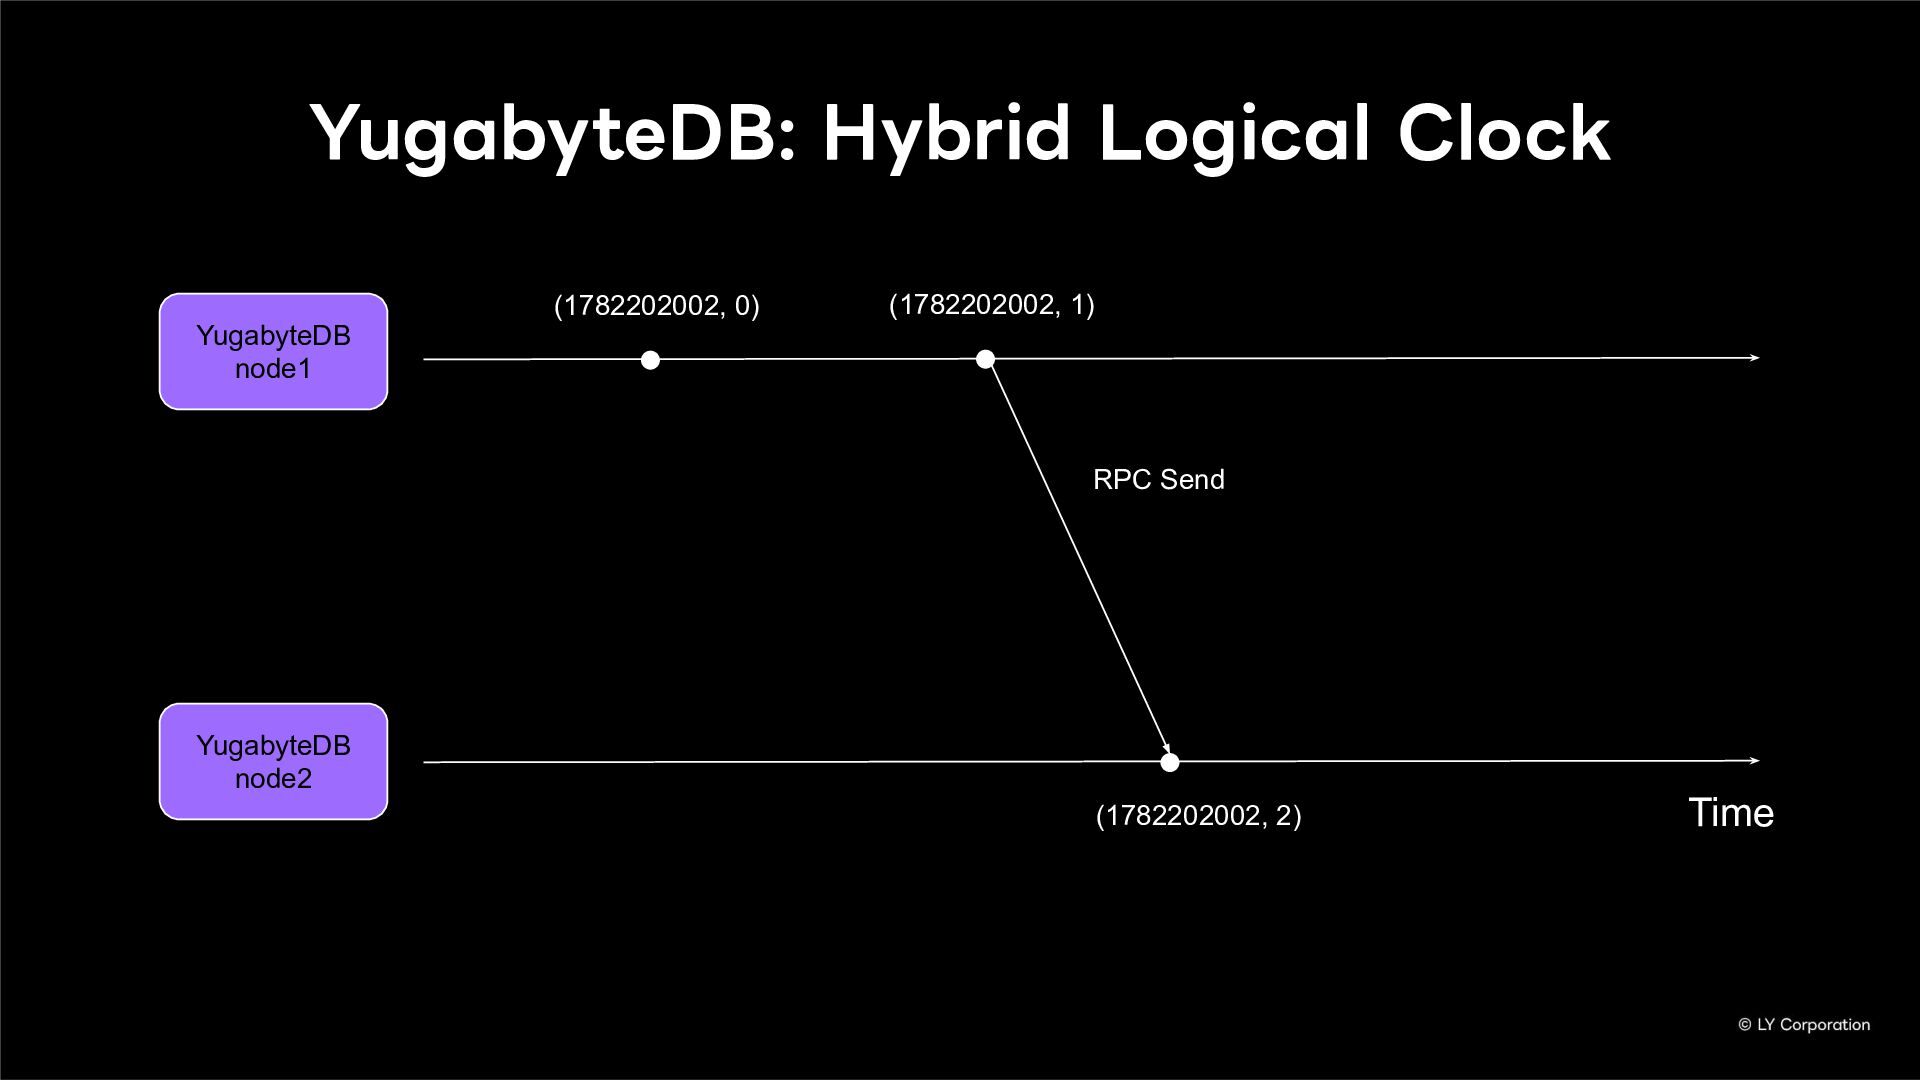
YugabyteDB: Hybrid Logical Clock YugabyteDB node1 YugabyteDB node2 Time (1782202002,
0) (1782202002, 1) (1782202002, 2) RPC Send -
Feature Set Resiliency Performance (Latency + Throughput) 01 03 02
Selection Criteria -
Essential requirement not to violate the SLO of the Messenger
service Two types of evaluation methods • Benchmark tool (YCSB) • Production representative workload replay (Replayer) 01 02 Performance Evaluation -
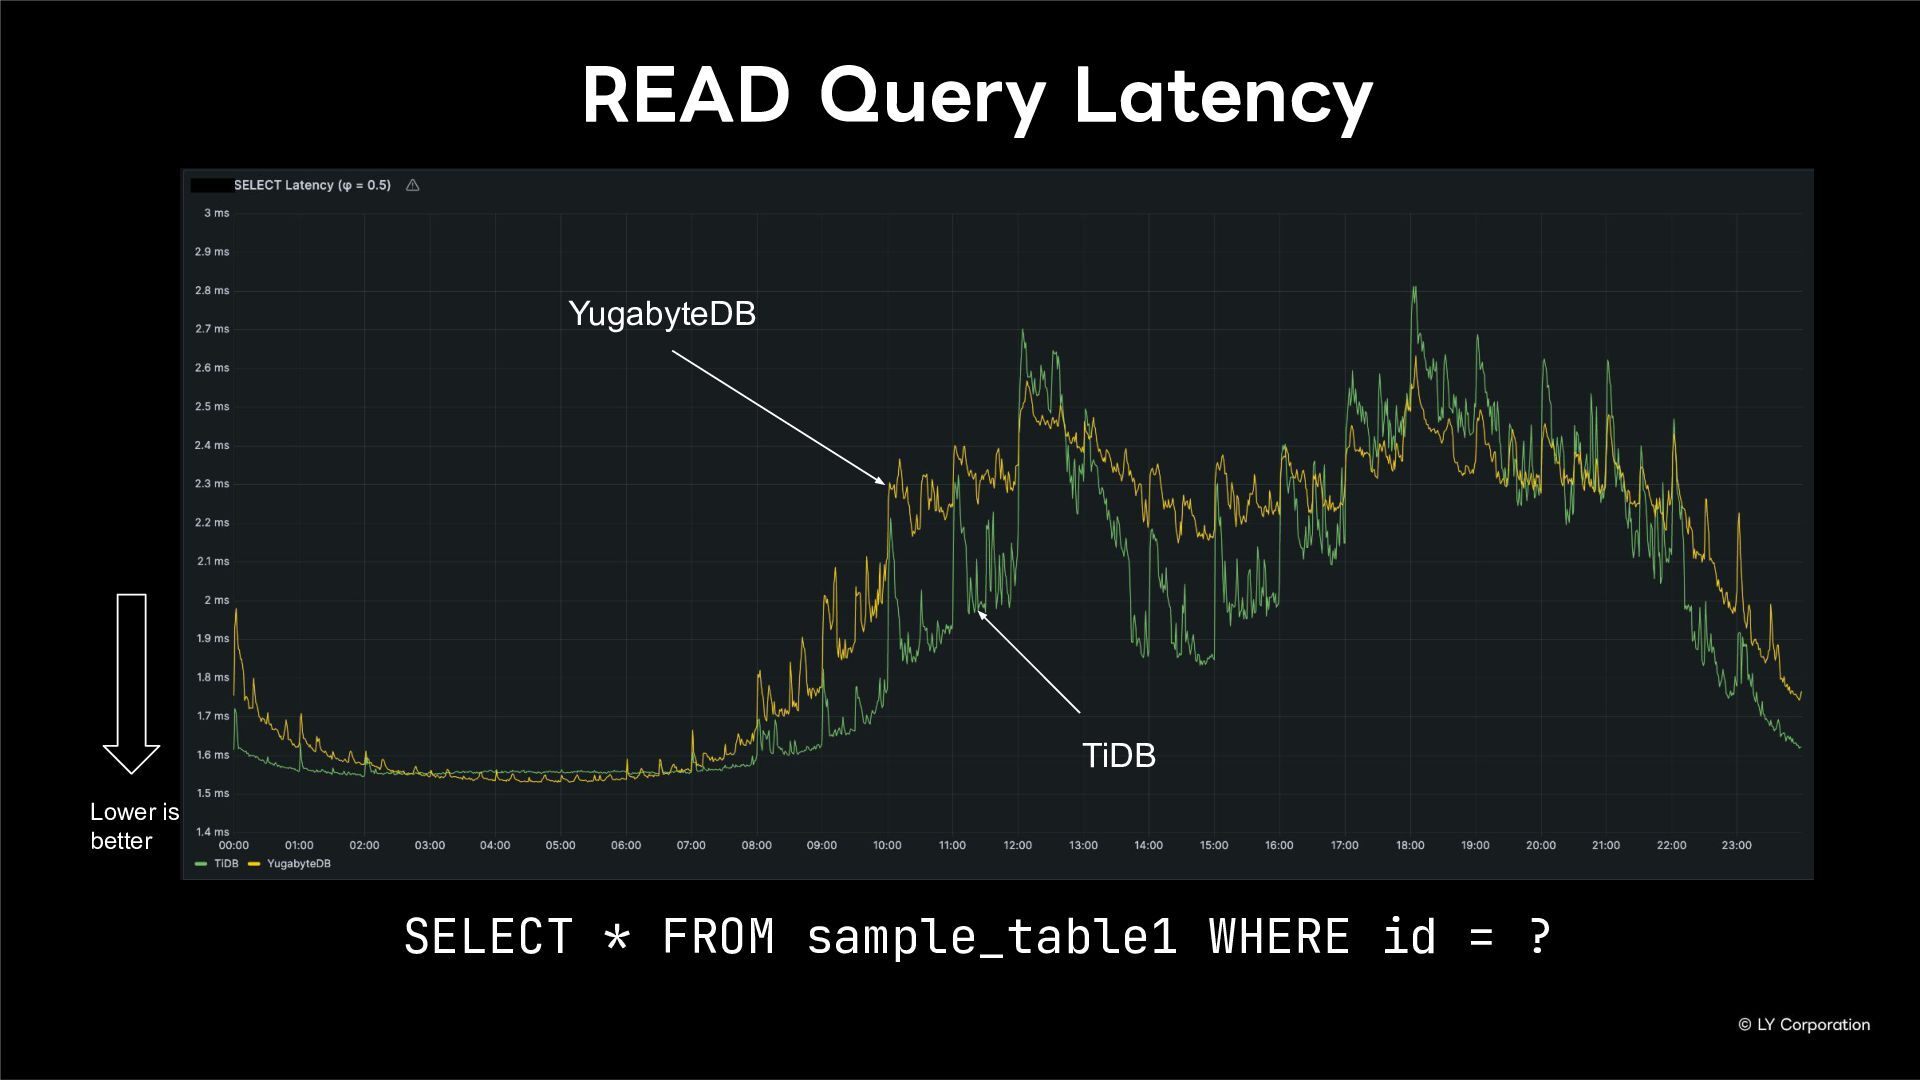
READ Query Latency SELECT * FROM sample_table1 WHERE id =
? YugabyteDB TiDB Lower is better -
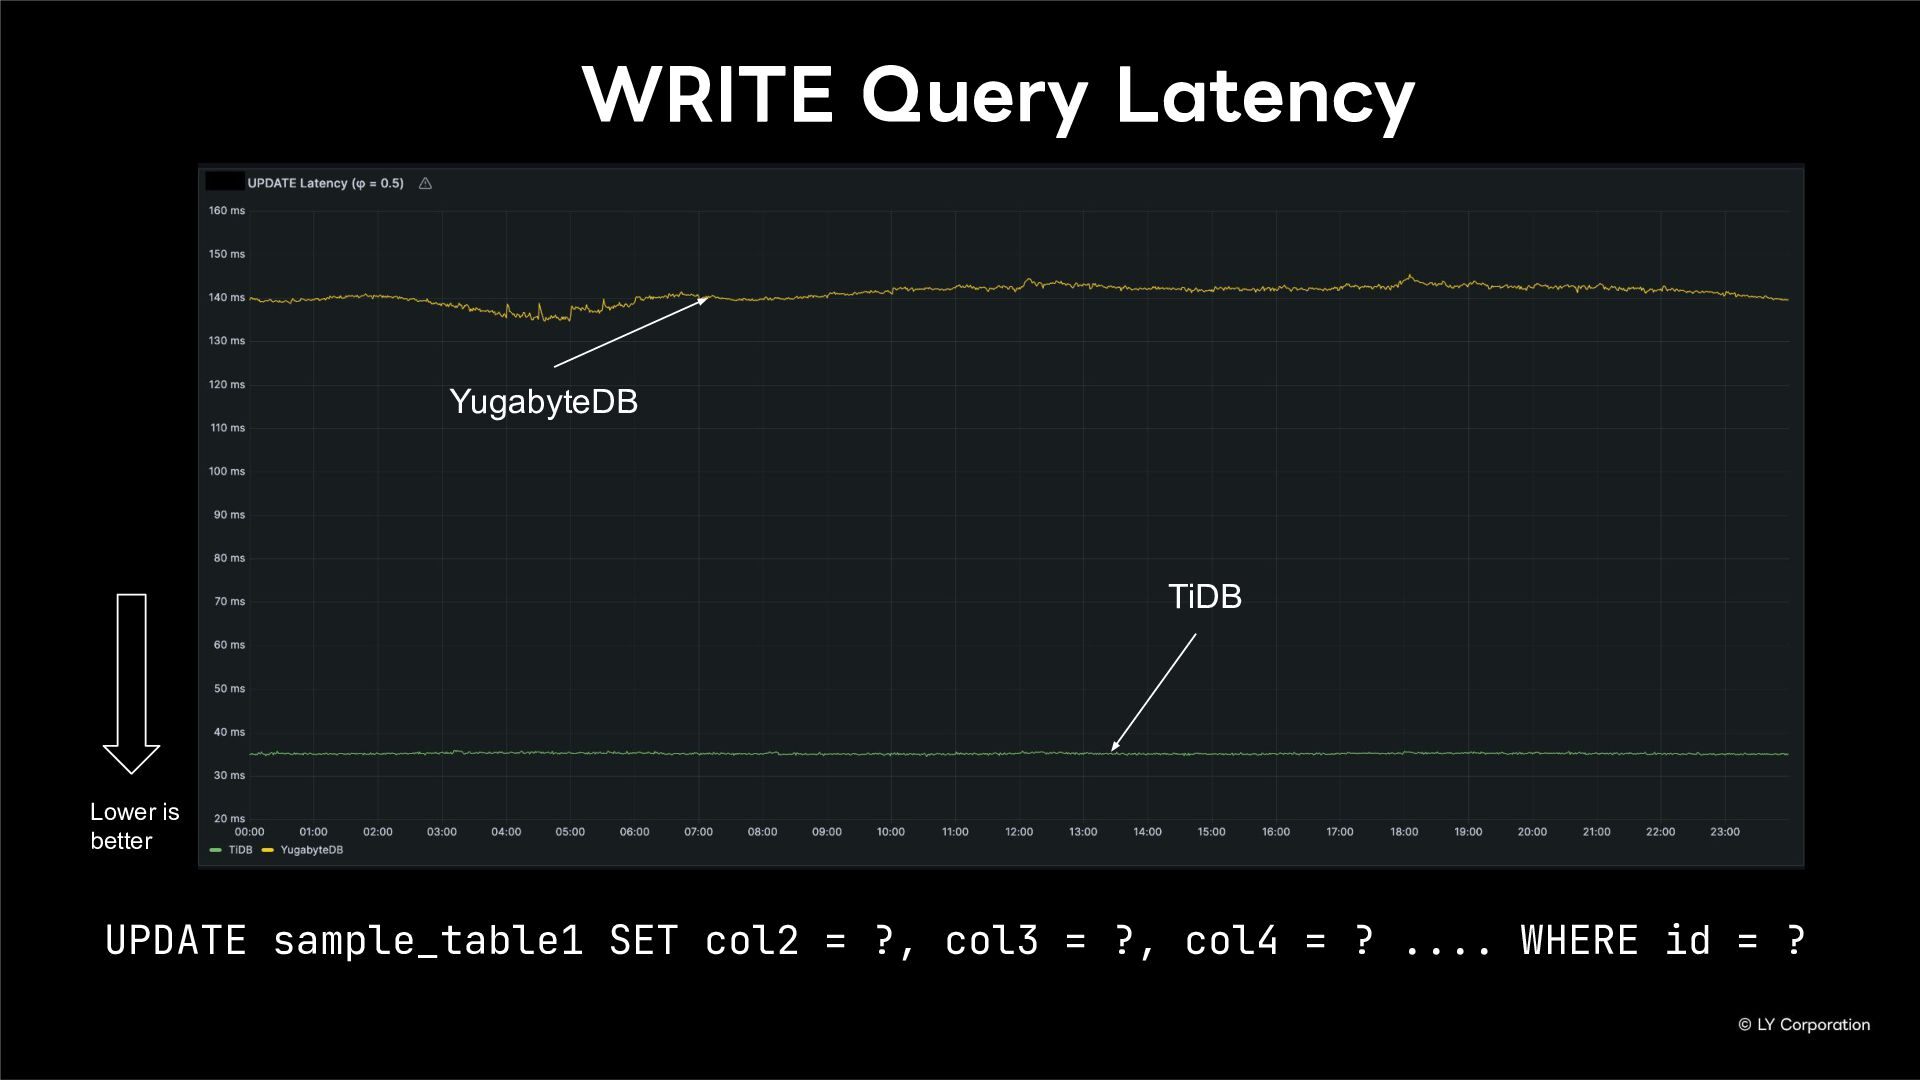
WRITE Query Latency UPDATE sample_table1 SET col2 = ?, col3
= ?, col4 = ? .... WHERE id = ? YugabyteDB TiDB Lower is better -
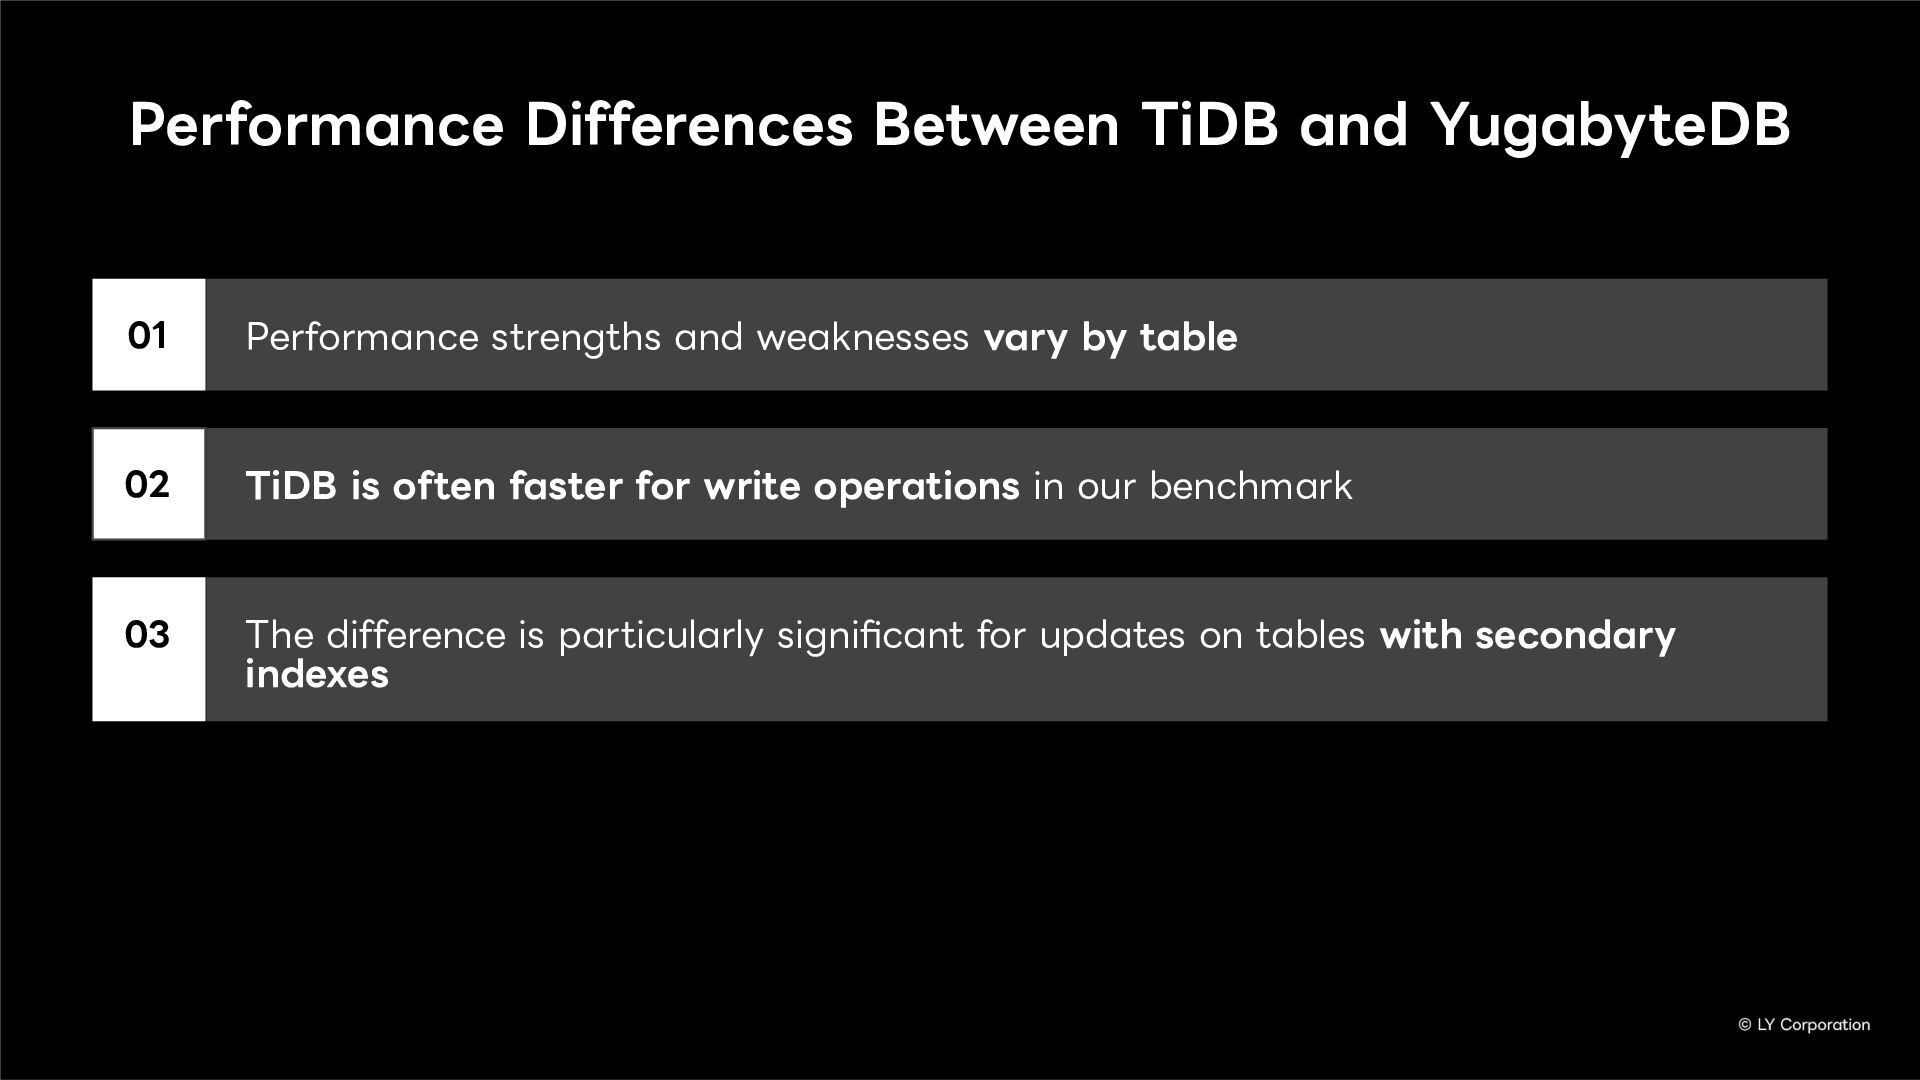
Performance strengths and weaknesses vary by table TiDB is often
faster for write operations in our benchmark The difference is particularly significant for updates on tables with secondary indexes 01 03 02 Performance Differences Between TiDB and YugabyteDB -
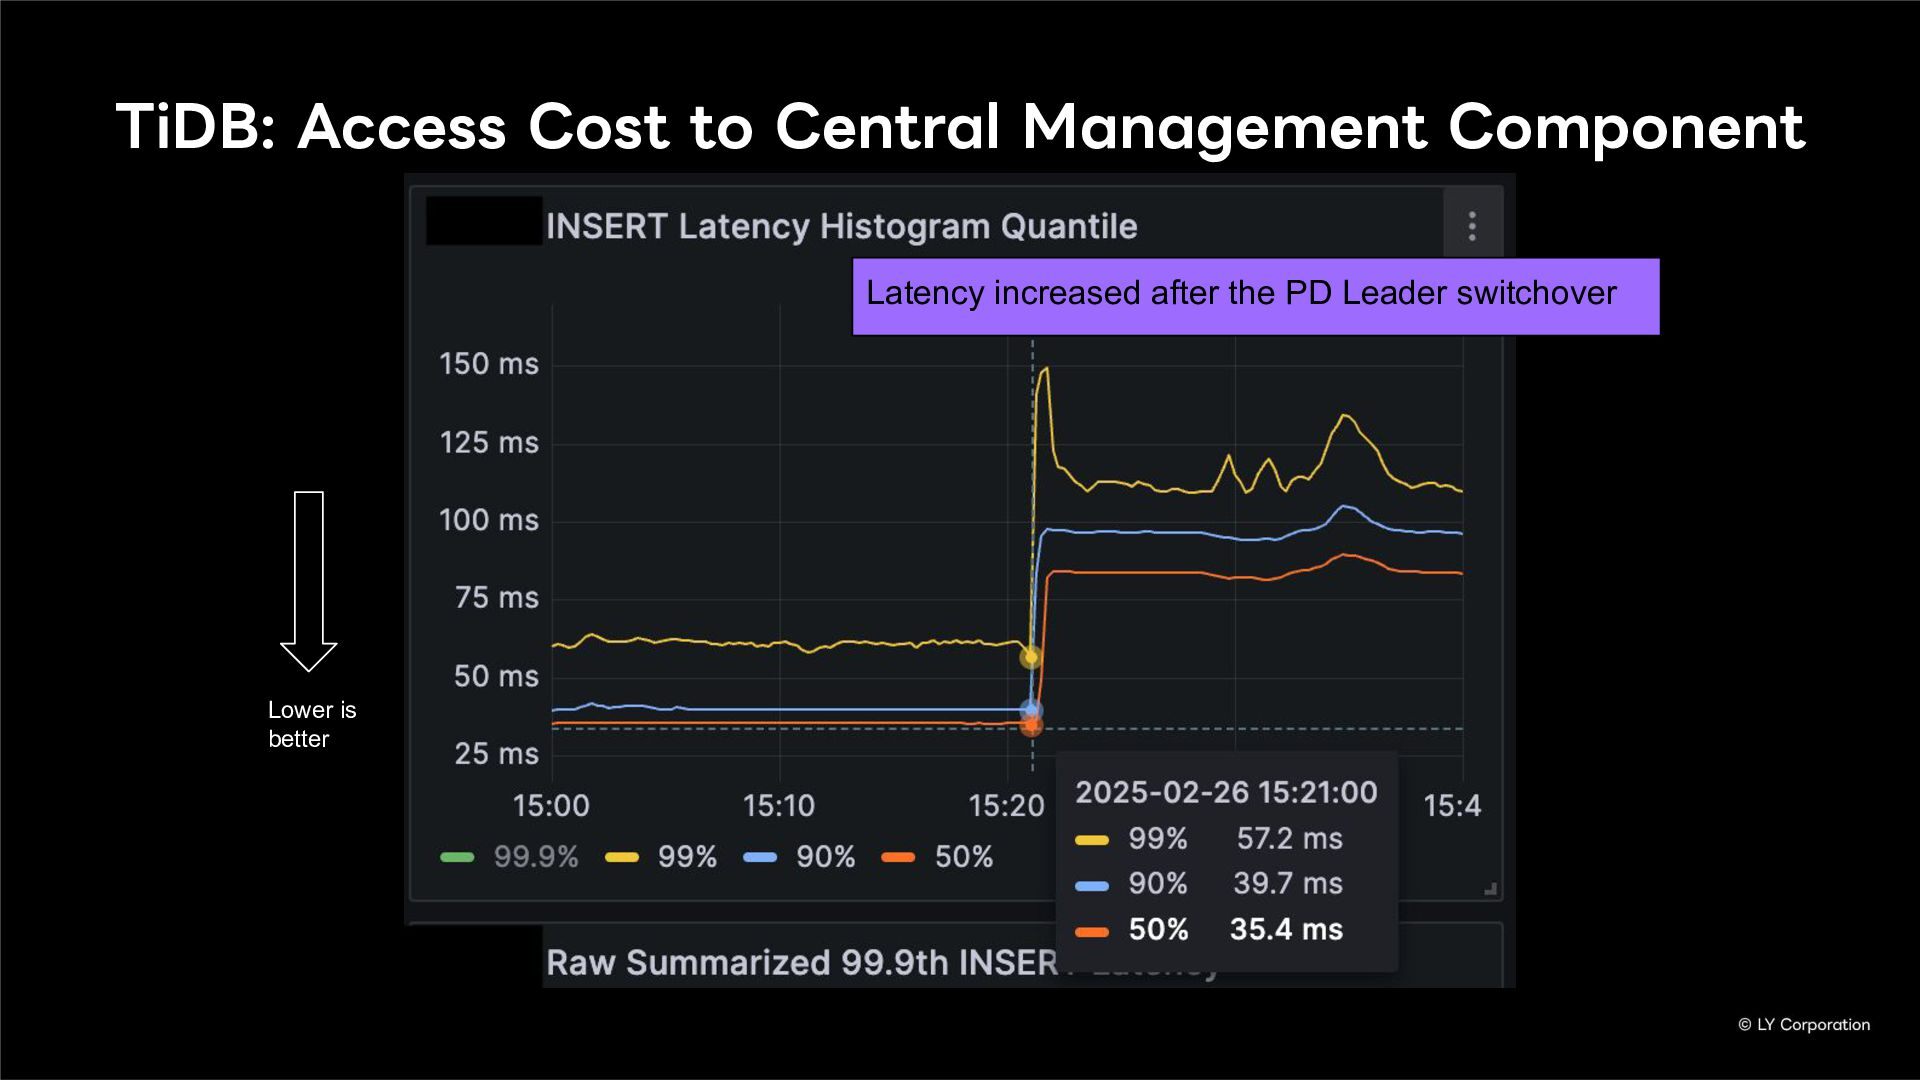
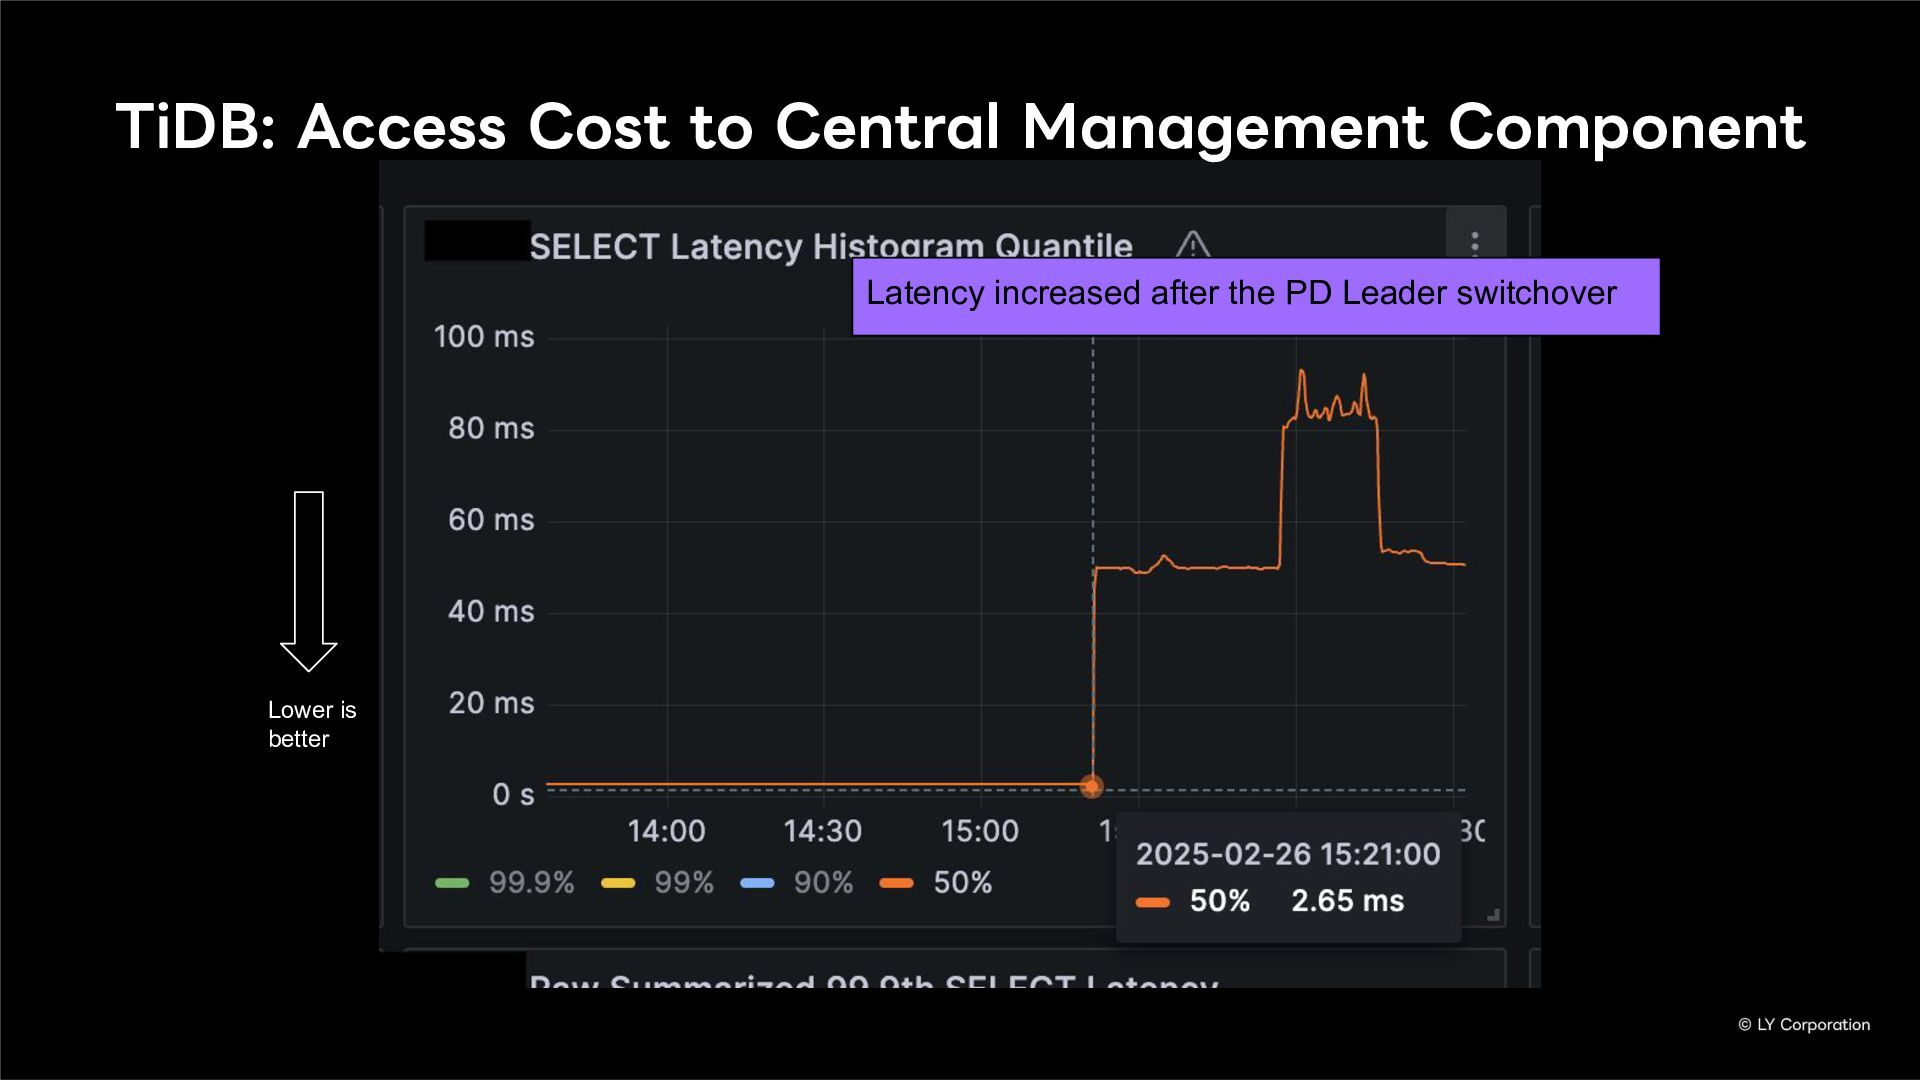
TiDB: Access Cost to Central Management Component Latency increased after
the PD Leader switchover Lower is better -
Latency increased after the PD Leader switchover TiDB: Access Cost
to Central Management Component Lower is better -
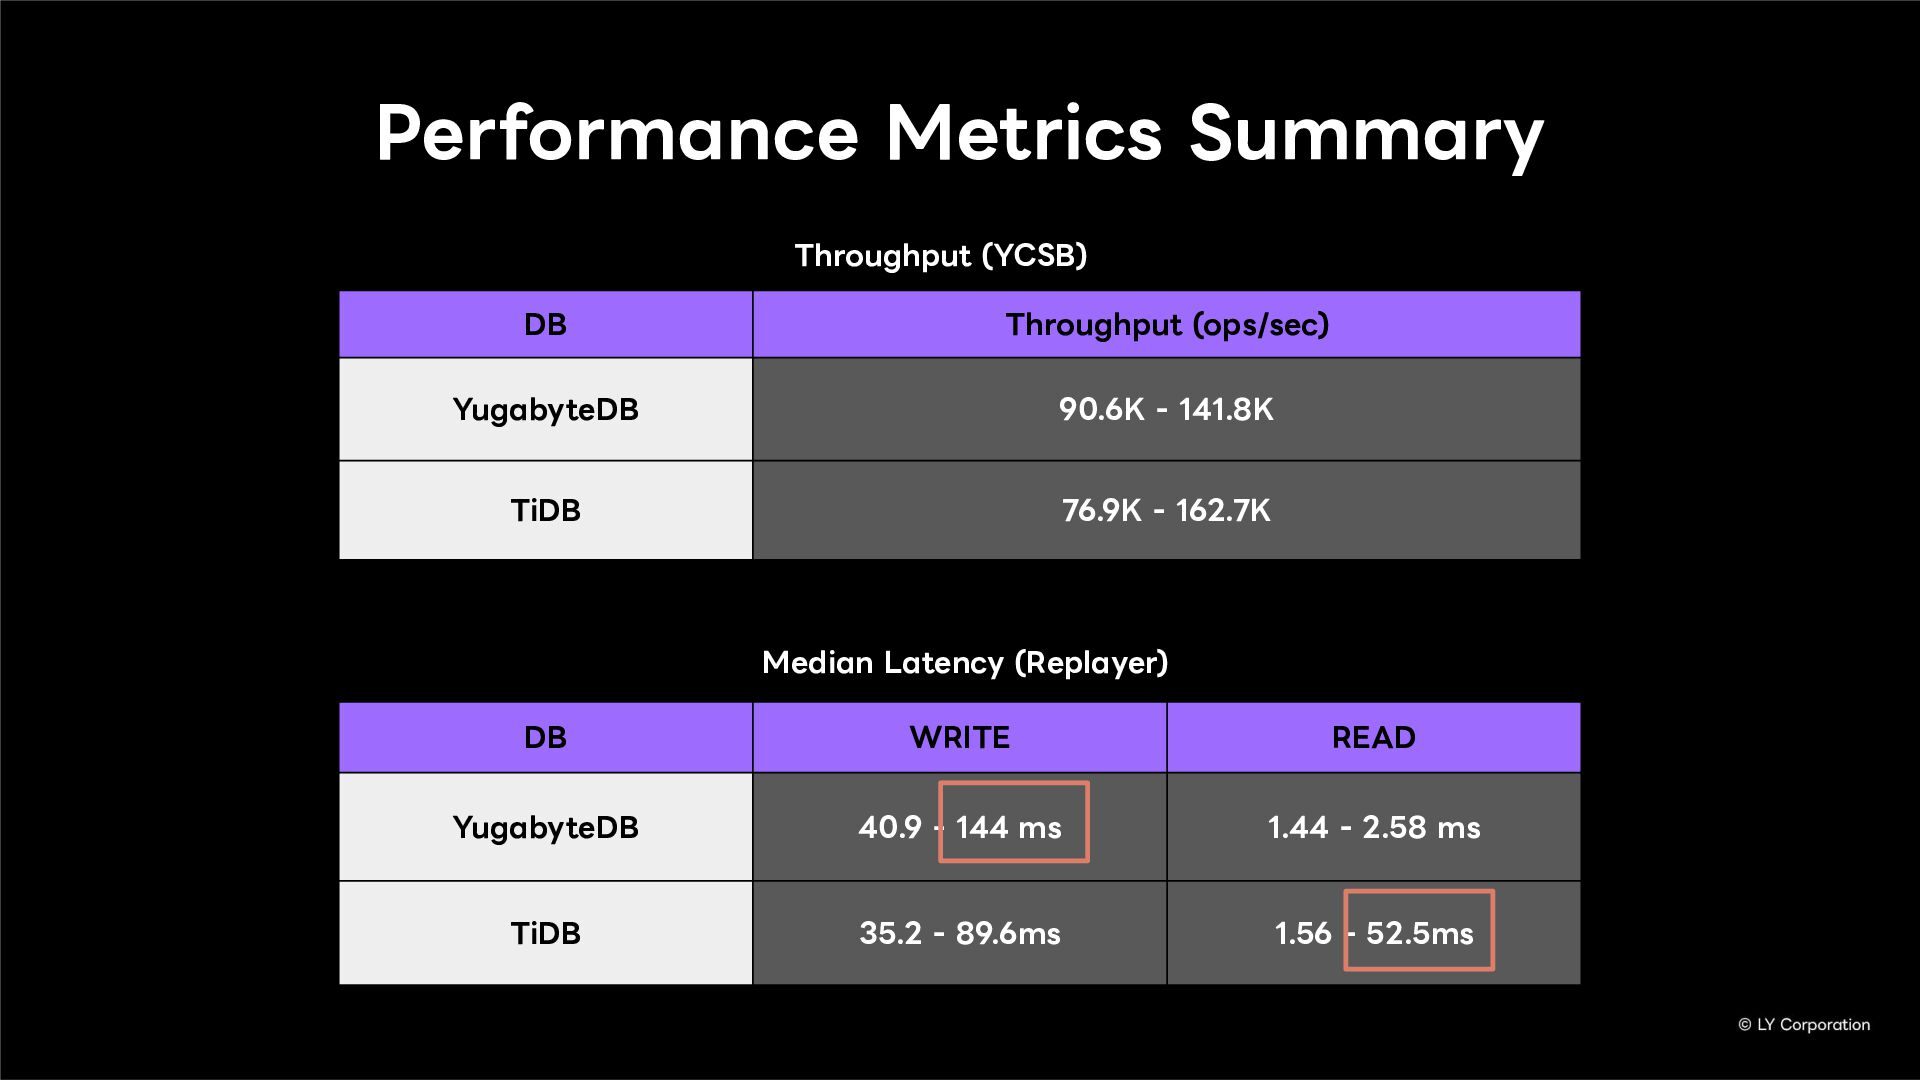
Performance Metrics Summary Median Latency (Replayer) DB WRITE READ YugabyteDB
40.9 - 144 ms 1.44 - 2.58 ms TiDB 35.2 - 89.6ms 1.56 - 52.5ms Throughput (YCSB) DB Throughput (ops/sec) YugabyteDB 90.6K - 141.8K TiDB 76.9K - 162.7K -
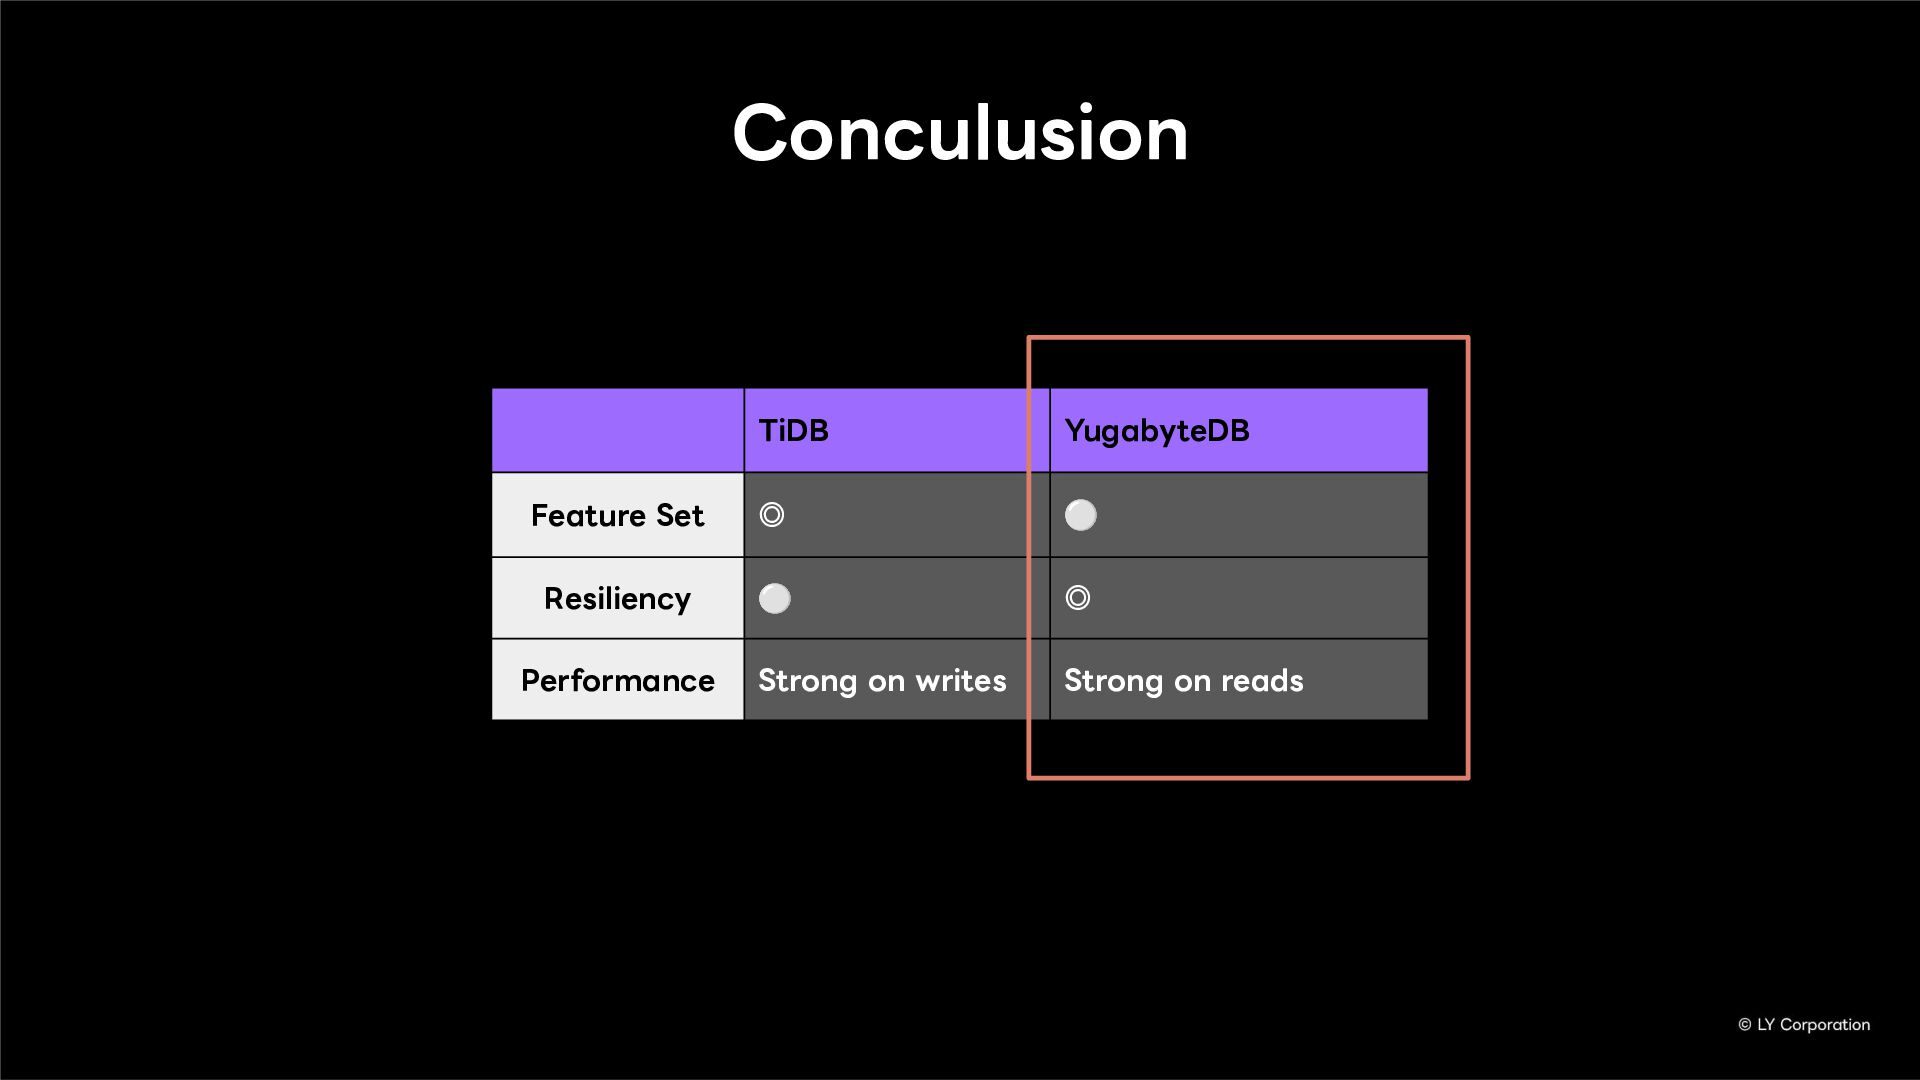
Conculusion TiDB YugabyteDB Feature Set ◎ ⚪ Resiliency ⚪ ◎
Performance Strong on writes Strong on reads -
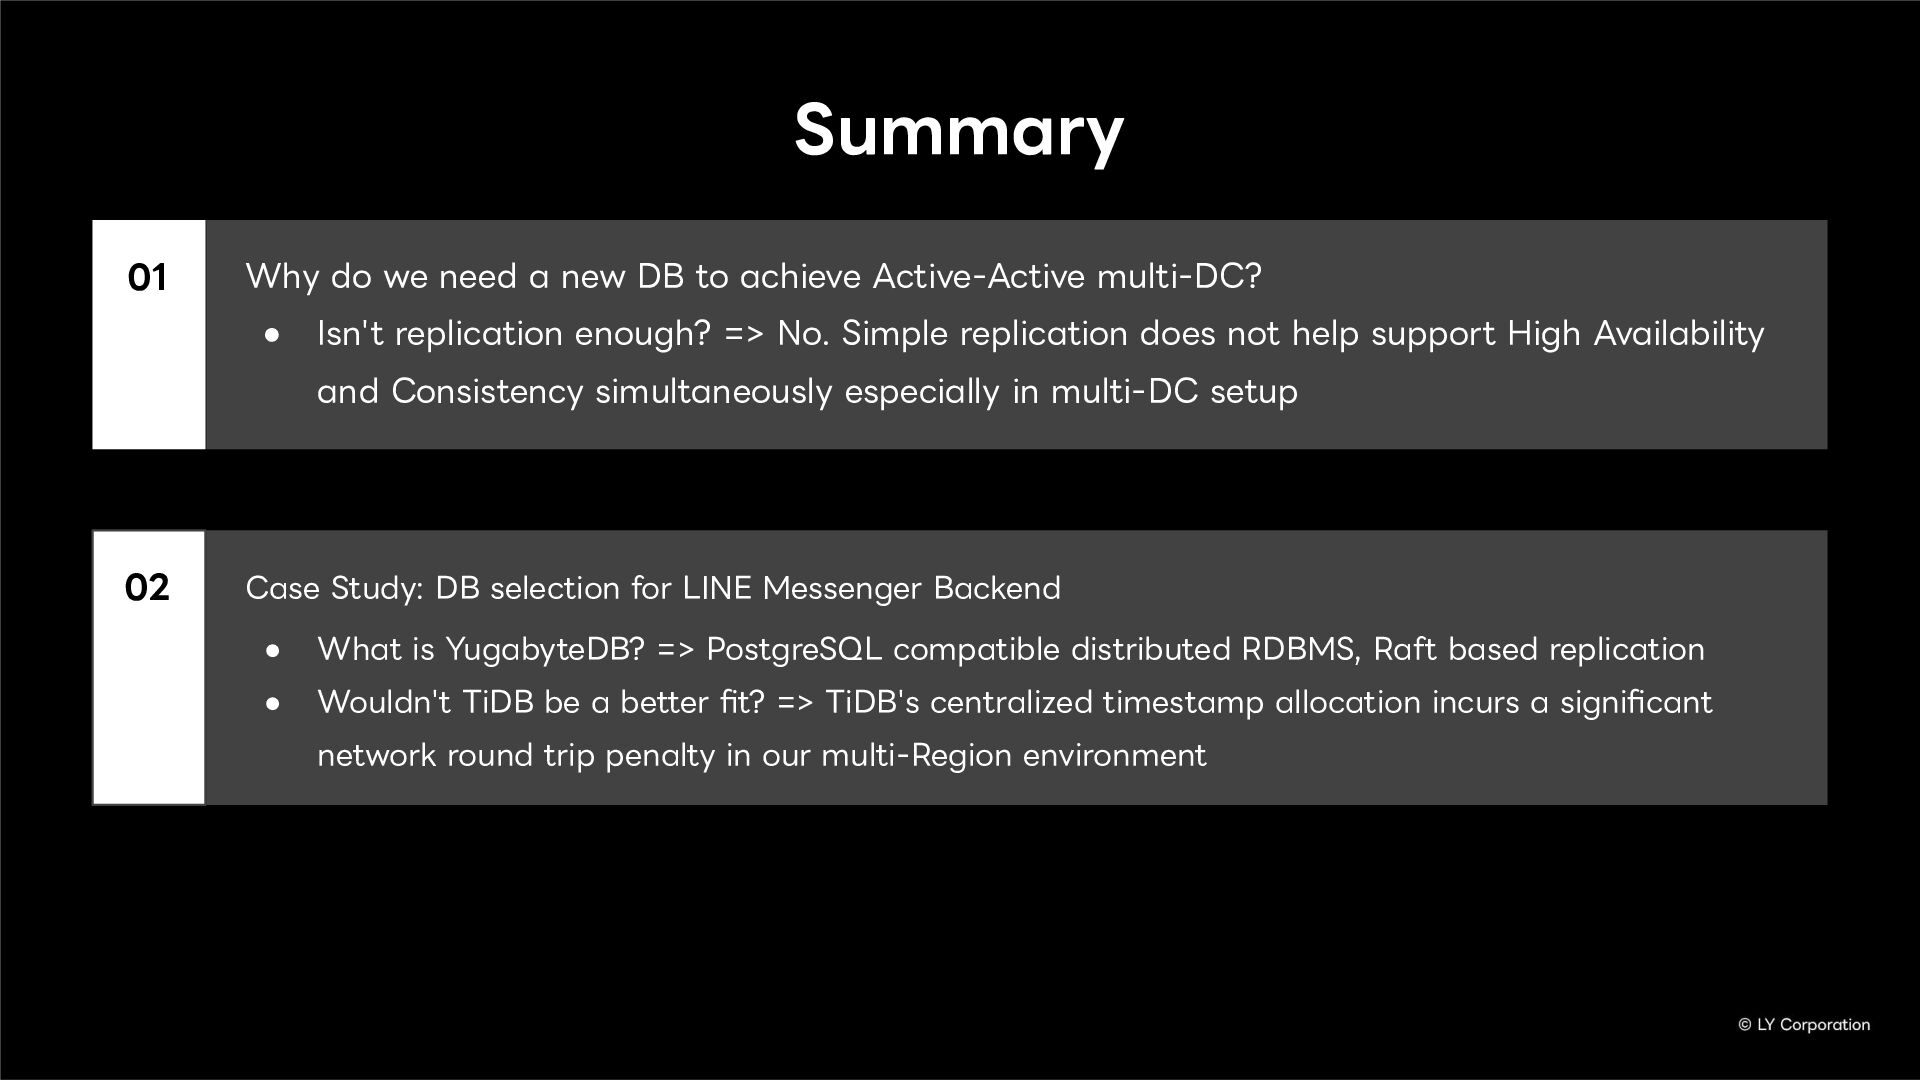
Summary Why do we need a new DB to achieve
Active-Active multi-DC? • Isn't replication enough? => No. Simple replication does not help support High Availability and Consistency simultaneously especially in multi-DC setup Case Study: DB selection for LINE Messenger Backend • What is YugabyteDB? => PostgreSQL compatible distributed RDBMS, Raft based replication • Wouldn't TiDB be a better fit? => TiDB's centralized timestamp allocation incurs a significant network round trip penalty in our multi-Region environment 01 02 -
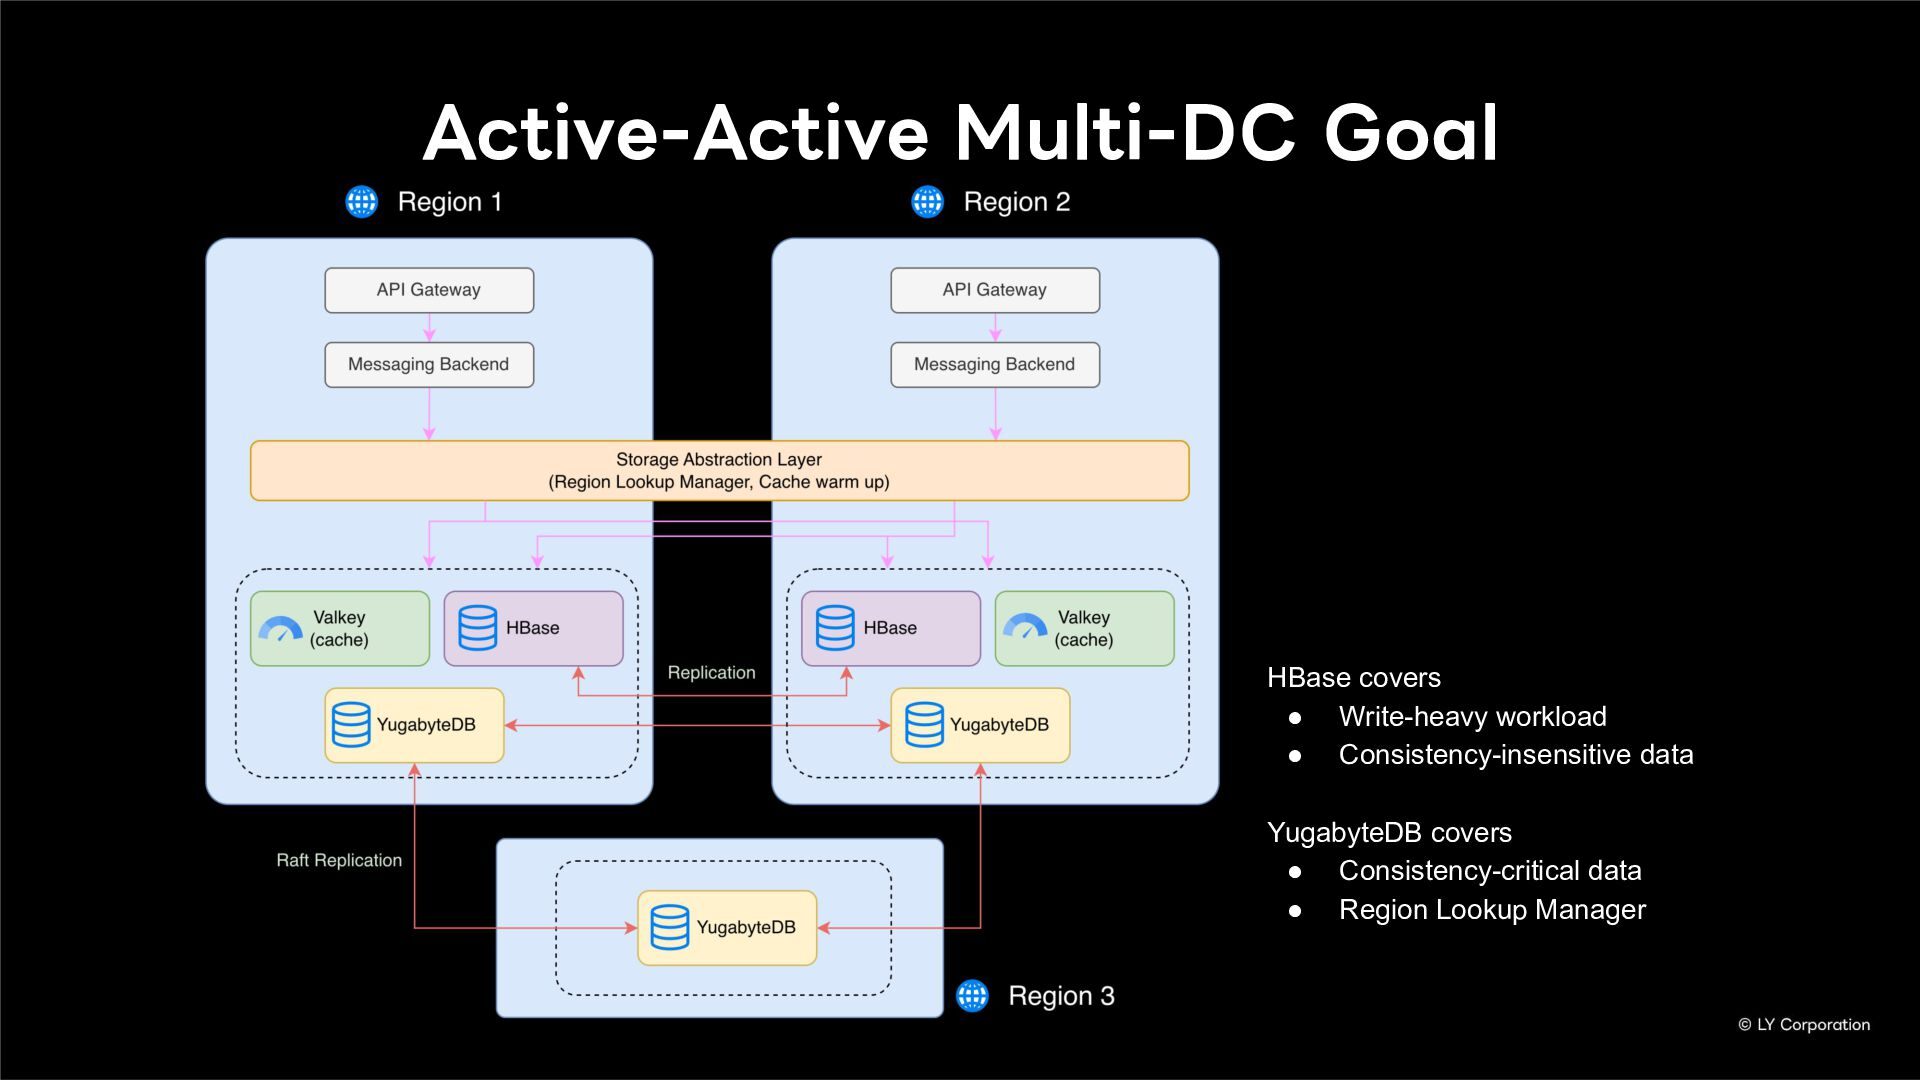
Active-Active Multi-DC Goal HBase covers • Write-heavy workload • Consistency-insensitive
data YugabyteDB covers • Consistency-critical data • Region Lookup Manager