Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
AIは公平な評価, 決断を行えるか? 〜 LLM-as-a-Judgeの限界と意思決定バイア...
Search
Neurogica
May 04, 2026
Technology
68
0
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
AIは公平な評価, 決断を行えるか? 〜 LLM-as-a-Judgeの限界と意思決定バイアス 〜 Can AI Make Fair Evaluations and Decisions?
Neurogica
May 04, 2026
More Decks by Neurogica
See All by Neurogica
MapReduceを読む - 大量データを分担する Understanding MapReduce — Distributing Large-Scale Data Processing
neurogica
0
4
Sparse Autoencoder 〜 大規模言語モデルの内部表現を読む 〜 Sparse Autoencoder: Understanding LLM's Latent Representations
neurogica
0
39
LLMは“⼼”をモデル化しているのか? Do LLMs Model the Mind?
neurogica
0
18
LLM-MAS×時系列予測 LLM-MAS × Time-Series Forecasting
neurogica
0
51
推薦タスクの整理と 時系列基盤モデル活用を考える How Recommender Systems Use Time-Series Data and Where Foundation Models Fit
neurogica
0
21
画像生成AIの生成速度の遅さと 画風のばらつきを解決する手法 Methods for Solving Image Generation AI's Slowness and Style Inconsistency
neurogica
0
24
DBコネクションプール Database Connection Pooling
neurogica
0
71
時系列基盤モデルは作れるのか? Can We Build a Foundation Model for Time Series?
neurogica
1
130
双曲空間と機械学習 〜 階層性を活かした学習〜 Hyperbolic Space and Machine Learning ~ Learning that Leverages Hierarchical Structure ~
neurogica
0
51
Other Decks in Technology
See All in Technology
AIがコードを書く時代に、エンジニアは何で自分の価値を証明するのか / In an era where AI writes code how do engineers prove their value
carta_engineering
1
780
More Freedom on the Same Shared GPU Cluster: A Small Team’s Experience with vCluster
nttcom
0
150
Kiro Crewをはじめよう
kizawa2020
1
130
組み立てて楽しむ AWS Blocks 入門
kmiya84377
0
230
OR学会2026年秋期大会_機械学習と数理最適化の融合による、配合レシピ最適化システム開発事例
brainpadpr
0
120
実体験から学ぶ分析エージェントの開発と運⽤
recruitengineers
PRO
8
1.9k
不可逆な意思決定を避けながら10億超の顧客データを AI Ready にするデータ基盤設計
baseballyama
1
280
DWH の限界突破! AI エージェント向け爆速リアルタイムデータ基盤 ClickHouse
jozono
1
360
二歩目のフロントエンド・ウェブアクセシビリティ
camiha
2
330
夫婦で子育てするための育児標準化
codmoninc
PRO
0
130
全PRの83%が AIレビューだけでマージできるようになった開発組織は その後どうなったか @2026/10
athug
0
140
Cognition AI Japan - ウェビナー2_テストQA_運用監視
cogakira
0
130
Featured
See All Featured
Raft: Consensus for Rubyists
vanstee
142
7.7k
Discover your Explorer Soul
emna__ayadi
2
1.3k
ピンチをチャンスに:未来をつくるプロダクトロードマップ #pmconf2020
aki_iinuma
128
56k
How to Build an AI Search Optimization Roadmap - Criteria and Steps to Take #SEOIRL
aleyda
1
2.2k
Context Engineering - Making Every Token Count
addyosmani
9
1.2k
The State of eCommerce SEO: How to Win in Today's Products SERPs - #SEOweek
aleyda
2
12k
Conquering PDFs: document understanding beyond plain text
inesmontani
PRO
4
3.2k
For a Future-Friendly Web
brad_frost
184
10k
No one is an island. Learnings from fostering a developers community.
thoeni
21
3.8k
How Software Deployment tools have changed in the past 20 years
geshan
2
35k
How to Ace a Technical Interview
jacobian
280
24k
Rails Girls Zürich Keynote
gr2m
96
14k
Transcript
AIは公平な評価, 決断を⾏えるか? 〜 LLM-as-a-Judgeの限界と意思決定バイアス 〜 株式会社ニューロジカ 開発部 三ツ井 智哉 AIは公平な評価,
決断を⾏えるか? 〜 LLM-as-a-Judgeの限界と意思決定バイアス 〜
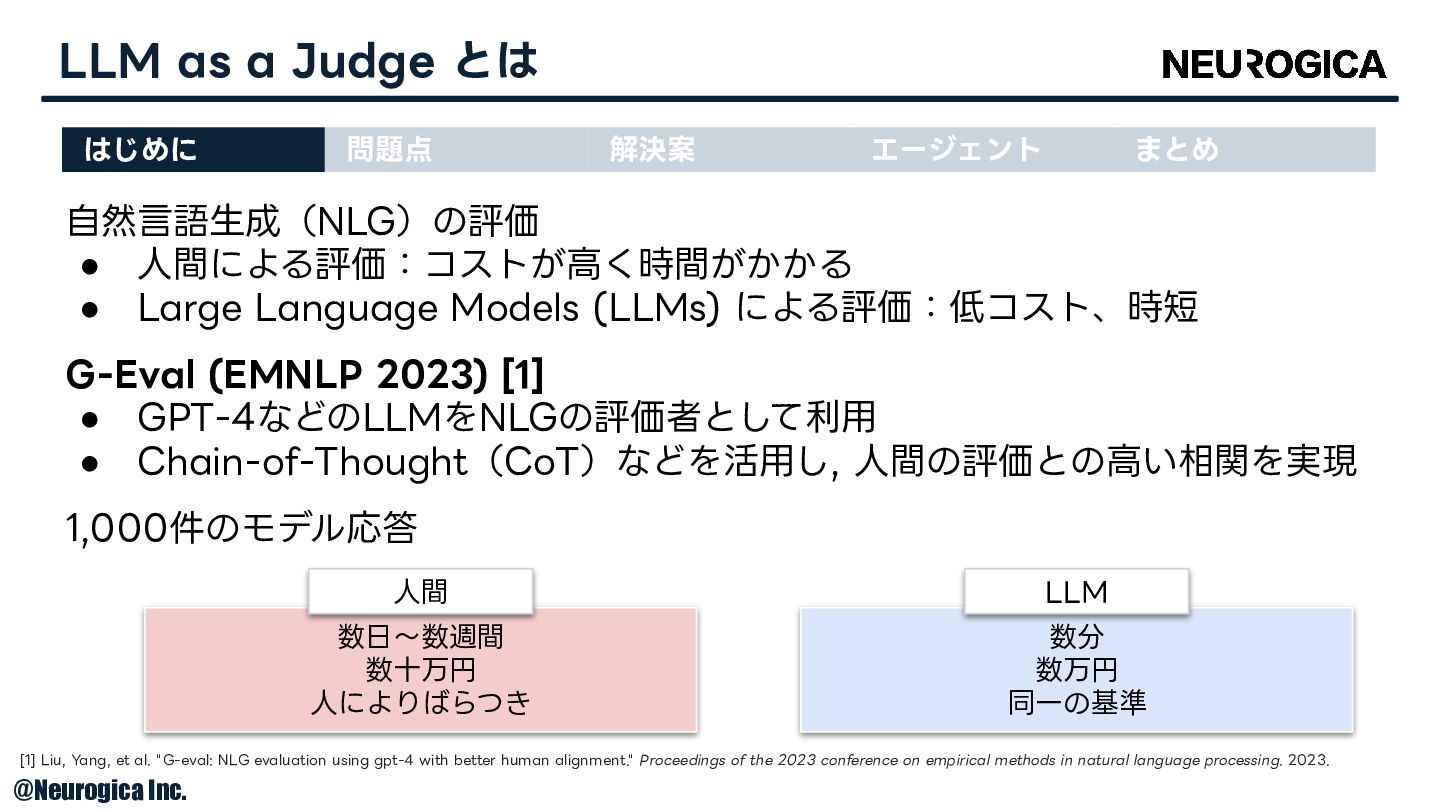
⾃然⾔語⽣成(NLG)の評価 • ⼈間による評価:コストが⾼く時間がかかる • Large Language Models (LLMs) による評価:低コスト、時短 G-Eval
(EMNLP 2023) [1] • GPT-4などのLLMをNLGの評価者として利⽤ • Chain-of-Thought(CoT)などを活⽤し, ⼈間の評価との⾼い相関を実現 1,000件のモデル応答 LLM as a Judge とは © Neurogica Inc. はじめに [1] Liu, Yang, et al. "G-eval: NLG evaluation using gpt-4 with better human alignment." Proceedings of the 2023 conference on empirical methods in natural language processing. 2023. 問題点 解決案 エージェント まとめ 数⽇〜数週間 数⼗万円 ⼈によりばらつき 数分 数万円 同⼀の基準 ⼈間 LLM
Large Language Models are not Fair Evaluators (ACL 2024) [2]
• LLMの位置バイアスの実証 • “AとB, どちらの出⼒が良いか?” という⽐較において, 選択肢の提⽰順(AとB)を⼊れ替えるだけで勝敗判定が変化 • 順番を⼊れ替えた結果を平均化する⼯夫が必要 LLM as a Judge の問題点 ① はじめに [2] Wang, Peiyi, et al. "Large language models are not fair evaluators." Proceedings of the 62nd Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers). 2024. 問題点 解決案 エージェント まとめ Which response is better? Response 1: … Response 2: … Which response is better? Response 1: … Response 2: … Response 1: … Response 2: … LLM Judge © Neurogica Inc.
Self-Preference Bias in LLM-as-a-Judge (NeurIPS 2024 Workshop) [3] • LLMは⾃⾝の⽣成物を不当に⾼く評価してしまう傾向
• モデルにとって馴染みやすい, 予測しやすい⽂章を⾼く評価 • ⽣成側と評価側のスタイルの相性が混⼊ LLM as a Judge の問題点 ② はじめに [3] Wataoka, Koki, Tsubasa Takahashi, and Ryokan Ri. "Self-Preference Bias in LLM-as-a-Judge." Neurips Safe Generative AI Workshop 2024. 問題点 解決案 エージェント まとめ © Neurogica Inc.
Pairwise or Pointwise? (COLM 2025) [4] • 評価プロトコル⾃体の違いによるバイアスの受けやすさを⽐較 • Pairwise(A/B⽐較):順番の⼊れ替えなどで評価が逆転する割合が約35%
と⾼い • Pointwise(絶対評価・スコアリング):評価のブレが約9%に留まり, より ノイズに対して頑健 問題の解決案 はじめに [4] Tripathi, Tuhina, et al. "Pairwise or Pointwise? Evaluating Feedback Protocols for Bias in LLM-Based Evaluation." Second Conference on Language Modeling., 2025 問題点 解決案 エージェント まとめ Which response is better? Response 1: … Response 2: … Scoring this response Response 1: … Pairwise Pointwise © Neurogica Inc..
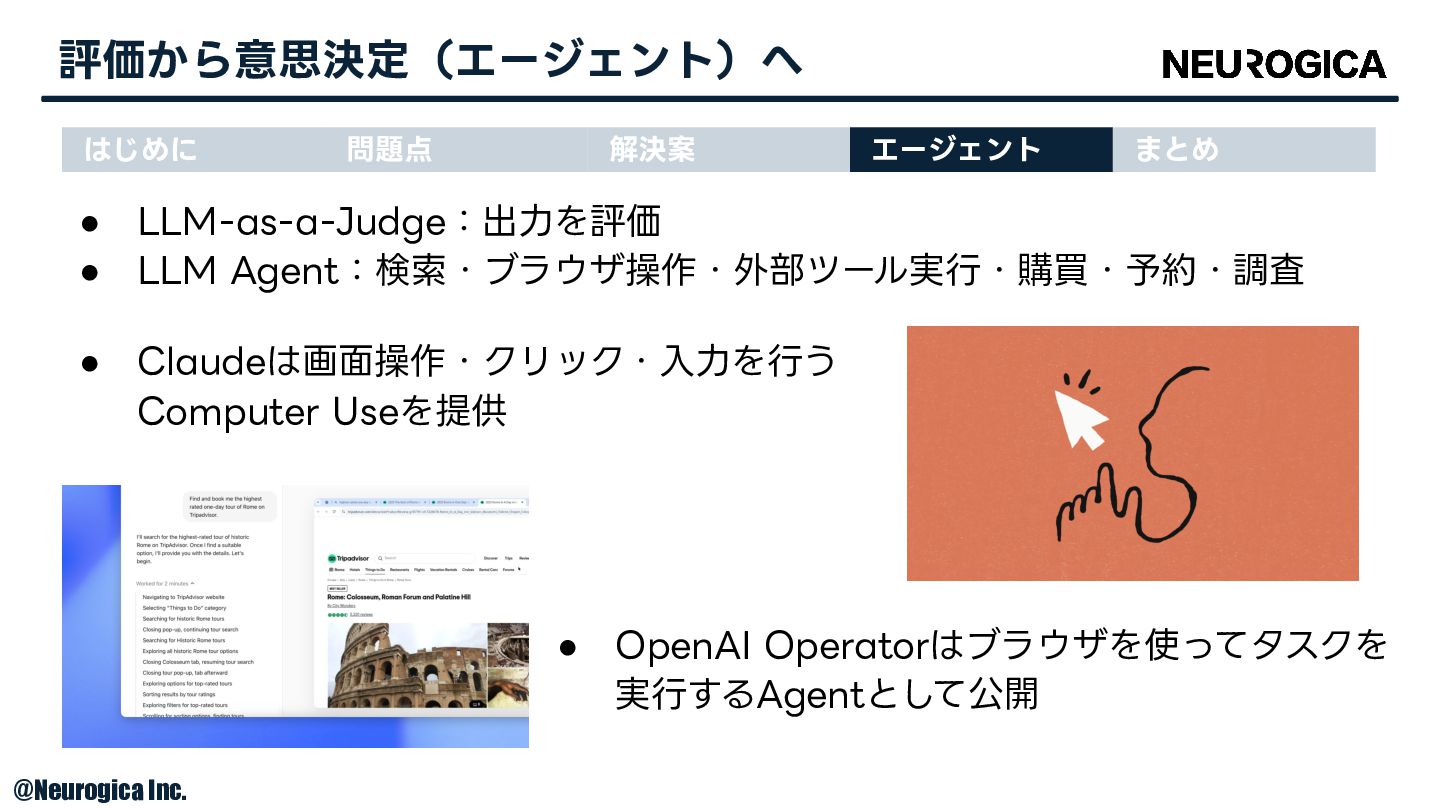
• LLM-as-a-Judge:出⼒を評価 • LLM Agent:検索・ブラウザ操作・外部ツール実⾏・購買・予約・調査 評価から意思決定(エージェント)へ はじめに 問題点 解決案 エージェント
まとめ • Claudeは画⾯操作・クリック・⼊⼒を⾏う Computer Useを提供 • OpenAI Operatorはブラウザを使ってタスクを 実⾏するAgentとして公開 © Neurogica Inc.
Actions Speak Louder than Words [5] • 差別的な回答をしないよう調整されたLLMでも, エージェントとしての意思決 定には潜在的な社会的バイアス
エージェントにおけるバイアス ① はじめに [5] Li, Yuxuan, Hirokazu Shirado, and Sauvik Das. "Actions speak louder than words: Agent decisions reveal implicit biases in language models." Proceedings of the 2025 ACM Conference on Fairness, Accountability, and Transparency. 2025. 問題点 解決案 エージェント まとめ • LLMにペルソナを与え, 避難・融資・採⽤などの 意思決定シナリオで⽐較 • ほぼすべてのシミュレー ションで有意な意思決定 格差が観測 © Neurogica Inc.
What Is Your AI Agent Buying? [6] • LLM購買エージェントについて, モデルごとの選好バ
イアスを実証 • 商品の位置, 価格, レビュー数, 広告タグの有無などに 対する感応度がモデルごと, 世代ごとに異なる. エージェントにおけるバイアス ② はじめに [6] Allouah, Amine, et al. "What Is Your AI Agent Buying? Evaluation, Biases, Model Dependence, & Emerging Implications of Agentic E-Commerce." Proceedings of the ACM Web Conference 2026. 問題点 解決案 エージェント まとめ ←位置バイアスを⽰す タグや評価による→ 影響を⽰す © Neurogica Inc.
まとめ はじめに 問題点 解決案 エージェント まとめ LLM評価の問題 • 選択肢の順番にバイア スが存在
• 評価するモデルと同じ モデルの⽣成物を⾼く 評価 エージェントへの進化 • テキスト評価だけでな く操作, 意思決定も • LLMの意思決定にもバ イアスが存在 © Neurogica Inc.. LLM as a Judge ⼈間と近い評価を⼈間よりは るかに短時間低コストで実⾏ 可能


 neurogica
 carta_engineering
 nttcom
 kizawa2020
 kmiya84377
 brainpadpr
 recruitengineers
 baseballyama
 jozono
 camiha
 codmoninc
 athug
 cogakira
 vanstee
 emna__ayadi
 aki_iinuma
 aleyda
 addyosmani
 inesmontani
 brad_frost
 thoeni
 geshan
 jacobian
 gr2m