(Availability, Query Performance, Data Freshness ) for a multi-tenant, cross datacenter search architecture based on solrcloud • Scaling issues related to Query Performance: ▪ Inability to auto scale solr serving with increasing index sizes ▪ Dynamic Shard Setup based on index size • SLA issues due to Availability: ▪ Nightmare to do manipulate cluster/collection setup with expanding clusters and frequent node replacements (AWS issues) ▪ Flexible Replica Allocation based on custom strategies to guarantee 99.995% availability • Data Freshness (aka Indexing Performance) hiccups: ▪ Break the tight coupling between Indexing and Serving latency (Tp 95) SLAs • Build a generic framework that can be contributed back to the solr community Rebalance API was envisioned and implemented to alleviate these issues and offer fine grained SLA management for solrcloud
Management for SolrCloud • Forms the basis for Solr Auto Scale • 2 levels of abstraction • Scaling Strategies ◦ Aid with shard, replica and cluster manipulation techniques to guarantee SLA ◦ Zero Downtime operations ◦ Tunable for Availability, Performance or Cost • Allocation Strategies ◦ Decides Core Placement ◦ Tunable for Availability, Performance or Cost
Per shard latency goes up • Tp 95 shoots up • No way to change shards dynamically • Delete, Recreate, Re-index • Availability goes down Default Solr Behavior
of destination shards. (e.g can help with reducing latency) • Includes re-distributing the index and configs consistently. • Zero downtime - No query failures • Avoiding any heavy re-indexing processes. • Can be size based as well • API Call: /admin/collections?action=REBALANCE &scaling_strategy=AUTO_SHARD &collection=collection_name&num_shards=number of shards &size_cap=1G &allocation_strategy=least_used
documents from all shards - Lucene library based • Split the merged shard into desired number • Auto Zk update for shard ranges • Heavyweight but works • Based on size, could take in 20-30 of minutes to complete
Identify minimum number of splits • Split shards in parallel to required desired setup • Relatively high performance ◦ 2 Tb index from 2 to 4 shards - 2.5 mins • Auto Zk Update
node - Does nothing • No Redistribution of solr cores • Machines running out of disk space - heavier collections need to be moved out • Problem amplifies at large scale - 100s of nodes, 1000s of collections • Manual Management of core placement - Nightmare Default Solr Behavior
• Desired Core placement computation - External or Trigger based • Migration of cores within the cluster • Knobs to control min/max to reduce cluster load • Zero downtime - No query failures and resiliency to node failures • API Call: /admin/collections?action=REBALANCE&scalin g_strategy=REDISTRIBUTE
die, need to be replaced, decommissioned • Default behavior - Do nothing • Can cause downtime - Heavy cores on the nodes • Problem exacerbated with 1000s of nodes/collections Default Solr Behavior
Topology of cluster • Migrate replicas from node about to die to new node • Zero downtime • API Call: ◦ /admin/collections?action=REBALANCE&scaling_strategy=REPLACE &collection=collectionName&source_node=source_host &dest_node=dest_host
the indexing (parallelism) • Faster indexing - Data Freshness SLA • Solr - # shards is the same for indexing vs serving • Shard setup - tweaked for serving query performance • E.g. ◦ Indexing 100M docs in 2 shards - 2 hours ◦ Serving 100M docs in 2 shards - Tp 95 < 100 ms
Indexing shard setup vs serving • More shards for indexing - Merged into lesser shards for serving • Post Indexing issue API to merge into serving collection • API Call: ◦ /admin/collections?action=Rebalance&scaling_strategy=SMART_MERGE_DISTRIBUTED&collection=collectionN ame&num_shards=numRequiredShards • Parallel Merge • Zero downtime
vs Serving has different collections • Indexed Collection merged into Serving - Using smart merge call • Indexing can be tuned independently for performance • Serving SLA unaffected
placement methodology and heart of Solr Auto Scale • Least Used Strategy - Pick the node that has the least amount of cores • AZ aware Strategy - Pick the node that is in a different availability zone than the other cores for a given collection • Unused Strategy - Pick the node that does not have any cores for a given collection • All of them are compatible with all scaling strategies
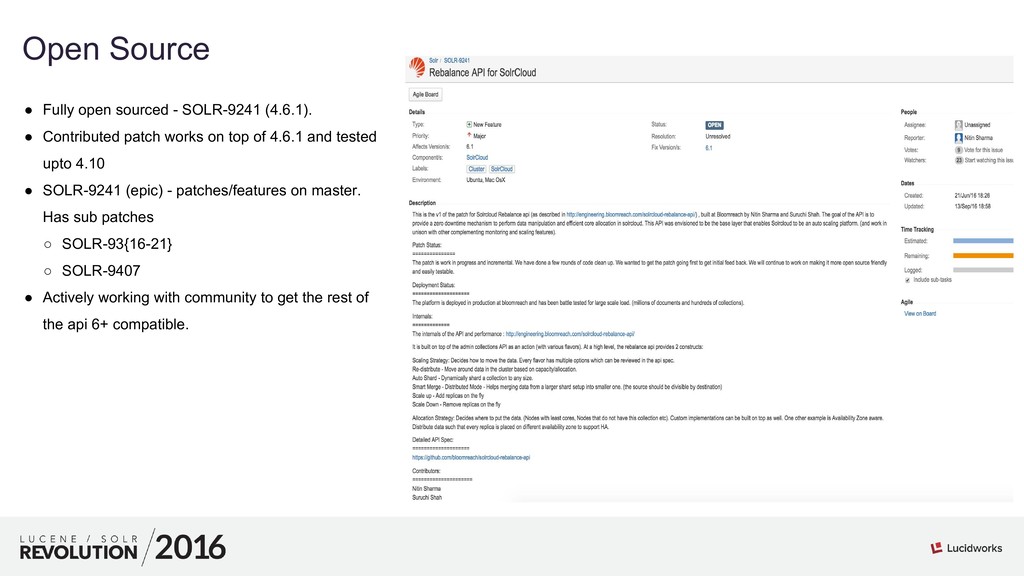
SOLR-9241 (4.6.1). • Contributed patch works on top of 4.6.1 and tested upto 4.10 • SOLR-9241 (epic) - patches/features on master. Has sub patches ◦ SOLR-93{16-21} ◦ SOLR-9407 • Actively working with community to get the rest of the api 6+ compatible.
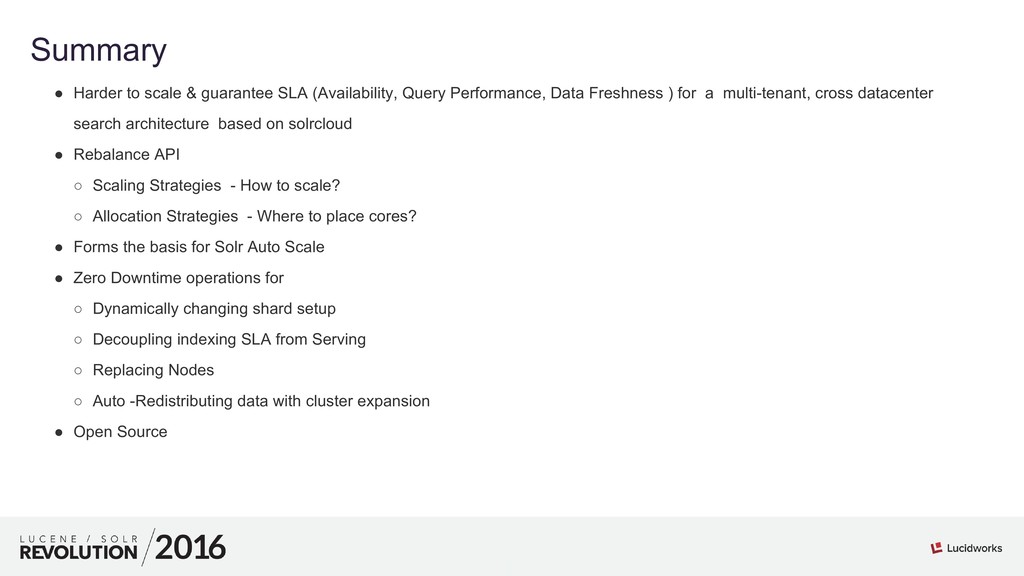
SLA (Availability, Query Performance, Data Freshness ) for a multi-tenant, cross datacenter search architecture based on solrcloud • Rebalance API ◦ Scaling Strategies - How to scale? ◦ Allocation Strategies - Where to place cores? • Forms the basis for Solr Auto Scale • Zero Downtime operations for ◦ Dynamically changing shard setup ◦ Decoupling indexing SLA from Serving ◦ Replacing Nodes ◦ Auto -Redistributing data with cluster expansion • Open Source


 nitingithub
 teamlab
 recruitengineers
 kworkdev
 greenmidori
 jtakeda
 pfn
 oikon48
 yahonda
 satomasahiro2005
 yu23ki14
 kentarofujii
 lcolladotor
 inesmontani
 bkeepers
 tessaabrams
 popppiees
 aleyda
 jmmastey
 tamaranovitovic
 coloredviolet
 axbom
 jacobtomlinson