Upgrade to Pro — share decks privately, control downloads, hide ads and more …

Netflix ML Recommendations Fact Store - Spark ...

Sponsored · Ship Features Fearlessly Turn features on and off without deploys. Used by thousands of Ruby developers. →

Netflix ML Recommendations Fact Store - Spark Summit 2018

Netflix ML Recommendations Fact Store - Spark Summit 2018

Avatar for Nitin S

Nitin S

June 06, 2018

More Decks by Nitin S

Other Decks in Technology

Transcript

  1. #DevSAIS11 Recommendations at Netflix • Personalized Homepage for each member

    ◦ Goal: Quickly help members find content they’d like to watch ◦ Risk: Member may lose interest and abandon the service ◦ Challenge: Recommendations at Scale
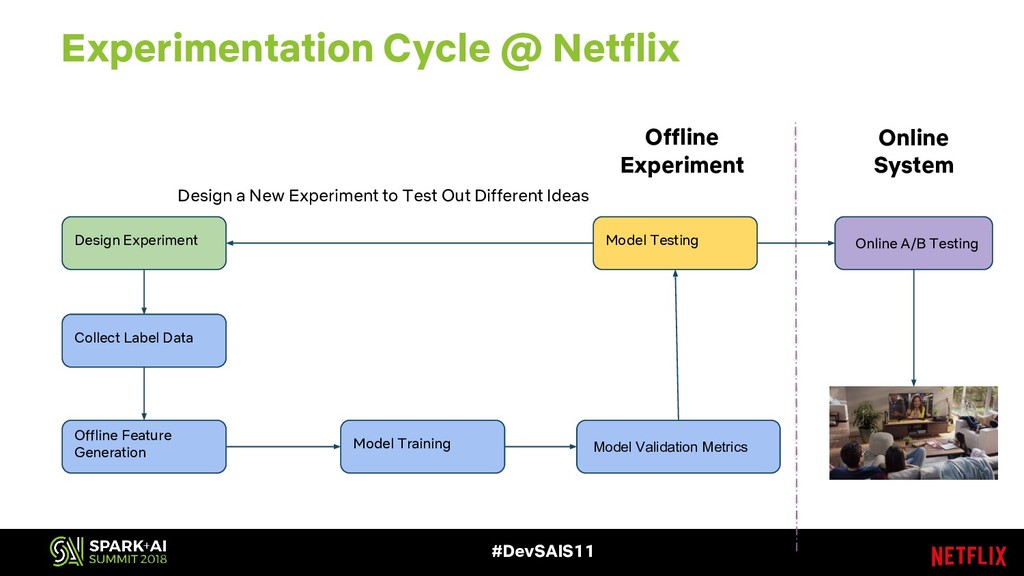
  2. #DevSAIS11 Experimentation Cycle @ Netflix Design a New Experiment to

    Test Out Different Ideas Offline Experiment Online System Design Experiment Model Testing Collect Label Data Offline Feature Generation Model Training Model Validation Metrics Online A/B Testing
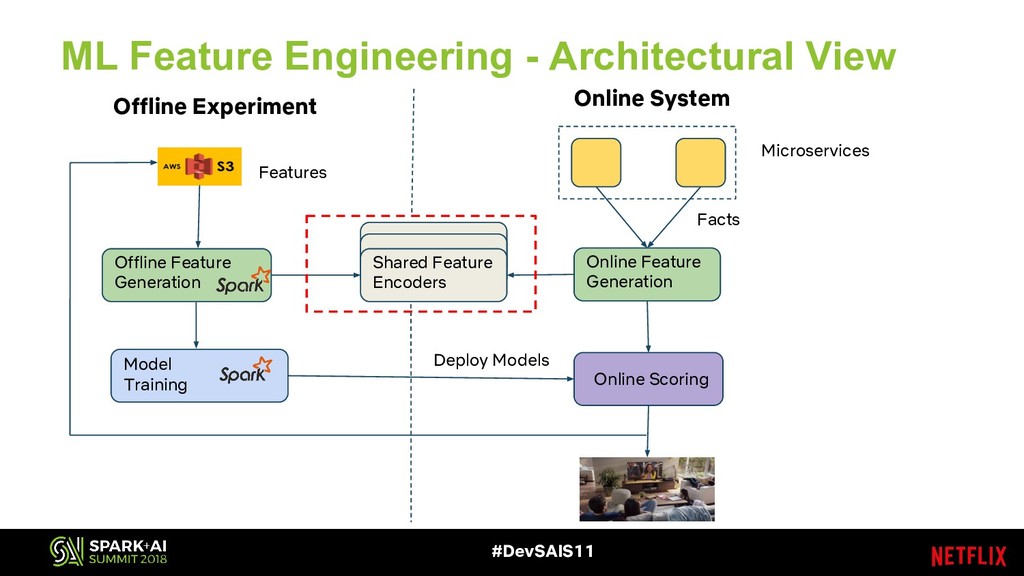
  3. #DevSAIS11 ML Feature Engineering - Architectural View Online Feature Generation

    Microservices Online Scoring Offline Feature Generation Shared Feature Encoders Model Training Deploy Models Online System Offline Experiment Features Facts
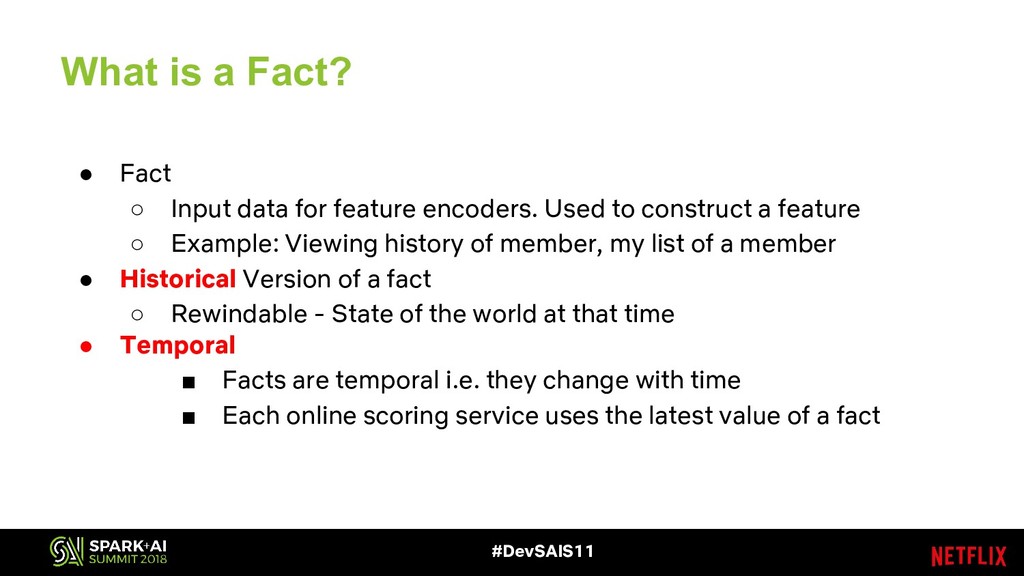
  4. #DevSAIS11 What is a Fact? • Fact ◦ Input data

    for feature encoders. Used to construct a feature ◦ Example: Viewing history of member, my list of a member • Historical Version of a fact ◦ Rewindable - State of the world at that time • Temporal ▪ Facts are temporal i.e. they change with time ▪ Each online scoring service uses the latest value of a fact
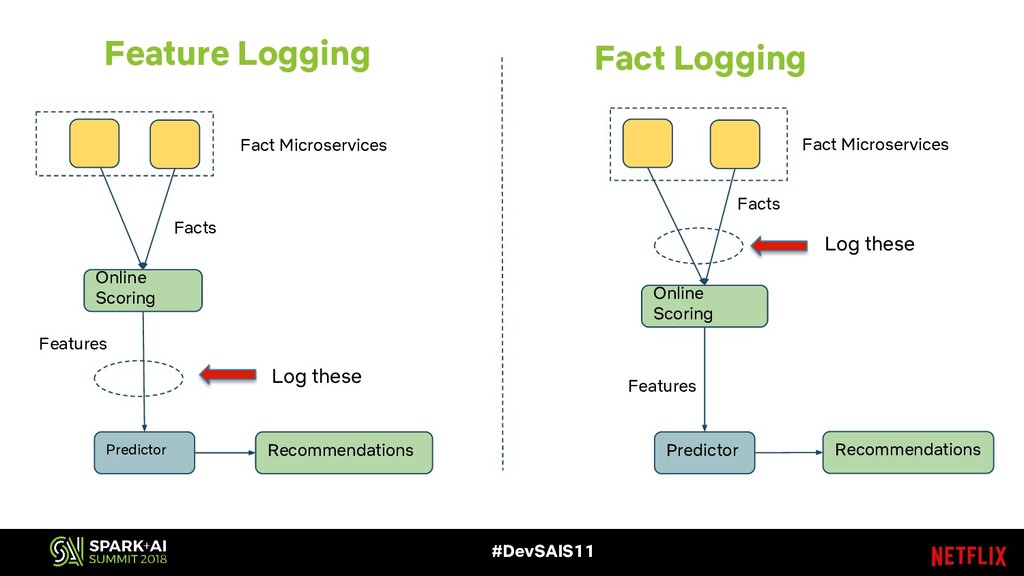
  5. #DevSAIS11 Online Scoring Predictor Fact Microservices Features Facts Log these

    Online Scoring Predictor Fact Microservices Features Facts Log these Recommendations Recommendations Feature Logging Fact Logging
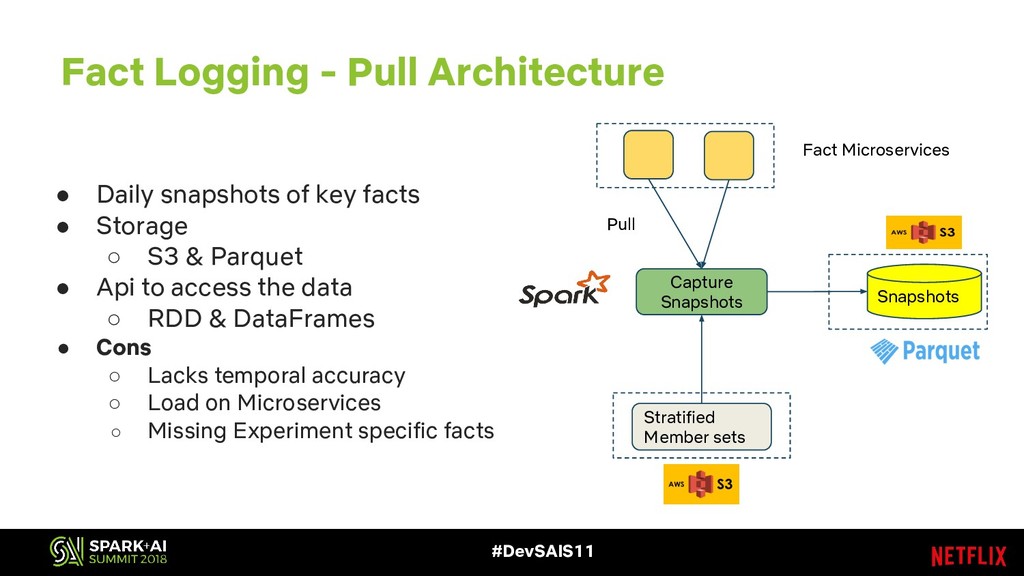
  6. #DevSAIS11 Fact Logging - Pull Architecture Pull • Daily snapshots

    of key facts • Storage ◦ S3 & Parquet • Api to access the data ◦ RDD & DataFrames • Cons ◦ Lacks temporal accuracy ◦ Load on Microservices ◦ Missing Experiment specific facts Capture Snapshots Fact Microservices Stratified Member sets Snapshots
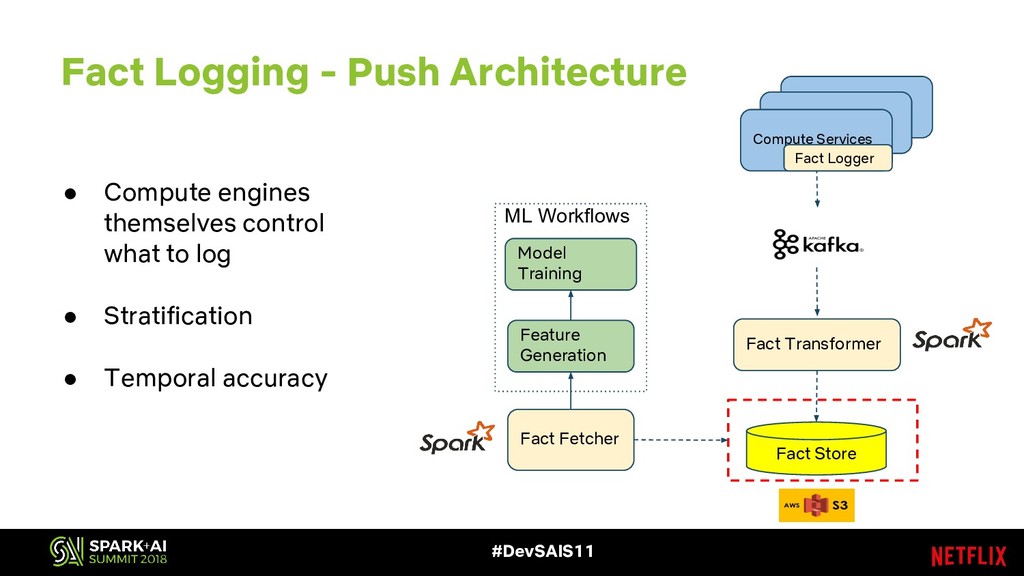
  7. #DevSAIS11 Fact Logging - Push Architecture • Compute engines themselves

    control what to log • Stratification • Temporal accuracy Compute Services Fact Store Fact Transformer Fact Fetcher Fact Logger ML Workflows Feature Generation Model Training
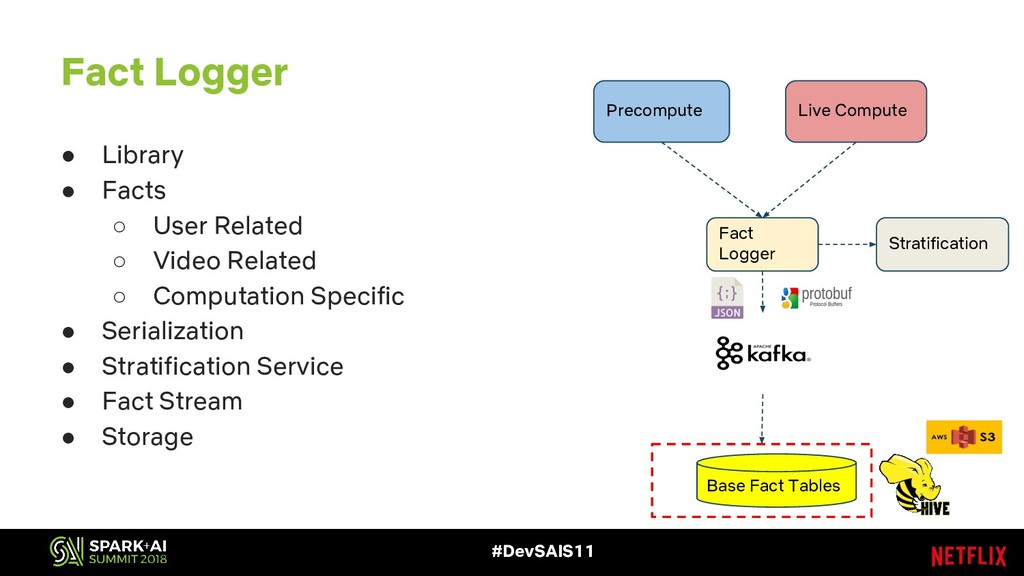
  8. #DevSAIS11 Fact Logger Precompute Live Compute Fact Logger • Library

    • Facts ◦ User Related ◦ Video Related ◦ Computation Specific • Serialization • Stratification Service • Fact Stream • Storage Base Fact Tables Stratification
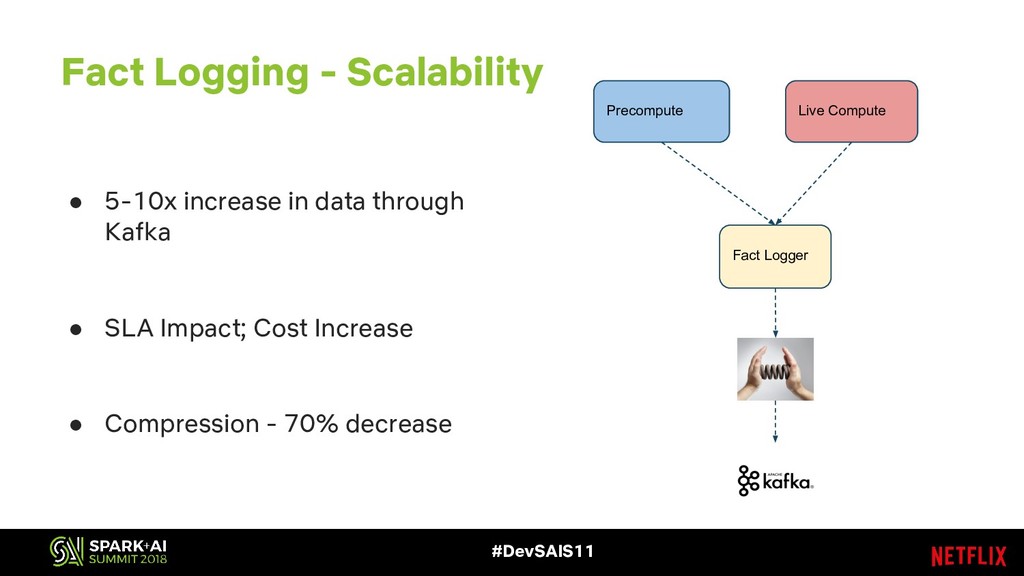
  9. #DevSAIS11 Fact Logging - Scalability Precompute Live Compute Fact Logger

    • 5-10x increase in data through Kafka • SLA Impact; Cost Increase • Compression - 70% decrease
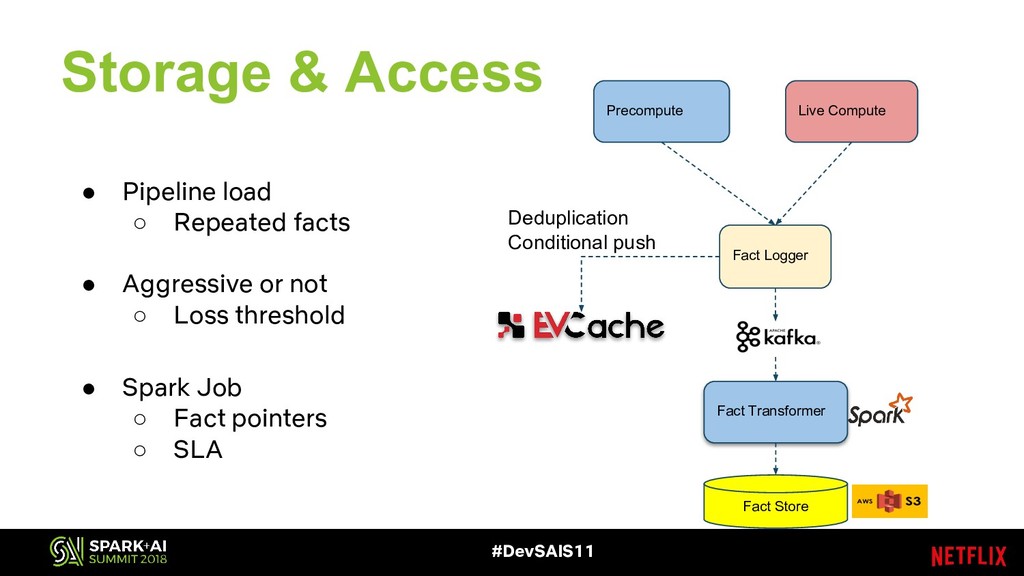
  10. Storage & Access Fact Store Fact Transformer Deduplication Precompute Live

    Compute Fact Logger • Pipeline load ◦ Repeated facts • Aggressive or not ◦ Loss threshold Conditional push • Spark Job ◦ Fact pointers ◦ SLA #DevSAIS11
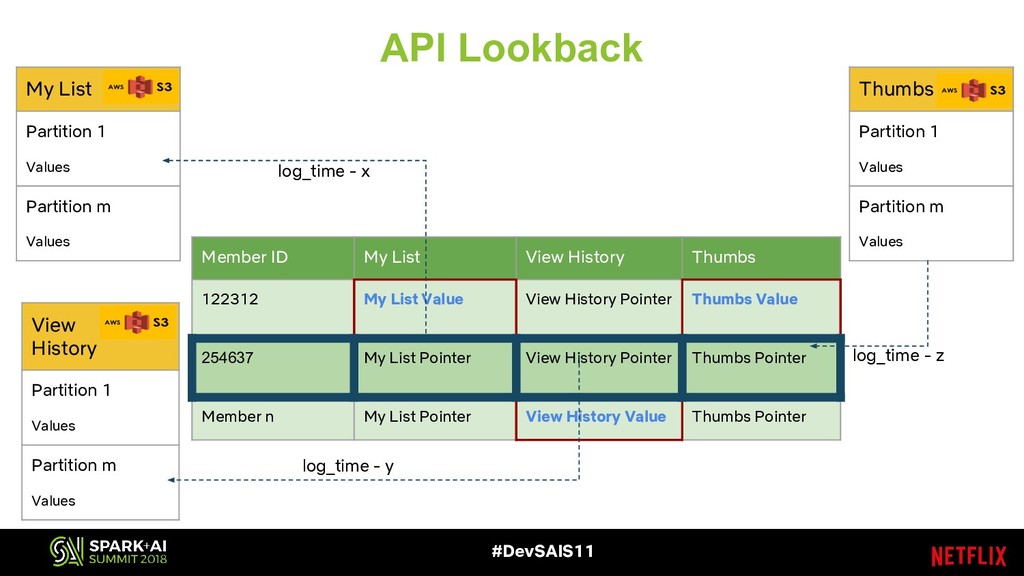
  11. #DevSAIS11 API Lookback Member ID My List View History Thumbs

    122312 My List Value View History Pointer Thumbs Value 254637 My List Pointer View History Pointer Thumbs Pointer Member n My List Pointer View History Value Thumbs Pointer My List Partition 1 Values Partition m Values View History Partition 1 Values Partition m Values Thumbs Partition 1 Values Partition m Values log_time - x log_time - y log_time - z
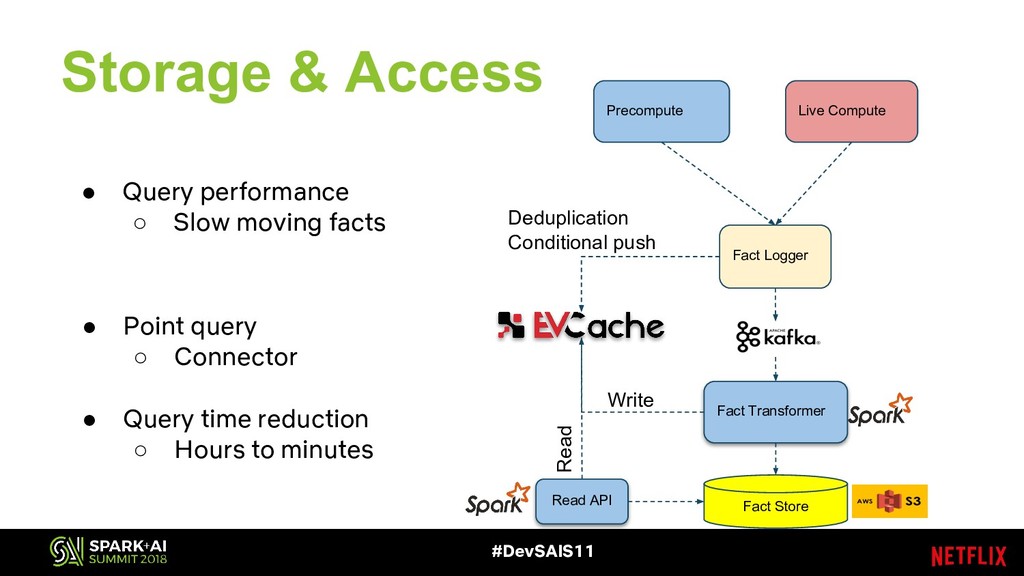
  12. Storage & Access Fact Store Fact Transformer Read API Precompute

    Live Compute Fact Logger • Query performance ◦ Slow moving facts • Point query ◦ Connector • Query time reduction ◦ Hours to minutes Deduplication Conditional push Write Read #DevSAIS11
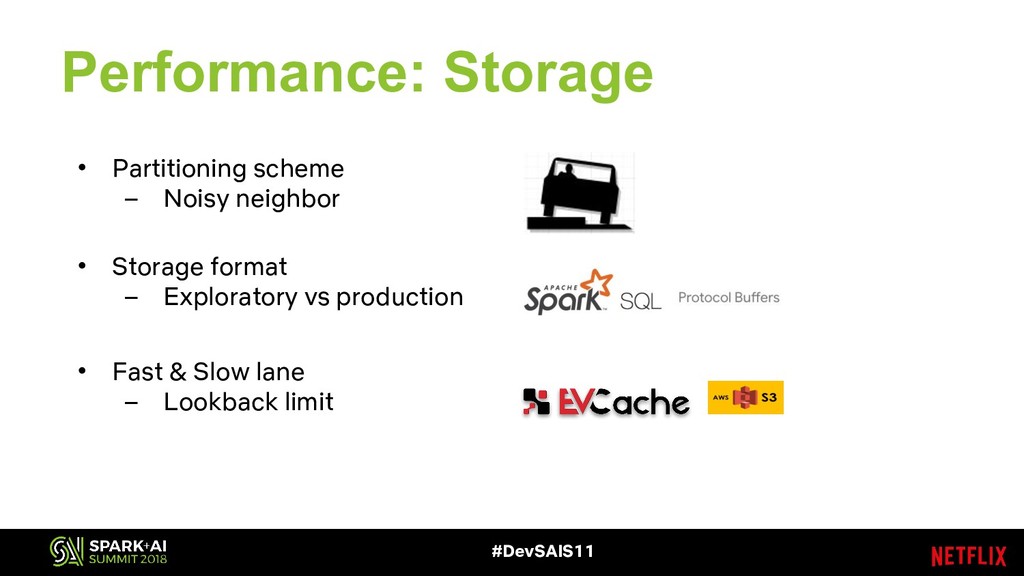
  13. Performance: Storage • Partitioning scheme – Noisy neighbor • Storage

    format – Exploratory vs production • Fast & Slow lane – Lookback limit #DevSAIS11
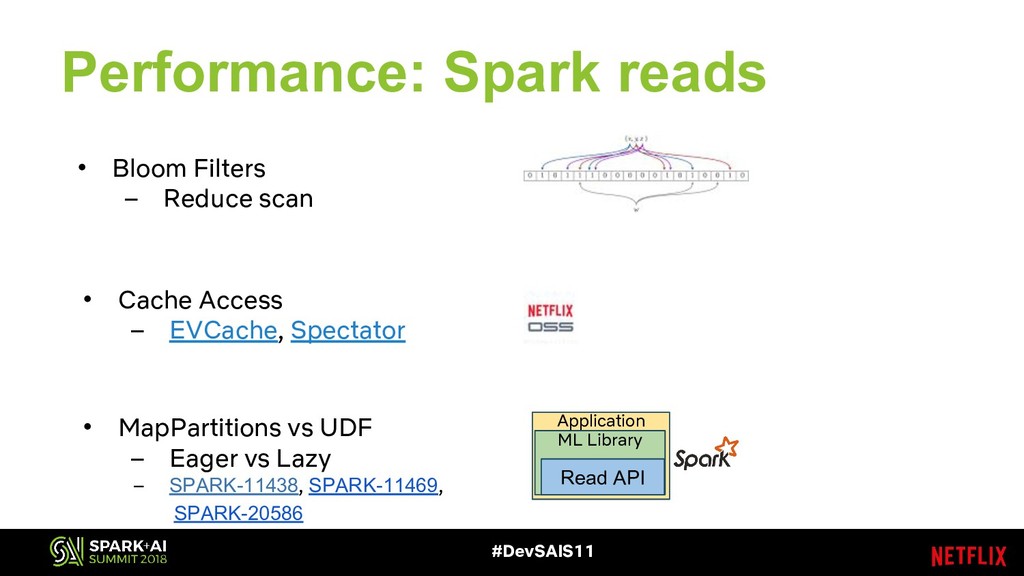
  14. Performance: Spark reads • Bloom Filters – Reduce scan •

    Cache Access – EVCache, Spectator • MapPartitions vs UDF – Eager vs Lazy – SPARK-11438, SPARK-11469, SPARK-20586 Application ML Library Read API #DevSAIS11
  15. Future Work • Structured with schema evolution – Best of

    both (POJO & Spark SQL), Iceberg • Streaming vs Batch – Multiple lanes, accountability, independent scale • Duplication – Storage vs Runtime cost #DevSAIS11