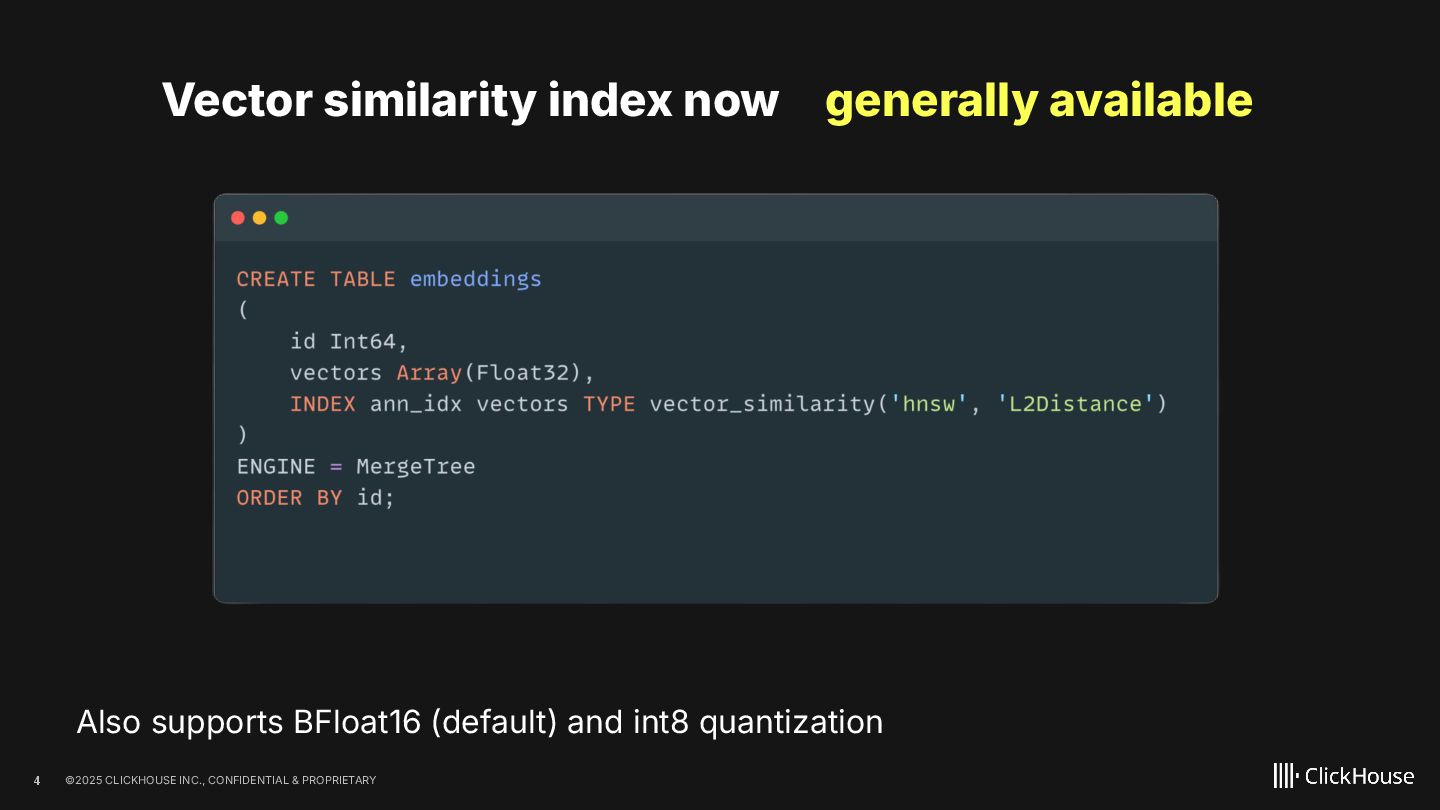
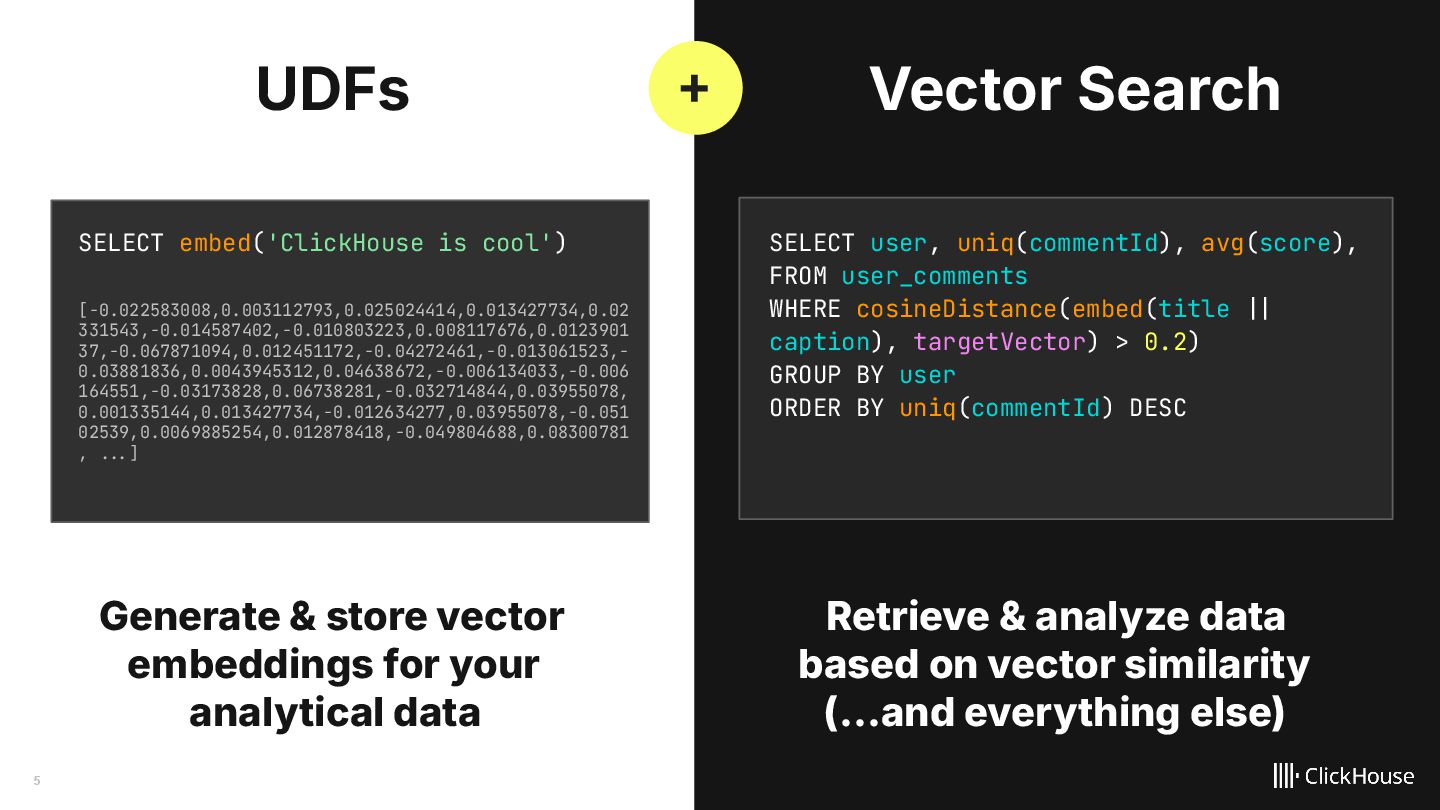
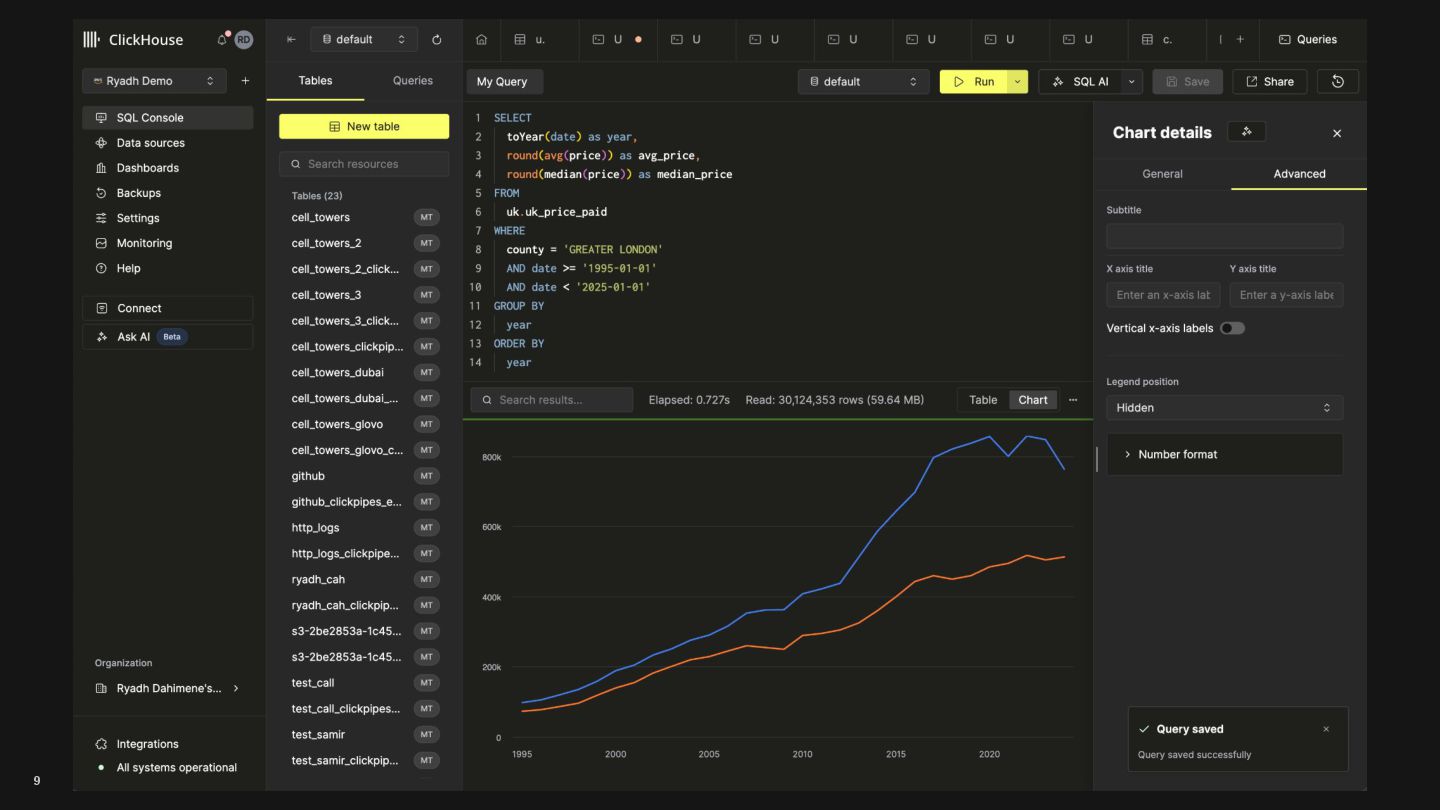
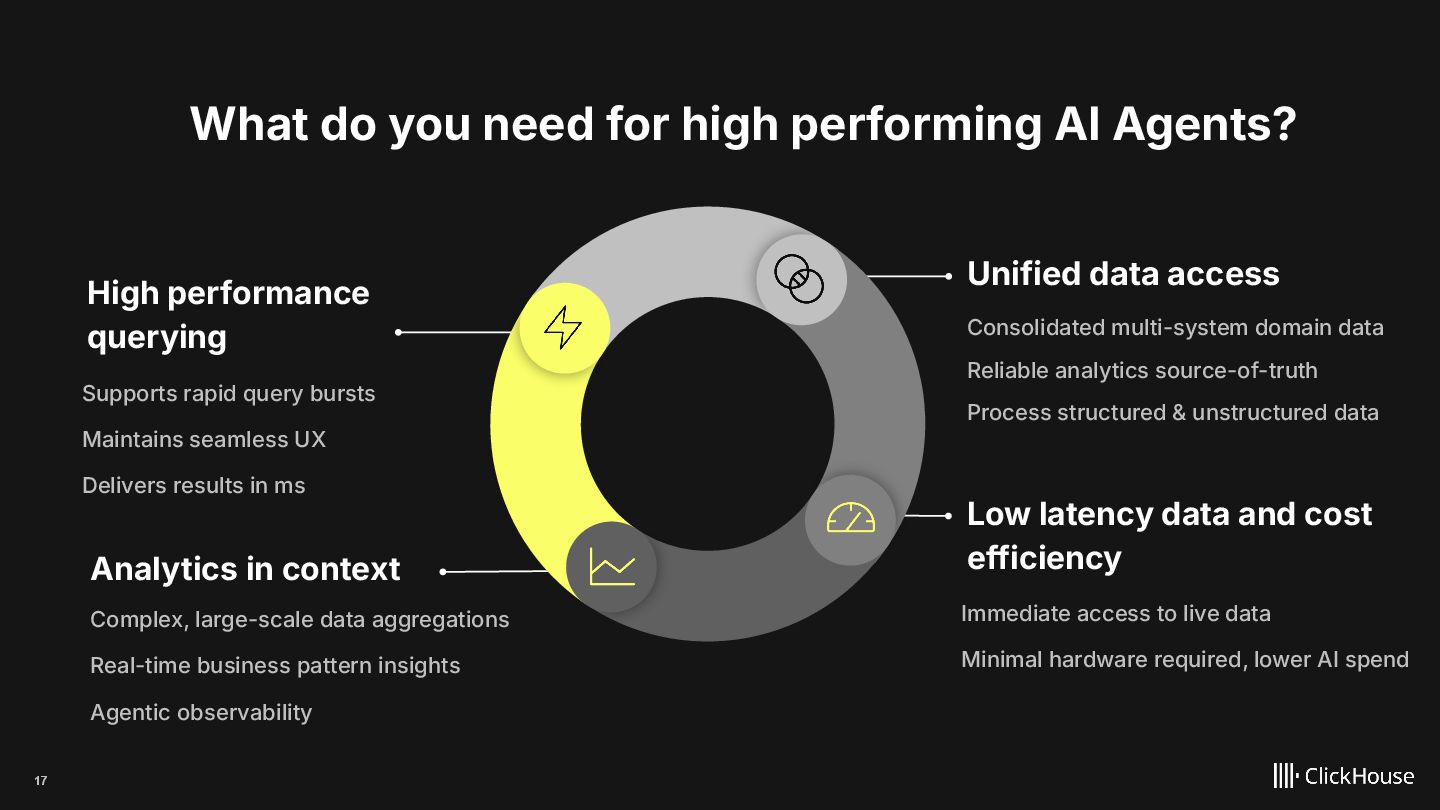
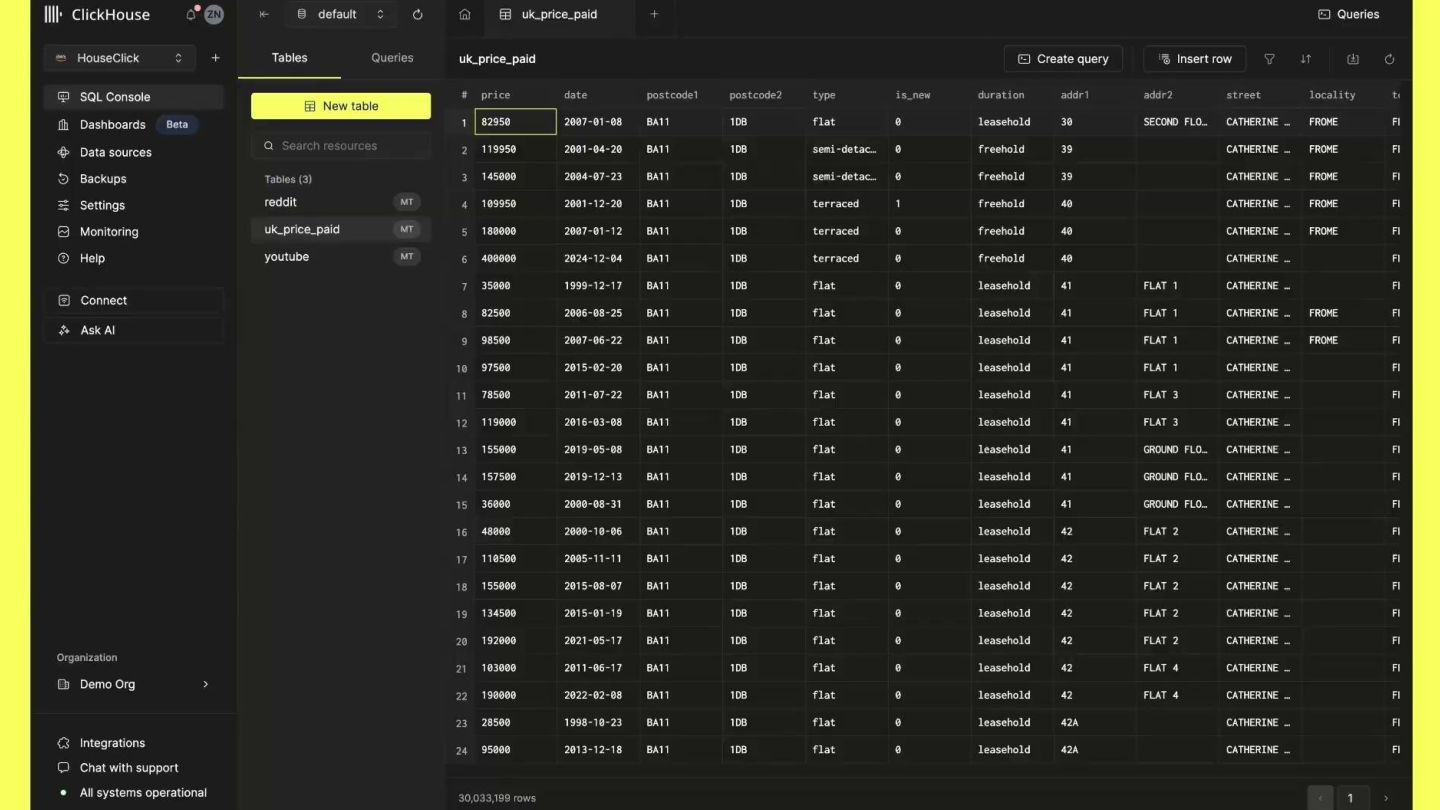
for your analytical data Retrieve & analyze data based on vector similarity (...and everything else) SELECT embed('ClickHouse is cool') [-0.022583008,0.003112793,0.025024414,0.013427734,0.02 331543,-0.014587402,-0.010803223,0.008117676,0.0123901 37,-0.067871094,0.012451172,-0.04272461,-0.013061523,- 0.03881836,0.0043945312,0.04638672,-0.006134033,-0.006 164551,-0.03173828,0.06738281,-0.032714844,0.03955078, 0.001335144,0.013427734,-0.012634277,0.03955078,-0.051 02539,0.0069885254,0.012878418,-0.049804688,0.08300781 , ||.] SELECT user, uniq(commentId), avg(score), FROM user_comments WHERE cosineDistance(embed(title || caption), targetVector) > 0.2) GROUP BY user ORDER BY uniq(commentId) DESC


 pjhampton
 ludicmind
 vivion
 oikon48
 mochizuki875
 dada4386
 tomzoh
 yokawasa
 athug
 recruitengineers
 pauli
 pei0804
 addyosmani
 marcelosomers
 skoyamalab
 sabderemane
 ammeep
 ryanjones
 trishagee
 lynnandtonic
 emna__ayadi
 schroneko
 eileencodes