Upgrade to Pro — share decks privately, control downloads, hide ads and more …

Making Deployments Easy with TF Serving | TF Ev...

Sponsored · SiteGround - Reliable hosting with speed, security, and support you can count on. →

Making Deployments Easy with TF Serving | TF Everywhere India

My talk at TensorFlow Everywhere India

Rishit Dagli

May 11, 2021

Transcript

58 slides
  1. Making Deployments Easy with TF Serving Rishit Dagli High School

    TEDx, TED-Ed Speaker rishit_dagli Rishit-dagli
  2. • High School Student • TEDx and Ted-Ed Speaker •

    ♡ Hackathons and competitions • ♡ Research • My coordinates - www.rishit.tech $whoami rishit_dagli Rishit-dagli
  3. • Devs who have worked on Deep Learning Models (Keras)

    • Devs looking for ways to put their model into production ready manner Ideal Audience
  4. • Package the model • Post the model on Server

    • Maintain the server What things to take care of?
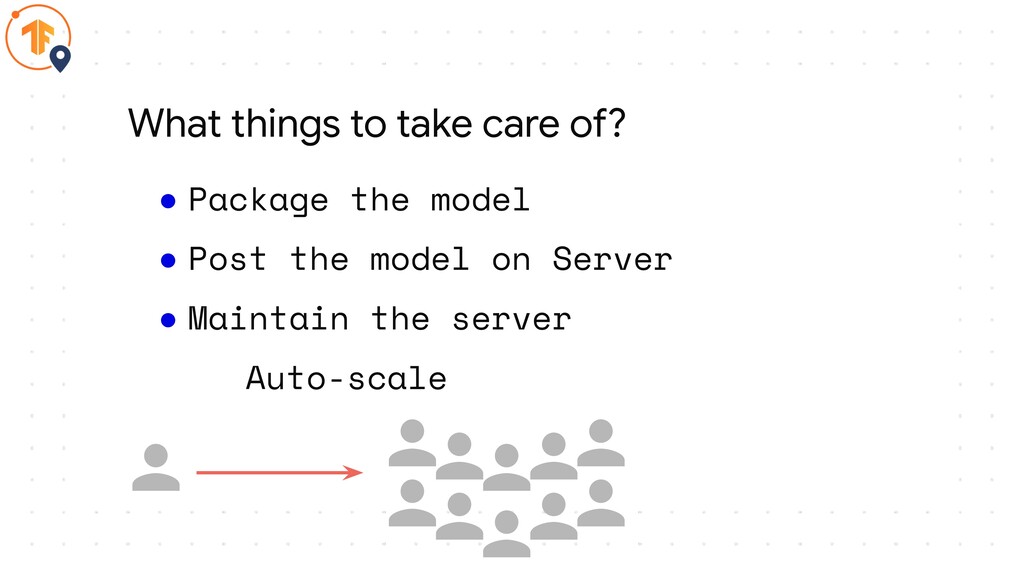
  5. • Package the model • Post the model on Server

    • Maintain the server Auto-scale What things to take care of?
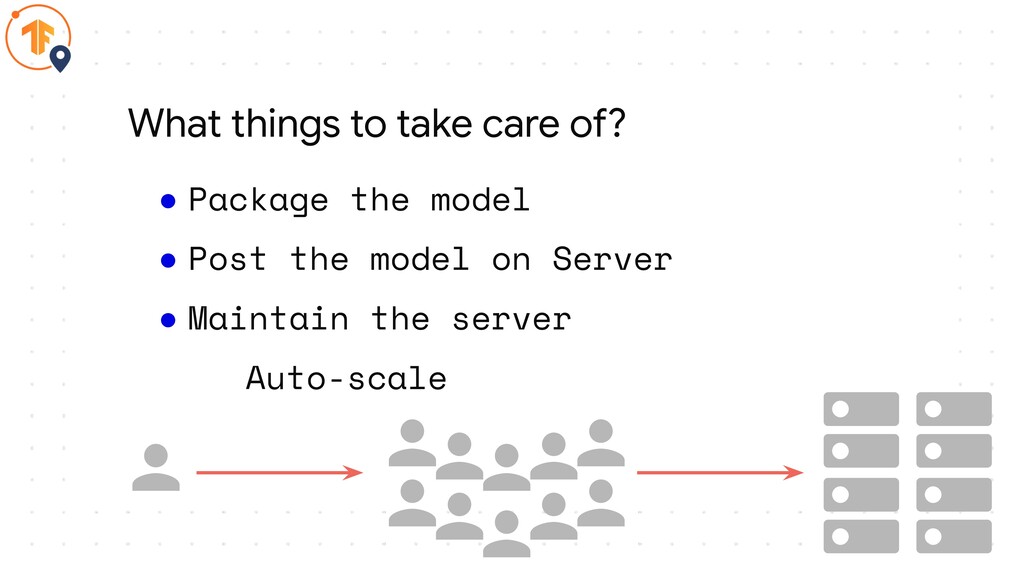
  6. • Package the model • Post the model on Server

    • Maintain the server Auto-scale What things to take care of?
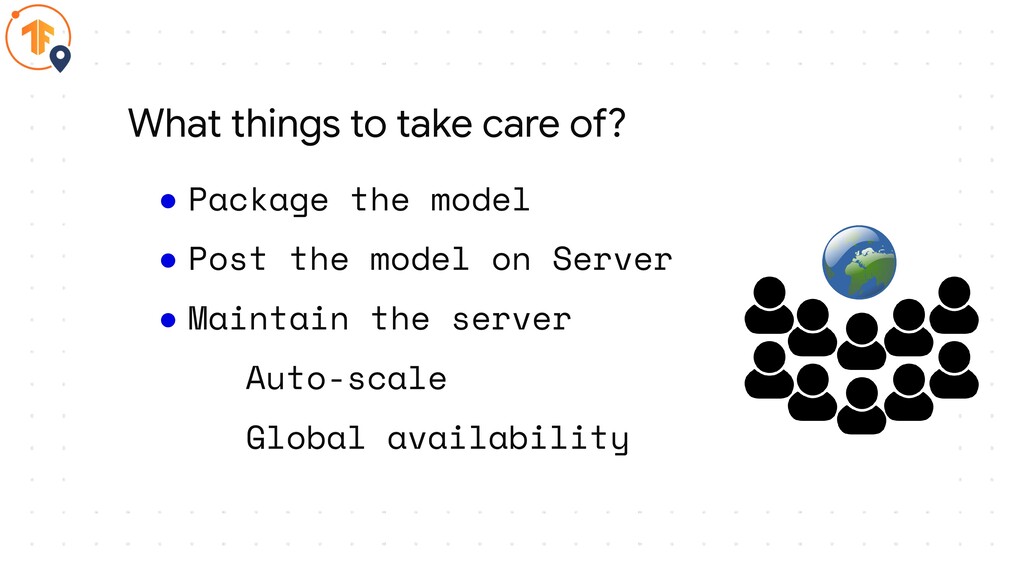
  7. • Package the model • Post the model on Server

    • Maintain the server Auto-scale Global availability What things to take care of?
  8. • Package the model • Post the model on Server

    • Maintain the server Auto-scale Global availability Latency What things to take care of?
  9. • Package the model • Post the model on Server

    • Maintain the server • API What things to take care of?
  10. • Package the model • Post the model on Server

    • Maintain the server • API • Model Versioning What things to take care of?
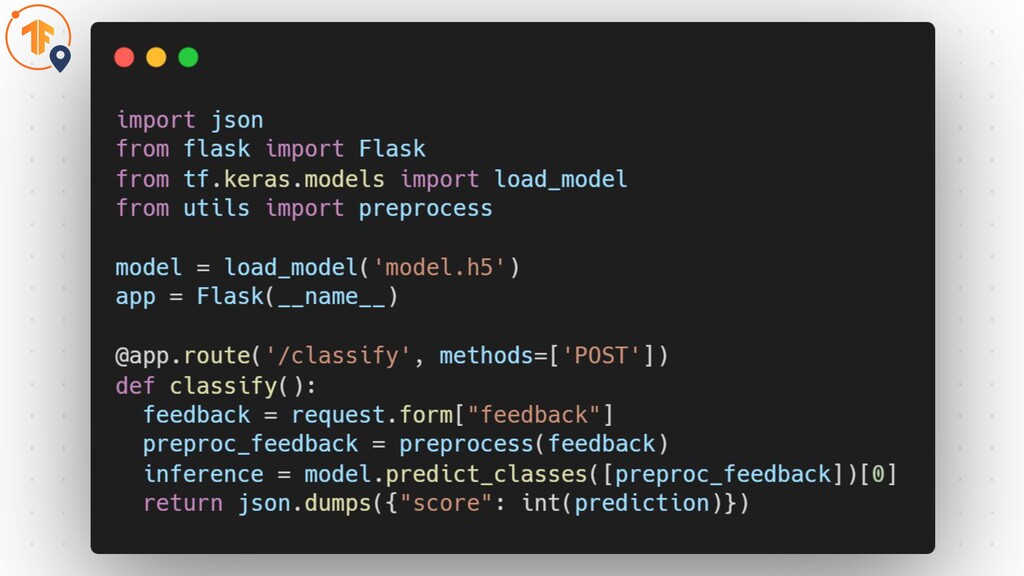
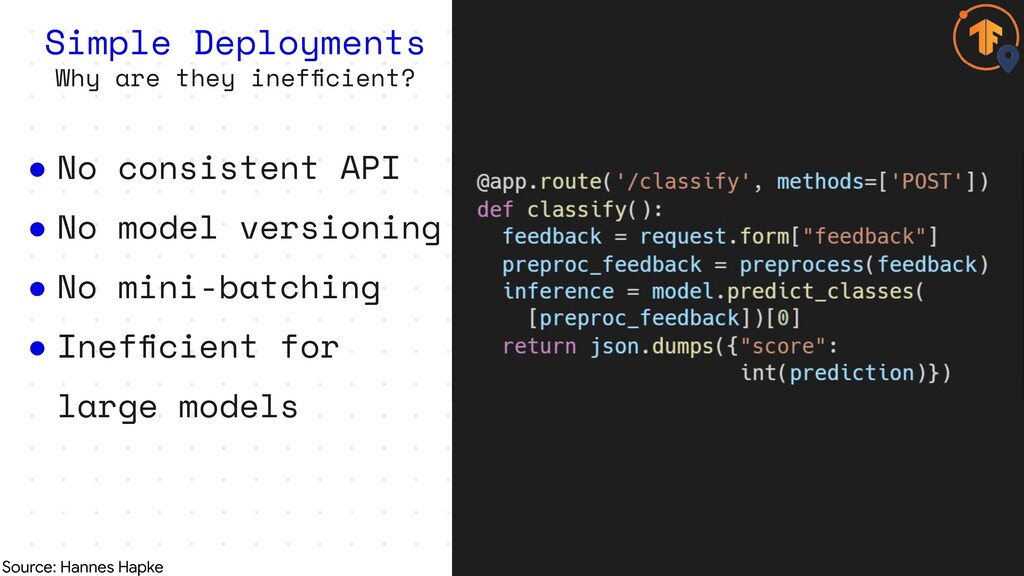
  11. Simple Deployments Why are they inefficient? • No consistent API

    • No model versioning • No mini-batching • Inefficient for large models Source: Hannes Hapke
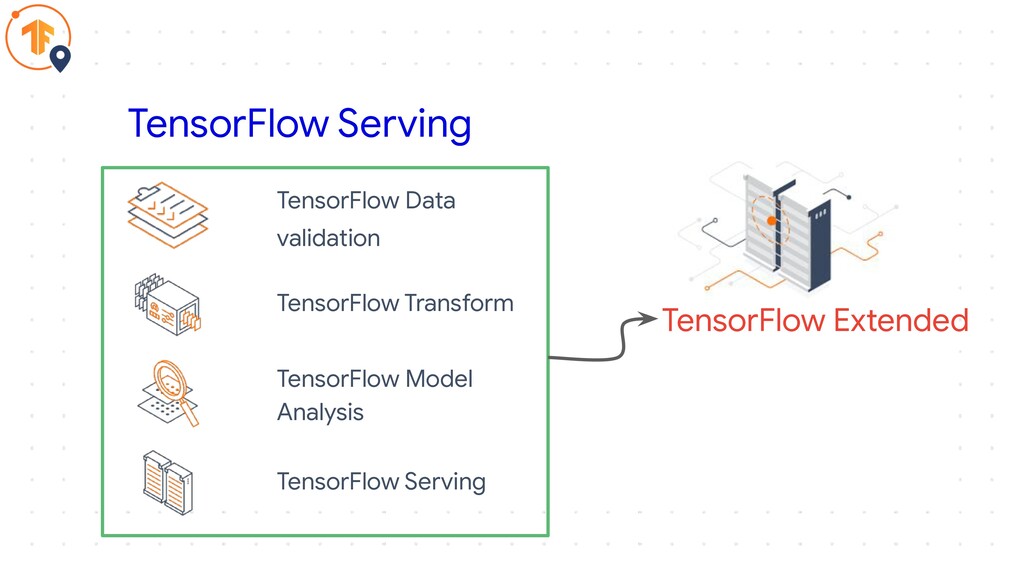
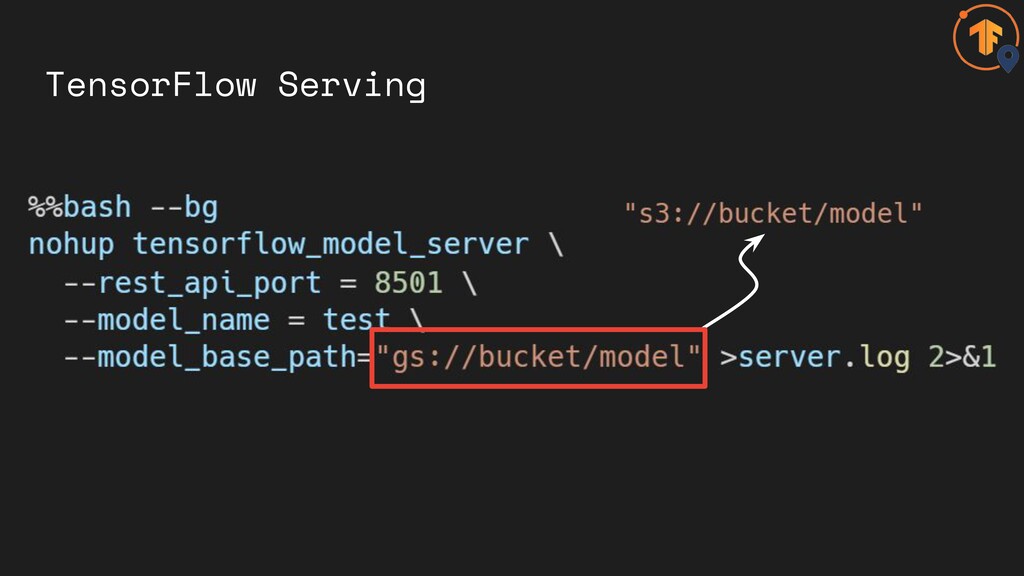
  12. • Part of TensorFlow Extended • Used Internally at Google

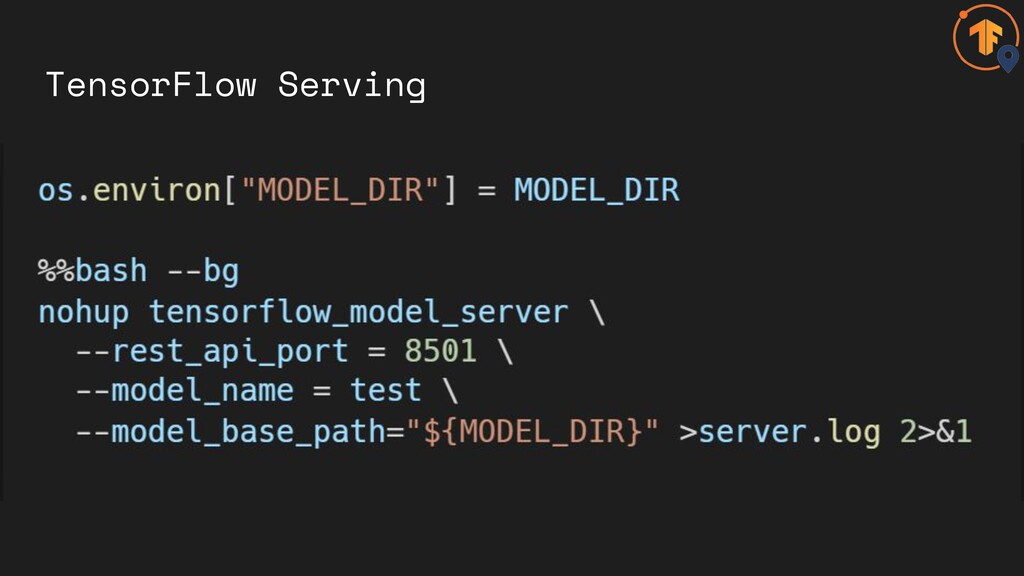
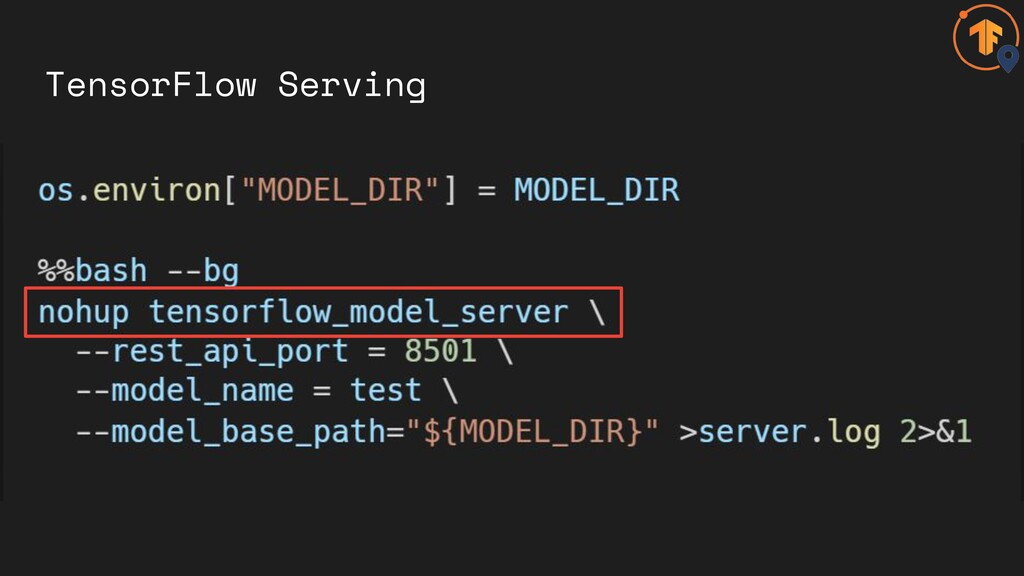
    • Makes deployment a lot easier TensorFlow Serving
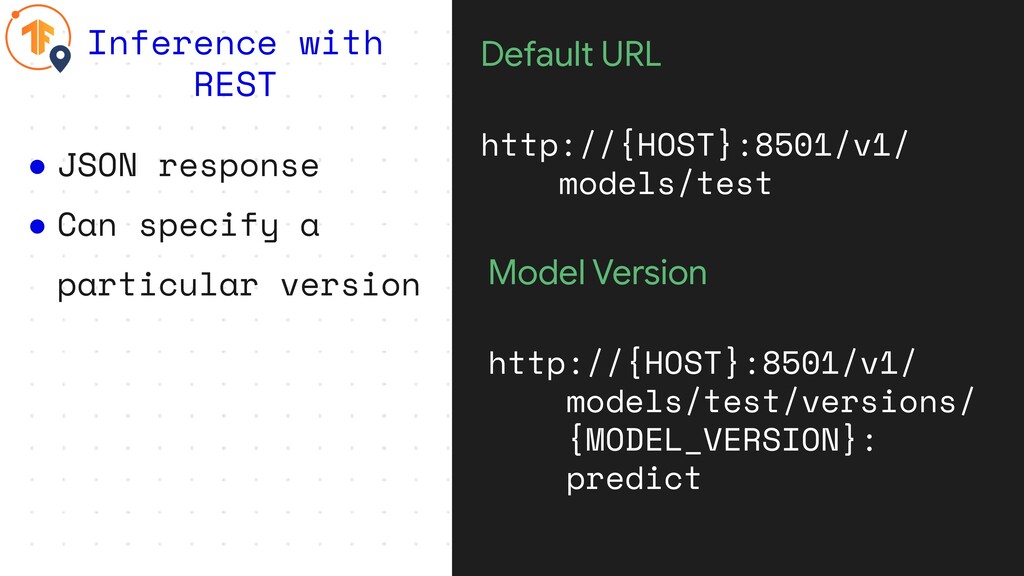
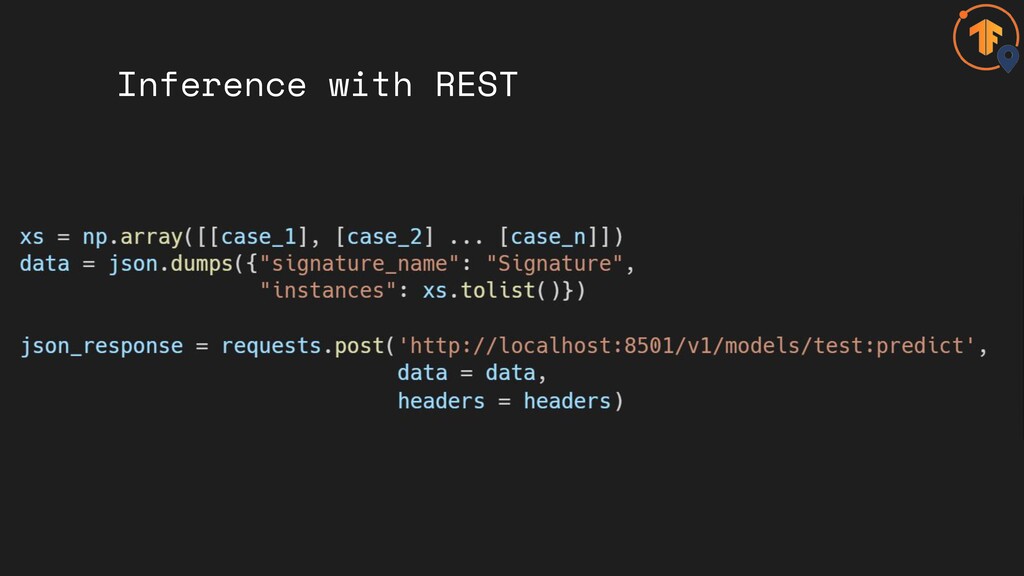
  13. • JSON response • Can specify a particular version Inference

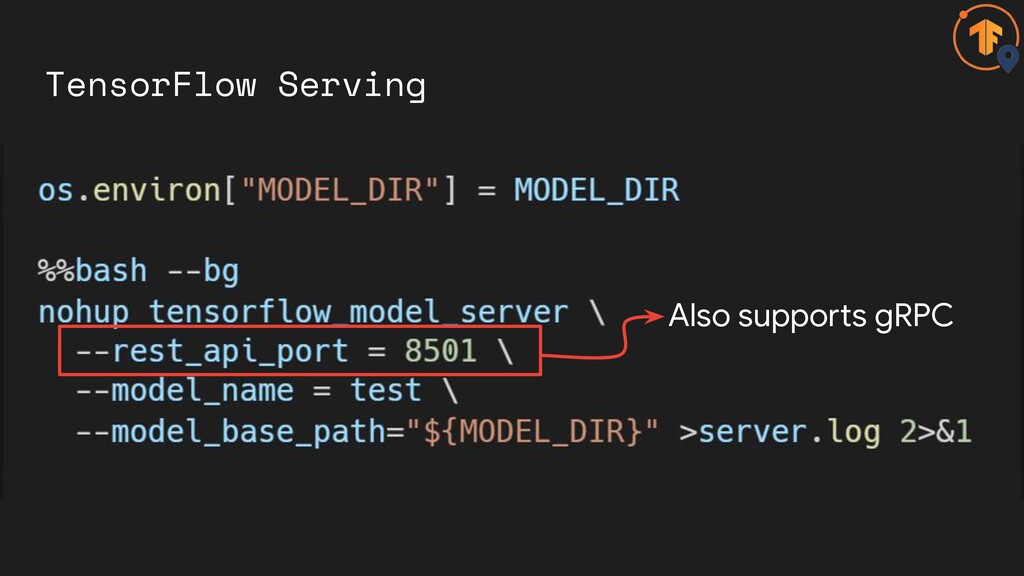
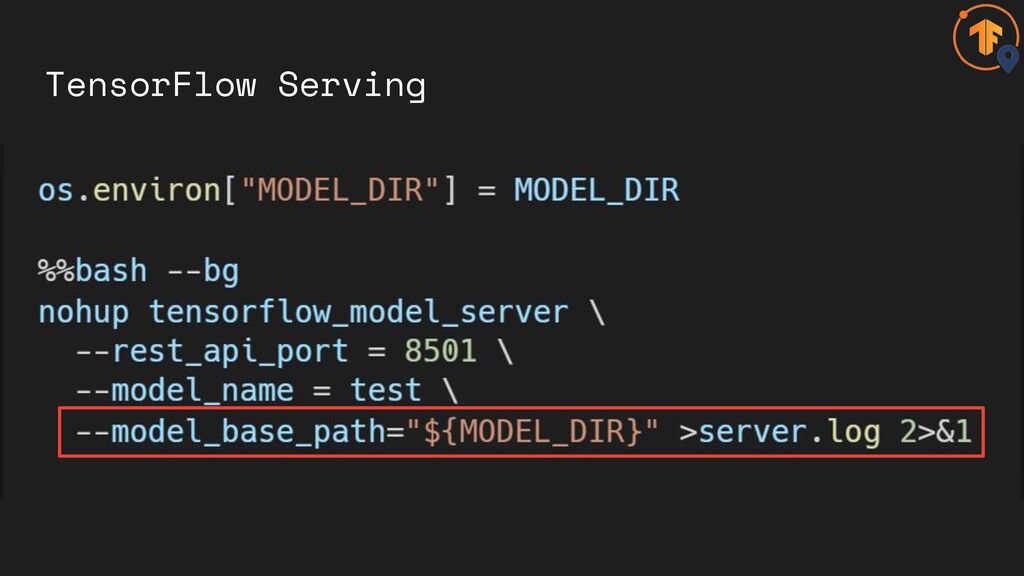
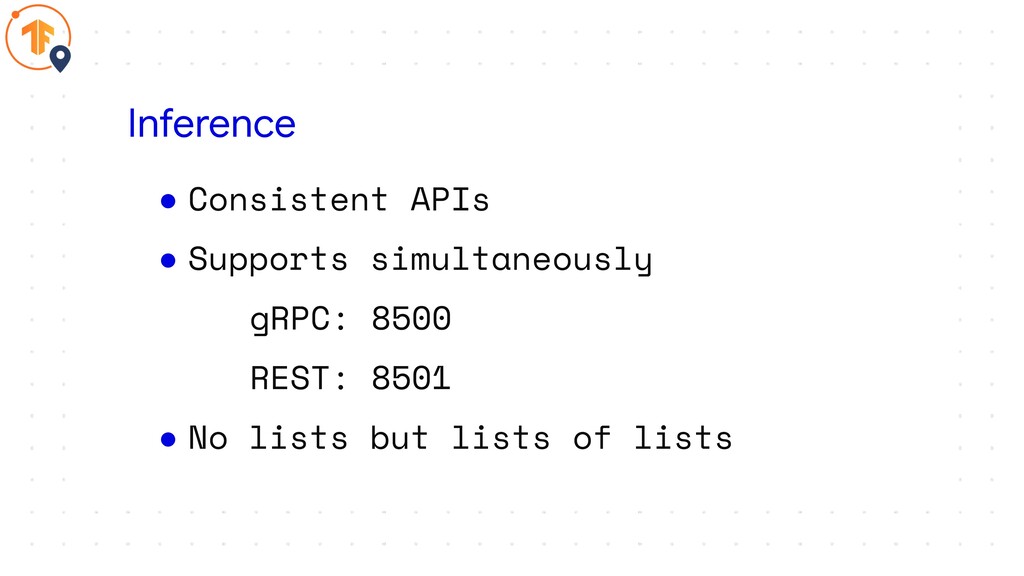
    with REST Default URL http://{HOST}:8501/v1/ models/test Model Version http://{HOST}:8501/v1/ models/test/versions/ {MODEL_VERSION}: predict
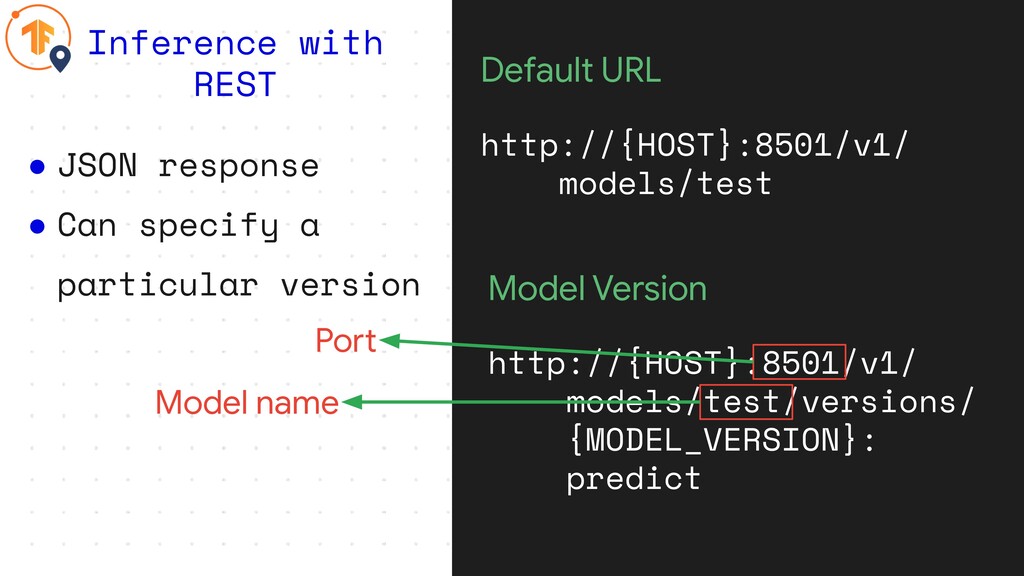
  14. • JSON response • Can specify a particular version Inference

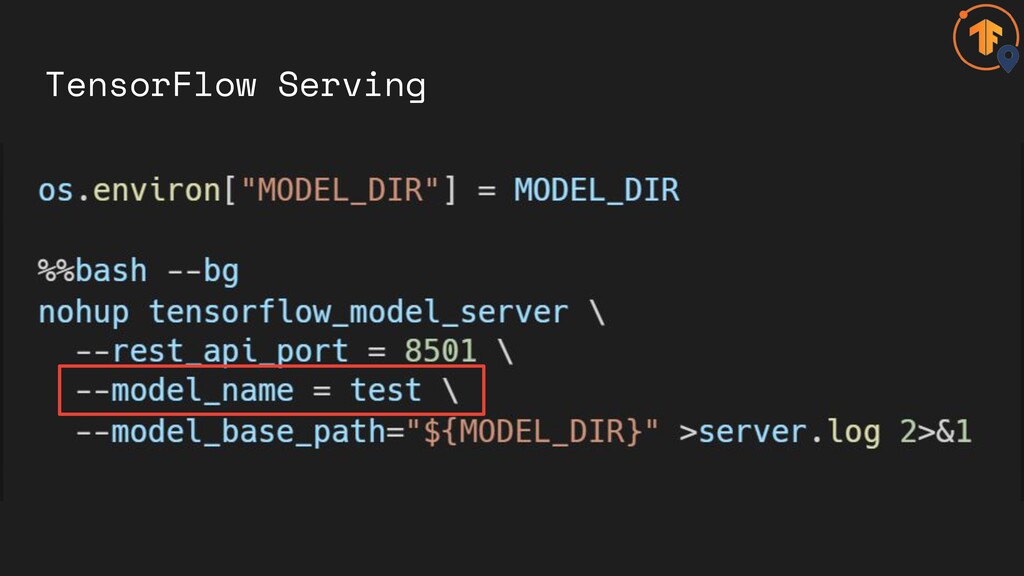
    with REST Default URL http://{HOST}:8501/v1/ models/test Model Version http://{HOST}:8501/v1/ models/test/versions/ {MODEL_VERSION}: predict Port Model name
  15. • Better connections • Data converted to protocol buffer •

    Request types have designated type • Payload converted to base64 • Use gRPC stubs Inference with gRPC
  16. • You have an API to get meta info •

    Useful for model tracking in telementry systems • Provides model input/ outputs, signatures Model Meta Information
  17. • Use hardware efficiently • Save costs and compute resources

    • Take multiple requests process them together • Super cool😎 for large models Batch inferences
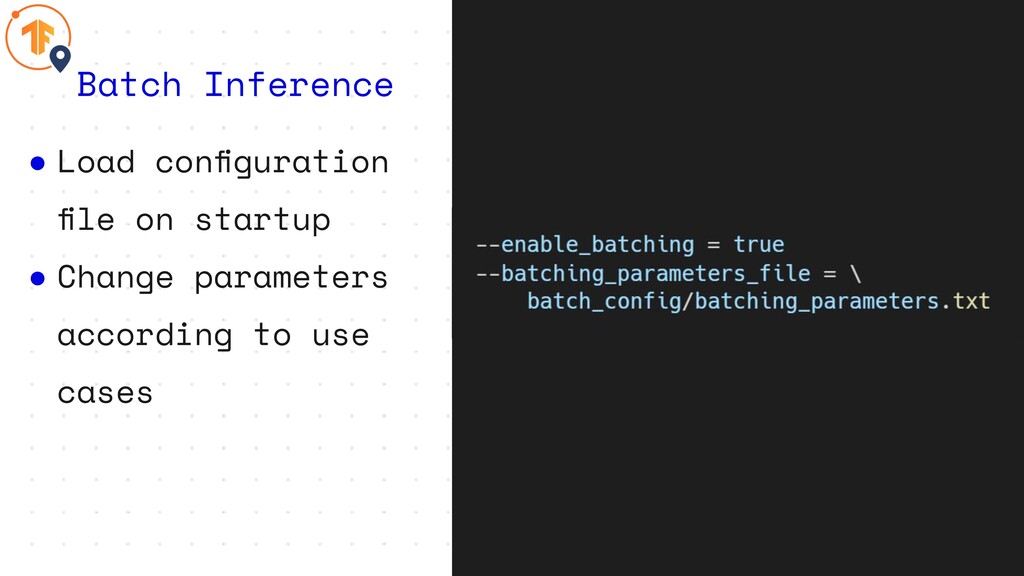
  18. • max_batch_size • batch_timeout_micros • num_batch_threads • max_enqueued_batches • file_system_poll_wait

    _seconds • tensorflow_session _paralellism • tensorflow_intra_op _parallelism Batch Inference Highly customizable
  19. • Kubeflow deployments • Data pre-processing on server🚅 • AI

    Platform Predictions • Deployment on edge devices • Federated learning Also take a look at...

More Decks by Rishit Dagli

Other Decks in Programming