Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
Multi-Scale Self-Attention for Text Classification
Search
Scatter Lab Inc.
January 16, 2020
Research
2.5k
0
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
Multi-Scale Self-Attention for Text Classification
Scatter Lab Inc.
January 16, 2020
Transcript
24 slides
Multi-Scale Self-Attention for Text Classification ߔ (ML Research Scientist, Pingpong)
ݾର ݾର! 1. Introduction 1. Self-Attention 2. Problem 2. Proposed
Method 1. Scale-Aware Self-Attention 2. Multi-Scale Multi-Head Self-Attention 3. Multi-Scale Transformer 3. Experiments 1. Effective Scale 2. Text Classification
Introduction Introduction
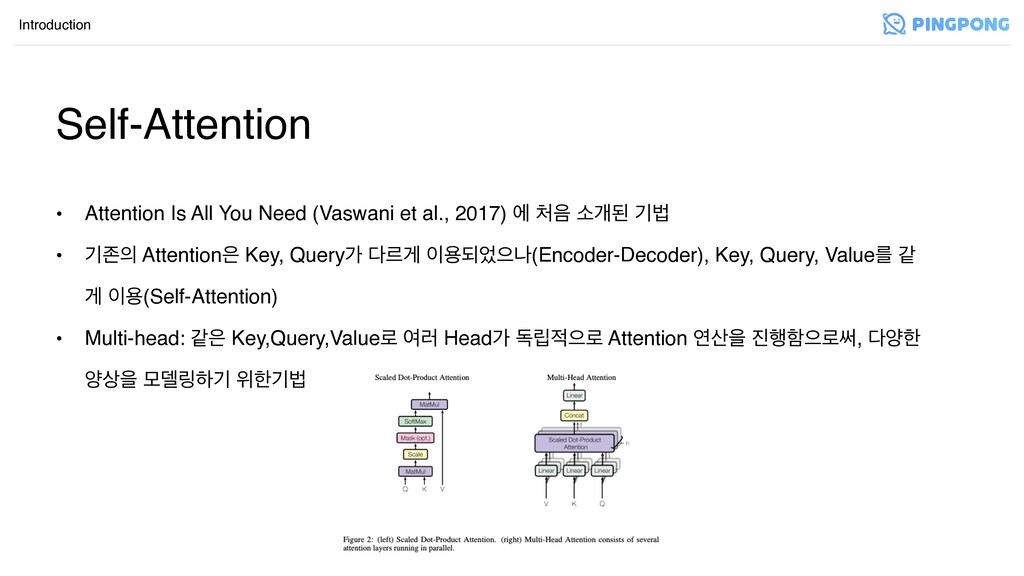
• Attention Is All You Need (Vaswani et al., 2017)
ী ࣗѐػ ӝߨ • ӝઓ Attention Key, Queryо ܰѱ ਊغਵա(Encoder-Decoder), Key, Query, Valueܳ э ѱ ਊ(Self-Attention) • Multi-head: э Key,Query,Value۽ ৈ۞ Headо ة݀ਵ۽ Attention োਸ ೯ೣਵ۽ॄ, নೠ ন࢚ਸ ݽ؛݂ೞӝ ਤೠӝߨ Introduction Self-Attention
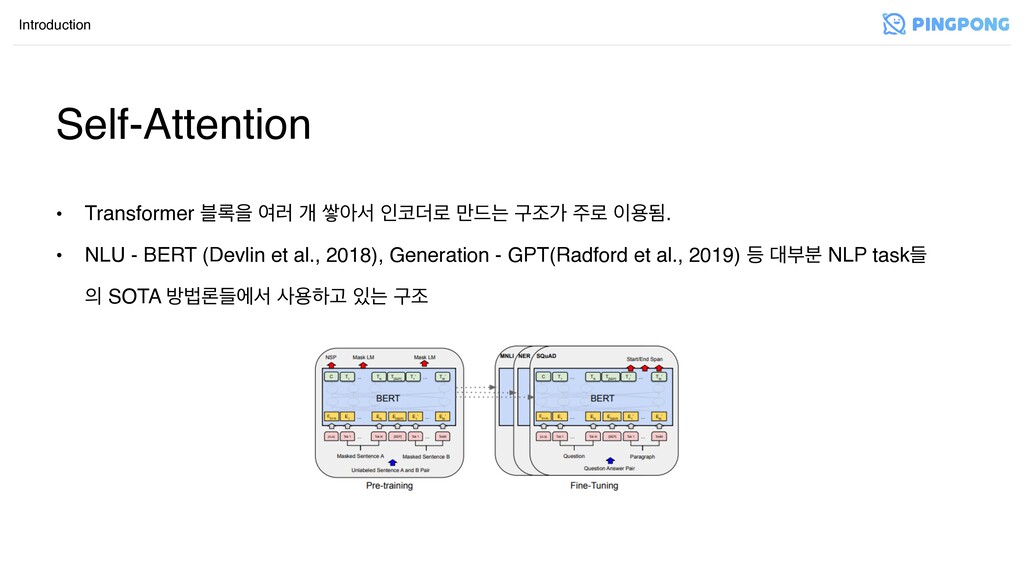
• Transformer ࠶۾ਸ ৈ۞ ѐ ऺইࢲ ੋ؊۽ ݅٘ח ҳઑо ۽
ਊؽ. • NLU - BERT (Devlin et al., 2018), Generation - GPT(Radford et al., 2019) ١ ࠗ࠙ NLP taskٜ SOTA ߑߨۿٜীࢲ ࢎਊೞҊ ח ҳઑ Introduction Self-Attention
• Transformerח ܲ ݽٕٜ(CNN, RNN)ী ࠺೧ Inductive Bias ޙઁী ౠ
ஂডೣ • ݽ؛ ҳઑо ఀ • ݽ؛ী ઁড . • CNN, RNN: ౠ ױযٜ ࢎী ࢚ഐਊਸ ݽ؛݂ • Transformer: ױযٜ ࢎ pair-wised ࢚ഐਊਸ ݽ؛݂(ݽٚ ױযী Ӕ оמ) • ܳ ӓࠂೞӝ ਤ೧ Large Corpus۽ pre-training ೞח ߑधਸ ࢎਊೣ. → ؘఠ۽ ߄۽ णदெب ੜ زೞח Transformer • যীب Multi-Scale ҳઑо ઓೣ.(Hierarchical Structure) • High-level feature -> Low-level term ઑ • Transformer ҳઑীח ۞ೠ ਸ ߈ೡ ࣻ হ.( layerࠗఠ ݽٚ wordী Ӕ оמೣ. ࠗ࠙ب BERT method۽ যו ب ೧Ѿ ؽ.) → Multi-Scaleਸ ߈ೡ ࣻ ח Transformer Introduction Problem
Proposed Method Proposed Method
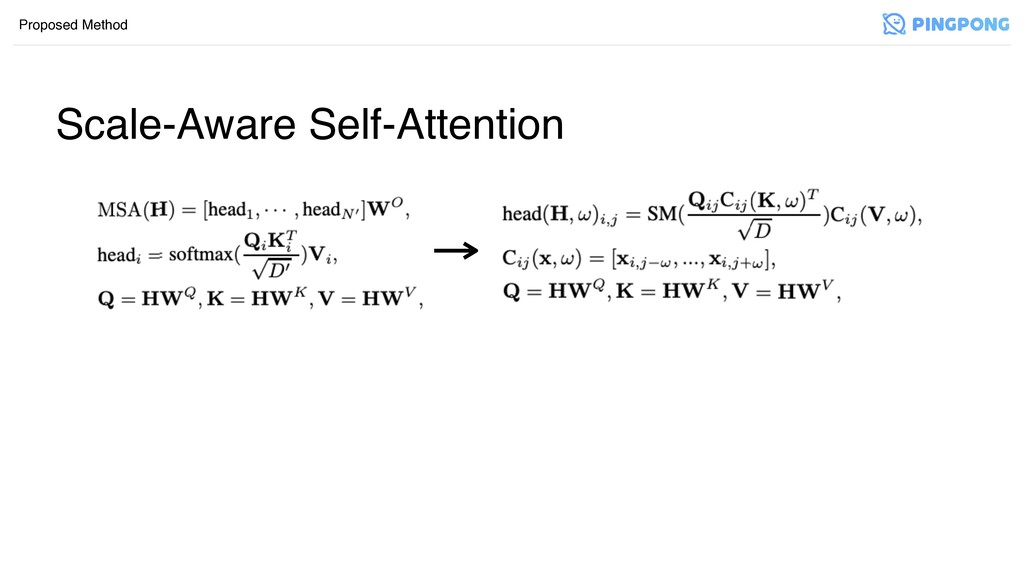
Scale-Aware Self-Attention Proposed Method
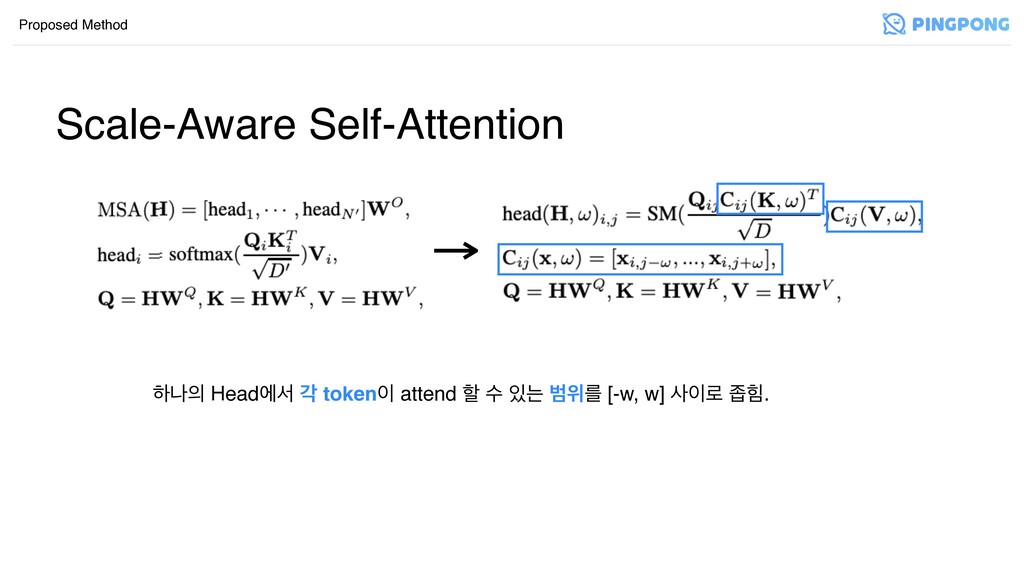
Scale-Aware Self-Attention Proposed Method ೞա Headীࢲ п token attend ೡ
ࣻ ח ߧਤܳ [-w, w] ࢎ۽ ગ൨.
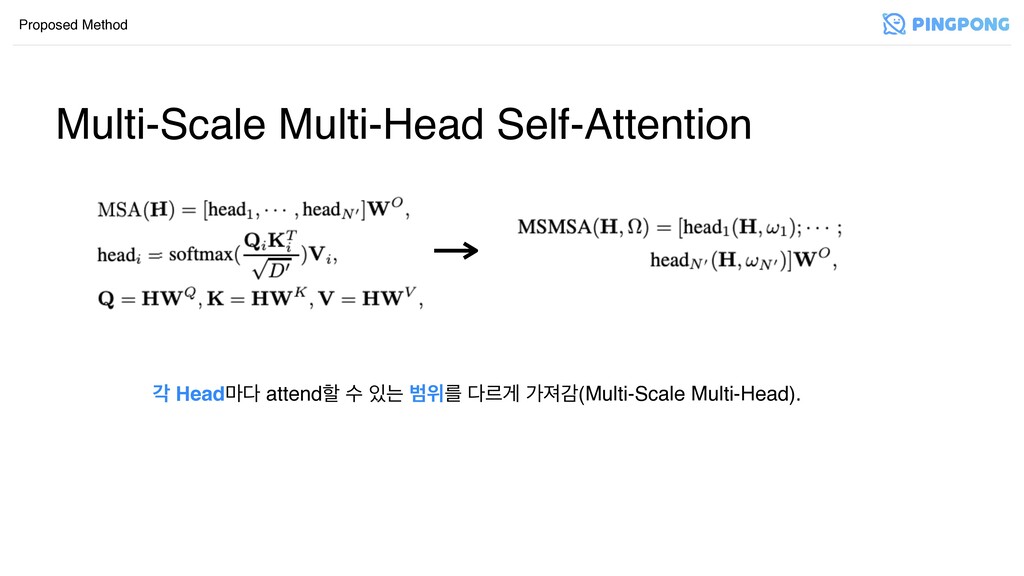
Multi-Scale Multi-Head Self-Attention Proposed Method п Head݃ attendೡ ࣻ ח
ߧਤܳ ܰѱ оઉх(Multi-Scale Multi-Head).
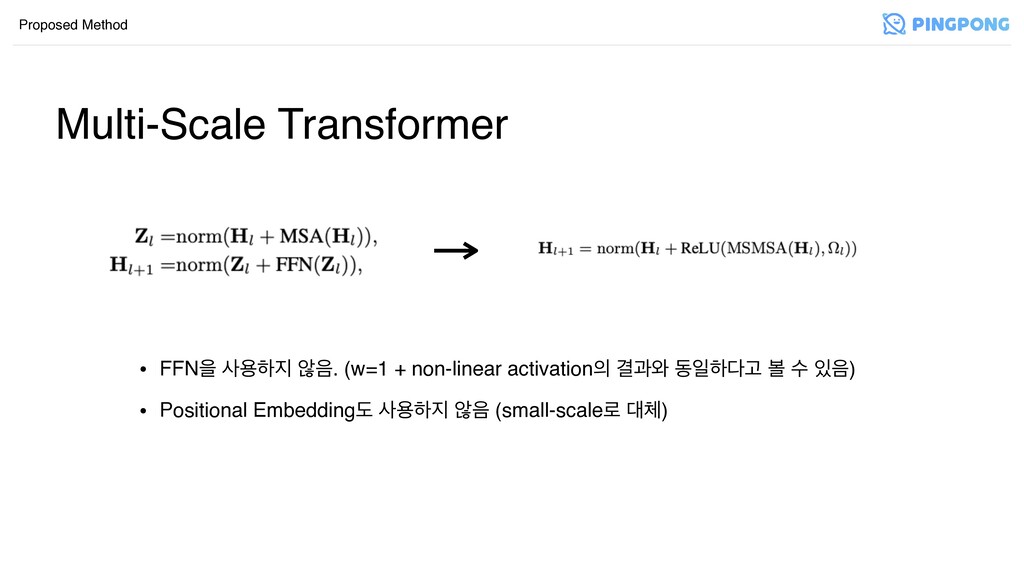
Multi-Scale Transformer Proposed Method • FFNਸ ࢎਊೞ ঋ. (w=1 +
non-linear activation Ѿҗ৬ زੌೞҊ ࠅ ࣻ ) • Positional Embeddingب ࢎਊೞ ঋ (small-scale۽ )
Multi-Scale Transformer Proposed Method • Classification Node • Bertীࢲח [CLS]
ష representationਸ Classificationী ਊೣ • [CLS]ష representation + աݠ ష representation max pooling feature
Experiments Experiments
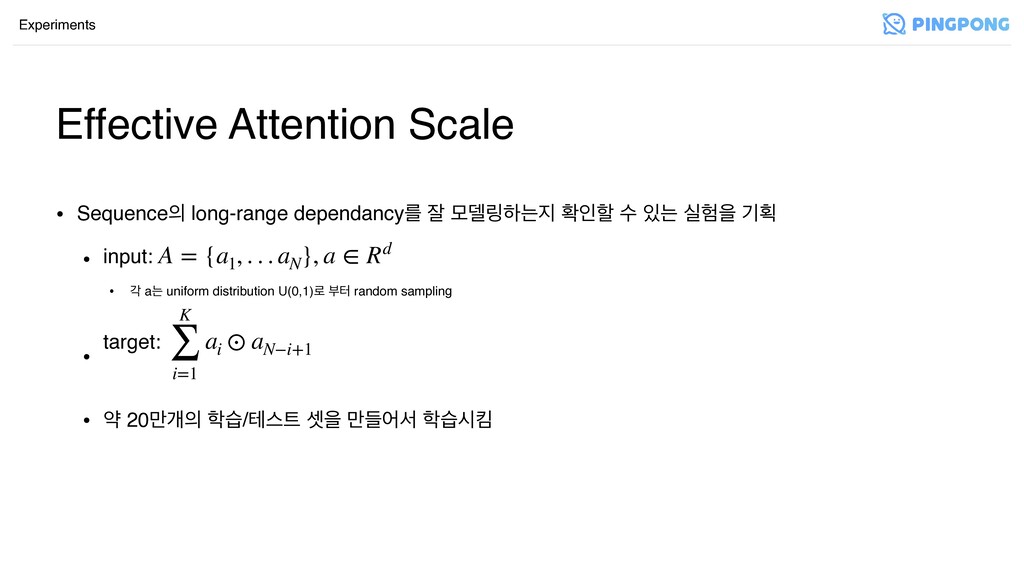
Effective Attention Scale Experiments • Sequence long-range dependancyܳ ੜ ݽ؛݂ೞח
ഛੋೡ ࣻ ח पਸ ӝദ • input: • п aח uniform distribution U(0,1)۽ ࠗఠ random sampling • target: • ড 20݅ѐ ण/పझ ࣇਸ ٜ݅যࢲ णदఇ A = {a 1 , . . . a N }, a ∈ Rd K ∑ i= 1 a i ⊙ a N−i+1
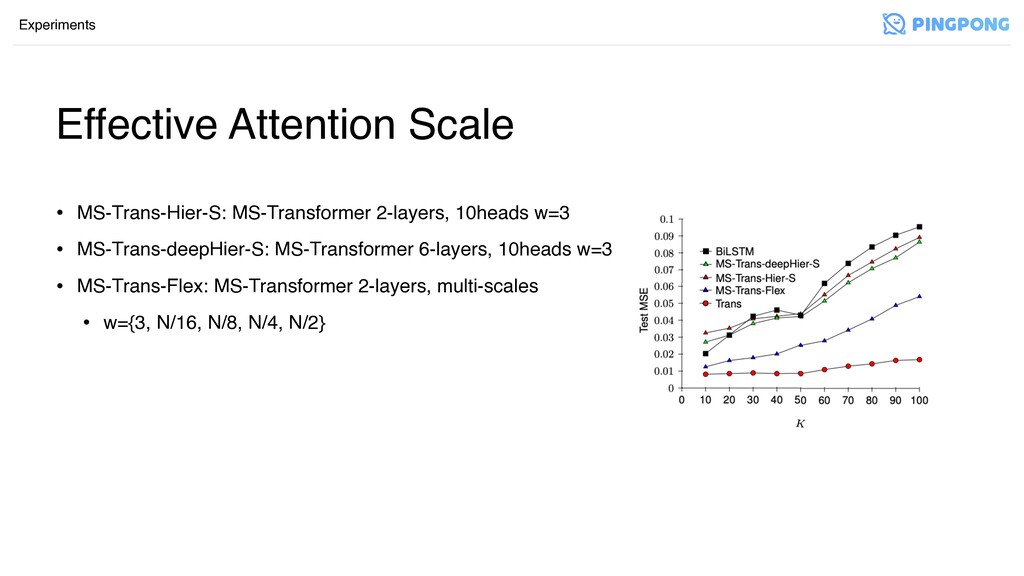
Effective Attention Scale Experiments • MS-Trans-Hier-S: MS-Transformer 2-layers, 10heads w=3
• MS-Trans-deepHier-S: MS-Transformer 6-layers, 10heads w=3 • MS-Trans-Flex: MS-Transformer 2-layers, multi-scales • w={3, N/16, N/8, N/4, N/2}
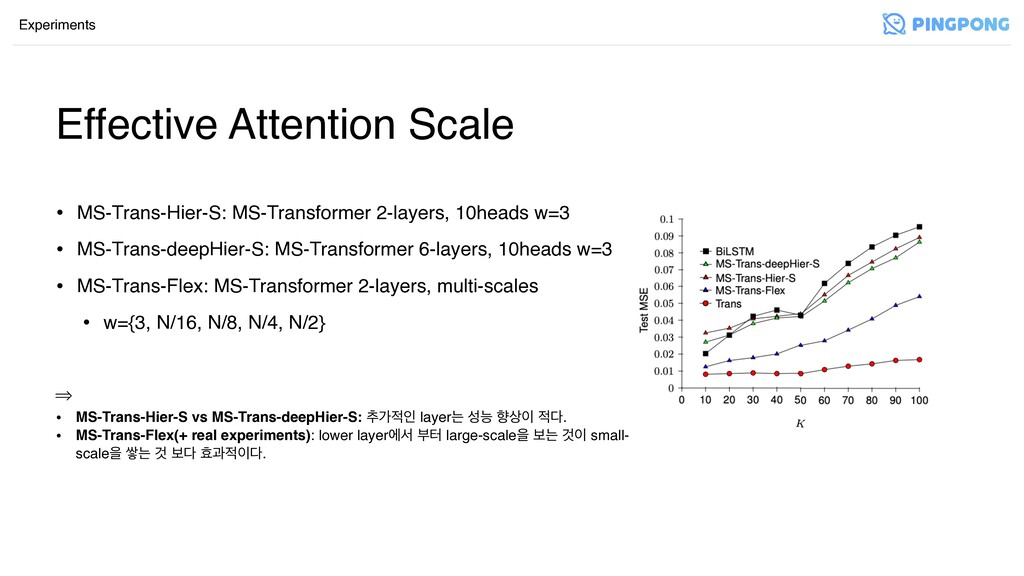
Effective Attention Scale Experiments • MS-Trans-Hier-S: MS-Transformer 2-layers, 10heads w=3
• MS-Trans-deepHier-S: MS-Transformer 6-layers, 10heads w=3 • MS-Trans-Flex: MS-Transformer 2-layers, multi-scales • w={3, N/16, N/8, N/4, N/2} Ã • MS-Trans-Hier-S vs MS-Trans-deepHier-S: ୶оੋ layerח ࢿמ ೱ࢚ . • MS-Trans-Flex(+ real experiments): lower layerীࢲ ࠗఠ large-scaleਸ ࠁח Ѫ small- scaleਸ ऺח Ѫ ࠁ ബҗ.
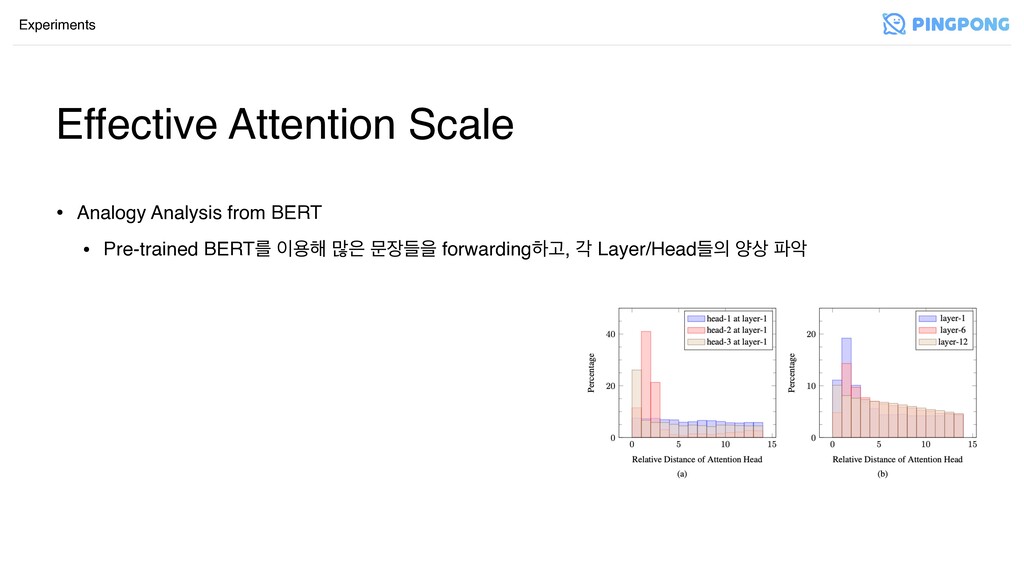
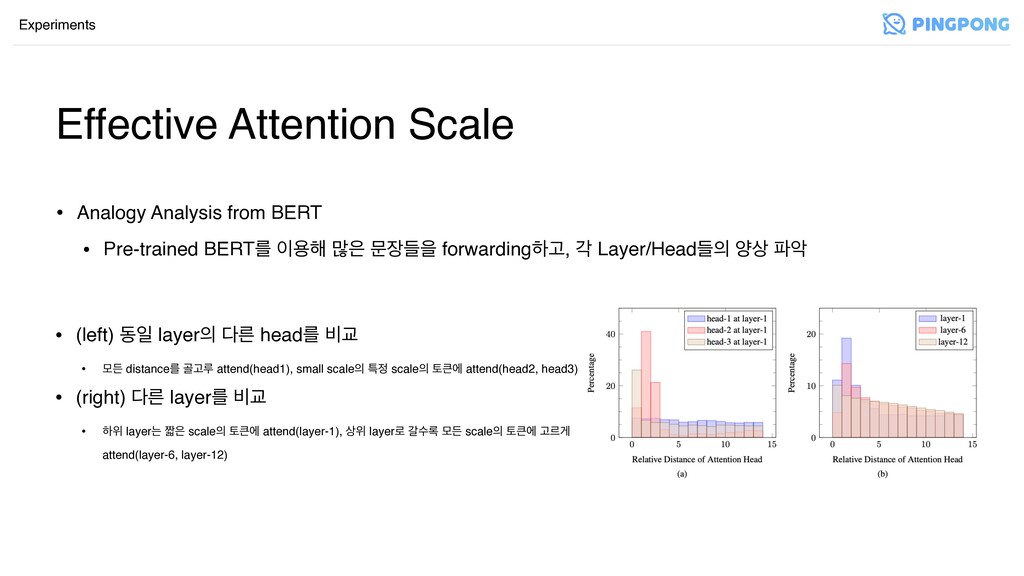
Effective Attention Scale Experiments • Analogy Analysis from BERT •
Pre-trained BERTܳ ਊ೧ ݆ ޙٜਸ forwardingೞҊ, п Layer/Headٜ ন࢚ ঈ
Effective Attention Scale Experiments • Analogy Analysis from BERT •
Pre-trained BERTܳ ਊ೧ ݆ ޙٜਸ forwardingೞҊ, п Layer/Headٜ ন࢚ ঈ • (left) زੌ layer ܲ headܳ ࠺Ү • ݽٚ distanceܳ ҎҊܖ attend(head1), small scale ౠ scale షী attend(head2, head3) • (right) ܲ layerܳ ࠺Ү • ೞਤ layerח ૣ scale షী attend(layer-1), ࢚ਤ layer۽ тࣻ۾ ݽٚ scale షী Ҋܰѱ attend(layer-6, layer-12)
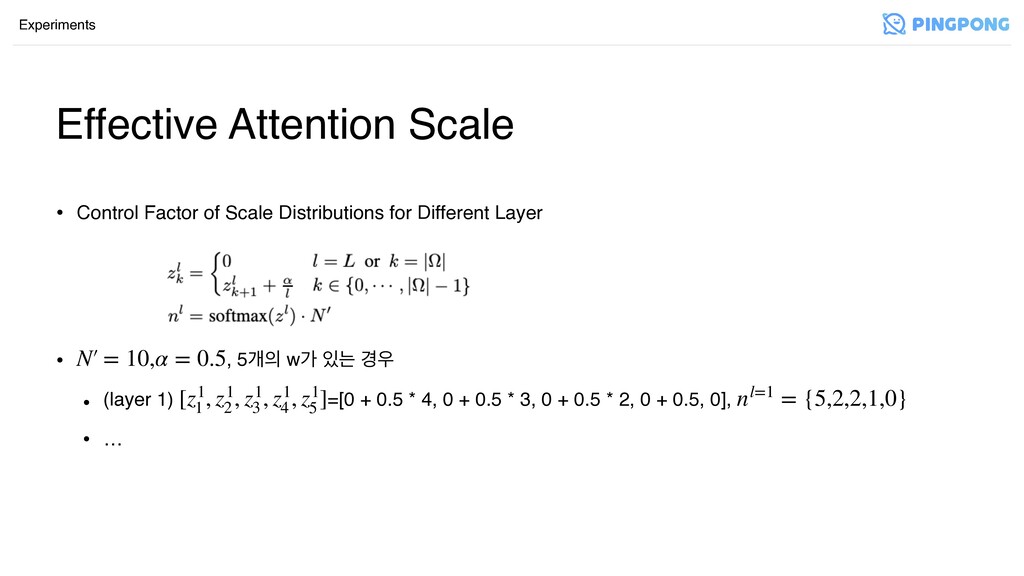
Effective Attention Scale Experiments • Control Factor of Scale Distributions
for Different Layer • , 5ѐ wо ח ҃ • (layer 1) =[0 + 0.5 * 4, 0 + 0.5 * 3, 0 + 0.5 * 2, 0 + 0.5, 0], • … N′ = 10,α = 0.5 [z1 1 , z1 2 , z1 3 , z1 4 , z1 5 ] n l= 1 = {5,2,2,1,0}
Experiment Settings Experiments • Classifier: 2-layer MLP • GloVe Pre-trained
Word-Embeddings • BERT৬ э self-supervised learning method৬ח ࠺Ү ೞ ঋ. • ݽٚ ण word-embeddingਸ ઁ৻ೞҊ from scratch
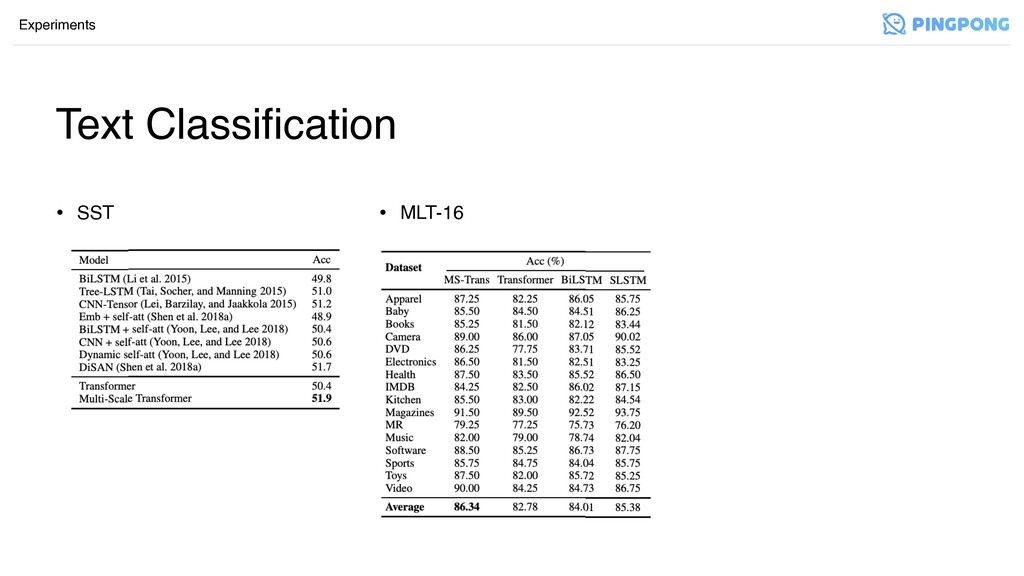
Text Classification Experiments • SST • MLT-16
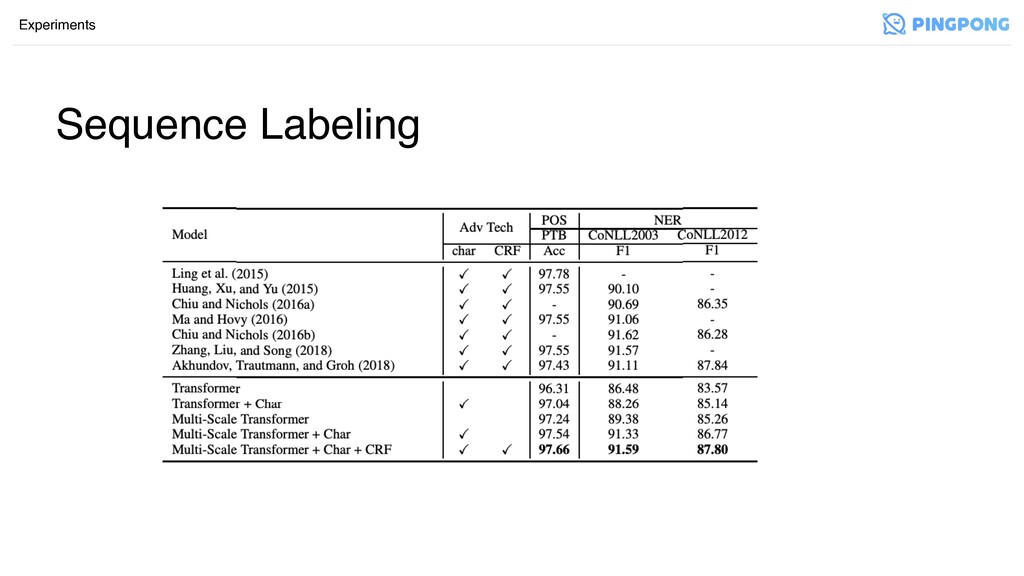
Sequence Labeling Experiments
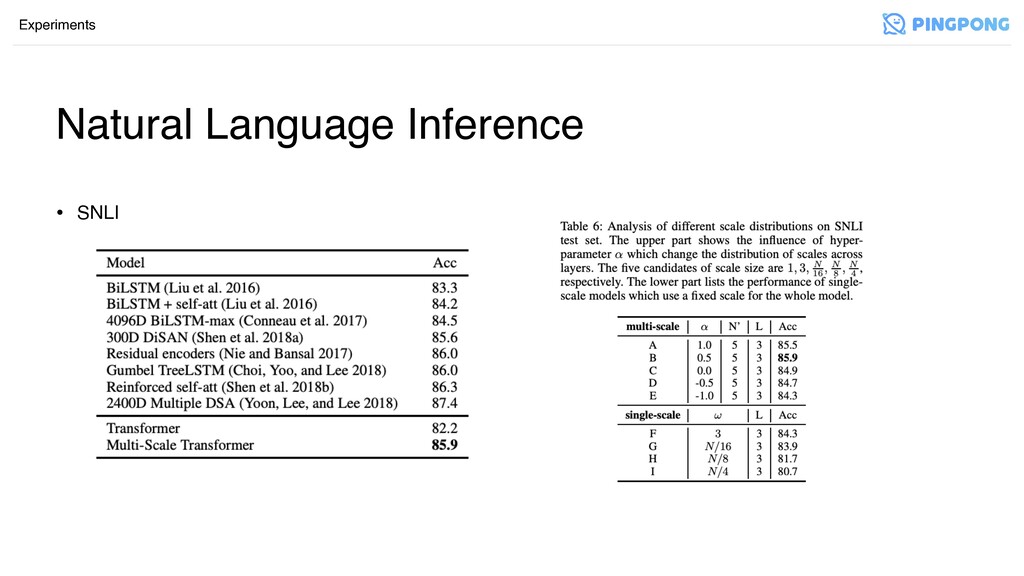
Natural Language Inference Experiments • SNLI
хࢎפ✌ ୶о ޙ ژח ҾӘೠ ݶ ઁٚ ইې োۅ۽
োۅ ࣁਃ! ߔ (ML Software Engineer, Pingpong)
[email protected]
More Decks by Scatter Lab Inc.
See All by Scatter Lab Inc.
zeta introduction
scatterlab
0
2.2k
SimCLR: A Simple Framework for Contrastive Learning of Visual Representations
scatterlab
0
4.6k
Adversarial Filters of Dataset Biases
scatterlab
0
2.3k
Sparse, Dense, and Attentional Representations for Text Retrieval
scatterlab
0
2.4k
Weight Poisoning Attacks on Pre-trained Models
scatterlab
0
2.2k
Approximate Nearest Neighbor Negative Contrastive Learning for Dense Text Retrieval
scatterlab
0
2.6k
Beyond Accuracy: Behavioral Testing of NLP Models with CheckList
scatterlab
0
2.4k
Open-Retrieval Conversational Question Answering
scatterlab
0
2.4k
What Can Neural Networks Reason About?
scatterlab
0
2.4k
Other Decks in Research
See All in Research
[WebDB2026]セレンディピティ指向推薦システム再考 ―セレンディピティの原義・類型・発生過程に基づく設計指針―
recsyslab
PRO
0
230
フィジカルAIの社会実装に向けて -AIエージェントからAgentic Roboticsへ-
hf149
1
2.8k
進化?迷走?CasualConc ファミリーアプリの現在地 @ 英語コーパス学会 2026
casualconc
0
160
Adapter les bergeries aux fortes chaleurs
institutdelelevage
PRO
0
180
生成AIなんでも展示会vol6 LT登壇資料 NexteraBERT
rikkabotan7
0
220
Kaggle|AI Agent Security — しくじり先生、俺みたいになるな
pomcho555
1
140
OWASP AISVS - C7
shiell
2
870
ros2-perf-multihost: 分散システムにおける客観的なアーキテクチャ評価フレームワーク
takasehideki
0
350
SAM3を用いたコマ・吹き出しの 領域検出と分割構造からの読み順推定
kzmssk
0
230
Evaluation génomique des femelles laitières croisées : comprendre la méthode pour accompagner les éleveurs à son utilisation
institutdelelevage
PRO
0
230
就労支援の現場での生成AI活用
enochan
0
220
Top 4セキュリティ会議に一通り論文が採択されるまでの道のりと展望 / Top 4 Security Grand Slam
takaomurakami
0
1.1k
Featured
See All Featured
Darren the Foodie - Storyboard
khoart
PRO
5
4.1k
DevOps and Value Stream Thinking: Enabling flow, efficiency and business value
helenjbeal
2
450
4 Signs Your Business is Dying
shpigford
187
23k
AI: The stuff that nobody shows you
jnunemaker
PRO
12
1.3k
Designing for humans not robots
tammielis
254
26k
HU Berlin: Industrial-Strength Natural Language Processing with spaCy and Prodigy
inesmontani
PRO
0
810
Highjacked: Video Game Concept Design
rkendrick25
PRO
2
580
Pawsitive SEO: Lessons from My Dog (and Many Mistakes) on Thriving as a Consultant in the Age of AI
davidcarrasco
1
300
Being A Developer After 40
akosma
PRO
92
590k
Responsive Adventures: Dirty Tricks From The Dark Corners of Front-End
smashingmag
254
23k
How to build an LLM SEO readiness audit: a practical framework
nmsamuel
2
990
Designing Dashboards & Data Visualisations in Web Apps
destraynor
232
55k


 scatterlab
 recsyslab
 hf149
 casualconc
 institutdelelevage
 rikkabotan7
 pomcho555
 shiell
 takasehideki
 kzmssk
 enochan
 takaomurakami
 khoart
 helenjbeal
 shpigford
 jnunemaker
 tammielis
 inesmontani
 rkendrick25
 davidcarrasco
 akosma
 smashingmag
 nmsamuel
 destraynor