Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
(CVPR2026) Back to Basics: Let Denoising Genera...
Search
Sponsored
·
Your Podcast. Everywhere. Effortlessly.
Share. Educate. Inspire. Entertain. You do you. We'll handle the rest.
→
Shumpei Takezaki
June 09, 2026
Science
480
0
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
(CVPR2026) Back to Basics: Let Denoising Generative Models Denoise
https://arxiv.org/abs/2511.13720
Shumpei Takezaki
June 09, 2026
Transcript
12 slides
拡散モデルには画像を予測させよ 2026.06.09 Shumpei Takezaki
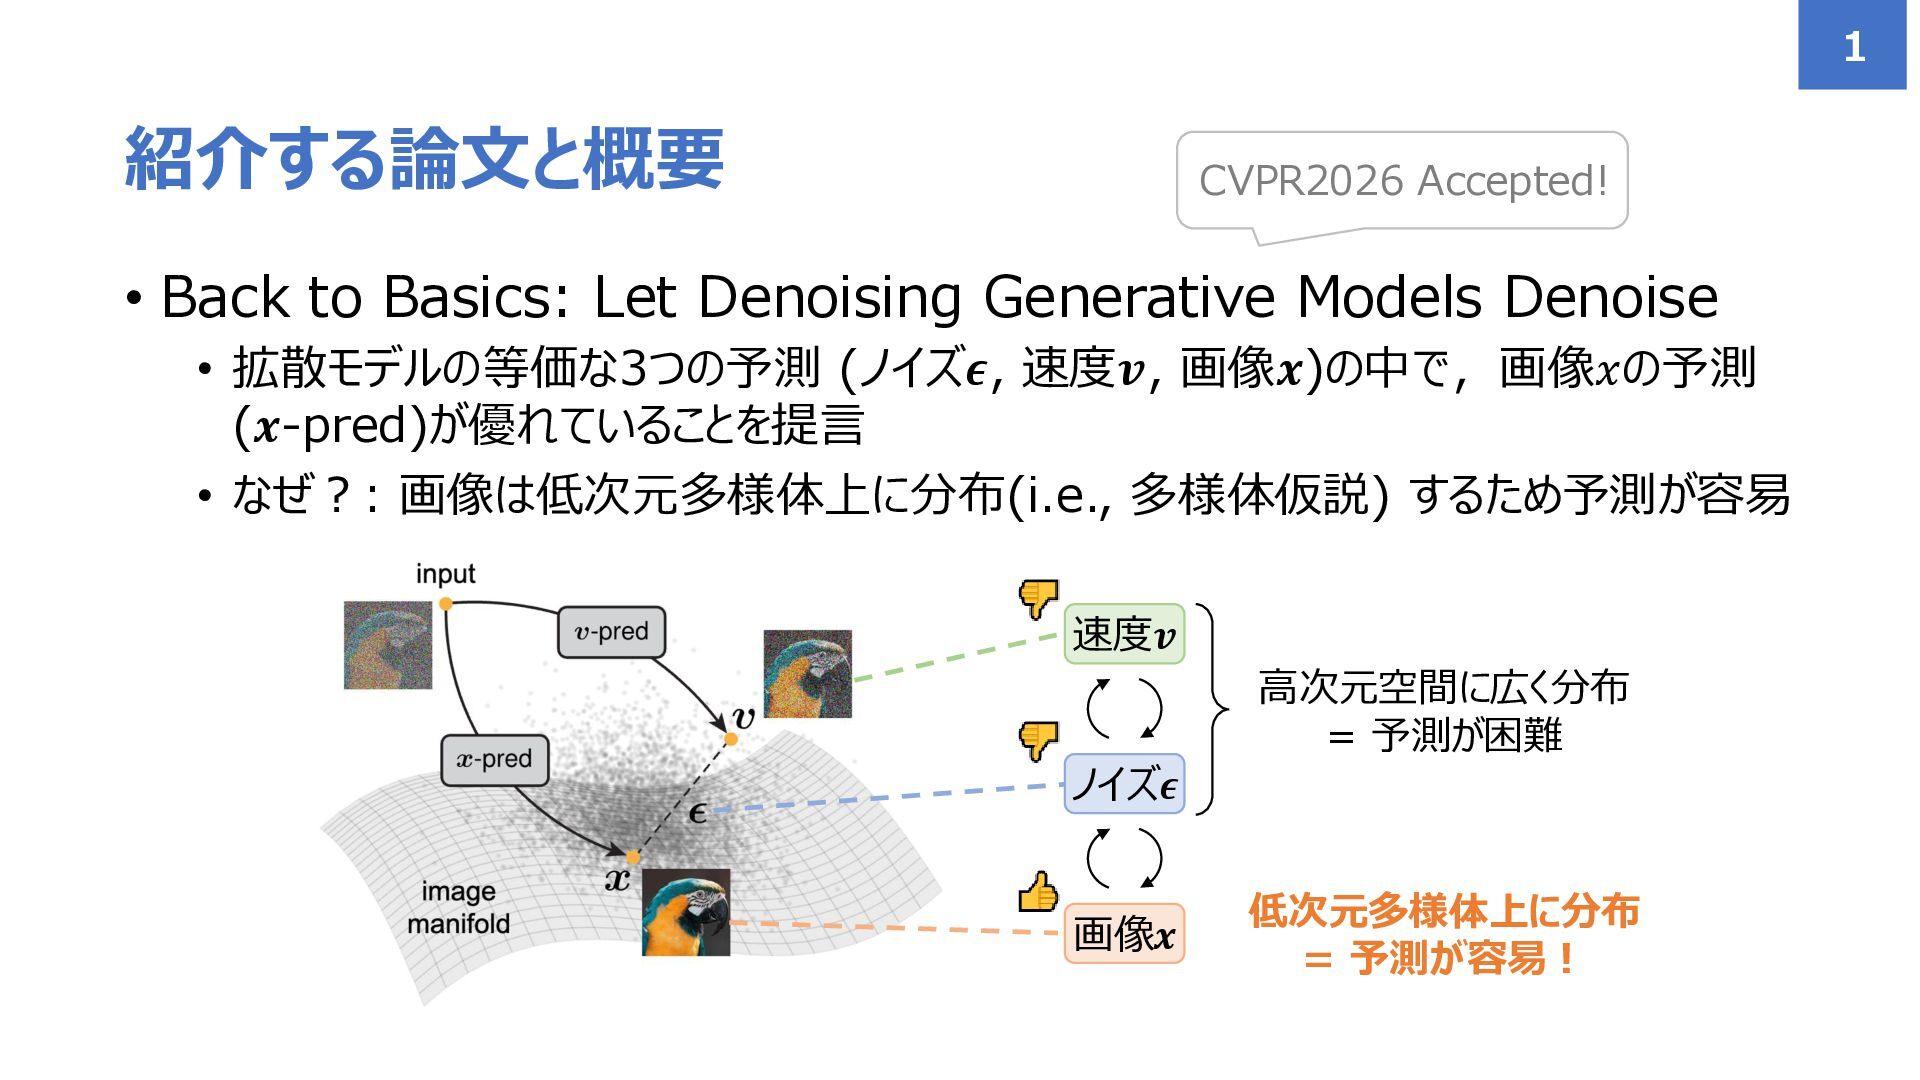
• Back to Basics: Let Denoising Generative Models Denoise •
拡散モデルの等価な3つの予測 (ノイズ𝝐, 速度𝒗, 画像𝒙)の中で,画像𝑥の予測 (𝒙-pred)が優れていることを提言 • なぜ?: 画像は低次元多様体上に分布(i.e., 多様体仮説) するため予測が容易 紹介する論文と概要 1 CVPR2026 Accepted! 画像𝒙 ノイズ𝝐 速度𝒗 高次元空間に広く分布 = 予測が困難 低次元多様体上に分布 = 予測が容易!
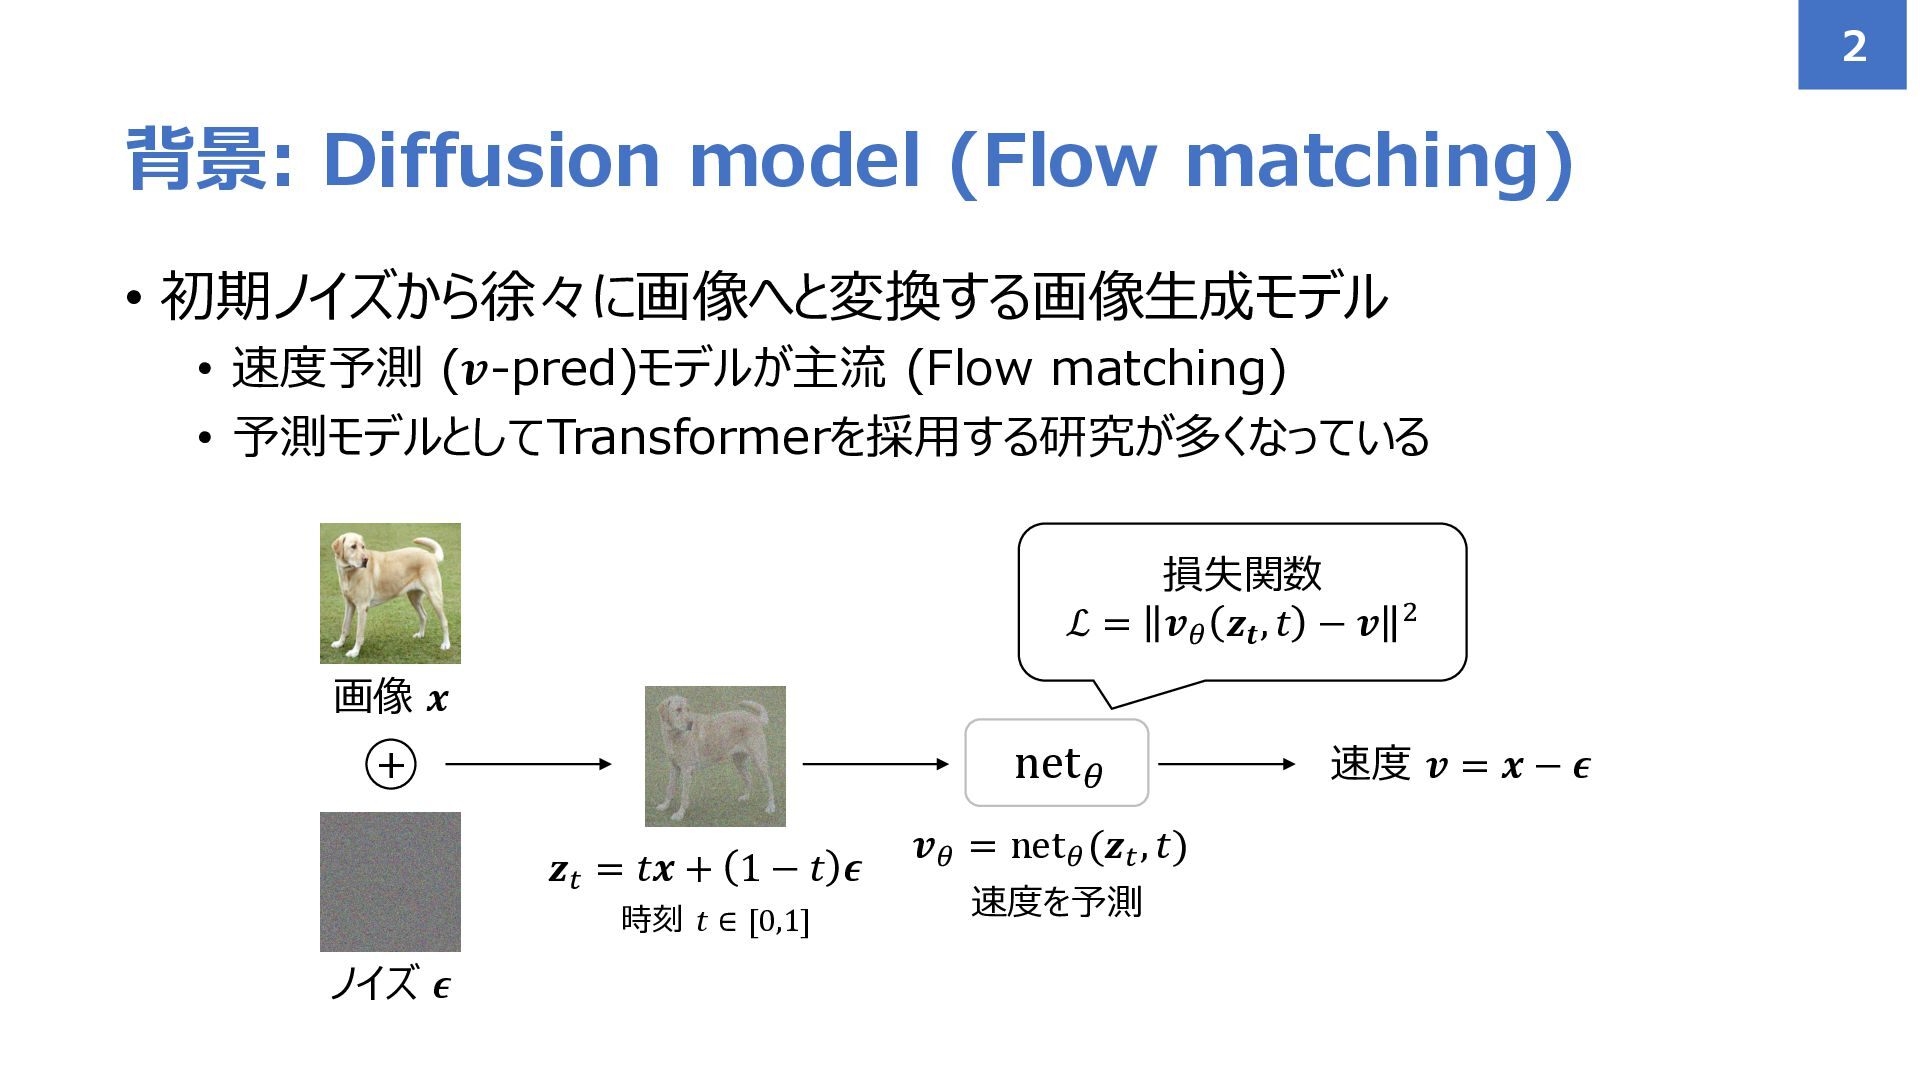
• 初期ノイズから徐々に画像へと変換する画像生成モデル • 速度予測 (𝒗-pred)モデルが主流 (Flow matching) • 予測モデルとしてTransformerを採用する研究が多くなっている 背景:
Diffusion model (Flow matching) 2 画像 𝒙 ノイズ 𝝐 net𝜃 𝒛𝑡 = 𝑡𝒙 + 1 − 𝑡 𝝐 時刻 𝑡 ∈ [0,1] + 速度 𝒗 = 𝒙 − 𝝐 損失関数 ℒ = 𝒗𝜃 𝒛𝒕 , 𝑡 − 𝒗 2 𝒗𝜃 = net𝜃 (𝒛𝑡 , 𝑡) 速度を予測
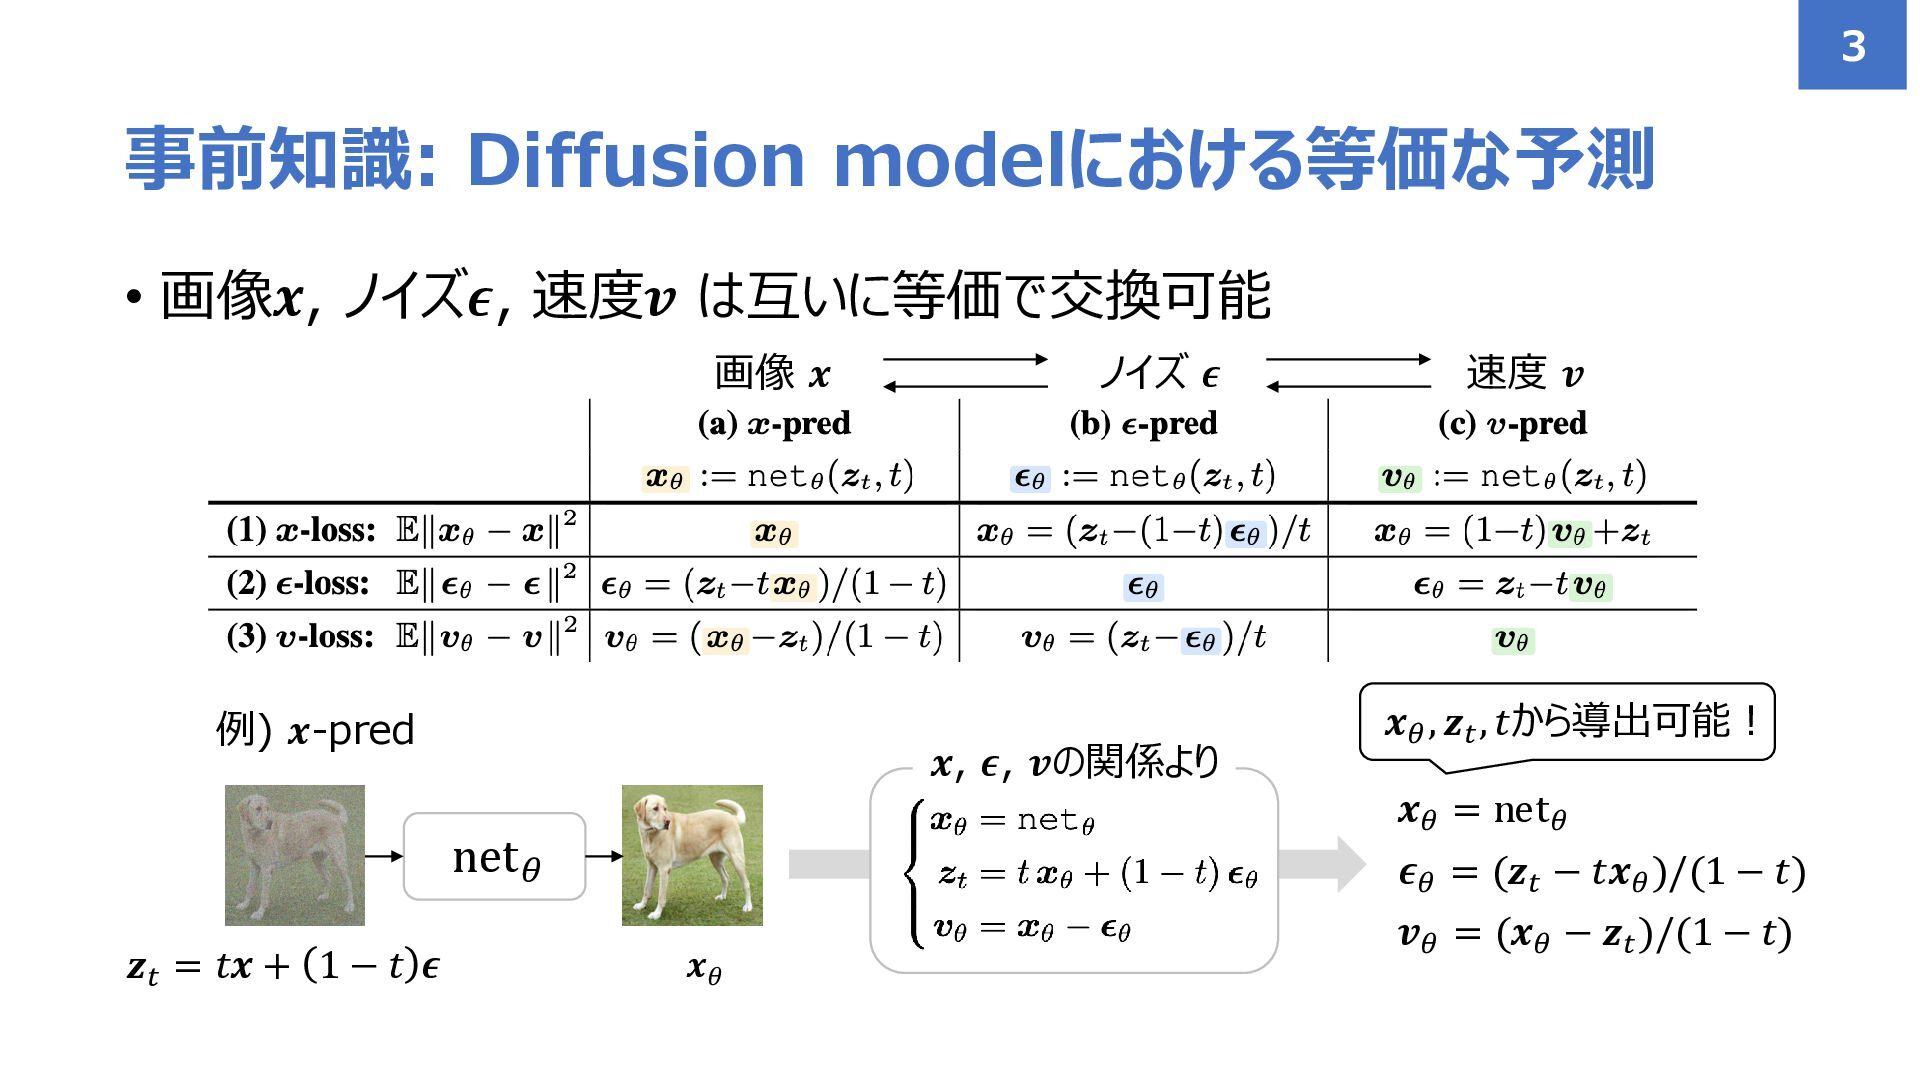
• 画像𝒙, ノイズ𝝐, 速度𝒗 は互いに等価で交換可能 事前知識: Diffusion modelにおける等価な予測 3 画像
𝒙 ノイズ 𝝐 速度 𝒗 net𝜃 例) 𝒙-pred 𝒛𝑡 = 𝑡𝒙 + 1 − 𝑡 𝝐 𝒙𝜃 𝒙𝜃 = net𝜃 𝝐𝜃 = (𝒛𝑡 − 𝑡𝒙𝜃 )/(1 − 𝑡) 𝒗𝜃 = (𝒙𝜃 − 𝒛𝑡 )/(1 − 𝑡) 𝒙, 𝝐, 𝒗の関係より 𝒙𝜃 , 𝒛𝑡 , 𝑡から導出可能!
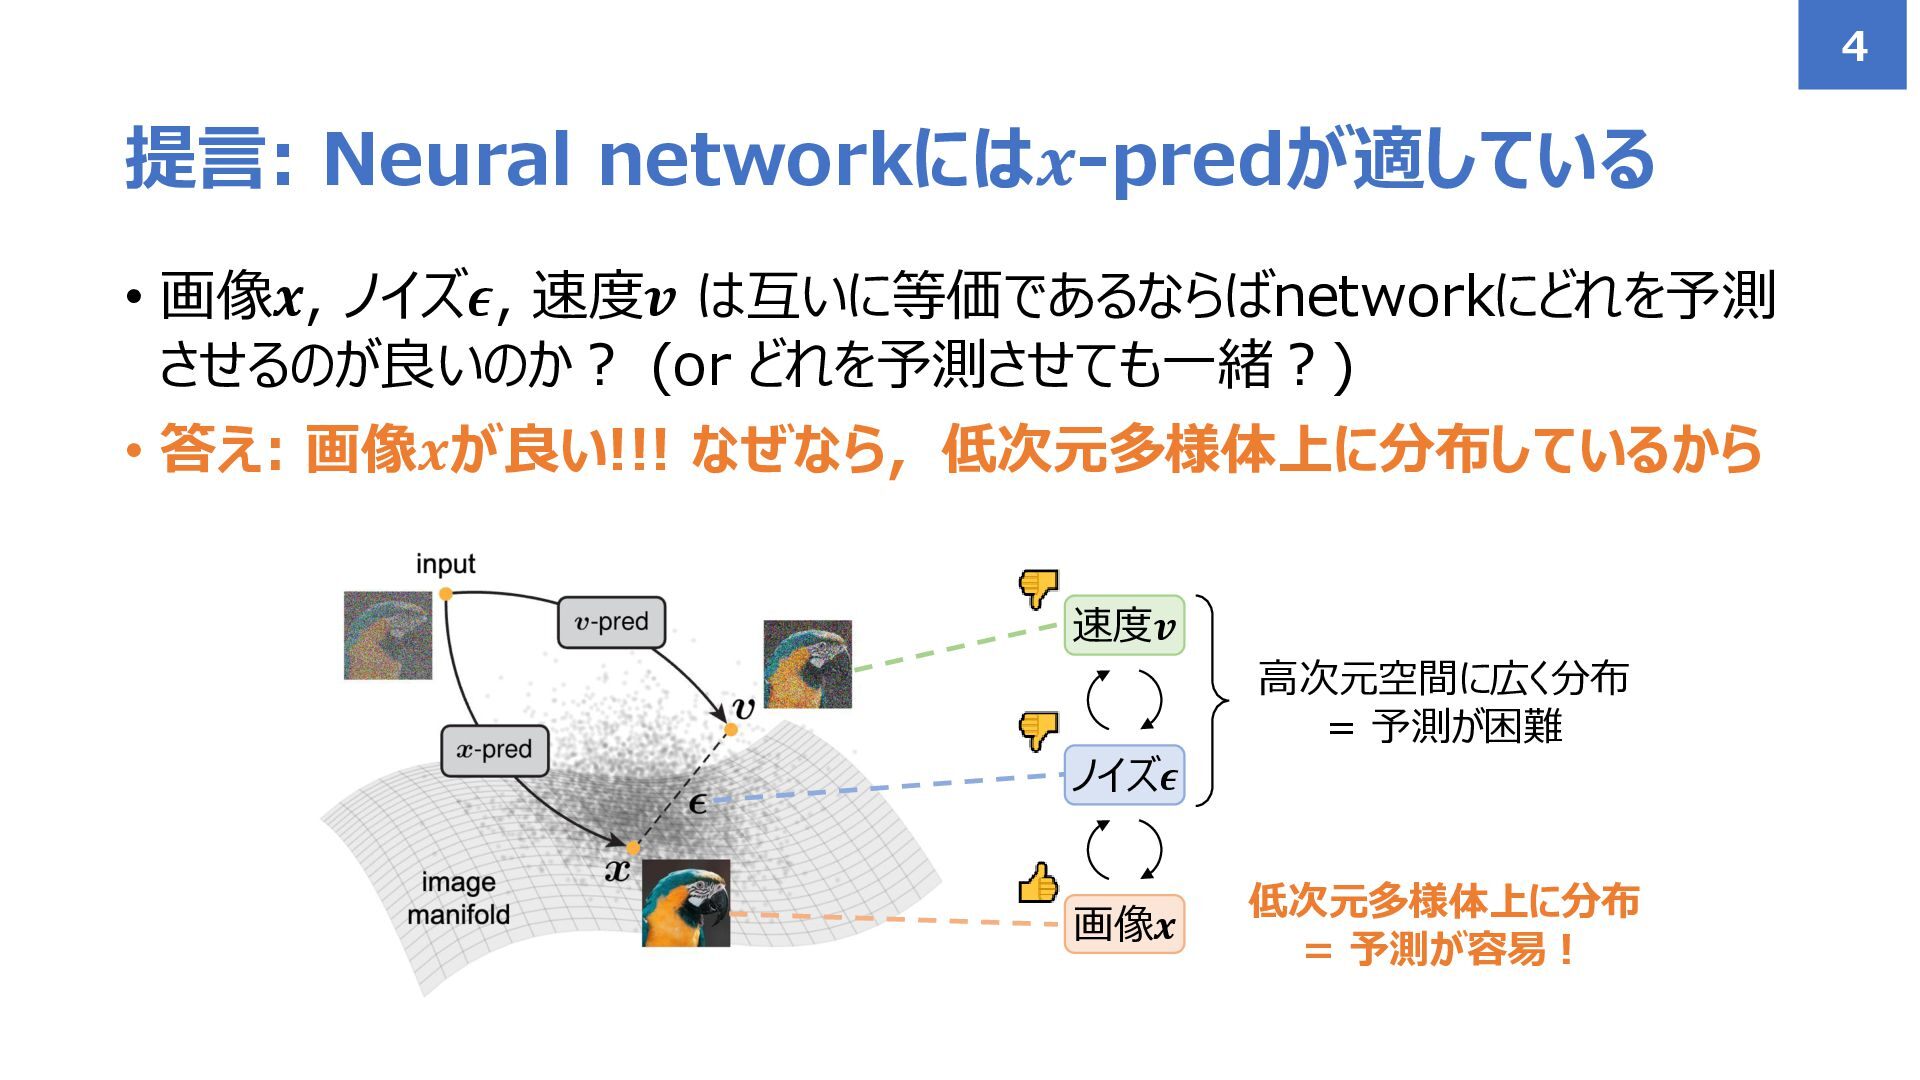
• 画像𝒙, ノイズ𝝐, 速度𝒗 は互いに等価であるならばnetworkにどれを予測 させるのが良いのか? (or どれを予測させても一緒?) • 答え:
画像𝒙が良い!!! なぜなら,低次元多様体上に分布しているから 提言: Neural networkには𝒙-predが適している 4 画像𝒙 ノイズ𝝐 速度𝒗 高次元空間に広く分布 = 予測が困難 低次元多様体上に分布 = 予測が容易!
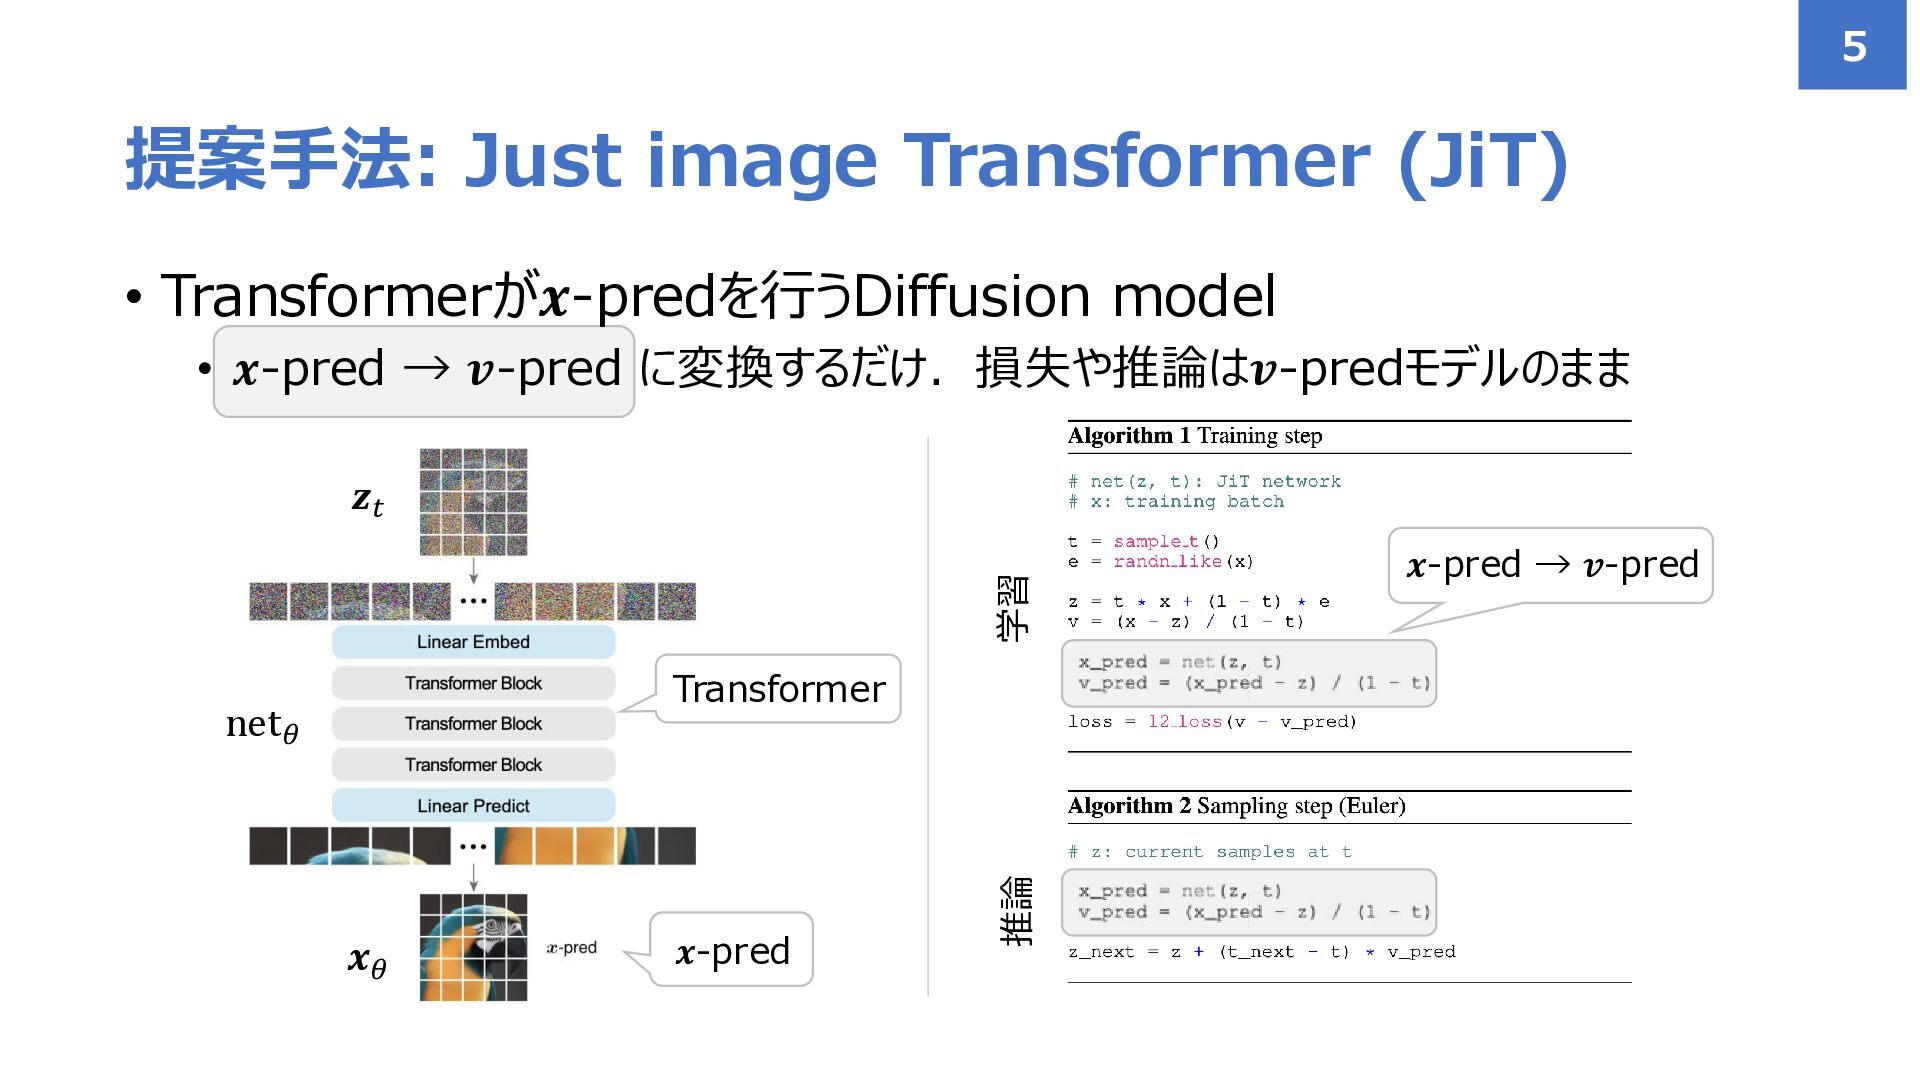
• Transformerが𝒙-predを行うDiffusion model • 𝒙-pred → 𝒗-pred に変換するだけ.損失や推論は𝒗-predモデルのまま 提案手法: Just
image Transformer (JiT) 5 𝒛𝑡 𝒙𝜃 net𝜃 𝒙-pred Transformer 𝒙-pred → 𝒗-pred 学習 推論
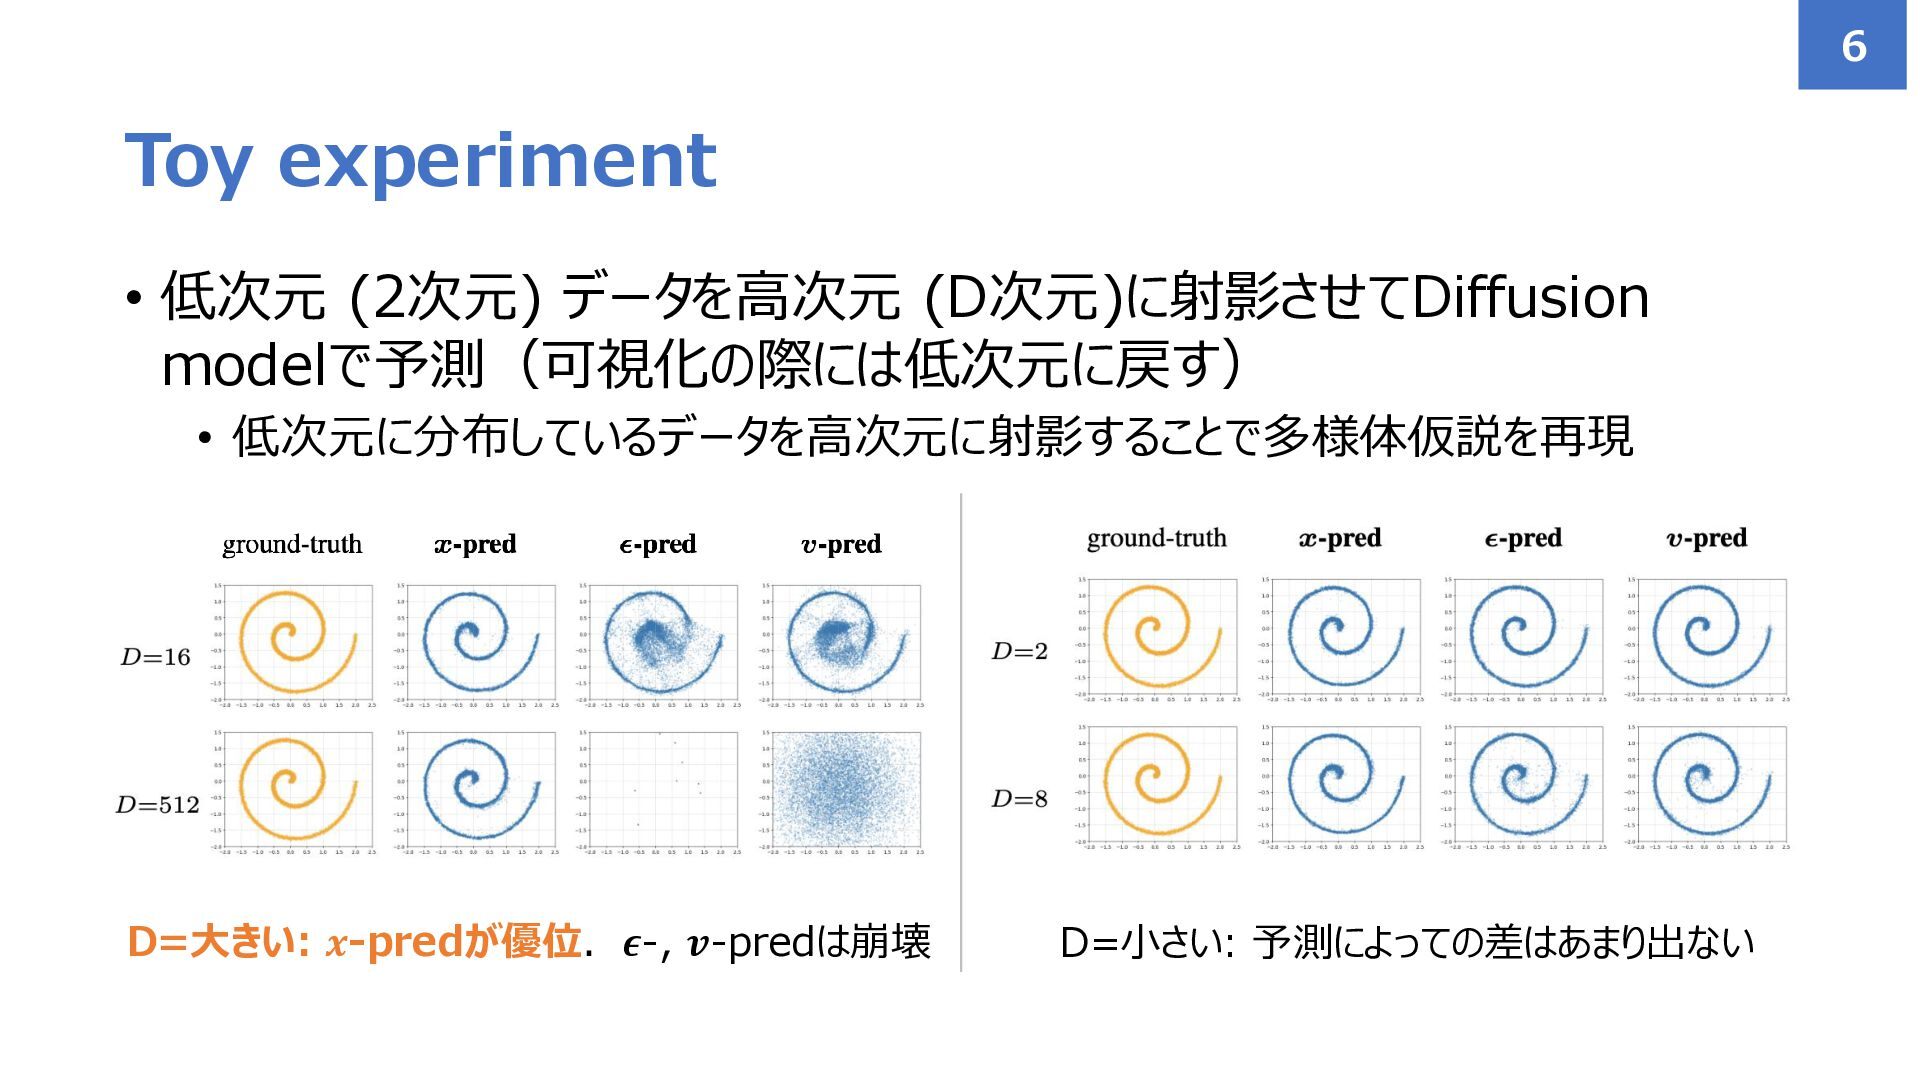
• 低次元 (2次元) データを高次元 (D次元)に射影させてDiffusion modelで予測(可視化の際には低次元に戻す) • 低次元に分布しているデータを高次元に射影することで多様体仮説を再現 Toy experiment
6 D=小さい: 予測によっての差はあまり出ない D=大きい: 𝒙-predが優位.𝝐-, 𝒗-predは崩壊
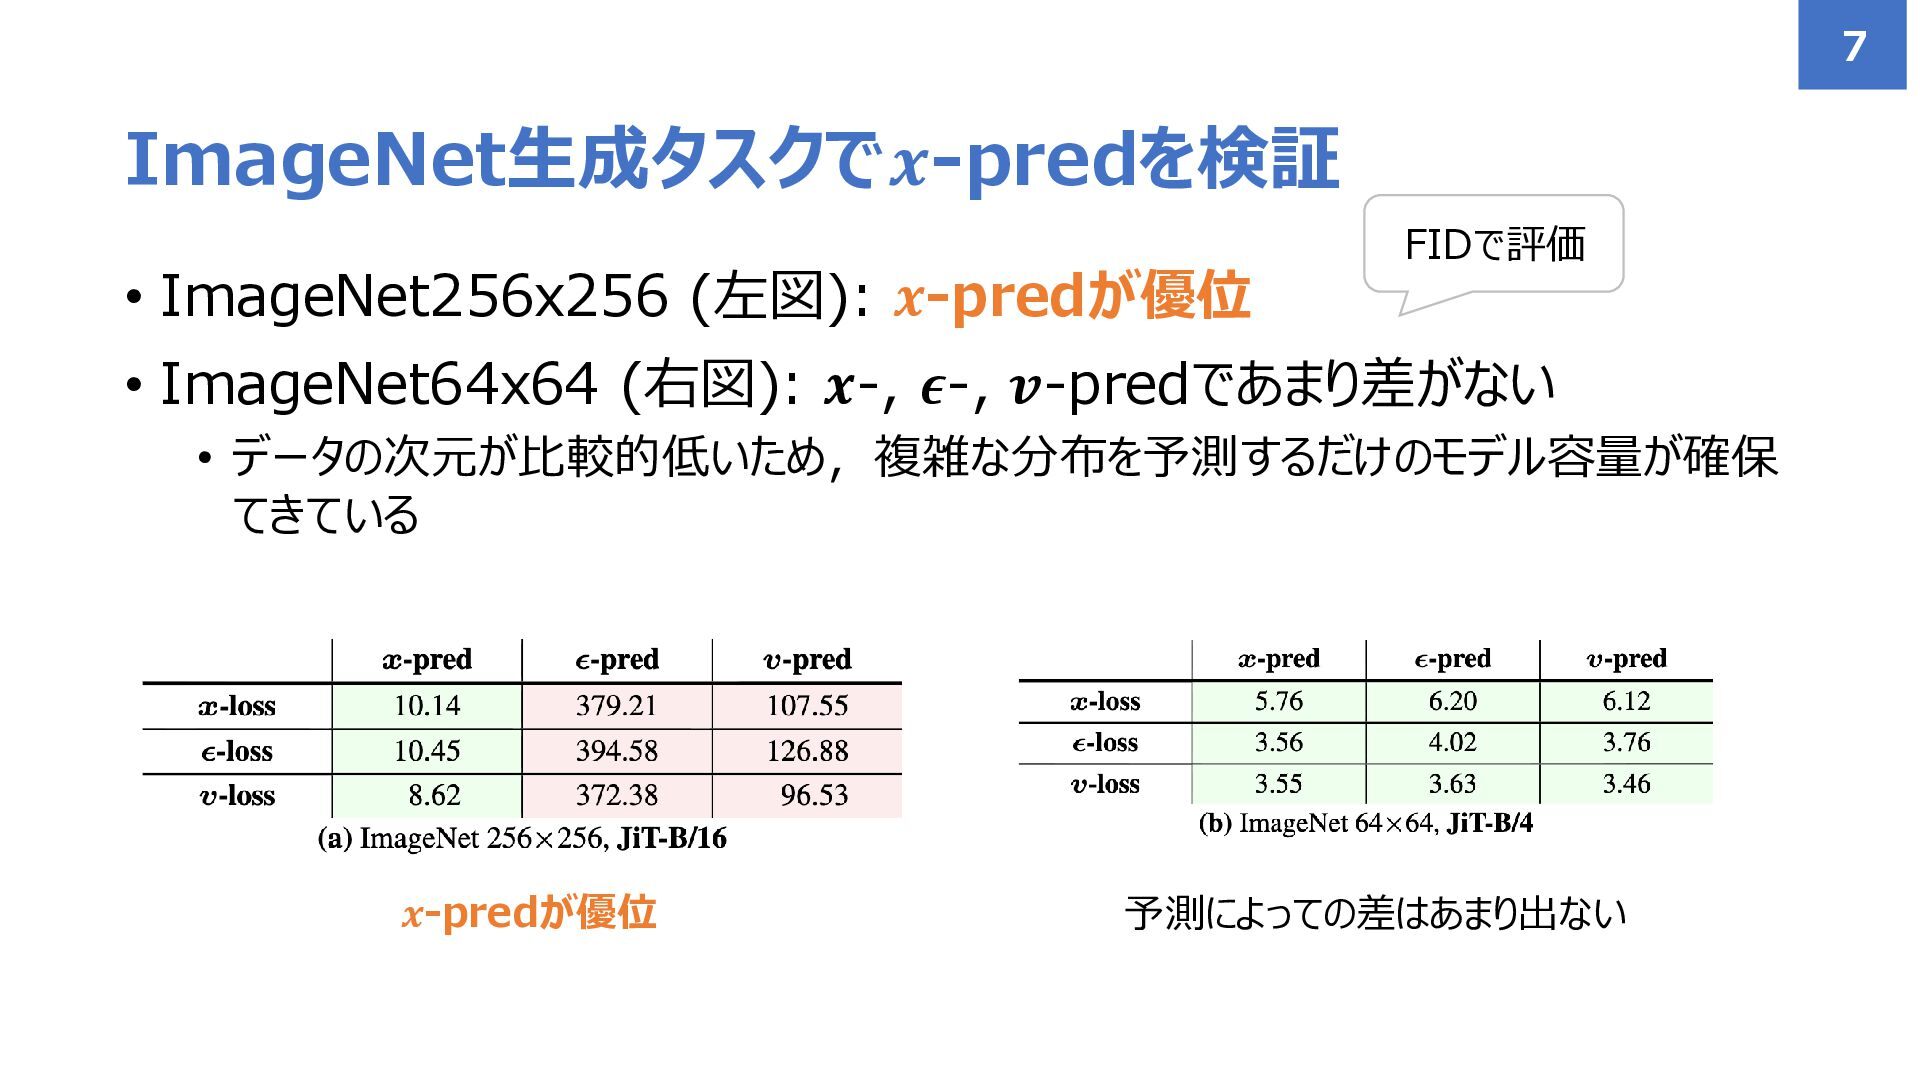
• ImageNet256x256 (左図): 𝒙-predが優位 • ImageNet64x64 (右図): 𝒙-, 𝝐-, 𝒗-predであまり差がない
• データの次元が比較的低いため,複雑な分布を予測するだけのモデル容量が確保 てきている ImageNet生成タスクで𝒙-predを検証 7 FIDで評価 𝒙-predが優位 予測によっての差はあまり出ない
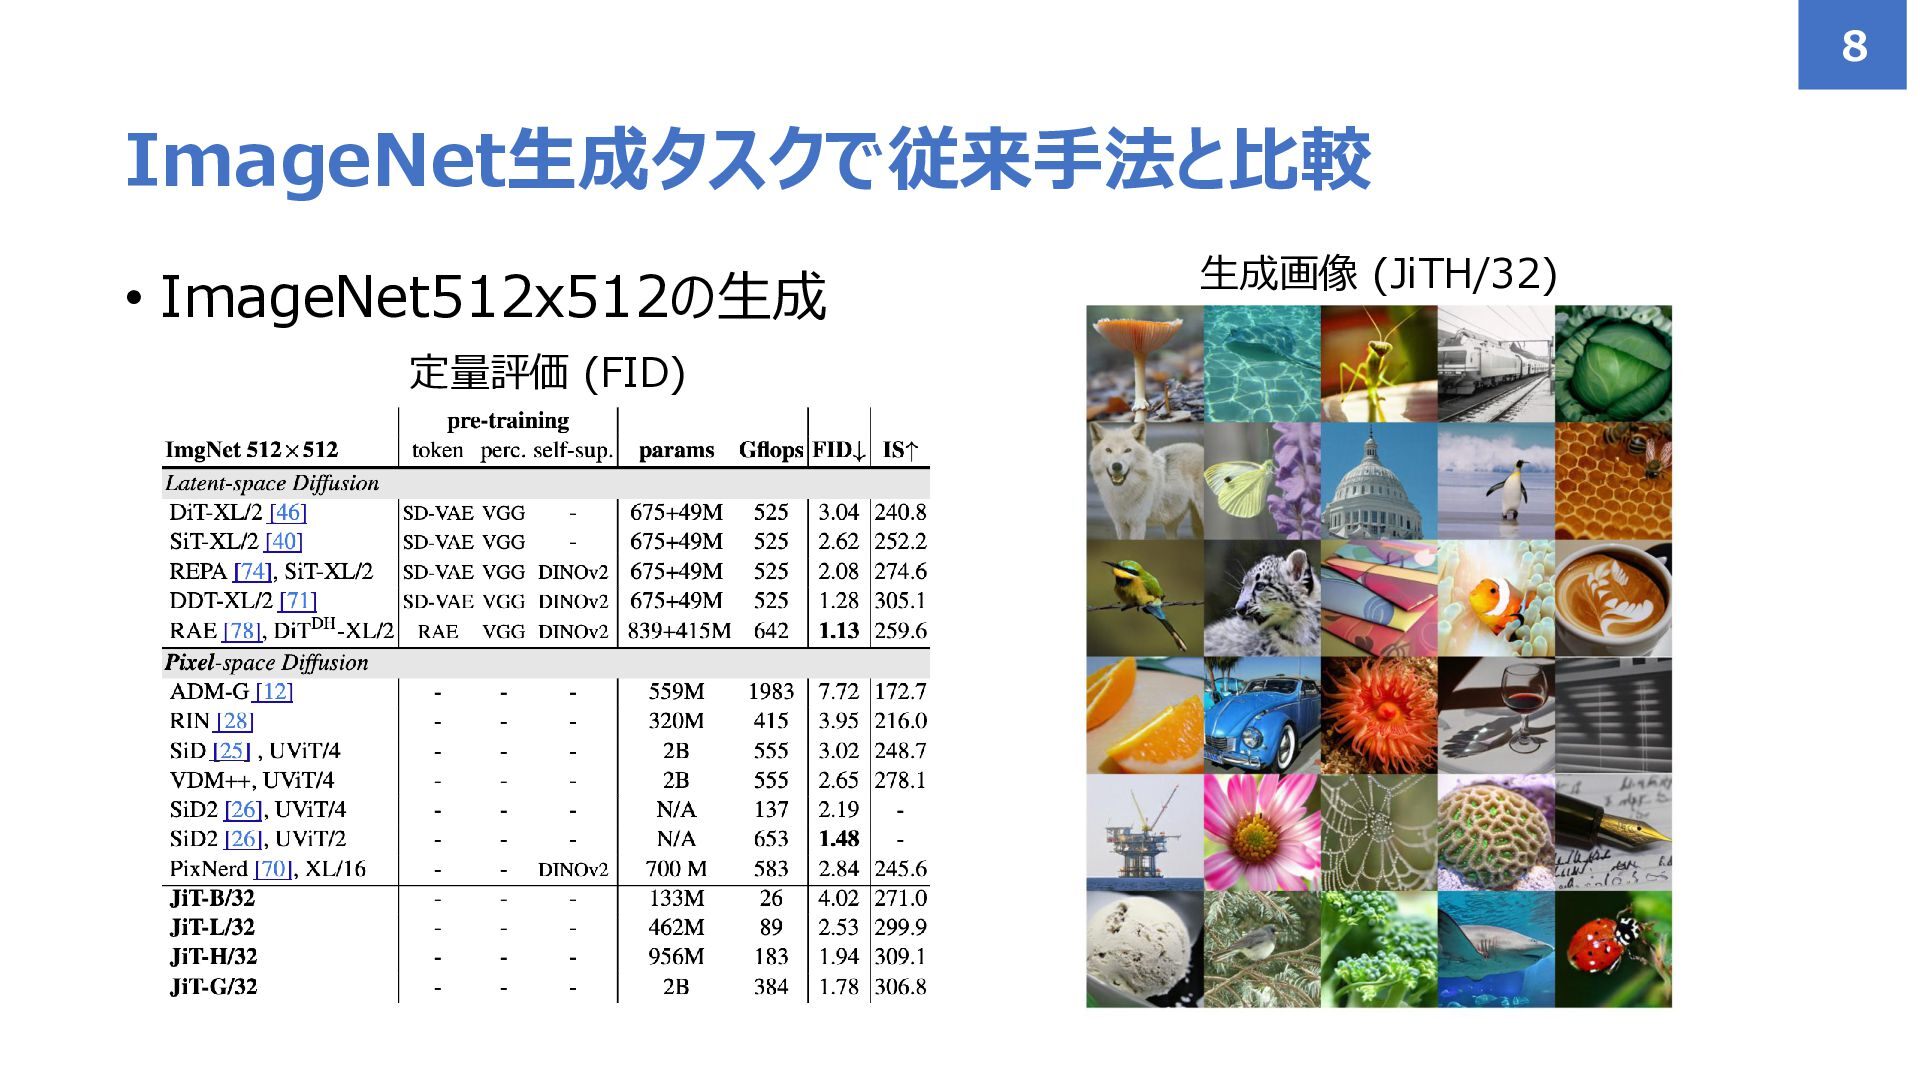
• ImageNet512x512の生成 ImageNet生成タスクで従来手法と比較 8 生成画像 (JiTH/32) 定量評価 (FID)
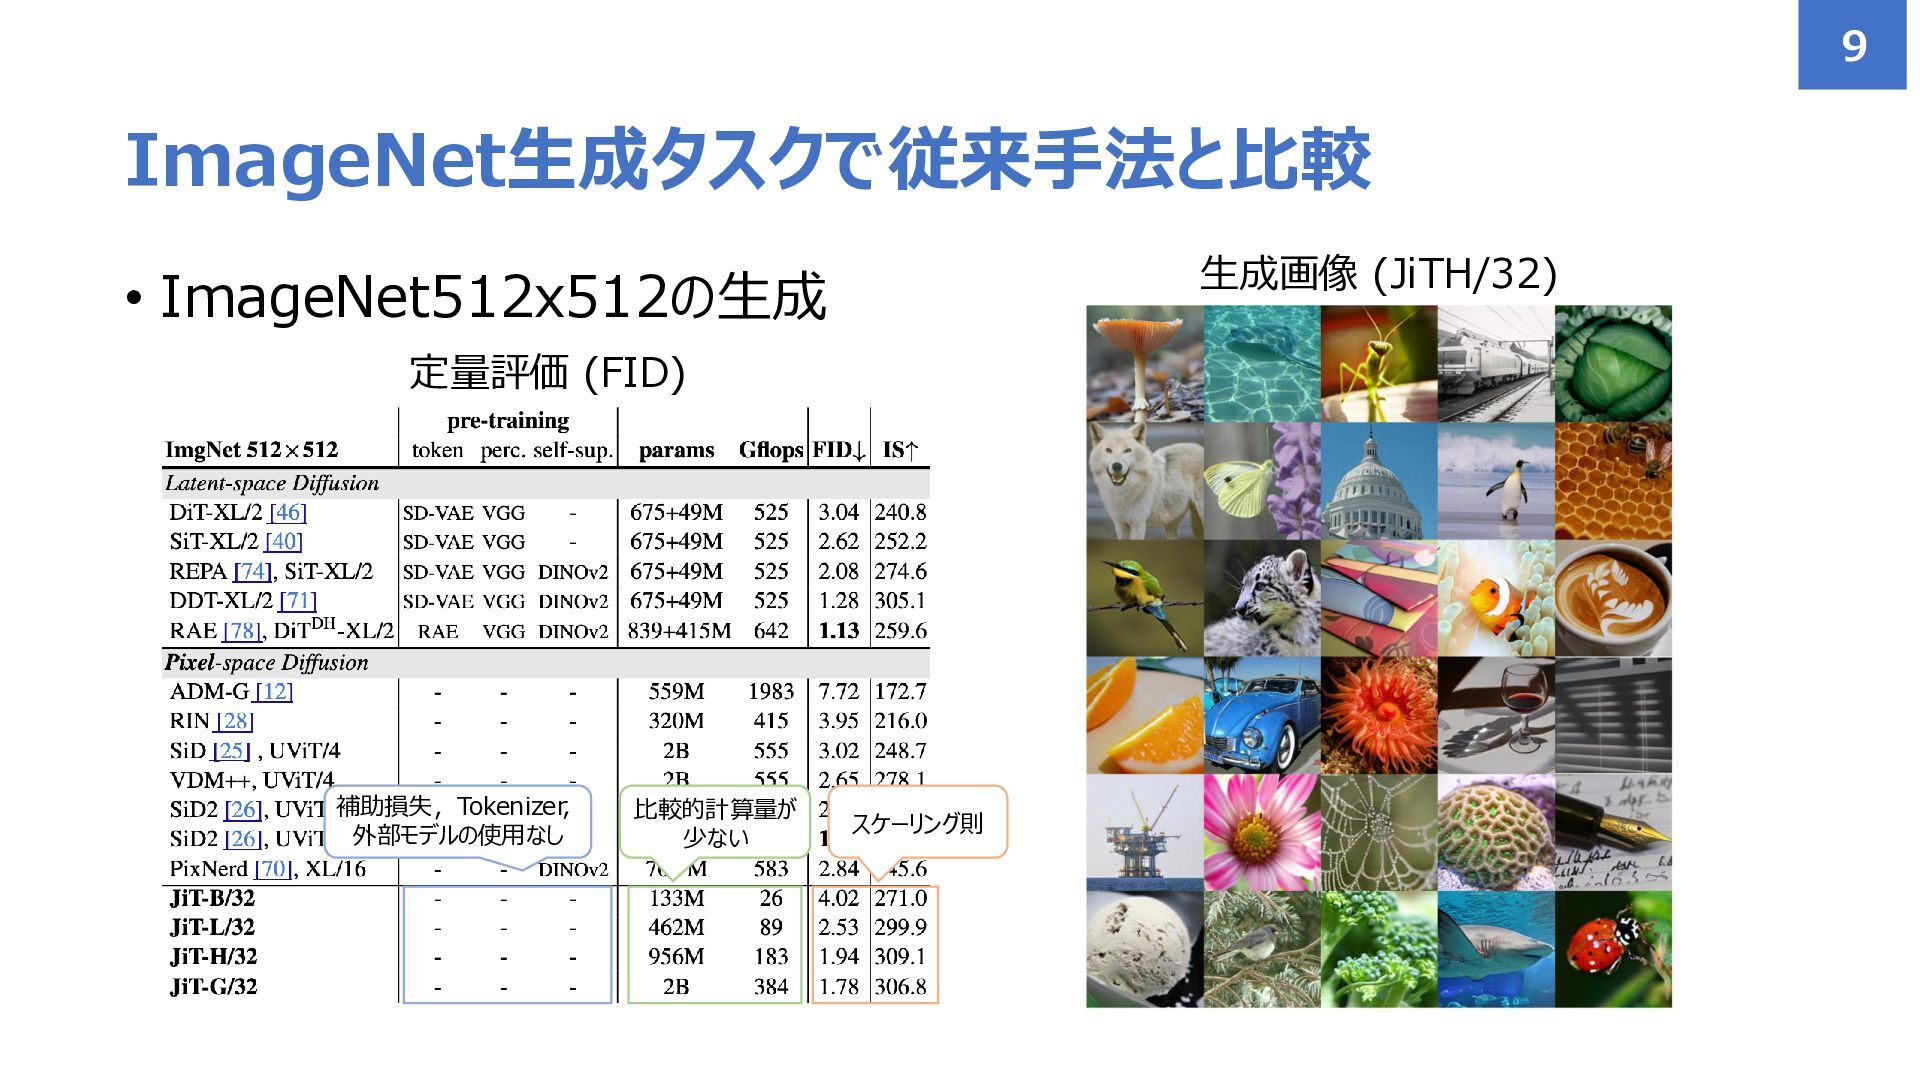
• ImageNet512x512の生成 ImageNet生成タスクで従来手法と比較 9 生成画像 (JiTH/32) 定量評価 (FID) 補助損失,Tokenizer, 外部モデルの使用なし
比較的計算量が 少ない スケーリング則
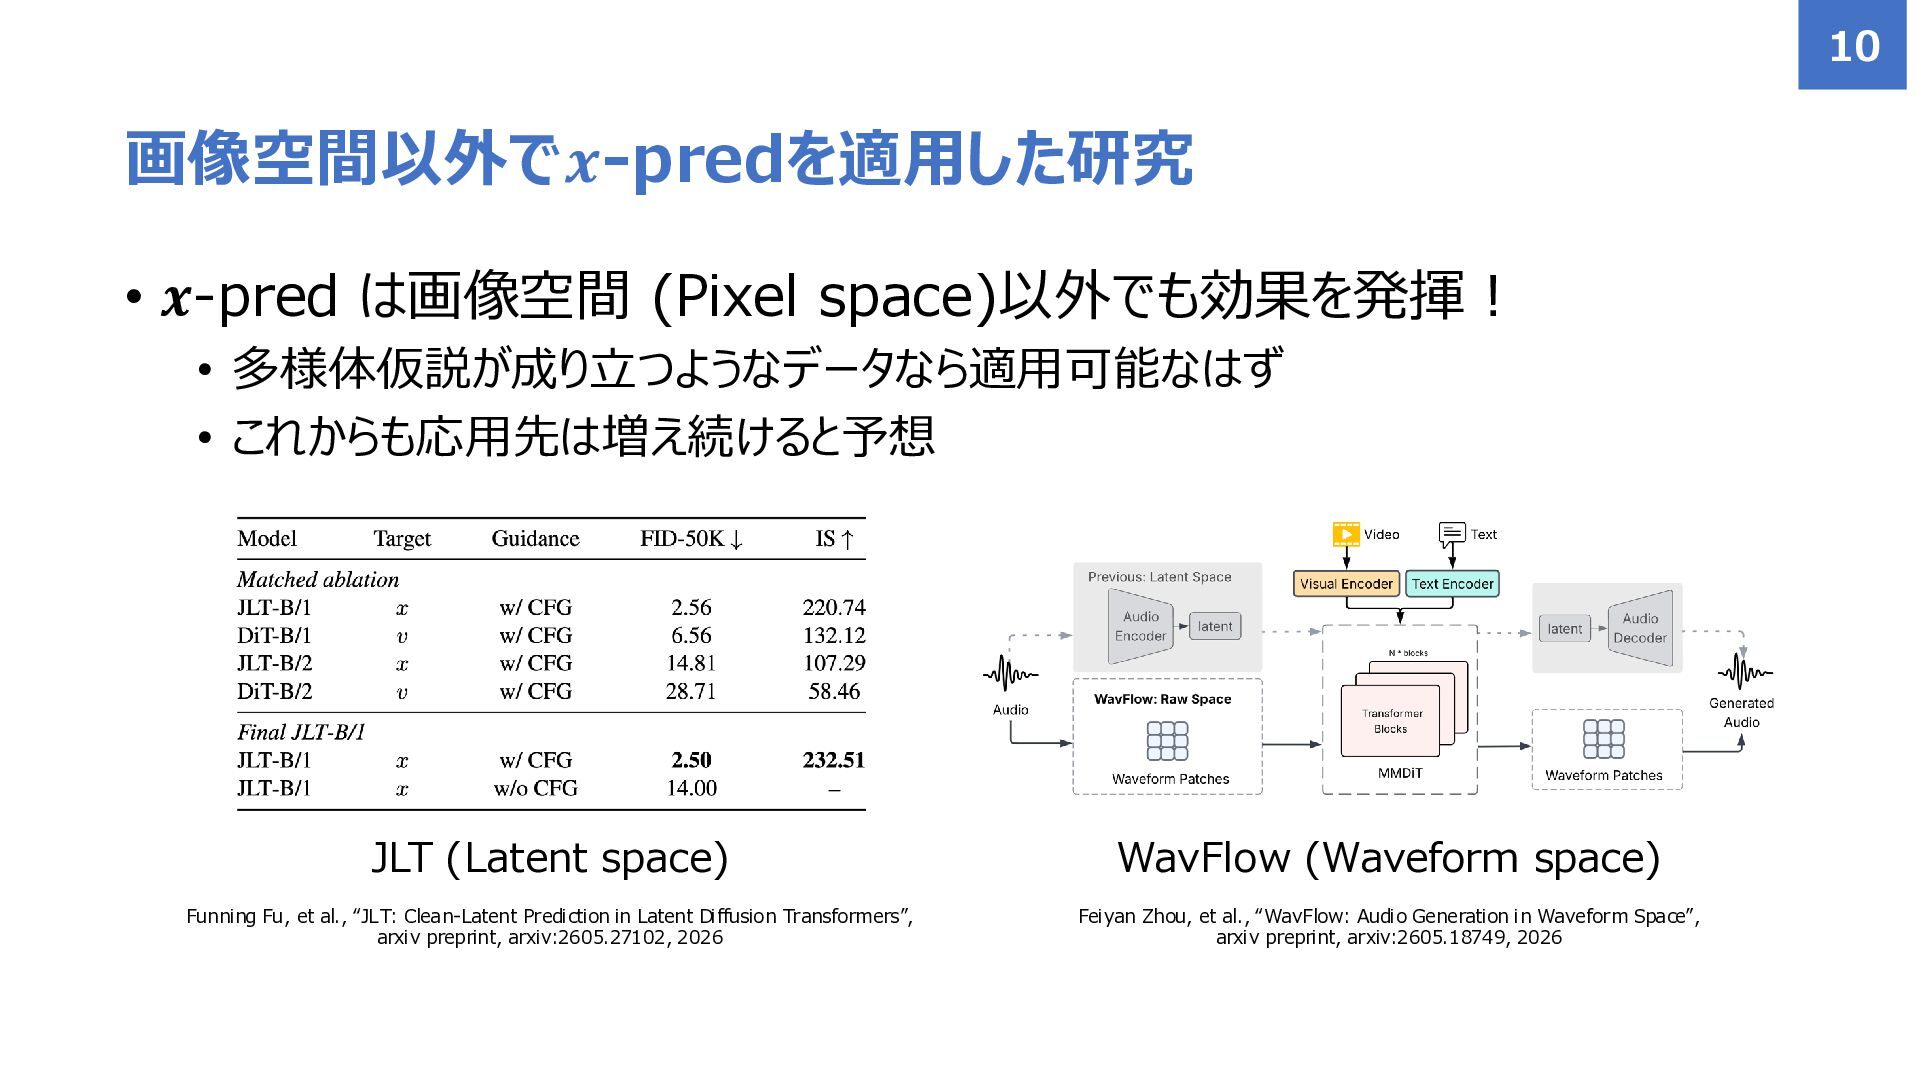
• 𝒙-pred は画像空間 (Pixel space)以外でも効果を発揮! • 多様体仮説が成り立つようなデータなら適用可能なはず • これからも応用先は増え続けると予想 画像空間以外で𝒙-predを適用した研究
10 WavFlow (Waveform space) JLT (Latent space) Funning Fu, et al., “JLT: Clean-Latent Prediction in Latent Diffusion Transformers”, arxiv preprint, arxiv:2605.27102, 2026 Feiyan Zhou, et al., “WavFlow: Audio Generation in Waveform Space”, arxiv preprint, arxiv:2605.18749, 2026
• まとめ • 拡散モデルの等価な3つの予測 (ノイズ𝝐, 速度𝒗, 画像𝒙)の中で,画像𝑥の予測 (𝒙-pred)が優れていることを提言 • 画像は低次元多様体上に分布(i.e.,
多様体仮説) するため予測が容易であるこ とがその要因 • Latent space, Waveform spaceでも機能することが報告 • 感想 • シンプルな提言 (拡散モデルで何を予測するのか?)かつインパクトのある結果 • 美しい まとめ 11
More Decks by Shumpei Takezaki
See All by Shumpei Takezaki
(IJCNN2026) Cell Instance Segmentation via Multi-Task Image-to-Image Schrödinger Bridge
shumpei777
0
45
(IJCNN2026) SCoRe: Clean Image Generation from Diffusion Models Trained on Noisy Images
shumpei777
0
47
(Preprint) Diffusion Transformers with Representation Autoencoders
shumpei777
1
1.3k
(Blog post) Diffusion is spectral autoregression
shumpei777
3
1.5k
(Preprint) Diffusion Classifiers Understand Compositionality, but Conditions Apply
shumpei777
2
710
(ICLR2021) Score-Based Generative Modeling through Stochastic Differential Equations
shumpei777
1
760
(ICLR2023) Improving Deep Regression with Ordinal Entropy
shumpei777
0
75
(NeurIPS2024) Guiding a Diffusion Model with a Bad Version of Itself
shumpei777
0
71
(ICML2023) I2SB: Image-to-Image Schrödinger Bridge
shumpei777
0
98
Other Decks in Science
See All in Science
データベース09: 実体関連モデル上の一貫性制約
trycycle
PRO
0
1.9k
Засідання студентського наукового гуртка «Садово-паркове господарство»
mariiabarkan12
0
120
Path integral polarons for real semiconductors
jarvist
0
130
自社のレビュー履歴からAIコードレビュアーをつくる方法
estie
5
2k
薬学部出身の新卒営業がAmazon Bio Discoveryで自由研究してみた!
kusunokikeisuke
0
260
Utiliser Bitcoin sans Internet
rlifchitz
0
460
TypeScript で WebAssembly を用いた 型安全なプラグイン設計
nagano
3
700
データベース14: B+木 & ハッシュ索引
trycycle
PRO
0
1k
O(log n)-Approximation Algorithms for Bipartiteness Ratio
tasusu
0
320
CVPR2026_VGGTとその仲間たち
mickey_0226
0
1.3k
第67回コンピュータビジョン勉強会論文紹介「RoboWheel: A Data Engine from Real-World Human Demonstrations for Cross-Embodiment Robotic Learning」
x_ttyszk
0
260
Cognitive Debt - What AI will do to us
martinlippert
1
150
Featured
See All Featured
How to build a perfect <img>
jonoalderson
1
6.2k
Mobile First: as difficult as doing things right
swwweet
225
10k
Measuring & Analyzing Core Web Vitals
bluesmoon
9
1.1k
Google's AI Overviews - The New Search
badams
0
1.7k
What the history of the web can teach us about the future of AI
inesmontani
PRO
3
820
Applied NLP in the Age of Generative AI
inesmontani
PRO
4
2.6k
Well, that’s weird…
csswizardry
1
110
CoffeeScript is Beautiful & I Never Want to Write Plain JavaScript Again
sstephenson
162
16k
Fight the Zombie Pattern Library - RWD Summit 2016
marcelosomers
234
18k
Navigating the moral maze — ethical principles for Al-driven product design
skipperchong
2
690
Web Performance Is a Journey [PerfNow 2026]
tammyeverts
1
53
Navigating the Design Leadership Dip - Product Design Week Design Leaders+ Conference 2024
apolaine
2
530


 shumpei777
 trycycle
 mariiabarkan12
 jarvist
 estie
 kusunokikeisuke
 rlifchitz
 nagano
 tasusu
 mickey_0226
 x_ttyszk
 martinlippert
 jonoalderson
 swwweet
 bluesmoon
 badams
 inesmontani
 csswizardry
 sstephenson
 marcelosomers
 skipperchong
 tammyeverts
 apolaine