Share
Embed
How do we do Benchmark? Impressions from Conversations with the Community
Stefan Marr
September 30, 2021
Transcript
35 slides
-
How do we do Benchmark? Impressions from Conversations with the
Community VMM’21, Virtual Stefan Marr -
What are we doing? and What are we struggling with?
I had a different ques/on 7 -
Outline 1. My Interview Methodology 2. Some Anecdotes 3. Our
struggles 4. Our best prac/ces 8 -
My Methodology • 21 interviews • With groups in the
field of “programming languages and systems” • .ny sample • not representa.ve 11 -
My Methodology • 21 interviews • With groups in the
field of “programming languages and systems” • Semi-structured interviews • .ny sample • not representa.ve • not the same for all interviews 12 -
My Methodology • 21 interviews • With groups in the
field of “programming languages and systems” • Semi-structured interviews • Ad hoc result analysis • tiny sample • not representative • not the same for all interviews • Interpretation biases 13 -
Use of Automated Test, Continuous Integration Do you use some
form of automated tes/ng/CI? 15 Using Zoom’s Reactions likely at the bottom of the screen -
Use of Automated Test, Con=nuous Integra=on Do you use some
form of automated tes/ng/CI? 16 Using Zoom’s Reactions likely at the bottom of the screen 👏 yes ❤ some=mes 😮 no -
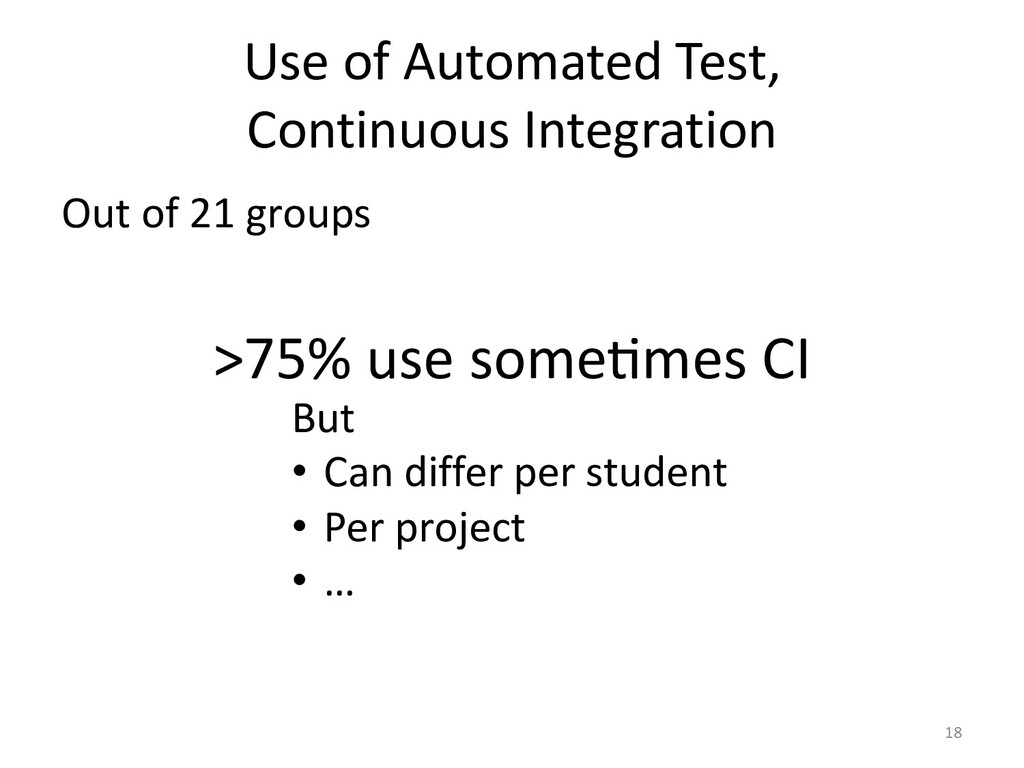
Use of Automated Test, Con=nuous Integra=on Out of 21 groups
>75% use some0mes CI 17 -
Use of Automated Test, Continuous Integration Out of 21 groups
>75% use some0mes CI 18 But • Can differ per student • Per project • … -
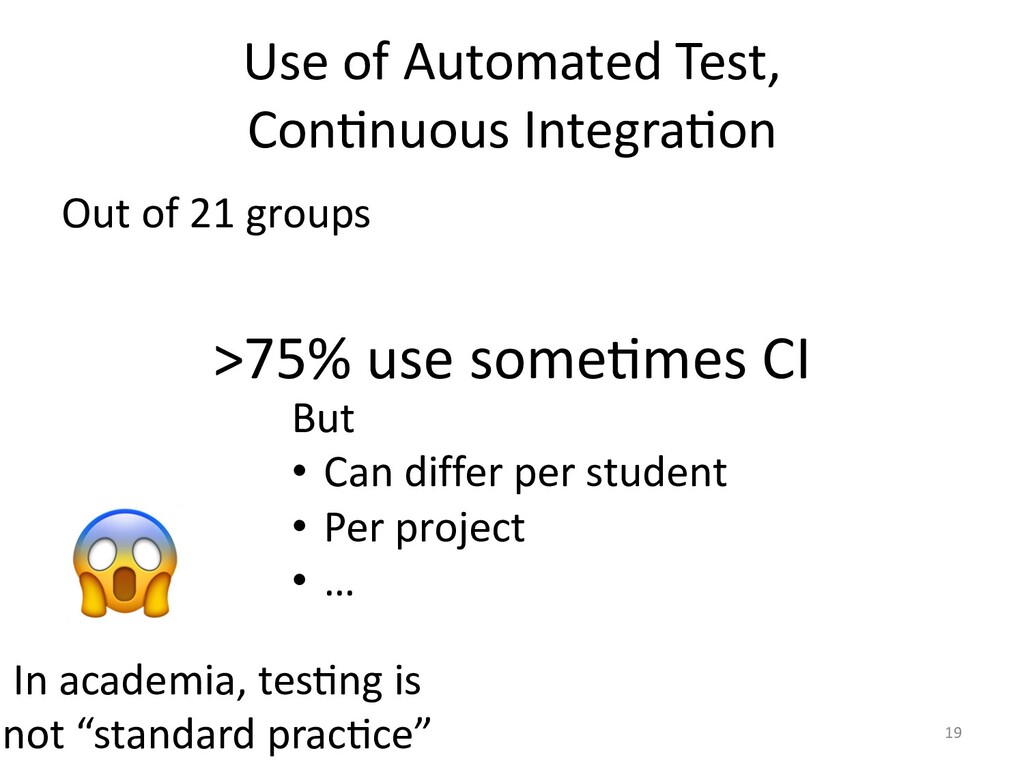
Use of Automated Test, Con=nuous Integra=on Out of 21 groups
>75% use some0mes CI 19 But • Can differ per student • Per project • … 😱 In academia, tes/ng is not “standard prac/ce” -
Benchmarking and Frequency Do you run benchmarks for your day-to-day
engineering? 20 👏 don’t need it ❤ yes 😮 only for a paper -
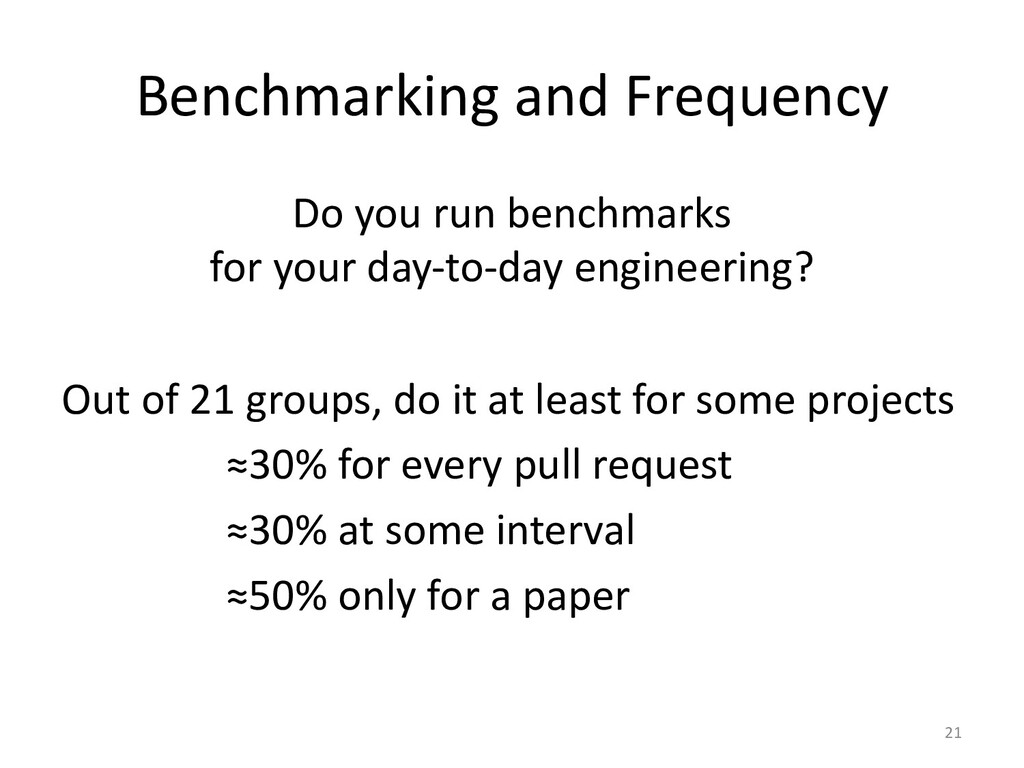
Benchmarking and Frequency Do you run benchmarks for your day-to-day
engineering? Out of 21 groups, do it at least for some projects ≈30% for every pull request ≈30% at some interval ≈50% only for a paper 21 -
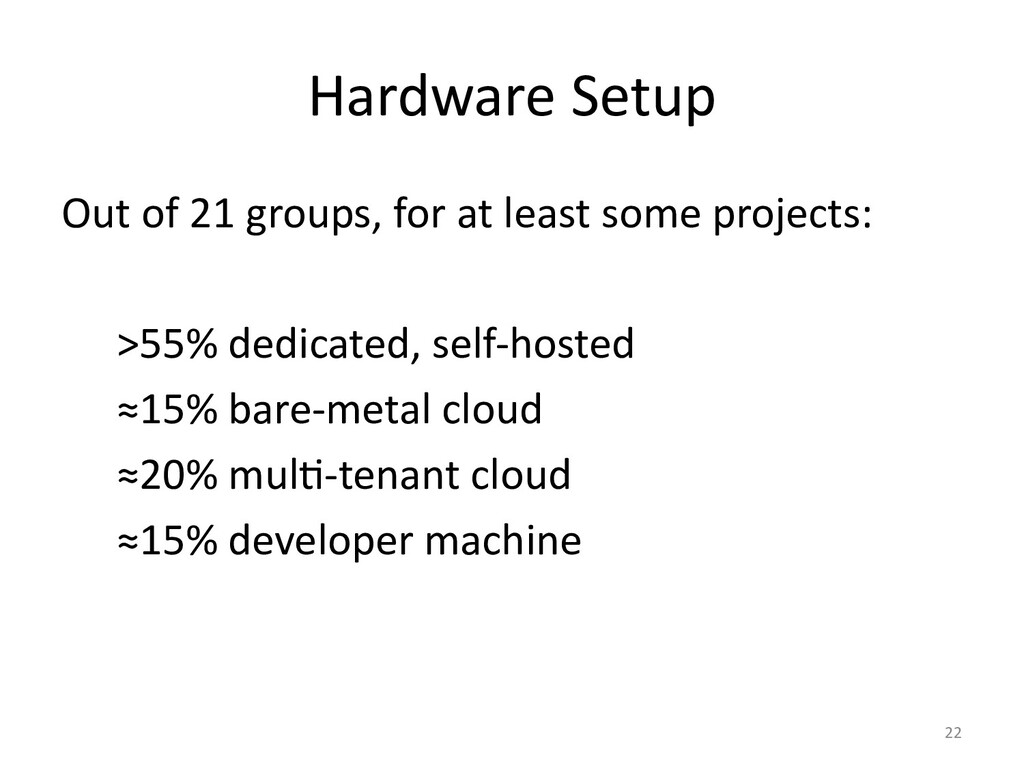
Hardware Setup Out of 21 groups, for at least some
projects: >55% dedicated, self-hosted ≈15% bare-metal cloud ≈20% mul/-tenant cloud ≈15% developer machine 22 -
Hardware Setup Out of 21 groups, for at least some
projects: >55% dedicated, self-hosted ≈15% bare-metal cloud ≈20% mul/-tenant cloud ≈15% developer machine 23 60% of groups: high cost/effort of maintaining machines and tools -
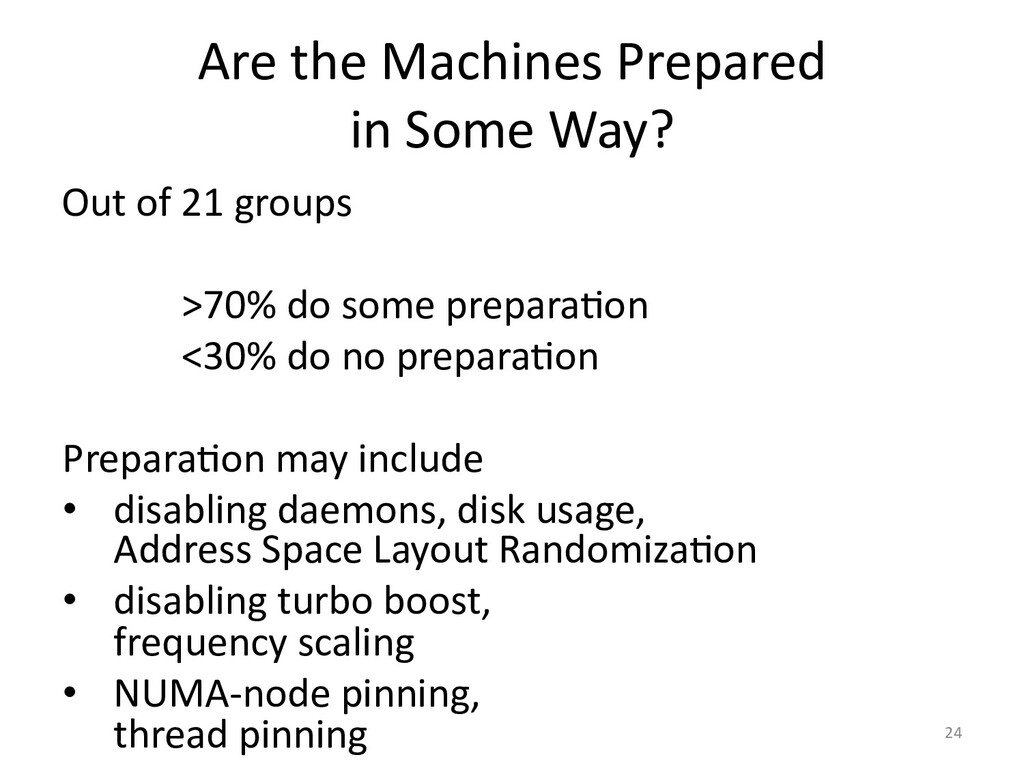
Are the Machines Prepared in Some Way? Out of 21
groups >70% do some prepara5on <30% do no prepara5on Prepara5on may include • disabling daemons, disk usage, Address Space Layout Randomiza5on • disabling turbo boost, frequency scaling • NUMA-node pinning, thread pinning 24 -
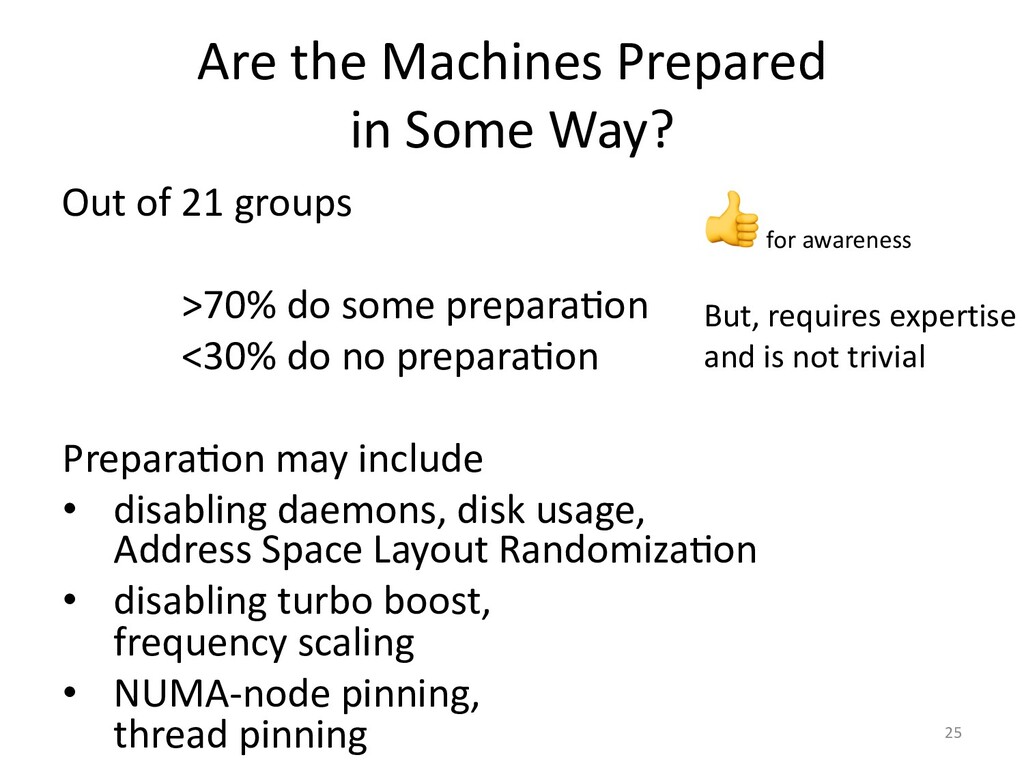
Are the Machines Prepared in Some Way? Out of 21
groups >70% do some prepara5on <30% do no prepara5on Prepara5on may include • disabling daemons, disk usage, Address Space Layout Randomiza5on • disabling turbo boost, frequency scaling • NUMA-node pinning, thread pinning 25 👍 for awareness But, requires expertise and is not trivial -
Data Provenance Did you ever have an issue like: –
Unsure what was measured? – Mixed up data from experiments? – Unsure which parameters were used 26 👏 yes ❤ no -
Data Provenance Out of 21 groups, for some projects <50%
track it systematically >60% do not track it 27 -
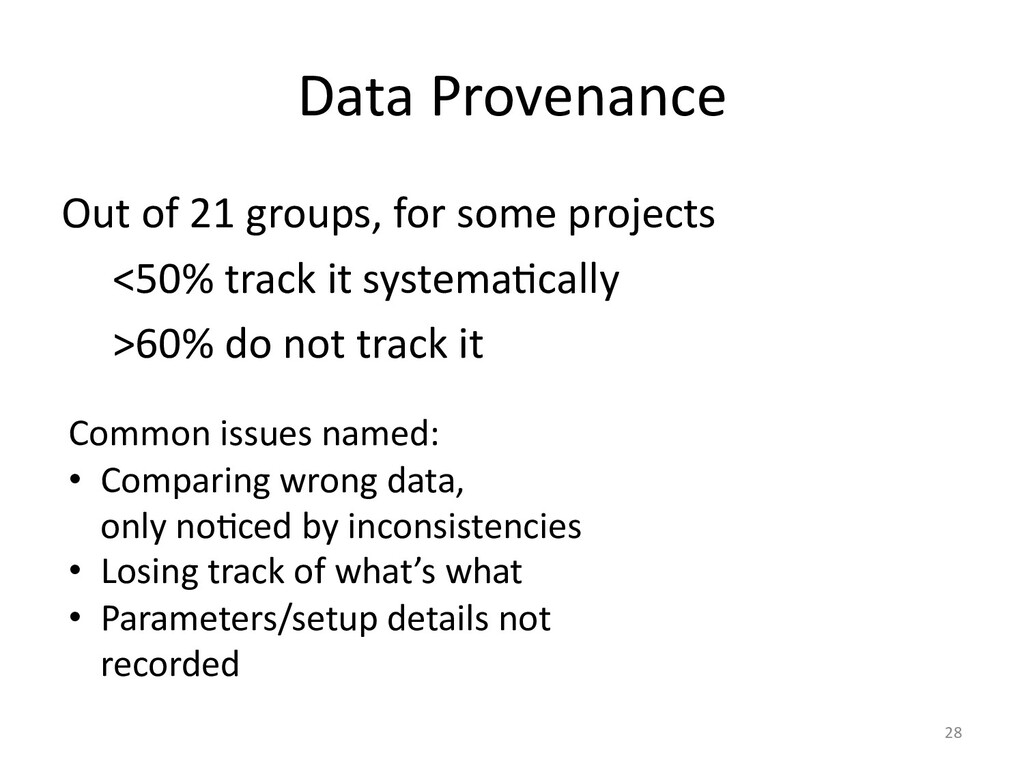
Data Provenance Out of 21 groups, for some projects <50%
track it systema/cally >60% do not track it 28 Common issues named: • Comparing wrong data, only no5ced by inconsistencies • Losing track of what’s what • Parameters/setup details not recorded -
Data Processing The 21 groups named the following: >71% Python
>40% Matplotlib ≈40% R ≈33% Spreadsheets and other things 29 -
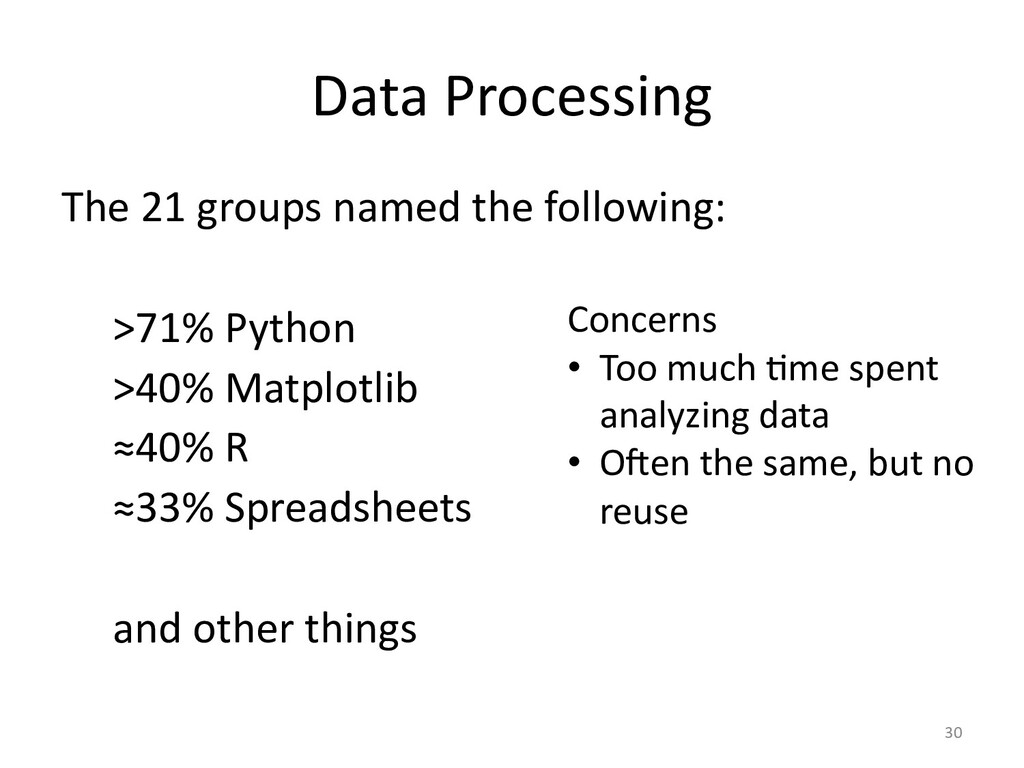
Data Processing The 21 groups named the following: >71% Python
>40% Matplotlib ≈40% R ≈33% Spreadsheets and other things 30 Concerns • Too much .me spent analyzing data • OFen the same, but no reuse -
Data Processing Of the 21 groups, >88% do something manual
>70% have some things scripted 2 groups automate everything including generating Latex macros 31 -
Our Struggles • Finding good benchmarks • Setup and maintain
machines, minimizing measurement error • Tracking data provenance • Historic data available/useful • Standard analyses, data processing, and sta/s/cs 33 -
Best Prac0ces • Use CI/Automated Tes0ng – At the very
least, check that benchmarks produce correct results • Use same setup for day-to-day engineering as for producing data for papers – The setup is already debugged! • Most CI systems can store ar0facts – Basic provenance tracking for results! • Automate data handling – Spreadsheets can import data from external data sources – Avoid manually copying data around • Define workflow that works for your group – And teach it! 34 -
?? ? Ques%ons? Our Struggles • Finding good benchmarks •
Setup and maintain machines, minimizing measurement error • Tracking data provenance • Historic data available/useful • Standard analyses, data processing, and staBsBcs Best Prac/ces • Use CI/Automated Testing • Use same setup for day-to-day engineering as for producing data for papers • Most CI systems can store artifacts • Automate data handling • Define workflow that works for your group 35