Share
Embed
Supersize your Key-Value Store
Presented at ConFoo 2014
We've all heard in recent years about how Key-Value stores cast off the scaling problems of SQL-based solutions and give developers the flexibility to choose in-memory or disk-persistent, single-node or clustered options.
In this talk, we review design and performance of several key-value stores (Riak, LevelDB, and MySQL API), and several techniques such as efficient compression and schema extraction to get the most out of any KV store.
Sunny Gleason
February 28, 2014
Transcript
42 slides
-
whoami •distributed systems engineer sunnycloud - boston, ma •previous work
@ Amazon, Ning •github: sunnygleason twitter: @sunnygleason speakerdeck: sunnygleason •don’t be a stranger! -
what's this all about? • NoSQL is getting a lot
of love right now • NoSQL core ideas: simplification and doing more with less • These techniques apply to any system • You can create future-proof APIs and still enjoy the benefits of your favorite data store -
agenda • What is a Key-Value store? • 3 Sample
KV Implementations • Some techniques for getting the most out of your KV store -
key-value stores • kv is a model, not an implementation
• goal: get improved scalability & performance characteristics by restricting the persistence model • GET(key), PUT(key), DELETE(key) -
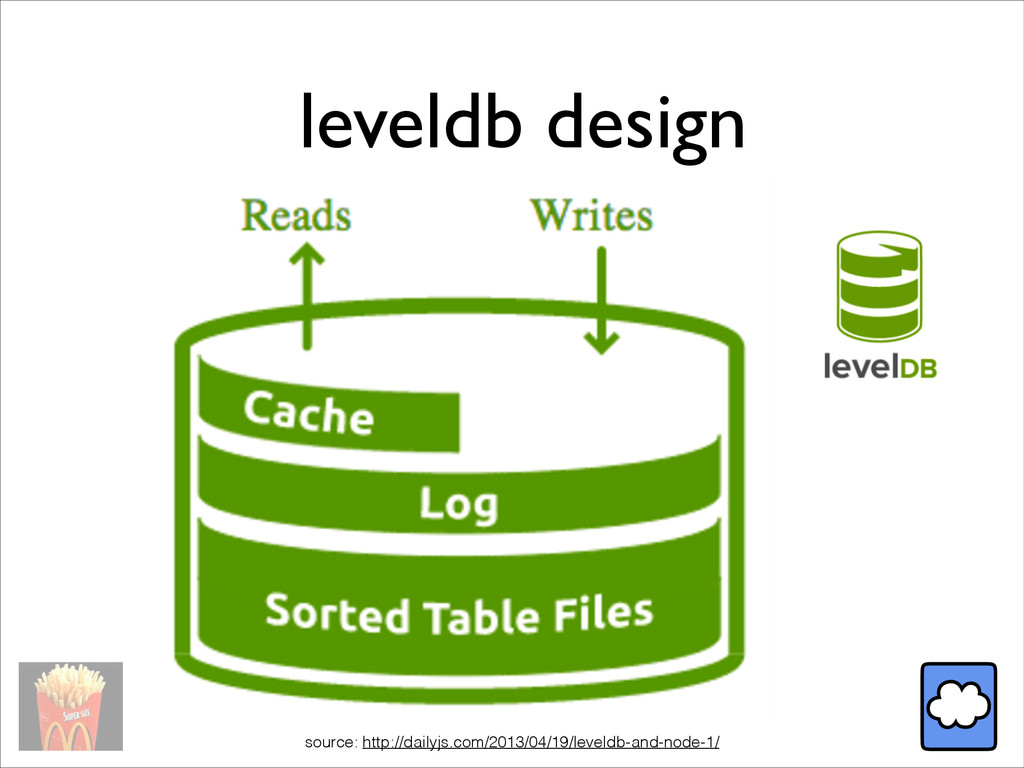
leveldb • Open-Source (BSD License) Embedded Key-Value Store • Created
by Jeff Dean and Sanjay Ghemawat at Google • Written in C/C++ • Original intent: embedded data store in Chromium browser -
leveldb api • byte[] DB.get(byte[] key) void DB.put(byte[] key, byte[]
value) void DB.delete(byte[] key) DBIterator DB.iterator() • DBIterator.seek(byte[] key) DBIterator.peekNext() DBIterator.prev() DBIterator.seekToFirst() / seekToLast() • Check out: https://code.google.com/p/leveldb/ (c/c++) https://github.com/dain/leveldb (pure java) https://github.com/fusesource/leveldbjni (java/jni) -
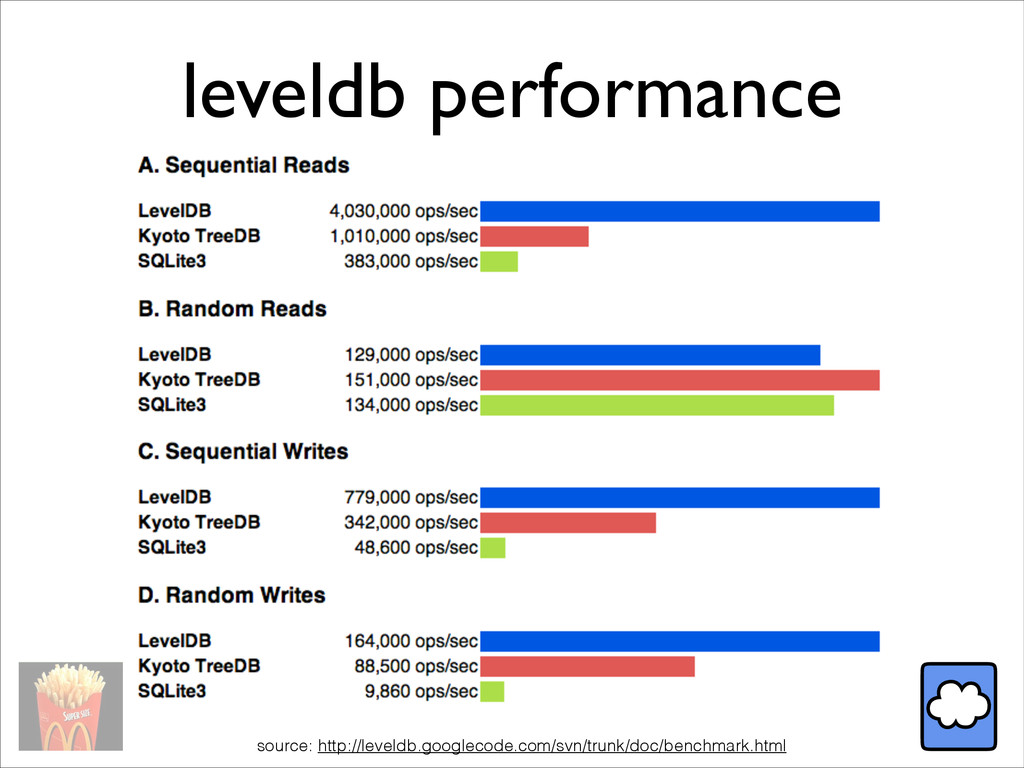
leveldb thoughts • leveldb is a great general-purpose embedded KV
store • backup / restore model is not great - close file and copy, or iterate over snapshot and write to new file • as with any embedded KV store, beware large data set sizes • OSS license and adoption are nice relative to alternatives like BDB, BDB-JE, Tokyo Cabinet • Promising newcomer: RocksDB (from Facebook) -
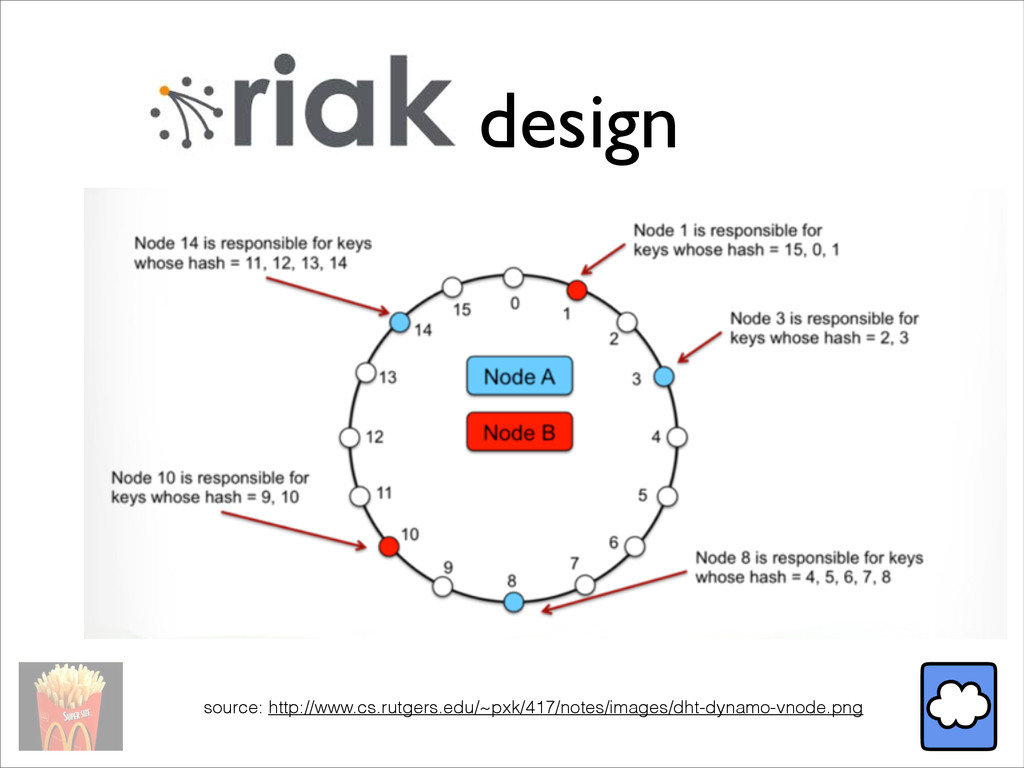
• Open-Source (Apache 2) distributed data store • Based on
the Amazon Dynamo model (as presented SOSP 2007) • Created by Basho Technologies as their primary product • Written in Erlang, with some JavaScript capabilities (MapReduce) • Pluggable data stores: most commonly eleveldb, also bitcask -
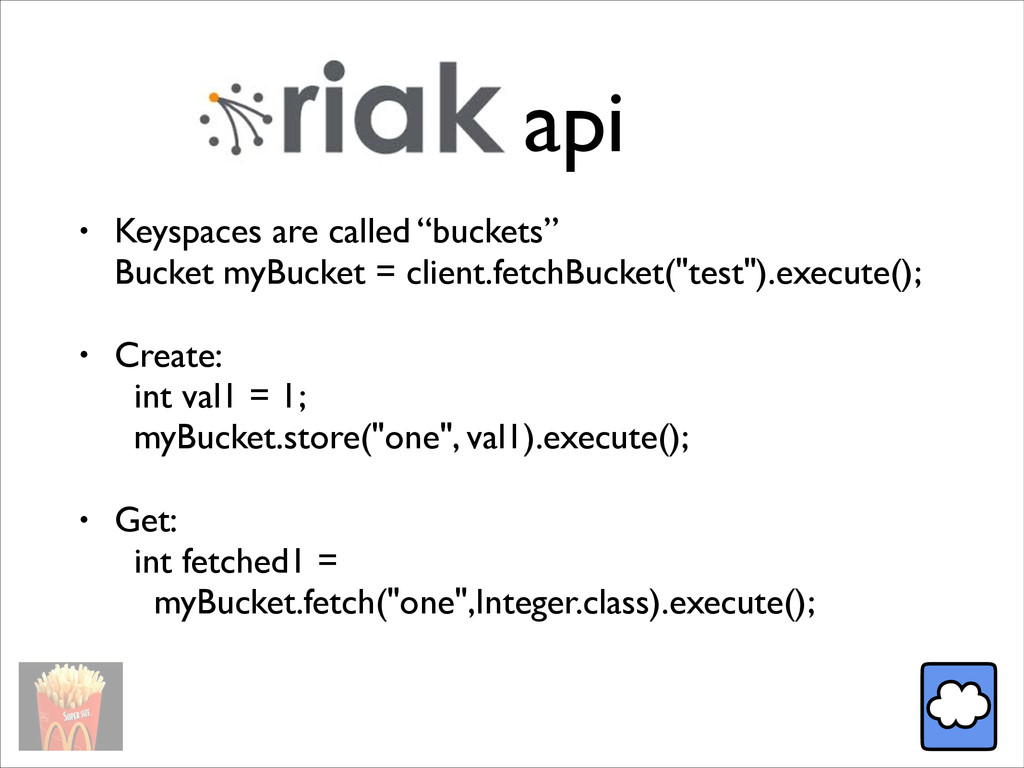
api • Keyspaces are called “buckets” Bucket myBucket = client.fetchBucket("test").execute();
• Create: int val1 = 1; myBucket.store("one", val1).execute(); • Get: int fetched1 = myBucket.fetch("one",Integer.class).execute(); -
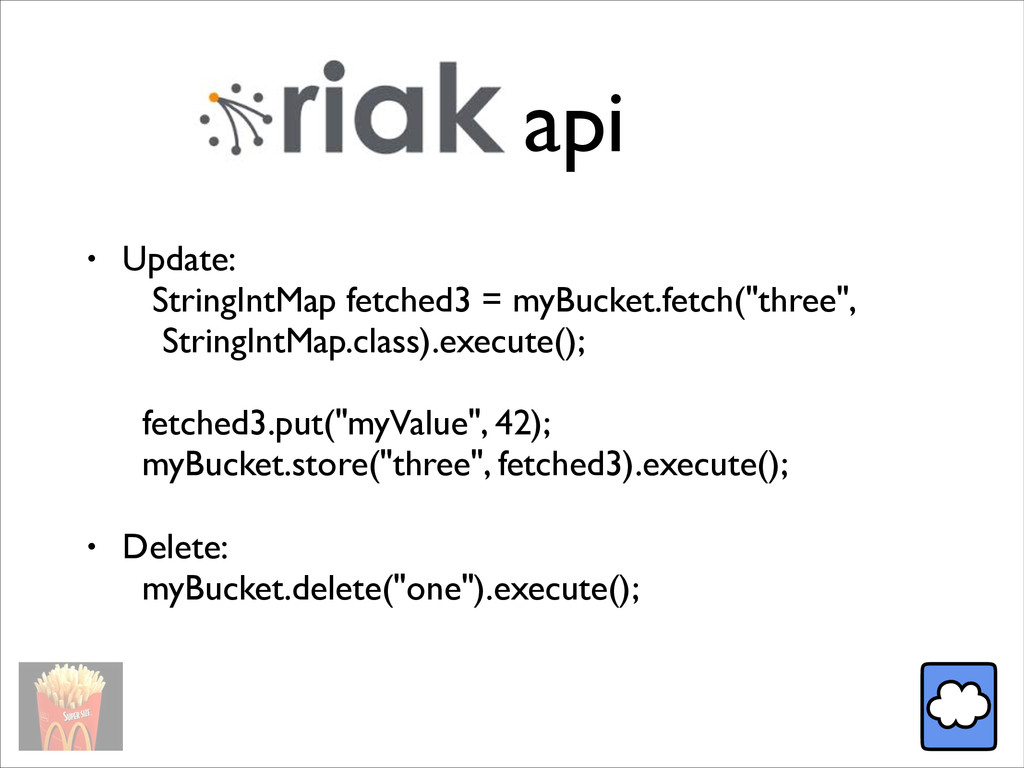
• Update: StringIntMap fetched3 = myBucket.fetch("three", StringIntMap.class).execute(); fetched3.put("myValue", 42);
myBucket.store("three", fetched3).execute(); • Delete: myBucket.delete("one").execute(); api -
riak gotchas • Lower throughput compared to embedded data
store • Time is no longer a single-node, authoritative concept • Sibling resolution: concurrent updates happen, "last write wins" almost always loses - need to provide a Strategy • Backup/restore is challenging - not just one leveldb, several nodes with leveldbs • Erlang: can be tough to get under the hood -
riak advantages • Battle-tested, kernel-level understanding of leveldb • Commercial
distribution with support • Wide-area replication with very efficient synchronization (merkle trees) • Riak CS for large files / blobs • Erlang: a lot of power & reliability once you get under the hood -
mysql KV schema • Not a separate product: just use
MySQL with a restricted schema • MySQL itself is Open Source (GPL2), you will likely never need to modify it • Owned/maintained by Oracle • All the commercial support you will pay for • Other variants by Percona (recommended), MariaDB -
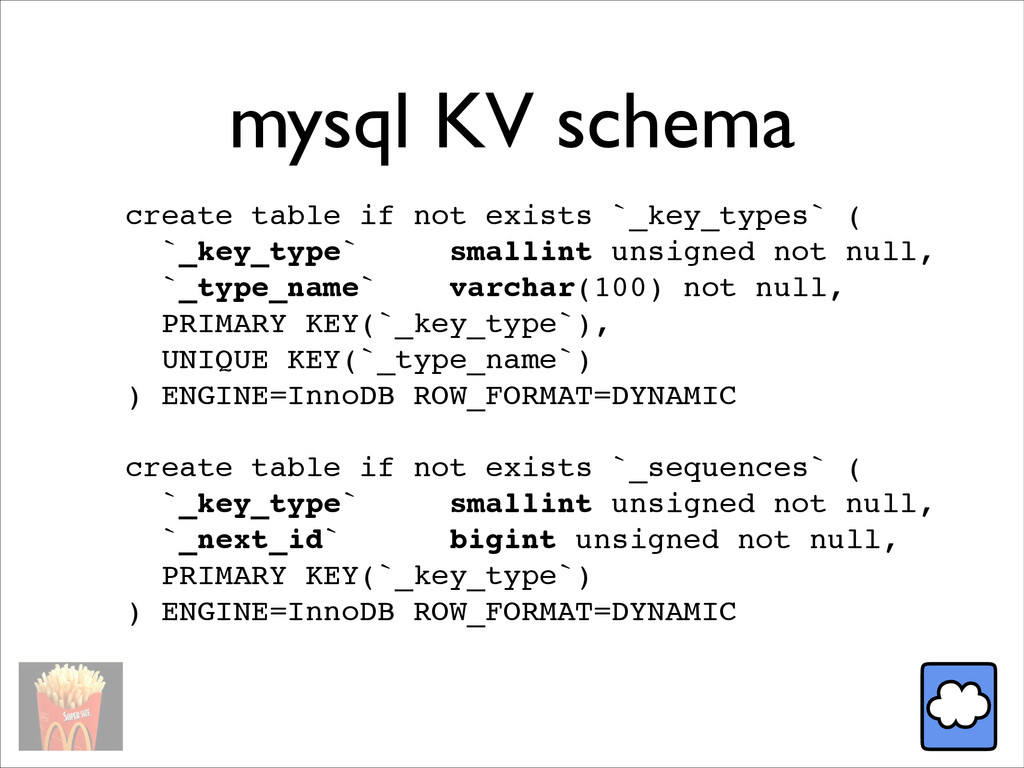
mysql KV schema create table if not exists `_key_types` (!
`_key_type` smallint unsigned not null,! `_type_name` varchar(100) not null,! PRIMARY KEY(`_key_type`),! UNIQUE KEY(`_type_name`)! ) ENGINE=InnoDB ROW_FORMAT=DYNAMIC! ! create table if not exists `_sequences` (! `_key_type` smallint unsigned not null,! `_next_id` bigint unsigned not null,! PRIMARY KEY(`_key_type`)! ) ENGINE=InnoDB ROW_FORMAT=DYNAMIC -
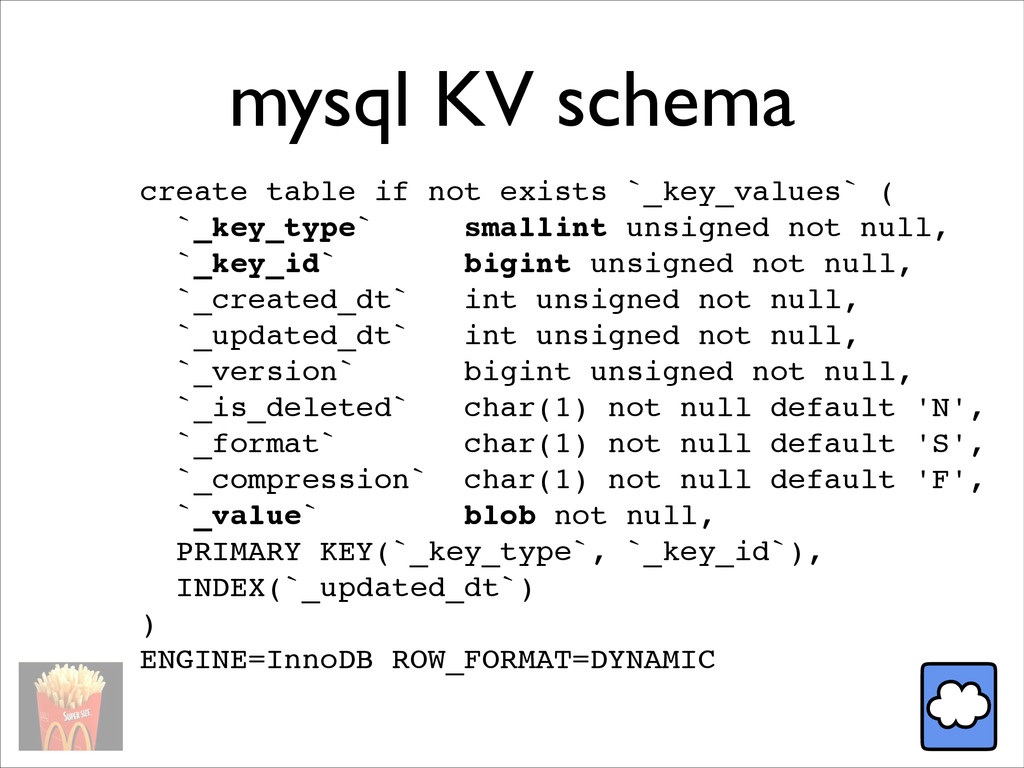
mysql KV schema create table if not exists `_key_values` (!
`_key_type` smallint unsigned not null,! `_key_id` bigint unsigned not null,! `_created_dt` int unsigned not null,! `_updated_dt` int unsigned not null,! `_version` bigint unsigned not null,! `_is_deleted` char(1) not null default 'N',! `_format` char(1) not null default 'S',! `_compression` char(1) not null default 'F',! `_value` blob not null,! PRIMARY KEY(`_key_type`, `_key_id`),! INDEX(`_updated_dt`)! ) ENGINE=InnoDB ROW_FORMAT=DYNAMIC -
mysql KV schema design • Key is 2-parts: type_id +
sequence_id • Value is a blob (alternatively could be binary) • Separate sequence/id generation from DB implementation • Use int/long as identifier mapping for types to reduce size -
mysql KV api • get(key, value): SELECT … WHERE key_type
= ? and key_id = ? • insert(key, value): INSERT INTO … VALUES (?, ?, ?) • update(key, value): UPDATE … SET value = ? • delete(key): DELETE FROM … WHERE key_type = ? and key_id = ? UPDATE … SET is_deleted = ‘Y’ WHERE … -
mysql KV schema gotchas • Roll your own data store
• Hey, this isn't NoSQL?! • Requires DB tuning and operational knowledge • Not distributed or fully symmetric like Riak: requires vertical scaling or sharding -
mysql KV schema advantages • Utilize existing widely deployed technology:
easy sell to DBA’s and manager types • Transactional guarantees provided by MySQL • Improve scaling & durability through replication (read slaves) • Strong durability using InnoDB, easy hot backup (full and incremental) using tools like Percona Xtrabackup • Works with other SQL databases as well: H2, Sqlite3, MSSQL, Postgres, Oracle, … -
taking KV to the next level • Turn your “big
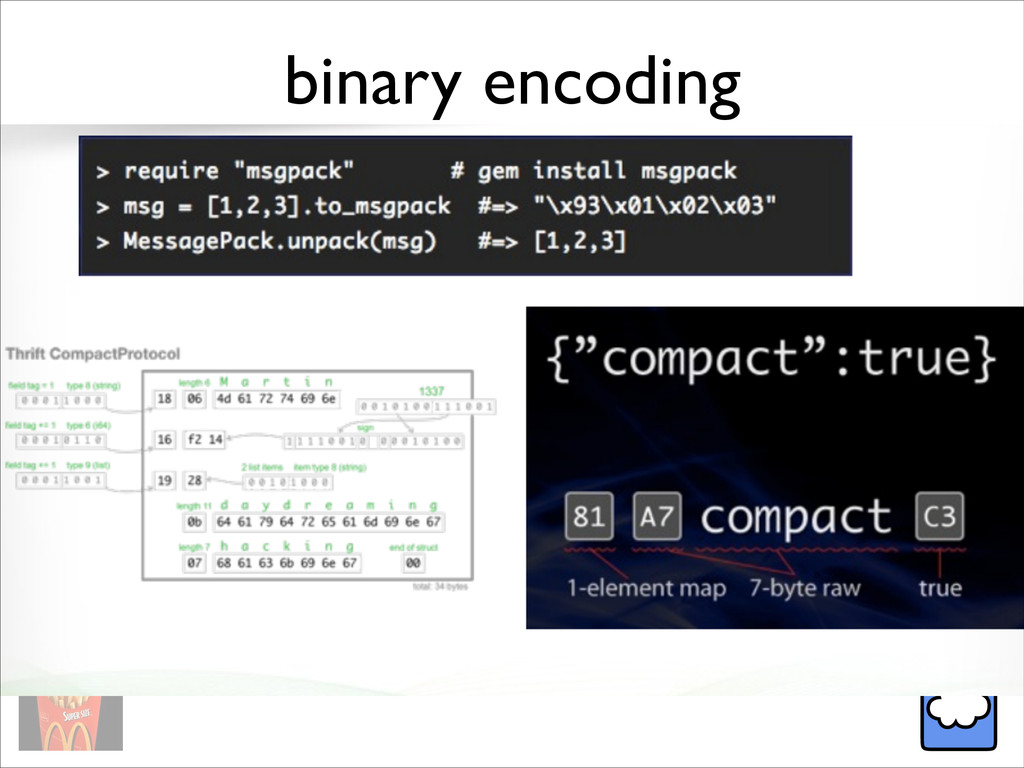
data” into smaller data • Compression: apply compression algorithms to byte[] values • Binary Encoding: smaller binary representations of JSON (for example) • Schema Extraction: use limited, flexible schema information to reduce data storage requirements -
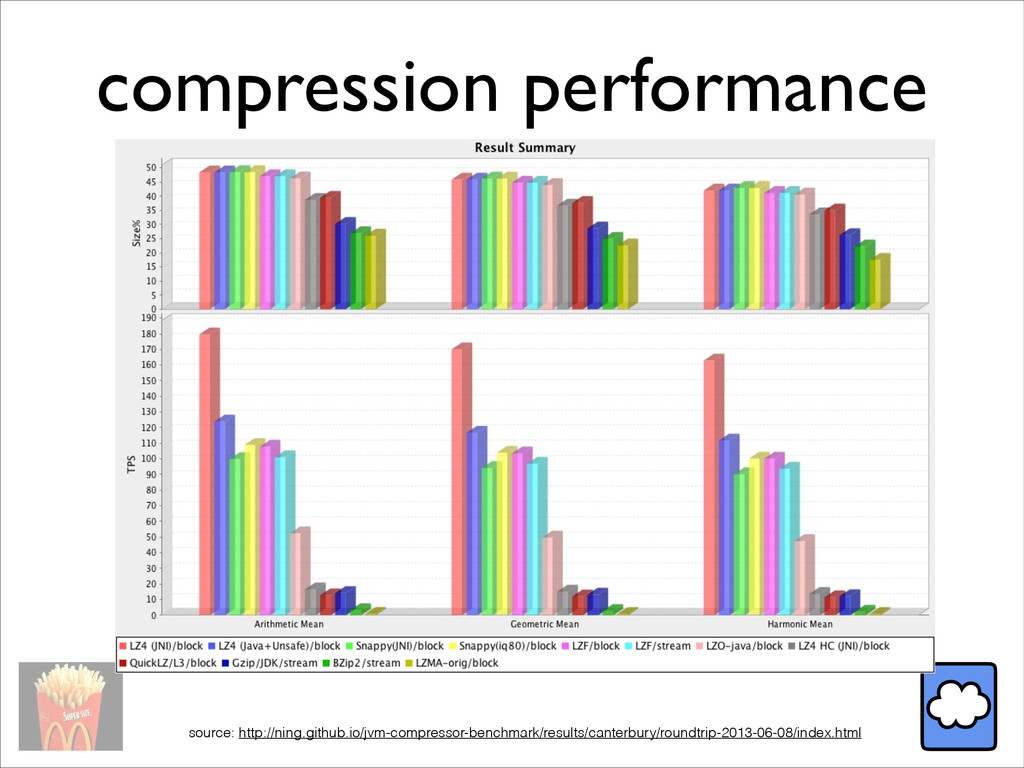
compression • Instead of TEXT/LONGTEXT and huge JSON or XML
values • Use BLOB/LONGBLOB, and compress the value prior to storage: • GZip • Snappy • LZF -
compression notes • GZip, Bzip2 typically have great compression (70%+),
(but) very high CPU utilization • Snappy, LZF have good compression (30-50%) and lower CPU utilization • However, all of these algorithms typically fall short for small values (< 1024 bytes) -
huffman encoding • For small documents, consider using a Hufman
Coding library for compression* • Analyze a representative set of data beforehand to create a statistical data model • Can yield 30-50% compression or more for small documents (2-1024 bytes) • *Also consider InnoDB page compression (however, its use of zlib puts CPU burden on the database) -
schema extraction • Idea: Extract a subset of key-value pairs
into a schema, represent as Array vs. Map • Additionally, use more efficient types to represent values (such as boolean -> bit, enum -> int) • Benefits: explicit schema versioning, decouple schema evolution, more compact representation • Downside: approaching relational DB complexity without benefits of querying (yet) & table-level consistency -
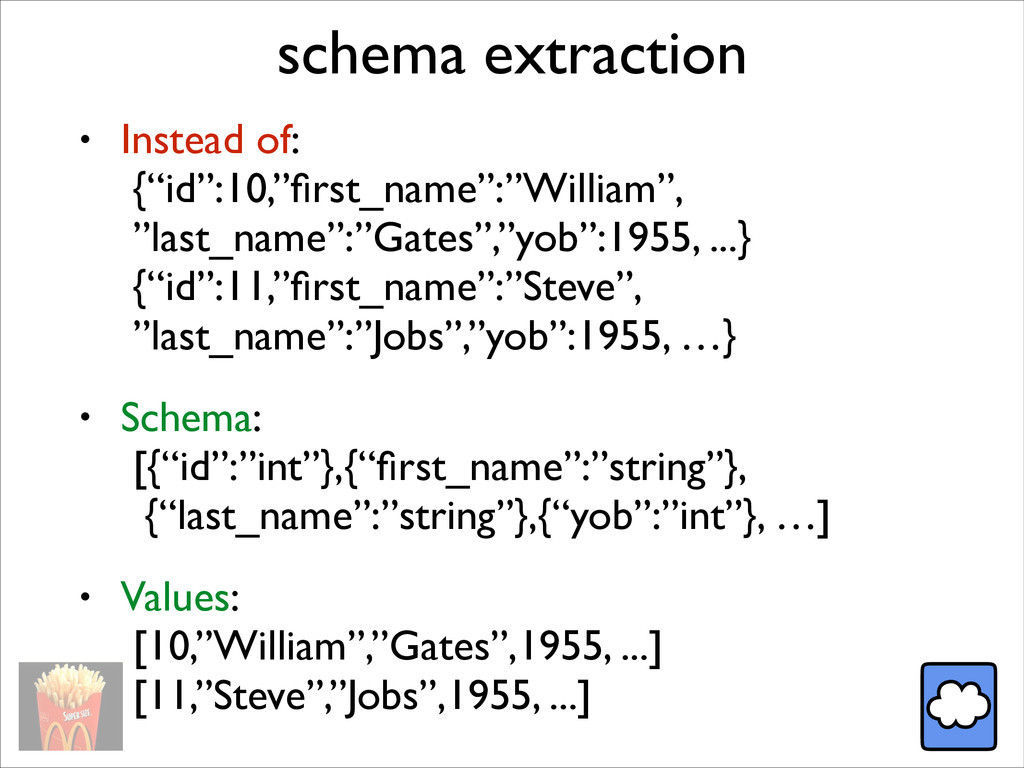
schema extraction • Instead of: {“id”:10,”first_name”:”William”, ”last_name”:”Gates”,”yob”:1955, ...} {“id”:11,”first_name”:”Steve”, ”last_name”:”Jobs”,”yob”:1955,
…} • Schema: [{“id”:”int”},{“first_name”:”string”}, {“last_name”:”string”},{“yob”:”int”}, …] • Values: [10,”William”,”Gates”,1955, ...] [11,”Steve”,”Jobs”,1955, ...] -
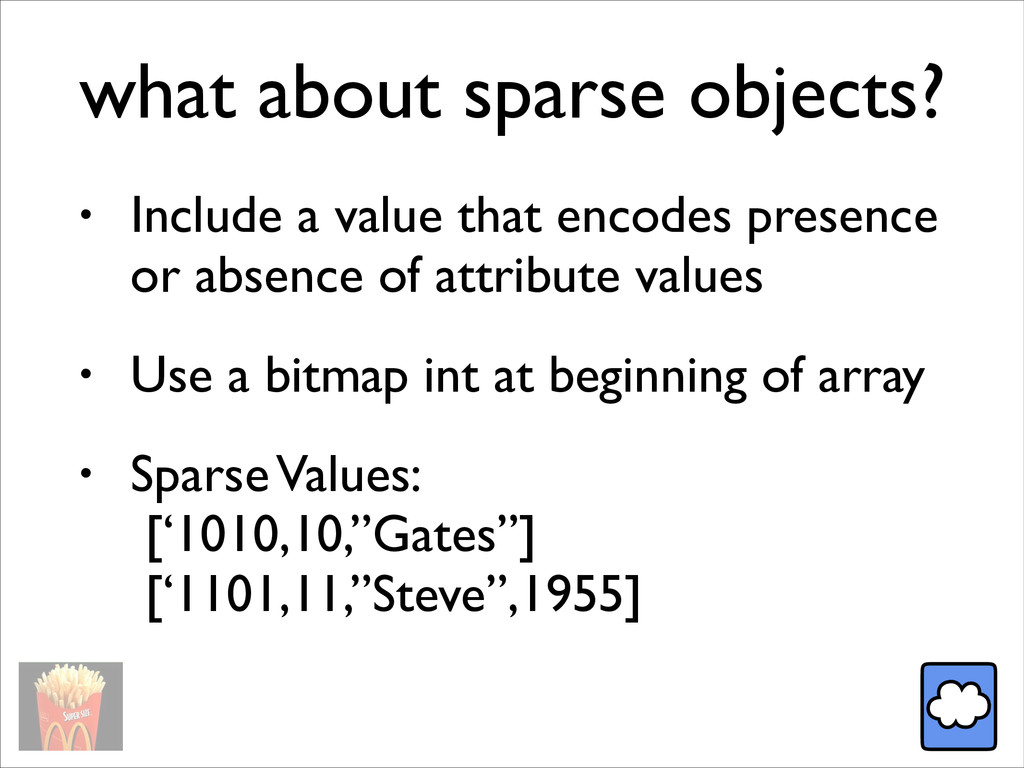
what about sparse objects? • Include a value that encodes
presence or absence of attribute values • Use a bitmap int at beginning of array • Sparse Values: [‘1010,10,”Gates”] [‘1101,11,”Steve”,1955] -
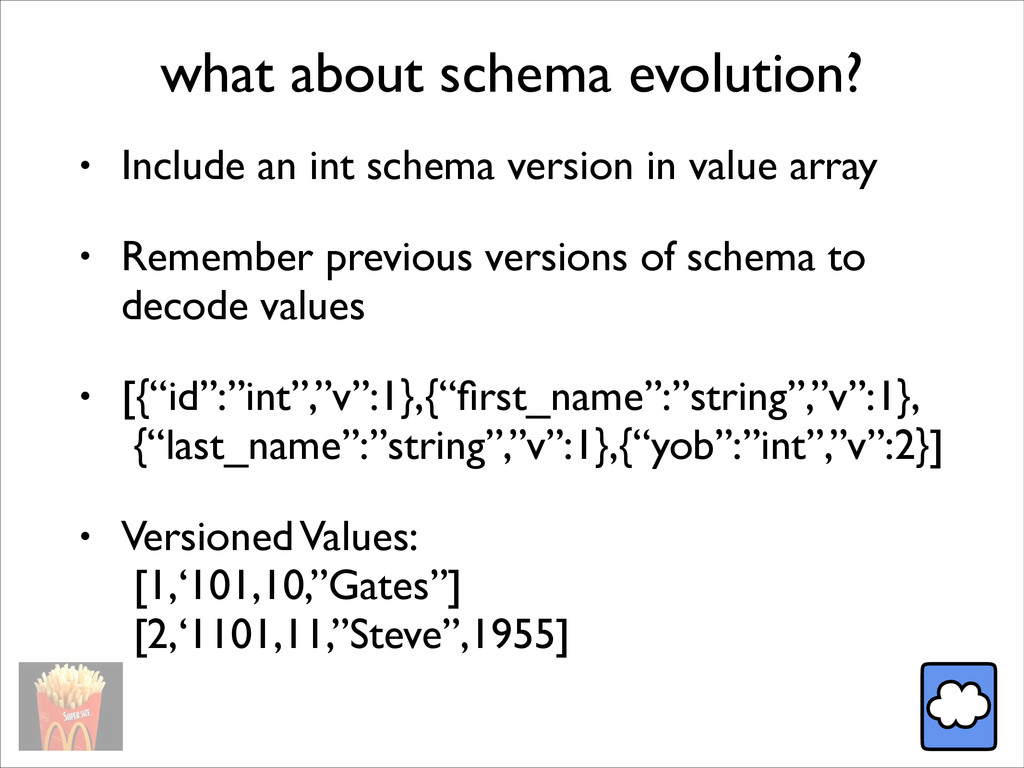
what about schema evolution? • Include an int schema version
in value array • Remember previous versions of schema to decode values • [{“id”:”int”,”v”:1},{“first_name”:”string”,”v”:1}, {“last_name”:”string”,”v”:1},{“yob”:”int”,”v”:2}] • Versioned Values: [1,‘101,10,”Gates”] [2,‘1101,11,”Steve”,1955] -
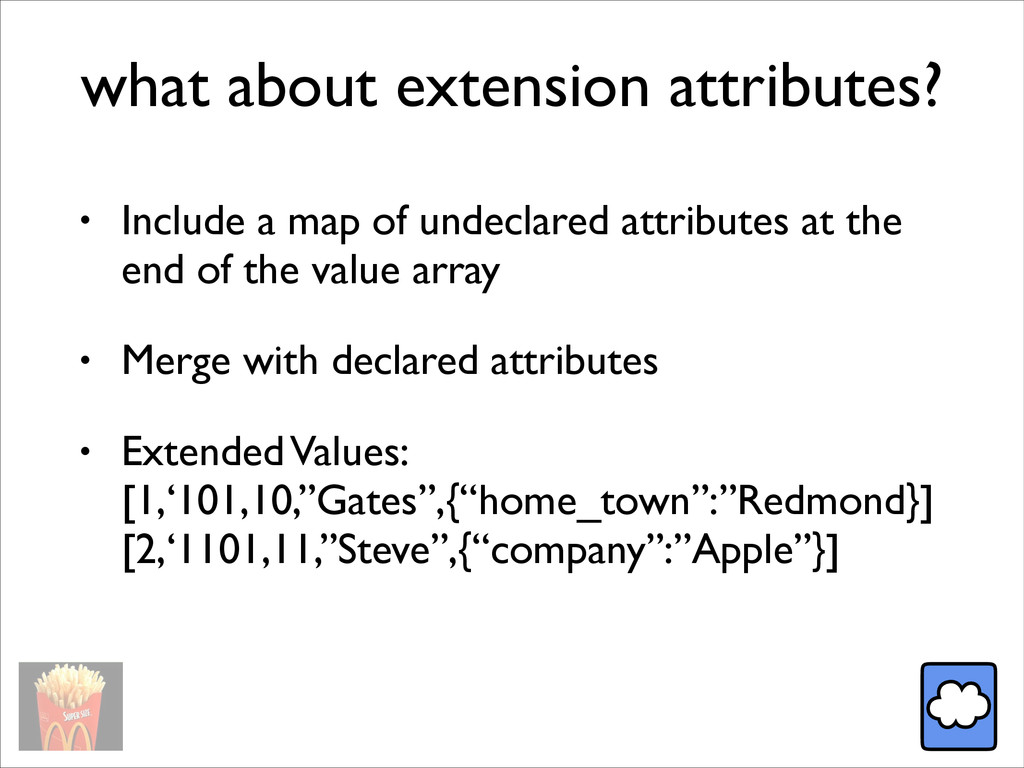
what about extension attributes? • Include a map of undeclared
attributes at the end of the value array • Merge with declared attributes • Extended Values: [1,‘101,10,”Gates”,{“home_town”:”Redmond}] [2,‘1101,11,”Steve”,{“company”:”Apple”}] -
techniques recap • Improve the scalability of your KV store
by applying techniques like compression, binary encoding and schema extraction • These techniques can also have follow-on benefits in the caching and application layers as well, at the expense of tighter coupling • Please view these techniques more like a spectrum or continuum, and less like a shopping list -
kazuki • Open-Source (Apache 2) Data Store written in Java
• Collection of persistence patterns: KV Store, KV Cache, Full-text Index, Range-Based Indexes, Counters, Journal Store • Run as embedded library or REST service • Portable Implementations: KV Store: MySQL, H2DB, Sqlite3 KV Store Soon: MSSQL, LevelDB, Riak, Cassandra KV Cache: Memcached, Redis Full-text Index: ElasticSearch, Solr Journal Store: KV Stores, plus Java Chronicle -
kazuki features • now: persistence plus schema extraction, encoding (smile),
compression (lzf, huffman soon) • coming up next: schema evolution, backup/ restore, plugins, more data store portability • ideas / participation welcome! github.com/kazukidb/kazuki