Share
Embed
What's new in PostgreSQL?
Institute of Computer Science, University of Wrocław
Seminar: What's new in database world?
26.11.2015
Rafał Łasocha
November 26, 2015
Transcript
22 slides
-
What's new in PostgreSQL? Rafał Łasocha 26.11.2015 Institute of Computer
Science, University of Wrocław Databases seminar -
UPSERT - scenario • social platform • table with „likes”
– columns user_id, post_id – uniqueness validation (nobody can give 2 likes to one post) • what if someone send two requests to „like” something to our app? -
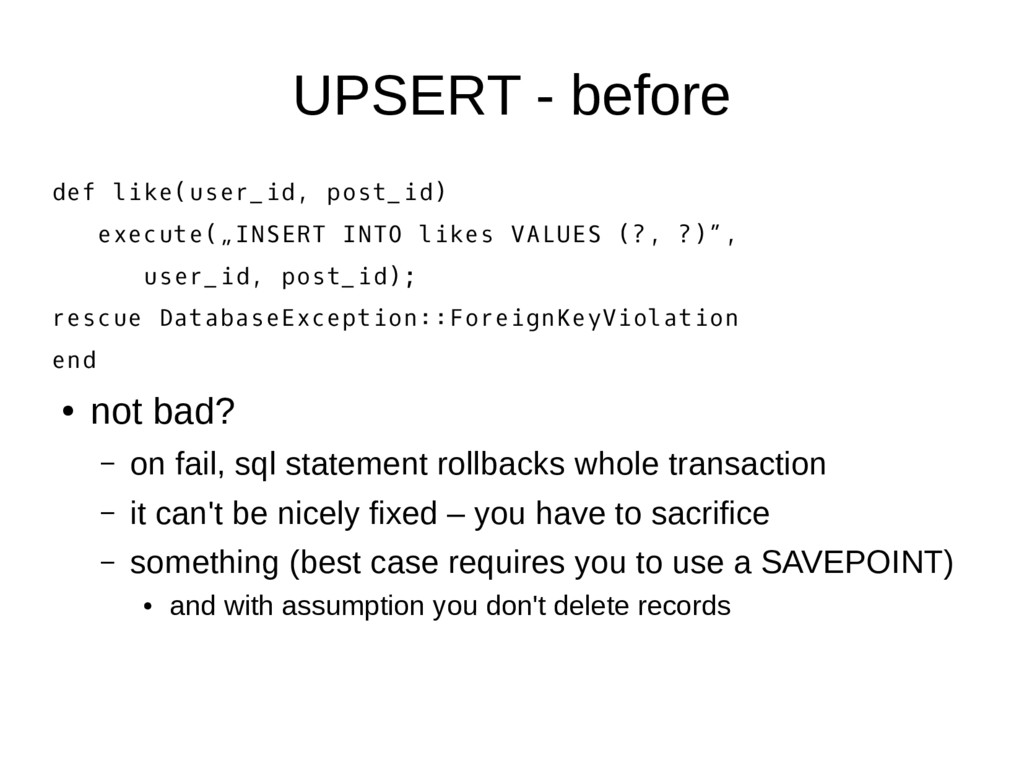
UPSERT - before def like(user_id, post_id) execute(„INSERT INTO likes VALUES
(?, ?)”, user_id, post_id); rescue DatabaseException::ForeignKeyViolation end • not bad? – on fail, sql statement rollbacks whole transaction – it can't be nicely fixed – you have to sacrifice – something (best case requires you to use a SAVEPOINT) • and with assumption you don't delete records -
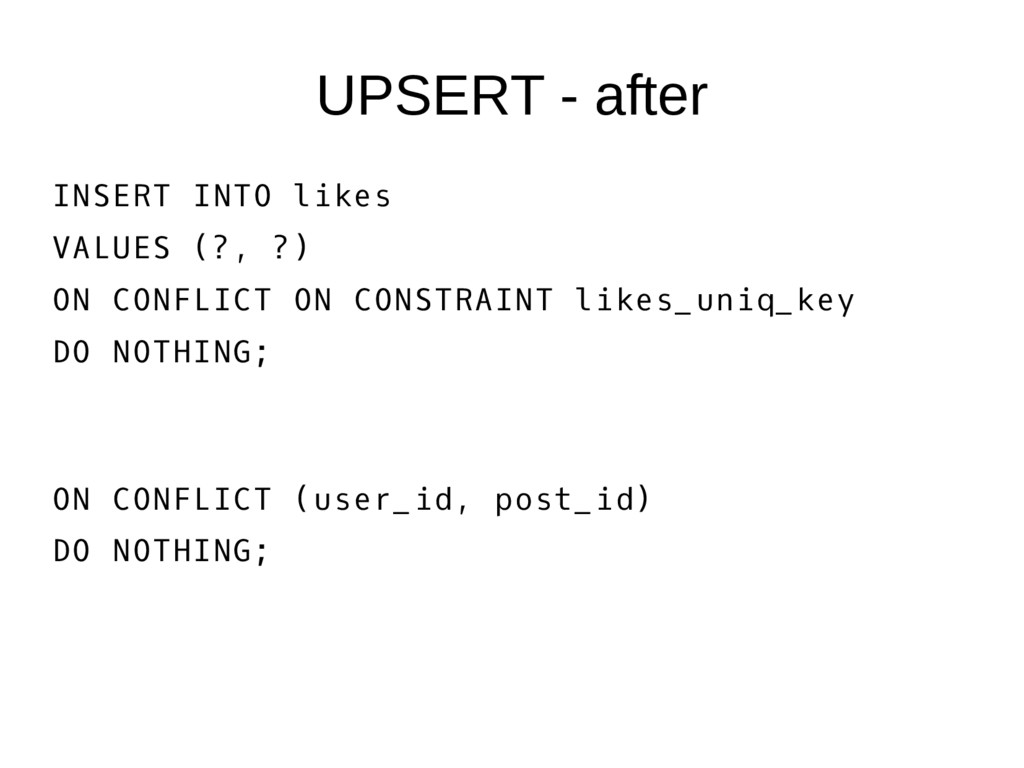
UPSERT - after INSERT INTO likes VALUES (?, ?) ON
CONFLICT ON CONSTRAINT likes_uniq_key DO NOTHING; ON CONFLICT (user_id, post_id) DO NOTHING; -
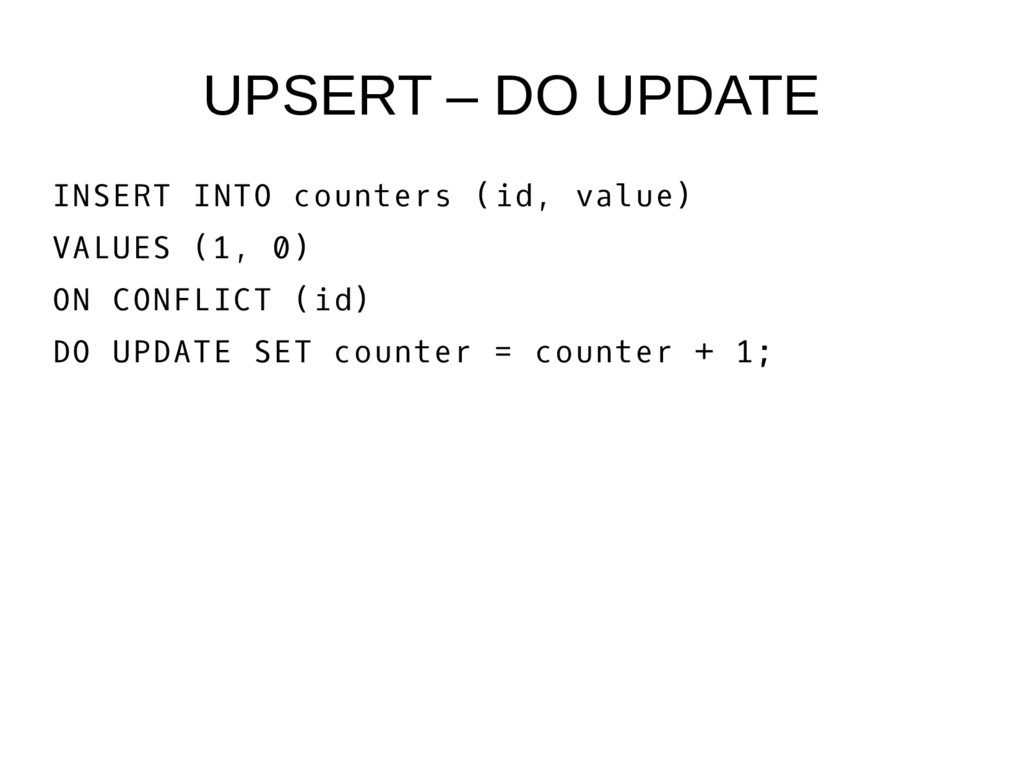
UPSERT – DO UPDATE INSERT INTO counters (id, value) VALUES
(1, 0) ON CONFLICT (id) DO UPDATE SET counter = counter + 1; -
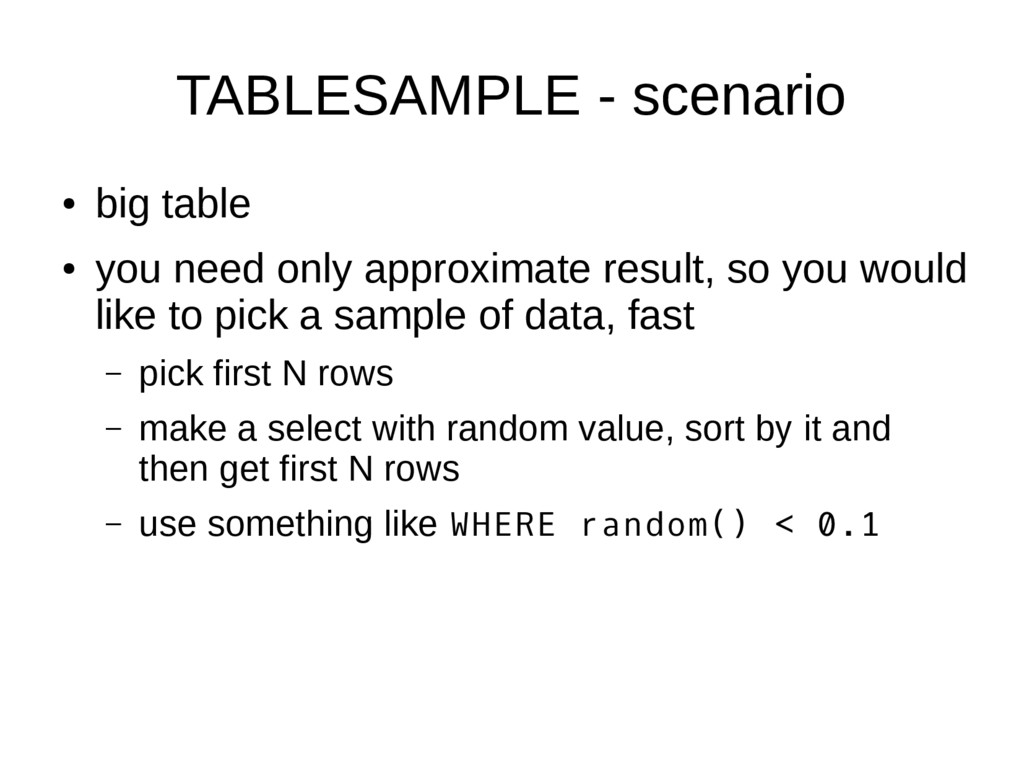
TABLESAMPLE - scenario • big table • you need only
approximate result, so you would like to pick a sample of data, fast – pick first N rows – make a select with random value, sort by it and then get first N rows – use something like WHERE random() < 0.1 -
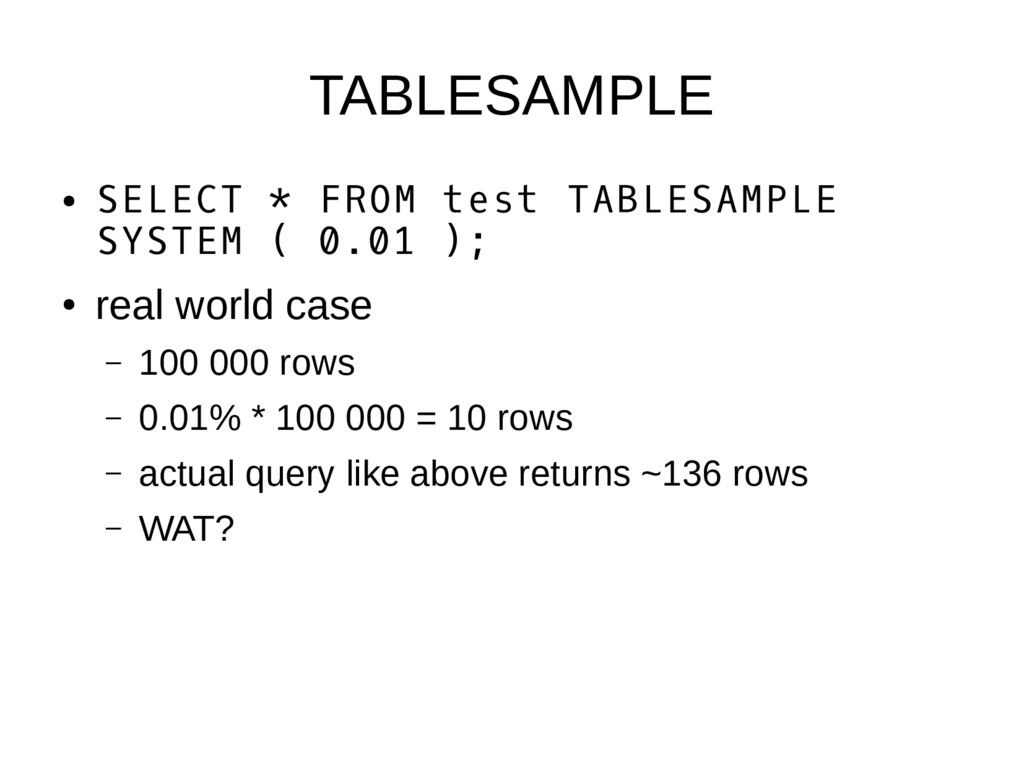
TABLESAMPLE • SELECT * FROM test TABLESAMPLE SYSTEM ( 0.01
); • real world case – 100 000 rows – 0.01% * 100 000 = 10 rows – actual query like above returns ~136 rows – WAT? -
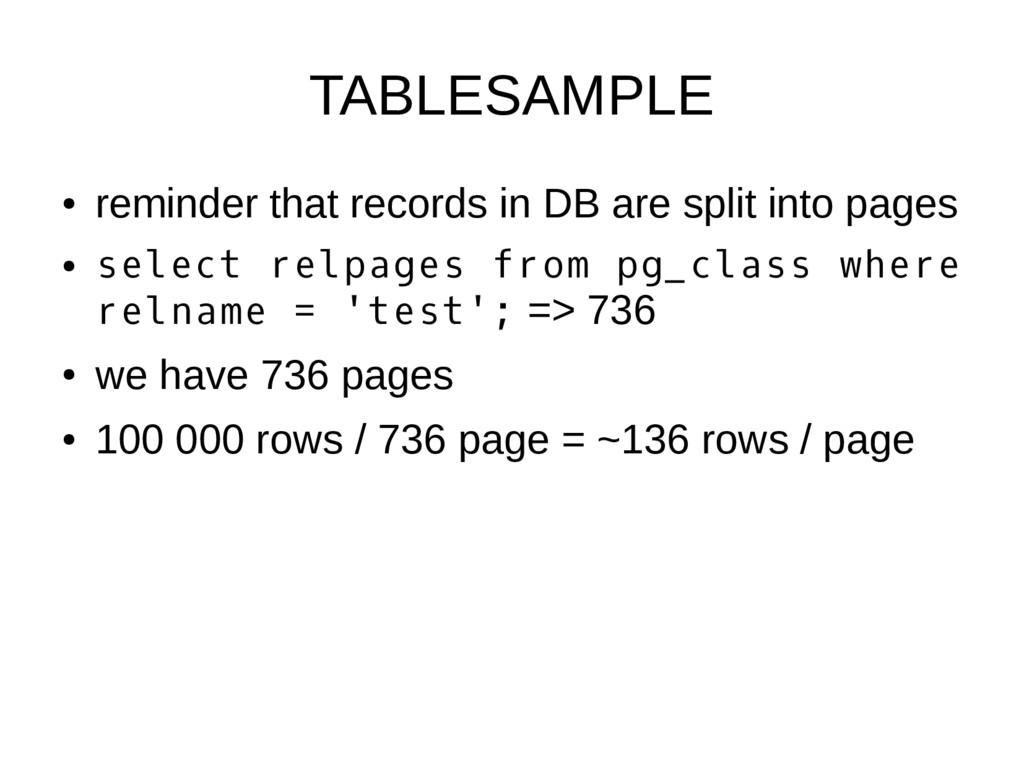
TABLESAMPLE • reminder that records in DB are split into
pages • select relpages from pg_class where relname = 'test'; => 736 • we have 736 pages • 100 000 rows / 736 page = ~136 rows / page -
TABLESAMPLE - SYSTEM • SYSTEM algorithm – it returns whole
pages – if you request 0.01 sample, you get at least 0.01% of the table – in our case much more (136 instead of 10) – advantage: very fast! • just pick random pages from 736, in our case 1 page was enough – with x as (select * from test tablesample system ( 0.01 )) select * from x order by random() limit 10; -
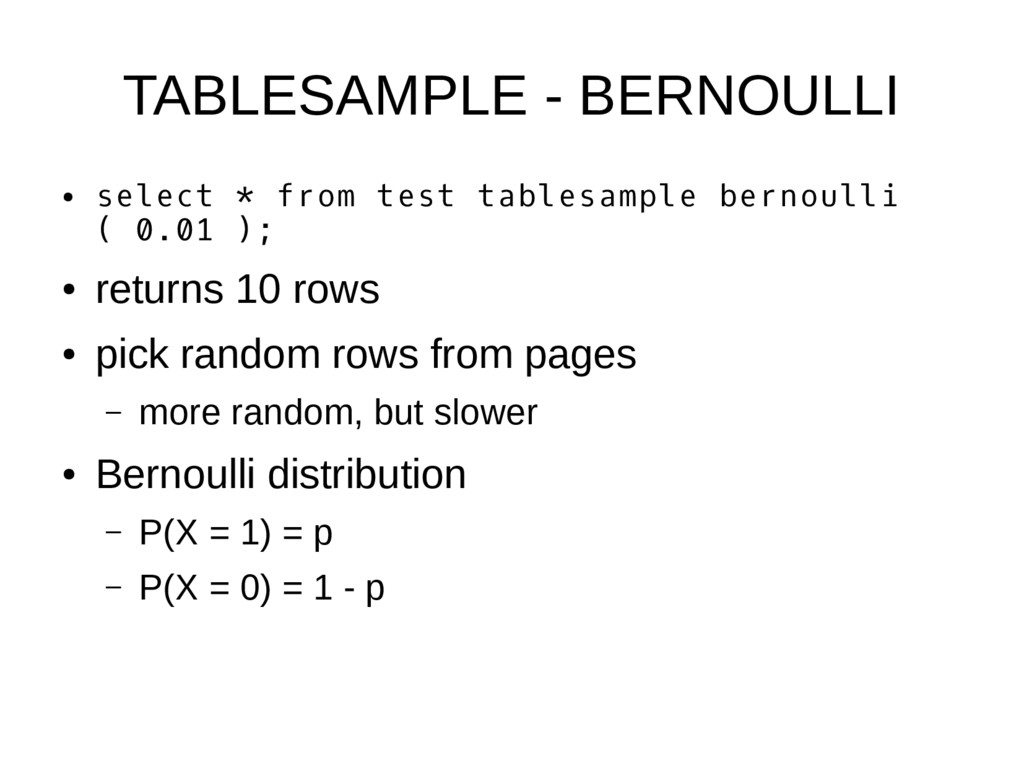
TABLESAMPLE - BERNOULLI • select * from test tablesample bernoulli
( 0.01 ); • returns 10 rows • pick random rows from pages – more random, but slower • Bernoulli distribution – P(X = 1) = p – P(X = 0) = 1 - p -
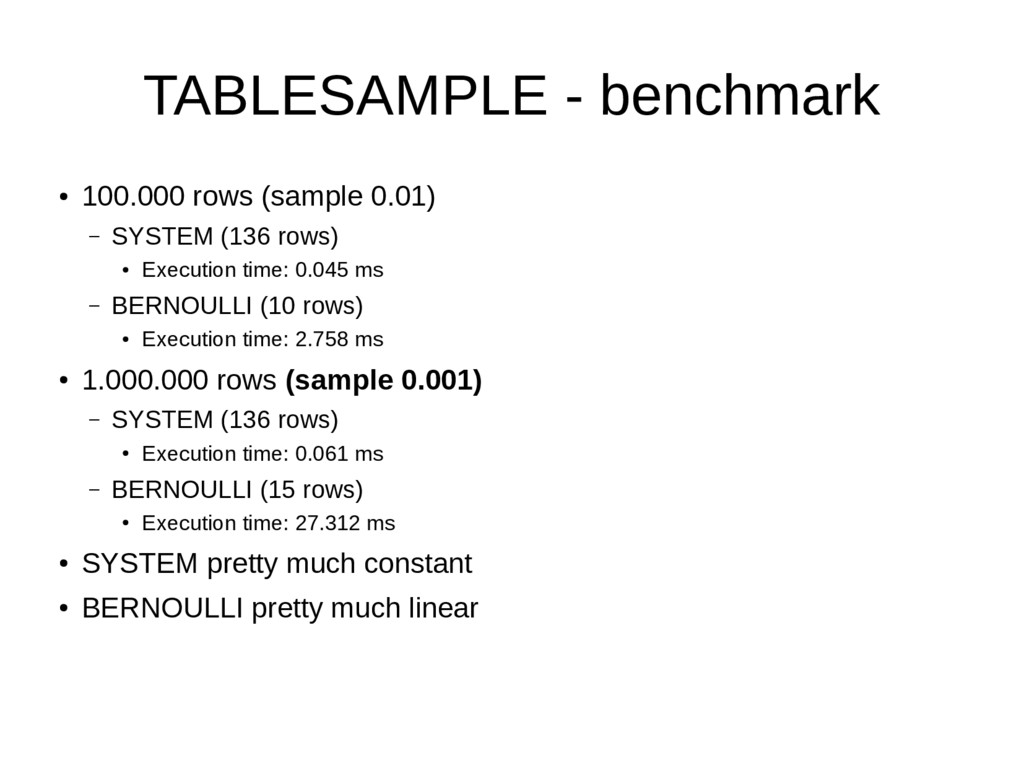
TABLESAMPLE - benchmark • 100.000 rows (sample 0.01) – SYSTEM
(136 rows) • Execution time: 0.045 ms – BERNOULLI (10 rows) • Execution time: 2.758 ms • 1.000.000 rows (sample 0.001) – SYSTEM (136 rows) • Execution time: 0.061 ms – BERNOULLI (15 rows) • Execution time: 27.312 ms • SYSTEM pretty much constant • BERNOULLI pretty much linear -
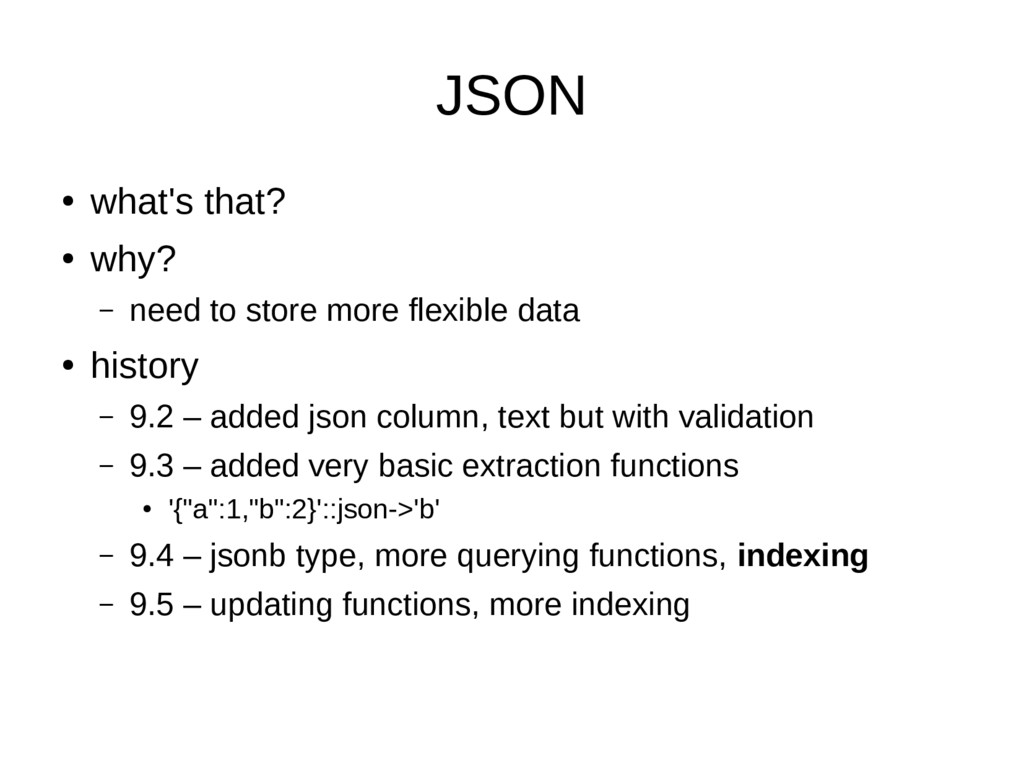
JSON • what's that? • why? – need to store
more flexible data • history – 9.2 – added json column, text but with validation – 9.3 – added very basic extraction functions • '{"a":1,"b":2}'::json->'b' – 9.4 – jsonb type, more querying functions, indexing – 9.5 – updating functions, more indexing -
JSON queries (9.4) • Does the left JSON value contain
within it the right value? – '{"a":1, "b":2}'::jsonb @> '{"b":2}'::jsonb • Does the key/element string exist within the JSON value? – '{"a":1, "b":2}'::jsonb ? 'b' • Do any of these key/element strings exist? – '{"a":1, "b":2, "c":3}'::jsonb ?| array['b', 'c'] • Do all of these key/element strings exist? – '["a", "b"]'::jsonb ?& array['a', 'b'] • Returns the number of elements in the outermost JSON array. – json_array_length(json) • Returns set of keys in the outermost JSON object. – json_object_keys(json) -
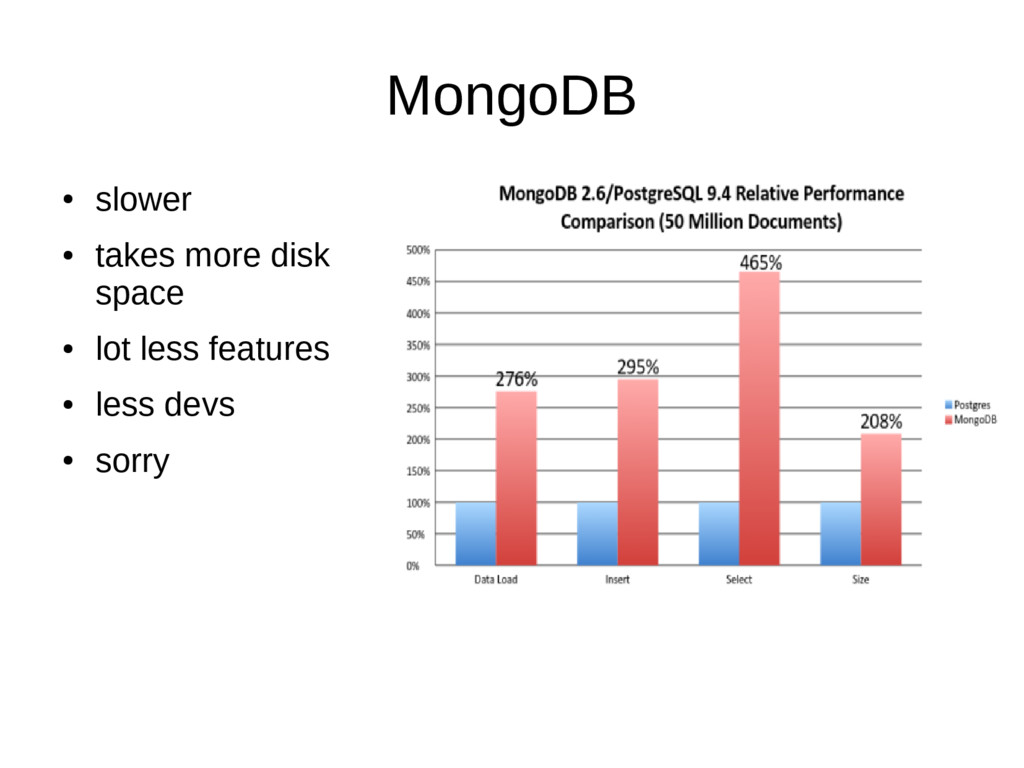
MongoDB • slower • takes more disk space • lot
less features • less devs • sorry -
JSON updates (9.5) • merging – '["a", "b"]'::jsonb || '["c",
"d"]'::jsonb • deleting – '{"a": "b"}'::jsonb – 'a' • updating – jsonb_set('[{"f1":1,"f2":null},2,null,3]', '{0,f1}','[2,3,4]', false) – [{"f1":[2,3,4],"f2":null},2,null,3] -
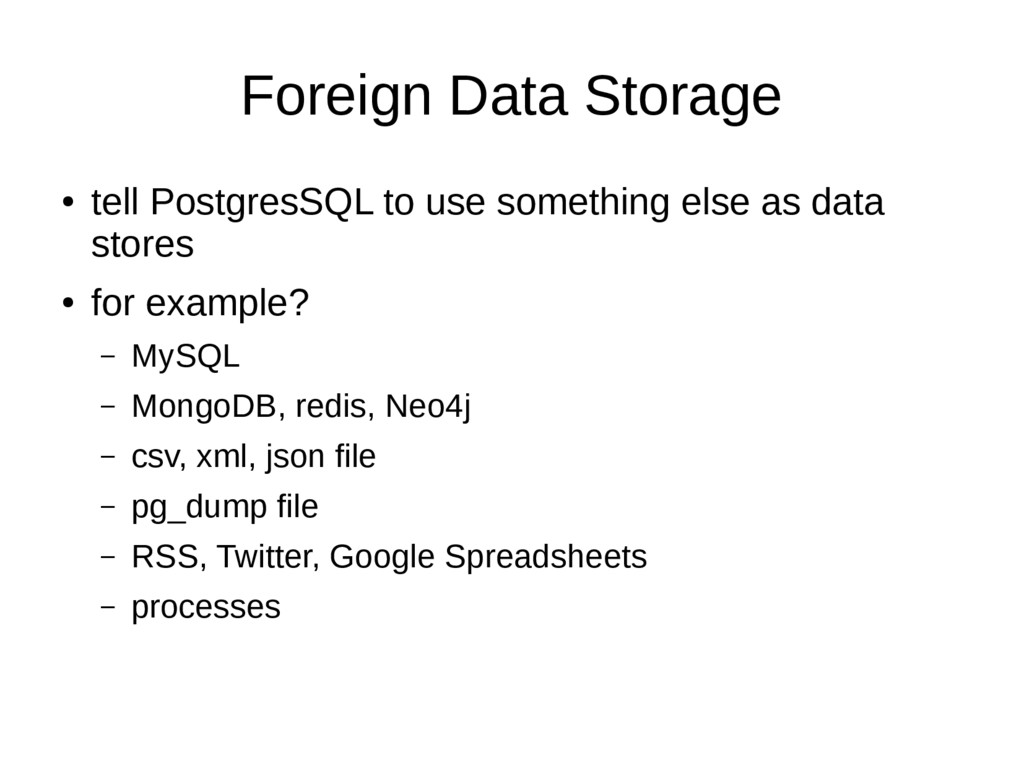
Foreign Data Storage • tell PostgresSQL to use something else
as data stores • for example? – MySQL – MongoDB, redis, Neo4j – csv, xml, json file – pg_dump file – RSS, Twitter, Google Spreadsheets – processes -
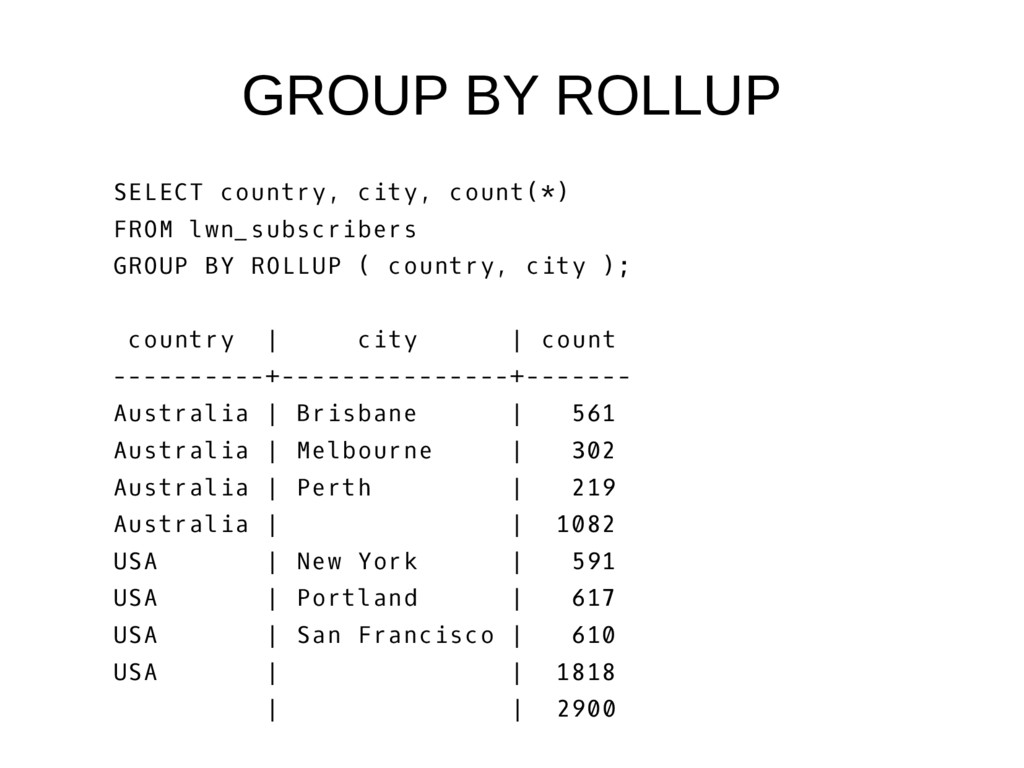
GROUP BY ROLLUP SELECT country, city, count(*) FROM lwn_subscribers GROUP
BY ROLLUP ( country, city ); country | city | count ----------+---------------+------- Australia | Brisbane | 561 Australia | Melbourne | 302 Australia | Perth | 219 Australia | | 1082 USA | New York | 591 USA | Portland | 617 USA | San Francisco | 610 USA | | 1818 | | 2900 -
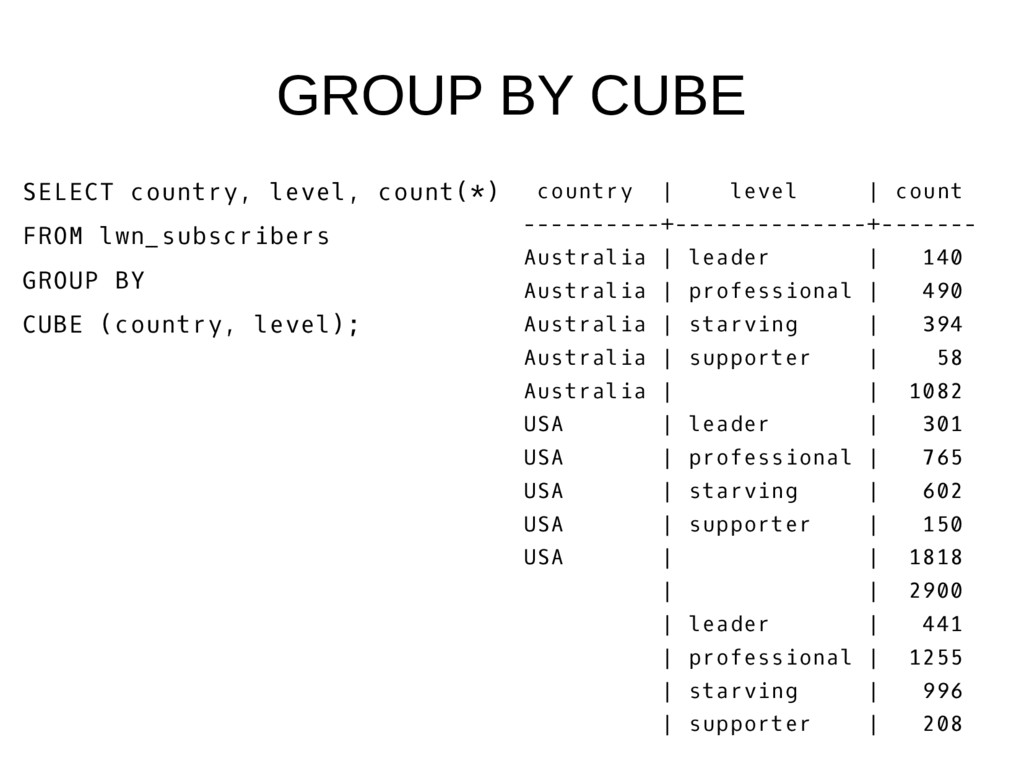
GROUP BY CUBE SELECT country, level, count(*) FROM lwn_subscribers GROUP
BY CUBE (country, level); country | level | count ----------+--------------+------- Australia | leader | 140 Australia | professional | 490 Australia | starving | 394 Australia | supporter | 58 Australia | | 1082 USA | leader | 301 USA | professional | 765 USA | starving | 602 USA | supporter | 150 USA | | 1818 | | 2900 | leader | 441 | professional | 1255 | starving | 996 | supporter | 208 -
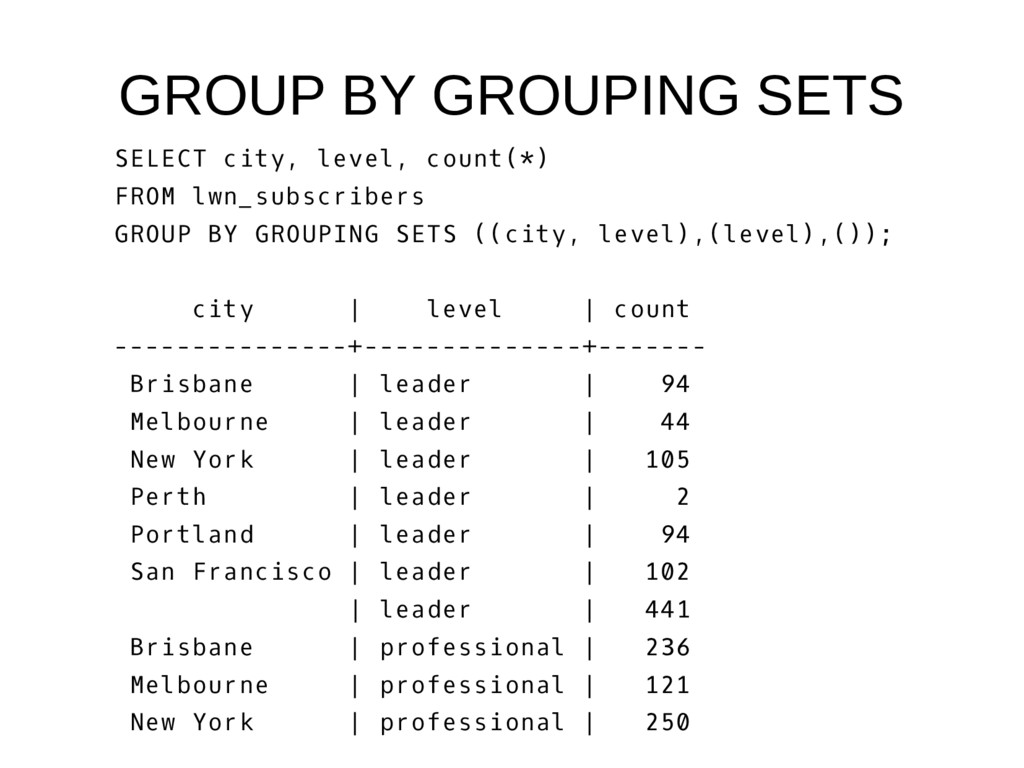
GROUP BY GROUPING SETS SELECT city, level, count(*) FROM lwn_subscribers
GROUP BY GROUPING SETS ((city, level),(level),()); city | level | count ---------------+--------------+------- Brisbane | leader | 94 Melbourne | leader | 44 New York | leader | 105 Perth | leader | 2 Portland | leader | 94 San Francisco | leader | 102 | leader | 441 Brisbane | professional | 236 Melbourne | professional | 121 New York | professional | 250 -
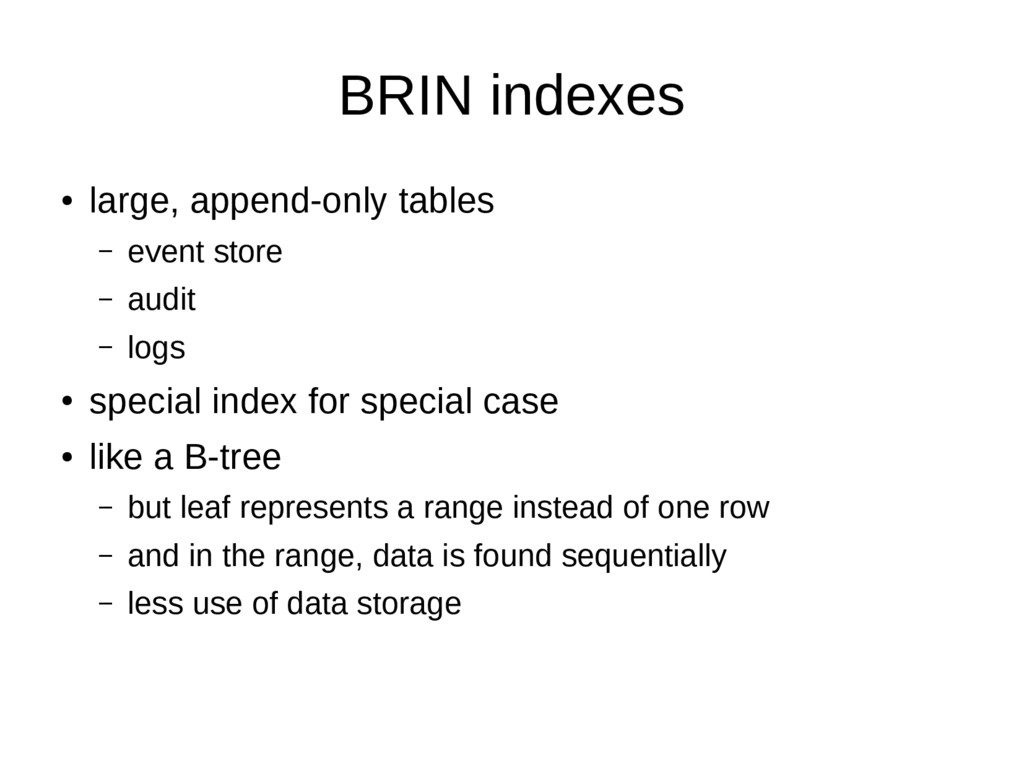
BRIN indexes • large, append-only tables – event store –
audit – logs • special index for special case • like a B-tree – but leaf represents a range instead of one row – and in the range, data is found sequentially – less use of data storage -
Retrospection • BTW. It is a pleasure now to test
bleeding-edge software • Old way – compilation, adding external package sources, etc… • New way – Install docker – docker run -it jberkus/postgres95-test -
Sources • tablesample – http://www.depesz.com/2015/05/23/waiting-for-9-5-tablesample-sql-standard-and-extensible / – http://www.depesz.com/2007/09/16/my-thoughts-on-getting-random-row/ • upsert
– http://www.depesz.com/2012/06/10/why-is-upsert-so-complicated/ – merge vs. upsert • http://www.postgresql.org/message-id/CAM3SWZRP0c3g6+aJ=YYDGYAcTZg0xA8-1 [email protected] – • pg vs. mongo – http://www.enterprisedb.com/postgres-plus-edb-blog/marc-linster/postgres-outperforms-mo ngodb-and-ushers-new-developer-reality – http://www.aptuz.com/blog/is-postgres-nosql-database-better-than-mongodb/ • https://wiki.postgresql.org/wiki/PostgreSQLTestDockerImage