Share
Embed
Assembly: The mother of all languages
A dive into every programmer's core roots - the assembly language - the foundation of every high-level language, like C++, Java, Scala & Clojure, and the major reason for their evolution.
Key points:
* The basics of the assembly language and how it differs from the JVM Bytecode.
* How the assembly language varies between architectures, e.g. x64, ARM, and OSs, e.g. Windows, Linux, Android.
* See how the differences between high-level languages, like Java, Scala & C/C++, affect the assembly behind them.
* How the JIT compiler utilizes assembly for maximum efficiency at run-time.

Takipi
November 19, 2013
Transcript
70 slides
-
About me • Moshe Ba’avur • Lead Engineer at Takipi
www.takipi.com -
About me – what was • Started coding at the
age of 12, and haven’t looked back since. • Prestigious course of an elite IDF tech unit • Dev at Microsoft – PCHealth group • B.Sc. in mathematics & computer science from TAU www.takipi.com -
So, what’s on schedule? • Assembly 101 • Platform dependent
assembly • Java & C++ - looking under the hood • The JIT compiler www.takipi.com -
Let’s start… What is Assembly? • Generic name for any
CPU language • Intel, AMD, ARM, MIPS etc. • Intel has over 500 instructions Why should I know it? • Performance limits • Security problems • CPU limits • Reverse engineering • The important of all…fun! www.takipi.com -
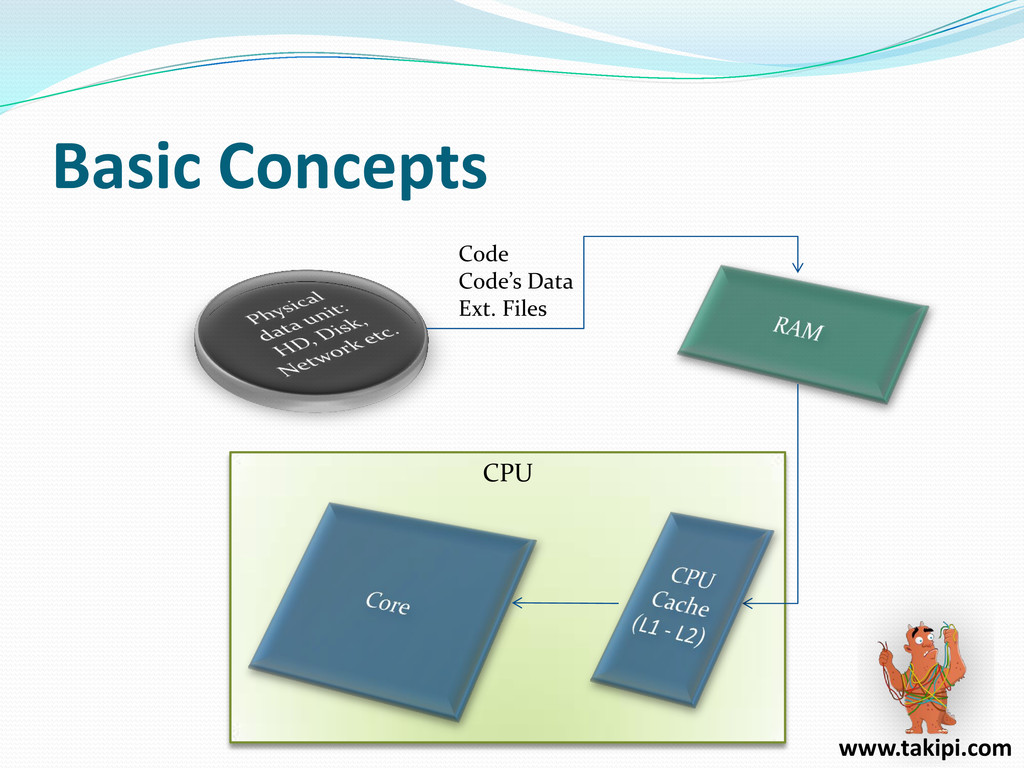
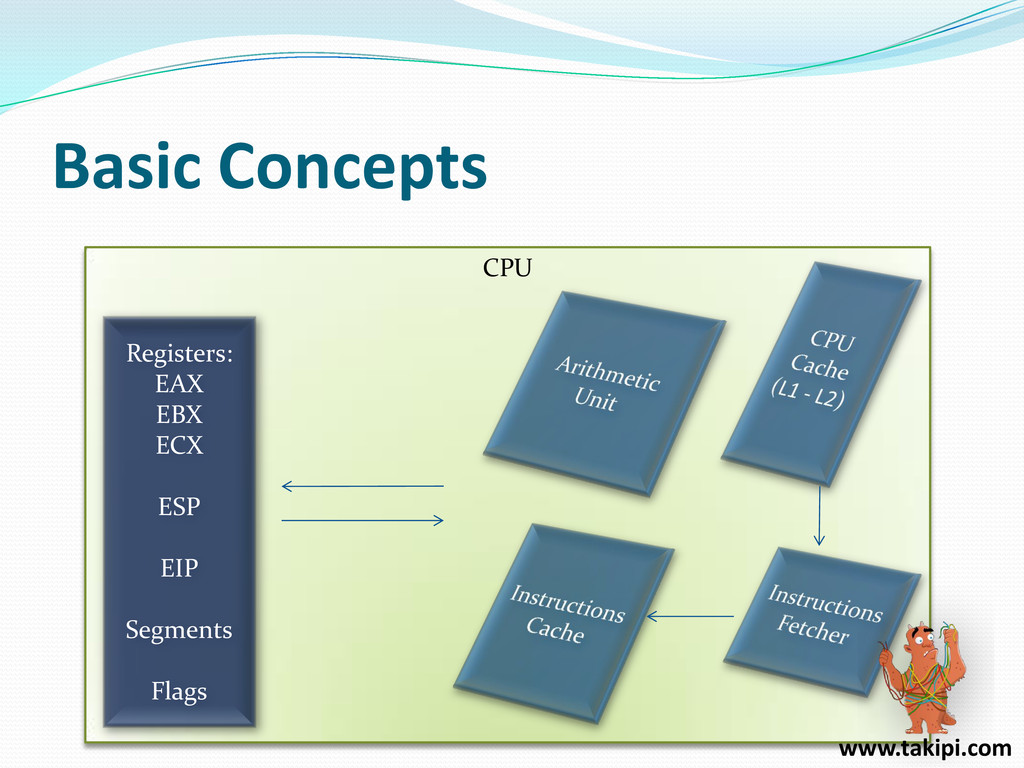
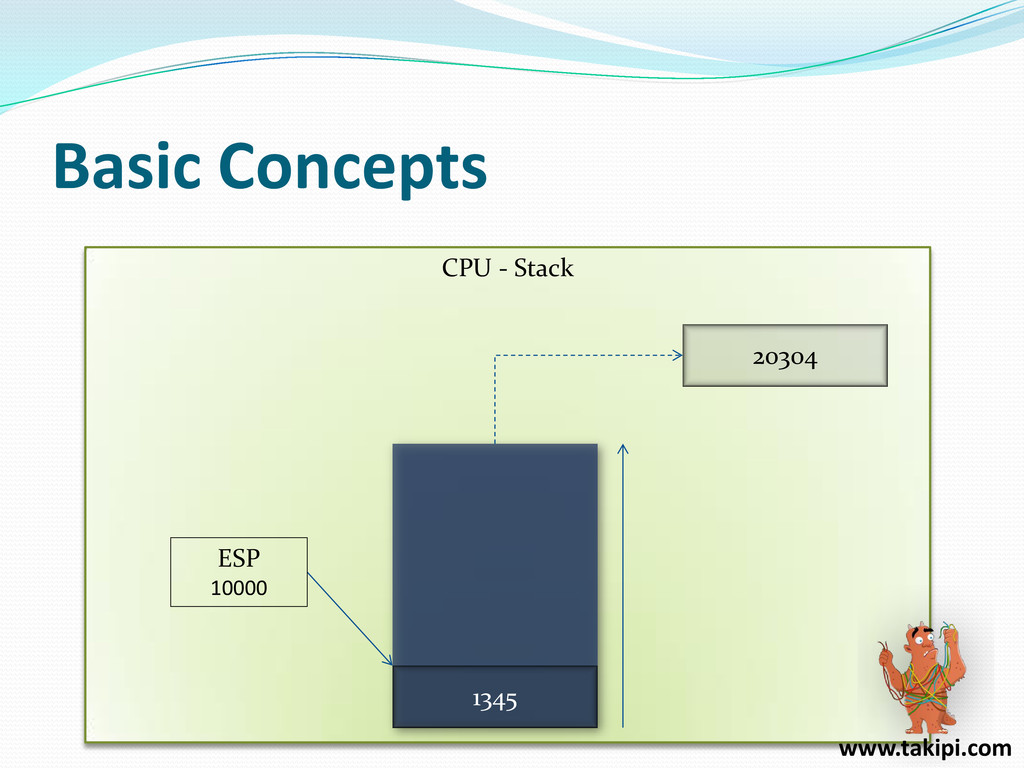
CPU Basic Concepts Registers: EAX EBX ECX ESP EIP Segments
Flags www.takipi.com -
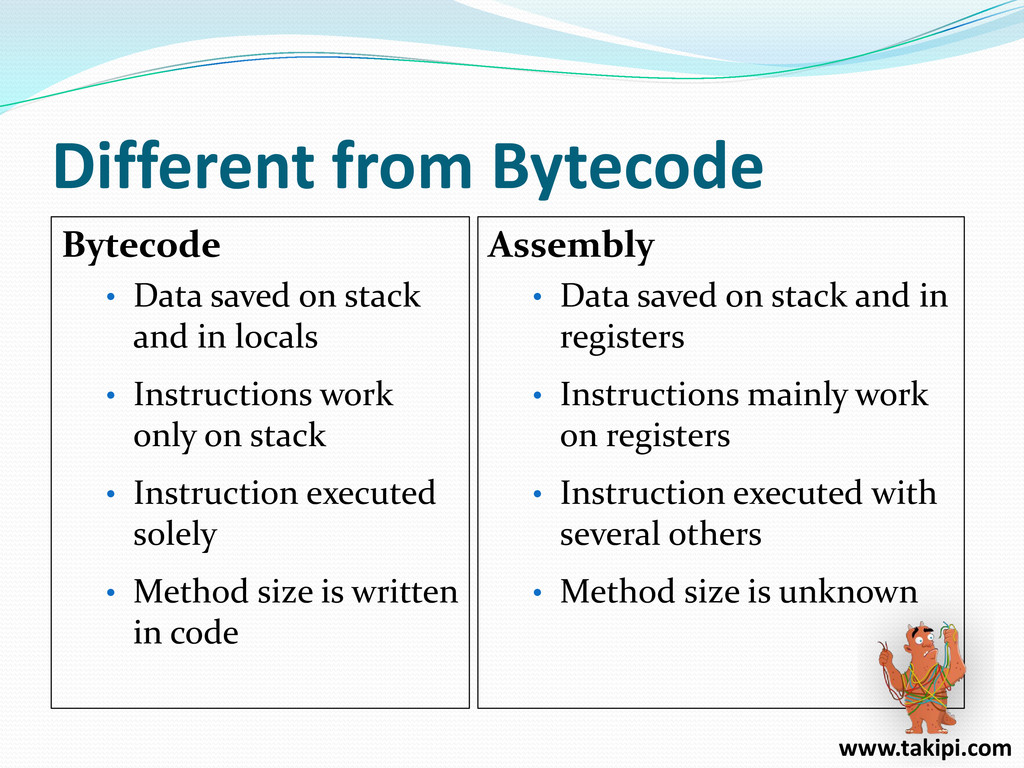
Different from Bytecode Bytecode • Data saved on stack and
in locals • Instructions work only on stack • Instruction executed solely • Method size is written in code Assembly • Data saved on stack and in registers • Instructions mainly work on registers • Instruction executed with several others • Method size is unknown www.takipi.com -
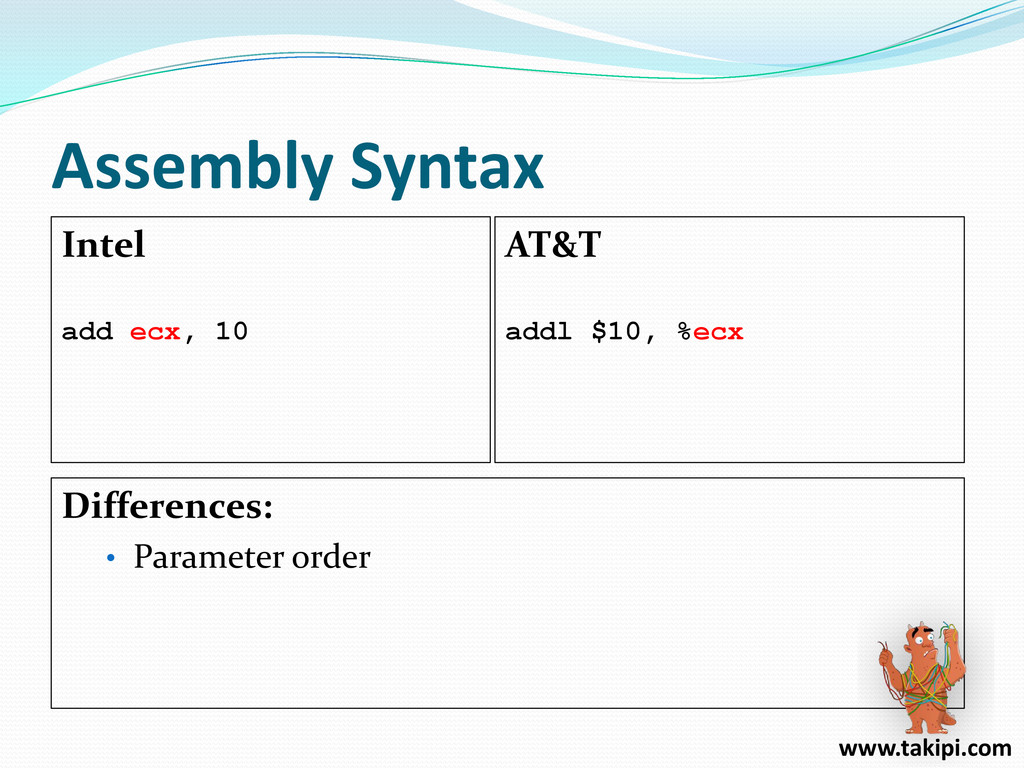
Assembly Syntax Intel add ecx, 10 AT&T addl $10, %ecx
Differences: www.takipi.com -
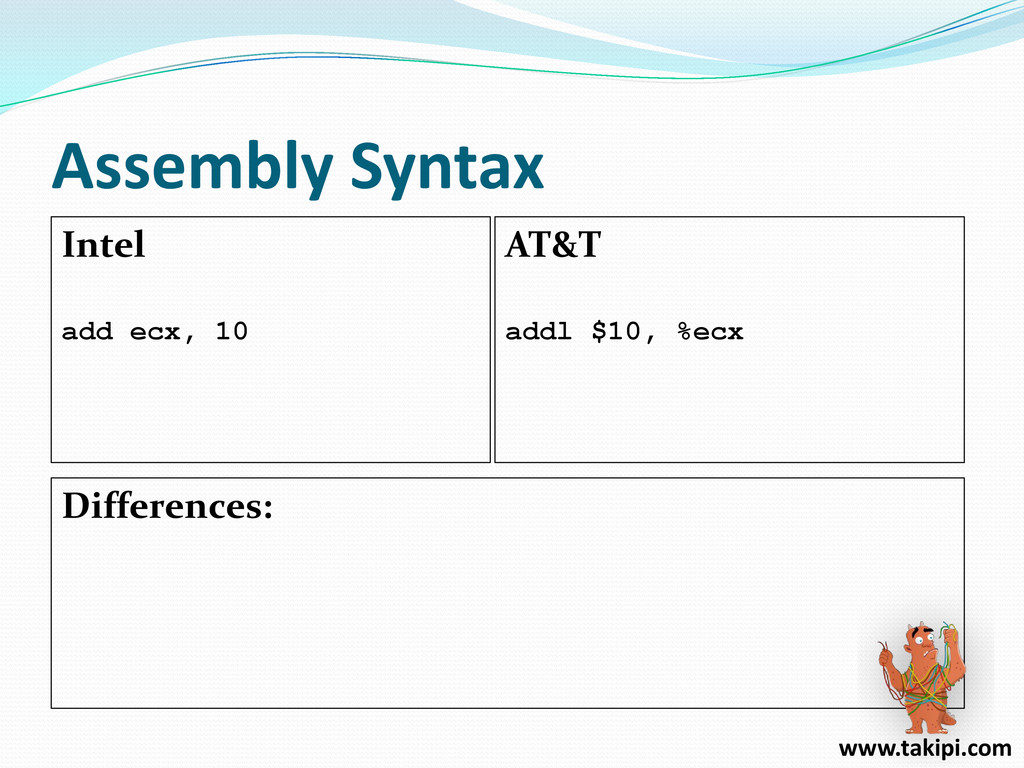
Assembly Syntax Intel add ecx, 10 AT&T addl $10, %ecx
Differences: • Parameter order www.takipi.com -
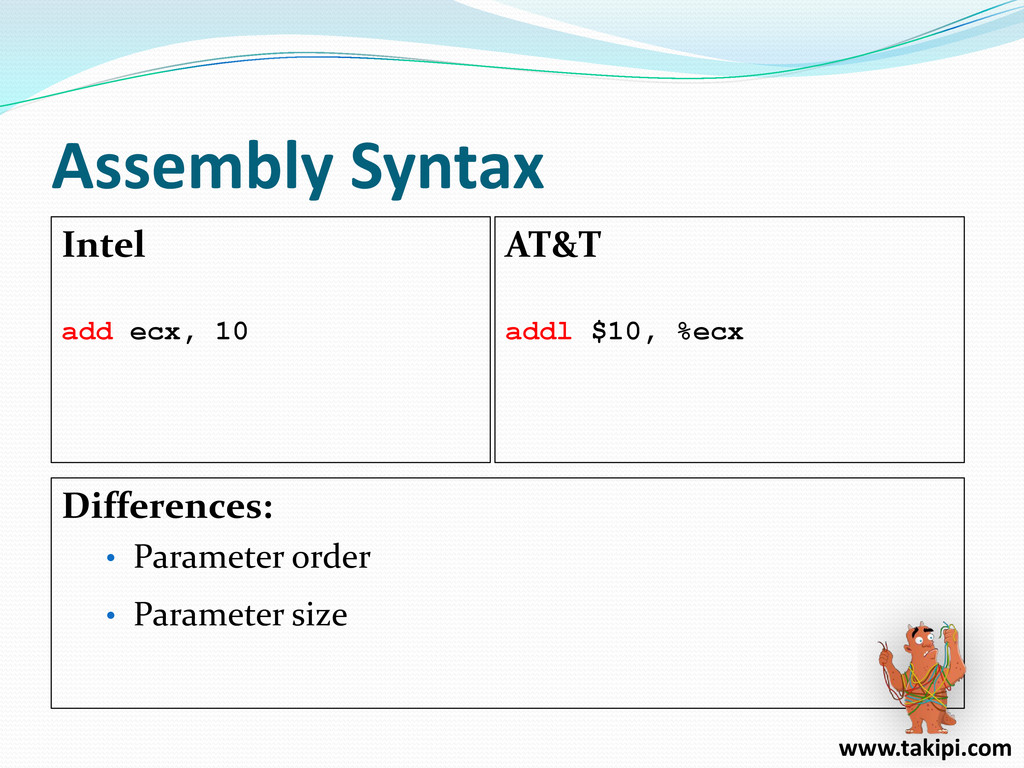
Assembly Syntax Intel add ecx, 10 AT&T addl $10, %ecx
Differences: • Parameter order • Parameter size www.takipi.com -
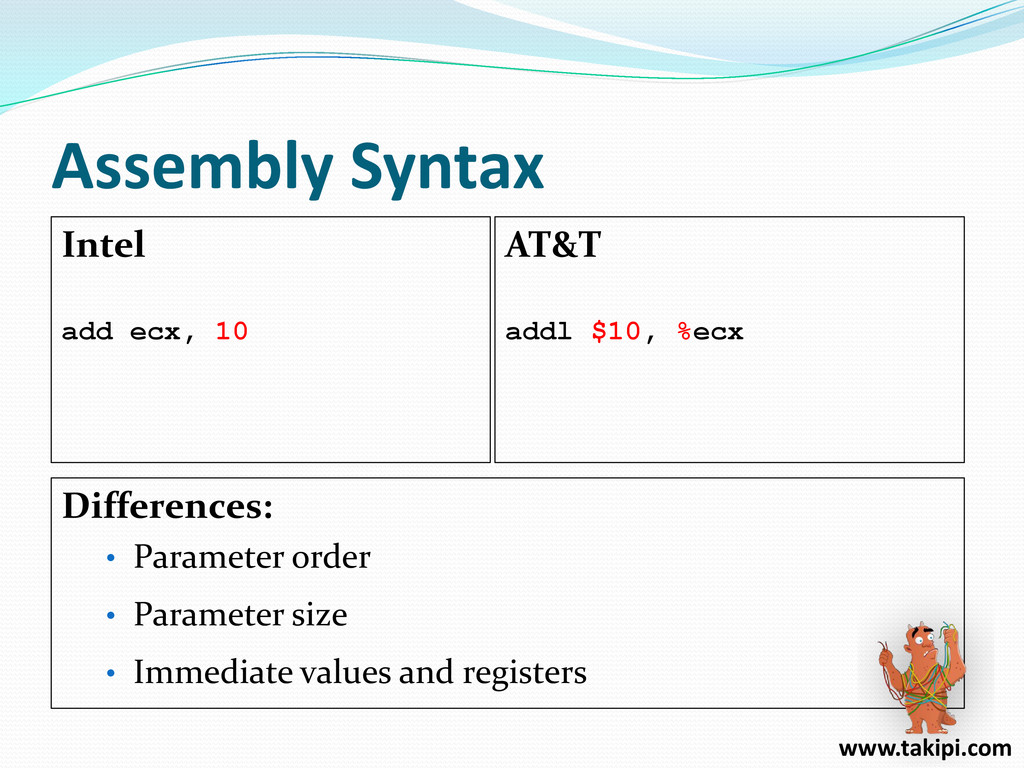
Assembly Syntax Intel add ecx, 10 AT&T addl $10, %ecx
Differences: • Parameter order • Parameter size • Immediate values and registers www.takipi.com -
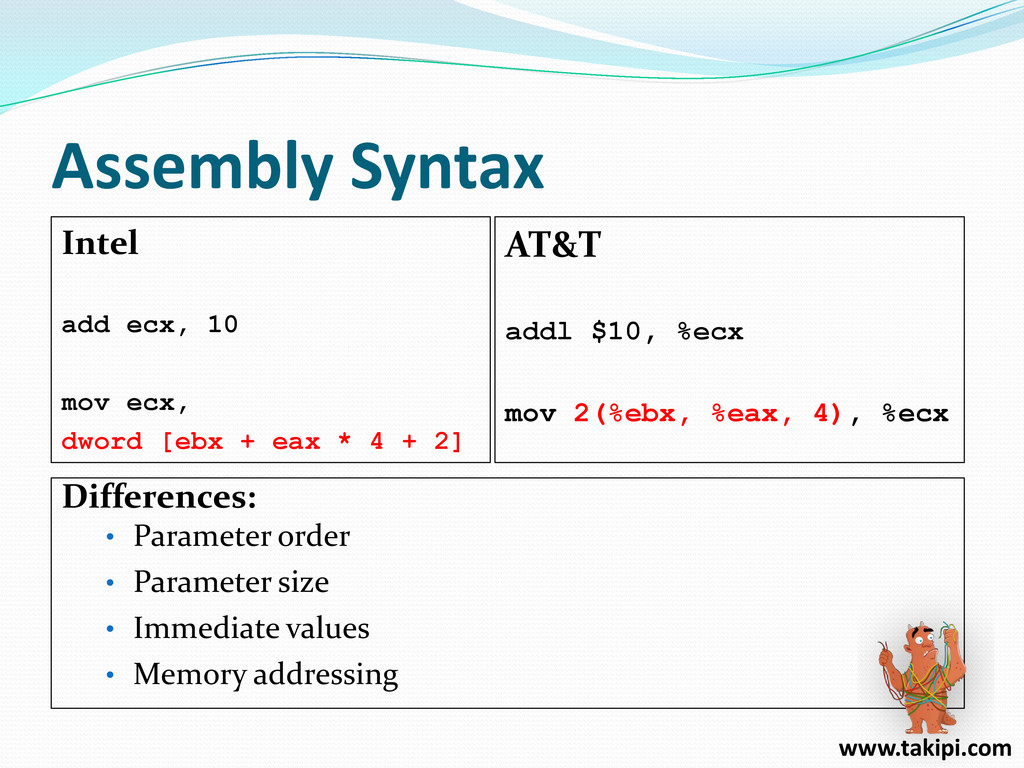
Assembly Syntax Intel add ecx, 10 mov ecx, dword [ebx
+ eax * 4 + 2] AT&T addl $10, %ecx mov 2(%ebx, %eax, 4), %ecx Differences: • Parameter order • Parameter size • Immediate values • Memory addressing www.takipi.com -
MOV “The assignment operator” Assigns data into registers or memory
locations. Assigned Data can be: • Constants • Registers • Memory data, unless destination is memory Syntax: mov eax, 12 // eax = 12 mov ax, bx // ax = bx -> eax = 0x0000ffff & bx mov [ebx + 16], eax // ebx[16] = eax www.takipi.com -
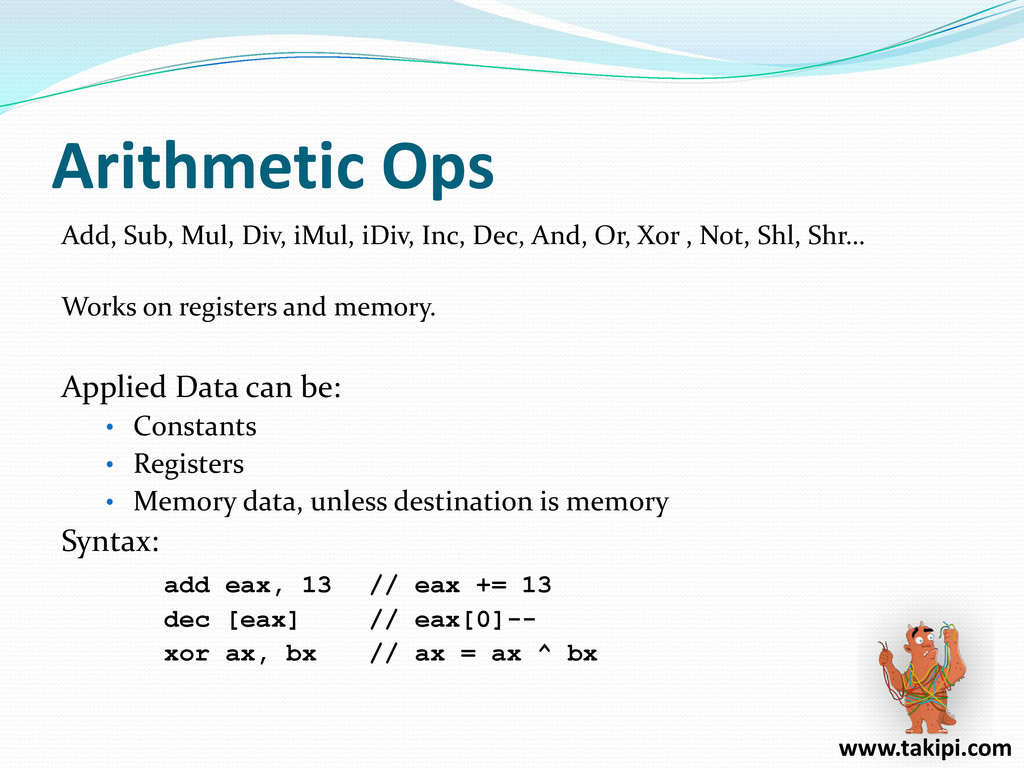
Arithmetic Ops Add, Sub, Mul, Div, iMul, iDiv, Inc, Dec,
And, Or, Xor , Not, Shl, Shr… Works on registers and memory. Applied Data can be: • Constants • Registers • Memory data, unless destination is memory Syntax: add eax, 13 // eax += 13 dec [eax] // eax[0]-- xor ax, bx // ax = ax ^ bx www.takipi.com -
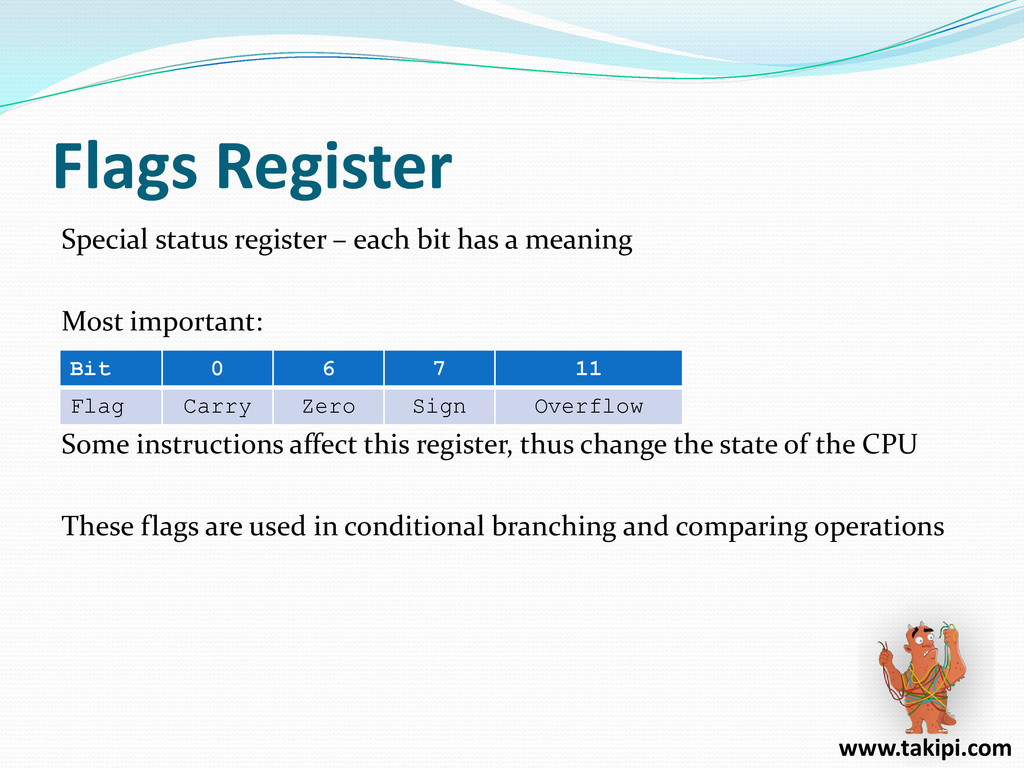
Flags Register Special status register – each bit has a
meaning Most important: Some instructions affect this register, thus change the state of the CPU These flags are used in conditional branching and comparing operations Bit 0 6 7 11 Flag Carry Zero Sign Overflow www.takipi.com -
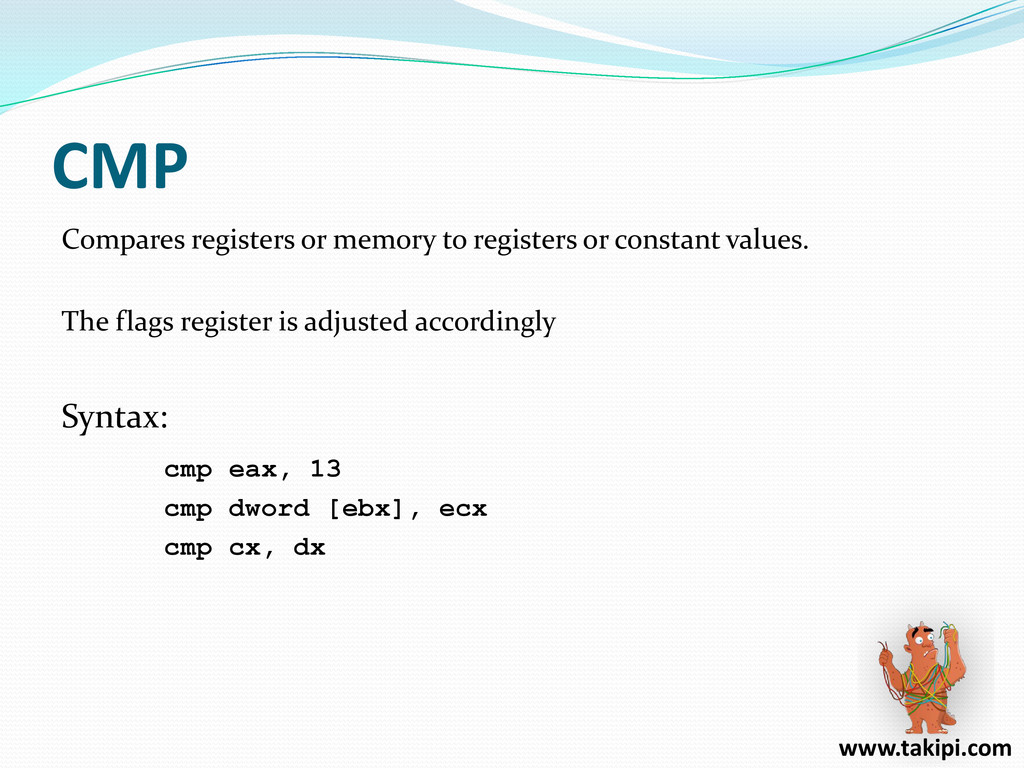
CMP Compares registers or memory to registers or constant values.
The flags register is adjusted accordingly Syntax: cmp eax, 13 cmp dword [ebx], ecx cmp cx, dx www.takipi.com -
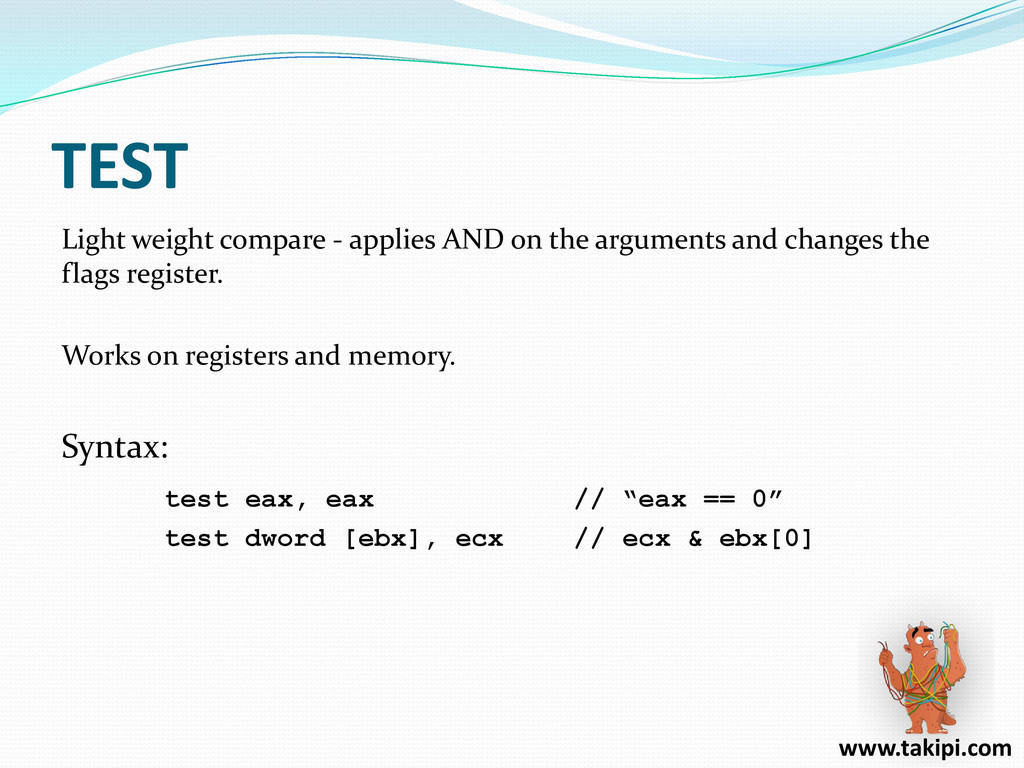
TEST Light weight compare - applies AND on the arguments
and changes the flags register. Works on registers and memory. Syntax: test eax, eax // “eax == 0” test dword [ebx], ecx // ecx & ebx[0] www.takipi.com -
XOR & ADC Nice examples: • Example 1: XOR can
be used for zeroing: xor eax, eax // eax = 0 • Example 2: The following piece of code: a += (c >= 100) ? 1 : 0 ; On most computers translates to: // a -> eax, c -> ecx cmp ecx, 100 adc eax, 0 www.takipi.com -
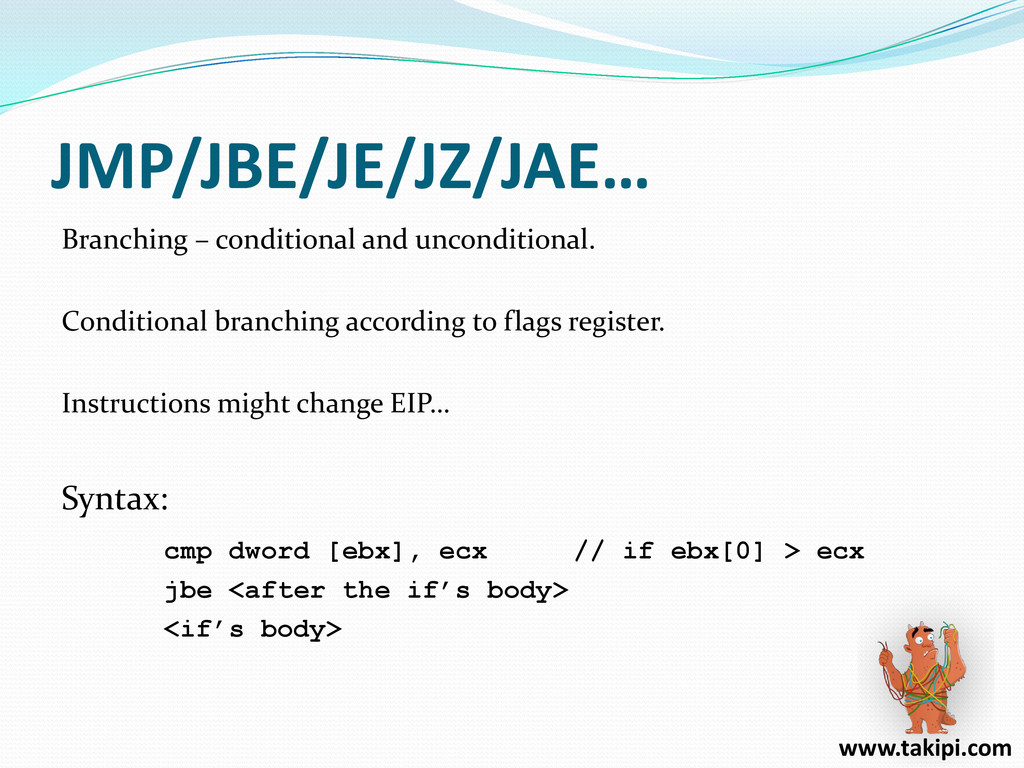
JMP/JBE/JE/JZ/JAE… Branching – conditional and unconditional. Conditional branching according to
flags register. Instructions might change EIP… Syntax: cmp dword [ebx], ecx // if ebx[0] > ecx jbe <after the if’s body> <if’s body> www.takipi.com -
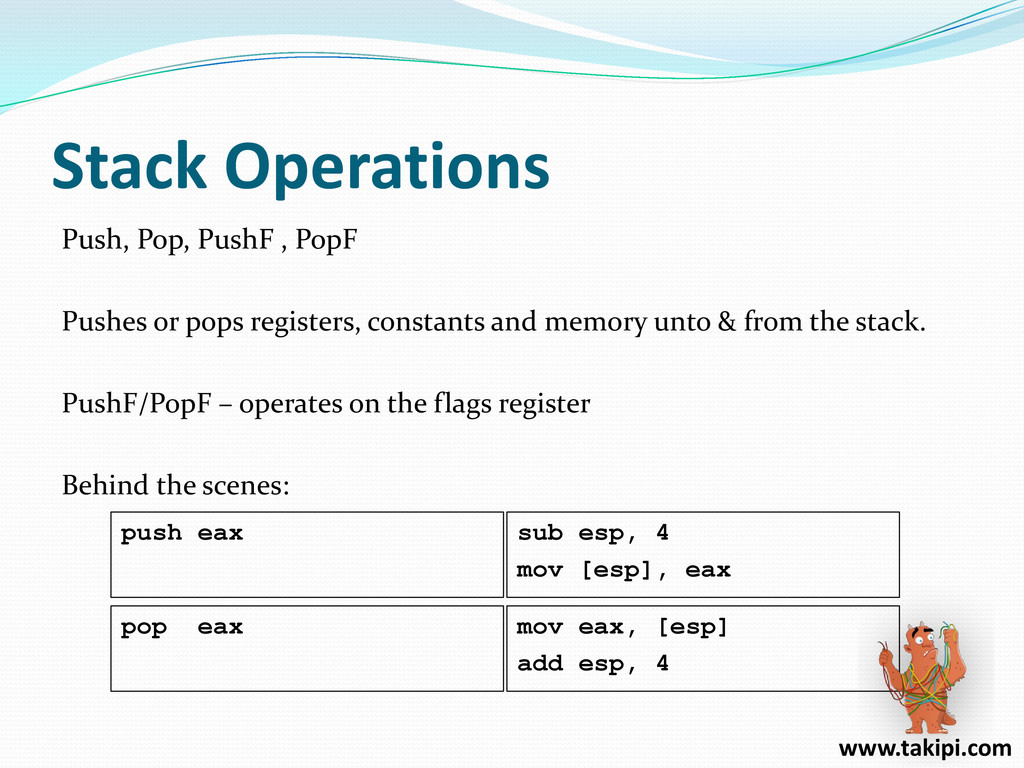
Stack Operations Push, Pop, PushF , PopF Pushes or pops
registers, constants and memory unto & from the stack. PushF/PopF – operates on the flags register Behind the scenes: push eax sub esp, 4 mov [esp], eax pop eax mov eax, [esp] add esp, 4 www.takipi.com -
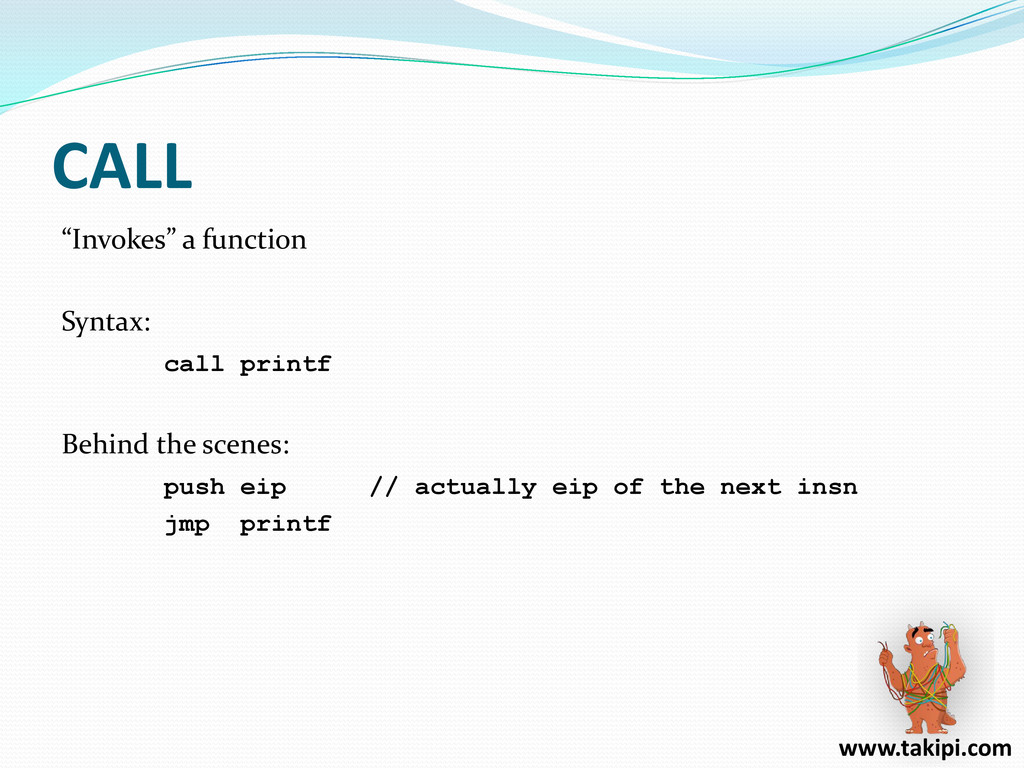
CALL “Invokes” a function Syntax: call printf Behind the scenes:
push eip // actually eip of the next insn jmp printf www.takipi.com -
RET Return from a function Syntax: ret Behind the scenes:
pop eax jmp *eax www.takipi.com -
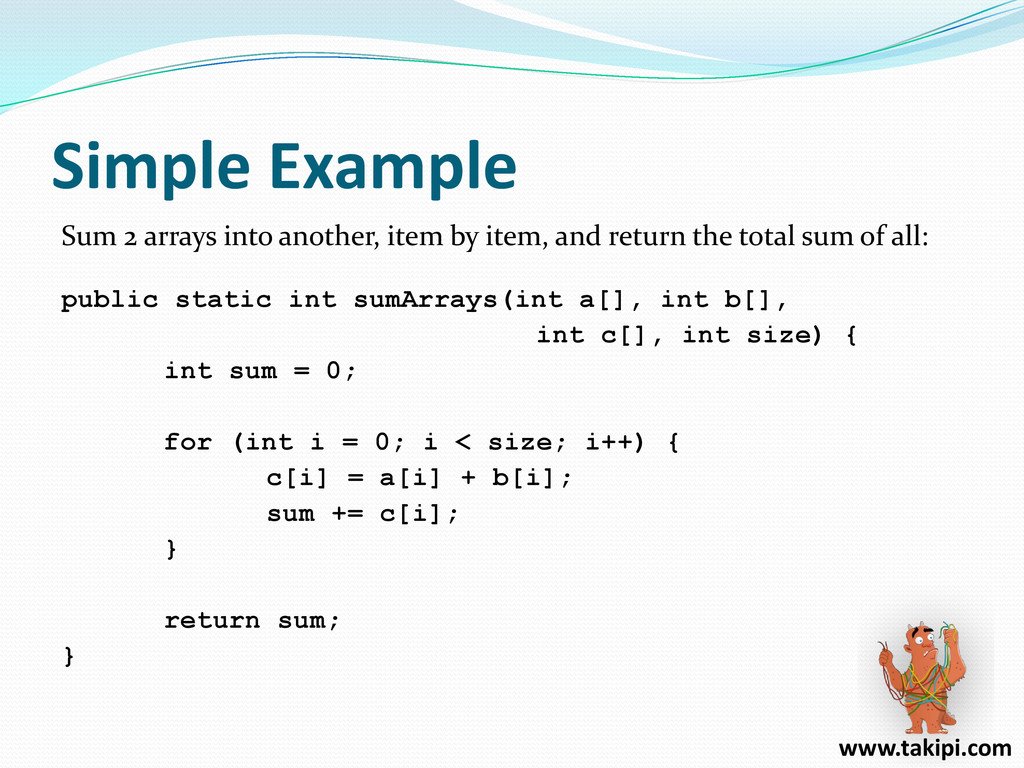
Simple Example Sum 2 arrays into another, item by item,
and return the total sum of all: public static int sumArrays(int a[], int b[], int c[], int size) { int sum = 0; for (int i = 0; i < size; i++) { c[i] = a[i] + b[i]; sum += c[i]; } return sum; } www.takipi.com -
Simple Example – Part 1 int sum = 0; for
(int i = 0; i < size a[] in r8 b[] in r9 c[] in r10 size in r11 return in rax xor eax, eax // eax = 0 mov rcx, r11 // rcx = r11 = size cmp rcx, 0 jbe end_func // if (rcx <= 0) “goto end_func”; www.takipi.com -
Simple Example – Part 2 c[i] = a[i] + b[i];
sum += c[i]; func_loop: mov rdx, [r8] // rdx = r8[0]; add rdx, [r9] // rdx += r9[0]; mov [r10], rdx // r10[0] = rdx; add rax, rdx // rax += rdx; = sum += c[i]; add r8, 4 // r8 += 4; add r9, 4 // r9 += 4; add r10, 4 // r10 += 4; a[] in r8 b[] in r9 c[] in r10 size in r11 return in rax www.takipi.com -
Simple Example – Part 3 for (…; i < size;
i++) return sum; dec rcx // rcx--; jnz func_loop // if (rcx != 0) “goto func_loop”; end_func: ret // return rax; a[] in r8 b[] in r9 c[] in r10 size in r11 return in rax www.takipi.com -
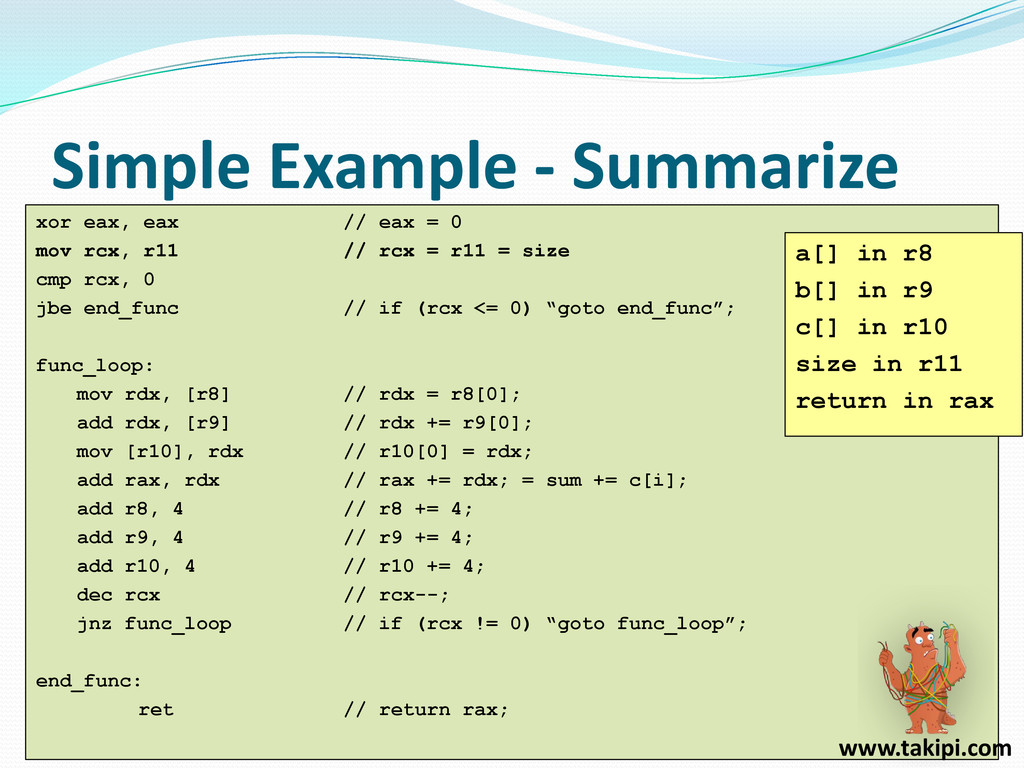
Simple Example - Summarize xor eax, eax // eax =
0 mov rcx, r11 // rcx = r11 = size cmp rcx, 0 jbe end_func // if (rcx <= 0) “goto end_func”; func_loop: mov rdx, [r8] // rdx = r8[0]; add rdx, [r9] // rdx += r9[0]; mov [r10], rdx // r10[0] = rdx; add rax, rdx // rax += rdx; = sum += c[i]; add r8, 4 // r8 += 4; add r9, 4 // r9 += 4; add r10, 4 // r10 += 4; dec rcx // rcx--; jnz func_loop // if (rcx != 0) “goto func_loop”; end_func: ret // return rax; a[] in r8 b[] in r9 c[] in r10 size in r11 return in rax www.takipi.com -
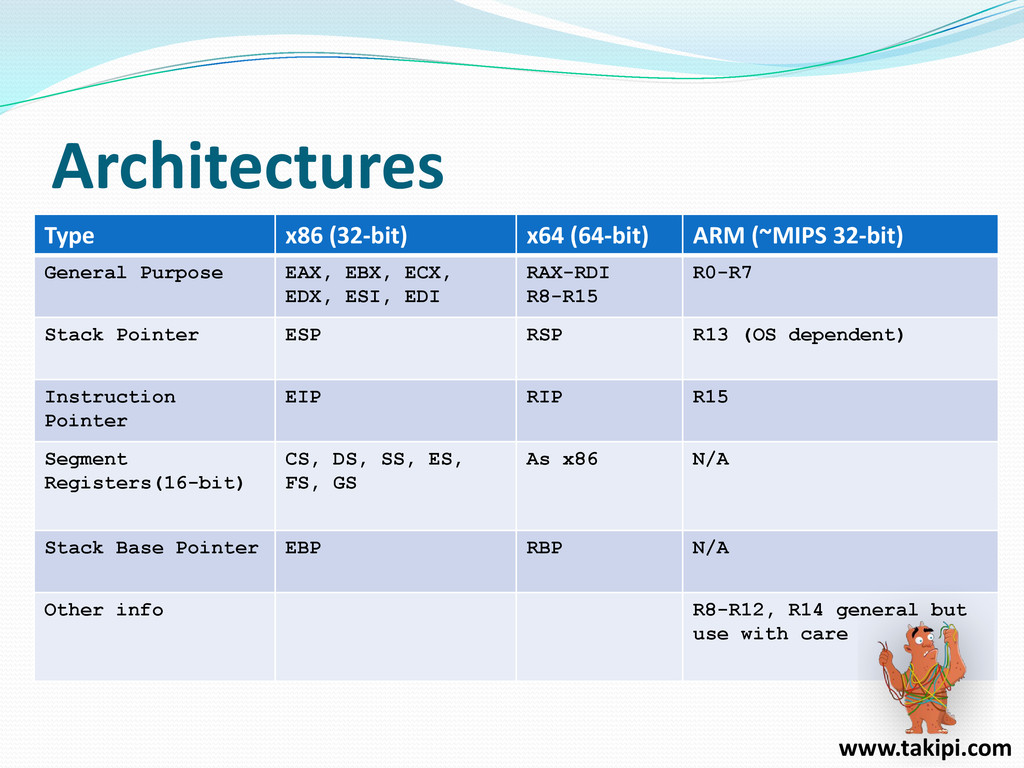
Type x86 (32-bit) x64 (64-bit) ARM (~MIPS 32-bit) General Purpose
EAX, EBX, ECX, EDX, ESI, EDI RAX-RDI R8-R15 R0-R7 Stack Pointer ESP RSP R13 (OS dependent) Instruction Pointer EIP RIP R15 Segment Registers(16-bit) CS, DS, SS, ES, FS, GS As x86 N/A Stack Base Pointer EBP RBP N/A Other info R8-R12, R14 general but use with care Architectures www.takipi.com -
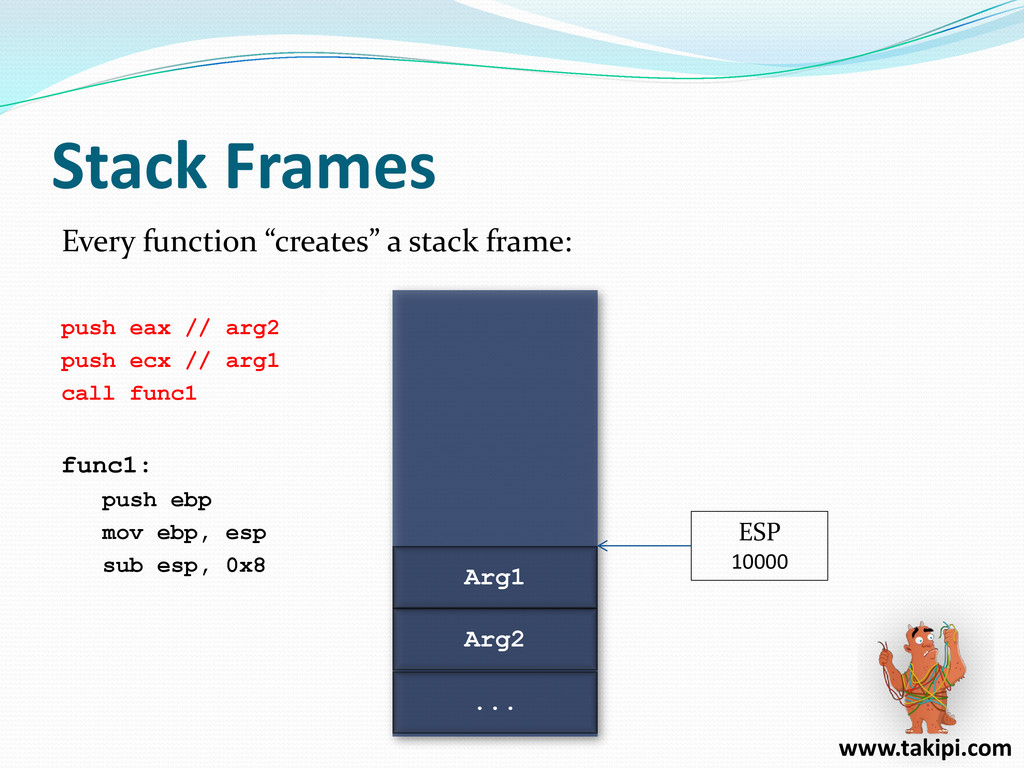
Stack Frames Every function “creates” a stack frame: push eax
// arg2 push ecx // arg1 call func1 func1: push ebp mov ebp, esp sub esp, 0x8 Arg1 ESP 10000 Arg2 ... www.takipi.com -
Stack Frames Every function “creates” a stack frame: push eax
// arg2 push ecx // arg1 call func1 func1: push ebp mov ebp, esp sub esp, 0x8 Arg1 ESP 10000 Arg2 ... www.takipi.com -
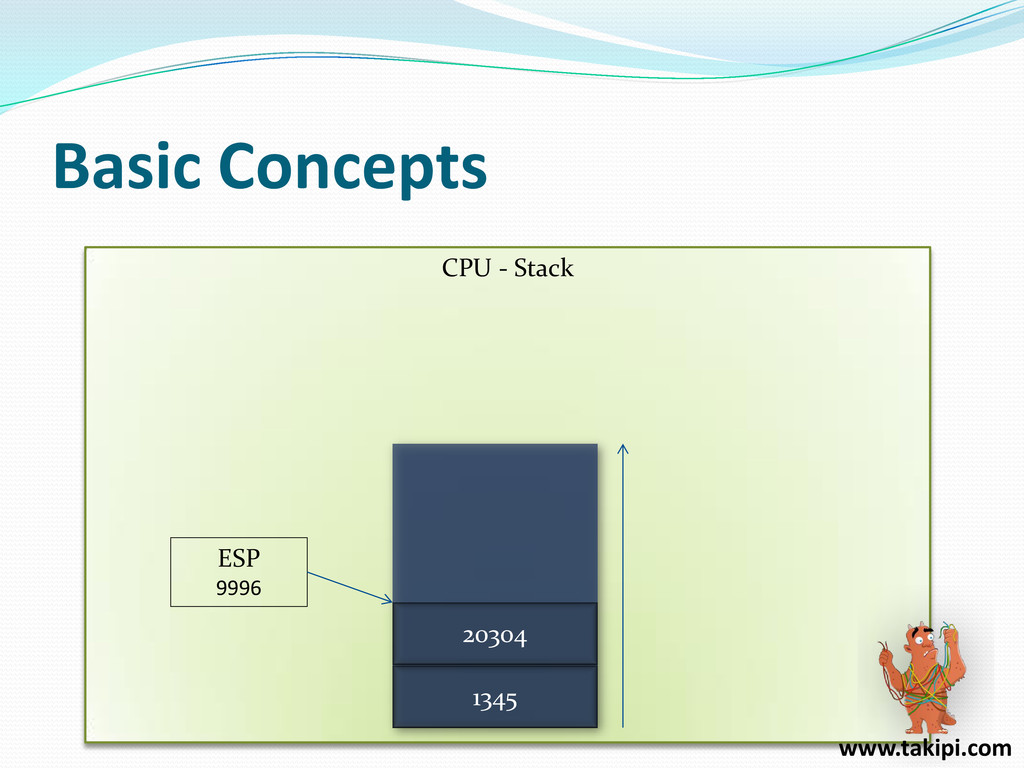
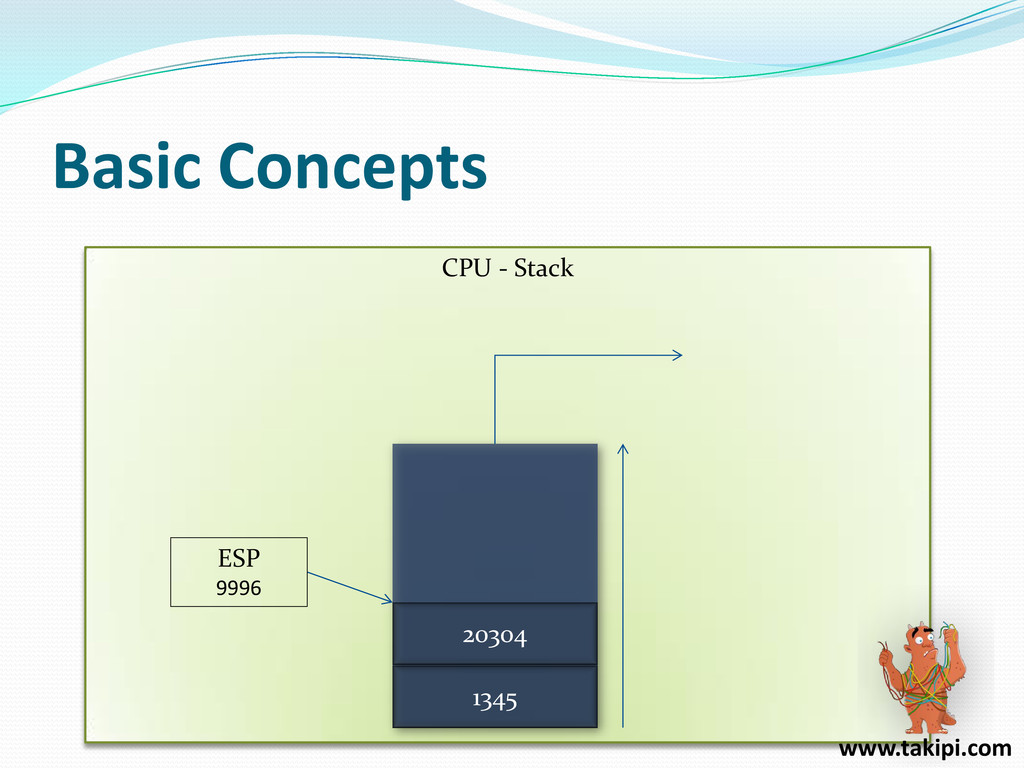
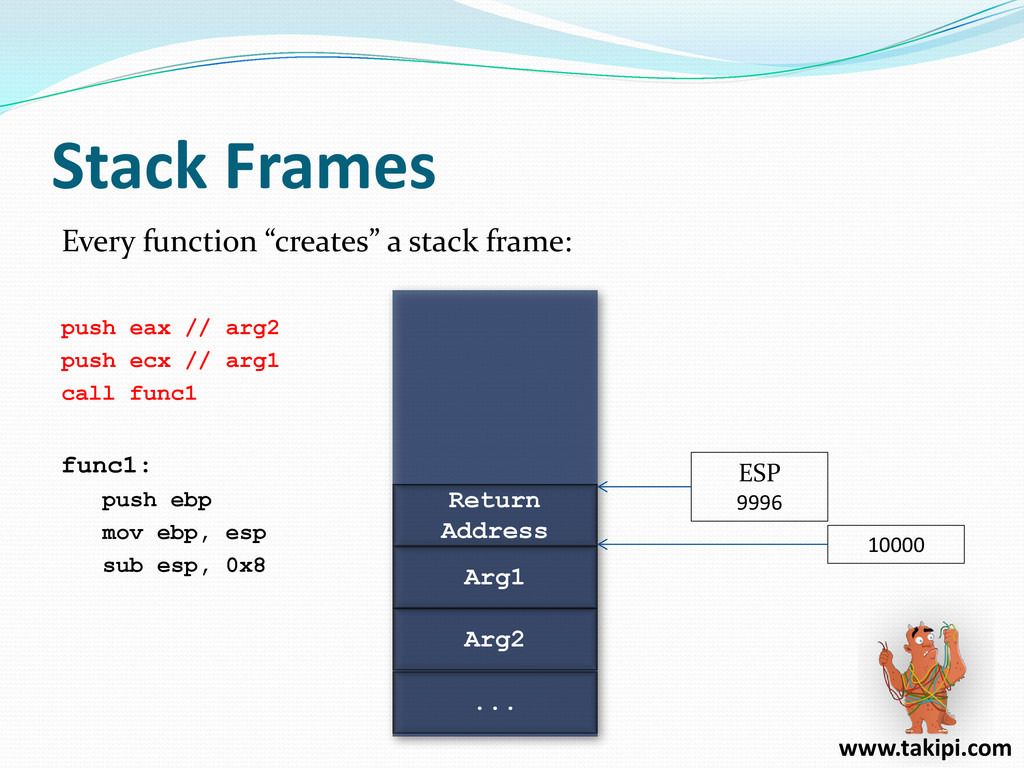
Stack Frames Every function “creates” a stack frame: push eax
// arg2 push ecx // arg1 call func1 func1: push ebp mov ebp, esp sub esp, 0x8 Arg1 ESP 9996 Arg2 ... Return Address 10000 www.takipi.com -
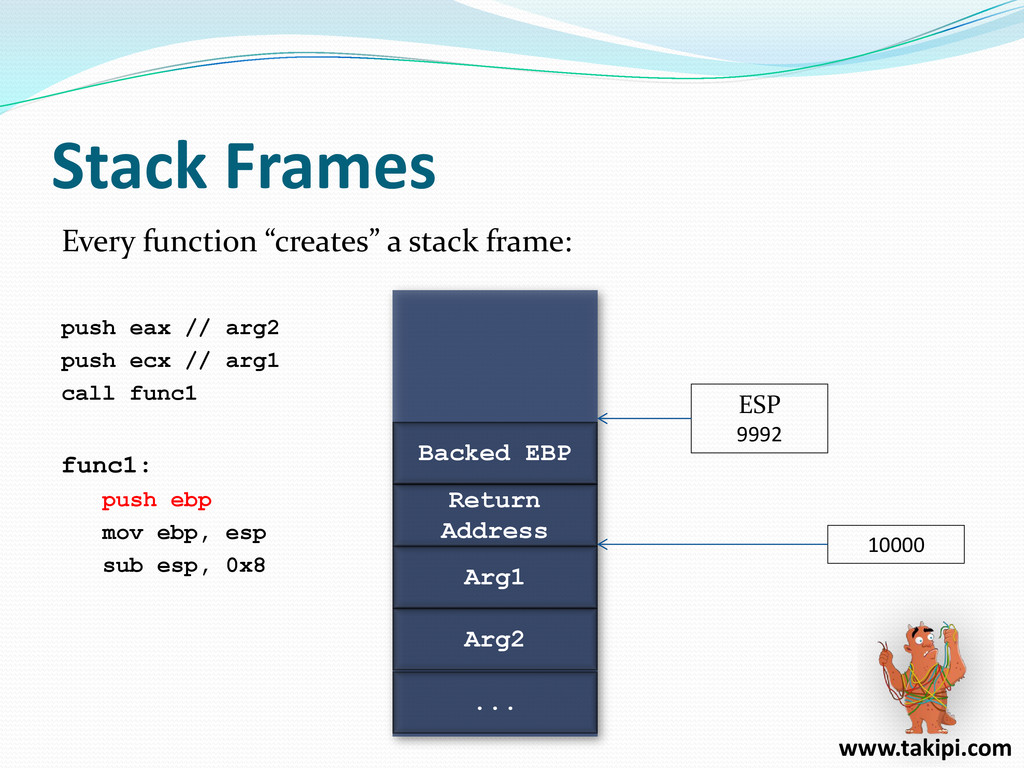
Stack Frames Every function “creates” a stack frame: push eax
// arg2 push ecx // arg1 call func1 func1: push ebp mov ebp, esp sub esp, 0x8 Arg1 ESP 9992 Arg2 ... Return Address 10000 Backed EBP www.takipi.com -
Stack Frames Every function “creates” a stack frame: push eax
// arg2 push ecx // arg1 call func1 func1: push ebp mov ebp, esp sub esp, 0x8 Arg1 ESP 9992 Arg2 ... Return Address 10000 Backed EBP EBP 9992 www.takipi.com -
Stack Frames Every function “creates” a stack frame: push eax
// arg2 push ecx // arg1 call func1 func1: push ebp mov ebp, esp sub esp, 0x8 Arg1 ESP 9984 EBP 9992 Return Address Backed EBP N/A N/A 10000 Arg2 ... S t a c k F r a m e www.takipi.com -
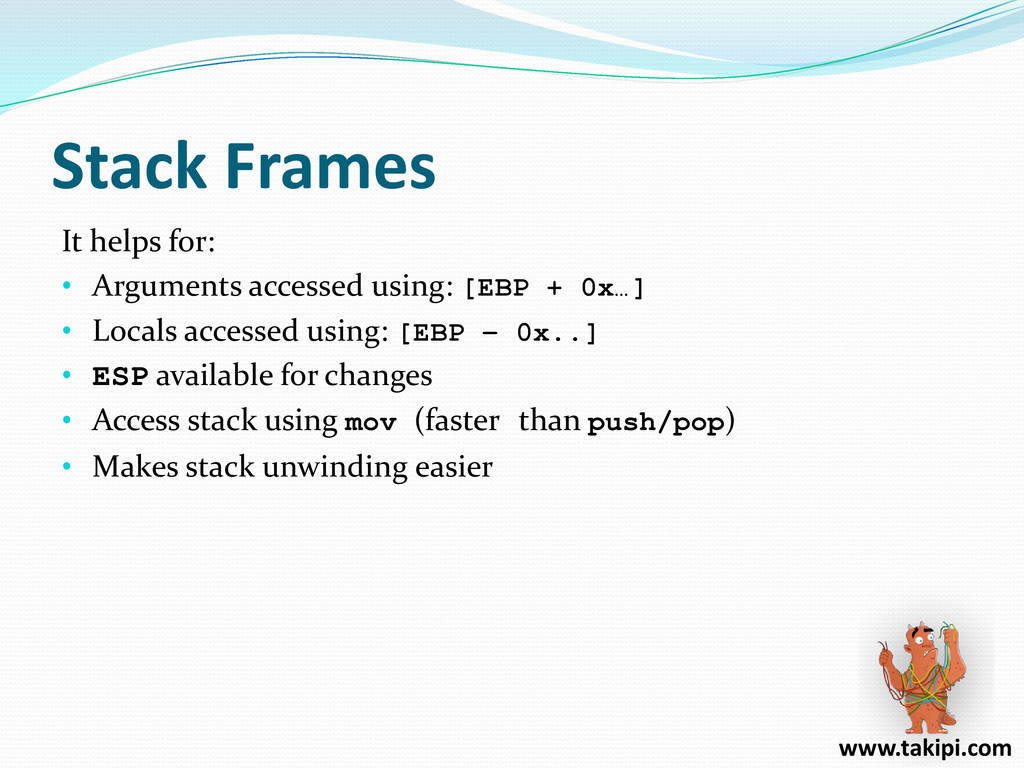
Stack Frames It helps for: • Arguments accessed using: [EBP
+ 0x…] • Locals accessed using: [EBP – 0x..] • ESP available for changes • Access stack using mov (faster than push/pop) • Makes stack unwinding easier www.takipi.com -
OSes – focusing on PCs Each OS has an ABI
(Application Binary Interface) Declares: • Calling Convention • Volatile & Non-volatile registers For 32-bit OSes: • Windows 32-bit • Linux 32-bit Mainly a mess – too many types of ABIs! www.takipi.com -
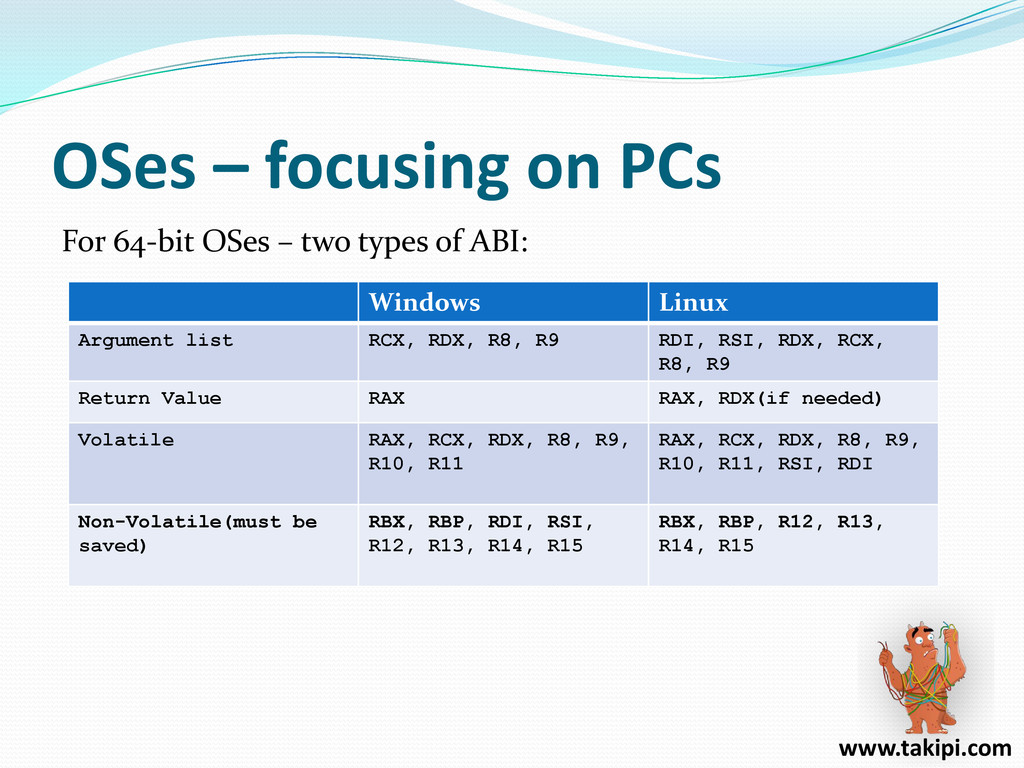
OSes – focusing on PCs For 64-bit OSes – two
types of ABI: Windows Linux Argument list RCX, RDX, R8, R9 RDI, RSI, RDX, RCX, R8, R9 Return Value RAX RAX, RDX(if needed) Volatile RAX, RCX, RDX, R8, R9, R10, R11 RAX, RCX, RDX, R8, R9, R10, R11, RSI, RDI Non-Volatile(must be saved) RBX, RBP, RDI, RSI, R12, R13, R14, R15 RBX, RBP, R12, R13, R14, R15 www.takipi.com -
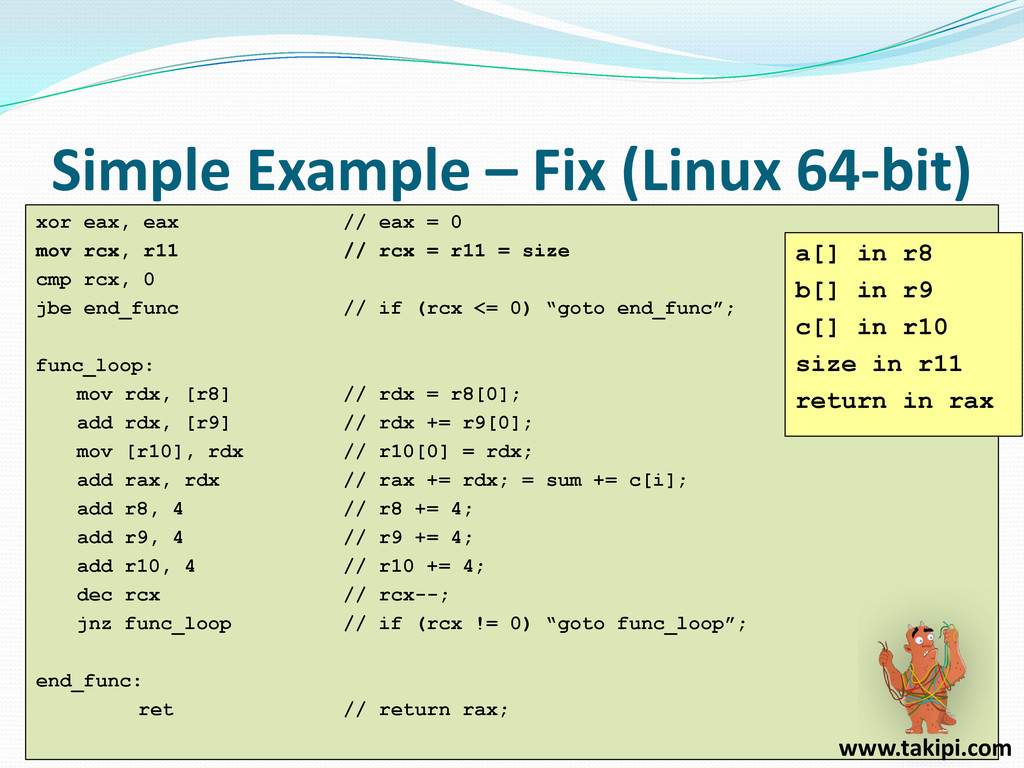
Simple Example – Fix (Linux 64-bit) xor eax, eax //
eax = 0 mov rcx, r11 // rcx = r11 = size cmp rcx, 0 jbe end_func // if (rcx <= 0) “goto end_func”; func_loop: mov rdx, [r8] // rdx = r8[0]; add rdx, [r9] // rdx += r9[0]; mov [r10], rdx // r10[0] = rdx; add rax, rdx // rax += rdx; = sum += c[i]; add r8, 4 // r8 += 4; add r9, 4 // r9 += 4; add r10, 4 // r10 += 4; dec rcx // rcx--; jnz func_loop // if (rcx != 0) “goto func_loop”; end_func: ret // return rax; a[] in r8 b[] in r9 c[] in r10 size in r11 return in rax www.takipi.com -
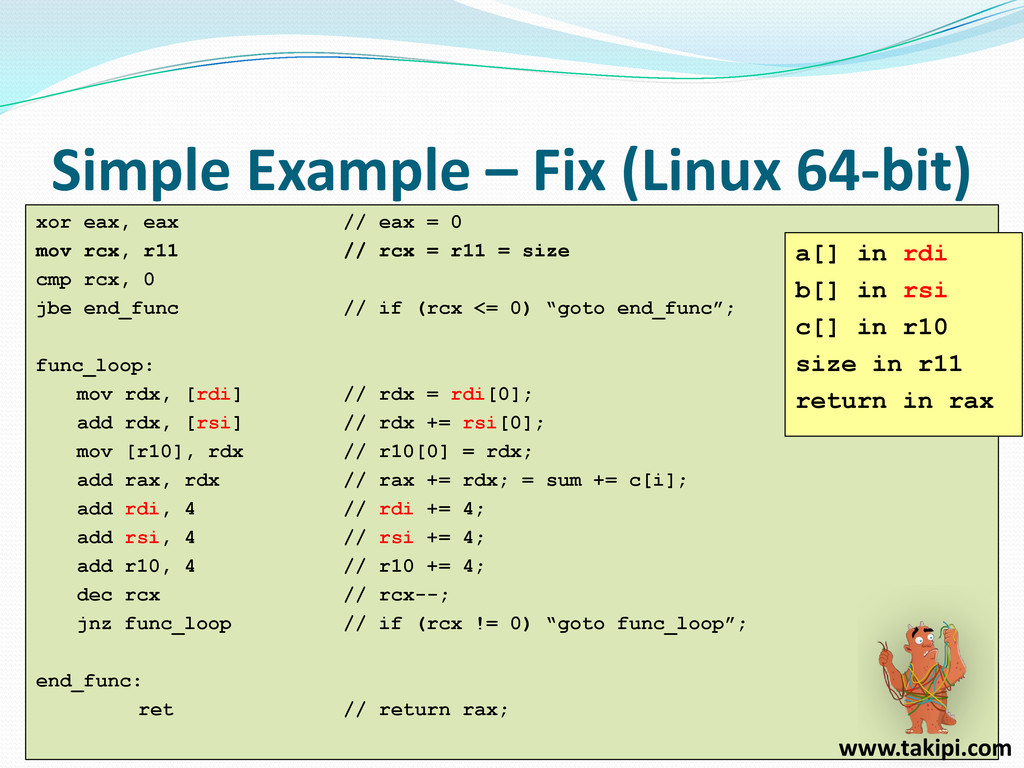
Simple Example – Fix (Linux 64-bit) xor eax, eax //
eax = 0 mov rcx, r11 // rcx = r11 = size cmp rcx, 0 jbe end_func // if (rcx <= 0) “goto end_func”; func_loop: mov rdx, [rdi] // rdx = rdi[0]; add rdx, [rsi] // rdx += rsi[0]; mov [r10], rdx // r10[0] = rdx; add rax, rdx // rax += rdx; = sum += c[i]; add rdi, 4 // rdi += 4; add rsi, 4 // rsi += 4; add r10, 4 // r10 += 4; dec rcx // rcx--; jnz func_loop // if (rcx != 0) “goto func_loop”; end_func: ret // return rax; a[] in rdi b[] in rsi c[] in r10 size in r11 return in rax www.takipi.com -
Simple Example – Fix (Linux 64-bit) xor eax, eax //
eax = 0 mov rcx, r11 // rcx = r11 = size cmp rcx, 0 jbe end_func // if (rcx <= 0) “goto end_func”; func_loop: mov rdx, [rdi] // rdx = rdi[0]; add rdx, [rsi] // rdx += rsi[0]; mov [r10], rdx // r10[0] = rdx; add rax, rdx // rax += rdx; = sum += c[i]; add rdi, 4 // rdi += 4; add rsi, 4 // rsi += 4; add r10, 4 // r10 += 4; dec rcx // rcx--; jnz func_loop // if (rcx != 0) “goto func_loop”; end_func: ret // return rax; a[] in rdi b[] in rsi c[] in r10 size in rcx return in rax www.takipi.com -
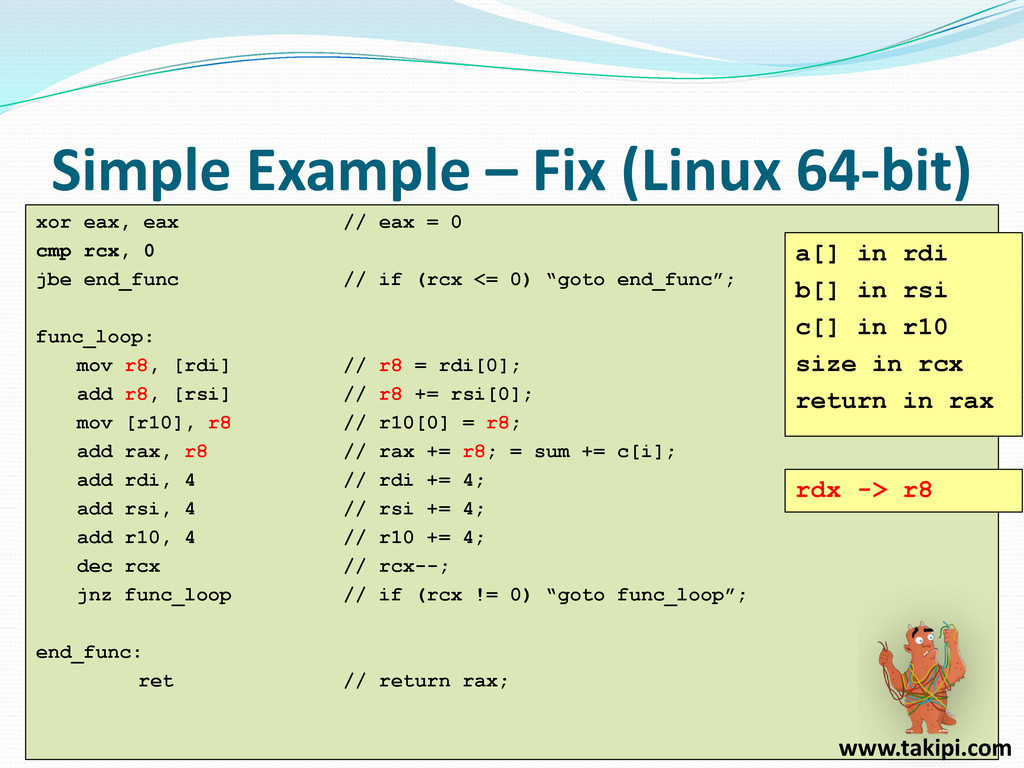
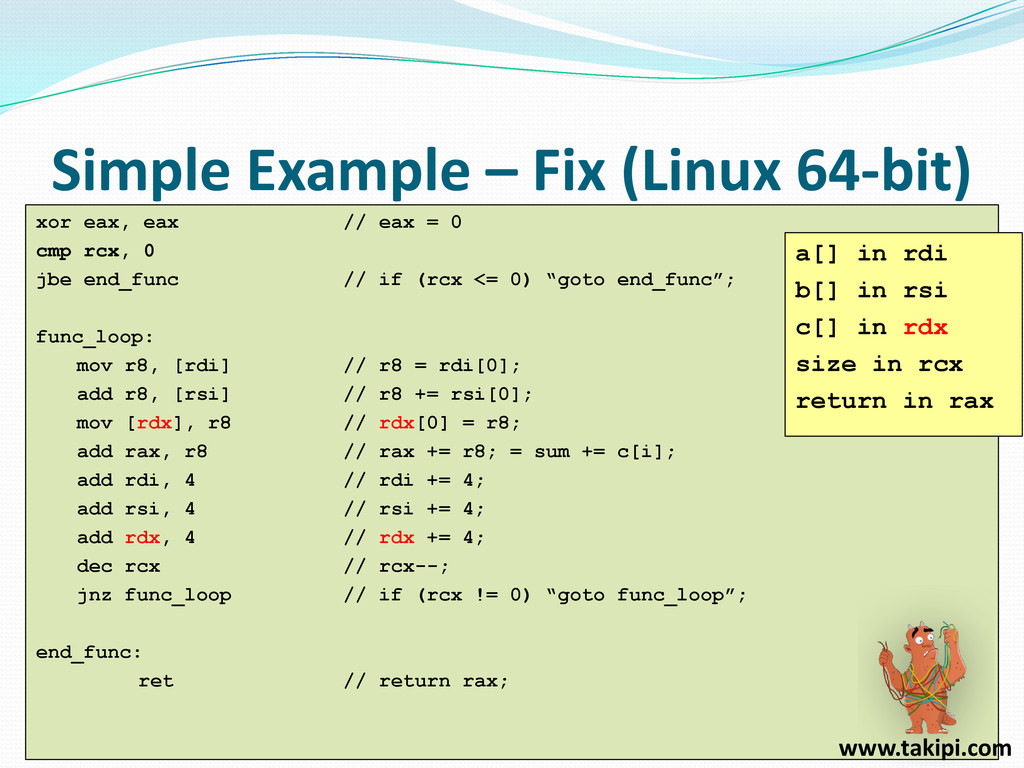
Simple Example – Fix (Linux 64-bit) xor eax, eax //
eax = 0 cmp rcx, 0 jbe end_func // if (rcx <= 0) “goto end_func”; func_loop: mov r8, [rdi] // r8 = rdi[0]; add r8, [rsi] // r8 += rsi[0]; mov [r10], r8 // r10[0] = r8; add rax, r8 // rax += r8; = sum += c[i]; add rdi, 4 // rdi += 4; add rsi, 4 // rsi += 4; add r10, 4 // r10 += 4; dec rcx // rcx--; jnz func_loop // if (rcx != 0) “goto func_loop”; end_func: ret // return rax; rdx -> r8 a[] in rdi b[] in rsi c[] in r10 size in rcx return in rax www.takipi.com -
Simple Example – Fix (Linux 64-bit) xor eax, eax //
eax = 0 cmp rcx, 0 jbe end_func // if (rcx <= 0) “goto end_func”; func_loop: mov r8, [rdi] // r8 = rdi[0]; add r8, [rsi] // r8 += rsi[0]; mov [rdx], r8 // rdx[0] = r8; add rax, r8 // rax += r8; = sum += c[i]; add rdi, 4 // rdi += 4; add rsi, 4 // rsi += 4; add rdx, 4 // rdx += 4; dec rcx // rcx--; jnz func_loop // if (rcx != 0) “goto func_loop”; end_func: ret // return rax; a[] in rdi b[] in rsi c[] in rdx size in rcx return in rax www.takipi.com -
To Sum up till now… Assembly offers: • Access to
any memory location or hardware • Better performance • Smaller executable Learning assembly is easy, but mastering it is very very very hard! www.takipi.com -
Back to our sample (Win x64) public static int sumArrays(int
a[], int b[], int c[], int size) { int sum = 0; for (int i = 0; i < size; i++) { c[i] = a[i] + b[i]; sum += c[i]; } return sum; } www.takipi.com -
And after JIT…(~100 Insn.) mov [rsp-0x00006000], eax push rbp sub
rsp, 0x30 xor r11d, r11d mov r10d, edi test edi, edi jng 0x023CFFCB mov ecx, [rdx+0x0C] test ecx, ecx jbe 0x023CFFCF mov ebx, edi dec ebx cmp ebx, ecx jnc 0x023CFFCF mov edi, [r8+0x0C] test edi, edi jbe 0x023CFFCF cmp ebx, edi jnc 0x023CFFCF mov ecx, [r9+0x0C] test ecx, ecx jbe 0x023CFFCF cmp ebx, ecx jnc 0x023CFFCF xor eax, eax mov ebx, [r8+r11*4+0x10] add ebx, [rdx+r11*4+0x10] mov [r9+r11*4+0x10], ebx add eax, ebx inc r11d cmp r11d, 0x01 jl 0x023CFF1B mov edi, r10d add edi, 0xFFFFFFFD mov ebx, 0x80000000 cmp r10d, edi cmovl edi, ebx cmp r11d, edi jl 0x023CFF53 mov ebx, r11d jmp 0x023CFFA3 mov r11d, ebx mov ecx, [rdx+r11*4+0x10] add ecx, [r8+r11*4+0x10] mov [r9+r11*4+0x10], ecx add eax, ecx mov ebx, r11d add ebx, 0x04 movsxd rbp, r11 mov r11d, [rdx+rbp*4+0x14] add r11d, [r8+rbp*4+0x14] mov [r9+rbp*4+0x14], r11d mov esi, [r8+rbp*4+0x18] add esi, [rdx+rbp*4+0x18] mov [r9+rbp*4+0x18], esi mov ecx, [r8+rbp*4+0x1C] add ecx, [rdx+rbp*4+0x1C] mov [r9+rbp*4+0x1C], ecx add eax, r11d add eax, esi add eax, ecx cmp ebx, edi jl 0x023CFF50 cmp ebx, r10d jnl 0x023CFFBF mov ecx, [r8+rbx*4+0x10] add ecx, [rdx+rbx*4+0x10] mov [r9+rbx*4+0x10], ecx add eax, ecx inc ebx cmp ebx, r10d jl 0x023CFFA8 add rsp, 0x30 pop rbp test [0x00000000004C0000], eax ret xor eax, eax jmp 0x023CFFBF mov rbp, rdx mov qword [rsp], r8 mov qword [rsp+0x08], r9 mov [rsp+0x10], r10d mov edx, 0xFFFFFF86 nop call 0x023A90A0 int3 hlt hlt hlt hlt hlt hlt hlt hlt hlt hlt hlt int sum = 0; for (int i = 0; i < size; i++) { c[i] = a[i] + b[i]; sum += c[i]; } return sum; www.takipi.com -
And after JIT…(~100 Insn.) mov [rsp-0x00006000], eax push rbp sub
rsp, 0x30 xor r11d, r11d mov r10d, edi test edi, edi jng 0x023CFFCB mov ecx, [rdx+0x0C] test ecx, ecx jbe 0x023CFFCF mov ebx, edi dec ebx cmp ebx, ecx jnc 0x023CFFCF mov edi, [r8+0x0C] test edi, edi jbe 0x023CFFCF cmp ebx, edi jnc 0x023CFFCF mov ecx, [r9+0x0C] test ecx, ecx jbe 0x023CFFCF cmp ebx, ecx jnc 0x023CFFCF xor eax, eax mov ebx, [r8+r11*4+0x10] add ebx, [rdx+r11*4+0x10] mov [r9+r11*4+0x10], ebx add eax, ebx inc r11d cmp r11d, 0x01 jl 0x023CFF1B mov edi, r10d add edi, 0xFFFFFFFD mov ebx, 0x80000000 cmp r10d, edi cmovl edi, ebx cmp r11d, edi jl 0x023CFF53 mov ebx, r11d jmp 0x023CFFA3 mov r11d, ebx mov ecx, [rdx+r11*4+0x10] add ecx, [r8+r11*4+0x10] mov [r9+r11*4+0x10], ecx add eax, ecx mov ebx, r11d add ebx, 0x04 movsxd rbp, r11 mov r11d, [rdx+rbp*4+0x14] add r11d, [r8+rbp*4+0x14] mov [r9+rbp*4+0x14], r11d mov esi, [r8+rbp*4+0x18] add esi, [rdx+rbp*4+0x18] mov [r9+rbp*4+0x18], esi mov ecx, [r8+rbp*4+0x1C] add ecx, [rdx+rbp*4+0x1C] mov [r9+rbp*4+0x1C], ecx add eax, r11d add eax, esi add eax, ecx cmp ebx, edi jl 0x023CFF50 cmp ebx, r10d jnl 0x023CFFBF mov ecx, [r8+rbx*4+0x10] add ecx, [rdx+rbx*4+0x10] mov [r9+rbx*4+0x10], ecx add eax, ecx inc ebx cmp ebx, r10d jl 0x023CFFA8 add rsp, 0x30 pop rbp test [0x00000000004C0000], eax ret xor eax, eax jmp 0x023CFFBF mov rbp, rdx mov qword [rsp], r8 mov qword [rsp+0x08], r9 mov [rsp+0x10], r10d mov edx, 0xFFFFFF86 nop call 0x023A90A0 int3 hlt hlt hlt hlt hlt hlt hlt hlt hlt hlt hlt int sum = 0; for (int i = 0; i < size; i++) { c[i] = a[i] + b[i]; sum += c[i]; } return sum; www.takipi.com -
And after JIT…(~100 Insn.) mov [rsp-0x00006000], eax push rbp sub
rsp, 0x30 xor r11d, r11d mov r10d, edi test edi, edi jng 0x023CFFCB mov ecx, [rdx+0x0C] test ecx, ecx jbe 0x023CFFCF mov ebx, edi dec ebx cmp ebx, ecx jnc 0x023CFFCF mov edi, [r8+0x0C] test edi, edi jbe 0x023CFFCF cmp ebx, edi jnc 0x023CFFCF mov ecx, [r9+0x0C] test ecx, ecx jbe 0x023CFFCF cmp ebx, ecx jnc 0x023CFFCF xor eax, eax mov ebx, [r8+r11*4+0x10] add ebx, [rdx+r11*4+0x10] mov [r9+r11*4+0x10], ebx add eax, ebx inc r11d cmp r11d, 0x01 jl 0x023CFF1B mov edi, r10d add edi, 0xFFFFFFFD mov ebx, 0x80000000 cmp r10d, edi cmovl edi, ebx cmp r11d, edi jl 0x023CFF53 mov ebx, r11d jmp 0x023CFFA3 mov r11d, ebx mov ecx, [rdx+r11*4+0x10] add ecx, [r8+r11*4+0x10] mov [r9+r11*4+0x10], ecx add eax, ecx mov ebx, r11d add ebx, 0x04 movsxd rbp, r11 mov r11d, [rdx+rbp*4+0x14] add r11d, [r8+rbp*4+0x14] mov [r9+rbp*4+0x14], r11d mov esi, [r8+rbp*4+0x18] add esi, [rdx+rbp*4+0x18] mov [r9+rbp*4+0x18], esi mov ecx, [r8+rbp*4+0x1C] add ecx, [rdx+rbp*4+0x1C] mov [r9+rbp*4+0x1C], ecx add eax, r11d add eax, esi add eax, ecx cmp ebx, edi jl 0x023CFF50 cmp ebx, r10d jnl 0x023CFFBF mov ecx, [r8+rbx*4+0x10] add ecx, [rdx+rbx*4+0x10] mov [r9+rbx*4+0x10], ecx add eax, ecx inc ebx cmp ebx, r10d jl 0x023CFFA8 add rsp, 0x30 pop rbp test [0x00000000004C0000], eax ret xor eax, eax jmp 0x023CFFBF mov rbp, rdx mov qword [rsp], r8 mov qword [rsp+0x08], r9 mov [rsp+0x10], r10d mov edx, 0xFFFFFF86 nop call 0x023A90A0 int3 hlt hlt hlt hlt hlt hlt hlt hlt hlt hlt hlt int sum = 0; for (int i = 0; i < size; i++) { c[i] = a[i] + b[i]; sum += c[i]; } return sum; www.takipi.com -
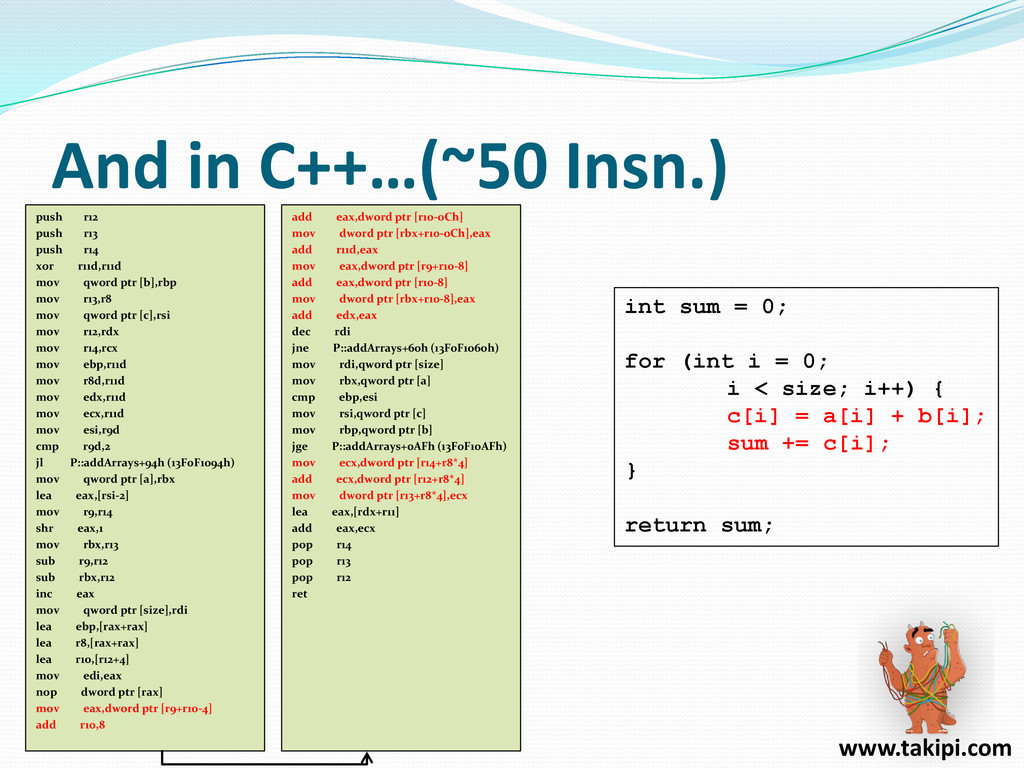
And in C++…(~50 Insn.) push r12 push r13 push r14
xor r11d,r11d mov qword ptr [b],rbp mov r13,r8 mov qword ptr [c],rsi mov r12,rdx mov r14,rcx mov ebp,r11d mov r8d,r11d mov edx,r11d mov ecx,r11d mov esi,r9d cmp r9d,2 jl P::addArrays+94h (13F0F1094h) mov qword ptr [a],rbx lea eax,[rsi-2] mov r9,r14 shr eax,1 mov rbx,r13 sub r9,r12 sub rbx,r12 inc eax mov qword ptr [size],rdi lea ebp,[rax+rax] lea r8,[rax+rax] lea r10,[r12+4] mov edi,eax nop dword ptr [rax] mov eax,dword ptr [r9+r10-4] add r10,8 add eax,dword ptr [r10-0Ch] mov dword ptr [rbx+r10-0Ch],eax add r11d,eax mov eax,dword ptr [r9+r10-8] add eax,dword ptr [r10-8] mov dword ptr [rbx+r10-8],eax add edx,eax dec rdi jne P::addArrays+60h (13F0F1060h) mov rdi,qword ptr [size] mov rbx,qword ptr [a] cmp ebp,esi mov rsi,qword ptr [c] mov rbp,qword ptr [b] jge P::addArrays+0AFh (13F0F10AFh) mov ecx,dword ptr [r14+r8*4] add ecx,dword ptr [r12+r8*4] mov dword ptr [r13+r8*4],ecx lea eax,[rdx+r11] add eax,ecx pop r14 pop r13 pop r12 ret int sum = 0; for (int i = 0; i < size; i++) { c[i] = a[i] + b[i]; sum += c[i]; } return sum; www.takipi.com -
The JIT Compiler It’s a compiler! • Generates assembly code
from bytecode • Optimizes code like other compilers, but… It has additional information www.takipi.com -
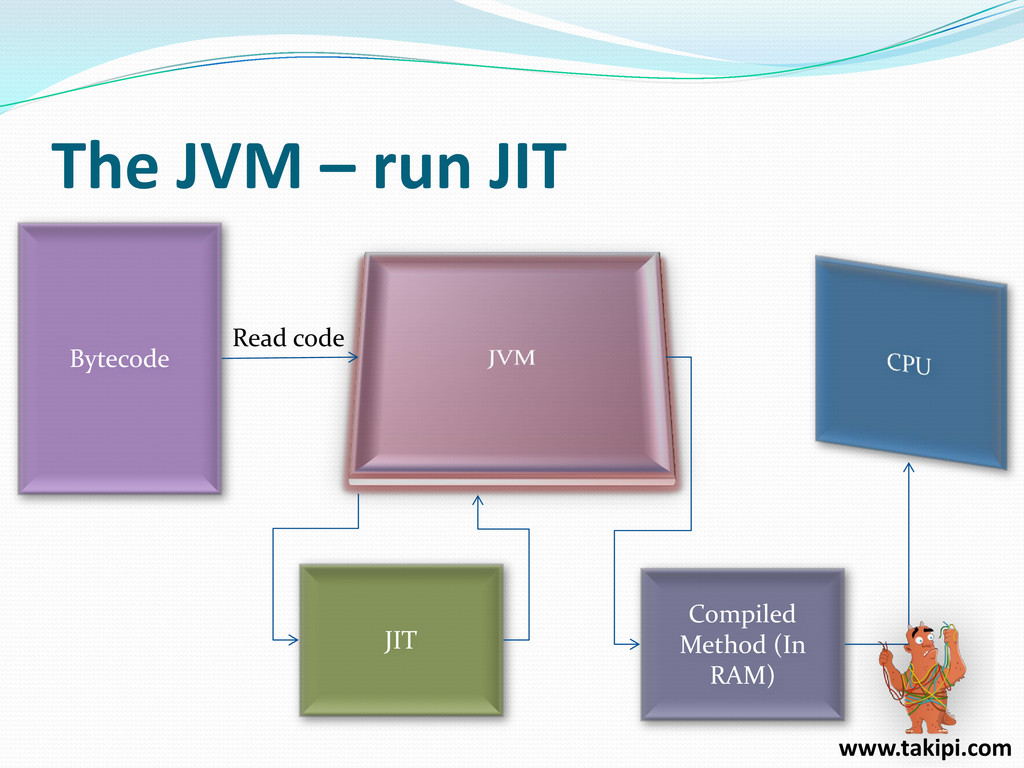
The JVM – run JIT Bytecode Read code JIT Compiled
Method (In RAM) www.takipi.com -
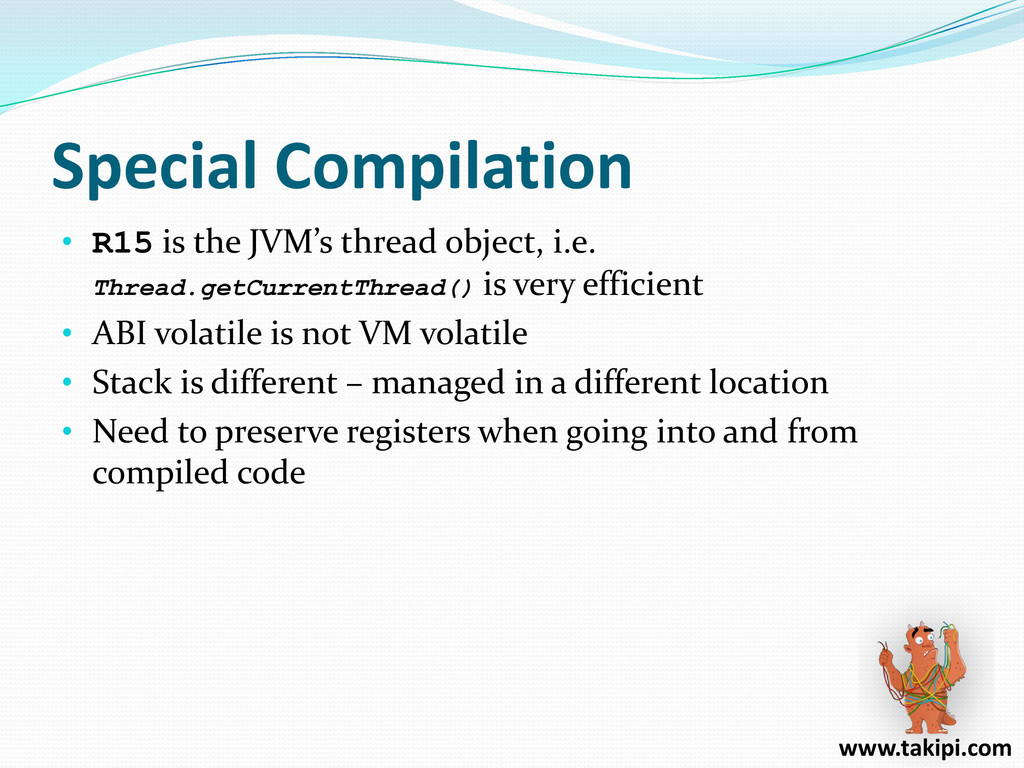
Special Compilation • R15 is the JVM’s thread object, i.e.
Thread.getCurrentThread() is very efficient • ABI volatile is not VM volatile • Stack is different – managed in a different location • Need to preserve registers when going into and from compiled code www.takipi.com -
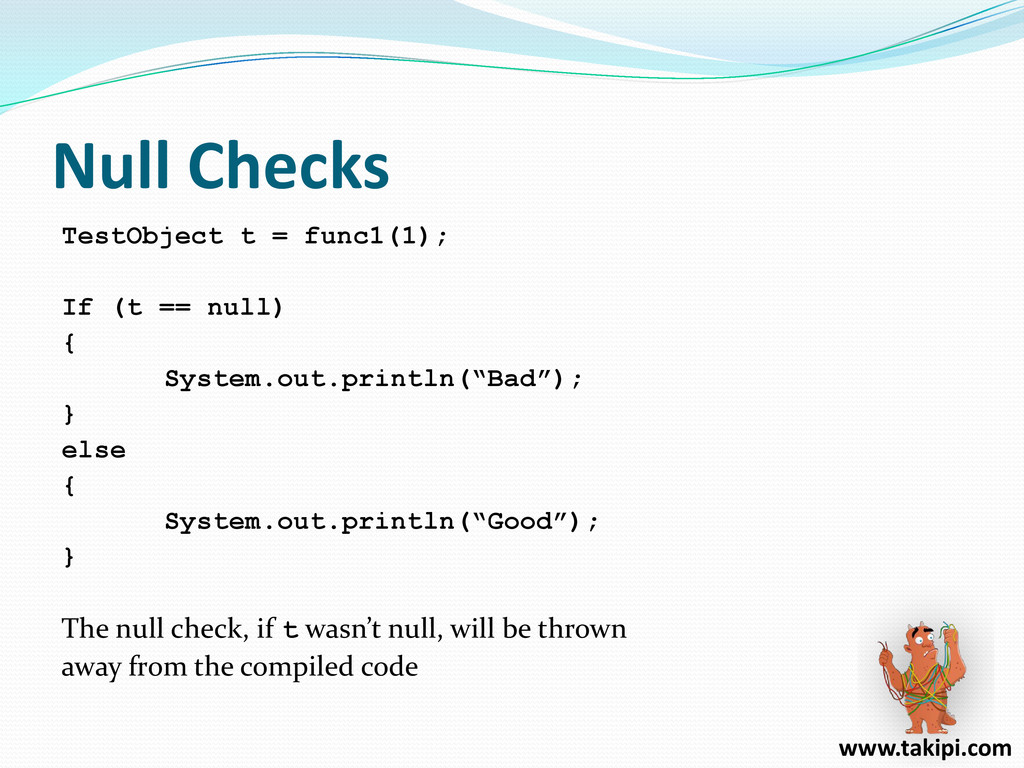
Null Checks TestObject t = func1(1); If (t == null)
{ System.out.println(“Bad”); } else { System.out.println(“Good”); } The null check, if t wasn’t null, will be thrown away from the compiled code www.takipi.com -
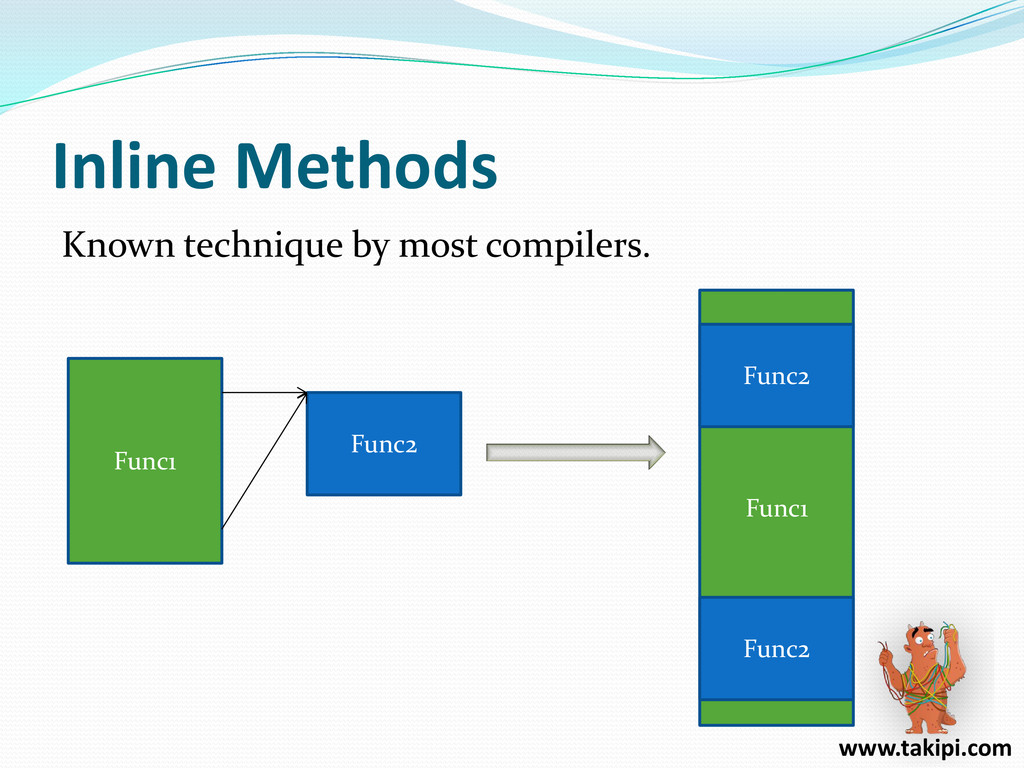
Inline Methods Known technique by most compilers. Func1 Func2 Func1
Func2 Func2 www.takipi.com -
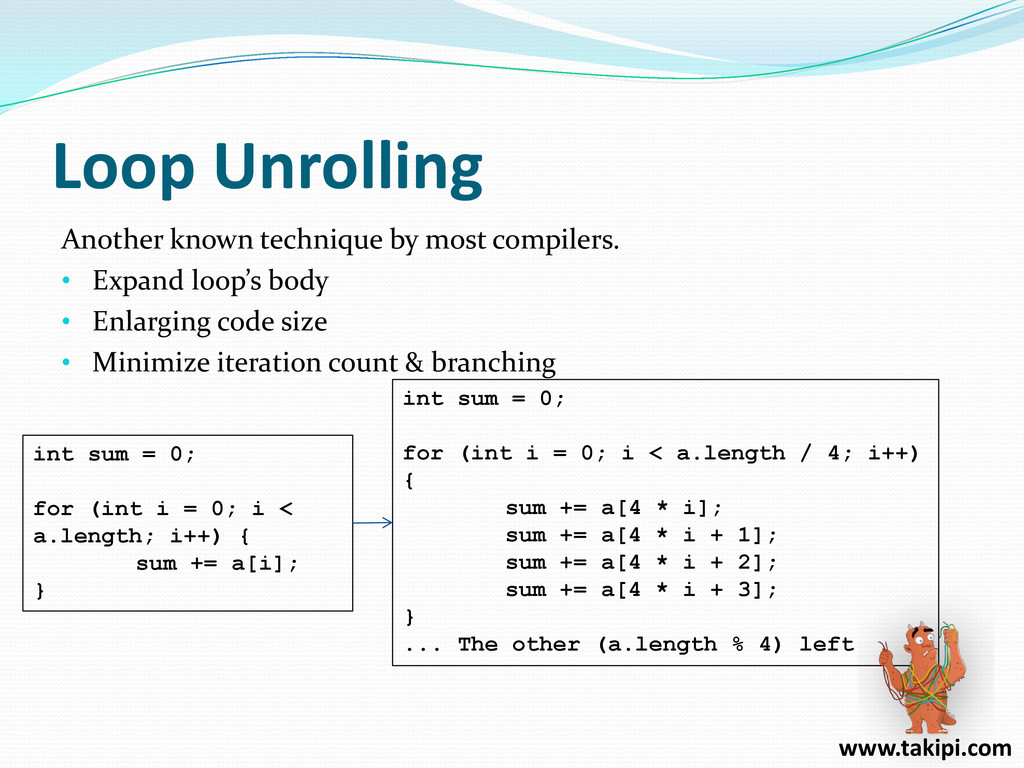
Loop Unrolling Another known technique by most compilers. • Expand
loop’s body • Enlarging code size • Minimize iteration count & branching int sum = 0; for (int i = 0; i < a.length; i++) { sum += a[i]; } int sum = 0; for (int i = 0; i < a.length / 4; i++) { sum += a[4 * i]; sum += a[4 * i + 1]; sum += a[4 * i + 2]; sum += a[4 * i + 3]; } ... The other (a.length % 4) left www.takipi.com -
Escapement Analysis Find the scope of variables Allows: • Use
of the assembly stack • Allocate outside of the function www.takipi.com -
Some more reading… http://en.wikipedia.org/wiki/X86_assembly_language http://en.wikipedia.org/wiki/X86_instruction_listings http://en.wikipedia.org/wiki/X86-64
http://www.intel.com/content/www/us/en/processors/architectures- software-developer-manuals.html http://faydoc.tripod.com/cpu http://www.peter-cockerell.net/aalp/html/frames.html www.takipi.com
 takipiadmin
 uwabami
 richargh
 l2hyunwoo
 ooga04
 3saito
 seike460
 kasacchiful
 hakkadaikon
 drumath2237
 hasutosasaki
 akihisaikeda
 nasum
 akademiya2063
 moore
 bkeepers
 reverentgeek
 sachag
 aleyda
 jmmastey
 techseoconnect
 chriscoyier
 eileencodes
 kristinabergwall1