Share
Tracking, not Tracing, Linux Thread Activity for Complete System Visibility
Video of the 10 minute talk:
https://www.youtube.com/watch?v=ImOOLwGyj-w
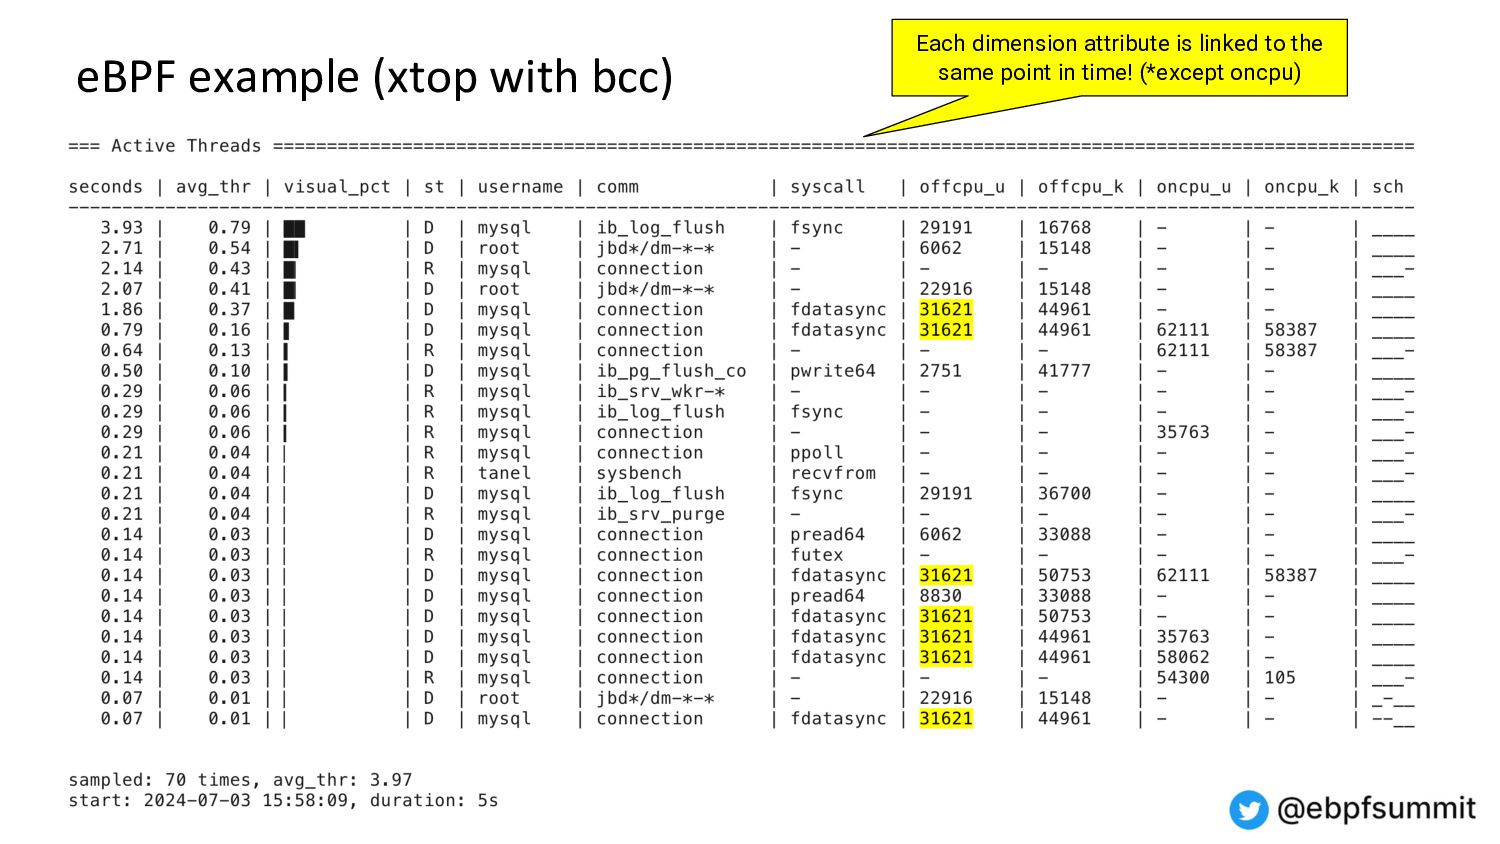
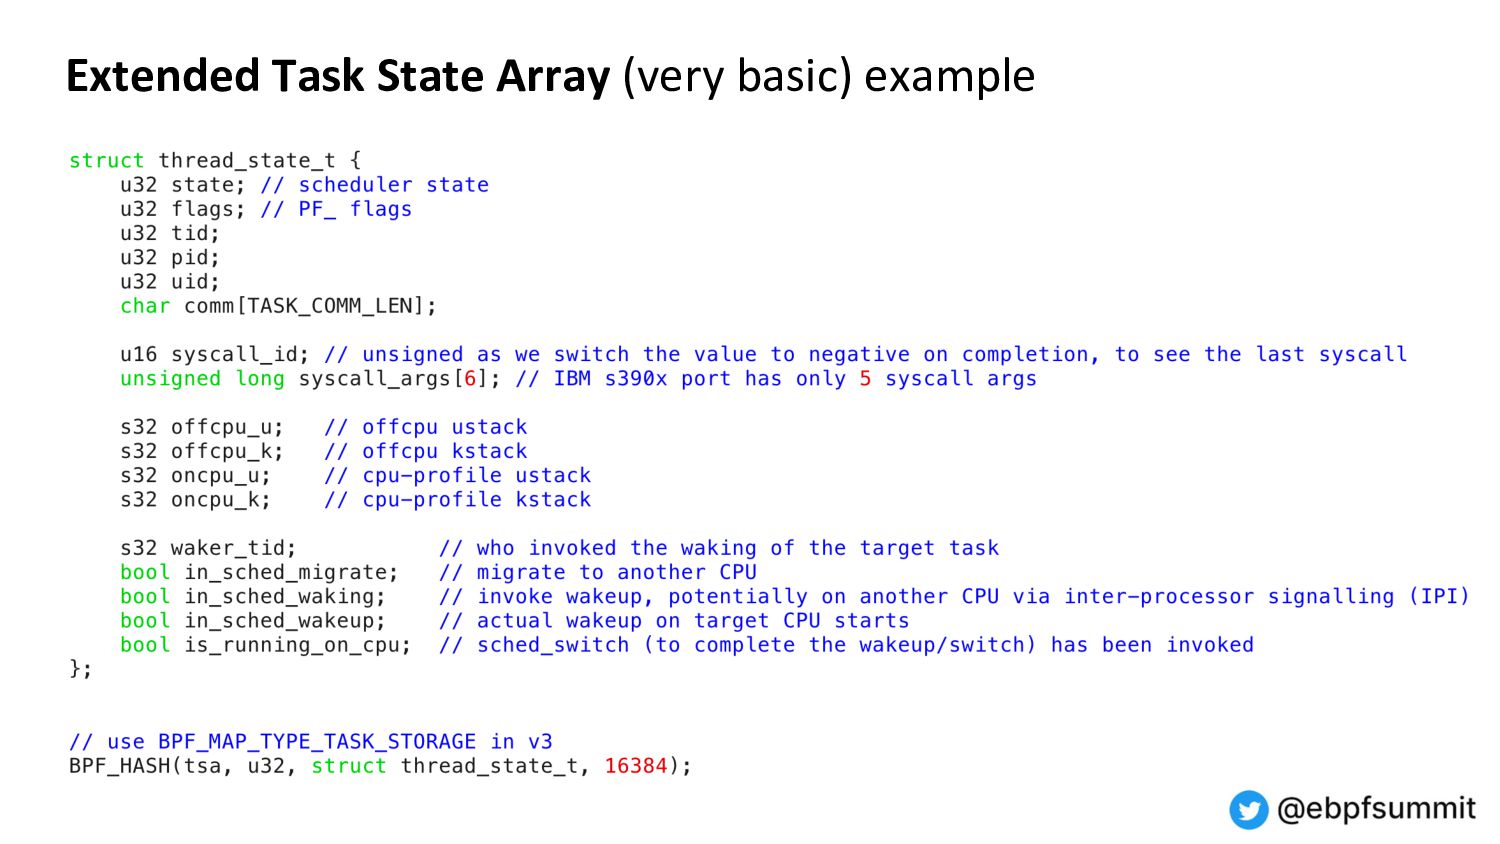
Demo and architecture of the 0x.tools xtop & xcapture-bpf programs using always-on eBPF probes to maintain an “extended task state array”, with periodic state sampling for reporting and display.
This is not traditional tracing, profiling, or global metrics accumulation, but a new approach combining “thread states of interest” sampled over time with application-specific context. It provides visibility into all threads, what they are doing on the CPU, and the reasons for going off the CPU.
This method gives you a reasonable view into the whole system activity, with the ability to drill down into individual thread levels - without having to trace and log every single event.
Tanel Poder
Transcript
19 slides
-
Speaker Guide Tanel Põder Tracking, not tracing, Linux thread activity
for complete system visibility Extended Thread State Sampling with eBPF in action! -
For systematic performance & troubleshooting work, I want to: •
See the full system activity (“active threads”) • Not only system-wide utilization averages • Not only on-CPU thread stacks, but all thread states (and offcpu stacks) • With ability to drill down into each thread’s activity • See what each thread of interest is doing, for whom and why (context) • I/O & function call latencies tied to each thread & its context at the time • All this without tracing & postprocessing every event for every thread! Detailed full system activity without tracing every event? -
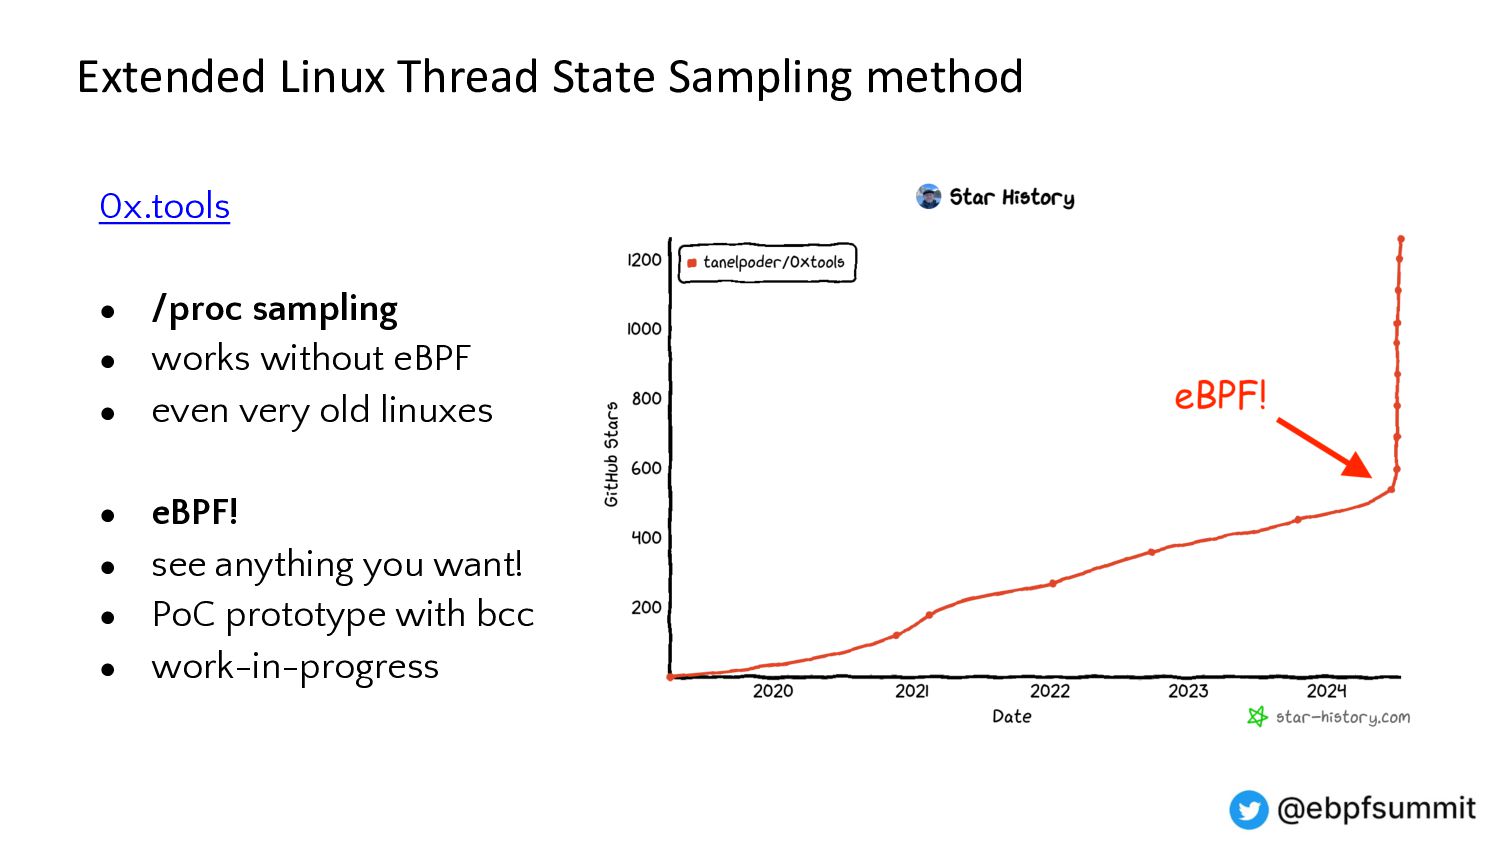
0x.tools • /proc sampling • works without eBPF • even
very old linuxes • eBPF! • see anything you want! • PoC prototype with bcc • work-in-progress Extended Linux Thread State Sampling method -
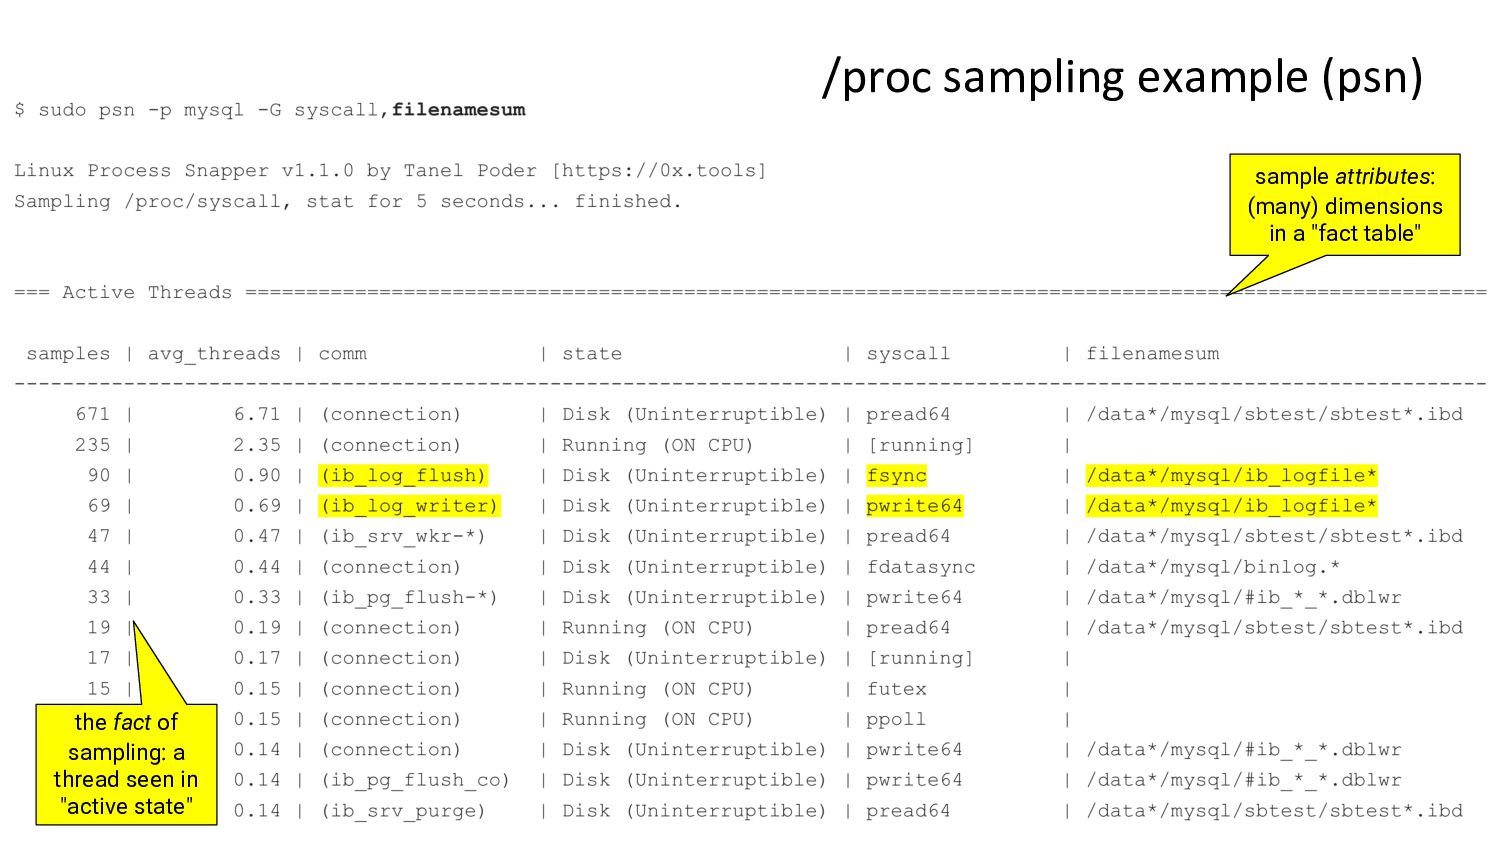
/proc sampling example (psn) the fact of sampling: a thread
seen in "active state" sample attributes: (many) dimensions in a "fact table" -
eBPF example (xtop with bcc) Each dimension attribute is linked
to the same point in time! (*except oncpu) -
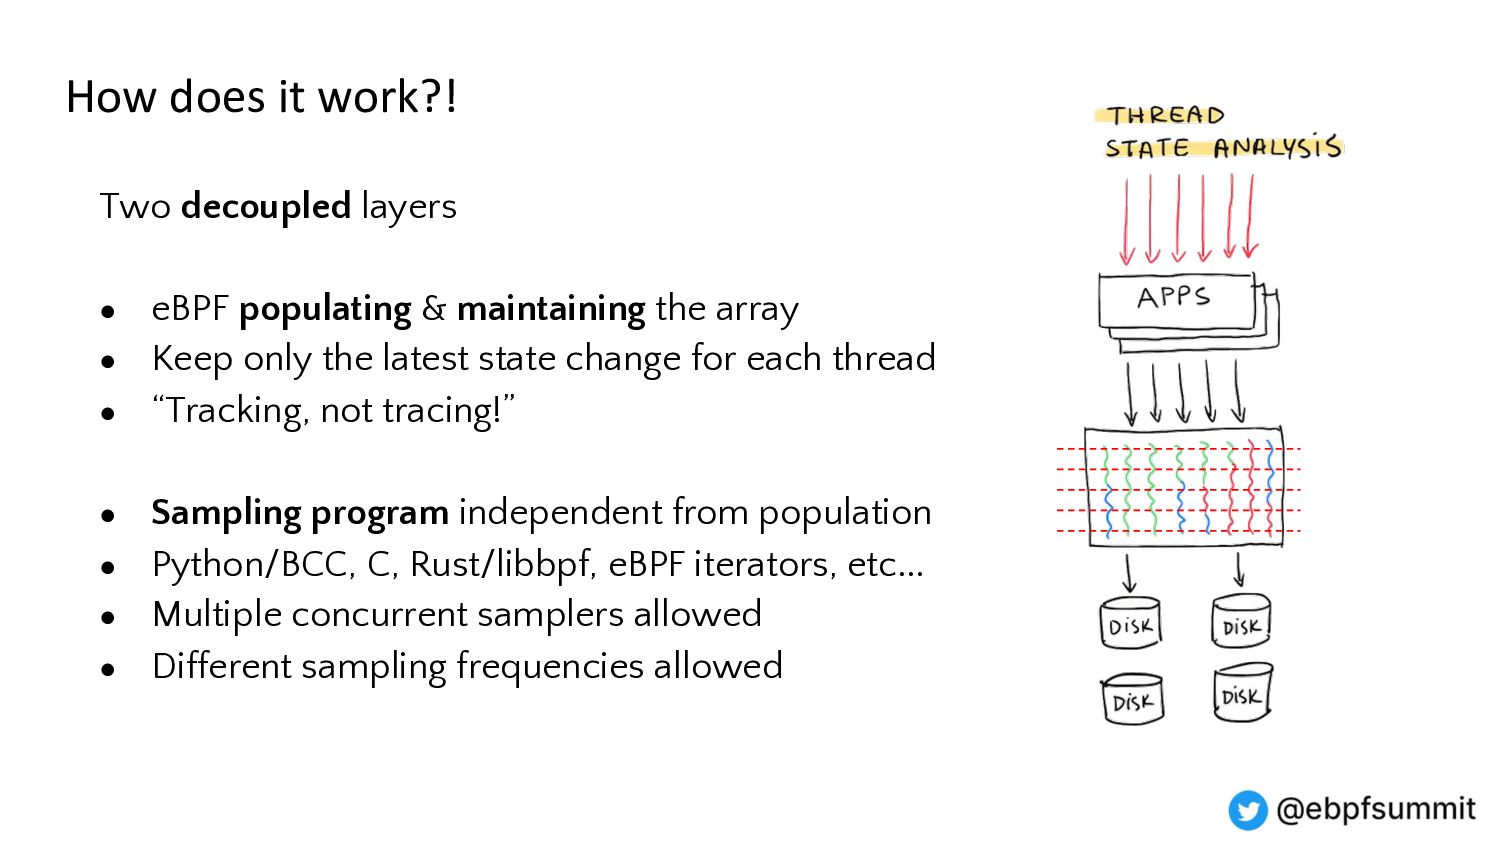
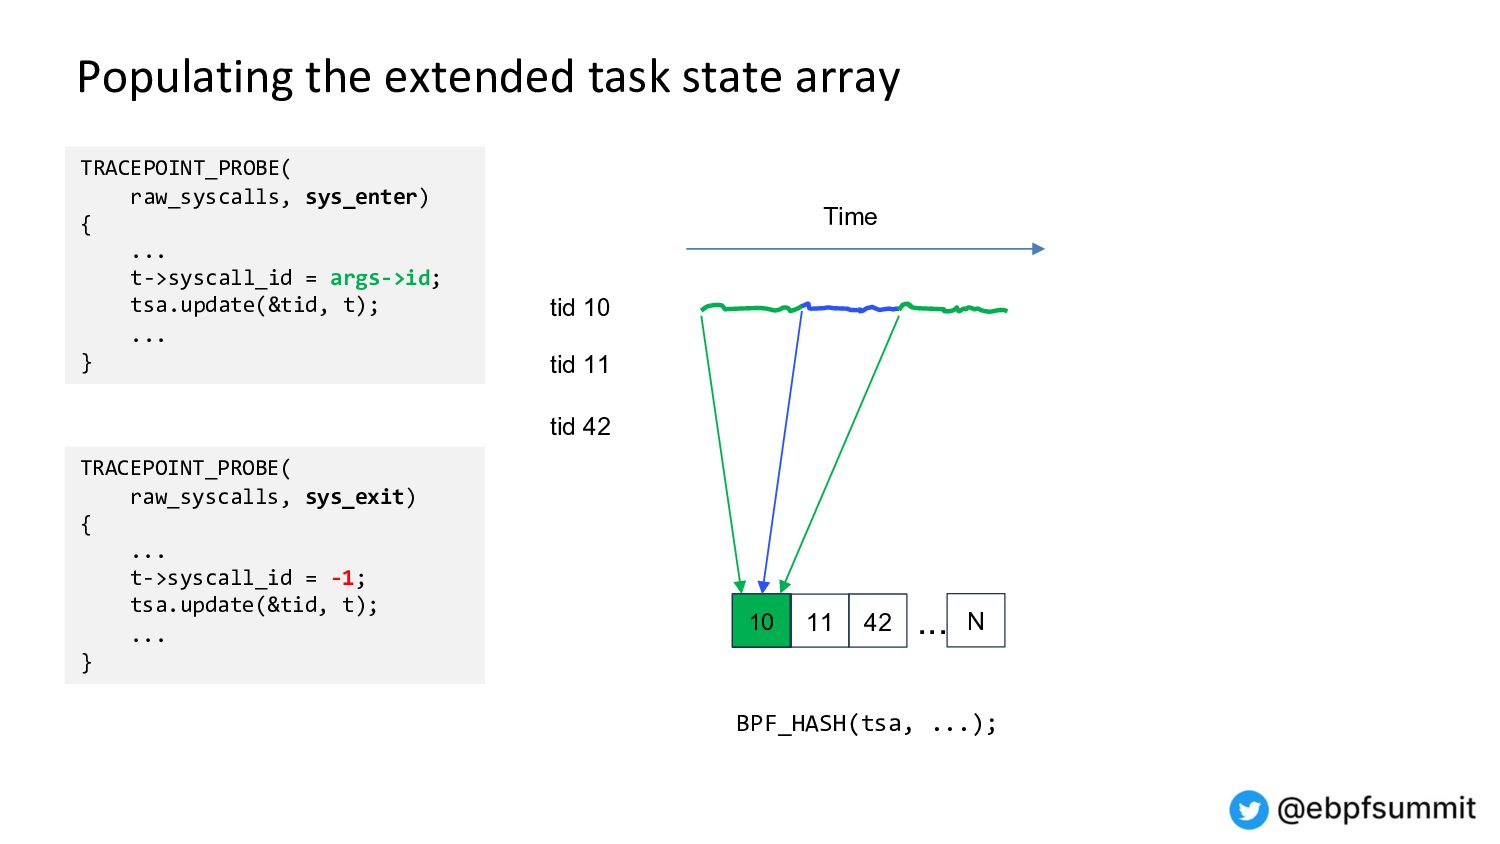
How does it work?! Two decoupled layers • eBPF populating
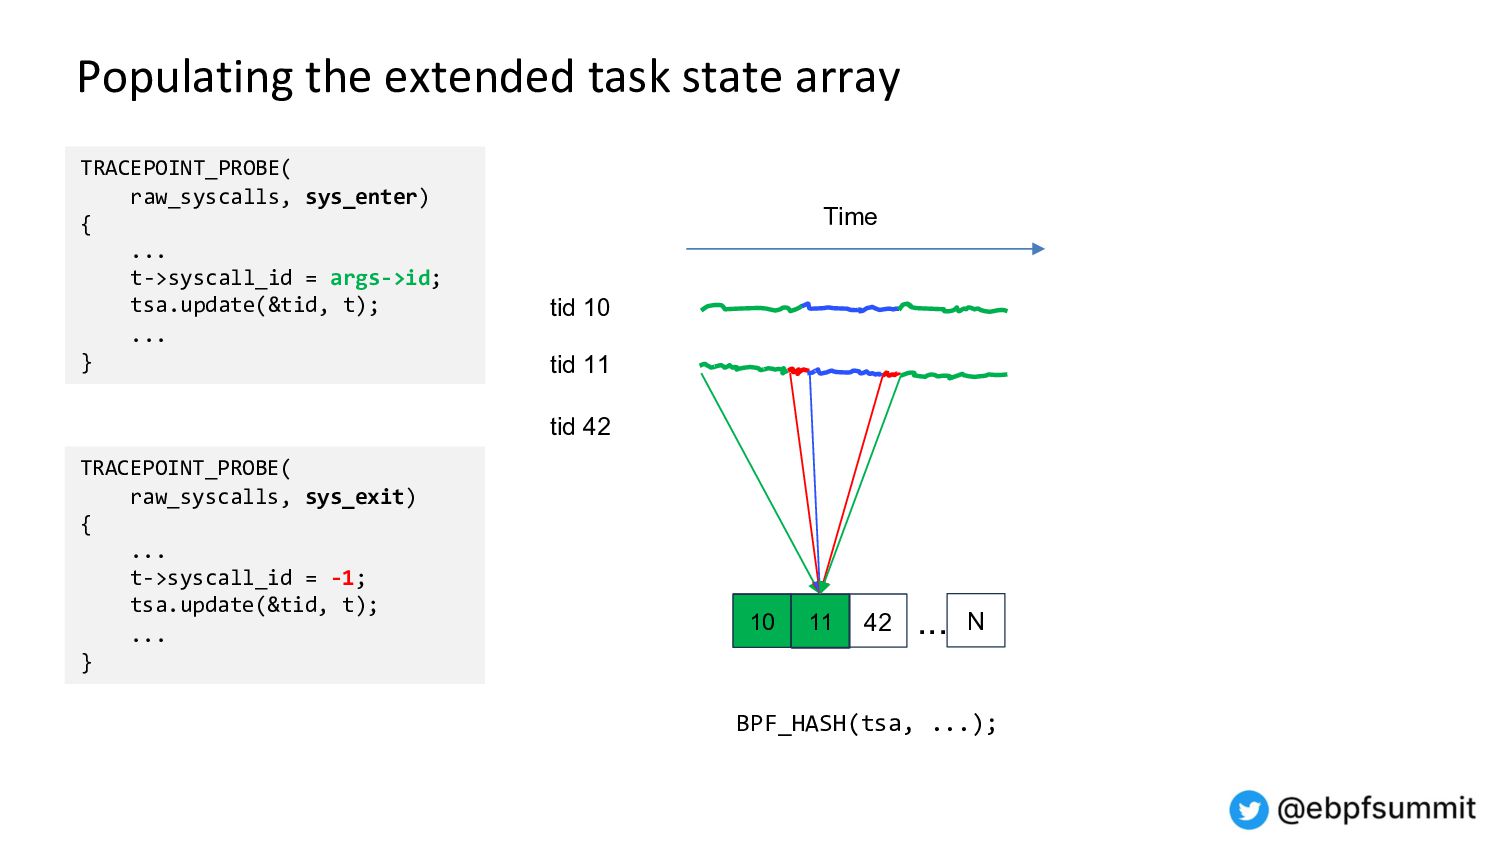
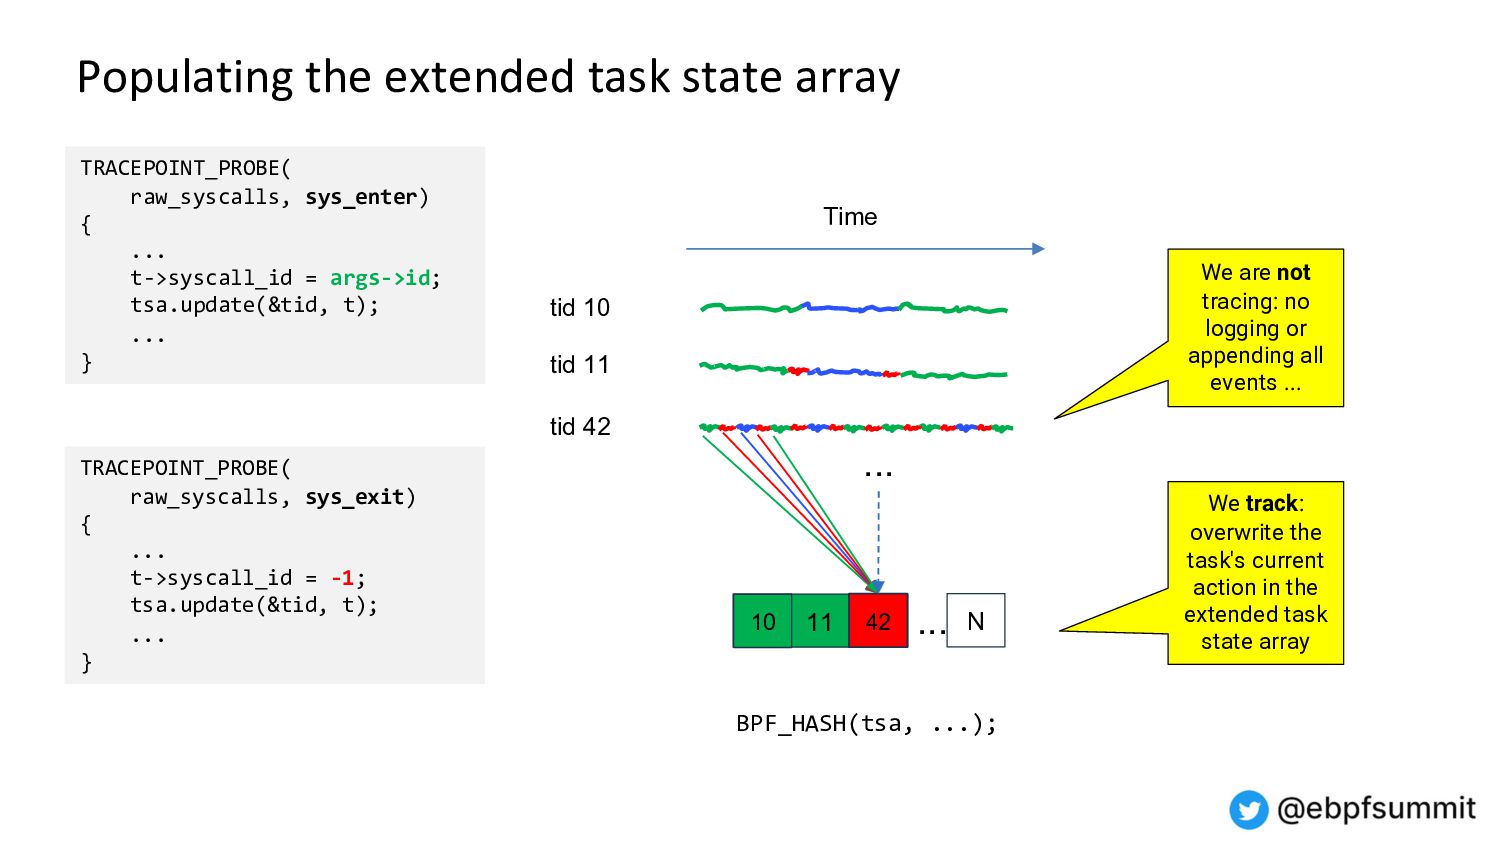
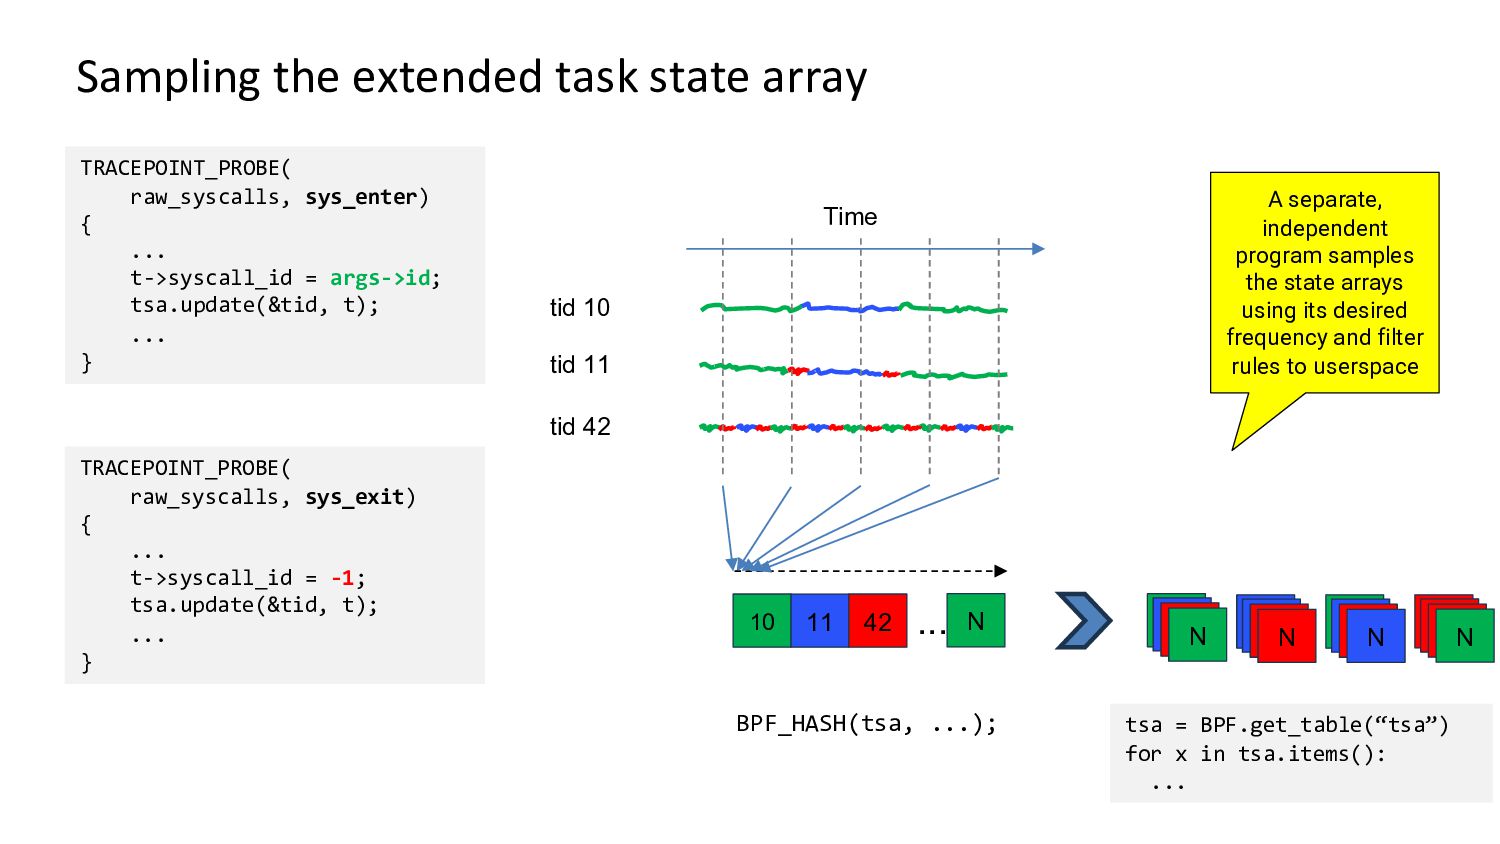
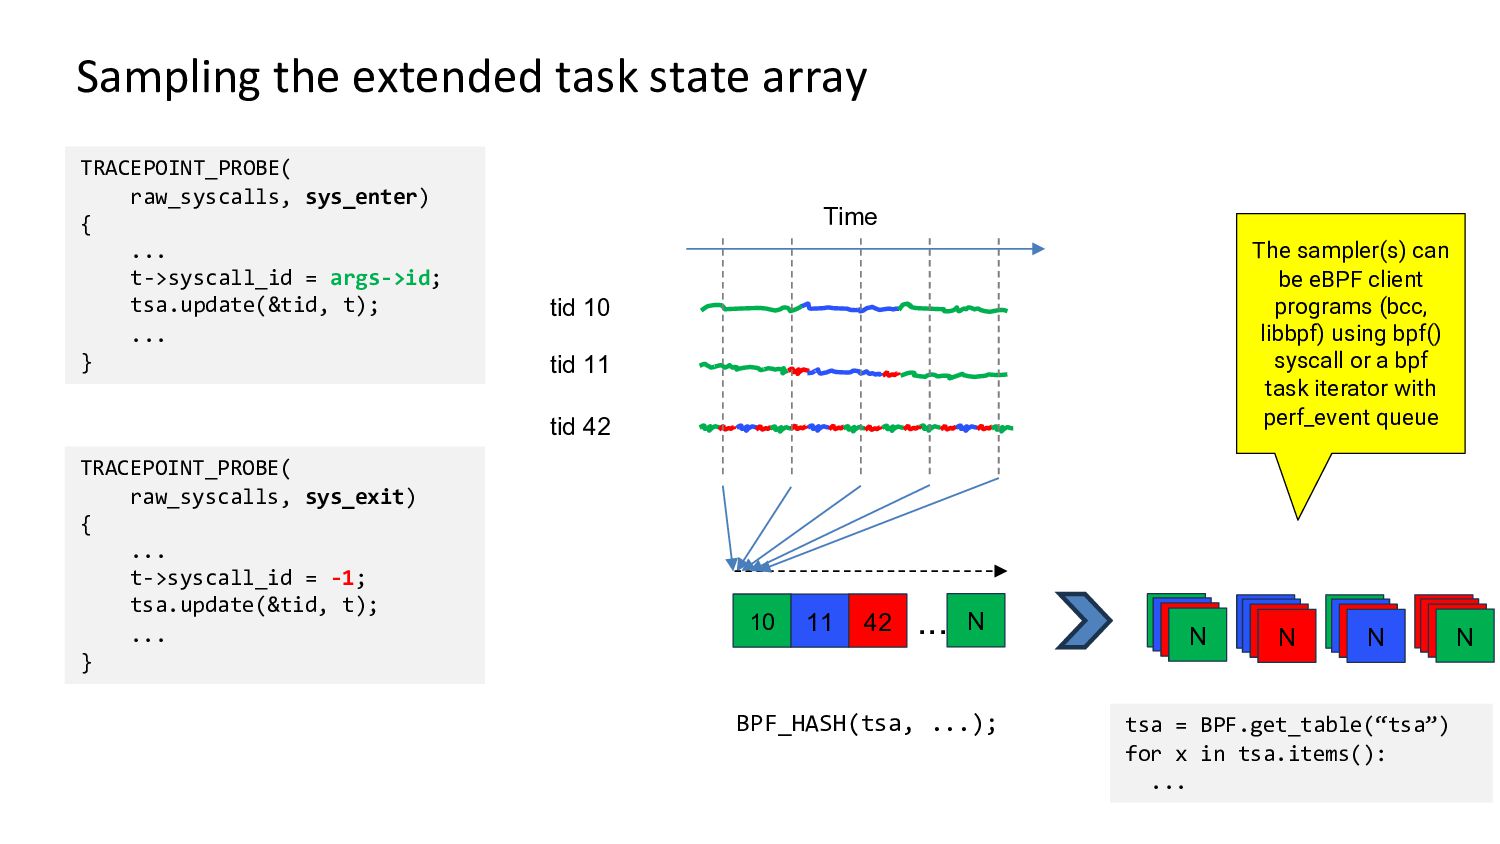
& maintaining the array • Keep only the latest state change for each thread • “Tracking, not tracing!” • Sampling program independent from population • Python/BCC, C, Rust/libbpf, eBPF iterators, etc... • Multiple concurrent samplers allowed • Different sampling frequencies allowed -
Time tid 10 tid 11 tid 42 10 11 42
N ... 10 10 10 TRACEPOINT_PROBE( raw_syscalls, sys_enter) { ... t->syscall_id = args->id; tsa.update(&tid, t); ... } BPF_HASH(tsa, ...); TRACEPOINT_PROBE( raw_syscalls, sys_exit) { ... t->syscall_id = -1; tsa.update(&tid, t); ... } Populating the extended task state array -
Time tid 10 tid 11 tid 42 10 11 42
N ... 10 11 11 11 11 11 BPF_HASH(tsa, ...); TRACEPOINT_PROBE( raw_syscalls, sys_enter) { ... t->syscall_id = args->id; tsa.update(&tid, t); ... } TRACEPOINT_PROBE( raw_syscalls, sys_exit) { ... t->syscall_id = -1; tsa.update(&tid, t); ... } Populating the extended task state array -
Time tid 10 tid 11 tid 42 10 11 42
N ... 10 42 42 42 42 42 42 42 42 42 42 42 We are not tracing: no logging or appending all events ... We track: overwrite the task's current action in the extended task state array ... BPF_HASH(tsa, ...); TRACEPOINT_PROBE( raw_syscalls, sys_enter) { ... t->syscall_id = args->id; tsa.update(&tid, t); ... } TRACEPOINT_PROBE( raw_syscalls, sys_exit) { ... t->syscall_id = -1; tsa.update(&tid, t); ... } Populating the extended task state array -
Time tid 10 tid 11 tid 42 10 11 42
N ... A separate, independent program samples the state arrays using its desired frequency and filter rules to userspace tsa = BPF.get_table(“tsa”) for x in tsa.items(): ... 10 11 42 N 10 11 42 N 10 11 42 N 10 11 42 N BPF_HASH(tsa, ...); TRACEPOINT_PROBE( raw_syscalls, sys_enter) { ... t->syscall_id = args->id; tsa.update(&tid, t); ... } TRACEPOINT_PROBE( raw_syscalls, sys_exit) { ... t->syscall_id = -1; tsa.update(&tid, t); ... } Sampling the extended task state array -
Time tid 10 tid 11 tid 42 10 11 42
N ... 10 11 42 N 10 11 42 N 10 11 42 N 10 11 42 N The sampler(s) can be eBPF client programs (bcc, libbpf) using bpf() syscall or a bpf task iterator with perf_event queue BPF_HASH(tsa, ...); TRACEPOINT_PROBE( raw_syscalls, sys_enter) { ... t->syscall_id = args->id; tsa.update(&tid, t); ... } TRACEPOINT_PROBE( raw_syscalls, sys_exit) { ... t->syscall_id = -1; tsa.update(&tid, t); ... } tsa = BPF.get_table(“tsa”) for x in tsa.items(): ... Sampling the extended task state array -
Always-on output logging (for time travel and advanced analytics) $
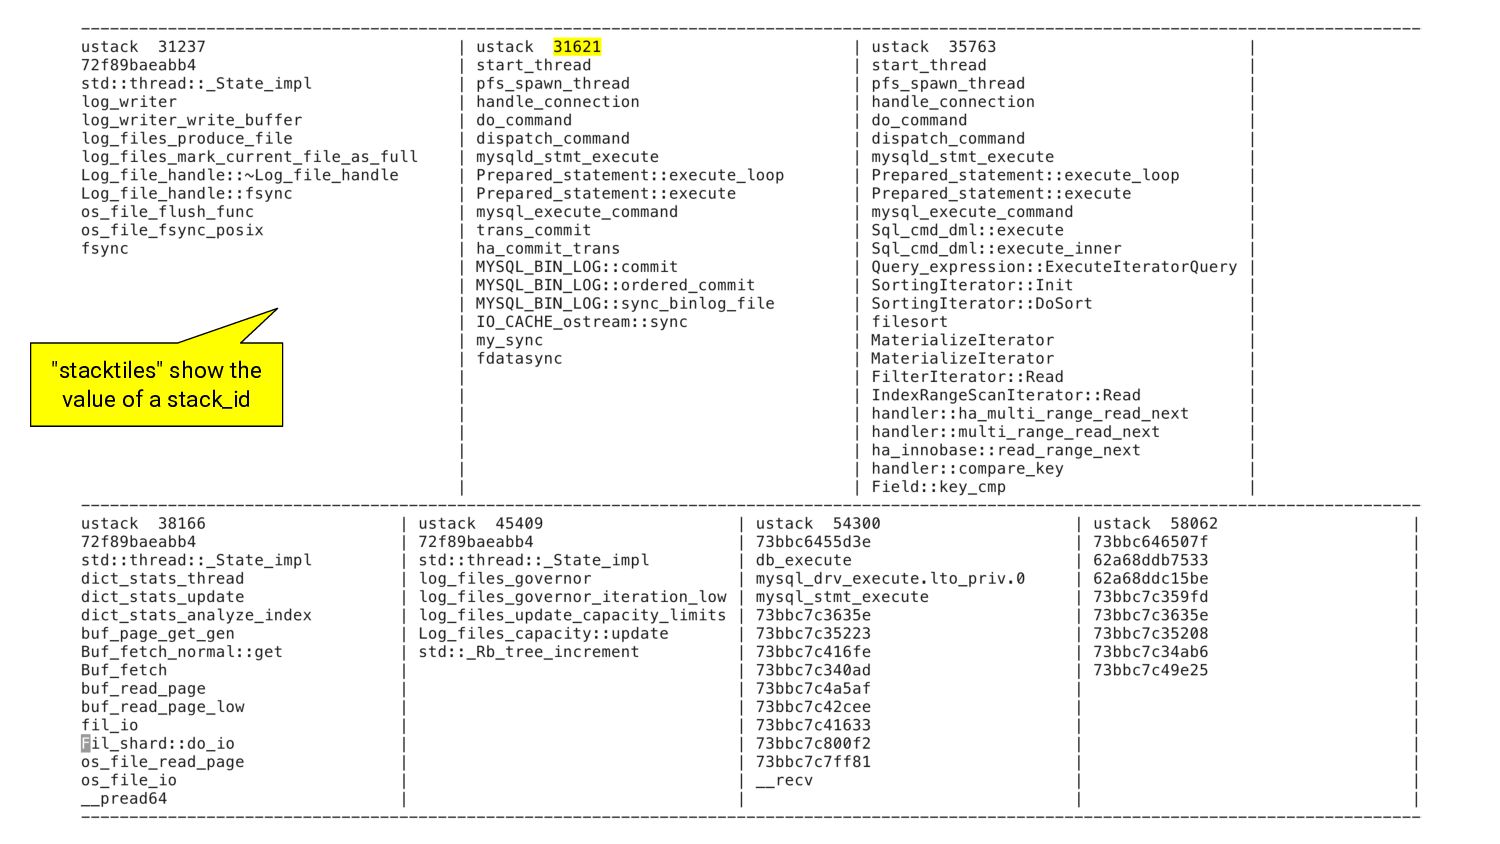
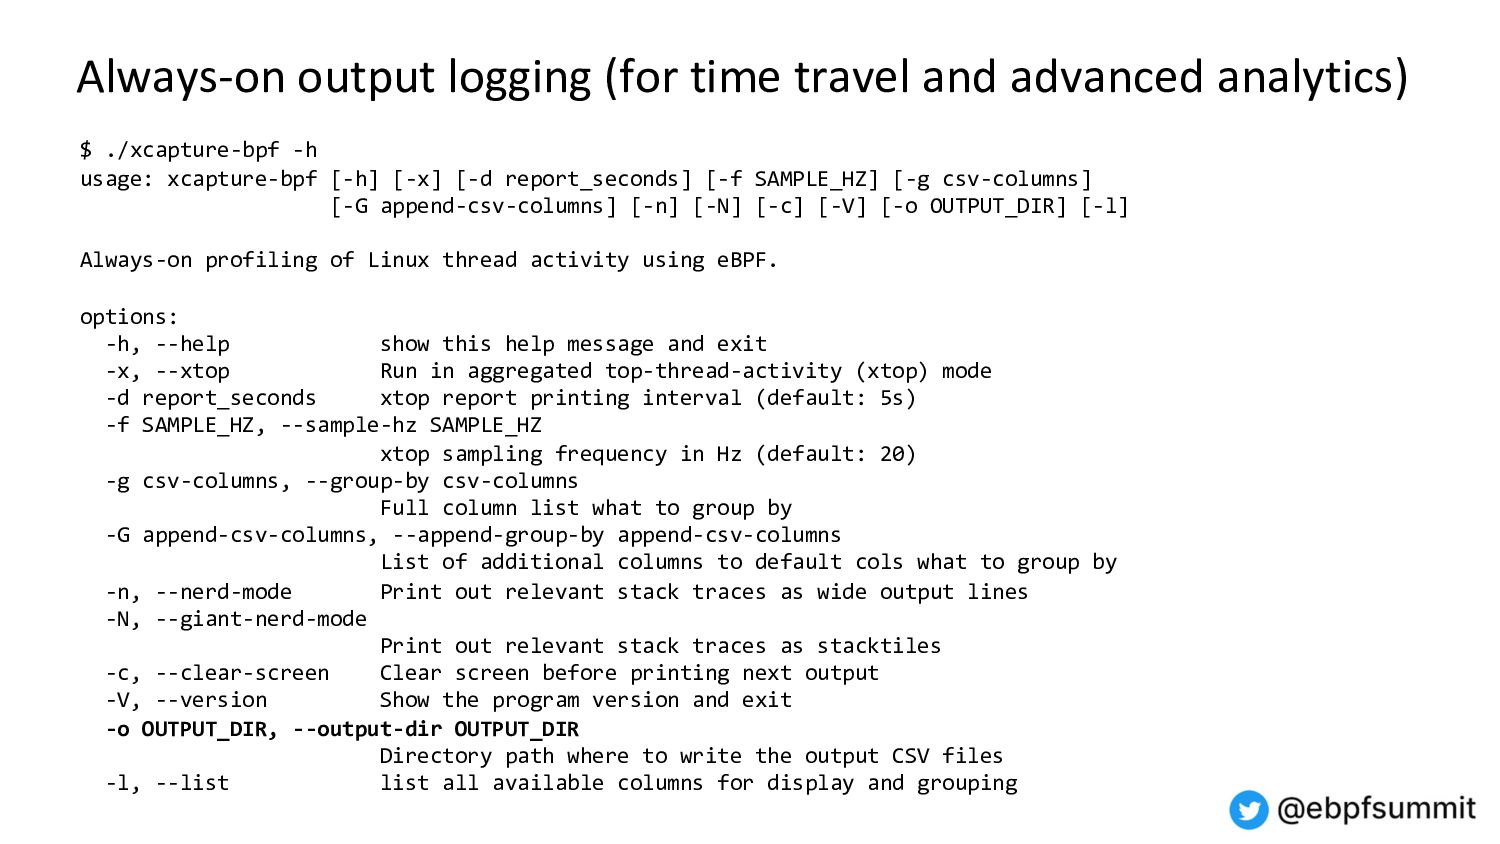
./xcapture-bpf -h usage: xcapture-bpf [-h] [-x] [-d report_seconds] [-f SAMPLE_HZ] [-g csv-columns] [-G append-csv-columns] [-n] [-N] [-c] [-V] [-o OUTPUT_DIR] [-l] Always-on profiling of Linux thread activity using eBPF. options: -h, --help show this help message and exit -x, --xtop Run in aggregated top-thread-activity (xtop) mode -d report_seconds xtop report printing interval (default: 5s) -f SAMPLE_HZ, --sample-hz SAMPLE_HZ xtop sampling frequency in Hz (default: 20) -g csv-columns, --group-by csv-columns Full column list what to group by -G append-csv-columns, --append-group-by append-csv-columns List of additional columns to default cols what to group by -n, --nerd-mode Print out relevant stack traces as wide output lines -N, --giant-nerd-mode Print out relevant stack traces as stacktiles -c, --clear-screen Clear screen before printing next output -V, --version Show the program version and exit -o OUTPUT_DIR, --output-dir OUTPUT_DIR Directory path where to write the output CSV files -l, --list list all available columns for display and grouping -
Always-on output logging (for time travel and advanced analytics) $
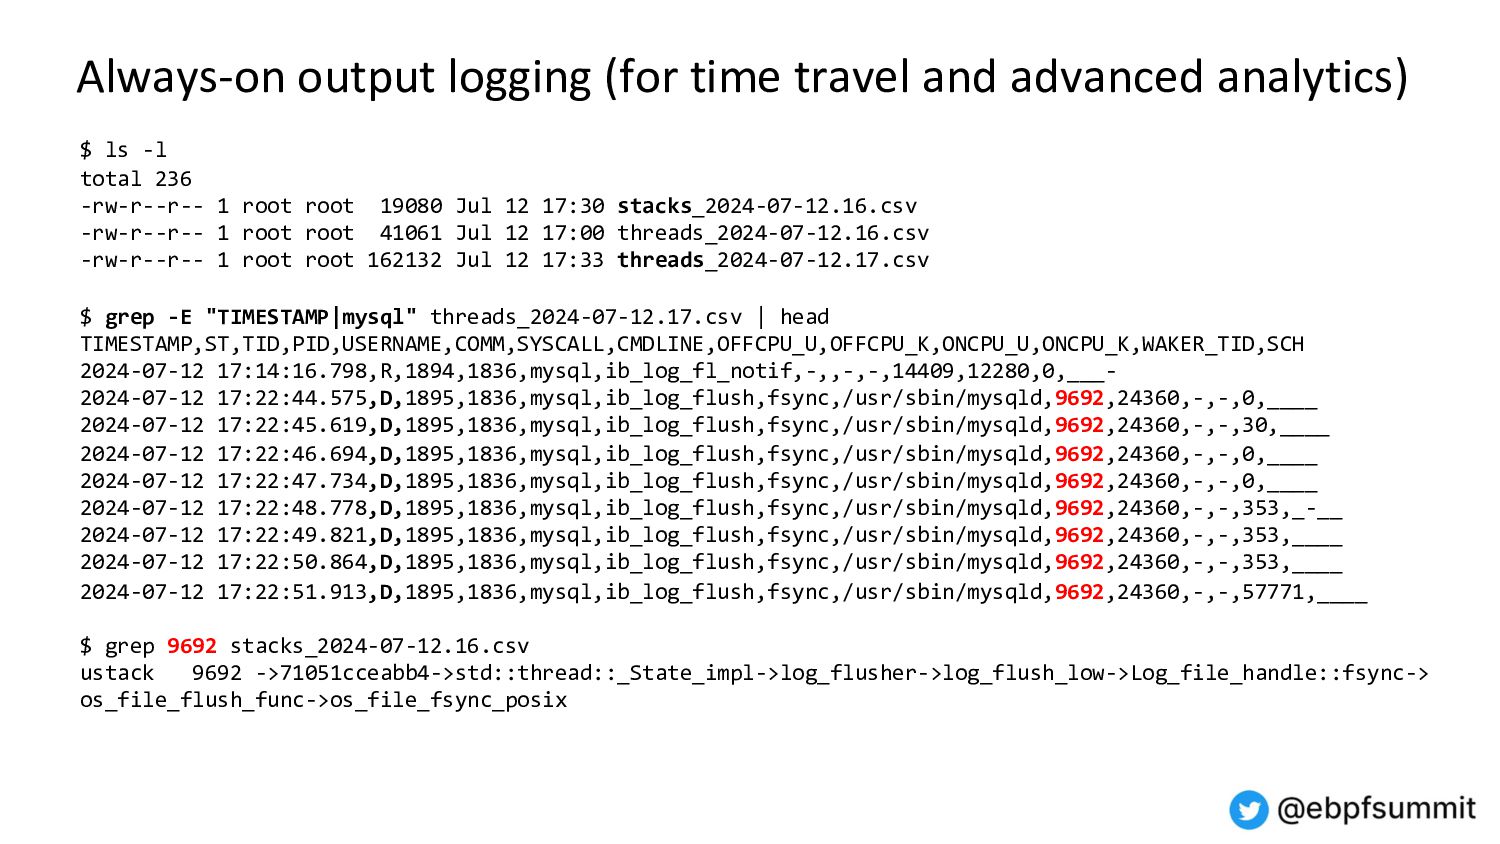
ls -l total 236 -rw-r--r-- 1 root root 19080 Jul 12 17:30 stacks_2024-07-12.16.csv -rw-r--r-- 1 root root 41061 Jul 12 17:00 threads_2024-07-12.16.csv -rw-r--r-- 1 root root 162132 Jul 12 17:33 threads_2024-07-12.17.csv $ grep -E "TIMESTAMP|mysql" threads_2024-07-12.17.csv | head TIMESTAMP,ST,TID,PID,USERNAME,COMM,SYSCALL,CMDLINE,OFFCPU_U,OFFCPU_K,ONCPU_U,ONCPU_K,WAKER_TID,SCH 2024-07-12 17:14:16.798,R,1894,1836,mysql,ib_log_fl_notif,-,,-,-,14409,12280,0,___- 2024-07-12 17:22:44.575,D,1895,1836,mysql,ib_log_flush,fsync,/usr/sbin/mysqld,9692,24360,-,-,0,____ 2024-07-12 17:22:45.619,D,1895,1836,mysql,ib_log_flush,fsync,/usr/sbin/mysqld,9692,24360,-,-,30,____ 2024-07-12 17:22:46.694,D,1895,1836,mysql,ib_log_flush,fsync,/usr/sbin/mysqld,9692,24360,-,-,0,____ 2024-07-12 17:22:47.734,D,1895,1836,mysql,ib_log_flush,fsync,/usr/sbin/mysqld,9692,24360,-,-,0,____ 2024-07-12 17:22:48.778,D,1895,1836,mysql,ib_log_flush,fsync,/usr/sbin/mysqld,9692,24360,-,-,353,_-__ 2024-07-12 17:22:49.821,D,1895,1836,mysql,ib_log_flush,fsync,/usr/sbin/mysqld,9692,24360,-,-,353,____ 2024-07-12 17:22:50.864,D,1895,1836,mysql,ib_log_flush,fsync,/usr/sbin/mysqld,9692,24360,-,-,353,____ 2024-07-12 17:22:51.913,D,1895,1836,mysql,ib_log_flush,fsync,/usr/sbin/mysqld,9692,24360,-,-,57771,____ $ grep 9692 stacks_2024-07-12.16.csv ustack 9692 ->71051cceabb4->std::thread::_State_impl->log_flusher->log_flush_low->Log_file_handle::fsync-> os_file_flush_func->os_file_fsync_posix -
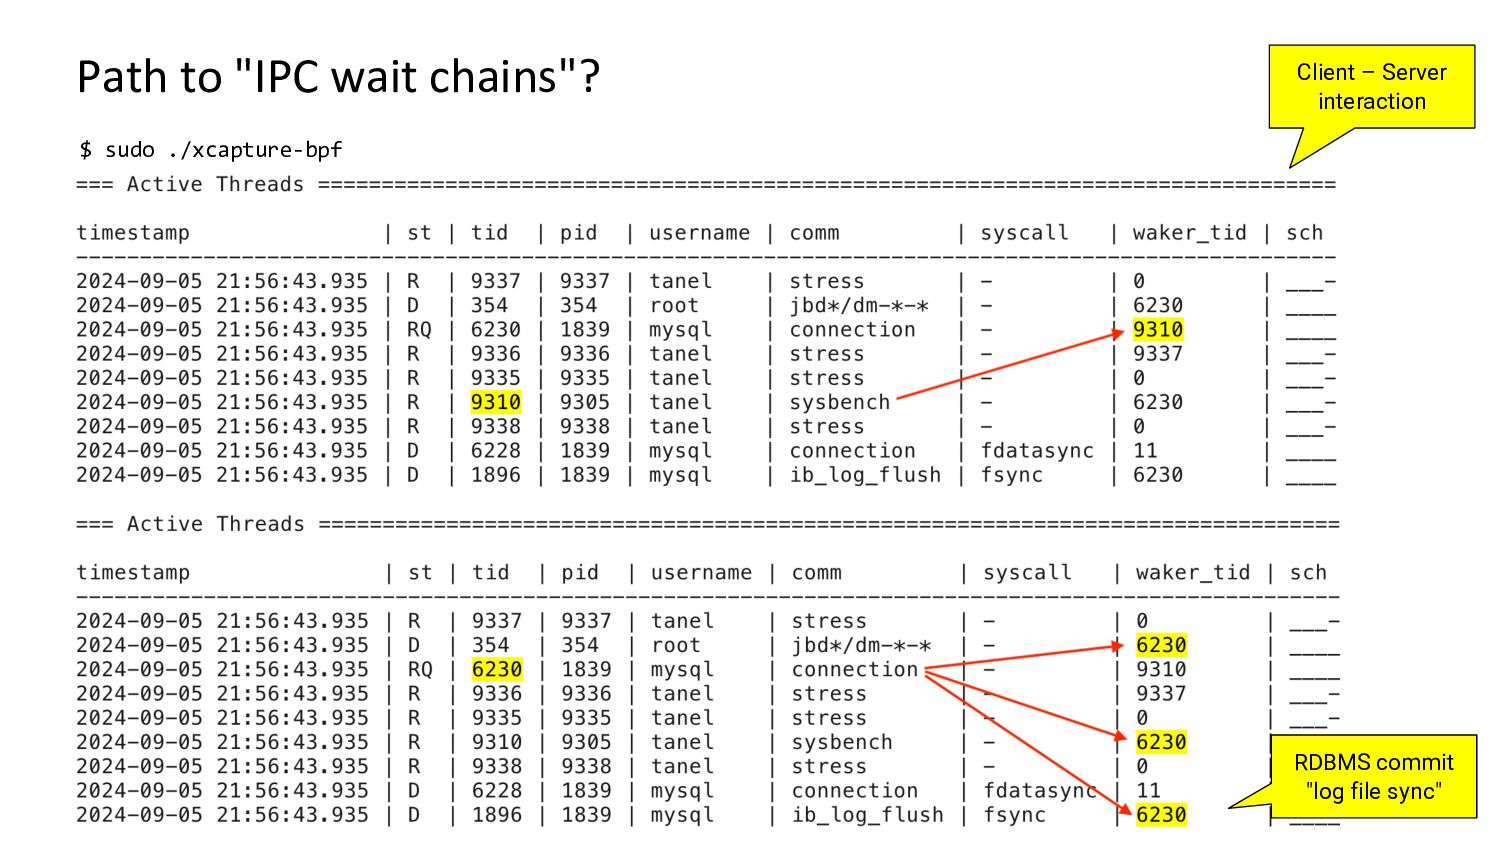
Path to "IPC wait chains"? $ sudo ./xcapture-bpf Client –
Server interaction RDBMS commit "log file sync" -
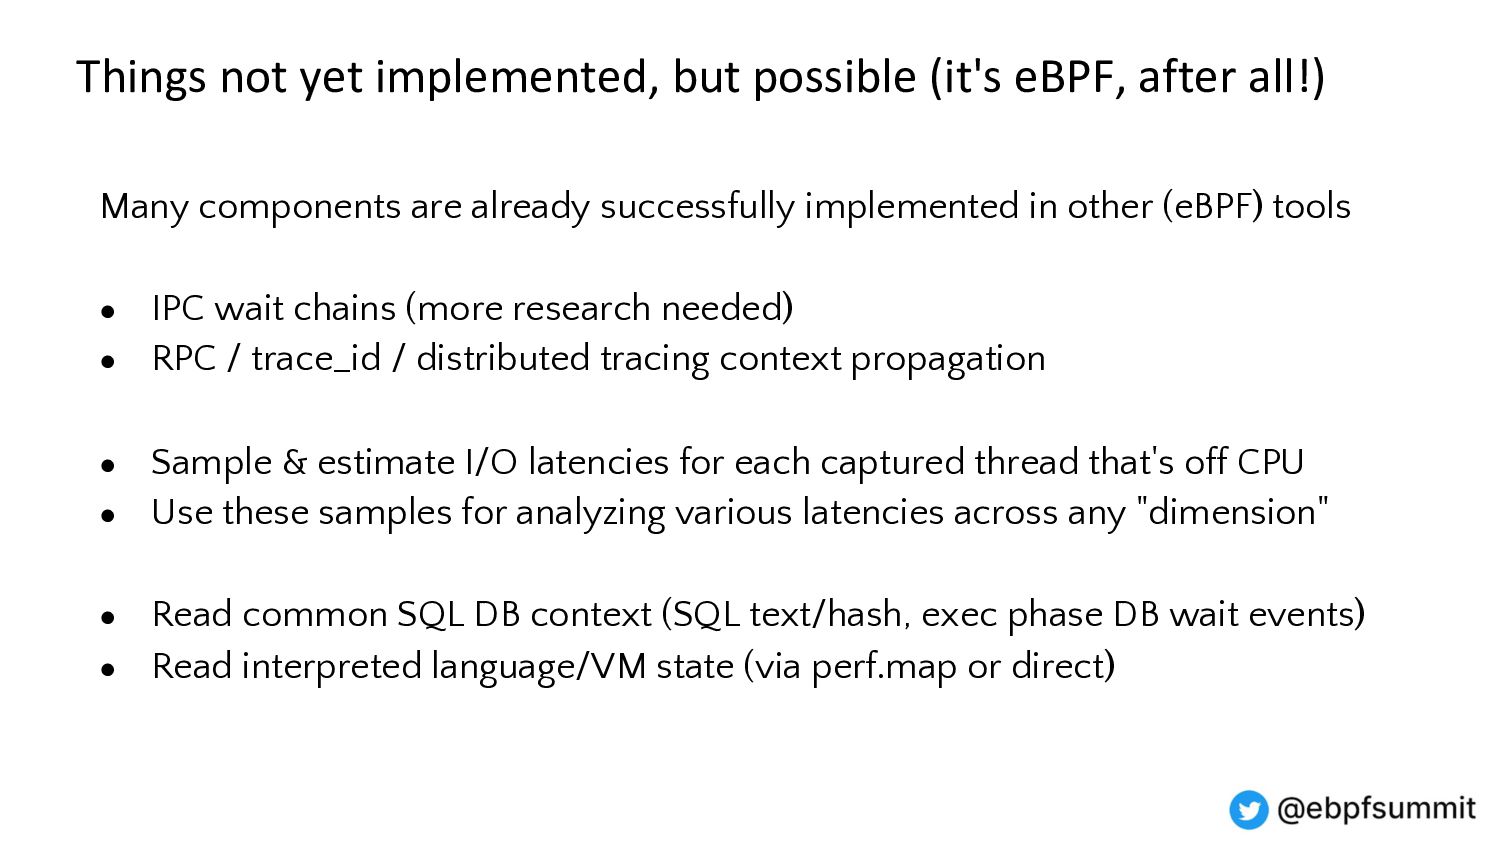
Things not yet implemented, but possible (it's eBPF, after all!)
Many components are already successfully implemented in other (eBPF) tools • IPC wait chains (more research needed) • RPC / trace_id / distributed tracing context propagation • Sample & estimate I/O latencies for each captured thread that's off CPU • Use these samples for analyzing various latencies across any "dimension" • Read common SQL DB context (SQL text/hash, exec phase DB wait events) • Read interpreted language/VM state (via perf.map or direct) -
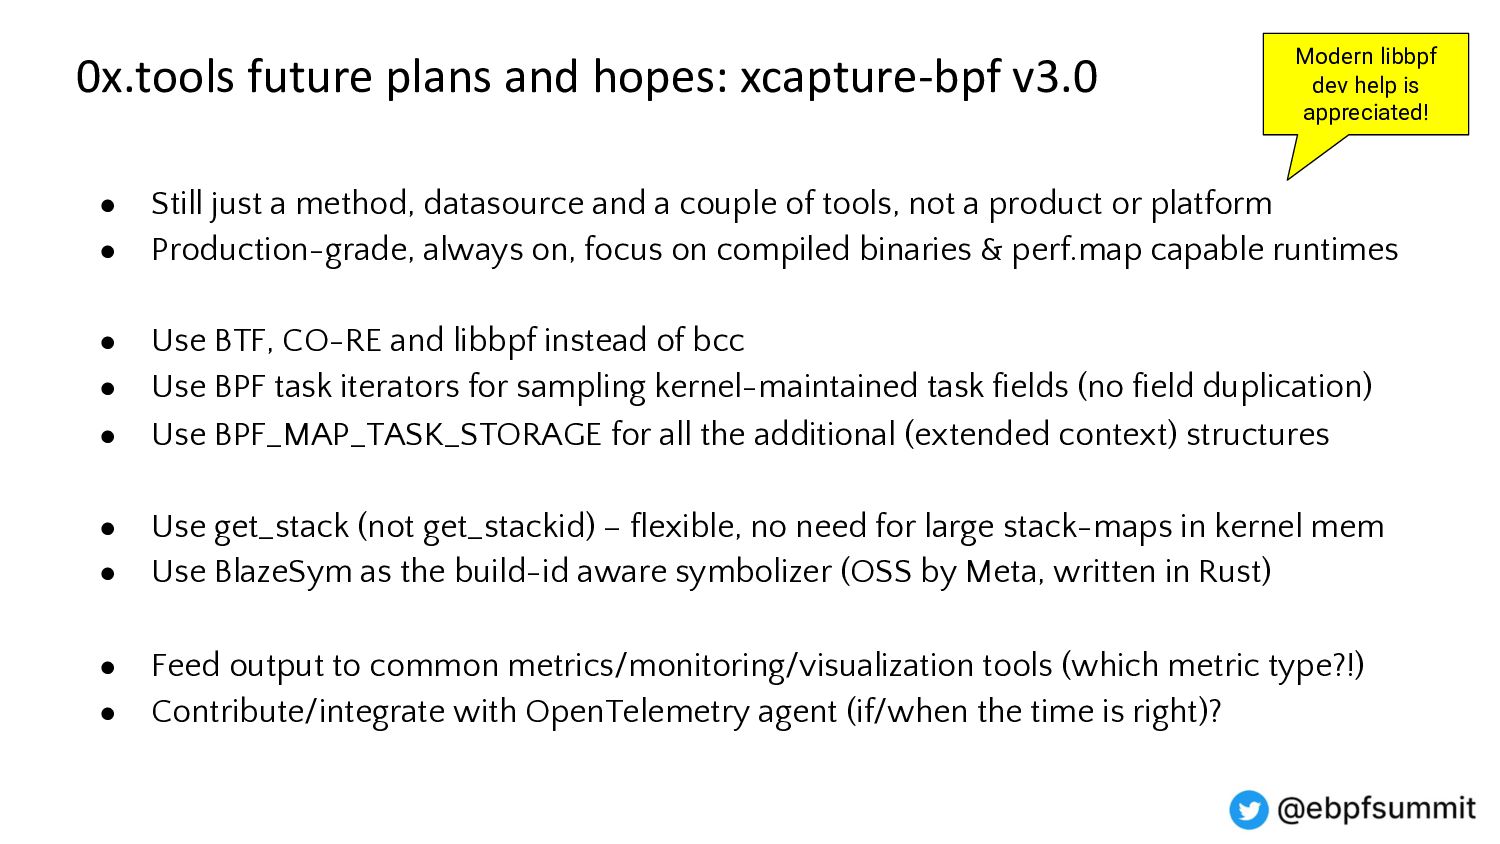
• Still just a method, datasource and a couple of
tools, not a product or platform • Production-grade, always on, focus on compiled binaries & perf.map capable runtimes • Use BTF, CO-RE and libbpf instead of bcc • Use BPF task iterators for sampling kernel-maintained task fields (no field duplication) • Use BPF_MAP_TASK_STORAGE for all the additional (extended context) structures • Use get_stack (not get_stackid) – flexible, no need for large stack-maps in kernel mem • Use BlazeSym as the build-id aware symbolizer (OSS by Meta, written in Rust) • Feed output to common metrics/monitoring/visualization tools (which metric type?!) • Contribute/integrate with OpenTelemetry agent (if/when the time is right)? 0x.tools future plans and hopes: xcapture-bpf v3.0 Modern libbpf dev help is appreciated!