Share
Embed
Transcript
25 slides
-
Supervised Learning of Universal Sentence Representations from Natural Language Inference
Data A. Conneau, D. Kiela, H. Schwenk, L. Barrault, and A. Bordes, Proceedings of the 2017 Conference on Empirical Methods in Natural Language Processing, pp. 670–680, 2017. Nagaoka University of Technology Takumi Maruyama Literature review: -
Introduction Ø This paper proposed universal sentence representations trained using
the supervised data of the Stanford Natural Language Inference datasets Ø Sentence embeddings with supervised data were tested on 12 different transfer tasks Ø BiLSTM network with max pooling makes the best current universal sentence encoding methods 2 -
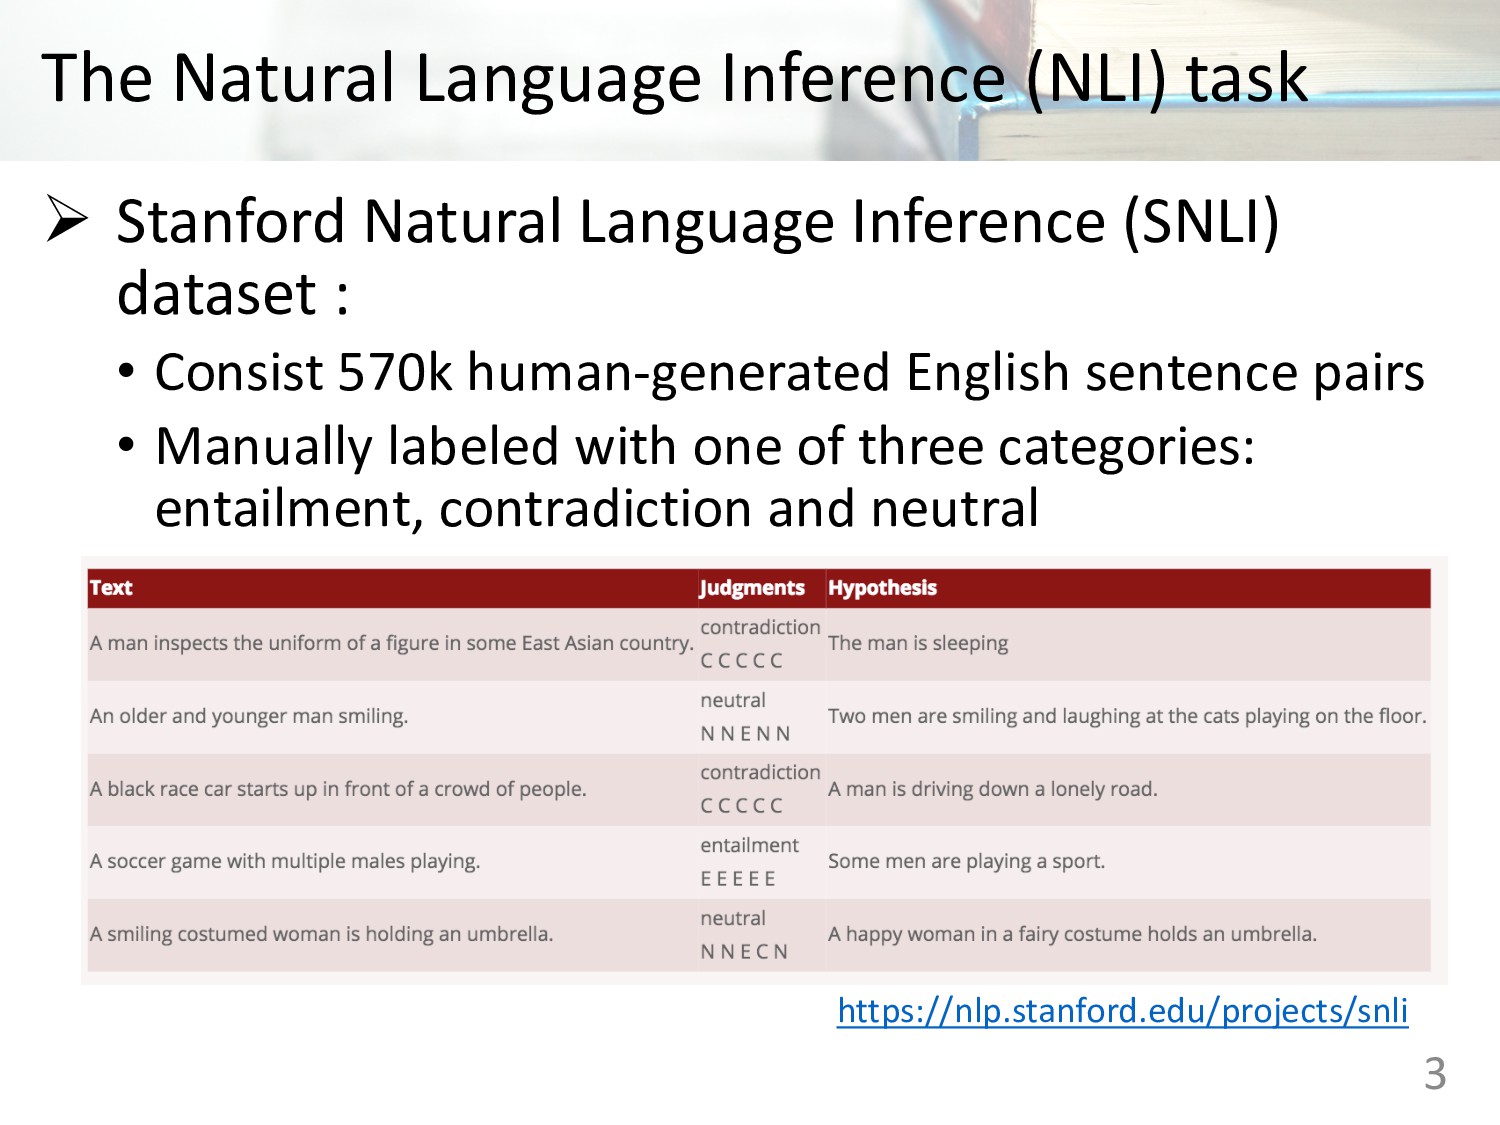
The Natural Language Inference (NLI) task Ø Stanford Natural Language
Inference (SNLI) dataset : • Consist 570k human-generated English sentence pairs • Manually labeled with one of three categories: entailment, contradiction and neutral https://nlp.stanford.edu/projects/snli 3 -
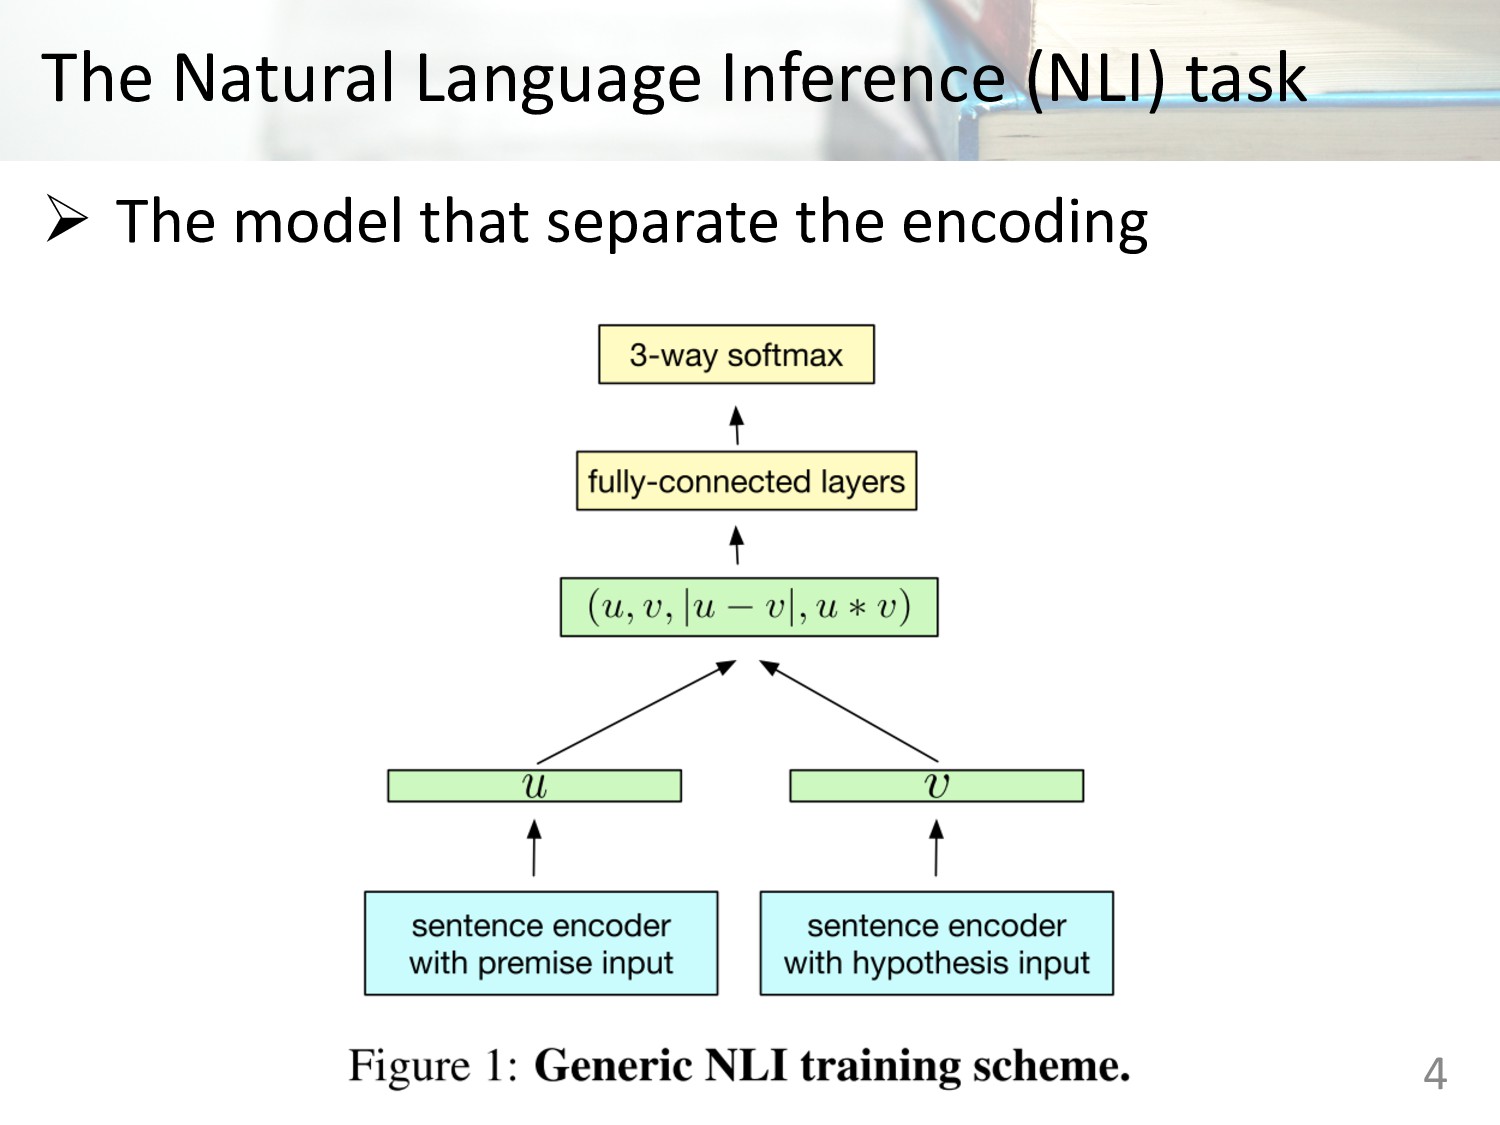
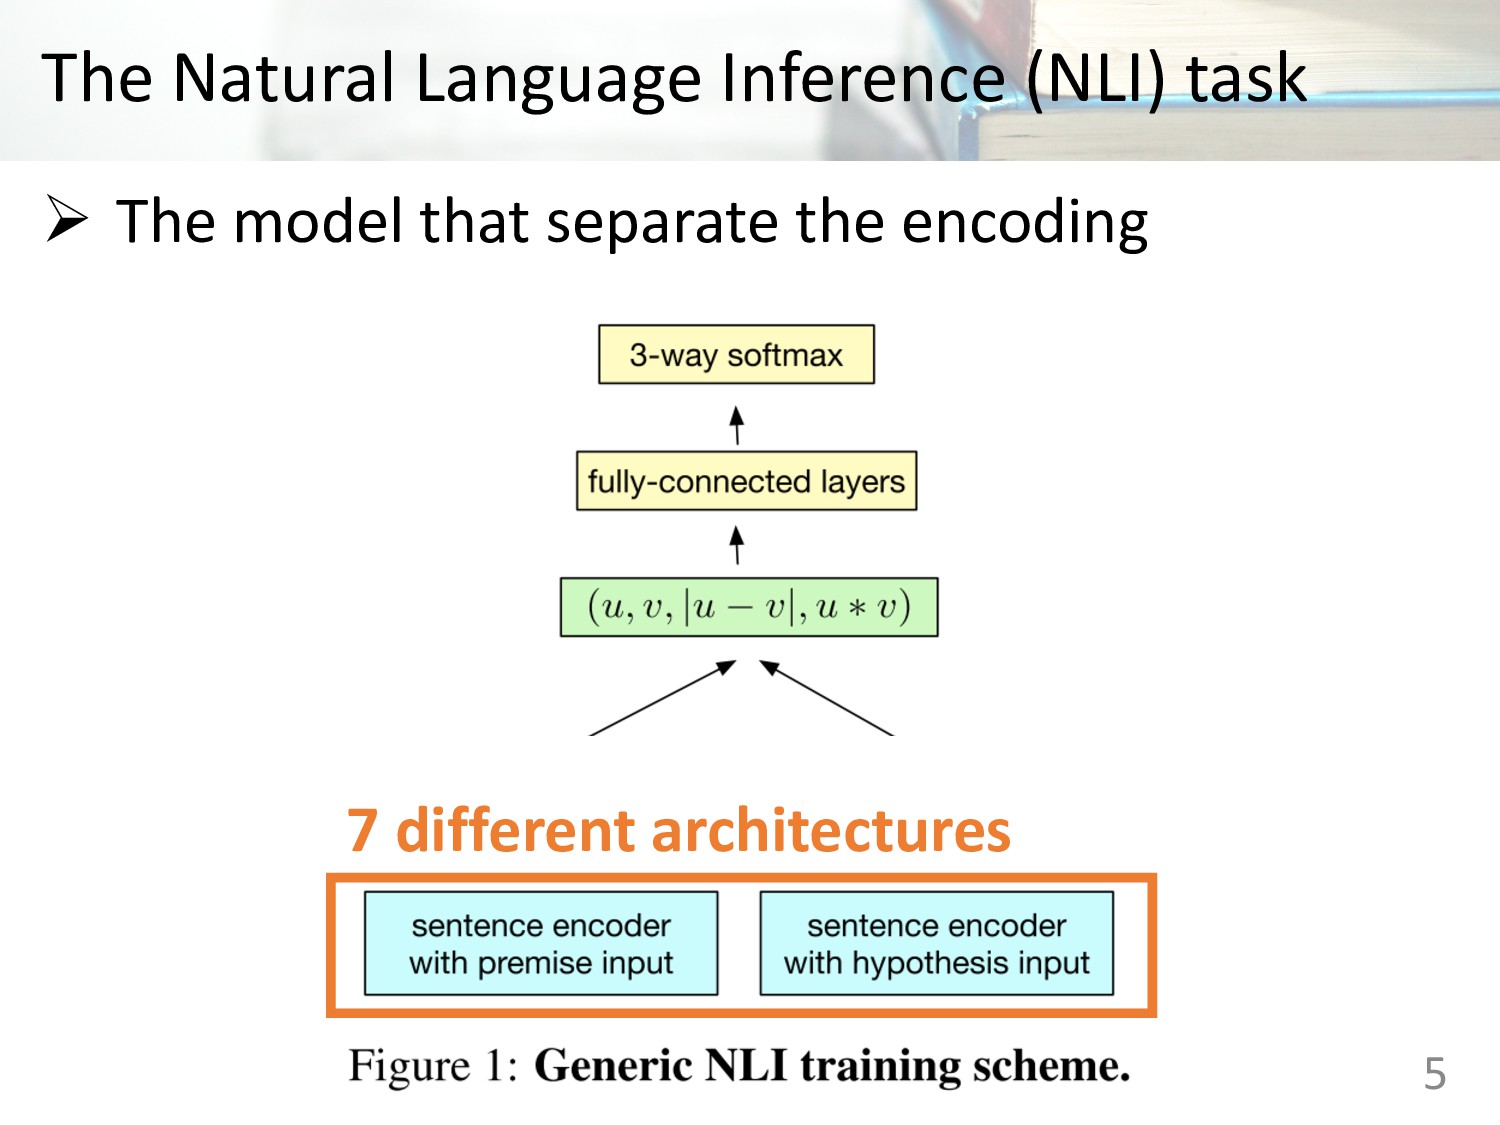
The Natural Language Inference (NLI) task Ø The model that
separate the encoding 4 -
The Natural Language Inference (NLI) task Ø The model that
separate the encoding 5 7 different architectures -
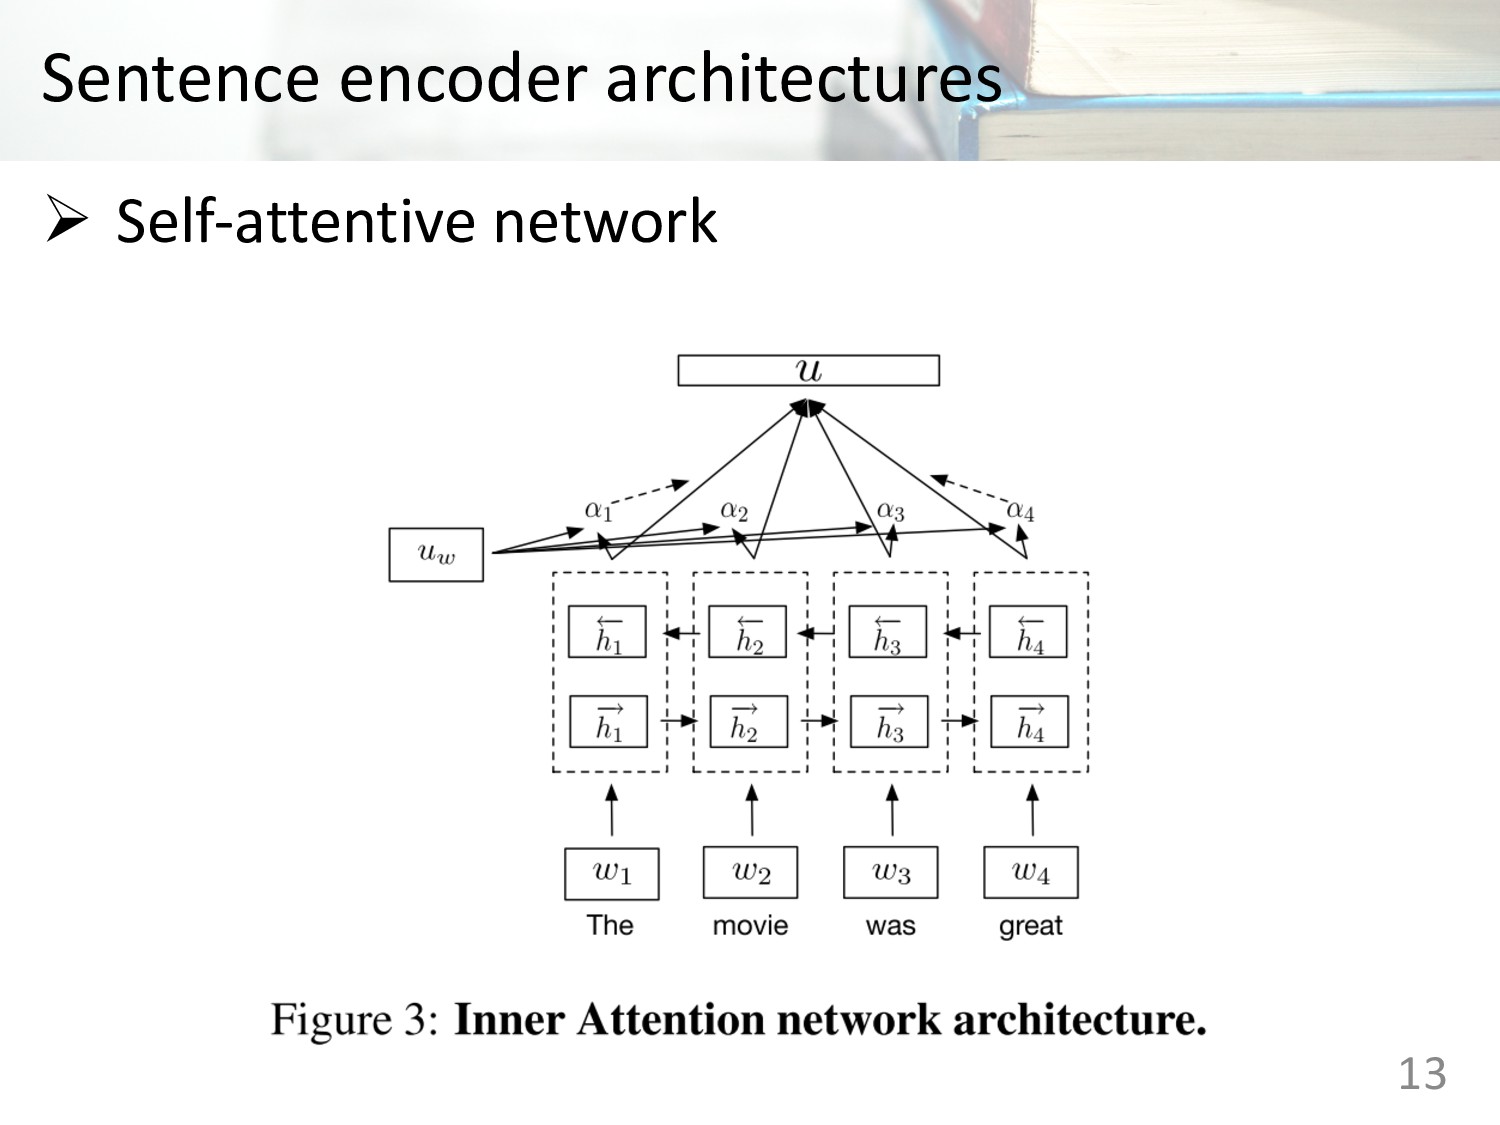
Sentence encoder architectures Ø 7 different architectures • Long Short-Term
Memory (LSTM) • Gated Recurrent Units (GRU) • Concatenation of last hidden states of forward and backward GRU • Bi-directional LSTMs with mean pooling • Bi-directional LSTMs with max pooling • Self-attentive network • Hierarchical convolutional networks 6 -
Sentence encoder architectures Ø 7 different architectures • Long Short-Term
Memory (LSTM) • Gated Recurrent Units (GRU) • Concatenation of last hidden states of forward and backward GRU • Bi-directional LSTMs with mean pooling • Bi-directional LSTMs with max pooling • Self-attentive network • Hierarchical convolutional networks 7 -
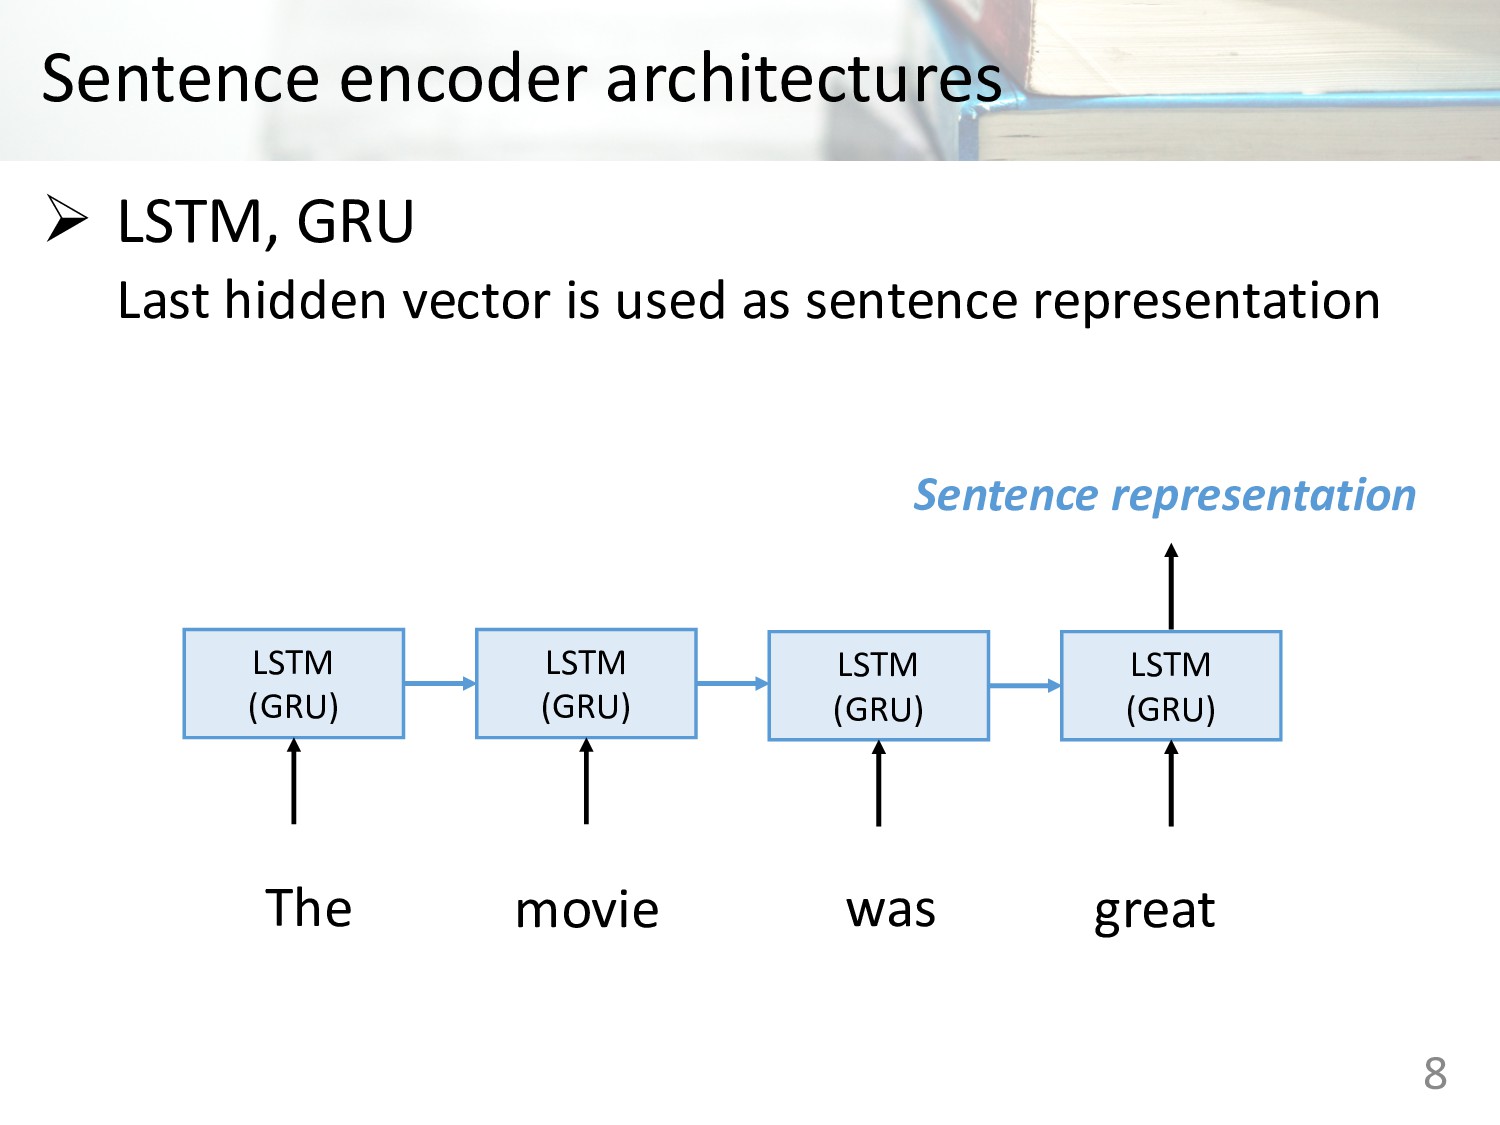
Sentence encoder architectures Ø LSTM, GRU Last hidden vector is
used as sentence representation 8 LSTM (GRU) The movie LSTM (GRU) LSTM (GRU) LSTM (GRU) was great Sentence representation -
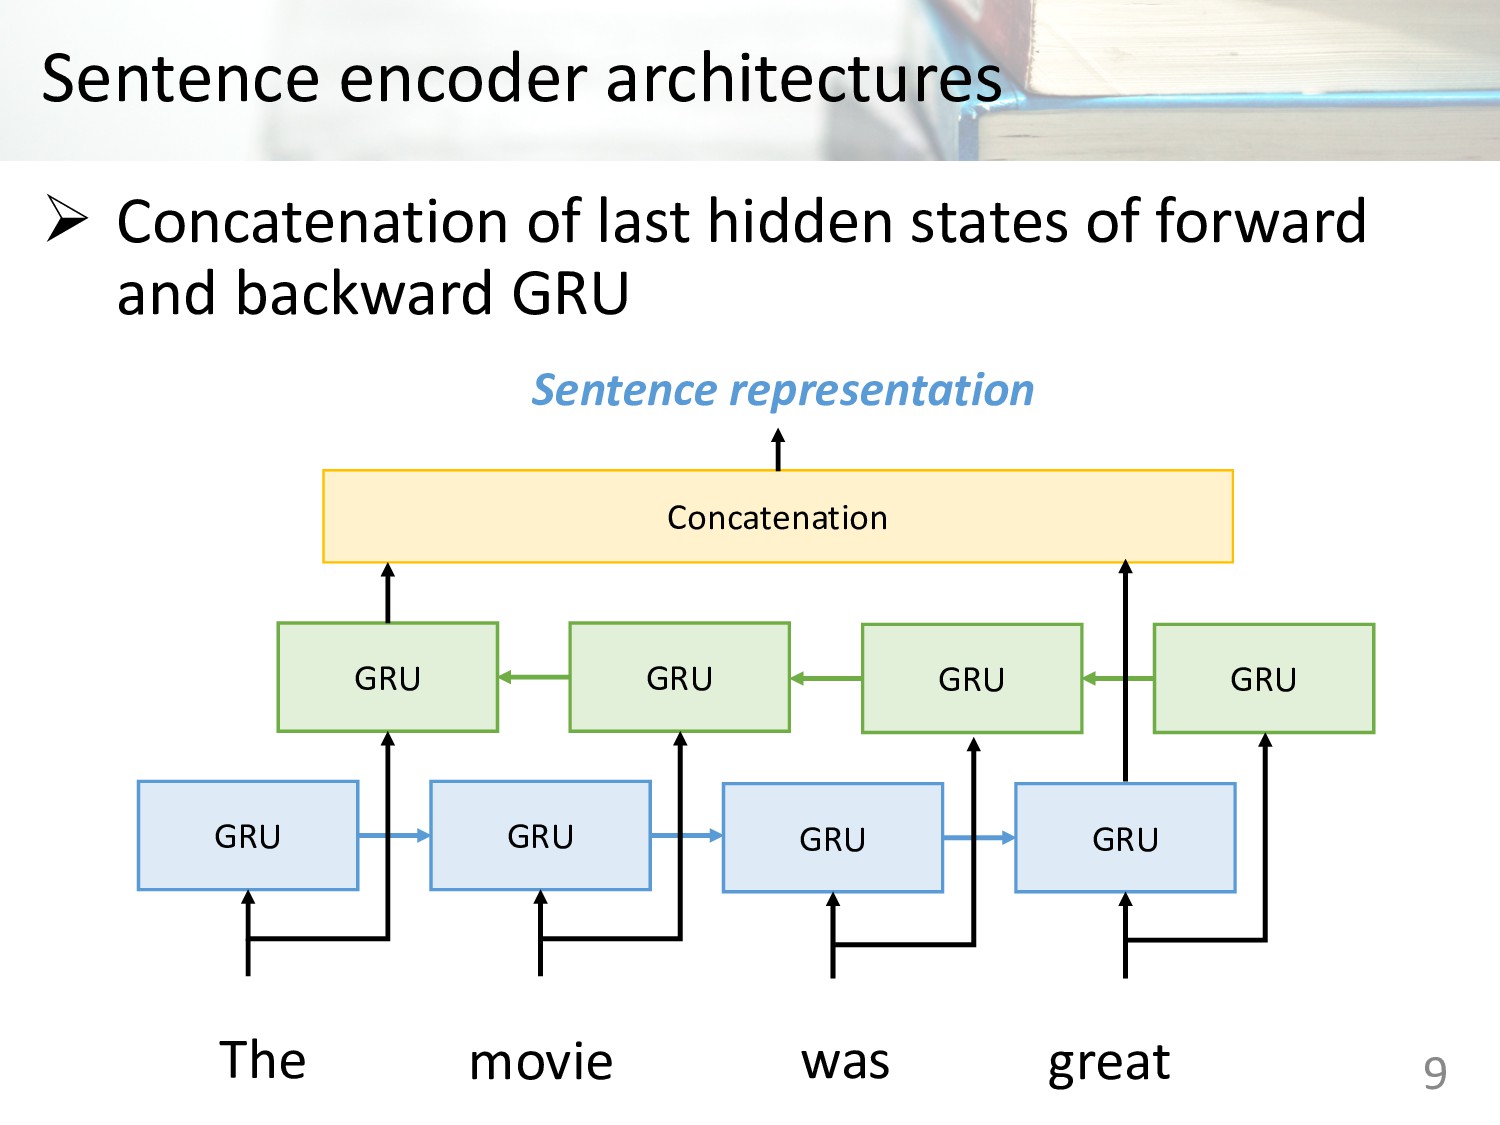
Sentence encoder architectures Ø Concatenation of last hidden states of
forward and backward GRU 9 GRU The movie GRU GRU GRU was great GRU GRU GRU GRU Concatenation Sentence representation -
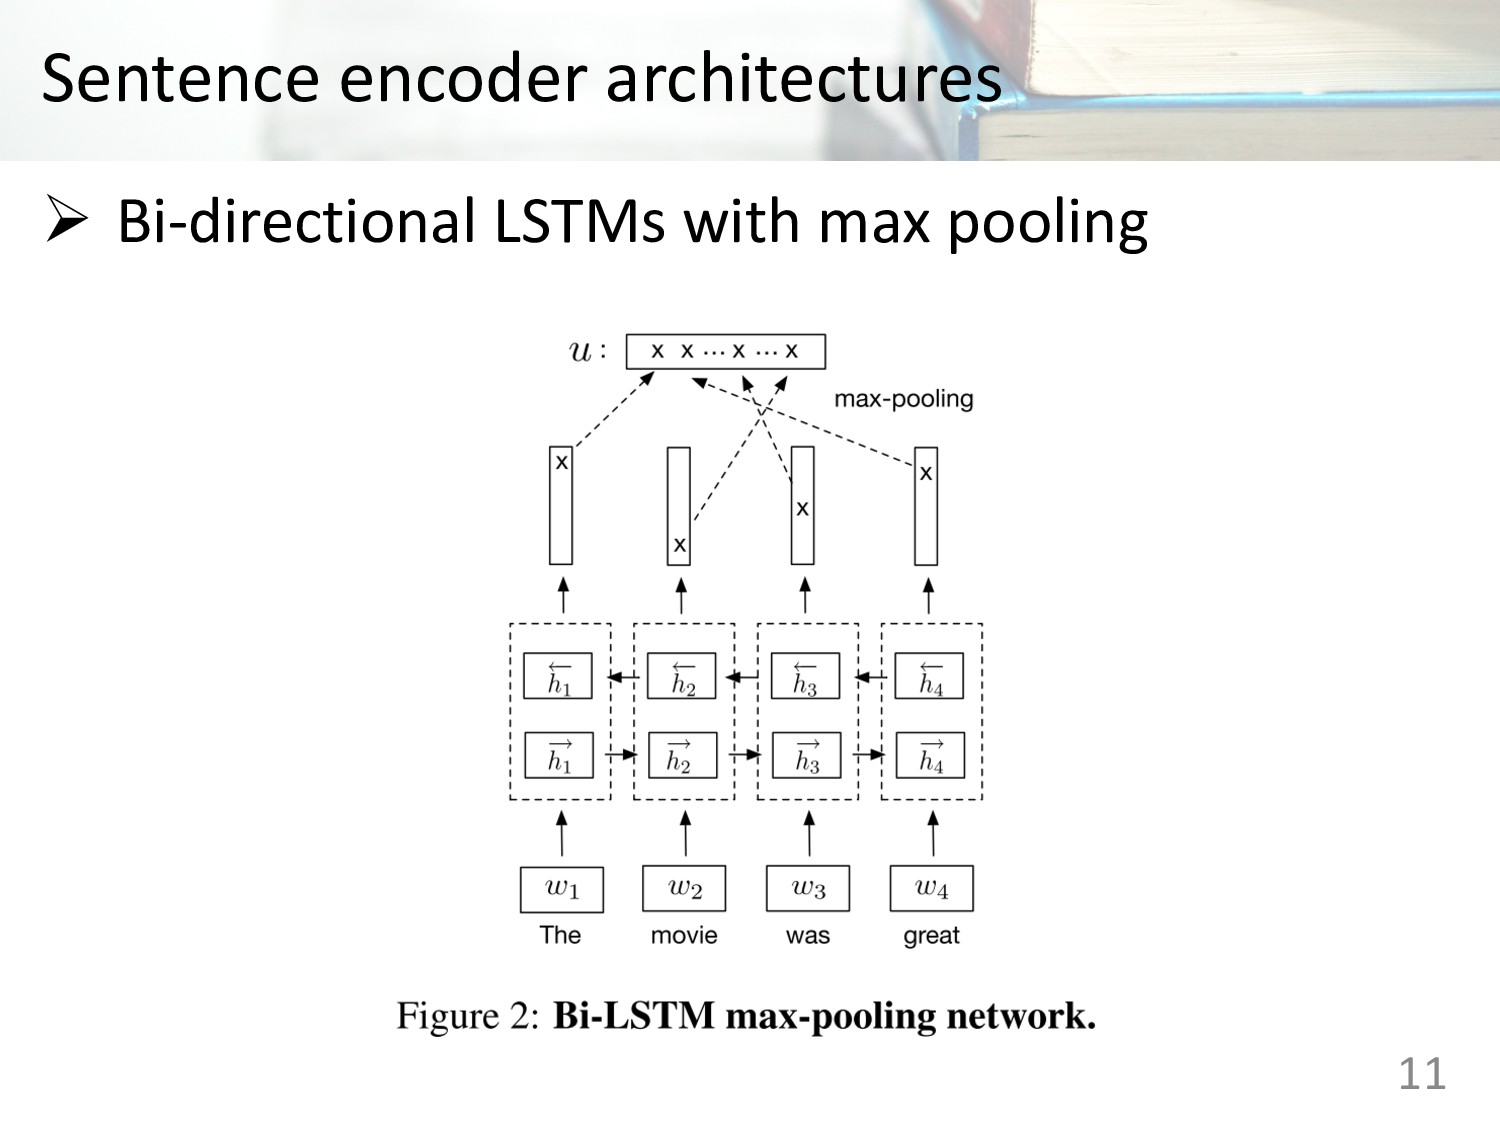
Sentence encoder architectures Ø 7 different architectures • Long Short-Term
Memory (LSTM) • Gated Recurrent Units (GRU) • Concatenation of last hidden states of forward and backward GRU • Bi-directional LSTMs with mean pooling • Bi-directional LSTMs with max pooling • Self-attentive network • Hierarchical convolutional networks 10 -
Sentence encoder architectures Ø 7 different architectures • Long Short-Term
Memory (LSTM) • Gated Recurrent Units (GRU) • Concatenation of last hidden states of forward and backward GRU • Bi-directional LSTMs with mean pooling • Bi-directional LSTMs with max pooling • Self-attentive network • Hierarchical convolutional networks 12 -
Sentence encoder architectures Ø 7 different architectures • Long Short-Term
Memory (LSTM) • Gated Recurrent Units (GRU) • Concatenation of last hidden states of forward and backward GRU • Bi-directional LSTMs with mean pooling • Bi-directional LSTMs with max pooling • Self-attentive network • Hierarchical convolutional networks 14 -
Evaluation of sentence representations 16 Ø 12 tasks to evaluate
sentence representations • Binary and multi-class classification • Entailment and semantic relatedness • Semantic Textual Similarity • Paraphrase detection • Caption-Image retrieval -
Evaluation of sentence representations 17 Ø 12 tasks to evaluate
sentence representations • Binary and multi-class classification • Entailment and semantic relatedness • Semantic Textual Similarity • Paraphrase detection • Caption-Image retrieval -
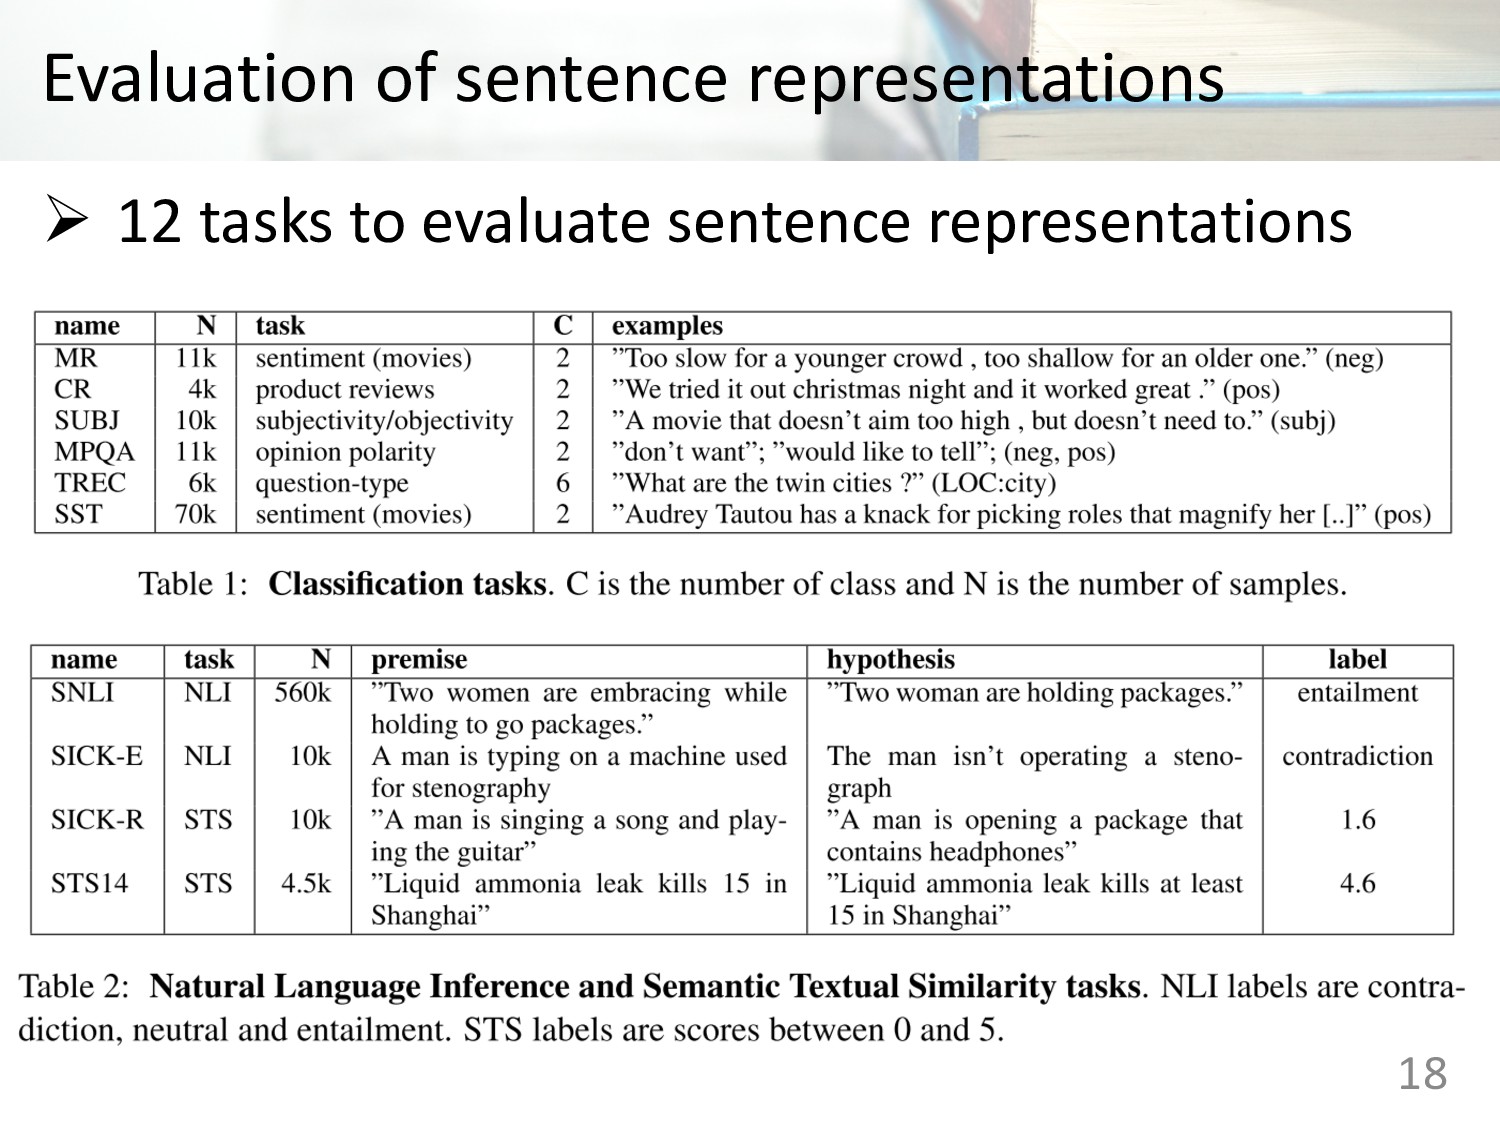
Evaluation of sentence representations 18 Ø 12 tasks to evaluate
sentence representations -
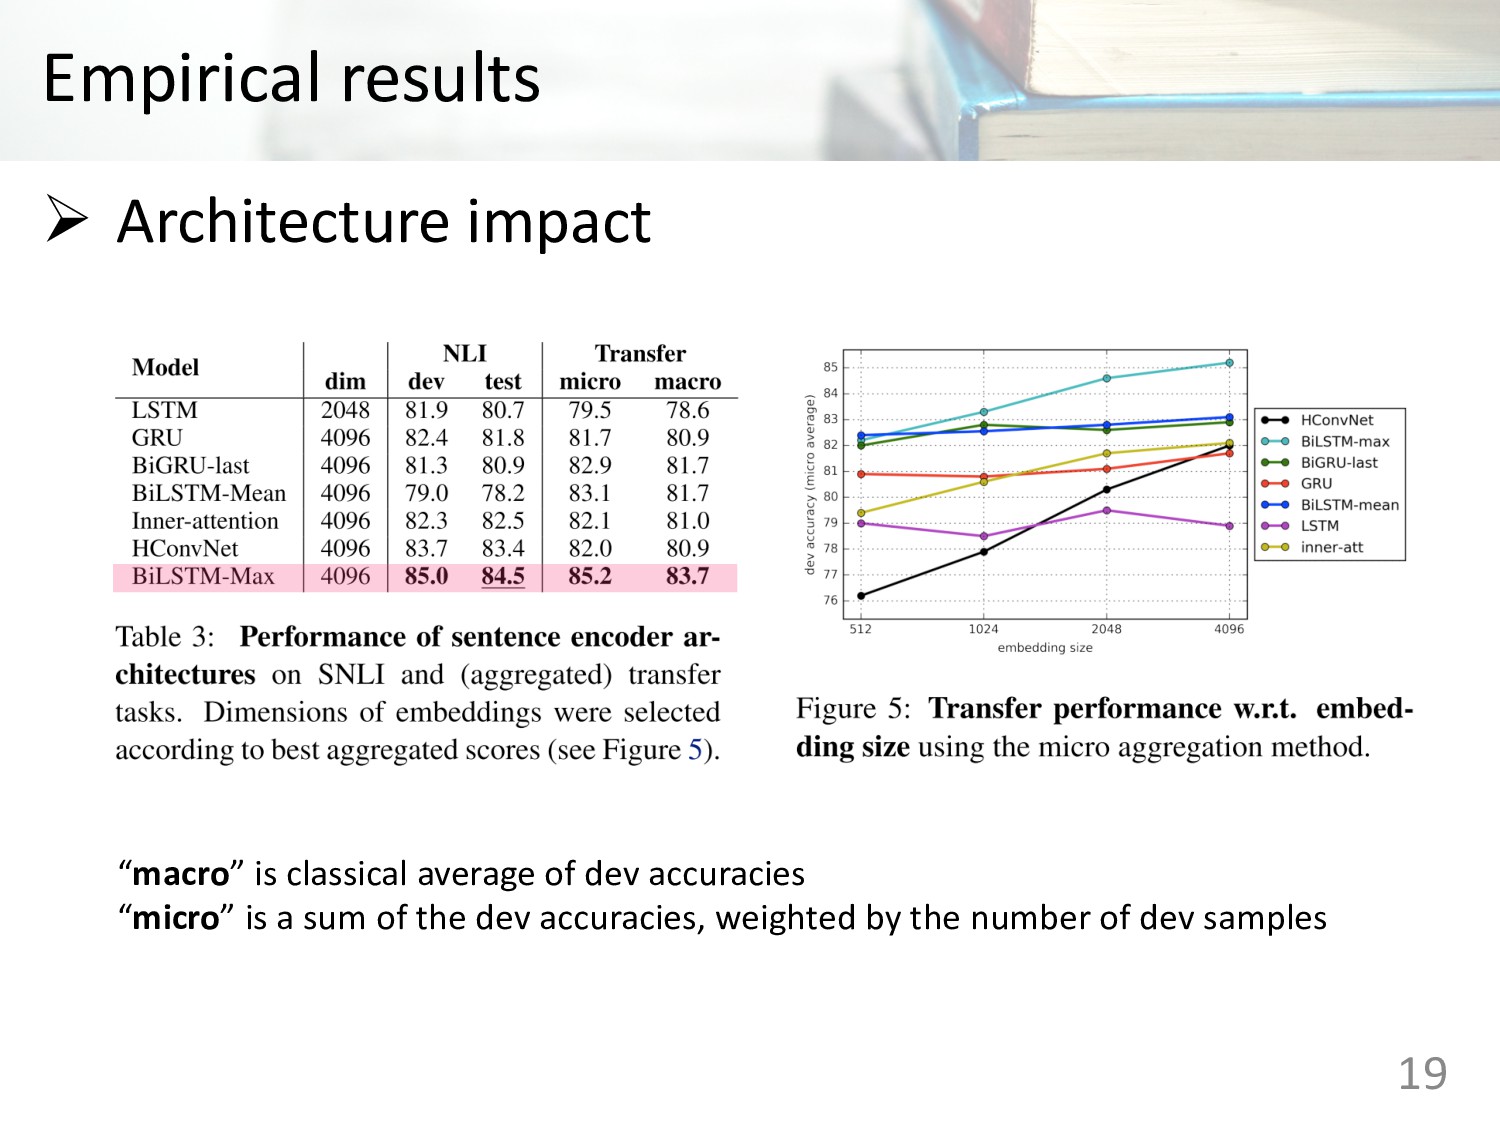
Empirical results Ø Architecture impact 19 “macro” is classical average
of dev accuracies “micro” is a sum of the dev accuracies, weighted by the number of dev samples -
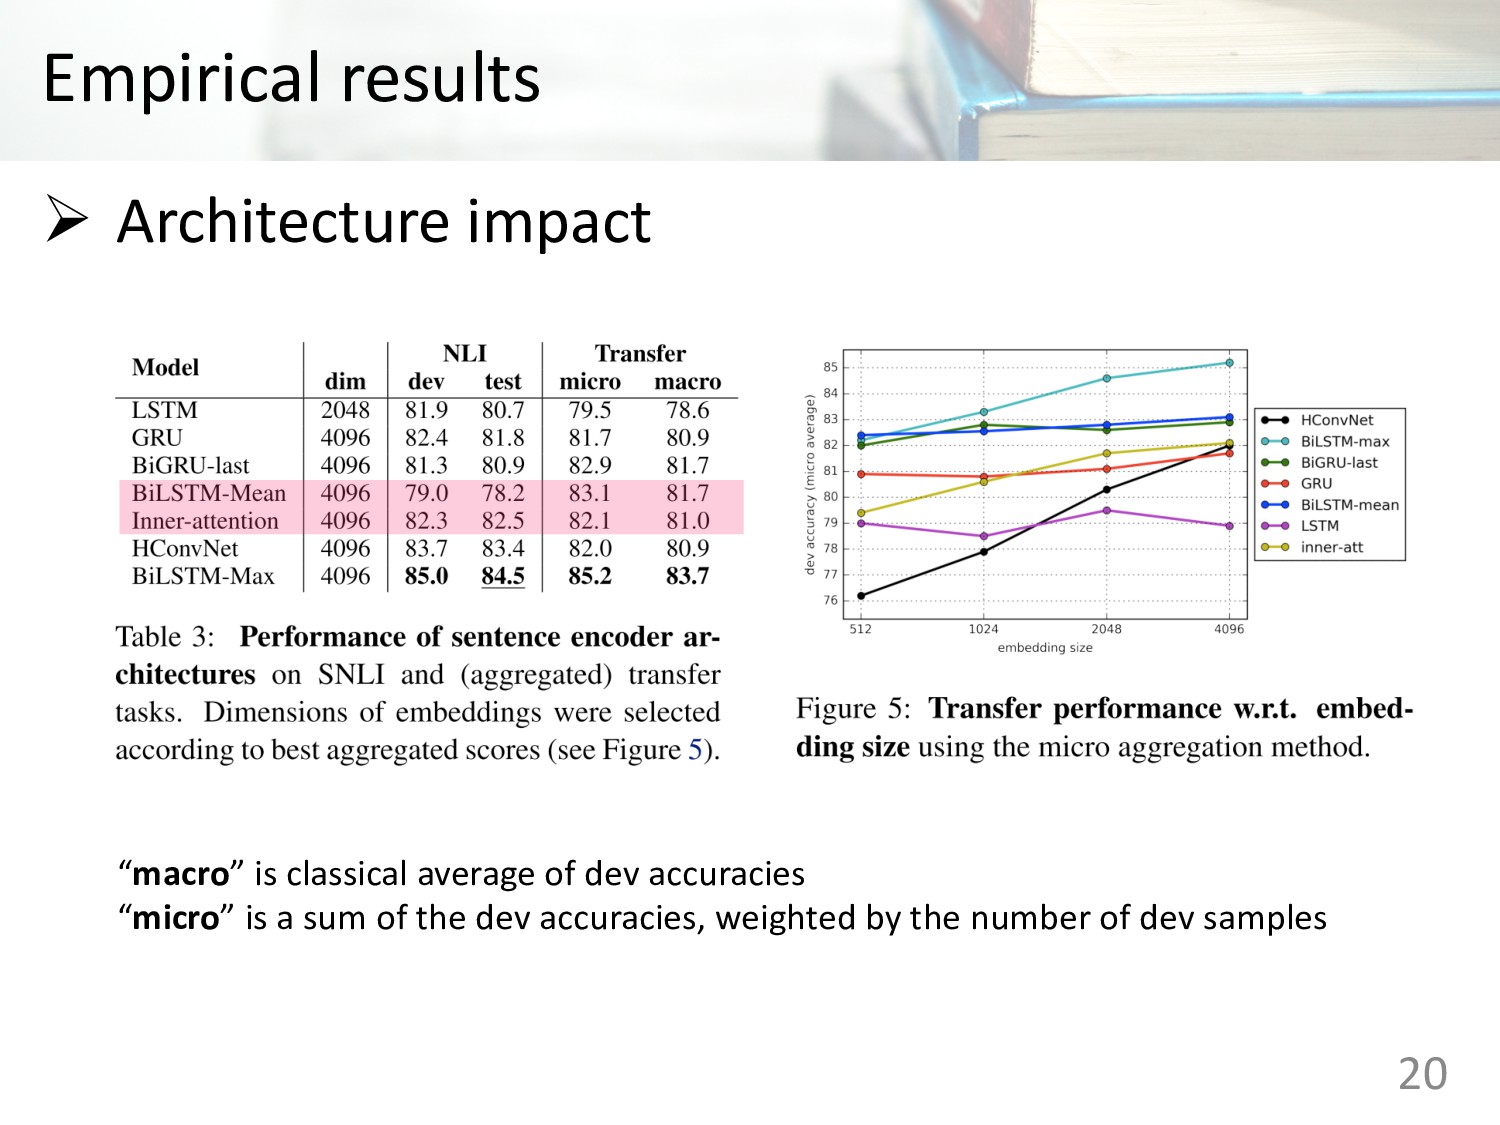
Empirical results Ø Architecture impact 20 “macro” is classical average
of dev accuracies “micro” is a sum of the dev accuracies, weighted by the number of dev samples -
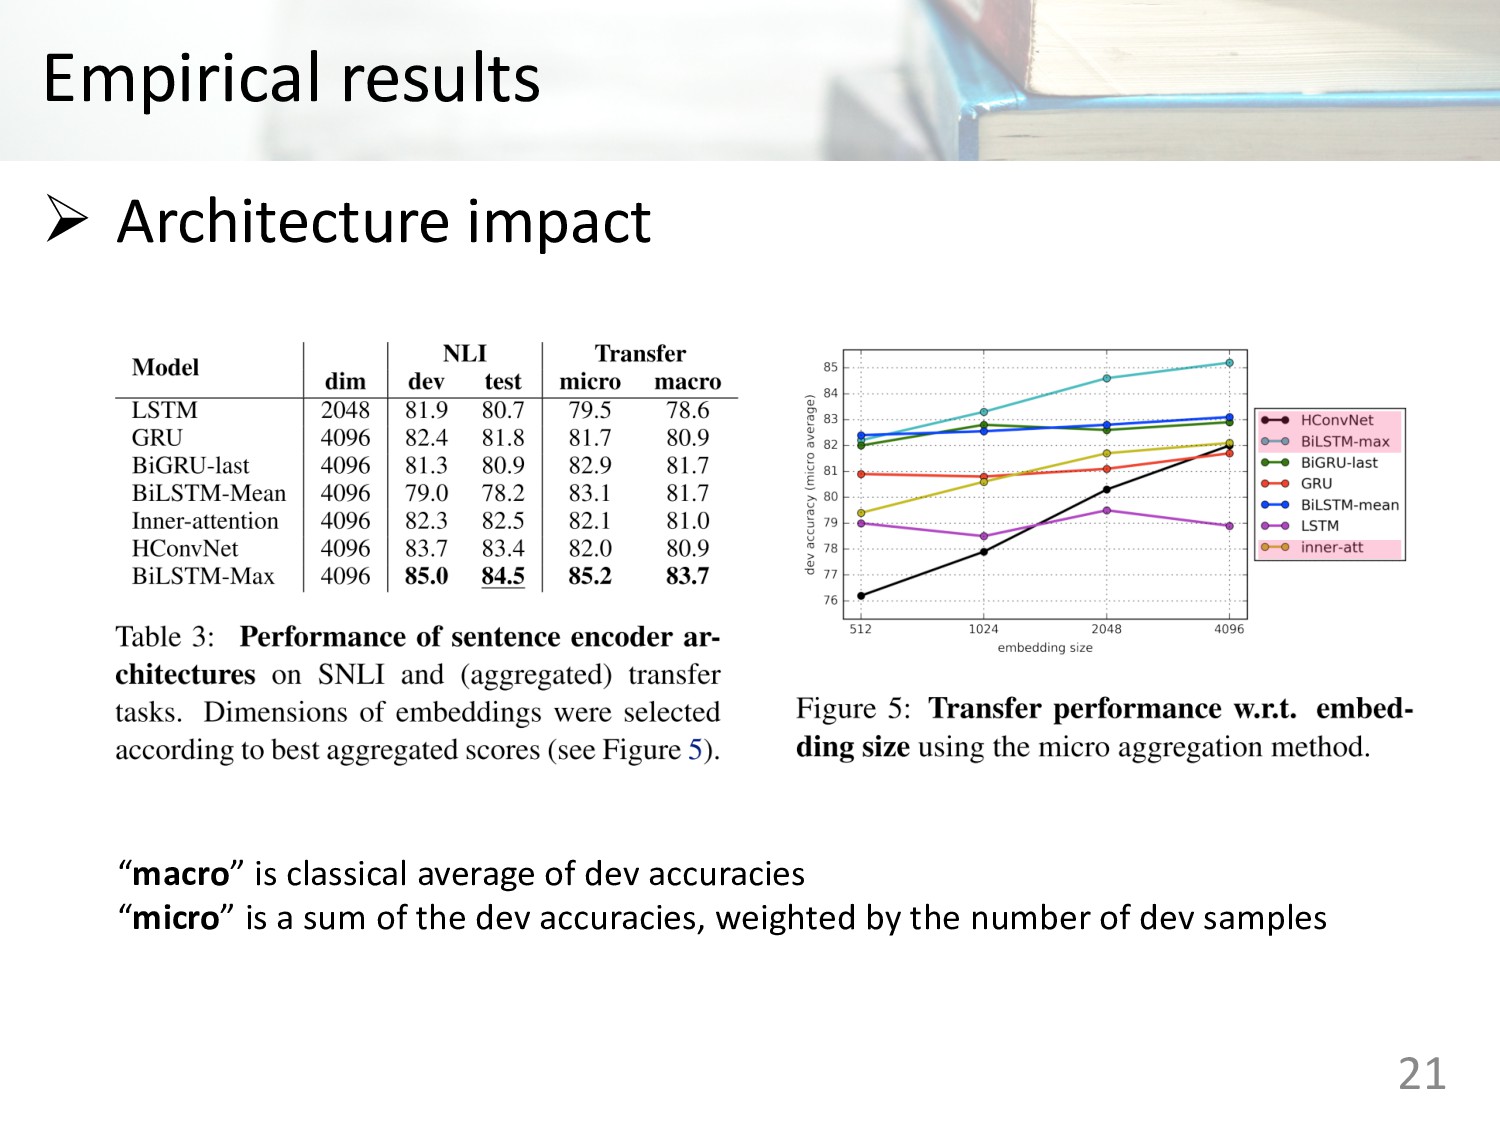
Empirical results Ø Architecture impact 21 “macro” is classical average
of dev accuracies “micro” is a sum of the dev accuracies, weighted by the number of dev samples -
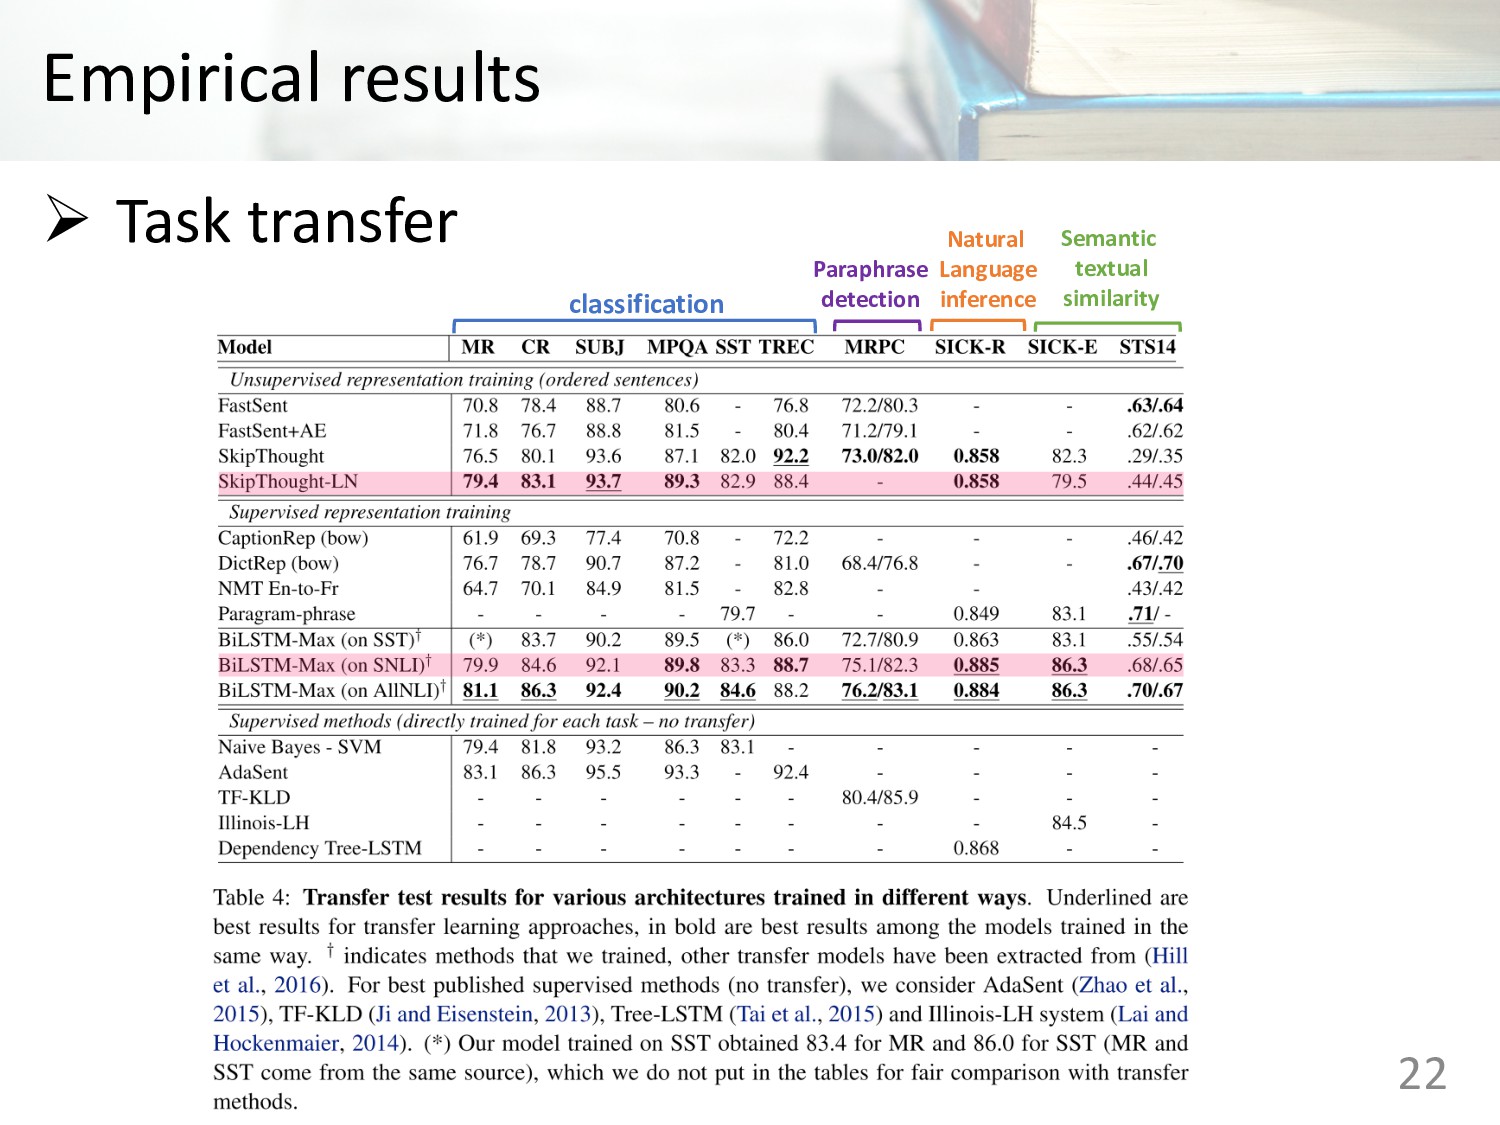
Empirical results Ø Task transfer 22 classification Paraphrase detection Semantic
textual similarity Natural Language inference -
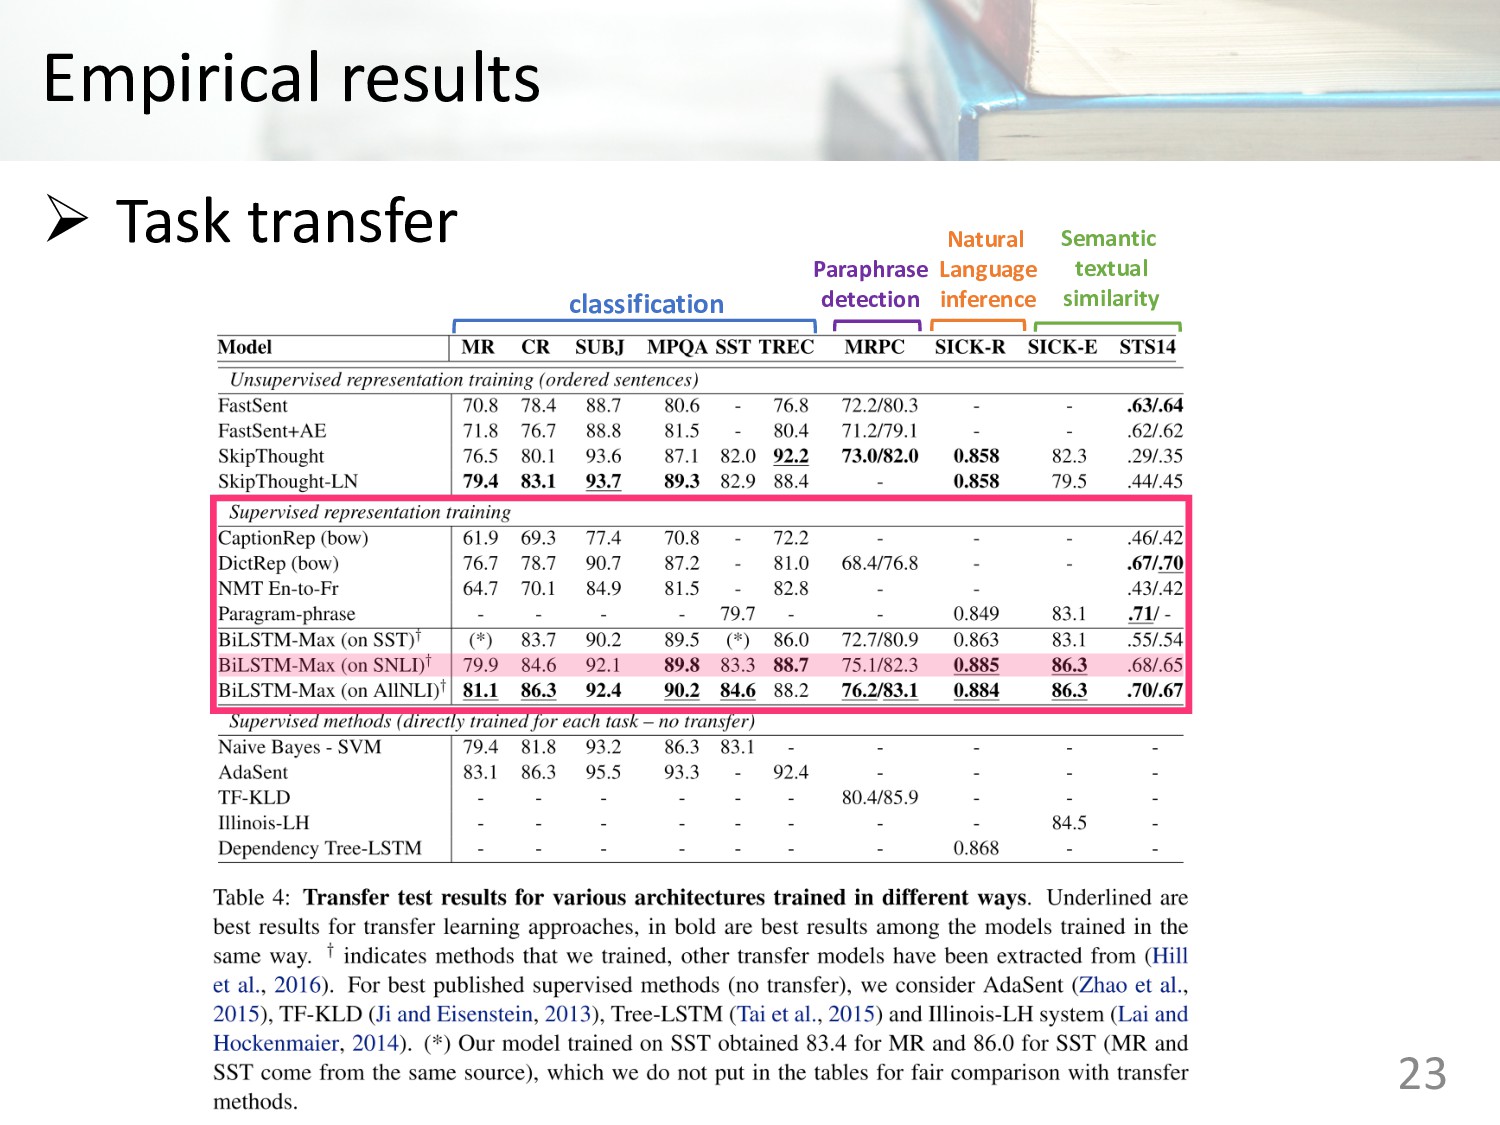
Empirical results Ø Task transfer 23 classification Paraphrase detection Semantic
textual similarity Natural Language inference -
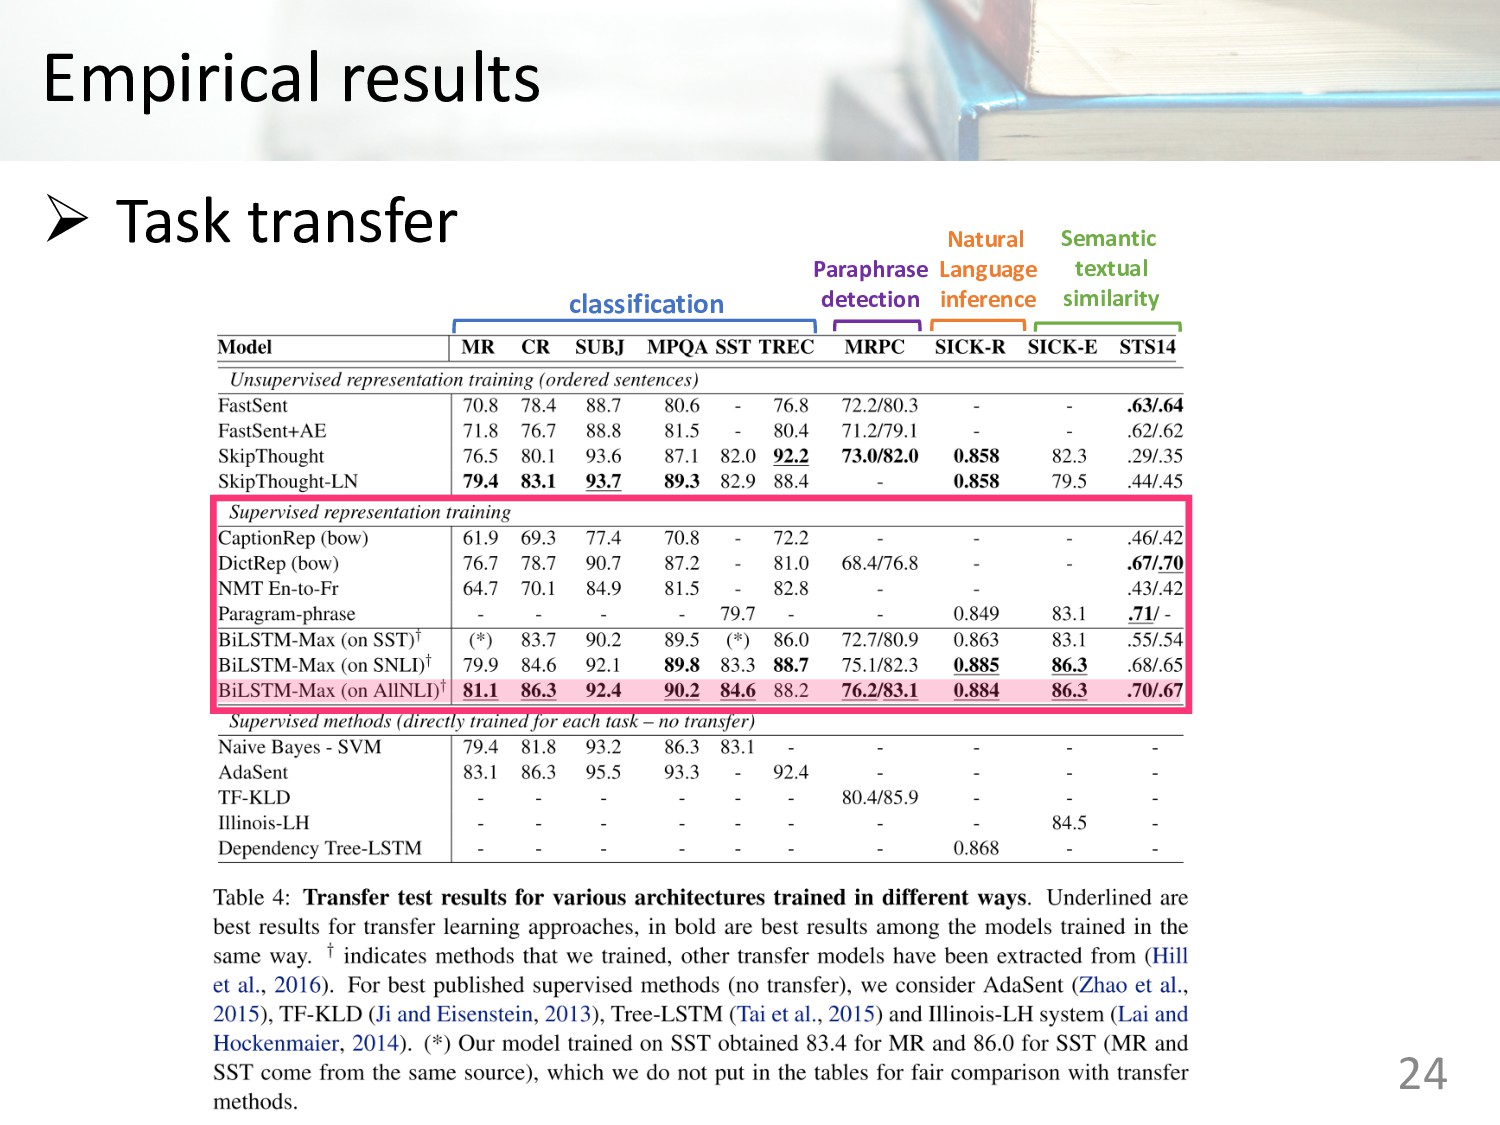
Empirical results Ø Task transfer 24 classification Paraphrase detection Semantic
textual similarity Natural Language inference -
Conclusion Ø This paper proposed universal sentence representations trained using
the supervised data Ø Sentence embeddings with supervised data were tested on 12 different transfer tasks Ø BiLSTM network with max pooling makes the best current universal sentence encoding methods 25