Share
Embed
Reading: A Cooperative Para-virtualized Scheduling Framework for Manycore Machines

wkb8s
June 04, 2024
Transcript
24 slides
-
CPS: A Cooperative Para-virtualized Scheduling Framework for Manycore Machines Yuxuan
Liu1, Tianqiang Xu1, Zeyu Mi1,2, Zhichao Hua1,2, Binyu Zang1,2, Haibo Chen1,2 (1Institute of Parallel and Distributed Systems, SEIEE, Shanghai Jiao Tong University, 2Engineering Research Center for Domain-specific Operating Systems Ministry of Education) Keio University Kono Laboratory, Daiki Wakabayashi ASPLOS ’23 -
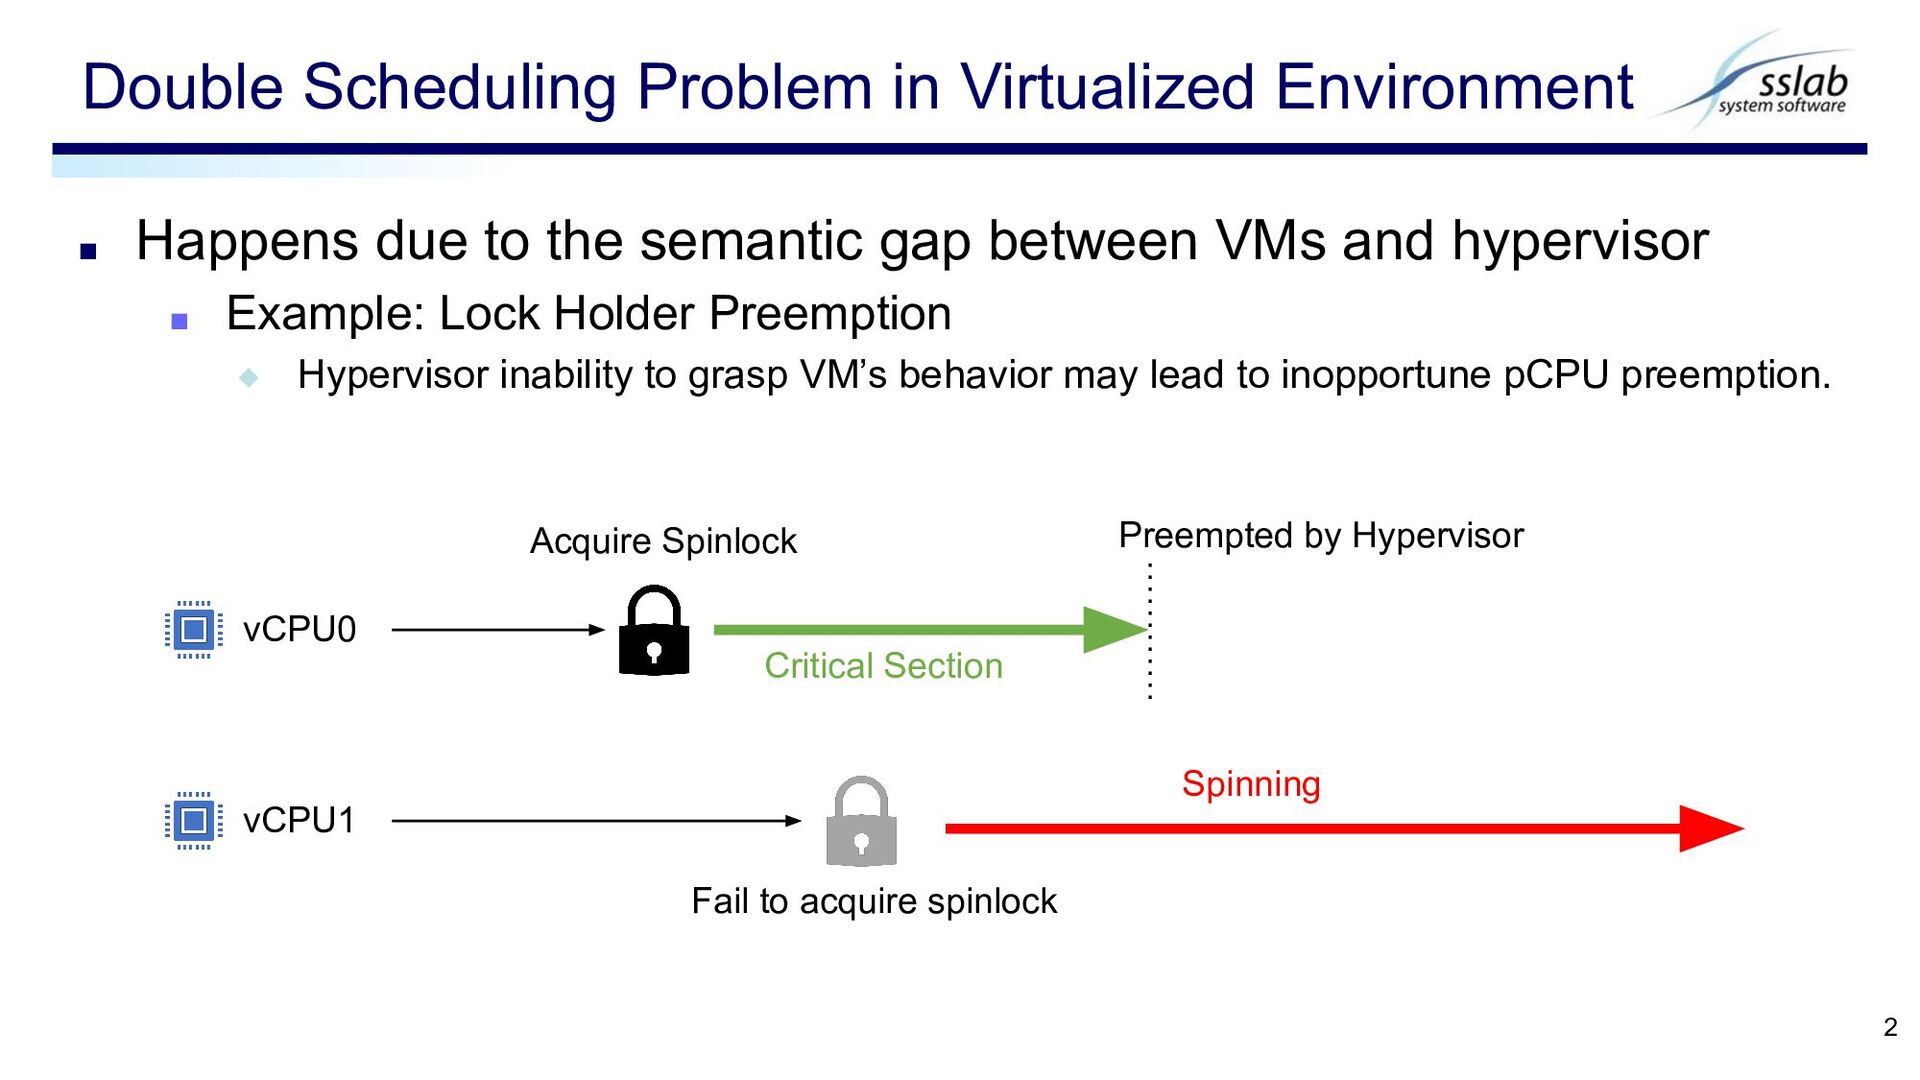
▪ Happens due to the semantic gap between VMs and
hypervisor ▪ Example: Lock Holder Preemption ◆ Hypervisor inability to grasp VM’s behavior may lead to inopportune pCPU preemption. Double Scheduling Problem in Virtualized Environment 2 vCPU0 vCPU1 Acquire Spinlock Preempted by Hypervisor Critical Section Fail to acquire spinlock Spinning -
▪ Mitigating Excessive VCPU Spinning in VM-Agnostic KVM [Ishiguro+, VEE
’21] ▪ Utilize Intel’s Pause Loop Exiting to detect vCPUs that keep busy waiting ▪ Difficult to pinpoint the lockholder due to the semantic gap ▪ eCS [Kashyap+, USENIX ATC ’18] ▪ Let the guest to annotate critical sections in which hypervisor will not schedule out the vCPU ▪ Only resolve the locking related issues ▪ VScale [Luwei+, Eurosys ’16] ▪ Employ gang scheduling and simultaneously schedule all vCPUs of a VM ▪ Can lead to significant CPU fragmentation Prior Efforts 3 -
▪ Problem that result in suboptimal decisions made by guest
kernels due to the absence of hypervisor-internal information on the following ▪ pCPU load ▪ pCPU runtime ▪ etc. ▪ ≠ locking based problems ▪ Locking based problems are on the hypervisor’s perspective. Runtime Hypervisor-internal States (RHS) Problem 4 -
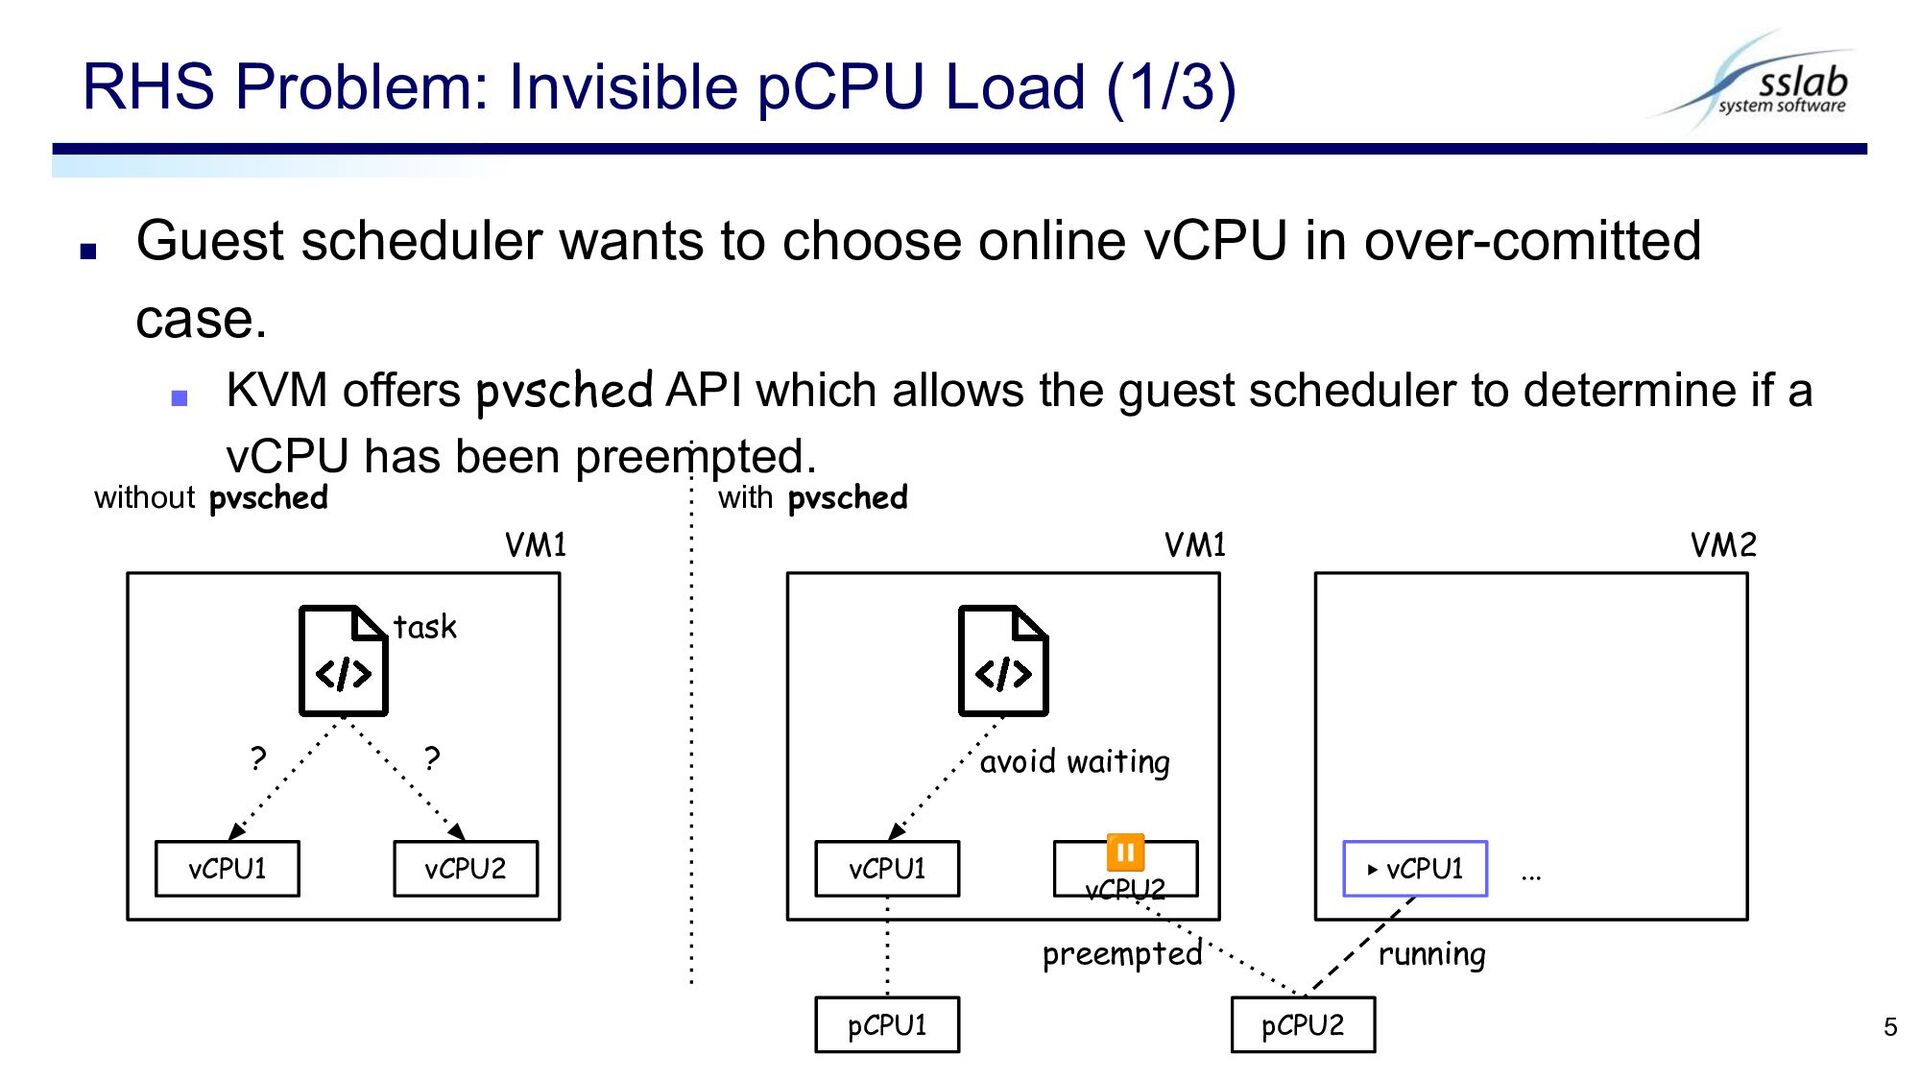
▪ Guest scheduler wants to choose online vCPU in over-comitted
case. ▪ KVM offers pvsched API which allows the guest scheduler to determine if a vCPU has been preempted. RHS Problem: Invisible pCPU Load (1/3) 5 vCPU1 vCPU2 VM1 ? ? without pvsched with pvsched pCPU1 pCPU2 VM1 ▶ vCPU1 ... VM2 vCPU1 ⏸ vCPU2 running preempted avoid waiting task -
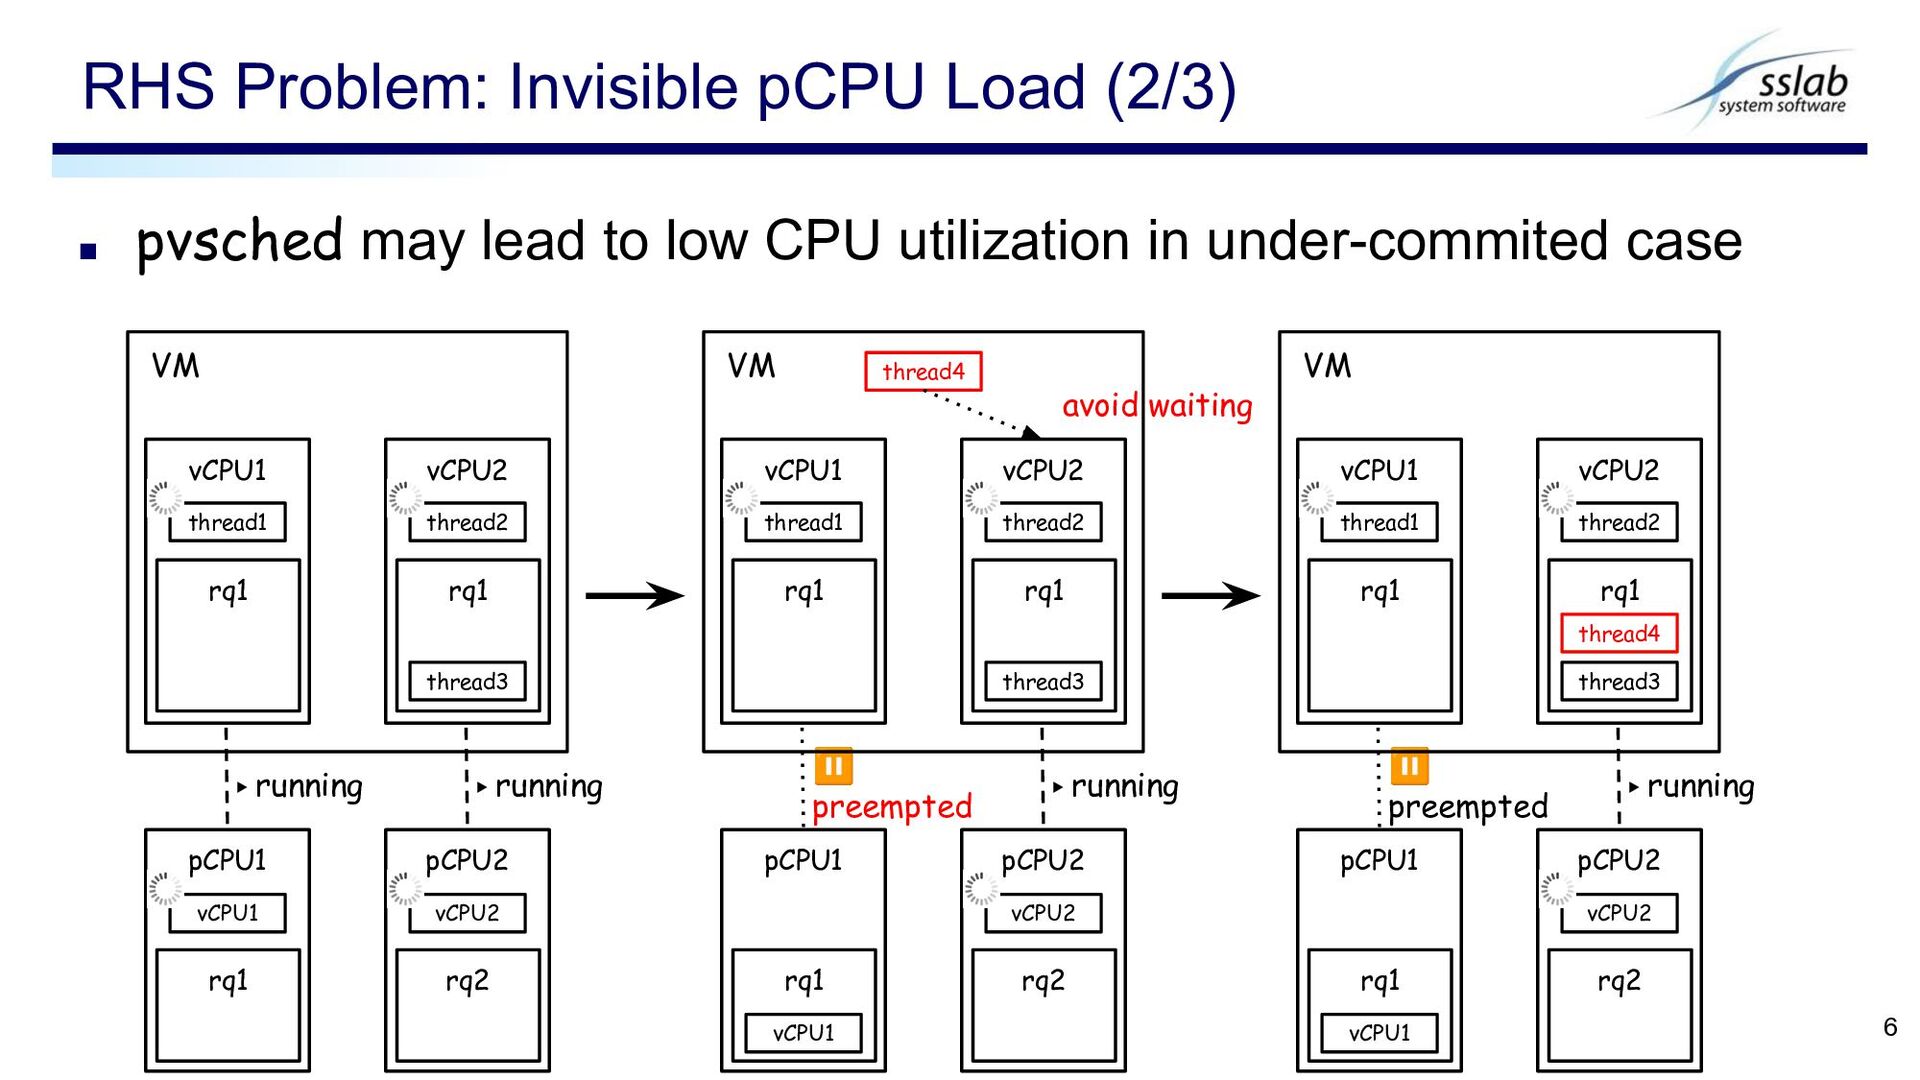
▪ pvsched may lead to low CPU utilization in under-commited
case RHS Problem: Invisible pCPU Load (2/3) 6 ▶ running ▶ running ▶ running ⏸ preempted ▶ running ⏸ preempted thread4 VM avoid waiting pCPU1 rq1 vCPU1 pCPU2 rq2 vCPU2 pCPU1 rq1 vCPU1 pCPU2 rq2 vCPU2 pCPU1 rq1 vCPU1 pCPU2 rq2 vCPU2 vCPU1 rq1 thread1 vCPU2 rq1 thread2 thread3 VM vCPU1 rq1 thread1 vCPU2 rq1 thread2 thread3 VM vCPU1 rq1 thread1 vCPU2 rq1 thread2 thread3 thread4 -
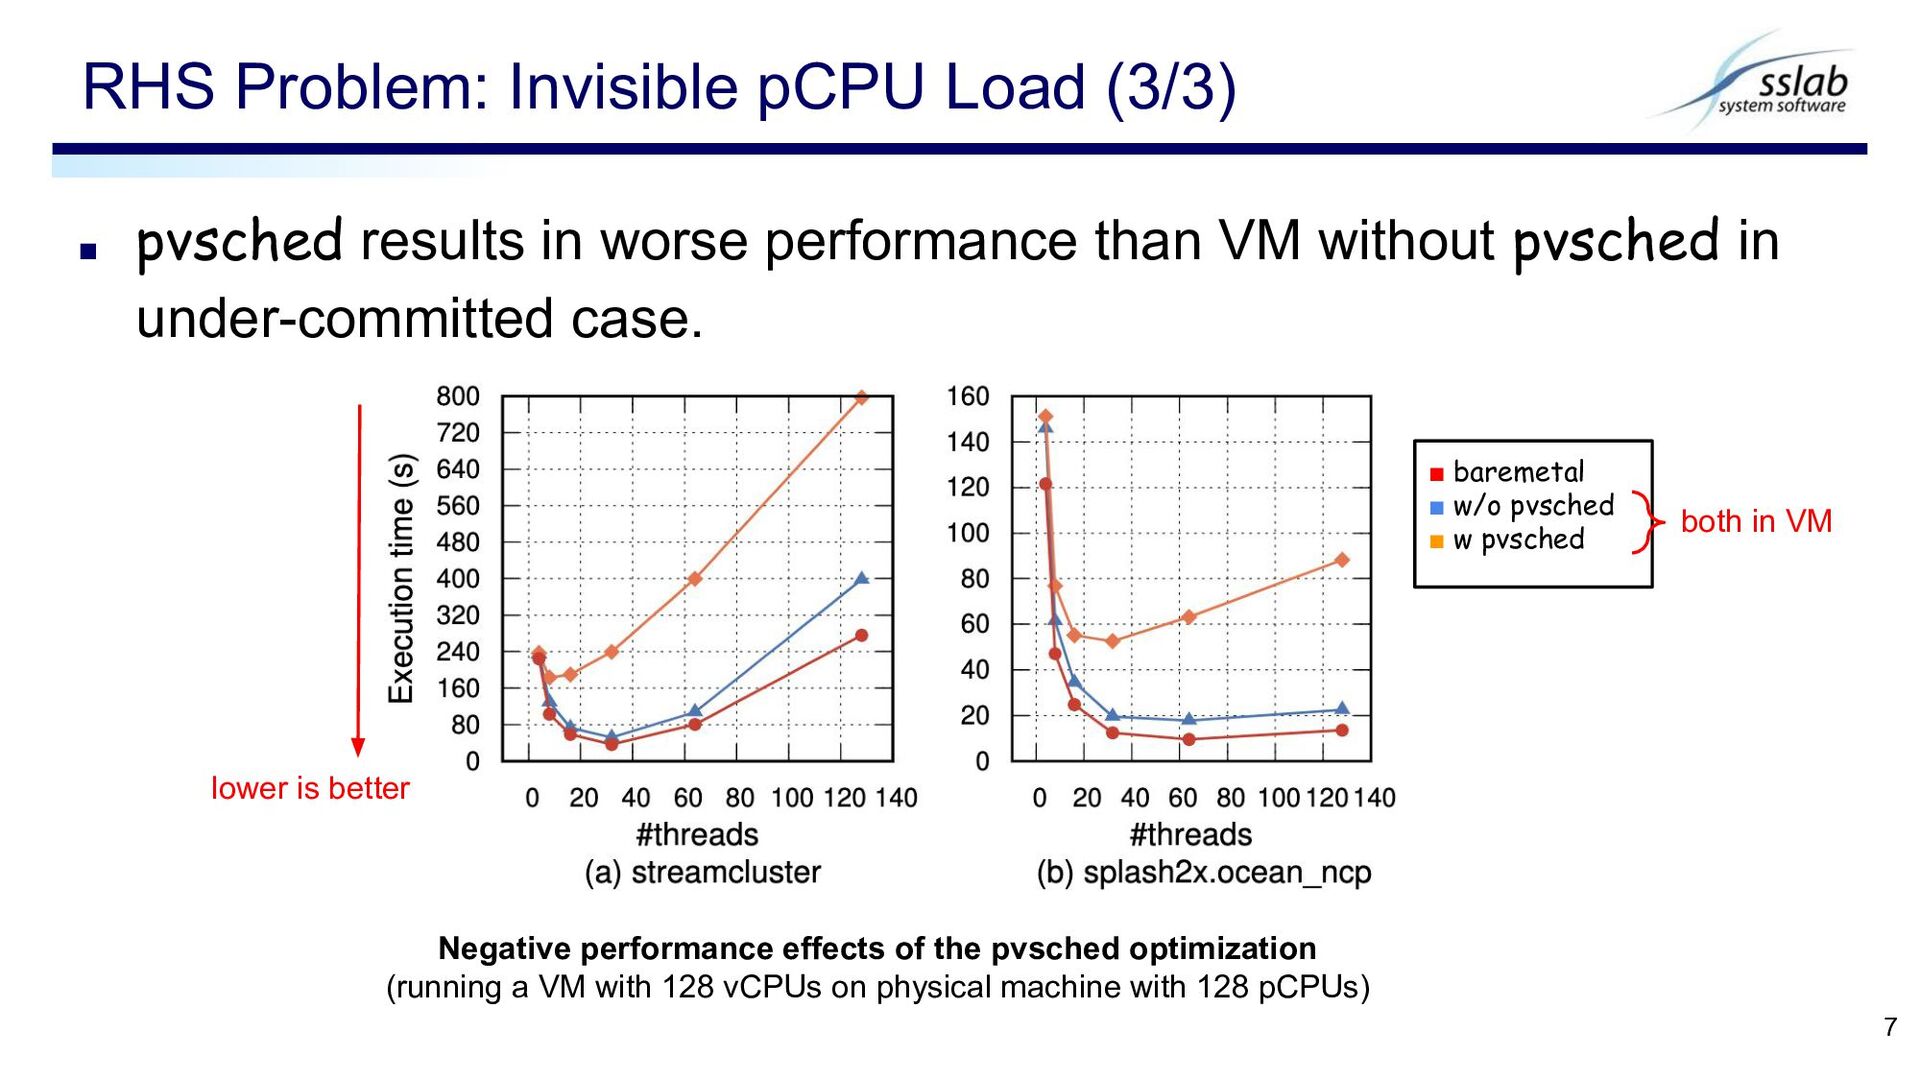
▪ pvsched results in worse performance than VM without pvsched
in under-committed case. RHS Problem: Invisible pCPU Load (3/3) 7 ▪ baremetal ▪ w/o pvsched ▪ w pvsched both in VM lower is better Negative performance effects of the pvsched optimization (running a VM with 128 vCPUs on physical machine with 128 pCPUs) -
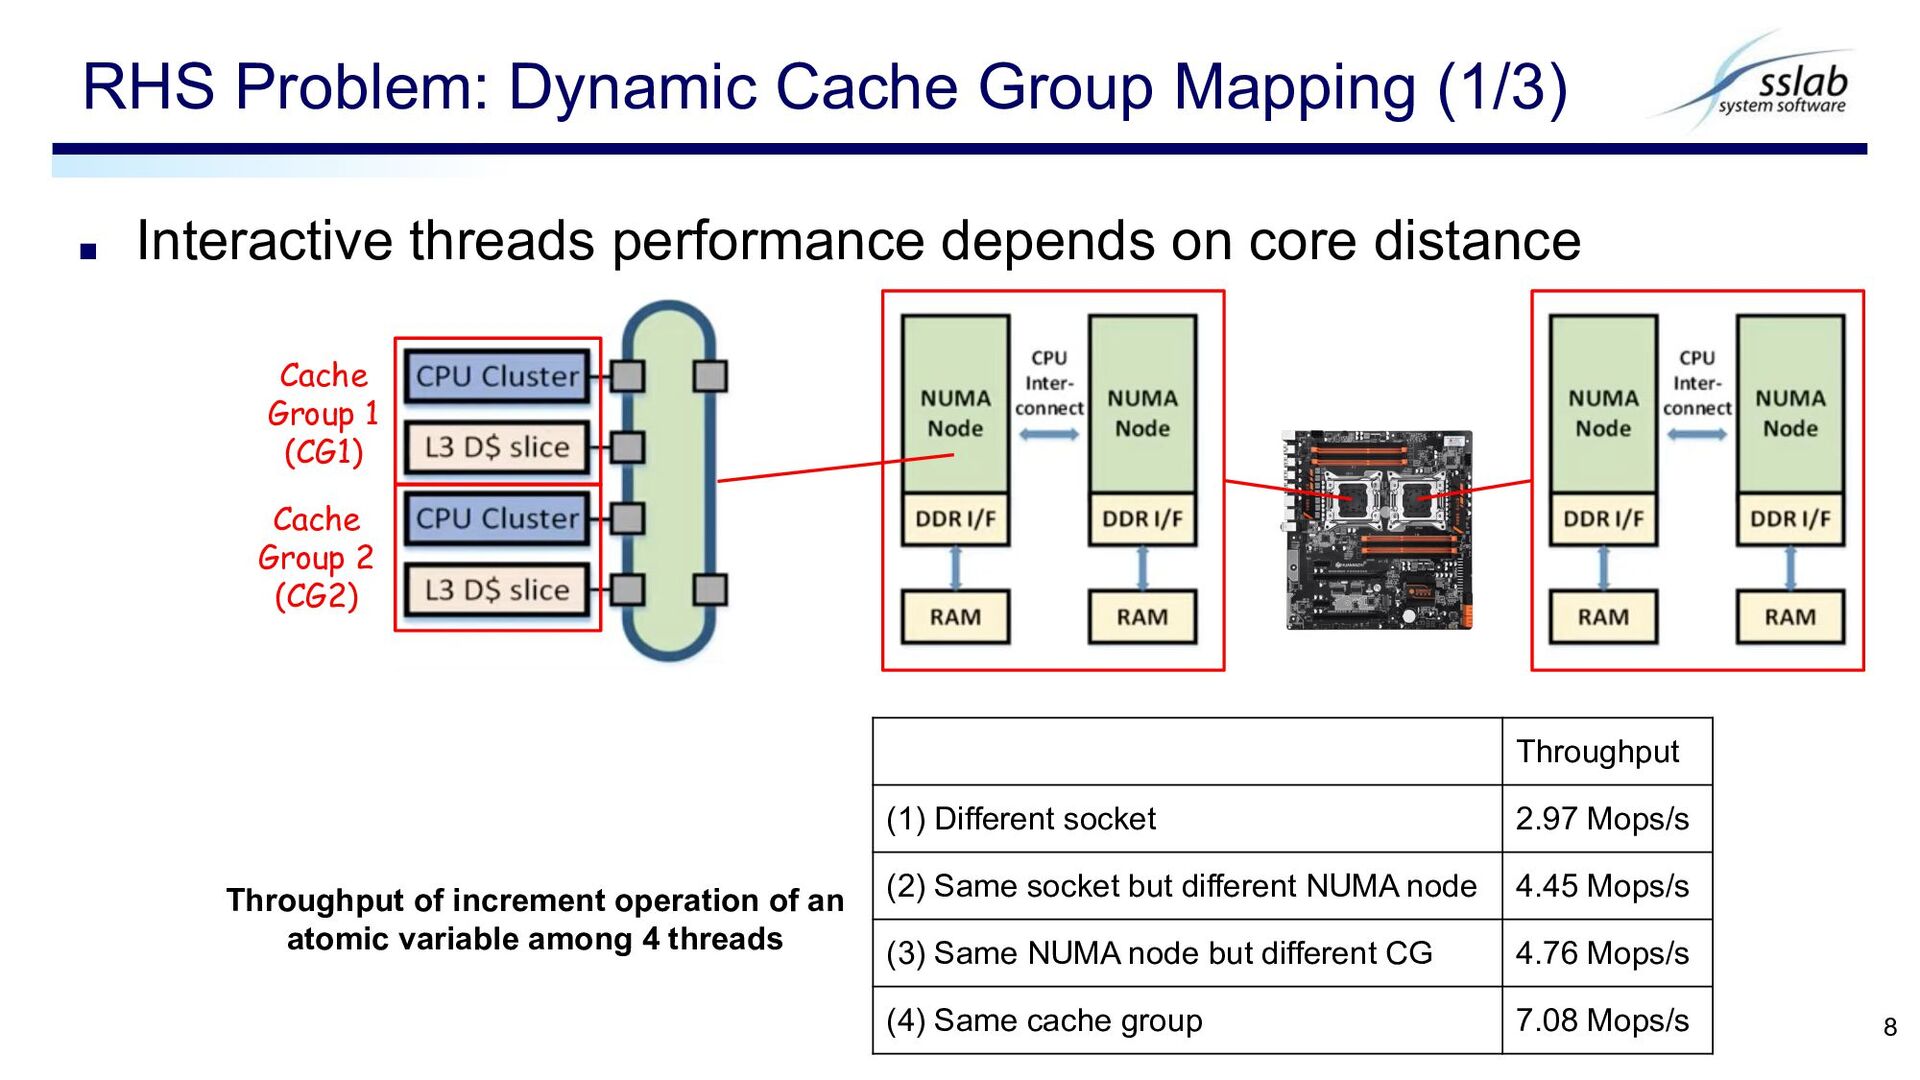
▪ Interactive threads performance depends on core distance RHS Problem:
Dynamic Cache Group Mapping (1/3) 8 Cache Group 1 (CG1) Cache Group 2 (CG2) Throughput (1) Different socket 2.97 Mops/s (2) Same socket but different NUMA node 4.45 Mops/s (3) Same NUMA node but different CG 4.76 Mops/s (4) Same cache group 7.08 Mops/s Throughput of increment operation of an atomic variable among 4 threads -
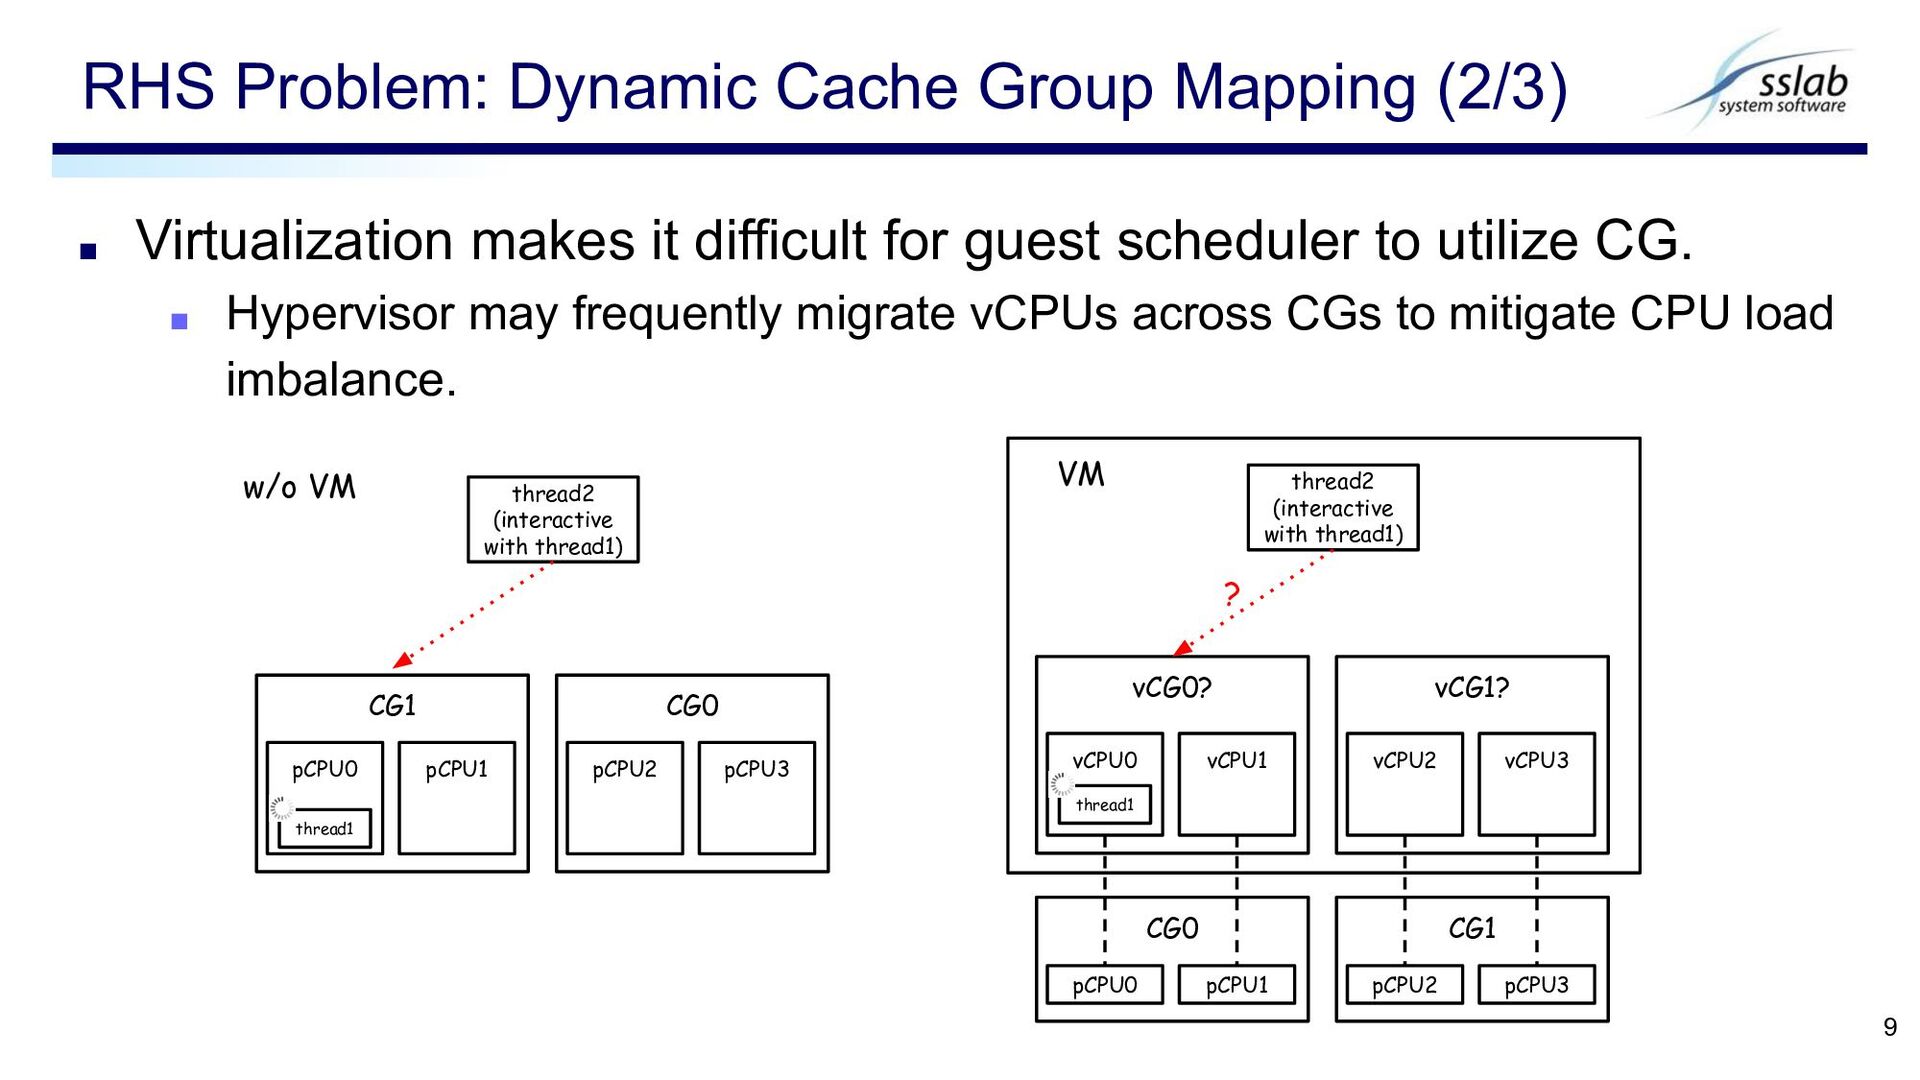
▪ Virtualization makes it difficult for guest scheduler to utilize
CG. ▪ Hypervisor may frequently migrate vCPUs across CGs to mitigate CPU load imbalance. RHS Problem: Dynamic Cache Group Mapping (2/3) 9 w/o VM CG1 pCPU0 pCPU1 thread2 (interactive with thread1) CG0 pCPU2 pCPU3 thread1 VM CG0 pCPU0 pCPU1 vCG0? vCPU0 vCPU1 thread2 (interactive with thread1) CG1 pCPU2 pCPU3 vCG1? vCPU2 vCPU3 thread1 ? -
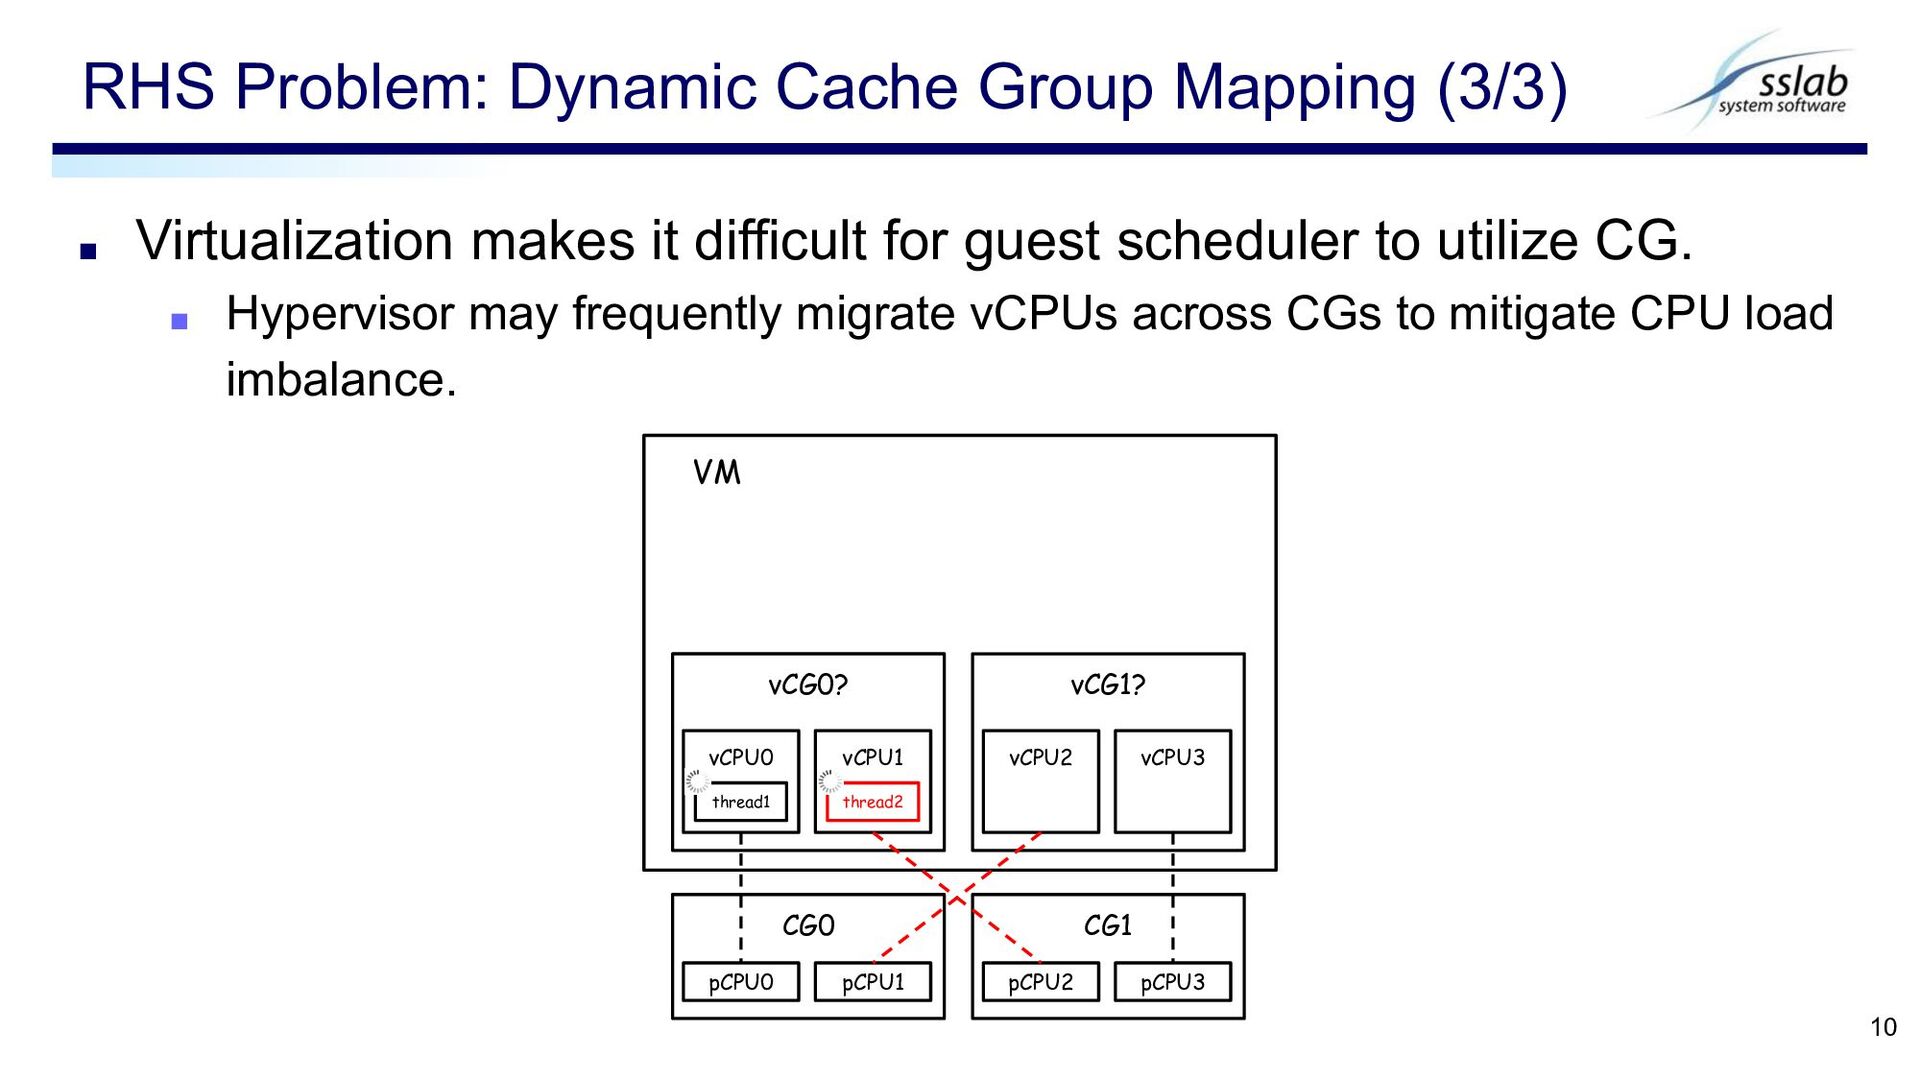
▪ Virtualization makes it difficult for guest scheduler to utilize
CG. ▪ Hypervisor may frequently migrate vCPUs across CGs to mitigate CPU load imbalance. RHS Problem: Dynamic Cache Group Mapping (3/3) 10 VM CG0 pCPU0 pCPU1 vCG0? vCPU0 vCPU1 CG1 pCPU2 pCPU3 vCG1? vCPU2 vCPU3 thread1 thread2 -
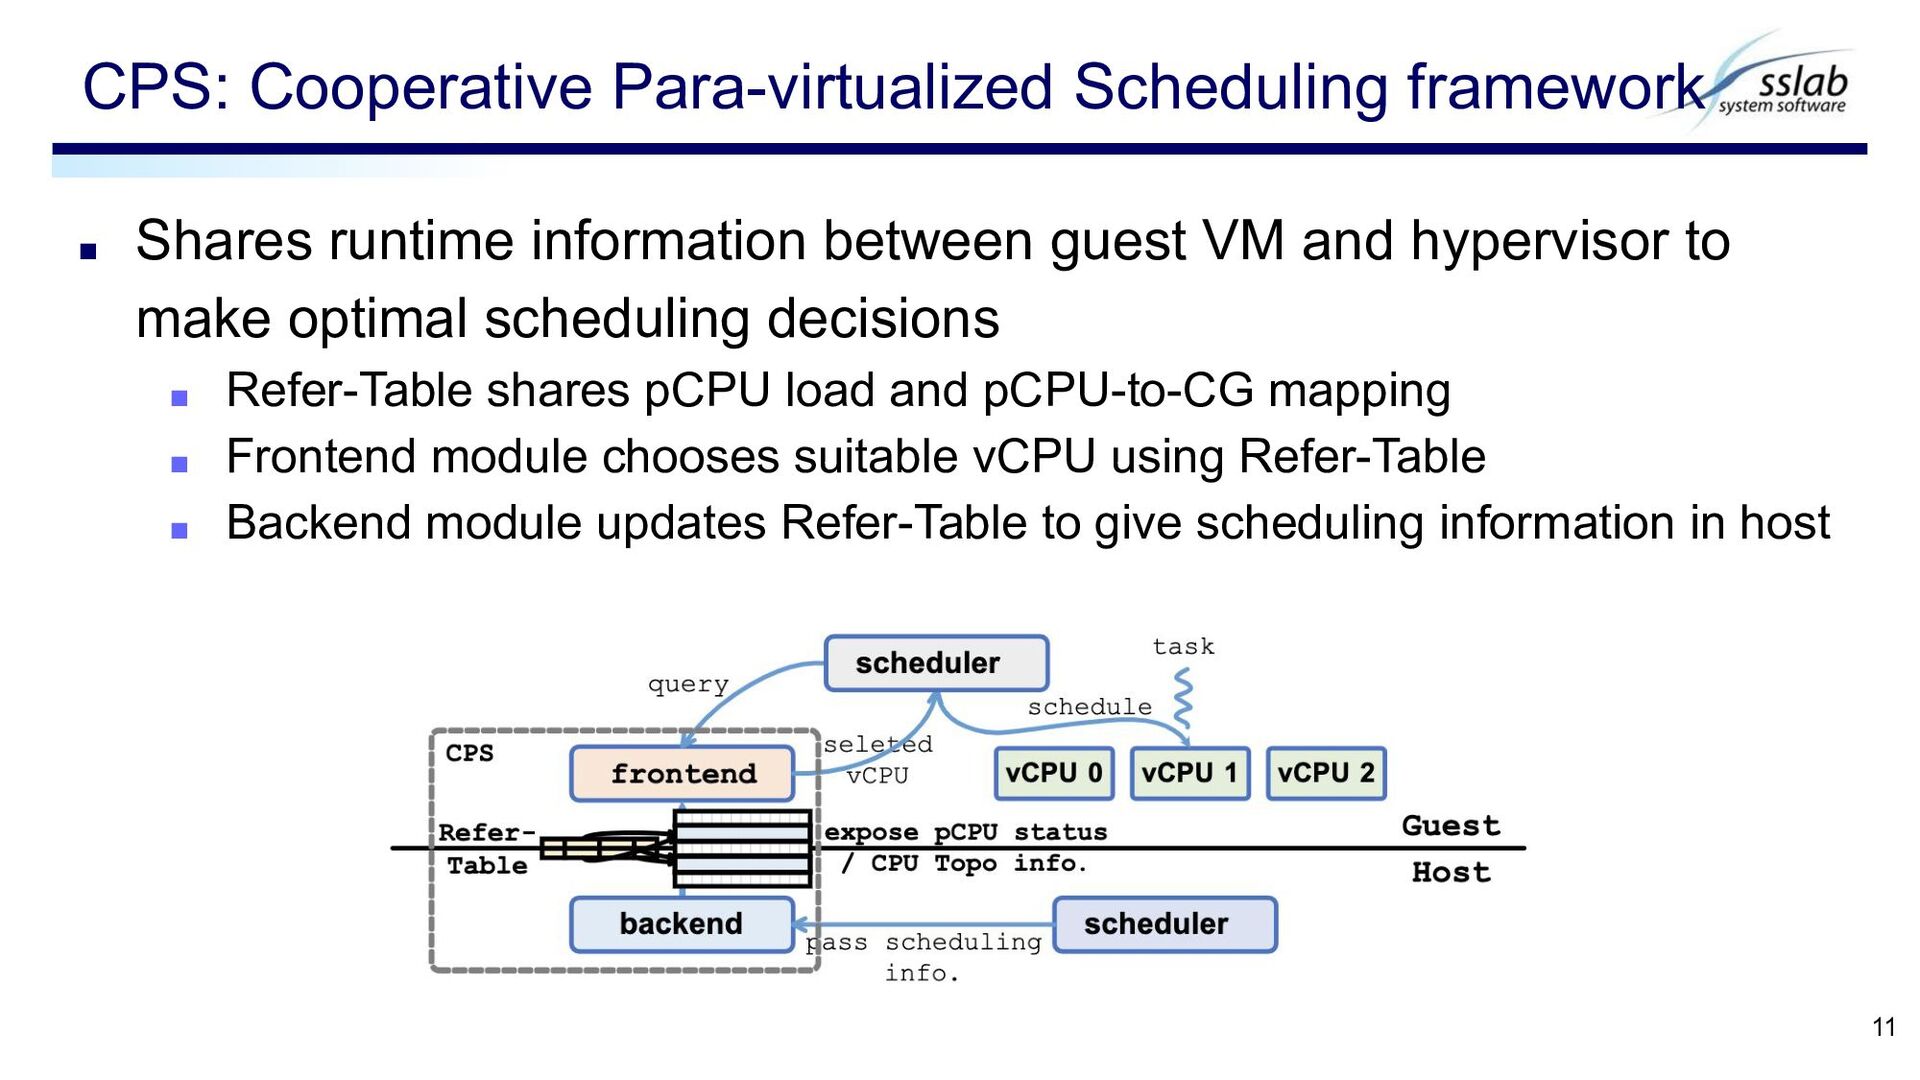
▪ Shares runtime information between guest VM and hypervisor to
make optimal scheduling decisions ▪ Refer-Table shares pCPU load and pCPU-to-CG mapping ▪ Frontend module chooses suitable vCPU using Refer-Table ▪ Backend module updates Refer-Table to give scheduling information in host 11 CPS: Cooperative Para-virtualized Scheduling framework -
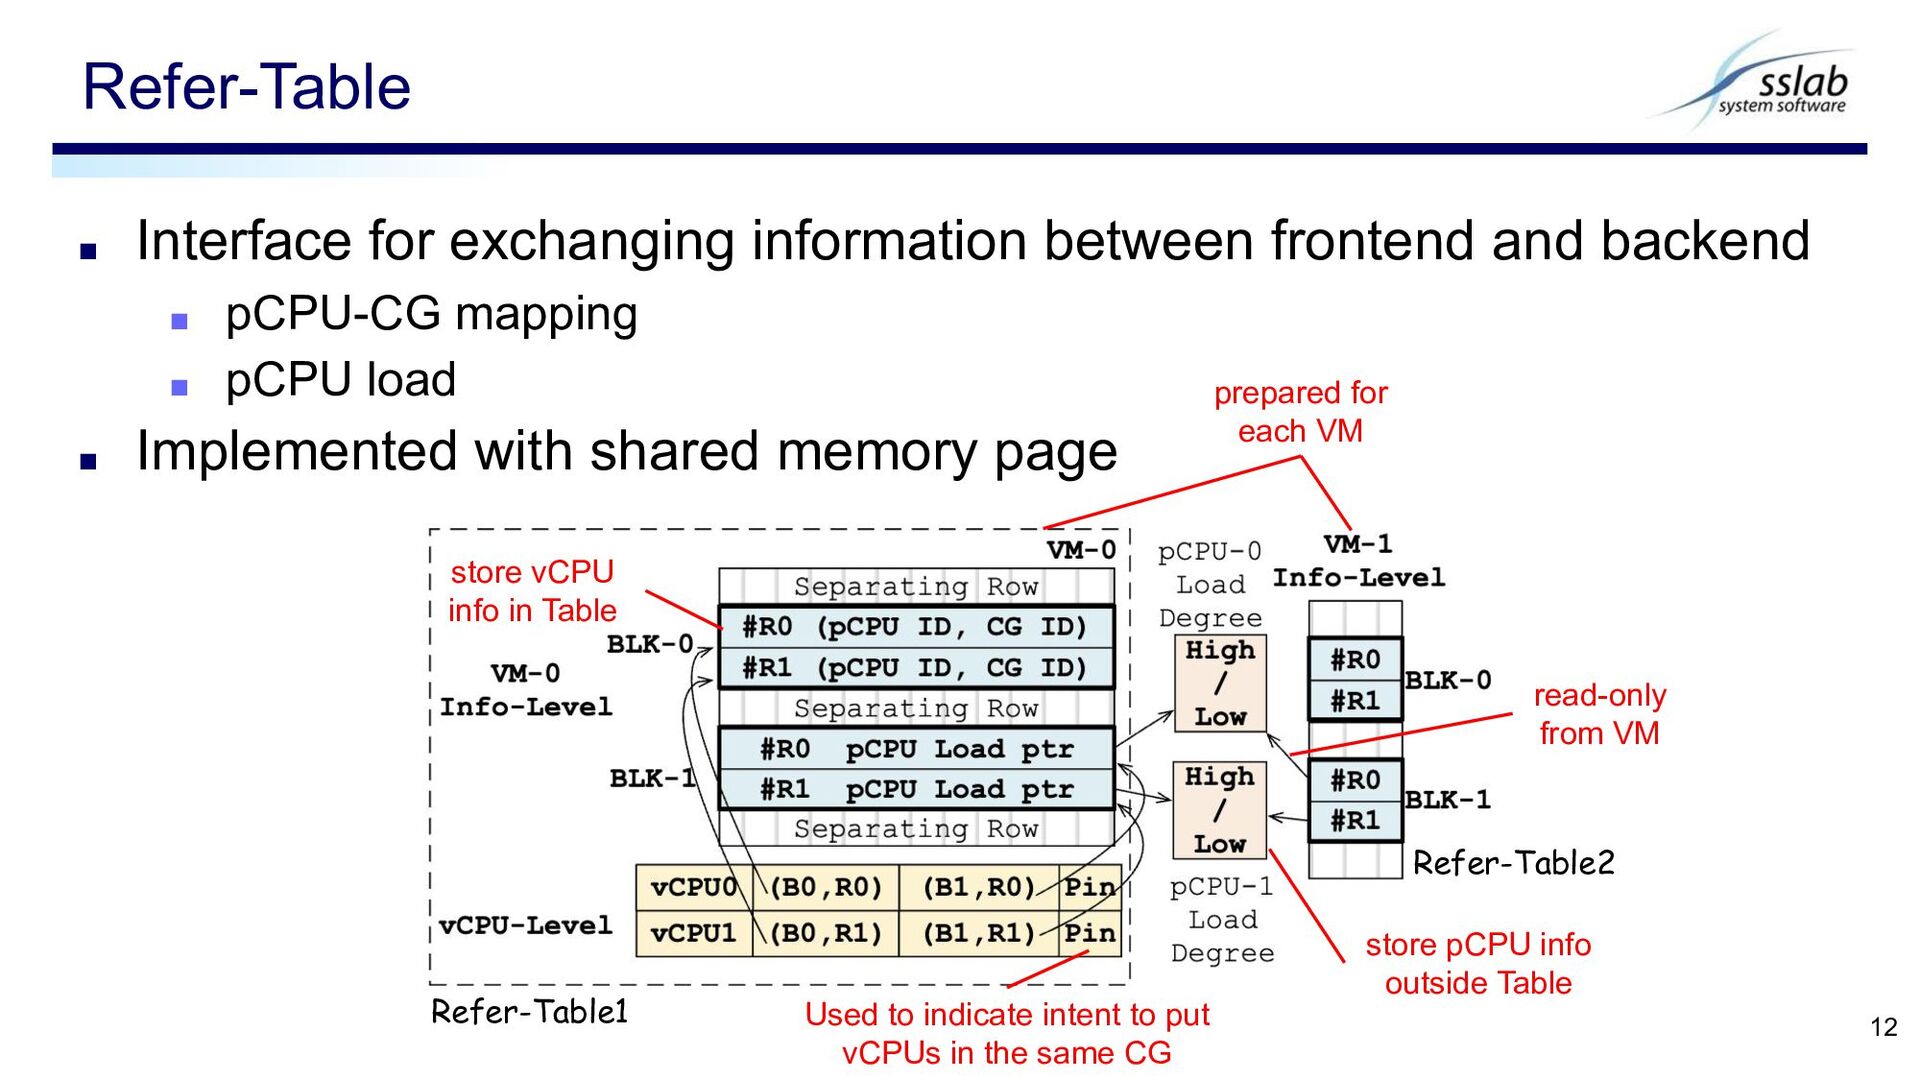
▪ Interface for exchanging information between frontend and backend ▪
pCPU-CG mapping ▪ pCPU load ▪ Implemented with shared memory page Refer-Table 12 prepared for each VM store vCPU info in Table store pCPU info outside Table read-only from VM Used to indicate intent to put vCPUs in the same CG Refer-Table1 Refer-Table2 -
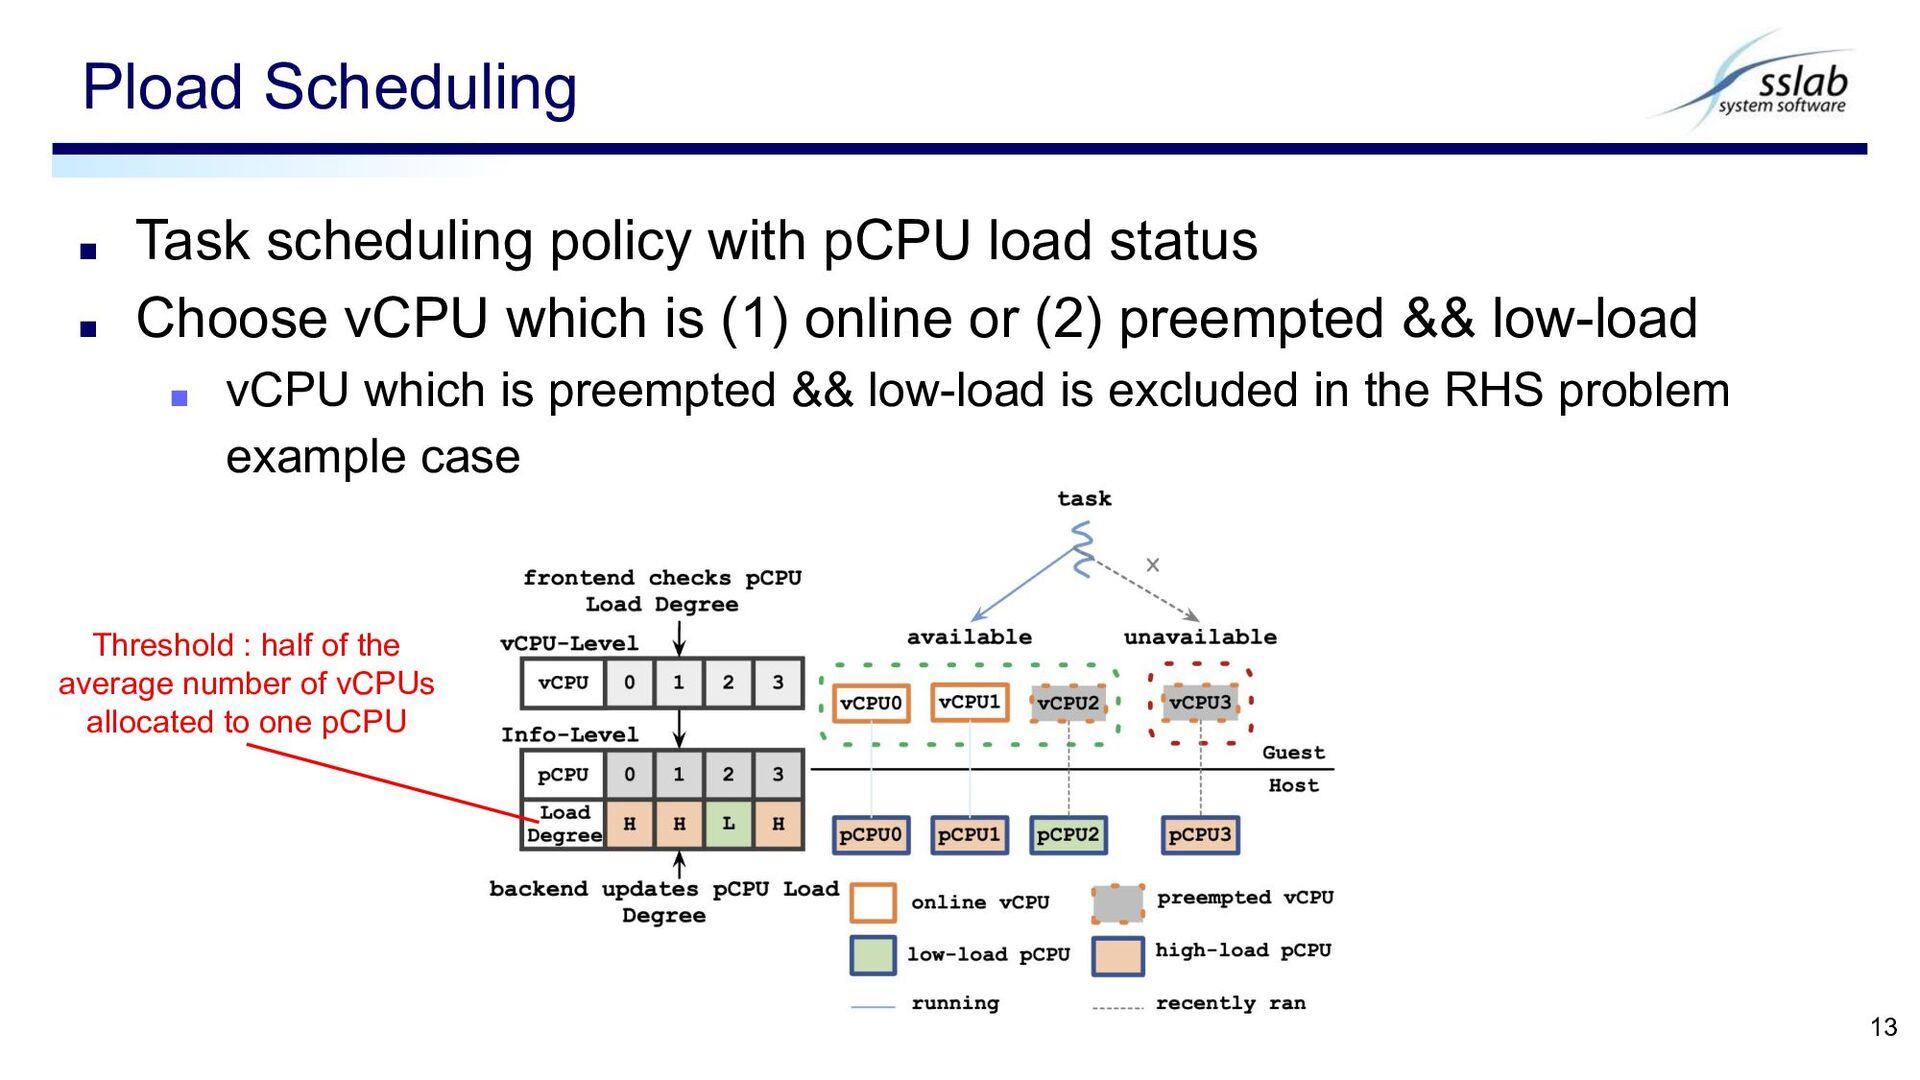
Pload Scheduling 13 ▪ Task scheduling policy with pCPU load
status ▪ Choose vCPU which is (1) online or (2) preempted && low-load ▪ vCPU which is preempted && low-load is excluded in the RHS problem example case Threshold : half of the average number of vCPUs allocated to one pCPU -
▪ Method to group interactive threads into same CG ▪
If vCPU is migrated, CPS interrupt guest to update Refer-Table and other internal objects. CG-aware Scheduling (1/5) 14 VM1 CG0 pCPU0 pCPU1 vCG0 vCPU0 vCPU1 thread2 (interactive with thread1) CG1 pCPU2 pCPU3 vCG1 vCPU2 vCPU3 thread1 ? ? CPS Refer-Table1 vCPU0: pCPU0, CG0 vCPU1: pCPU1, CG0 vCPU2: pCPU2, CG1 vCPU3: pCPU3, CG1 Thread count of interactive group1 vCG0: 1 vCG1: 0 CPS doesn’t have vCG mapping like… vCG0 {vCPU0, vCPU1} vCG1 {vCPU2, vCPU3} -
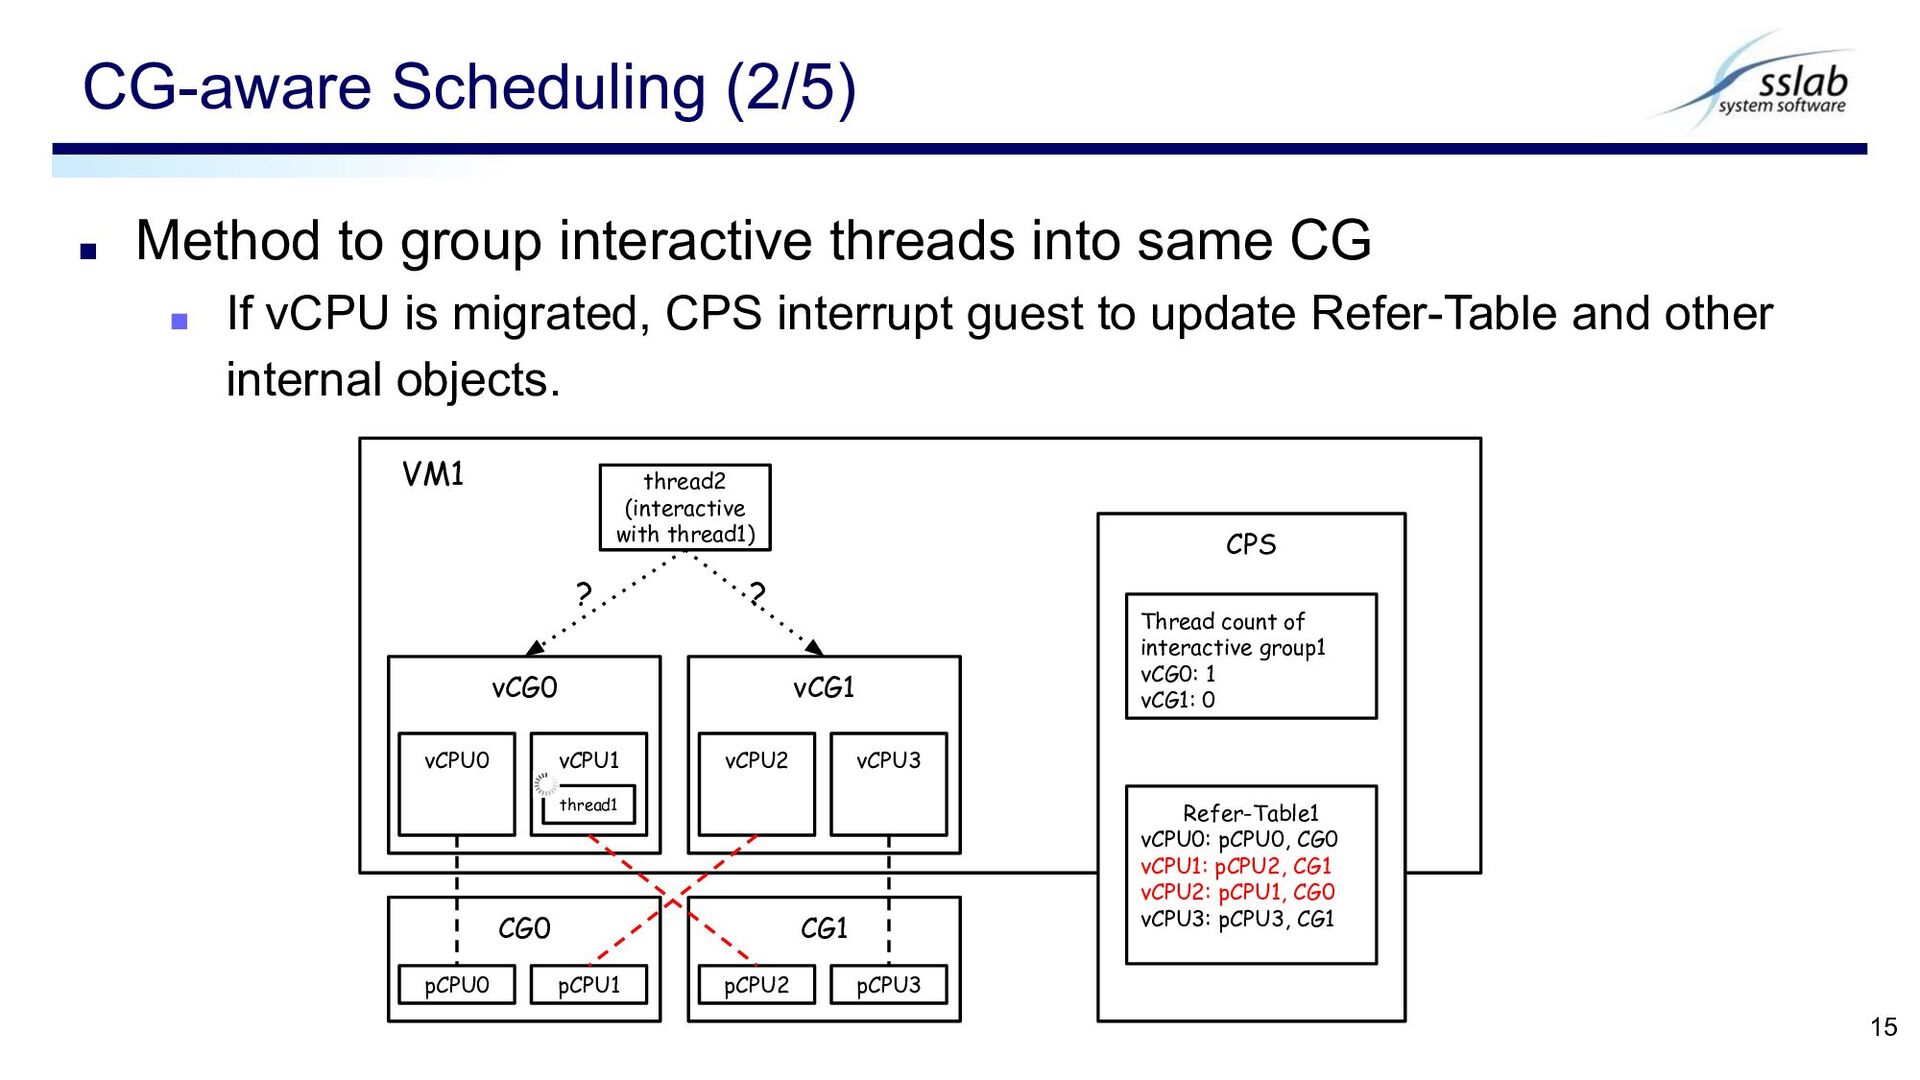
▪ Method to group interactive threads into same CG ▪
If vCPU is migrated, CPS interrupt guest to update Refer-Table and other internal objects. CG-aware Scheduling (2/5) 15 VM1 CG0 pCPU0 pCPU1 vCG0 vCPU0 vCPU1 thread2 (interactive with thread1) CG1 pCPU2 pCPU3 vCG1 vCPU2 vCPU3 thread1 ? ? CPS Refer-Table1 vCPU0: pCPU0, CG0 vCPU1: pCPU2, CG1 vCPU2: pCPU1, CG0 vCPU3: pCPU3, CG1 Thread count of interactive group1 vCG0: 1 vCG1: 0 -
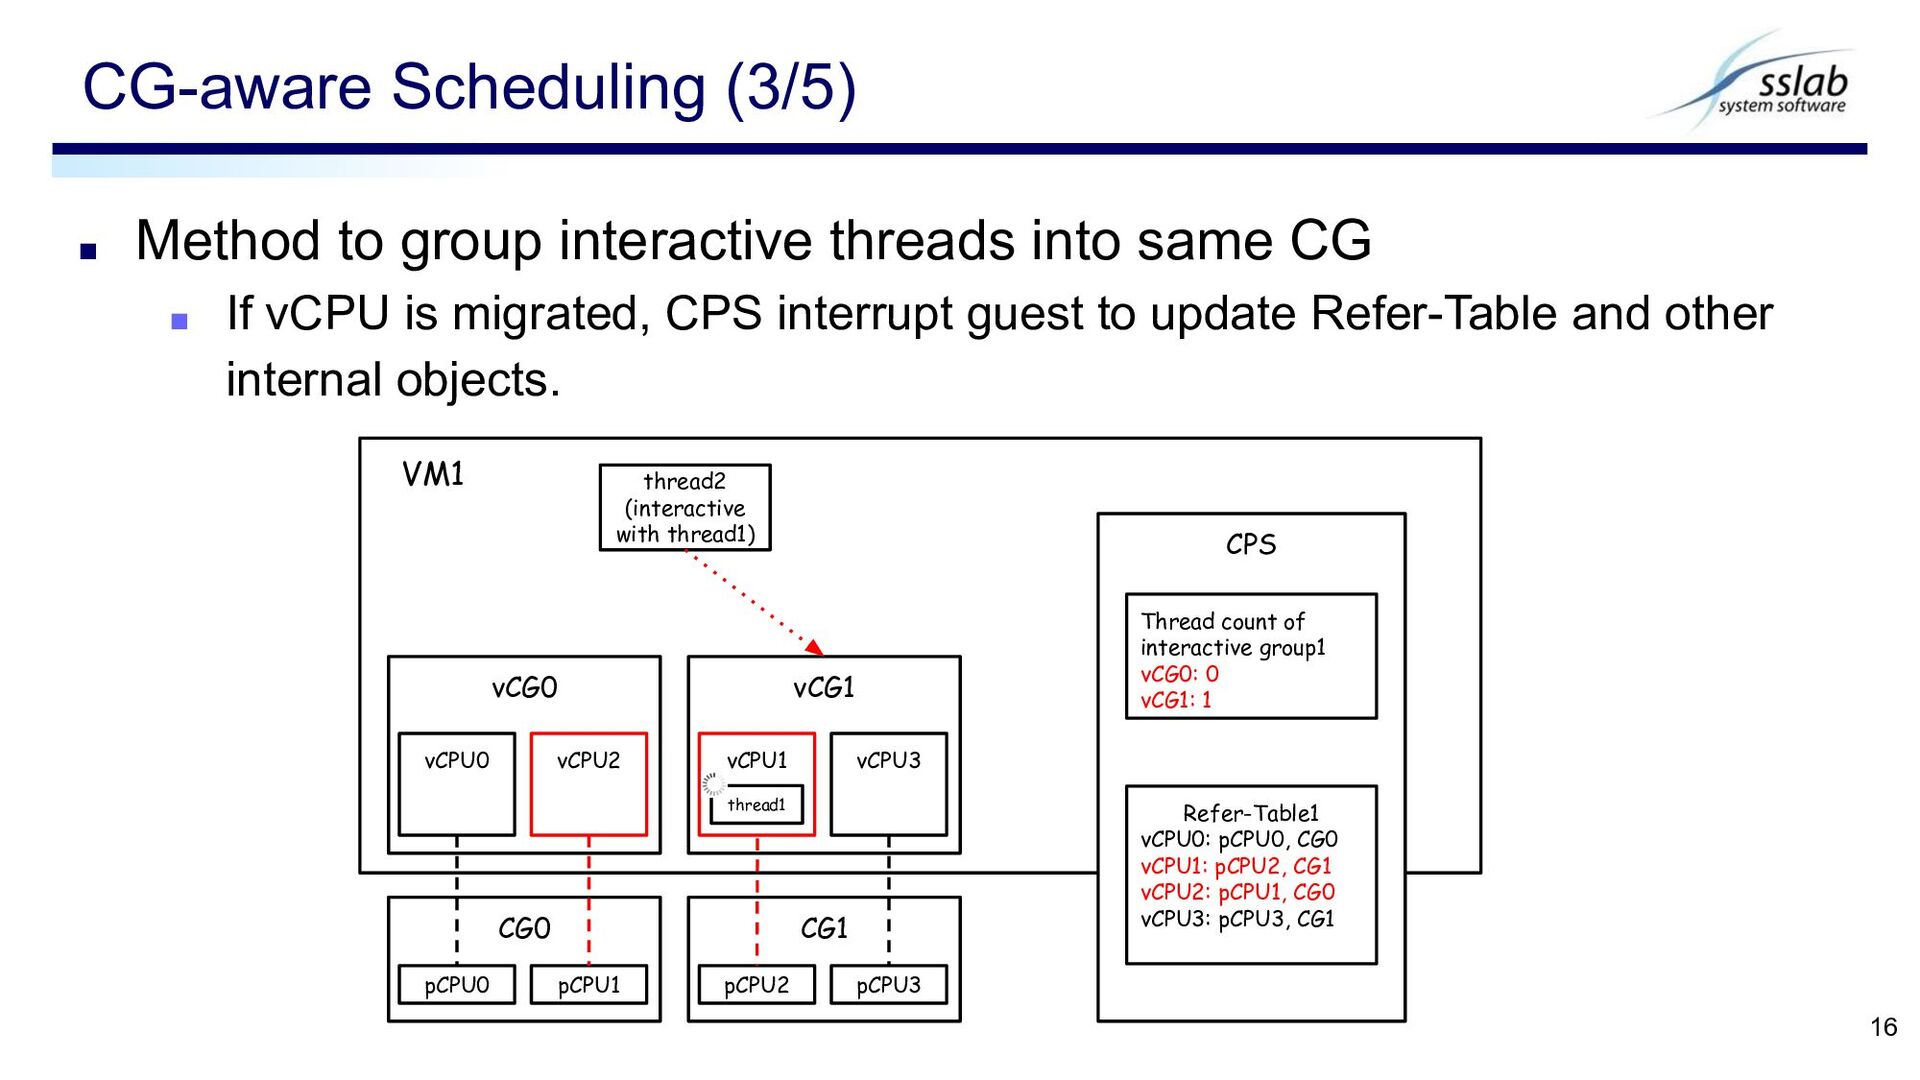
vCG1 ▪ Method to group interactive threads into same CG
▪ If vCPU is migrated, CPS interrupt guest to update Refer-Table and other internal objects. CG-aware Scheduling (3/5) 16 VM1 CG0 pCPU0 pCPU1 vCG0 vCPU0 vCPU1 thread2 (interactive with thread1) CG1 pCPU2 pCPU3 vCPU2 vCPU3 thread1 CPS Refer-Table1 vCPU0: pCPU0, CG0 vCPU1: pCPU2, CG1 vCPU2: pCPU1, CG0 vCPU3: pCPU3, CG1 Thread count of interactive group1 vCG0: 0 vCG1: 1 -
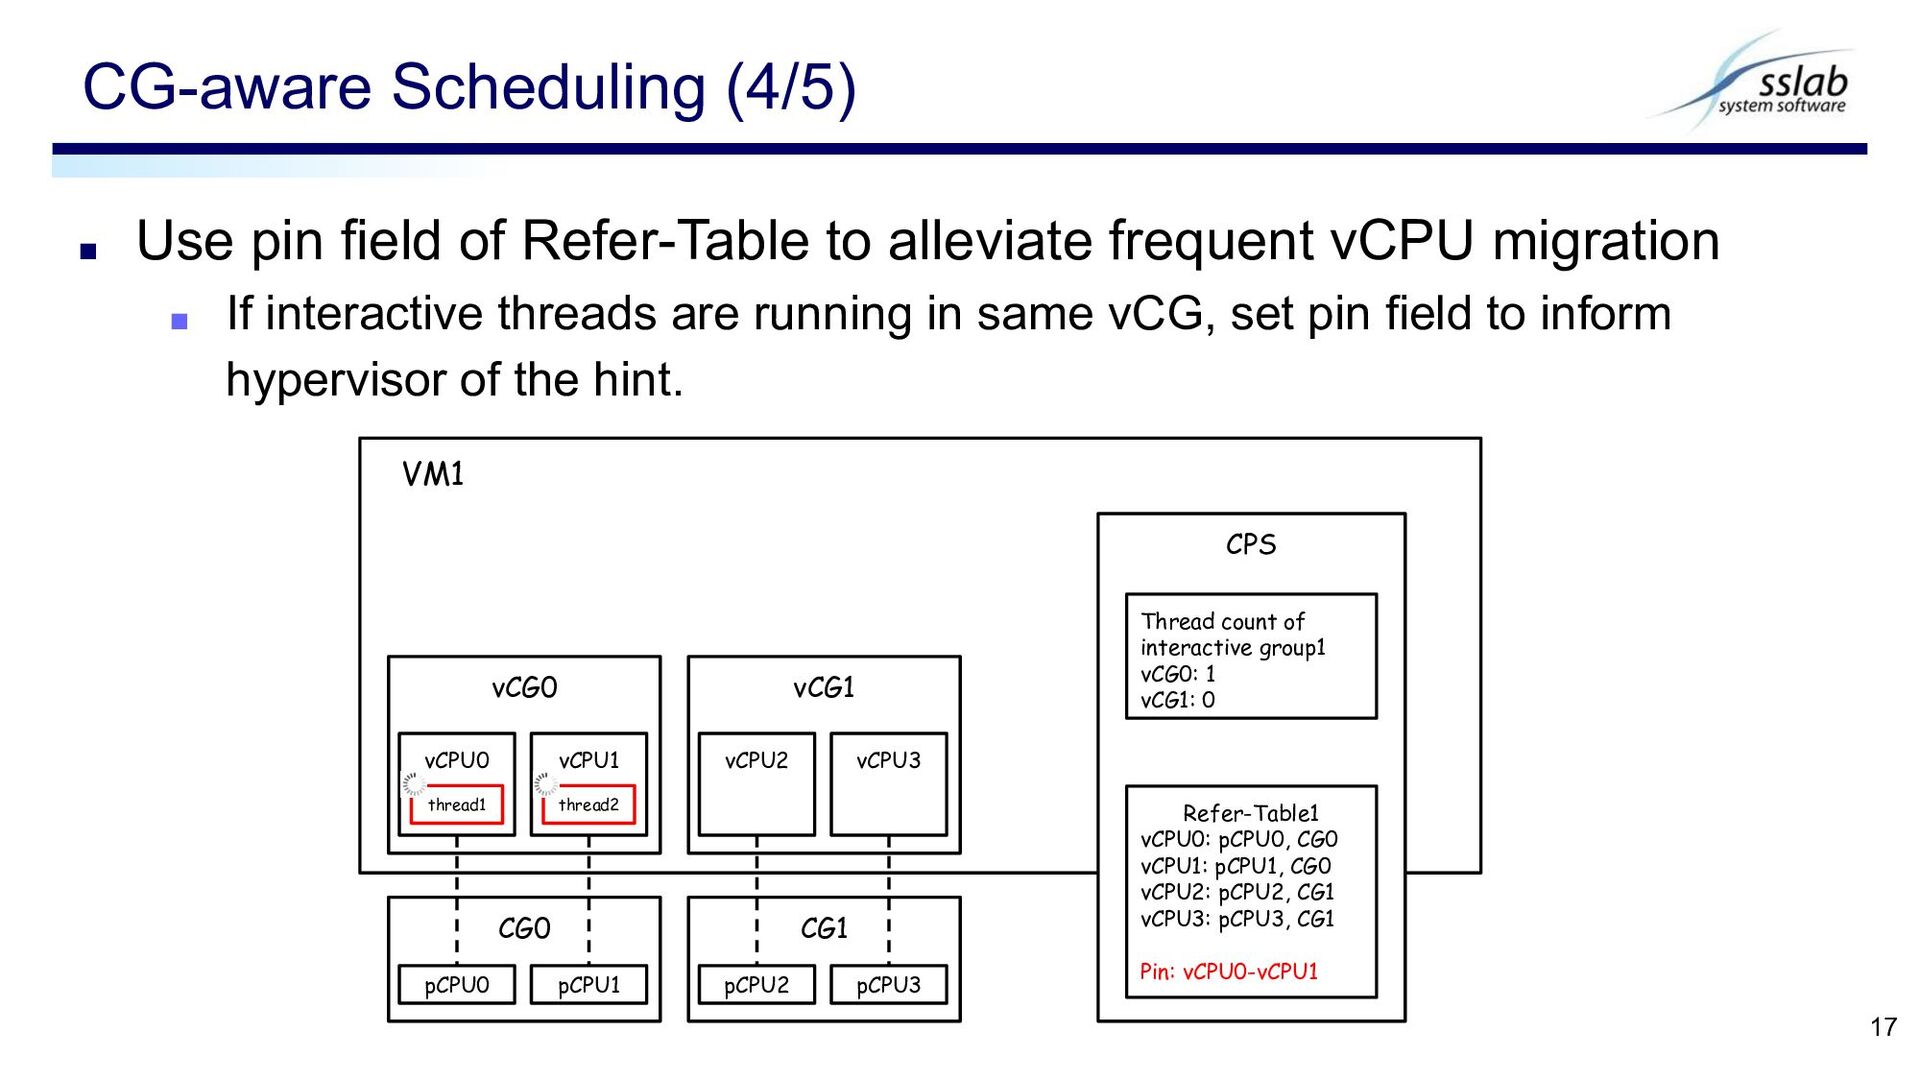
▪ Use pin field of Refer-Table to alleviate frequent vCPU
migration ▪ If interactive threads are running in same vCG, set pin field to inform hypervisor of the hint. CG-aware Scheduling (4/5) 17 VM1 CG0 pCPU0 pCPU1 vCG0 vCPU0 vCPU1 CG1 pCPU2 pCPU3 vCG1 vCPU2 vCPU3 thread2 CPS Refer-Table1 vCPU0: pCPU0, CG0 vCPU1: pCPU1, CG0 vCPU2: pCPU2, CG1 vCPU3: pCPU3, CG1 Pin: vCPU0-vCPU1 Thread count of interactive group1 vCG0: 1 vCG1: 0 thread1 -
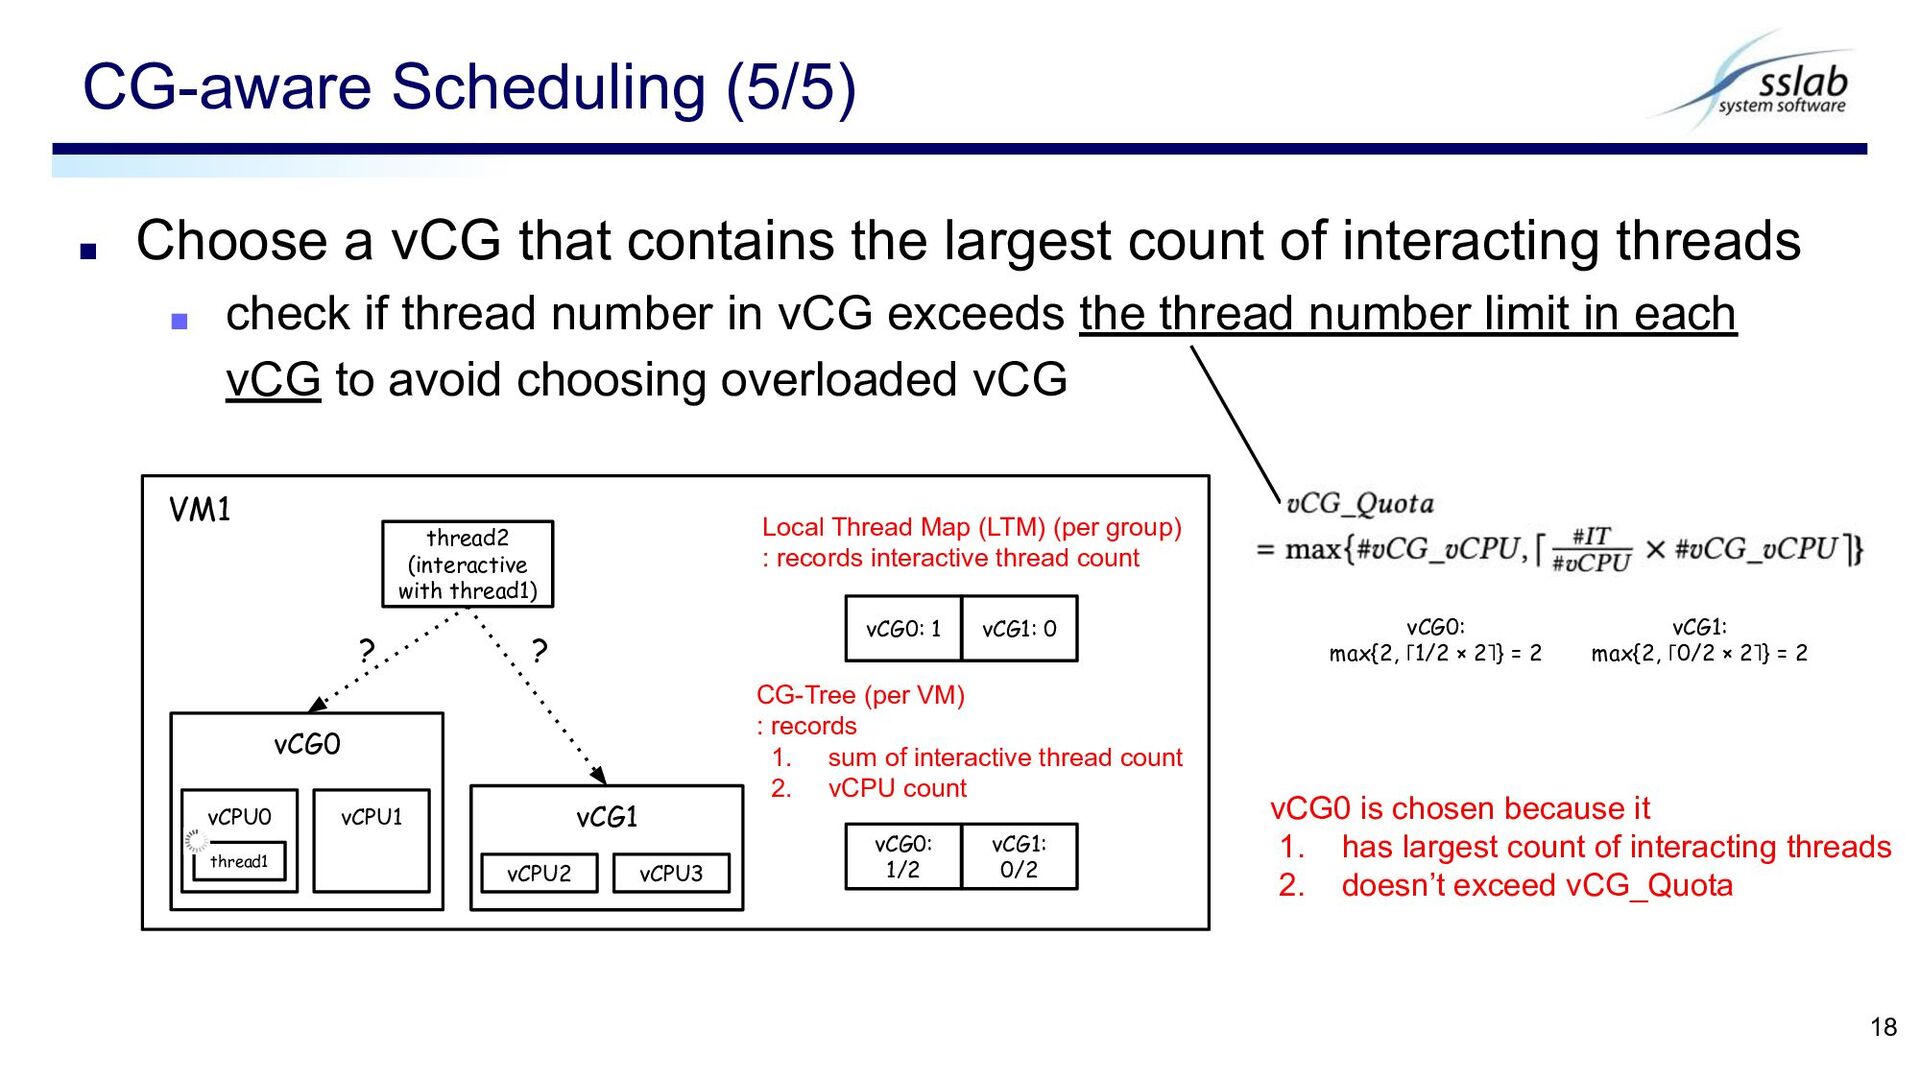
▪ Choose a vCG that contains the largest count of
interacting threads ▪ check if thread number in vCG exceeds the thread number limit in each vCG to avoid choosing overloaded vCG CG-aware Scheduling (5/5) 18 VM1 vCG0 vCPU0 vCPU1 thread2 (interactive with thread1) vCG0: 1 Local Thread Map (LTM) (per group) : records interactive thread count vCG1 vCPU2 vCPU3 thread1 ? ? vCG1: 0 vCG0: 1/2 CG-Tree (per VM) : records 1. sum of interactive thread count 2. vCPU count vCG1: 0/2 vCG0: max{2, ⌈1/2 × 2⌉} = 2 vCG1: max{2, ⌈0/2 × 2⌉} = 2 vCG0 is chosen because it 1. has largest count of interacting threads 2. doesn’t exceed vCG_Quota -
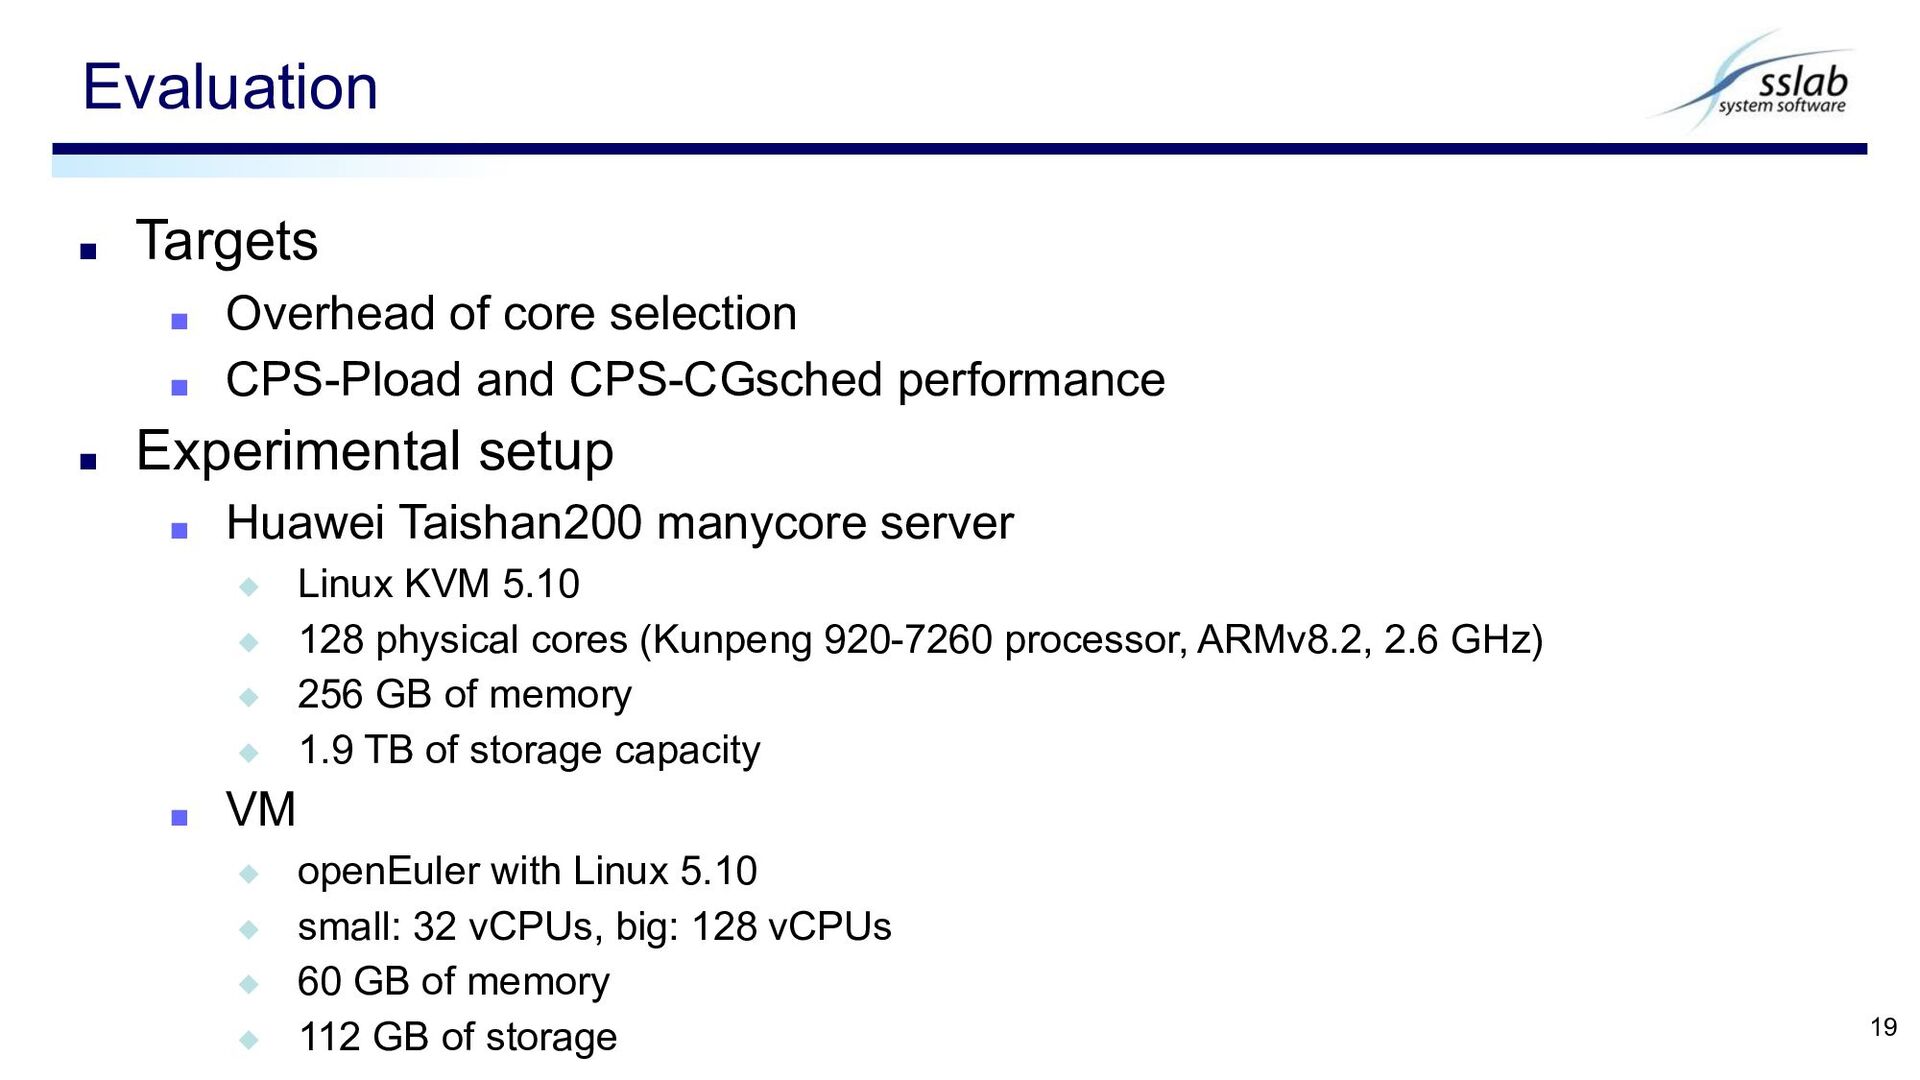
▪ Targets ▪ Overhead of core selection ▪ CPS-Pload and
CPS-CGsched performance ▪ Experimental setup ▪ Huawei Taishan200 manycore server ◆ Linux KVM 5.10 ◆ 128 physical cores (Kunpeng 920-7260 processor, ARMv8.2, 2.6 GHz) ◆ 256 GB of memory ◆ 1.9 TB of storage capacity ▪ VM ◆ openEuler with Linux 5.10 ◆ small: 32 vCPUs, big: 128 vCPUs ◆ 60 GB of memory ◆ 112 GB of storage Evaluation 19 -
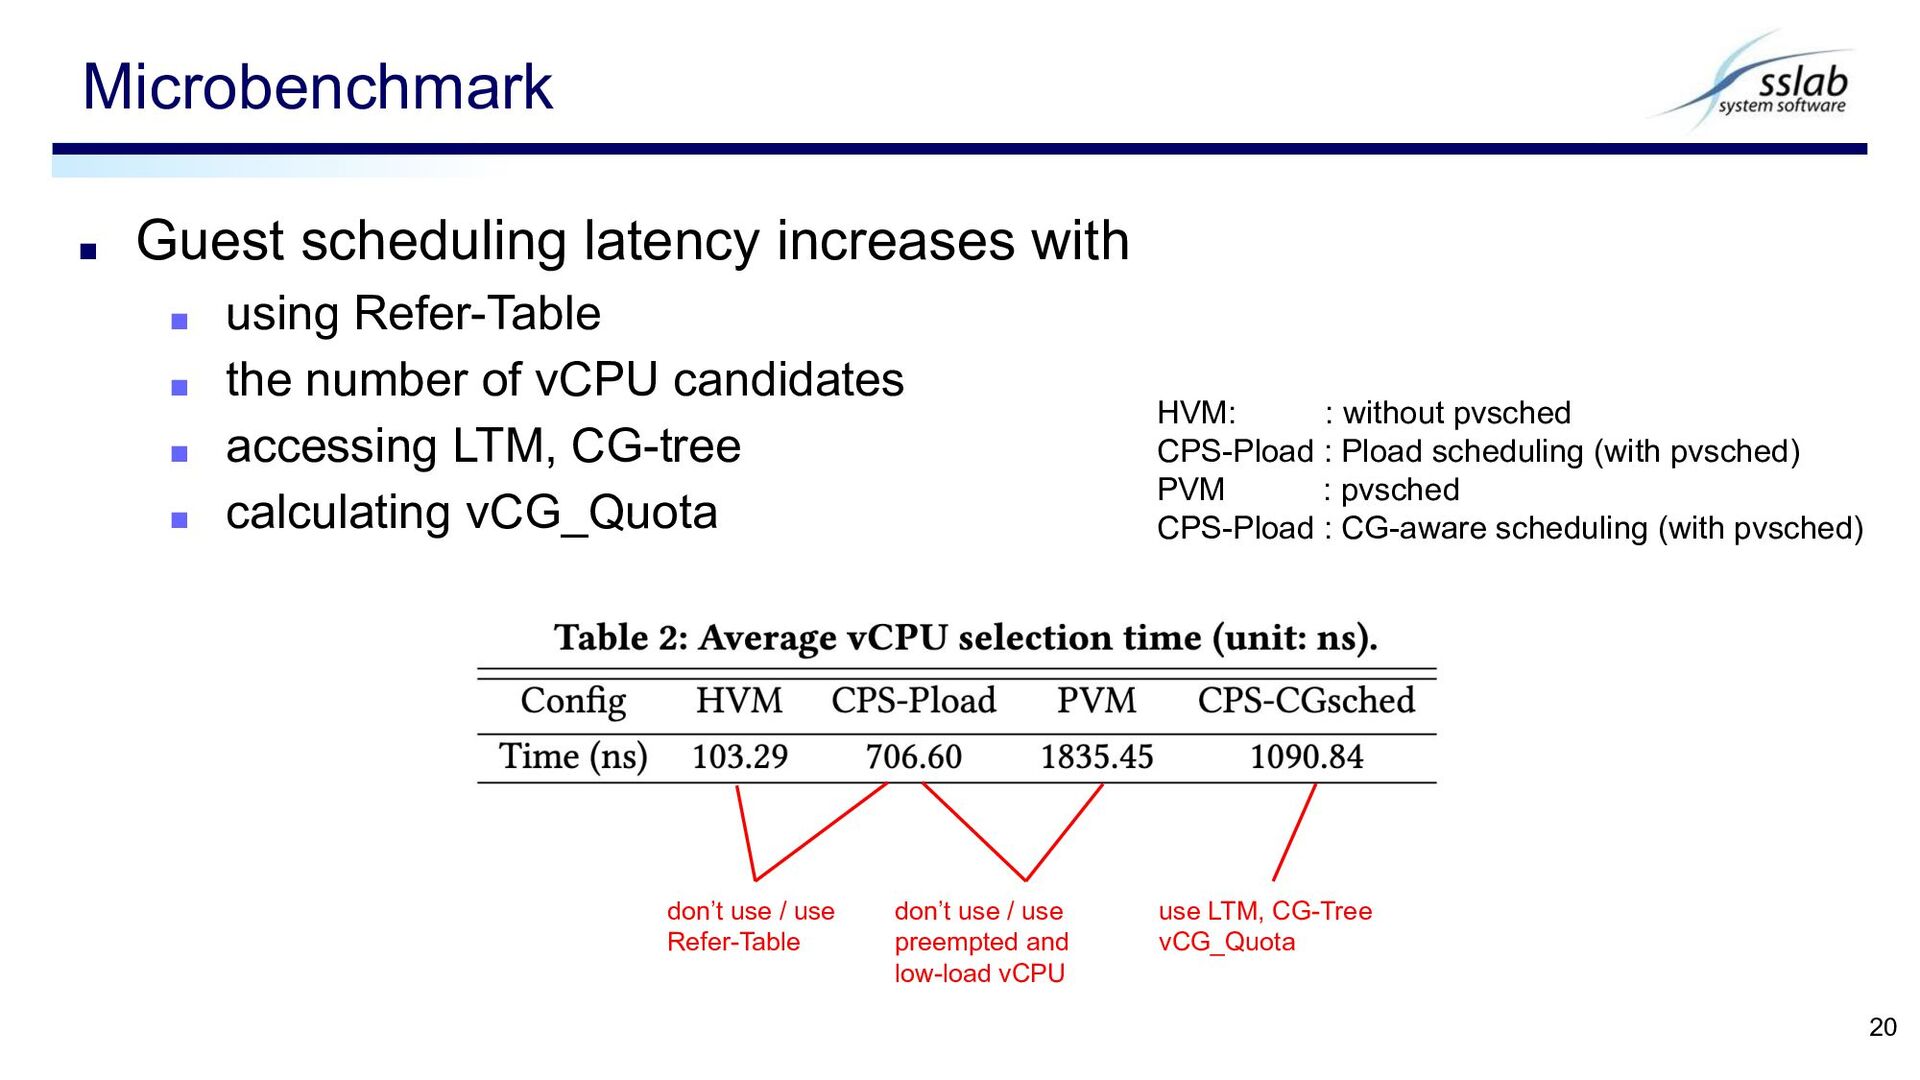
▪ Guest scheduling latency increases with ▪ using Refer-Table ▪
the number of vCPU candidates ▪ accessing LTM, CG-tree ▪ calculating vCG_Quota Microbenchmark 20 HVM: : without pvsched CPS-Pload : Pload scheduling (with pvsched) PVM : pvsched CPS-Pload : CG-aware scheduling (with pvsched) don’t use / use Refer-Table don’t use / use preempted and low-load vCPU use LTM, CG-Tree vCG_Quota -
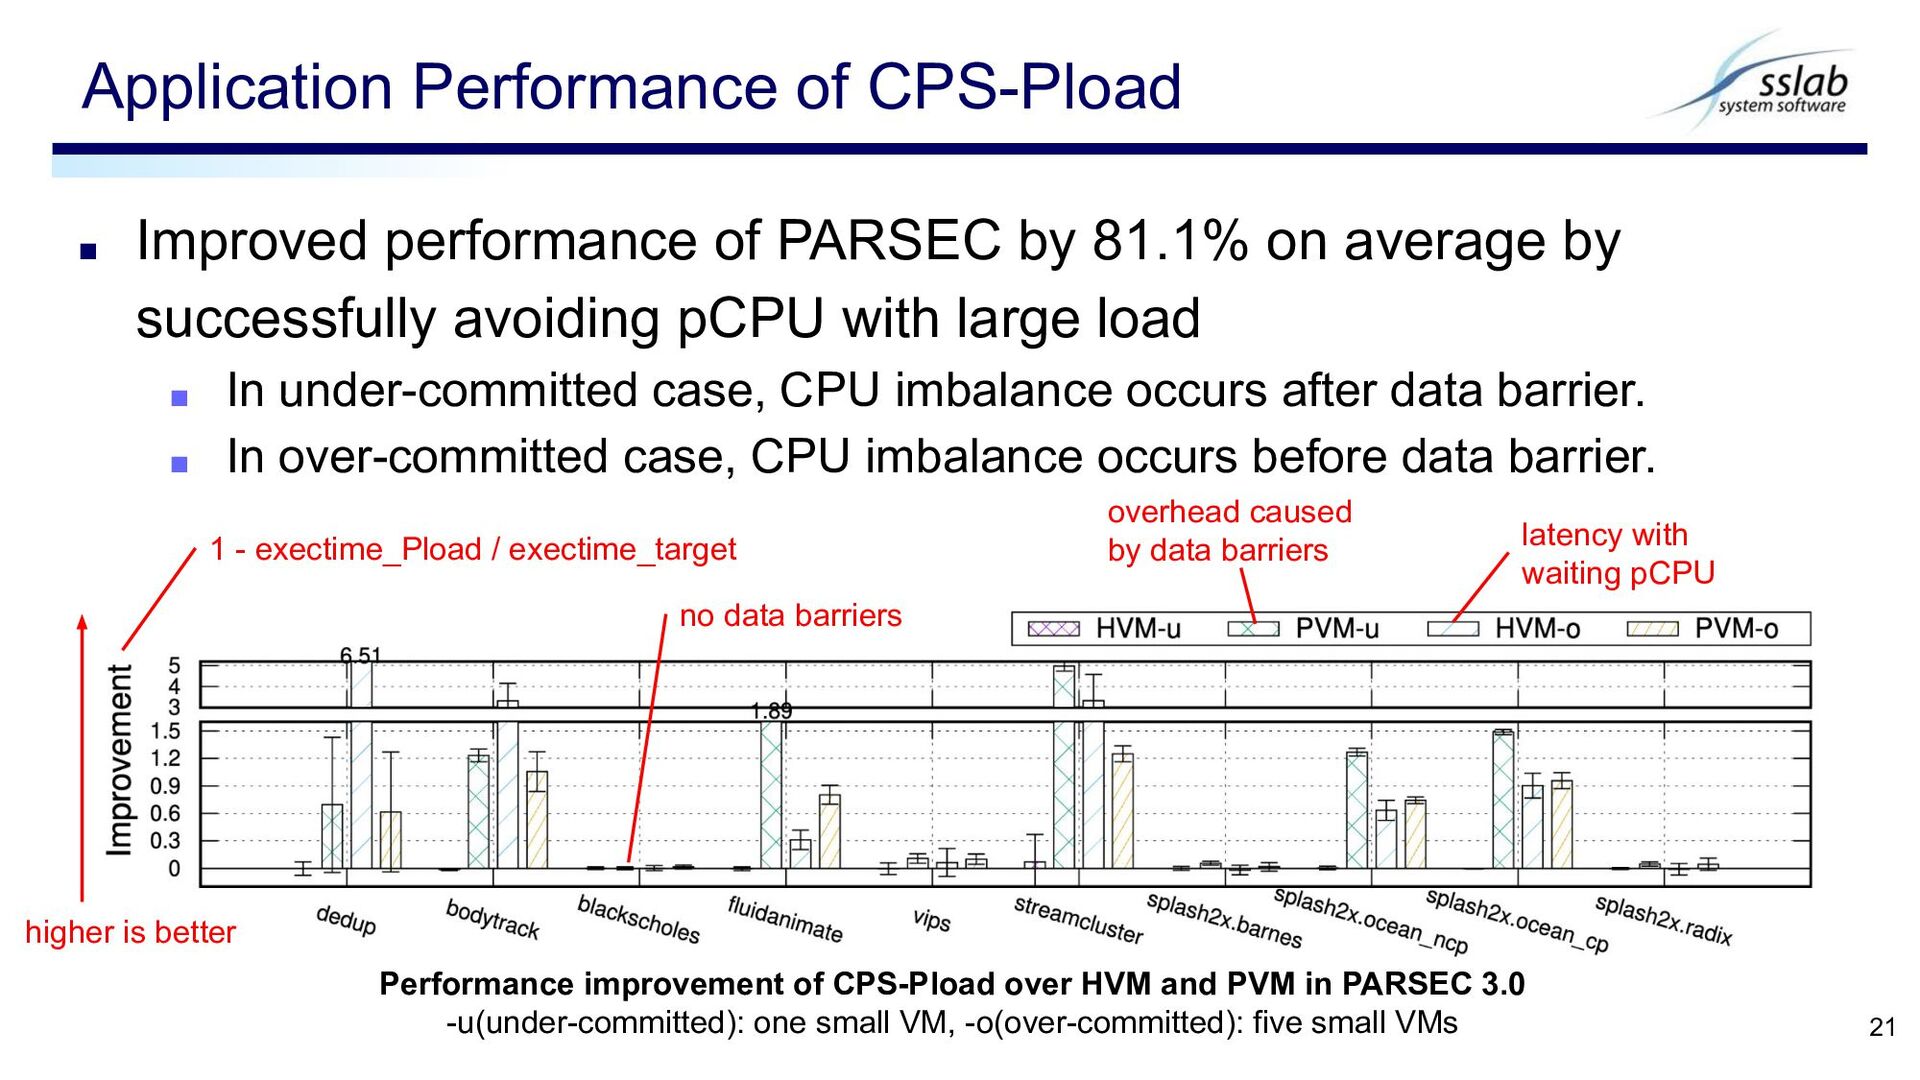
▪ Improved performance of PARSEC by 81.1% on average by
successfully avoiding pCPU with large load ▪ In under-committed case, CPU imbalance occurs after data barrier. ▪ In over-committed case, CPU imbalance occurs before data barrier. Application Performance of CPS-Pload 21 higher is better 1 - exectime_Pload / exectime_target Performance improvement of CPS-Pload over HVM and PVM in PARSEC 3.0 -u(under-committed): one small VM, -o(over-committed): five small VMs overhead caused by data barriers no data barriers latency with waiting pCPU -
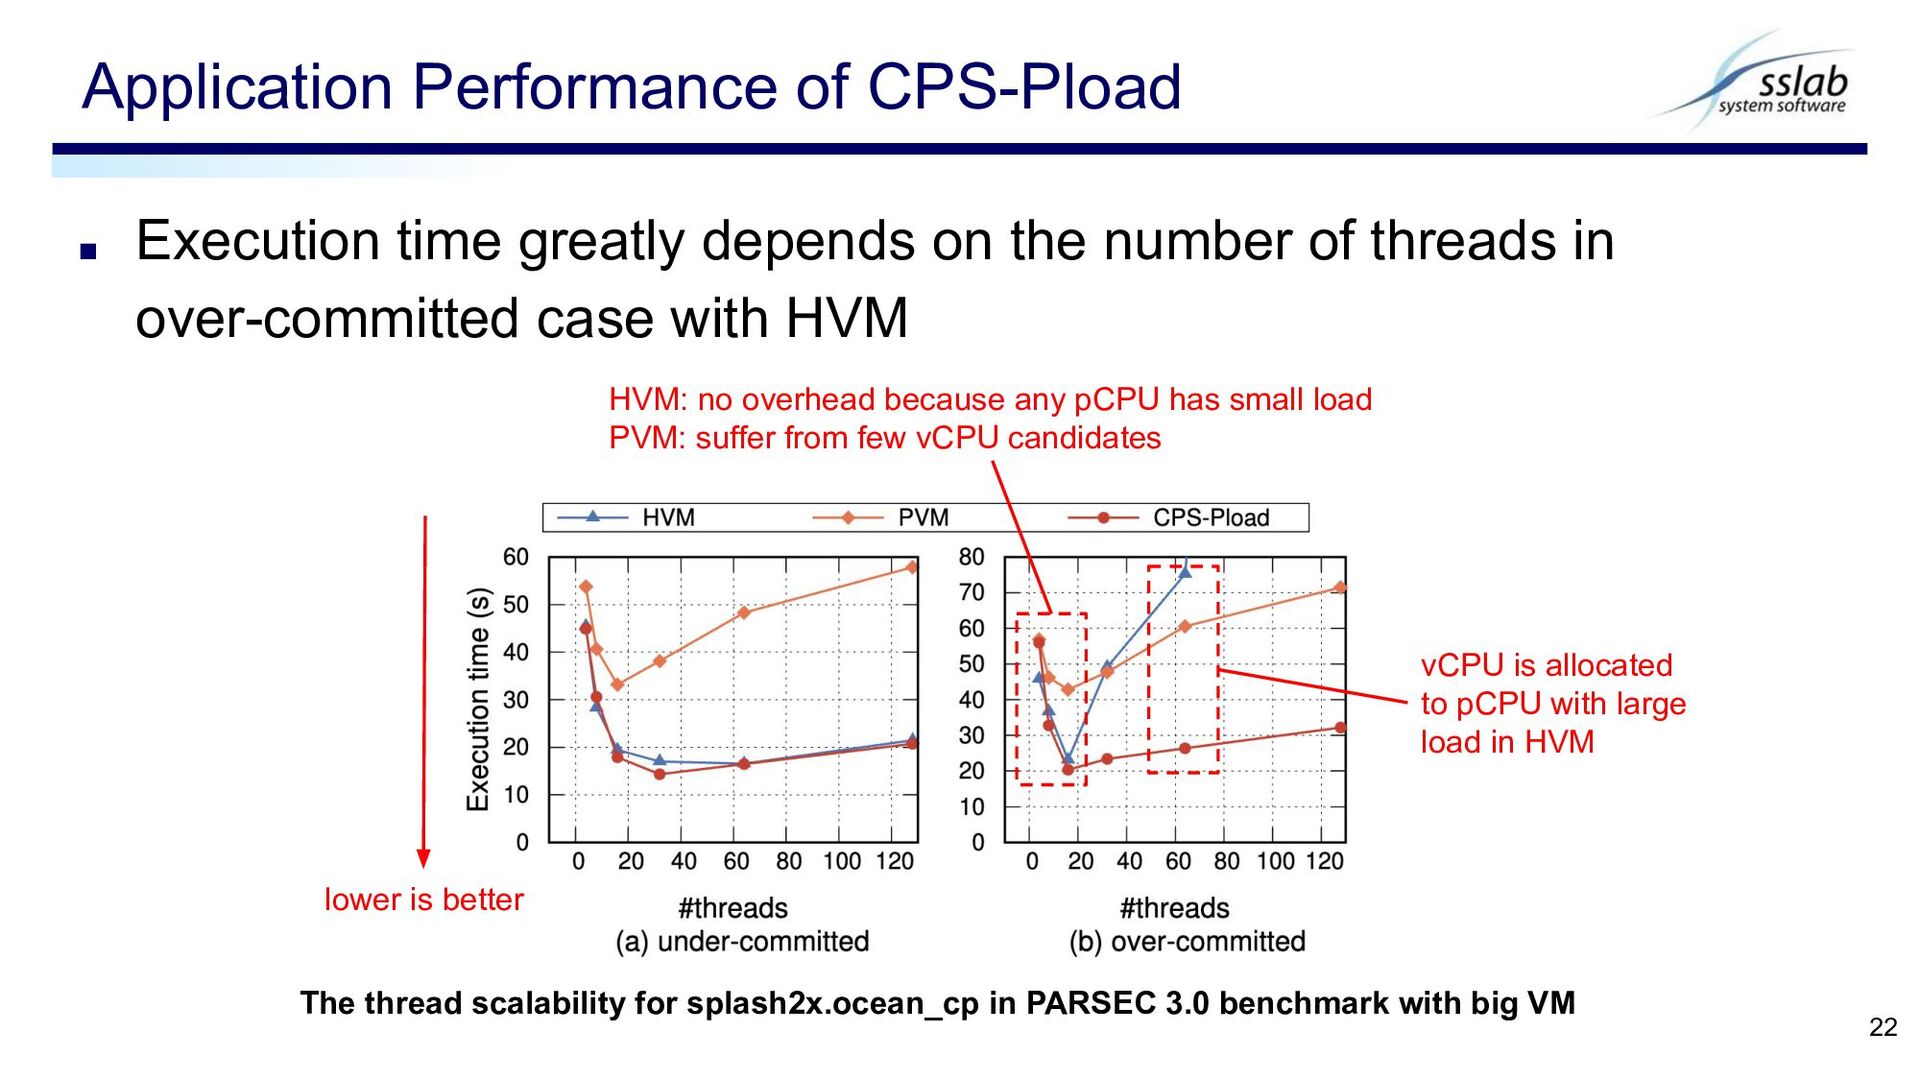
▪ Execution time greatly depends on the number of threads
in over-committed case with HVM Application Performance of CPS-Pload 22 lower is better HVM: no overhead because any pCPU has small load PVM: suffer from few vCPU candidates vCPU is allocated to pCPU with large load in HVM The thread scalability for splash2x.ocean_cp in PARSEC 3.0 benchmark with big VM -
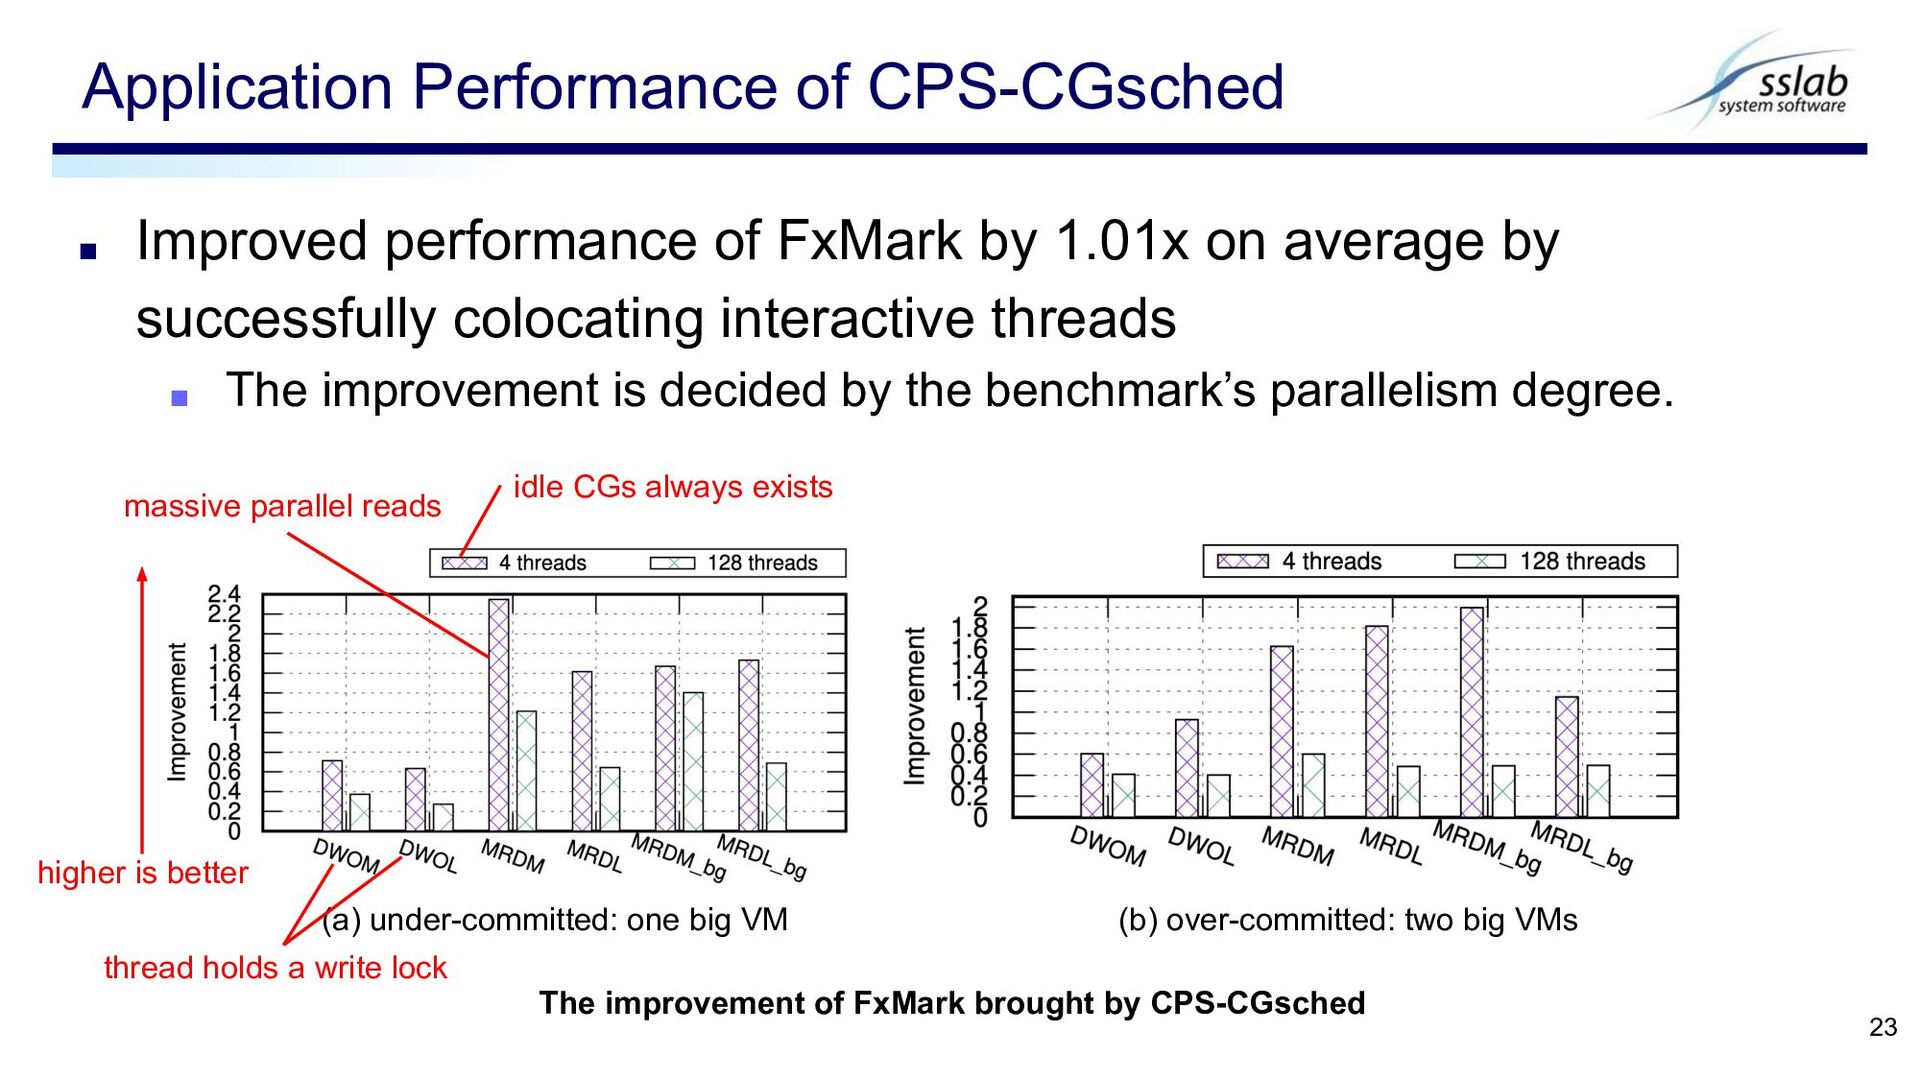
▪ Improved performance of FxMark by 1.01x on average by
successfully colocating interactive threads ▪ The improvement is decided by the benchmark’s parallelism degree. Application Performance of CPS-CGsched 23 The improvement of FxMark brought by CPS-CGsched (a) under-committed: one big VM (b) over-committed: two big VMs higher is better idle CGs always exists massive parallel reads thread holds a write lock -
▪ Suboptimal decisions made by guest scheduler due to the
absence of RHS. ▪ CPS allows host and guest to share dynamic scheduling information made by each other. ▪ Improved performance of PARSEC by 81.1% and FxMark by 1.01x on average for the two RHS problems. Conclusion 24
 wkb8s
 lauravandoore
 eileencodes
 rkaga
 bkeepers
 sarafernandez
 techseoconnect
 lfama
 baasie
 katarinadahlin
 bryan
 kevinliebholz
 coloredviolet