Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
Simply Distributed
Search
Nugroho Herucahyono
October 22, 2015
Technology
130
0
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
Simply Distributed
Nugroho Herucahyono
October 22, 2015
Transcript
63 slides
Simply Distributed KNIF 2015, Bandung
Who? Nugroho Herucahyono @xinuc Programmer @Bukalapak
Keandalan Sistem dalam Mendukung Penyediaan Layanan
“Andal" => reliable & scalable
reliable: fault tolerant scalable: able to grow
How a reliable & scalable system built?
Most systems start small
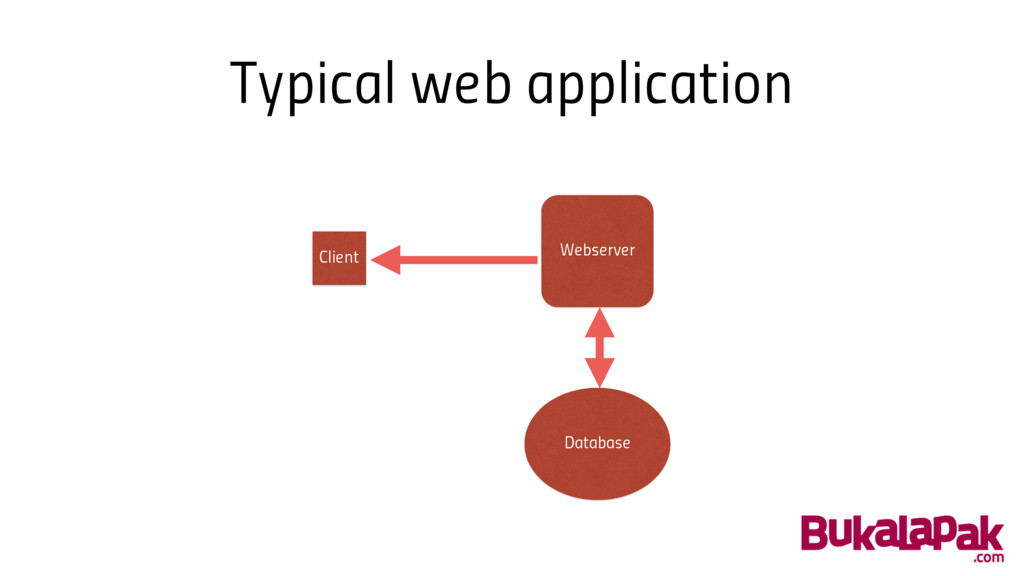
Typical web application Webserver Database Client
Typical web application • Need more features • Serve more
users • Need to be more reliable
More features Add more code Split the system
More users Need to scale machine limitation add more machines
More business value Need more reliable System should be fault
tolerant Self healing Backup, redundancy
How we do it? Current “Best practice”: • Split system
into smaller services • Communicate with http • Scale independently • Gracefully handle failure
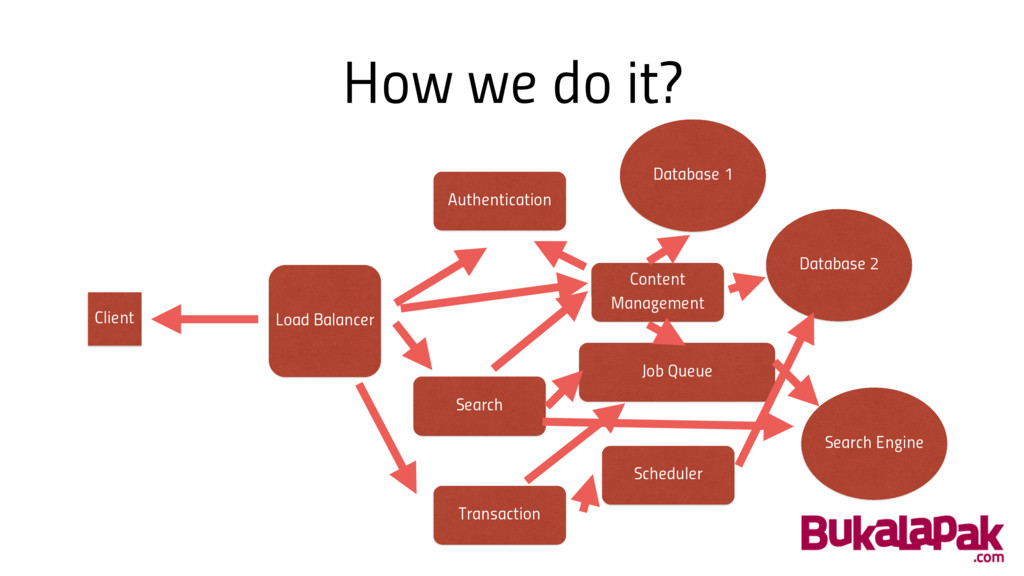
How we do it? Load Balancer Search Engine Client Authentication
Content Management Search Scheduler Transaction Database 2 Database 1 Job Queue
How we do it? Current “Best practice” apparently is not
the best: • Requires massive change to our system • Manual load balancing, replication • Manual resource management • Inefficient communication (http? really?)
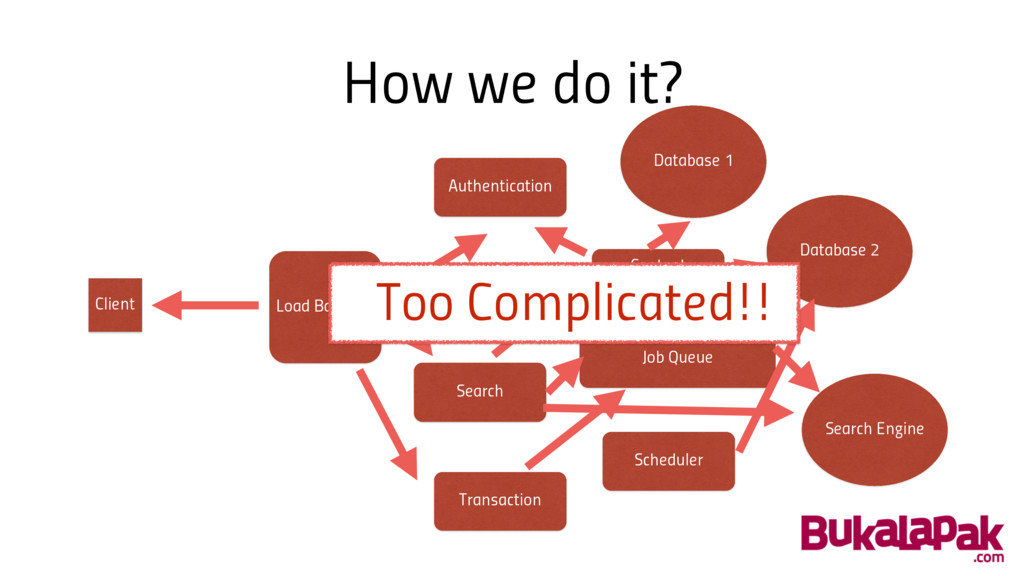
How we do it? Load Balancer Search Engine Client Authentication
Content Management Search Scheduler Transaction Database 2 Database 1 Job Queue Too Complicated!!
What would a good computer scientist do?
Introduce a new layer of abstraction!
A new layer of abstraction • Handle resource management •
Handle load balancing • Handle service communication • Handle service failure • Handle replication
A new layer of abstraction We need “Operating System” of
a cluster
A new layer of abstraction Cluster Operating system Operating System
Pod Application Hardware Operating System Pod Application Hardware Operating System Pod Application Hardware
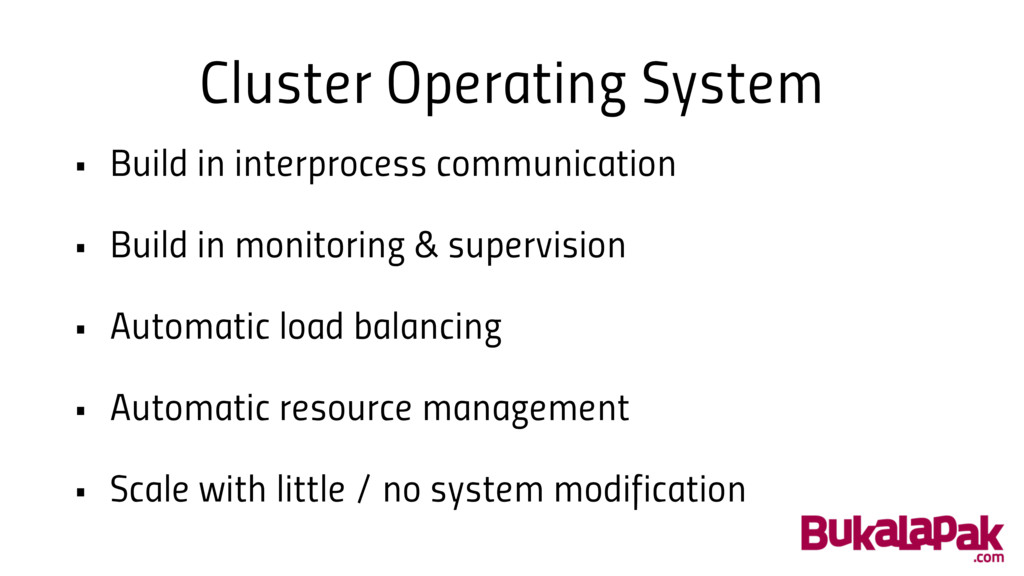
Cluster Operating System • Build in interprocess communication • Build
in monitoring & supervision • Automatic load balancing • Automatic resource management • Scale with little / no system modification
What do we have now? • Erlang VM & OTP
• Docker, Kubernetes
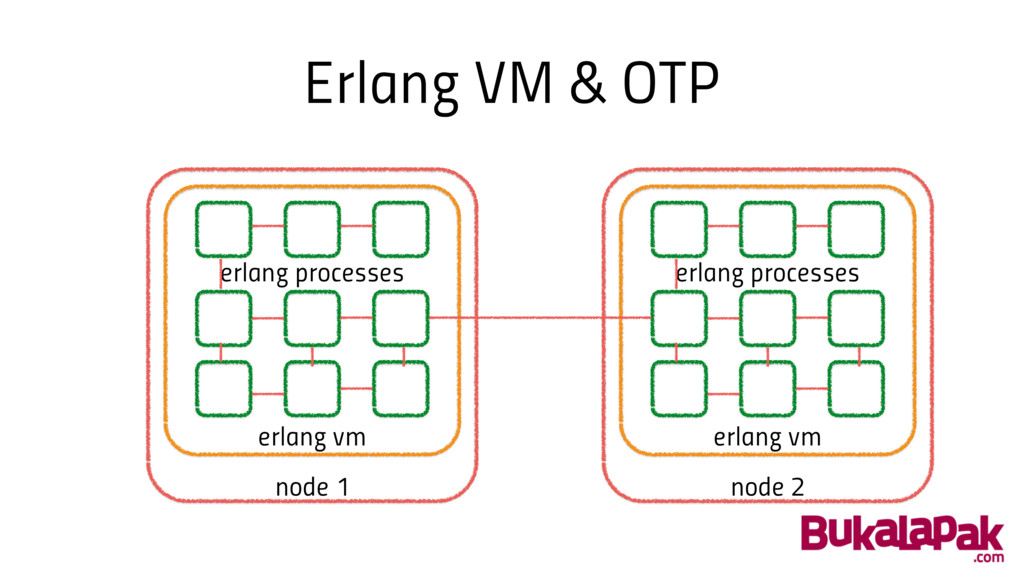
Erlang VM & OTP node 1 erlang vm erlang processes
node 2 erlang vm erlang processes
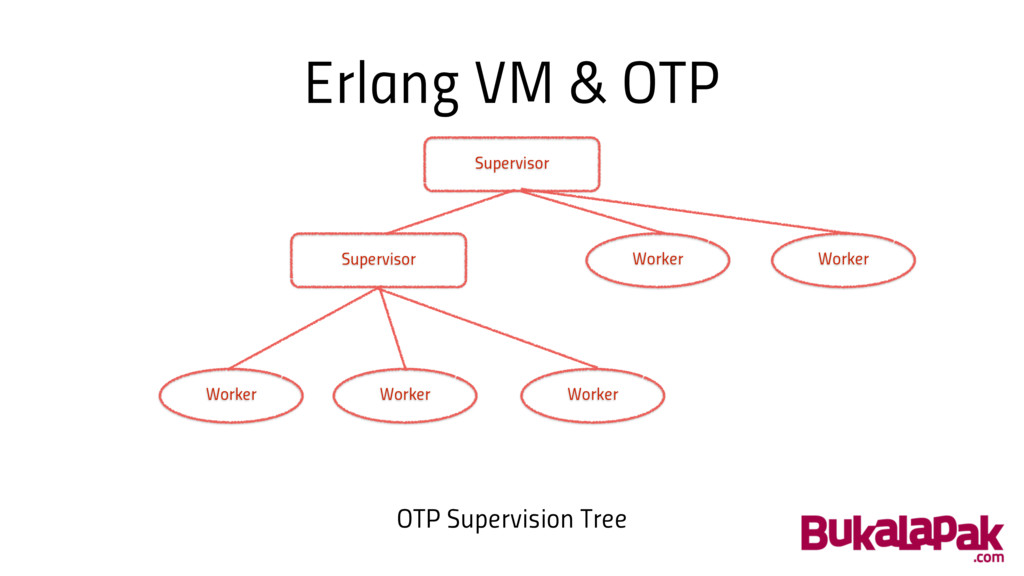
Erlang VM & OTP Supervisor Supervisor Worker Worker Worker Worker
Worker OTP Supervision Tree
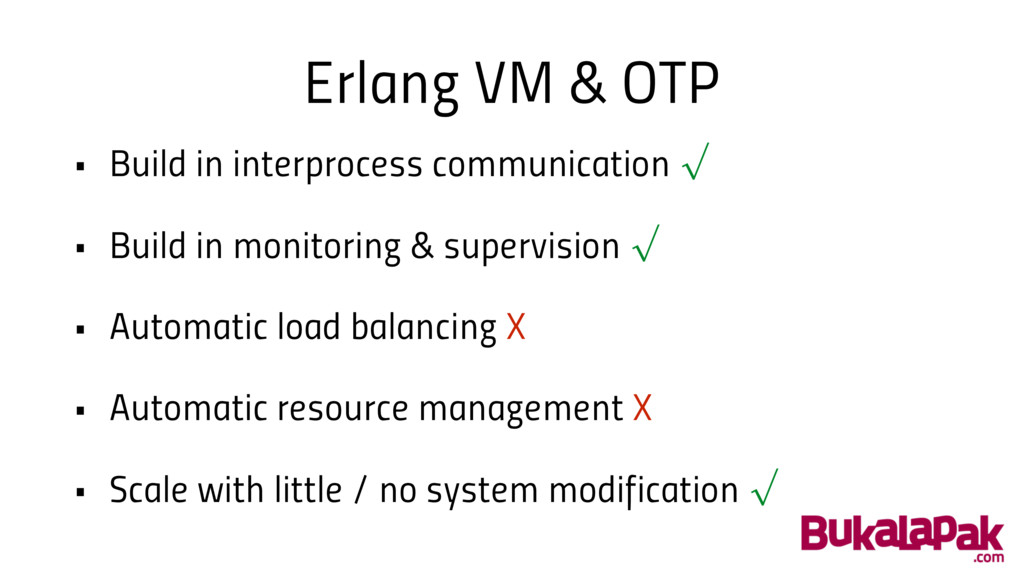
Erlang VM & OTP • Build in interprocess communication √
• Build in monitoring & supervision √ • Automatic load balancing X • Automatic resource management X • Scale with little / no system modification √
Erlang VM & OTP • The building block is too
low level? (erlang processes) • Your application need to be written in erlang (or other erlang vm languages)
Docker • Like virtual machine, but much lighter • Encapsulate
our application into single “executable” • Remove dependencies, development vs production headache
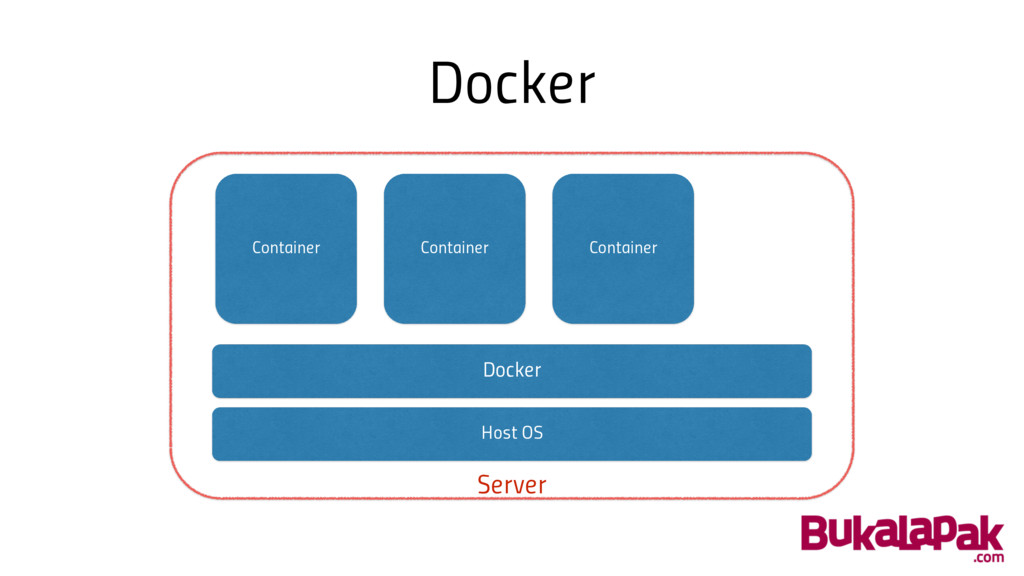
Docker Host OS Docker Container Container Container Server
Kubernetes • Manages & monitors containers • Resource allocation between
containers
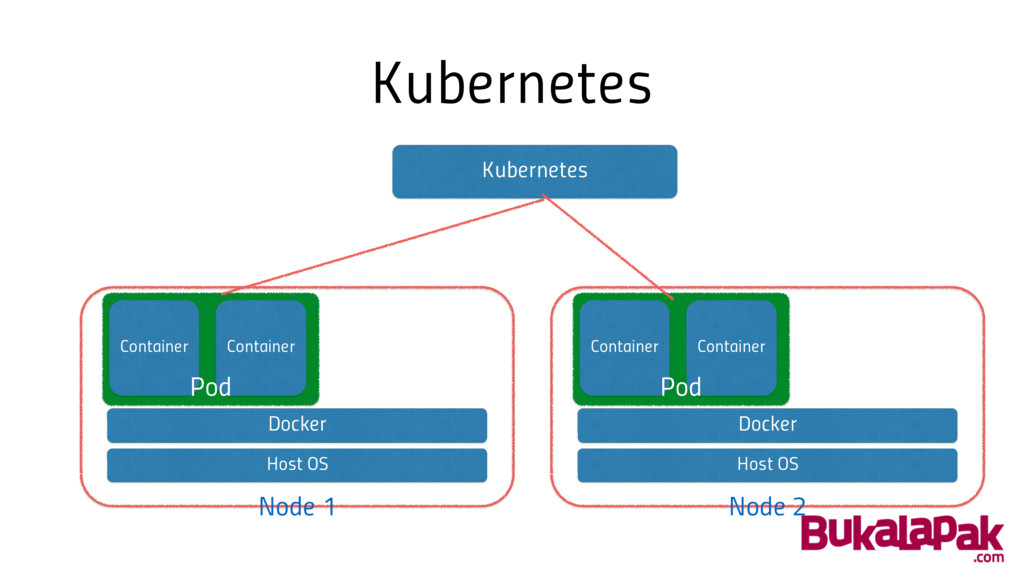
Kubernetes Host OS Docker Container Container Pod Host OS Docker
Container Container Pod Node 1 Node 2 Kubernetes
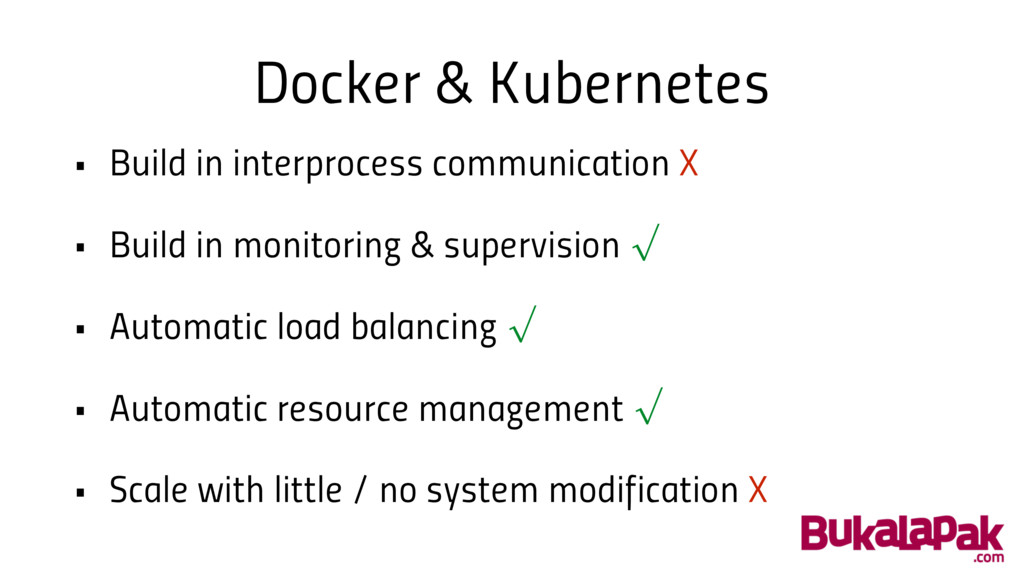
Docker & Kubernetes • Build in interprocess communication X •
Build in monitoring & supervision √ • Automatic load balancing √ • Automatic resource management √ • Scale with little / no system modification X
Docker & Kubernetes • No build in interprocess communication •
Still have to modify the system (split into smaller services) • Too complicated
Can we do better?
Let’s zoom out a bit • Service vs Process •
Node vs Core They’re conceptually the same
Maybe we can push down the abstraction layer?
What if, our “Cluster operating system” is a real Operating
System?
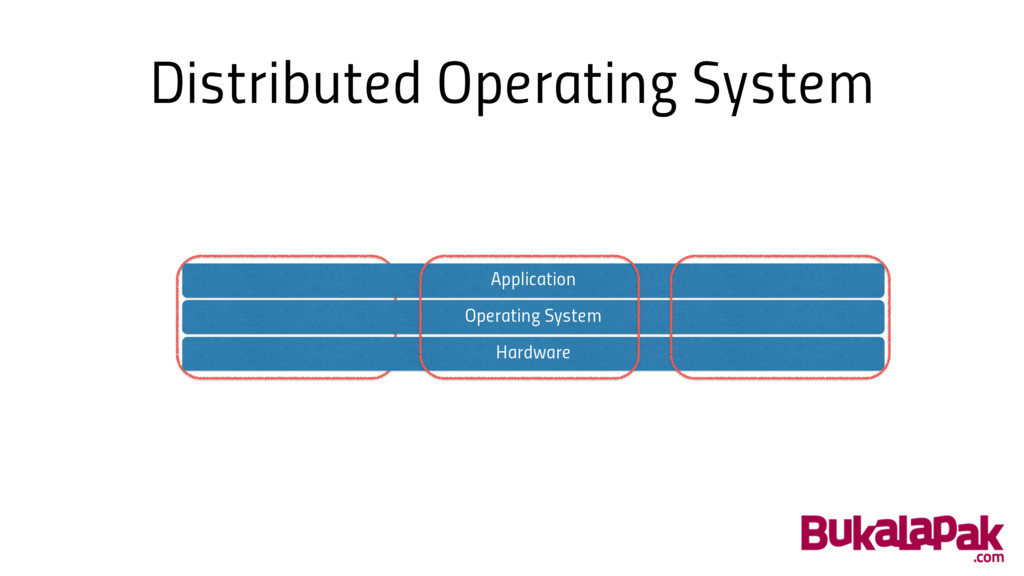
We need a real “Distributed Operating System”
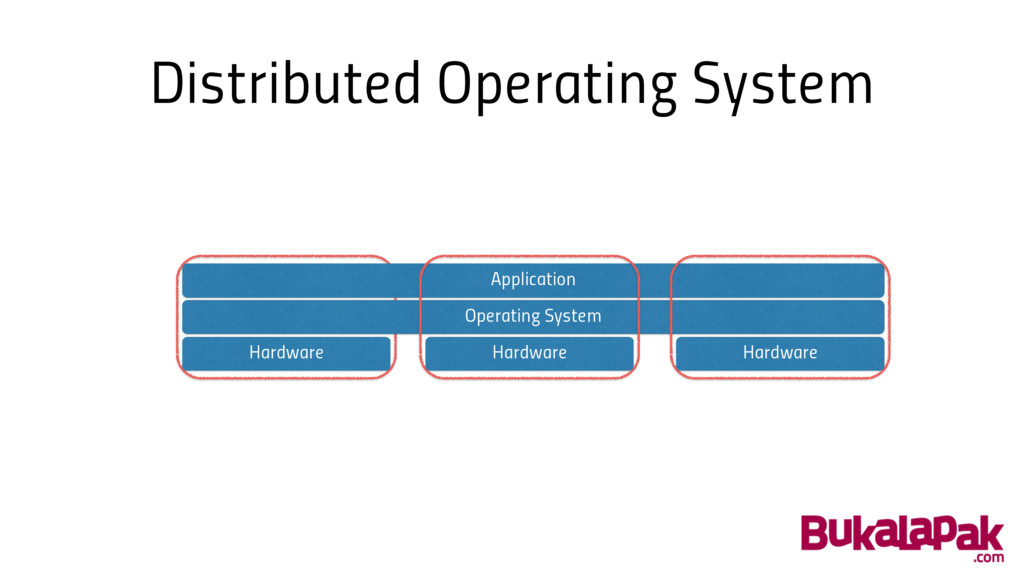
Distributed Operating System Operating System Application Hardware Hardware Hardware
Distributed Operating System • Encapsulate multiple machines as a single
node • Transparent from user / application point of view • Handle load balancing, replication & distribution automatically • Better yet, if we can add more machine on the fly
Is it possible? I have no idea.
We’ve done something similar • Raid • Multiple disk, single
volume • Transparent from applications • Automatic failure handling & replication
We need Raid for CPU & Memory
Or maybe, we can push it down further, to the
hardware level?
We need a real “Distributed Motherboard” :D
Distributed Operating System Operating System Application Hardware
Distributed Motherboard • Node 1, 32 Cores, 32 GB RAM
• Node 2, 32 Cores, 32 GB RAM • Detected by operating system as 1 Node, 64 Cores, 64 GB RAM
Distributed Motherboard • We can add more node, on the
fly • Motherboard will communicate between each other • Abstract their resources as a SINGLE NODE
Again, is it possible? I have no idea.
We’ve done that too • Hardware Raid Controller • Multiple
Disk, detected as a single hardware • Transparent from operating system & application
Too much wishful thinking?
Why does it matter?
Why does it matter? Scalable & Reliable system is a
SOLVED problem We already have Google, Facebook, etc as a prove
Why does it matter? • Scalable & Reliable system is
not easy & cheap • Need a group of highly skilled experts to build
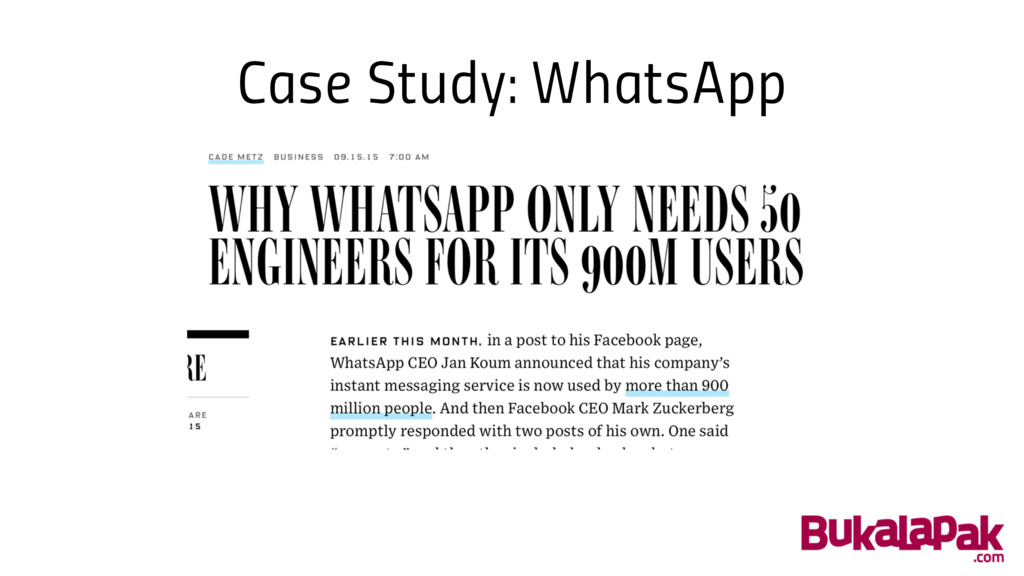
Case Study: WhatsApp
Case Study: WhatsApp • WhatsApp use Erlang VM & OTP
• They can scale it without adding too much complexity
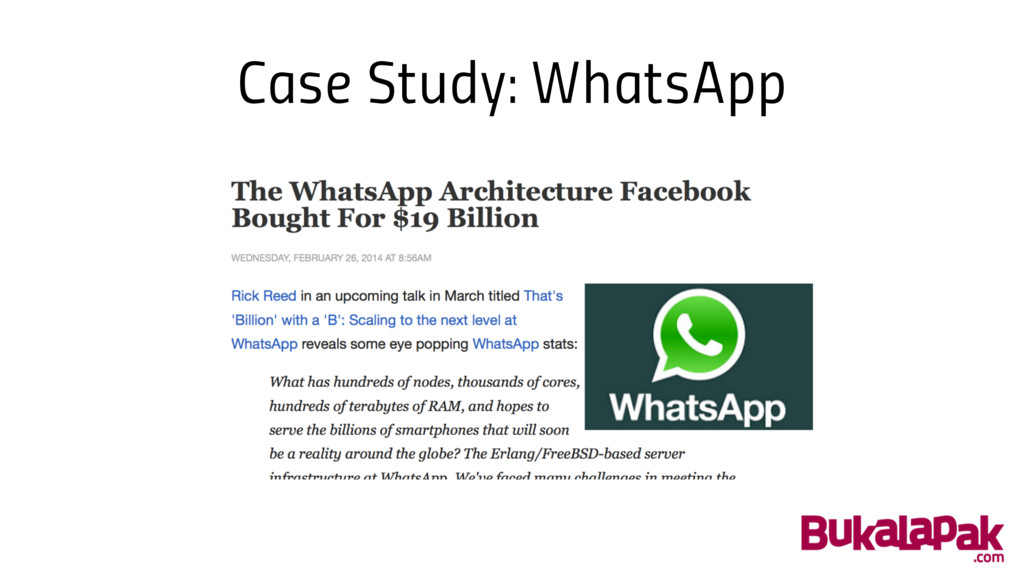
Case Study: WhatsApp
Case Study: WhatsApp We need more companies like WhatsApp
Small Startups? Can 4-fresh-graduate startup create a product used by
a billion users?
Non profits? Can we create non profit system than serve
billons of users?
./bukalapak
more research on this, please :)
Thank you
More Decks by Nugroho Herucahyono
See All by Nugroho Herucahyono
Choosing the right technology
xinuc
0
190
This Talk is so Meta
xinuc
1
140
A Tale of a Happy Programmer
xinuc
0
160
Rails on Wiradipa - Jakarta.rb Februari 2012 - Hafiz Badrie Lubiz
xinuc
1
180
Why Ruby? - View from business aspect - Jakarta.rb Februari 2012 - Fajrin Rasyid
xinuc
1
360
Other Decks in Technology
See All in Technology
属人化したISMS運用をGitHubとAIで仕組み化した1年間の記録
sioncojp
4
2.6k
ラクスル会社紹介資料|エンジニア向け / RAKSUL Introduction for Engineers
raksulrecruiting
0
100
JAWSコミュニティに 参加して1年経った結果
ssakita
0
150
AI時代の組織作り:チーム開発から「個人×AI」への移行と、持続可能な「開発資本」の築き方
ham0215
3
840
高品質と高スピードを支える品質のシフトレフトのアプローチ
goyoki
3
1k
Quick Automate | 目指せ Quick マスター 12
inariku
PRO
1
110
【Oracle AI SPOTLIGHT ウェビナー】【特別開催:日本語で解説!】Oracle AI World 2026 最新情報フィードバック
oracle4engineer
PRO
1
210
変更差分を読むために環境を整備しよう
pipepasta
1
120
Context Ontology Accelerator 入門 (業務データの意味を、AI エージェントに渡す)
inariku
PRO
3
670
Linuxネットワークスタック進化の軌跡: 過去10年の歩みと最新トレンド
orimanabu
3
630
サボる子はいねぇがー!AgentCoreハーネスの脆弱性に学ぶ、エージェントの入力バリデーション
iwamot
PRO
5
340
速くなるほど、深く考える AI時代のQAに学ぶ
kobayashiyorimitsu
0
200
Featured
See All Featured
Tell your own story through comics
letsgokoyo
1
1.1k
New Earth Scene 8
popppiees
5
2.8k
Believing is Seeing
oripsolob
1
280
Exploring the Power of Turbo Streams & Action Cable | RailsConf2023
kevinliebholz
37
6.7k
The Language of Interfaces
destraynor
162
27k
Art, The Web, and Tiny UX
lynnandtonic
304
22k
Accessibility Awareness
sabderemane
1
300
Bash Introduction
62gerente
615
220k
The Myth of the Modular Monolith - Day 2 Keynote - Rails World 2024
eileencodes
28
3.8k
Lessons Learnt from Crawling 1000+ Websites
charlesmeaden
PRO
1
1.7k
WCS-LA-2024
lcolladotor
0
990
Fight the Zombie Pattern Library - RWD Summit 2016
marcelosomers
234
18k


 xinuc
 sioncojp
 raksulrecruiting
 ssakita
 ham0215
 goyoki
 inariku
 oracle4engineer
 pipepasta
 orimanabu
 iwamot
 kobayashiyorimitsu
 letsgokoyo
 popppiees
 oripsolob
 kevinliebholz
 destraynor
 lynnandtonic
 sabderemane
 62gerente
 eileencodes
 charlesmeaden
 lcolladotor
 marcelosomers