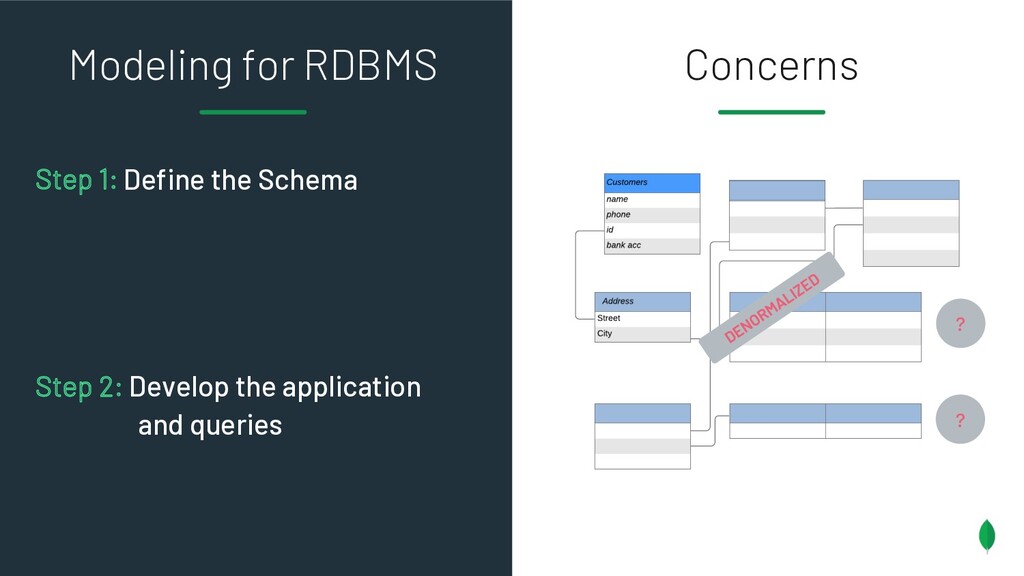
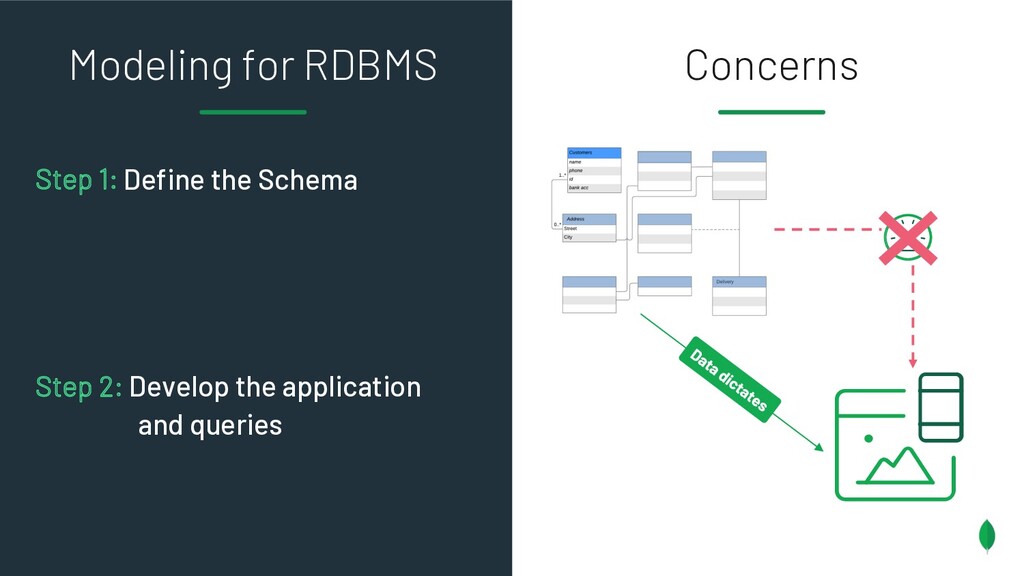
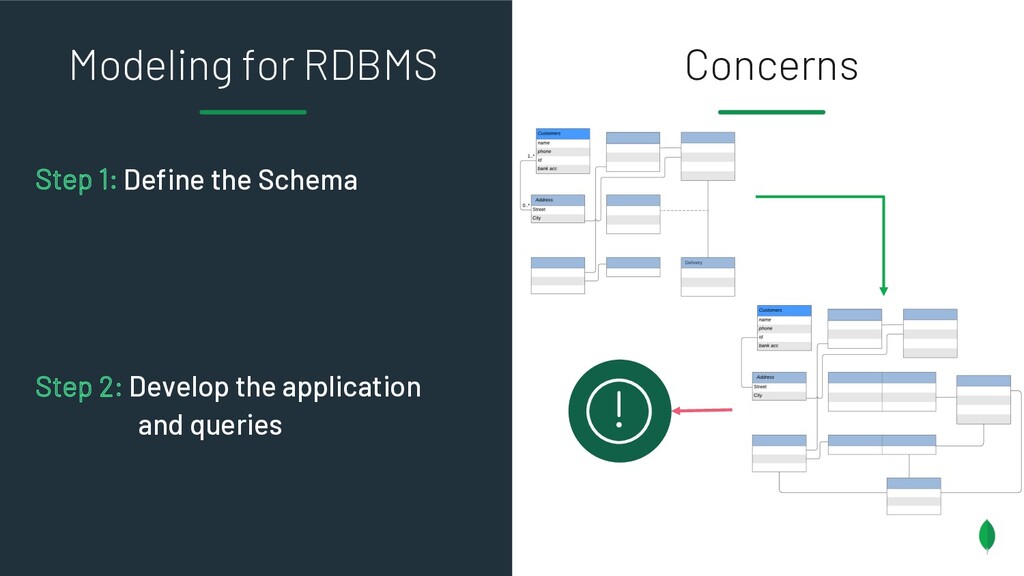
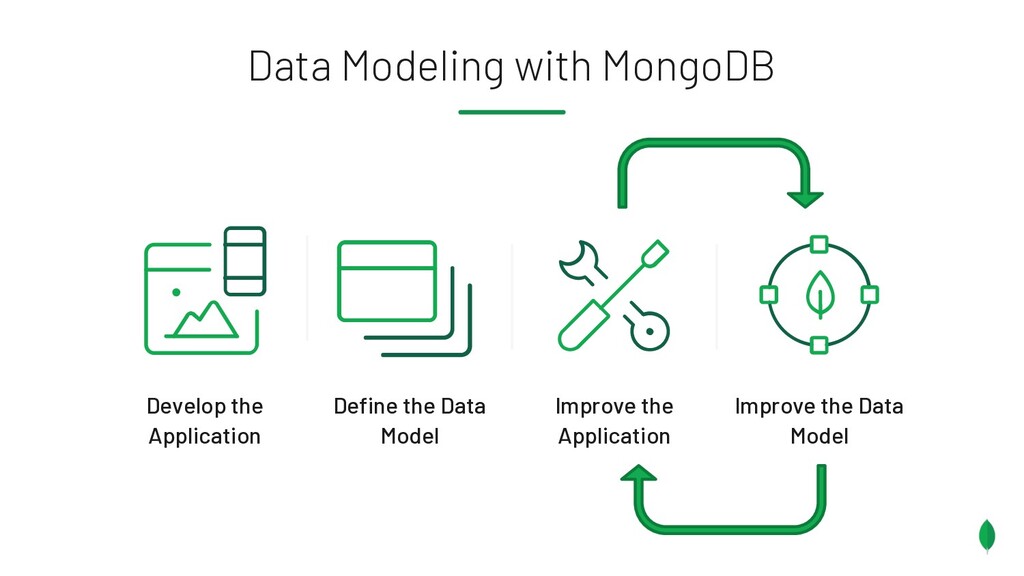
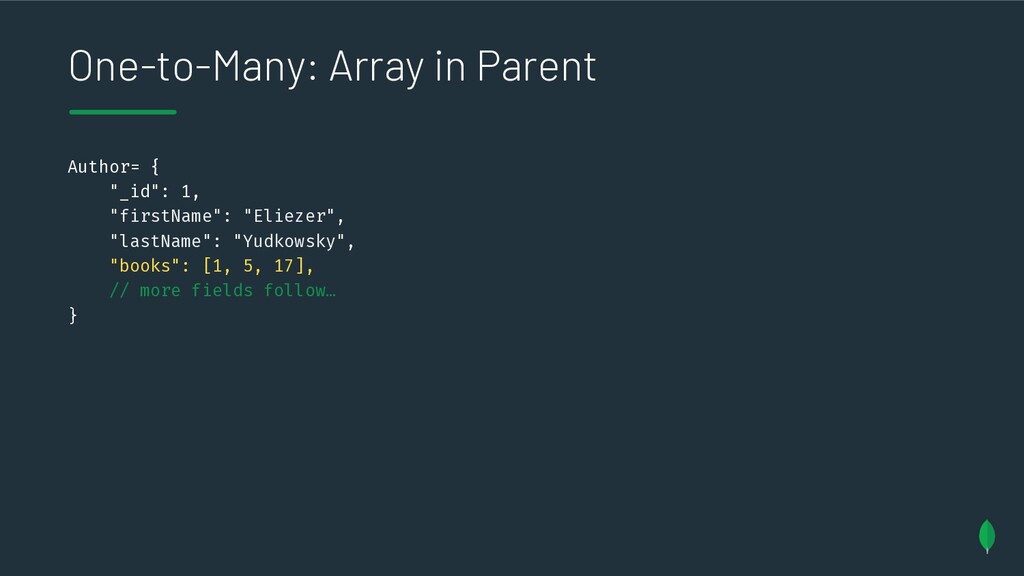
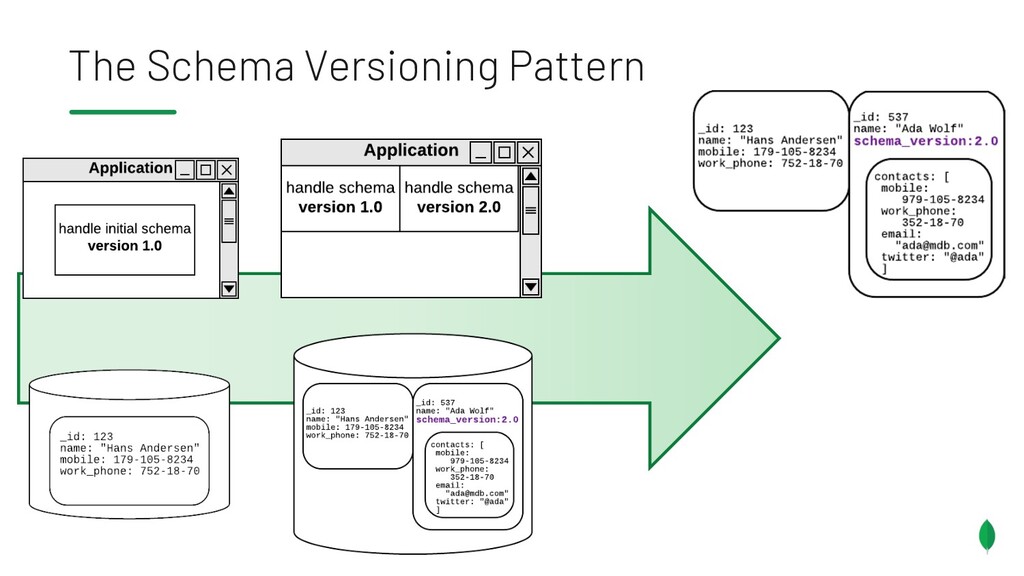
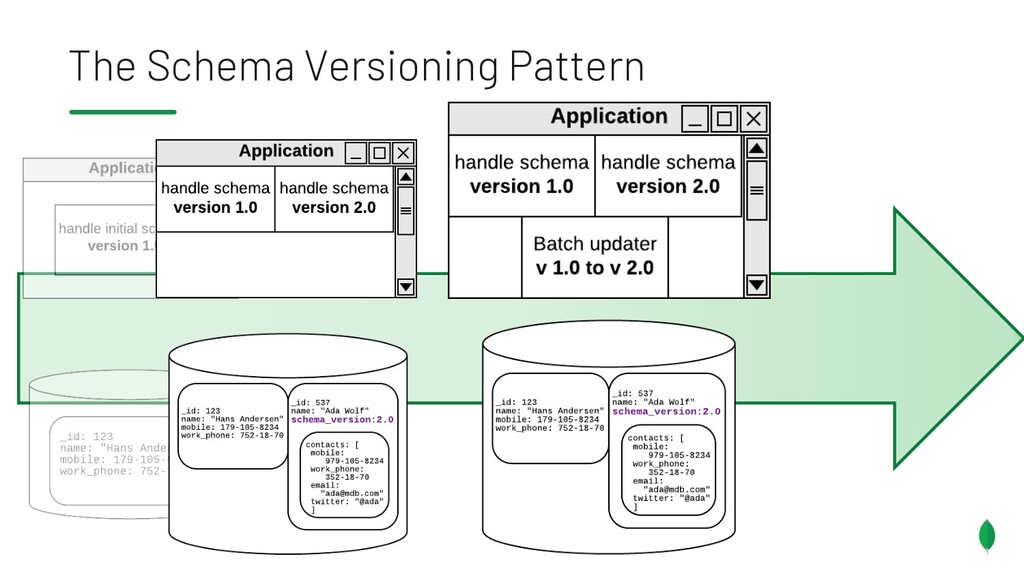
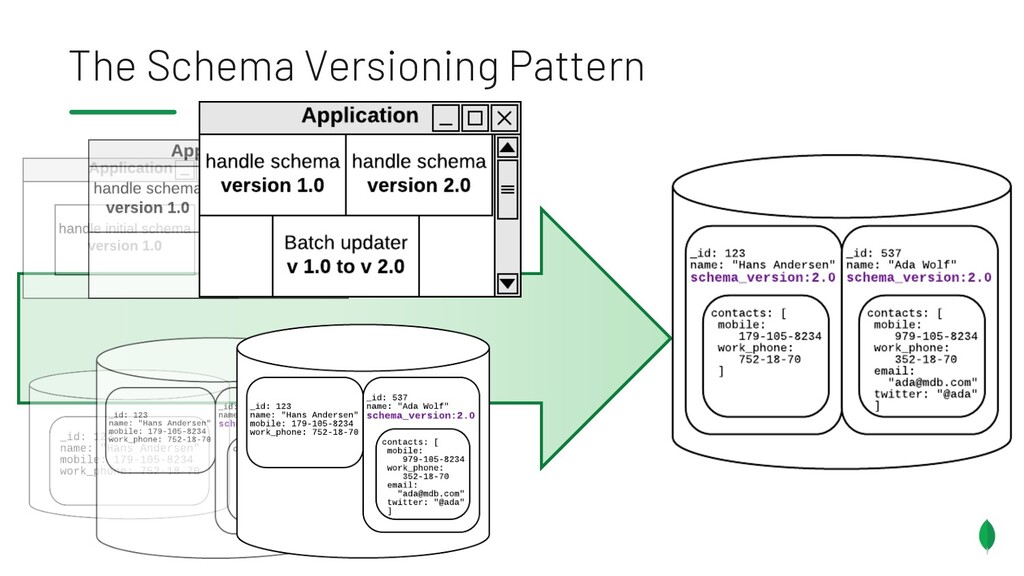
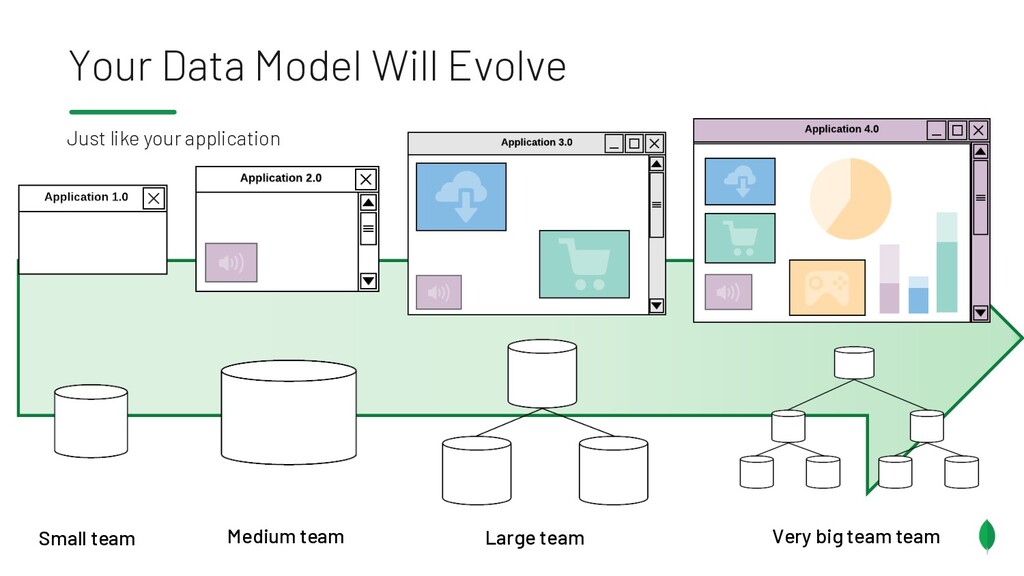
Data model is defined at the application level Design is part of each phase of the application lifetime What affects the data model: o The data that your application needs o Application’s read and write usage of the data
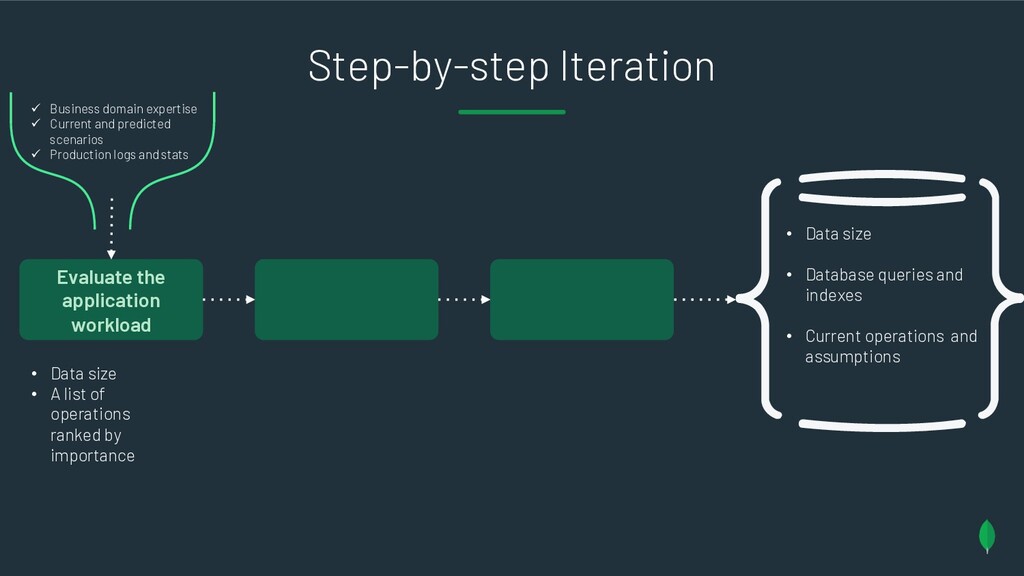
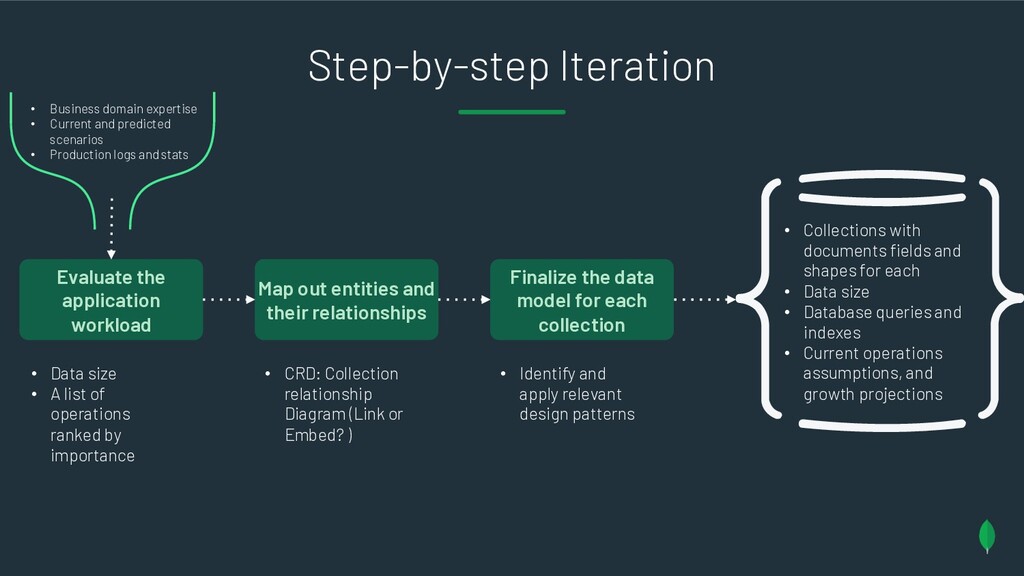
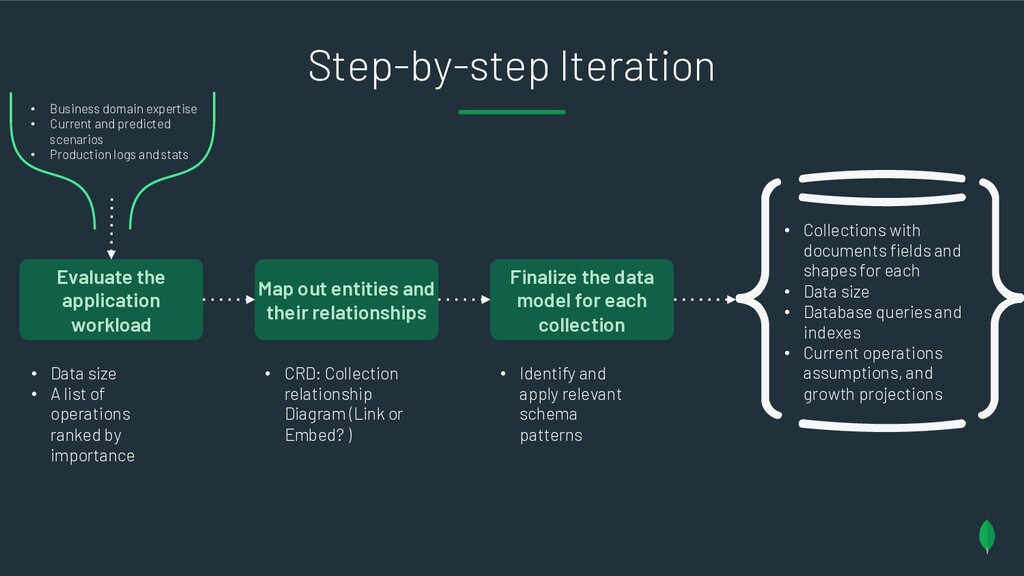
of operations ranked by importance Step-by-step Iteration • Data size • Database queries and indexes • Current operations and assumptions ü Business domain expertise ü Current and predicted scenarios ü Production logs and stats
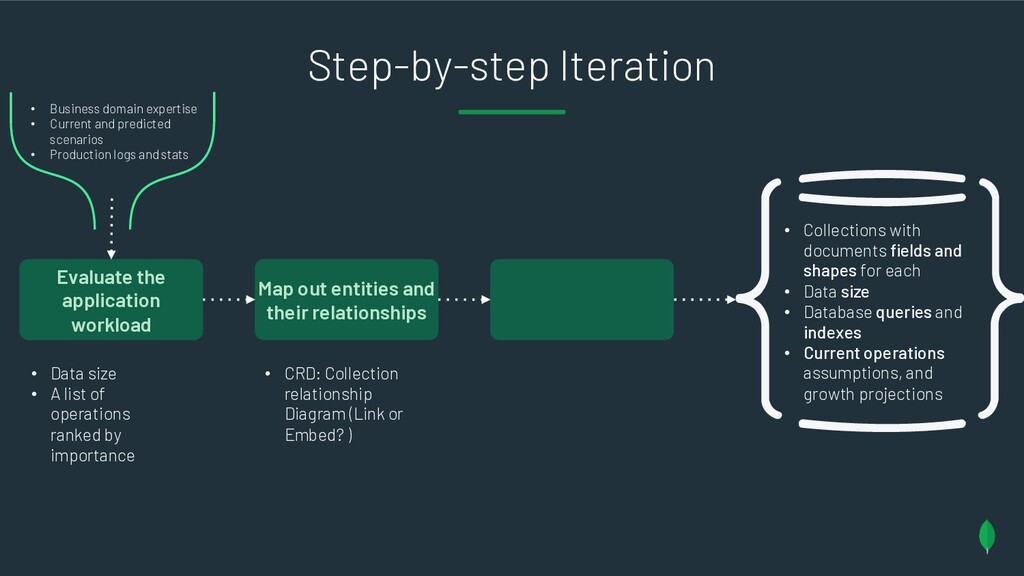
• Data size • A list of operations ranked by importance • CRD: Collection relationship Diagram (Link or Embed? ) Step-by-step Iteration • Data size • Database queries and indexes • Current operations and assumptions • Business domain expertise • Current and predicted scenarios • Production logs and stats
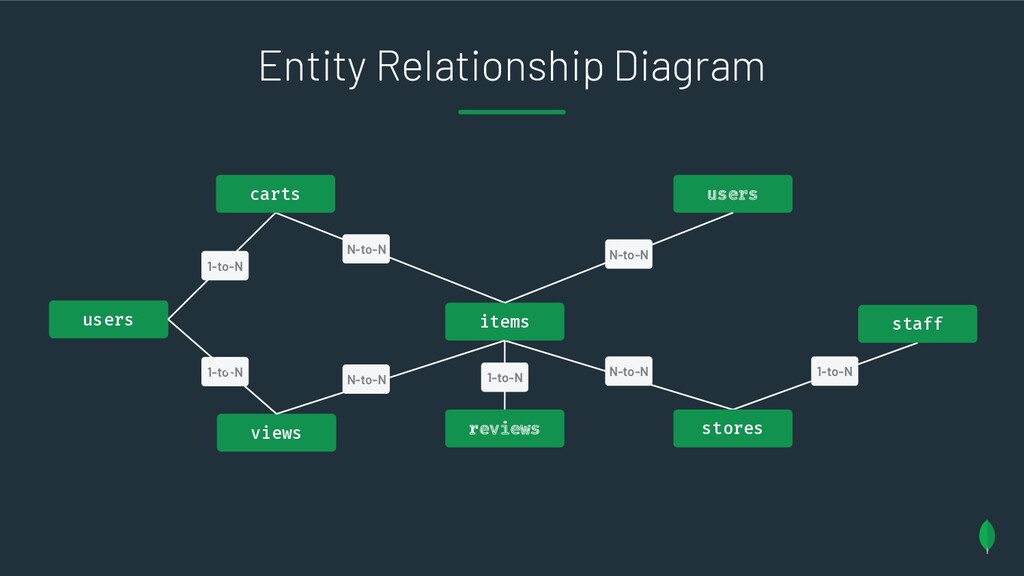
Many-to-many Example: Entities and relationships in a Blog users • name • email 1-to-N articles • title • date • text tags • name • url categories • name • url comments • name • url N-to-N 1-to-N N-to-N 1-to-N
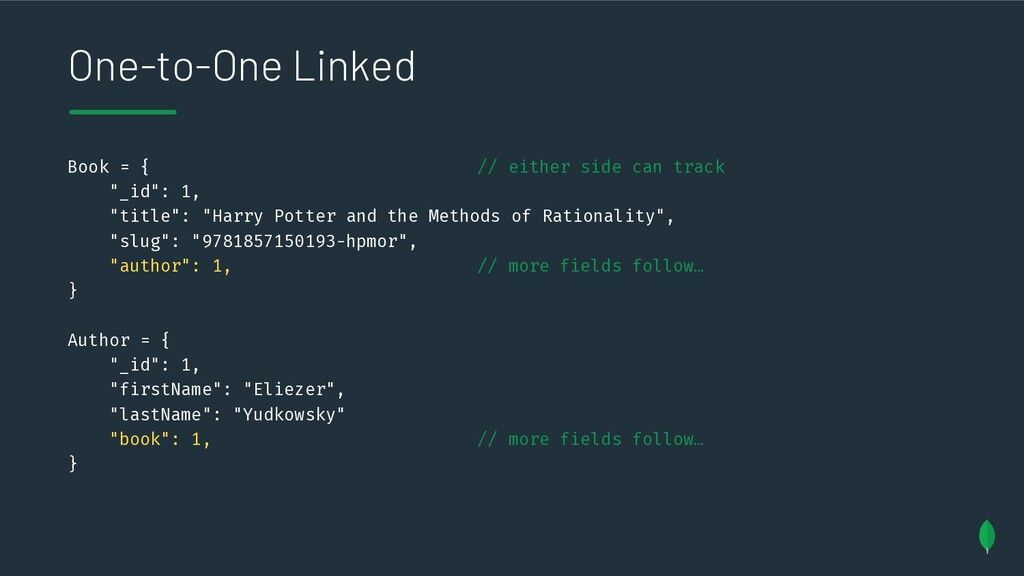
"_id": 1, "title": "Harry Potter and the Methods of Rationality", "slug": "9781857150193-hpmor", "author": 1, // more fields follow… } Author = { "_id": 1, "firstName": "Eliezer", "lastName": "Yudkowsky" "book": 1, // more fields follow… }
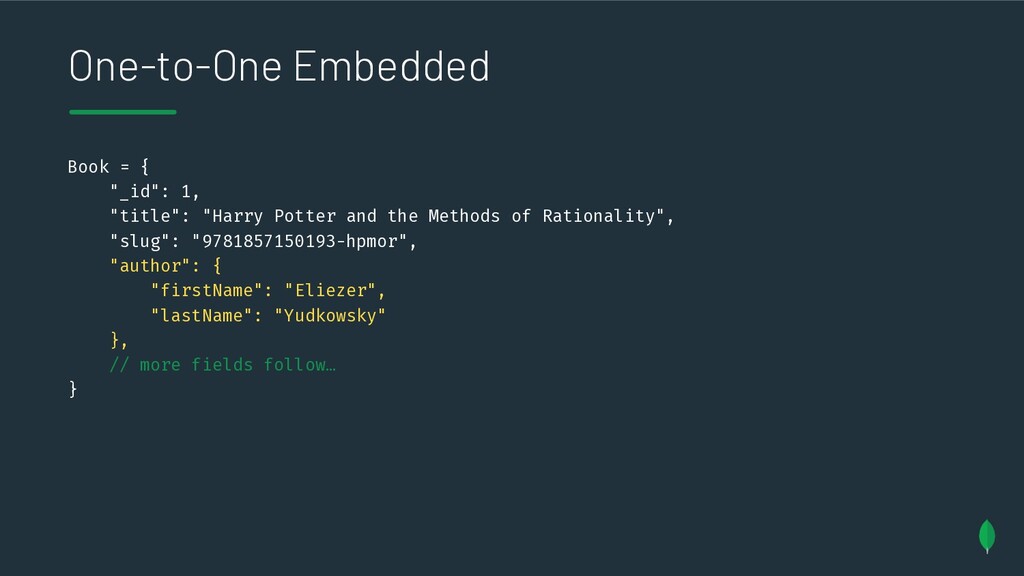
and the Methods of Rationality", "slug": "9781857150193-hpmor", "author": { "firstName": "Eliezer", "lastName": "Yudkowsky" }, // more fields follow… }
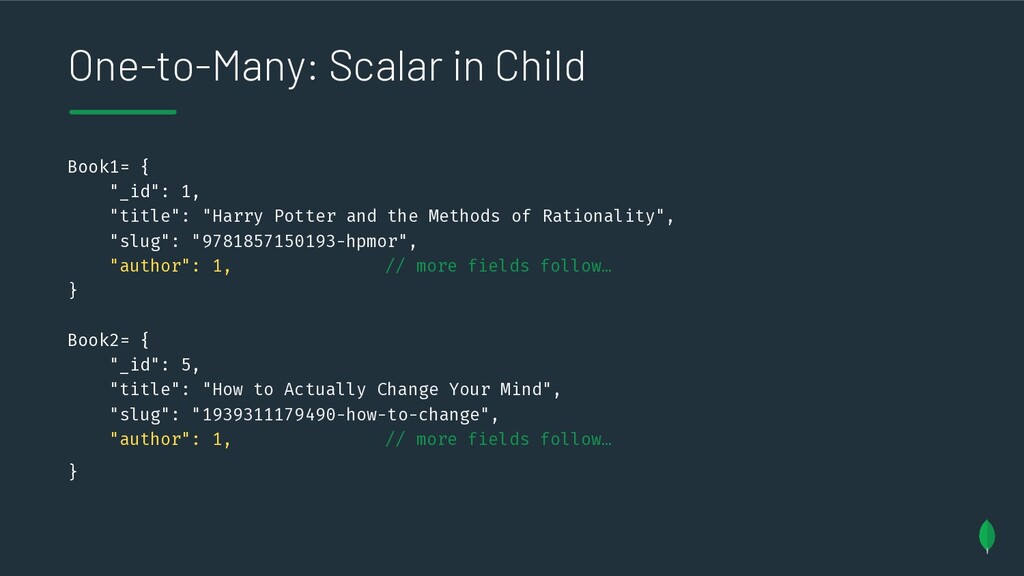
Potter and the Methods of Rationality", "slug": "9781857150193-hpmor", "author": 1, // more fields follow… } Book2= { "_id": 5, "title": "How to Actually Change Your Mind", "slug": "1939311179490-how-to-change", "author": 1, // more fields follow… }
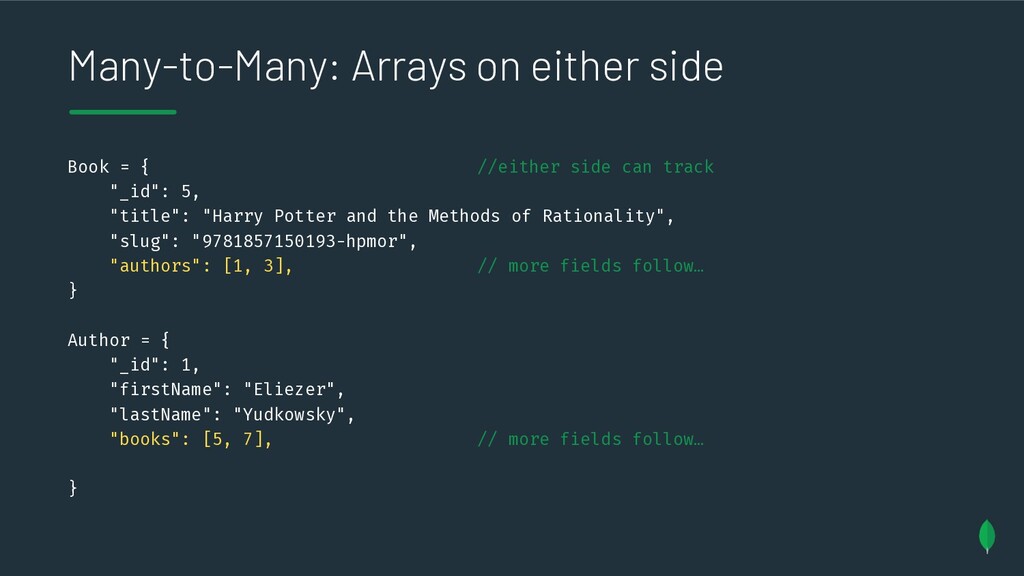
can track "_id": 5, "title": "Harry Potter and the Methods of Rationality", "slug": "9781857150193-hpmor", "authors": [1, 3], // more fields follow… } Author = { "_id": 1, "firstName": "Eliezer", "lastName": "Yudkowsky", "books": [5, 7], // more fields follow… }
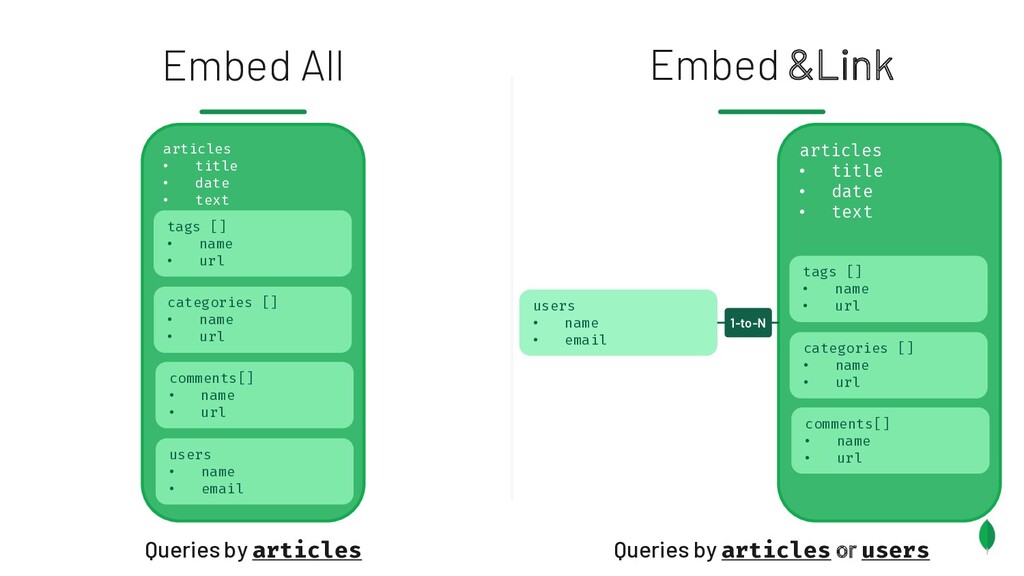
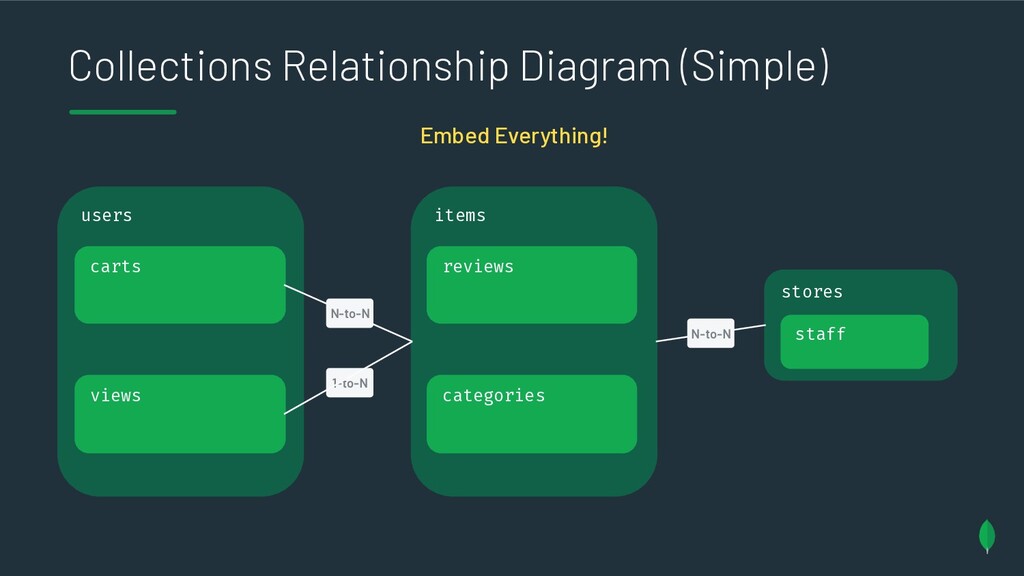
Embed All articles • title • date • text articles • title • date • text tags [] • name • url categories [] • name • url comments[] • name • url users • name • email tags [] • name • url categories [] • name • url comments[] • name • url users • name • email 1-to-N
Finalize the data model for each collection • Data size • A list of operations ranked by importance • CRD: Collection relationship Diagram (Link or Embed? ) • Identify and apply relevant design patterns Step-by-step Iteration • Collections with documents fields and shapes for each • Data size • Database queries and indexes • Current operations assumptions, and growth projections • Business domain expertise • Current and predicted scenarios • Production logs and stats
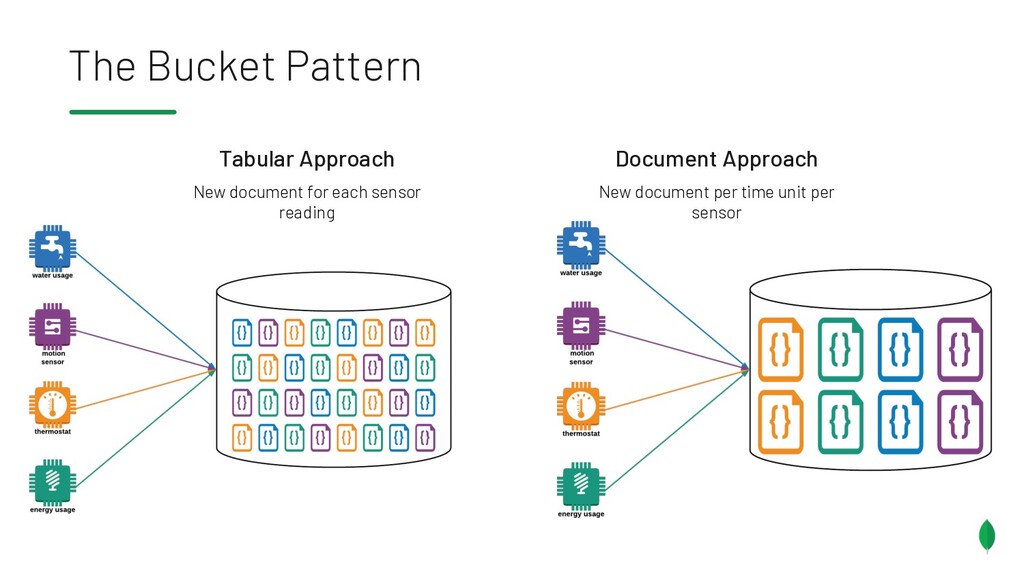
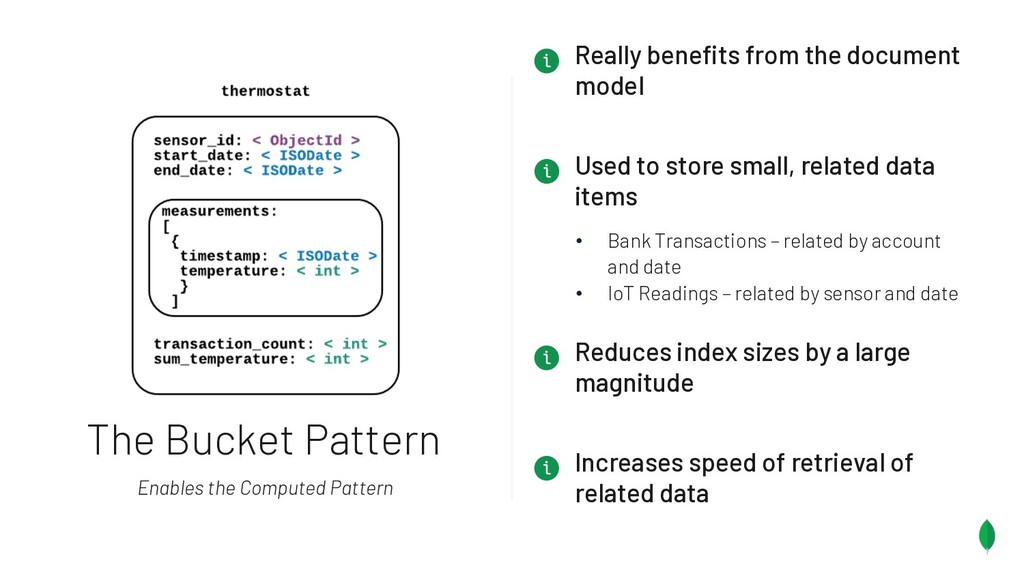
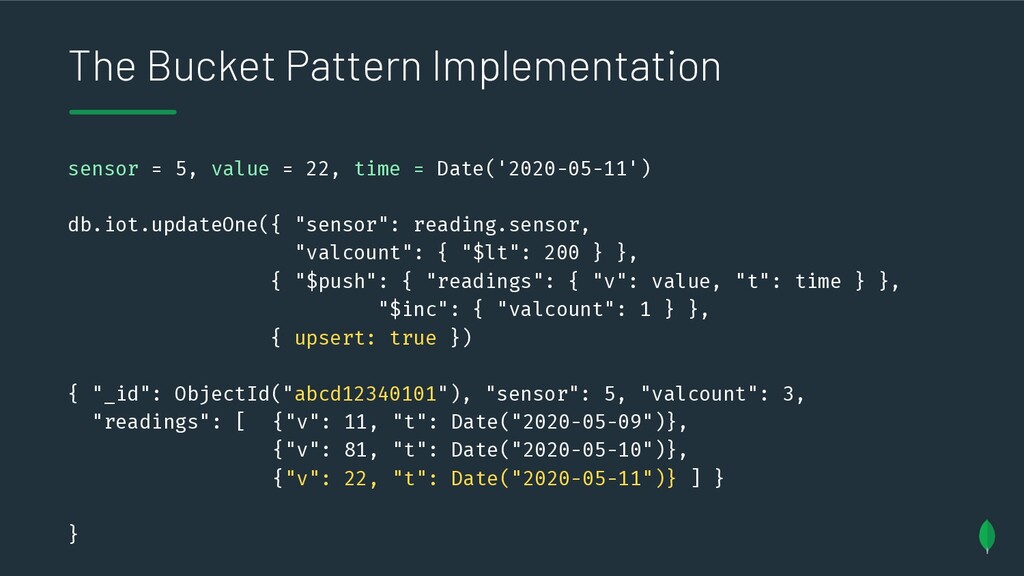
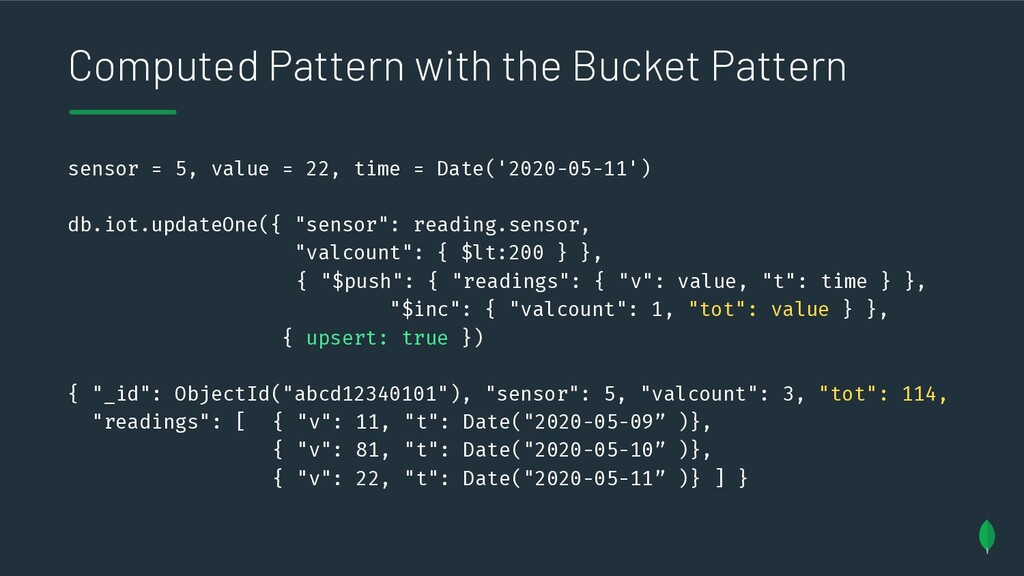
to store small, related data items • Bank Transactions – related by account and date • IoT Readings – related by sensor and date Reduces index sizes by a large magnitude Increases speed of retrieval of related data Enables the Computed Pattern
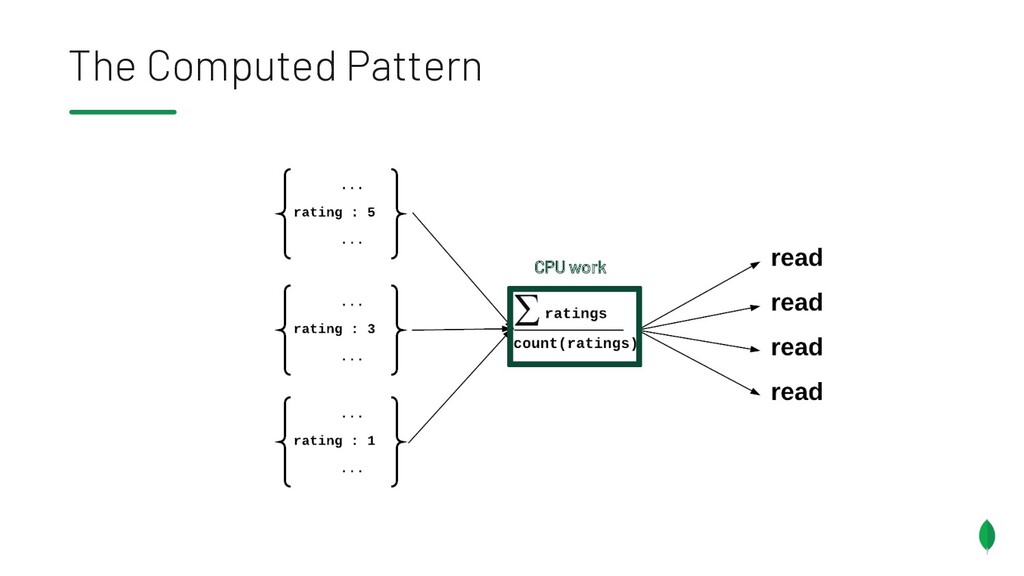
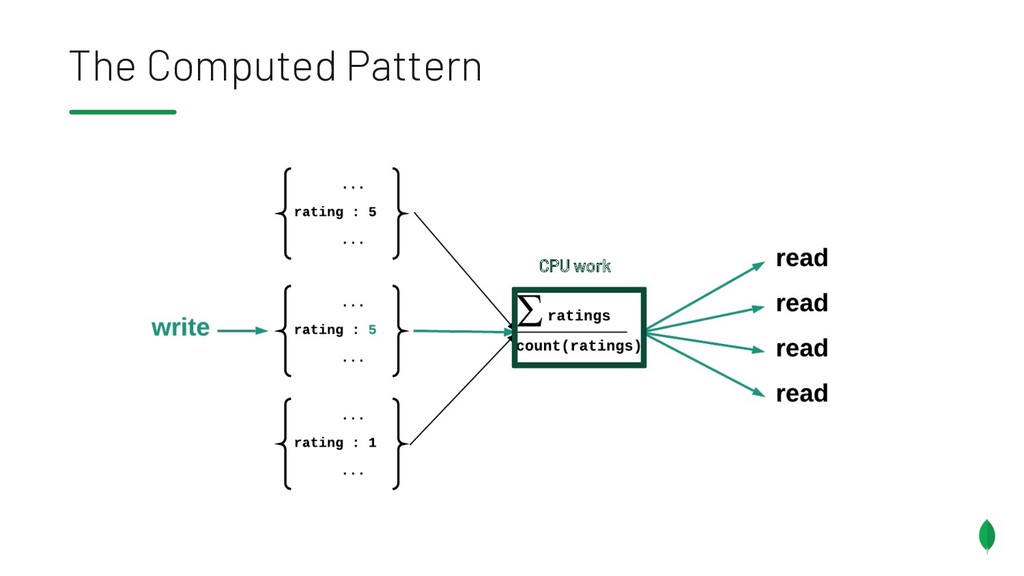
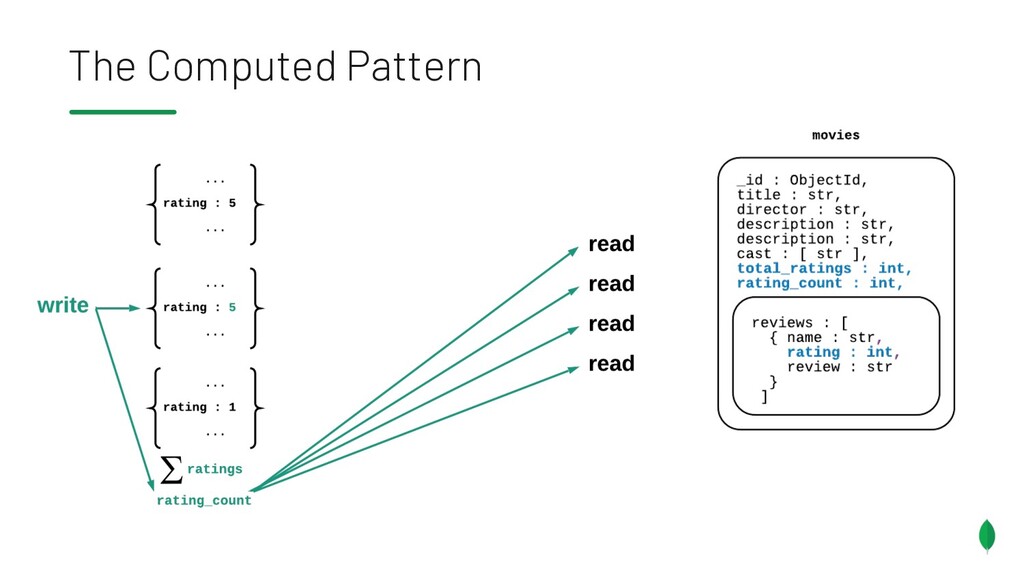
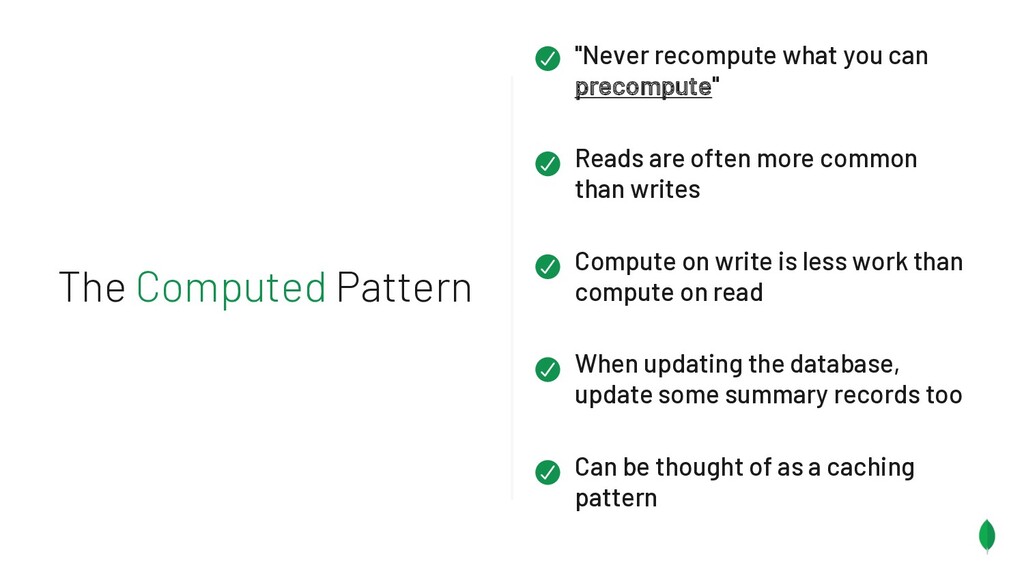
are often more common than writes When updating the database, update some summary records too Can be thought of as a caching pattern Compute on write is less work than compute on read
Developer Portal and MongoDB University are all great resources to continue learning about data modeling and patterns. Design Patterns: Elements of Reusable Object- Oriented Software – a book! Other talks at this conference: • Advanced Schema Design Patterns • A Complete Methodology to Data Modeling • Using JSON Schema to Save Lives • Attribute Pattern and the Wildcard Index: Is the Attribute Pattern Obsolete? Learning
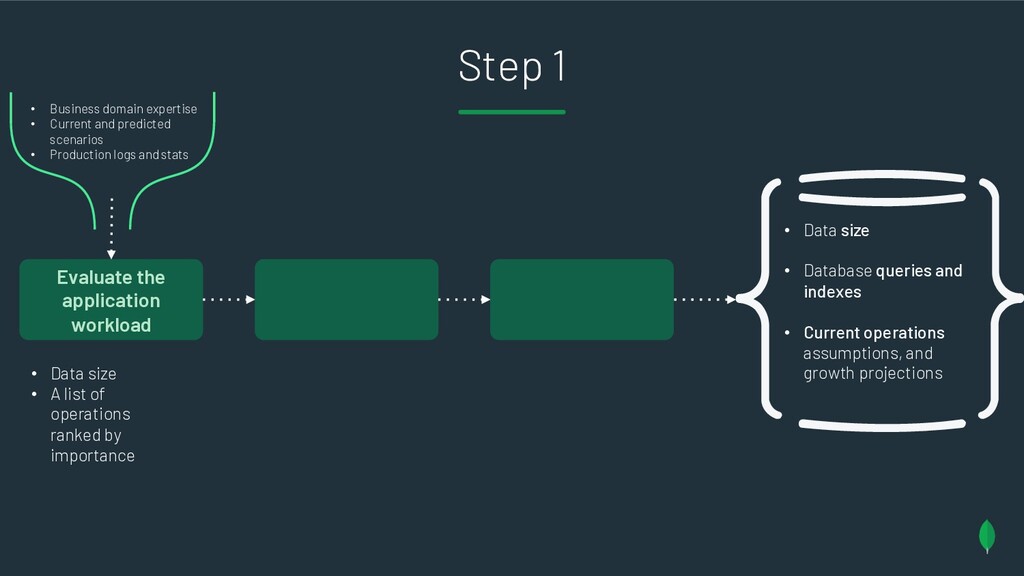
of operations ranked by importance Step 1 • Business domain expertise • Current and predicted scenarios • Production logs and stats • Data size • Database queries and indexes • Current operations assumptions, and growth projections
Million user accounts Analytics • 500 thousand new accounts per week • Logging in 20 times a year • Looking up 100 items per year • Creating 5 carts per year • Reviewing 2 items per year 50 employees per stores 1 store lookup per customer per year 100 reviews per item 500 thousand updates per day Placing 4 items in the cart Buying an average of 2 items per cart 10 data scientists each running 10 queries a day
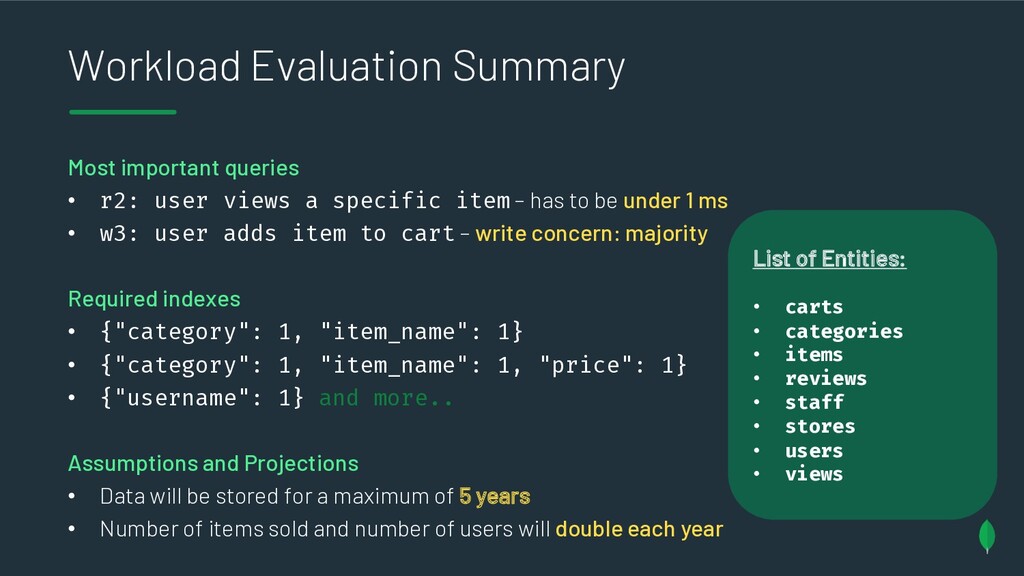
a specific item – has to be under 1 ms • w3: user adds item to cart – write concern: majority Required indexes • {"category": 1, "item_name": 1} • {"category": 1, "item_name": 1, "price": 1} • {"username": 1} and more.. Assumptions and Projections • Data will be stored for a maximum of 5 years • Number of items sold and number of users will double each year List of Entities: • carts • categories • items • reviews • staff • stores • users • views
• Data size • A list of operations ranked by importance • CRD: Collection relationship Diagram (Link or Embed? ) Step-by-step Iteration • Business domain expertise • Current and predicted scenarios • Production logs and stats • Collections with documents fields and shapes for each • Data size • Database queries and indexes • Current operations assumptions, and growth projections
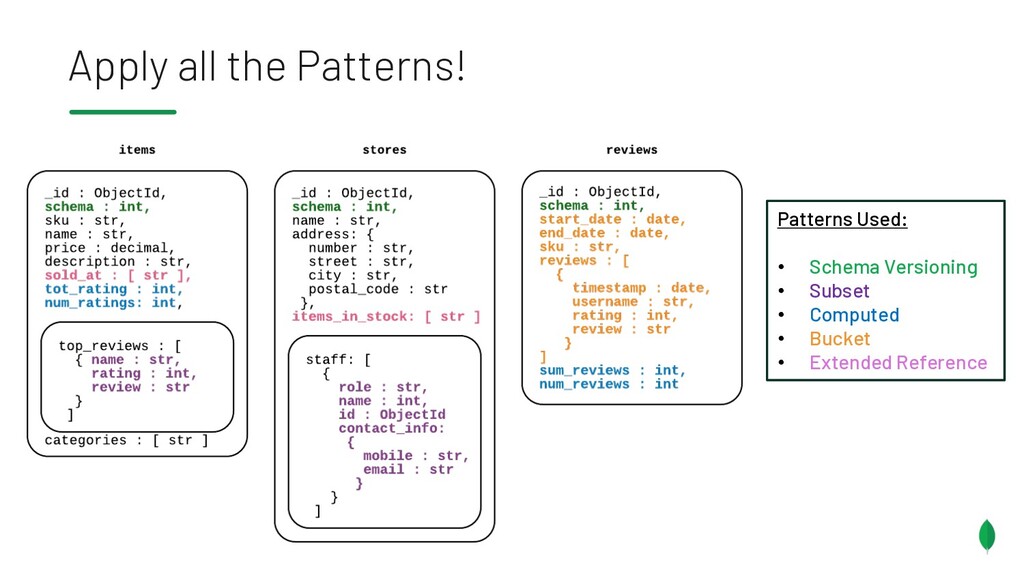
Finalize the data model for each collection • Data size • A list of operations ranked by importance • CRD: Collection relationship Diagram (Link or Embed? ) • Identify and apply relevant schema patterns Step-by-step Iteration • Business domain expertise • Current and predicted scenarios • Production logs and stats • Collections with documents fields and shapes for each • Data size • Database queries and indexes • Current operations assumptions, and growth projections
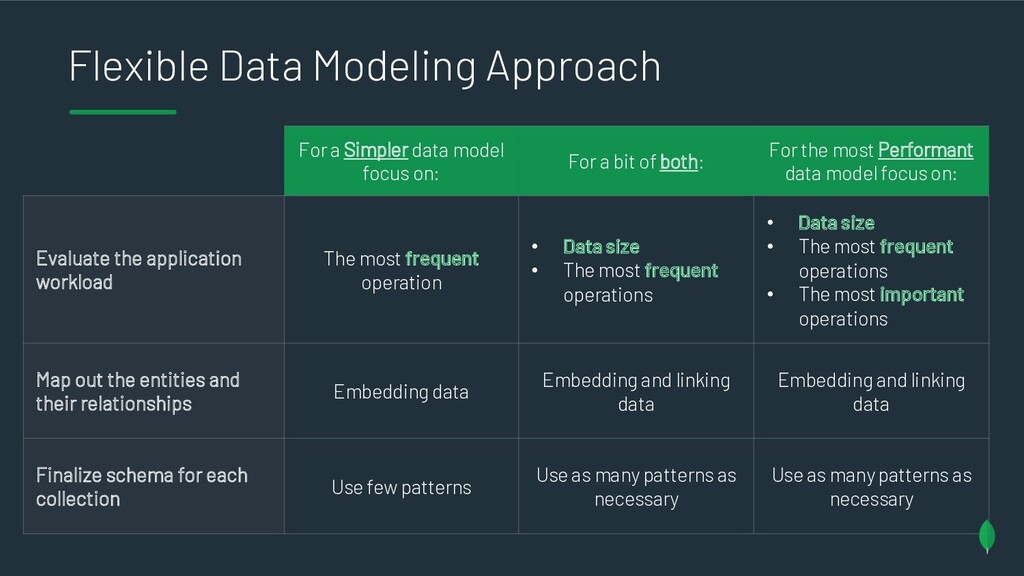
on: For a bit of both: For the most Performant data model focus on: Evaluate the application workload The most frequent operation • Data size • The most frequent operations • Data size • The most frequent operations • The most important operations Map out the entities and their relationships Embedding data Embedding and linking data Embedding and linking data Finalize schema for each collection Use few patterns Use as many patterns as necessary Use as many patterns as necessary


 codatum
 kworkdev
 glaforge
 yuuuuuuu168
 jyouryuusui
 jtakeda
 pfn
 kash1064
 willnet
 greenmidori
 yahonda
 endonanana
 shlominoach
 akademiya2063
 bcantrill
 wjessup
 aleyda
 moore
 honzajavorek
 palkan
 addyosmani
 eileencodes
 pwiseman