Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
Direct Preference Optimization
Search
Henry Cui
February 24, 2024
Science
490
0
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
Direct Preference Optimization
Henry Cui
February 24, 2024
More Decks by Henry Cui
See All by Henry Cui
プロダクション言語モデルの情報を盗む攻撃 / Stealing Part of a Production Language Model
zchenry
1
260
Diffusion Model with Perceptual Loss
zchenry
0
540
レンズの下のLLM / LLM under the Lens
zchenry
0
250
Go with the Prompt Flow
zchenry
0
260
Mojo Dojo
zchenry
0
290
ことのはの力で画像の異常検知 / Anomaly Detection by Language
zchenry
0
770
驚愕の事実!LangChainが抱える問題 / Problems of LangChain
zchenry
0
350
MLOps初心者がMLflowを触る / MLflow Brief Introduction
zchenry
0
230
{{guidance}}のガイダンス / Guidance of guidance
zchenry
0
220
Other Decks in Science
See All in Science
Cross-Media Technologies, Information Science and Human-Information Interaction
signer
PRO
3
33k
機械学習 - SVM
trycycle
PRO
2
1.3k
HOLO: Homography-Guided Pose Estimator Network for Fine-Grained Visual Localization on SD Maps
tomoaki0705
0
170
現代AI入門: 大規模言語モデルから思考するシステムへ — Test-Time Scaling, Loop, Harness, RSI
stillpedant
PRO
31
16k
Wet Active Matter
rajeshrinet
0
260
科学で迫る勝敗の法則-スポーツデータ分析の最前線 (刈谷市連携講座.2026年7月) / The principle of victory discovered by science. at Kariya City, 2027.07
konakalab
0
210
機械学習 - K-means & 階層的クラスタリング
trycycle
PRO
0
2.3k
白金鉱業Meetup Vol.25 【初学者向け発表枠】「で、この施策って効いてるの」に答える効果検証の基礎 ~ATE / ATT / CATE / LATEを現場の問いに翻訳する~
brainpadpr
1
380
暗号解読における量子計算の展望
neutron63zf
0
480
医療 LLM ベンチマークの現在地:多面的評価 と日本ローカライズ
analokmaus
1
770
Massey Ratings for Match Outcome Prediction in Table Tennis: Evidence of Greater Stability than the ITTF World Ranking
konakalab
0
180
明治薬科大学講義_ビッグデータ解析を支えるデータベース技術とクラウドコンピューティング
ktatsuya
1
200
Featured
See All Featured
The browser strikes back
jonoalderson
0
1.9k
GraphQLとの向き合い方2022年版
quramy
50
15k
How Software Deployment tools have changed in the past 20 years
geshan
2
35k
Scaling GitHub
holman
464
140k
How To Speak Unicorn (iThemes Webinar)
marktimemedia
1
610
Code Review Best Practice
trishagee
74
20k
10 Git Anti Patterns You Should be Aware of
lemiorhan
PRO
659
62k
Being A Developer After 40
akosma
PRO
92
590k
Designing for Performance
lara
612
70k
The Cost Of JavaScript in 2023
addyosmani
55
10k
Breaking role norms: Why Content Design is so much more than writing copy - Taylor Woolridge
uxyall
1
460
Max Prin - Stacking Signals: How International SEO Comes Together (And Falls Apart)
techseoconnect
PRO
0
500
Transcript
Direct Preference Optimization 機械学習の社会実装勉強会第32回 Henry 2024/2/24
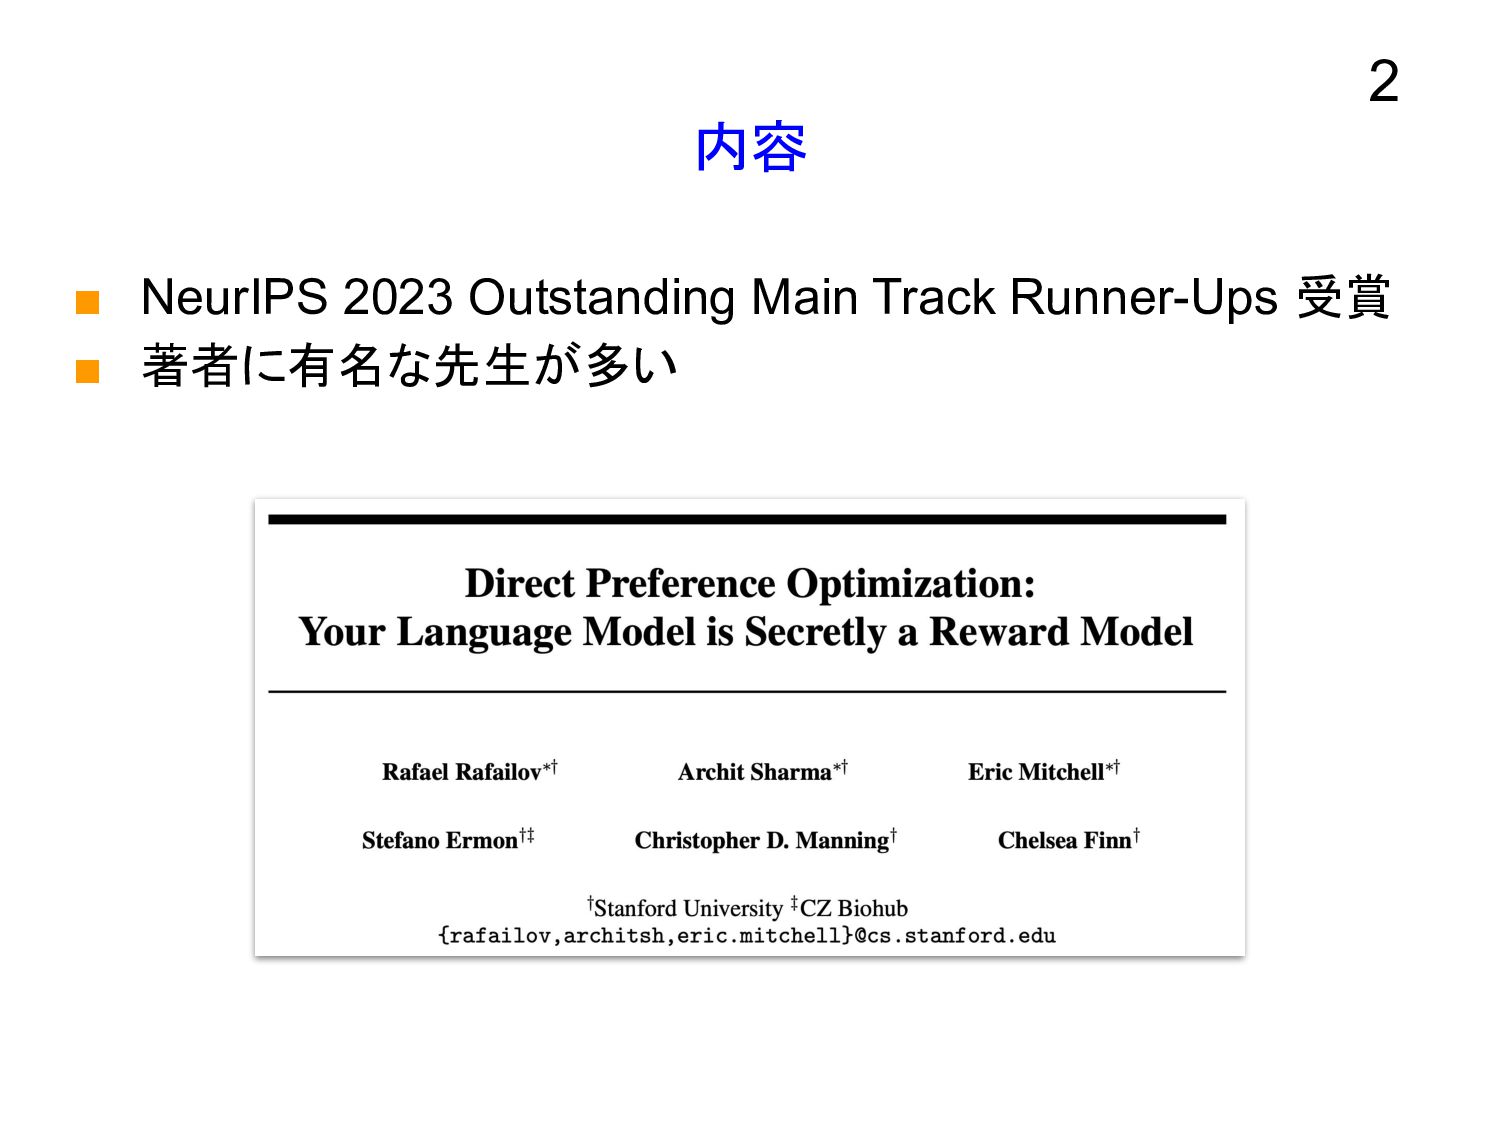
内容 ▪ NeurIPS 2023 Outstanding Main Track Runner-Ups 受賞 ▪
著者に有名な先生が多い 2
モチベーション ▪ 大量テキストで学習した言語モデルを望ましい挙動に微調整 する必要(Alignment) • 大量コードの平均能力でなく、少量存在の優れたコードに • 一般大衆のもつ誤認識でなく、それを修正すべき ▪ Alignmentを達成するために、現状2段階の複雑な強化学習
手法を使うので、それと理論上等価なシンプルな手法を提案 3
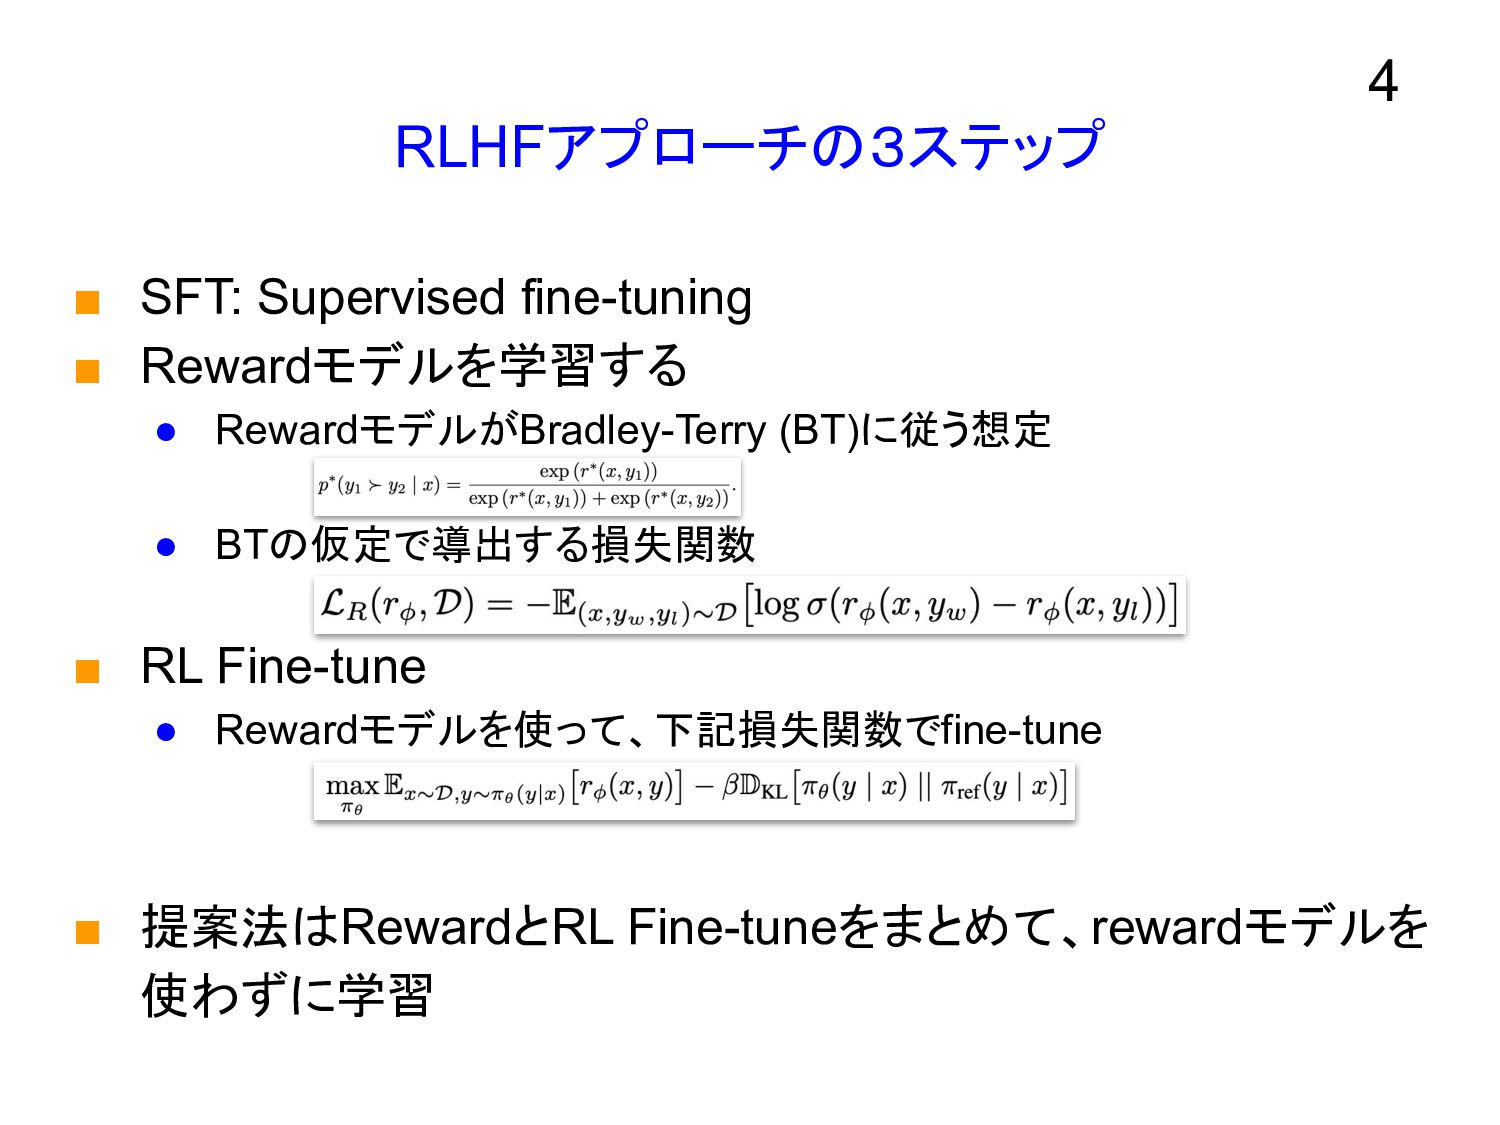
RLHFアプローチの3ステップ ▪ SFT: Supervised fine-tuning ▪ Rewardモデルを学習する • RewardモデルがBradley-Terry (BT)に従う想定
• BTの仮定で導出する損失関数 ▪ RL Fine-tune • Rewardモデルを使って、下記損失関数でfine-tune ▪ 提案法はRewardとRL Fine-tuneをまとめて、rewardモデルを 使わずに学習 4
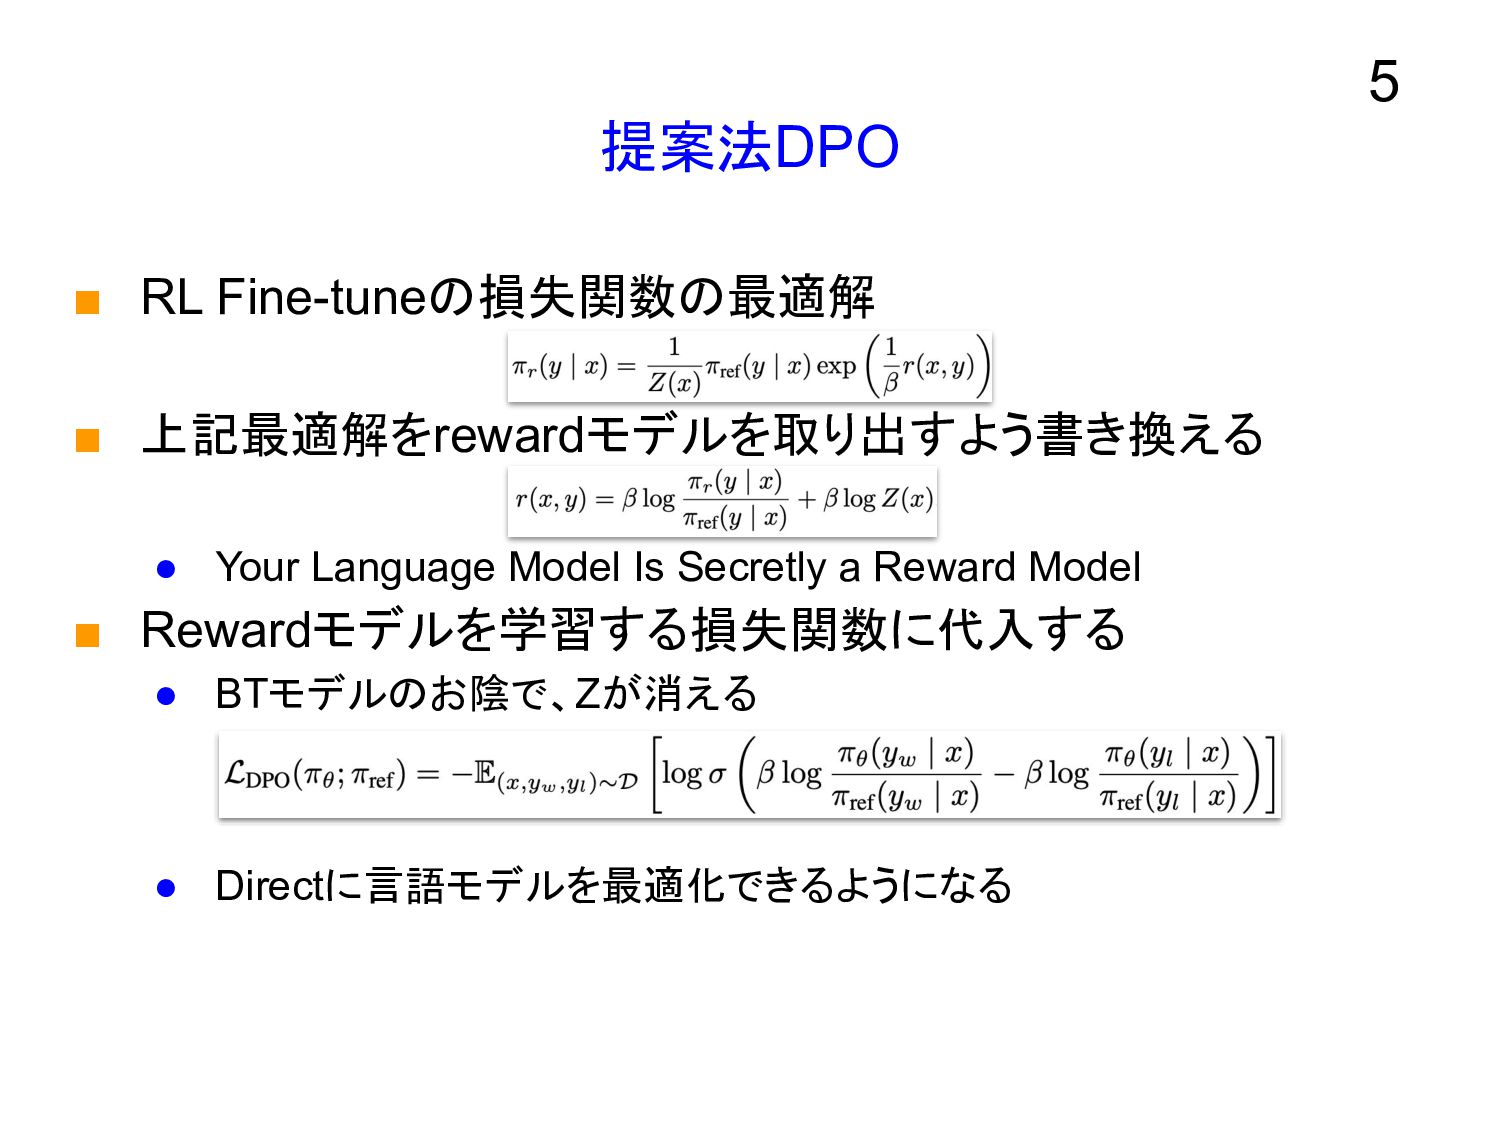
提案法DPO ▪ RL Fine-tuneの損失関数の最適解 ▪ 上記最適解をrewardモデルを取り出すよう書き換える • Your Language Model
Is Secretly a Reward Model ▪ Rewardモデルを学習する損失関数に代入する • BTモデルのお陰で、Zが消える • Directに言語モデルを最適化できるようになる 5
実験 ▪ 3つのタスクで評価 • controlled sentiment generation • summarization •
single-turn dialogue ▪ 複数スケールのデータセットでRHLFと同等またはそれ以上の 性能を確認 ▪ 多数のオープンソース言語モデルに実装 6


 zchenry
 signer
 trycycle
 tomoaki0705
 stillpedant
 rajeshrinet
 konakalab
 brainpadpr
 neutron63zf
 analokmaus
 ktatsuya
 jonoalderson
 quramy
 geshan
 holman
 marktimemedia
 trishagee
 lemiorhan
 akosma
 lara
 addyosmani
 uxyall
 techseoconnect