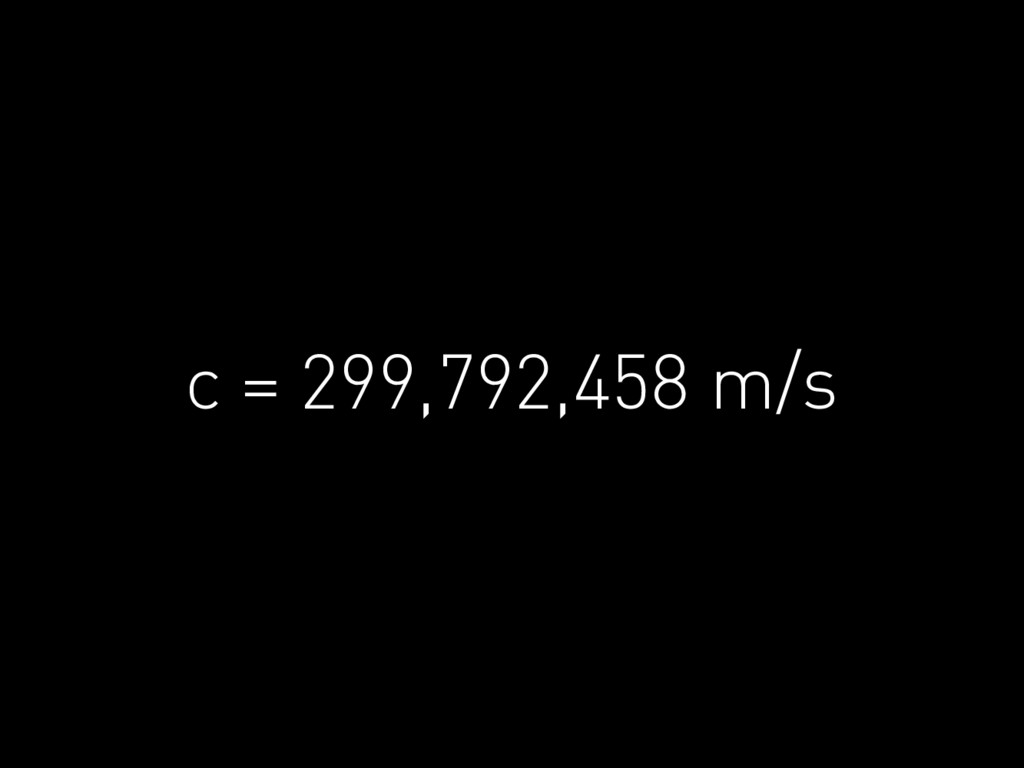Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
Scaling Django with Distributed Systems
Search
Sponsored
·
Ship Features Fearlessly
Turn features on and off without deploys. Used by thousands of Ruby developers.
→
Andrew Godwin
April 07, 2017
Programming
2.4k
3
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
Scaling Django with Distributed Systems
A talk I gave at PyCon Ukraine 2017.
Andrew Godwin
April 07, 2017
More Decks by Andrew Godwin
See All by Andrew Godwin
Reconciling Everything
andrewgodwin
1
420
Django Through The Years
andrewgodwin
0
340
Writing Maintainable Software At Scale
andrewgodwin
0
550
A Newcomer's Guide To Airflow's Architecture
andrewgodwin
0
430
Async, Python, and the Future
andrewgodwin
2
770
How To Break Django: With Async
andrewgodwin
1
850
Taking Django's ORM Async
andrewgodwin
0
880
The Long Road To Asynchrony
andrewgodwin
0
790
The Scientist & The Engineer
andrewgodwin
1
880
Other Decks in Programming
See All in Programming
【加筆修正版】Laravel のアプリケーションをどこにデプロイするか #phpcon_ehime
akase244
0
150
コードレビューのボトルネックを"する側"と"される側"の両面から解消する
yub0n
2
1.6k
UnityでSystem.Net.WebSocketsなWebSocketサーバが動かないのでUnity Monoのコードを覗いてみた / about implementing websocket server with unity mono
drumath2237
1
580
When benchmarks go bad - what I learned from measuring performance wrong
hollycummins
0
200
sbt 2.0: takeoff
eed3si9n
0
130
AI が書く Go コードの品質を劇的に向上させる Linter: “declscope”
mpyw
0
490
SREの越境 / SRE Collaboration
y0hgi
2
300
Workers Cache を知る
syumai
0
350
Are APIs Still Relevant in the AI Era?
soyuka
0
450
プロダクトコードからライブラリの境界を見つける
elmetal
PRO
0
110
ハーネス設計入門 〜 基礎知識の整理から実務へのステップアップ 〜
kinopeee
22
22k
KiroのSpecで「五目並べ」を作ってみる
satoshi256kbyte
1
370
Featured
See All Featured
What Being in a Rock Band Can Teach Us About Real World SEO
427marketing
0
1.1k
We Have a Design System, Now What?
morganepeng
55
8.4k
Abbi's Birthday
coloredviolet
4
10k
How to make the Groovebox
asonas
2
2.5k
Gemini Prompt Engineering: Practical Techniques for Tangible AI Outcomes
mfonobong
2
580
Mind Mapping
helmedeiros
1
400
Paper Plane (Part 1)
katiecoart
PRO
2
11k
The AI Revolution Will Not Be Monopolized: How open-source beats economies of scale, even for LLMs
inesmontani
PRO
3
3.8k
The untapped power of vector embeddings
frankvandijk
2
1.9k
Chasing Engaging Ingredients in Design
codingconduct
0
350
How to build an LLM SEO readiness audit: a practical framework
nmsamuel
2
940
Scaling GitHub
holman
464
140k
Transcript
None
Andrew Godwin Hi, I'm Django core developer Senior Software Engineer
at Used to complain about migrations a lot
Distributed Systems
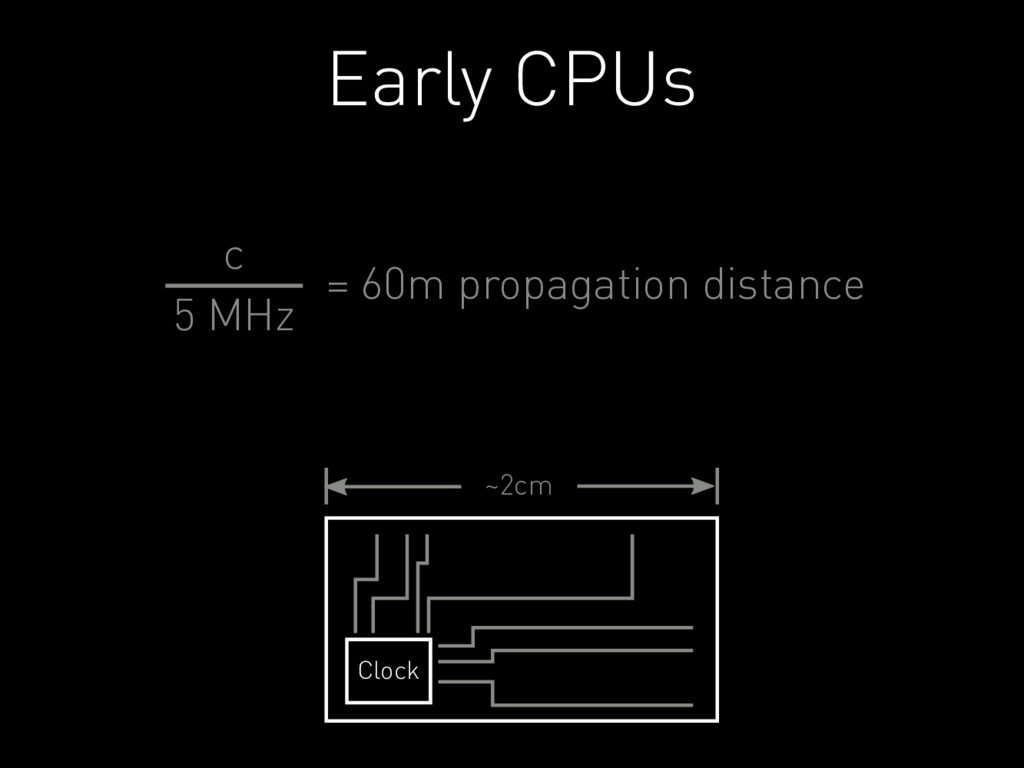
c = 299,792,458 m/s
Early CPUs c = 60m propagation distance Clock ~2cm 5
MHz
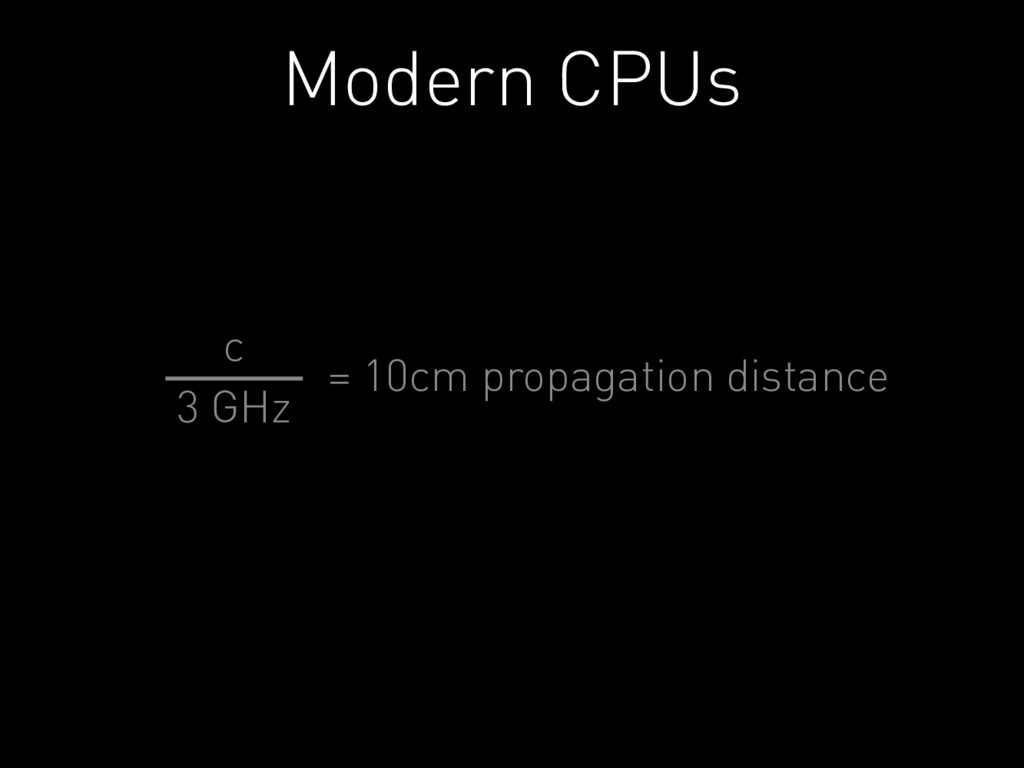
Modern CPUs c = 10cm propagation distance 3 GHz
Distributed systems are made of independent components
They are slower and harder to write than synchronous systems
But they can be scaled up much, much further
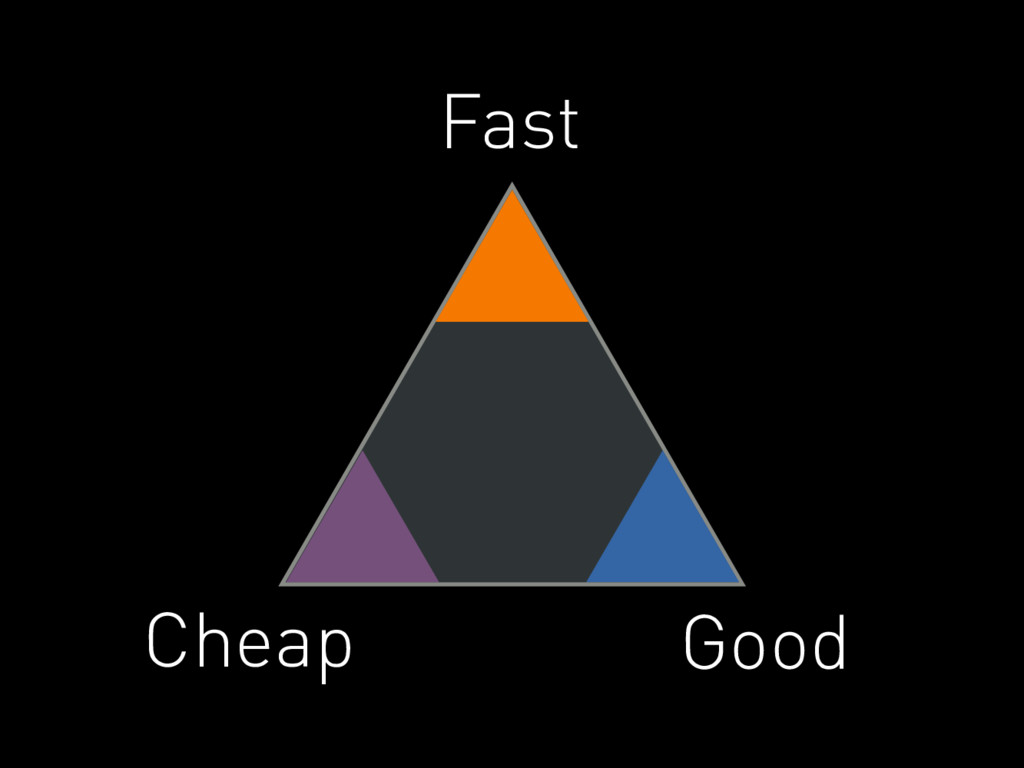
Trade-offs
There is never a perfect solution.
Fast Good Cheap
None
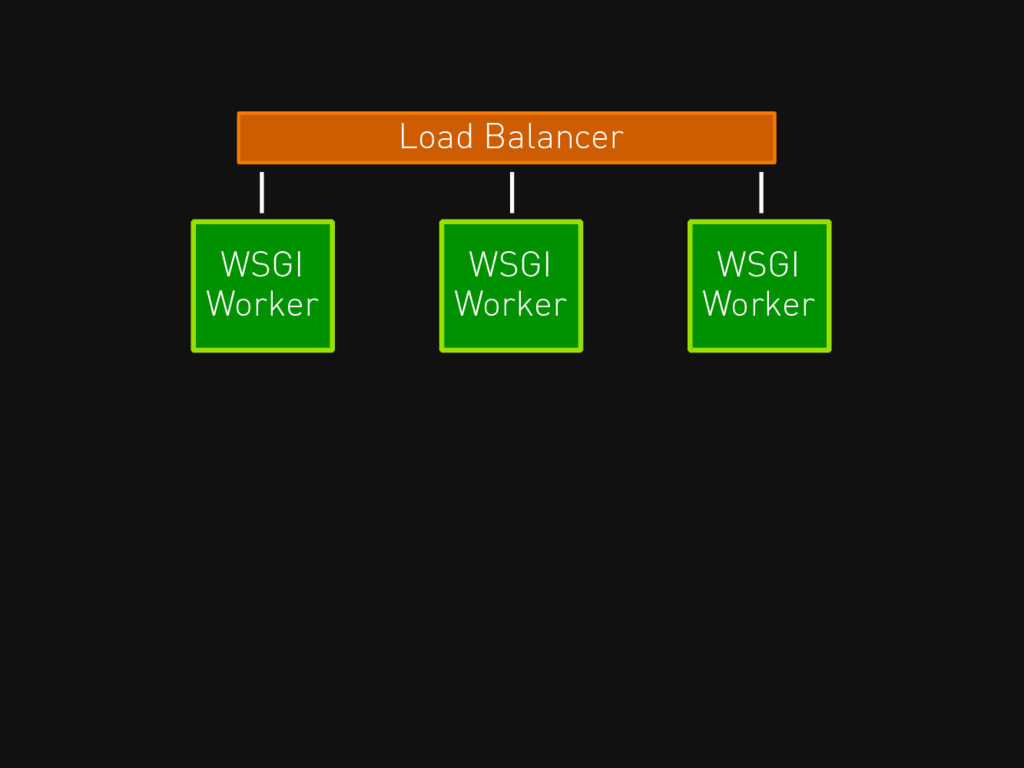
Load Balancer WSGI Worker WSGI Worker WSGI Worker
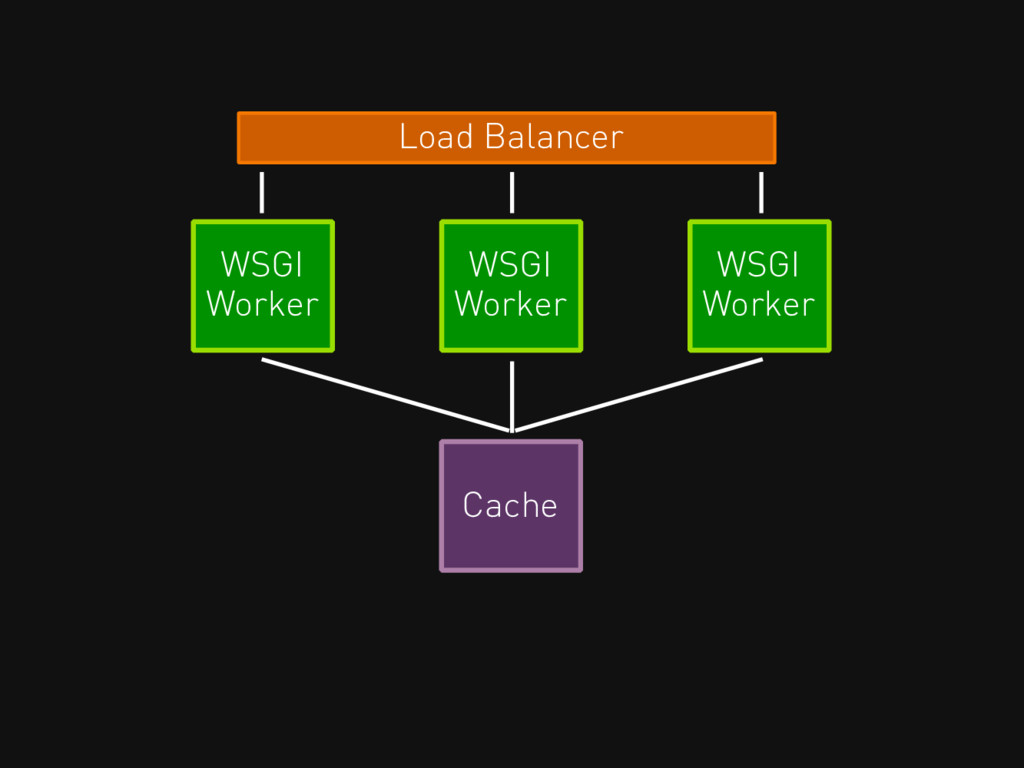
Load Balancer WSGI Worker WSGI Worker WSGI Worker Cache
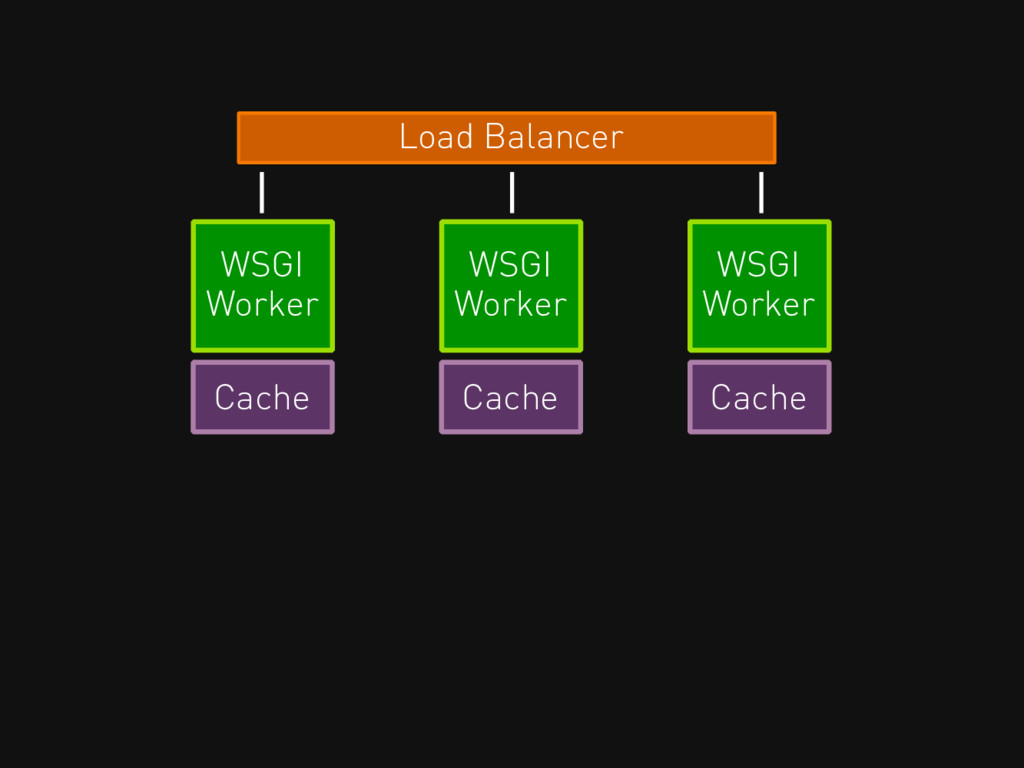
Load Balancer WSGI Worker WSGI Worker WSGI Worker Cache Cache
Cache
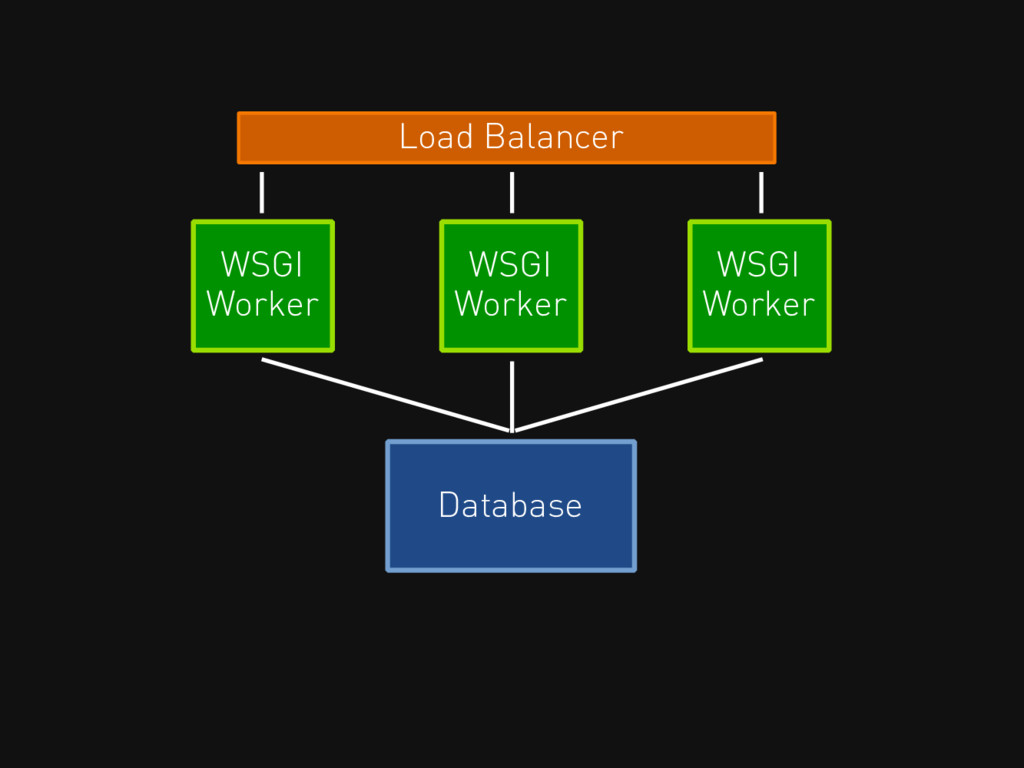
Load Balancer WSGI Worker WSGI Worker WSGI Worker Database
CAP Theorem
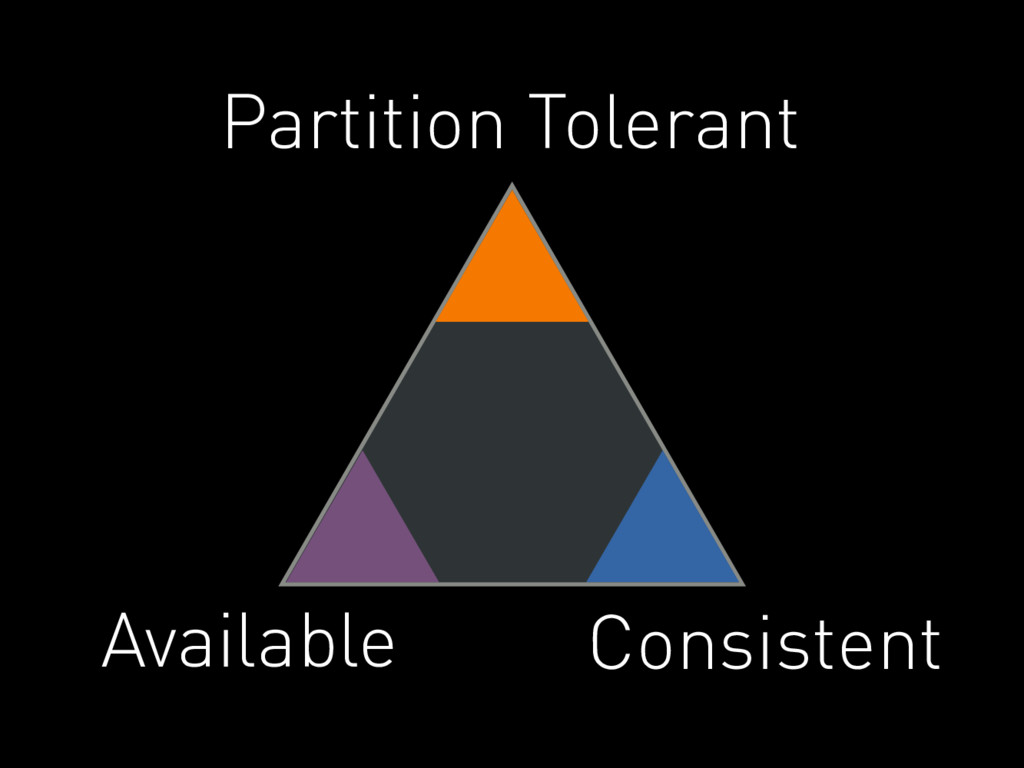
Partition Tolerant Consistent Available
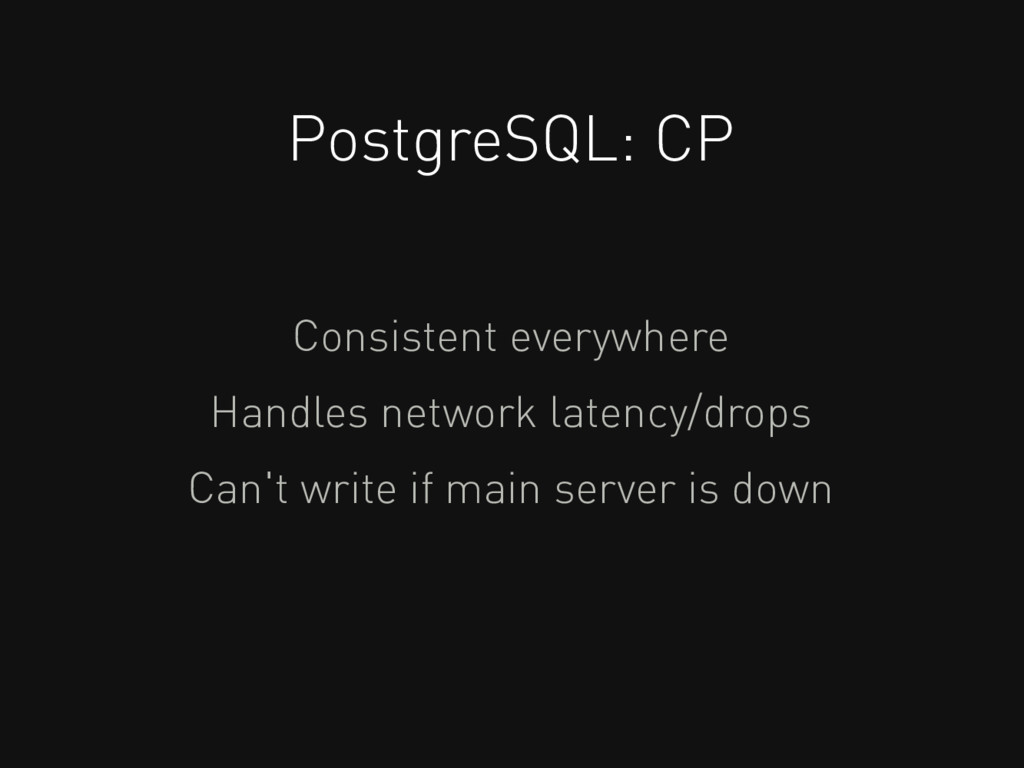
PostgreSQL: CP Consistent everywhere Handles network latency/drops Can't write if
main server is down
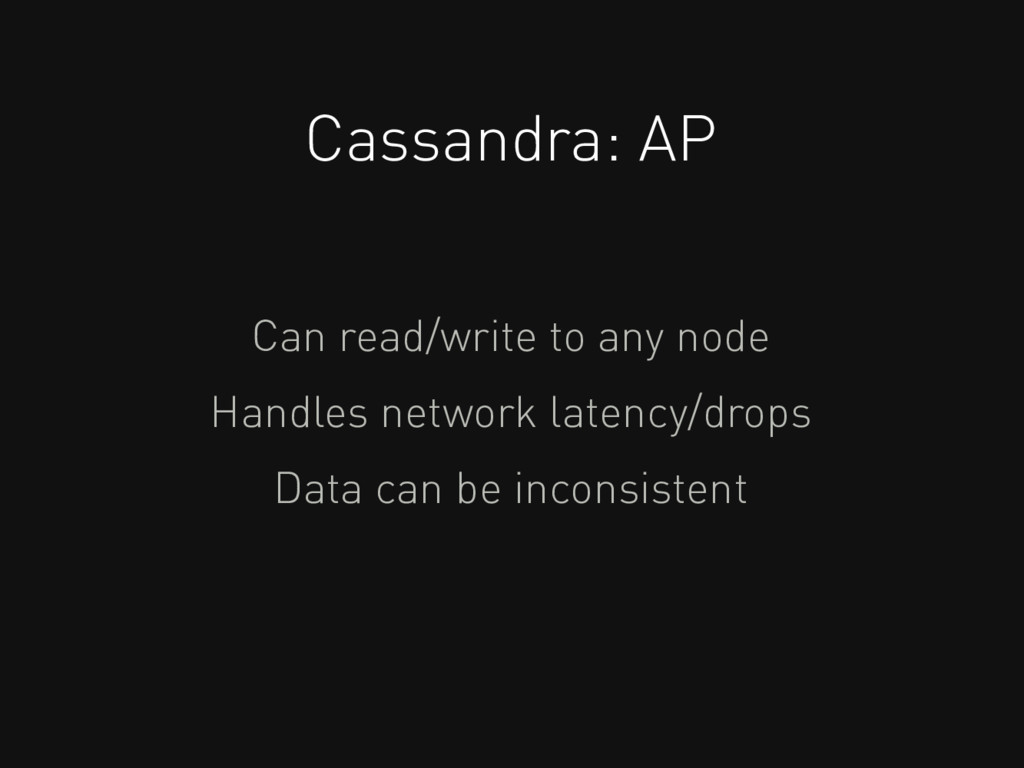
Cassandra: AP Can read/write to any node Handles network latency/drops
Data can be inconsistent
It's hard to design a product that might be inconsistent
But if you take the tradeoff, scaling is easy
Otherwise, you must find other solutions
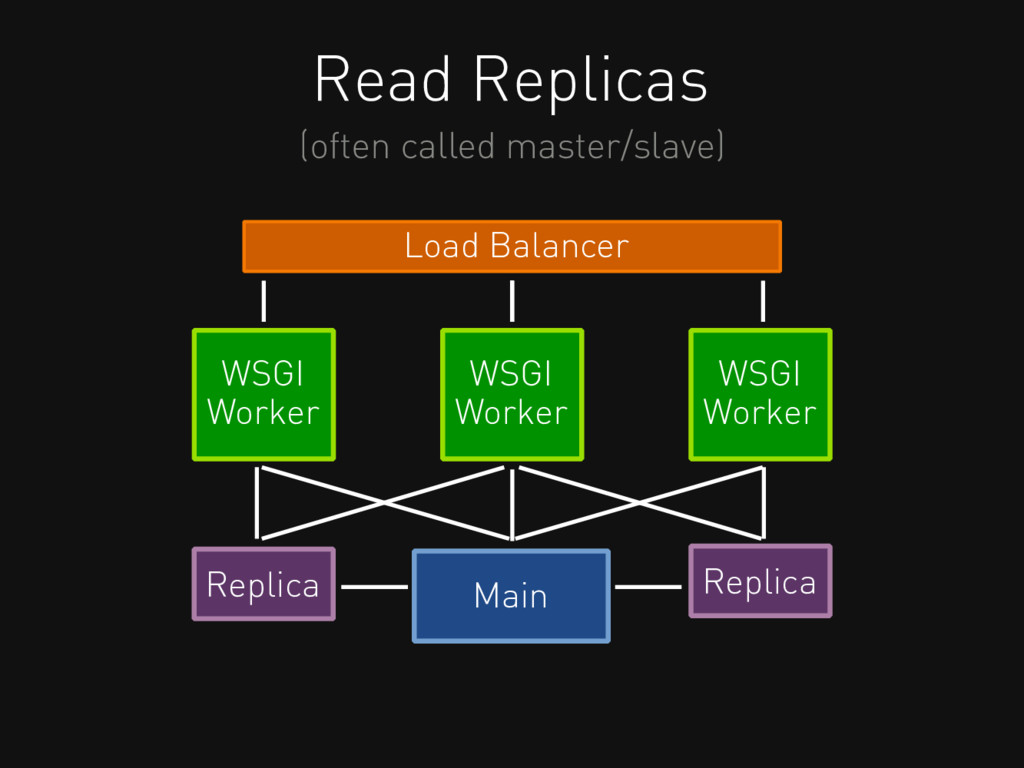
Read Replicas (often called master/slave) Load Balancer WSGI Worker WSGI
Worker WSGI Worker Replica Replica Main
Replicas scale reads forever... But writes must go to one
place
If a request writes to a table it must be
pinned there, so later reads do not get old data
When your write load is too high, you must then
shard
Vertical Sharding Users Tickets Events Payments
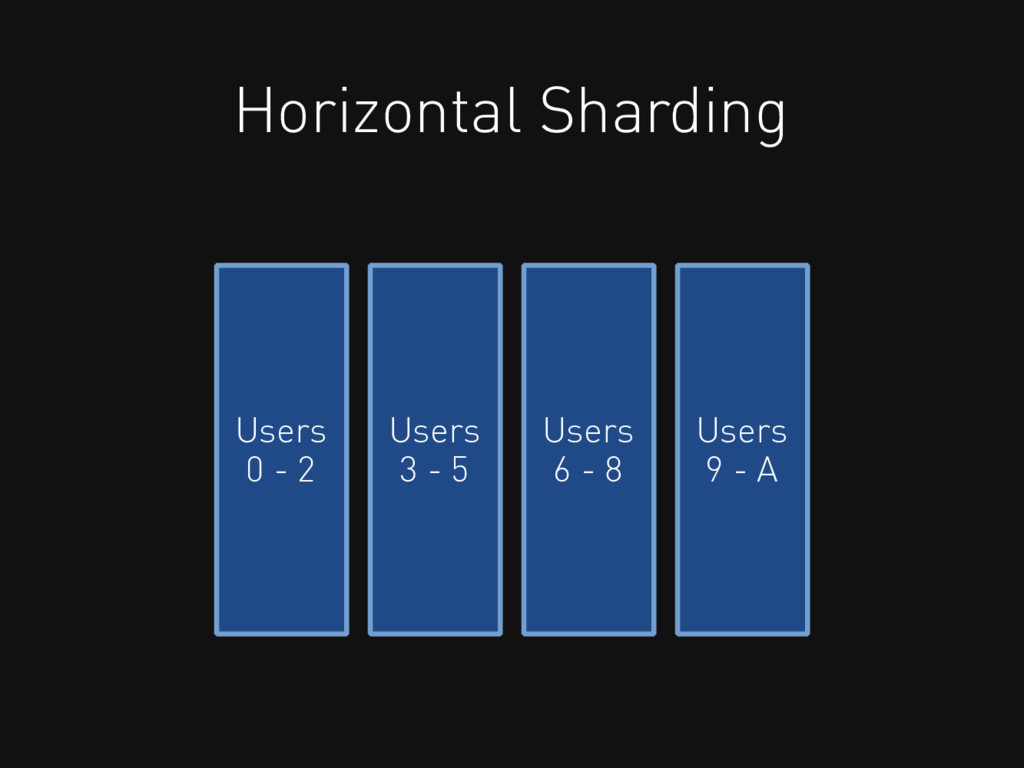
Horizontal Sharding Users 0 - 2 Users 3 - 5
Users 6 - 8 Users 9 - A
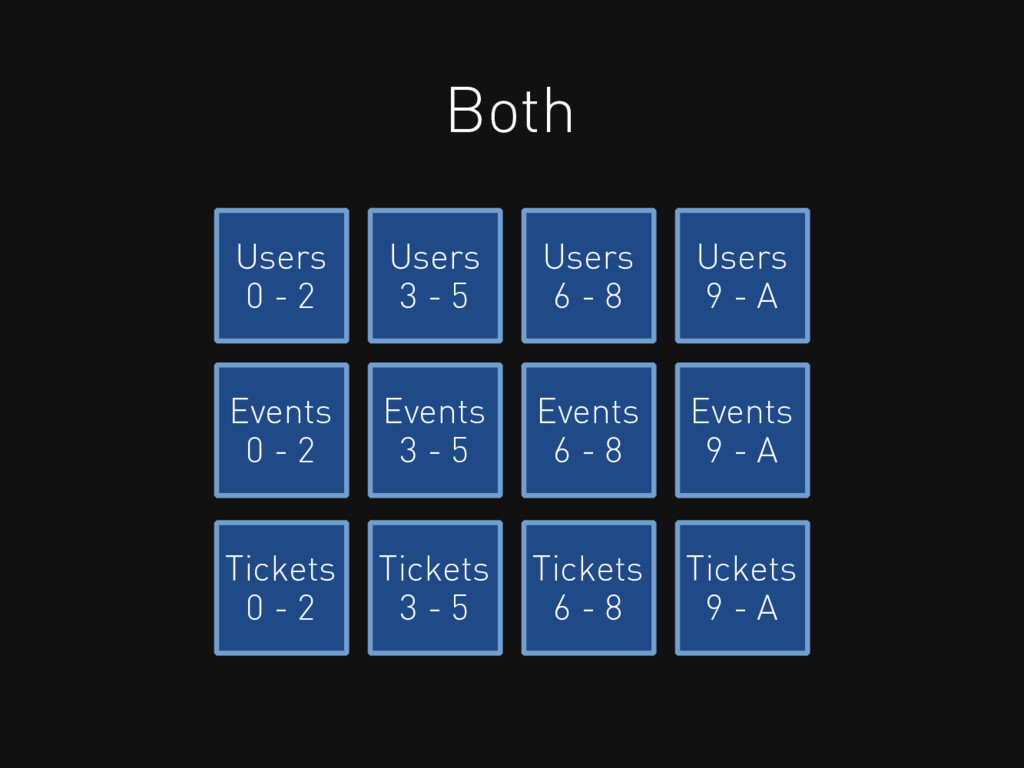
Both Users 0 - 2 Users 3 - 5 Users
6 - 8 Users 9 - A Events 0 - 2 Events 3 - 5 Events 6 - 8 Events 9 - A Tickets 0 - 2 Tickets 3 - 5 Tickets 6 - 8 Tickets 9 - A
Both plus caching Users 0 - 2 Users 3 -
5 Users 6 - 8 Users 9 - A Events 0 - 2 Events 3 - 5 Events 6 - 8 Events 9 - A Tickets 0 - 2 Tickets 3 - 5 Tickets 6 - 8 Tickets 9 - A User Cache Event Cache Ticket Cache
Teams have to scale too; nobody should have to understand
eveything in a big system.
Services allow complexity to be reduced - for a tradeoff
of speed
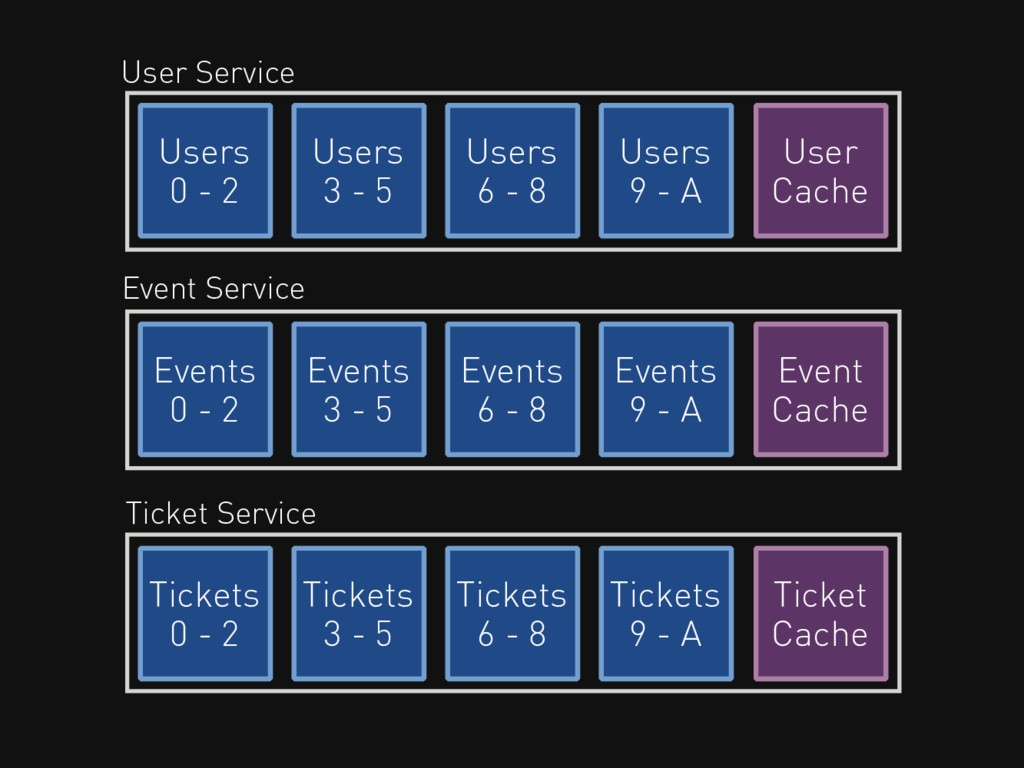
Users 0 - 2 Users 3 - 5 Users 6
- 8 Users 9 - A Events 0 - 2 Events 3 - 5 Events 6 - 8 Events 9 - A Tickets 0 - 2 Tickets 3 - 5 Tickets 6 - 8 Tickets 9 - A User Cache Event Cache Ticket Cache User Service Event Service Ticket Service
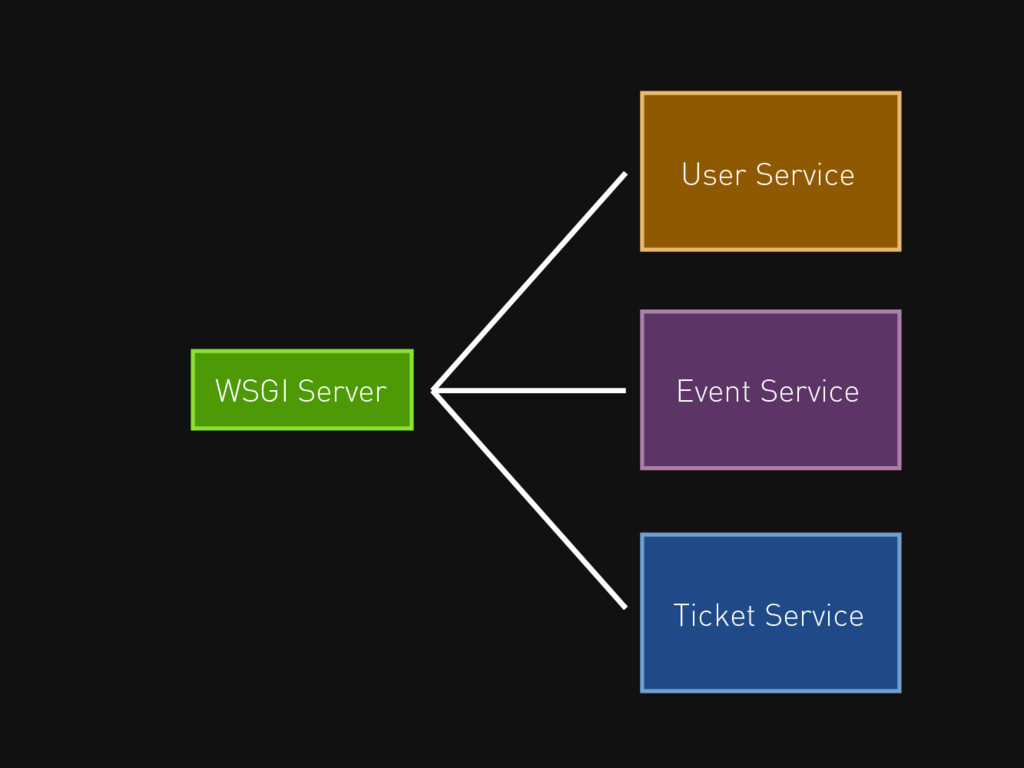
User Service Event Service Ticket Service WSGI Server
Each service is its own, smaller project, managed and scaled
separately.
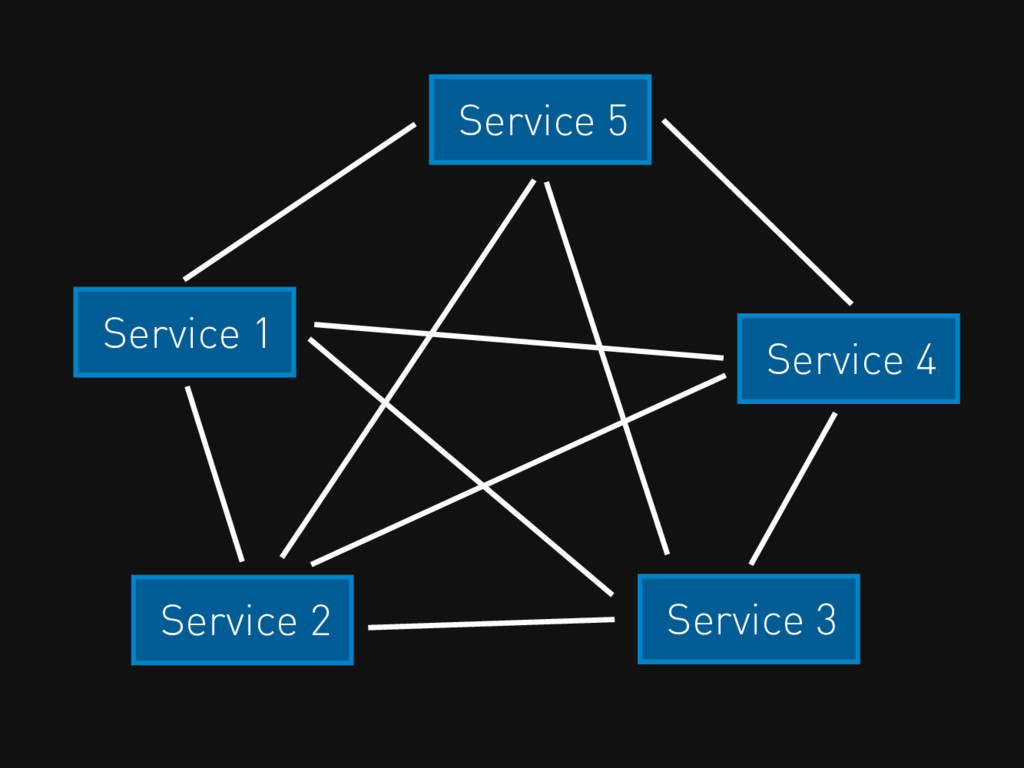
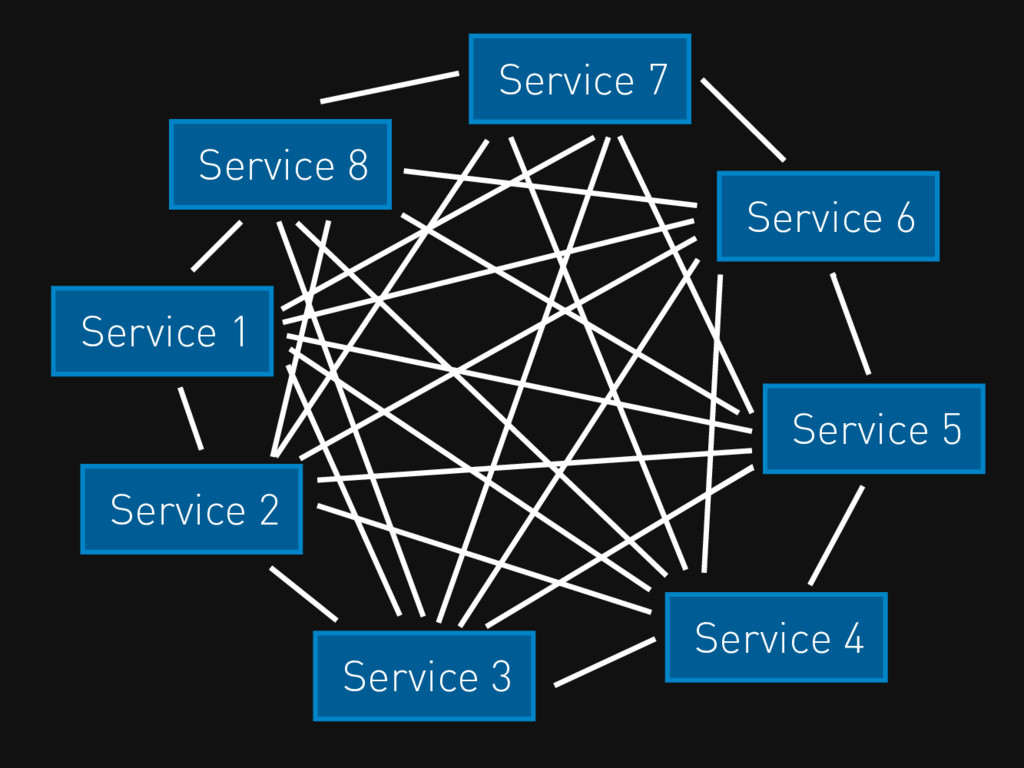
But how do you communicate between them?
Service 2 Service 3 Service 1 Direct Communication
Service 2 Service 3 Service 1 Service 4 Service 5
Service 2 Service 3 Service 1 Service 4 Service 5
Service 6 Service 7 Service 8
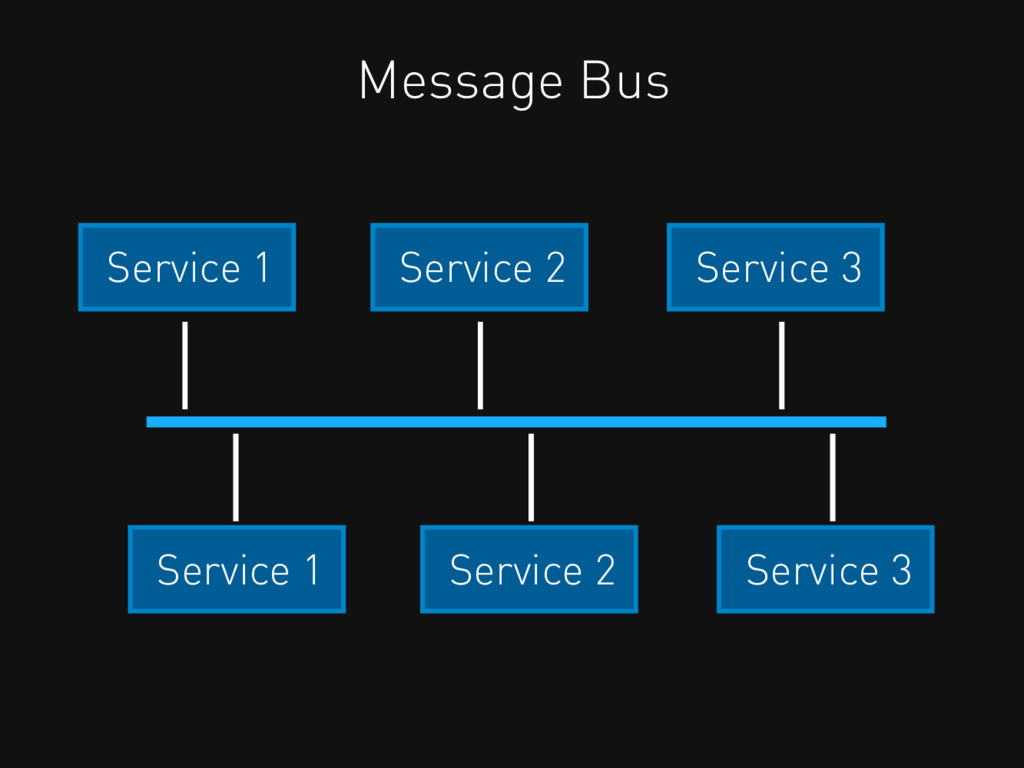
Service 2 Service 3 Service 1 Message Bus Service 2
Service 3 Service 1
A single point of failure is not always bad -
if the alternative is multiple, fragile ones
Channels and ASGI provide a standard message bus built with
certain tradeoffs
Backing Store e.g. Redis, RabbitMQ ASGI (Channel Layer) Channels Library
Django Django Channels Project
Backing Store e.g. Redis, RabbitMQ ASGI (Channel Layer) Pure Python
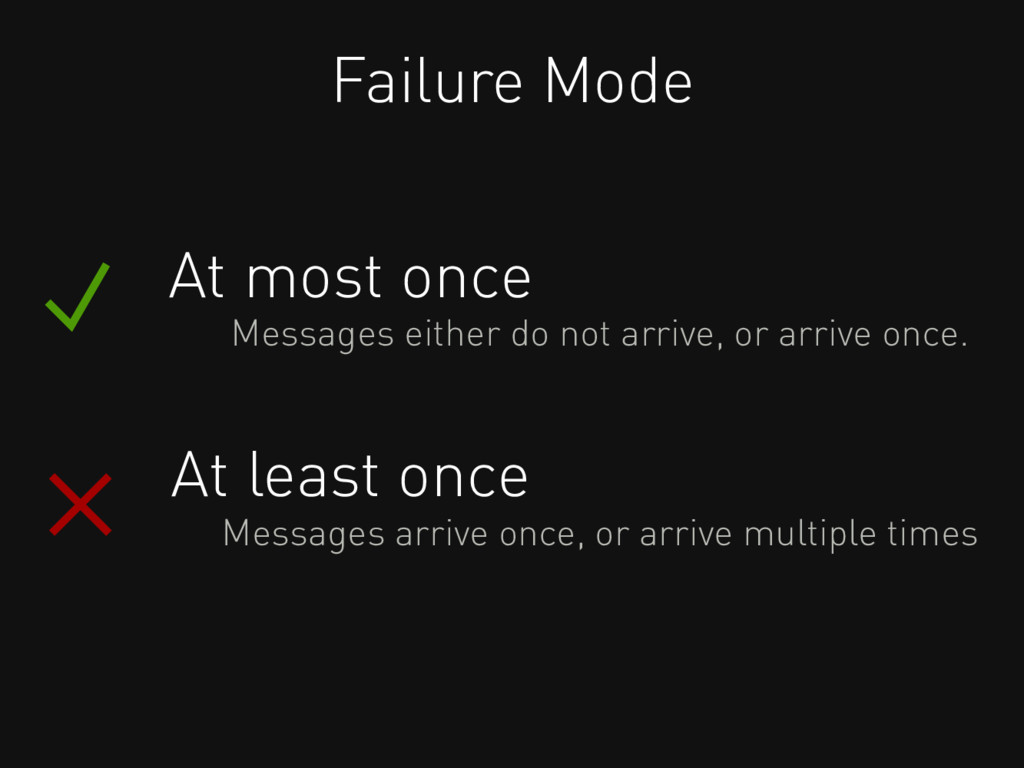
Failure Mode At most once Messages either do not arrive,
or arrive once. At least once Messages arrive once, or arrive multiple times
Guarantees vs. Latency Low latency Messages arrive very quickly but
go missing more Low loss rate Messages are almost never lost but arrive slower
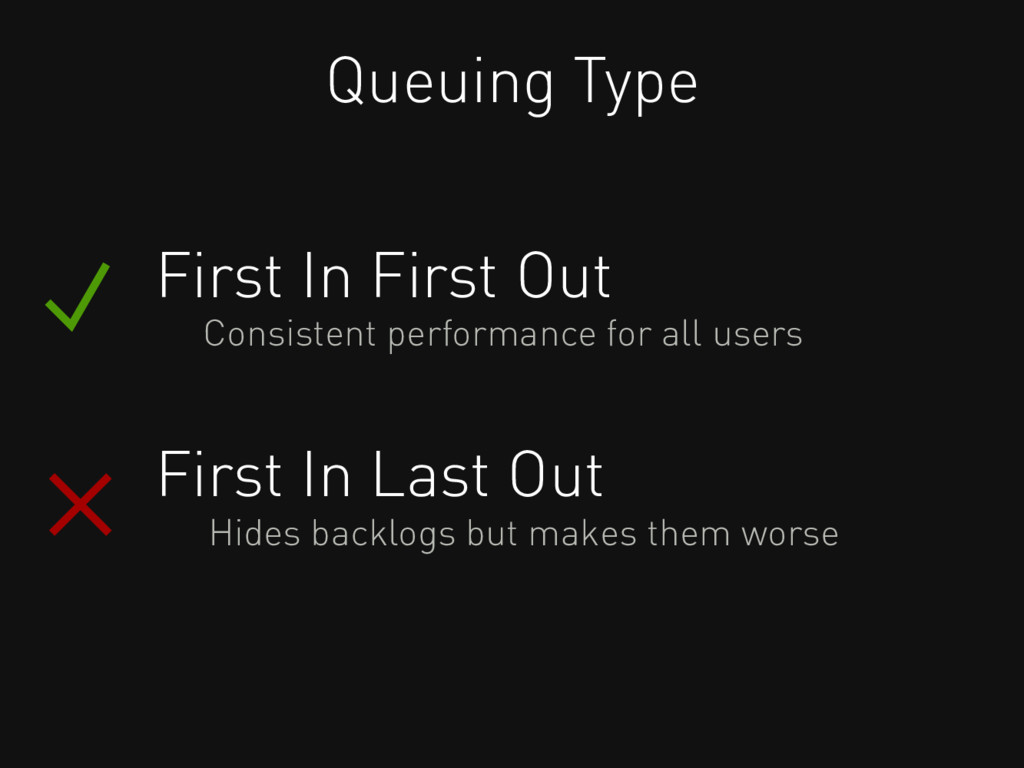
Queuing Type First In First Out Consistent performance for all
users First In Last Out Hides backlogs but makes them worse
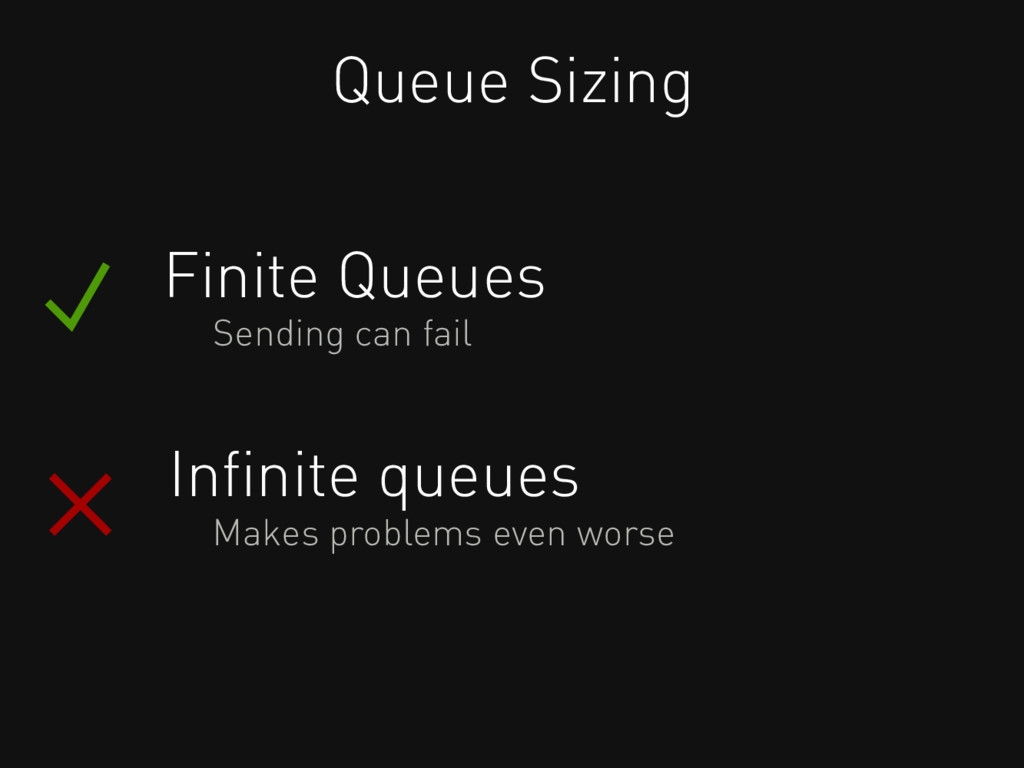
Queue Sizing Finite Queues Sending can fail Infinite queues Makes
problems even worse
You must understand what you are making (This is surprisingly
uncommon)
Design as much as possible around shared-nothing
Per-machine caches On-demand thumbnailing Signed cookie sessions
Has to be shared? Try to split it
Has to be shared? Try sharding it.
Django's job is to be slowly replaced by your code
Just make sure you match the API contract of what
you're replacing!
Don't try to scale too early; you'll pick the wrong
tradeoffs.
Thanks. Andrew Godwin @andrewgodwin channels.readthedocs.io


 andrewgodwin
 akase244
 yub0n
 drumath2237
 hollycummins
 eed3si9n
 mpyw
 y0hgi
 syumai
 soyuka
 elmetal
 kinopeee
 satoshi256kbyte
 427marketing
 morganepeng
 coloredviolet
 asonas
 mfonobong
 helmedeiros
 katiecoart
 inesmontani
 frankvandijk
 codingconduct
 nmsamuel
 holman