Share
Embed
Sean Cribbs on Scaling Riak in Production
Riak is a distributed, scalable, boring database. If you're looking for open source storage to support the growth of a new or existing system, there aren't many others out there that offer the durability and fault-tolerance guarantees that Riak does. That said, nothing is fool proof, every technology has tradeoffs and things will always fail.
In this talk, Basho Engineer Sean Cribbs takes a high-level look at what it takes to scale Riak in production. The keen administrator will tweak operating systems, hone networks and keep and eye out for things like TCP Incast. Sean dives into these and more, with a focus on what it takes to run Riak at scale.
Basho Technologies
September 28, 2012
Transcript
65 slides
-
WHAT MAKES RIAK GREAT High read/write availability & durability Predictable
latency Straightforward scale-out Minimal manual maintenance -
SCALE BREAKS EVERYTHING Failure probability goes up rapidly! Small problems
are amplified: Software bugs Human errors Cascading failures -
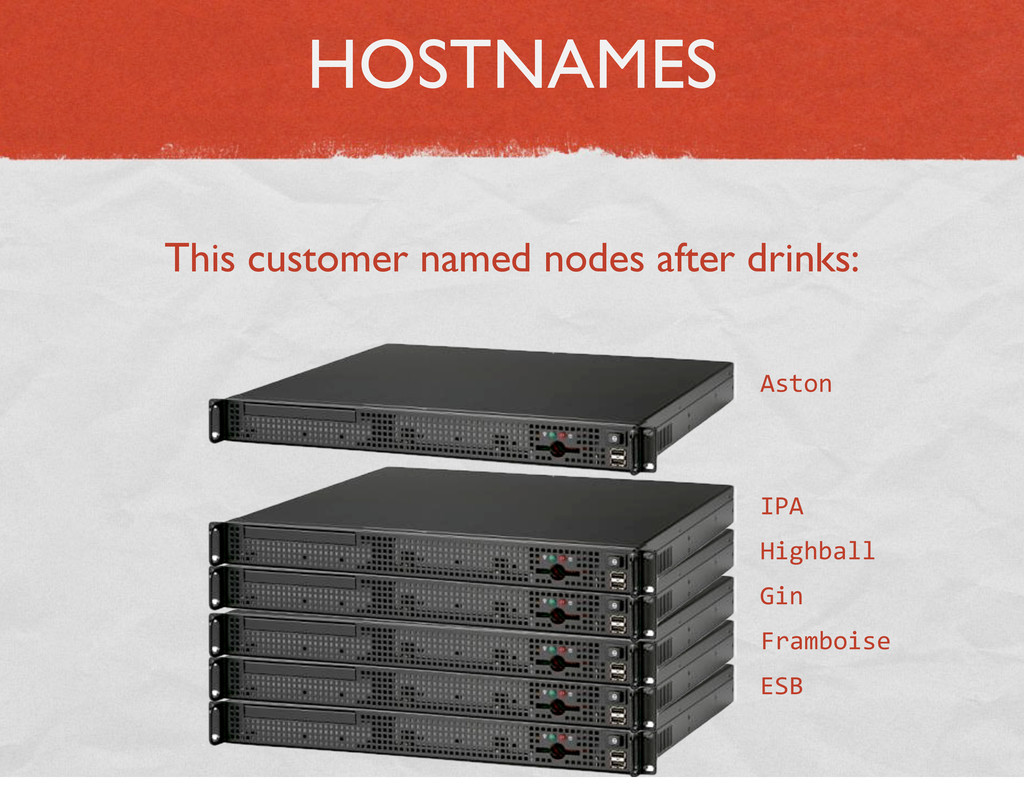
HOSTNAMES This customer named nodes after drinks: Aston IPA Highball
Gin Framboise ESB -
RIAK-ADMIN JOIN With Riak, it’s easy to add a new
node. on#aston: $"riak'admin"join"[email protected] Then you leave for a quick lunch. -
QUICK, WHAT DO YOU DO? 1. add another system! 2.
shutdown the entire site! 3. alert Basho Support via an URGENT ticket -
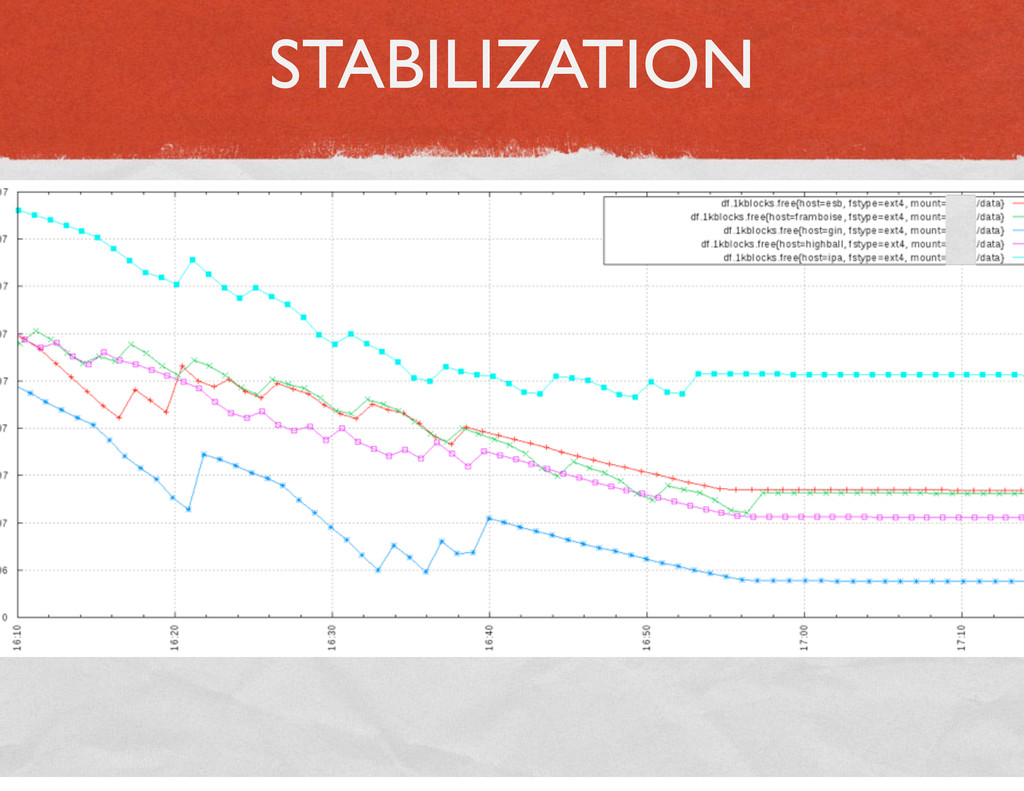
CONTROL THE SITUATION Stop the handoff between nodes on#every#node#we: riak8attach
application:set_env(riak_core,8handoff_concurrency,80). -
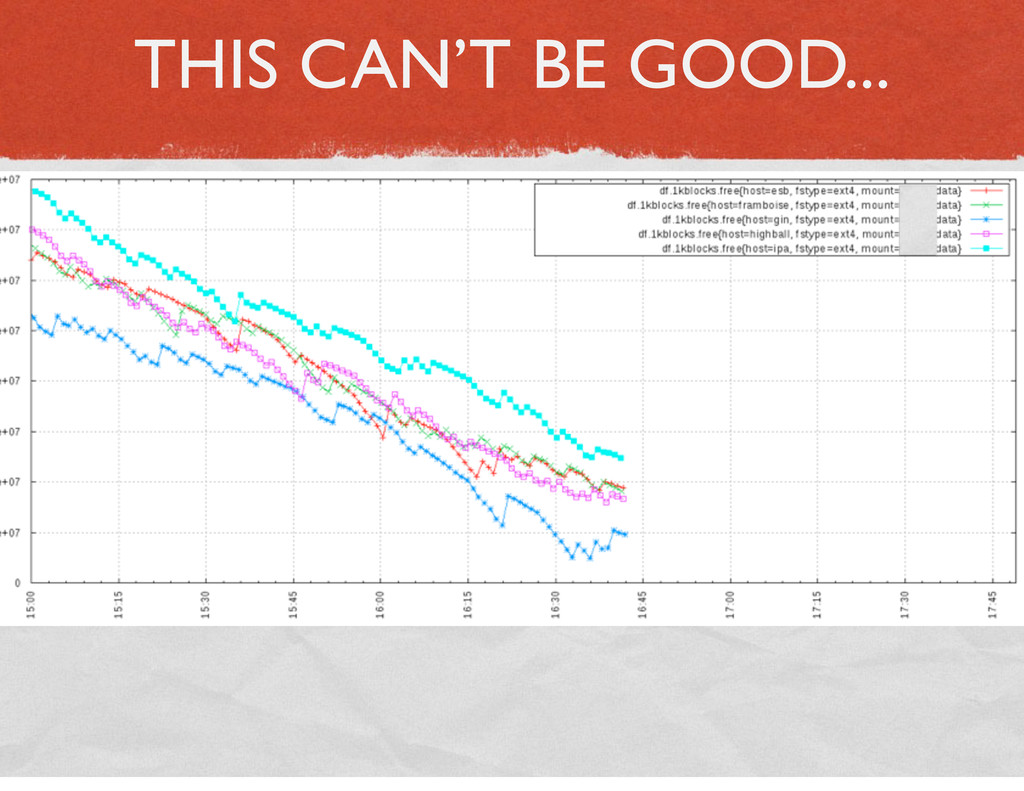
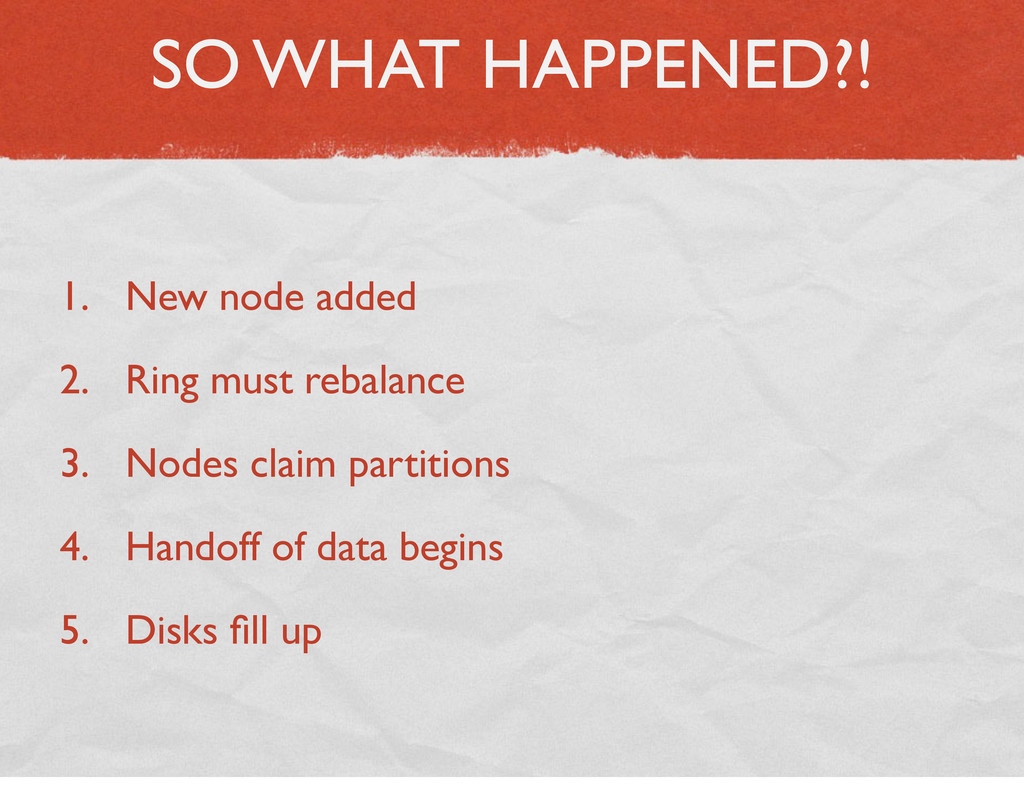
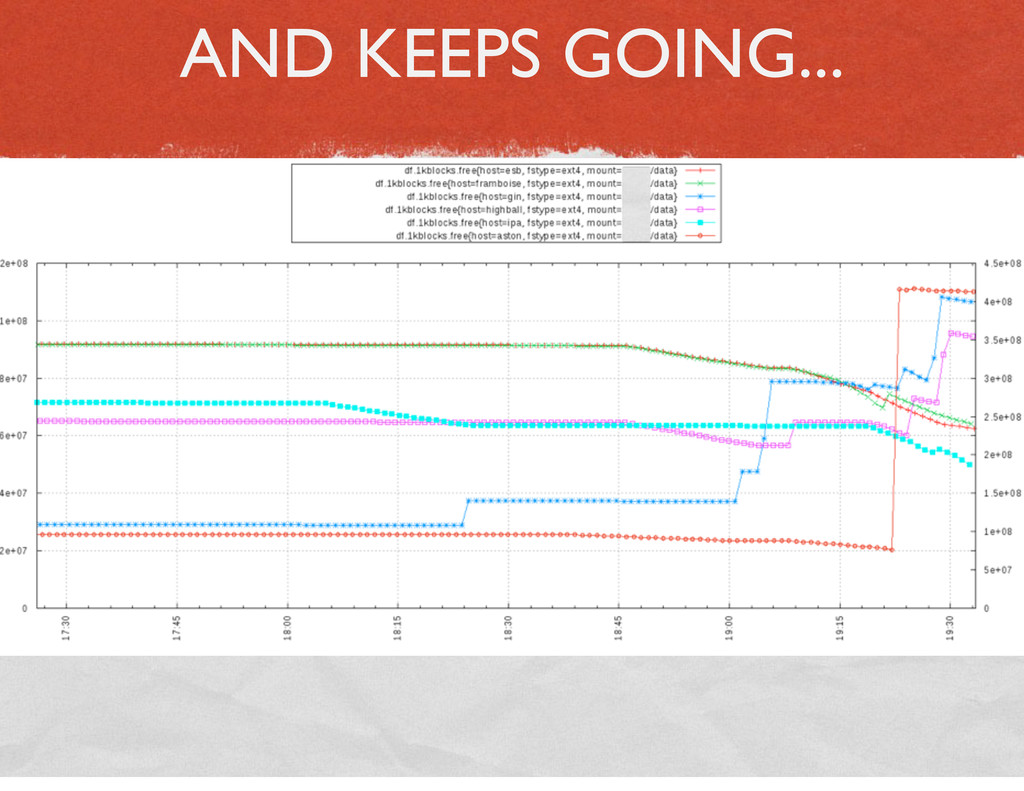
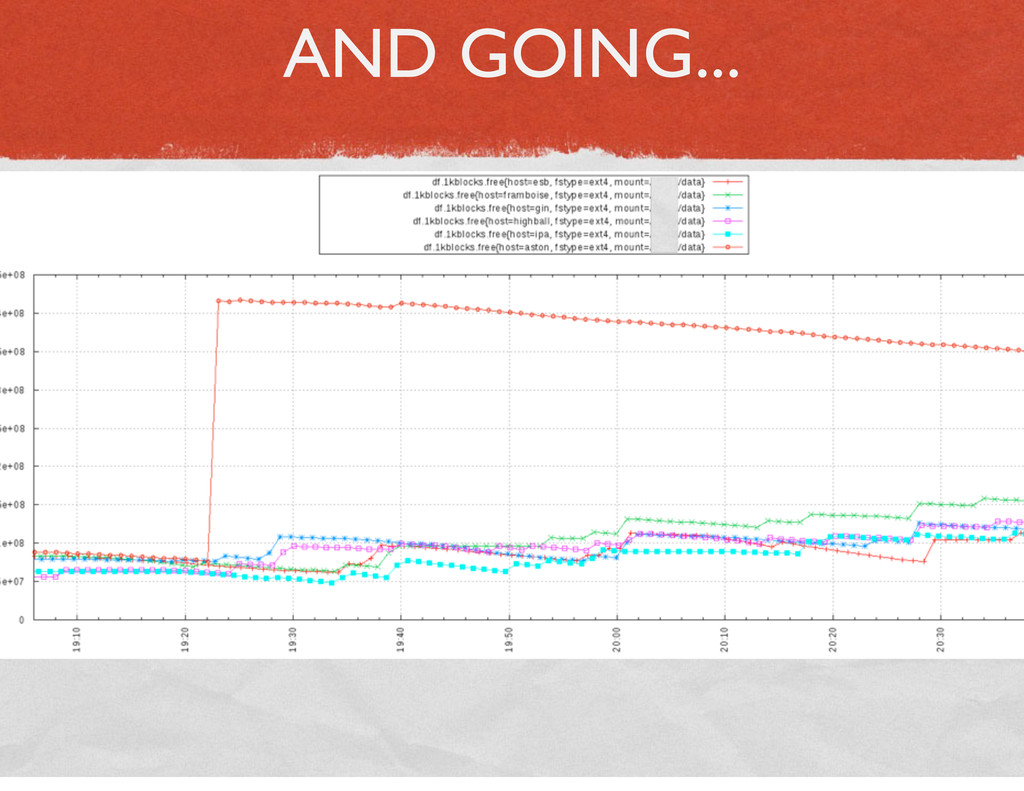
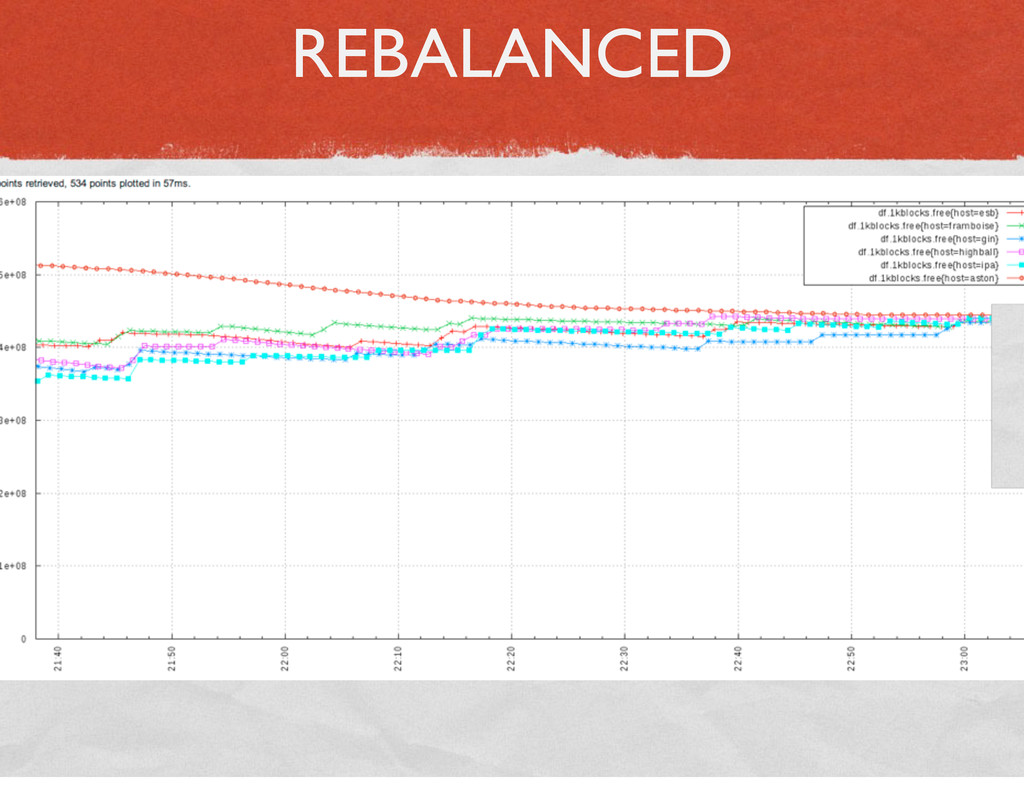
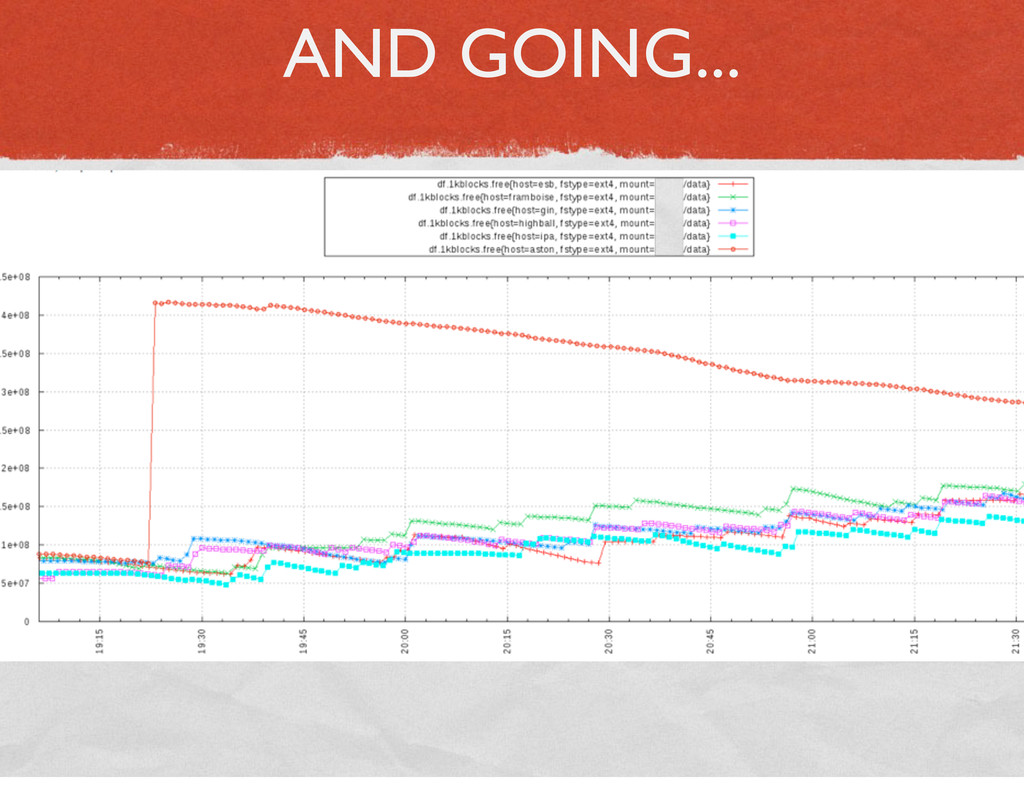
SO WHAT HAPPENED?! 1. New node added 2. Ring must
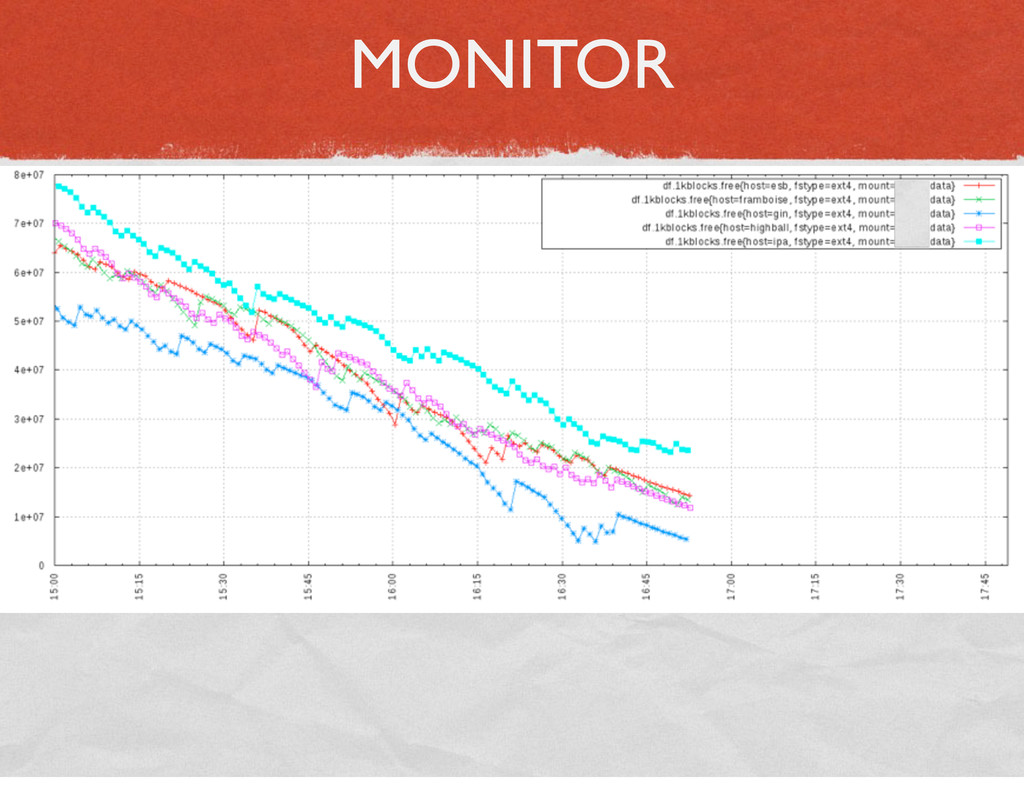
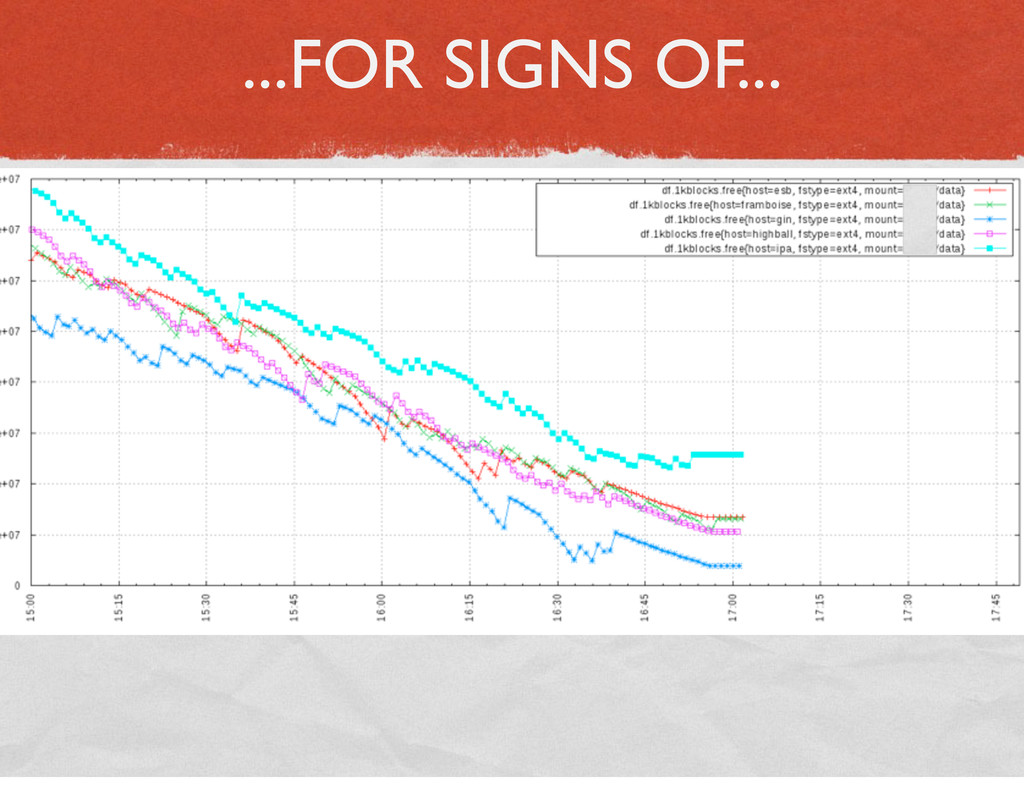
rebalance 3. Nodes claim partitions 4. Handoff of data begins 5. Disks fill up -
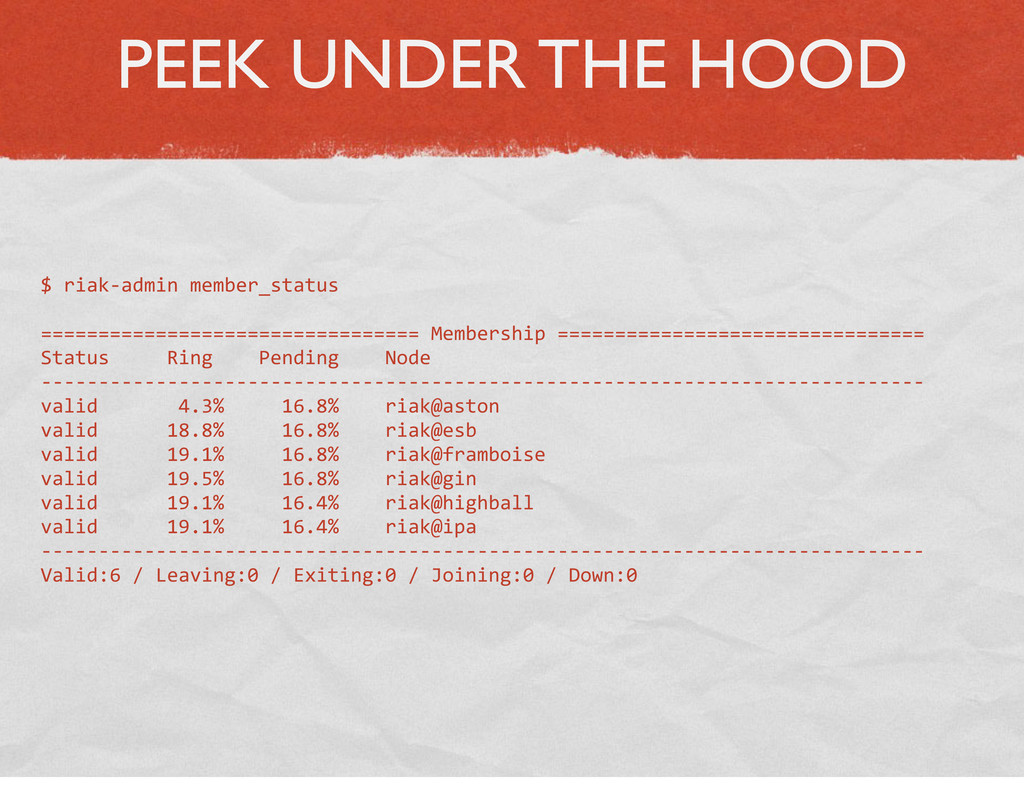
PEEK UNDER THE HOOD $8riakHadmin8member_status =================================8Membership8================================ Status88888Ring8888Pending8888Node HHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHH valid88888884.3%8888816.8%8888riak@aston valid88888818.8%8888816.8%8888riak@esb
valid88888819.1%8888816.8%8888riak@framboise valid88888819.5%8888816.8%8888riak@gin valid88888819.1%8888816.4%8888riak@highball valid88888819.1%8888816.4%8888riak@ipa HHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHHH Valid:68/8Leaving:08/8Exiting:08/8Joining:08/8Down:0 -
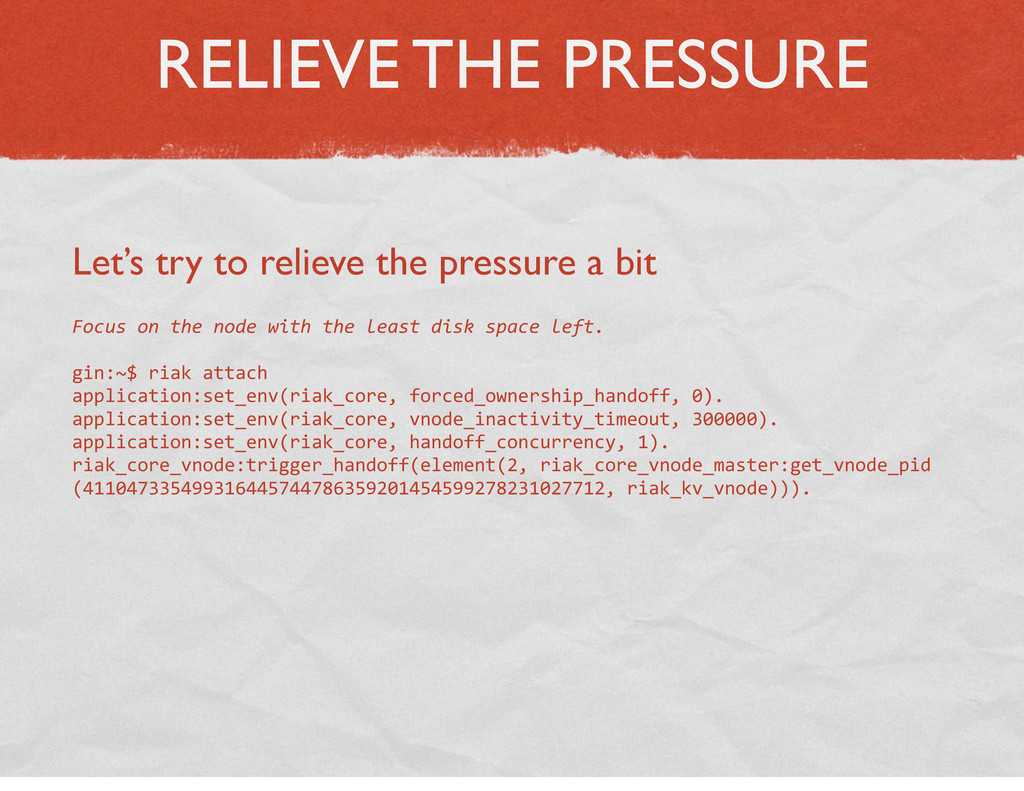
RELIEVE THE PRESSURE Let’s try to relieve the pressure a
bit Focus#on#the#node#with#the#least#disk#space#left. gin:~$8riak8attach application:set_env(riak_core,8forced_ownership_handoff,80). application:set_env(riak_core,8vnode_inactivity_timeout,8300000). application:set_env(riak_core,8handoff_concurrency,81).8 riak_core_vnode:trigger_handoff(element(2,8riak_core_vnode_master:get_vnode_pid (411047335499316445744786359201454599278231027712,8riak_kv_vnode))). -
RELIEF It took 20 minutes to transfer the vnode (riak@gin)7>819:34:00.5748[info]8Starting8handoff8of8partition8riak_kv_vnode8
4110473354993164457447863592014545992782310277128from8riak@gin8to8riak@aston gin:~$8sudo8netstat8Hnap8|8fgrep810.36.18.24588888 tcp8888888808881065810.36.110.79:4053288810.36.18.245:8099888ESTABLISHED827124/beam.smp88 tcp8888888808888880810.36.110.79:4634588810.36.18.245:5366488ESTABLISHED827124/beam.smp (riak@gin)7>819:54:56.7218[info]8Handoff8of8partition8riak_kv_vnode8 4110473354993164457447863592014545992782310277128from8riak@gin8to8riak@aston completed:8sent838057308objects8in81256.148seconds -
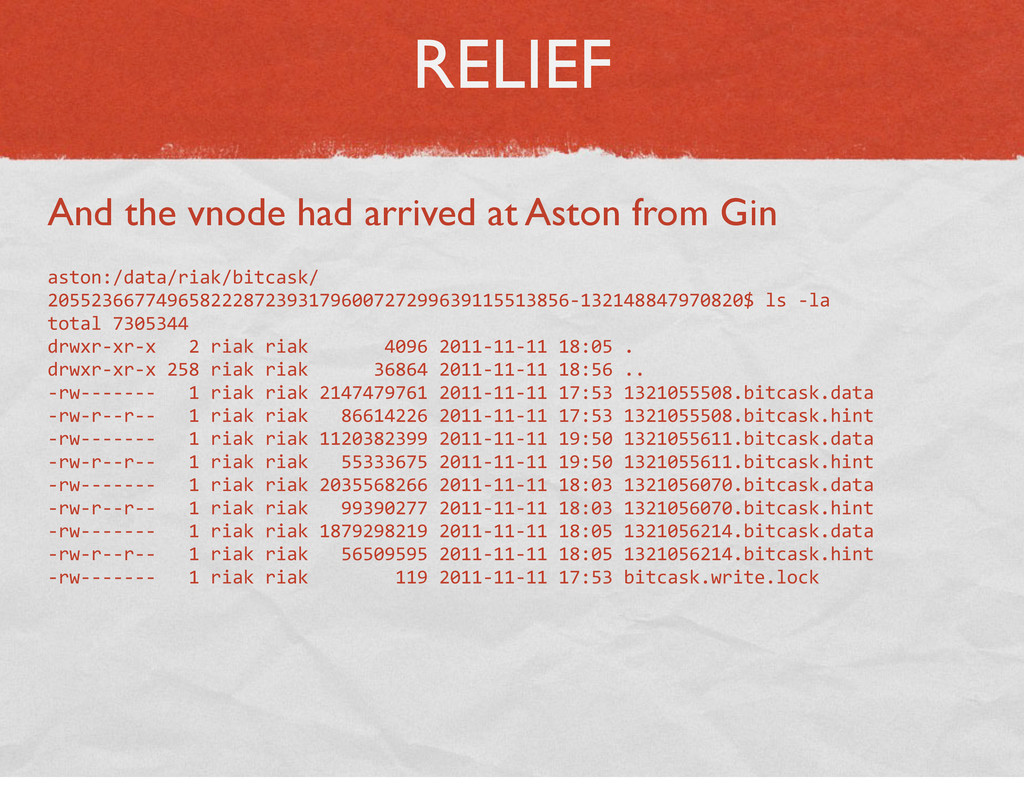
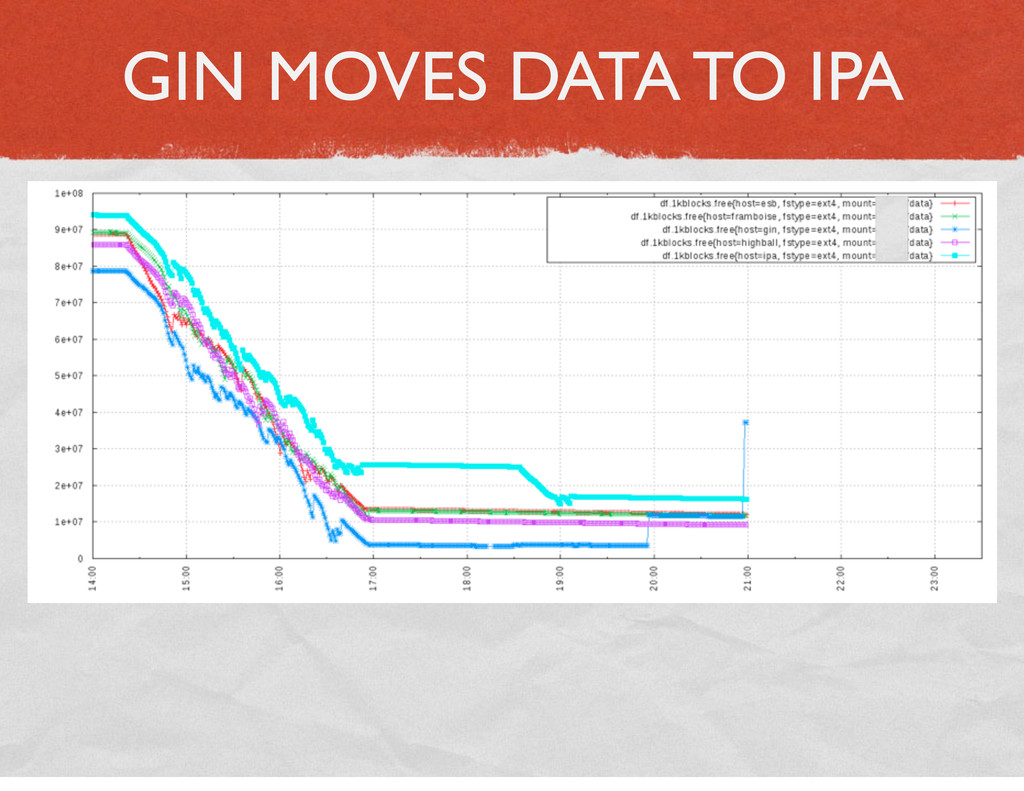
RELIEF And the vnode had arrived at Aston from Gin
aston:/data/riak/bitcask/ 205523667749658222872393179600727299639115513856H132148847970820$8ls8Hla total87305344 drwxrHxrHx88828riak8riak8888888409682011H11H11818:058. drwxrHxrHx82588riak8riak8888883686482011H11H11818:568.. HrwHHHHHHH88818riak8riak8214747976182011H11H11817:5381321055508.bitcask.data HrwHrHHrHH88818riak8riak8888661422682011H11H11817:5381321055508.bitcask.hint HrwHHHHHHH88818riak8riak8112038239982011H11H11819:5081321055611.bitcask.data HrwHrHHrHH88818riak8riak8885533367582011H11H11819:5081321055611.bitcask.hint HrwHHHHHHH88818riak8riak8203556826682011H11H11818:0381321056070.bitcask.data HrwHrHHrHH88818riak8riak8889939027782011H11H11818:0381321056070.bitcask.hint HrwHHHHHHH88818riak8riak8187929821982011H11H11818:0581321056214.bitcask.data HrwHrHHrHH88818riak8riak8885650959582011H11H11818:0581321056214.bitcask.hint HrwHHHHHHH88818riak8riak8888888811982011H11H11817:538bitcask.write.lock -
EUREKA! Data was not being cleaned up after handoff. This
would eventually eat all disk space! You gonna eat that inode? -
WHAT’S THE SOLUTION? We already had a bugfix for the
next release (1.0.2) that detects the problem Tested the bugfix locally before delivering to customer -
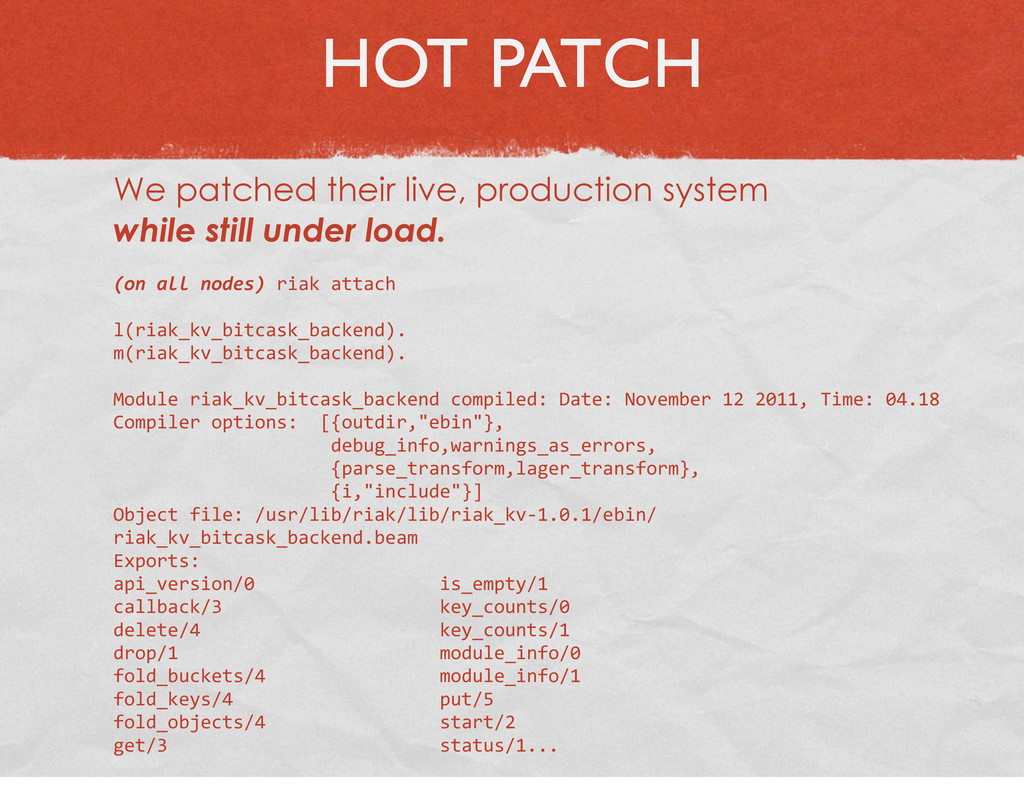
HOT PATCH We patched their live, production system while still
under load. (on#all#nodes)8riak8attach l(riak_kv_bitcask_backend). m(riak_kv_bitcask_backend). Module8riak_kv_bitcask_backend8compiled:8Date:8November81282011,8Time:804.18 Compiler8options:88[{outdir,"ebin"}, 88888888888888888888debug_info,warnings_as_errors, 88888888888888888888{parse_transform,lager_transform}, 88888888888888888888{i,"include"}] Object8file:8/usr/lib/riak/lib/riak_kvH1.0.1/ebin/ riak_kv_bitcask_backend.beam Exports:8 api_version/088888888888888888is_empty/1 callback/388888888888888888888key_counts/0 delete/48888888888888888888888key_counts/1 drop/1888888888888888888888888module_info/0 fold_buckets/48888888888888888module_info/1 fold_keys/48888888888888888888put/5 fold_objects/48888888888888888start/2 get/38888888888888888888888888status/1... -
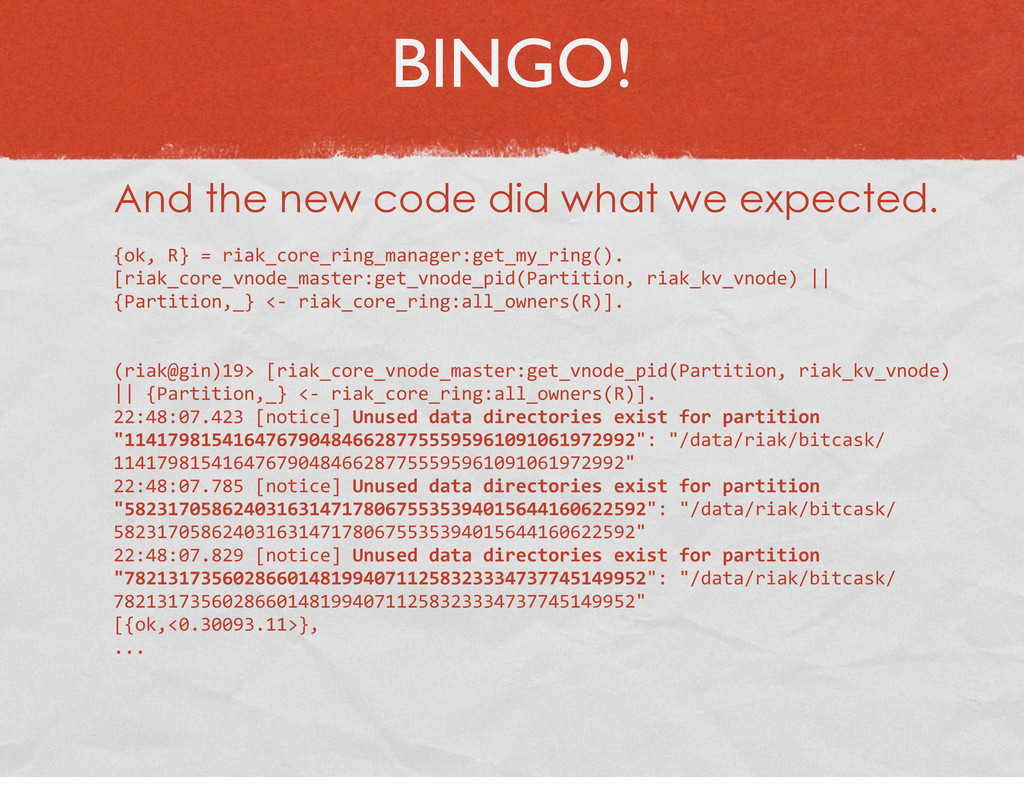
BINGO! And the new code did what we expected. {ok,8R}8=8riak_core_ring_manager:get_my_ring().
[riak_core_vnode_master:get_vnode_pid(Partition,8riak_kv_vnode)8||8 {Partition,_}8<H8riak_core_ring:all_owners(R)]. (riak@gin)19>8[riak_core_vnode_master:get_vnode_pid(Partition,8riak_kv_vnode)8 ||8{Partition,_}8<H8riak_core_ring:all_owners(R)]. 22:48:07.4238[notice]8Unused"data"directories"exist"for"partition" "11417981541647679048466287755595961091061972992":8"/data/riak/bitcask/ 11417981541647679048466287755595961091061972992" 22:48:07.7858[notice]8Unused"data"directories"exist"for"partition" "582317058624031631471780675535394015644160622592":8"/data/riak/bitcask/ 582317058624031631471780675535394015644160622592" 22:48:07.8298[notice]8Unused"data"directories"exist"for"partition" "782131735602866014819940711258323334737745149952":8"/data/riak/bitcask/ 782131735602866014819940711258323334737745149952" [{ok,<0.30093.11>}, ... -
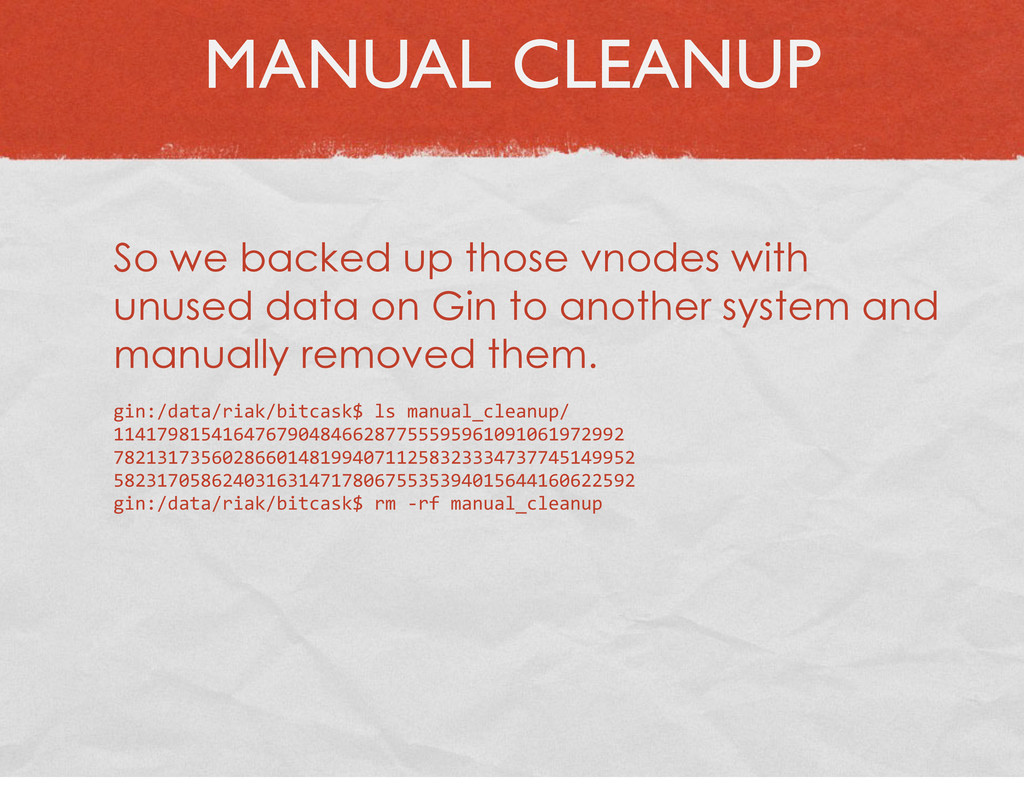
MANUAL CLEANUP So we backed up those vnodes with unused
data on Gin to another system and manually removed them. gin:/data/riak/bitcask$8ls8manual_cleanup/8 11417981541647679048466287755595961091061972992888 782131735602866014819940711258323334737745149952 582317058624031631471780675535394015644160622592 gin:/data/riak/bitcask$8rm8Hrf8manual_cleanup -
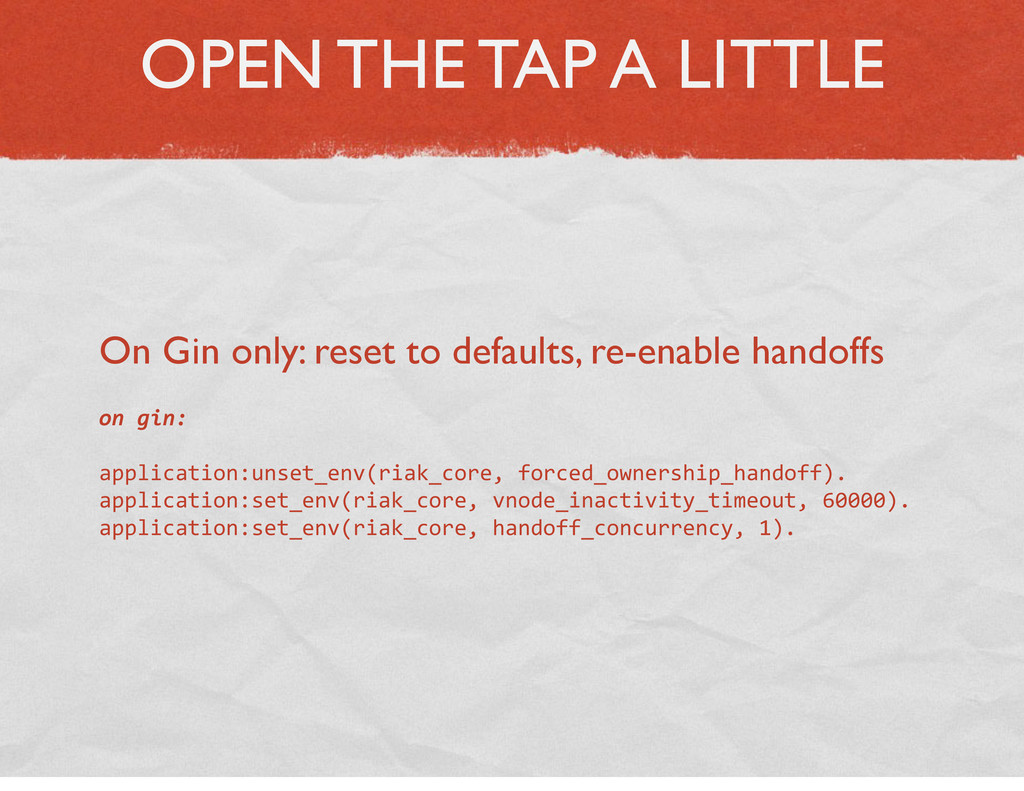
OPEN THE TAP A LITTLE On Gin only: reset to
defaults, re-enable handoffs on#gin: application:unset_env(riak_core,8forced_ownership_handoff). application:set_env(riak_core,8vnode_inactivity_timeout,860000). application:set_env(riak_core,8handoff_concurrency,81). -
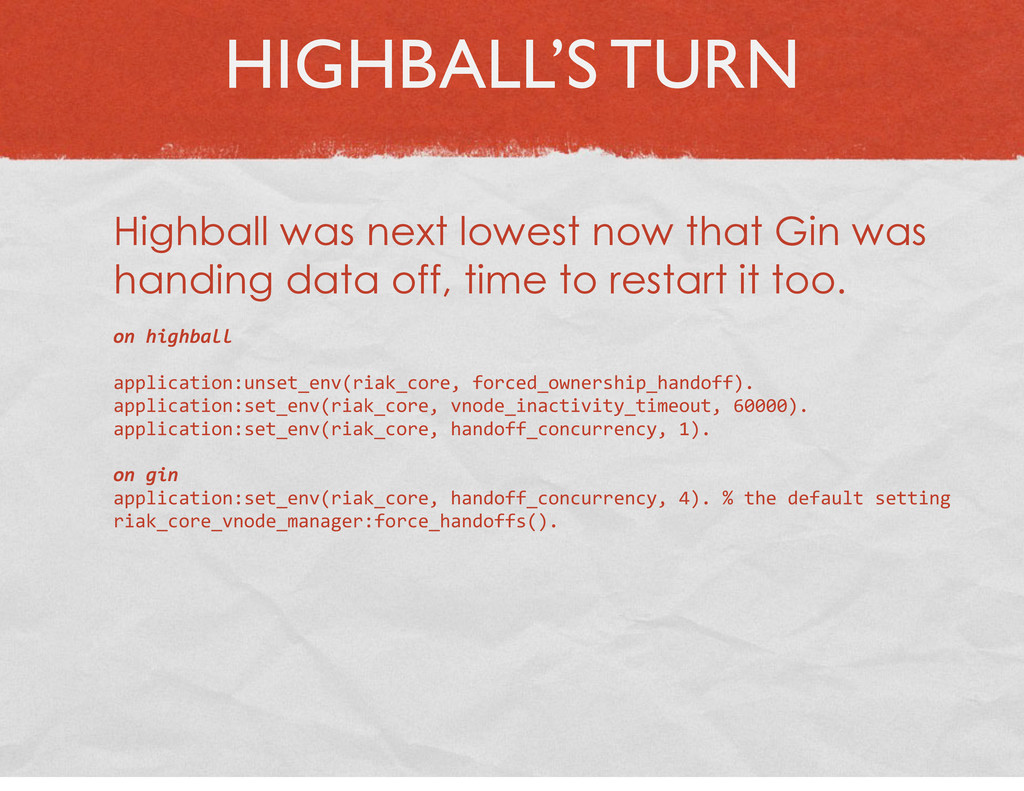
HIGHBALL’S TURN Highball was next lowest now that Gin was
handing data off, time to restart it too. on#highball application:unset_env(riak_core,8forced_ownership_handoff). application:set_env(riak_core,8vnode_inactivity_timeout,860000). application:set_env(riak_core,8handoff_concurrency,81). on#gin application:set_env(riak_core,8handoff_concurrency,84).8%8the8default8setting riak_core_vnode_manager:force_handoffs(). -
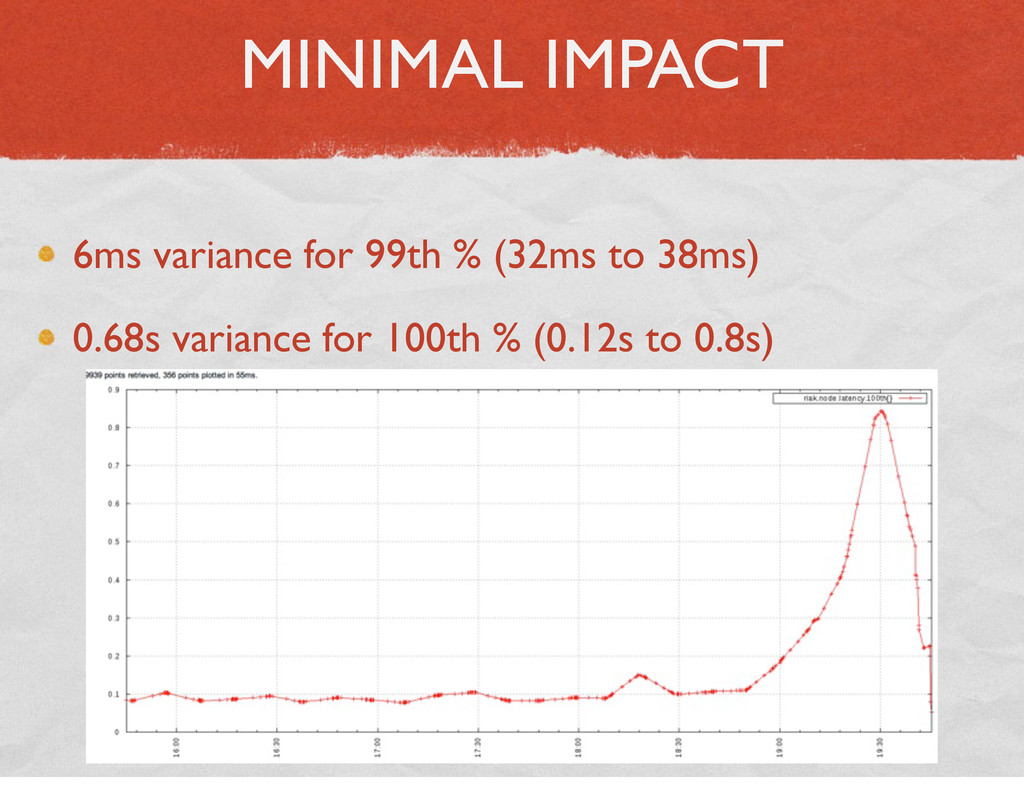
MINIMAL IMPACT 6ms variance for 99th % (32ms to 38ms)
0.68s variance for 100th % (0.12s to 0.8s) -
MORAL OF THE STORY Have shutoff-valves for bad behavior Construct
your system so you can triage without major downtime -
SITUATION Customer has ~15 node cluster Machines are really beefy
Multi-core, gobs of RAM RAID over SSDs, GigE networking -
RAM!! OMNOMNOM Riak processes become bloated Latency climbing to unacceptable
levels “Isn’t this why we bought nice hardware?” -
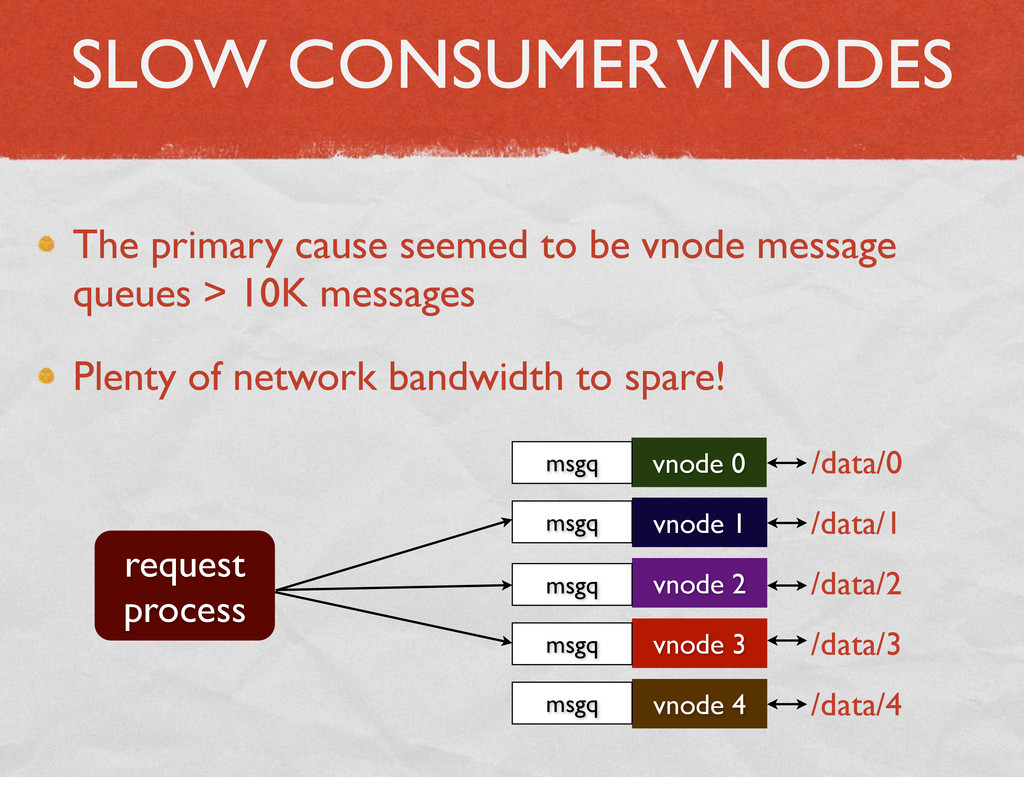
SLOW CONSUMER VNODES The primary cause seemed to be vnode
message queues > 10K messages Plenty of network bandwidth to spare! vnode 0 vnode 1 vnode 2 vnode 3 vnode 4 /data/0 /data/1 /data/2 /data/3 /data/4 msgq msgq msgq msgq msgq request process -
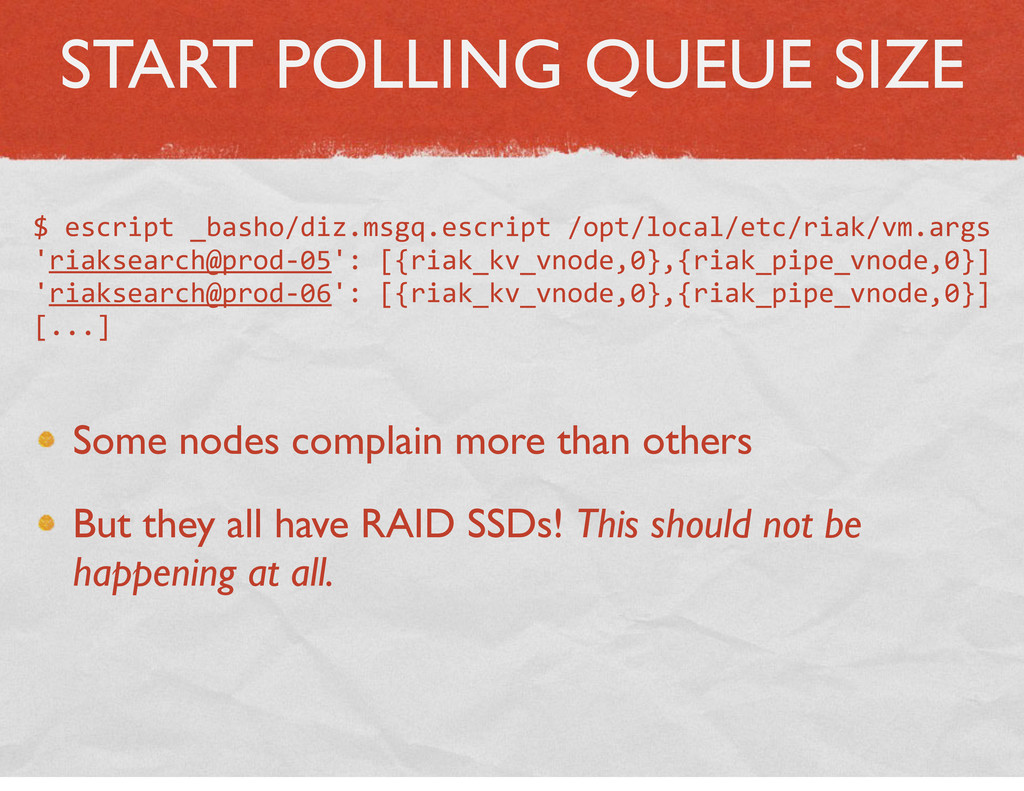
START POLLING QUEUE SIZE Some nodes complain more than others
But they all have RAID SSDs! This should not be happening at all. $8escript8_basho/diz.msgq.escript8/opt/local/etc/riak/vm.args 'riaksearch@prodH05':8[{riak_kv_vnode,0},{riak_pipe_vnode,0}] 'riaksearch@prodH06':8[{riak_kv_vnode,0},{riak_pipe_vnode,0}] [...] -
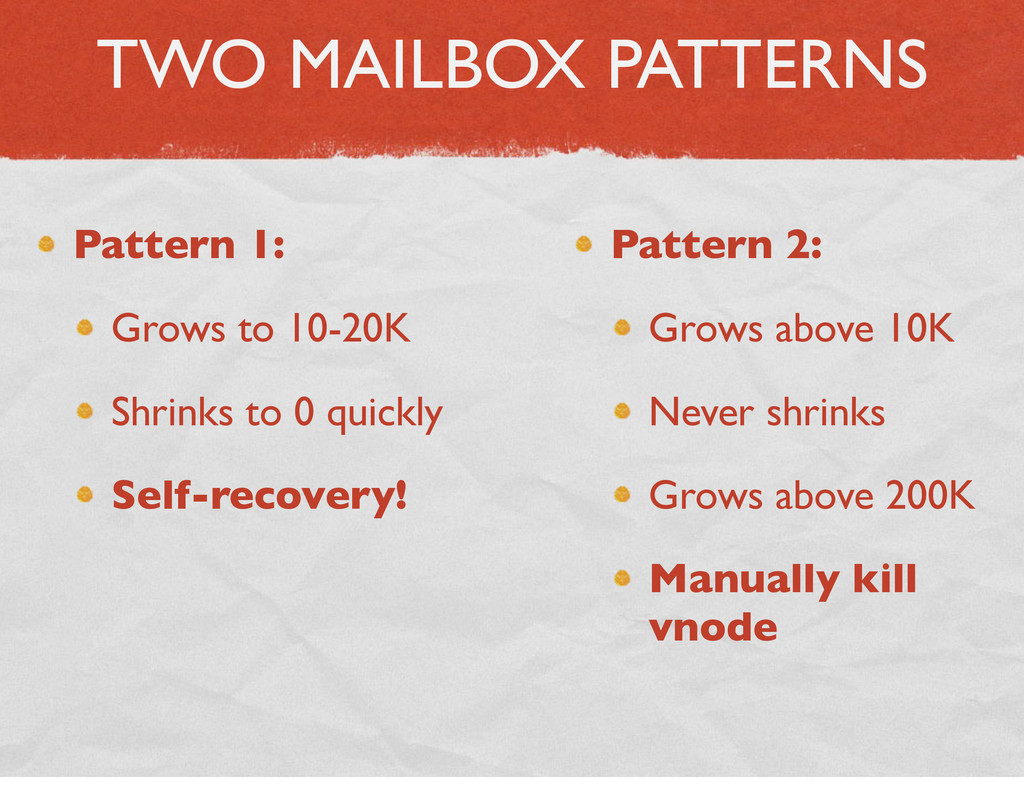
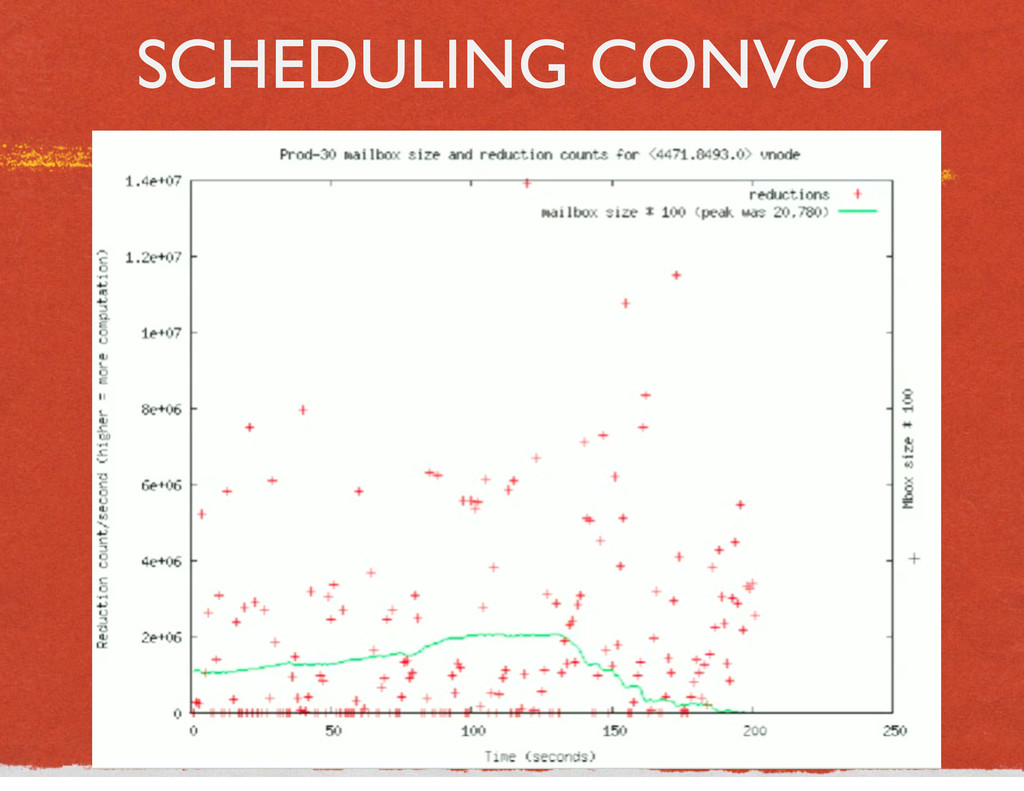
TWO MAILBOX PATTERNS Pattern 1: Grows to 10-20K Shrinks to
0 quickly Self-recovery! Pattern 2: Grows above 10K Never shrinks Grows above 200K Manually kill vnode -
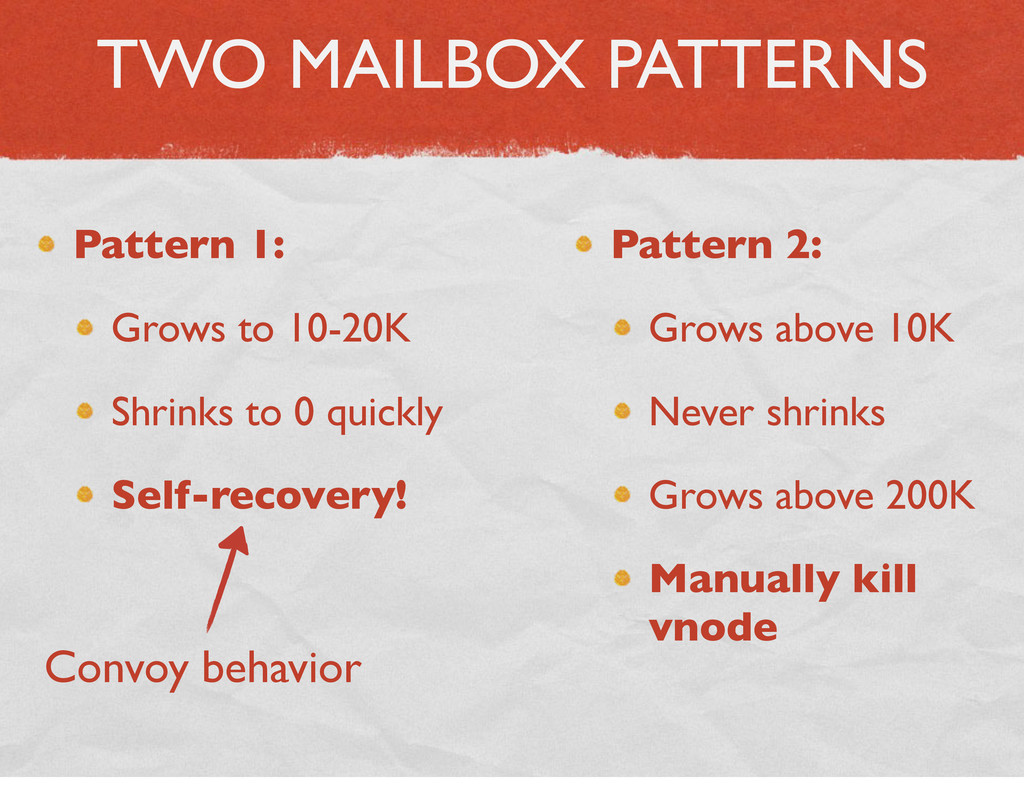
TWO MAILBOX PATTERNS Pattern 1: Grows to 10-20K Shrinks to
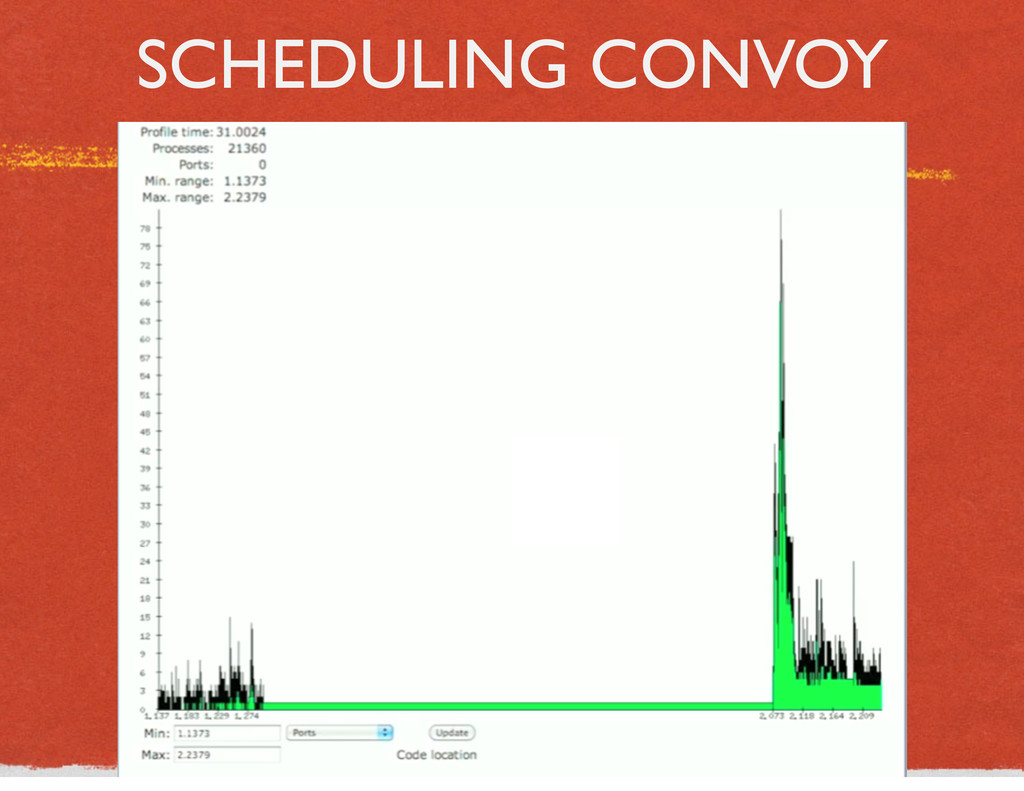
0 quickly Self-recovery! Pattern 2: Grows above 10K Never shrinks Grows above 200K Manually kill vnode Convoy behavior -
LET’S CHECK DAT RAID 10.28.60.20888prodH04888raidH0Hb 10.28.60.21088prodH05888raidH0Hb [...] 10.28.60.22688prodH13888RAID5HB 10.28.60.22888prodH14888RAID0HB 10.28.60.23088prodH15888RAID0HB
10.28.60.20288prodH16888HHNotHInHServiceHH 10.28.60.23288prodH17888raidH5Hb 10.28.60.23488prodH18888raidH5Hb 10.28.60.23888prodH19888RAID0HB Woops!!! -
BUT... RAID5 doesn’t seem correlated to msg queues iostat8Hkx81 has
weak correlation as well No anonymous paging going on (swap thrash) -
SCHEDULING CONVOYS 1. Very few processes runnable 2. Some event
happens 3. RUN ALL THE PROCESSES!!!!!!! aka “stampeding herd” -
STILL NO SMOKING GUN Bitcask merges? NOPE - 0 IOPS
Tune /proc/sys/vm8dirty_* values NO EFFECT Increase # of async I/O threads NO EFFECT -
FOUND A BUG!!! The Riak system monitor didn’t correctly report
“busy_dist_port” events Fix bug and BOOM!!!! Zillions of “busy_dist_port” events Increased dist port buffer size and rolled restart, but problem was not fixed -
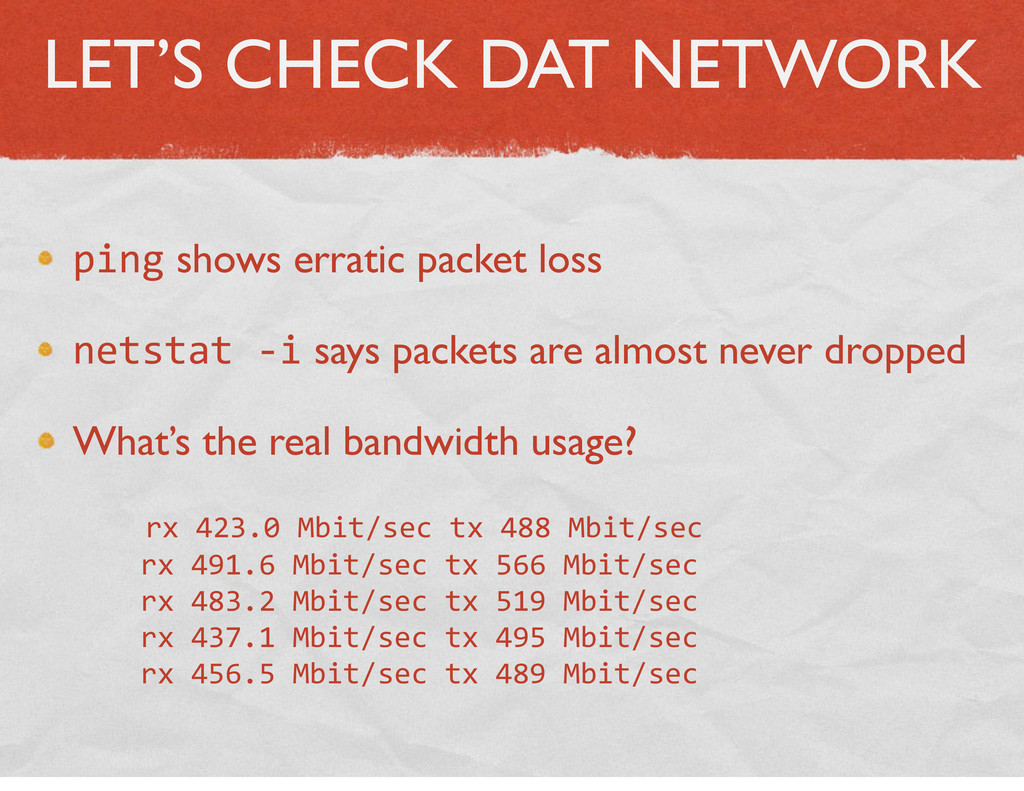
LET’S CHECK DAT NETWORK ping shows erratic packet loss netstat8Hi
says packets are almost never dropped What’s the real bandwidth usage? 8888rx8423.08Mbit/sec8tx84888Mbit/sec 8888rx8491.68Mbit/sec8tx85668Mbit/sec 8888rx8483.28Mbit/sec8tx85198Mbit/sec 8888rx8437.18Mbit/sec8tx84958Mbit/sec 8888rx8456.58Mbit/sec8tx84898Mbit/sec -
THAT’S ONLY HALF, RIGHT? MANY busy_dist_ports at 50% utilization Mailbox
sizes don’t drain if tput > 450Mb/sec At peak, many hundreds of packets/sec DROPPED WTF? -
A THEORY Hosting provider’s switches show egress packet drops Theory:
Even if average util is < 50%... microbursts in tiny windows ~> line rate switch buffers fill up packets drop! -
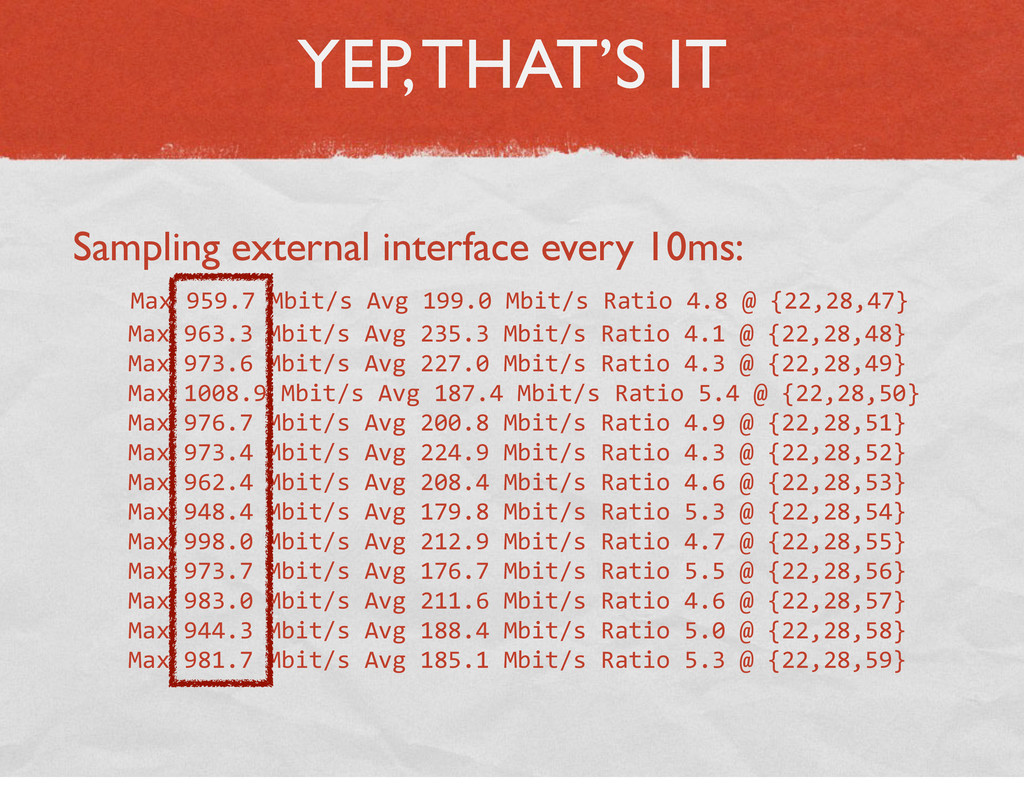
YEP, THAT’S IT Sampling external interface every 10ms: Max8959.78Mbit/s8Avg8199.08Mbit/s8Ratio84.88@8{22,28,47} 8888Max8963.38Mbit/s8Avg8235.38Mbit/s8Ratio84.18@8{22,28,48}
8888Max8973.68Mbit/s8Avg8227.08Mbit/s8Ratio84.38@8{22,28,49} 8888Max81008.98Mbit/s8Avg8187.48Mbit/s8Ratio85.48@8{22,28,50} 8888Max8976.78Mbit/s8Avg8200.88Mbit/s8Ratio84.98@8{22,28,51} 8888Max8973.48Mbit/s8Avg8224.98Mbit/s8Ratio84.38@8{22,28,52} 8888Max8962.48Mbit/s8Avg8208.48Mbit/s8Ratio84.68@8{22,28,53} 8888Max8948.48Mbit/s8Avg8179.88Mbit/s8Ratio85.38@8{22,28,54} 8888Max8998.08Mbit/s8Avg8212.98Mbit/s8Ratio84.78@8{22,28,55} 8888Max8973.78Mbit/s8Avg8176.78Mbit/s8Ratio85.58@8{22,28,56} 8888Max8983.08Mbit/s8Avg8211.68Mbit/s8Ratio84.68@8{22,28,57} 8888Max8944.38Mbit/s8Avg8188.48Mbit/s8Ratio85.08@8{22,28,58} 8888Max8981.78Mbit/s8Avg8185.18Mbit/s8Ratio85.38@8{22,28,59} -
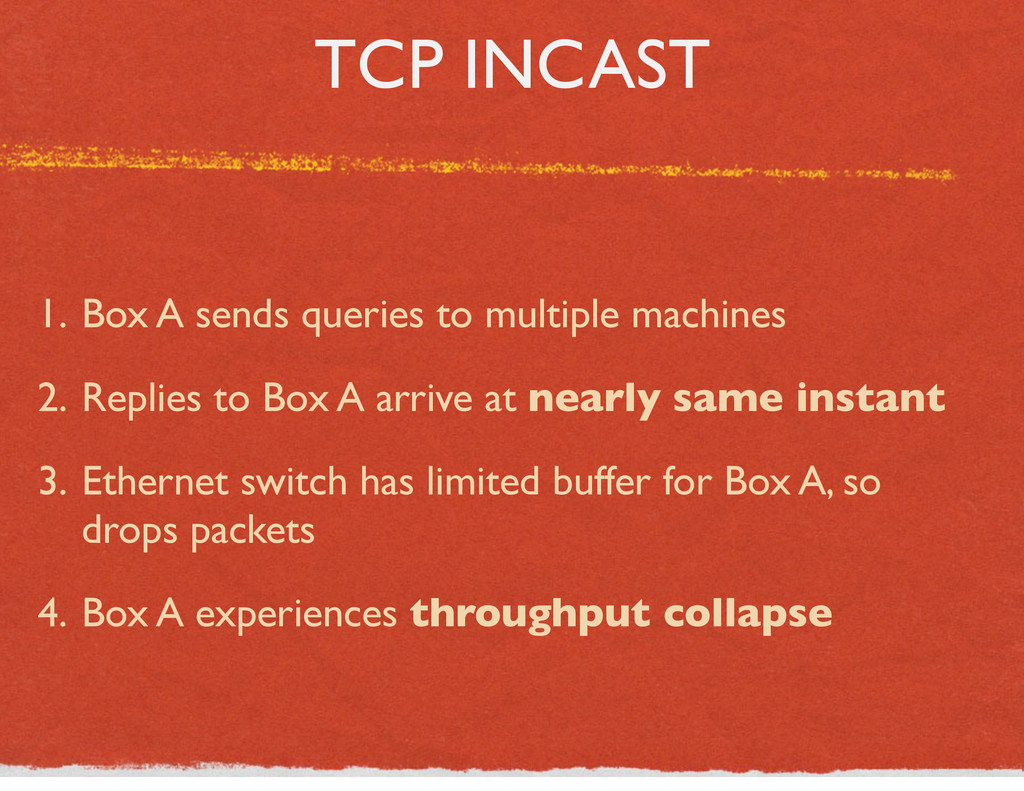
TCP INCAST 1. Box A sends queries to multiple machines
2. Replies to Box A arrive at nearly same instant 3. Ethernet switch has limited buffer for Box A, so drops packets 4. Box A experiences throughput collapse -
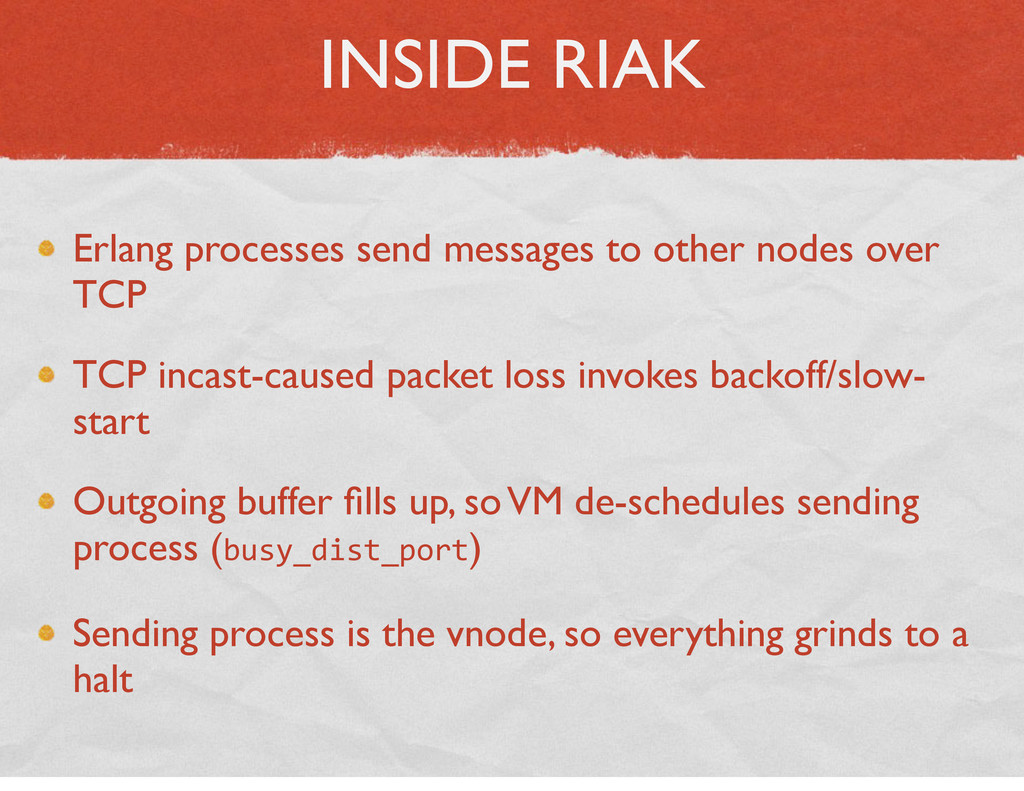
INSIDE RIAK Erlang processes send messages to other nodes over
TCP TCP incast-caused packet loss invokes backoff/slow- start Outgoing buffer fills up, so VM de-schedules sending process (busy_dist_port ) Sending process is the vnode, so everything grinds to a halt -
MORAL OF THE STORY One-second resolution is often too big
Averages tell you very little of the story “You can’t pour two buckets of manure into one bucket.” -
LESSONS LEARNED Monitoring and metrics are essential DUH Small failures
can lead to big failures Causes are not always obvious Brashly “scaling out” can make things worse