Upgrade to Pro — share decks privately, control downloads, hide ads and more …

One spec to validate them all: Testing and fixi...

One spec to validate them all: Testing and fixing agent integrations at scale

Temporal ships plugins that make agent SDKs durable, from OpenAI Agents and Google ADK to LangGraph, Strands and Pydantic AI. Before calling them GA, we needed to know how well each one held up, and reading them by hand wasn't going to scale.

Every plugin solves the same problem, so we asked them all the same questions. We wrote those questions once, as a single spec precise enough for coding agents to turn each one into a runnable reproduction for every plugin, many of them injecting failures on purpose. The basics held up everywhere. The agents also dug into the corners and found hundreds of defects, most of which only appear in specific setups. Fixes landed within weeks, and every lesson learned on one plugin became a check for the rest.

It also went wrong in useful ways: rules the agents couldn't see, and a review loop that burned an absurd number of tokens on one pull request.

You'll leave with a recipe for any family of integrations, SDKs or services that share a contract, and a clear view of where humans still have to stay in the loop.

Francesc Campoy Flores

November 18, 2026

Transcript

40 slides
  1. One spec to validate them all Testing and fixing agent

    integrations at scale Francesc Campoy Flores Staff Software Engineer, Temporal AI Software Factory Summit
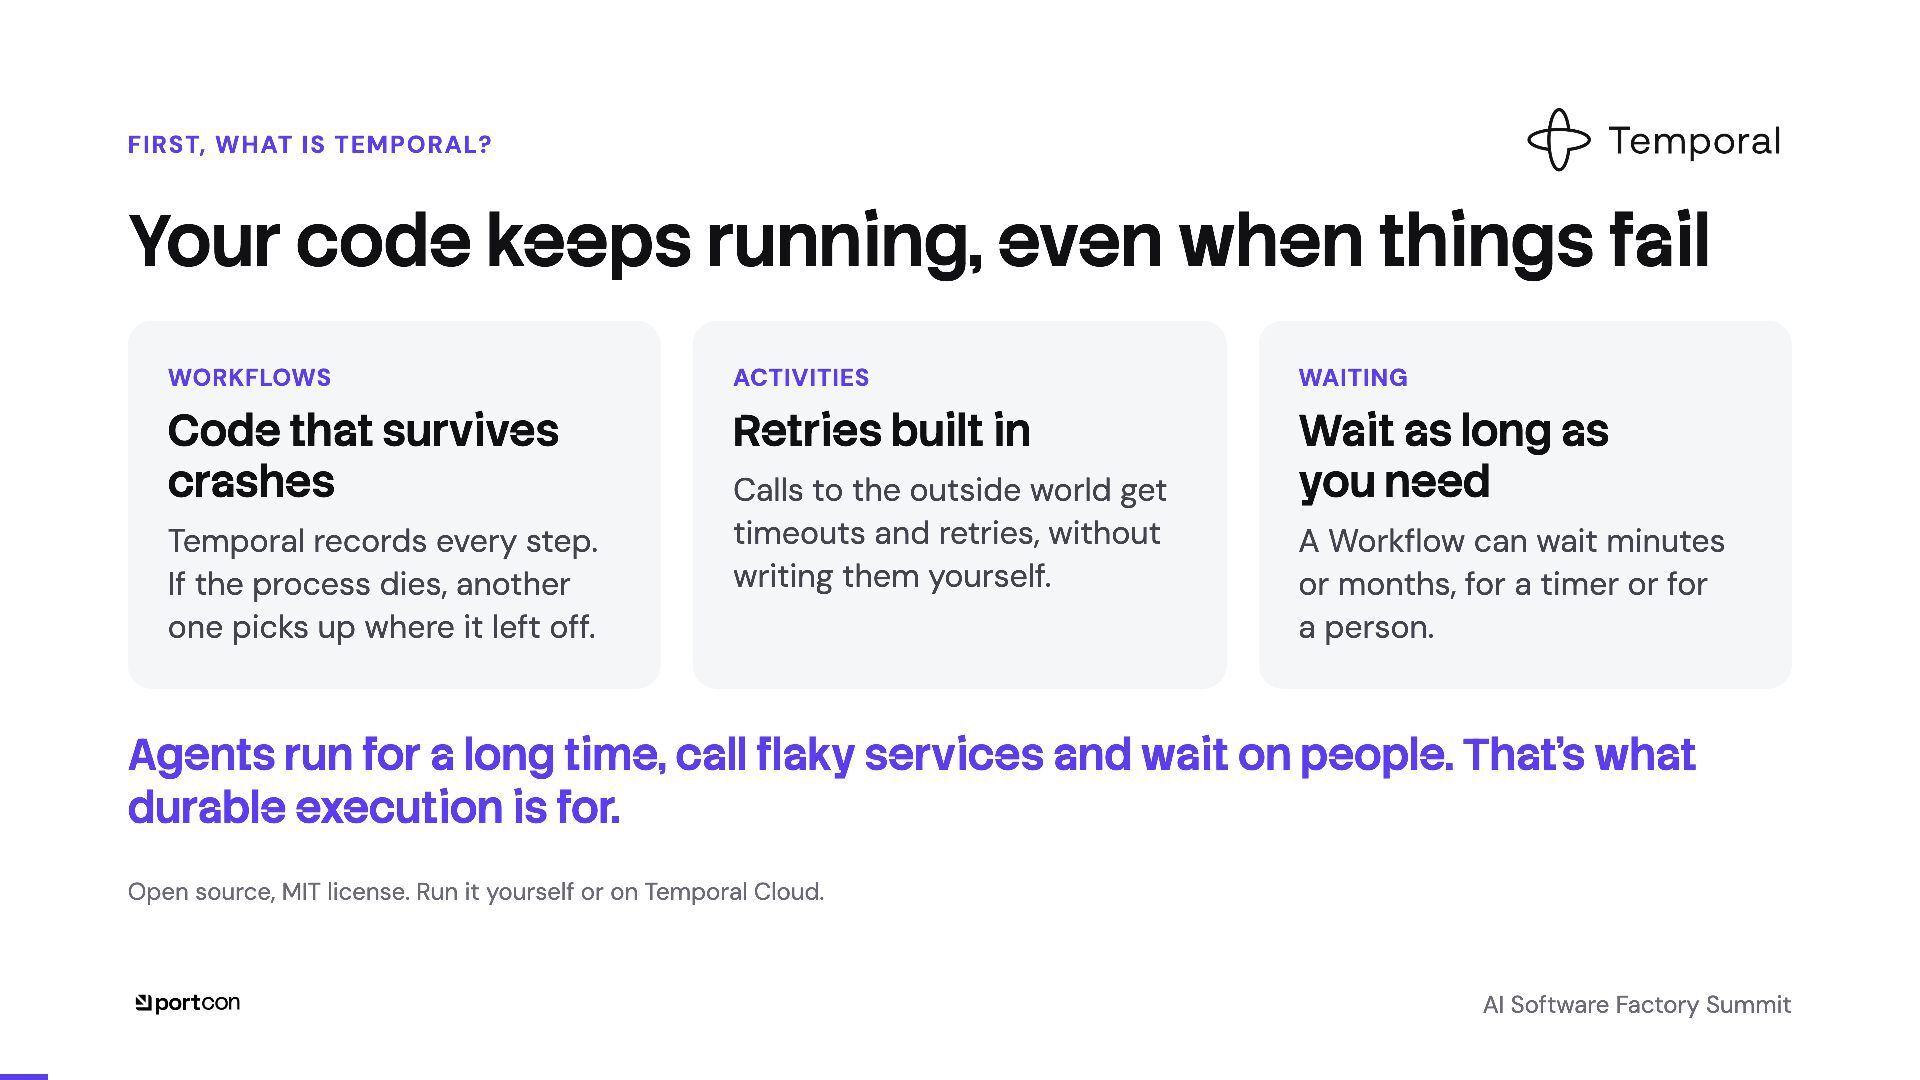
  2. FIRST, WHAT IS TEMPORAL? Your code keeps running, even when
    things fail WORKFLOWS ACTIVITIES WAITING Code that survives crashes Retries built in Wait as long as you need Temporal records every step. If the process dies, another one picks up where it left off. Calls to the outside world get timeouts and retries, without writing them yourself. A Workflow can wait minutes or months, for a timer or for a person. Agents run for a long time, call flaky services and wait on people. That’s what durable execution is for. Open source, MIT license. Run it yourself or on Temporal Cloud. AI Software Factory Summit
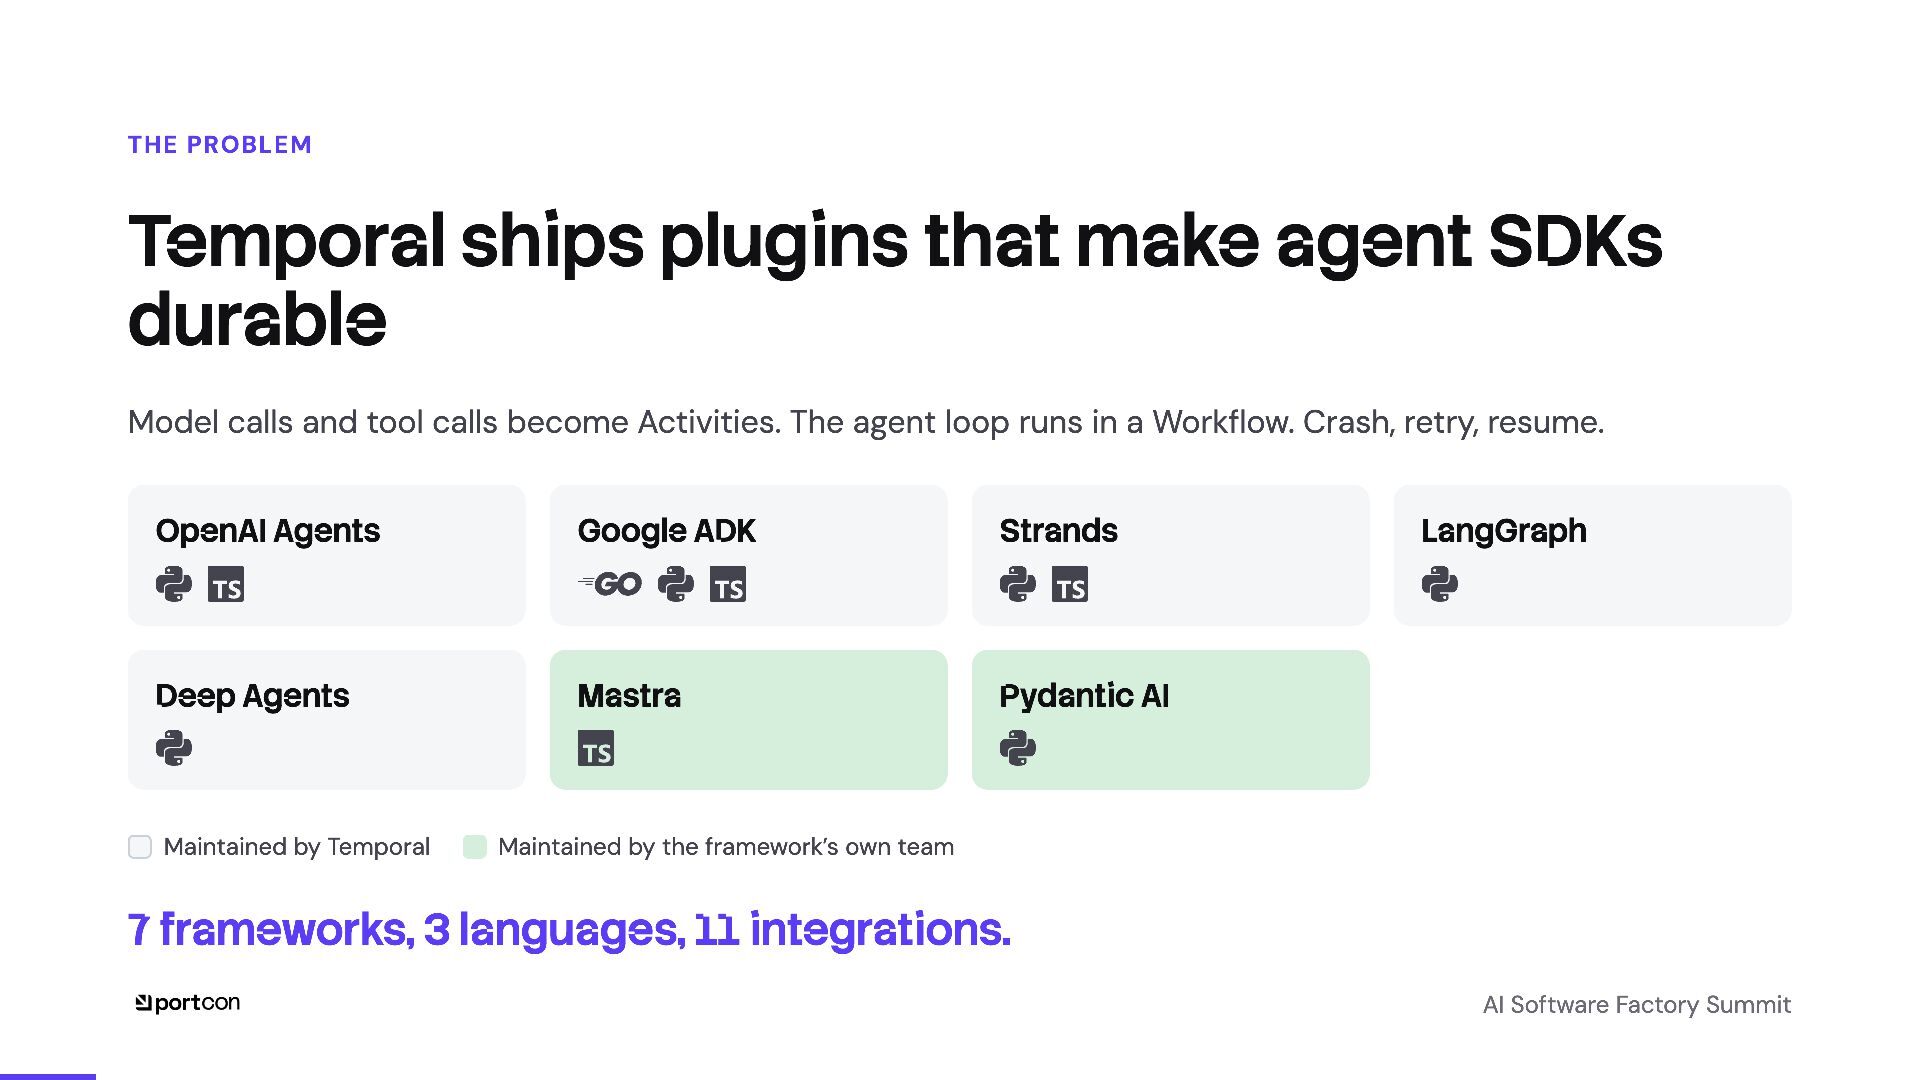
  3. THE PROBLEM Temporal ships plugins that make agent SDKs durable

    Model calls and tool calls become Activities. The agent loop runs in a Workflow. Crash, retry, resume. OpenAI Agents Google ADK Strands Deep Agents Mastra Pydantic AI Maintained by Temporal LangGraph Maintained by the framework’s own team 7 frameworks, 3 languages, 11 integrations. AI Software Factory Summit
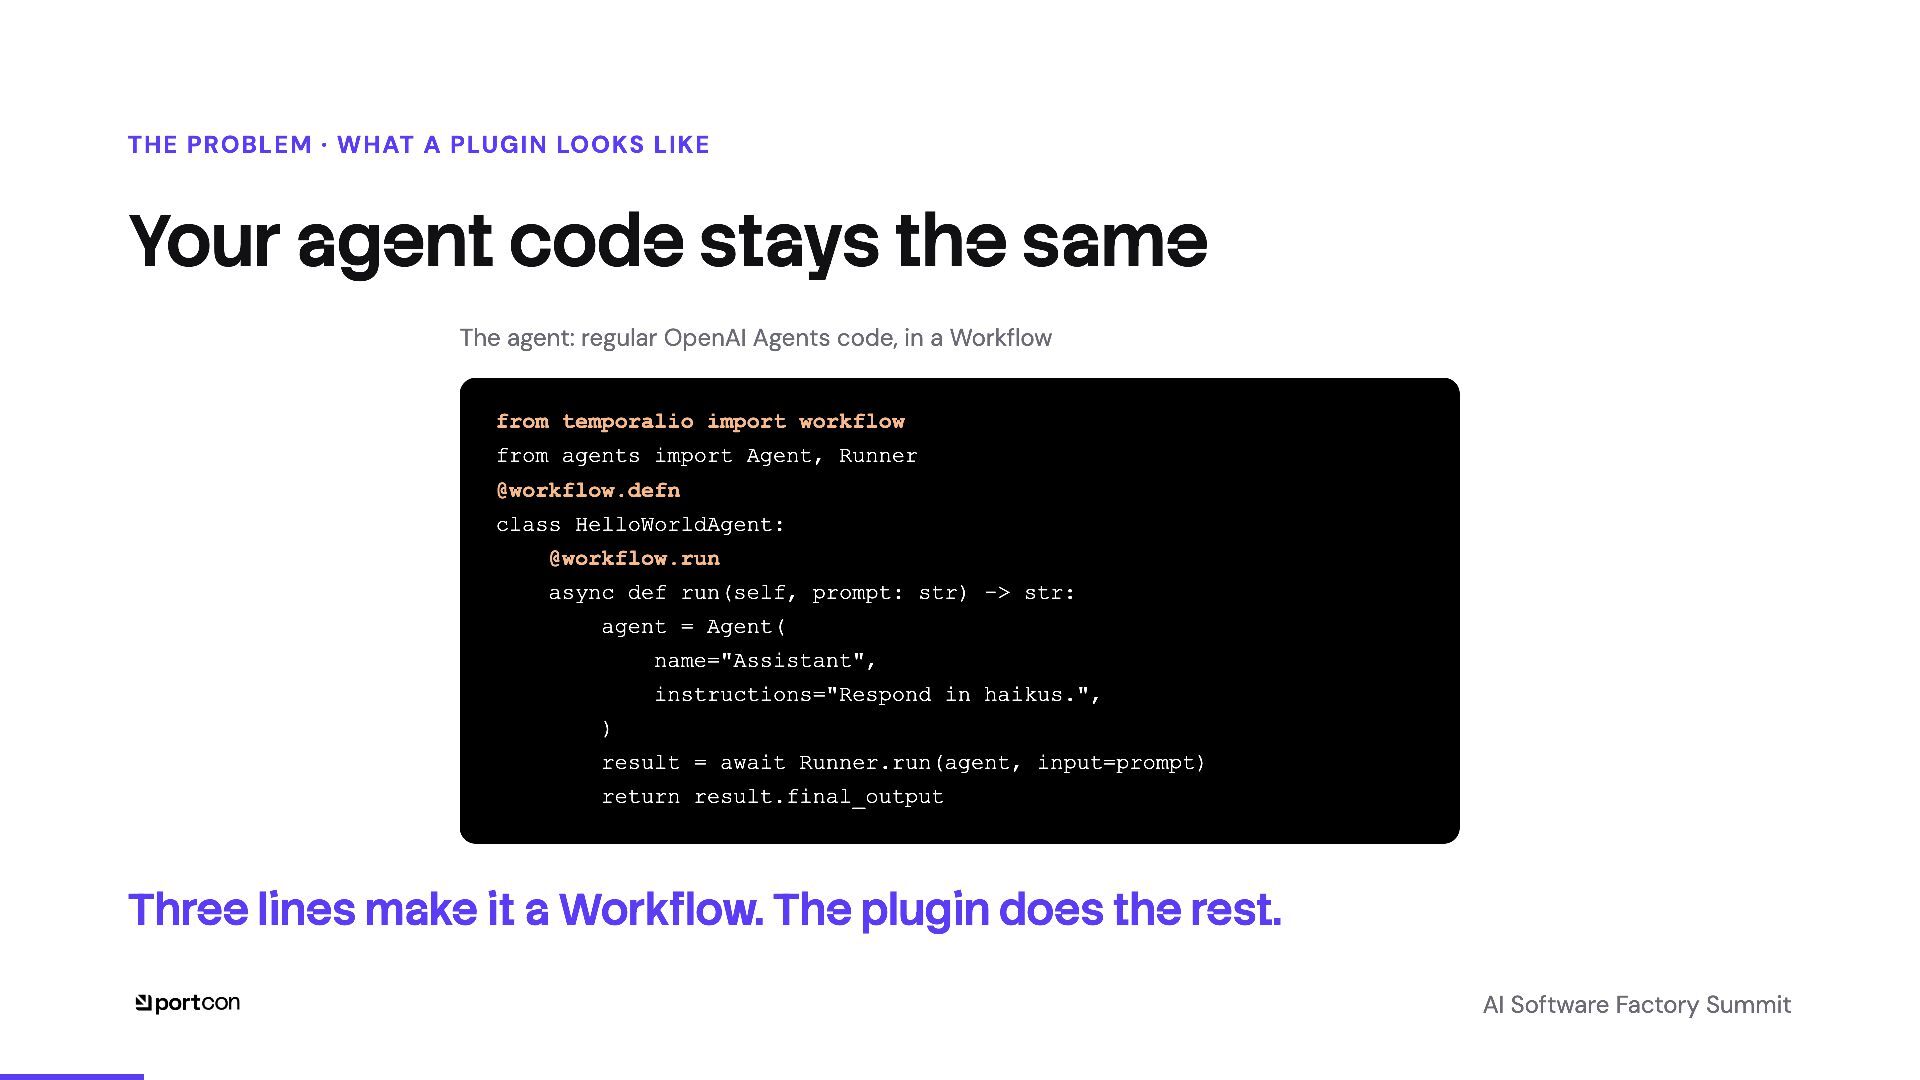
  4. THE PROBLEM · WHAT A PLUGIN LOOKS LIKE Your agent

    code stays the same The agent: regular OpenAI Agents code, in a Workflow from temporalio import workflow from agents import Agent, Runner @workflow.defn class HelloWorldAgent: @workflow.run async def run(self, prompt: str) -> str: agent = Agent( name="Assistant", instructions="Respond in haikus.", ) result = await Runner.run(agent, input=prompt) return result.final_output Three lines make it a Workflow. The plugin does the rest. AI Software Factory Summit
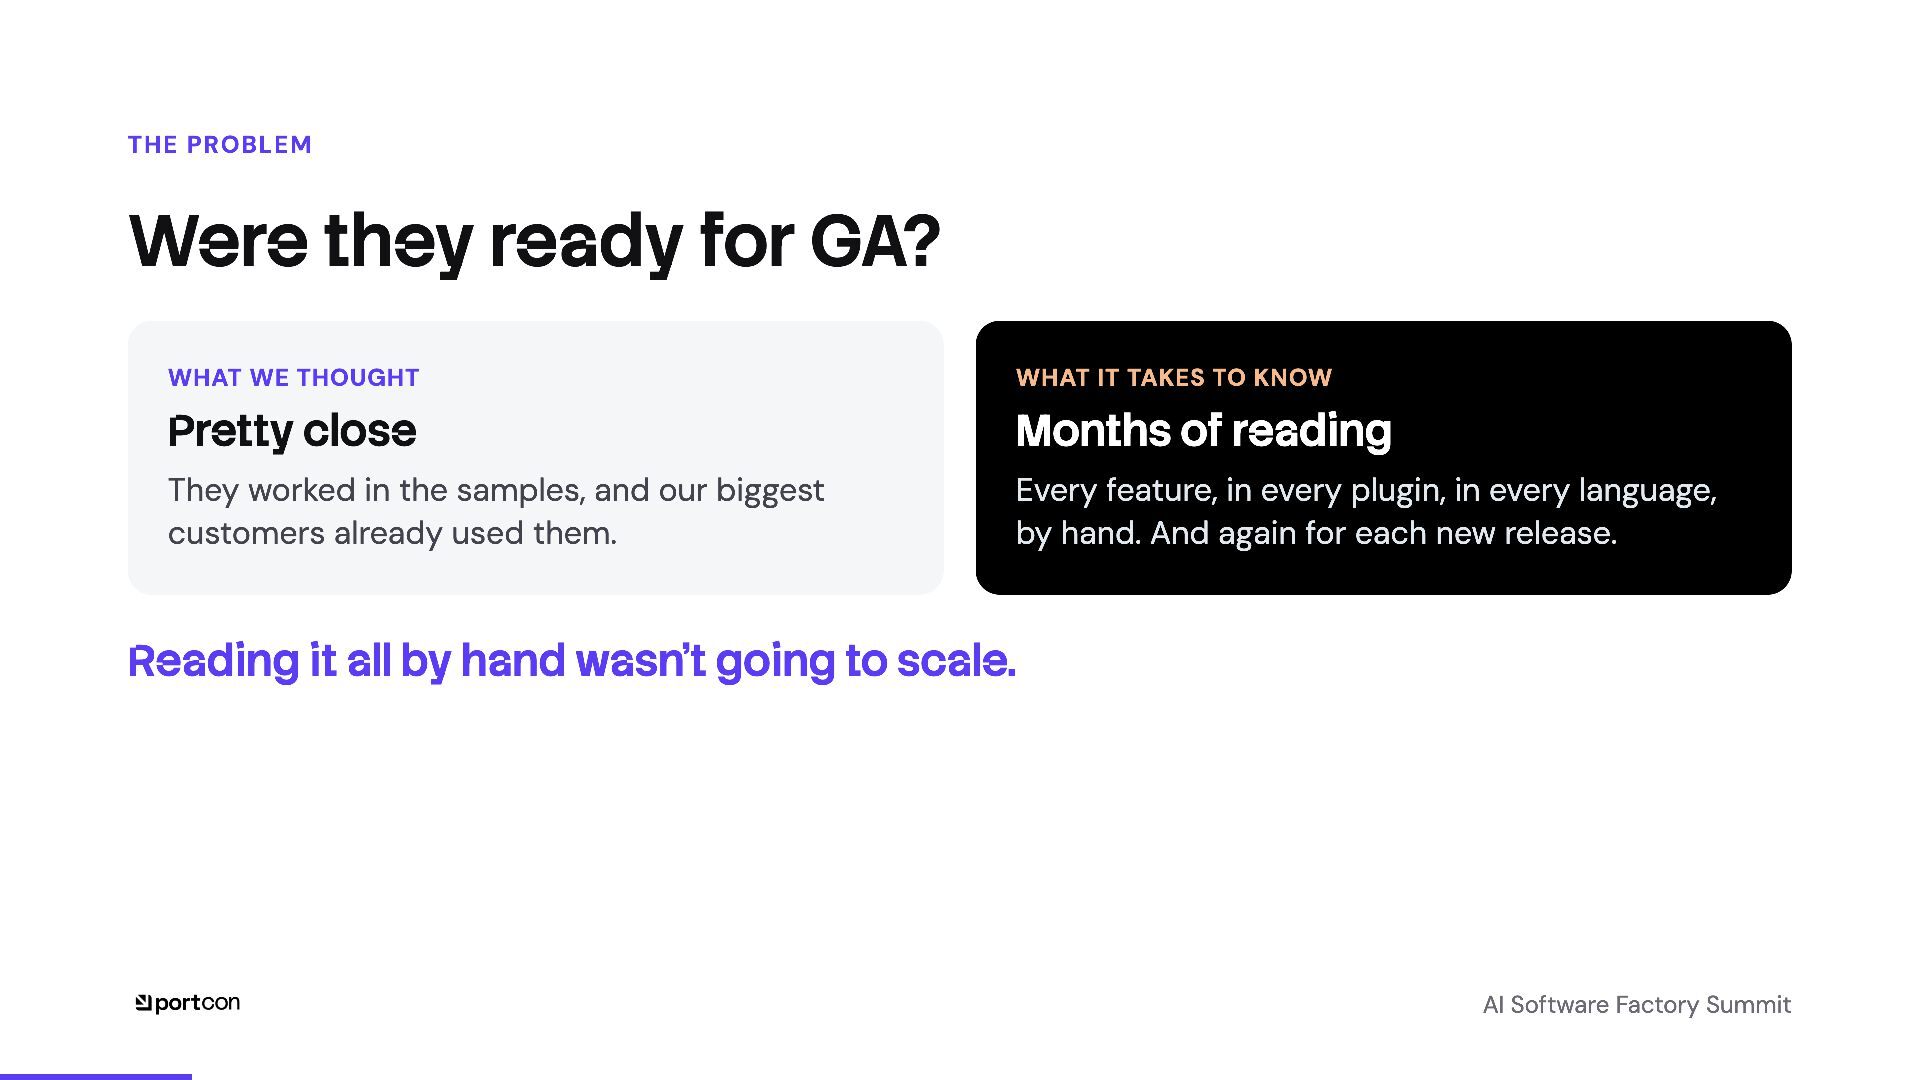
  5. THE PROBLEM Were they ready for GA? WHAT WE THOUGHT

    WHAT IT TAKES TO KNOW Pretty close Months of reading They worked in the samples, and our biggest customers already used them. Every feature, in every plugin, in every language, by hand. And again for each new release. Reading it all by hand wasn’t going to scale. AI Software Factory Summit
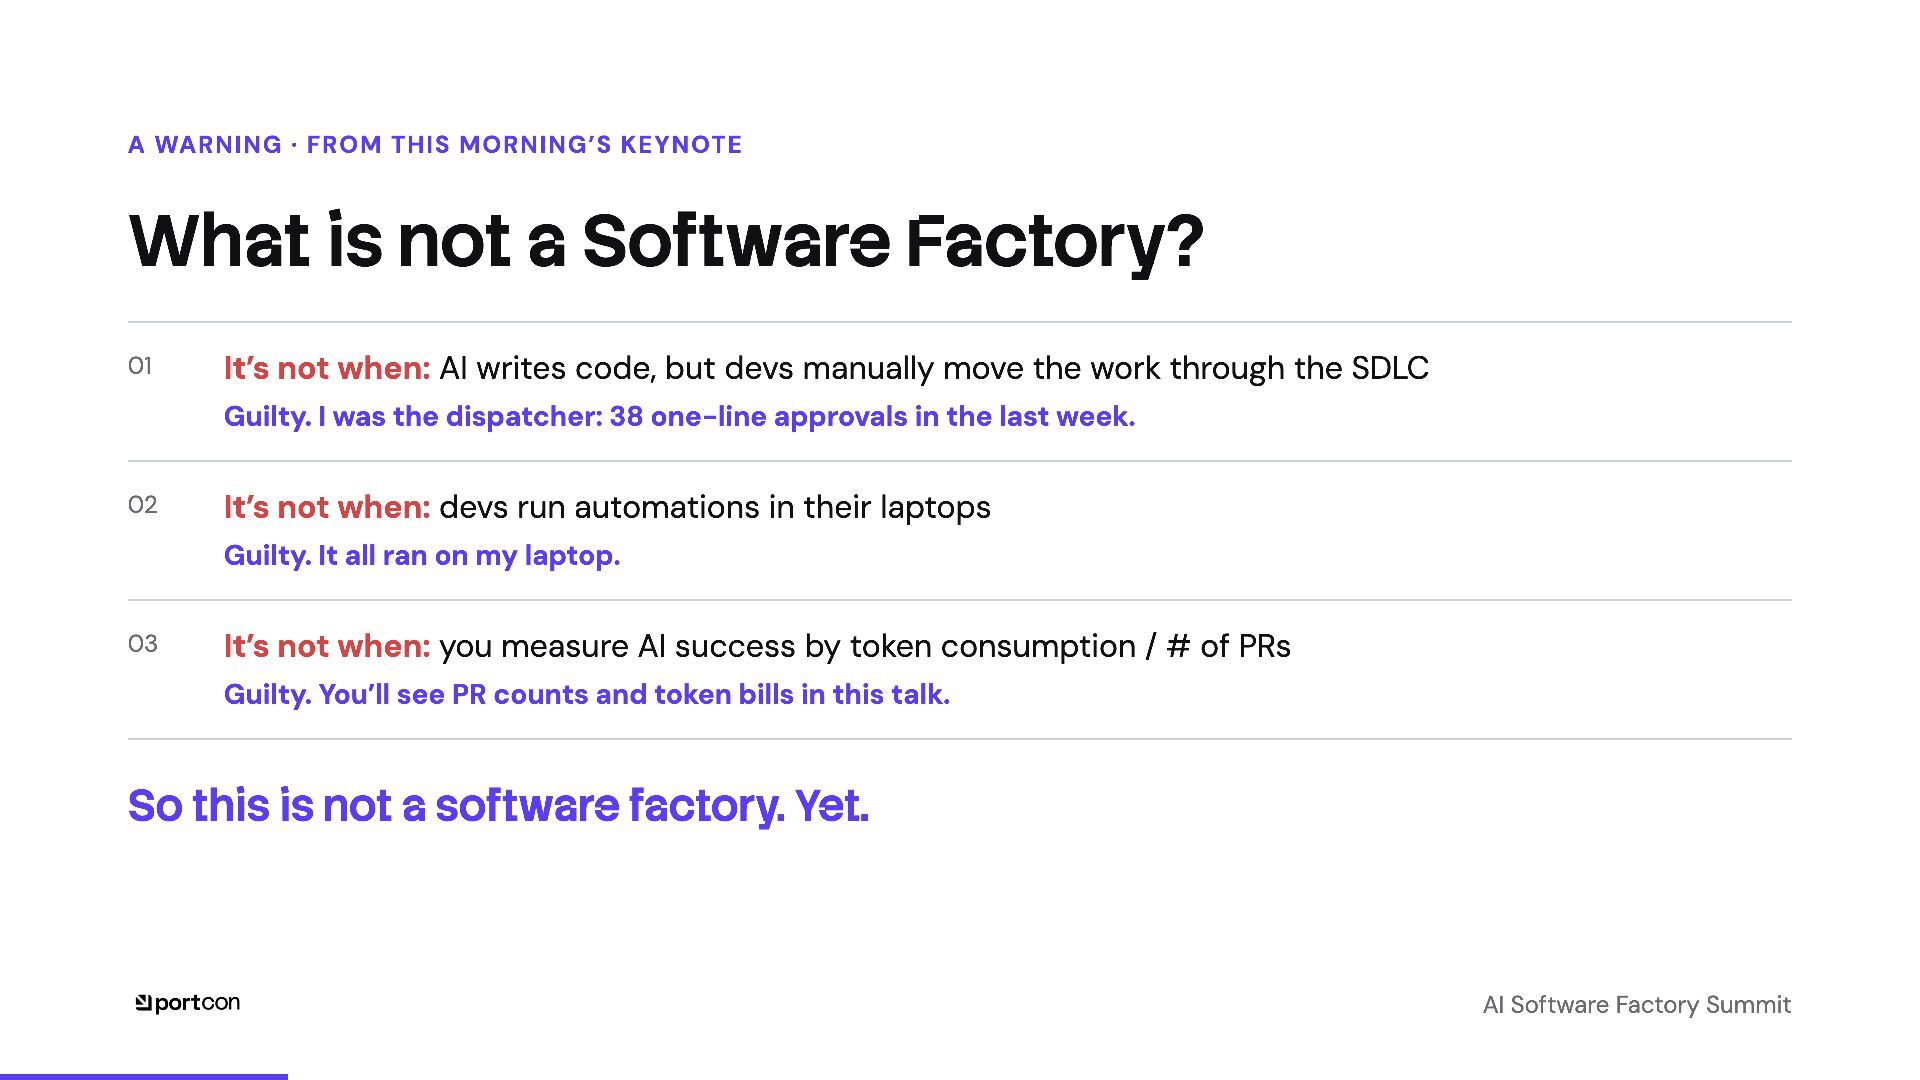
  6. A WARNING · FROM THIS MORNING’S KEYNOTE What is not

    a Software Factory? 01 It’s not when: AI writes code, but devs manually move the work through the SDLC Guilty. I was the dispatcher: 38 one-line approvals in the last week. 02 It’s not when: devs run automations in their laptops Guilty. It all ran on my laptop. 03 It’s not when: you measure AI success by token consumption / # of PRs Guilty. You’ll see PR counts and token bills in this talk. This is not a software factory. Yet? AI Software Factory Summit
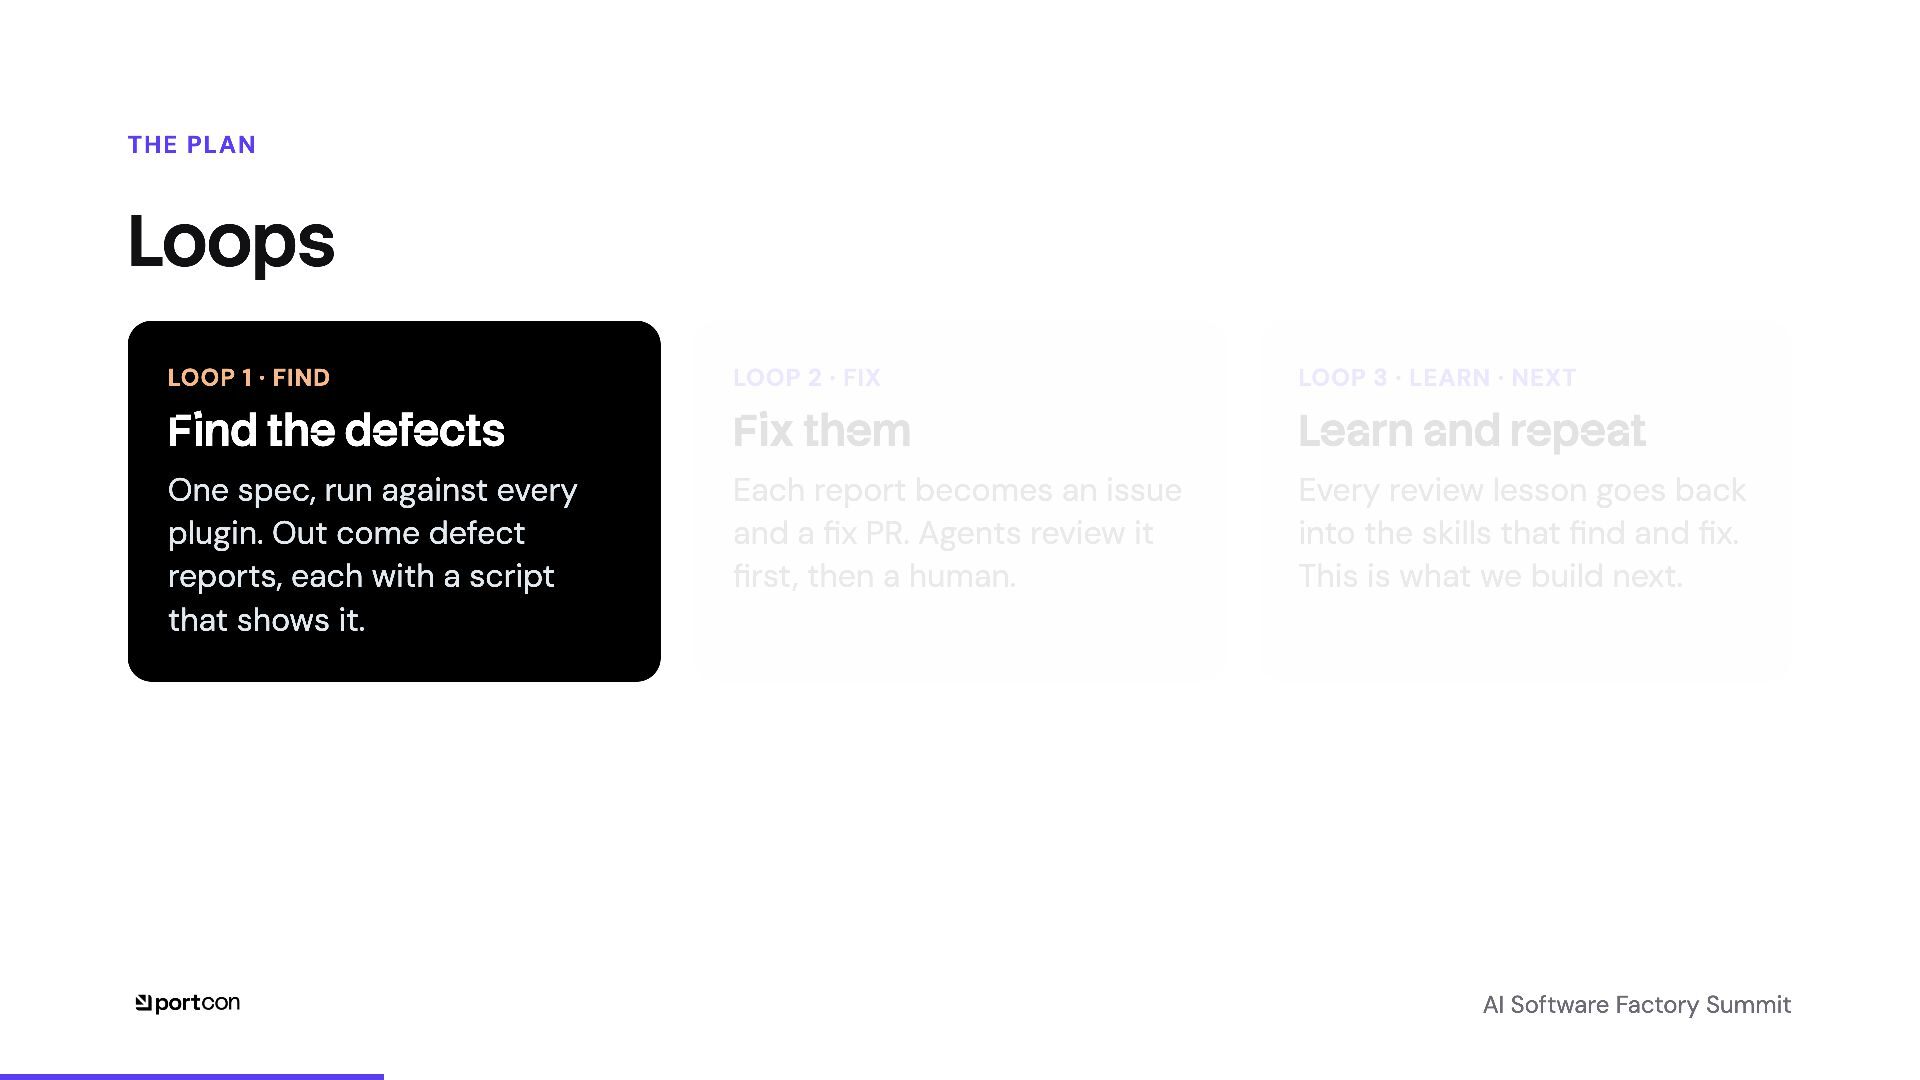
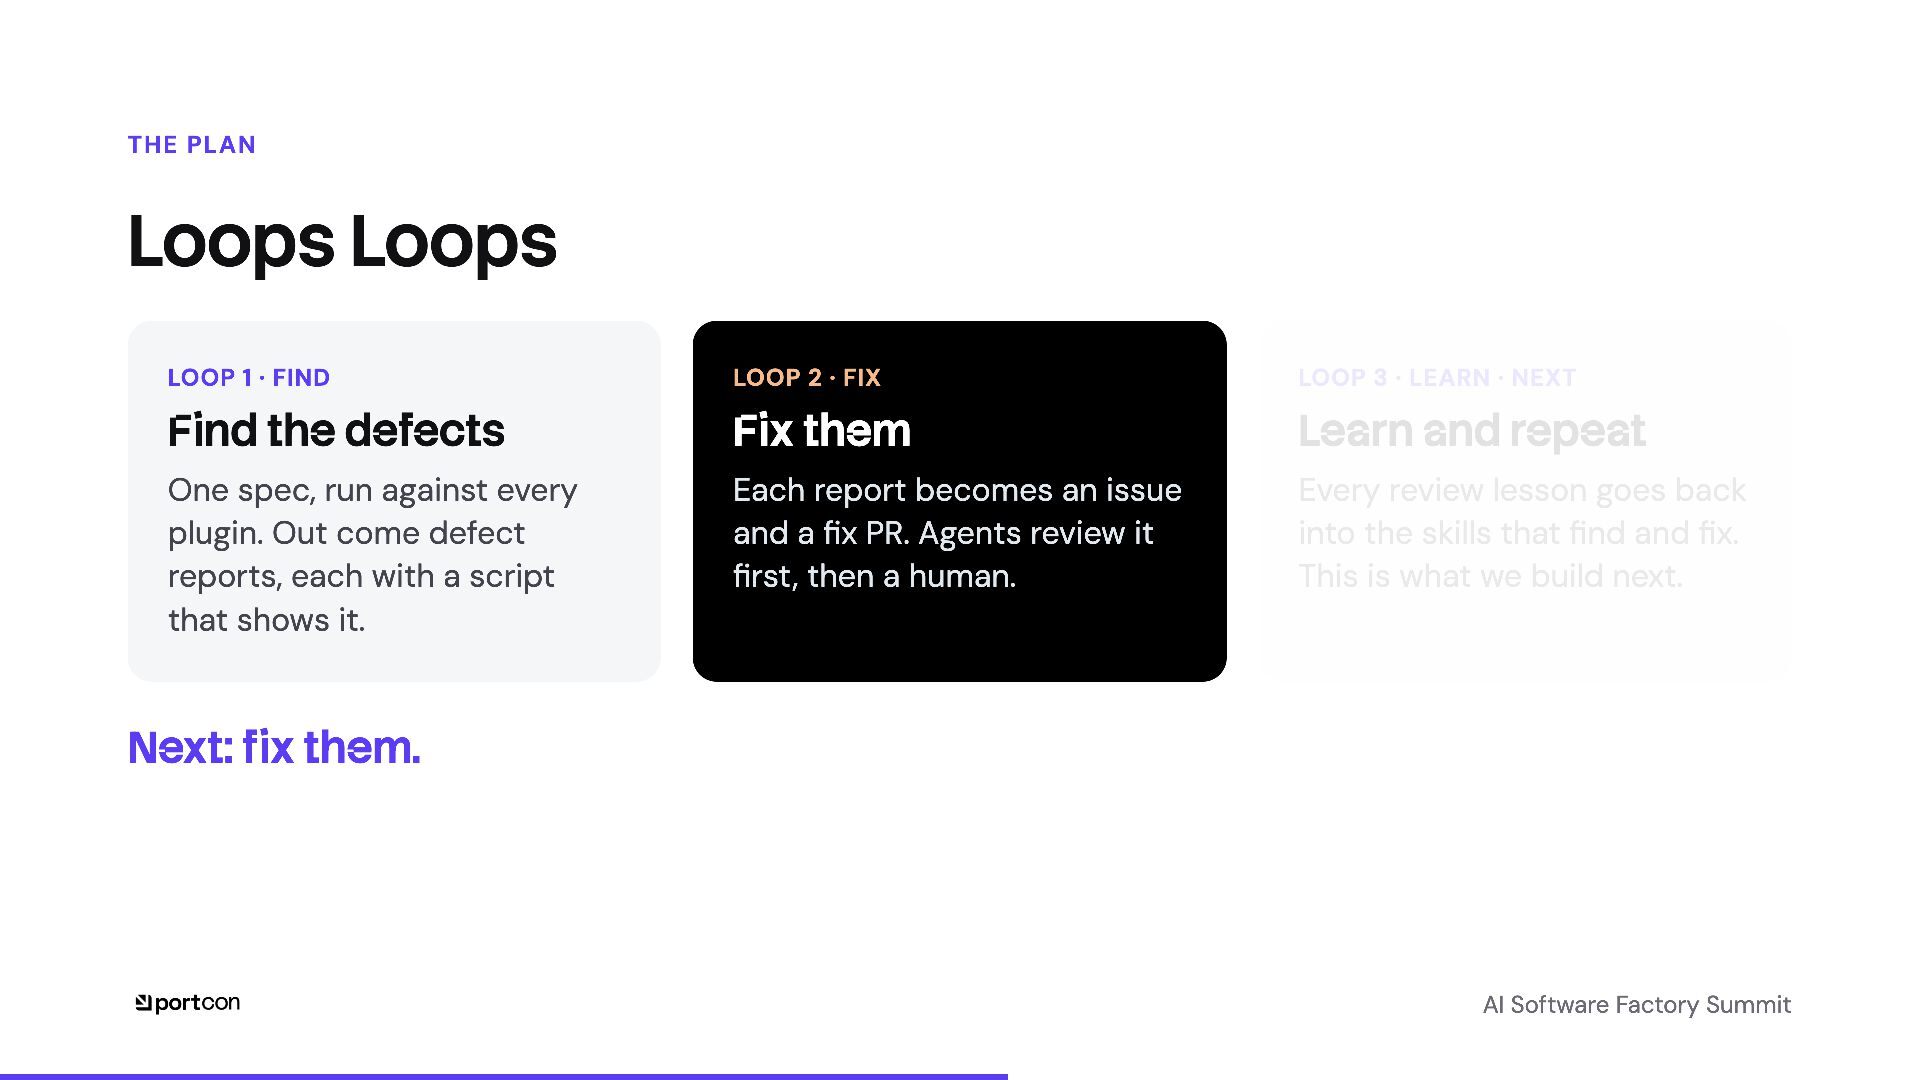
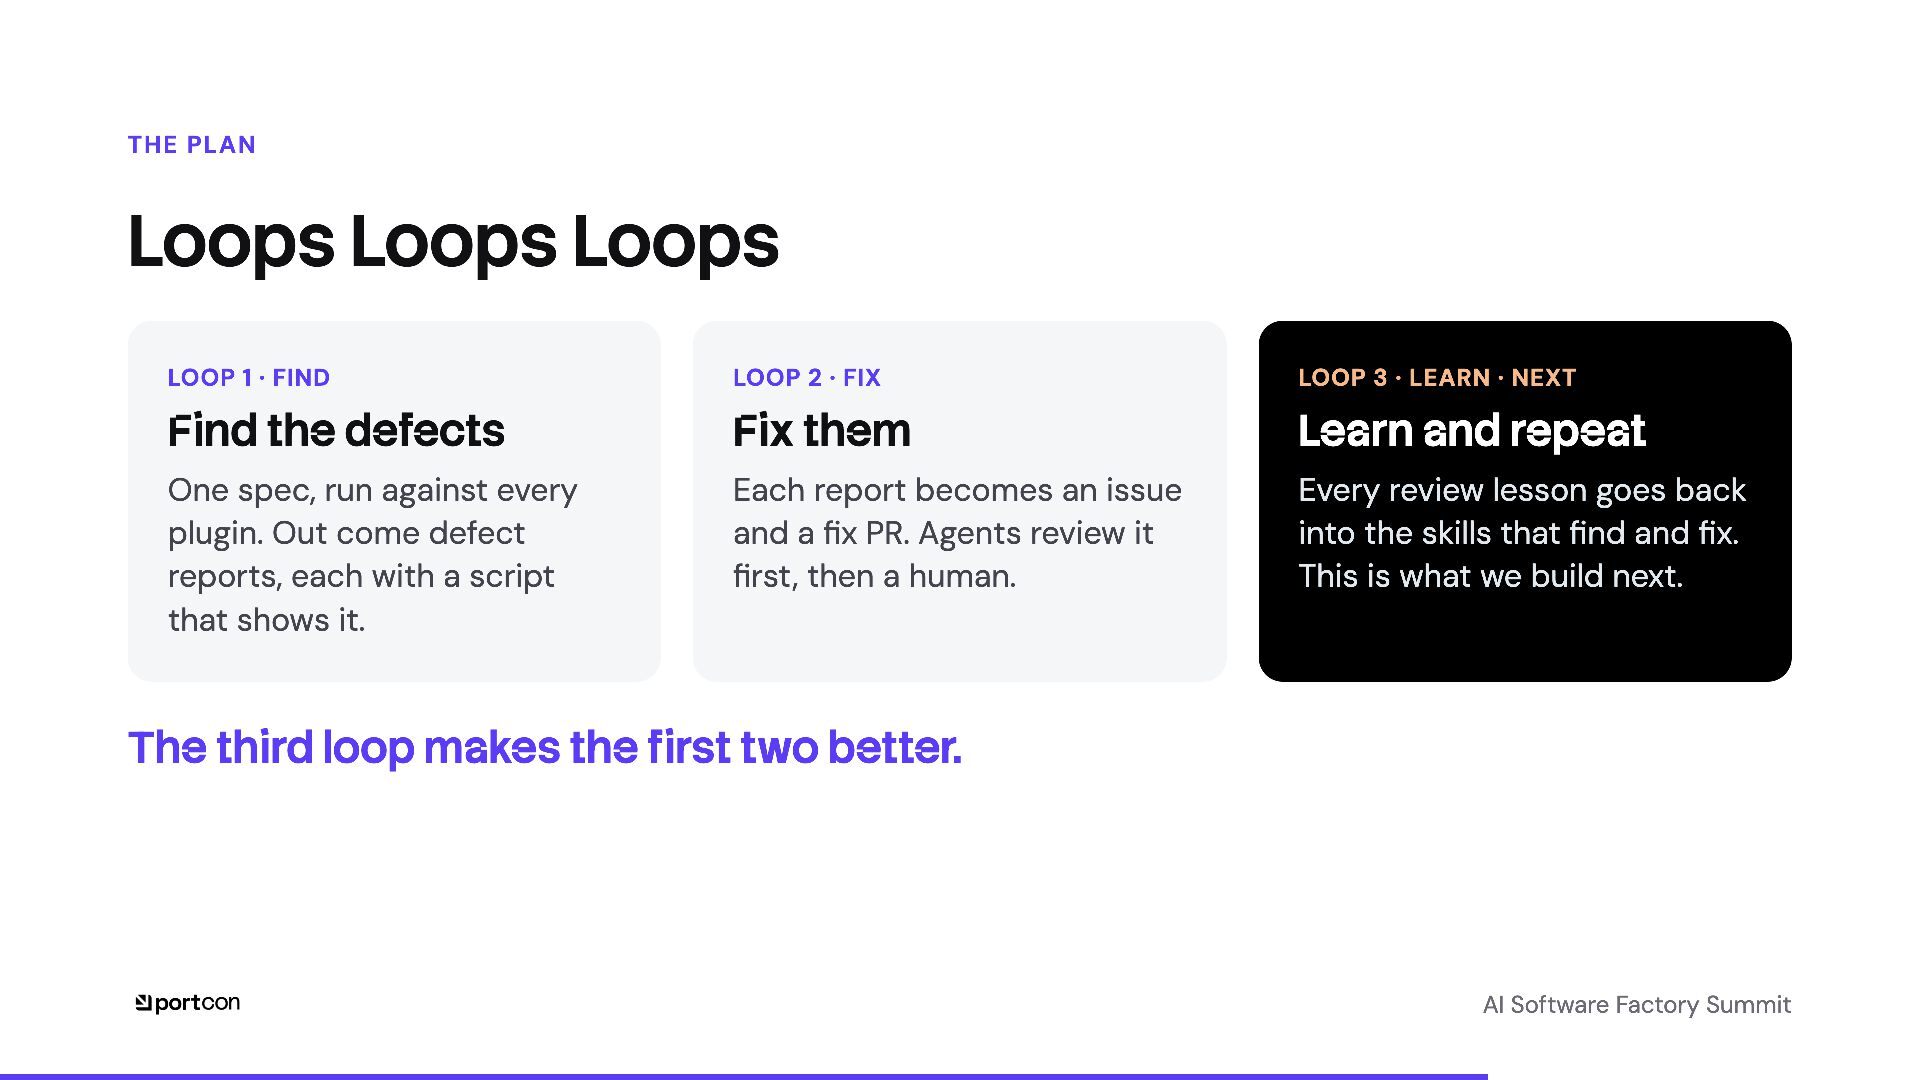
  7. THE PLAN Loops LOOP 1 · FIND LOOP 2 ·

    FIX LOOP 3 · LEARN · NEXT Find the defects Fix them Learn and repeat One spec, run against every plugin. Out come defect reports, each with a script that shows it. Each report becomes an issue and a fix PR. Agents review it first, then a human. Every review lesson goes back into the skills that find and fix. This is what we build next. AI Software Factory Summit
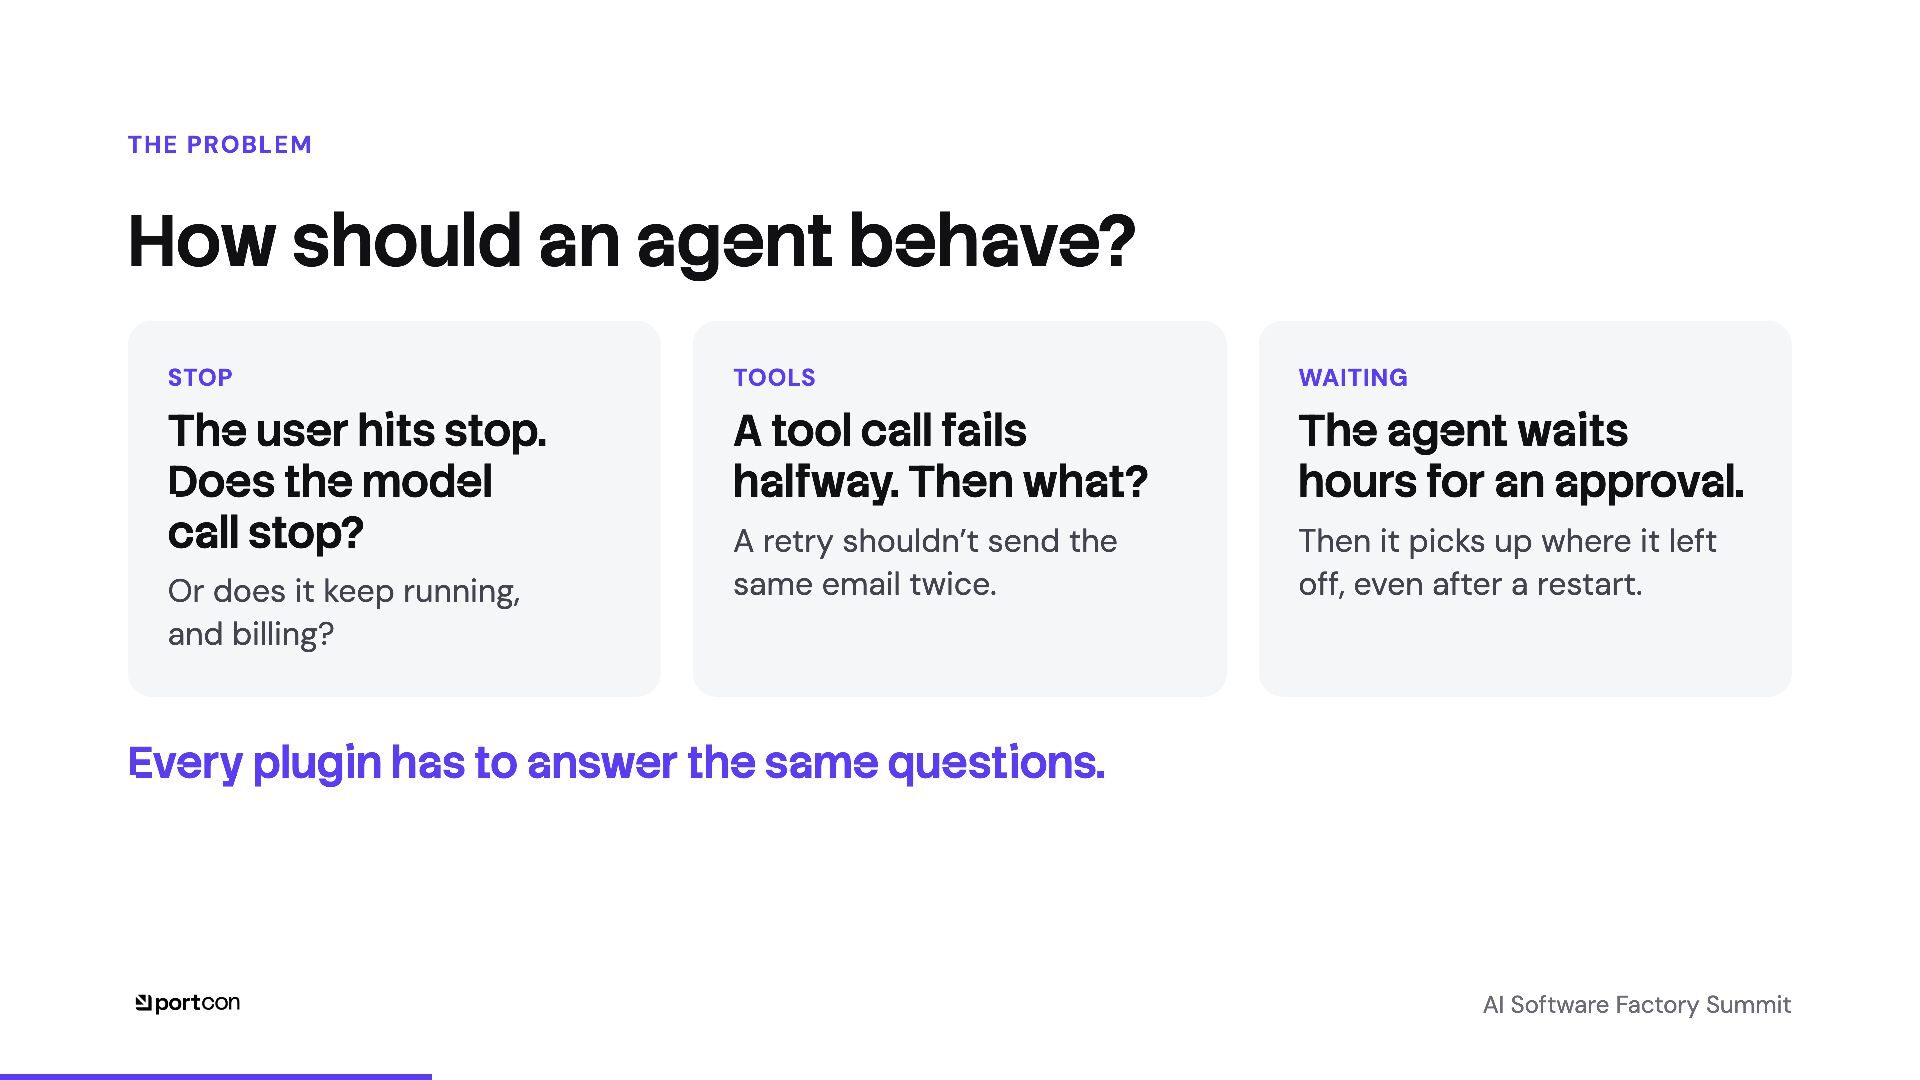
  8. THE PROBLEM How should an agent behave? STOP TOOLS WAITING

    The user hits stop. Does the model call stop? A tool call fails halfway. Then what? The agent waits hours for an approval. A retry shouldn’t send the same email twice. Then it picks up where it left off, even after a restart. Or does it keep running, and billing? Every plugin has to answer the same questions. AI Software Factory Summit
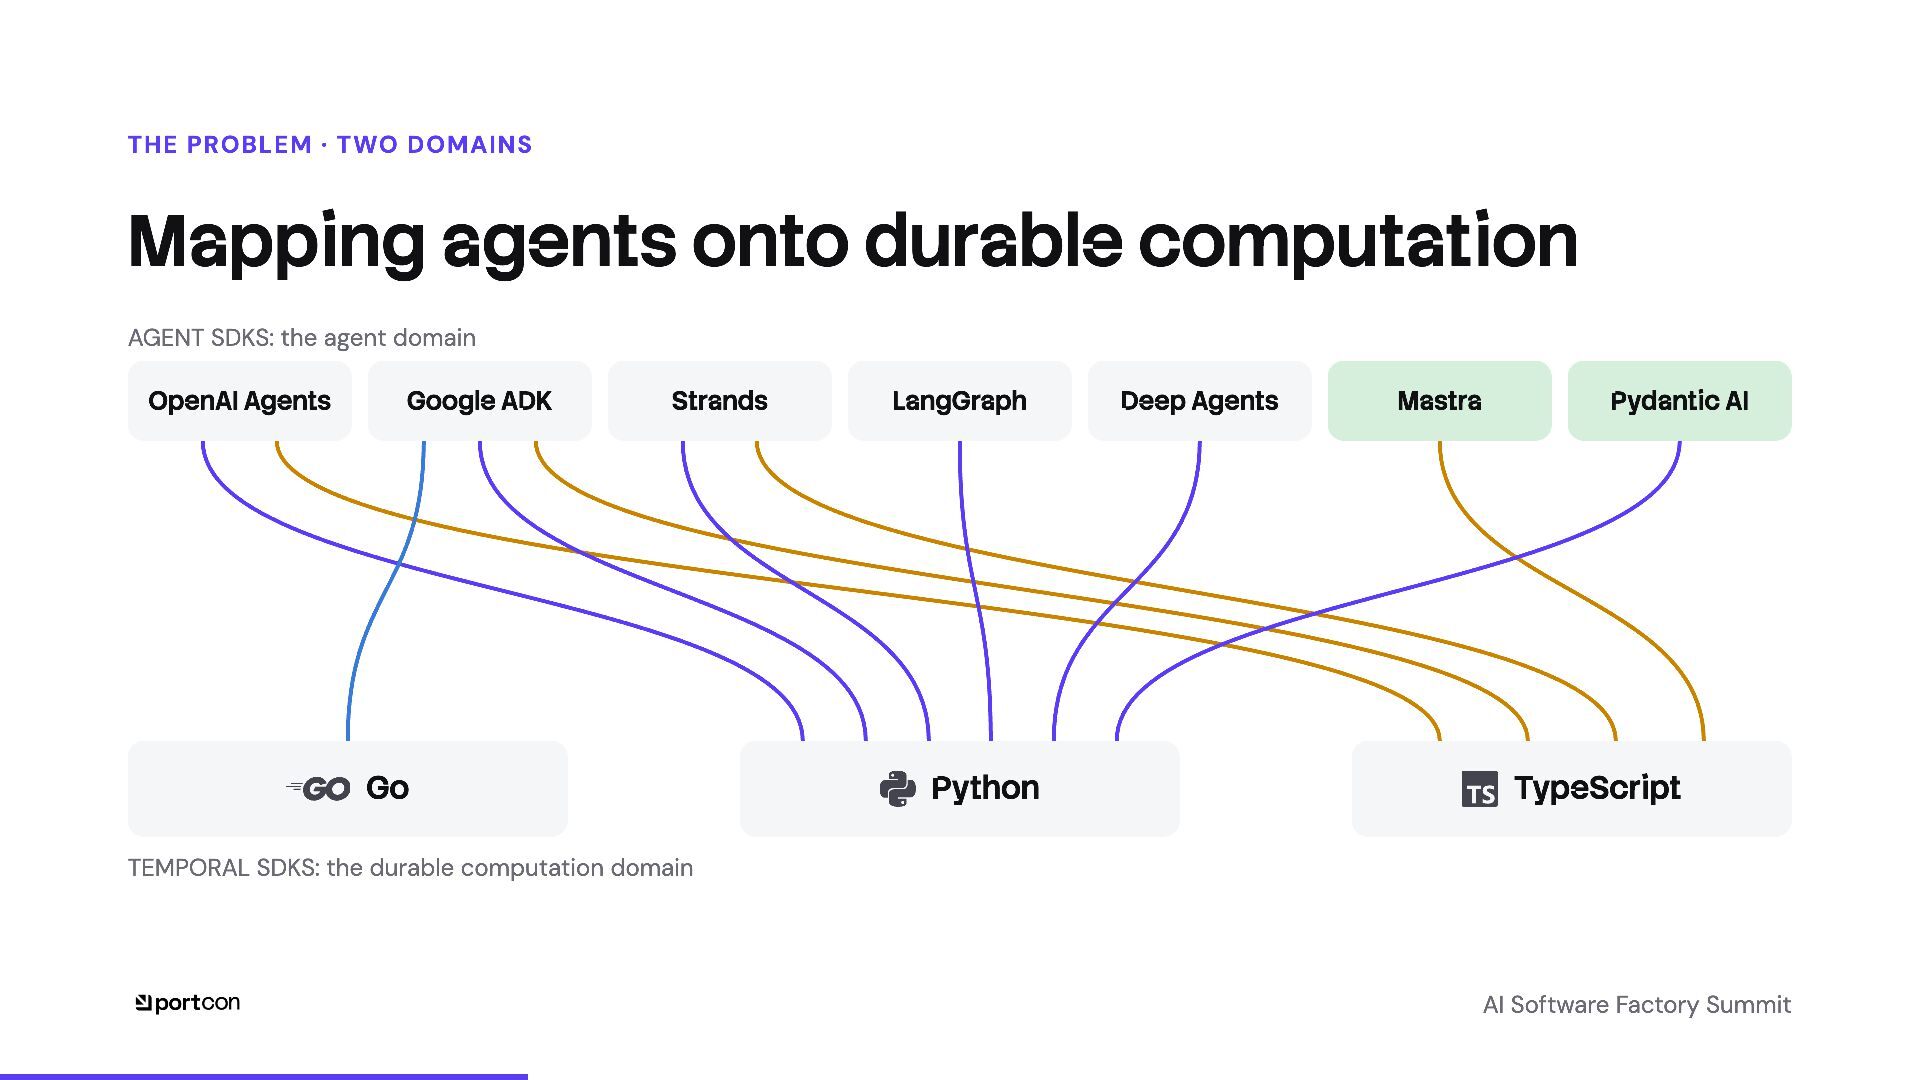
  9. THE PROBLEM · TWO DOMAINS Mapping agents onto durable computation

    AGENT SDKS: the agent domain OpenAI Agents Google ADK Strands Go LangGraph Python Deep Agents Mastra Pydantic AI TypeScript TEMPORAL SDKS: the durable computation domain AI Software Factory Summit
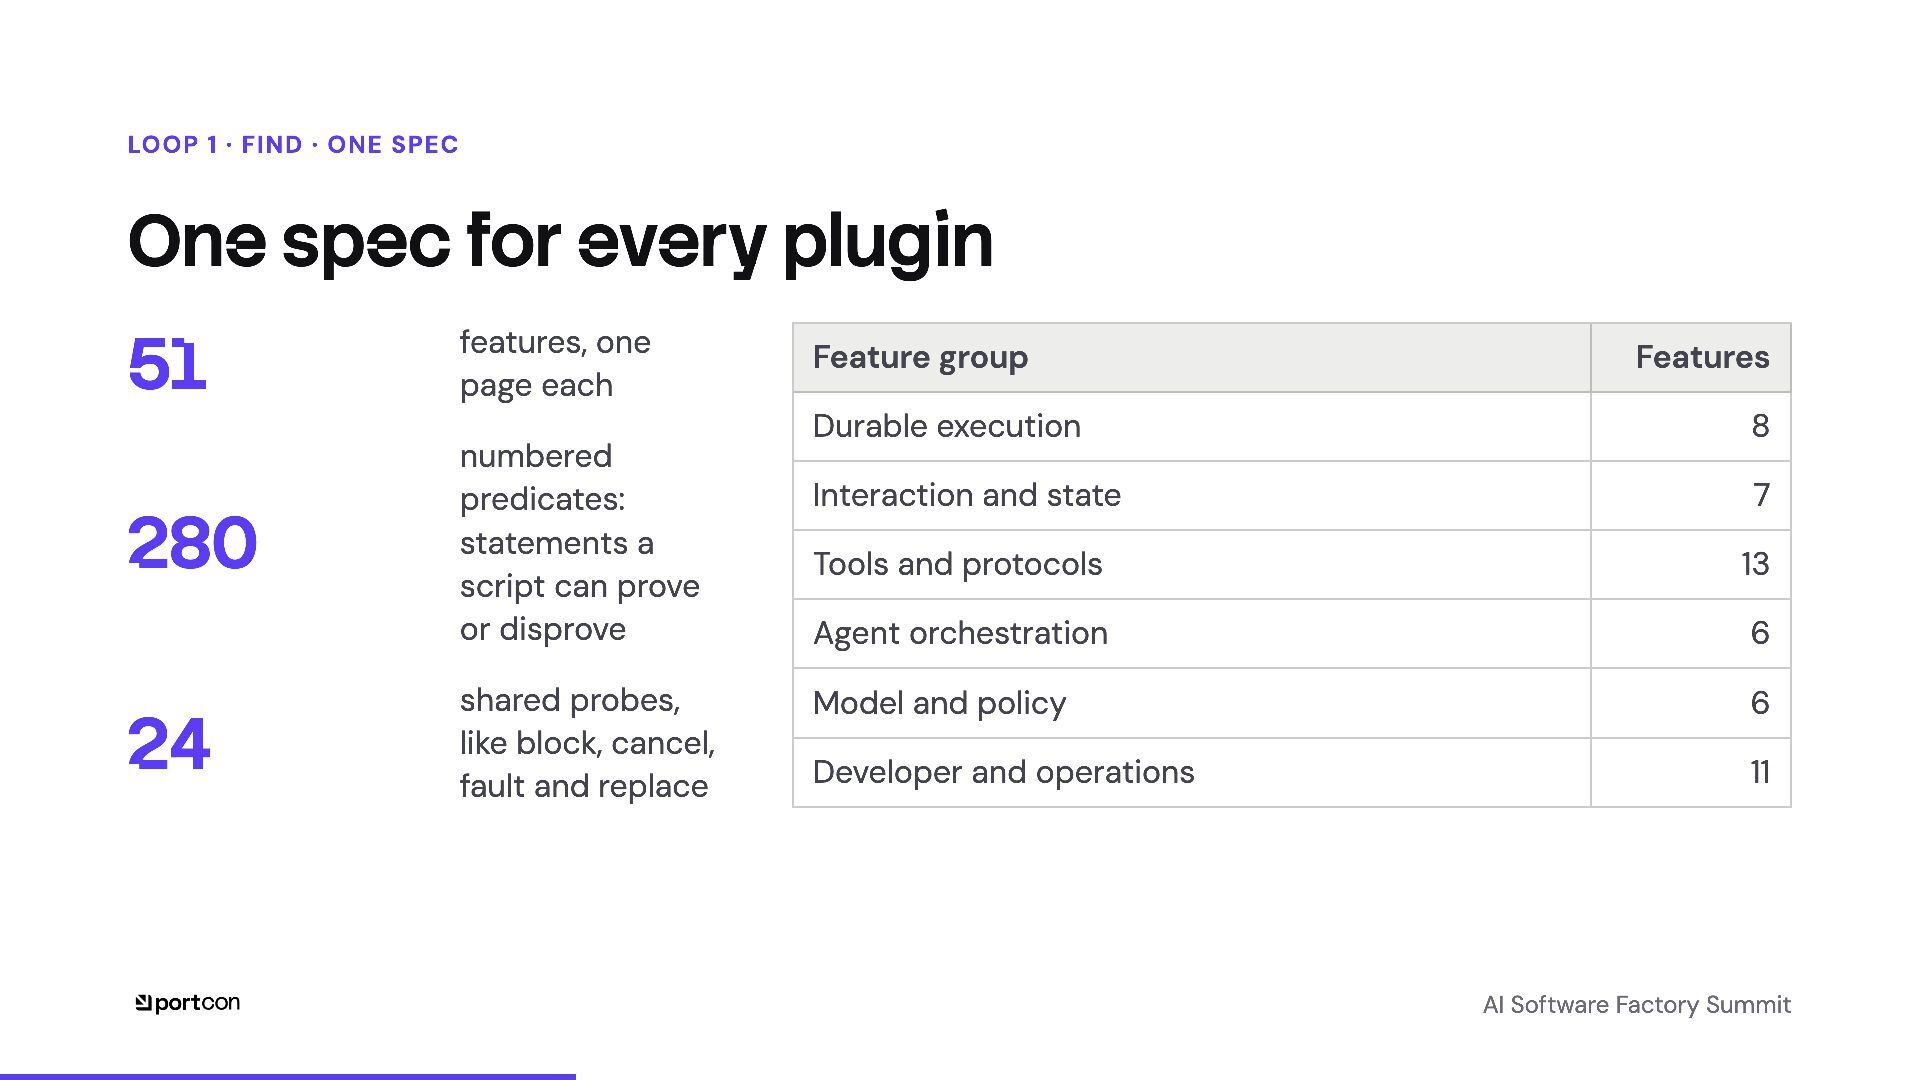
  10. LOOP 1 · FIND · ONE SPEC One spec for

    every plugin 51 280 24 features, one page each numbered predicates: statements a script can prove or disprove shared probes, like block, cancel, fault and replace Feature group Features Durable execution 8 Interaction and state 7 Tools and protocols 13 Agent orchestration 6 Model and policy 6 Developer and operations 11 AI Software Factory Summit
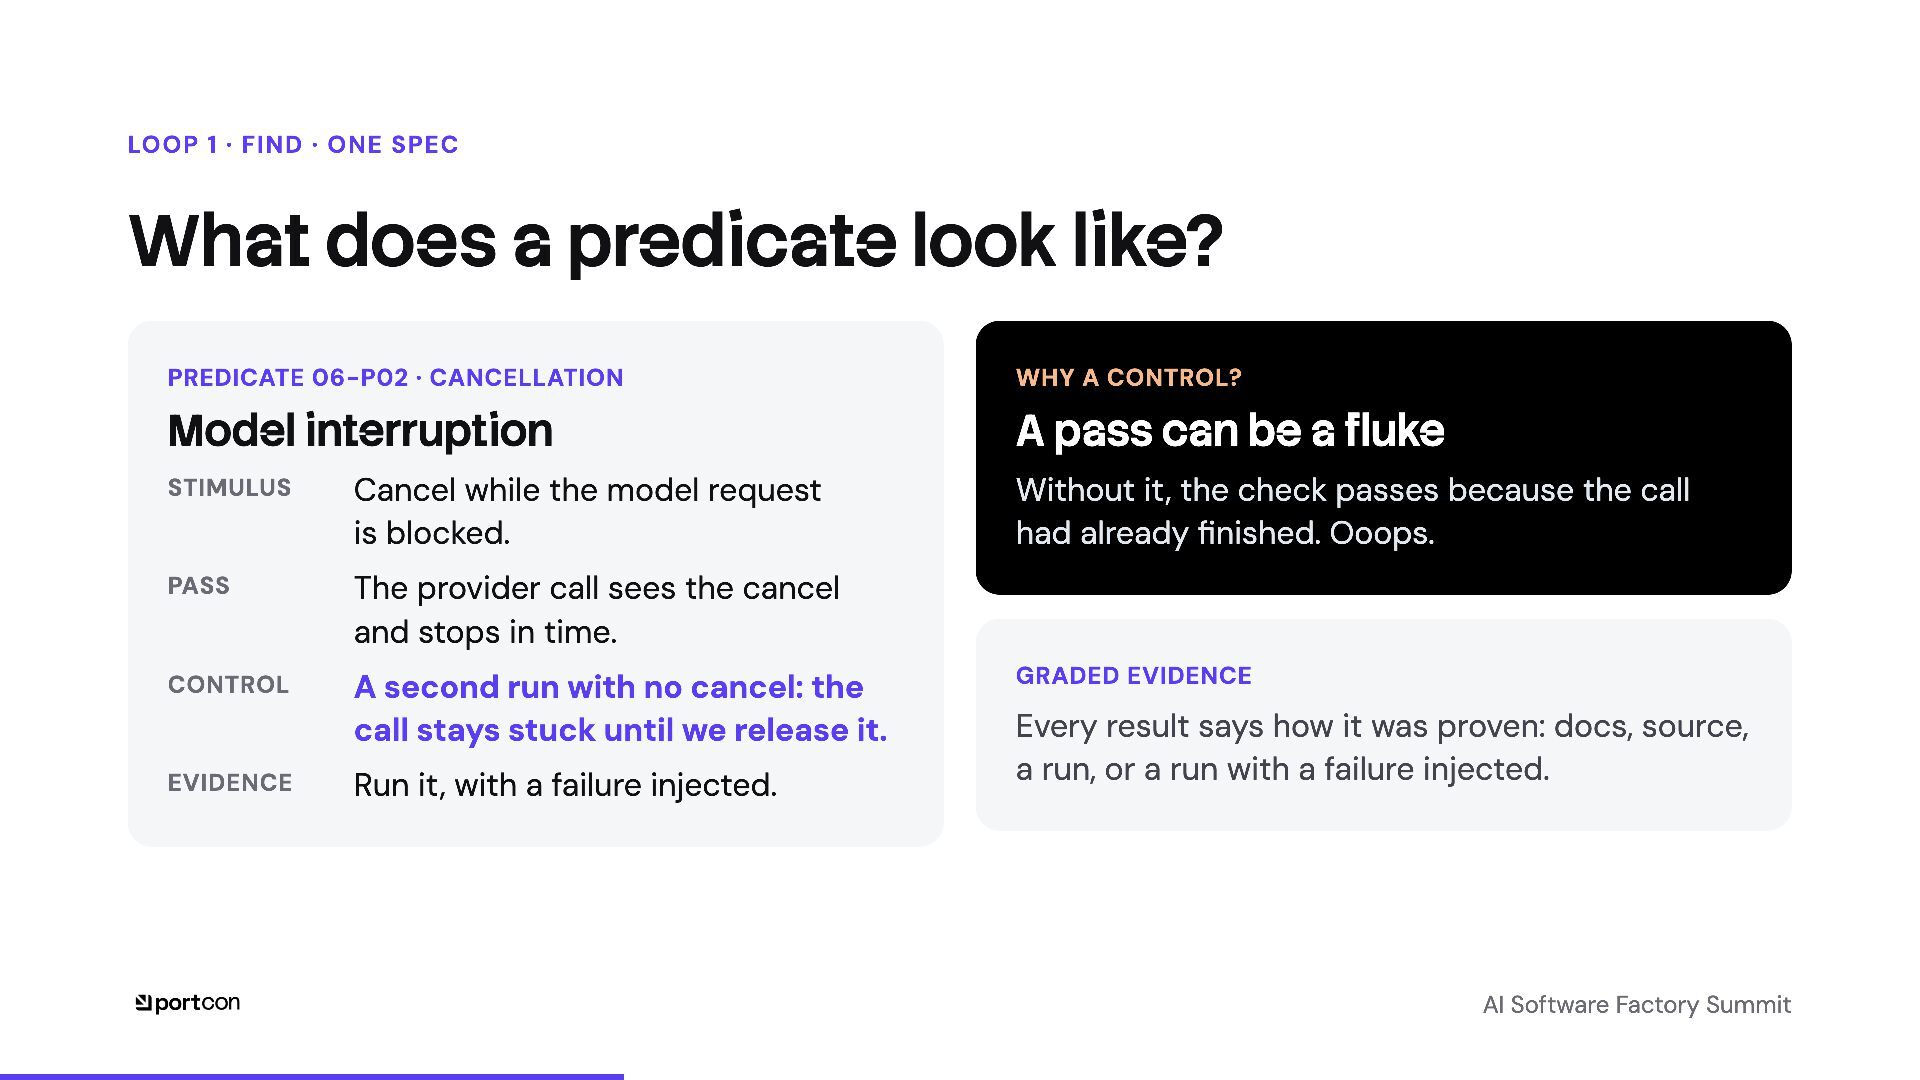
  11. LOOP 1 · FIND · ONE SPEC What does a

    predicate look like? PREDICATE 06-P02 · CANCELLATION WHY A CONTROL? Model interruption A pass can be a fluke STIMULUS Cancel while the model request is blocked. PASS The provider call sees the cancel and stops in time. CONTROL A second run with no cancel: the call stays stuck until we release it. EVIDENCE Run it, with a failure injected. Without it, the check passes because the call had already finished. Ooops. GRADED EVIDENCE Every result says how it was proven: docs, source, a run, or a run with a failure injected. AI Software Factory Summit
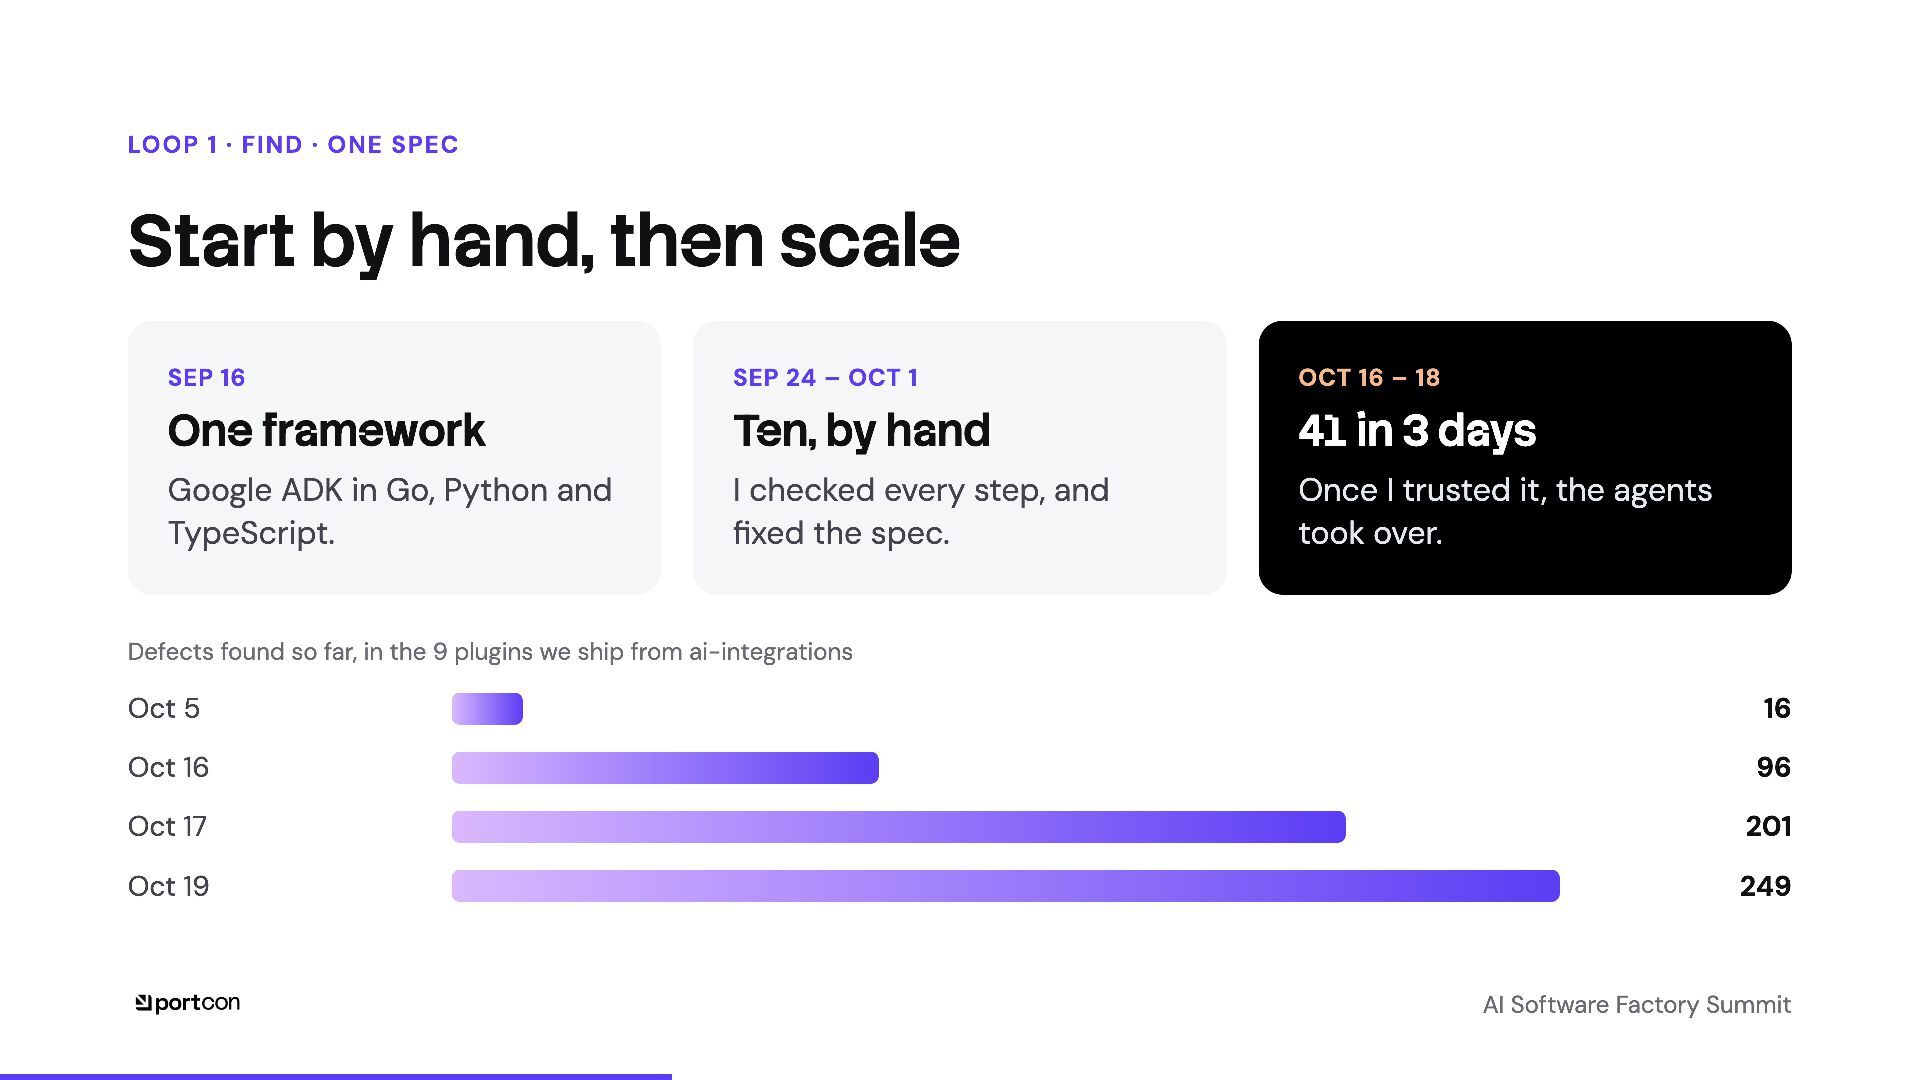
  12. LOOP 1 · FIND · ONE SPEC Start by hand,

    then scale SEP 16 SEP 24 – OCT 1 OCT 16 – 18 One framework Ten, by hand 41 in 3 days Google ADK in Go, Python and TypeScript. I checked every step, and fixed the spec. Once I trusted it, the agents took over. Defects found so far, in the 9 plugins we ship from ai-integrations Oct 5 16 Oct 16 96 Oct 17 201 Oct 19 249 AI Software Factory Summit
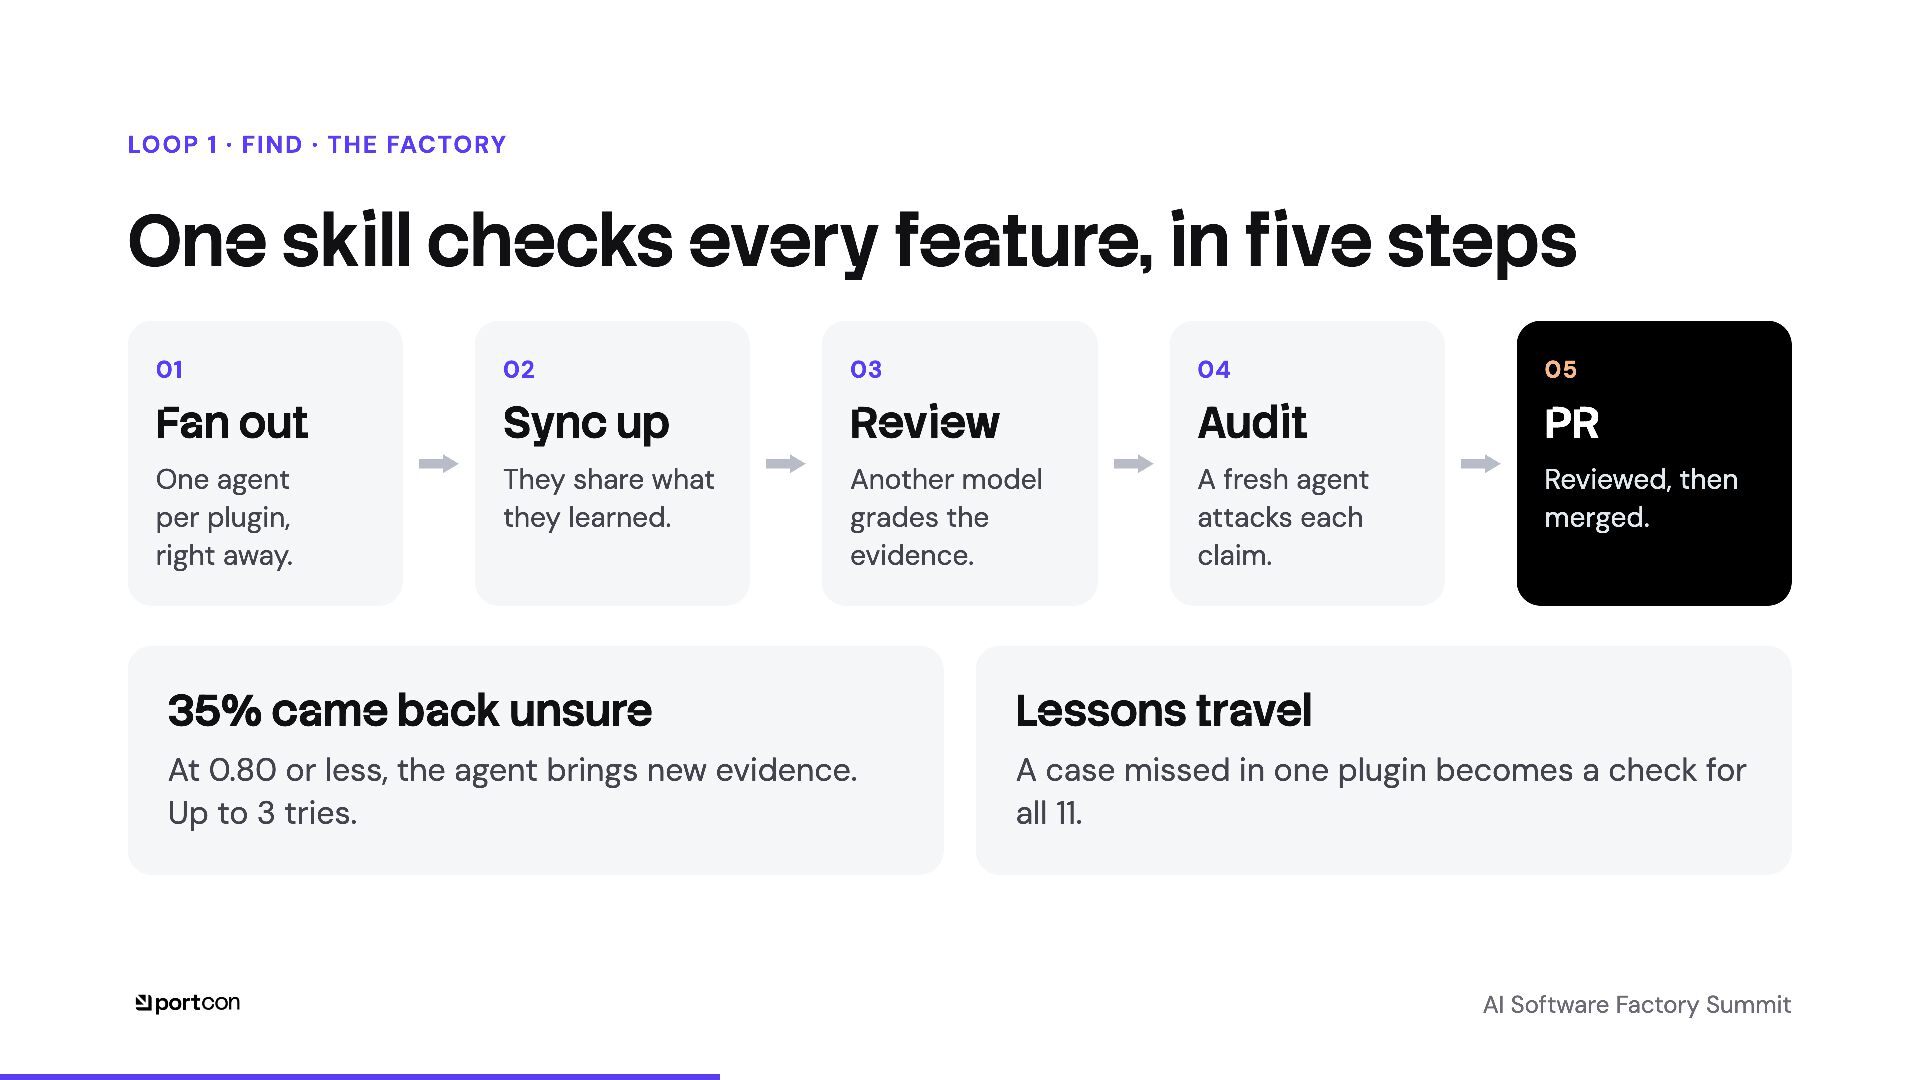
  13. LOOP 1 · FIND · THE FACTORY One skill checks

    every feature, in five steps 01 02 03 04 05 Fan out Sync up Review Audit PR One agent per plugin, right away. They share what they learned. Another model grades the evidence. A fresh agent attacks each claim. Reviewed, then merged. 35% came back unsure Lessons travel At 0.80 or less, the agent brings new evidence. Up to 3 tries. A case missed in one plugin becomes a check for all 11. AI Software Factory Summit
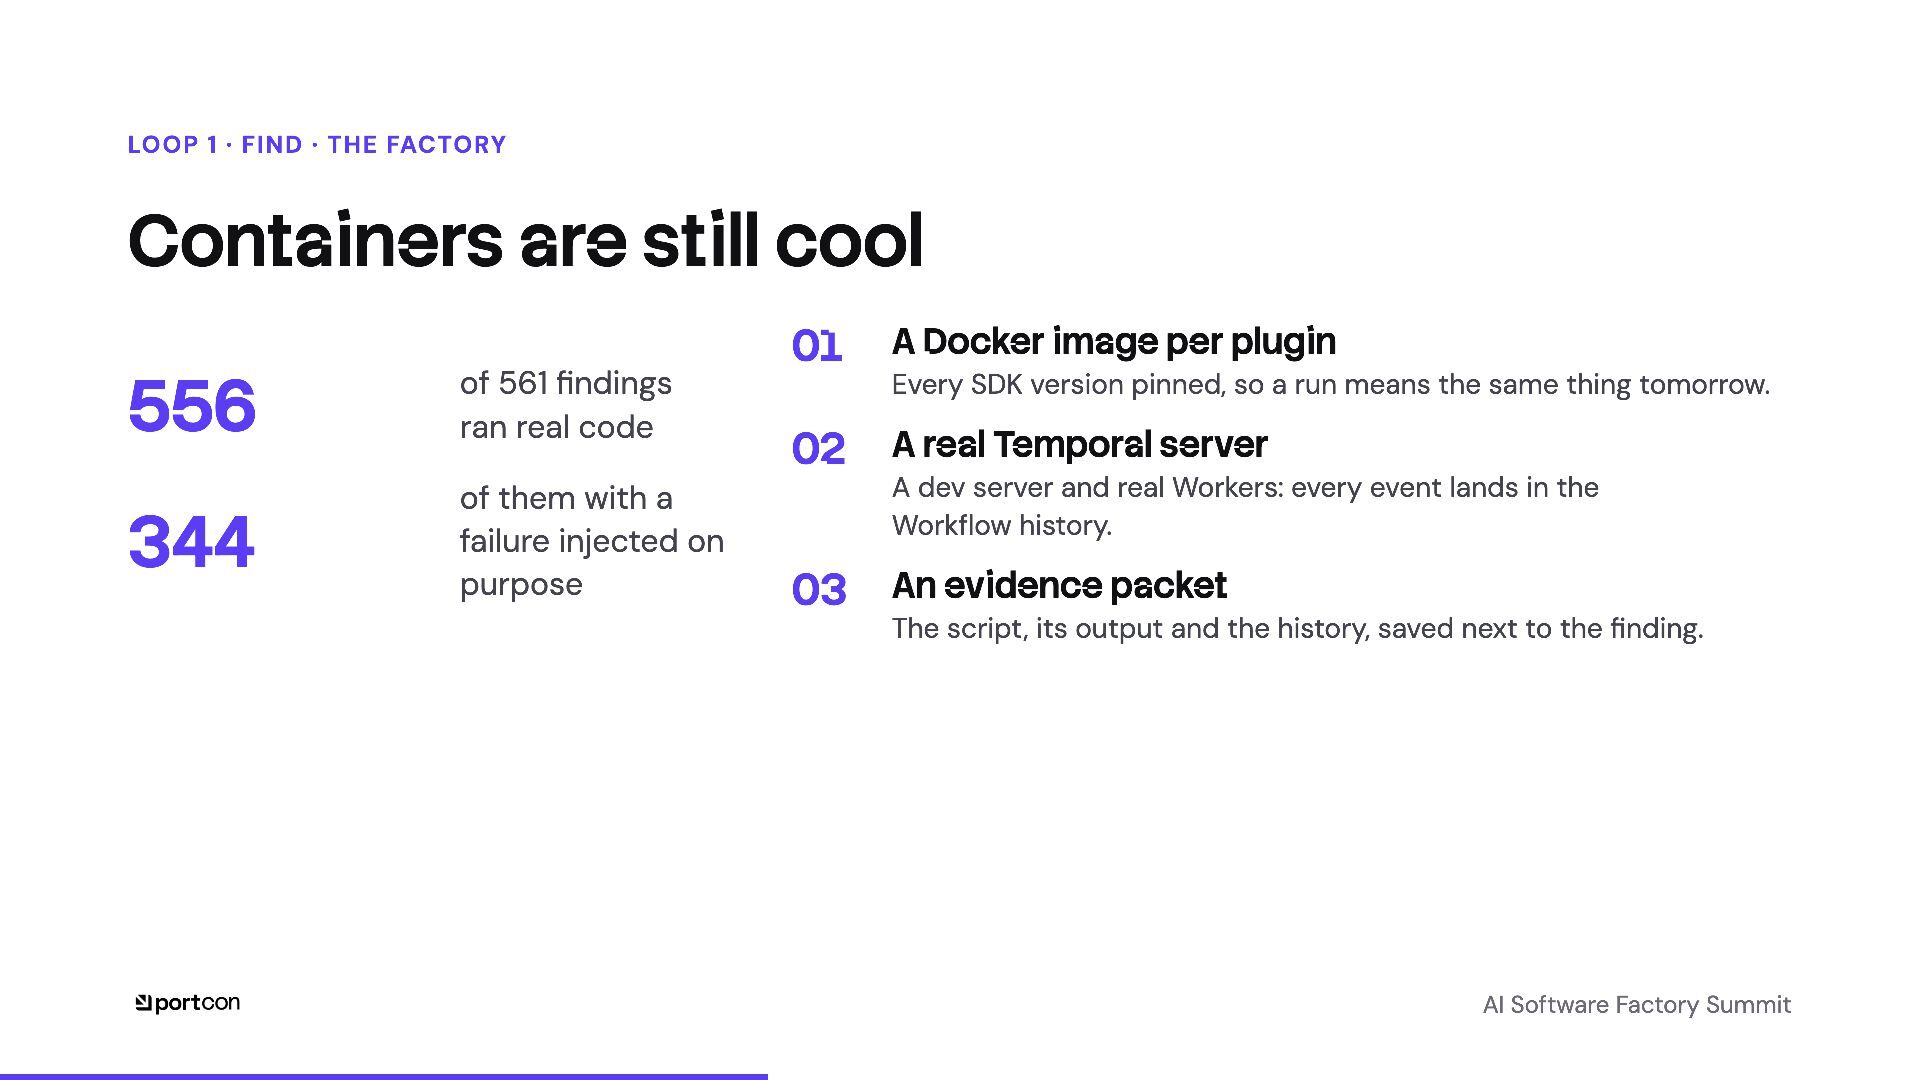
  14. LOOP 1 · FIND · THE FACTORY Containers are still

    cool 01 556 of 561 findings ran real code 344 of them with a failure injected on purpose A Docker image per plugin Every SDK version pinned, so a run means the same thing tomorrow. 02 A real Temporal server A dev server and real Workers: every event lands in the Workflow history. 03 An evidence packet The script, its output and the history, saved next to the finding. AI Software Factory Summit
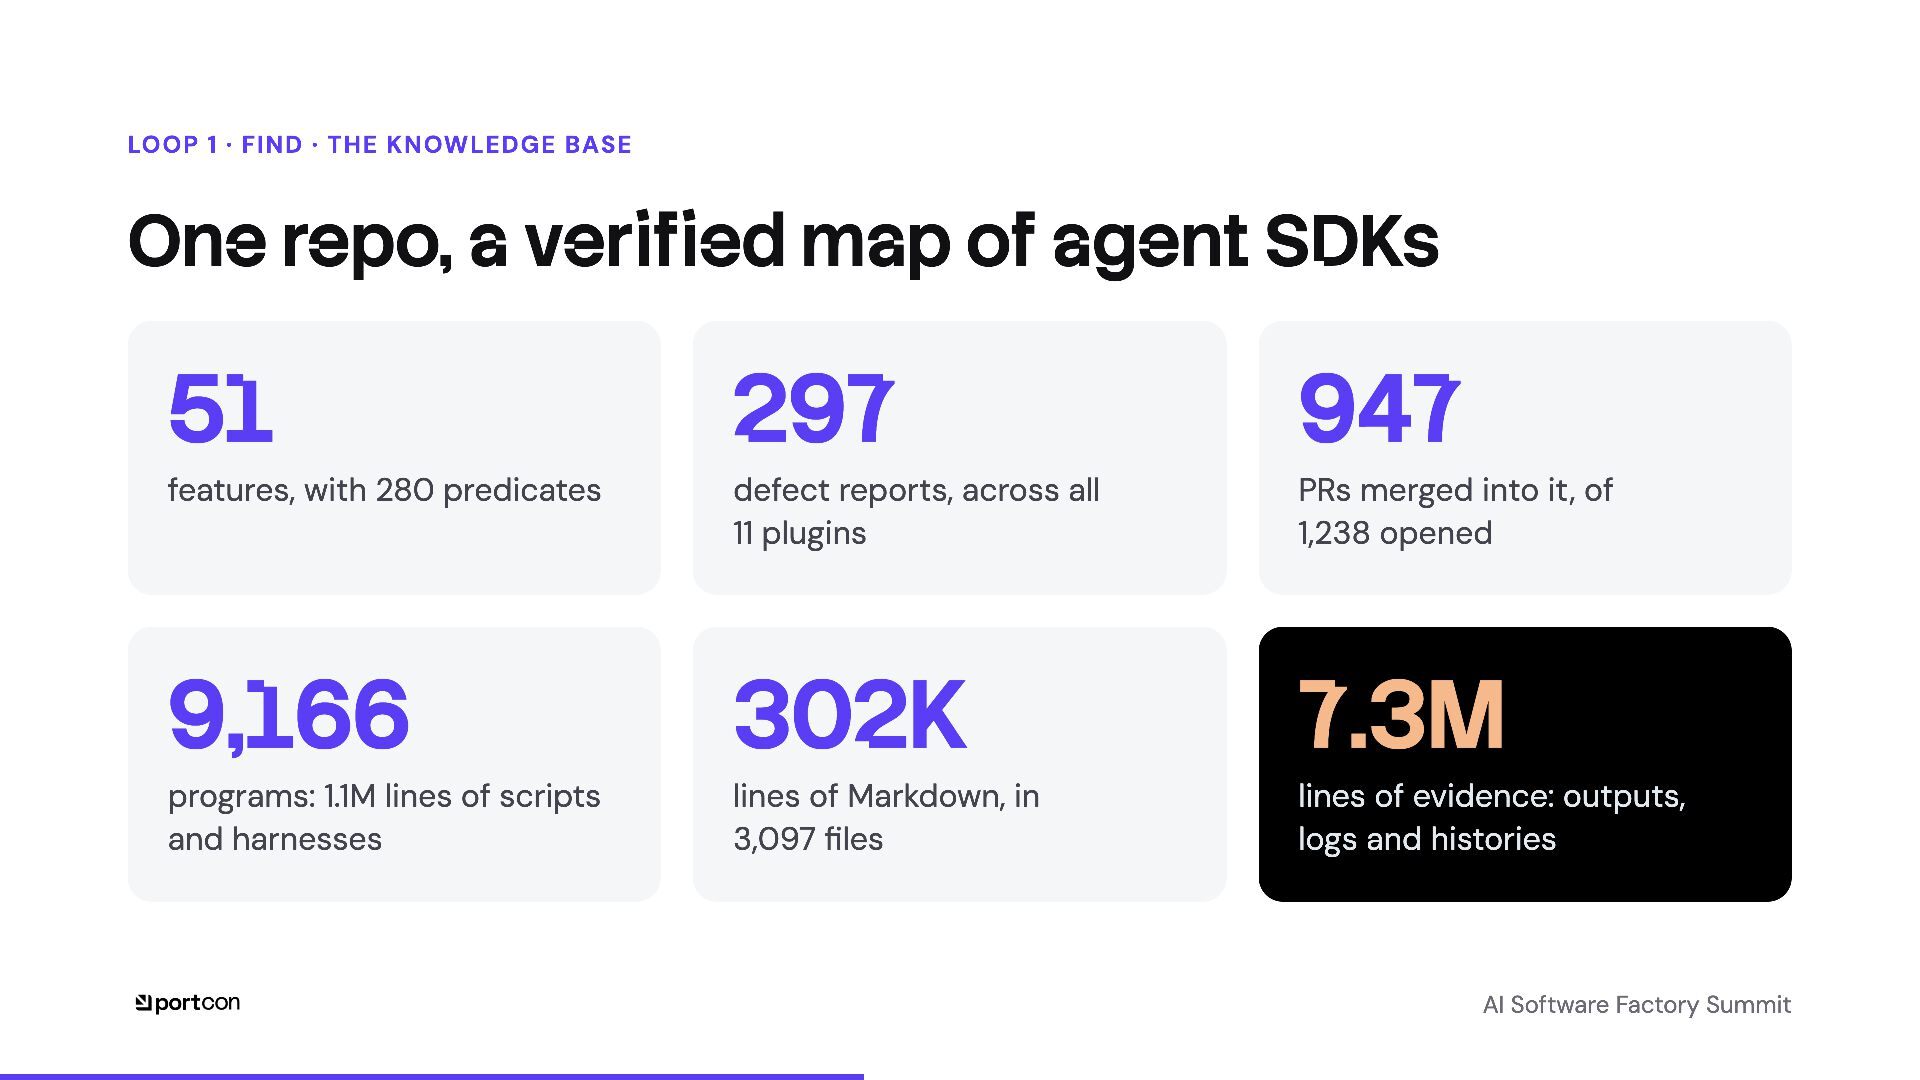
  15. LOOP 1 · FIND · THE KNOWLEDGE BASE One repo,

    a verified map of agent SDKs 51 297 947 features, with 280 predicates defect reports, across all 11 plugins PRs merged into it, of 1,238 opened 9,166 302K 7.3M programs: 1.1M lines of scripts and harnesses lines of Markdown, in 3,097 files lines of evidence: outputs, logs and histories AI Software Factory Summit
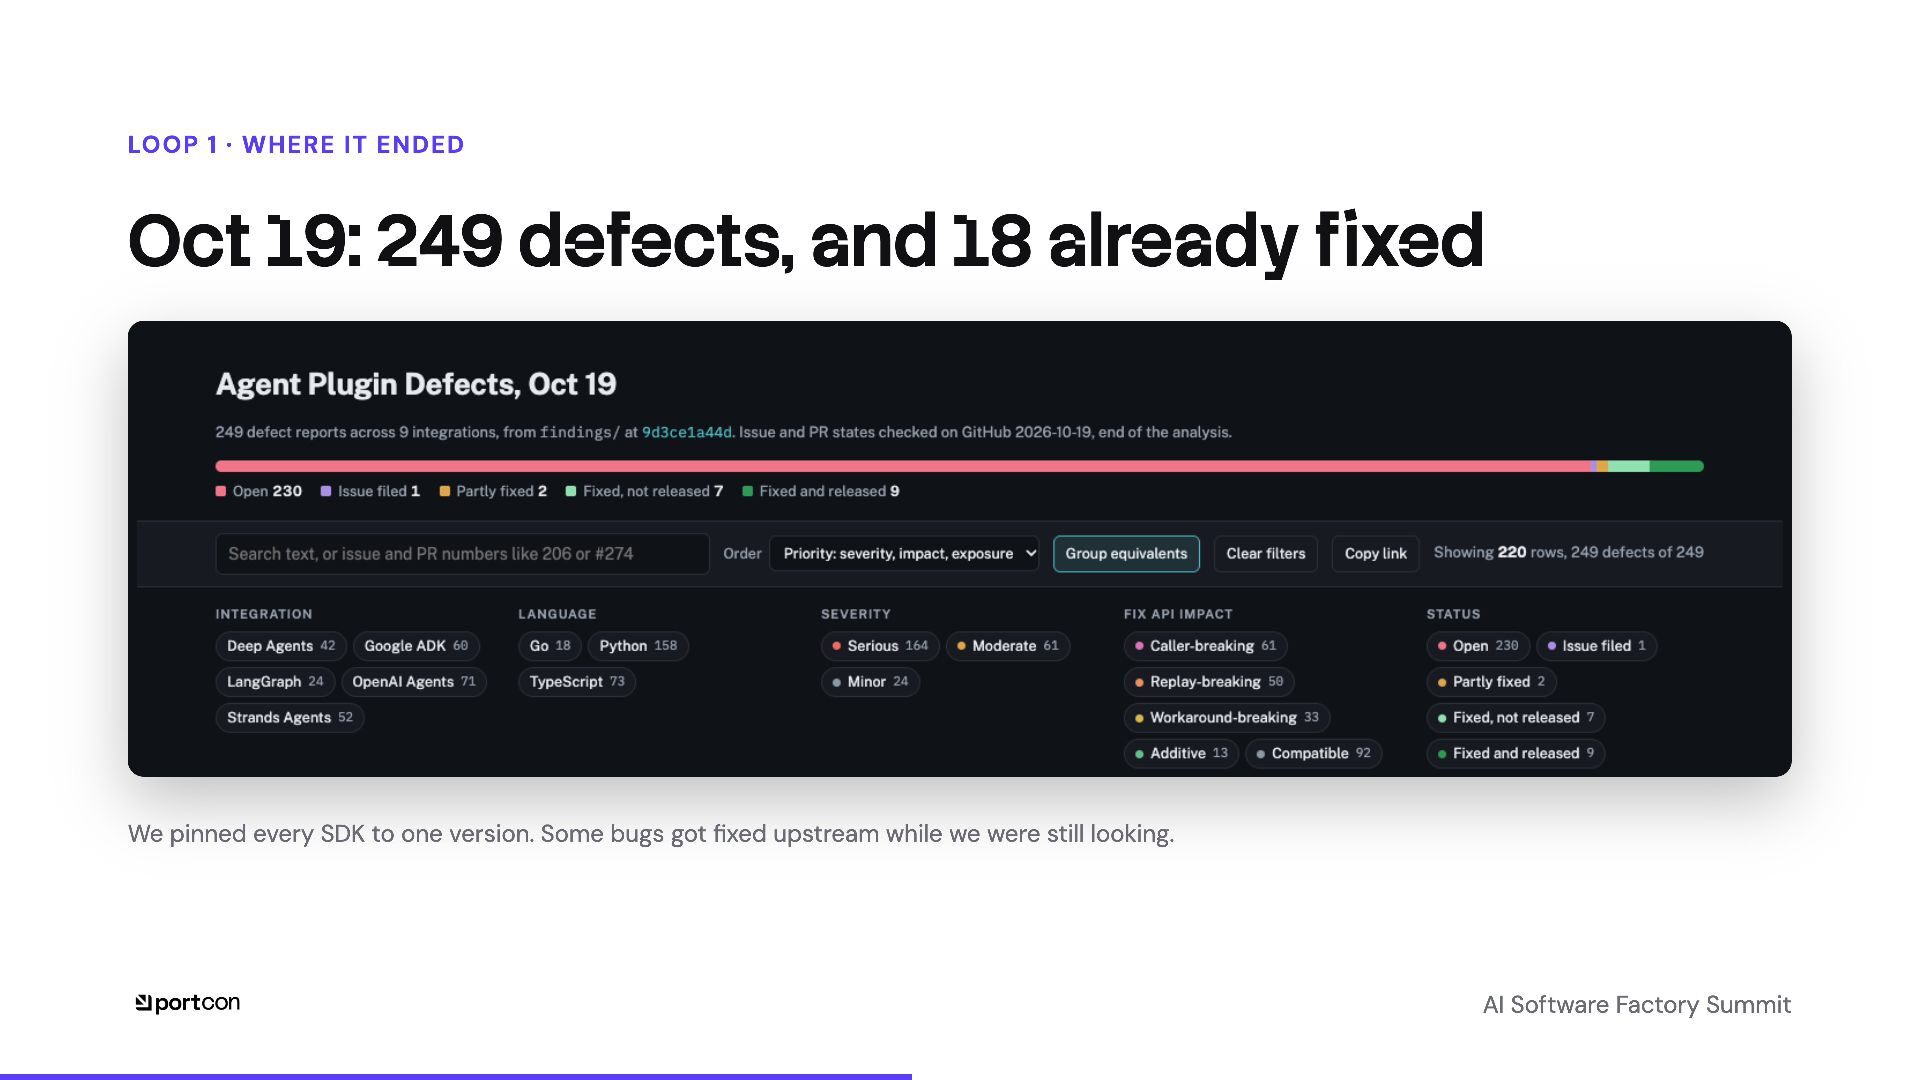
  16. LOOP 1 · WHERE IT ENDED Oct 19: 249 defects,

    and 18 already fixed We pinned every SDK to one version. Some bugs got fixed upstream while we were still looking. AI Software Factory Summit
  17. THE PLAN Loops Loops LOOP 1 · FIND LOOP 2

    · FIX LOOP 3 · LEARN · NEXT Find the defects Fix them Learn and repeat One spec, run against every plugin. Out come defect reports, each with a script that shows it. Each report becomes an issue and a fix PR. Agents review it first, then a human. Every review lesson goes back into the skills that find and fix. This is what we build next. Next: fix them. AI Software Factory Summit
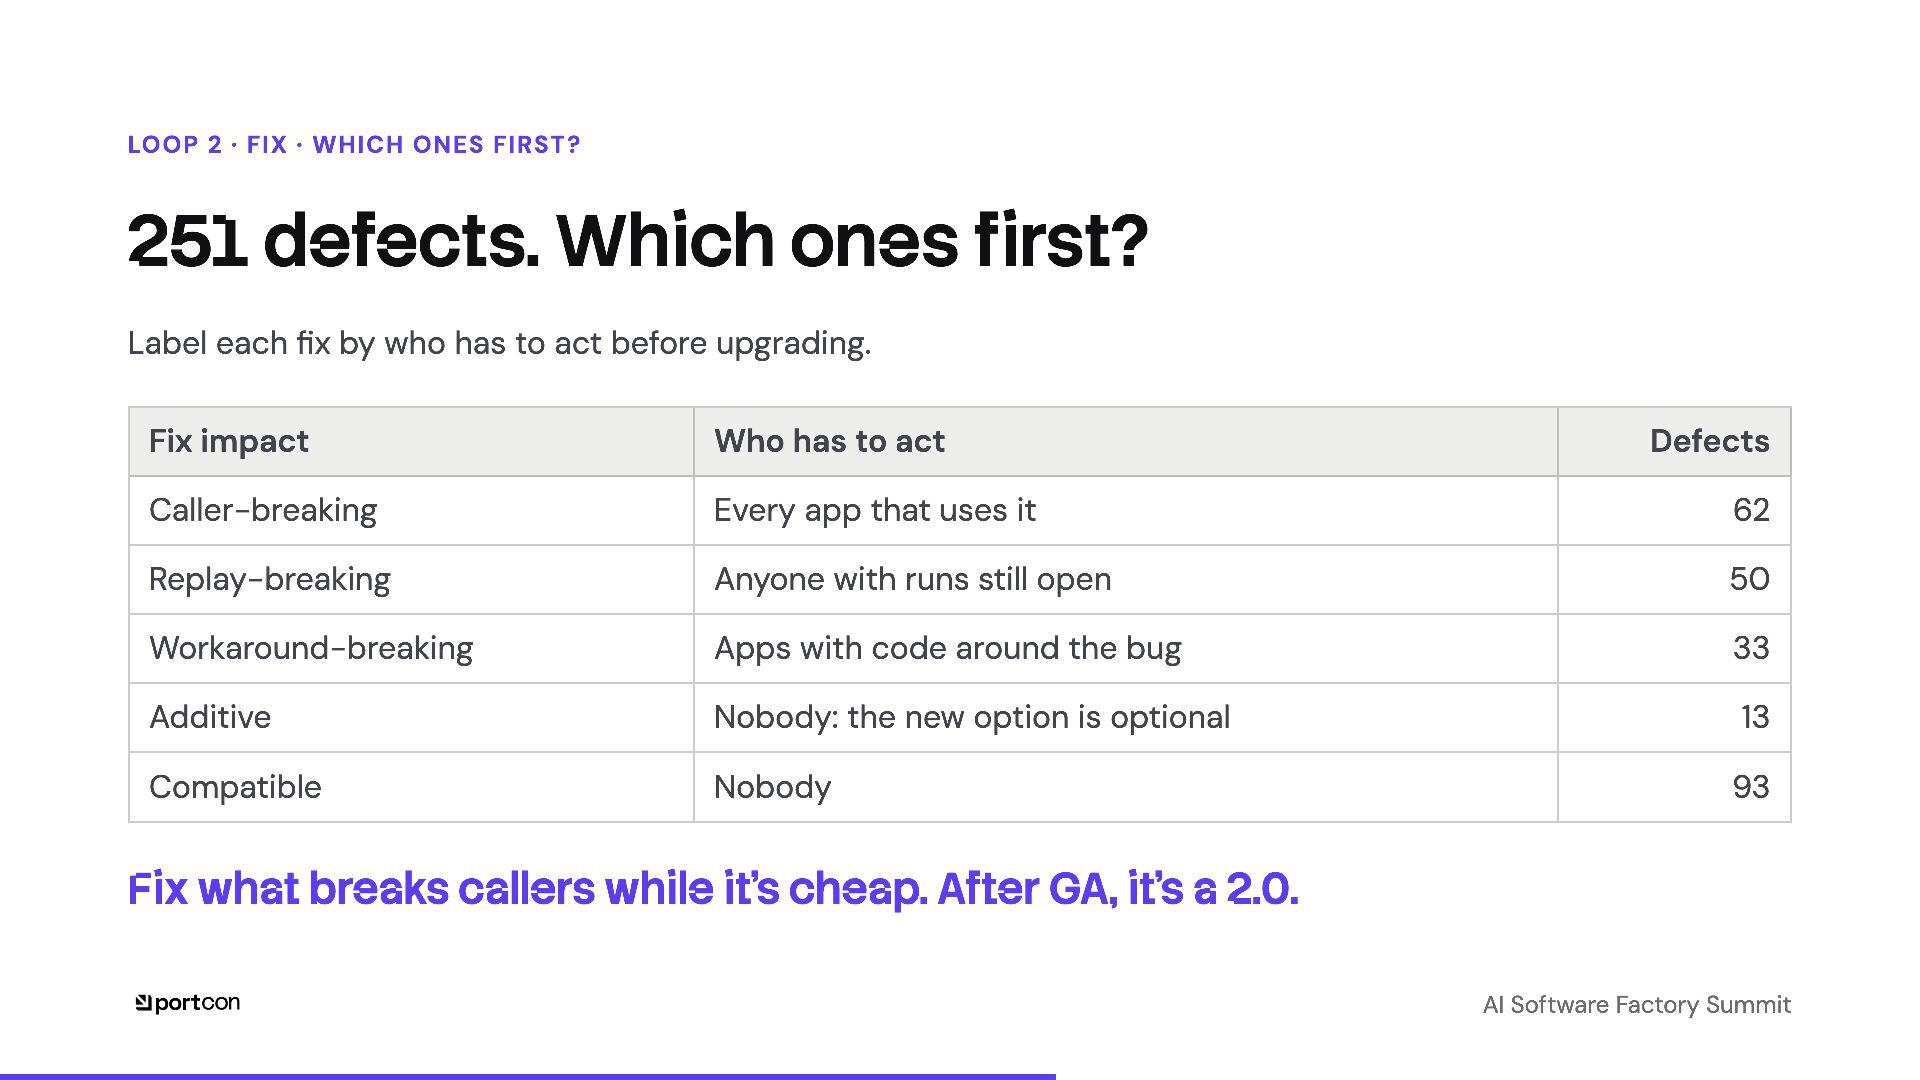
  18. LOOP 2 · FIX · WHICH ONES FIRST? 251 defects.

    Which ones first? Label each fix by who has to act before upgrading. Fix impact Who has to act Defects Caller-breaking Every app that uses it 62 Replay-breaking Anyone with runs still open 50 Workaround-breaking Apps with code around the bug 33 Additive Nobody: the new option is optional 13 Compatible Nobody 93 Fix what breaks callers while it’s cheap. After GA, it’s a 2.0. AI Software Factory Summit
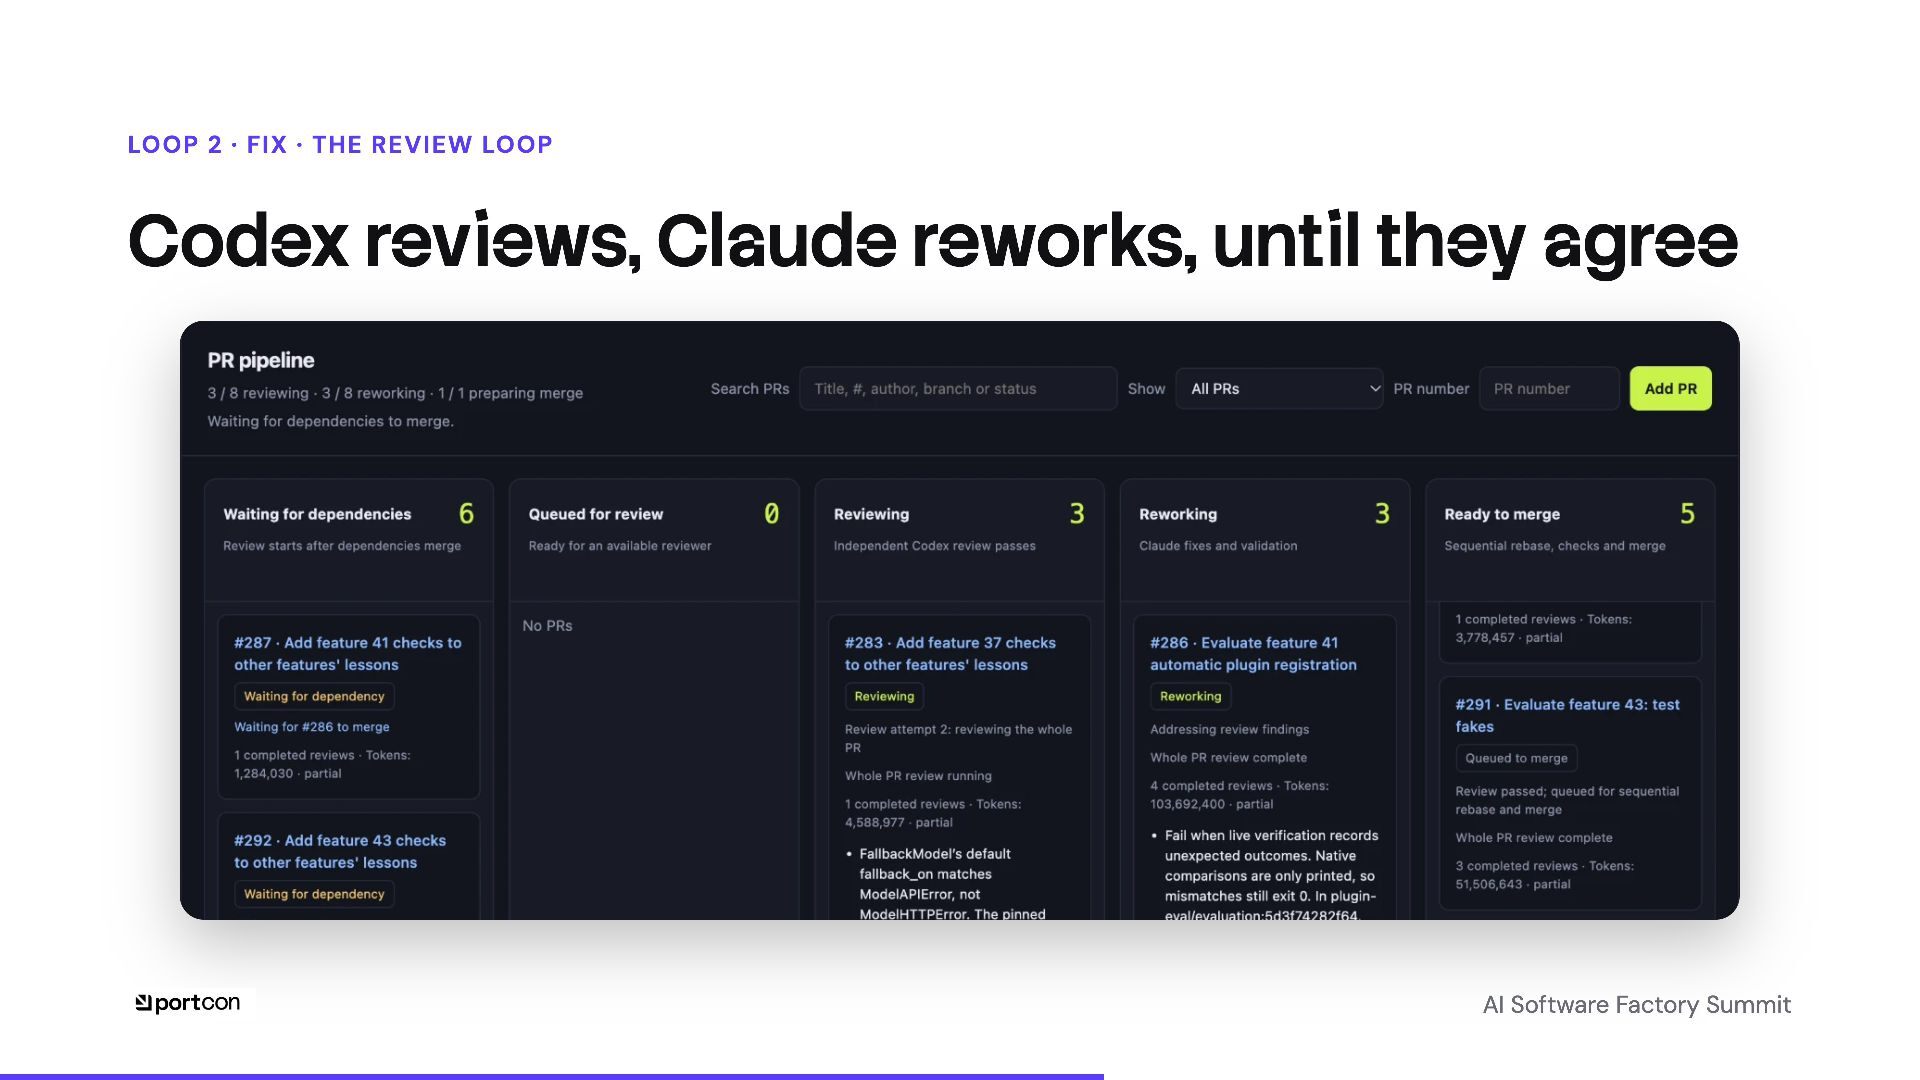
  19. LOOP 2 · FIX · THE REVIEW LOOP Codex reviews,

    Claude reworks, until they agree AI Software Factory Summit
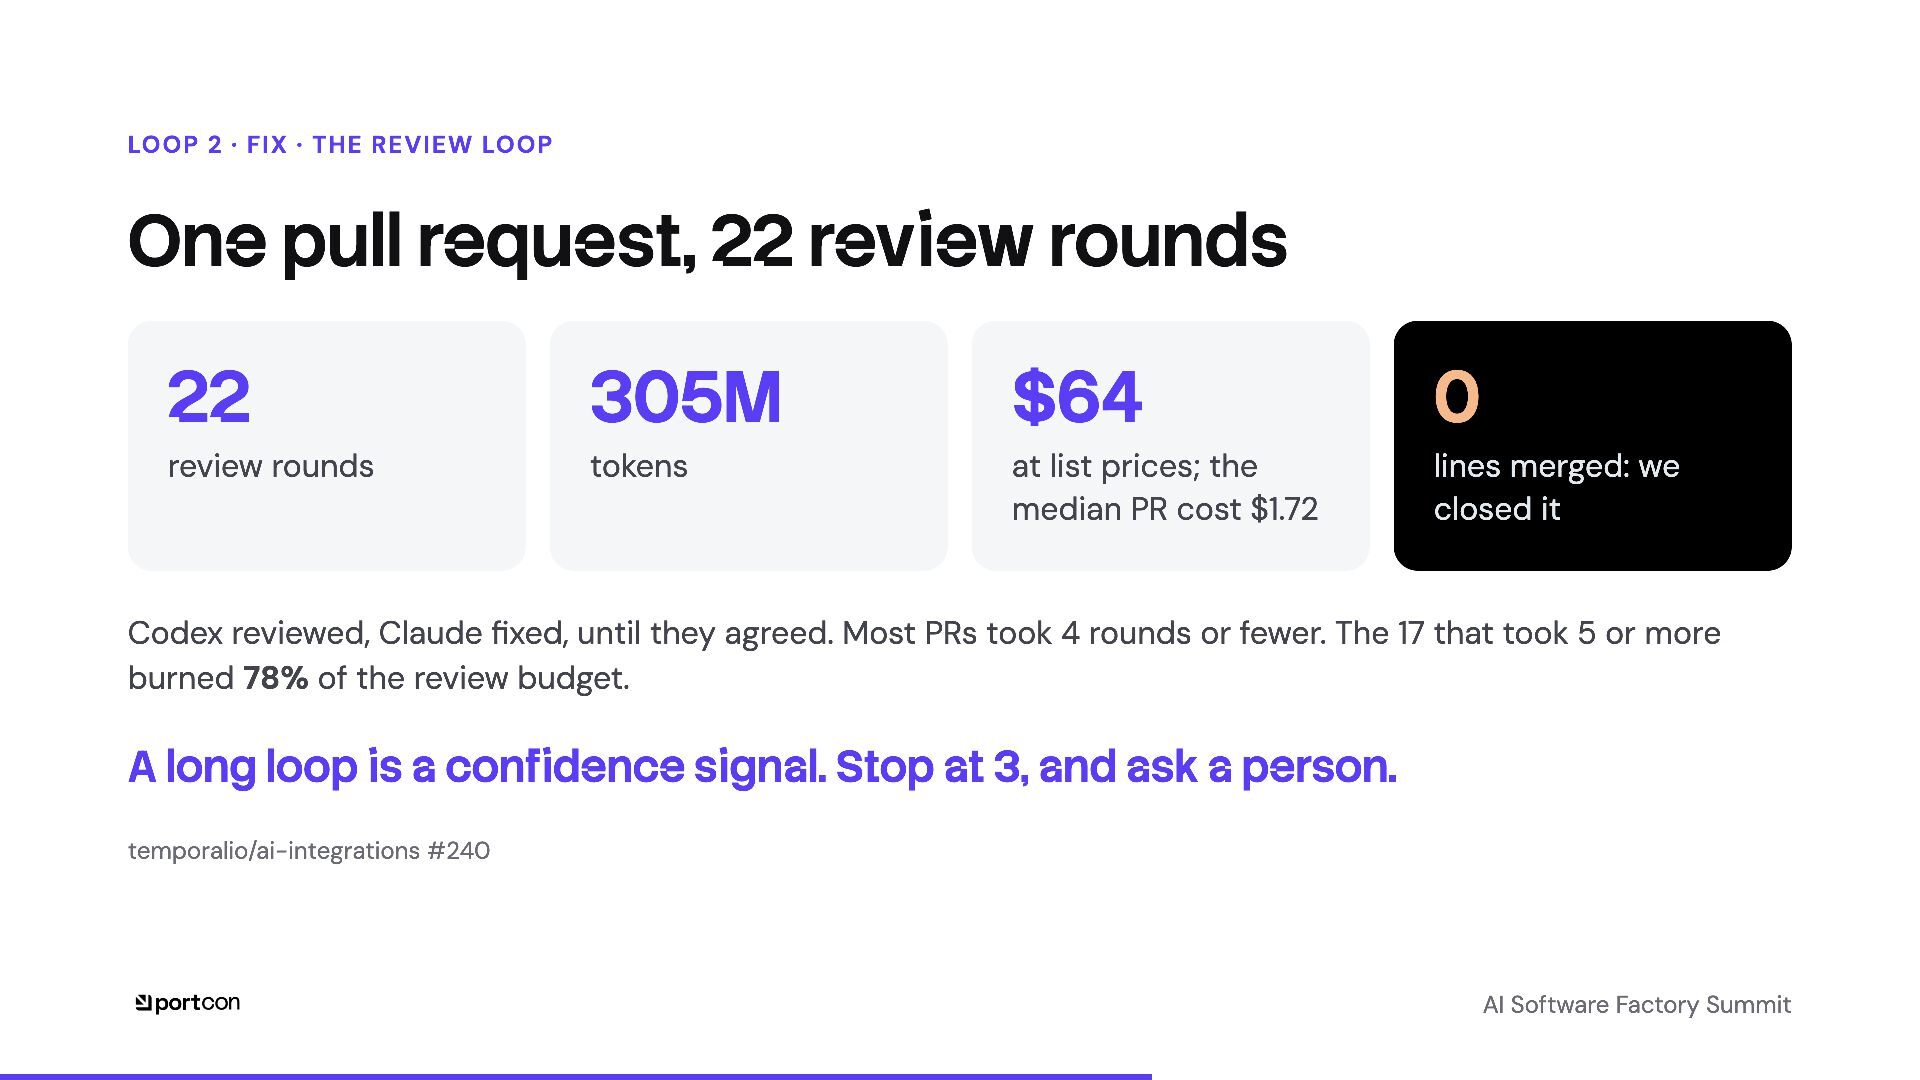
  20. LOOP 2 · FIX · THE REVIEW LOOP One pull

    request, 22 review rounds 22 305M $64 0 review rounds tokens at list prices; the median PR cost $1.72 lines merged: we closed it Codex reviewed, Claude fixed, until they agreed. Most PRs took 4 rounds or fewer. The 17 that took 5 or more burned 78% of the review budget. A long loop is a confidence signal. Stop at 3, and ask a person. temporalio/ai-integrations #240 AI Software Factory Summit
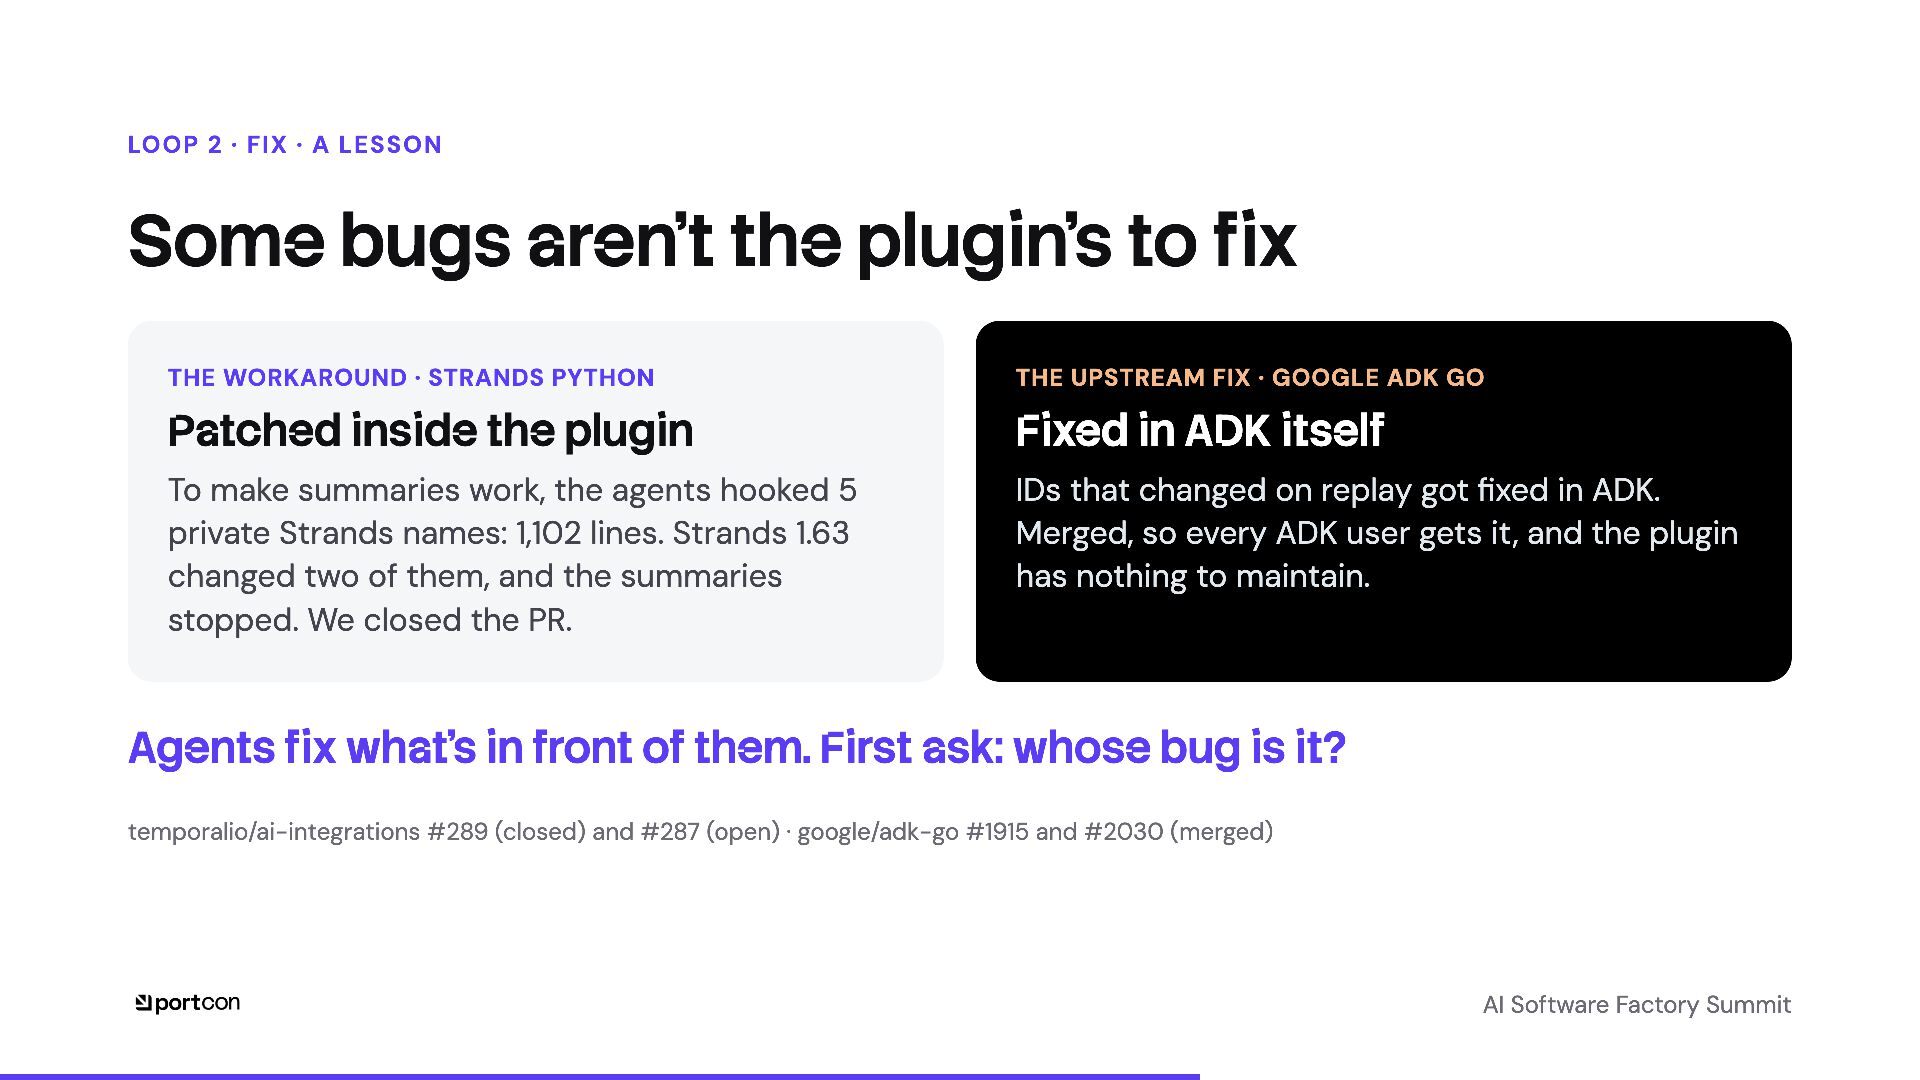
  21. LOOP 2 · FIX · A LESSON Some bugs aren’t

    the plugin’s to fix THE WORKAROUND · STRANDS PYTHON THE UPSTREAM FIX · GOOGLE ADK GO Patched inside the plugin Fixed in ADK itself To make summaries work, the agents hooked 5 private Strands names: 1,102 lines. Strands 1.63 changed two of them, and the summaries stopped. We closed the PR. IDs that changed on replay got fixed in ADK. Merged, so every ADK user gets it, and the plugin has nothing to maintain. Agents fix what’s in front of them. First ask: whose bug is it? temporalio/ai-integrations #289 (closed) and #287 (open) · google/adk-go #1915 and #2030 (merged) AI Software Factory Summit
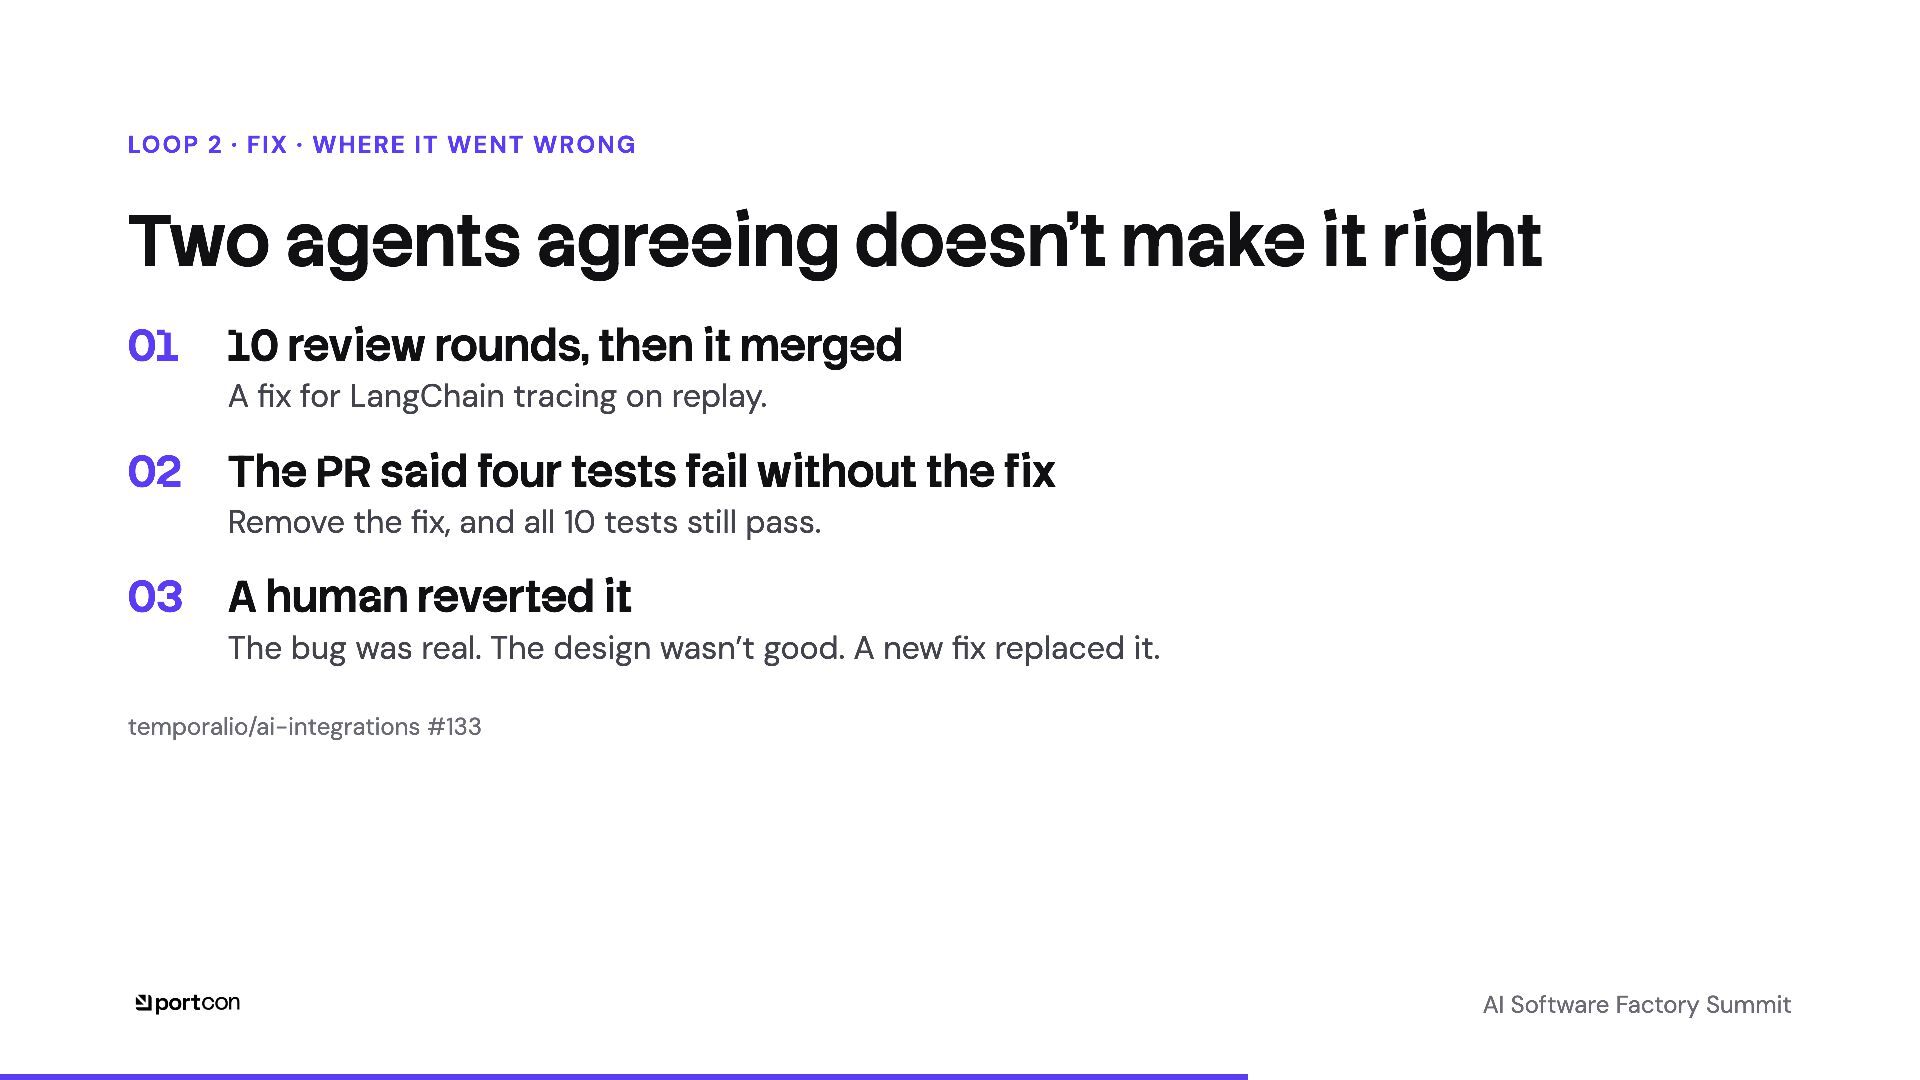
  22. LOOP 2 · FIX · WHERE IT WENT WRONG Two

    agents agreeing doesn’t make it right 01 10 review rounds, then it merged A fix for LangChain tracing on replay. 02 The PR said four tests fail without the fix Remove the fix, and all 10 tests still pass. 03 A human reverted it The bug was real. The design wasn’t good. A new fix replaced it. temporalio/ai-integrations #133 AI Software Factory Summit
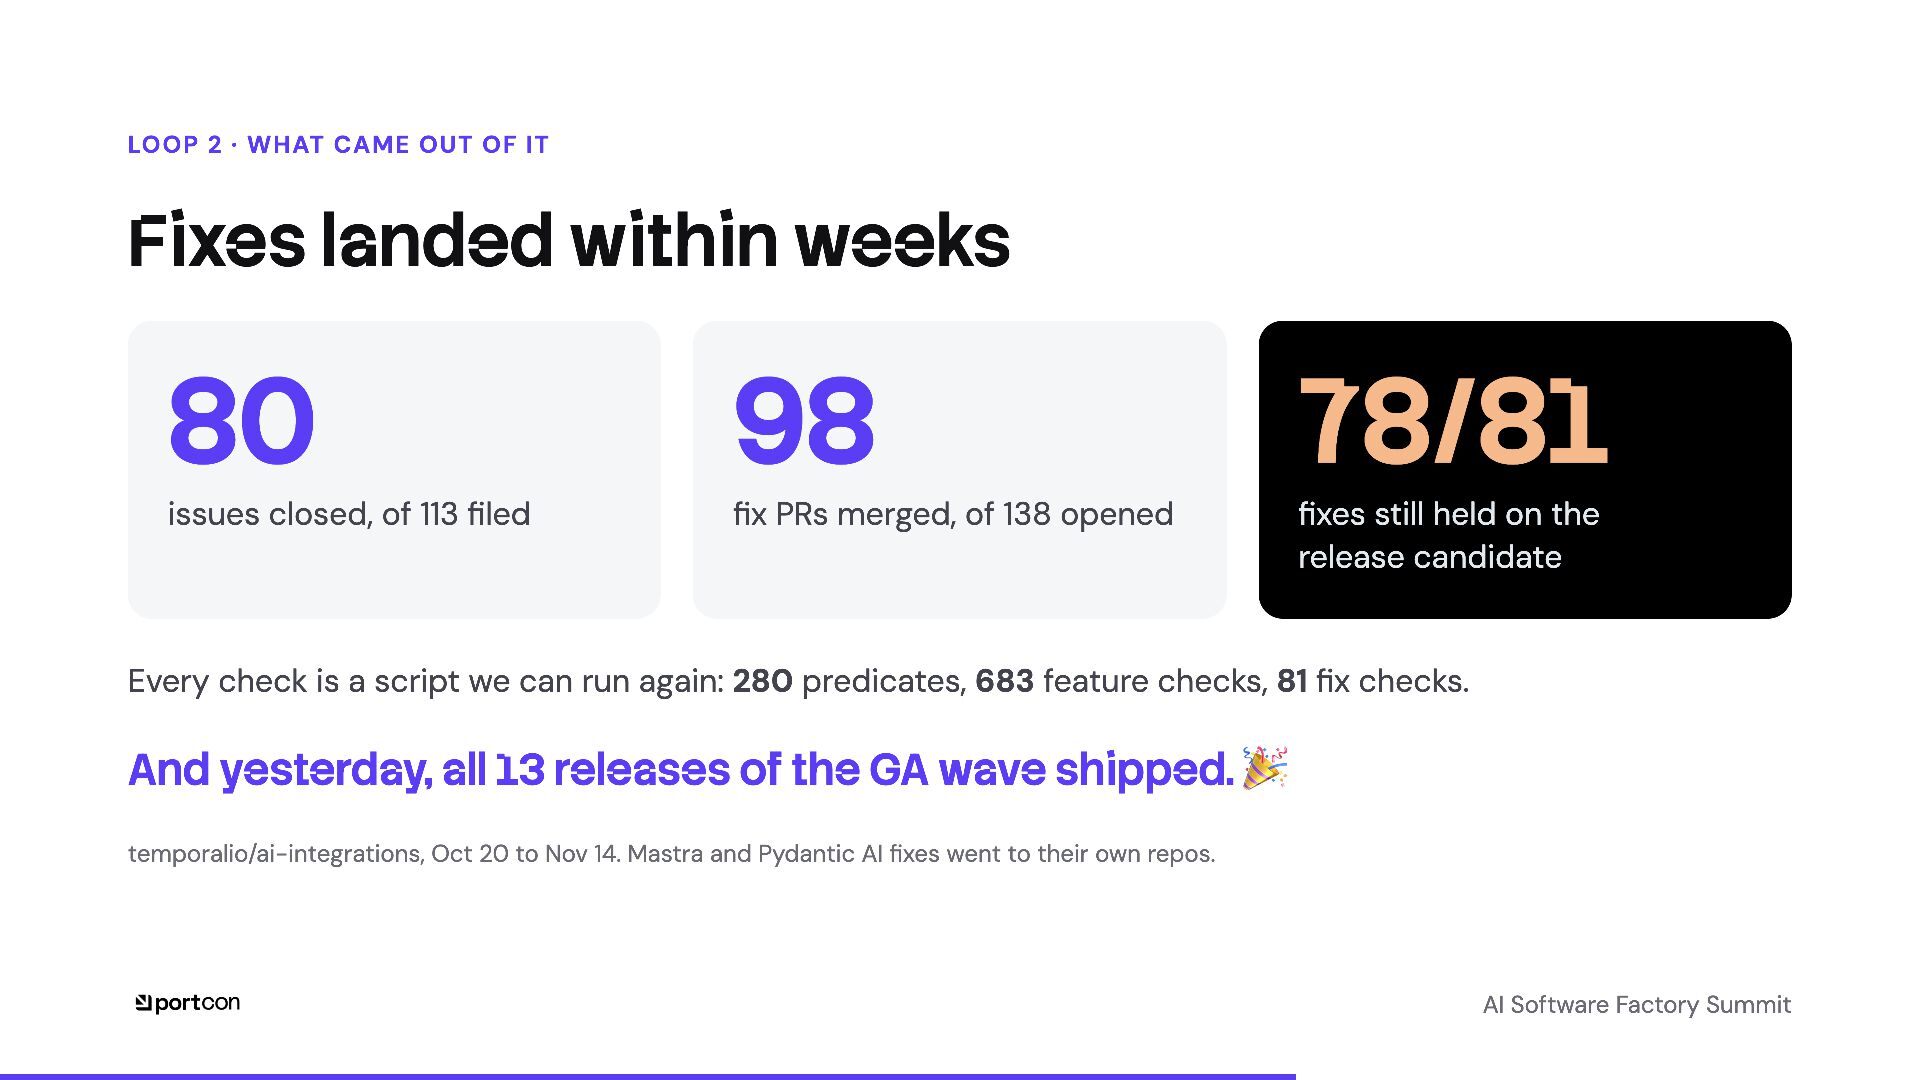
  23. LOOP 2 · WHAT CAME OUT OF IT Fixes landed

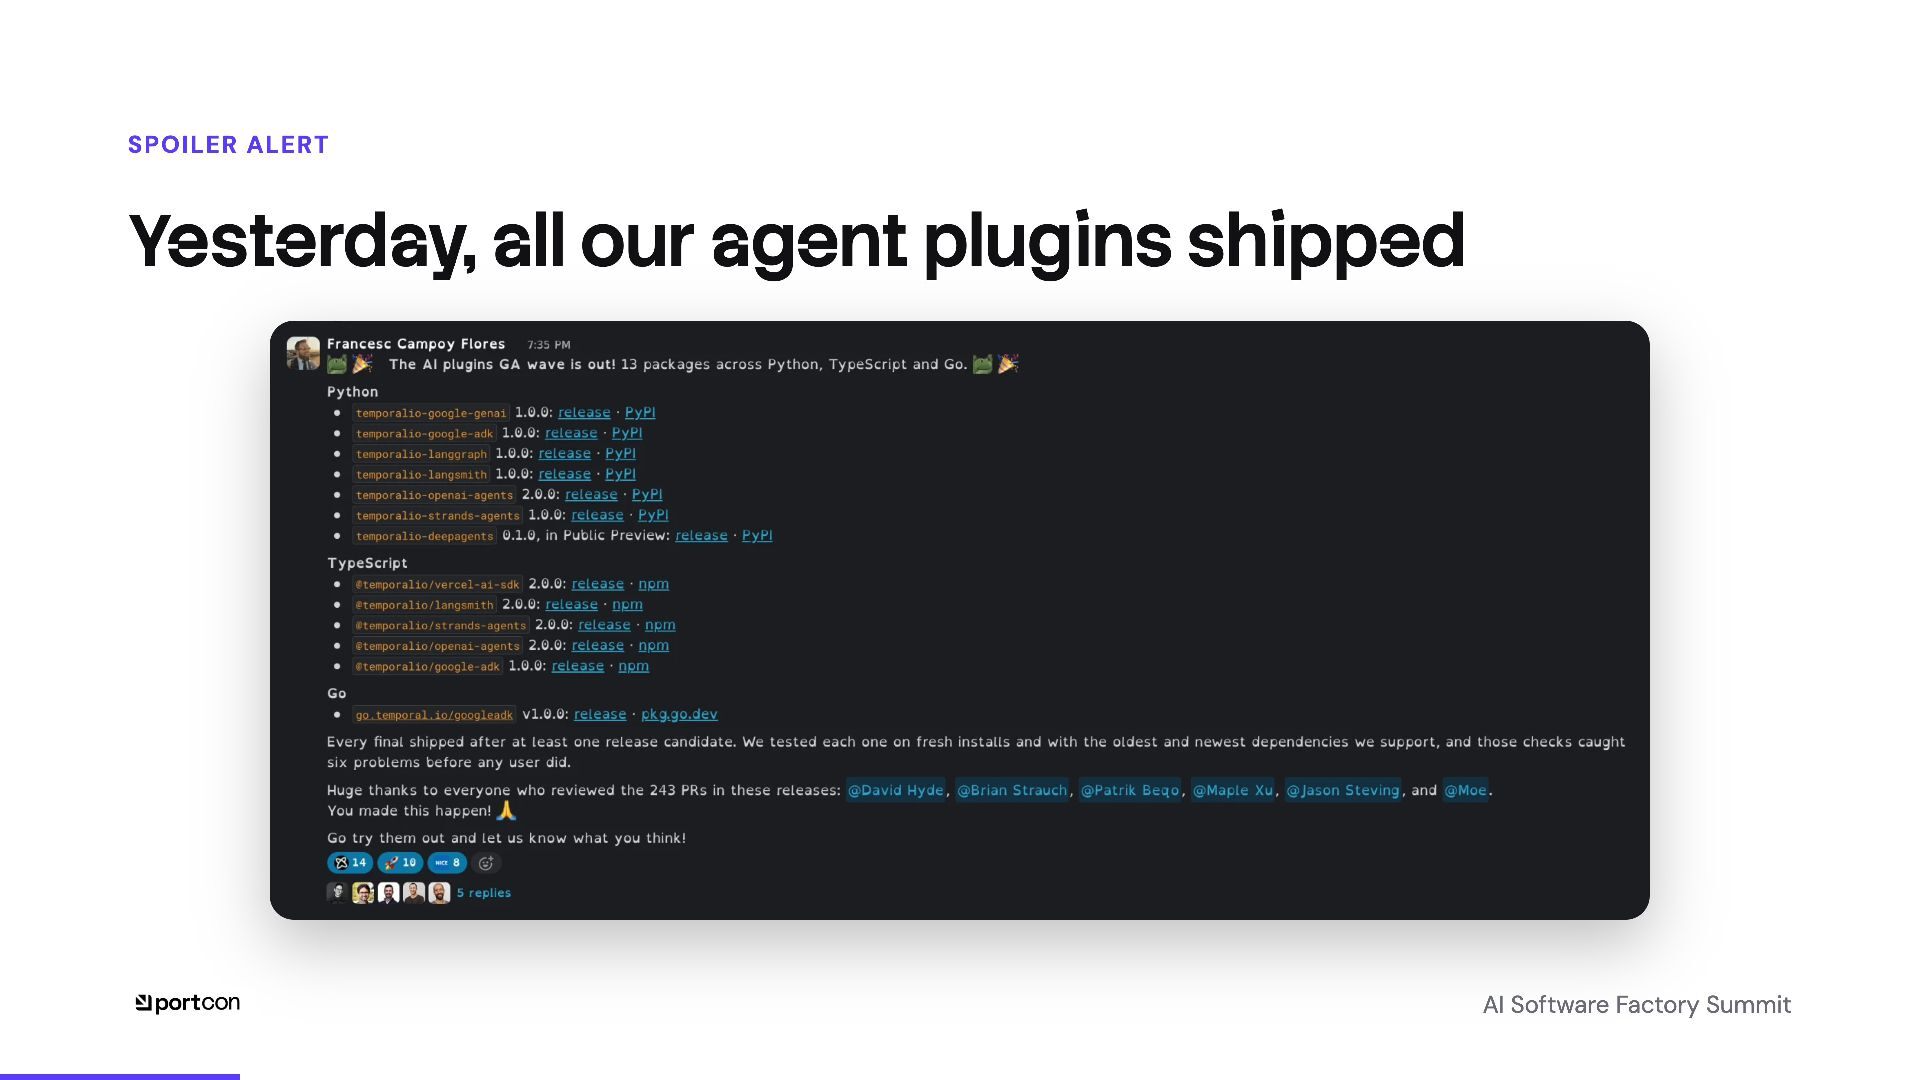
    within weeks 80 98 78/81 issues closed, of 113 filed fix PRs merged, of 138 opened fixes still held on the release candidate Every check is a script we can run again: 280 predicates, 683 feature checks, 81 fix checks. And yesterday, all 13 releases of the GA wave shipped. 🎉 temporalio/ai-integrations, Oct 20 to Nov 14. Mastra and Pydantic AI fixes went to their own repos. AI Software Factory Summit
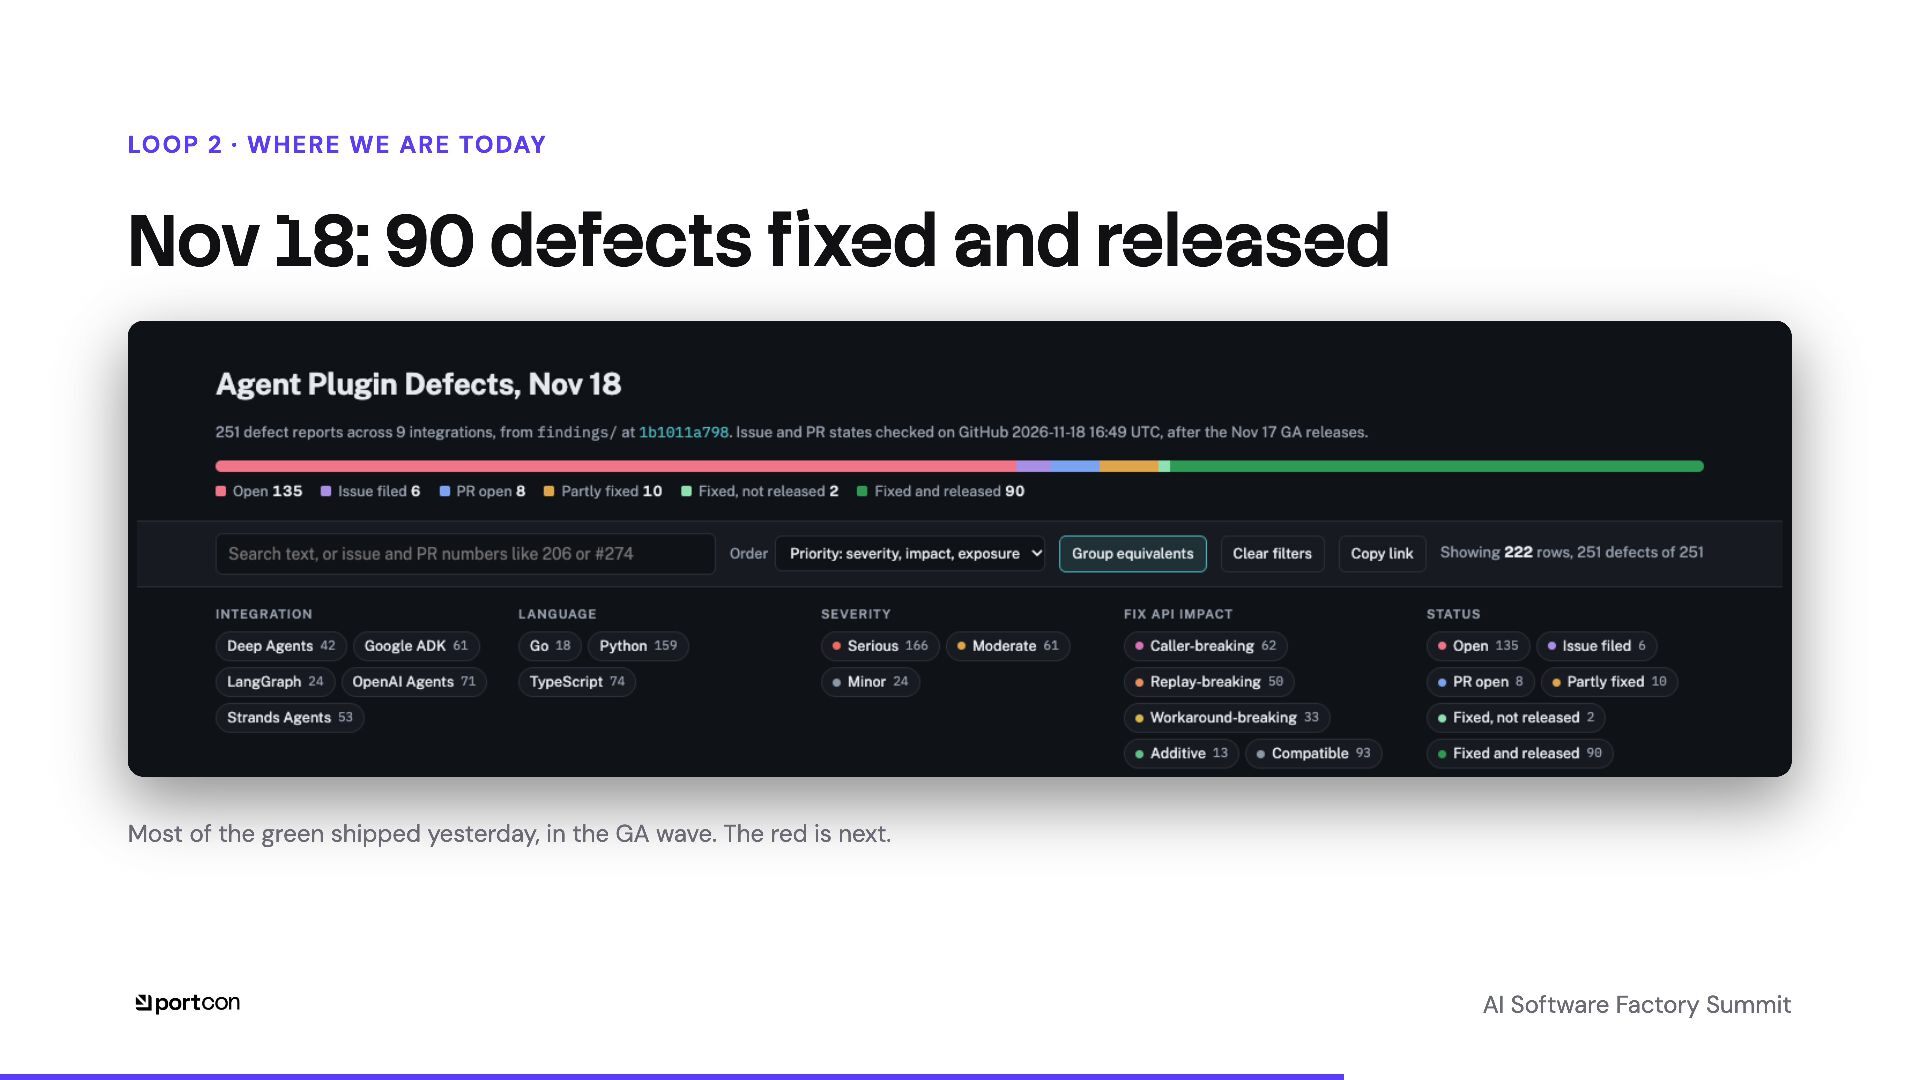
  24. LOOP 2 · WHERE WE ARE TODAY Nov 18: 90

    defects fixed and released Most of the green shipped yesterday, in the GA wave. The red is next. AI Software Factory Summit
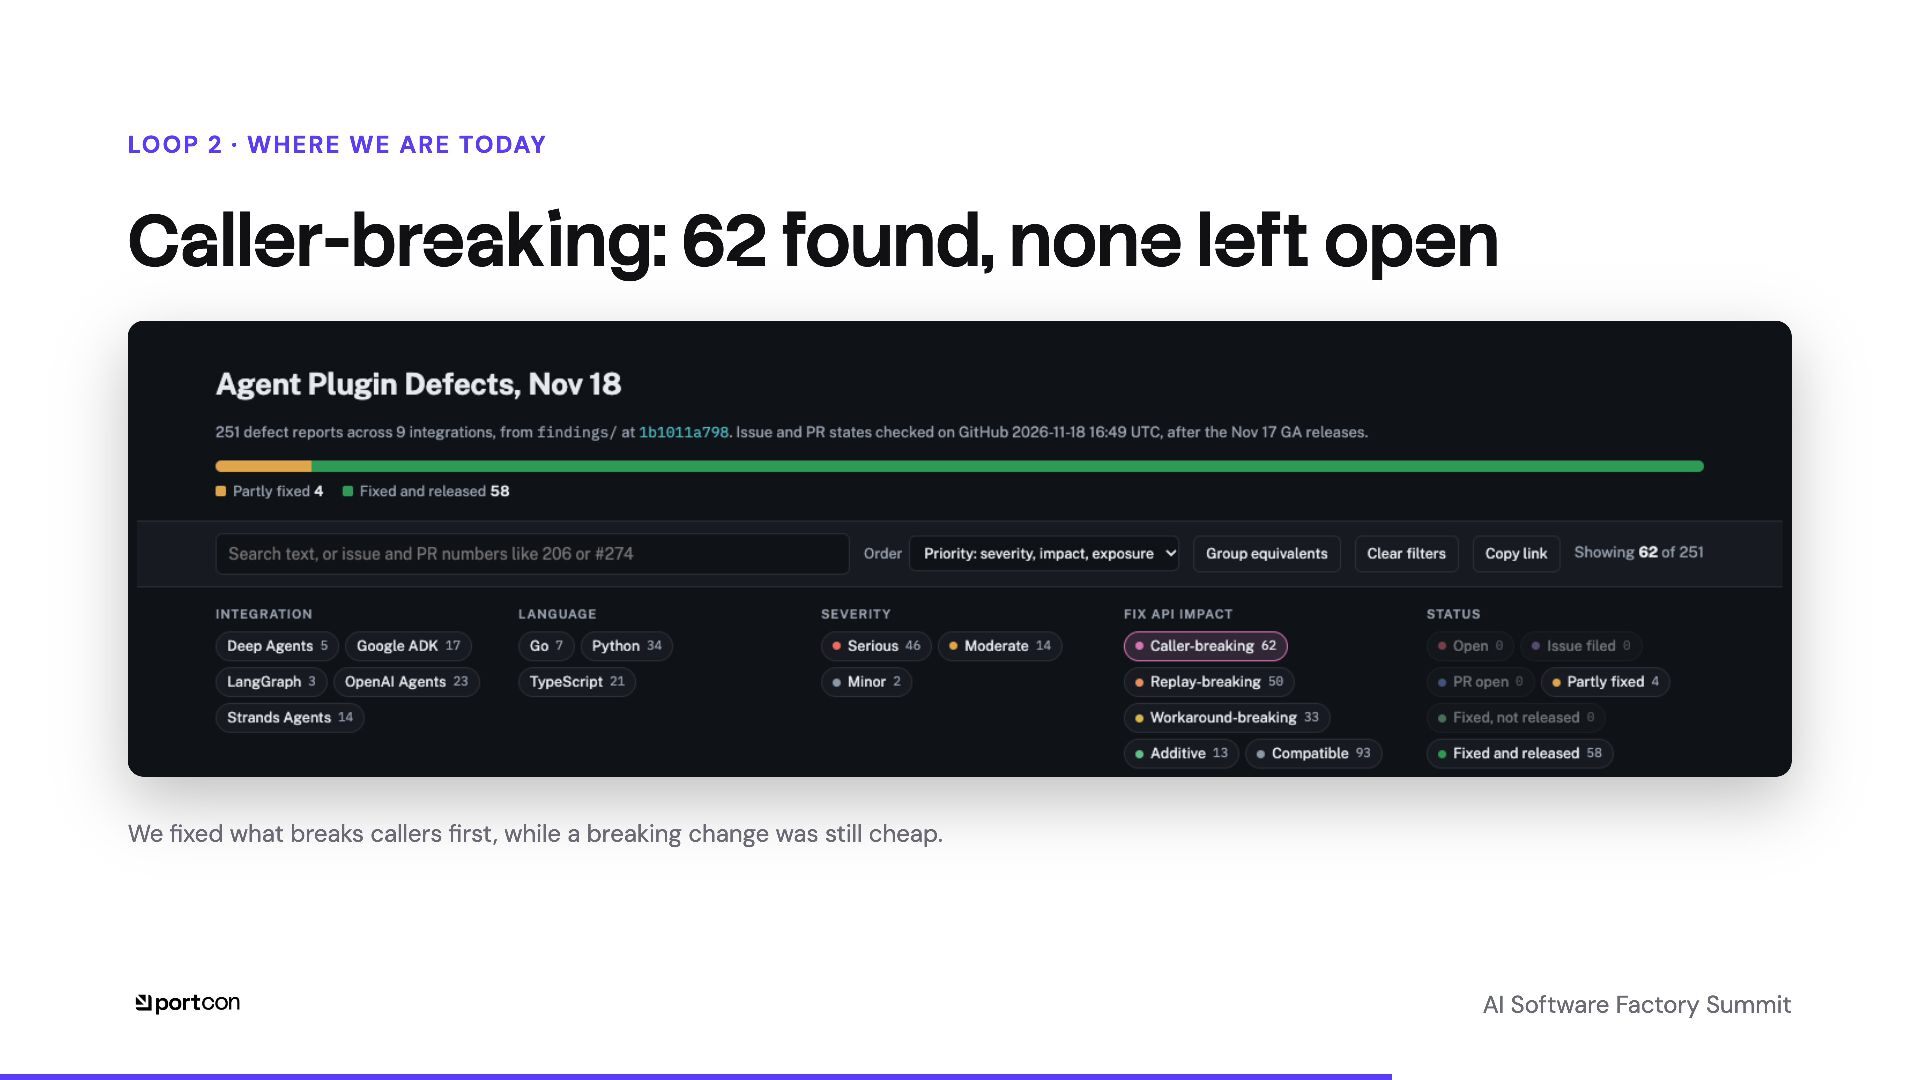
  25. LOOP 2 · WHERE WE ARE TODAY Caller-breaking: 62 found,

    none left open We fixed what breaks callers first, while a breaking change was still cheap. AI Software Factory Summit
  26. THE PLAN Loops Loops Loops LOOP 1 · FIND LOOP

    2 · FIX LOOP 3 · LEARN · NEXT Find the defects Fix them Learn and repeat One spec, run against every plugin. Out come defect reports, each with a script that shows it. Each report becomes an issue and a fix PR. Agents review it first, then a human. Every review lesson goes back into the skills that find and fix. This is what we build next. The third loop makes the first two better. AI Software Factory Summit
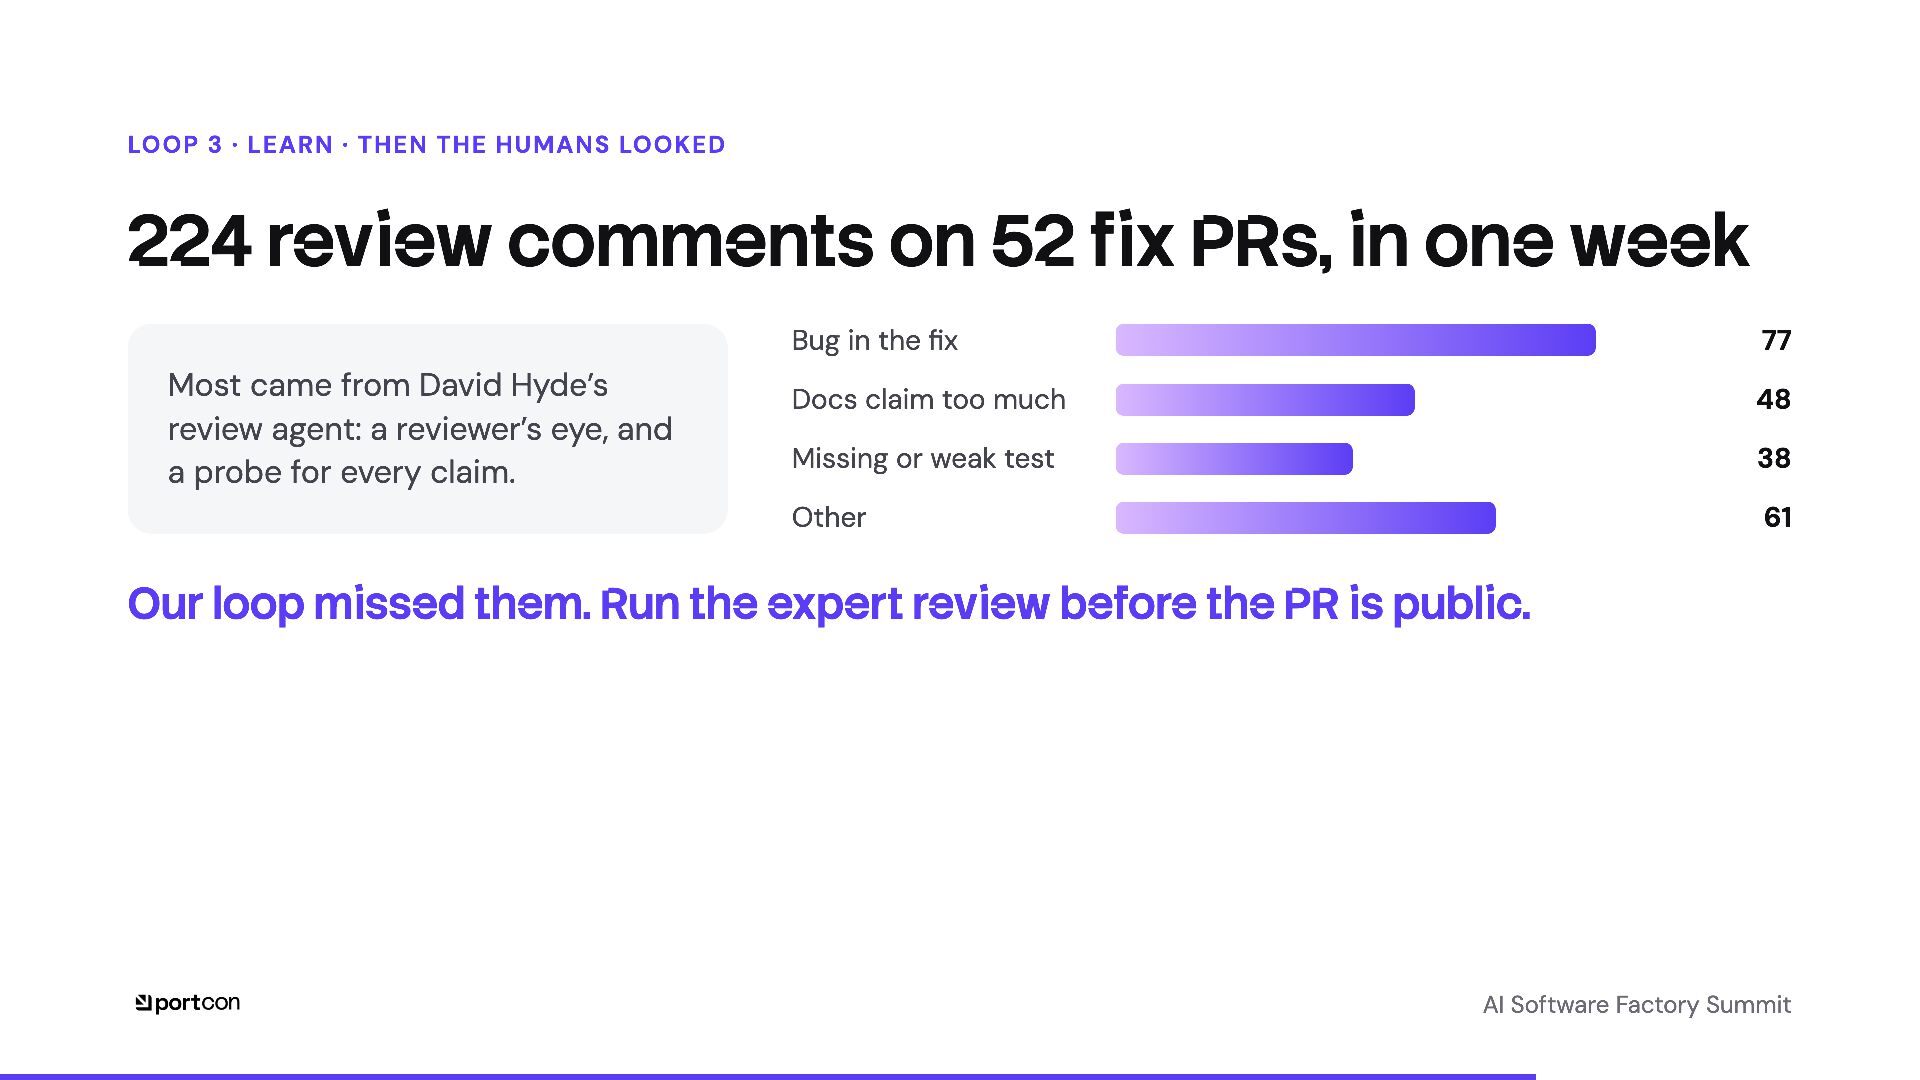
  27. LOOP 3 · LEARN · THEN THE HUMANS LOOKED 224

    review comments on 52 fix PRs, in one week Most came from David Hyde’s review agent: a reviewer’s eye, and a probe for every claim. Bug in the fix 77 Docs claim too much 48 Missing or weak test 38 Other 61 Our loop missed them. Run the expert review before the PR is public. AI Software Factory Summit
  28. IF YOU REMEMBER ONE SLIDE Start small. Keep everything, even

    your own sessions. Human time is the expensive part.
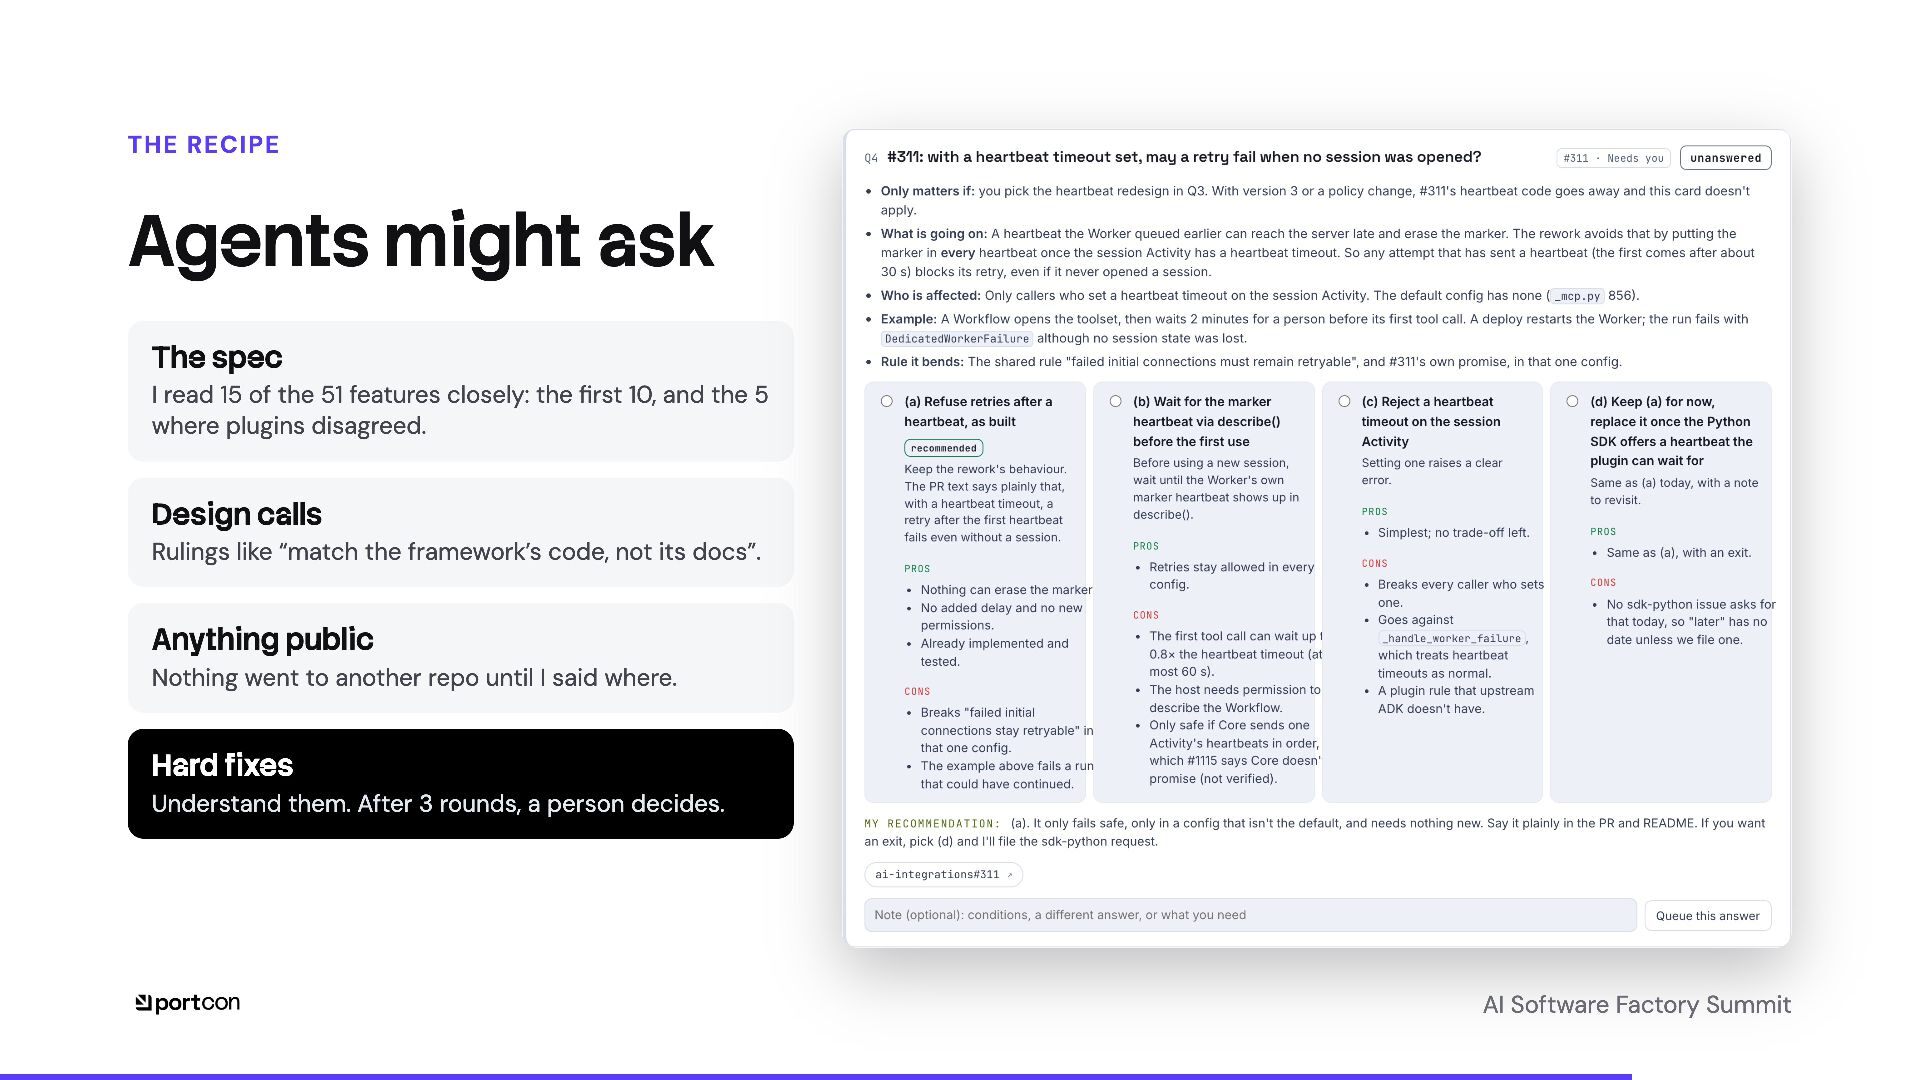
  29. THE RECIPE Agents might ask The spec I read 15

    of the 51 features closely: the first 10, and the 5 where plugins disagreed. Design calls Rulings like “match the framework’s code, not its docs”. Anything public Nothing went to another repo until I said where. Hard fixes Understand them. After 3 rounds, a person decides. AI Software Factory Summit
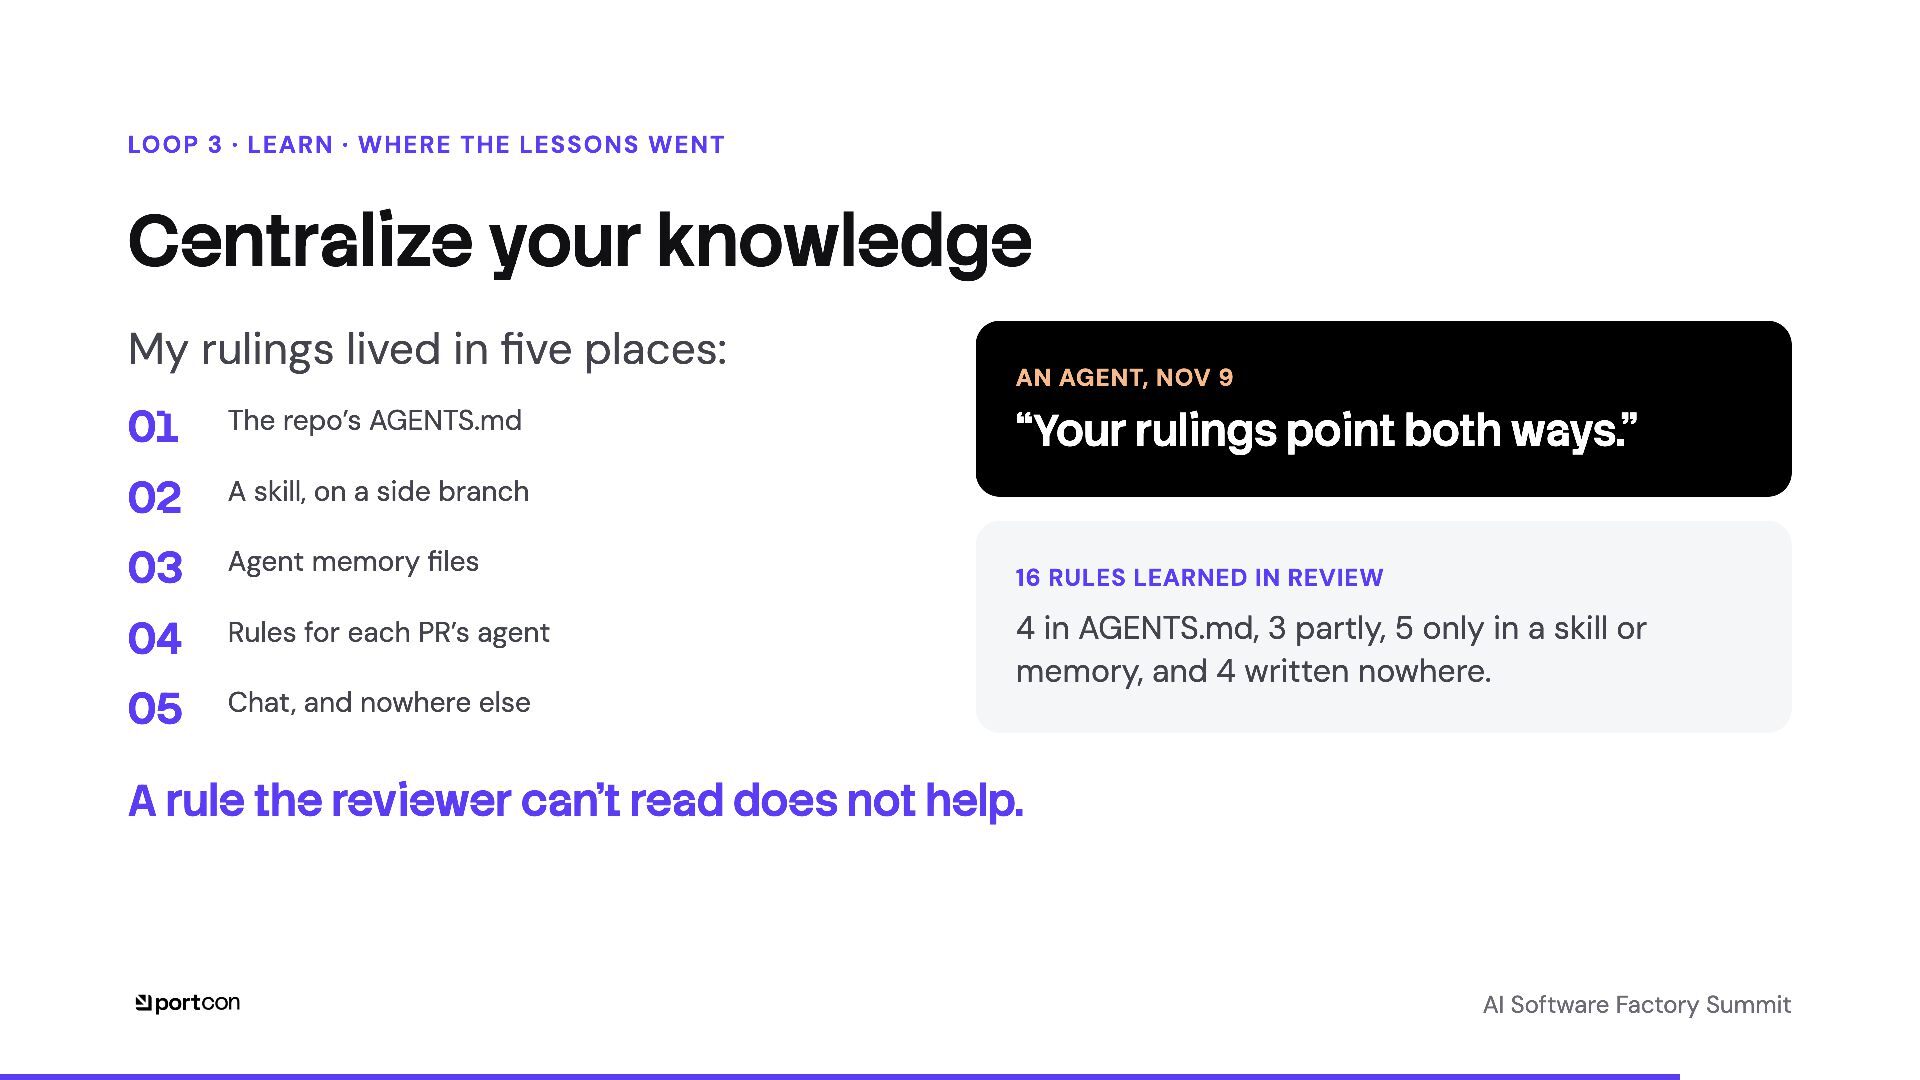
  30. LOOP 3 · LEARN · WHERE THE LESSONS WENT Centralize

    your knowledge My rulings lived in five places: 01 The repo’s AGENTS.md 02 A skill, on a side branch 03 Agent memory files 04 Rules for each PR’s agent 05 Chat, and nowhere else AN AGENT, NOV 9 “Your rulings point both ways.” 16 RULES LEARNED IN REVIEW 4 in AGENTS.md, 3 partly, 5 only in a skill or memory, and 4 written nowhere. A rule the reviewer can’t read does not help. AI Software Factory Summit
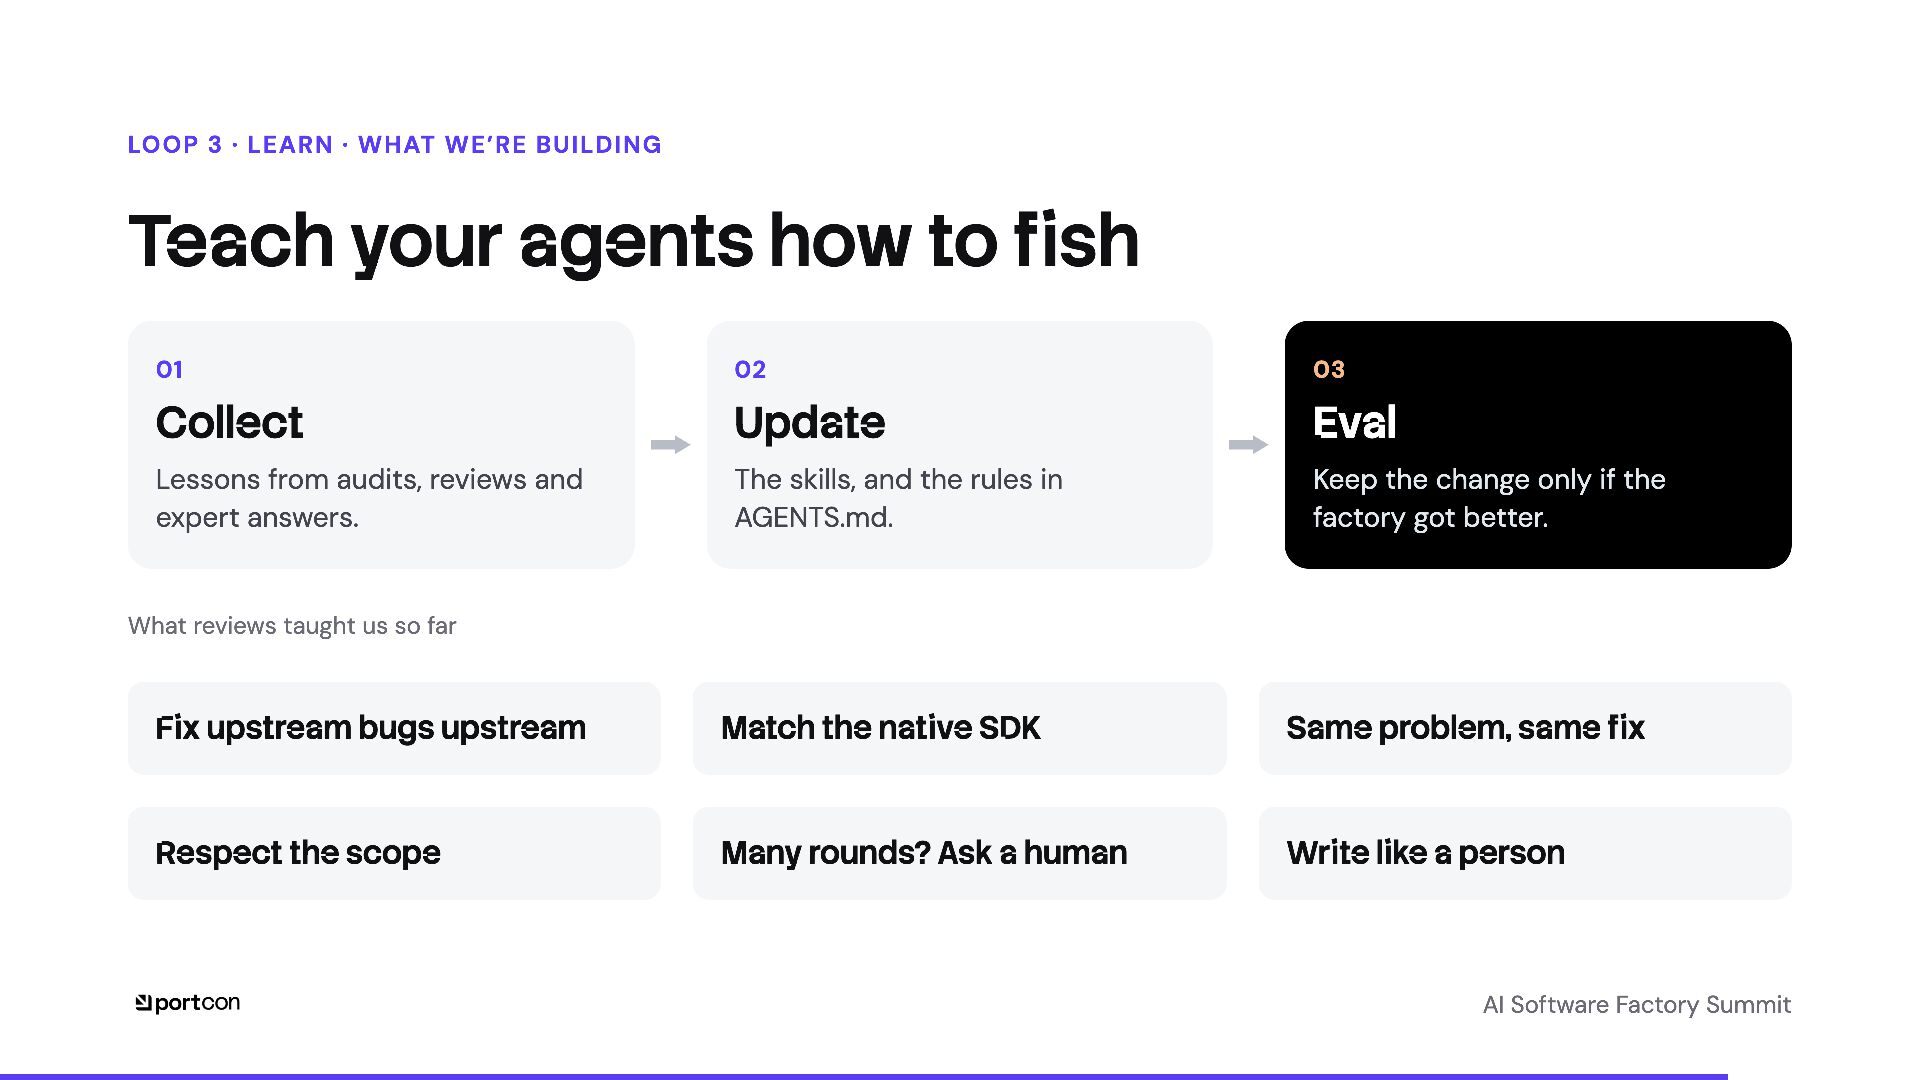
  31. LOOP 3 · LEARN · WHAT WE’RE BUILDING Teach your

    agents how to fish 01 02 03 Collect Update Eval Lessons from audits, reviews and expert answers. The skills, and the rules in AGENTS.md. Keep the change only if the factory got better. What reviews taught us so far Fix upstream bugs upstream Match the native SDK Same problem, same fix Respect the scope Many rounds? Ask a human Write like a person AI Software Factory Summit
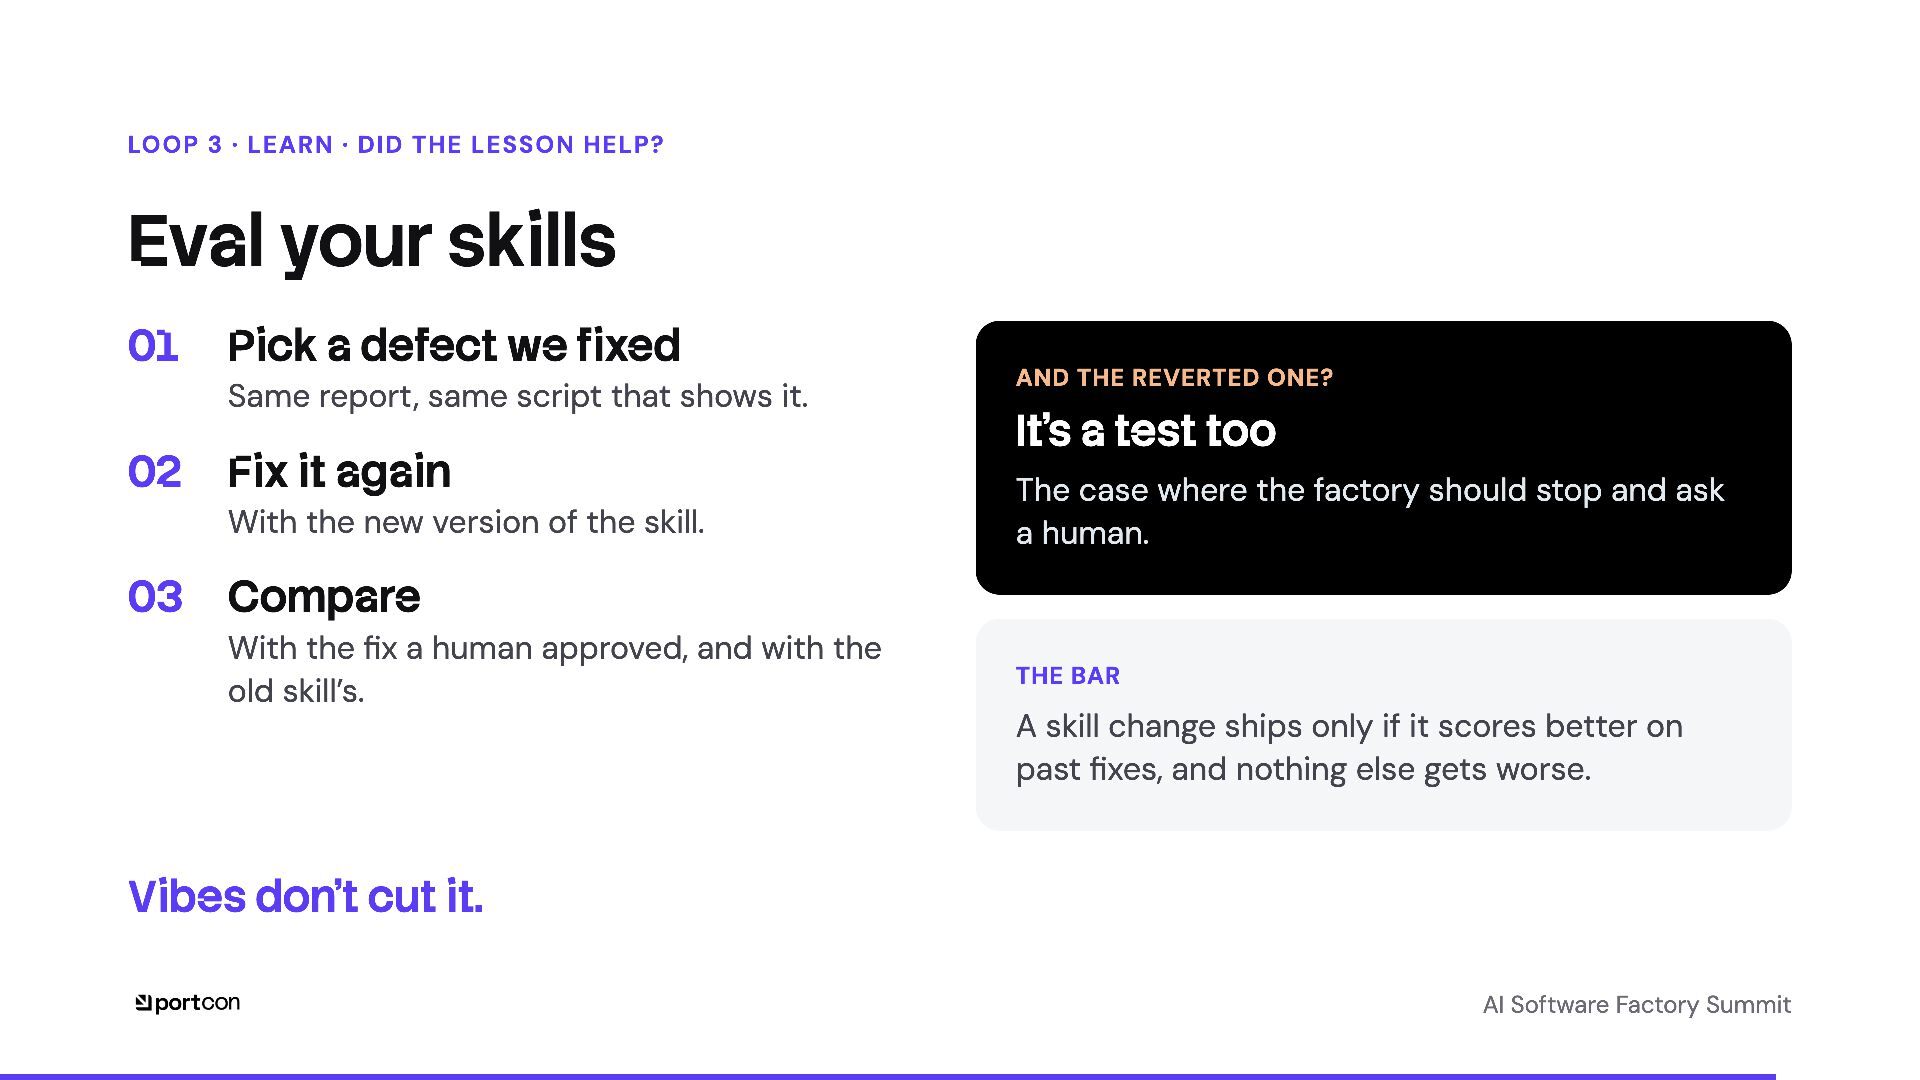
  32. LOOP 3 · LEARN · DID THE LESSON HELP? Eval

    your skills 01 Pick a defect we fixed Same report, same script that shows it. 02 Fix it again With the new version of the skill. 03 AND THE REVERTED ONE? It’s a test too The case where the factory should stop and ask a human. Compare With the fix a human approved, and with the old skill’s. THE BAR A skill change ships only if it scores better on past fixes, and nothing else gets worse. Vibes don't cut it. AI Software Factory Summit
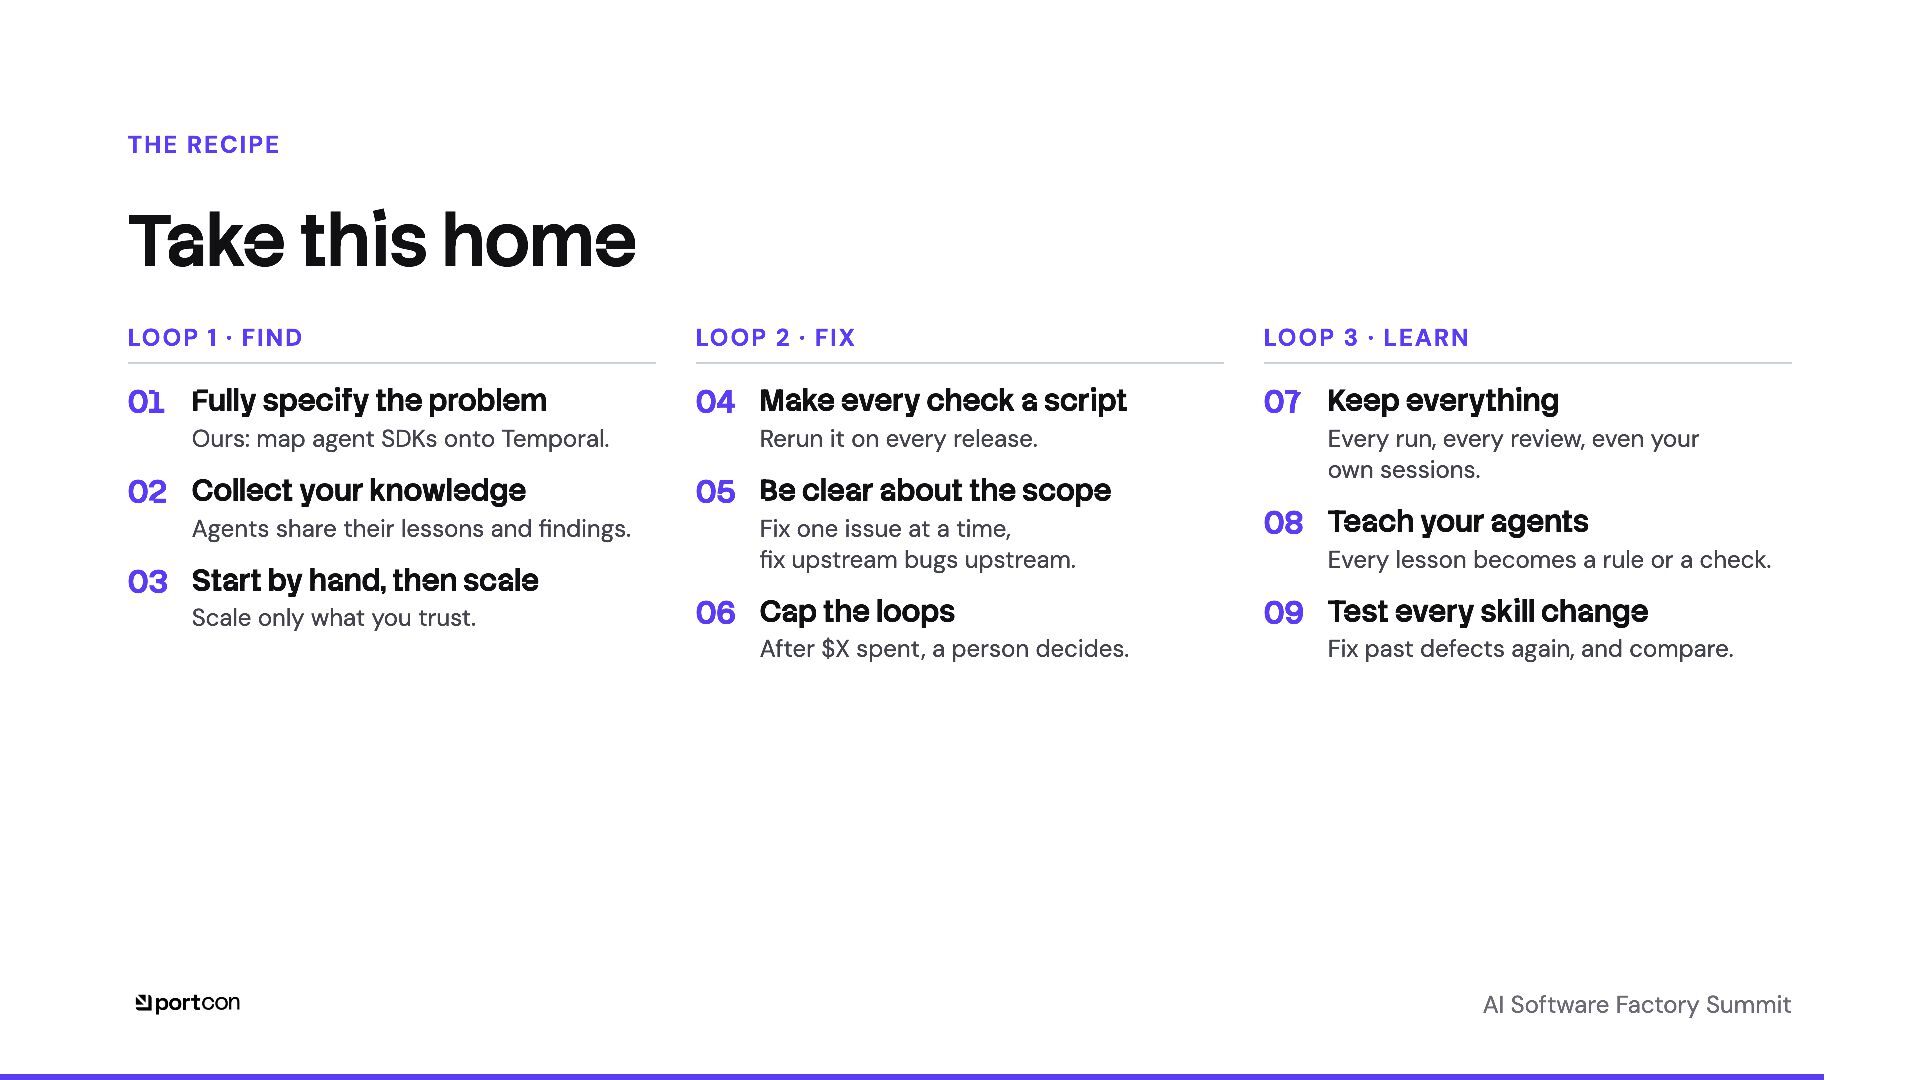
  33. THE RECIPE Take this home LOOP 1 · FIND LOOP

    2 · FIX LOOP 3 · LEARN 01 Fully specify the problem 04 Make every check a script 07 Keep everything Ours: map agent SDKs onto Temporal. 02 Collect your knowledge Agents share their lessons and findings. 03 Start by hand, then scale Scale only what you trust. Rerun it on every release. 05 Be clear about the scope Fix one issue at a time, fix upstream bugs upstream. 06 Cap the loops After $X spent, a person decides. Every run, every review, even your own sessions. 08 Teach your agents Every lesson becomes a rule or a check. 09 Test every skill change Fix past defects again, and compare. AI Software Factory Summit
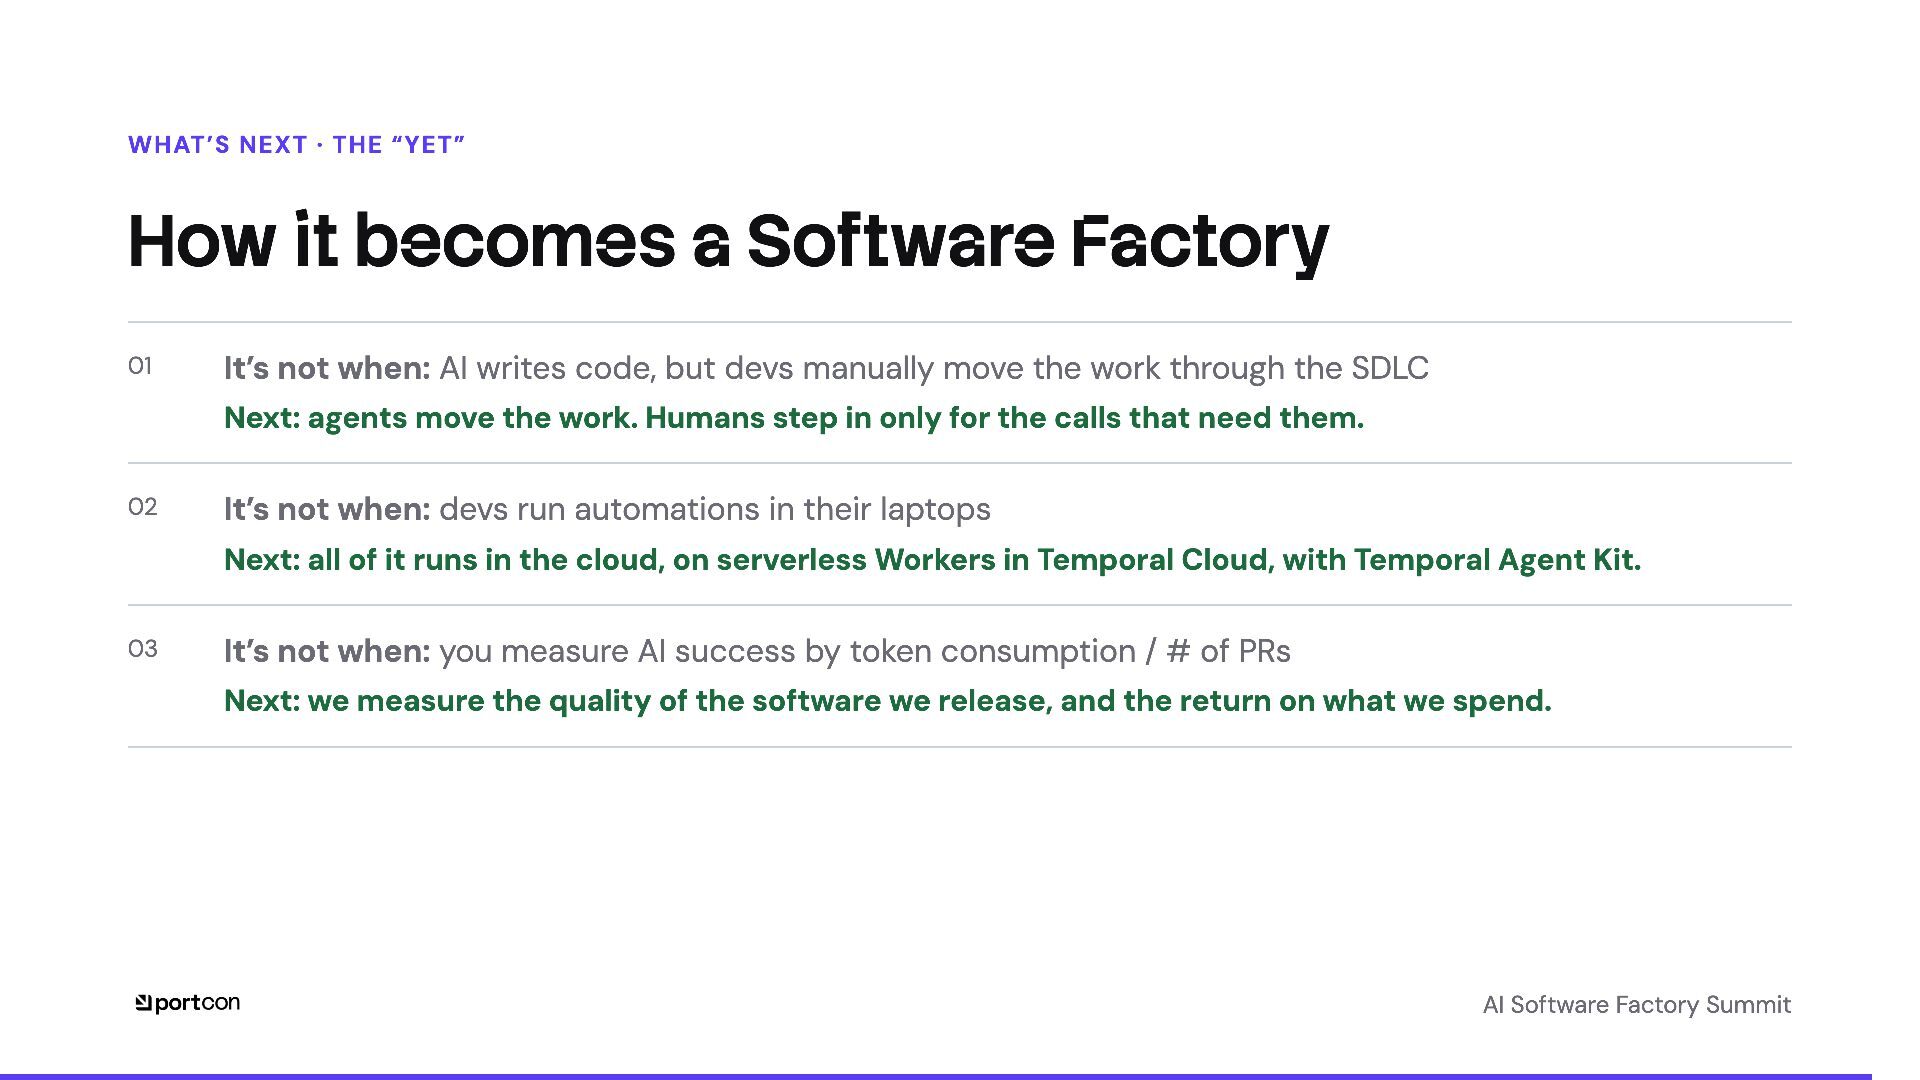
  34. WHAT’S NEXT · THE “YET” How it becomes a Software

    Factory 01 It’s not when: AI writes code, but devs manually move the work through the SDLC Next: agents move the work. Humans step in only for the calls that need them. 02 It’s not when: devs run automations in their laptops Next: all of it runs in the cloud, on serverless Workers in Temporal Cloud, with Temporal Agent Kit. 03 It’s not when: you measure AI success by token consumption / # of PRs Next: we measure the quality of the software we release, and the return on what we spend. AI Software Factory Summit
  35. Thank you! Questions? @francesc The plugins: github.com/temporalio/ai-integrations The slides: speakerdeck.com/campoy/one-spec-to-validate-them-all

    Thanks to AI Foundations team at Temporal for all of their help! Rate this talk, join the raffle

More Decks by Francesc Campoy Flores

Other Decks in Technology