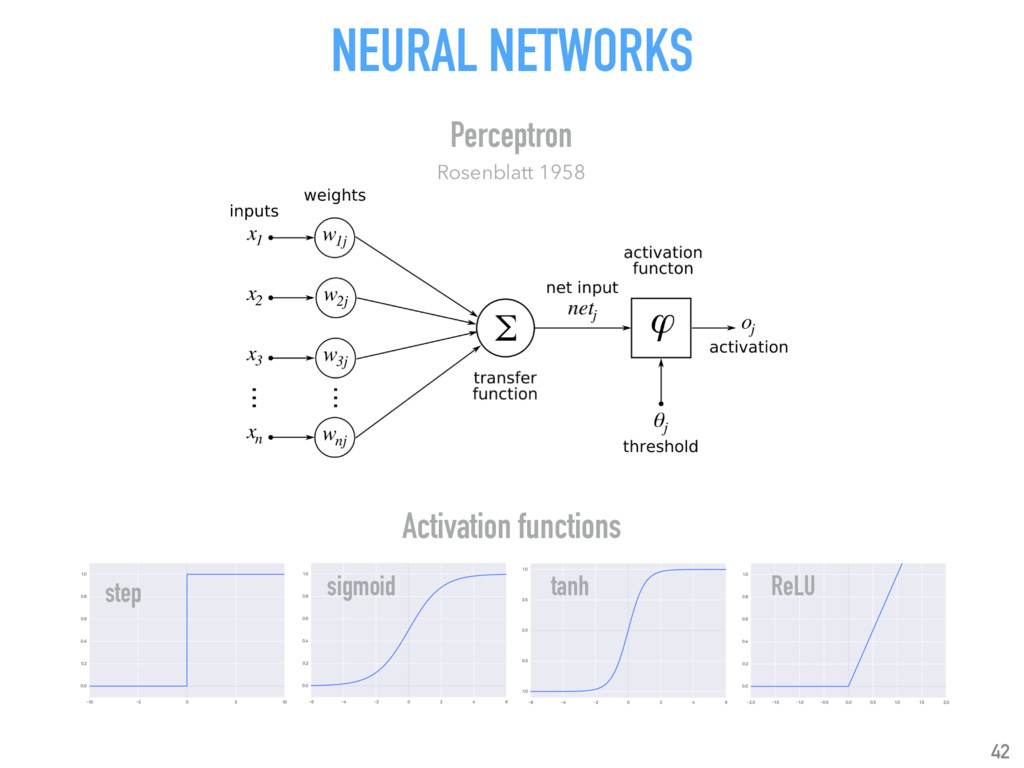
Share
Embed
High-contrast imaging post-processing methods for exoplanet detection and characterization
Talk given at INRIA Grenoble - Rhône-Alpes. Presents my latests results on "Supervised detection of exoplanets in high-contrast image sequences" (https://arxiv.org/abs/1712.02841) to experts in computer vision and machine (deep) learning (http://thoth.inrialpes.fr/).
Carlos Alberto Gomez Gonzalez
February 05, 2018
Transcript
63 slides
-
HIGH-CONTRAST IMAGING POST-PROCESSING METHODS FOR EXOPLANET DETECTION AND CHARACTERIZATION Carlos
Alberto Gómez Gonzalez INRIA Grenoble - Rhône-Alpes, 2018 -
OUTLINE 1. Introduction 2. State-of-the-art differential imaging post- processing techniques
3.Supervised learning applied to HCI 4. Conclusions -
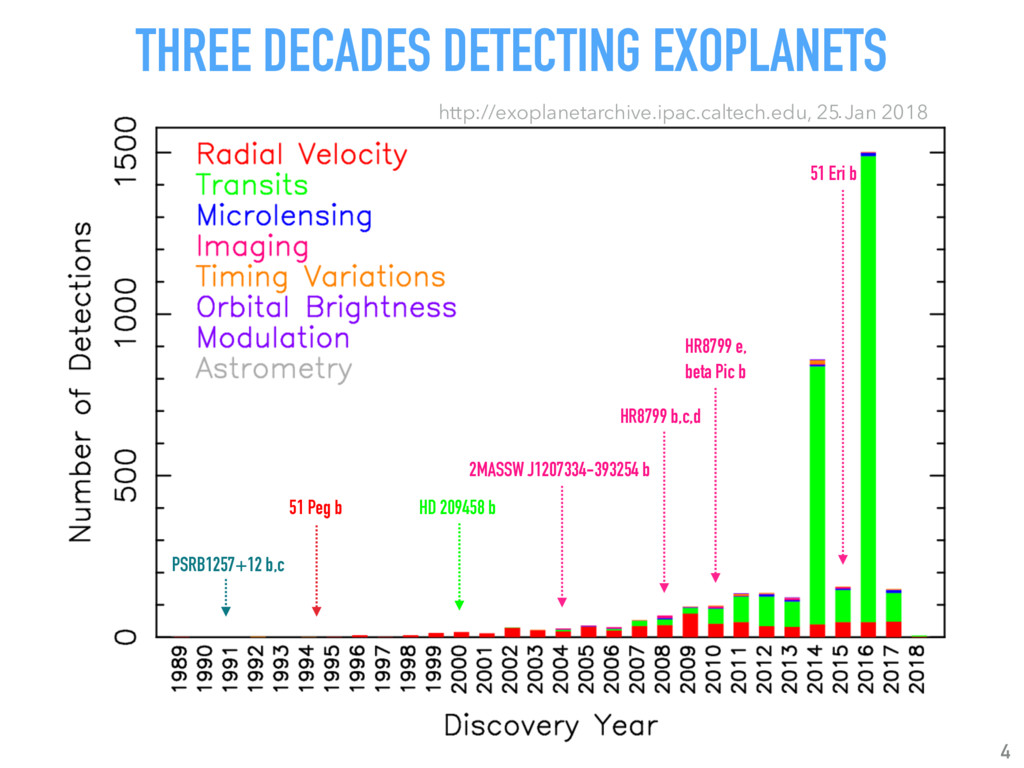
4 THREE DECADES DETECTING EXOPLANETS PSRB1257+12 b,c 51 Peg b
HD 209458 b 2MASSW J1207334-393254 b HR8799 b,c,d HR8799 e, beta Pic b 51 Eri b http://exoplanetarchive.ipac.caltech.edu, 25 Jan 2018 -
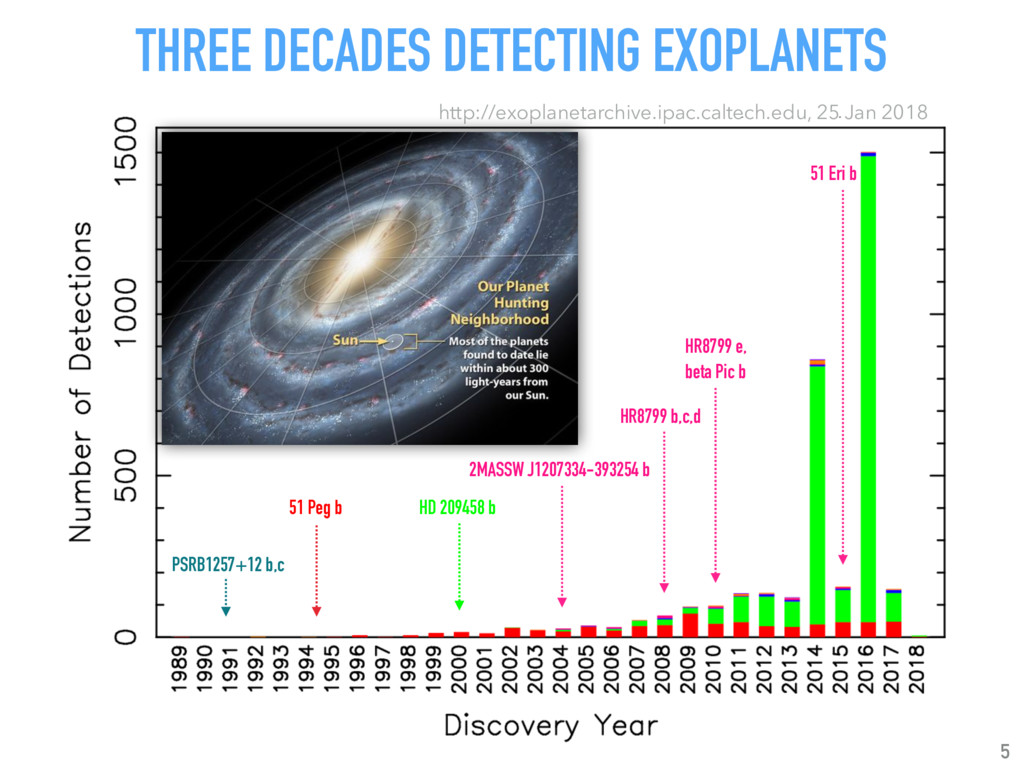
5 THREE DECADES DETECTING EXOPLANETS PSRB1257+12 b,c 51 Peg b
HD 209458 b 2MASSW J1207334-393254 b HR8799 b,c,d HR8799 e, beta Pic b 51 Eri b http://exoplanetarchive.ipac.caltech.edu, 25 Jan 2018 -
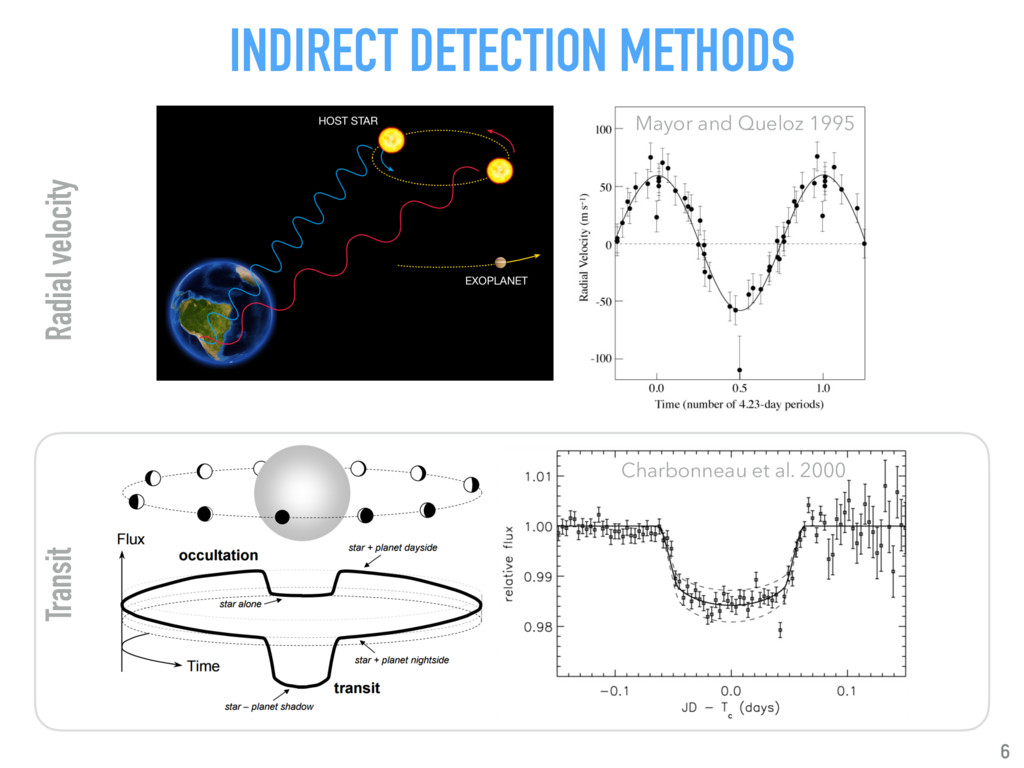
6 INDIRECT DETECTION METHODS Radial velocity Transit Mayor and Queloz
1995 Charbonneau et al. 2000 -
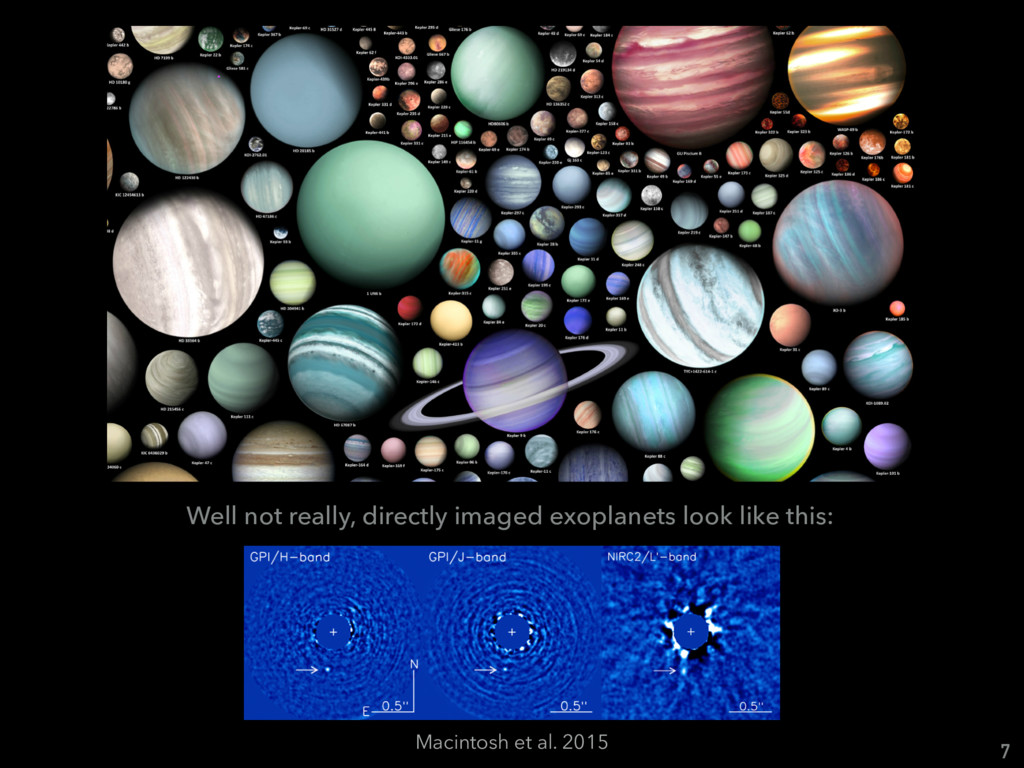
7 Well not really, directly imaged exoplanets look like this:
Macintosh et al. 2015 -
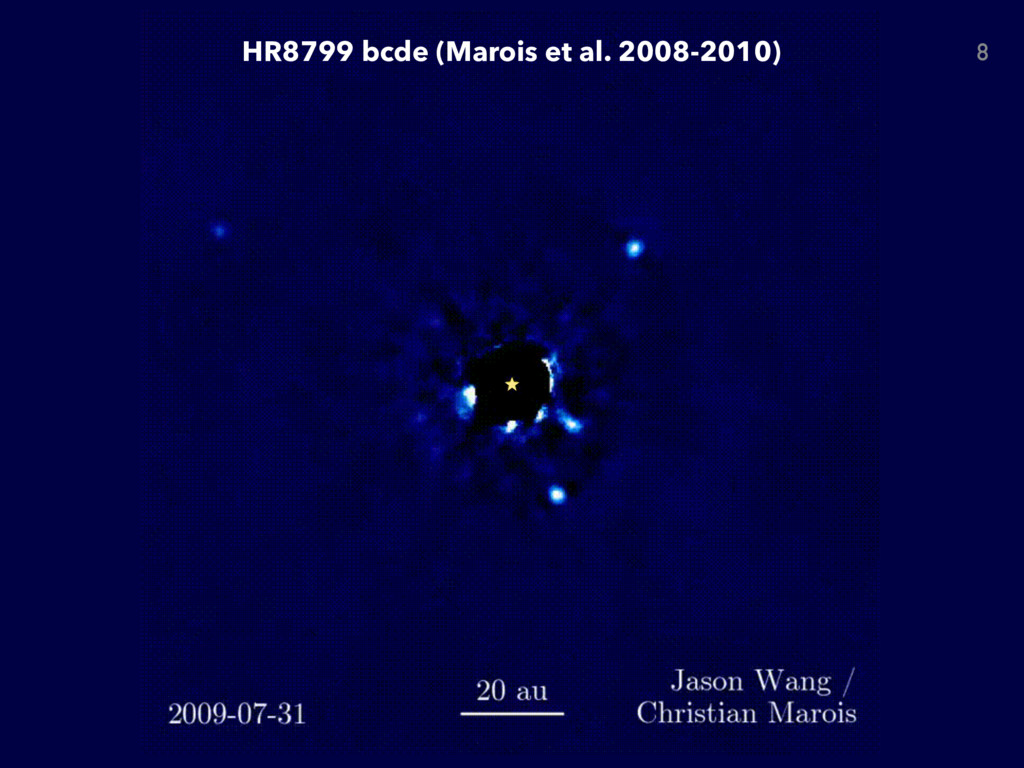
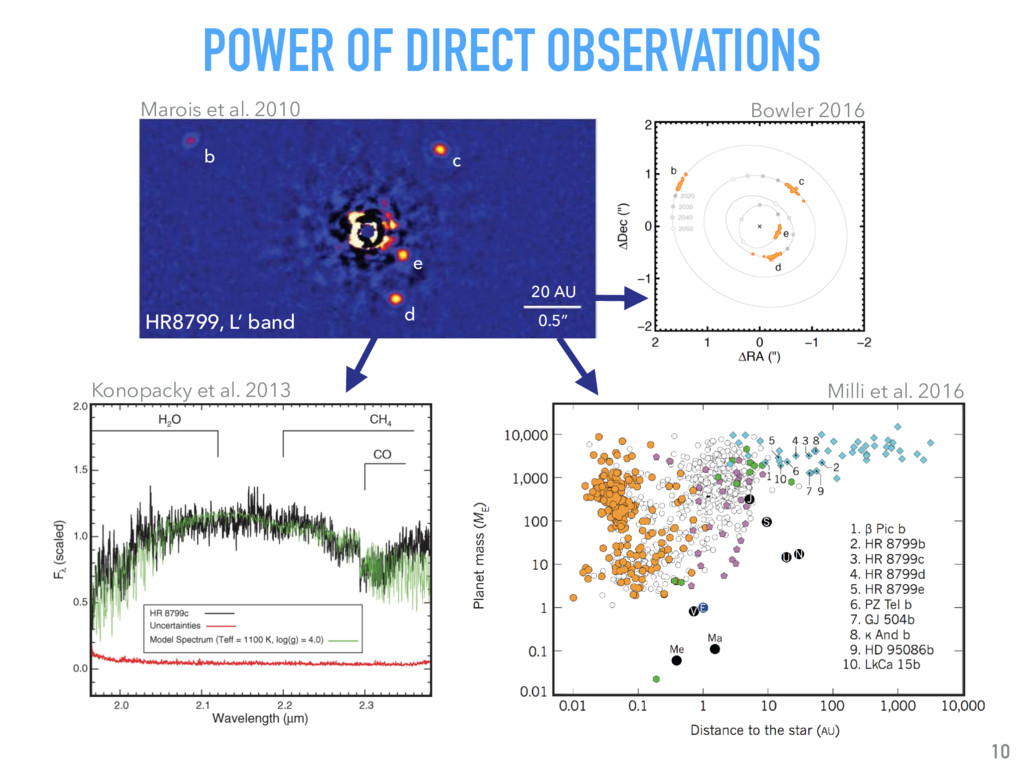
POWER OF DIRECT OBSERVATIONS 10 Milli et al. 2016 Konopacky
et al. 2013 Bowler 2016 Marois et al. 2010 HR8799, L’ band 20 AU 0.5” b c d e -
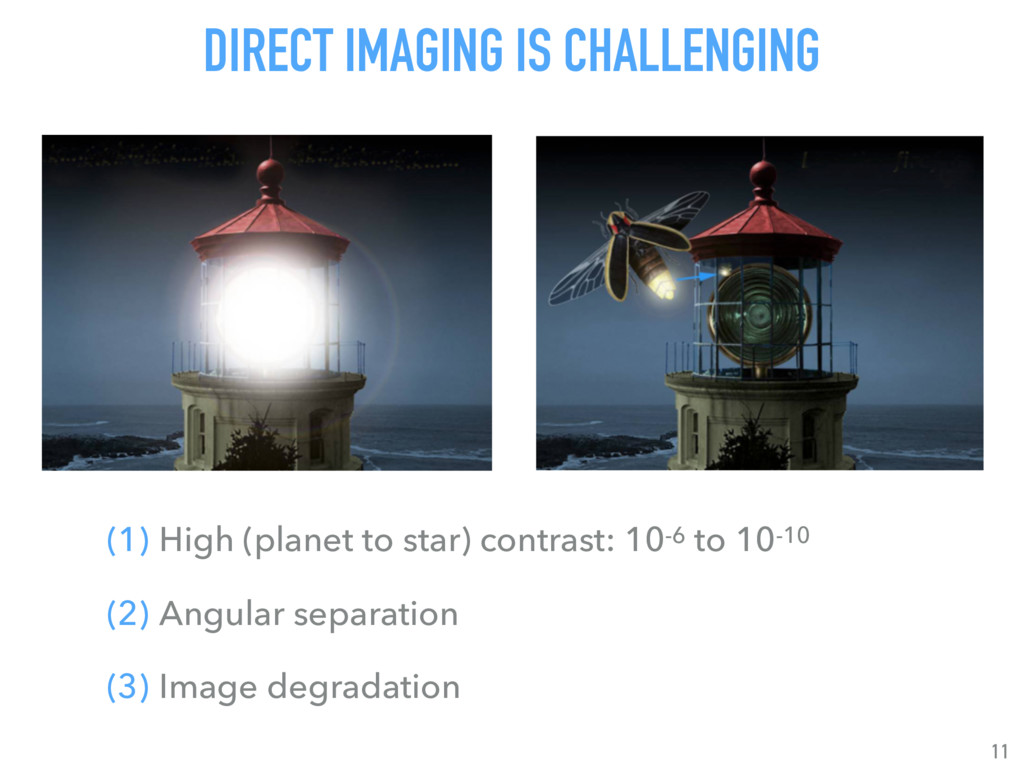
11 DIRECT IMAGING IS CHALLENGING (1) High (planet to star)
contrast: 10-6 to 10-10 (2) Angular separation (3) Image degradation -
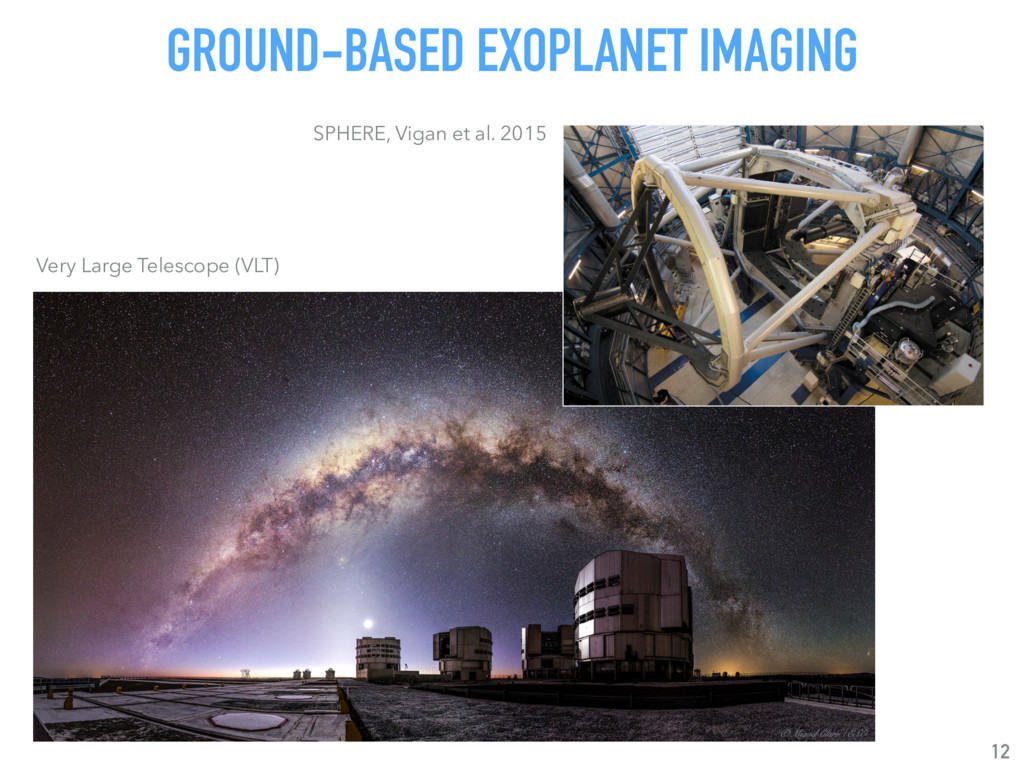
GROUND-BASED EXOPLANET IMAGING 12 SPHERE, Vigan et al. 2015 Very
Large Telescope (VLT) -
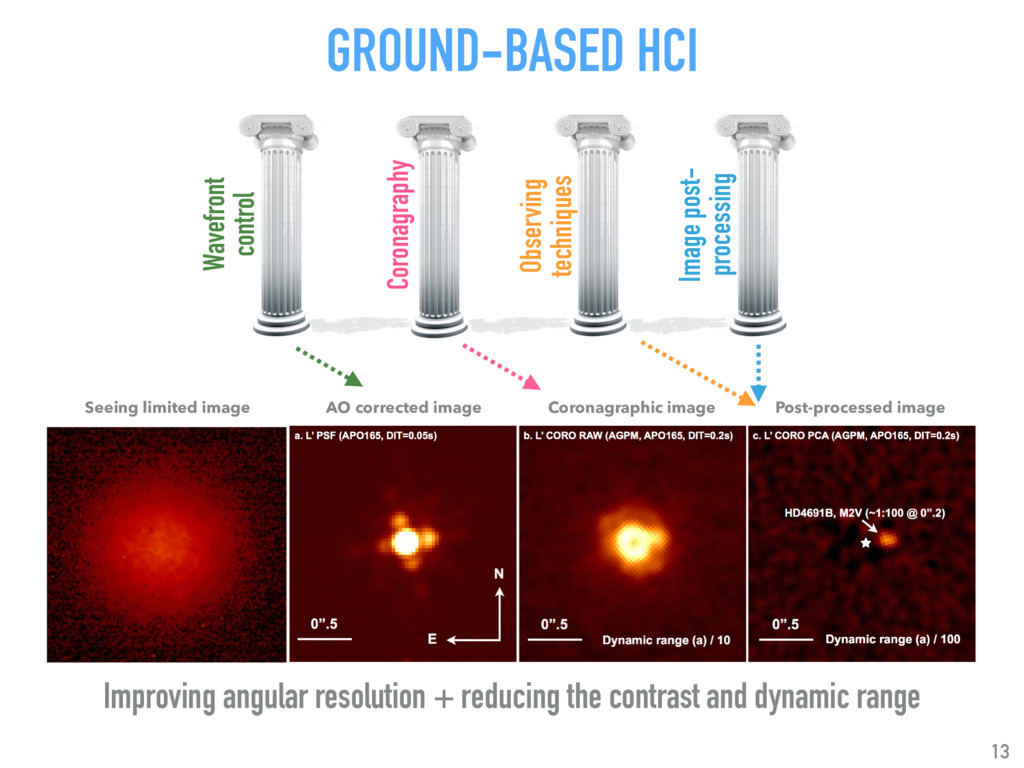
GROUND-BASED HCI 13 Seeing limited image Improving angular resolution +
reducing the contrast and dynamic range AO corrected image Coronagraphic image Post-processed image Coronagraphy Wavefront control Observing techniques Image post- processing -
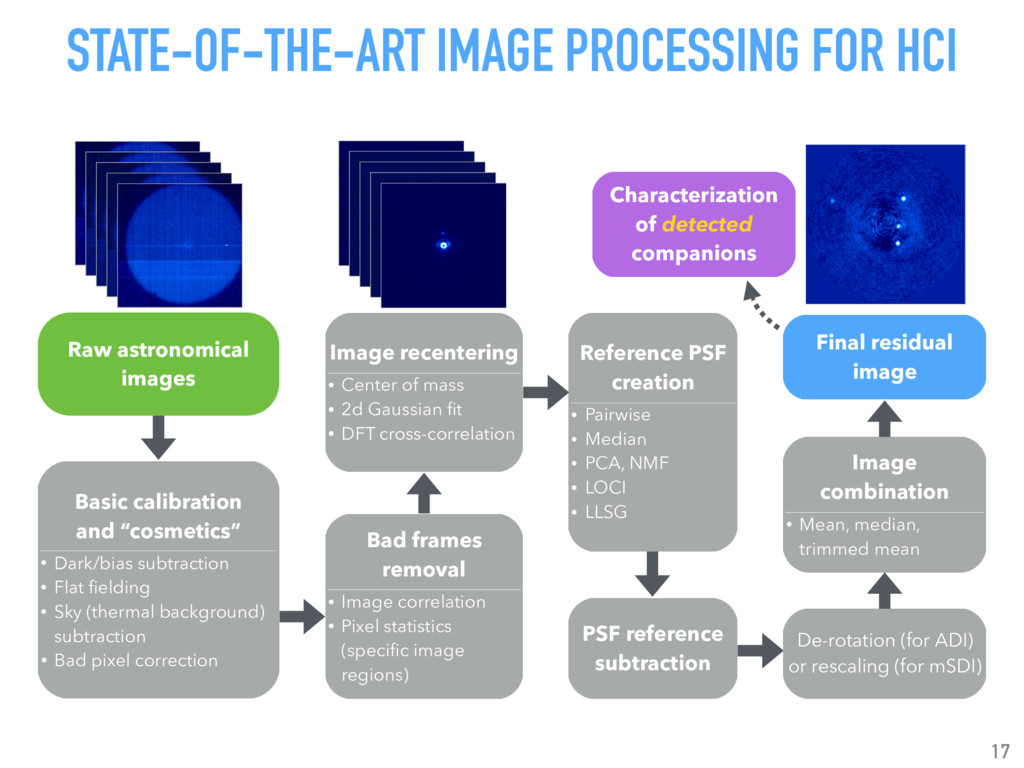
STATE-OF-THE-ART IMAGE PROCESSING FOR HCI 17 Basic calibration and “cosmetics”
• Dark/bias subtraction • Flat fielding • Sky (thermal background) subtraction • Bad pixel correction Raw astronomical images Final residual image Image recentering • Center of mass • 2d Gaussian fit • DFT cross-correlation Bad frames removal • Image correlation • Pixel statistics (specific image regions) Reference PSF creation • Pairwise • Median • PCA, NMF • LOCI • LLSG Image combination • Mean, median, trimmed mean PSF reference subtraction De-rotation (for ADI) or rescaling (for mSDI) Characterization of detected companions -
VORTEX IMAGE PROCESSING (VIP) LIBRARY • VIP: open-source python library
for reproducible and robust data reduction, providing a wide collection of pre- and post-processing algorithms for HCI data processing • Three observing techniques: angular, reference-star, and multi-spectral differential imaging • Mature ADI processing. RDI and mSDI are work in progress 18 Gomez Gonzalez et al. 2017 -
• 50k+ lines of code, 1+7 contributors • 279 commits,
64 PRs, 48 closed issues, 12 releases • Growing community of users • > 10 papers published/submitted citing VIP • Documentation: http://vip.readthedocs.io/ + Jupyter tutorial • Open-science & reproducibility (Jupyter workflows/ pipelines) 19 Gomez Gonzalez et al. 2017 VORTEX IMAGE PROCESSING (VIP) LIBRARY -
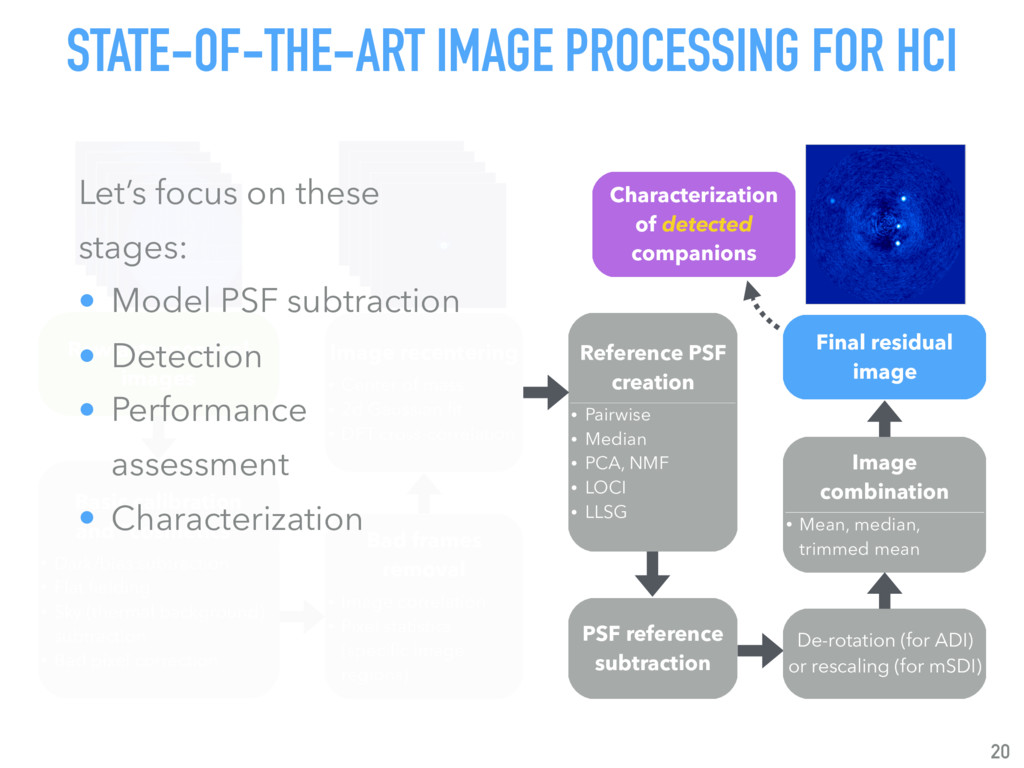
STATE-OF-THE-ART IMAGE PROCESSING FOR HCI 20 Basic calibration and “cosmetics”
• Dark/bias subtraction • Flat fielding • Sky (thermal background) subtraction • Bad pixel correction Raw astronomical images Final residual image Image recentering • Center of mass • 2d Gaussian fit • DFT cross-correlation Bad frames removal • Image correlation • Pixel statistics (specific image regions) Reference PSF creation • Pairwise • Median • PCA, NMF • LOCI • LLSG Image combination • Mean, median, trimmed mean PSF reference subtraction De-rotation (for ADI) or rescaling (for mSDI) Characterization of detected companions Let’s focus on these stages: • Model PSF subtraction • Detection • Performance assessment • Characterization -
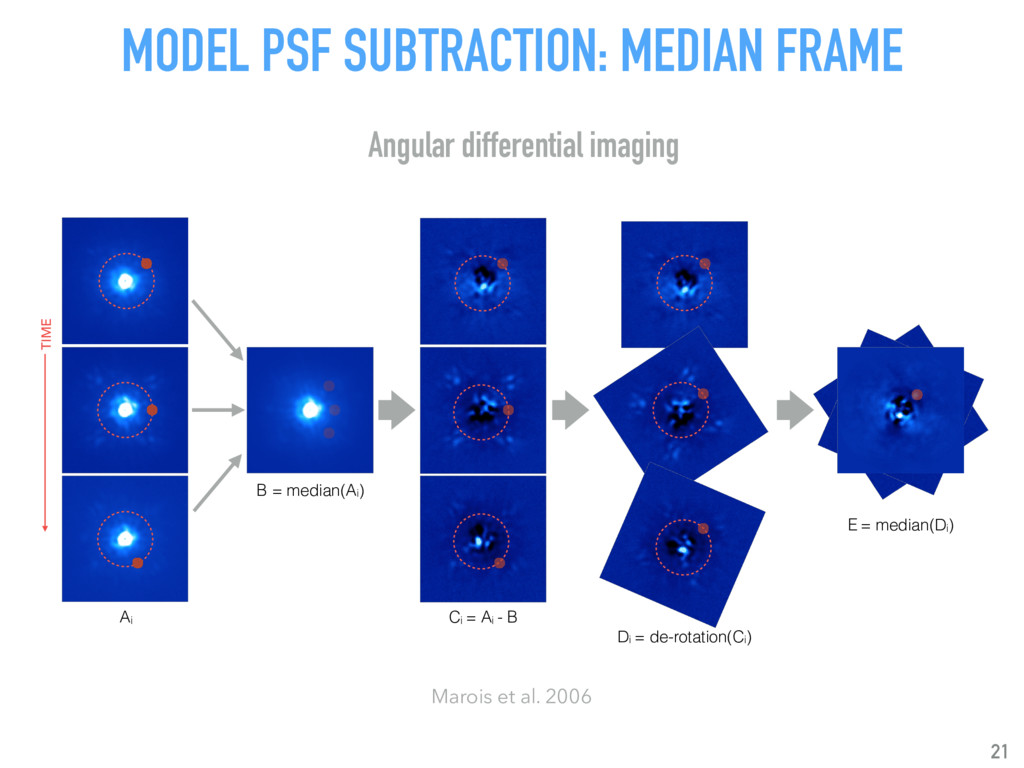
21 Angular differential imaging Ai TIME B = median(Ai) Ci
= Ai - B Di = de-rotation(Ci) E = median(Di) Marois et al. 2006 MODEL PSF SUBTRACTION: MEDIAN FRAME -
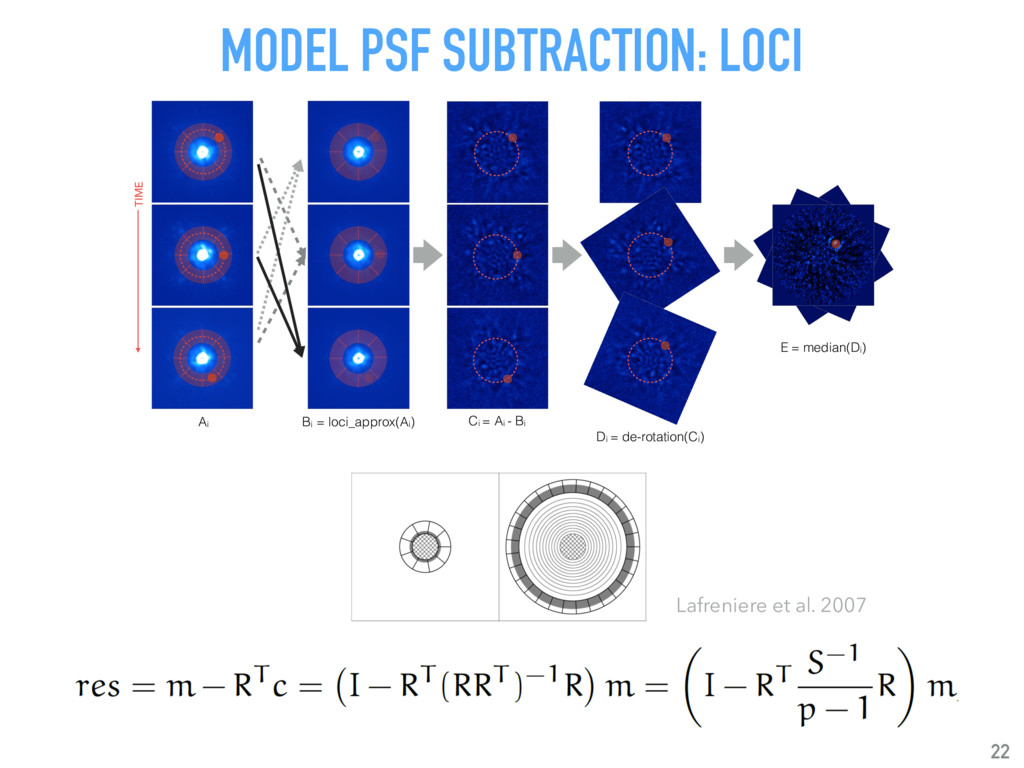
MODEL PSF SUBTRACTION: LOCI 22 Ai Bi = loci_approx(Ai) Ci
= Ai - Bi Di = de-rotation(Ci) E = median(Di) TIME Lafreniere et al. 2007 -
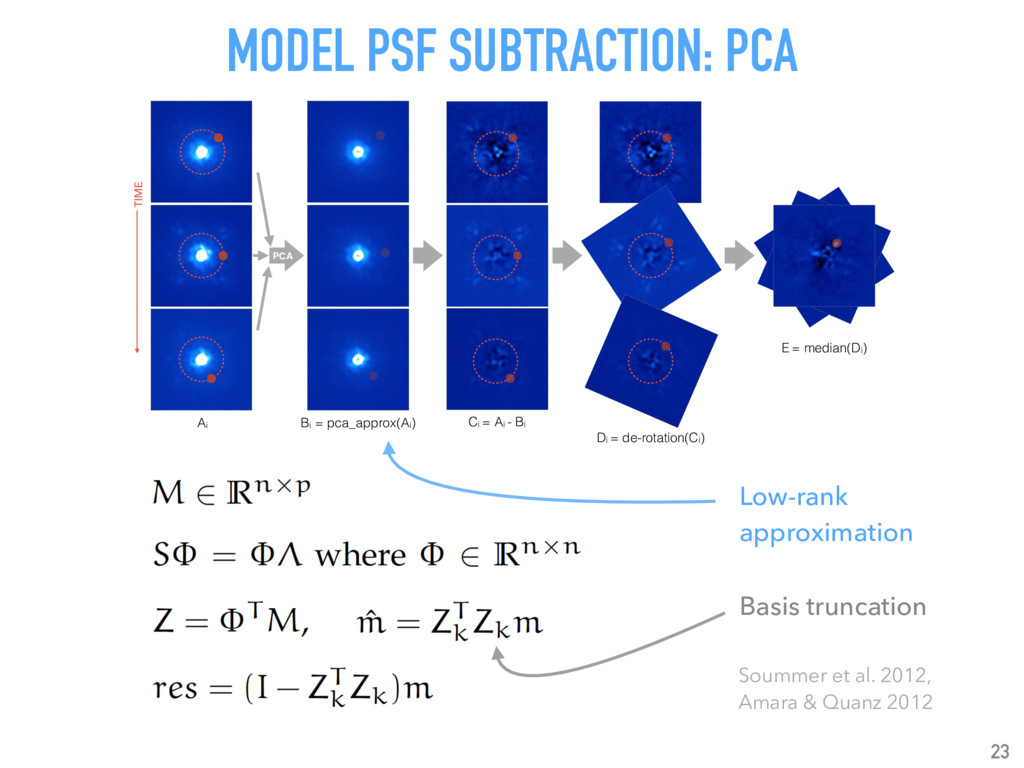
MODEL PSF SUBTRACTION: PCA 23 Ai PCA Bi = pca_approx(Ai)
Ci = Ai - Bi Di = de-rotation(Ci) E = median(Di) TIME Low-rank approximation Basis truncation Soummer et al. 2012, Amara & Quanz 2012 -
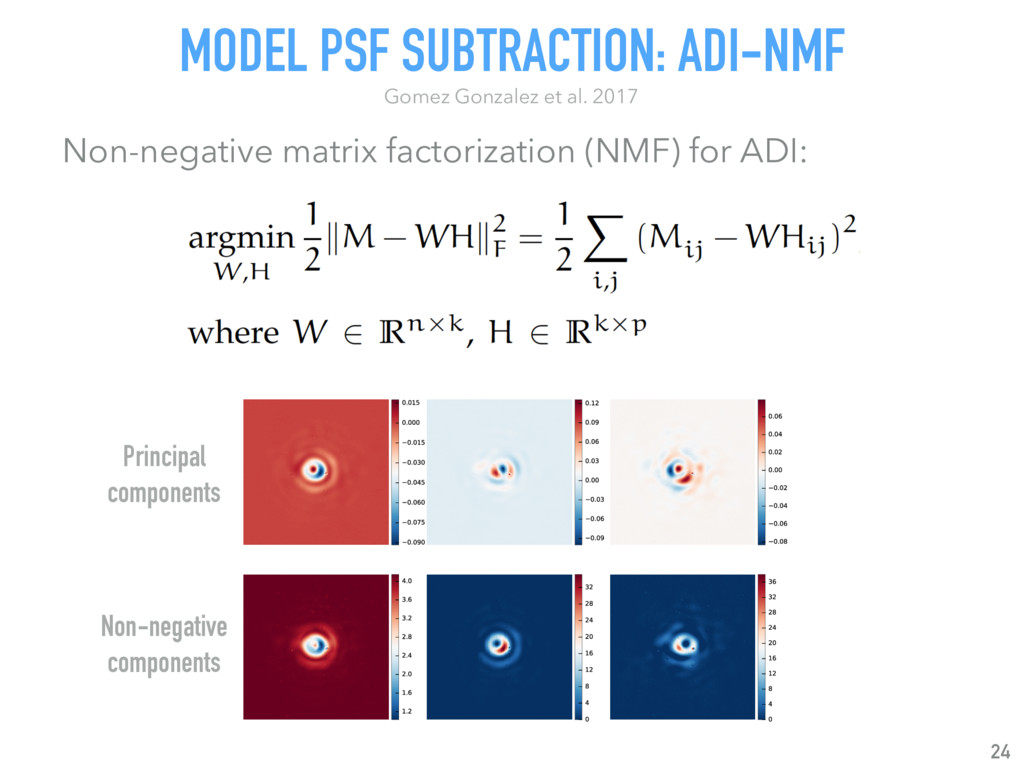
MODEL PSF SUBTRACTION: ADI-NMF 24 Non-negative matrix factorization (NMF) for
ADI: Gomez Gonzalez et al. 2017 Non-negative components Principal components -
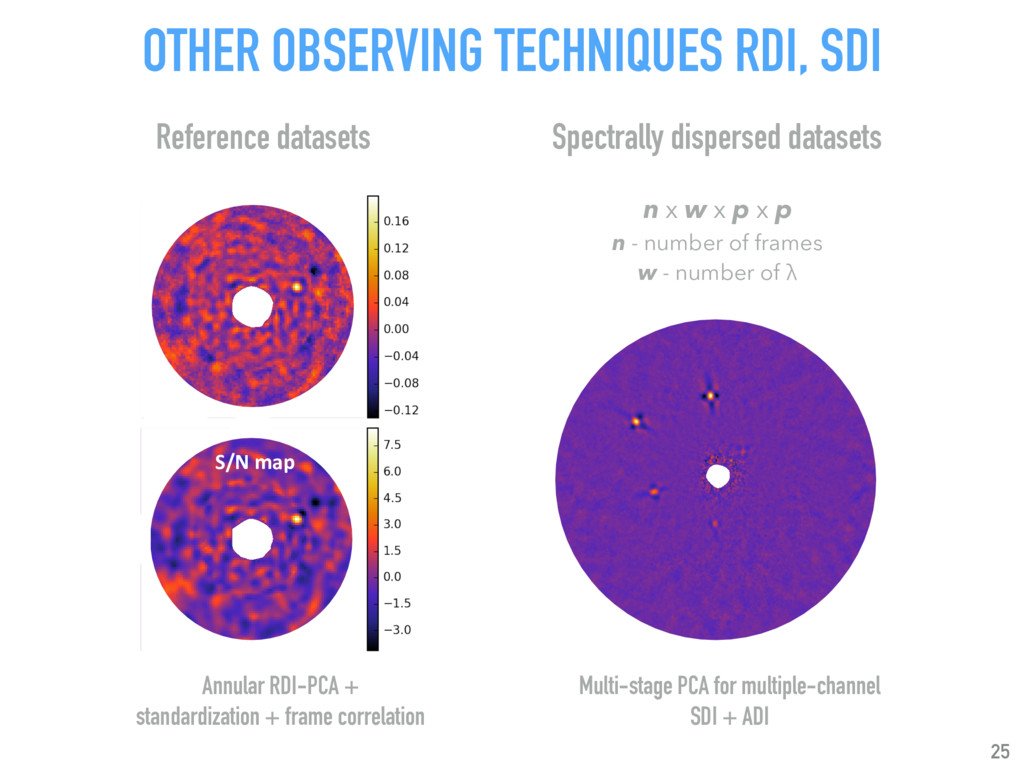
OTHER OBSERVING TECHNIQUES RDI, SDI 25 n x w x
p x p n - number of frames w - number of λ Annular RDI-PCA + standardization + frame correlation Multi-stage PCA for multiple-channel SDI + ADI S/N map Reference datasets Spectrally dispersed datasets -
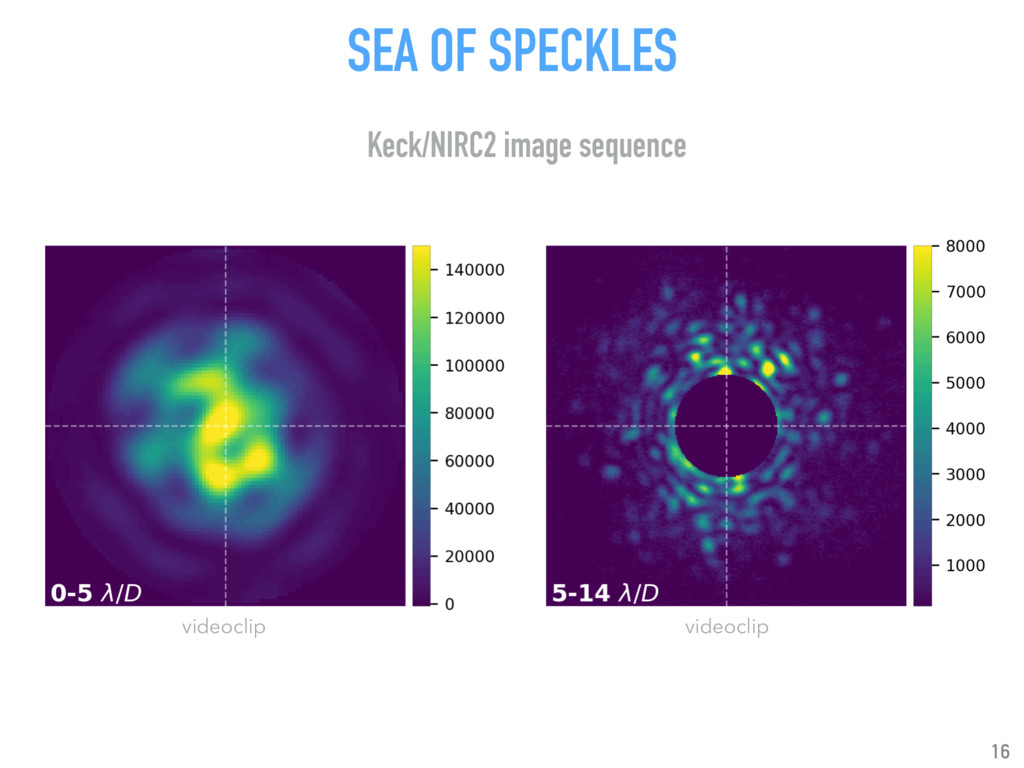
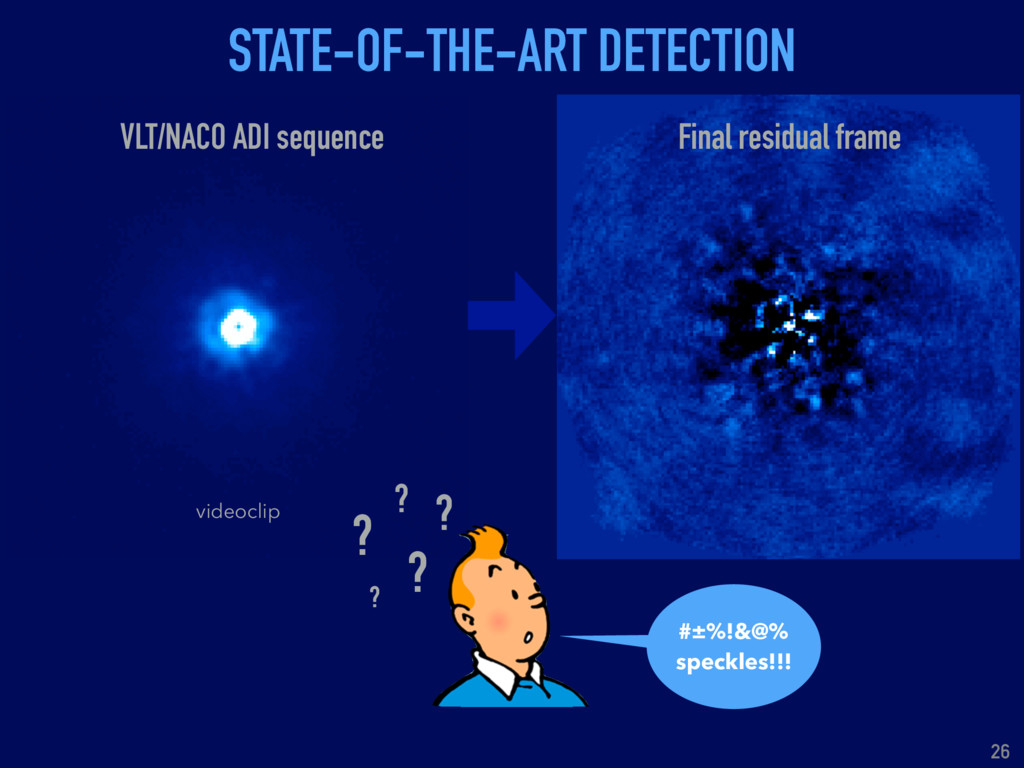
26 STATE-OF-THE-ART DETECTION VLT/NACO ADI sequence Final residual frame #±%!&@%
speckles!!! ? ? ? ? ? videoclip -
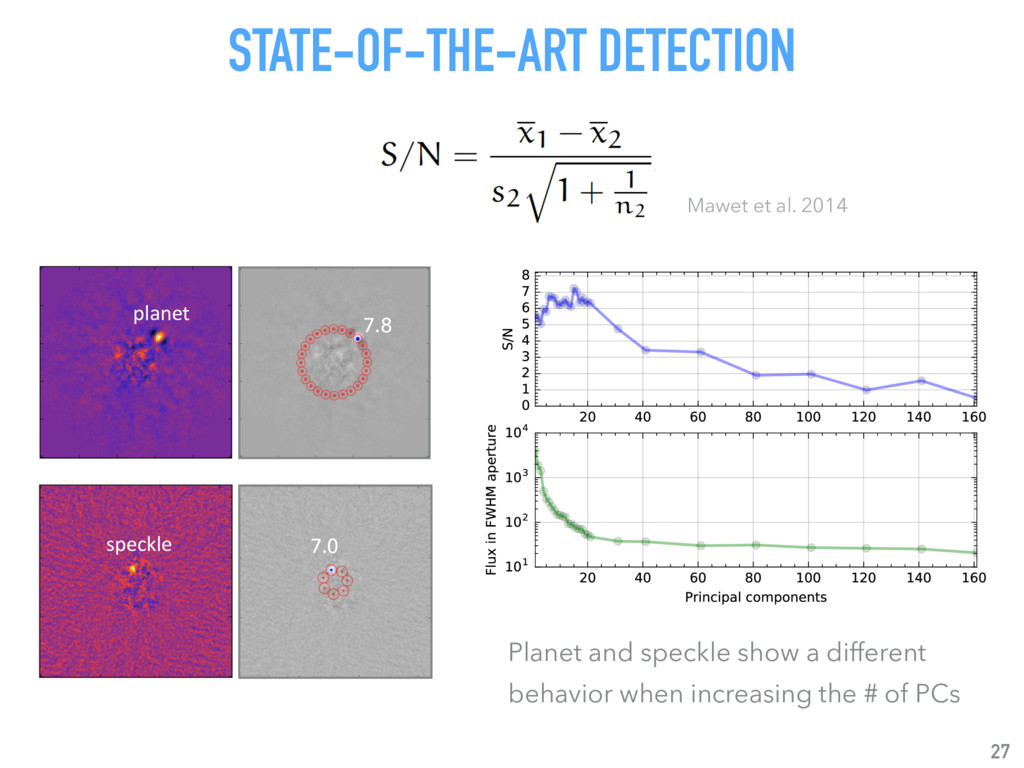
27 7.8 7.0 planet speckle Planet and speckle show a
different behavior when increasing the # of PCs STATE-OF-THE-ART DETECTION Mawet et al. 2014 -
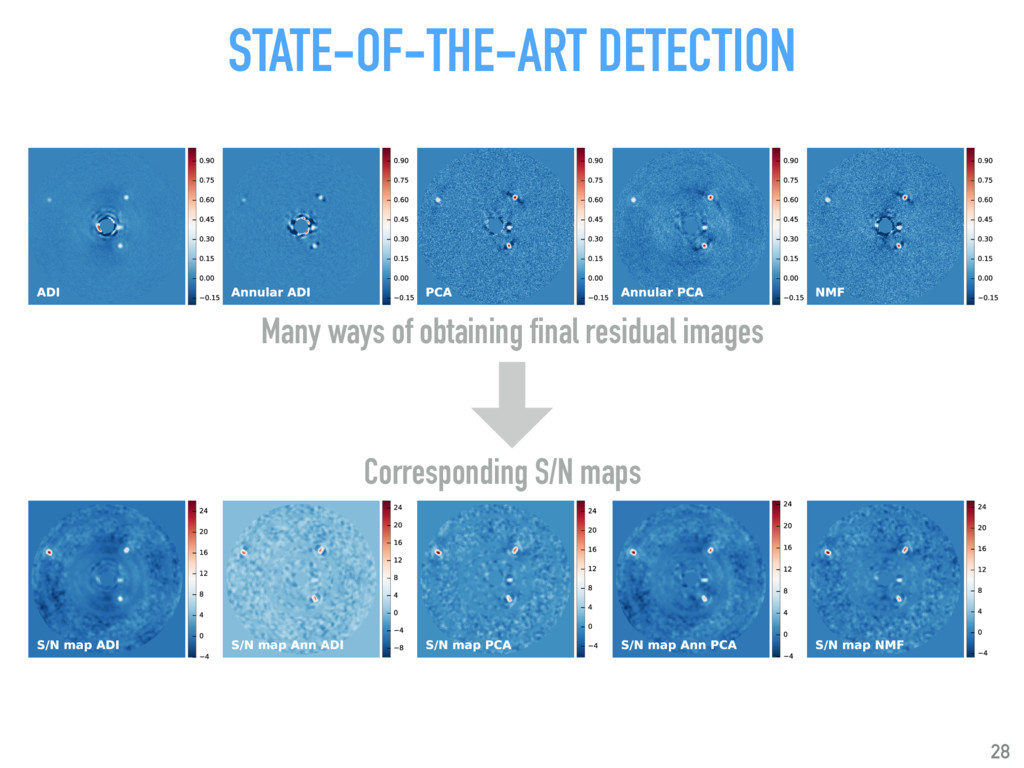
28 Corresponding S/N maps STATE-OF-THE-ART DETECTION Many ways of obtaining
final residual images -
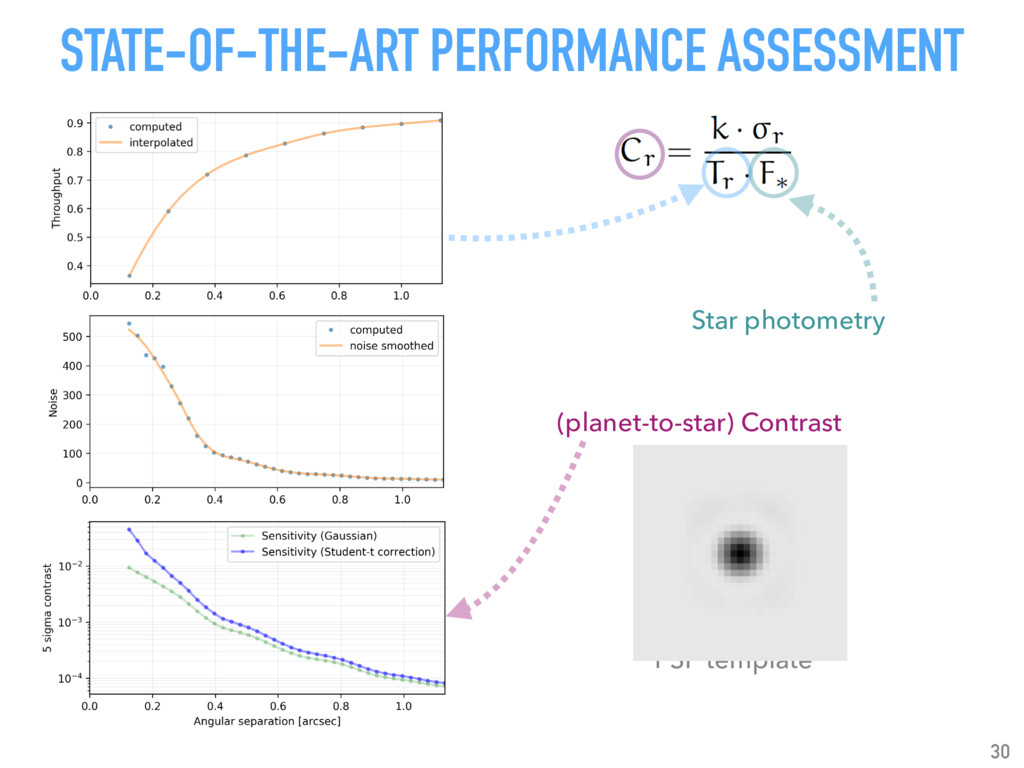
29 STATE-OF-THE-ART PERFORMANCE ASSESSMENT (planet-to-star) Contrast Standard deviation of the
flux in resolution elements -
31 STATE-OF-THE-ART PERFORMANCE ASSESSMENT • 50% completeness as a function
of the separation • Strong assumption about noise statistics (related to the FPR) • Not the best tool for assessing the performance of detection algorithms -
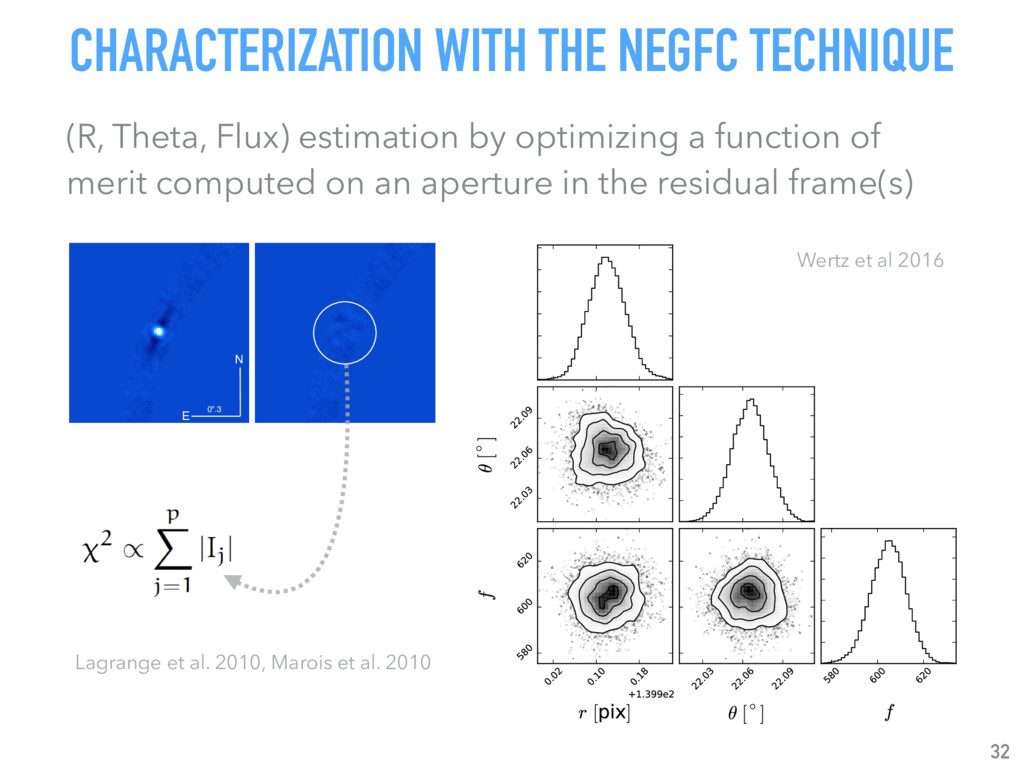
(R, Theta, Flux) estimation by optimizing a function of merit
computed on an aperture in the residual frame(s) 32 CHARACTERIZATION WITH THE NEGFC TECHNIQUE 29 -22 -16 -8.7 -2 4.8 12 18 25 32 3 0".3 E N 29 -22 -16 -8.7 -2 4.8 12 18 25 32 3 Lagrange et al. 2010, Marois et al. 2010 Wertz et al 2016 -
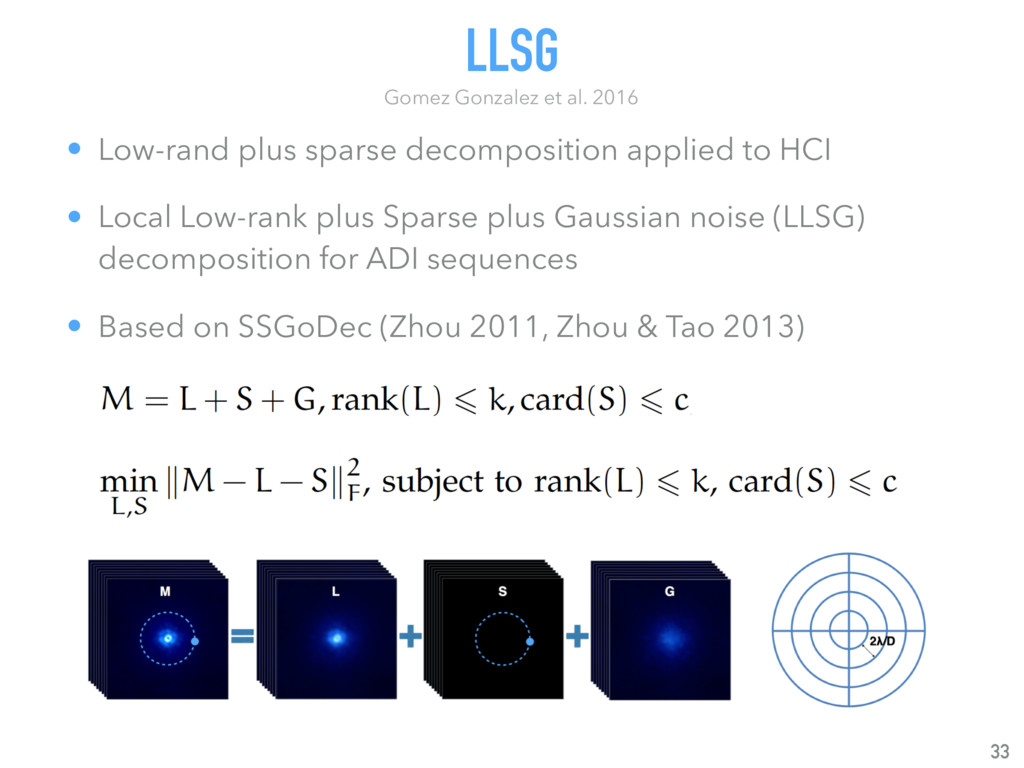
LLSG • Low-rand plus sparse decomposition applied to HCI •
Local Low-rank plus Sparse plus Gaussian noise (LLSG) decomposition for ADI sequences • Based on SSGoDec (Zhou 2011, Zhou & Tao 2013) 33 Gomez Gonzalez et al. 2016 -
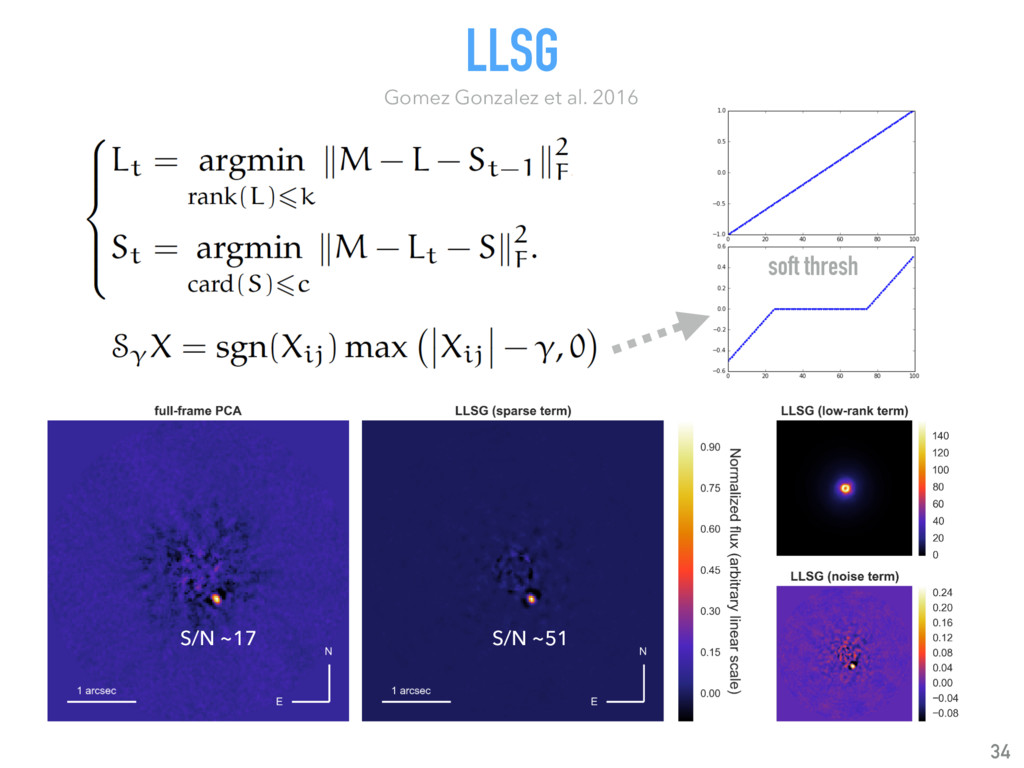
LLSG 34 S/N ~17 S/N ~51 Gomez Gonzalez et al.
2016 soft thresh -
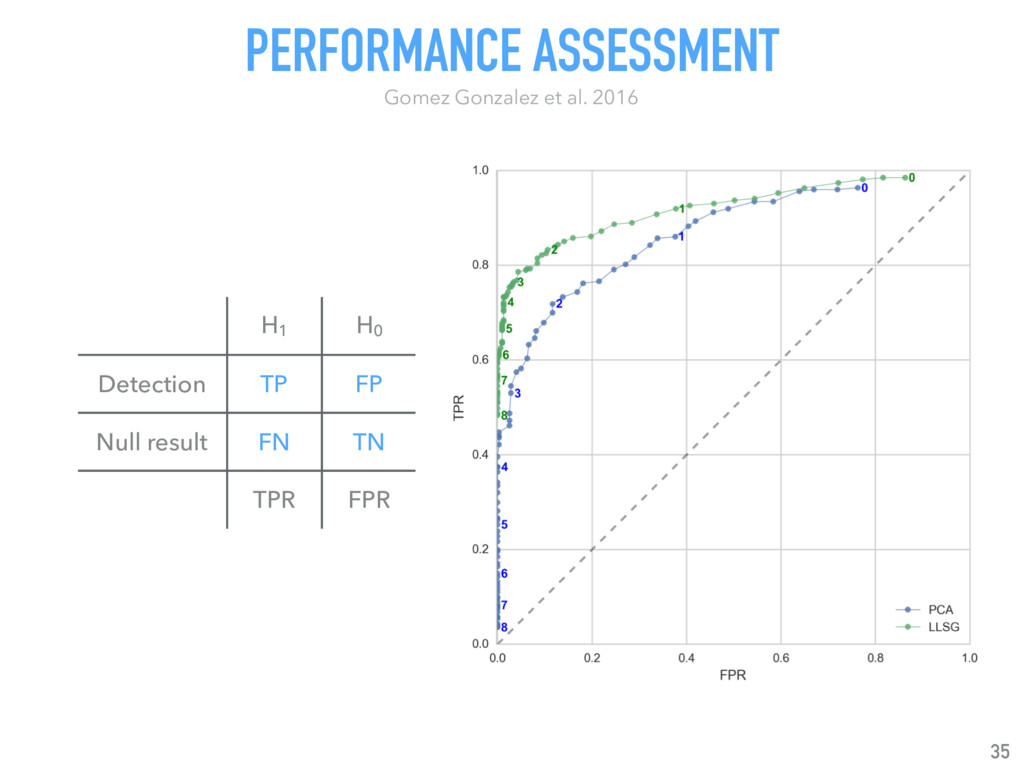
PERFORMANCE ASSESSMENT 35 Gomez Gonzalez et al. 2016 H1 H0
Detection TP FP Null result FN TN TPR FPR -
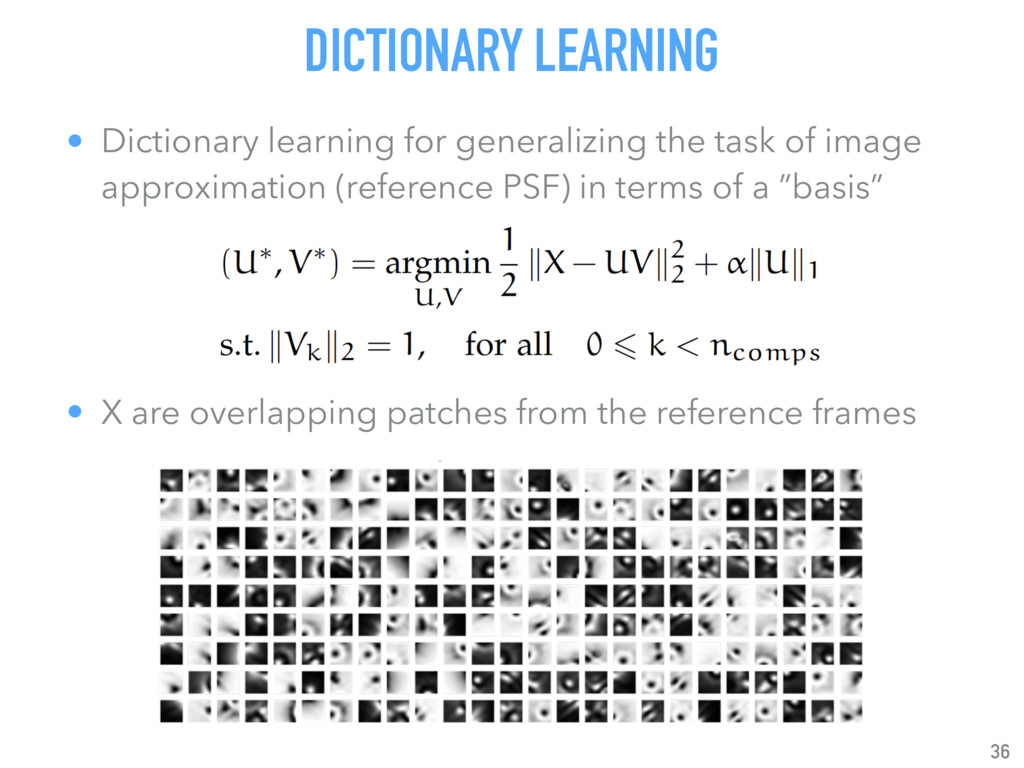
DICTIONARY LEARNING • Dictionary learning for generalizing the task of
image approximation (reference PSF) in terms of a ”basis” 36 Dictionary • X are overlapping patches from the reference frames -
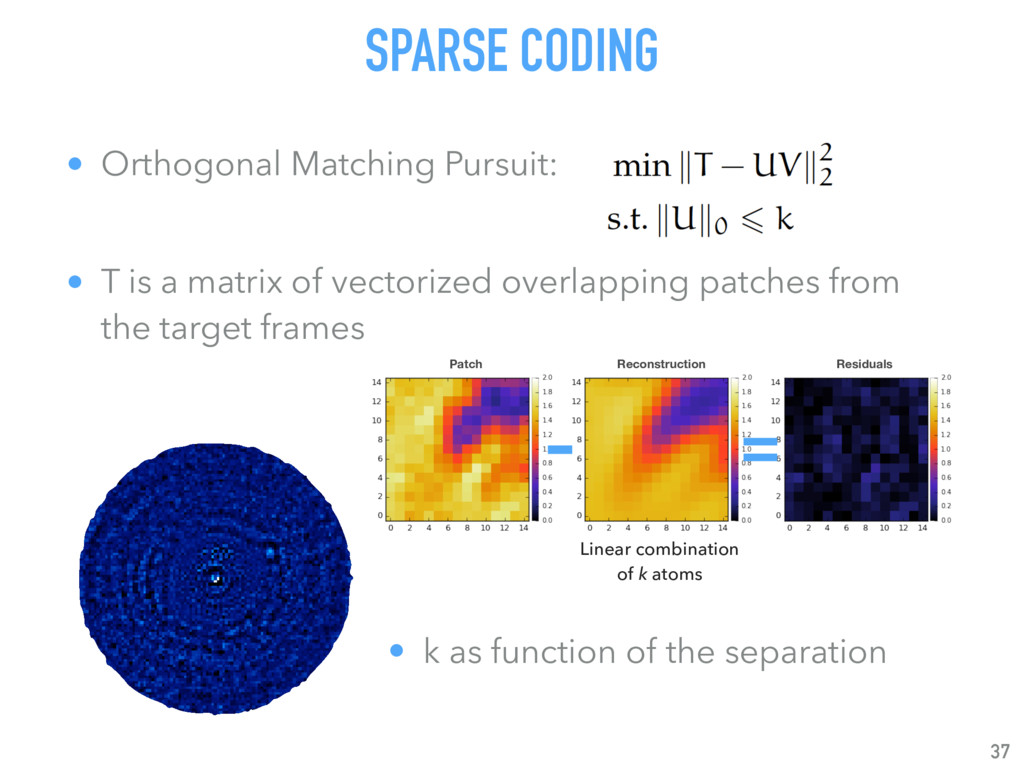
(c) • Orthogonal Matching Pursuit: • T is a matrix
of vectorized overlapping patches from the target frames SPARSE CODING 37 Patch Reconstruction Residuals Dictionary (b) (a) • k as function of the separation Linear combination of k atoms - = -
3. SUPERVISED LEARNING APPLIED TO HCI a.k.a. detecting exoplanets isn’t
about residual images after all -
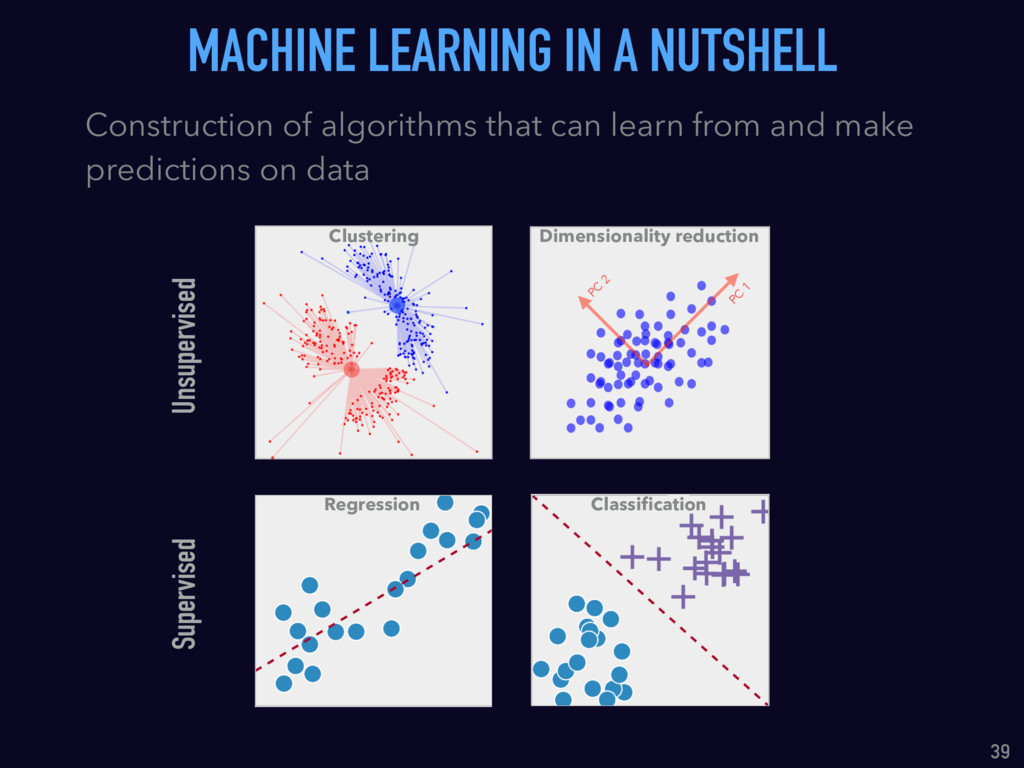
PC 1 PC 2 MACHINE LEARNING IN A NUTSHELL Construction
of algorithms that can learn from and make predictions on data 39 Unsupervised Supervised Regression Classification Dimensionality reduction Clustering -
40 “Essentially, all models are wrong, but some are useful.”
George Box “…if the model is going to be wrong anyway, why not see if you can get the computer to ‘quickly’ learn a model from the data, rather than have a human laboriously derive a model from a lot of thought.” Peter Norvig -
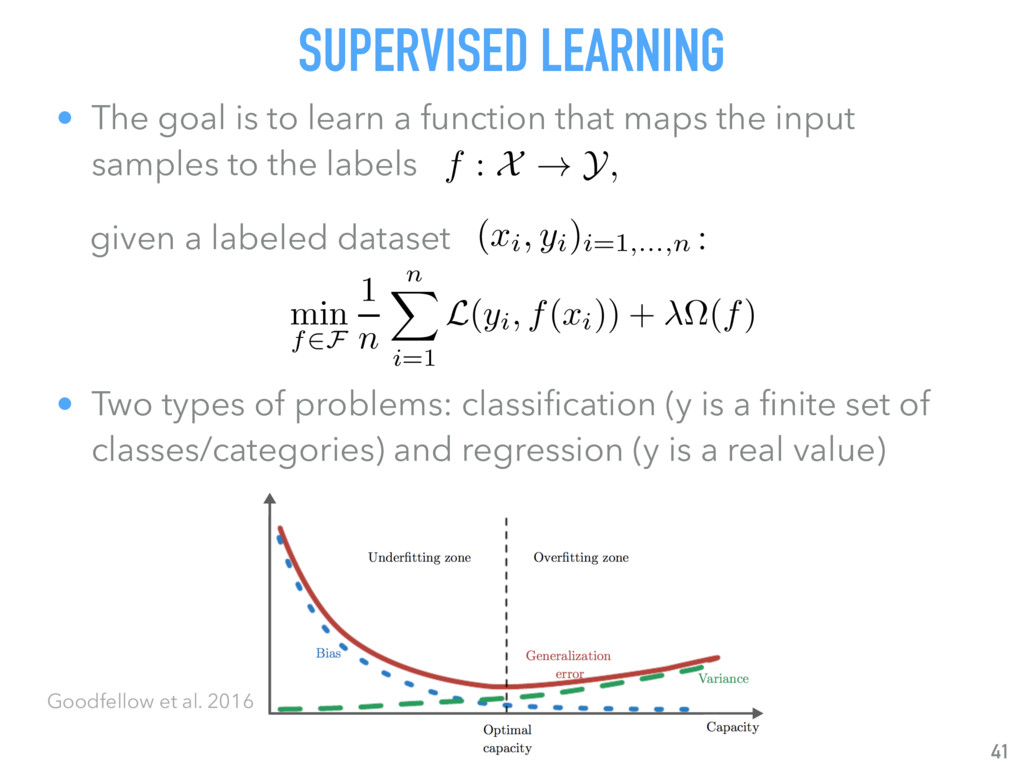
SUPERVISED LEARNING • The goal is to learn a function
that maps the input samples to the labels given a labeled dataset : • Two types of problems: classification (y is a finite set of classes/categories) and regression (y is a real value) 41 min f∈F 1 n n i=1 L(yi, f(xi )) + λΩ(f) f : X → Y, (xi, yi )i=1,...,n Goodfellow et al. 2016 -
DEEP NEURAL NETWORKS 43 Input X 1st Layer (data transformation)
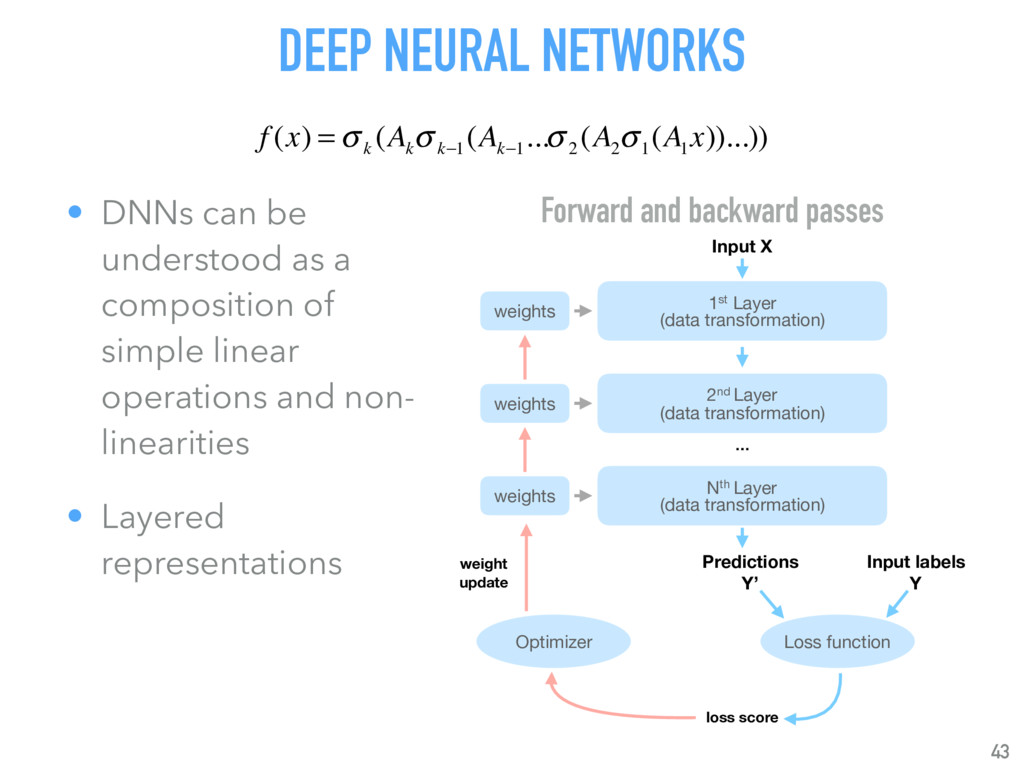
2nd Layer (data transformation) Nth Layer (data transformation) … Predictions Y’ Input labels Y Loss function weights weights weights Optimizer loss score weight update • DNNs can be understood as a composition of simple linear operations and non- linearities • Layered representations Forward and backward passes f (x) = σ k (A k σ k−1 (A k−1 ...σ 2 (A 2 σ 1 (A 1 x))...)) -
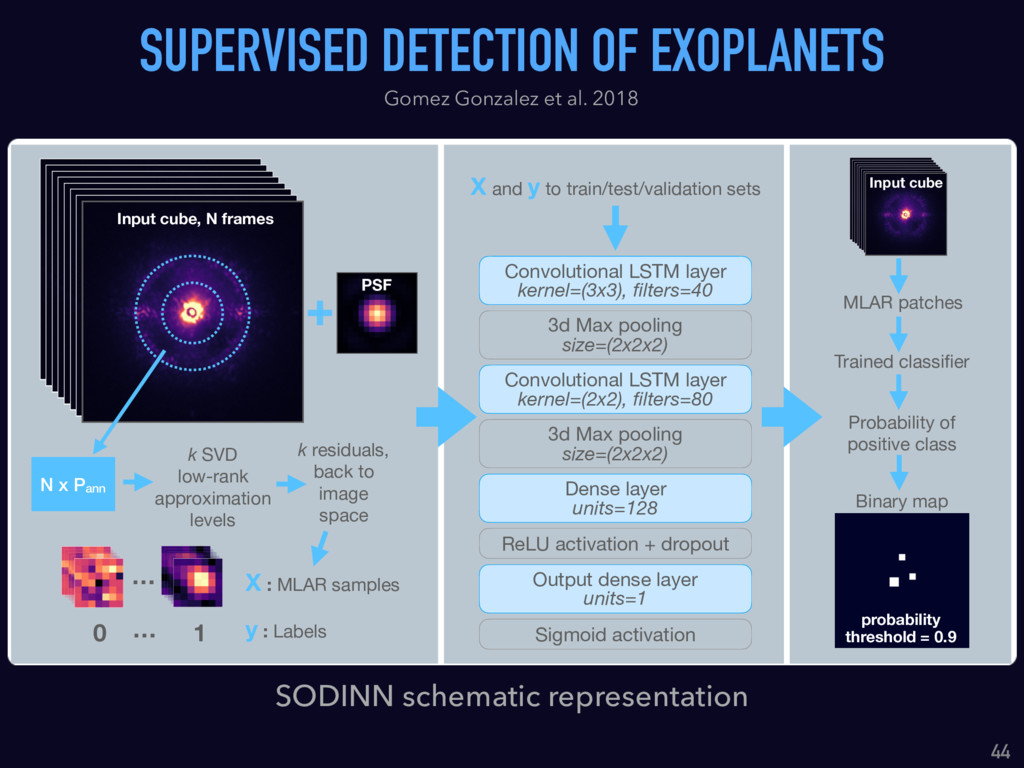
SUPERVISED DETECTION OF EXOPLANETS 44 N x Pann k SVD
low-rank approximation levels k residuals, back to image space X : MLAR samples 0 1 Convolutional LSTM layer kernel=(3x3), filters=40 Convolutional LSTM layer kernel=(2x2), filters=80 Dense layer units=128 Output dense layer units=1 3d Max pooling size=(2x2x2) 3d Max pooling size=(2x2x2) ReLU activation + dropout Sigmoid activation X and y to train/test/validation sets Probability of positive class MLAR patches Binary map probability threshold = 0.9 Trained classifier PSF Input cube, N frames Input cube y : Labels … … (a) (b) (c) Gomez Gonzalez et al. 2018 SODINN schematic representation -
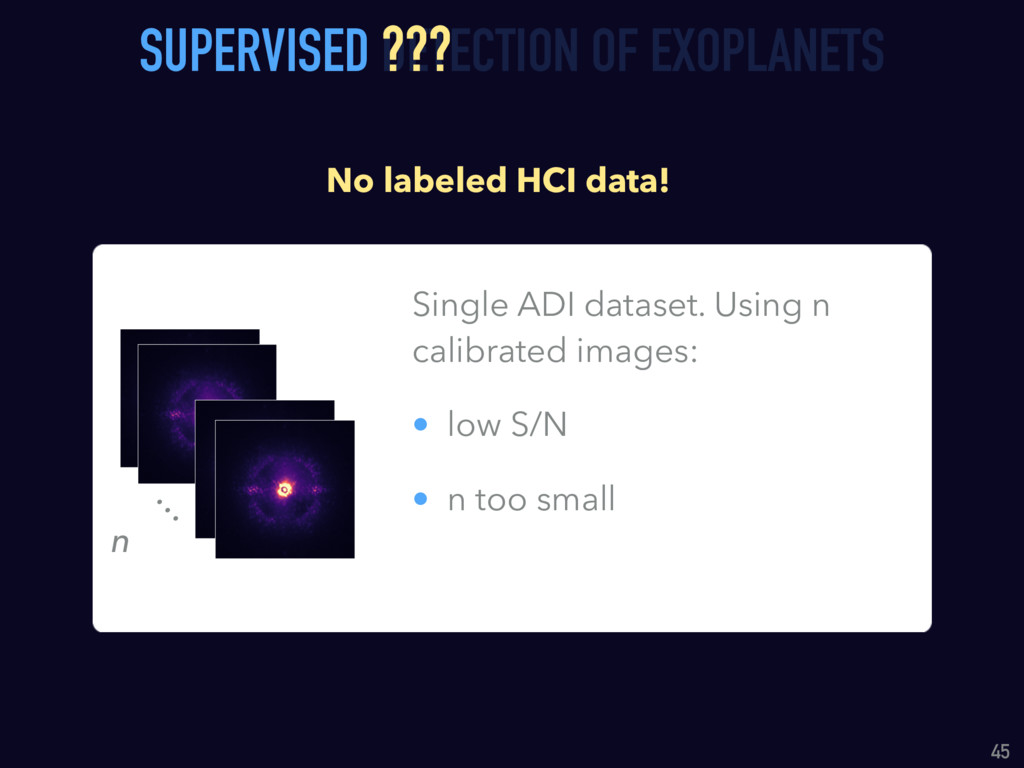
45 N x Pann k SVD low-rank approximation levels k
residuals, back to image space X : MLAR samples 0 1 Convolutional LSTM layer kernel=(3x3), filters=40 Convolutional LSTM layer kernel=(2x2), filters=80 Dense layer units=128 Output dense layer units=1 3d Max pooling size=(2x2x2) 3d Max pooling size=(2x2x2) ReLU activation + dropout Sigmoid activation X and y to train/test/validation sets Probability of positive class MLAR patches Binary map probability threshold = 0.9 Trained classifier PSF Input cube, N frames Input cube y : Labels … … (a) (b) (c) SUPERVISED DETECTION OF EXOPLANETS ??? n No labeled HCI data! Single ADI dataset. Using n calibrated images: • low S/N • n too small … -
46 N x Pann k SVD low-rank approximation levels k
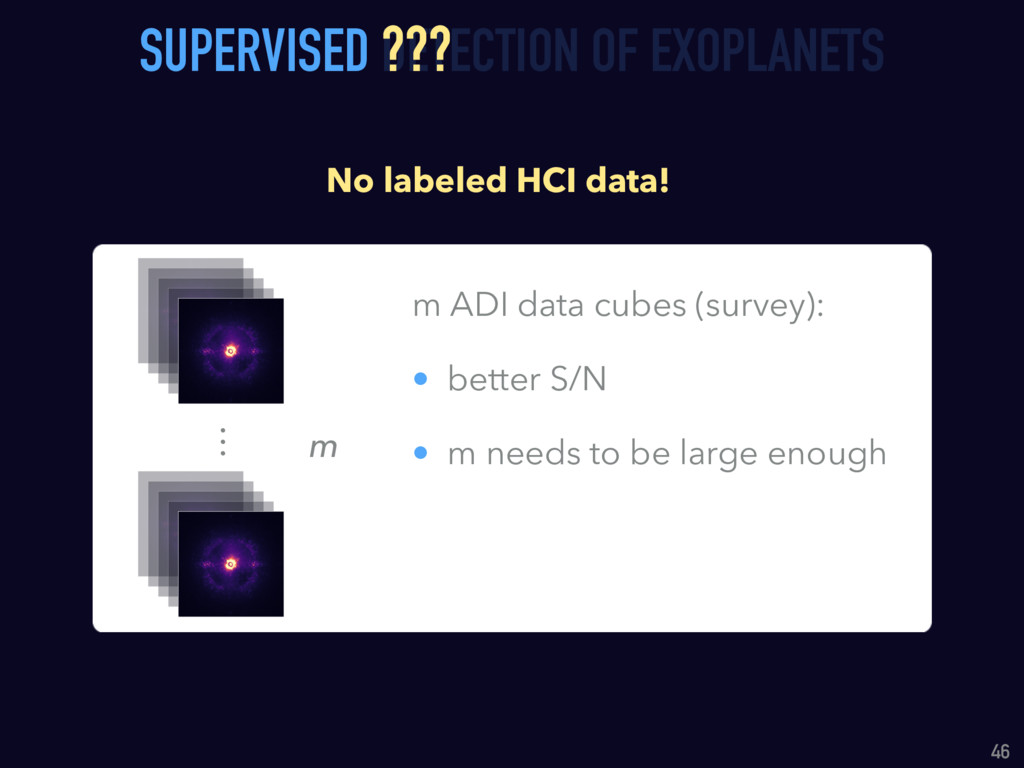
residuals, back to image space X : MLAR samples 0 1 Convolutional LSTM layer kernel=(3x3), filters=40 Convolutional LSTM layer kernel=(2x2), filters=80 Dense layer units=128 Output dense layer units=1 3d Max pooling size=(2x2x2) 3d Max pooling size=(2x2x2) ReLU activation + dropout Sigmoid activation X and y to train/test/validation sets Probability of positive class MLAR patches Binary map probability threshold = 0.9 Trained classifier PSF Input cube, N frames Input cube y : Labels … … (a) (b) (c) SUPERVISED DETECTION OF EXOPLANETS ??? m No labeled HCI data! m ADI data cubes (survey): • better S/N • m needs to be large enough … -
47 N x Pann k SVD low-rank approximation levels k
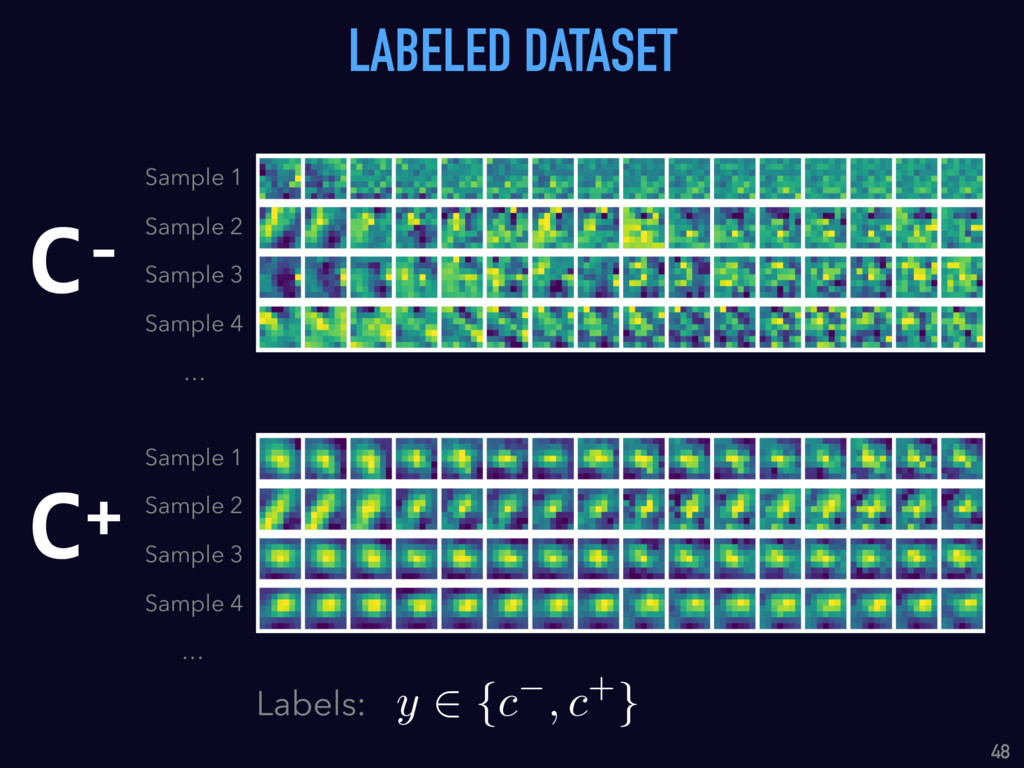
residuals, back to image space X : MLAR samples 0 1 Convolutional LSTM layer kernel=(3x3), filters=40 Convolutional LSTM layer kernel=(2x2), filters=80 Dense layer units=128 Output dense layer units=1 3d Max pooling size=(2x2x2) 3d Max pooling size=(2x2x2) ReLU activation + dropout Sigmoid activation X and y to train/test/validation sets Probability of positive class MLAR patches Binary map probability threshold = 0.9 Trained classifier PSF Input cube, N frames Input cube y : Labels … … (a) (b) (c) GENERATING A LABELED DATASET Explained variance ratio: Multi-level Low-rank Approximation Residual (MLAR) samples Step 1 ˆ σj 2 i ˆ σi 2 M ∈ Rn×p M = UΣV T = n i=1 σiuivT i res = M − MBT k Bk -
LABELED DATASET 48 (a) (b) (a) (b) Labels: C+ C-
y ∈ {c−, c+} Sample 1 Sample 2 Sample 3 Sample 4 Sample 1 Sample 2 Sample 3 Sample 4 … … -
N x Pann k SVD low-rank approximation levels k residuals,
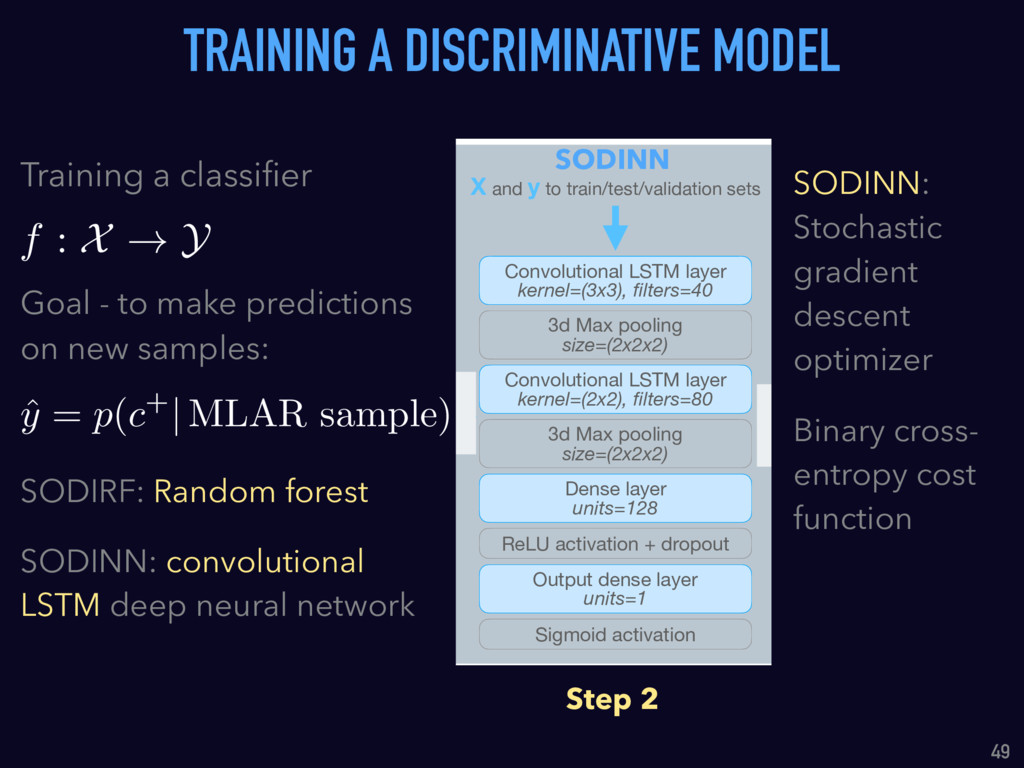
back to image space X : MLAR samples 0 1 Convolutional LSTM layer kernel=(3x3), filters=40 Convolutional LSTM layer kernel=(2x2), filters=80 Dense layer units=128 Output dense layer units=1 3d Max pooling size=(2x2x2) 3d Max pooling size=(2x2x2) ReLU activation + dropout Sigmoid activation X and y to train/test/validation sets Probability of positive class MLAR patches Binary map probability threshold = 0.9 Trained classifier PSF Input cube, N frames Input cube y : Labels … … (a) (b) (c) SODIRF: Random forest SODINN: convolutional LSTM deep neural network TRAINING A DISCRIMINATIVE MODEL 49 Step 2 Goal - to make predictions on new samples: SODINN: Stochastic gradient descent optimizer Binary cross- entropy cost function Training a classifier f : X → Y ˆ y = p(c+| MLAR sample) SODINN -
N x Pann k SVD low-rank approximation levels k residuals,
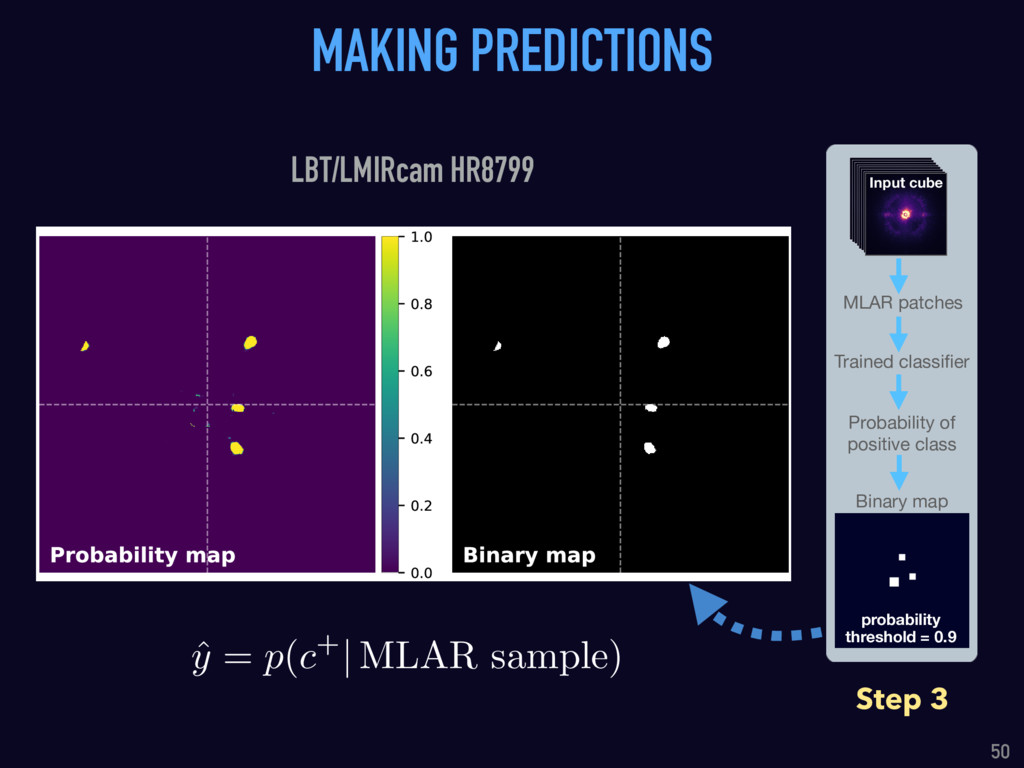
back to image space X : MLAR samples 0 1 Convolutional LSTM layer kernel=(3x3), filters=40 Convolutional LSTM layer kernel=(2x2), filters=80 Dense layer units=128 Output dense layer units=1 3d Max pooling size=(2x2x2) 3d Max pooling size=(2x2x2) ReLU activation + dropout Sigmoid activation X and y to train/test/validation sets Probability of positive class MLAR patches Binary map probability threshold = 0.9 Trained classifier PSF Input cube, N frames Input cube y : Labels … … (a) (b) (c) MAKING PREDICTIONS 50 Step 3 LBT/LMIRcam HR8799 ˆ y = p(c+| MLAR sample) -
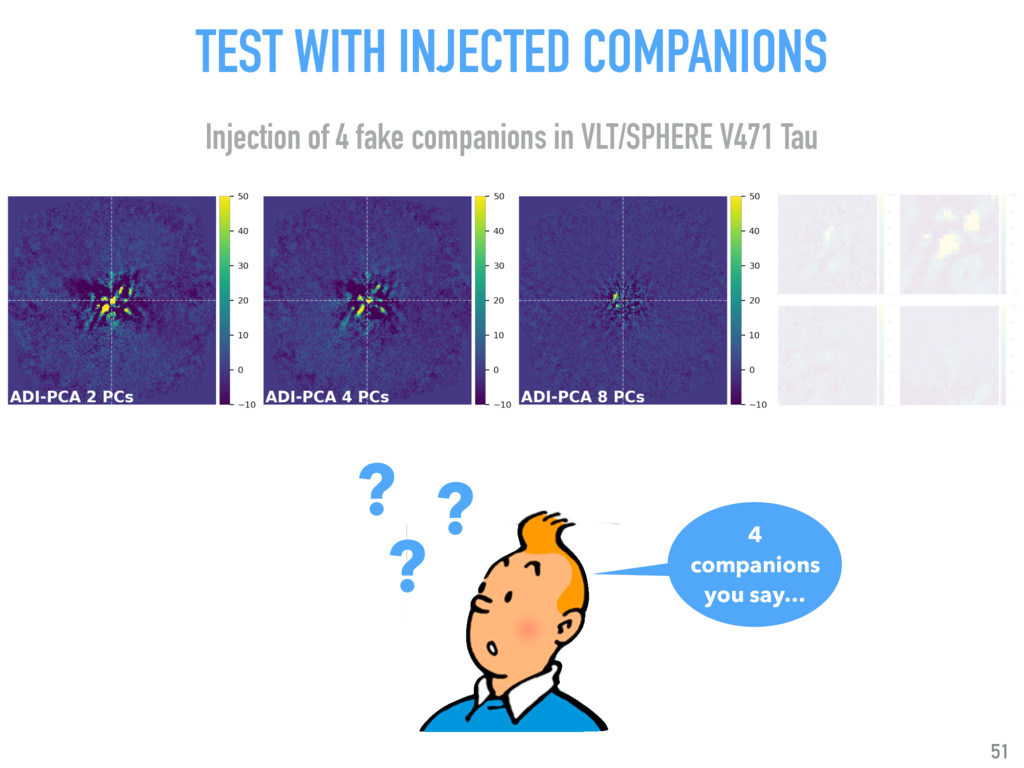
TEST WITH INJECTED COMPANIONS 51 Injection of 4 fake companions
in VLT/SPHERE V471 Tau ? 4 companions you say… ? ? -
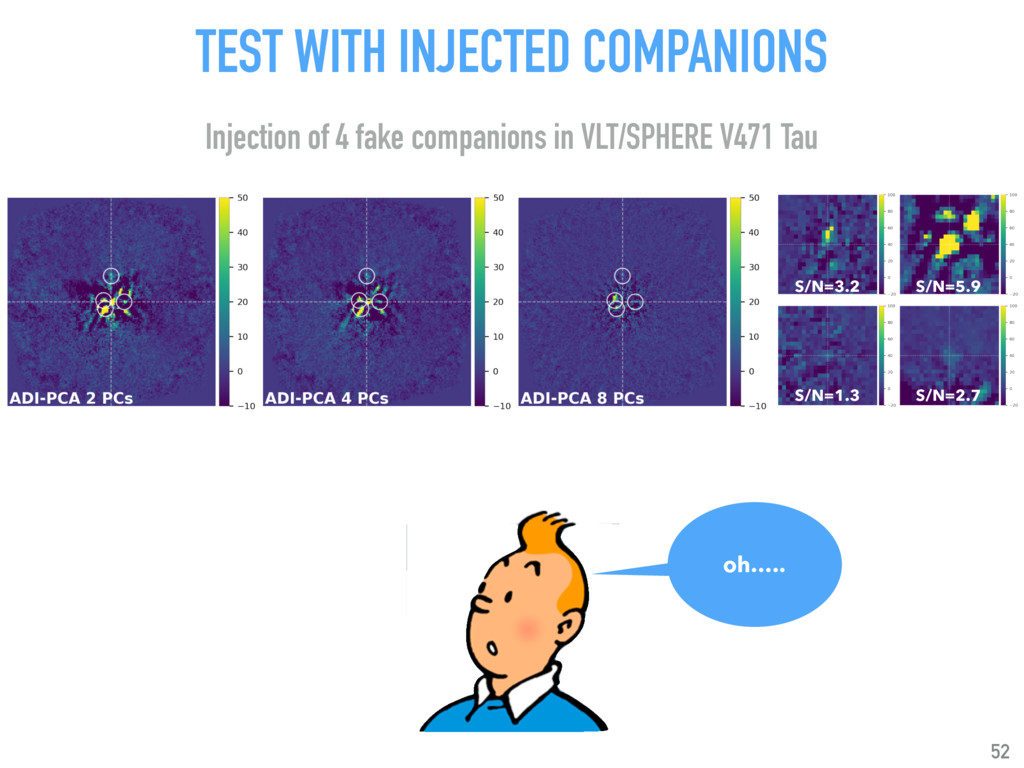
52 (a) (b) (c) (d) Injection of 4 fake companions
in VLT/SPHERE V471 Tau S/N=3.2 S/N=5.9 S/N=1.3 S/N=2.7 TEST WITH INJECTED COMPANIONS oh….. -
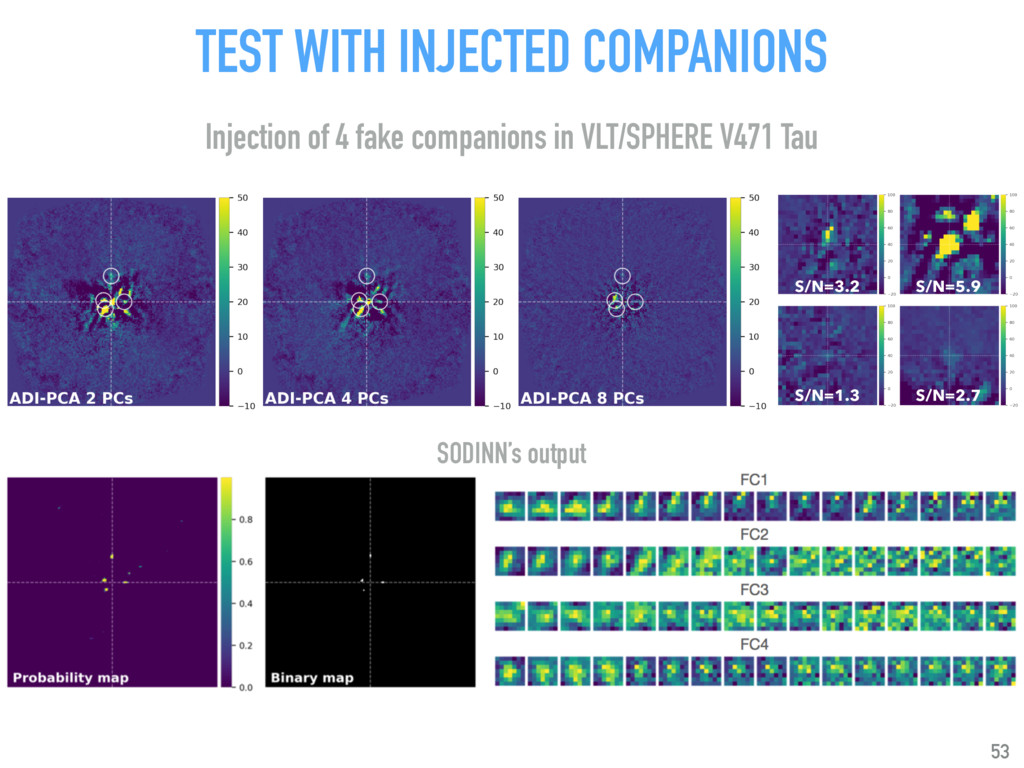
53 (a) (b) (c) (d) Injection of 4 fake companions
in VLT/SPHERE V471 Tau SODINN’s output S/N=3.2 S/N=5.9 S/N=1.3 S/N=2.7 TEST WITH INJECTED COMPANIONS -
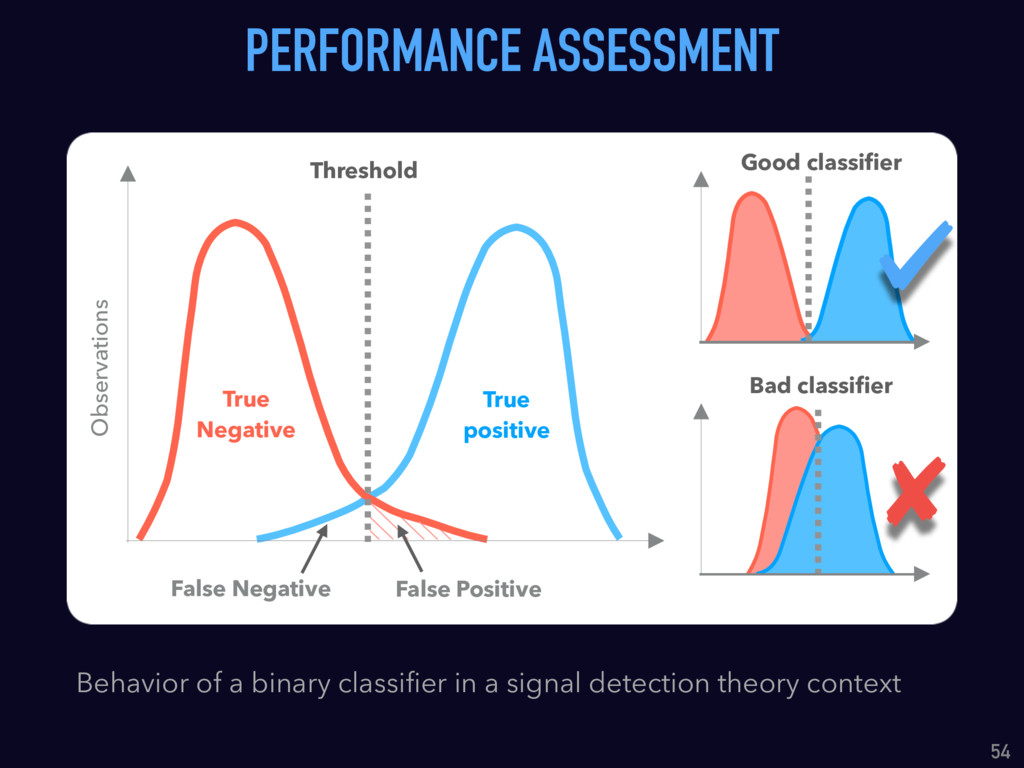
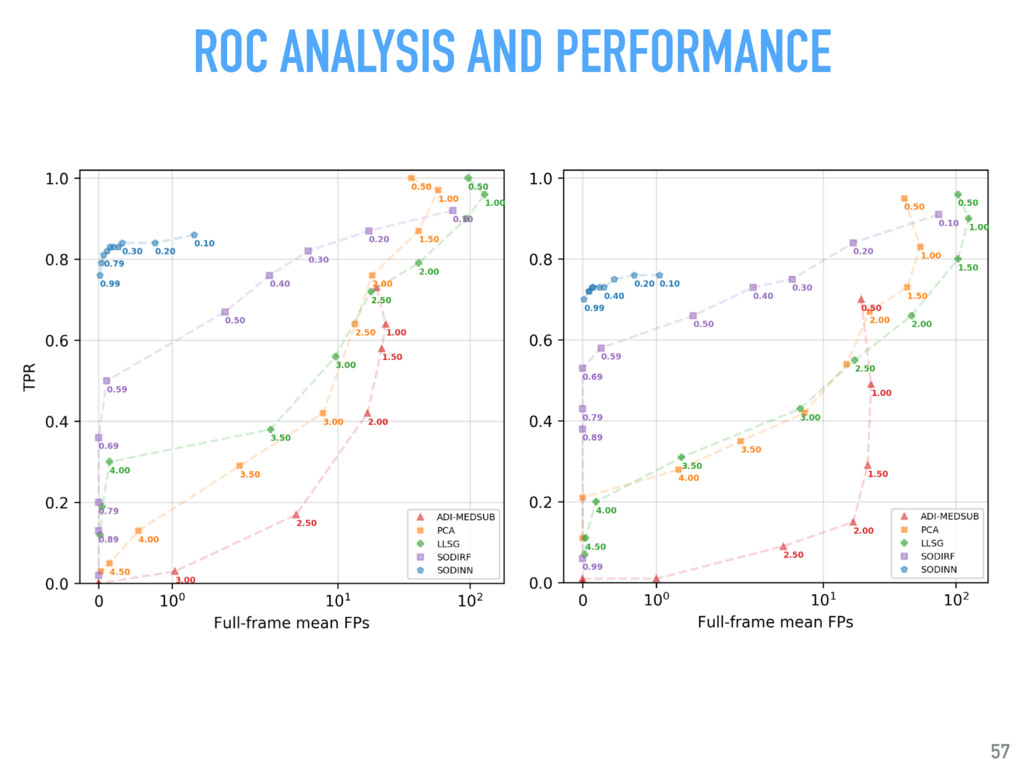
54 PERFORMANCE ASSESSMENT Good classifier True positive True Negative Threshold
False Negative False Positive Observations Bad classifier Behavior of a binary classifier in a signal detection theory context -
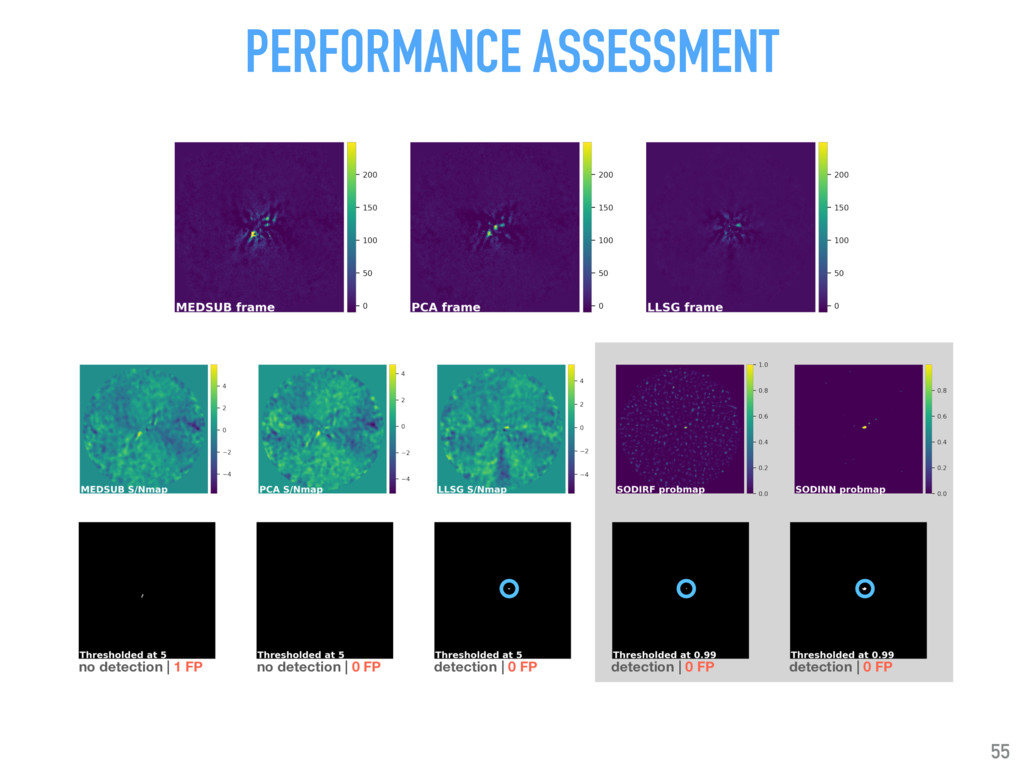
PERFORMANCE ASSESSMENT 55 (a) (b) (c) no detection | 1
FP no detection | 0 FP detection | 0 FP detection | 0 FP detection | 0 FP (a) (b) (c) no detection | 1 FP no detection | 0 FP detection | 0 FP detection | 0 FP detection | 0 FP -
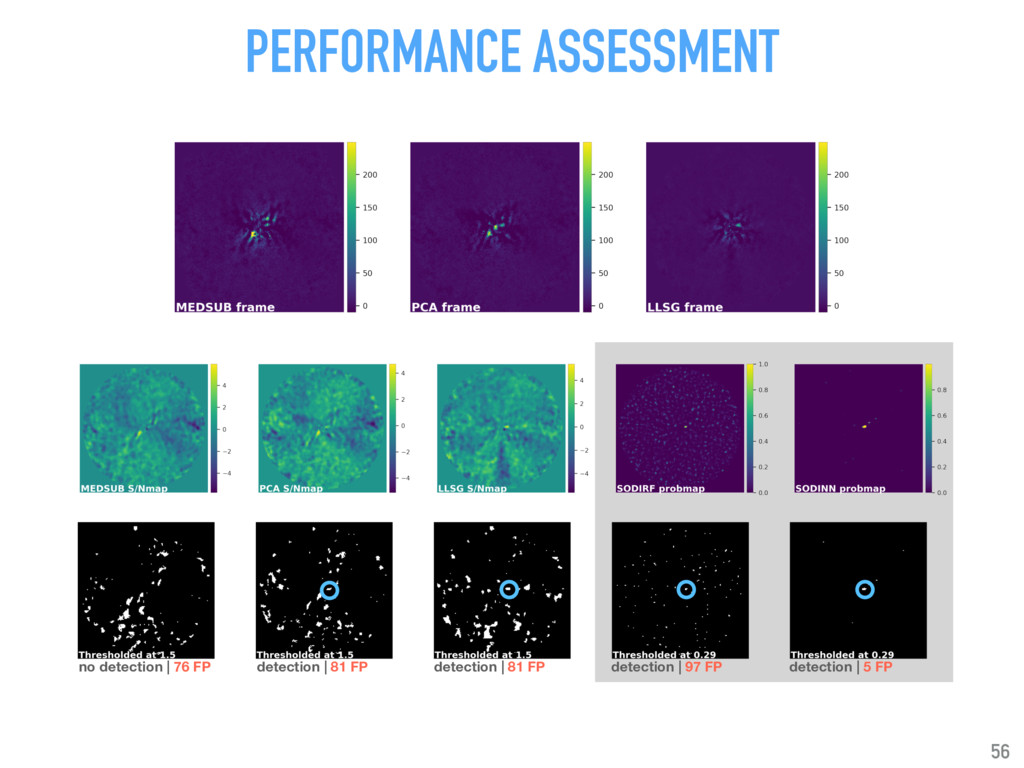
56 (a) (b) (c) no detection | 1 FP no
detection | 0 FP detection | 0 FP detection | 0 FP detection | 0 FP PERFORMANCE ASSESSMENT (b) (c) (d) no detection | 1 FP no detection | 0 FP detection | 0 FP detection | 0 FP detection | 0 FP no detection | 76 FP detection | 81 FP detection | 81 FP detection | 97 FP detection | 5 FP (e) no detection | 4 FP no detection | 4 FP detection | 7 FP detection | 5 FP detection | 2 FP -
60 PERSPECTIVES • Construction of a benchmark HCI datasets •
Community and Kaggle-like data challenges • Improving SODINN: • lighter DNN architecture • include flux and sub-px into the model • extend to ADI+SDI • avoid patches (on full images) • new (cheaper) labeled data generation strategy • extended structures (disks) • Application of more ML methods to HCI • Detecting through HCI an Earth-like exoplanet -
Transforming science: • Cross and inter-disciplinary research (collaboration with CS,
ML, AI fields) • Ensuring the use of robust statistical approaches and well- suited metrics • Integrating cutting-edge AI developments • Code release (open-source development) • Knowledge sharing (non-refereed publications) • Data challenges & benchmark datasets (ACADEMIC) DATA SCIENCE 61