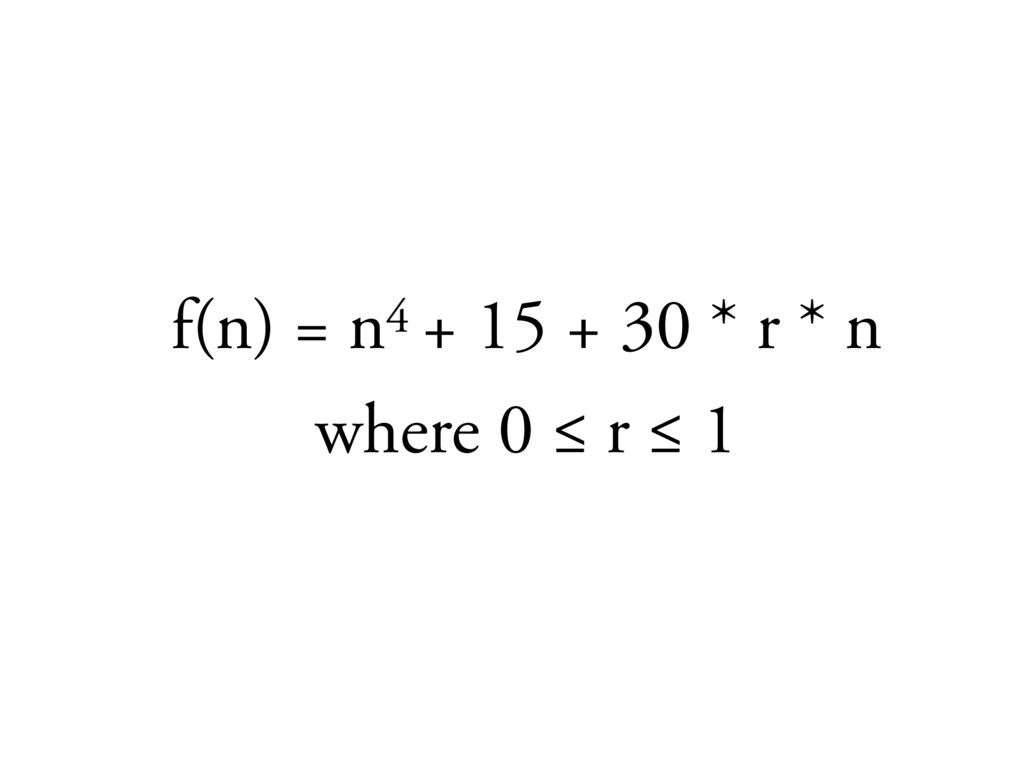Share
Embed
Transcript
36 slides
-
GenStage in Practice Evadne Wu github.com/evadne [email protected] // @evadne last
updated 24 January 2018 -
Me Programmer ➤ Primary languages: Elixir & C/Obj-C ➤ Day
job: Head of Exam Systems @ Faria Education Group ➤ Managed Services (for customers) ➤ Internal Components (for other teams) ➤ UK based team of 3 -
Our Use Case 2.5m documents in legacy solution which goes
EOL in 2 weeks. Replacement system is ready, but still waiting for data load. We need a migration pipeline that works quickly, so in case of mishaps, we can re-run the whole migration multiple times. (Subtext: spending less time preserves optionality.) -
Interim Solutions 1st Solution: Single-threaded Ruby migrator 2nd Solution: Ruby
migrator with Sidekiq, 48 cores 3rd Solution: Ruby migrator as SQS consumer, 100+ cores -
Problems Low Performance due to additional overhead in handling API
tokens, HTTPS traffic, marshalling/un-marshalling, etc. Threading Problems in Ruby… (which requires no further explanation) No Coordinated Rollbacks when migration fails partially; if the code crashes before it hits the deletion handler, there will be no deletion. Inherent Complexity in the legacy service which forced us to push every single document through a Headless Chrome process to extract JSONs -
Non-Problems Lack of Observability by spreading ingestion across 2 services.
This means an additional Web UI to build just so progress can be monitored! -
Final Solution Elixir in Anger! Our replacement service is already
written in Elixir, so theoretically, by conducting the entire ingestion process within our service as a separate module, we could eliminate problems #1, #2 and #3. Also replaced the roundtrip to/from Headless Chrome with a small regex which sped things up quite a lot. New Importer does the same thing in 320 lines of Elixir code. -
with \ {:ok, %{body: body}} <- HTTPoison.get(url), [{"script", _, [content]}]
<- Floki.find(body, "script:last-child"), [_, json] <- Regex.run(regex, content), {:ok, objects} = Poison.decode(json) do {:ok, objects} end -
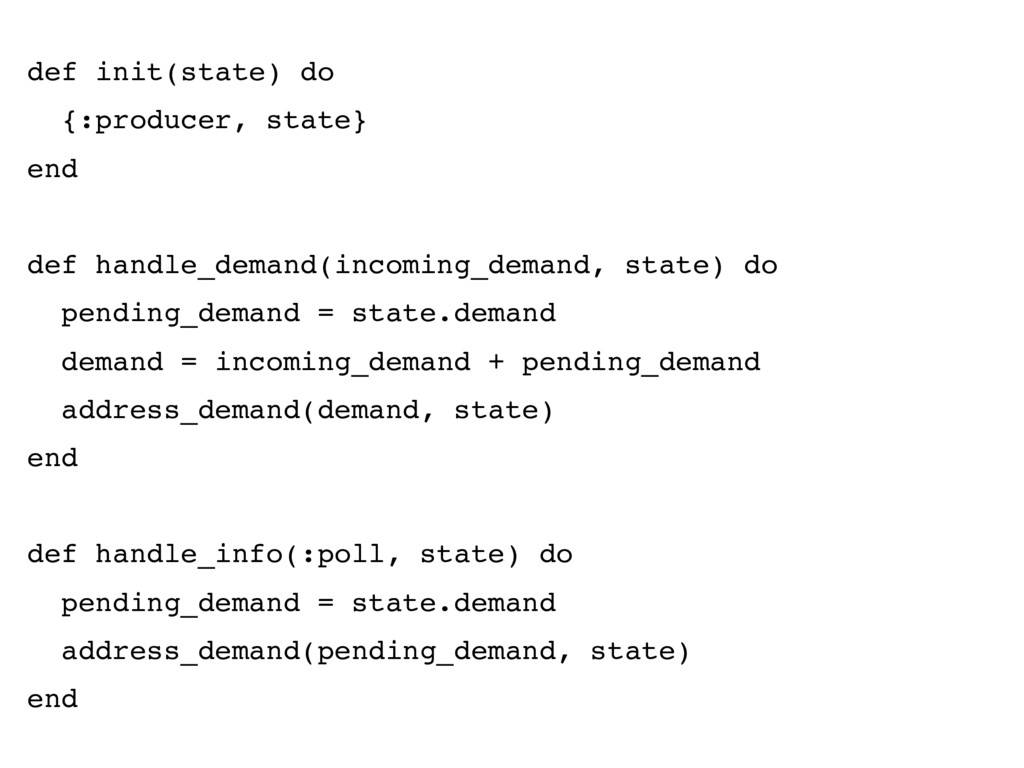
Polling Producer GenStage Producers always fulfil demand based on consumer
status. Pitfall: when the queue is emptied but there is pending demand, the Producer should still periodically check if any pending demand can be fulfilled, hence polling. Without this mechanism processing will cease once all pending demand is fulfilled. -
def init(state) do {:producer, state} end def handle_demand(incoming_demand, state) do
pending_demand = state.demand demand = incoming_demand + pending_demand address_demand(demand, state) end def handle_info(:poll, state) do pending_demand = state.demand address_demand(pending_demand, state) end -
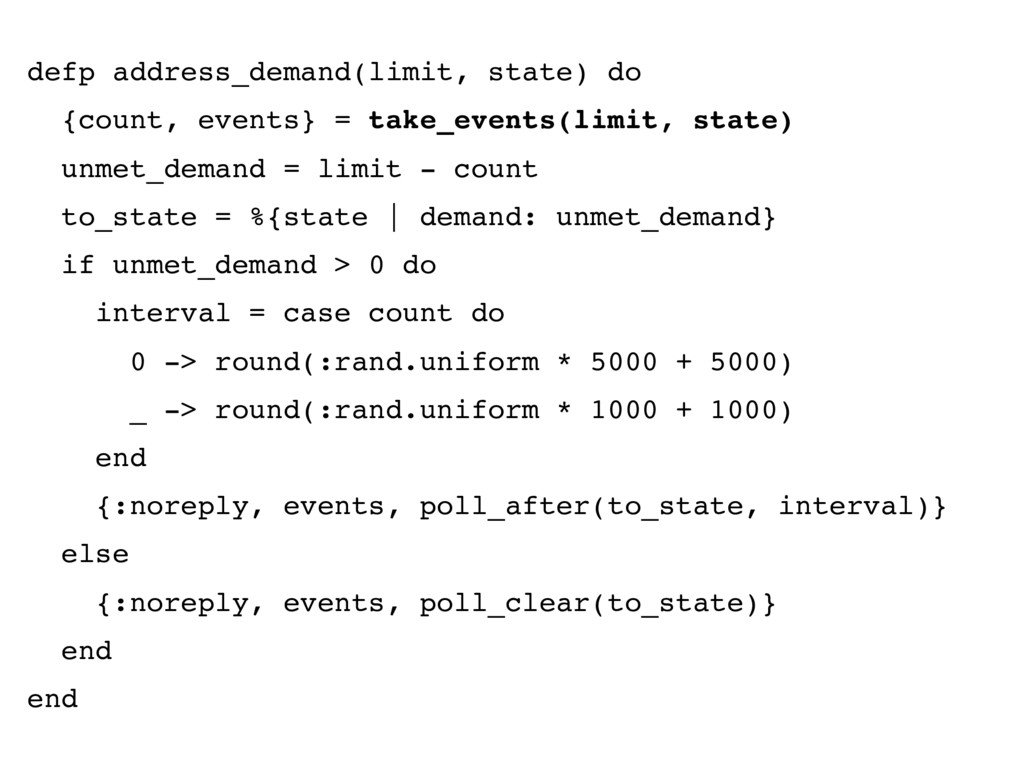
defp address_demand(limit, state) do {count, events} = take_events(limit, state) unmet_demand
= limit - count to_state = %{state | demand: unmet_demand} if unmet_demand > 0 do interval = case count do 0 -> round(:rand.uniform * 5000 + 5000) _ -> round(:rand.uniform * 1000 + 1000) end {:noreply, events, poll_after(to_state, interval)} else {:noreply, events, poll_clear(to_state)} end end -
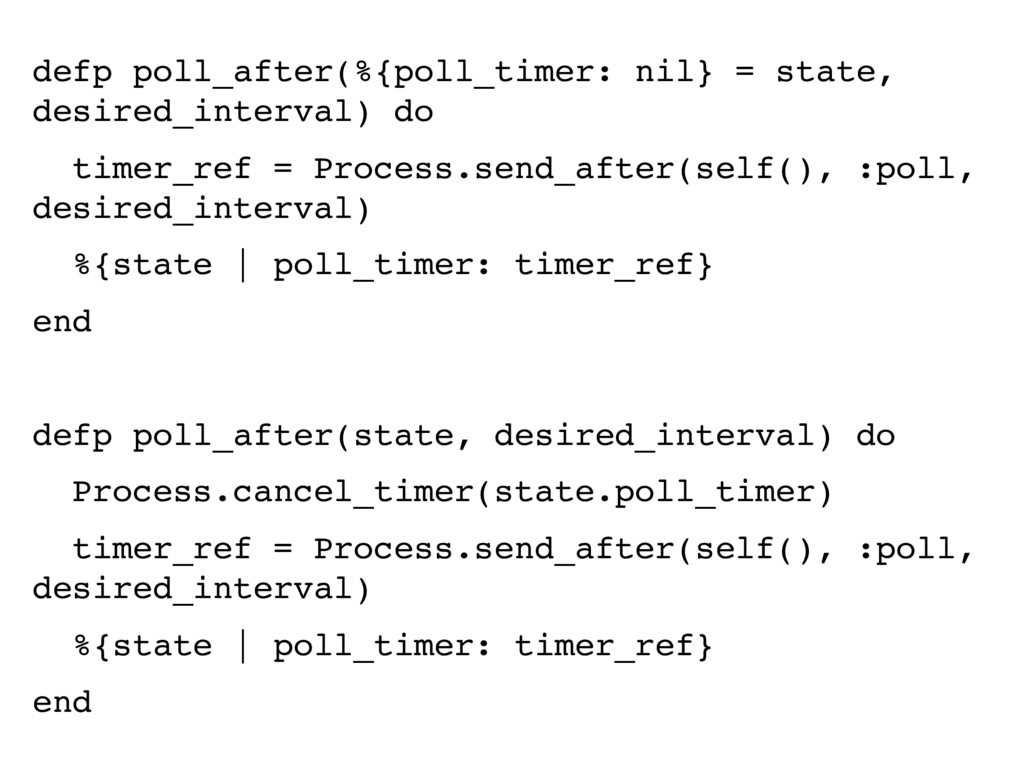
defp poll_after(%{poll_timer: nil} = state, desired_interval) do timer_ref = Process.send_after(self(),
:poll, desired_interval) %{state | poll_timer: timer_ref} end defp poll_after(state, desired_interval) do Process.cancel_timer(state.poll_timer) timer_ref = Process.send_after(self(), :poll, desired_interval) %{state | poll_timer: timer_ref} end -
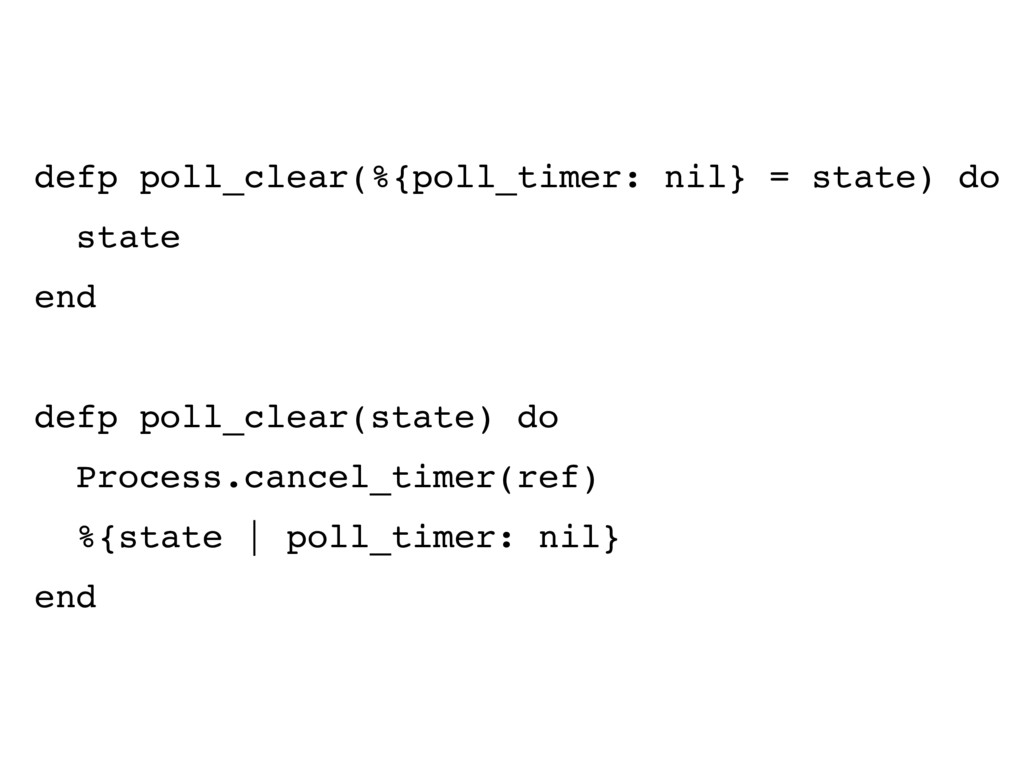
defp poll_clear(%{poll_timer: nil} = state) do state end defp poll_clear(state)
do Process.cancel_timer(ref) %{state | poll_timer: nil} end -
Explanation Address all incoming demand immediately ➤ Precise implementation left
to module user If there is leftover demand that is not fulfilled, start a poll cycle ➤ If none of the demand is fulfilled, poll in 5–10 seconds ➤ If some of the demand is fulfilled, poll in 1–2 seconds Clear existing timer references whenever polling -
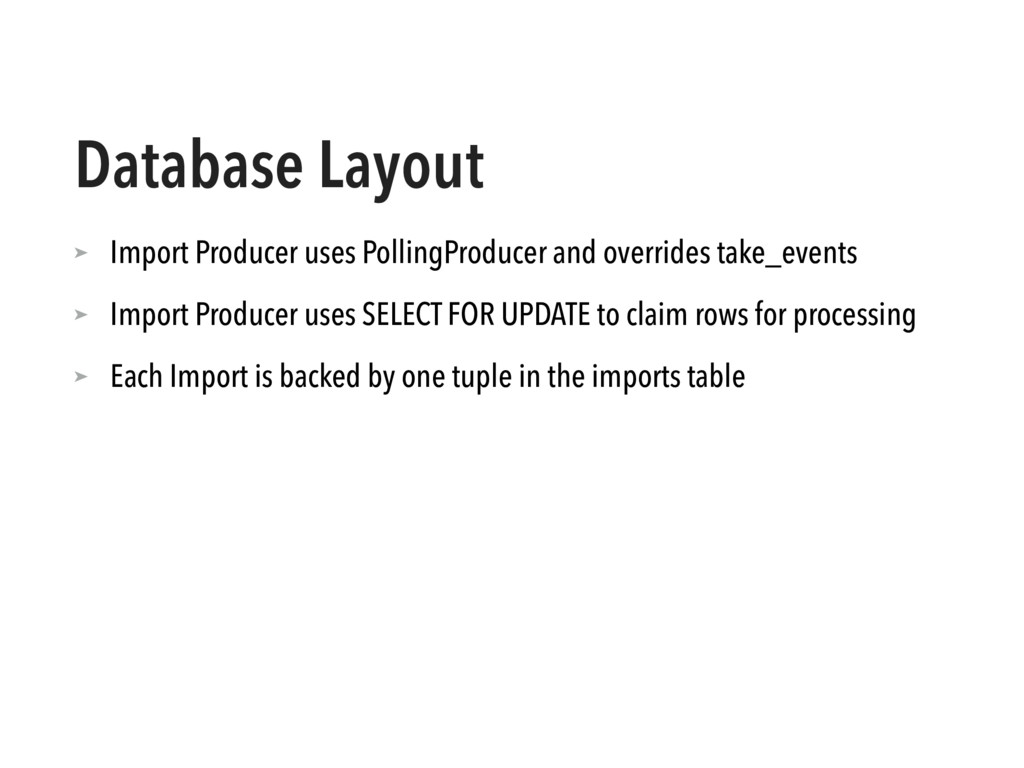
Database Layout ➤ Import Producer uses PollingProducer and overrides take_events
➤ Import Producer uses SELECT FOR UPDATE to claim rows for processing ➤ Each Import is backed by one tuple in the imports table -
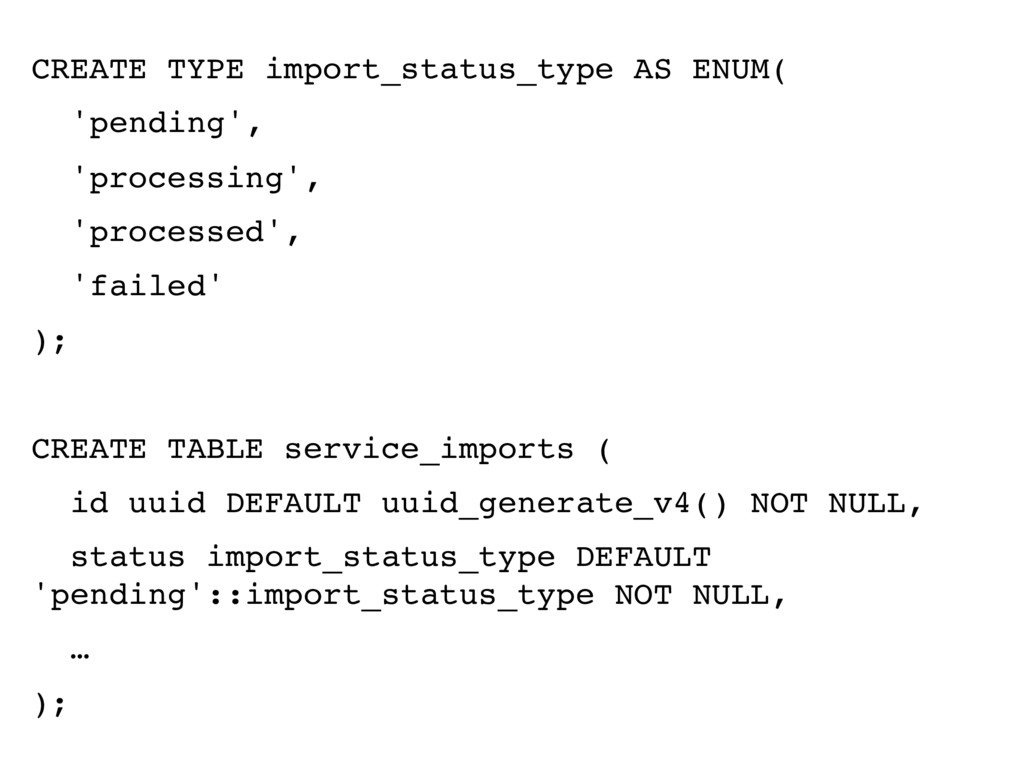
CREATE TYPE import_status_type AS ENUM( 'pending', 'processing', 'processed', 'failed' );
CREATE TABLE service_imports ( id uuid DEFAULT uuid_generate_v4() NOT NULL, status import_status_type DEFAULT 'pending'::import_status_type NOT NULL, … ); -
Retries ➤ Any good task queue will need a way
to handle retires ➤ Essentially, a simple SQL query problem at small scale ➤ Automatic exponential backoff ➤ Plus: automatic revival of dead (stuck) jobs -
f(n) = n4 + 15 + 30 * r *
n where 0 ≤ r ≤ 1 -
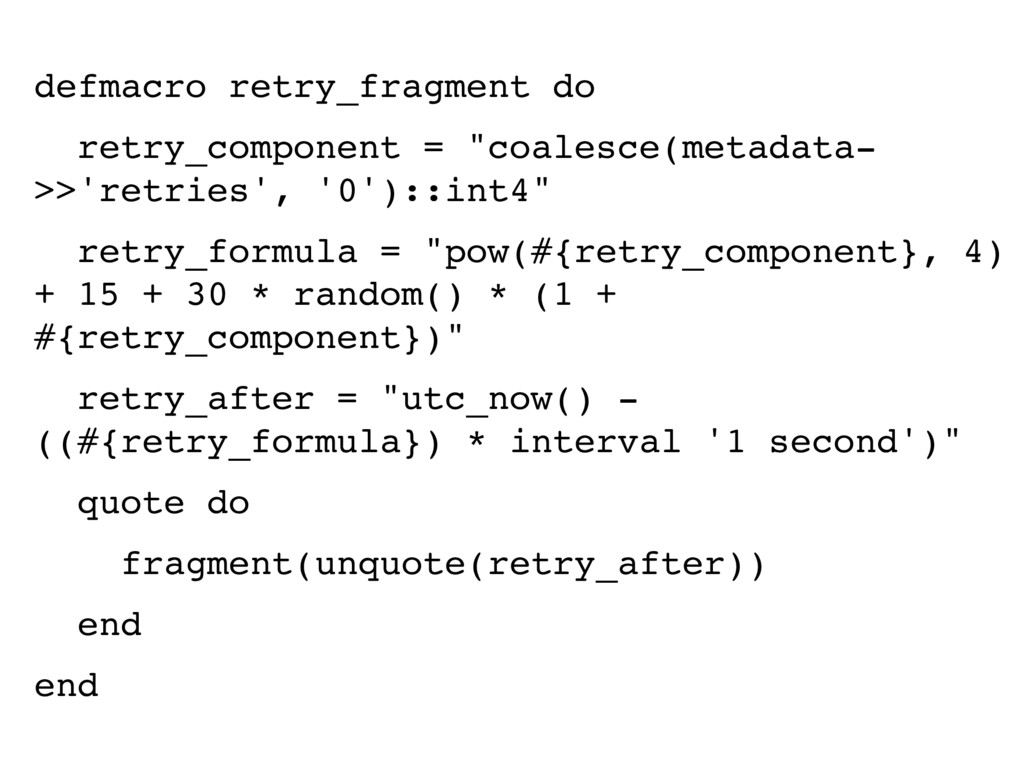
defmacro retry_fragment do retry_component = "coalesce(metadata- >>'retries', '0')::int4" retry_formula =
"pow(#{retry_component}, 4) + 15 + 30 * random() * (1 + #{retry_component})" retry_after = "utc_now() - ((#{retry_formula}) * interval '1 second')" quote do fragment(unquote(retry_after)) end end -
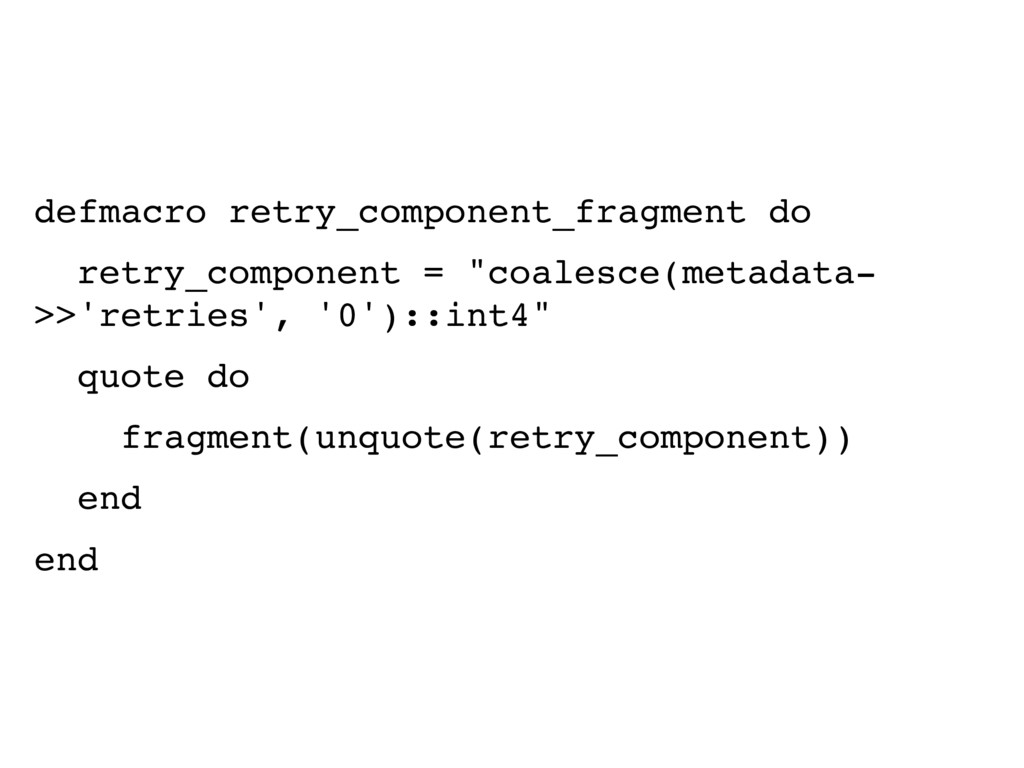
defmacro retry_component_fragment do retry_component = "coalesce(metadata- >>'retries', '0')::int4" quote do
fragment(unquote(retry_component)) end end -
select_query = Model |> where([i], i.status == "pending") |> or_where([i],
i.status == "processing" and i.started_at < fragment("utc_now() - interval '5 minute'")) |> or_where([i], i.status == "failed" and (is_nil(i.ended_at) or i.ended_at < retry_fragment()) and 32 > retry_component_fragment()) |> select([i], i.id) |> limit(^limit) |> lock("FOR UPDATE SKIP LOCKED") -
Repo.transaction(fn -> ids = Repo.all(select_query) update_query = Model |> where([i],
i.id in ^ids) {count, events} = Repo.update_all update_query, [set: [status: "processing"]], [returning: true] end) -
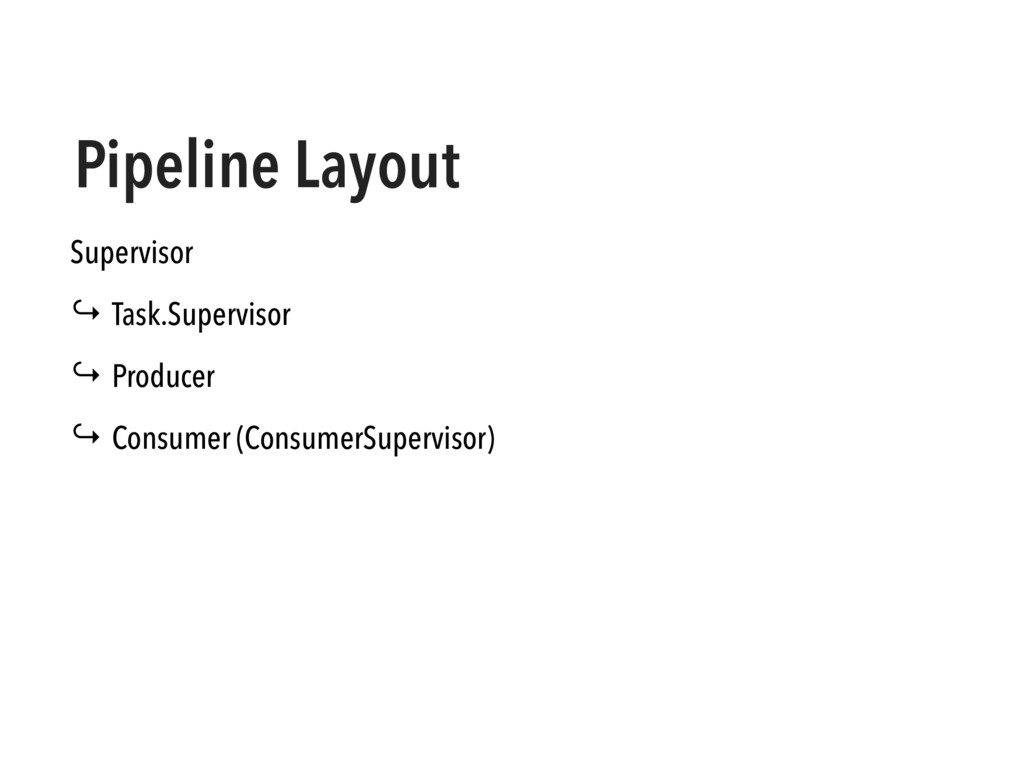
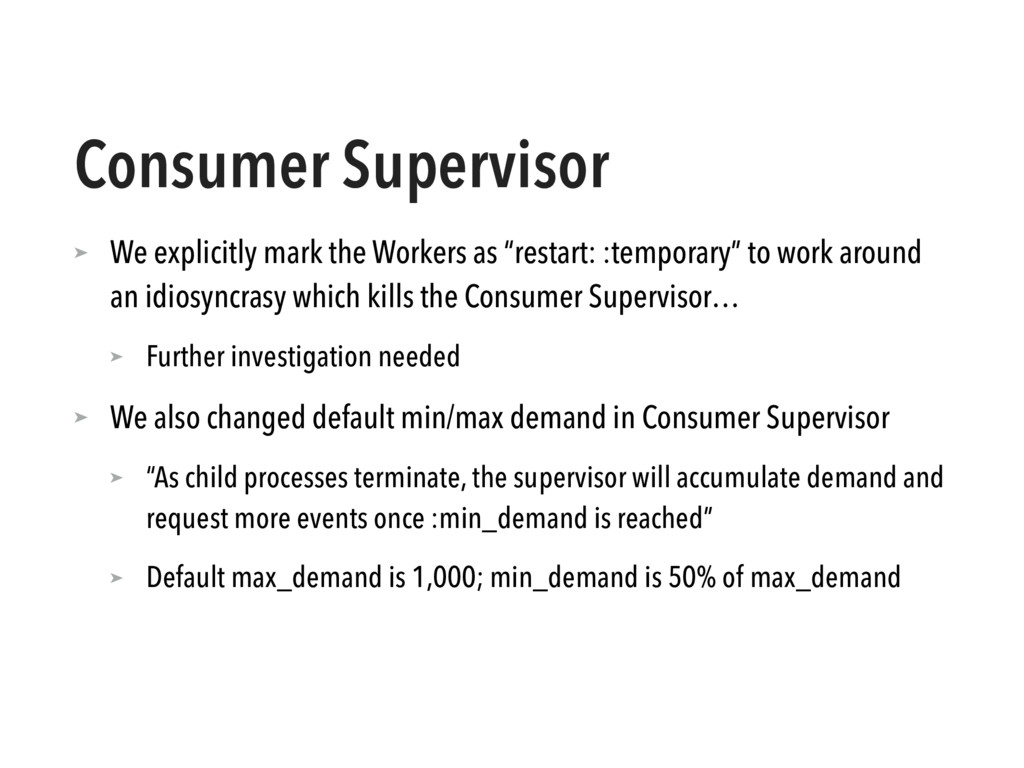
Consumer Supervisor ➤ We explicitly mark the Workers as “restart:
:temporary” to work around an idiosyncrasy which kills the Consumer Supervisor… ➤ Further investigation needed ➤ We also changed default min/max demand in Consumer Supervisor ➤ “As child processes terminate, the supervisor will accumulate demand and request more events once :min_demand is reached” ➤ Default max_demand is 1,000; min_demand is 50% of max_demand -
def start_link(args \\ []) do ConsumerSupervisor.start_link(__MODULE__, args) end def init(_)
do children = [worker(Worker, [], restart: :temporary)] min_demand = 6 * System.schedulers_online max_demand = 8 * System.schedulers_online subscription = [{Producer, min_demand: min_demand, max_demand: max_demand}] {:ok, children, [strategy: :one_for_one, subscribe_to: subscription]} end -
Explicit Timeout ➤ Some tasks may take a while to
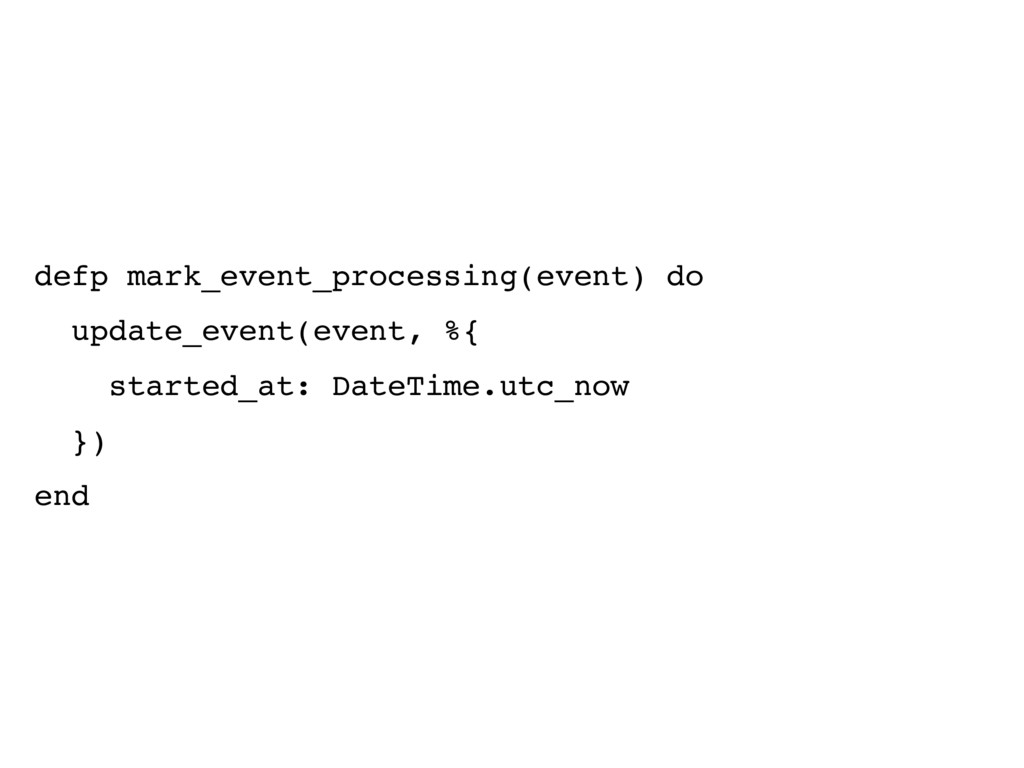
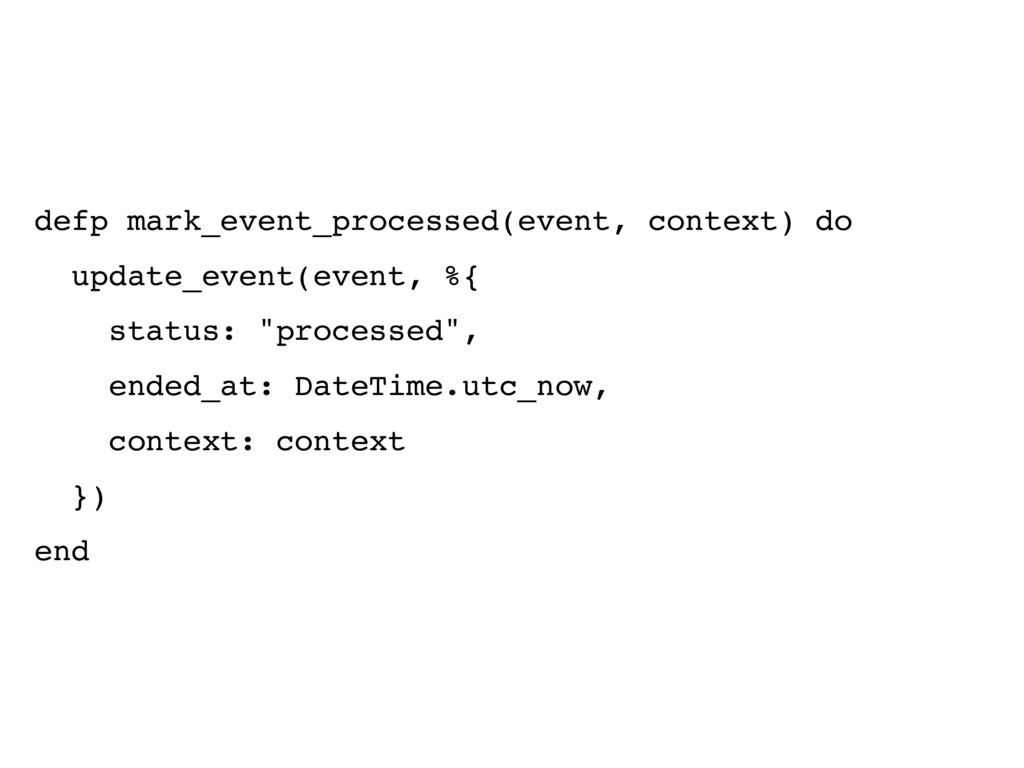
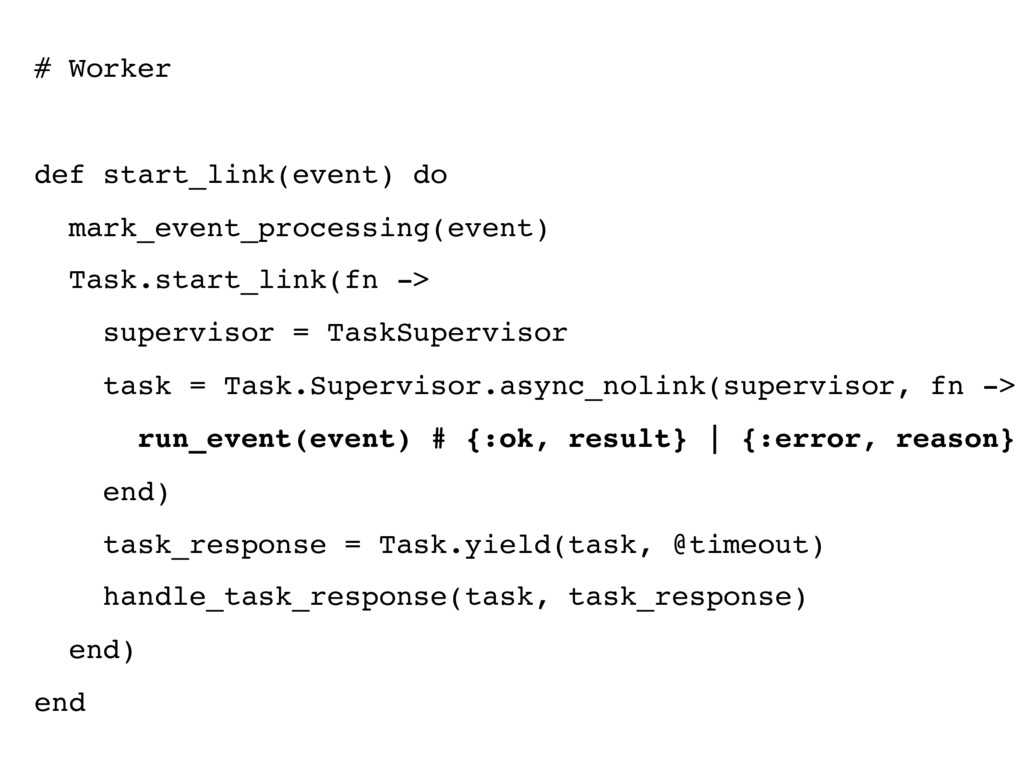
run and you’d not want to have timers everywhere, so we decided to wrap a stateless module in a Worker ➤ Therefore the Worker is actually just a runner, and uses another Task Supervisor and Task.yield to enforce timeouts ➤ Worker is responsible for updating contexts ➤ We also want stack traces in case of exits or exceptions -
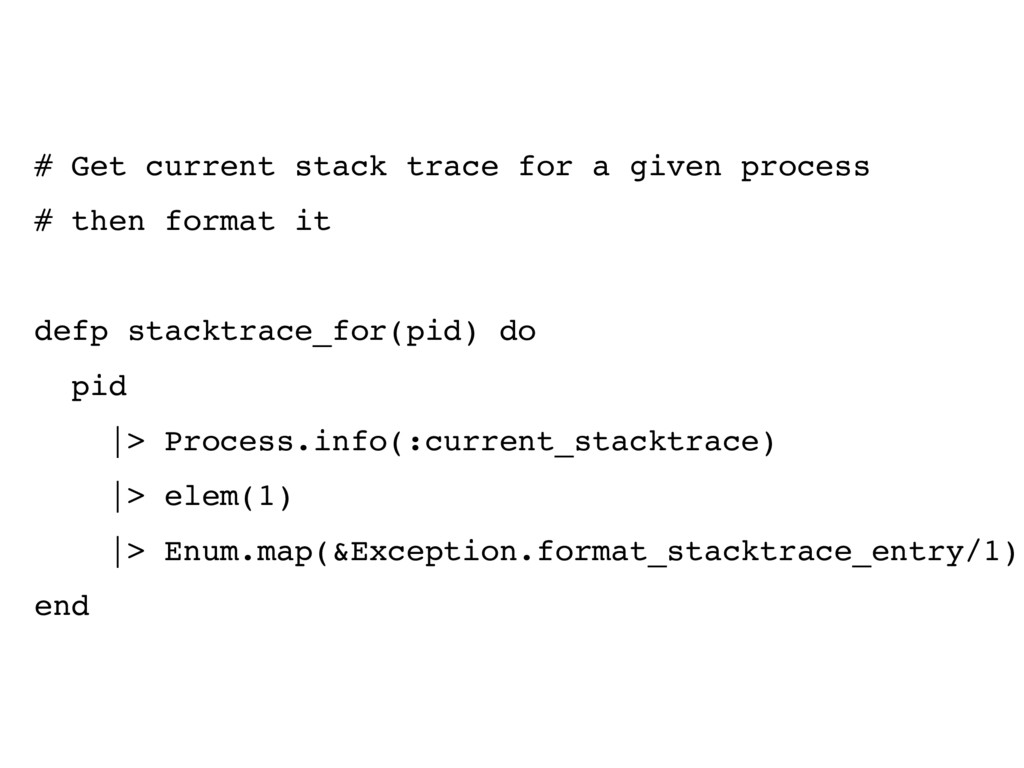
# Get current stack trace for a given process #
then format it defp stacktrace_for(pid) do pid |> Process.info(:current_stacktrace) |> elem(1) |> Enum.map(&Exception.format_stacktrace_entry/1) end -
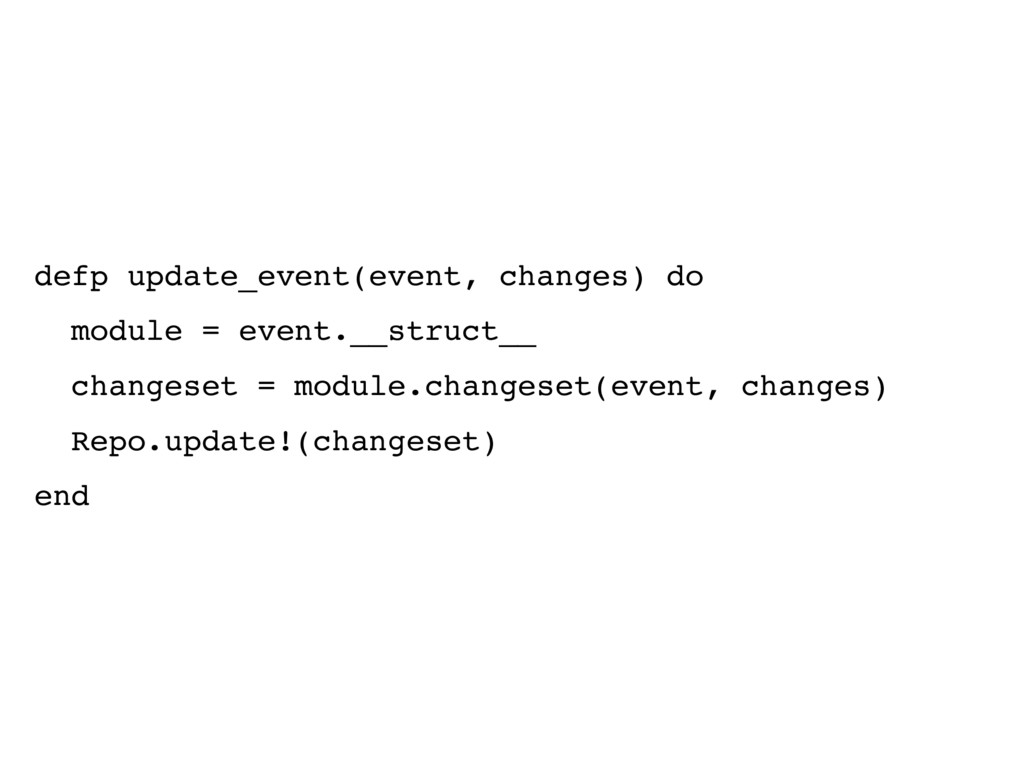
defp update_event(event, changes) do module = event.__struct__ changeset = module.changeset(event,
changes) Repo.update!(changeset) end -
defp mark_event_failed(event, reason, metadata \\ []) do updates = Map.merge(%{
error: reason, retries: (event.metadata["retries"] || 0) + 1 }, Map.new(metadata)) to_metadata = Map.merge(event.metadata, updates) update_event(event, %{ status: "failed", ended_at: DateTime.utc_now, metadata: to_metadata }) end -
# Worker def start_link(event) do mark_event_processing(event) Task.start_link(fn -> supervisor =
TaskSupervisor task = Task.Supervisor.async_nolink(supervisor, fn -> run_event(event) # {:ok, result} | {:error, reason} end) task_response = Task.yield(task, @timeout) handle_task_response(task, task_response) end) end -
# Task.yield returns nil # which means task is still
running and has timed out defp handle_task_response(task, nil) do stacktrace = stacktrace_for(task.pid) _ = Task.shutdown(task) mark_event_failed(event, :timeout, stacktrace: stacktrace) end -
defp handle_task_response(_, {:ok, {:ok, context}}), do: mark_event_processed(event, context) defp handle_task_response(_,
{:ok, {:error, reason}}) when is_atom(reason), do: mark_event_failed(event, Atom.to_string(reason)) defp handle_task_response(_, {:ok, {:error, reason}}), do: mark_event_failed(event, inspect(reason)) defp handle_task_response(_, {:exit, reason}), do: mark_event_failed(event, inspect(reason)) -
Outcome ➤ Migrated the whole dataset two times in December
➤ Another time in January 2018 ➤ Break/Fix included — due to higher performance, we were able to use time saved on investigating all corner cases ➤ “Smoothest deployment ever”, says customer ➤ Conclusion: GenStage saved our asses. Thank you!