Share
Embed
Jordan Appleson - A journey through Big Data
Presented at Hey! #11 on 22nd July, 2014.
Hey! Presents
July 22, 2014
Transcript
45 slides
-
I do a bit of this: Software Engineer, bit of
a geek. But then again, who isn’t? Lead the Insights and Search Analytics Platform at Branded3. Write lots of C#, PHP, JS amongst other languages -
Over the last several months: Decisions associated with choosing a
suitable Technology stack Making architectural decisions around structuring data for performance Future proofing and scaling solutions 4 -
What is Big Data? Large amounts of Structured and Unstructured
Data Volumes ranging from 100GB’s to PB’s Traditional RDBMS’s struggle to allow you effectively retrieve key information Varies depending on the Application / Company -
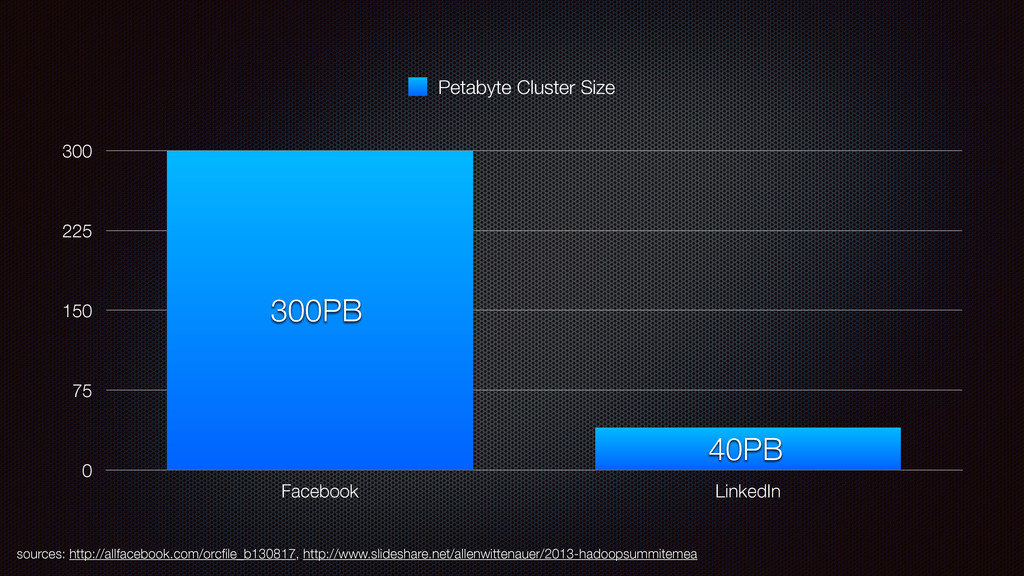
0 75 150 225 300 Facebook LinkedIn Petabyte Cluster Size
40PB 300PB sources: http://allfacebook.com/orcfile_b130817, http://www.slideshare.net/allenwittenauer/2013-hadoopsummitemea -
It’s not just about size… It’s about what you’re doing
with the data Analysing, Mining, Visualising It’s just as much about the tool set -
What is NoSQL? (Not Only SQL) Built to scale large
volumes of data and aid in distributed processing Different types of NoSQL. Document, Graph, Column-Store Schema-less (to a degree) Loss of JOINS, loss of certain aggregation features common to RDBMS’s -
Where I entered the Big Data scene… “Hey Jordan, come
check out this database we have! It’s almost 2TB and you’ll be taking it over…” -
“… oh and by the way, I’m leaving in a
week… Good Luck with it!” -
I was left with (in terms of data): a database
server running MSSQL storing almost 2TB of data 8GB RAM and 4 cores. (pathetic) Queries could take anywhere between 15 and 45 minutes 2 tables with 700 million and 300 million rows in (500GB and 300GB per table respectively) Other tables with 10s of millions of rows Lots of other tables! Some with 100s of columns -
Let’s be pragmatic… We definitely need something that can handle
this much data from the get go but can handle an exponential increase Is a RDBMs really the right solution for this? How much time am I going to have spend ops-side? -
Lets look at MySQL: Partitioning data is not easy, i.e.
Sharding <- Key Point Bound by Schemas and linear tables It has replication but how about transparent auto failover? Maintaining it could potentially be a full time job straight away… I need to be writing code though? -
Apache Hadoop Can we just use Hadoop on it’s own?
No. Need for other systems to allow for real time access and queries What about the learning curve? ! Potentially good for some aspects of our longer term goals though! -
Apache Cassandra Column Based Database Scales across different locations well
SQL Like Query Language (CQL) Dynamic Schema P2P based clustering (and it’s not a pain to setup!) Actually a very good option, even now! -
Apache Cassandra How much did I know about Column Based
Store optimisations? What’s the learning curve like? Interop options with different technology stacks (PHP, C# specifically) Documentation and community support TTL? Hm…. -
MongoDB Dynamic Schema (Document Based) Out-of-the-box Replication and Sharding JavaScript
Query Engine Large number of supported drivers Documentation and Community Support is Excellent -
MongoDB TTL potential looked great Built for large amounts of
data Migration possibilities for future proofing ticked the box But really, it looked like we could get a prototype up and running quick. -
MongoDB TTL potential looked great Migration possibilities for future proofing
ticked the box But really, it looked like we could get a prototype up and running quick. -
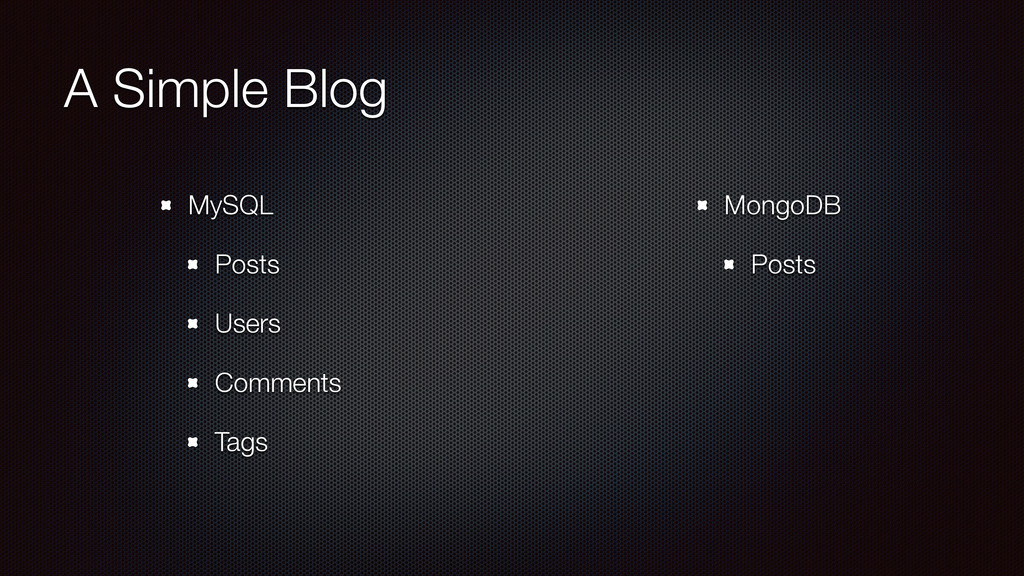
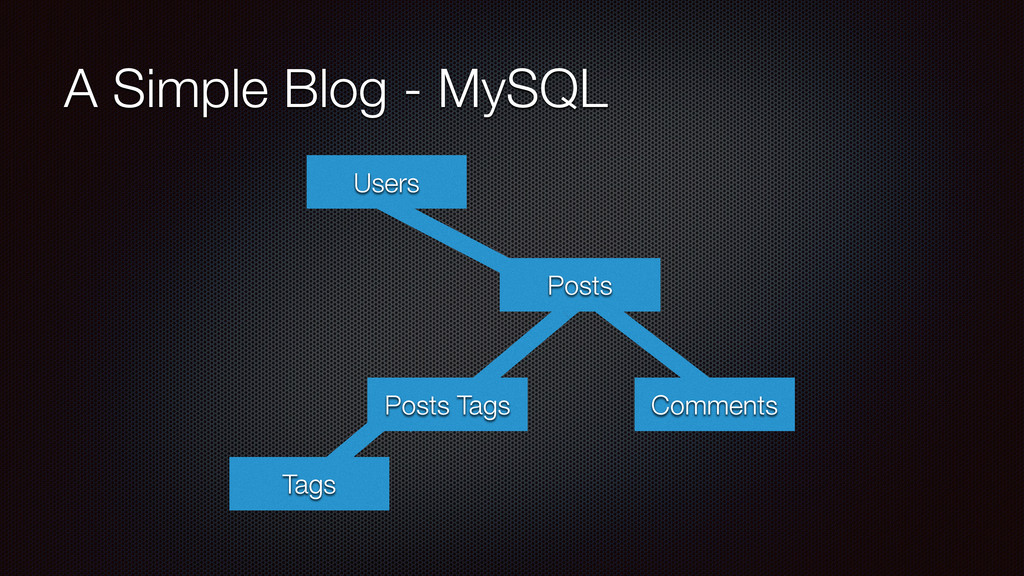
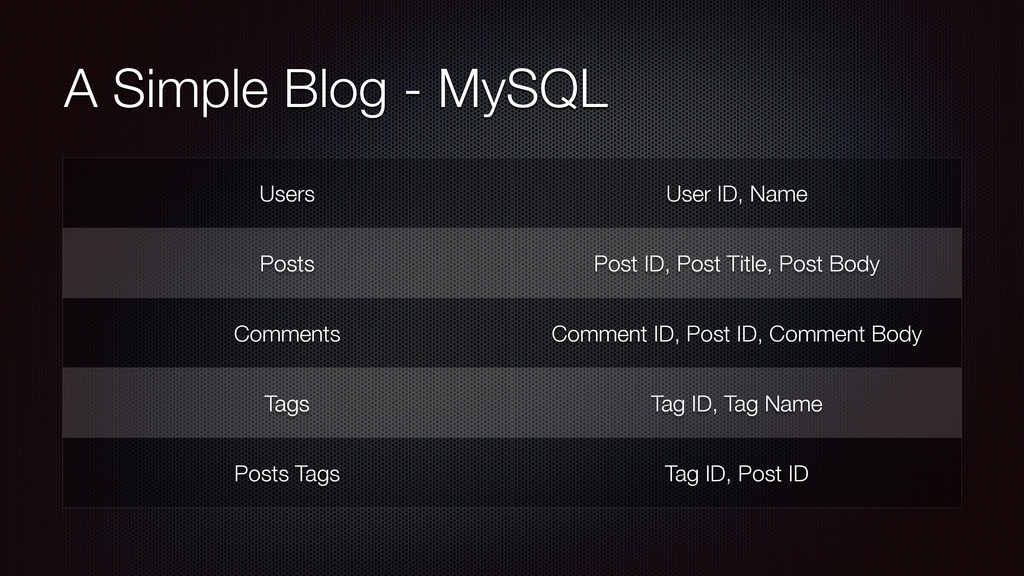
A Simple Blog - MySQL Users User ID, Name Posts
Post ID, Post Title, Post Body Comments Comment ID, Post ID, Comment Body Tags Tag ID, Tag Name Posts Tags Tag ID, Post ID -
MongoDB allows us to better form our data layer to
the application layer. ! Our schema is our code…. without migrations. -
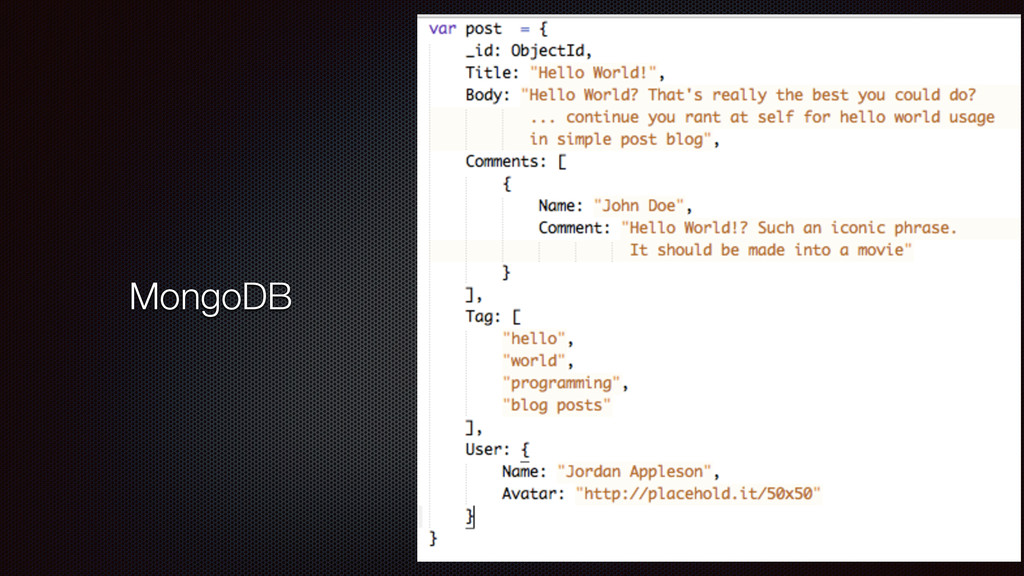
A Simple Blog - MongoDB One collection. One Query. No
aggregated queries to other tables = No extra query overhead Less overhead mapping the data layer to application layer - it’s already formed. Less time spent making the database because your application layer can be your schema. -
Just because the schema’s dynamic does not me you do
not have a schema. Seriously. -
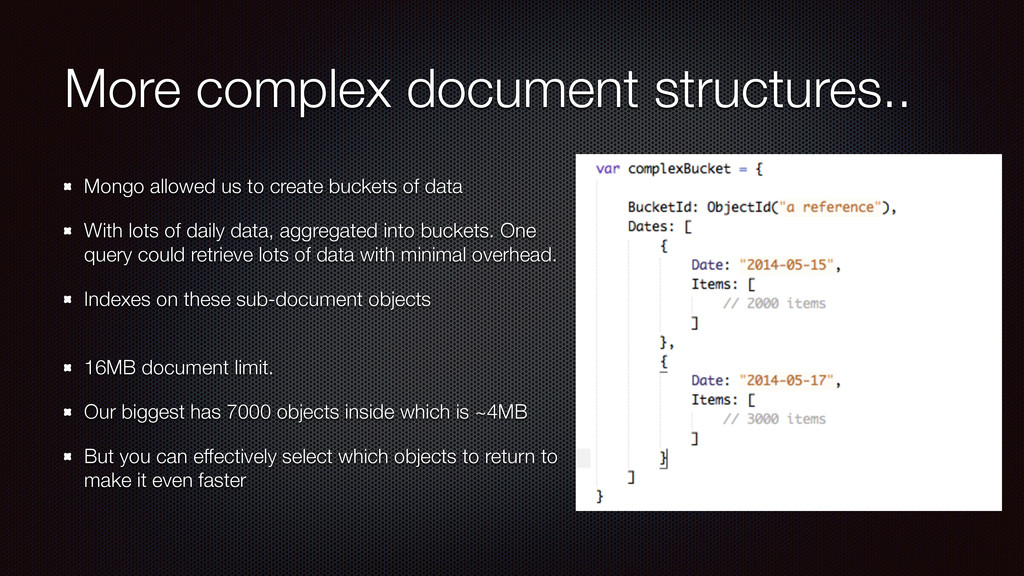
More complex document structures.. Mongo allowed us to create buckets
of data With lots of daily data, aggregated into buckets. One query could retrieve lots of data with minimal overhead. Indexes on these sub-document objects 16MB document limit. Our biggest has 7000 objects inside which is ~4MB But you can effectively select which objects to return to make it even faster -
Performance Issues Growing documents can cause page faults MongoDB allocates
padding If you exceed the padding, data is moved on disk and performance issues ensue -
Initial System 2 million updates to the buckets in 1
hour These updates were effectively small chunks of data that needed to be associated with a day Push the small chunk to the bucket for the relevant day ! Documents began to grow at an alarming rate. Fault… Fault.Fault.FaFaFault -
Revised System Insert data into initial collection chunk by chunk
(inserts are blazing fast) Compile the data for each day and then push to bucket Reduced page faults Super fast compared to the a first version -
Zero to Data API in a few lines of code
Prototype API mapped URL parameters to queries JSON API literally fell out of our computers in hours Getting to these data buckets was easy and our front end could consume and graph out the data with ease. Allowed to focus on processing and scaling -
Key Points We needed something that can handle terabytes of
data and didn’t require babysitting constantly We needed to be able to get off the ground quickly and get to our data as fast as we were putting data in We needed to be able to adapt to an extremely volatile industry our metrics are based on We needed scaling and redundancy options One person needed to do all this in a matter of months. -
Other Issues we had to deal with: Reducing read/write contention
Ensuring the indexes and collections are better suited to our data access patterns Dealing with page faults Mitigated by using SSDs Growing documents can actually have a negative impact on space efficiency -
Things work best when they’re in memory. ! Look at
the way you access data, what kind of data should be in memory? If you’re lazy, use SSDs but it won’t save you forever. -
Summary Dealing with large amounts of data may warrant NoSQL
technologies Use them effectively by looking at how to structure your data to best suite your access and processing patterns. Schema’s are important still #sigh Knowing the technology you’re using at a core level is VERY useful for performance enhancements There’s more than one way to skin a cat