Share
Embed
Lip Reading with LLMs? Visual Speech Recognition
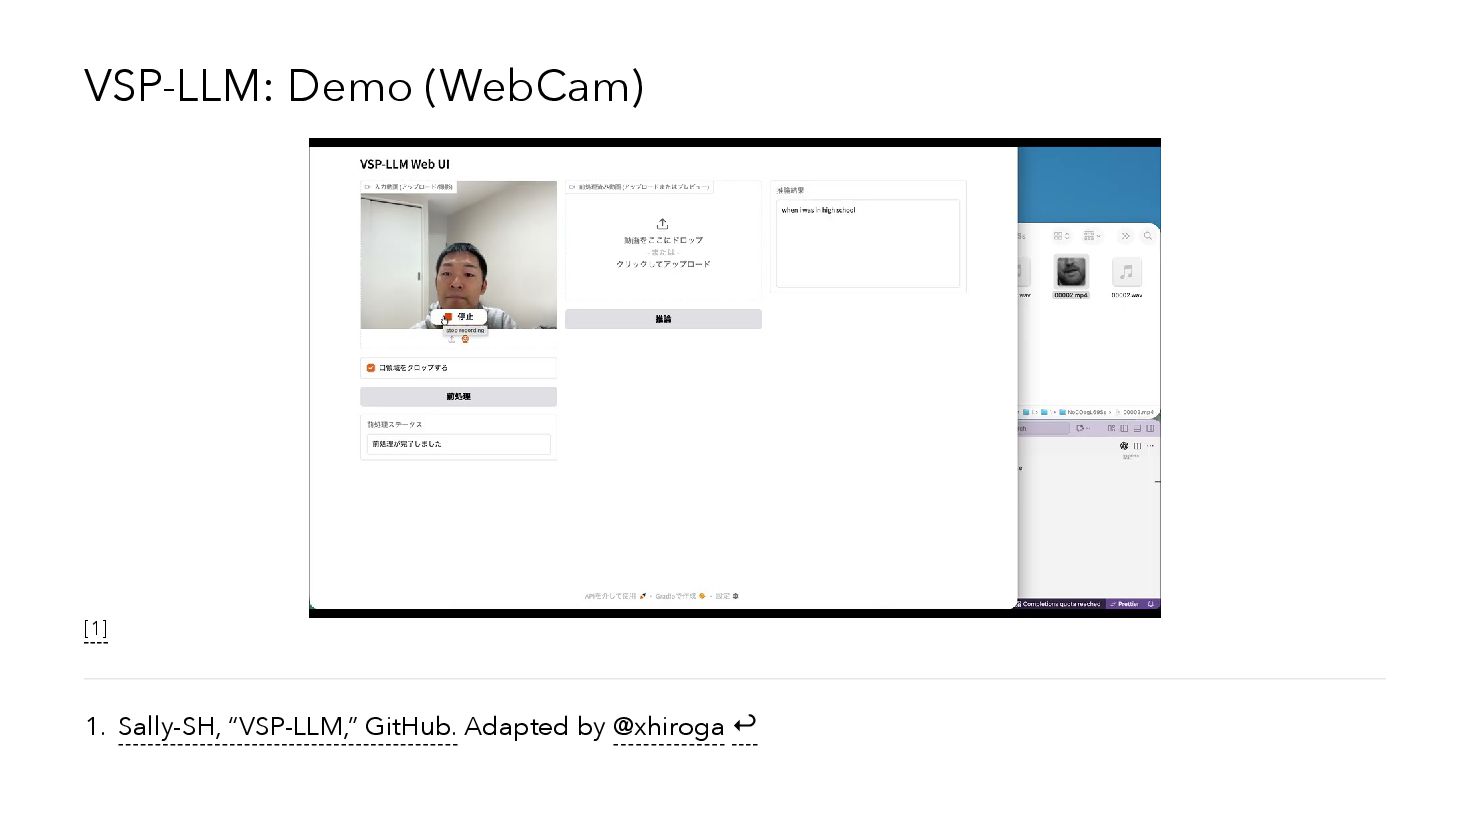
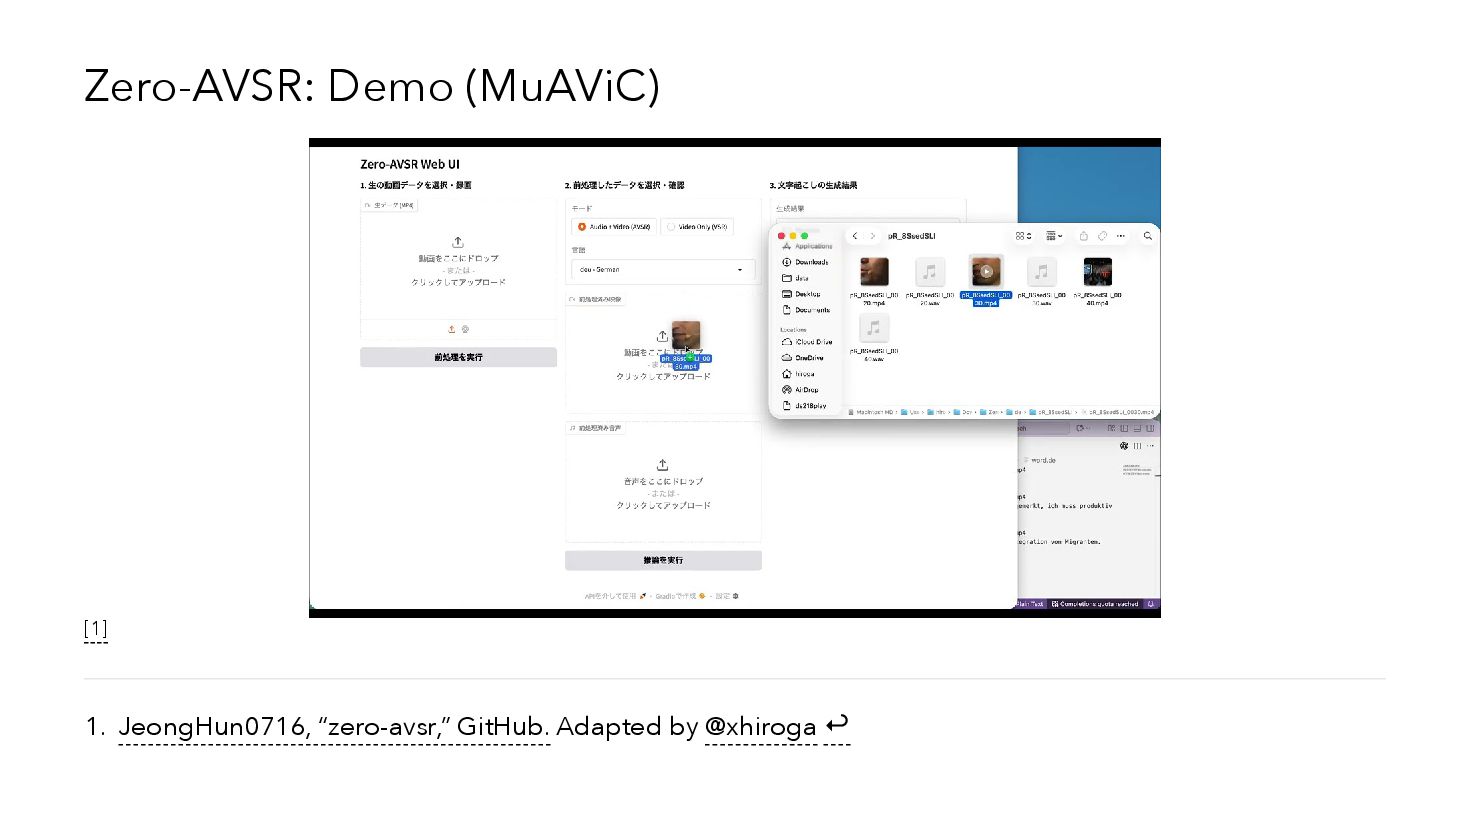
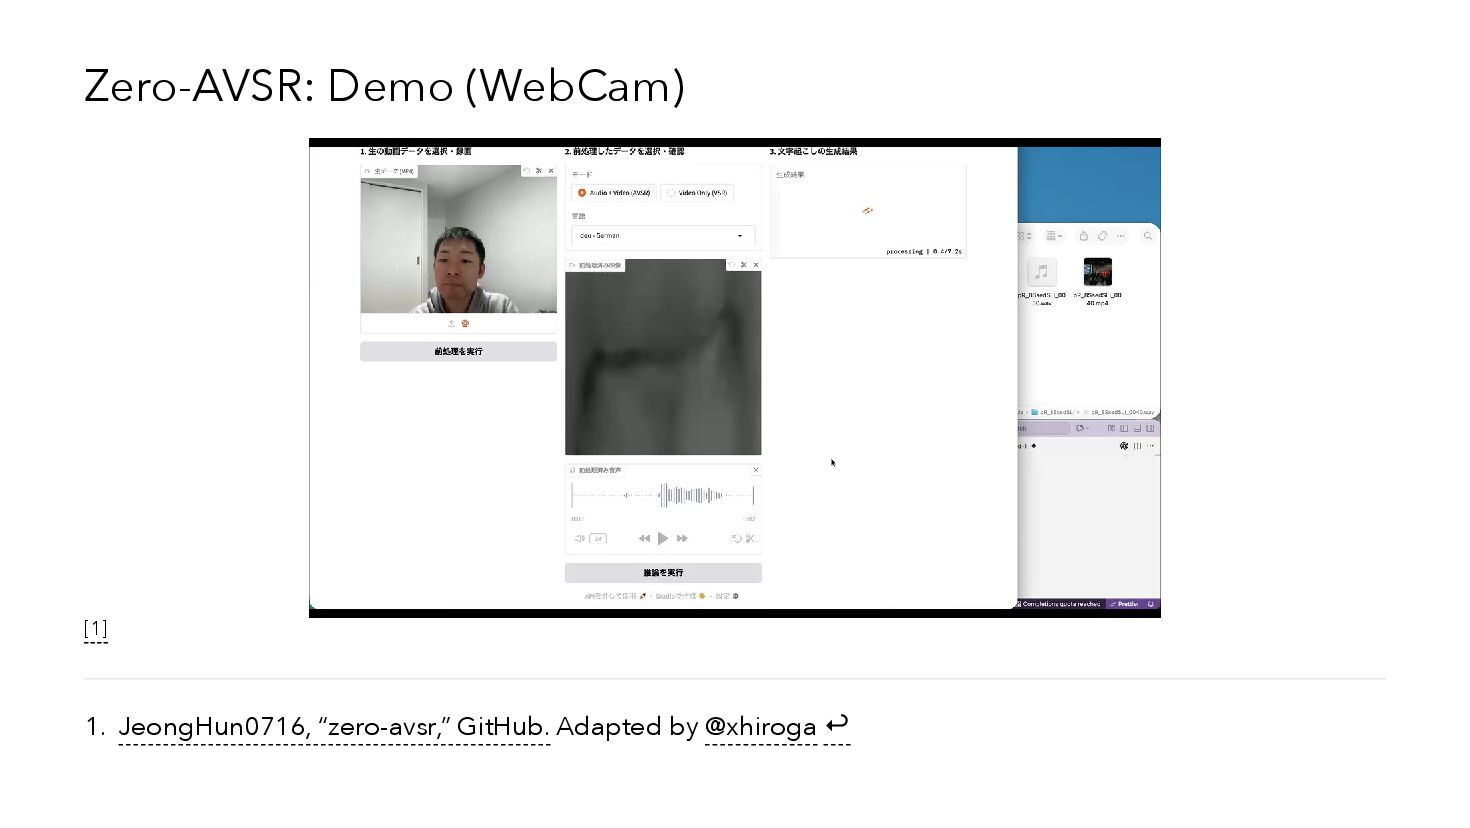
This document provides an overview of visual speech recognition (VSR) and related research, with a particular focus on novel approaches using large language models (LLMs). Through demonstrations, we will introduce the specific performance and application examples of models such as VSP-LLM and Zero-AVSR, and discuss comparisons with conventional methods and challenges. We will also consider the current state of visual information recognition, including the difficulties in creating datasets and the reliance on conventional models.
hiroga
October 21, 2025
Transcript
48 slides
-
Lip Reading with LLMs? Visual Speech Recognition J. H. Yeo
et al., “Where Visual Speech Meets Language: VSP-LLM Framework for Efficient and Context- Aware Visual Speech Processing,” J. H. Yeo et al., “Zero-AVSR: Zero-Shot Audio-Visual Speech Recognition with LLMs by Learning Language- Agnostic Speech Representations,” Hiroaki Ogasawara @ Matsuo Lab LLM Community Paper&Hacks #62 This deck is available on GitHub. -
About Me Hiroaki Ogasawara (Sawara) Since 2015: IBM Japan Since
2018: Software engineer/manager at an insurtech startup Since 2024: Freelance; building ML models and infrastructure at a machine learning startup Website: https://sawara.dev/ I share the latest updates on social media. Follow me! X (Twitter): @xhiroga GitHub: @xhiroga LinkedIn: @hiroga VRChat: @hiroga YouTube: @hiroga -
Agenda Demo What is lip-reading research? Visual speech recognition Applications
of visual speech recognition Why LLMs? Homophones / visemes Challenges in building datasets Are they different from general-purpose multimodal LLMs? Research on LLM-based visual speech recognition VSP-LLM Zero-AVSR Takeaways -
Visual Speech Recognition Also called VSR (Visual Speech Recognition) or
V-ASR (Visual Automatic Speech Recognition). Research that solves the task of transcribing spoken content using only the video of the utterance. A lower transcription WER (Word Error Rate) or CER (Character Error Rate) means better performance. Related research areas include VST (Visual Speech Translation), ASR (Automatic Speech Recognition), and AVSR (Audio-Visual Speech Recognition). -
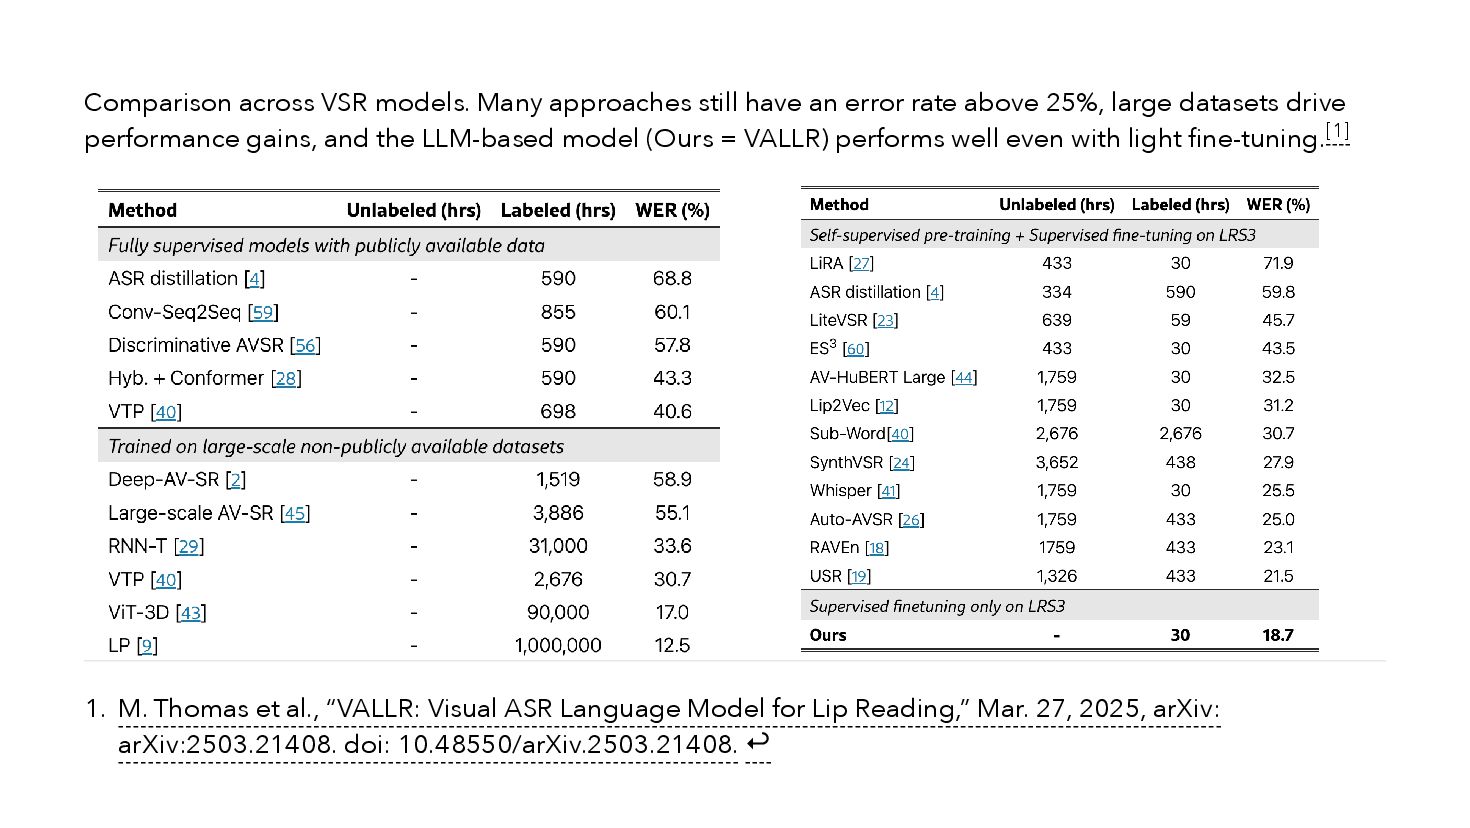
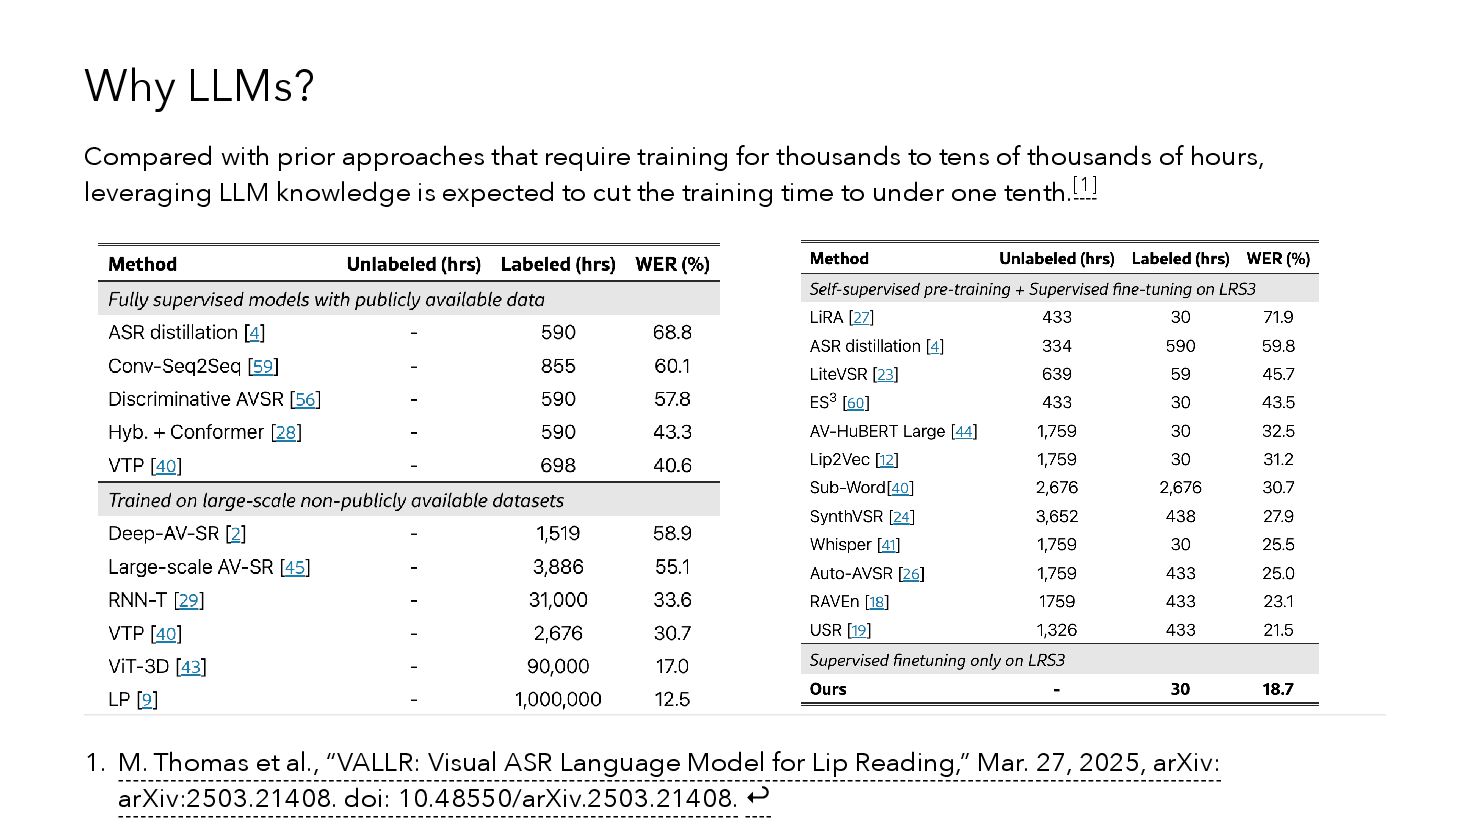
Comparison across VSR models. Many approaches still have an error
rate above 25%, large datasets drive performance gains, and the LLM-based model (Ours = VALLR) performs well even with light fine-tuning. 1. M. Thomas et al., “VALLR: Visual ASR Language Model for Lip Reading,” Mar. 27, 2025, arXiv: arXiv:2503.21408. doi: 10.48550/arXiv.2503.21408. ↩︎ [1] -
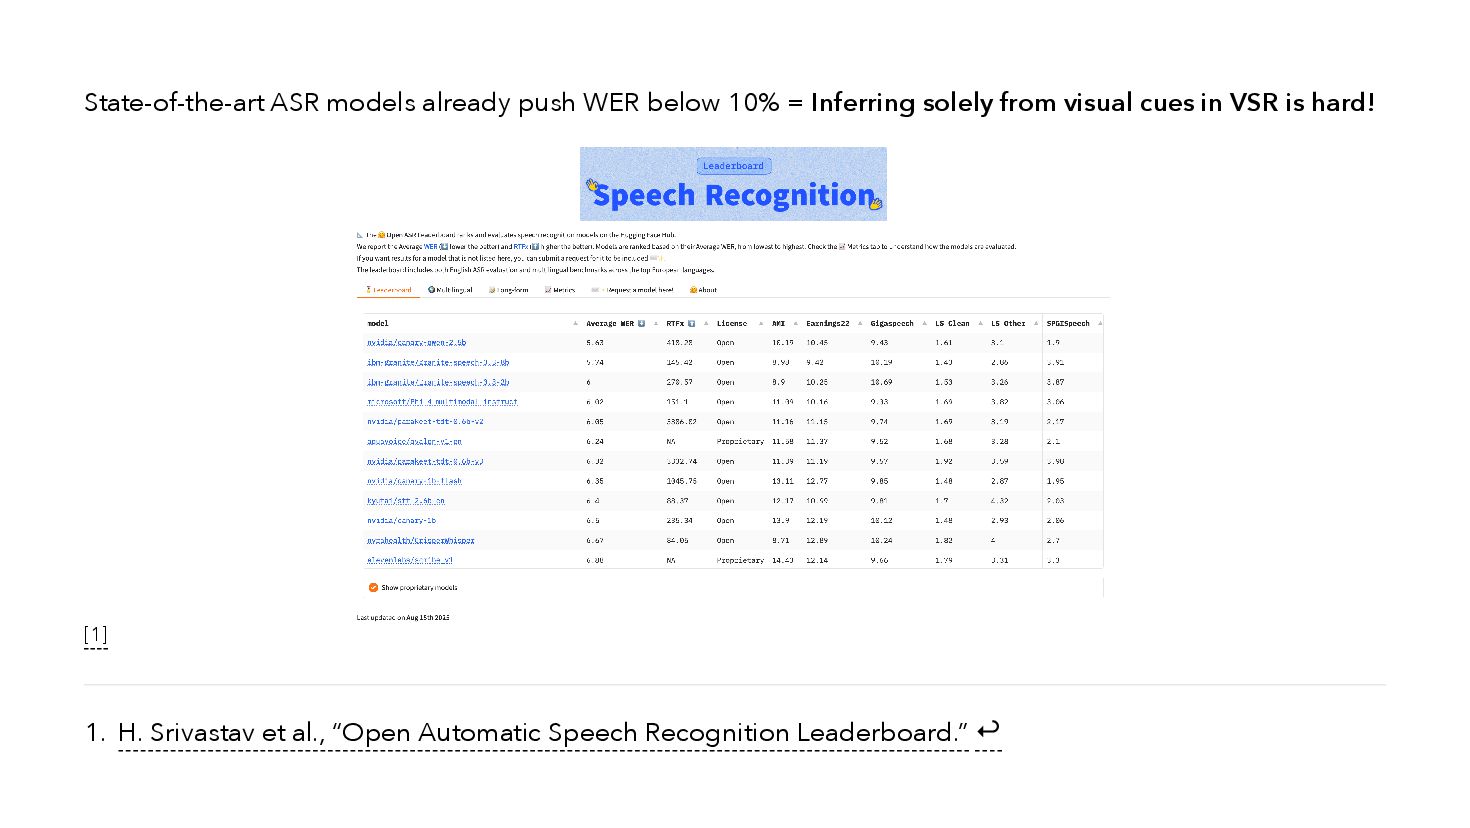
State-of-the-art ASR models already push WER below 10% = Inferring
solely from visual cues in VSR is hard! 1. H. Srivastav et al., “Open Automatic Speech Recognition Leaderboard.” ↩︎ [1] -
Applications of Visual Speech Recognition Supporting speech for people who
have lost their voice due to thyroid or laryngeal cancer Recognizing speech in quiet places like libraries or in noisy environments such as construction sites -
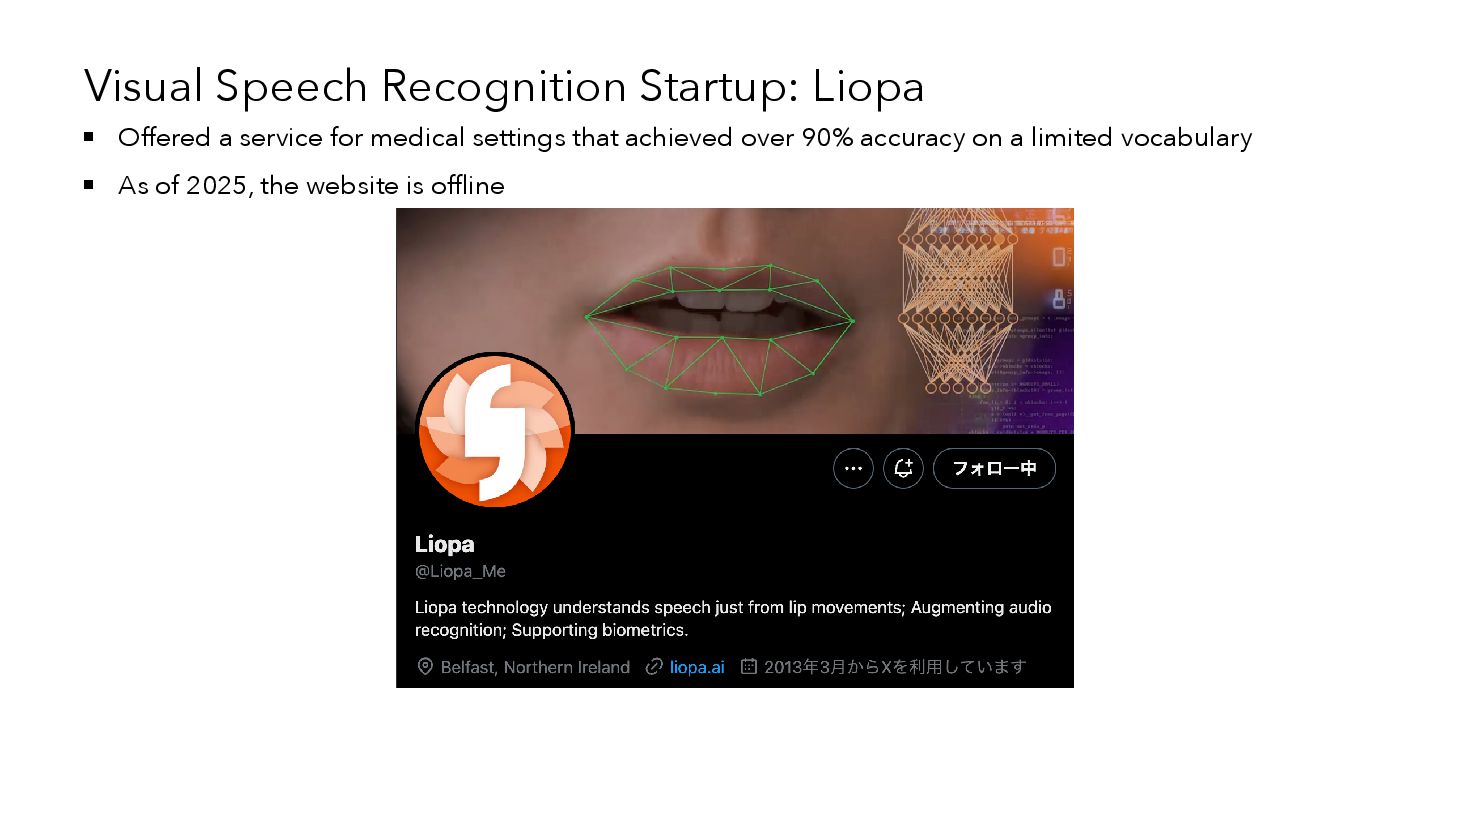
Visual Speech Recognition Startup: Liopa Offered a service for medical
settings that achieved over 90% accuracy on a limited vocabulary As of 2025, the website is offline -
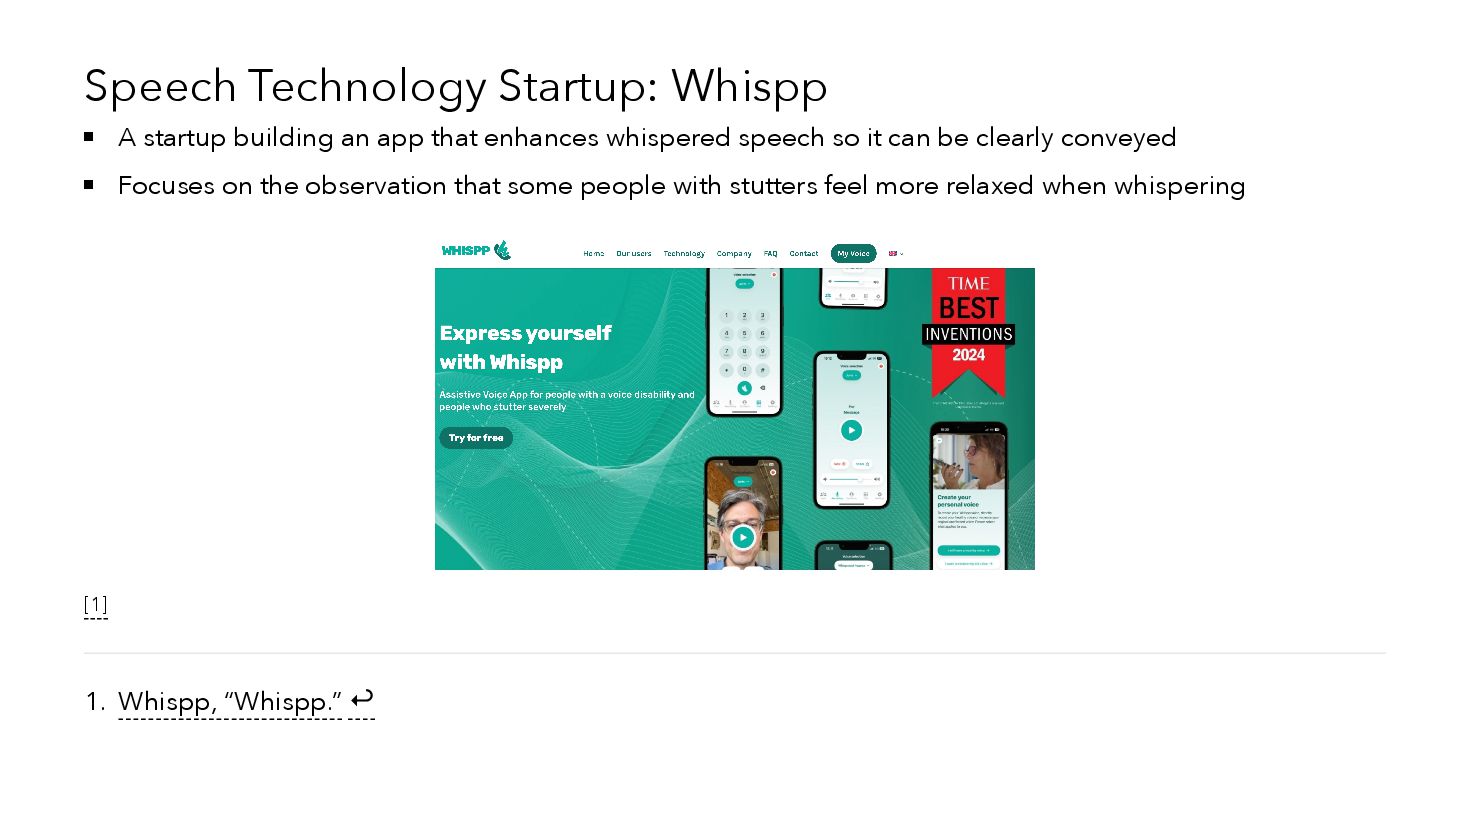
Speech Technology Startup: Whispp A startup building an app that
enhances whispered speech so it can be clearly conveyed Focuses on the observation that some people with stutters feel more relaxed when whispering 1. Whispp, “Whispp.” ↩︎ [1] -
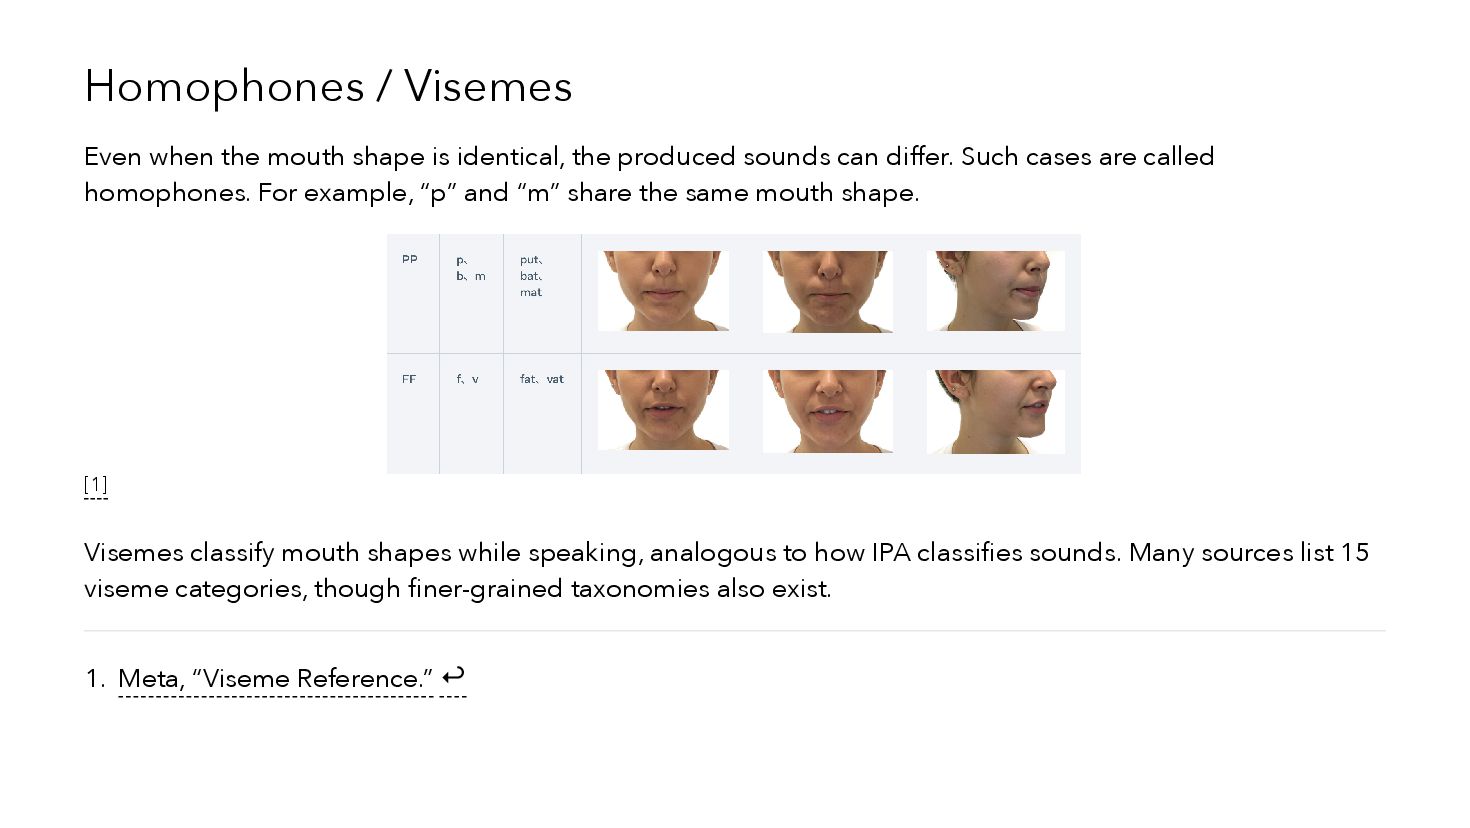
Homophones / Visemes Even when the mouth shape is identical,
the produced sounds can differ. Such cases are called homophones. For example, “p” and “m” share the same mouth shape. Visemes classify mouth shapes while speaking, analogous to how IPA classifies sounds. Many sources list 15 viseme categories, though finer-grained taxonomies also exist. 1. Meta, “Viseme Reference.” ↩︎ [1] -
Challenges in Building Datasets Creating datasets for lip-reading tasks involves
different hurdles than those for audio ASR. Video files are often larger than audio files Video captures faces, rooms, and other private information, leading to stronger privacy concerns Meanwhile, applications can sometimes tolerate noisy audio, depending on use cases. -
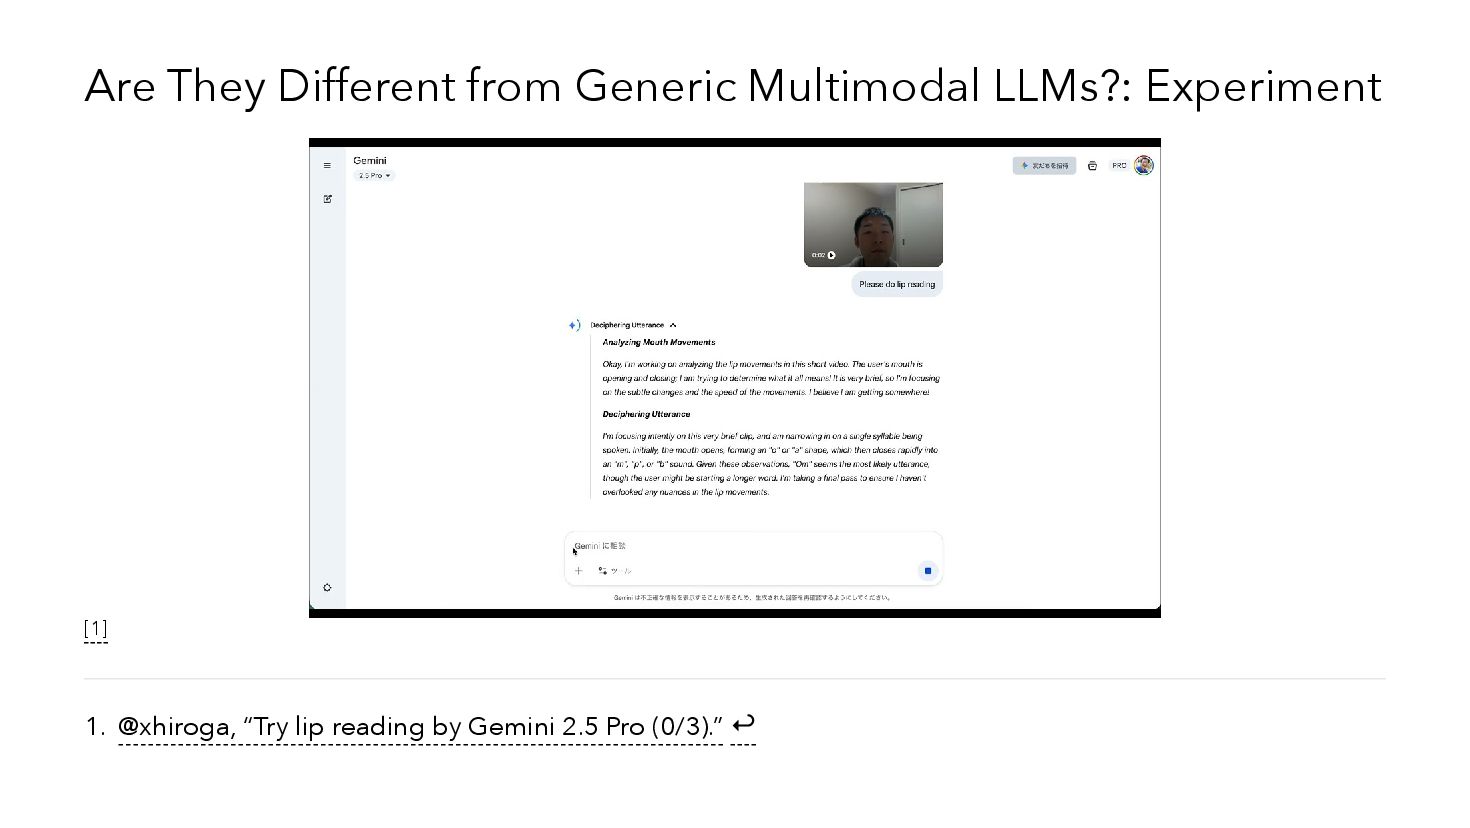
Are They Different from Generic Multimodal LLMs?: Experiment 1. @xhiroga,
“Try lip reading by Gemini 2.5 Pro (0/3).” ↩︎ [1] -
Are They Different from Generic Multimodal LLMs?: Answer General-purpose multimodal
LLMs include the building blocks for VSR, but using them as-is is tough. The coarse structure of 3D convolutions followed by embeddings can be reused In practice, you must learn to align mouth shapes with phonemes (or visemes) Very few studies fine-tune existing multimodal LLMs and repurpose them for VSR Therefore VSR research often relies on pretrained ASR models (plus LLM-style transcription backends). We will later demo AV-HuBERT, a representative visual speech recognition encoder. -
Why LLMs? Compared with prior approaches that require training for
thousands to tens of thousands of hours, leveraging LLM knowledge is expected to cut the training time to under one tenth. 1. M. Thomas et al., “VALLR: Visual ASR Language Model for Lip Reading,” Mar. 27, 2025, arXiv: arXiv:2503.21408. doi: 10.48550/arXiv.2503.21408. ↩︎ [1] -
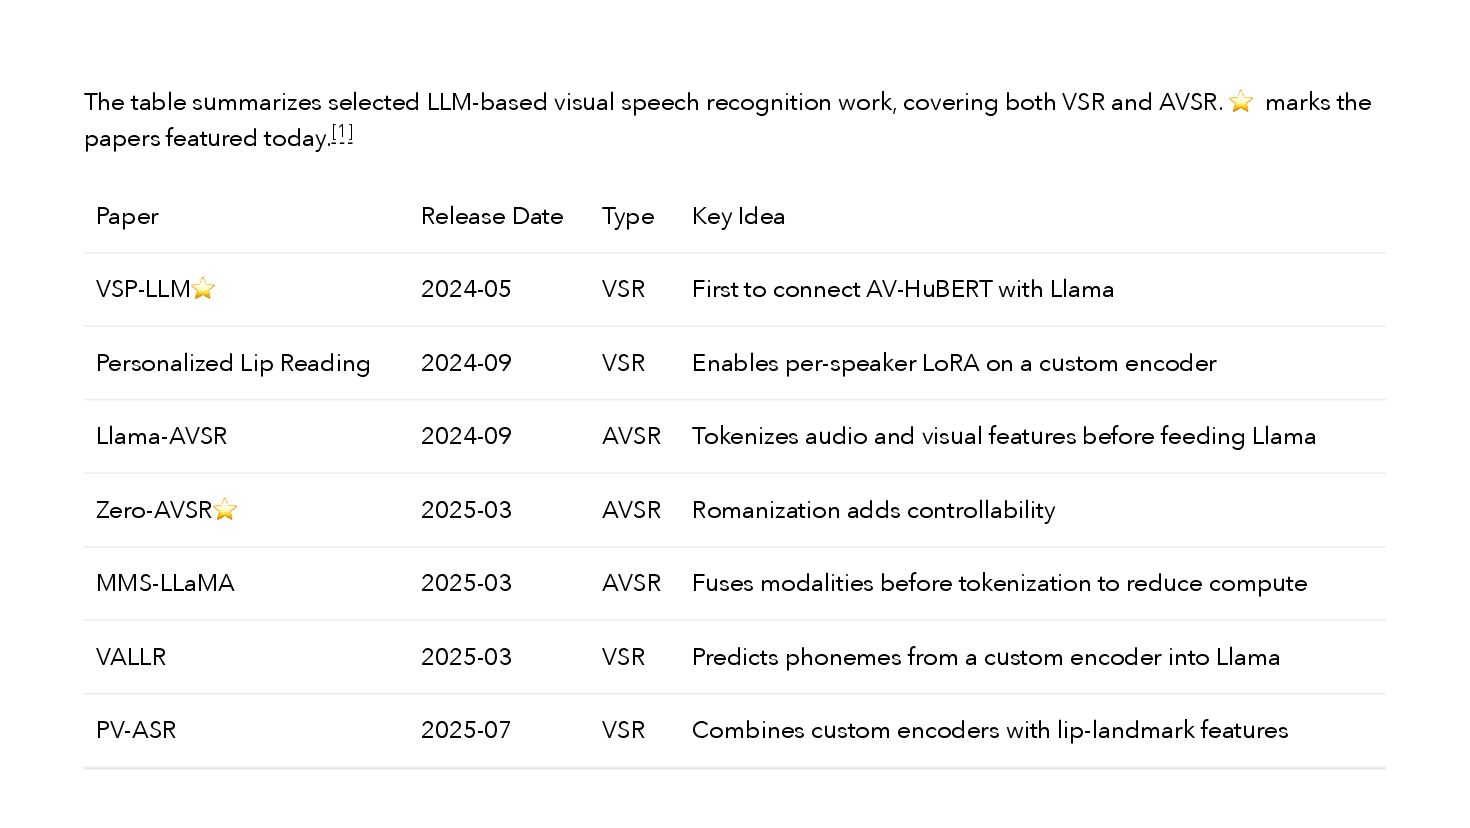
The table summarizes selected LLM-based visual speech recognition work, covering
both VSR and AVSR. ⭐️ marks the papers featured today. Paper Release Date Type Key Idea VSP-LLM ⭐️ 2024-05 VSR First to connect AV-HuBERT with Llama Personalized Lip Reading 2024-09 VSR Enables per-speaker LoRA on a custom encoder Llama-AVSR 2024-09 AVSR Tokenizes audio and visual features before feeding Llama Zero-AVSR ⭐️ 2025-03 AVSR Romanization adds controllability MMS-LLaMA 2025-03 AVSR Fuses modalities before tokenization to reduce compute VALLR 2025-03 VSR Predicts phonemes from a custom encoder into Llama PV-ASR 2025-07 VSR Combines custom encoders with lip-landmark features [1] -
Where Visual Speech Meets Language: VSP-LLM Framework for Efficient and
Context-Aware Visual Speech Processing 1. J. H. Yeo et al., “Where Visual Speech Meets Language: VSP-LLM Framework for Efficient and Context- Aware Visual Speech Processing,” May 14, 2024, arXiv: arXiv:2402.15151. doi: 10.48550/arXiv.2402.15151. ↩︎ [1] -
VSP-LLM: Problem Statement Can we leverage LLM capabilities for VSR?
With limited training data, can an LLM-backed model still deliver strong performance? -
VSP-LLM: Contributions to VSR 1. First work to integrate visual
speech modeling with an LLM, achieving state-of-the-art performance on VSR and VST 2. Groups consecutive frames based on feature similarity via k-means rather than fixed intervals -
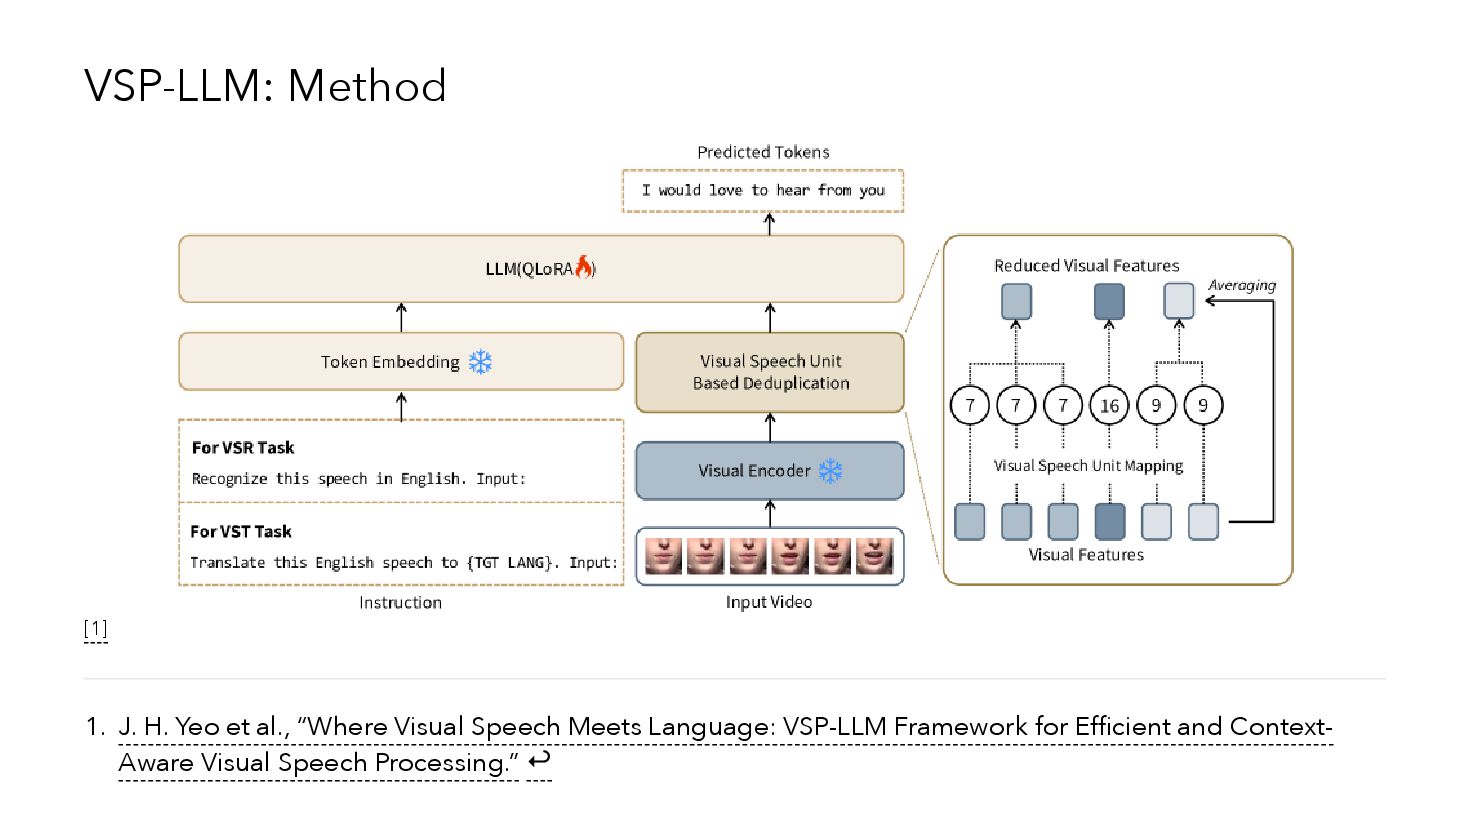
VSP-LLM: Method 1. J. H. Yeo et al., “Where Visual
Speech Meets Language: VSP-LLM Framework for Efficient and Context- Aware Visual Speech Processing.” ↩︎ [1] -
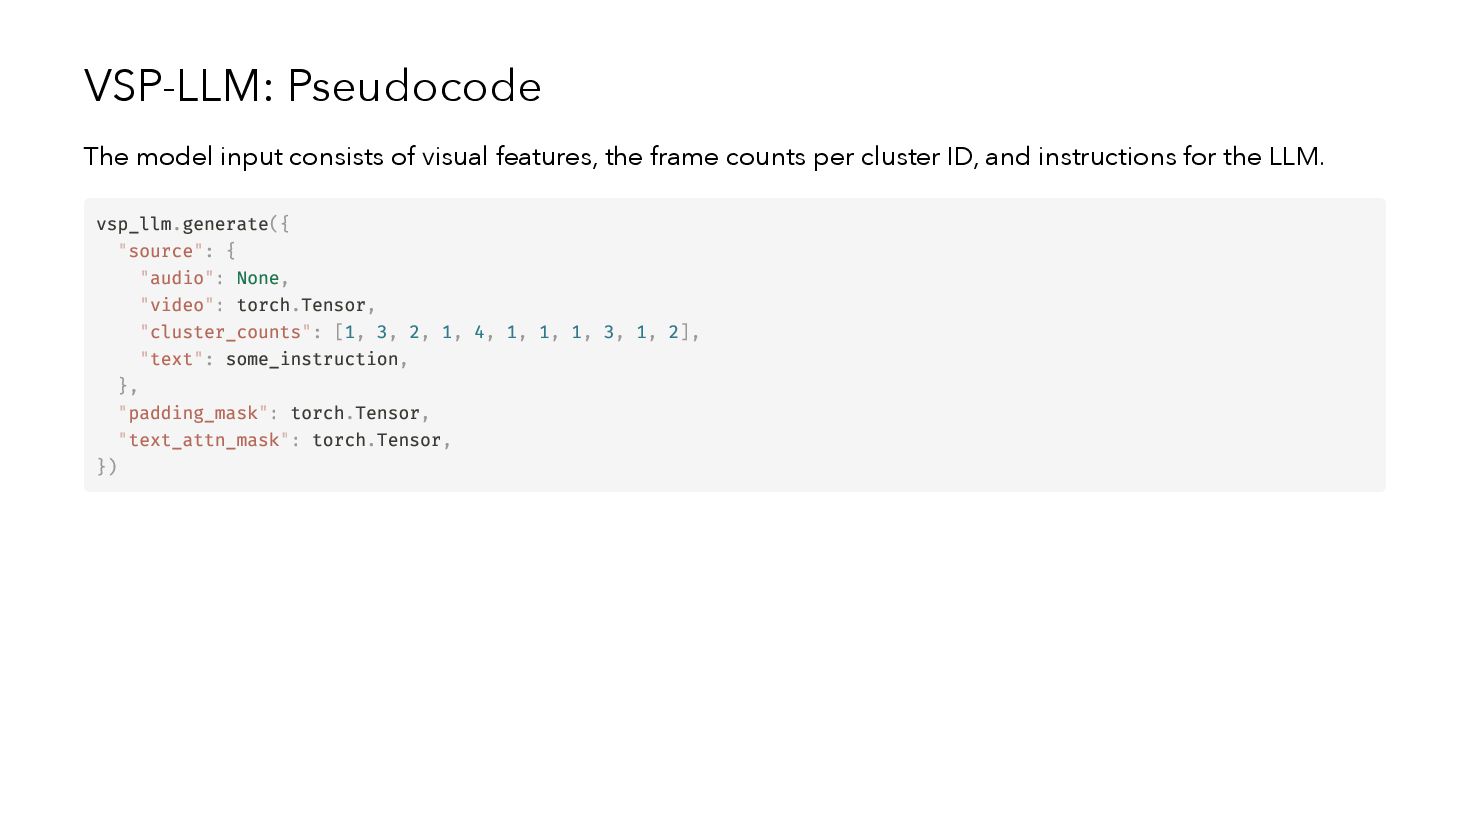
VSP-LLM: Pseudocode The model input consists of visual features, the
frame counts per cluster ID, and instructions for the LLM. vsp_llm.generate({ "source": { "audio": None, "video": torch.Tensor, "cluster_counts": [1, 3, 2, 1, 4, 1, 1, 1, 3, 1, 2], "text": some_instruction, }, "padding_mask": torch.Tensor, "text_attn_mask": torch.Tensor, }) -
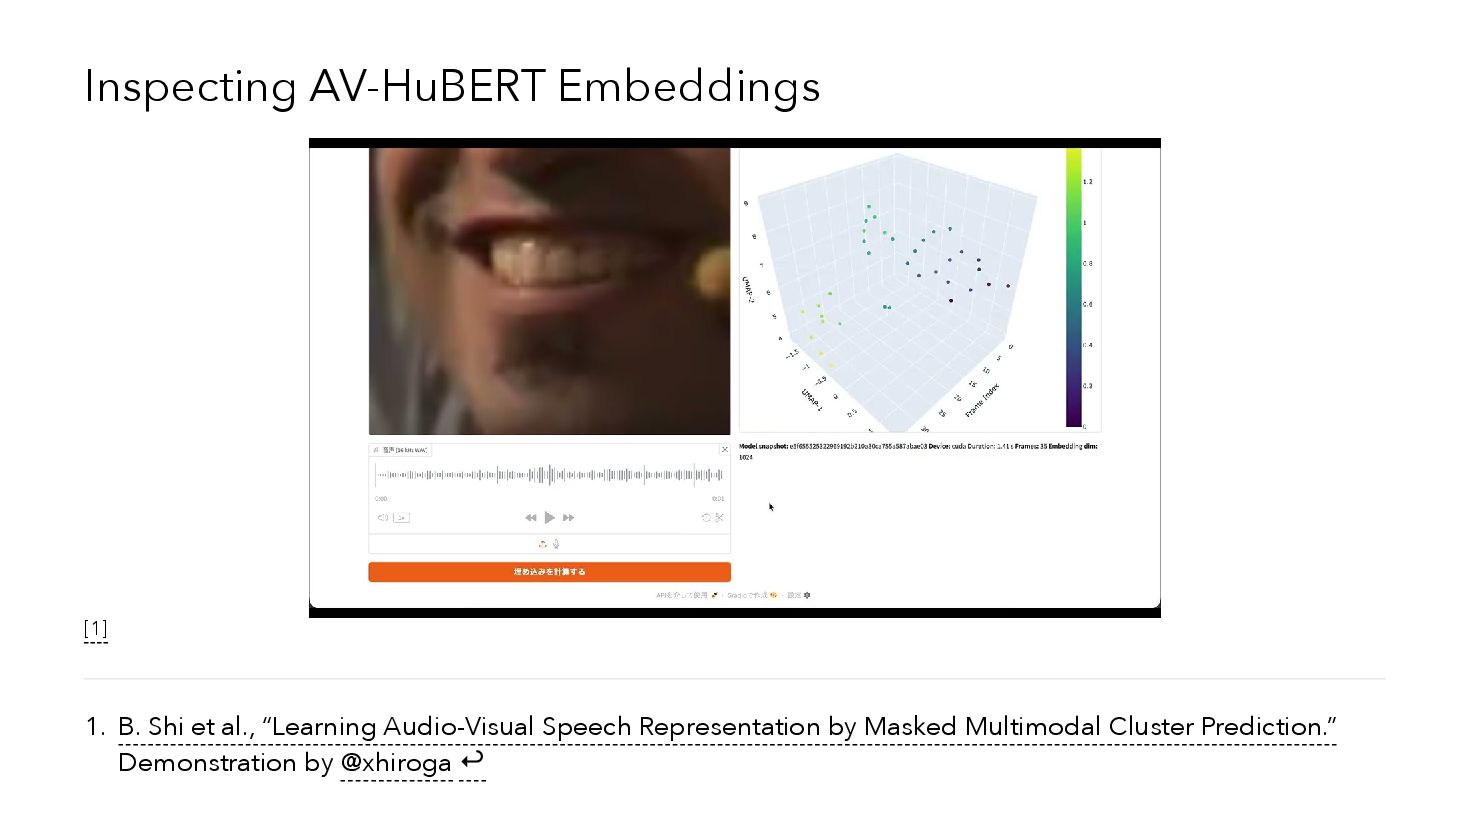
Inspecting AV-HuBERT Embeddings 1. B. Shi et al., “Learning Audio-Visual
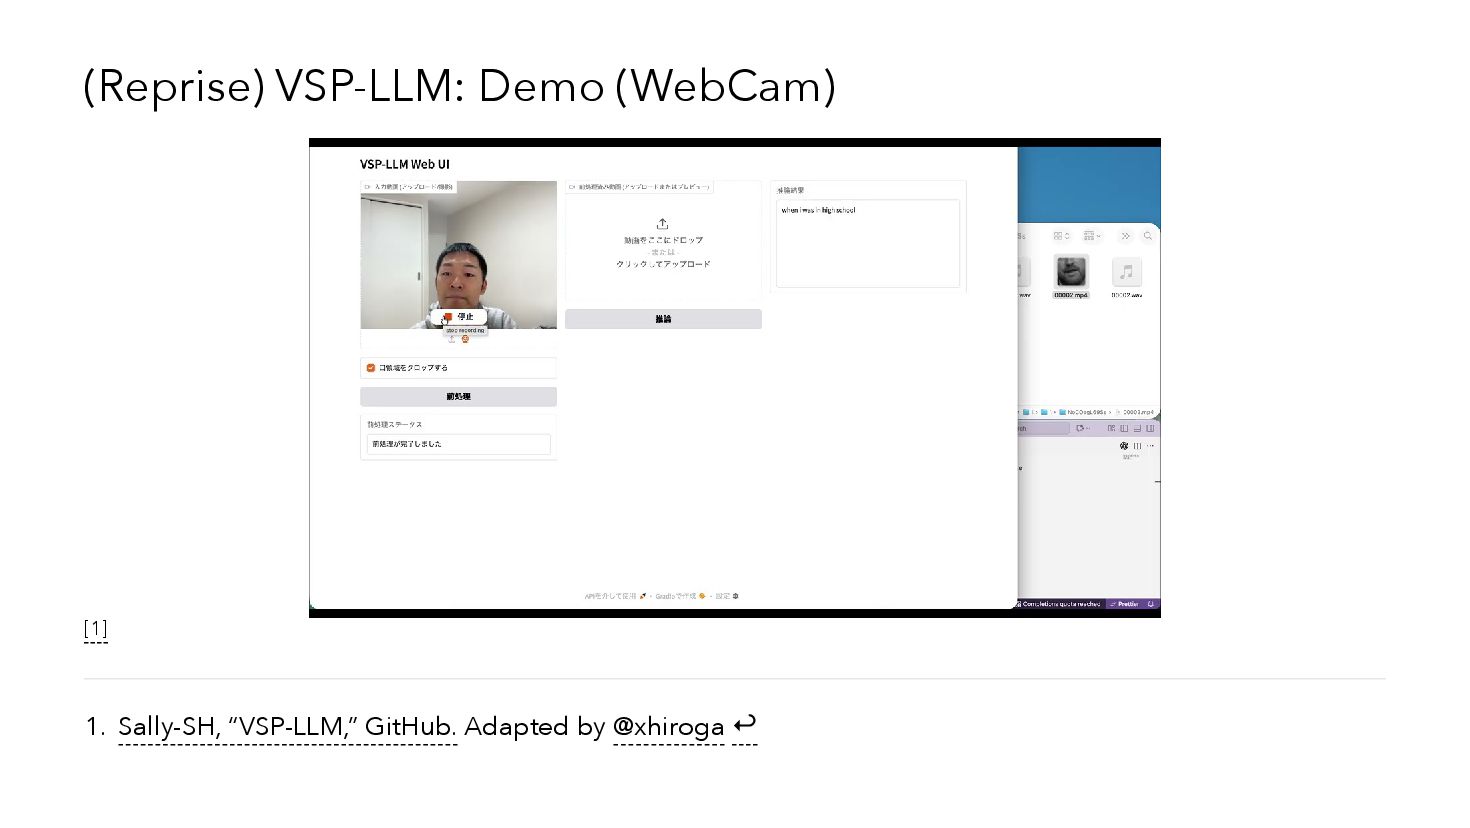
Speech Representation by Masked Multimodal Cluster Prediction.” Demonstration by @xhiroga ↩︎ [1] -
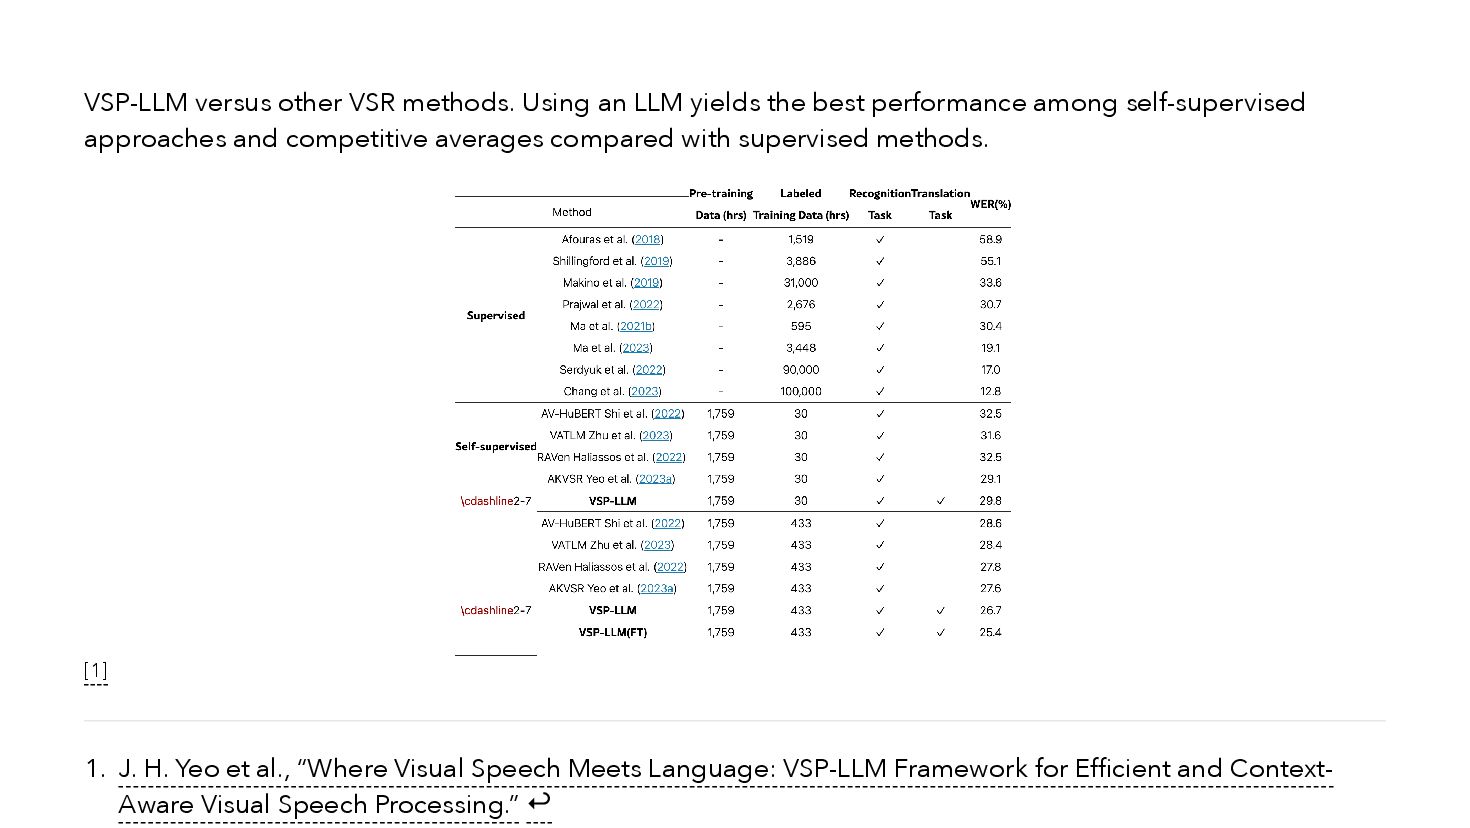
VSP-LLM versus other VSR methods. Using an LLM yields the
best performance among self-supervised approaches and competitive averages compared with supervised methods. 1. J. H. Yeo et al., “Where Visual Speech Meets Language: VSP-LLM Framework for Efficient and Context- Aware Visual Speech Processing.” ↩︎ [1] -
VSP-LLM: Observations The raw capability of the LLM matters a
lot Because it uses Llama 2, the model can sometimes loop and repeat words Clustering AV-HuBERT embeddings and then averaging them feels redundant If vectors are similar enough to cluster, why average them again? Later work sometimes reuses cached prototypes instead High scores on standard datasets, but real-world usage (e.g., webcam recordings) still seems challenging -
Zero-AVSR: Zero-Shot Audio-Visual Speech Recognition with LLMs by Learning Language-
Agnostic Speech Representations 1. J. H. Yeo, M. Kim, C. W. Kim, S. Petridis, and Y. M. Ro, “Zero-AVSR: Zero-Shot Audio-Visual Speech Recognition with LLMs by Learning Language-Agnostic Speech Representations,” July 21, 2025, arXiv: arXiv:2503.06273. doi: 10.48550/arXiv.2503.06273. ↩︎ [1] -
Zero-AVSR: Problem Statement Conventional audio-visual models depend on the languages
seen during training Existing multilingual audio-visual datasets cover only a handful of languages -
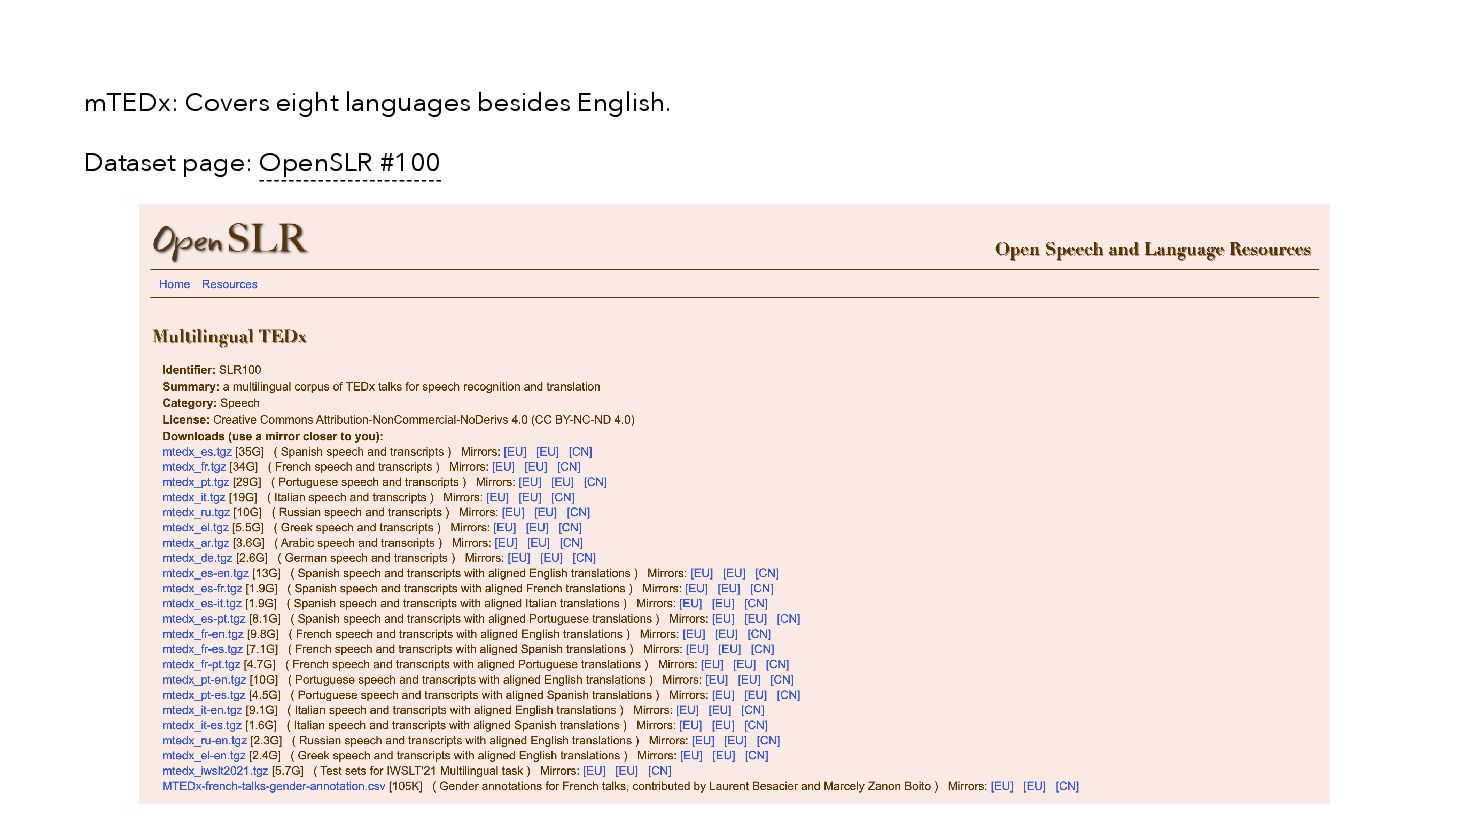
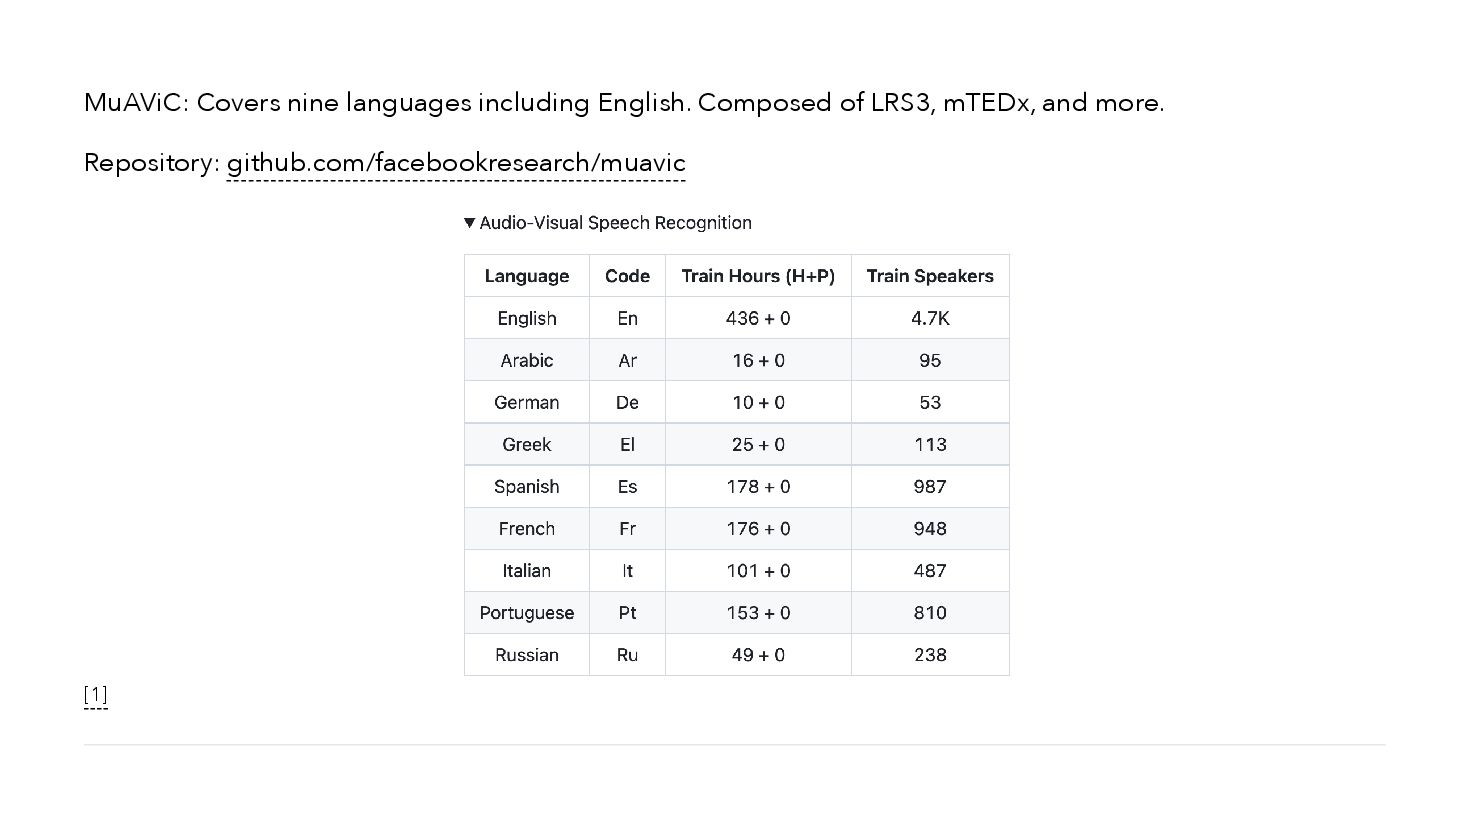
MuAViC: Covers nine languages including English. Composed of LRS3, mTEDx,
and more. Repository: github.com/facebookresearch/muavic [1] -
Zero-AVSR: Contributions Proposes the MARC dataset Demonstrates cross-lingual transfer potential
with the AV-HuBERT & Llama architecture Improves controllability by inserting a romanization module -
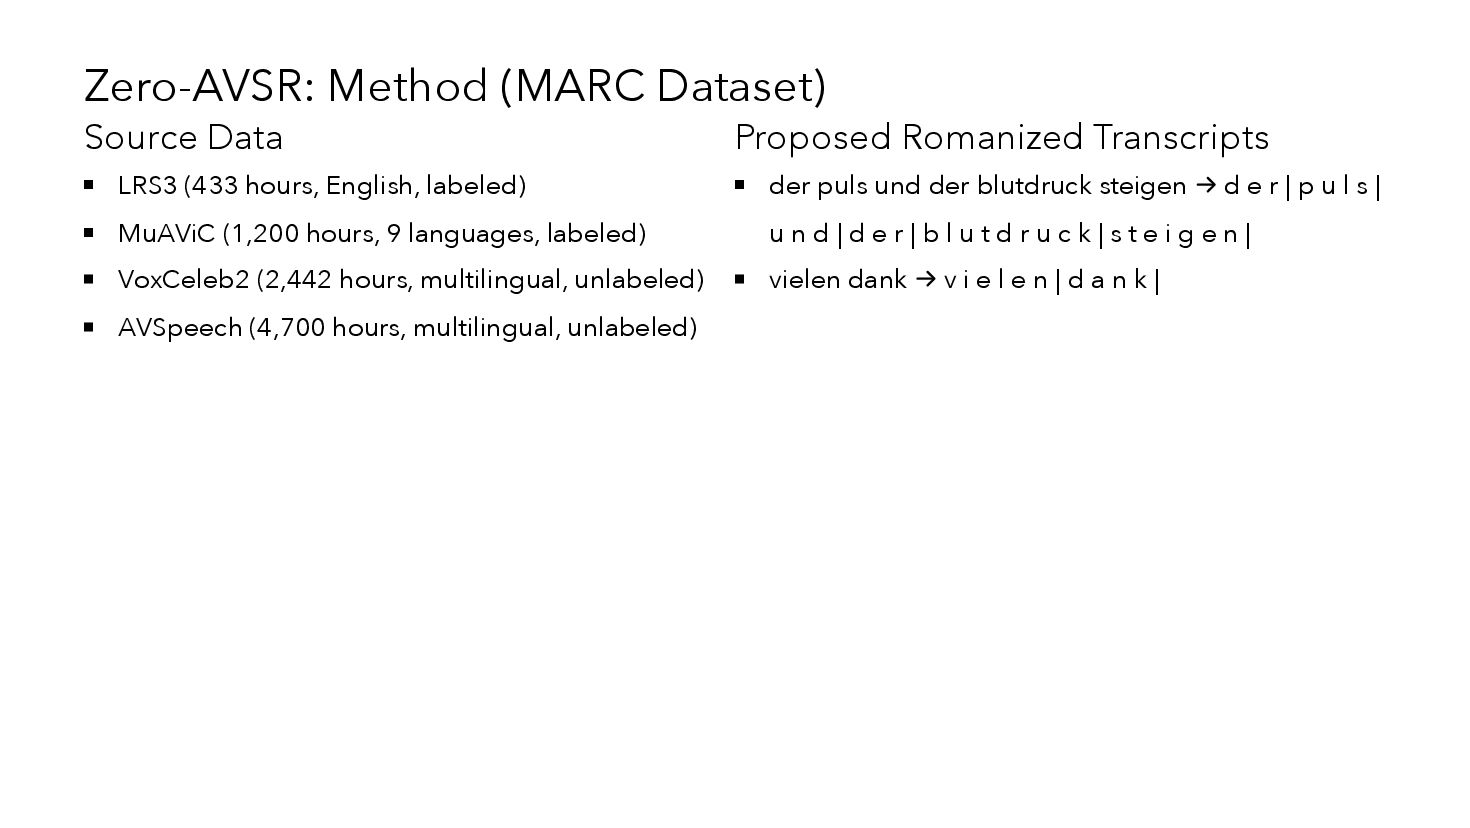
Zero-AVSR: Method (MARC Dataset) Source Data LRS3 (433 hours, English,
labeled) MuAViC (1,200 hours, 9 languages, labeled) VoxCeleb2 (2,442 hours, multilingual, unlabeled) AVSpeech (4,700 hours, multilingual, unlabeled) Proposed Romanized Transcripts der puls und der blutdruck steigen → d e r | p u l s | u n d | d e r | b l u t d r u c k | s t e i g e n | vielen dank → v i e l e n | d a n k | -
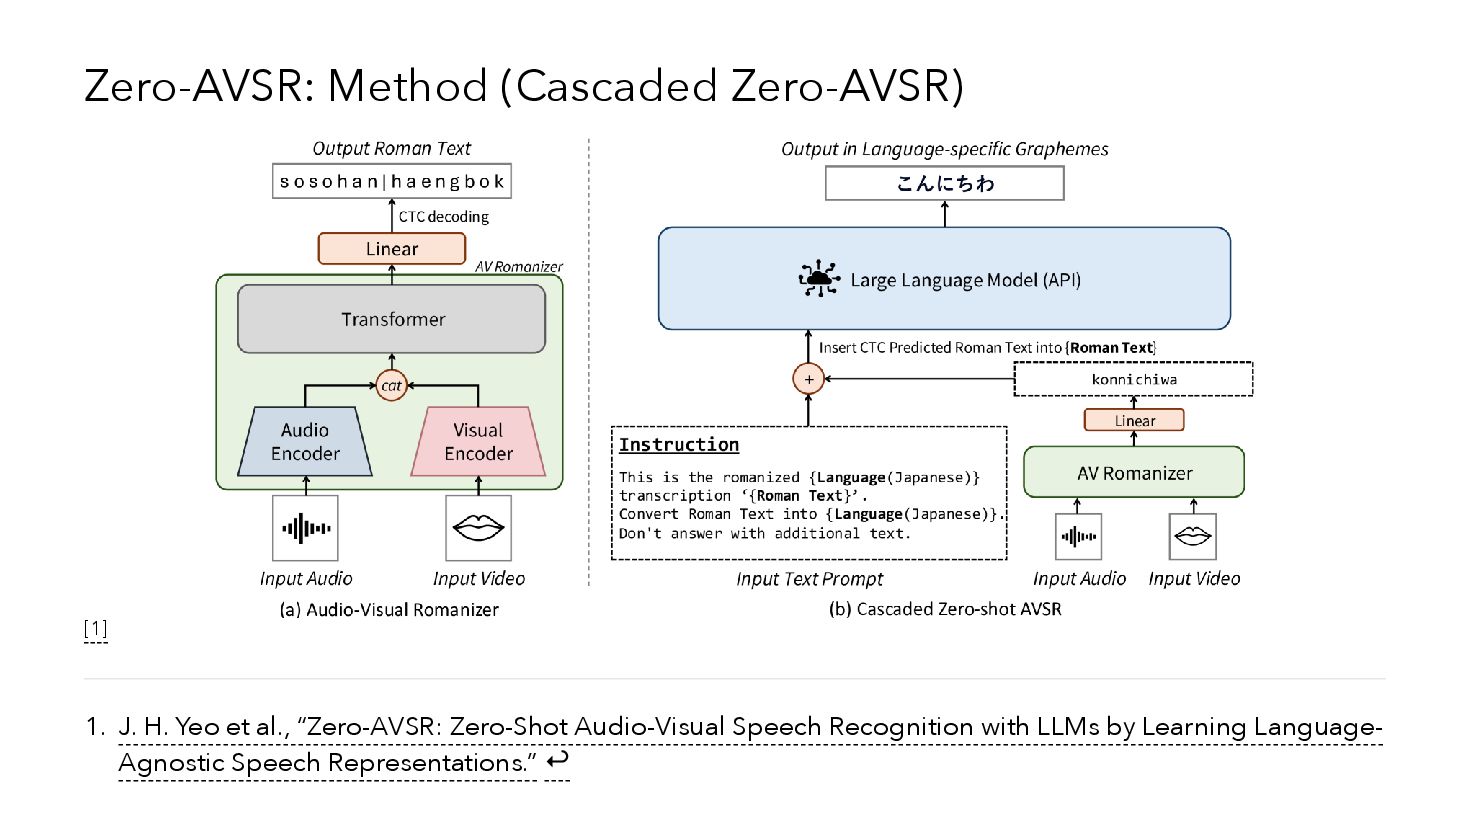
Zero-AVSR: Method (Cascaded Zero-AVSR) 1. J. H. Yeo et al.,
“Zero-AVSR: Zero-Shot Audio-Visual Speech Recognition with LLMs by Learning Language- Agnostic Speech Representations.” ↩︎ [1] -
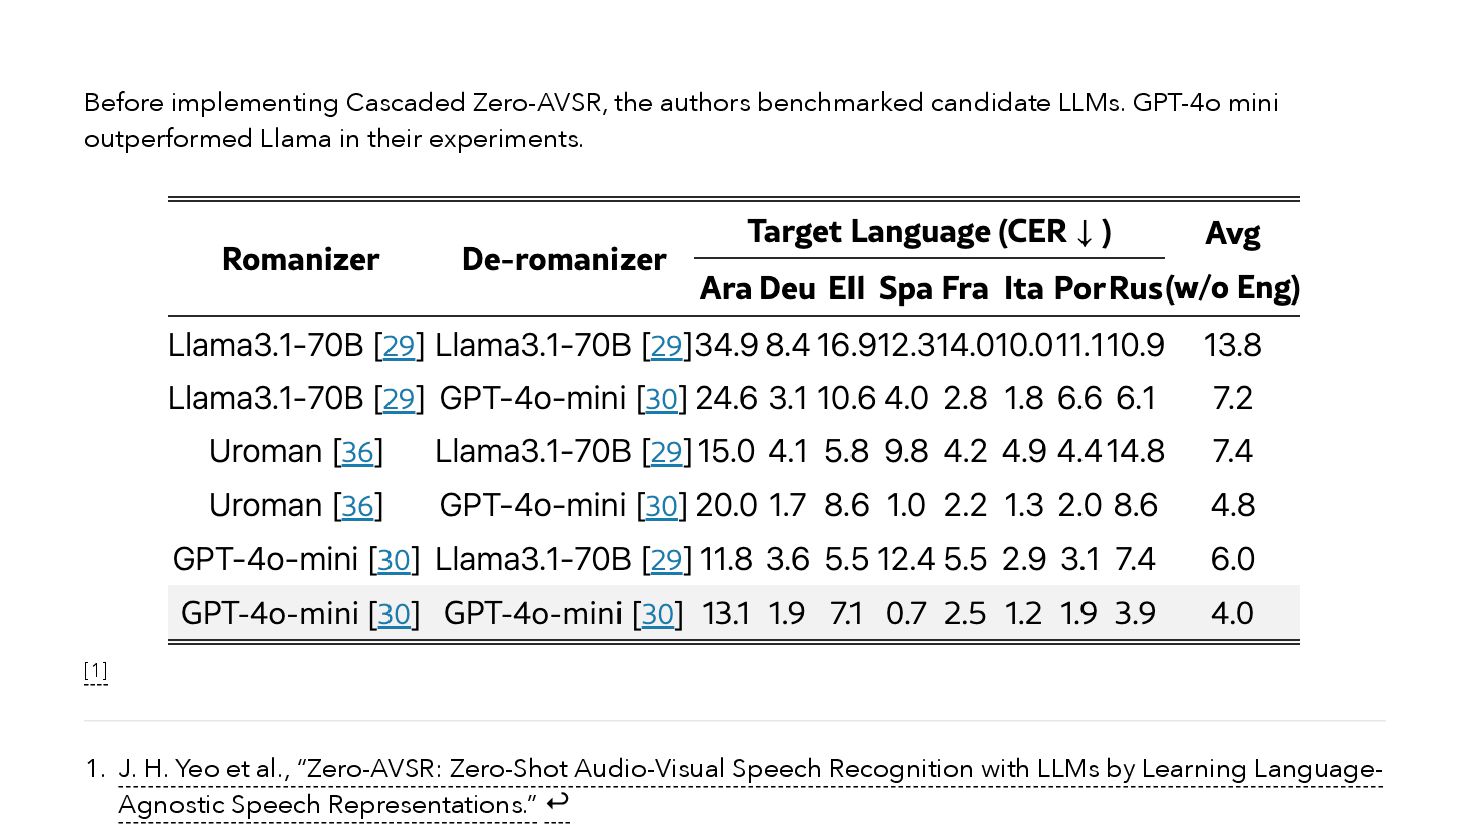
Before implementing Cascaded Zero-AVSR, the authors benchmarked candidate LLMs. GPT-4o
mini outperformed Llama in their experiments. 1. J. H. Yeo et al., “Zero-AVSR: Zero-Shot Audio-Visual Speech Recognition with LLMs by Learning Language- Agnostic Speech Representations.” ↩︎ [1] -
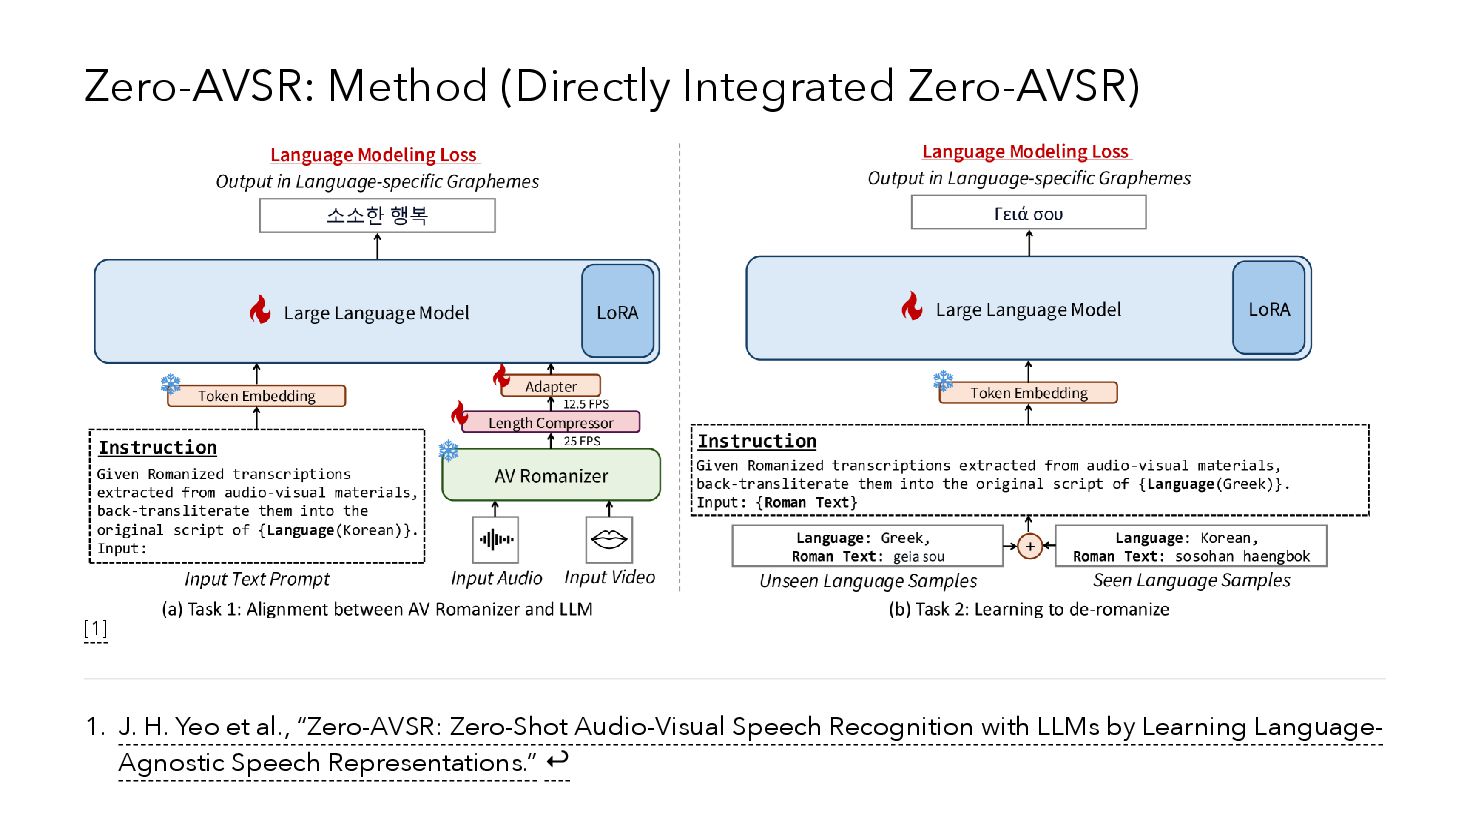
Zero-AVSR: Method (Directly Integrated Zero-AVSR) 1. J. H. Yeo et
al., “Zero-AVSR: Zero-Shot Audio-Visual Speech Recognition with LLMs by Learning Language- Agnostic Speech Representations.” ↩︎ [1] -
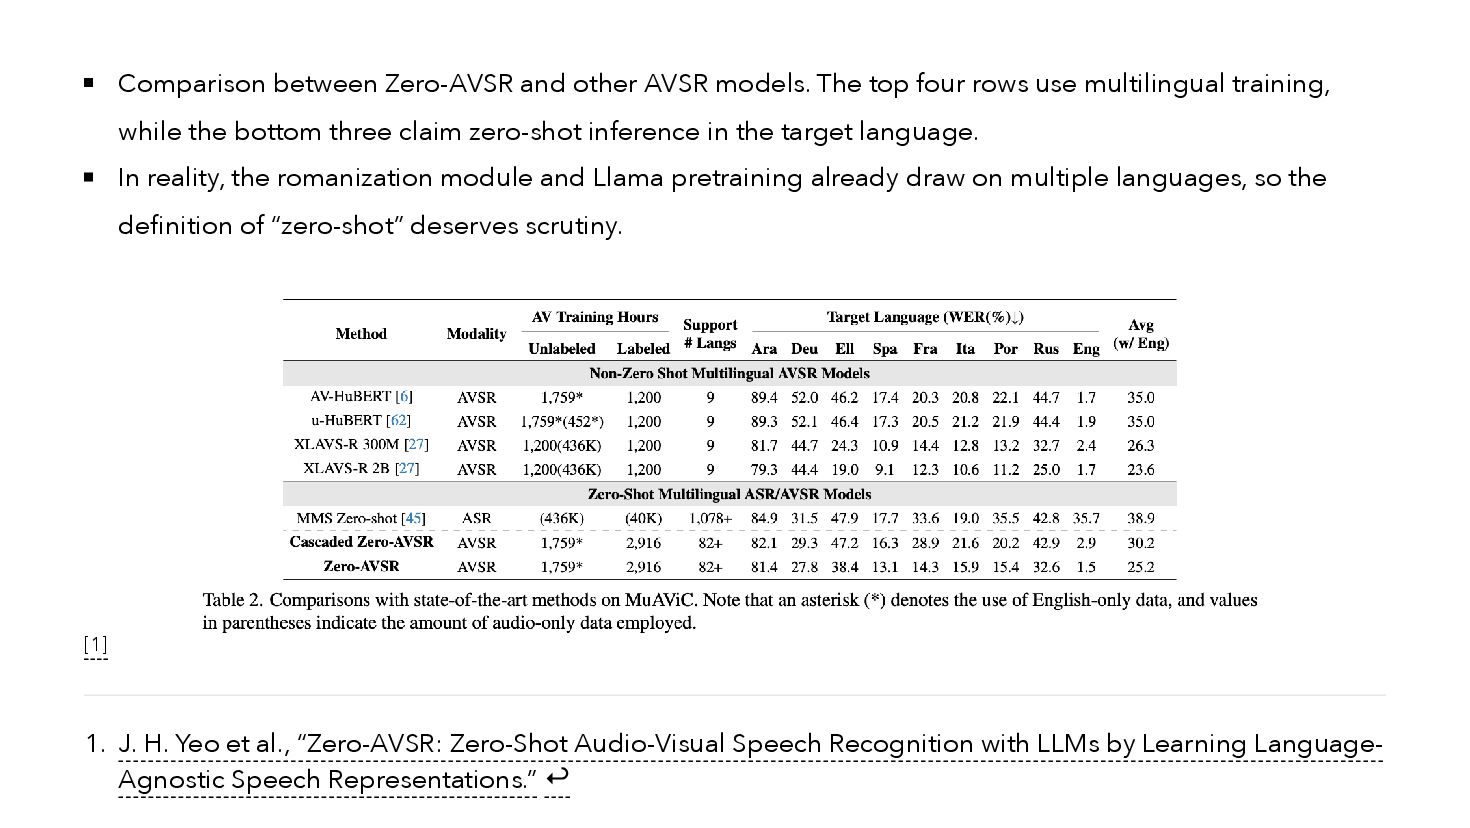
Comparison between Zero-AVSR and other AVSR models. The top four
rows use multilingual training, while the bottom three claim zero-shot inference in the target language. In reality, the romanization module and Llama pretraining already draw on multiple languages, so the definition of “zero-shot” deserves scrutiny. 1. J. H. Yeo et al., “Zero-AVSR: Zero-Shot Audio-Visual Speech Recognition with LLMs by Learning Language- Agnostic Speech Representations.” ↩︎ [1] -
Zero-AVSR: Observations Reinforces how powerful AV-HuBERT and Llama already are
Although the pipeline appears to romanize AV-HuBERT outputs before feeding Llama, the final architecture simply resamples AV-HuBERT embeddings Romanization is therefore less central (though useful for development and operations) The biggest takeaway for me: multilingual dataset training significantly shifts AV-HuBERT weights, suggesting room to scale with longer training -
Takeaways Lip reading (visual speech recognition) is increasingly adopting LLM-based
architectures instead of bespoke decoders Researchers are proposing diverse strategies for encoding video signals Many works aim to improve controllability via phonemes or romanization -
References (VSR/AVSR + LLM) #1 J. H. Yeo et al.,
“Where Visual Speech Meets Language: VSP-LLM Framework for Efficient and Context- Aware Visual Speech Processing,” May 14, 2024, arXiv: arXiv:2402.15151. doi: 10.48550/arXiv.2402.15151. J. H. Yeo et al., “Personalized Lip Reading: Adapting to Your Unique Lip Movements with Vision and Language,” Jan. 01, 2025, arXiv: arXiv:2409.00986. doi: 10.48550/arXiv.2409.00986. U. Cappellazzo et al., “Large Language Models Are Strong Audio-Visual Speech Recognition Learners,” Mar. 07, 2025, arXiv: arXiv:2409.12319. doi: 10.48550/arXiv.2409.12319. -
References (VSR/AVSR + LLM) #2 J. H. Yeo et al.,
“Zero-AVSR: Zero-Shot Audio-Visual Speech Recognition with LLMs by Learning Language- Agnostic Speech Representations,” July 21, 2025, arXiv: arXiv:2503.06273. doi: 10.48550/arXiv.2503.06273. J. H. Yeo et al., “MMS-LLaMA: Efficient LLM-based Audio-Visual Speech Recognition with Minimal Multimodal Speech Tokens,” June 05, 2025, arXiv: arXiv:2503.11315. doi: 10.48550/arXiv.2503.11315. M. Thomas et al., “VALLR: Visual ASR Language Model for Lip Reading,” Mar. 27, 2025, arXiv: arXiv:2503.21408. doi: 10.48550/arXiv.2503.21408. M. K. K. Teng et al., “Phoneme-Level Visual Speech Recognition via Point-Visual Fusion and Language Model Reconstruction,” July 25, 2025, arXiv: arXiv:2507.18863. doi: 10.48550/arXiv.2507.18863. -
References (Base Models, Datasets, Surveys) B. Shi et al., “Learning
Audio-Visual Speech Representation by Masked Multimodal Cluster Prediction,” Mar. 13, 2022, arXiv: arXiv:2201.02184. doi: 10.48550/arXiv.2201.02184. E. Salesky et al., “The Multilingual TEDx Corpus for Speech Recognition and Translation,” June 15, 2021, arXiv: arXiv:2102.01757. doi: 10.48550/arXiv.2102.01757. M. Anwar et al., “MuAViC: A Multilingual Audio-Visual Corpus for Robust Speech Recognition and Robust Speech-to-Text Translation,” Mar. 07, 2023, arXiv: arXiv:2303.00628. doi: 10.48550/arXiv.2303.00628. K. Rezaee and M. Yeganeh, “Automatic Visual Lip Reading: A Comparative Review of Machine-Learning Approaches,” Results in Engineering, p. 107171, Sept. 2025, doi: 10.1016/j.rineng.2025.107171.