Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
TAID: Temporally Adaptive Interpolated Distilla...
Search
ほき
March 22, 2025
Research
41
0
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
TAID: Temporally Adaptive Interpolated Distillation for Efficient Knowledge Transfer in Language Models
ほき
March 22, 2025
More Decks by ほき
See All by ほき
Expert-Level Detection of Epilepsy Markers in EEG on Short and Long Timescales
hokkey621
0
45
MMaDA: Multimodal Large Diffusion Language Models
hokkey621
0
42
脳波を用いた嗜好マッチングシステム
hokkey621
0
540
DeepSeek-R1: Incentivizing Reasoning Capability in LLMs via Reinforcement Learning
hokkey621
0
120
Learning to Model the World with Language
hokkey621
0
50
GeminiとUnityで実現するインタラクティブアート
hokkey621
0
1.8k
LT - Gemma Developer Time
hokkey621
0
35
wav2vec 2.0: A Framework for Self-Supervised Learning of Speech Representations
hokkey621
0
46
イベントを主催してわかった運営のノウハウ
hokkey621
0
87
Other Decks in Research
See All in Research
TESSERA: Temporal Embeddings of Surface Spectra for Earth Representation and Analysis
satai
2
100
ros2-perf-multihost: 分散システムにおける客観的なアーキテクチャ評価フレームワーク
takasehideki
0
280
JICA QUEST 共創×革新プログラム Impact Report(海ノ向こうコーヒー)
ontheslope
0
730
2026年6月_副業コンプライアンス調査_業界別リスク度分析_株式会社フクスケ.pdf
fkske
0
110
大規模言語モデルは誰を覚えているか / Who Do Large Language Models Memorize?
upura
0
200
論文紹介: Understanding Epistemic Language with a Language-augmented Bayesian Theory of Mind
hisaokatsumi
0
170
Visual SLAM未来予測 / Future Prediction in Visual SLAM
koide3
1
1.1k
[SNLP2026] Scaling up Test-Time Compute with Latent Reasoning: A Recurrent Depth Approach
wataruuuuu
0
320
Claude Code × autoresearch 実践
mathbullet
0
290
Développer des solutions de réduction des émissions de méthane entérique : 1ers résultats Méthane 2030
institudelelevage
PRO
0
200
全国町字単位空き家率推定データver1.0データ仕様
microbaseinc
0
270
データサイエンティストの就労意識~2015 → 2026 一般(個人)会員アンケートより
datascientistsociety
PRO
0
940
Featured
See All Featured
Marketing to machines
jonoalderson
1
5.8k
Building AI with AI
inesmontani
PRO
1
1.3k
Winning Ecommerce Organic Search in an AI Era - #searchnstuff2025
aleyda
2
2.2k
Abbi's Birthday
coloredviolet
4
10k
Performance Is Good for Brains [We Love Speed 2024]
tammyeverts
12
1.9k
Design of three-dimensional binary manipulators for pick-and-place task avoiding obstacles (IECON2024)
konakalab
0
610
Unsuck your backbone
ammeep
672
58k
Joys of Absence: A Defence of Solitary Play
codingconduct
1
530
svc-hook: hooking system calls on ARM64 by binary rewriting
retrage
2
600
The untapped power of vector embeddings
frankvandijk
2
1.9k
Keith and Marios Guide to Fast Websites
keithpitt
413
23k
From Legacy to Launchpad: Building Startup-Ready Communities
dugsong
0
340
Transcript
https://www.academix.jp/ AcademiX 論文輪読会 TAID: Temporally Adaptive Interpolated Distillation for Efficient
Knowledge Transfer in Language Models ほき 2025/03/22
書誌情報 • TAID: Temporally Adaptive Interpolated Distillation for Efficient Knowledge
Transfer in Language Models • Makoto Shing, Kou Misaki, Han Bao, Sho Yokoi, Takuya Akiba • ICLR 2025 • https://doi.org/10.48550/arXiv.2501.16937 ※本スライドの図は本論文またはSakana AIのテックブログより引用 2
LMsの活用と課題 • LMsは様々な分野で重要なツール • LMsは広く導入するには課題有り ◦ モデルサイズが大きすぎる ◦ デコード時間が長すぎる ◦
学習や推論に必要なエネルギー多すぎる • 大規模モデルを圧縮して小規模なモデルにしたい 3
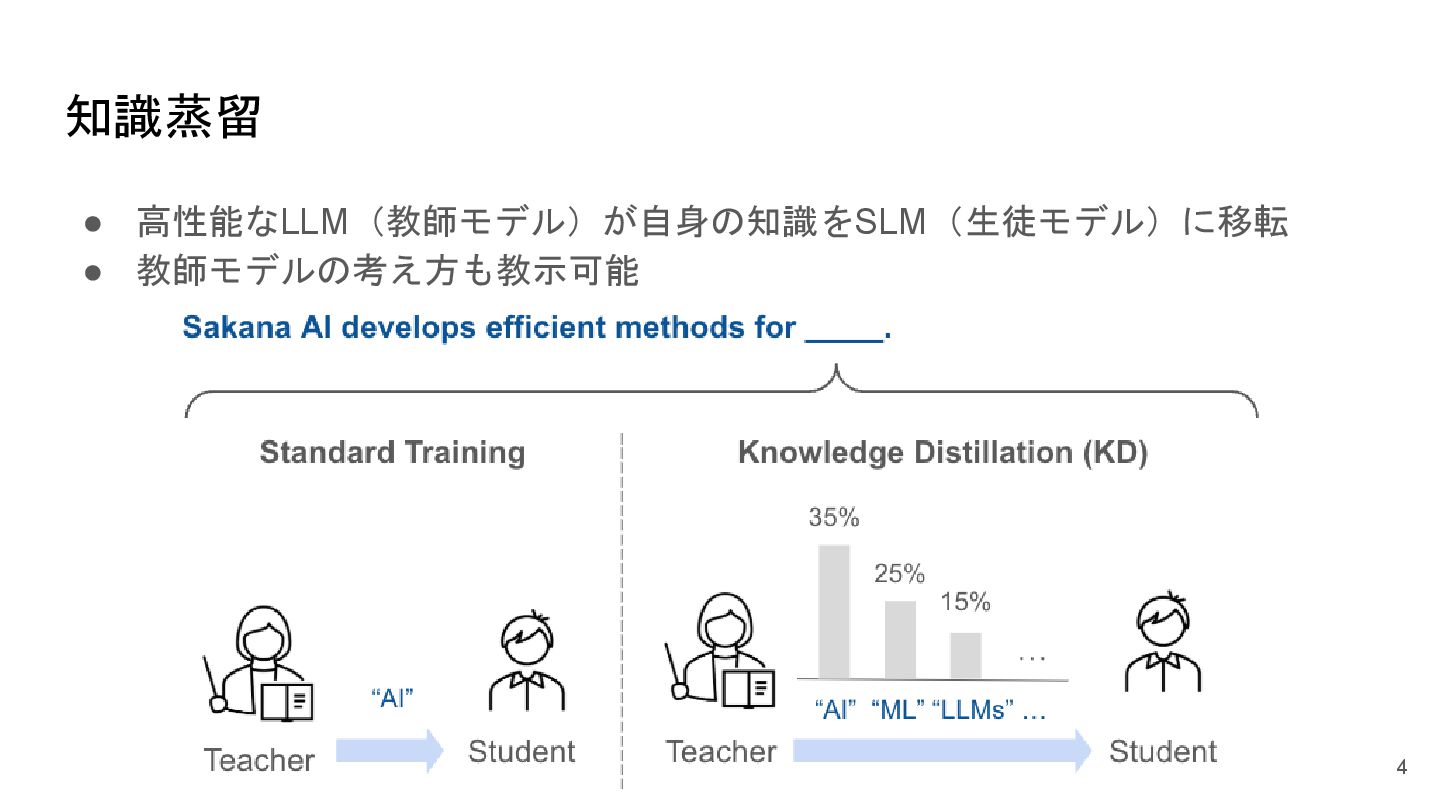
知識蒸留 • 高性能なLLM(教師モデル)が自身の知識をSLM(生徒モデル)に移転 • 教師モデルの考え方も教示可能 4
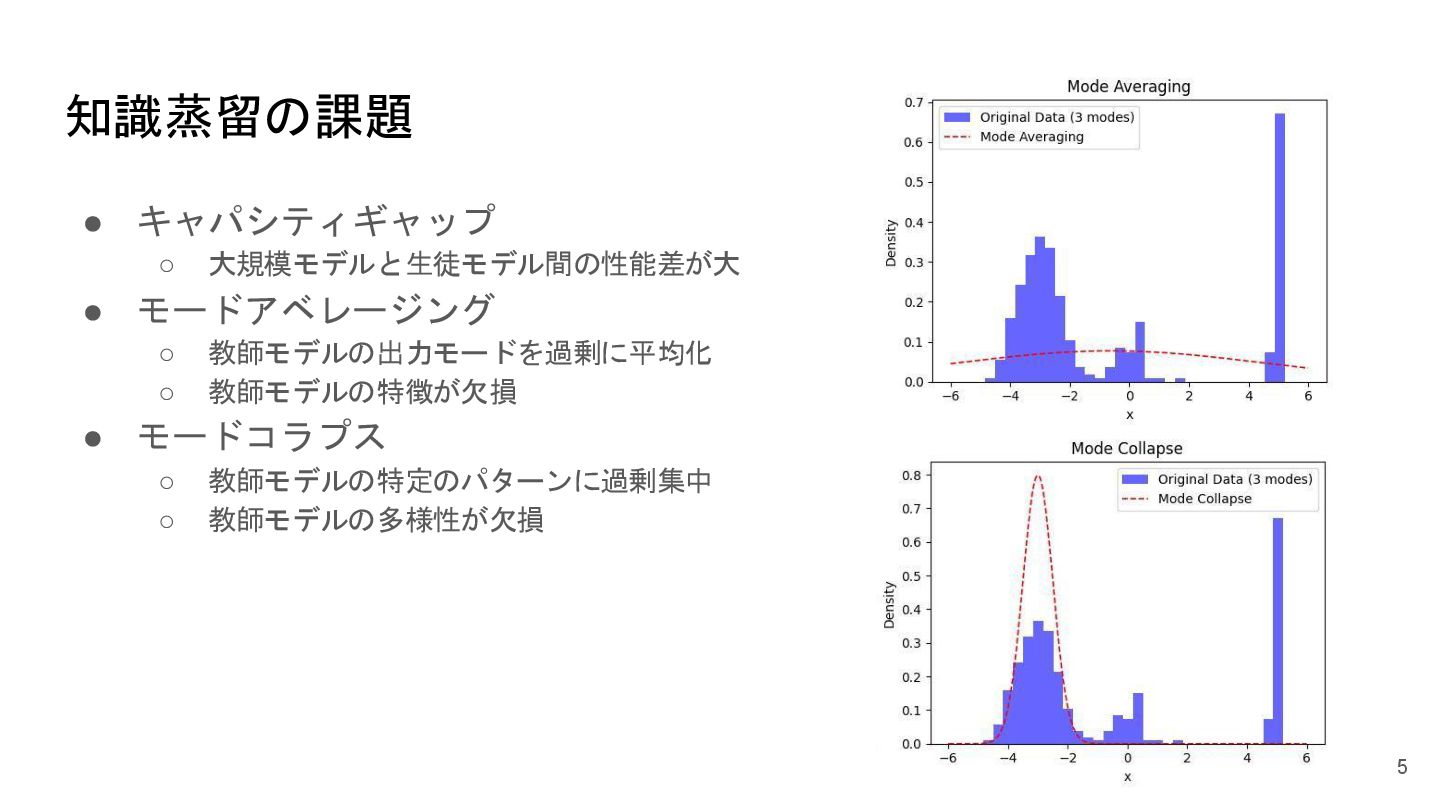
知識蒸留の課題 • キャパシティギャップ ◦ 大規模モデルと生徒モデル間の性能差が大 • モードアベレージング ◦ 教師モデルの出力モードを過剰に平均化 ◦
教師モデルの特徴が欠損 • モードコラプス ◦ 教師モデルの特定のパターンに過剰集中 ◦ 教師モデルの多様性が欠損 5
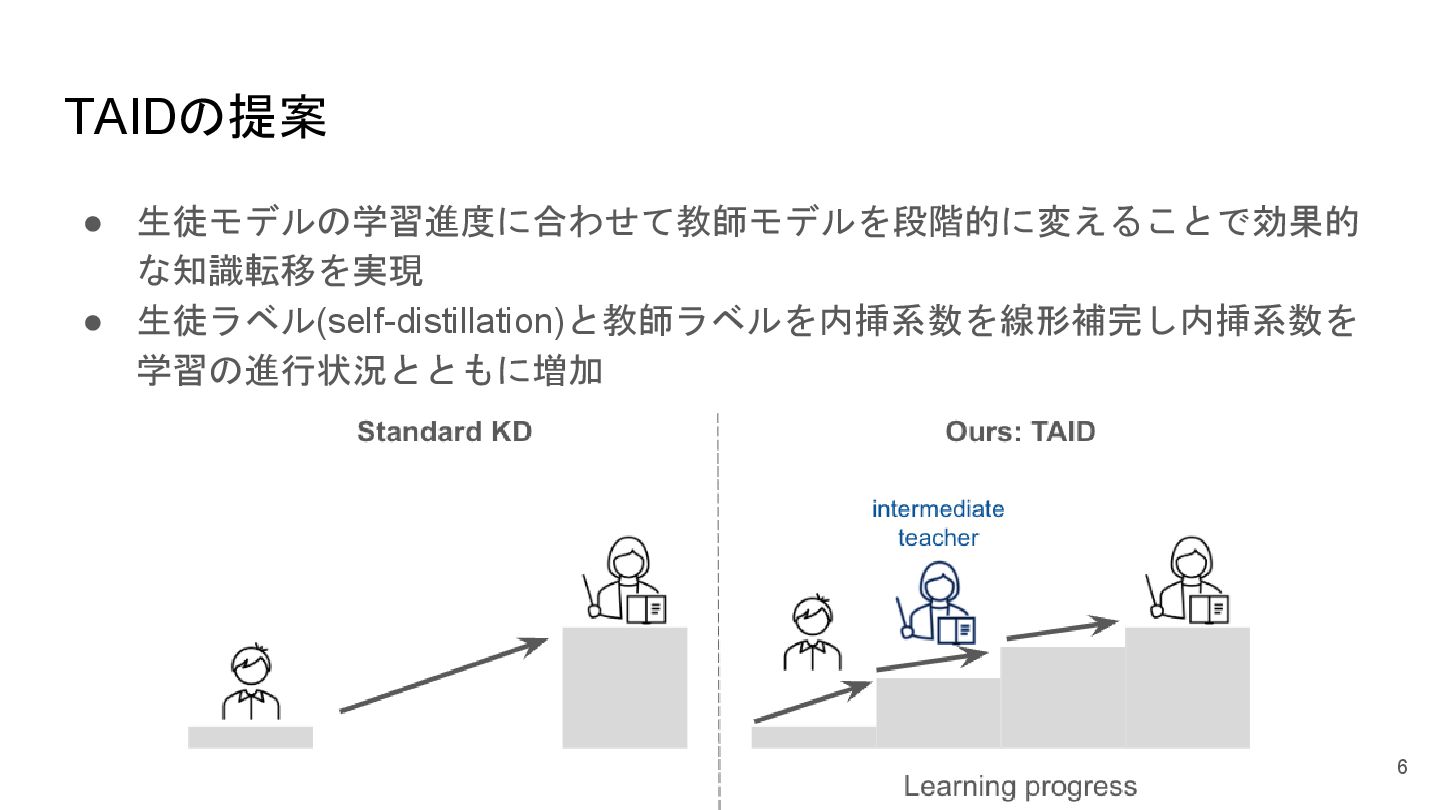
TAIDの提案 • 生徒モデルの学習進度に合わせて教師モデルを段階的に変えることで効果的 な知識転移を実現 • 生徒ラベル(self-distillation)と教師ラベルを内挿系数を線形補完し内挿系数を 学習の進行状況とともに増加 6
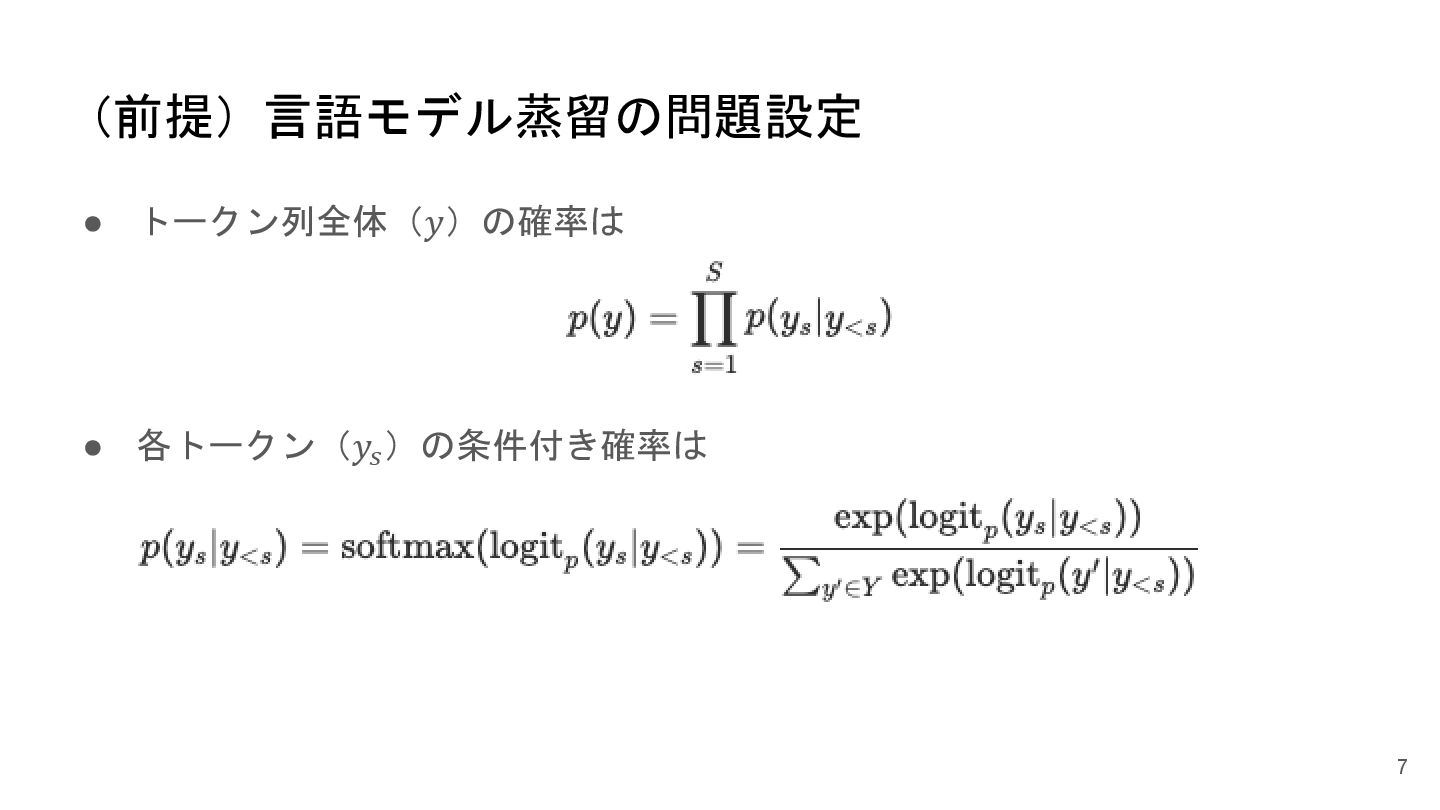
(前提)言語モデル蒸留の問題設定 • トークン列全体(𝑦)の確率は 7 • 各トークン(𝑦𝑠 )の条件付き確率は
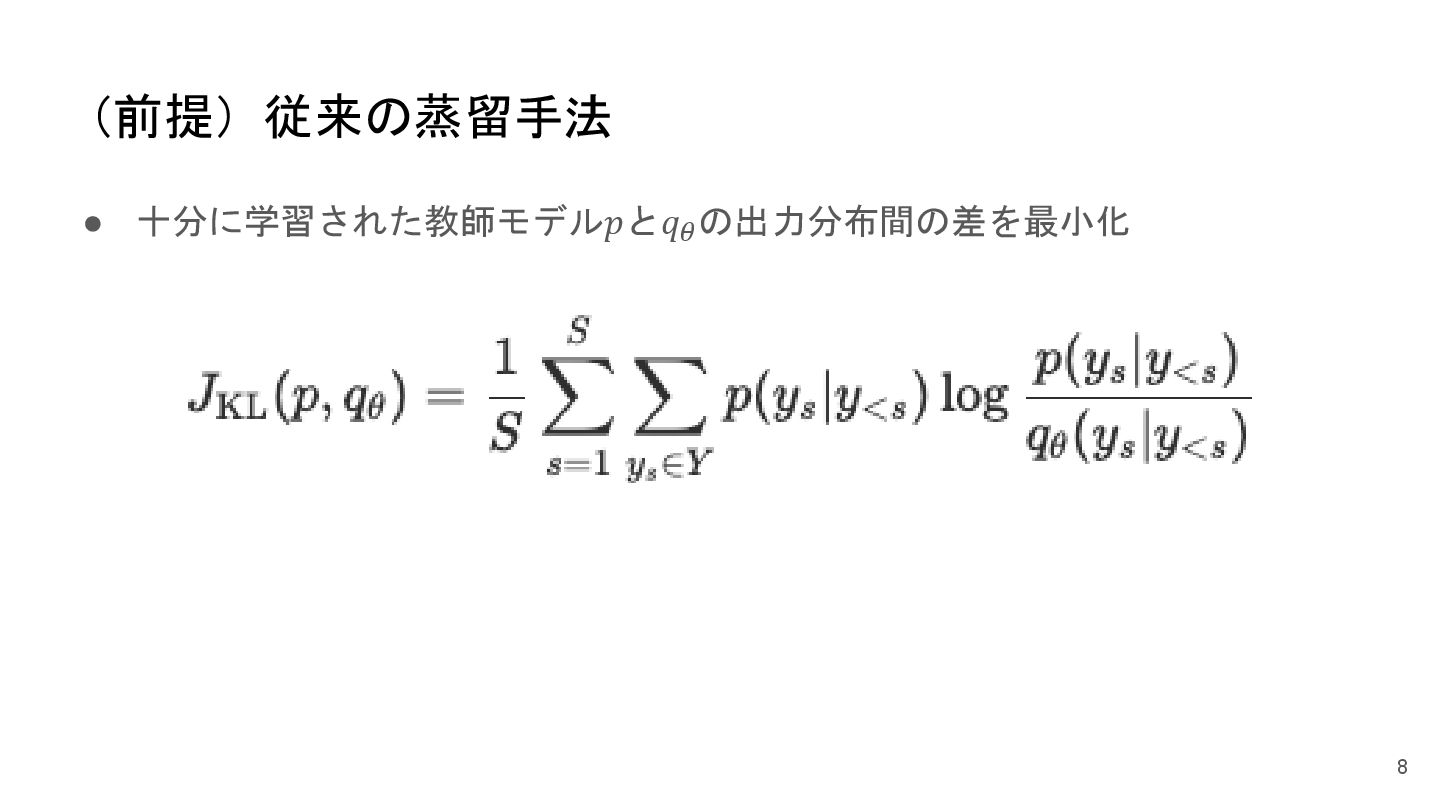
(前提)従来の蒸留手法 • 十分に学習された教師モデル𝑝と𝑞𝜃 の出力分布間の差を最小化 8
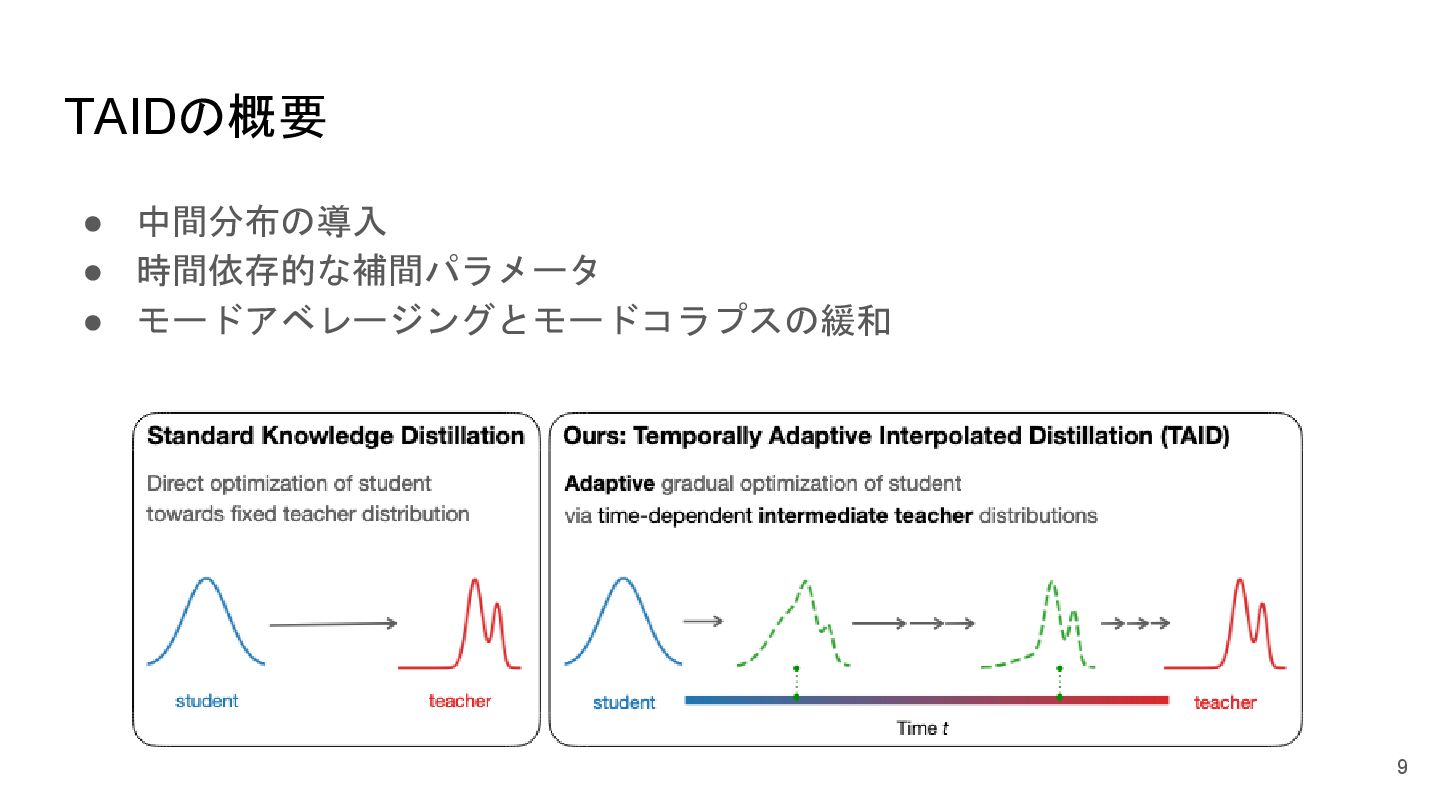
TAIDの概要 • 中間分布の導入 • 時間依存的な補間パラメータ • モードアベレージングとモードコラプスの緩和 9
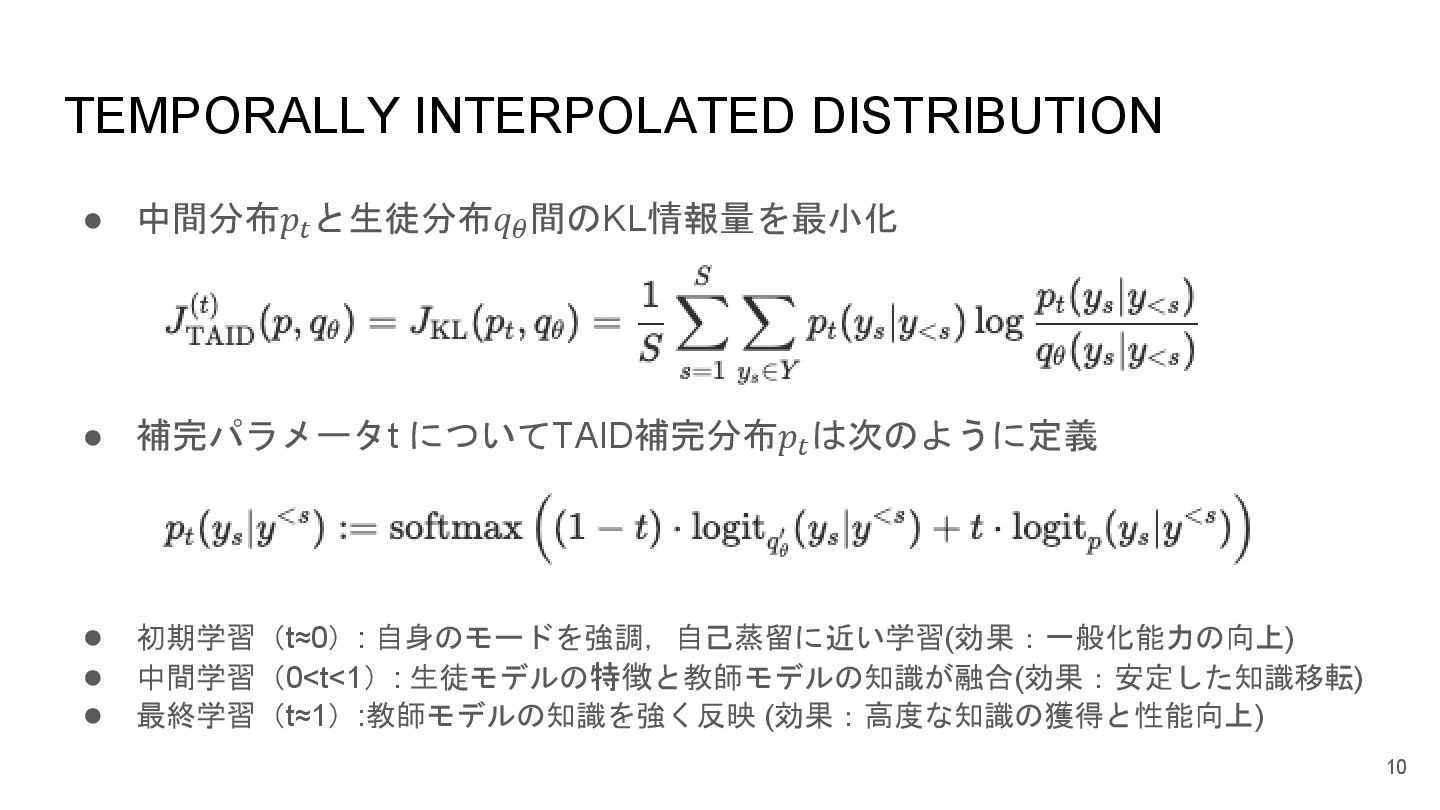
TEMPORALLY INTERPOLATED DISTRIBUTION • 中間分布𝑝𝑡 と生徒分布𝑞𝜃 間のKL情報量を最小化 10 • 補完パラメータt
についてTAID補完分布𝑝𝑡 は次のように定義 • 初期学習(t≈0): 自身のモードを強調,自己蒸留に近い学習(効果:一般化能力の向上) • 中間学習(0<t<1): 生徒モデルの特徴と教師モデルの知識が融合(効果:安定した知識移転) • 最終学習(t≈1):教師モデルの知識を強く反映 (効果:高度な知識の獲得と性能向上)
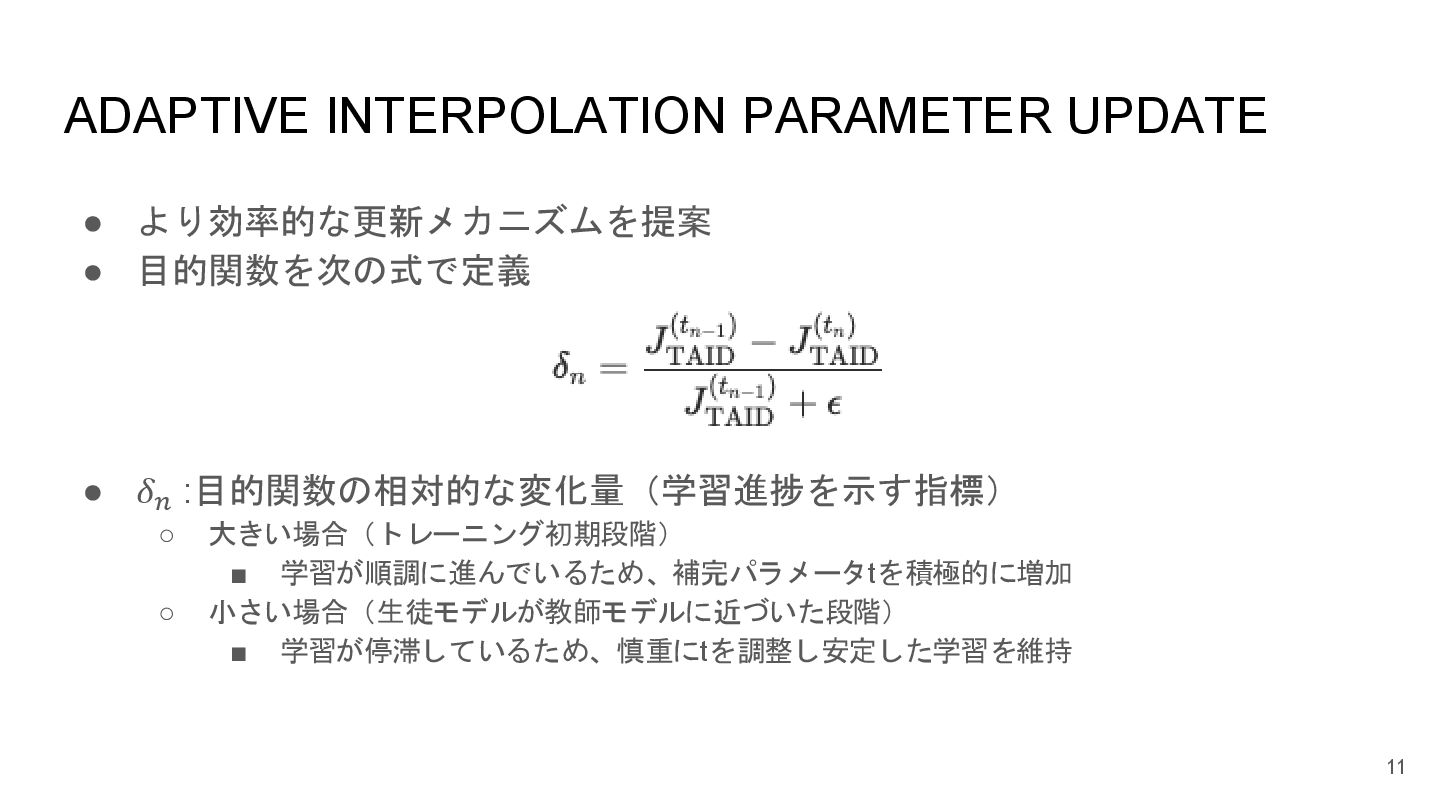
ADAPTIVE INTERPOLATION PARAMETER UPDATE • より効率的な更新メカニズムを提案 • 目的関数を次の式で定義 11 •
𝛿𝑛 :目的関数の相対的な変化量(学習進捗を示す指標) ◦ 大きい場合(トレーニング初期段階) ▪ 学習が順調に進んでいるため、補完パラメータtを積極的に増加 ◦ 小さい場合(生徒モデルが教師モデルに近づいた段階) ▪ 学習が停滞しているため、慎重にtを調整し安定した学習を維持
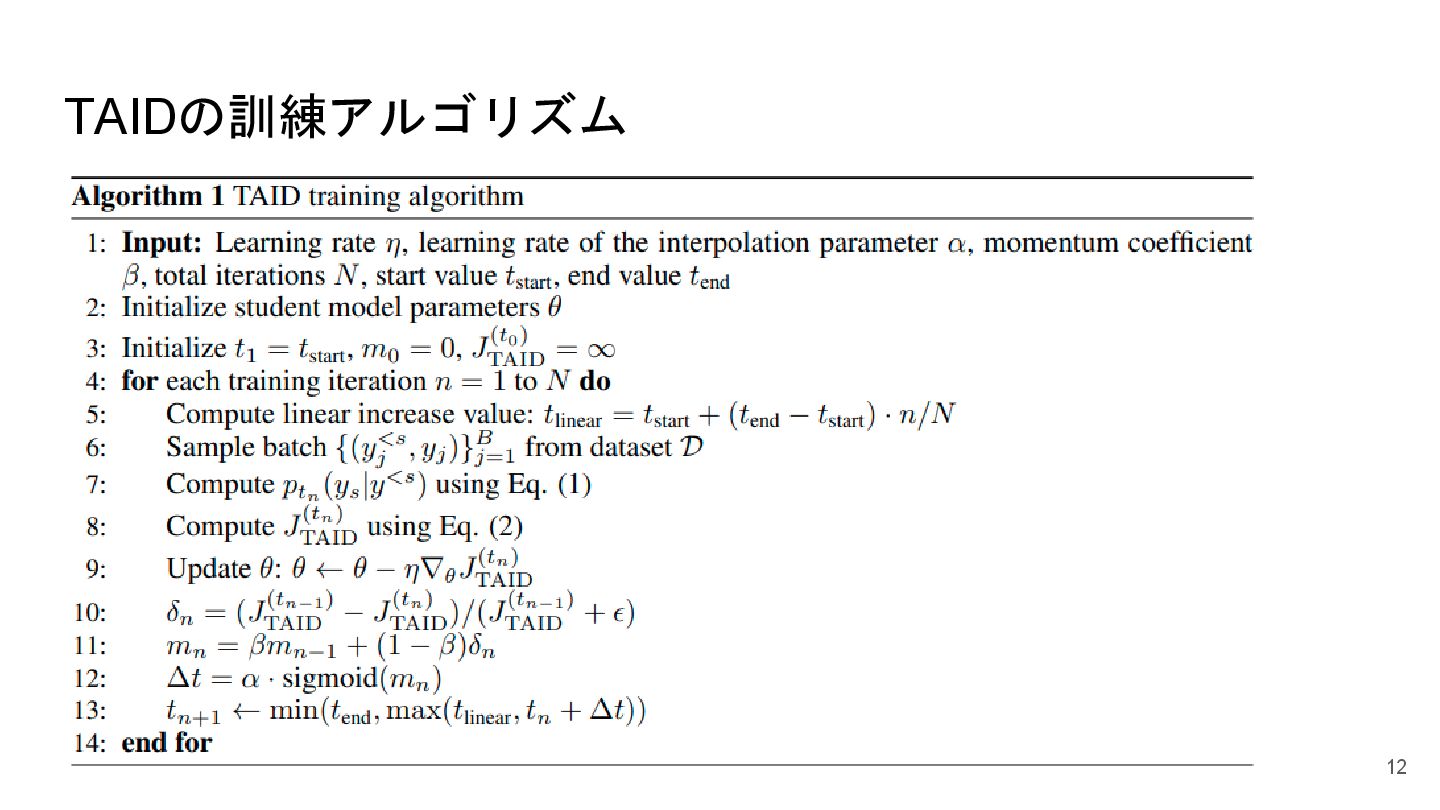
TAIDの訓練アルゴリズム 12
モード崩壊についての理論的分析 • ごめんなさいよくわからなかったので論文を見てください 13
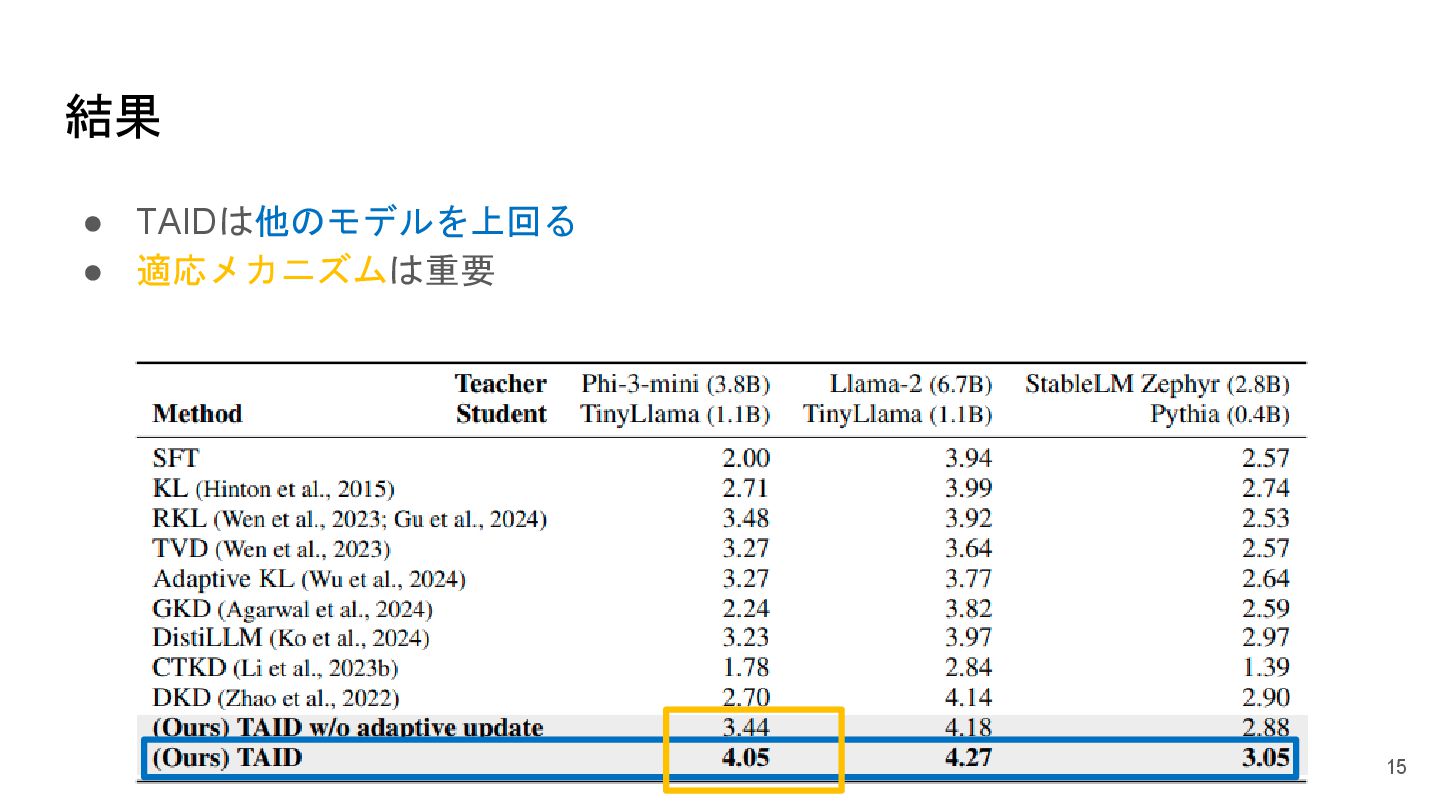
指示チューニングの実験 • 目的:モデルの性能を評価 • ベンチマーク:MT-Bench [Zheng, 2023] • 使用モデル 14
教師モデル 生徒モデル Phi-3-mini-4k-instruct TinyLlama Llama-2-7b-chat TinyLlama StableLM Zephyr 3B Pythia-410M
結果 • TAIDは他のモデルを上回る • 適応メカニズムは重要 15
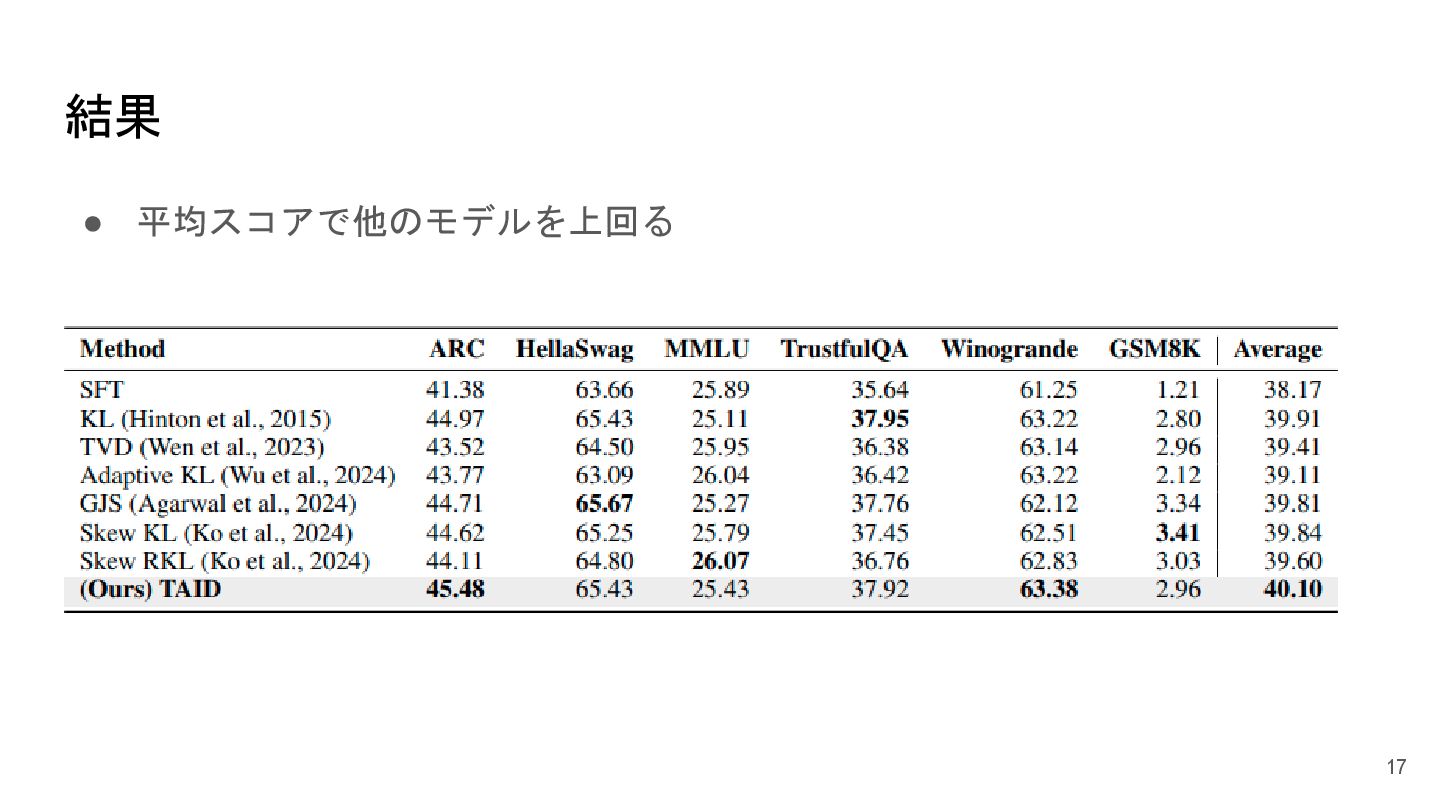
事前学習実験 • 目的:知識蒸留の効果を評価 • ベンチマーク:6つの異なるタスクを含む評価セット • 方法:Few-shot 評価に基づきモデルの基礎能力をテスト • 使用モデル
◦ 教師モデル:Phi-3-medium-4k-instruct ◦ 生徒モデル:TinyLlama 16
結果 • 平均スコアで他のモデルを上回る 17
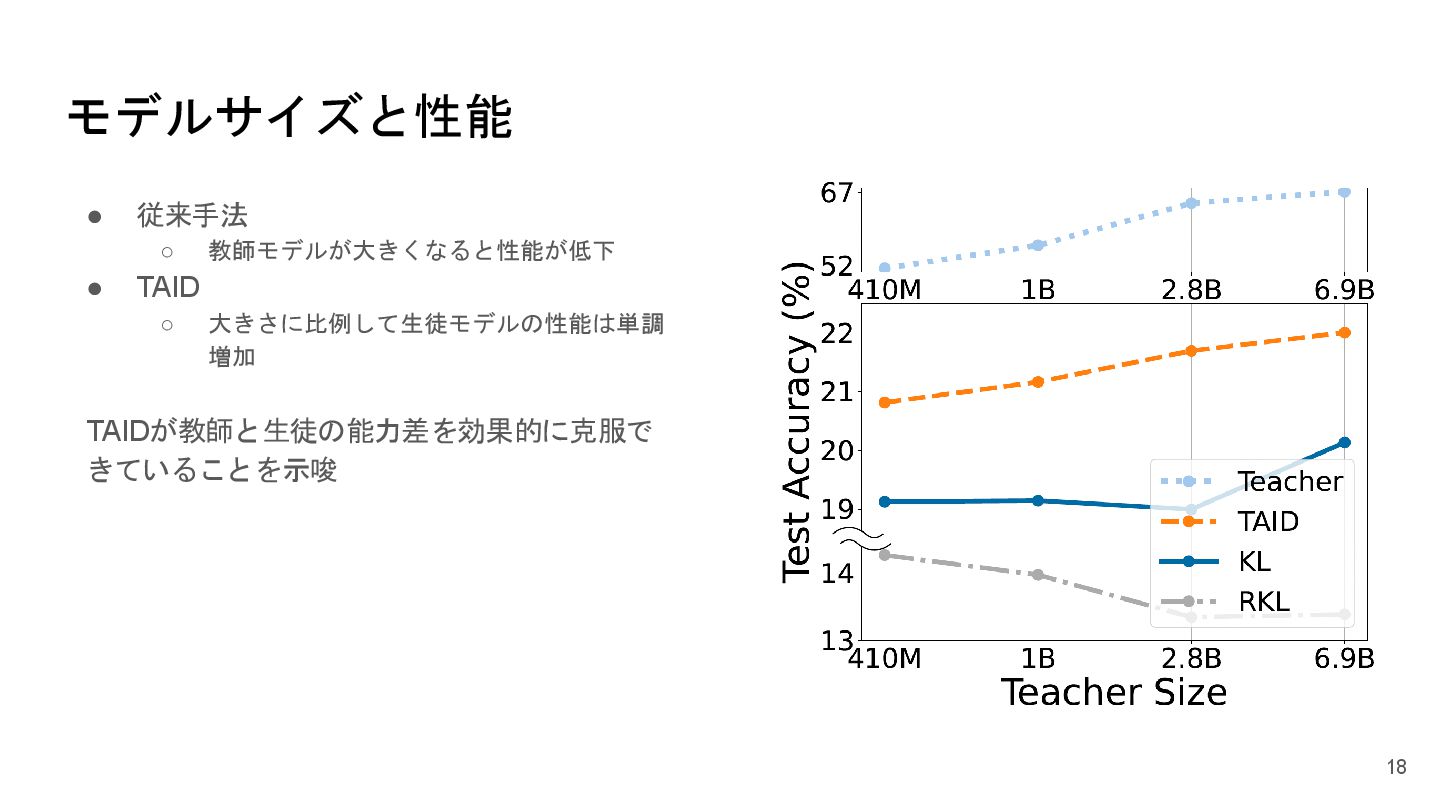
モデルサイズと性能 • 従来手法 ◦ 教師モデルが大きくなると性能が低下 • TAID ◦ 大きさに比例して生徒モデルの性能は単調 増加
TAIDが教師と生徒の能力差を効果的に克服で きていることを示唆 18
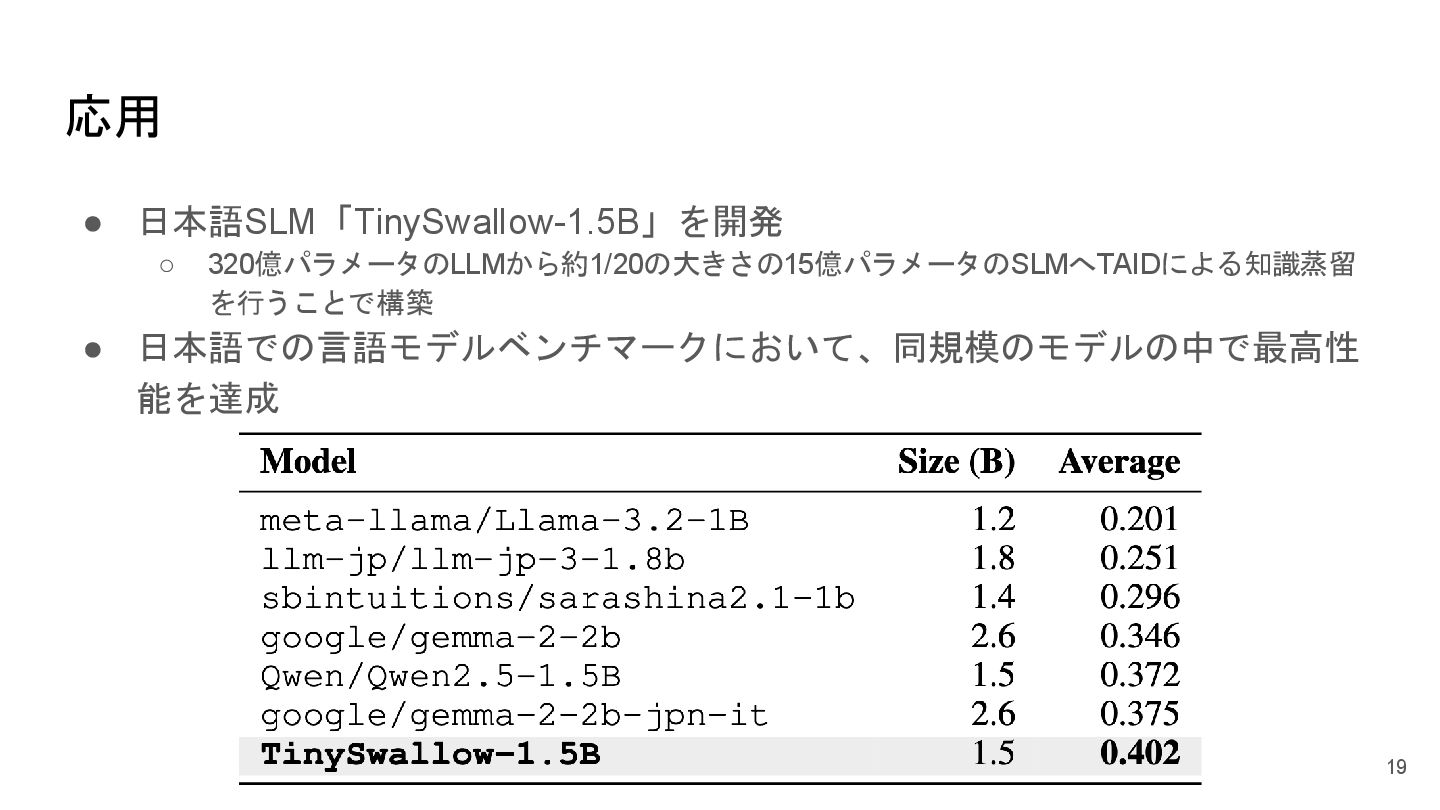
応用 • 日本語SLM「TinySwallow-1.5B」を開発 ◦ 320億パラメータのLLMから約1/20の大きさの15億パラメータのSLMへTAIDによる知識蒸留 を行うことで構築 • 日本語での言語モデルベンチマークにおいて、同規模のモデルの中で最高性 能を達成 19
まとめ • 大規模言語モデルの課題を知識蒸留を使って解決 • 中間分布を活用することによって蒸留の課題に対処 • ほかモデルを上回る結果を達成 20


 hokkey621
 satai
 takasehideki
 ontheslope
 fkske
 upura
 hisaokatsumi
 koide3
 wataruuuuu
 mathbullet
 institudelelevage
 microbaseinc
 datascientistsociety
 jonoalderson
 inesmontani
 aleyda
 coloredviolet
 tammyeverts
 konakalab
 ammeep
 codingconduct
 retrage
 frankvandijk
 keithpitt
 dugsong