Share
Conquering the crawl: How to get indexed in an AI world #EngagePDX
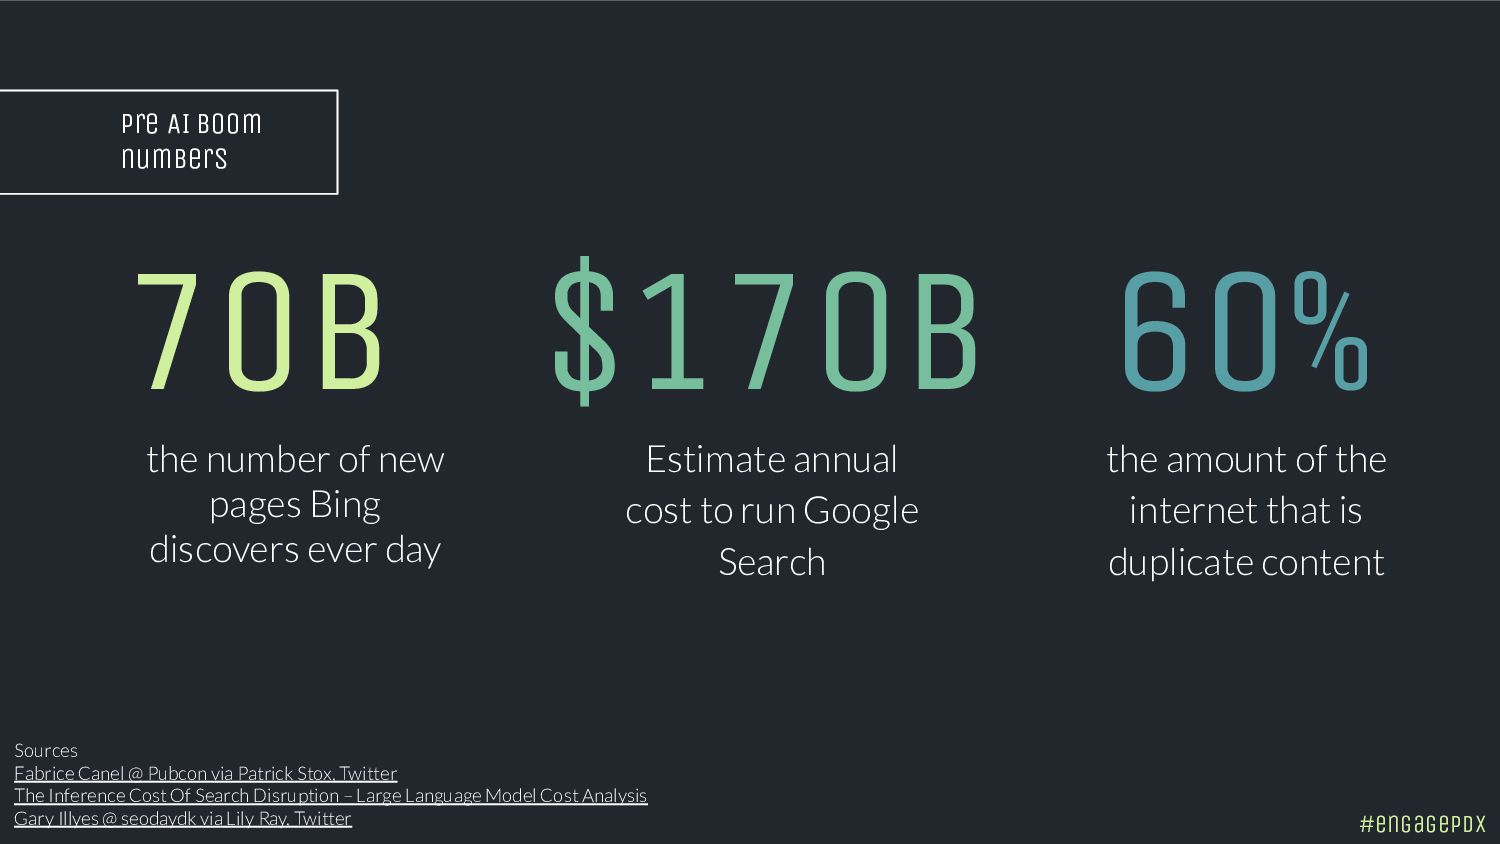
In 2022, Googler Gary Illyes said 60% of the web is duplicate content. The next year, Bing discovered 70 billion new pages daily. That was before generative AI exploded. The latest studies estimate that 400 million terabytes of content are created daily. Now Google wants to crawl less. Getting indexed is the new boss fight and ChatGPT isn't going to save you.
Join Jamie Indigo, Director of Technical SEO for Cox Automotive, for this session where she'll share actionable strategies to help you ensure your pages will be crawled by Google and avoid traps that will negatively affect your ranking.
After this session, you'll be able to:
- Understand Google's new crawl priorities
- Know what makes your site worth a search engine's investment
- Spot hidden indexing traps and crawling perils
- Control the configurations to curate your index
Jamie Indigo
Transcript
79 slides
-
Conquering the Crawl How to get indexed in an AI
world #engagePDX -
Welcome to your Jammerbot Audience Guide: • Not a robot;
speaks bot • Director of Technical SEO at Cox Automotive • Excitable nerd from New York (phones up is my cue to pause) • ⅕ of Notorious RBG (the stabby part) • /in/jamie-indigo #engagePDX -
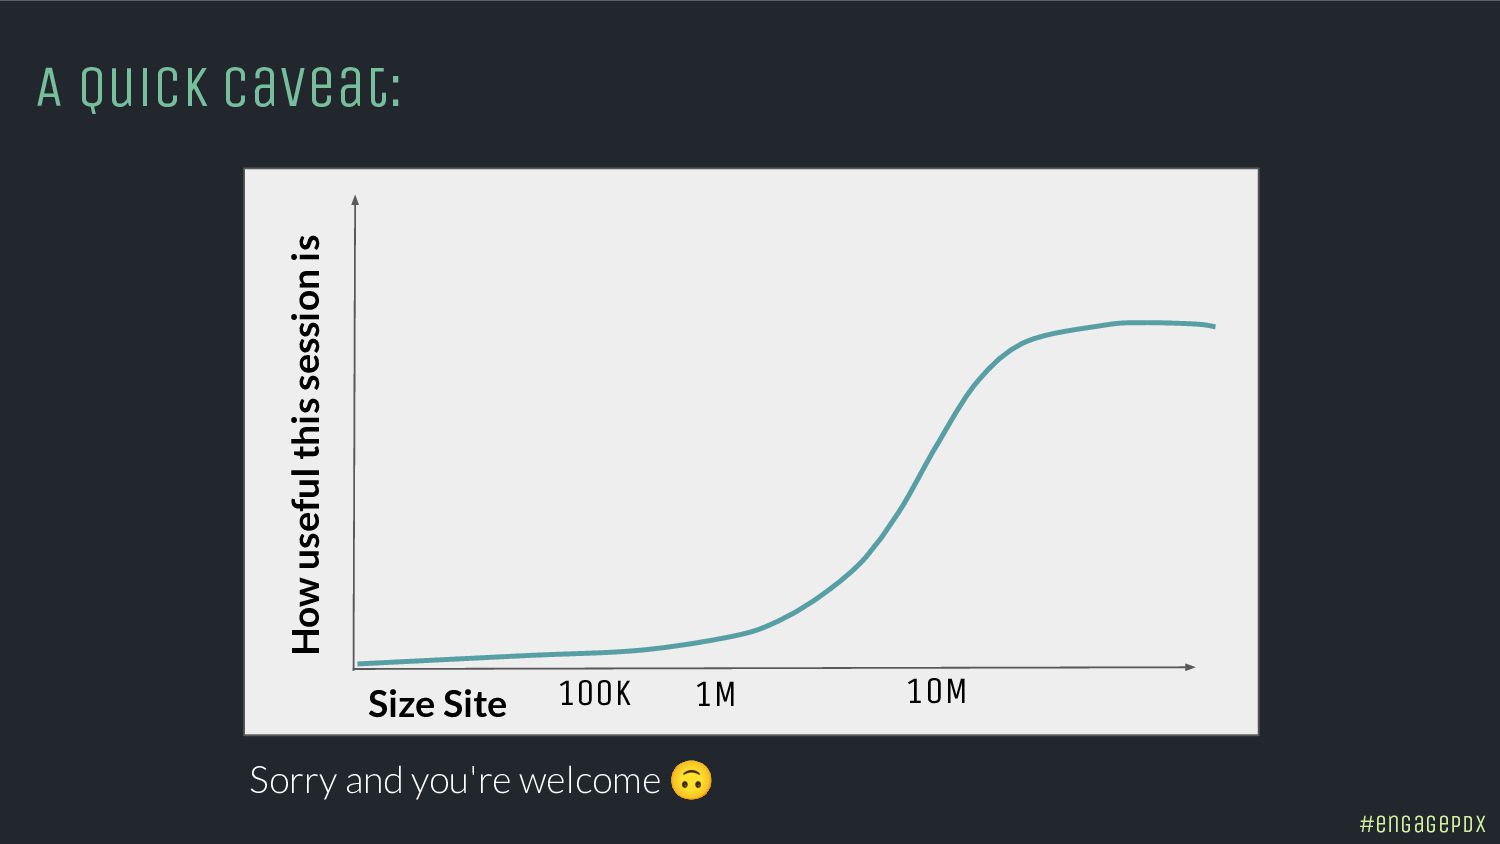
A Quick Caveat: #engagePDX How useful this session is Size
Site Sorry and you're welcome 🙃 100K 1M 10M -
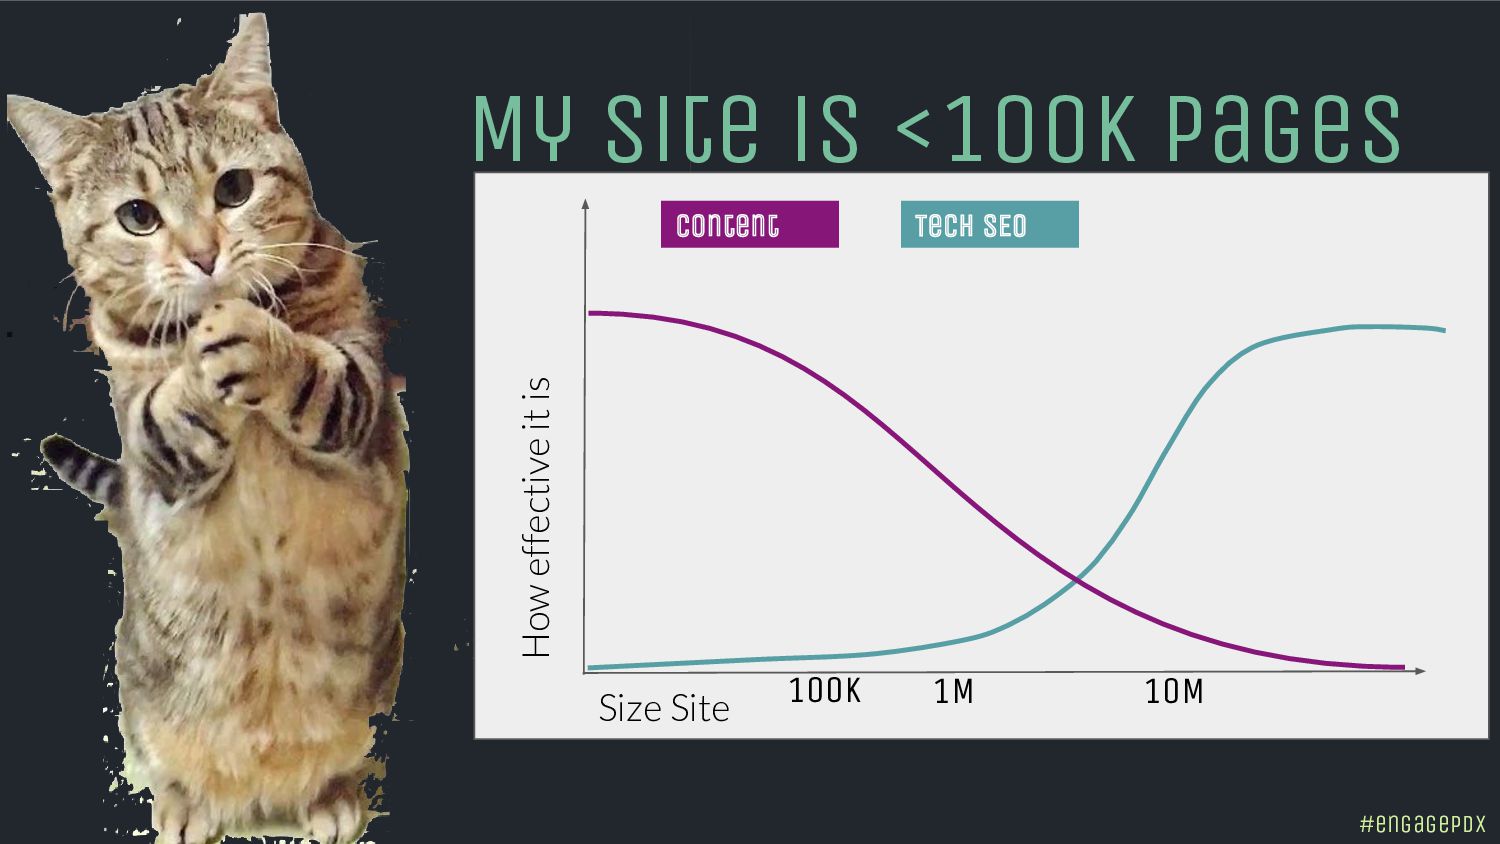
My site is <100K pages How effective it is Size
Site 100K Tech SEO Content 1M 10M #engagePDX -
70B the number of new pages Bing discovers ever day
$170B Estimate annual cost to run Google Search 60% the amount of the internet that is duplicate content Pre AI Boom numbers Sources Fabrice Canel @ Pubcon via Patrick Stox, Twitter The Inference Cost Of Search Disruption – Large Language Model Cost Analysis Gary Illyes @ seodaydk via Lily Ray, Twitter #engagePDX -
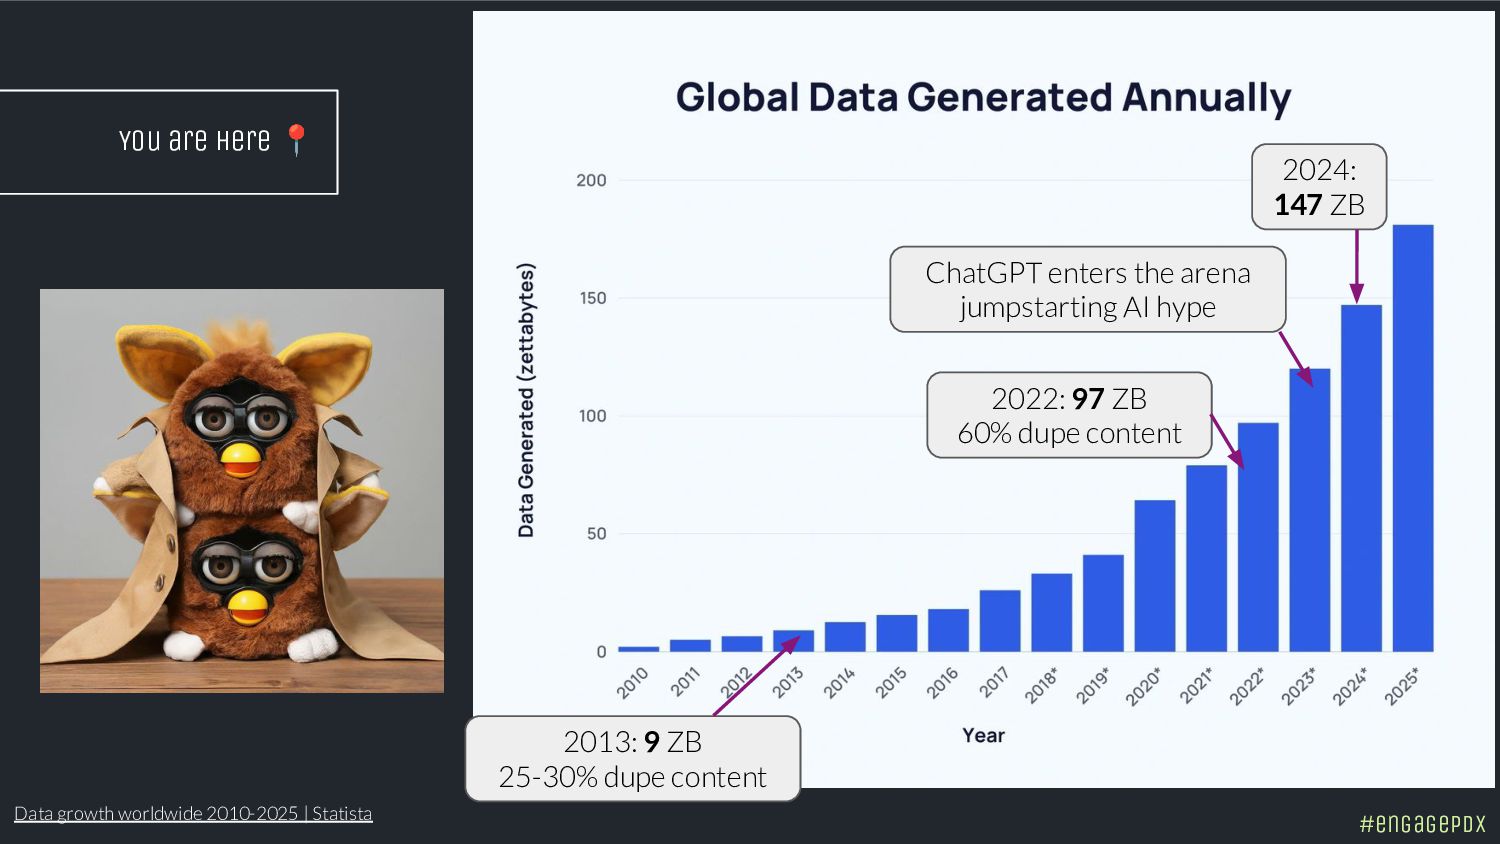
Data growth worldwide 2010-2025 | Statista You are here 📍
#engagePDX ChatGPT enters the arena jumpstarting AI hype 2022: 97 ZB 60% dupe content 2024: 147 ZB 2013: 9 ZB 25-30% dupe content -
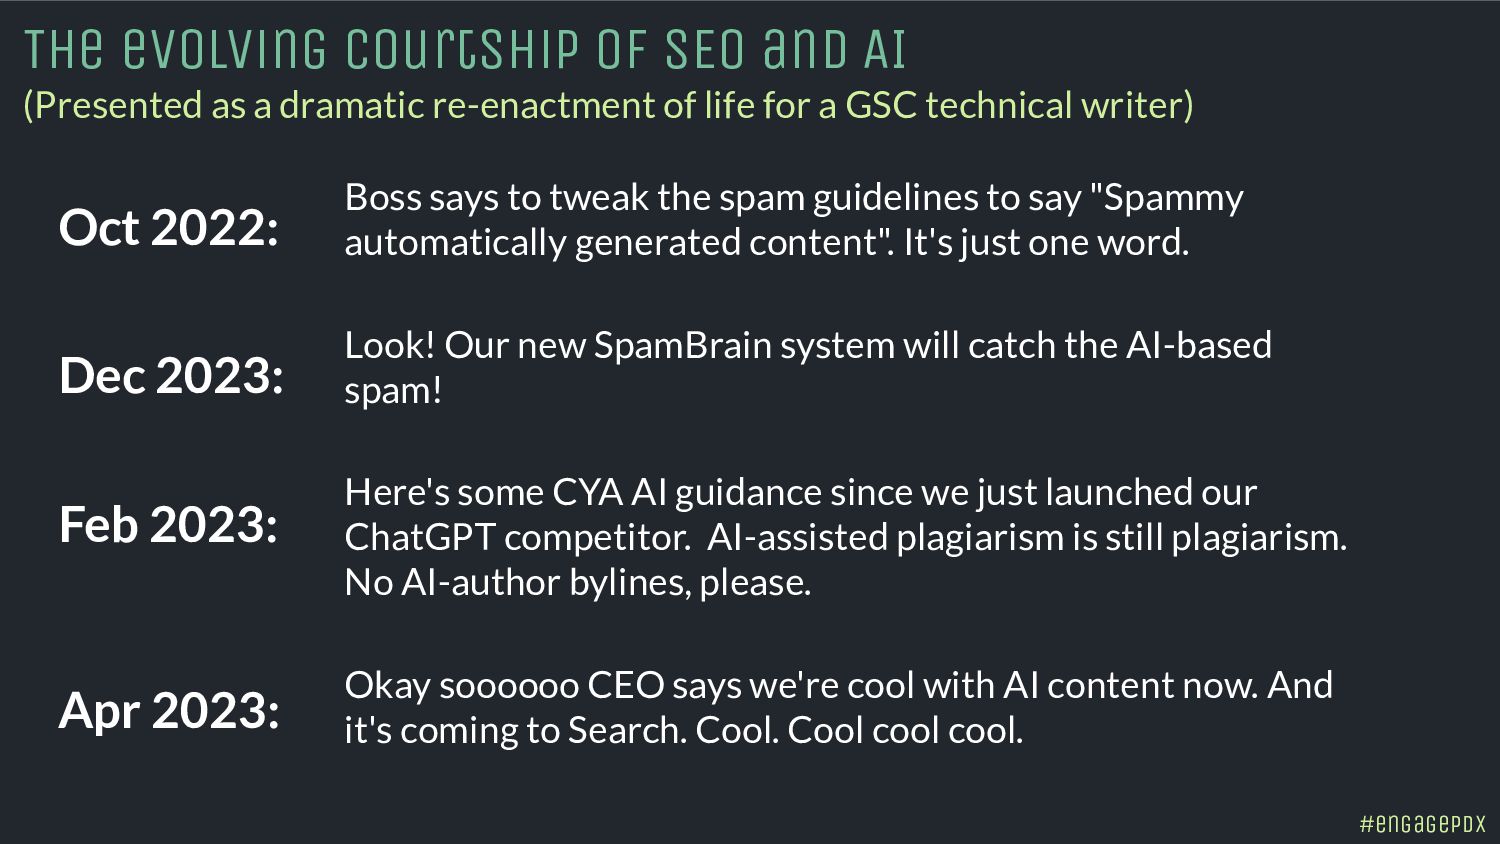
Boss says to tweak the spam guidelines to say "Spammy
automatically generated content". It's just one word. Look! Our new SpamBrain system will catch the AI-based spam! Here's some CYA AI guidance since we just launched our ChatGPT competitor. AI-assisted plagiarism is still plagiarism. No AI-author bylines, please. Okay soooooo CEO says we're cool with AI content now. And it's coming to Search. Cool. Cool cool cool. The evolving courtship of SEO and AI (Presented as a dramatic re-enactment of life for a GSC technical writer) #engagePDX Apr 2023: Feb 2023: Dec 2023: Oct 2022: -
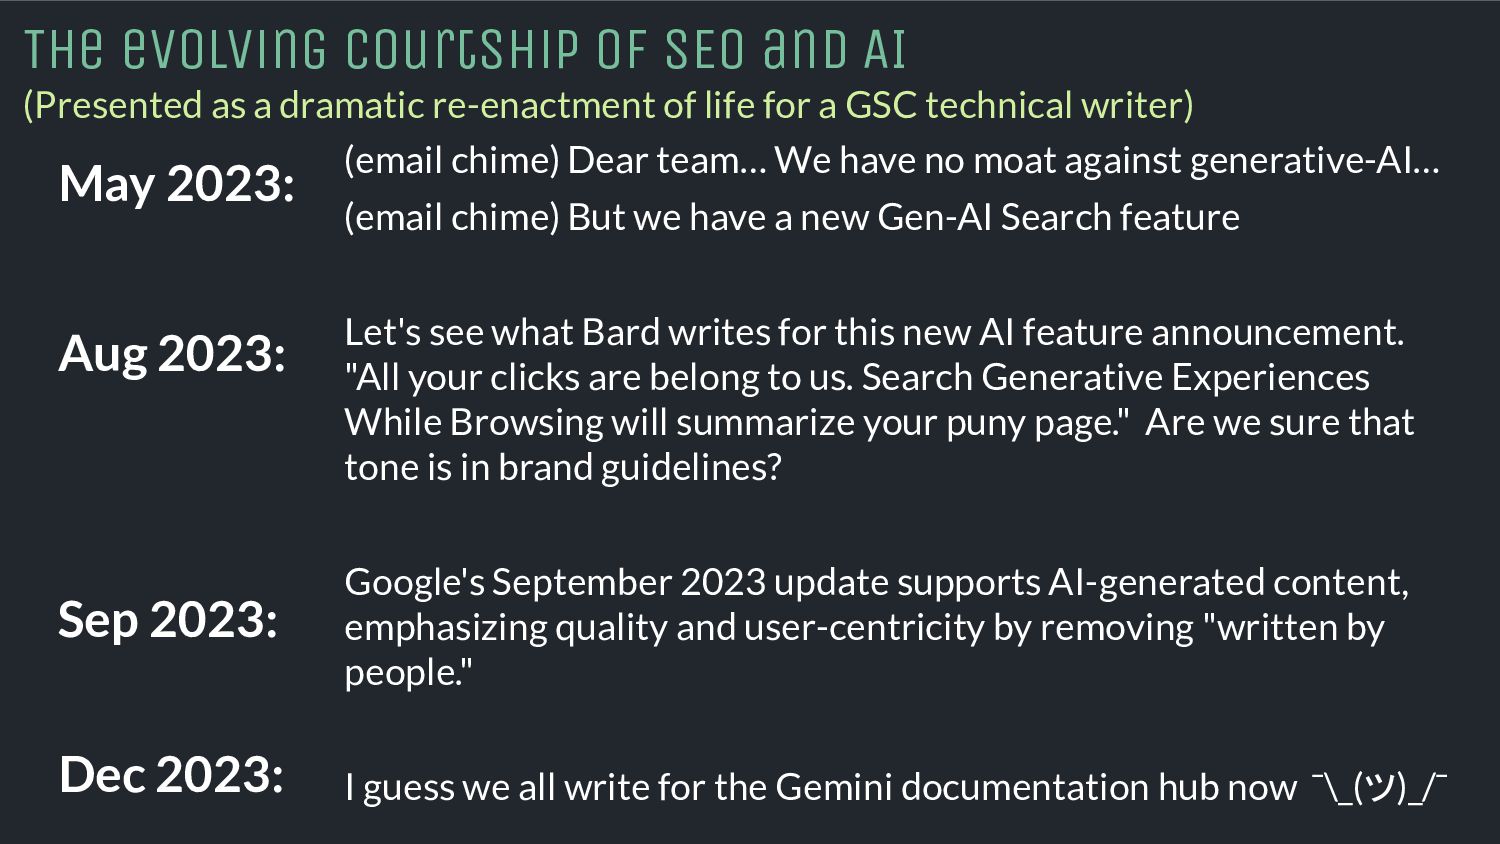
(email chime) Dear team… We have no moat against generative-AI…
(email chime) But we have a new Gen-AI Search feature Let's see what Bard writes for this new AI feature announcement. "All your clicks are belong to us. Search Generative Experiences While Browsing will summarize your puny page." Are we sure that tone is in brand guidelines? Google's September 2023 update supports AI-generated content, emphasizing quality and user-centricity by removing "written by people." I guess we all write for the Gemini documentation hub now ¯\_(ツ)_/¯ The evolving courtship of SEO and AI (Presented as a dramatic re-enactment of life for a GSC technical writer) Dec 2023: Sep 2023: Aug 2023: May 2023: -
Google braceD for impact with the Helpful Content Update “This
update introduces a new site-wide signal that we consider among many other signals for ranking web pages. Our systems automatically identify content that seems to have little value, low-added value or is otherwise not particularly helpful to those doing searches… Any content — not just unhelpful content — on sites determined to have relatively high amounts of unhelpful content overall is less likely to perform well in Search, assuming there is other content elsewhere from the web that's better to display. For this reason, removing unhelpful content could help the rankings of your other content." #engagePDX -
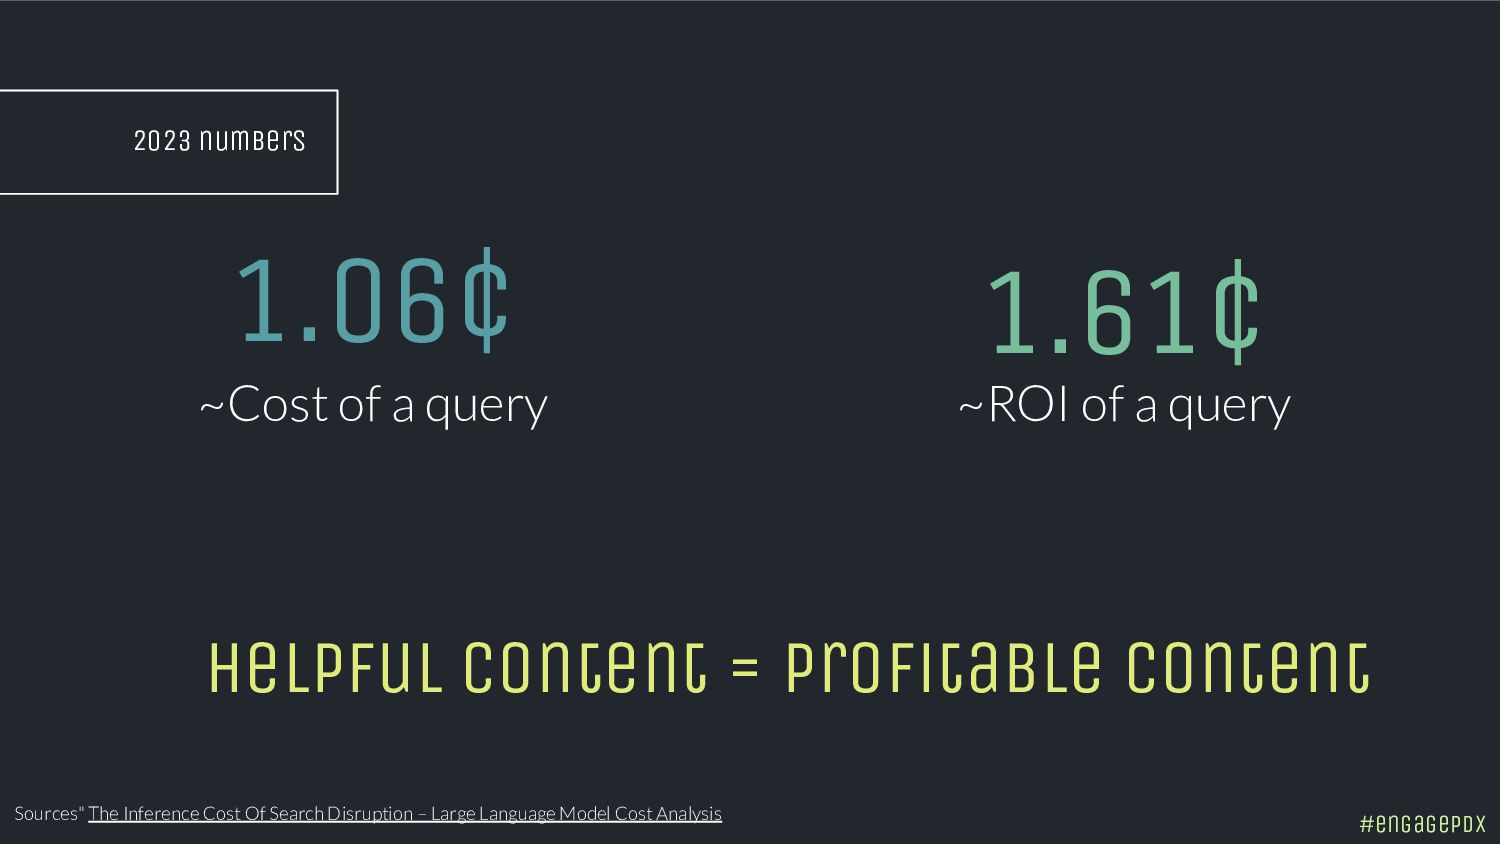
2023 numbers ~ROI of a query 1.61¢ Sources" The Inference
Cost Of Search Disruption – Large Language Model Cost Analysis #engagePDX 1.06¢ ~Cost of a query Helpful Content = Profitable content -
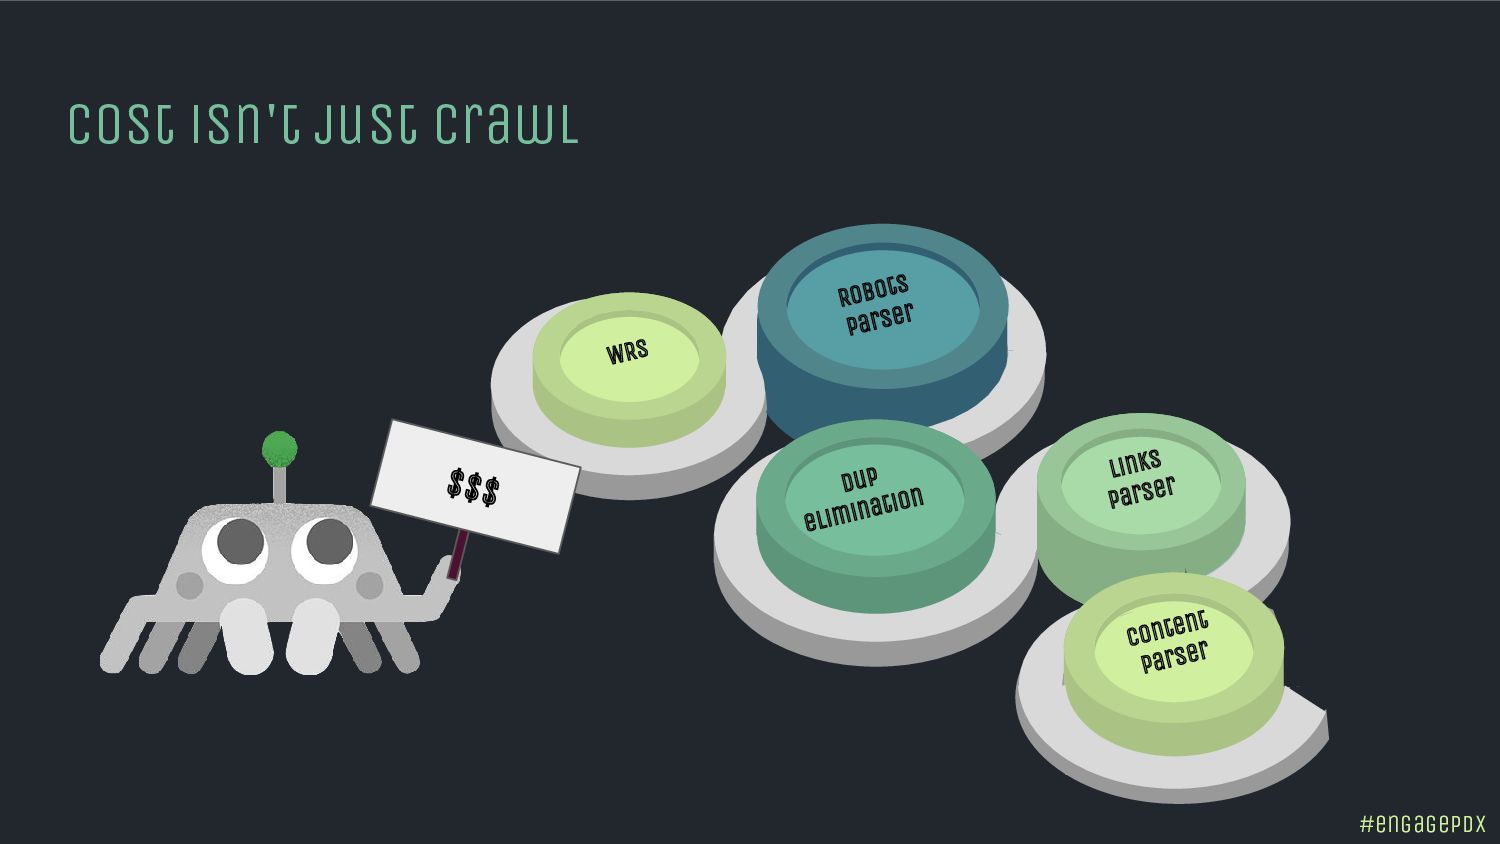
Issues WRS Robots Parser Dup elimination Links parser Content parser
$$$ #engagePDX Cost isn't just crawl -
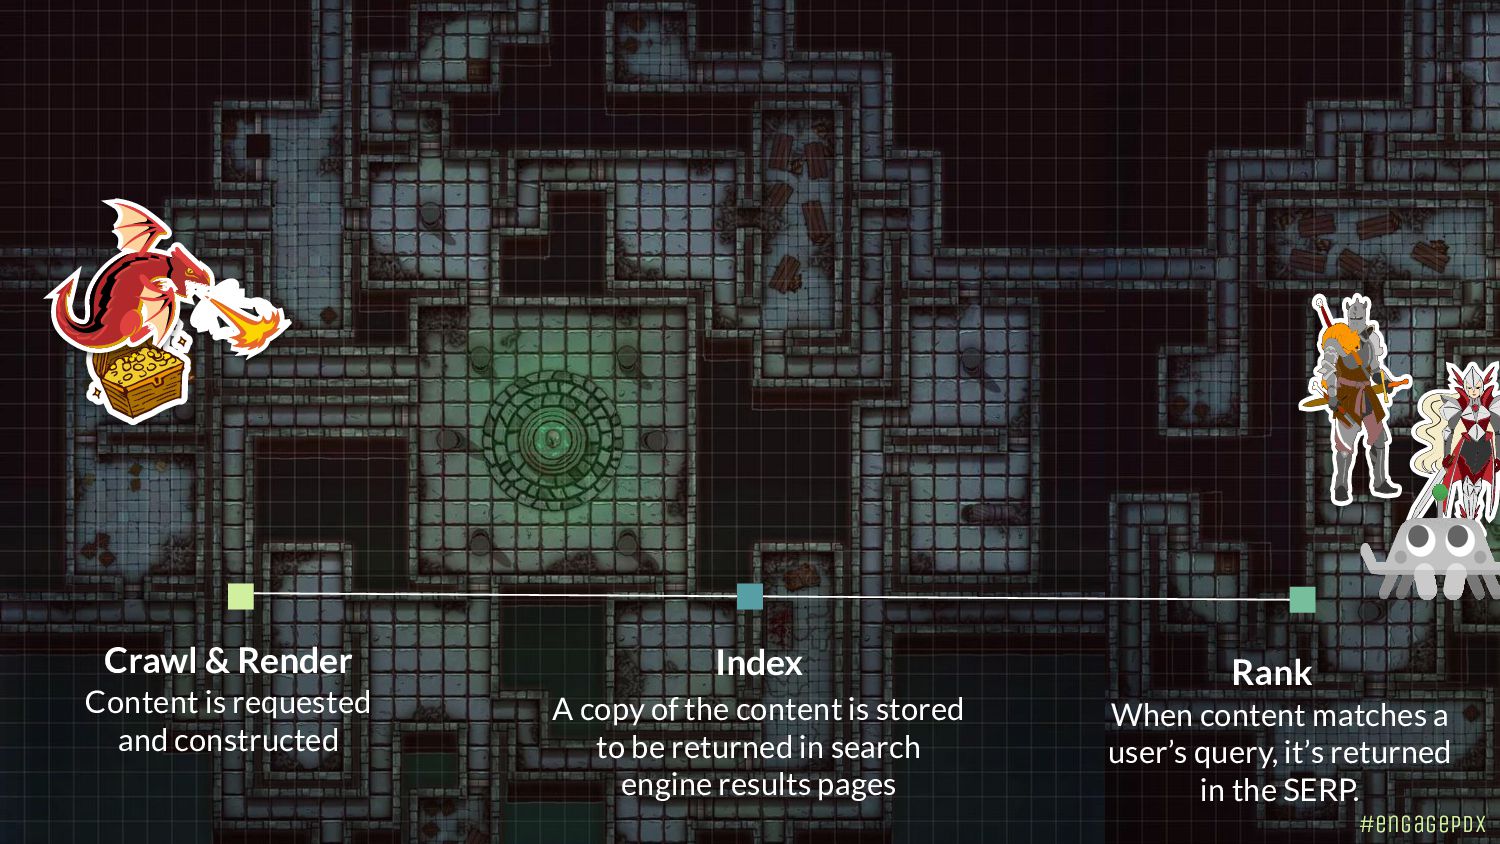
Content is requested and constructed Crawl & Render A copy
of the content is stored to be returned in search engine results pages Index When content matches a user’s query, it’s returned in the SERP. Rank #engagePDX -
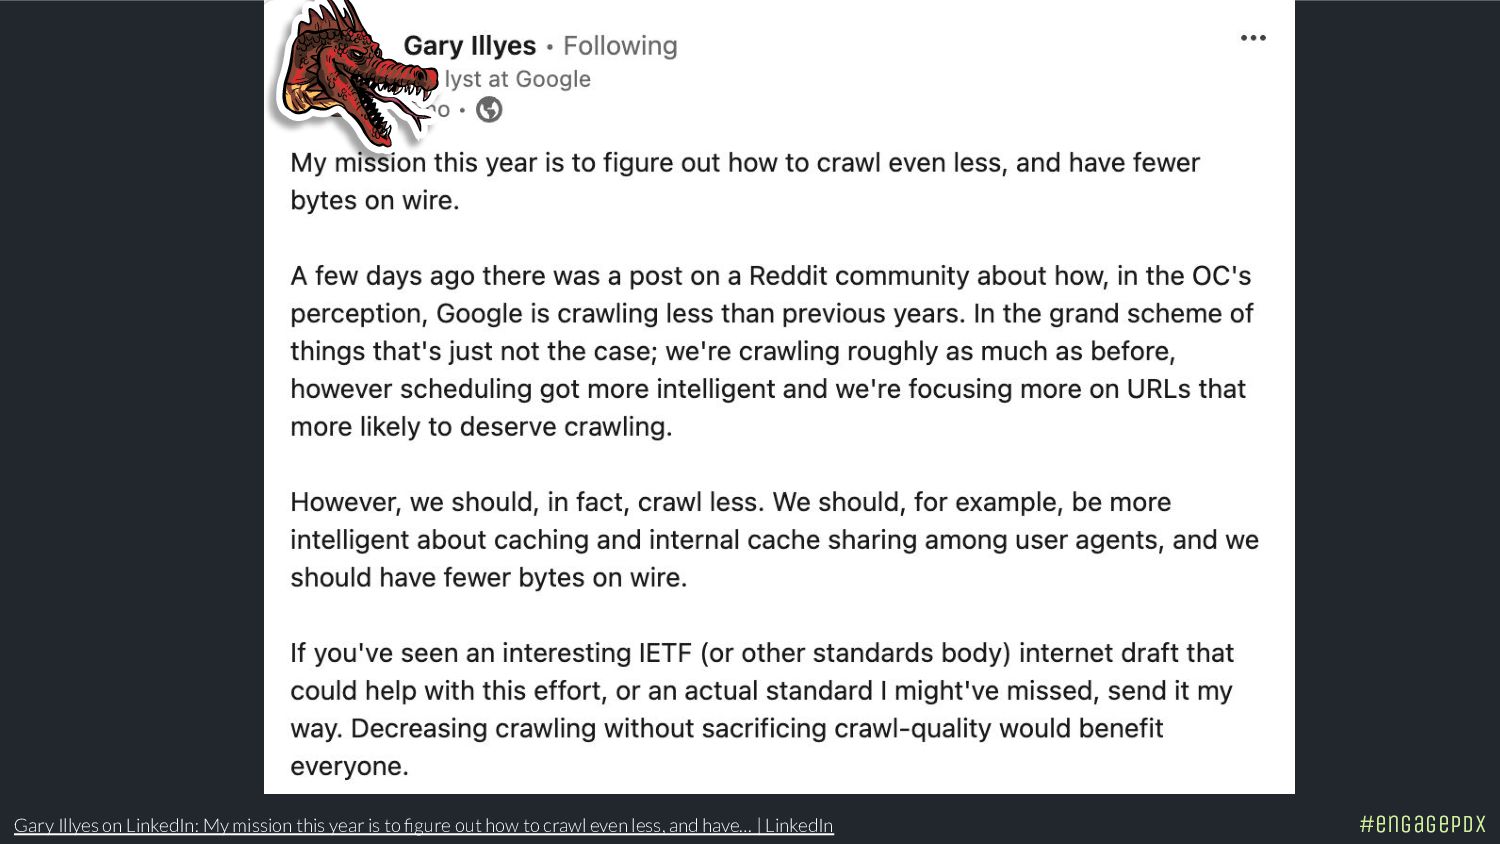
Gary Illyes on LinkedIn: My mission this year is to
figure out how to crawl even less, and have… | LinkedIn #engagePDX -
Crawl budget is a lie and nuance is for communists
#engagePDX What is a web crawler, really? | Search off the record podcast [00:09:20.53] Crawl Queue Scheduler Limiter Search Demand -
Google's New Crawl Priorities 1. Crawl less 2. Save money
(by reducing data consumption) 3. Rely on dynamic triggers to dynamically control crawl (Quality, or rather search demand, really fxn matters) 4. Crawl budget is more a concept than a thing (Shades of E-E-A-T) #engagePDX What is a web crawler, really? | Search off the record podcast -[00:09:20.53] -
Want new pages crawled? Linked them from Homepage #engagePDX “So
for the most part, for example, we would refresh crawl the homepage, I don’t know, once a day, or every couple of hours, or something like that. And if we find new links on their home page then we’ll go off and crawl those with the discovery crawl as well. And because of that you will always see a mix of discover and refresh happening with regard to crawling. And you’ll see some baseline of crawling happening every day. But if we recognize that individual pages change very rarely, then we realize we don’t have to crawl them all the time.” English Google SEO office-hours from January 7, 2022 -
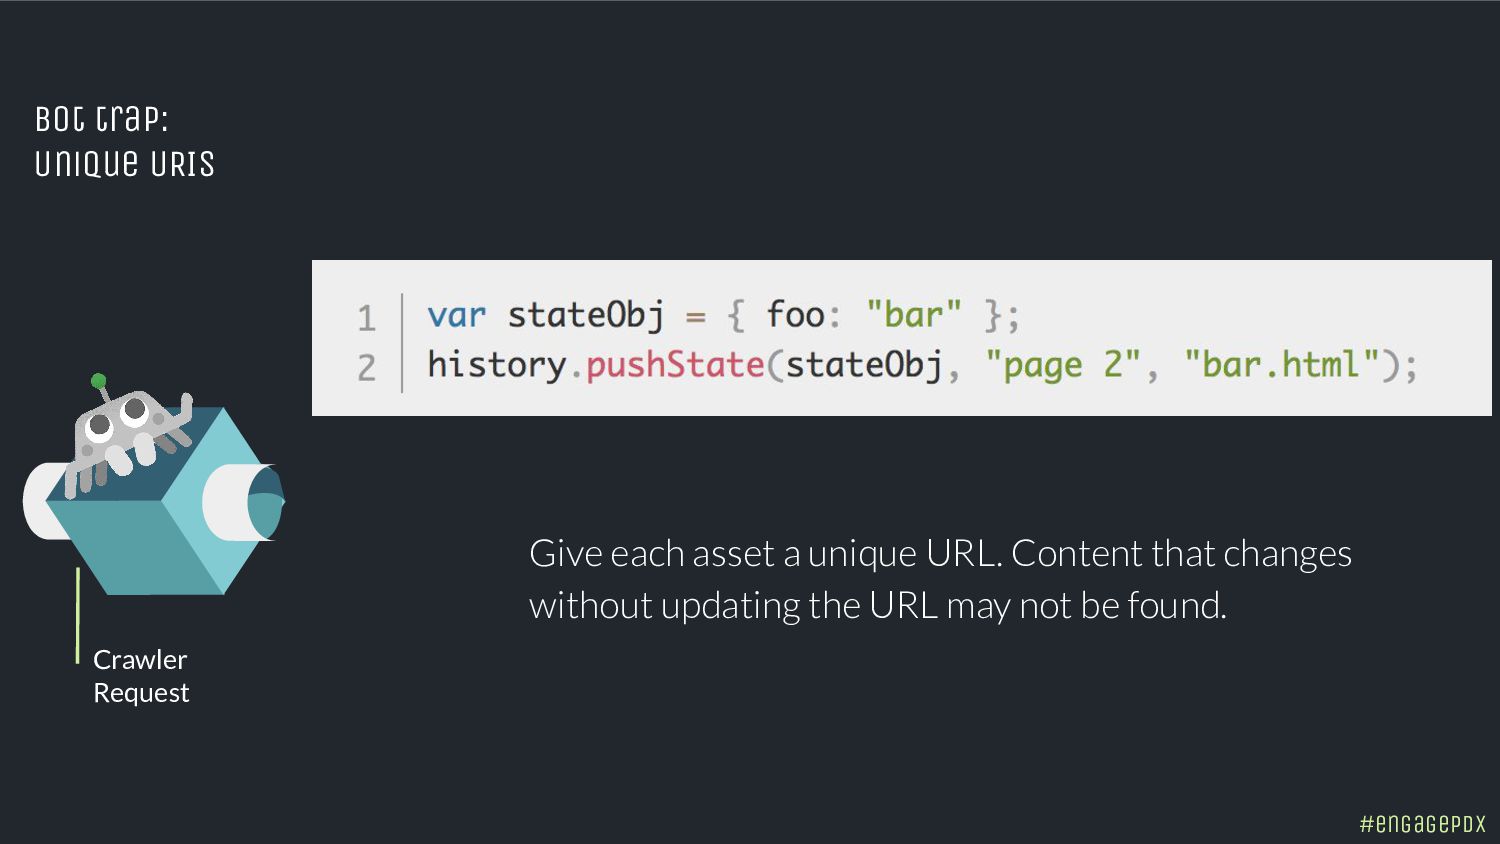
Crawler Request Give each asset a unique URL. Content that
changes without updating the URL may not be found. Bot trap: Unique URIs #engagePDX -
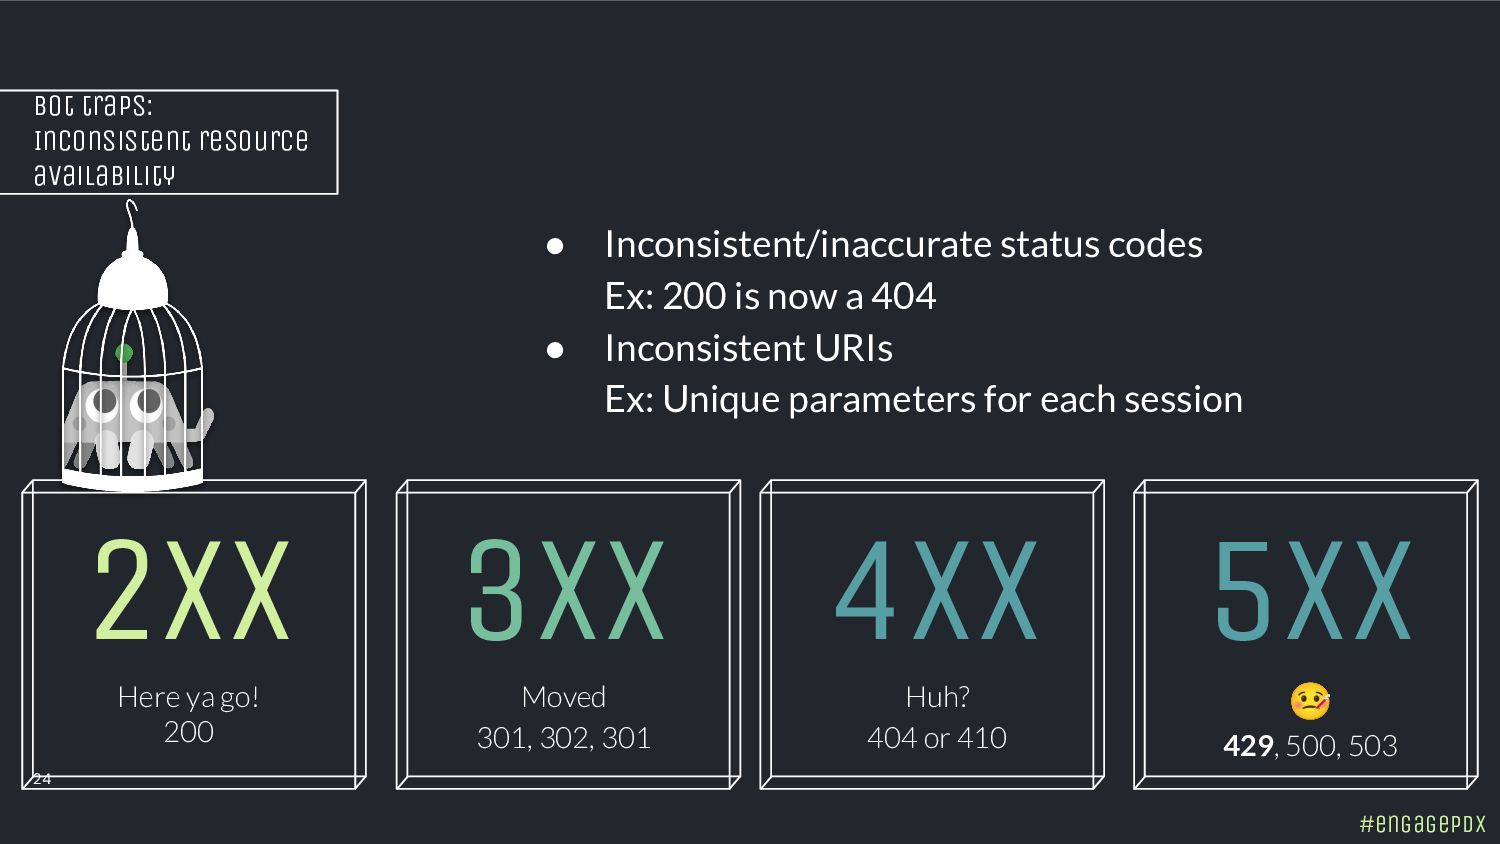
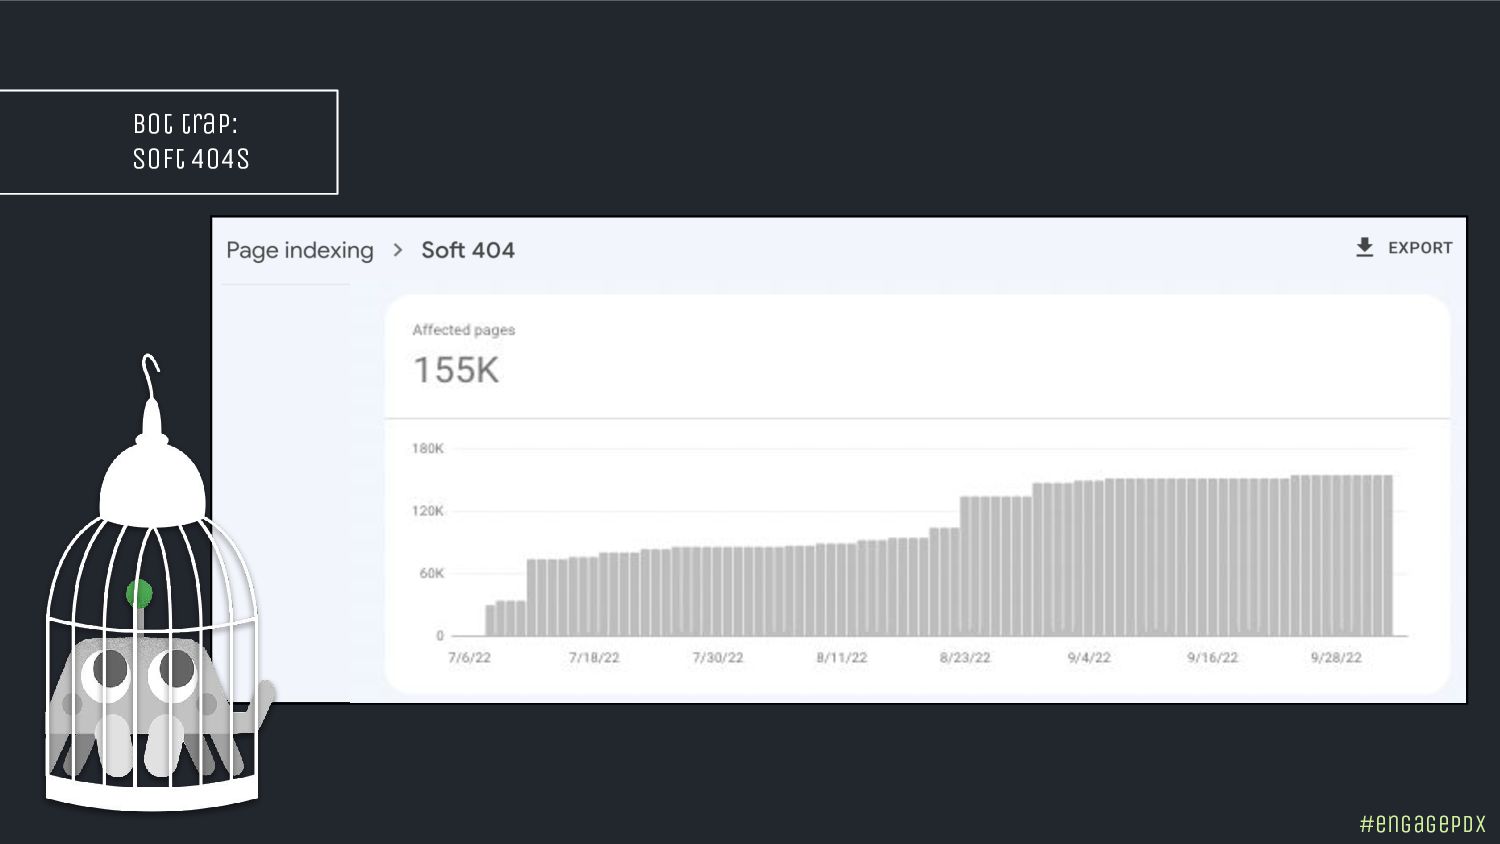
Bot traps: Inconsistent resource availability #engagePDX 24 • Inconsistent/inaccurate status
codes Ex: 200 is now a 404 • Inconsistent URIs Ex: Unique parameters for each session 2XX Here ya go! 200 3XX Moved 301, 302, 301 4XX Huh? 404 or 410 5XX 🤒 429, 500, 503 -
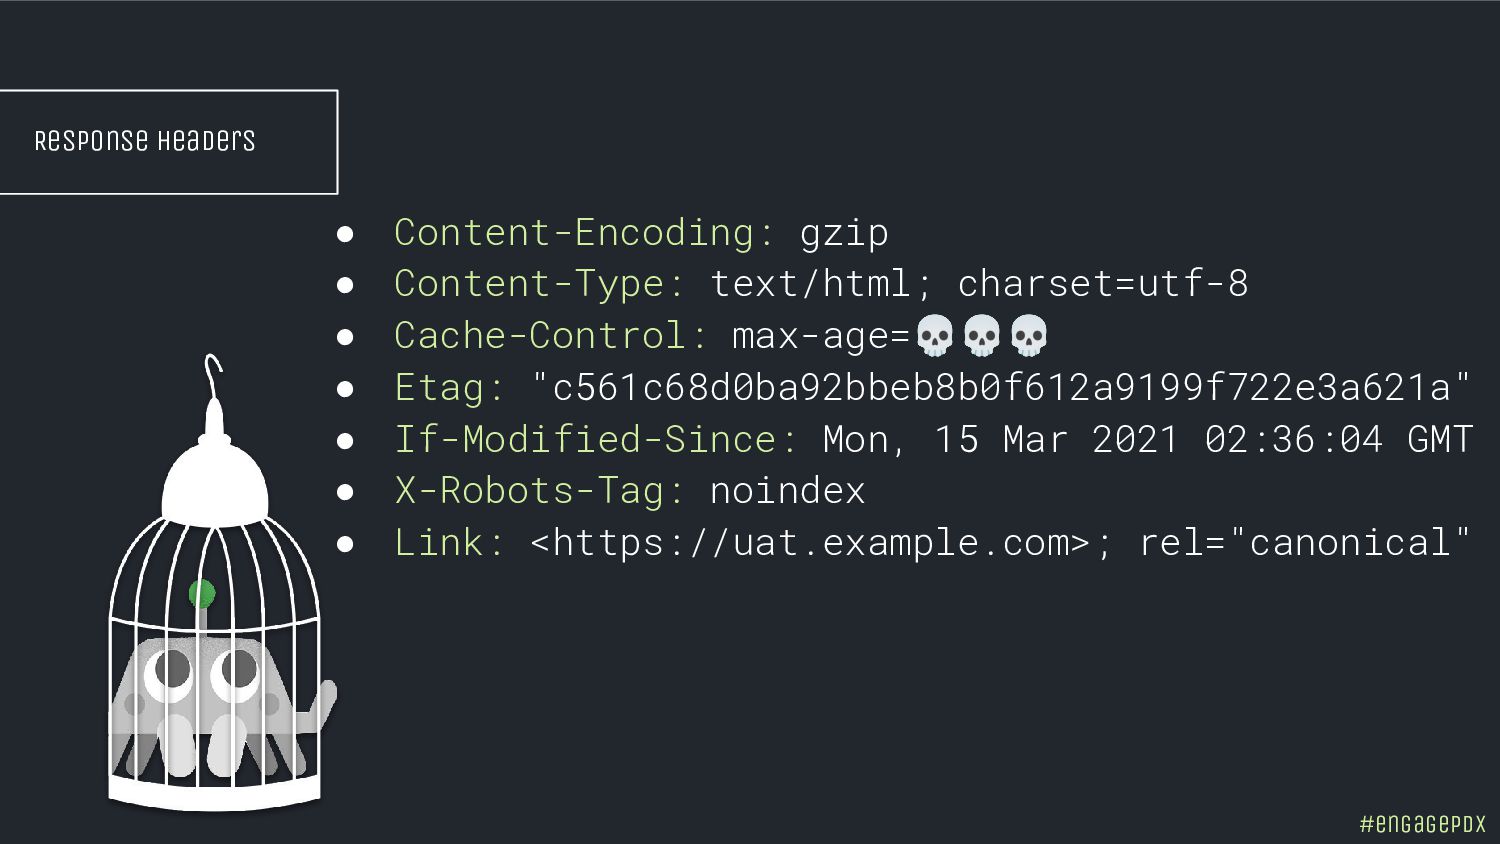
• Content-Encoding: gzip • Content-Type: text/html; charset=utf-8 • Cache-Control: max-age=💀💀💀
• Etag: "c561c68d0ba92bbeb8b0f612a9199f722e3a621a" • If-Modified-Since: Mon, 15 Mar 2021 02:36:04 GMT • X-Robots-Tag: noindex • Link: <https://uat.example.com>; rel="canonical" Response Headers #engagePDX -
• Googlebot won’t see past a noindex directive in initial
HTML to see an index placed in DOM Bot traps: Contradictory signals #engagePDX -
#engagePDX "Crawlers have lots of resources, they can afford to
waste some, your site likely doesn't. Soft errors are bad because: 1. the limited "crawl budget" spent on them could've been spent on real pages. 2. the pages will unlikely to show up in search because during indexing they're filtered out, basically no ROI on the resources you've spent on serving them." Gary Illyes on LinkedIn: Soft 404s and other soft/crypto errors. The banes of my existence and all… | 24 comments -
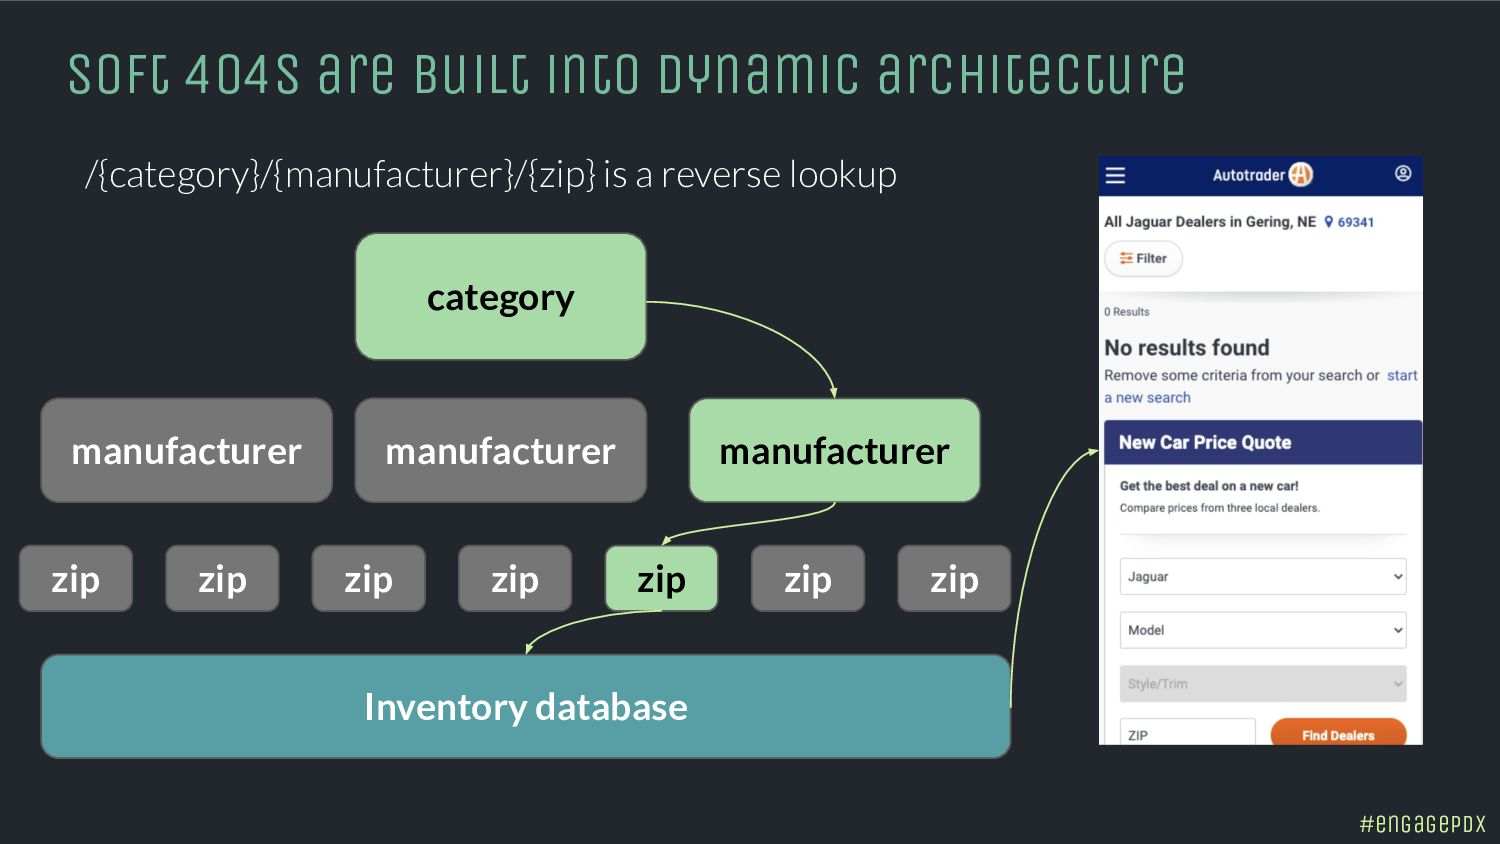
Soft 404s are built into dynamic architecture #engagePDX /{category}/{manufacturer}/{zip} is
a reverse lookup category manufacturer manufacturer manufacturer zip zip zip zip zip zip zip Inventory database -
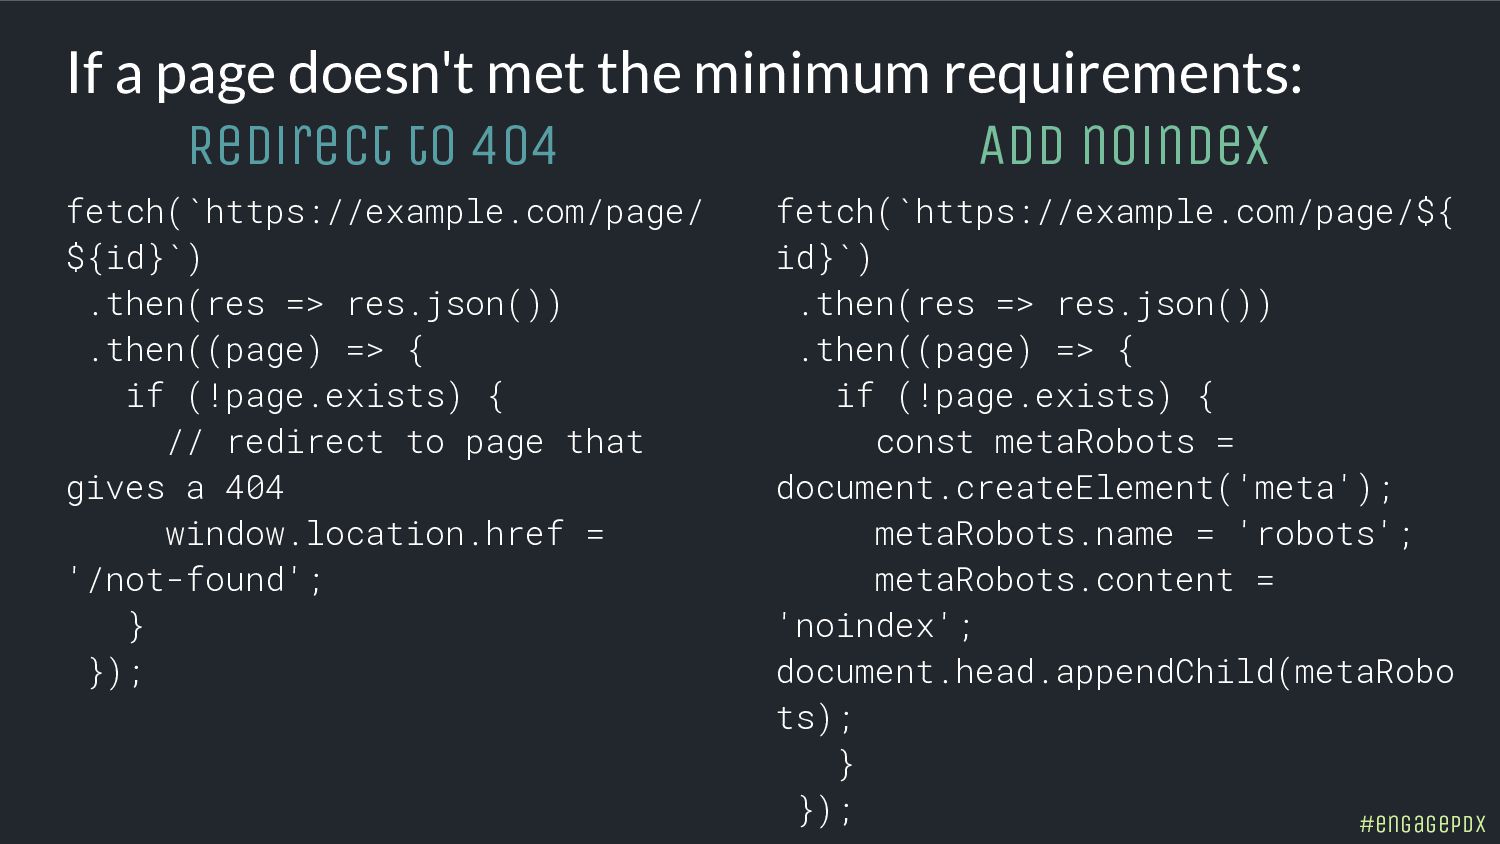
fetch(`https://example.com/page/ ${id}`) .then(res => res.json()) .then((page) => { if (!page.exists)
{ // redirect to page that gives a 404 window.location.href = '/not-found'; } }); fetch(`https://example.com/page/${ id}`) .then(res => res.json()) .then((page) => { if (!page.exists) { const metaRobots = document.createElement('meta'); metaRobots.name = 'robots'; metaRobots.content = 'noindex'; document.head.appendChild(metaRobo ts); } }); Redirect to 404 Add noindex #engagePDX If a page doesn't met the minimum requirements: -
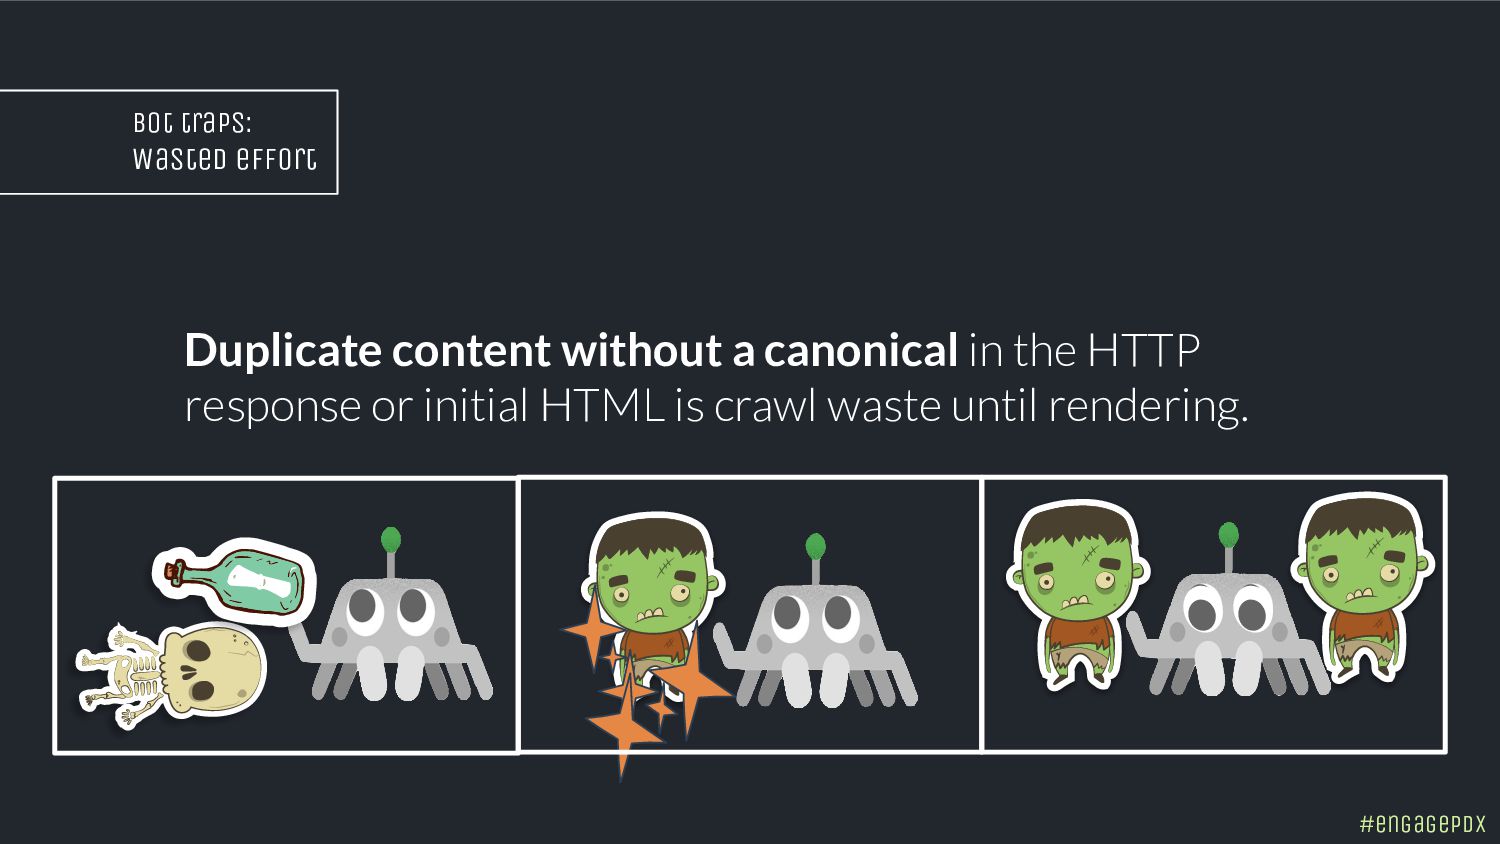
Duplicate content without a canonical in the HTTP response or
initial HTML is crawl waste until rendering. Bot traps: Wasted effort #engagePDX -
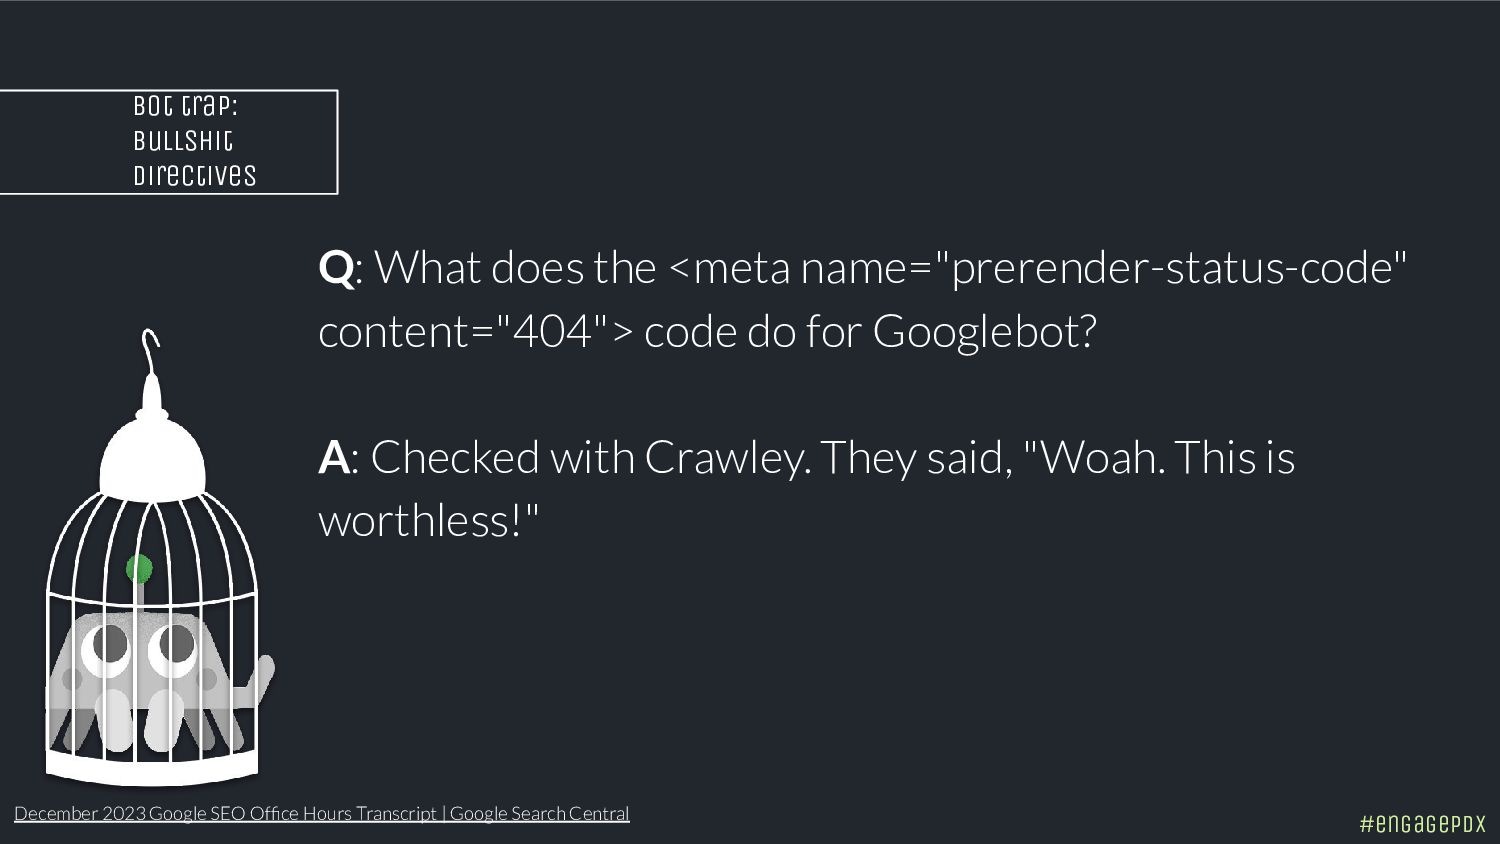
Bot trap: Bullshit directives #engagePDX Q: What does the <meta
name="prerender-status-code" content="404"> code do for Googlebot? A: Checked with Crawley. They said, "Woah. This is worthless!" December 2023 Google SEO Office Hours Transcript | Google Search Central -
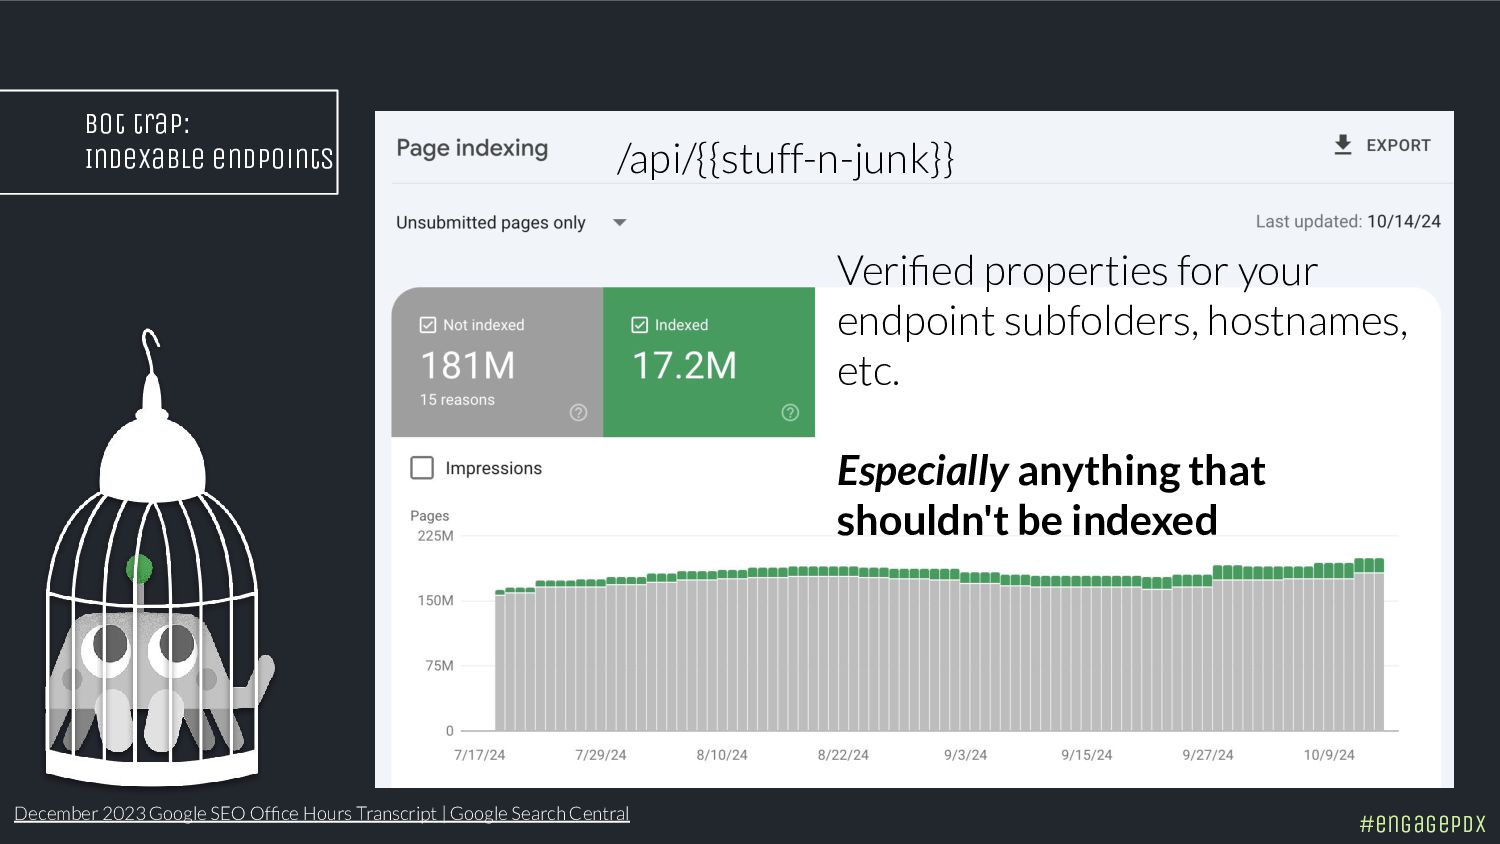
Bot trap: Indexable endpoints #engagePDX December 2023 Google SEO Office
Hours Transcript | Google Search Central /api/{{stuff-n-junk}} Verified properties for your endpoint subfolders, hostnames, etc. Especially anything that shouldn't be indexed -
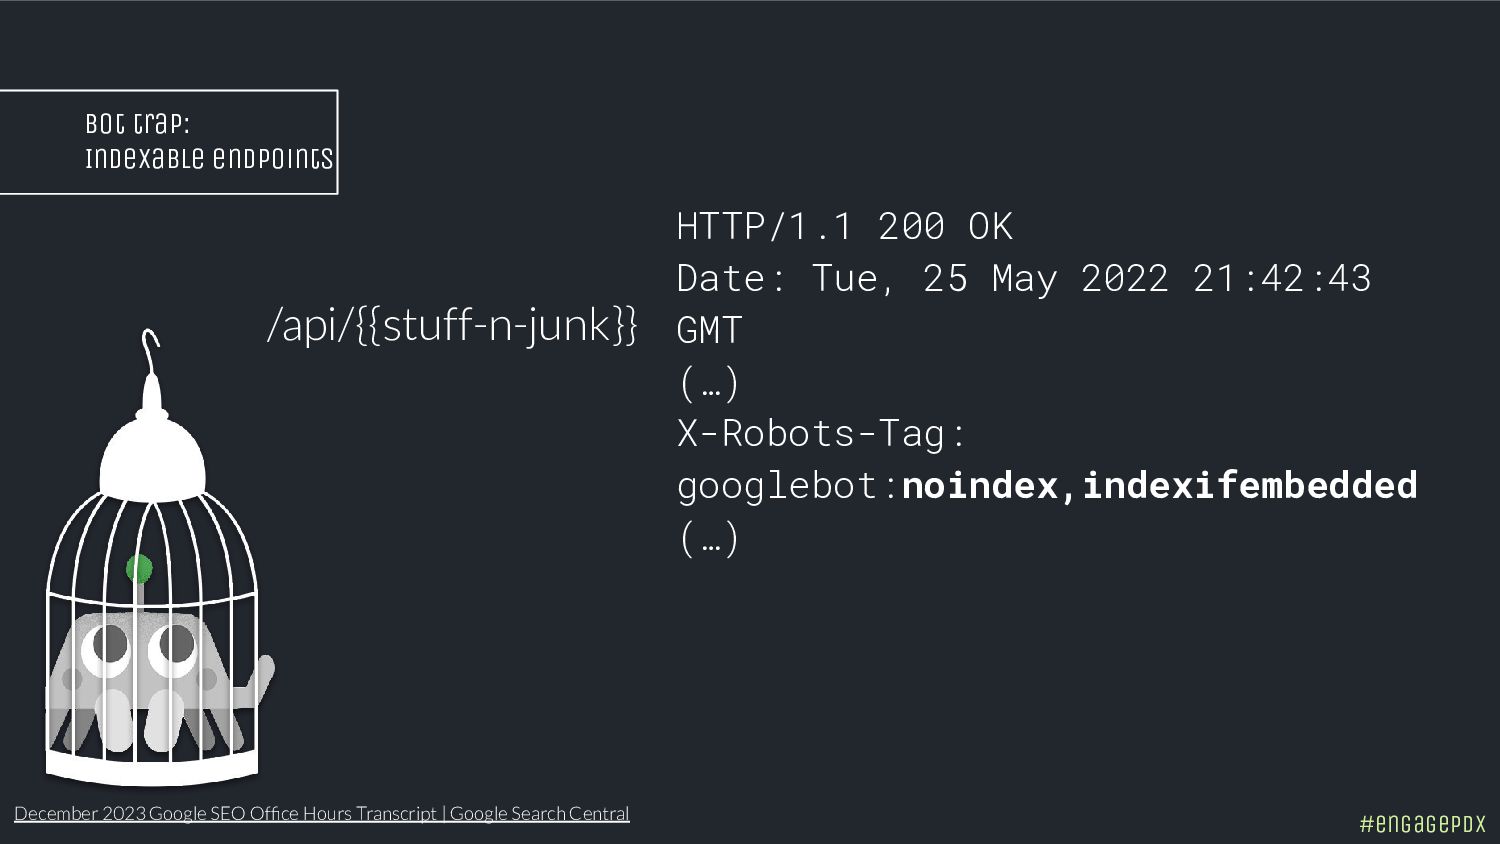
Bot trap: Indexable endpoints #engagePDX December 2023 Google SEO Office
Hours Transcript | Google Search Central HTTP/1.1 200 OK Date: Tue, 25 May 2022 21:42:43 GMT (…) X-Robots-Tag: googlebot:noindex,indexifembedded (…) /api/{{stuff-n-junk}} -
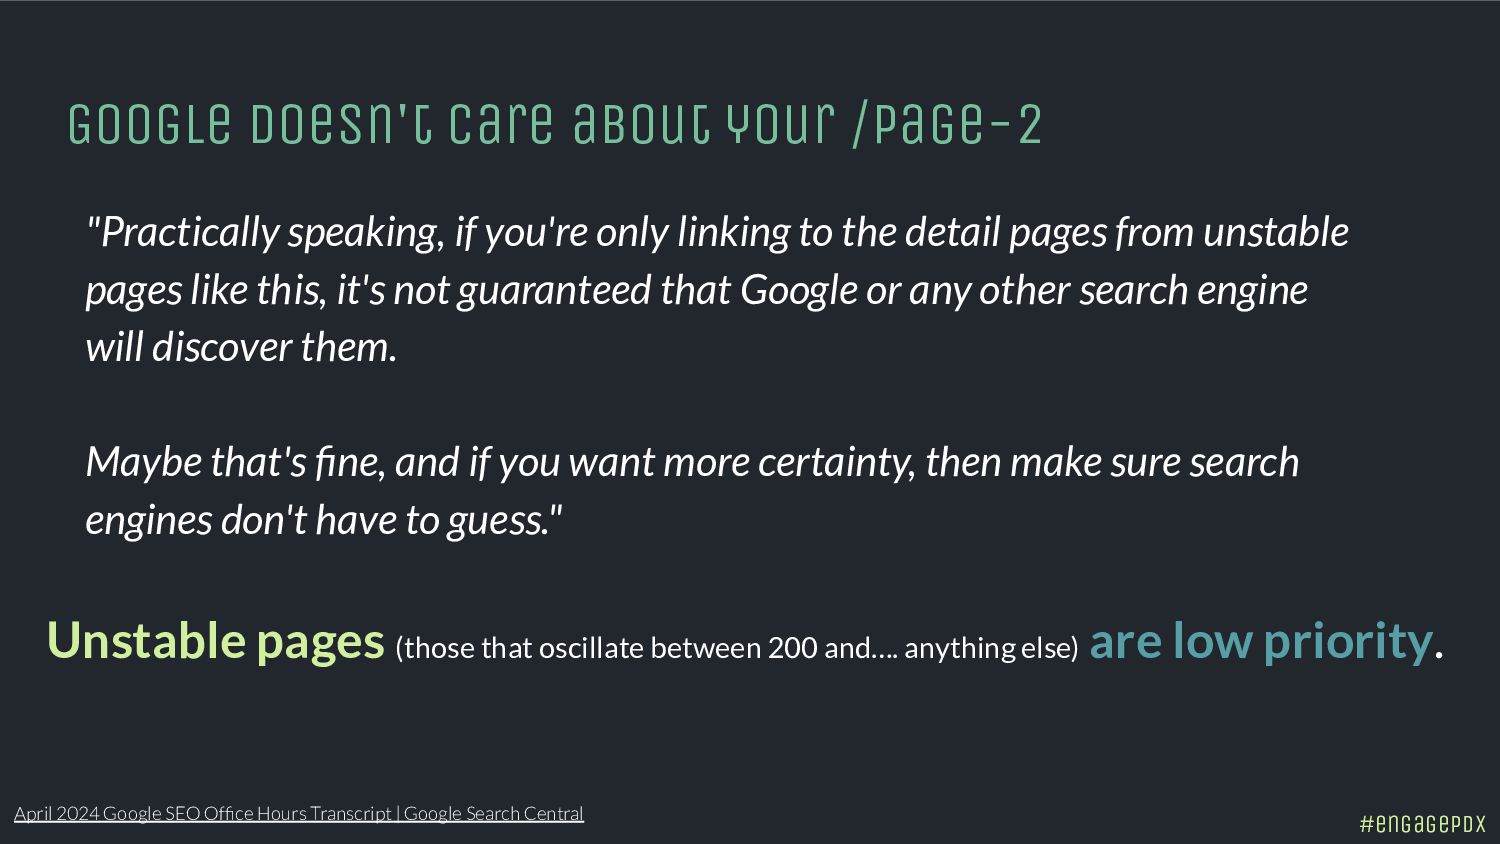
"Practically speaking, if you're only linking to the detail pages
from unstable pages like this, it's not guaranteed that Google or any other search engine will discover them. Maybe that's fine, and if you want more certainty, then make sure search engines don't have to guess." Google doesn't care about your /page-2 #engagePDX April 2024 Google SEO Office Hours Transcript | Google Search Central Unstable pages (those that oscillate between 200 and…. anything else) are low priority. -
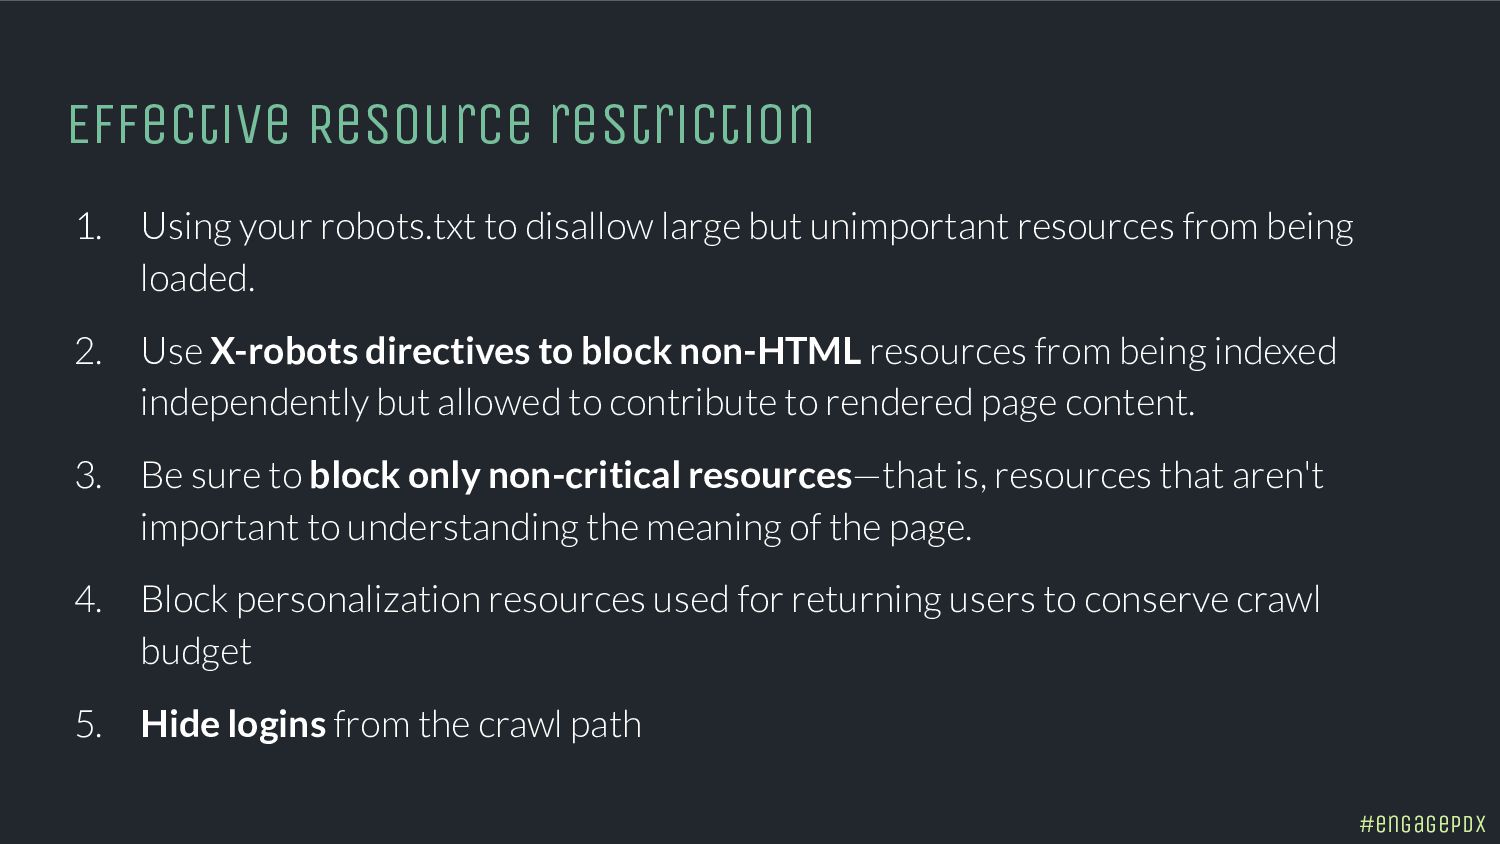
Effective Resource restriction 1. Using your robots.txt to disallow large
but unimportant resources from being loaded. 2. Use X-robots directives to block non-HTML resources from being indexed independently but allowed to contribute to rendered page content. 3. Be sure to block only non-critical resources—that is, resources that aren't important to understanding the meaning of the page. 4. Block personalization resources used for returning users to conserve crawl budget 5. Hide logins from the crawl path #engagePDX -
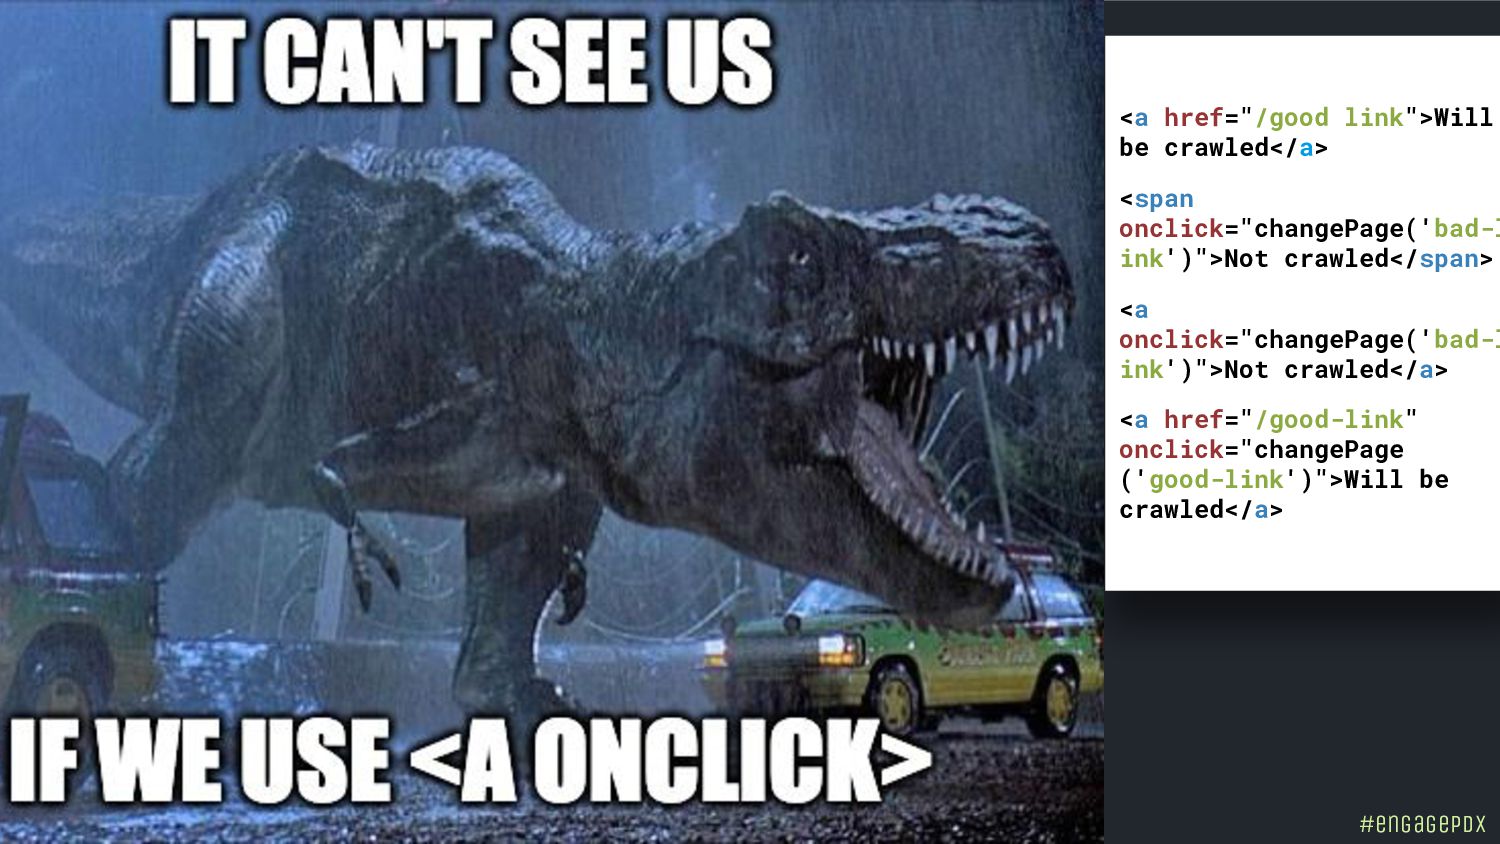
<a href="/good link">Will be crawled</a> <span onclick="changePage('bad-l ink')">Not crawled</span> <a
onclick="changePage('bad-l ink')">Not crawled</a> <a href="/good-link" onclick="changePage ('good-link')">Will be crawled</a> #engagePDX -
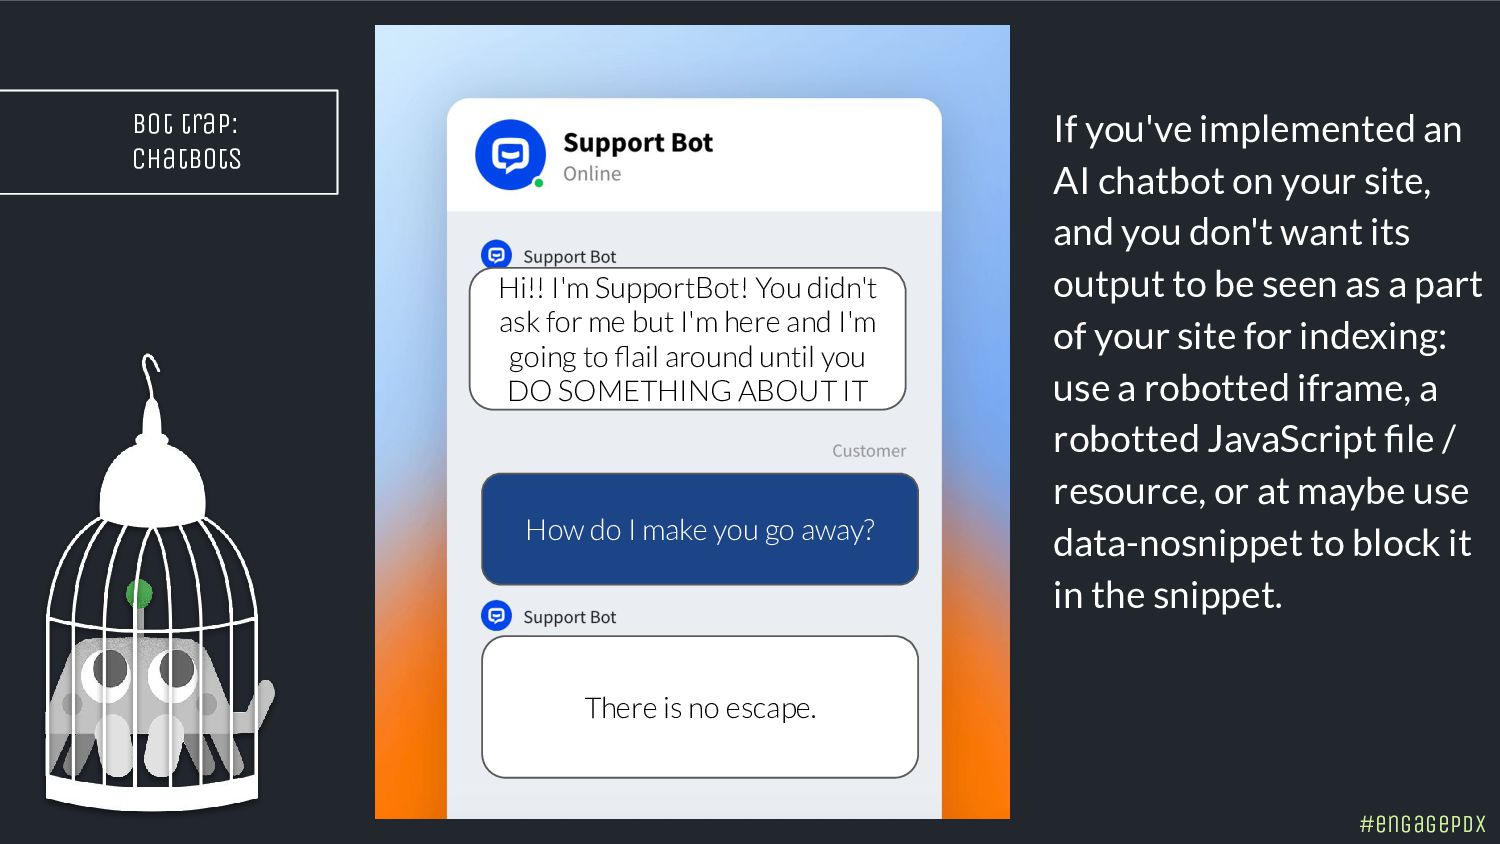
Bot trap: Chatbots #engagePDX Hi!! I'm SupportBot! You didn't ask
for me but I'm here and I'm going to flail around until you DO SOMETHING ABOUT IT How do I make you go away? There is no escape. If you've implemented an AI chatbot on your site, and you don't want its output to be seen as a part of your site for indexing: use a robotted iframe, a robotted JavaScript file / resource, or at maybe use data-nosnippet to block it in the snippet. -
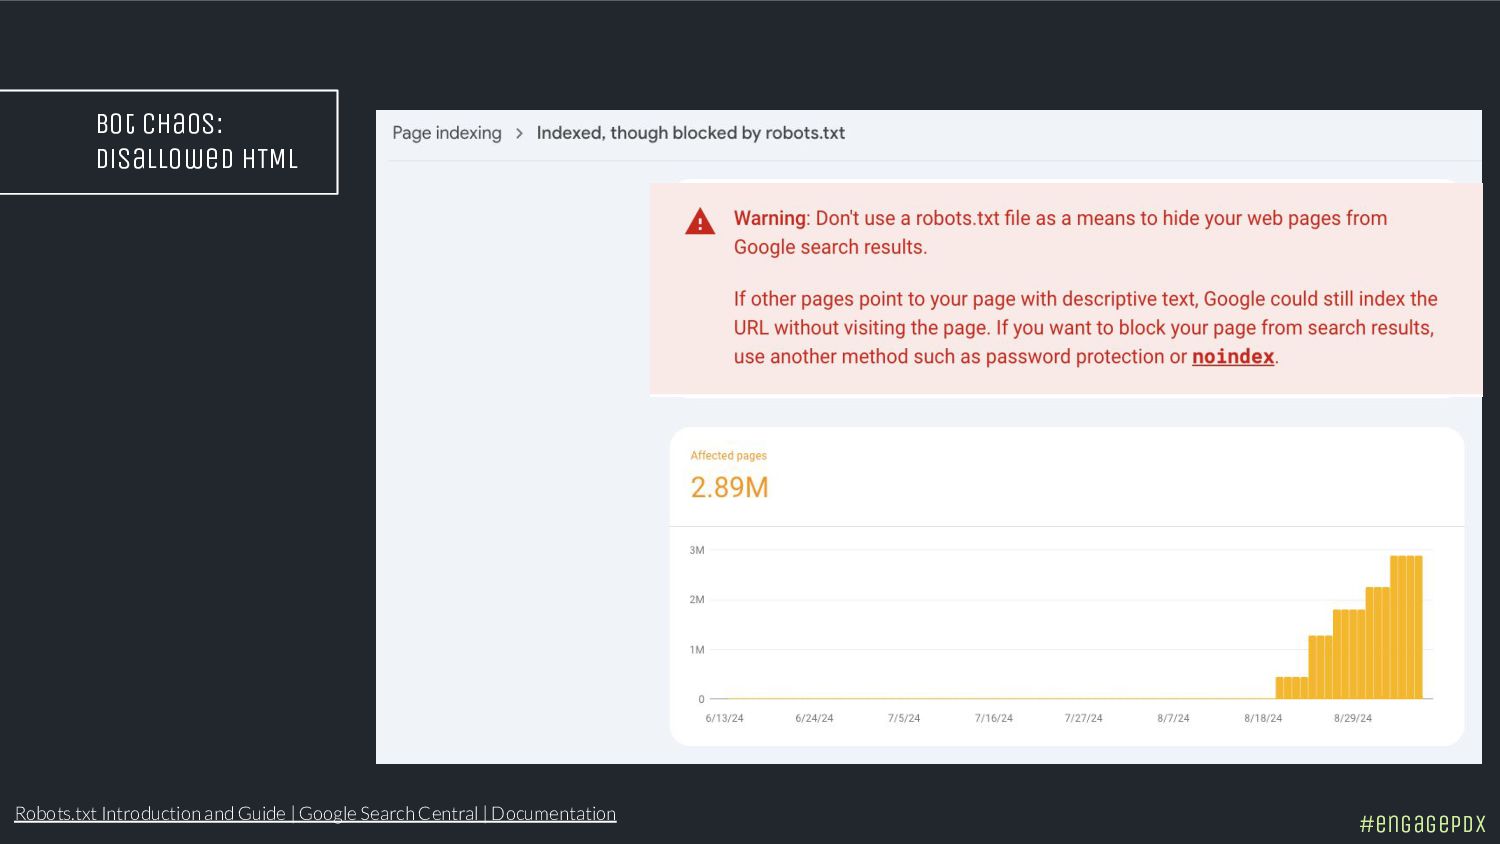
Bot Chaos: Disallowed HTML #engagePDX Robots.txt Introduction and Guide |
Google Search Central | Documentation -
1. Robots.txt is for managing crawl traffic 2. Robots.txt it
is not a mechanism for keeping a web page out of Google. 3. Blocked pages can still appear in Google Search. 4. Google won't shift this newly available crawl budget to other pages unless Google is already hitting your site's serving limit. Robots.txt Key Takeaways Robots.txt Introduction and Guide | Google Search Central | Documentation #engagePDX -
1. Using your robots.txt to disallow large but unimportant resources
from being loaded. 2. Use X-robots directives to block non-HTML resources from being indexed independently but allowed to contribute to rendered page content. 3. Be sure to block only non-critical resources—that is, resources that aren't important to understanding the meaning of the page. 4. Block personalization resources used for returning users to conserve crawl budget. Robots & WRS Key Takeaways Robots.txt Introduction and Guide | Google Search Central | Documentation #engagePDX -
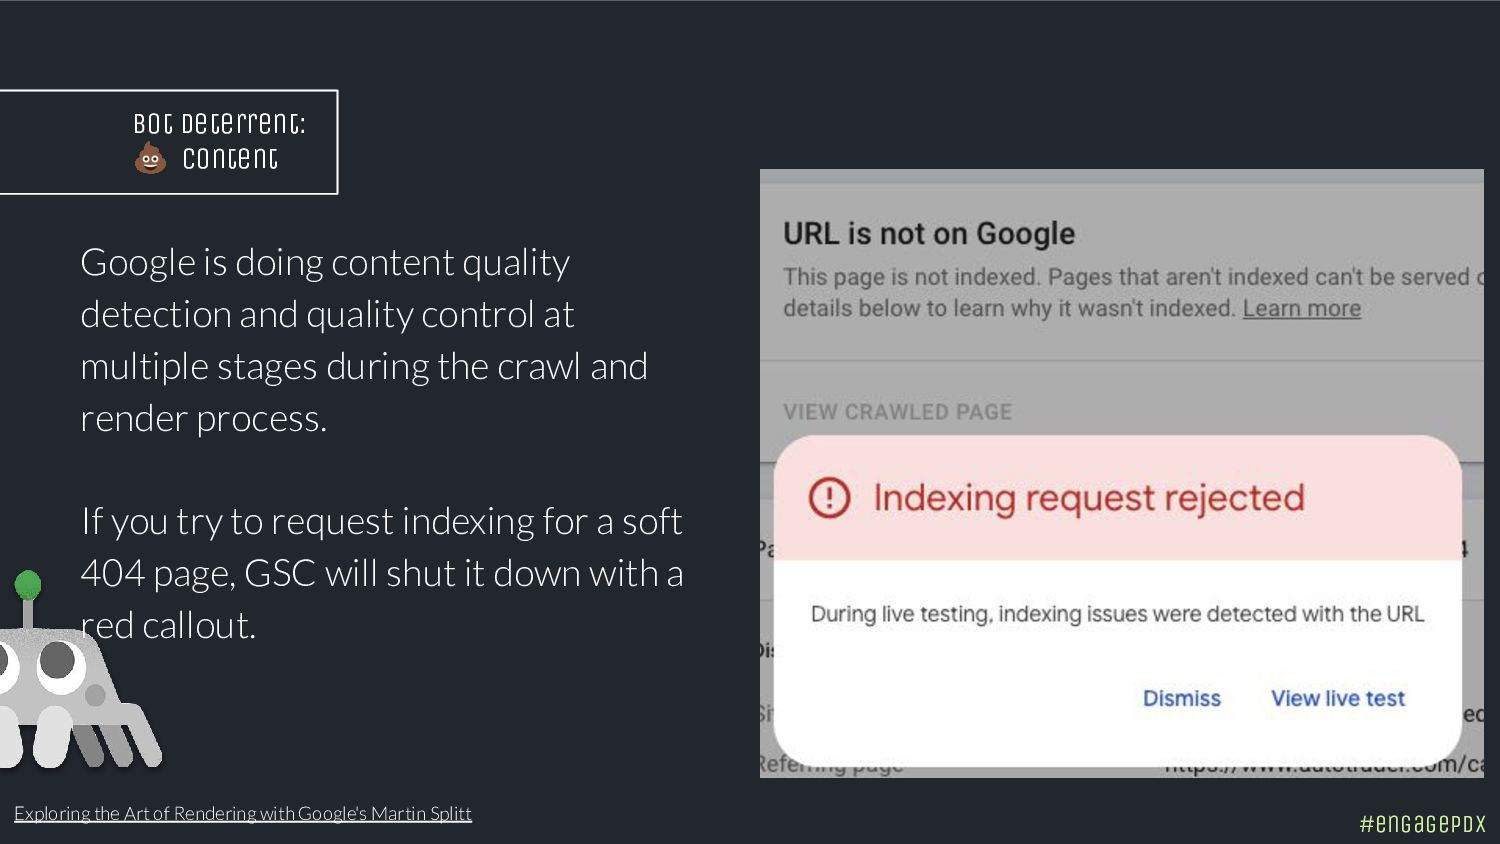
Bot Deterrent: 💩 content #engagePDX Google is doing content quality
detection and quality control at multiple stages during the crawl and render process. If you try to request indexing for a soft 404 page, GSC will shut it down with a red callout. Exploring the Art of Rendering with Google's Martin Splitt -
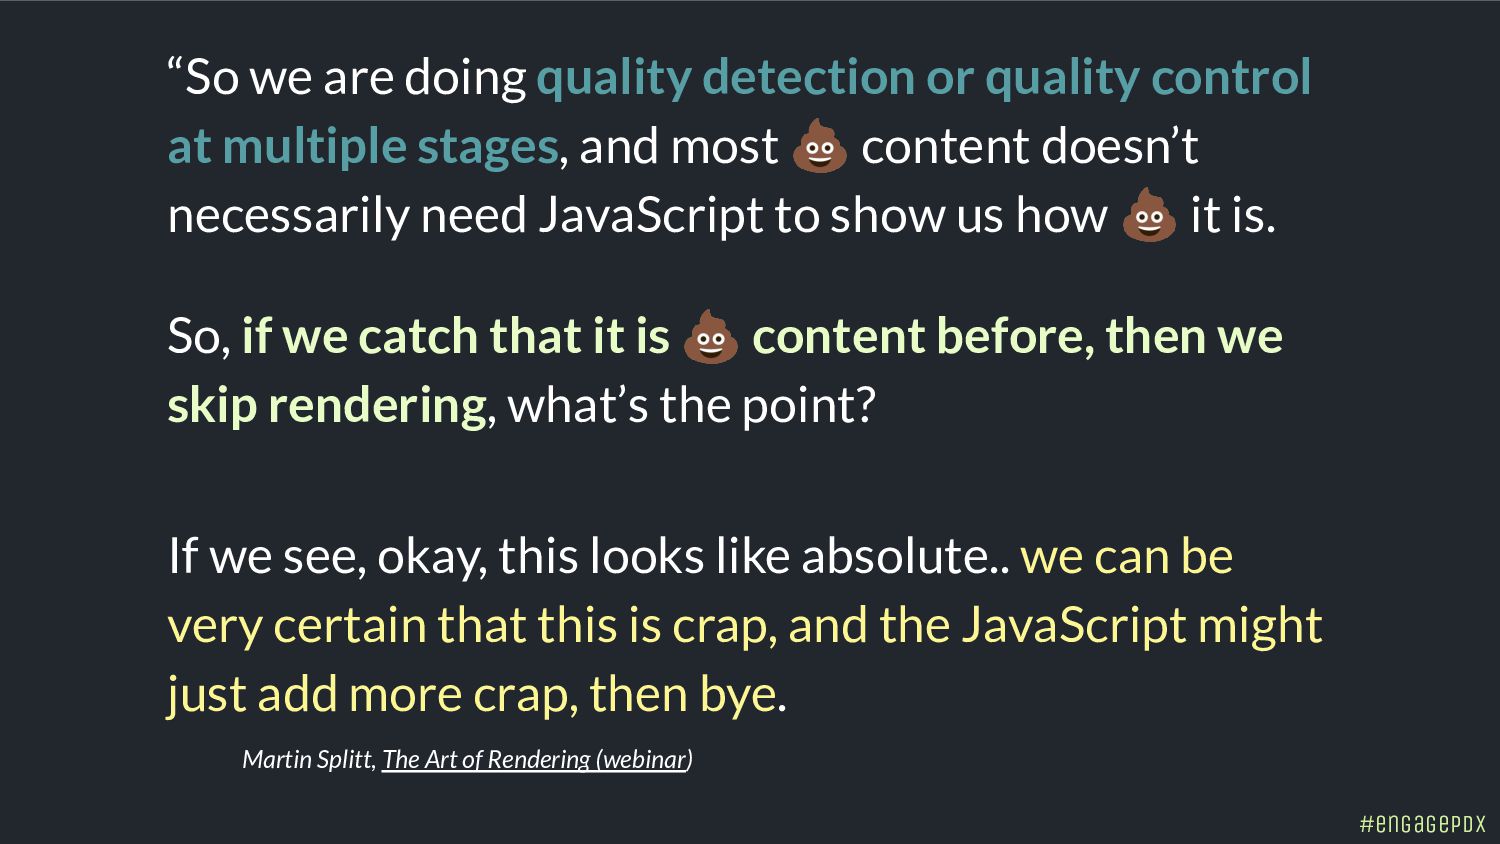
#engagePDX “So we are doing quality detection or quality control
at multiple stages, and most 💩 content doesn’t necessarily need JavaScript to show us how 💩 it is. So, if we catch that it is 💩 content before, then we skip rendering, what’s the point? If we see, okay, this looks like absolute.. we can be very certain that this is crap, and the JavaScript might just add more crap, then bye. Martin Splitt, The Art of Rendering (webinar) -
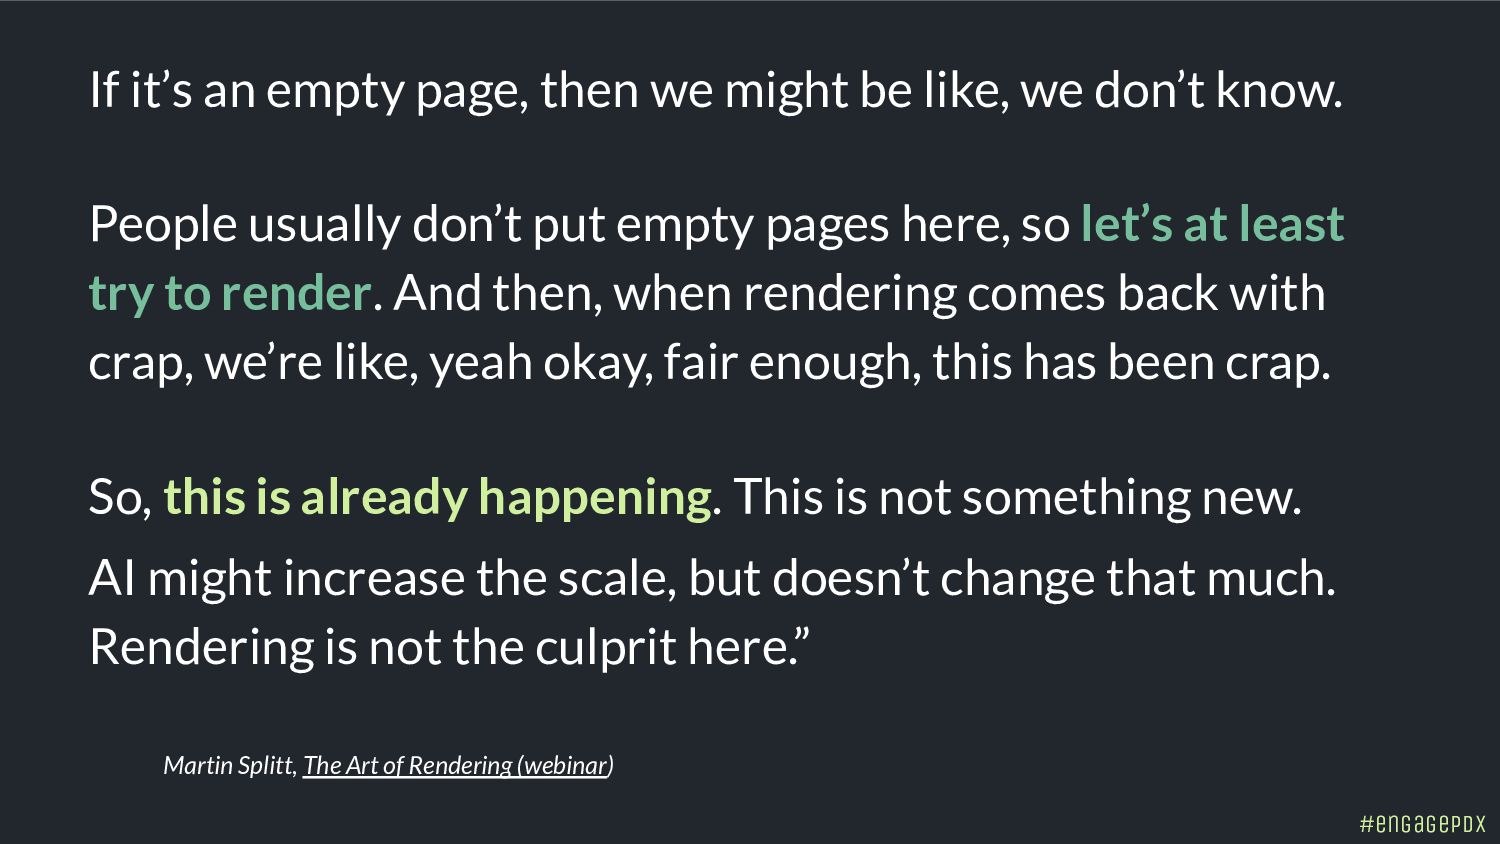
#engagePDX If it’s an empty page, then we might be
like, we don’t know. People usually don’t put empty pages here, so let’s at least try to render. And then, when rendering comes back with crap, we’re like, yeah okay, fair enough, this has been crap. So, this is already happening. This is not something new. AI might increase the scale, but doesn’t change that much. Rendering is not the culprit here.” Martin Splitt, The Art of Rendering (webinar) -
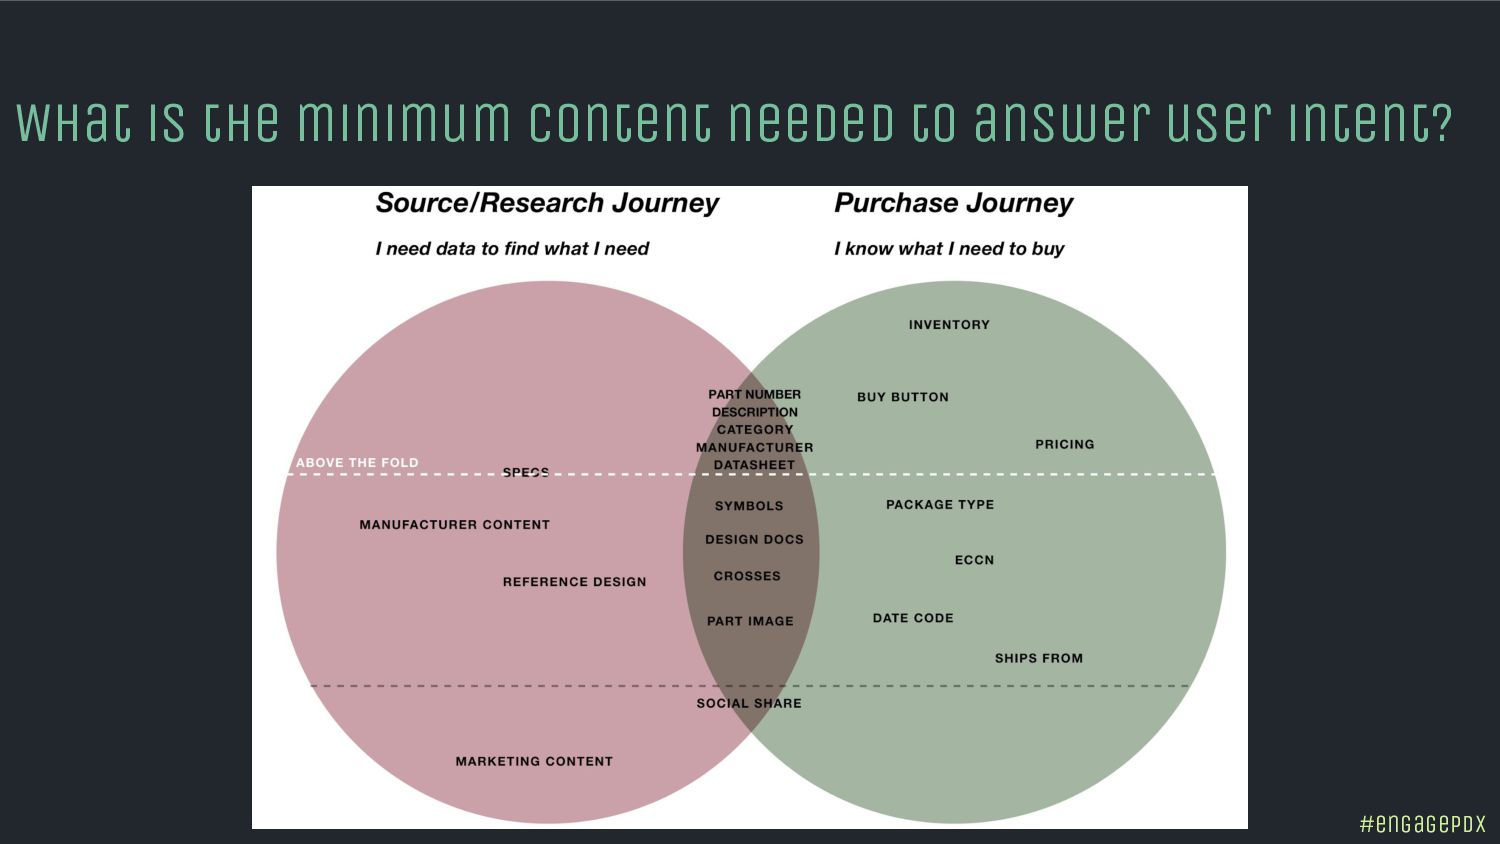
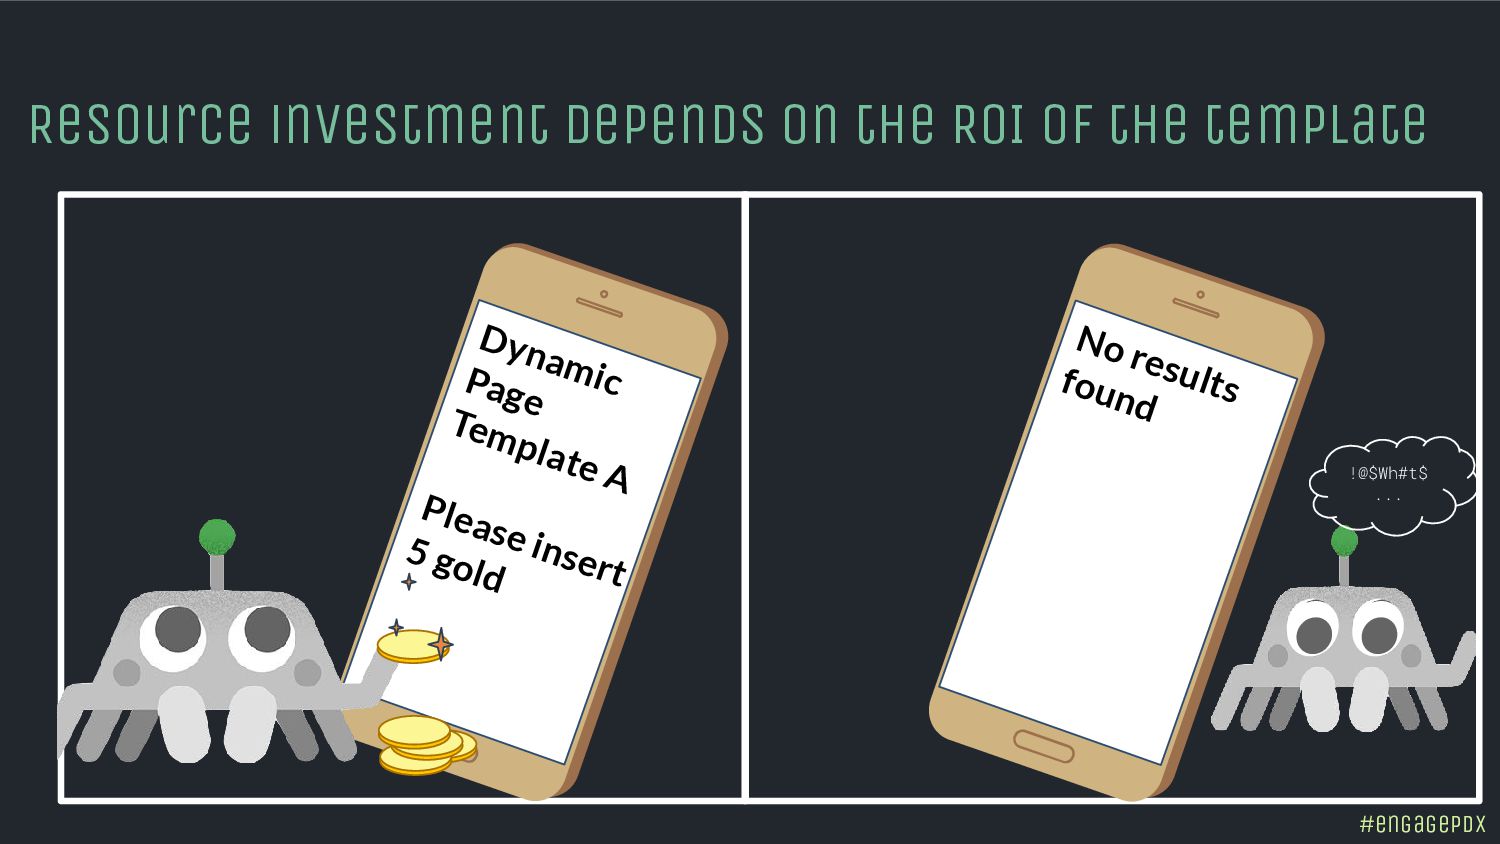
!@$Wh#t$ ... Dynamic Page Template A Please insert 5 gold
Resource investment depends on the ROI of the template No results found #engagePDX -
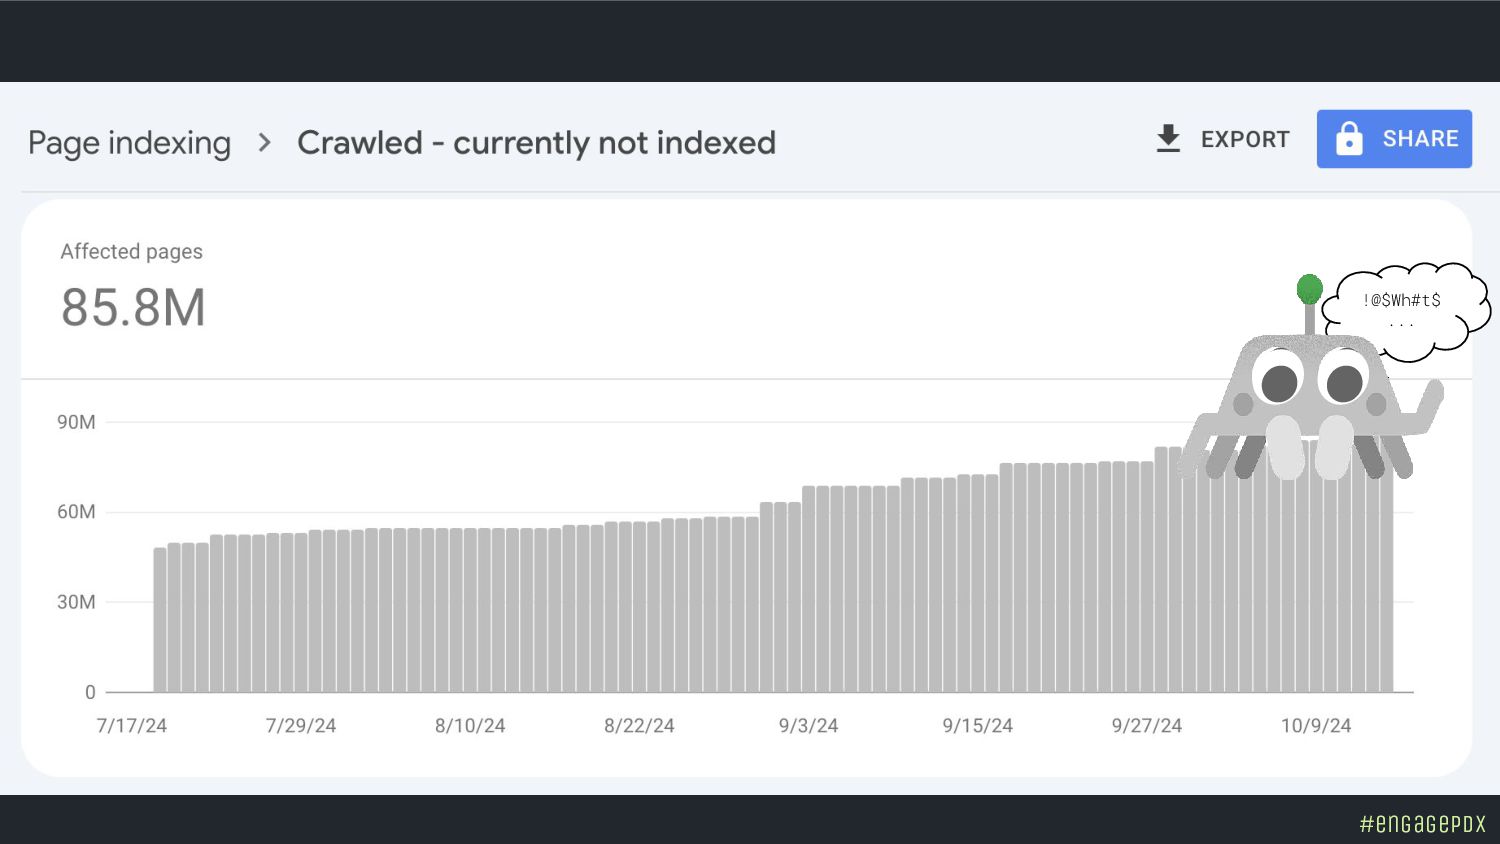
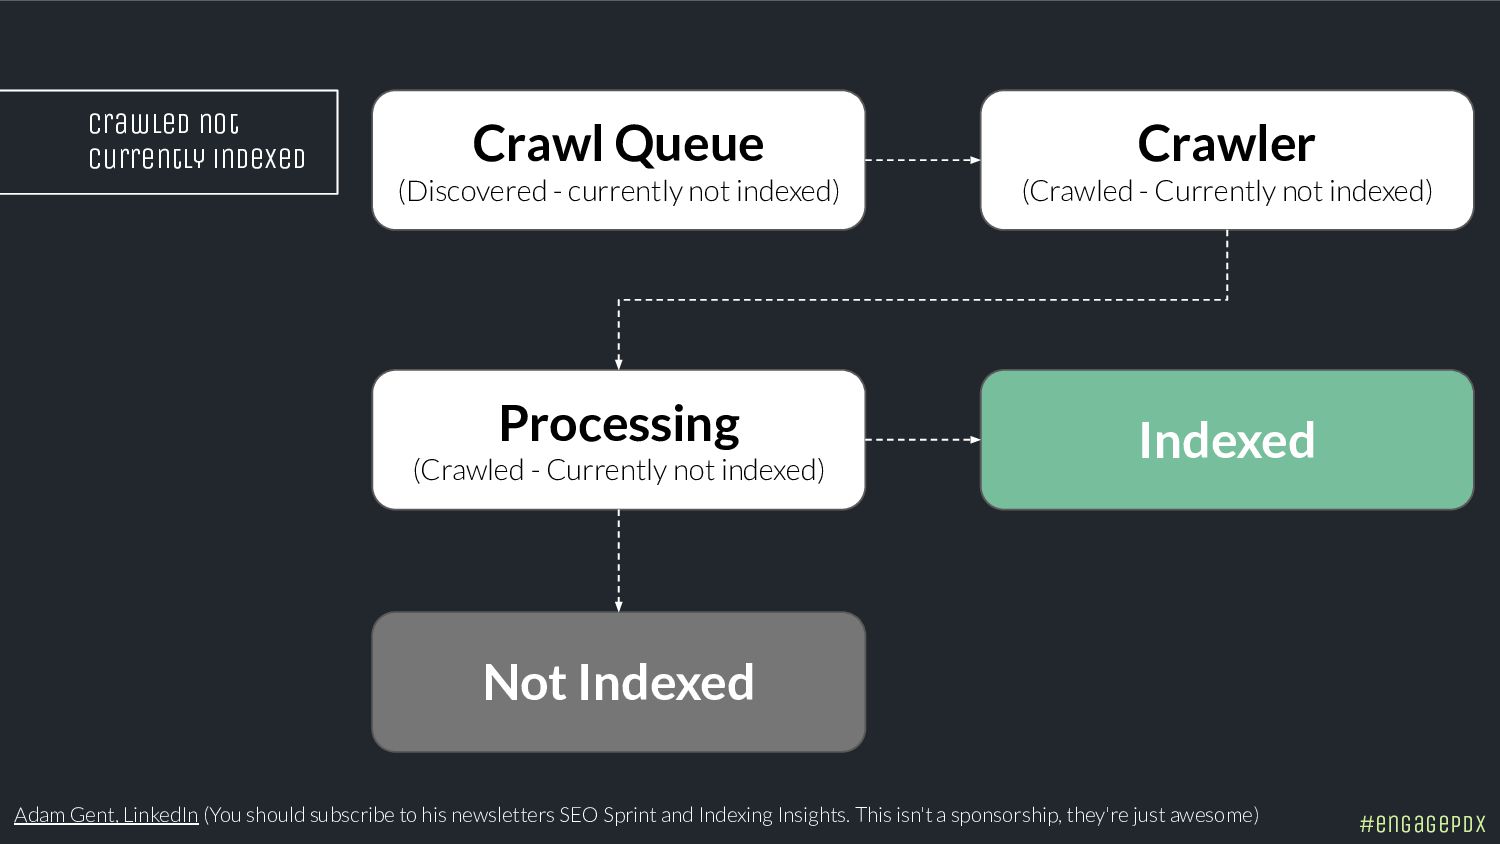
Crawled not currently indexed Adam Gent, LinkedIn (You should subscribe
to his newsletters SEO Sprint and Indexing Insights. This isn't a sponsorship, they're just awesome) Crawl Queue (Discovered - currently not indexed) Crawler (Crawled - Currently not indexed) Processing (Crawled - Currently not indexed) Indexed Not Indexed #engagePDX -
“When we crawl your page with Googlebot, we go fetch
the content and then we give it to chrome. Then Chrome runs all the scripts. It loads additional content. Once everything's loaded we take a snapshot of the page and that's the content that actually gets indexed.” Indexing & the Rendered DOM - Erik Hendriks, Software Engineer at Google Rendering (WMConf MTV '19) #engagePDX -
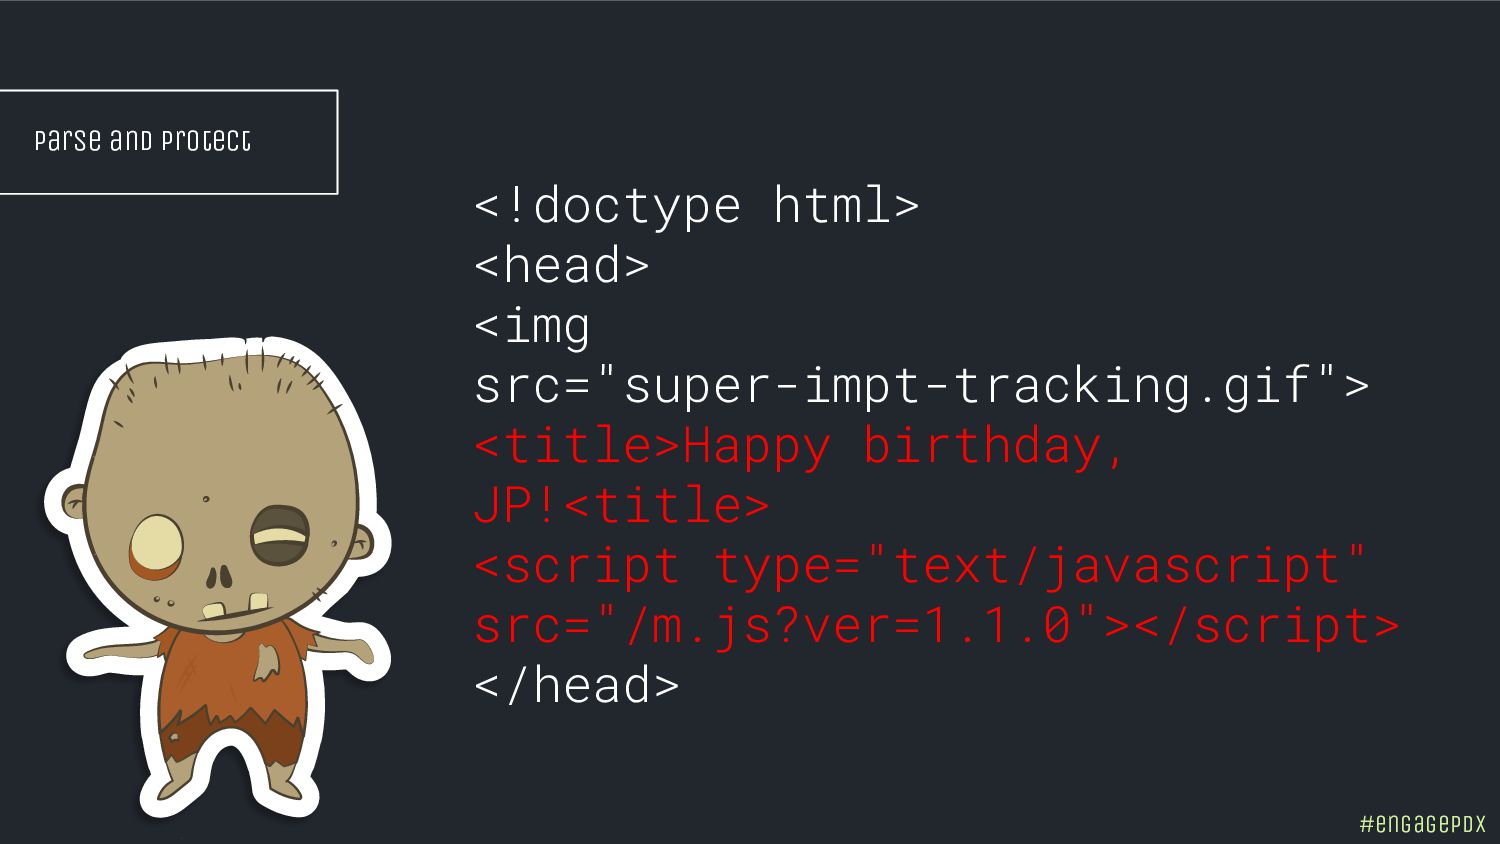
<!doctype html> <head> <img src="super-impt-tracking.gif"> <title>Happy birthday, JP!<title> <script type="text/javascript"
src="/m.js?ver=1.1.0"></script> </head> Parse and Protect #engagePDX -
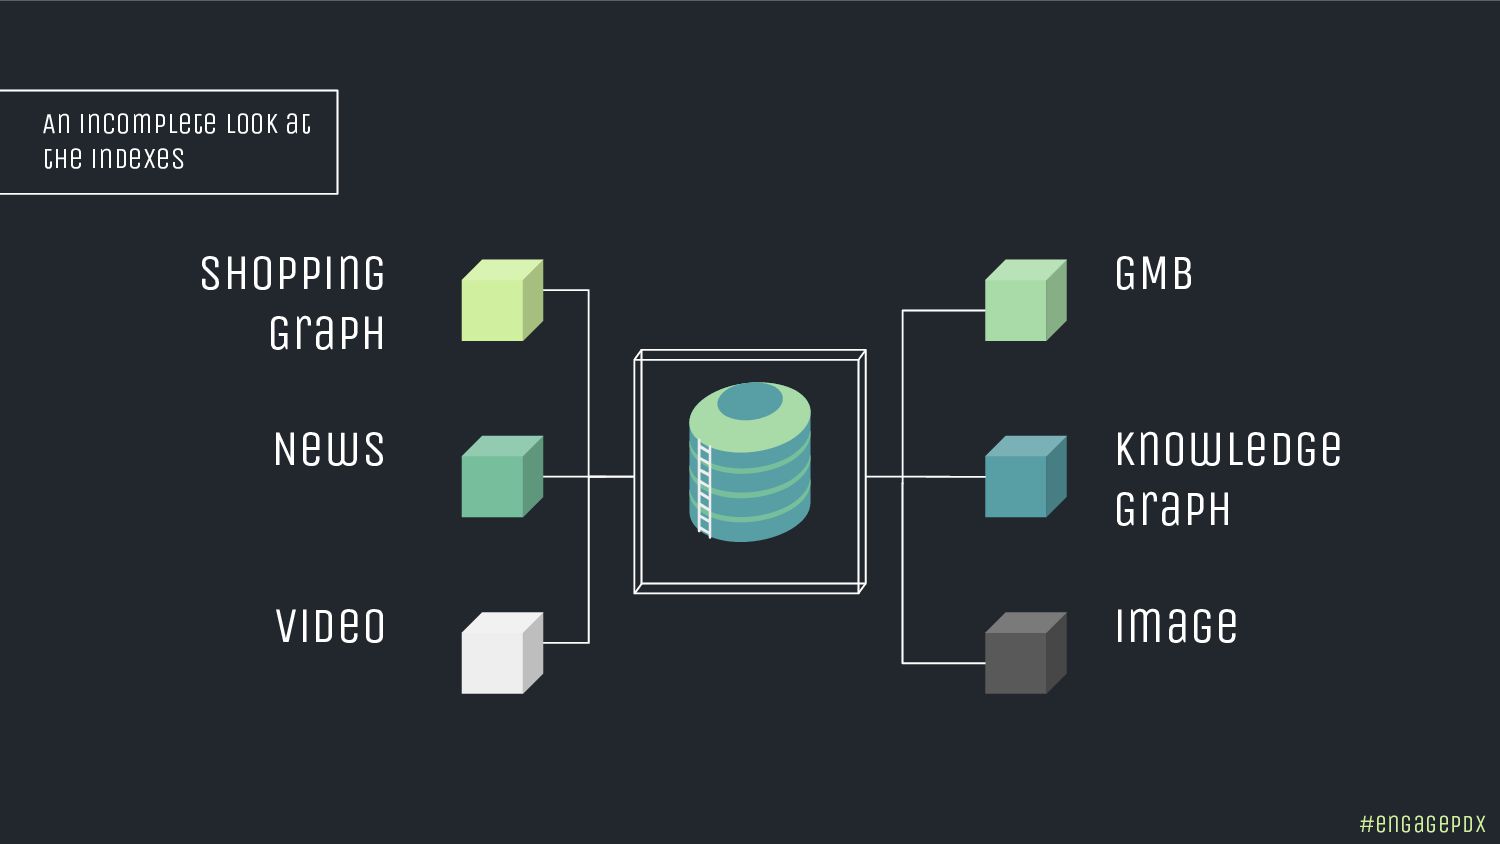
An incomplete look at the indexes Shopping Graph News Video
GMB Knowledge Graph image #engagePDX -
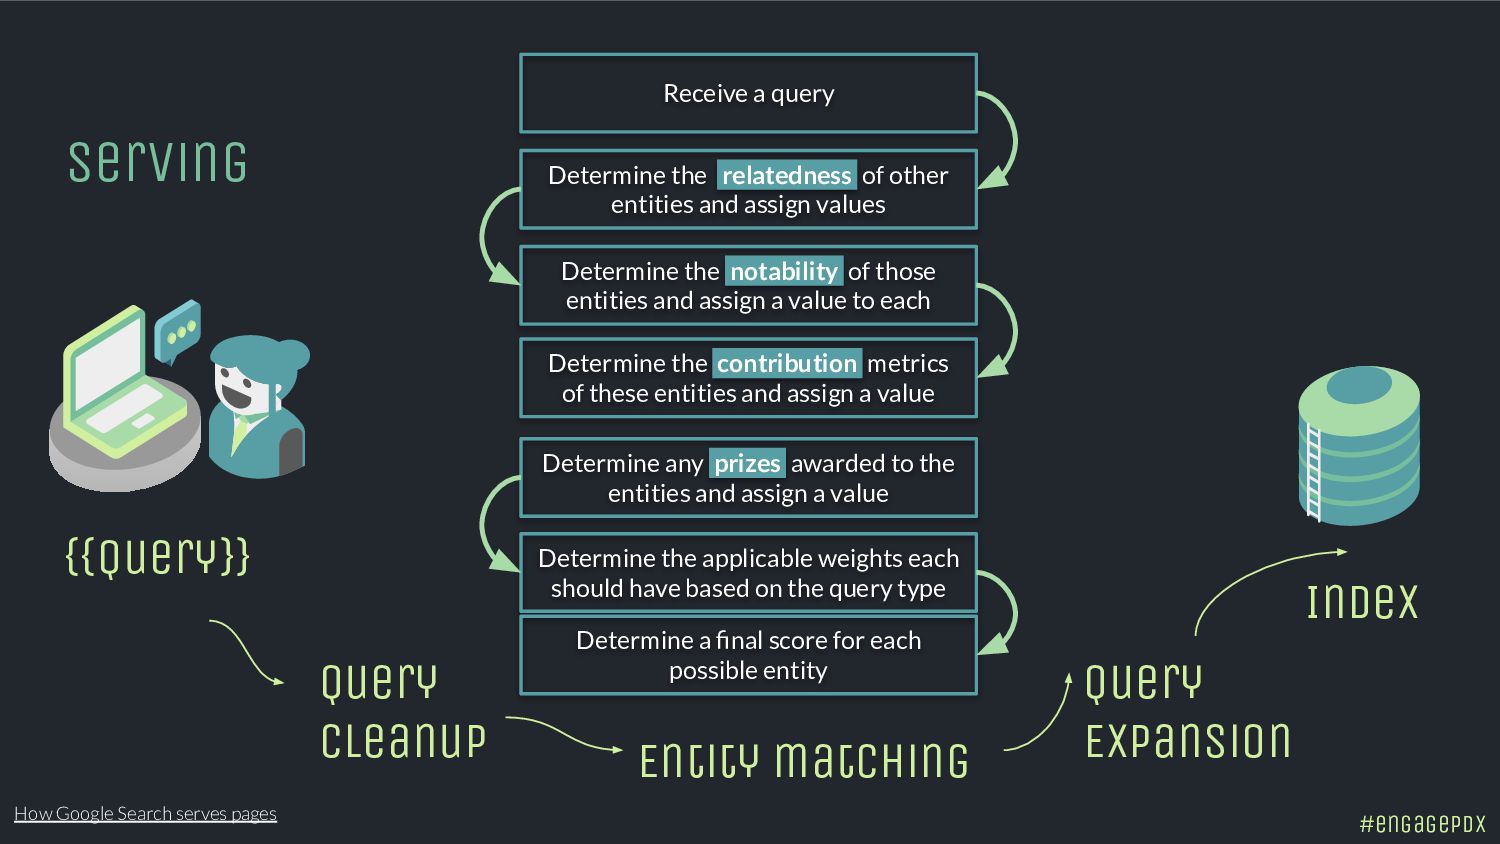
Serving {{Query}} Query cleanup Entity matching Index How Google Search
serves pages Receive a query Determine the relatedness of other entities and assign values Determine the notability of those entities and assign a value to each Determine the contribution metrics of these entities and assign a value Determine any prizes awarded to the entities and assign a value Determine the applicable weights each should have based on the query type Determine a final score for each possible entity Query Expansion #engagePDX -
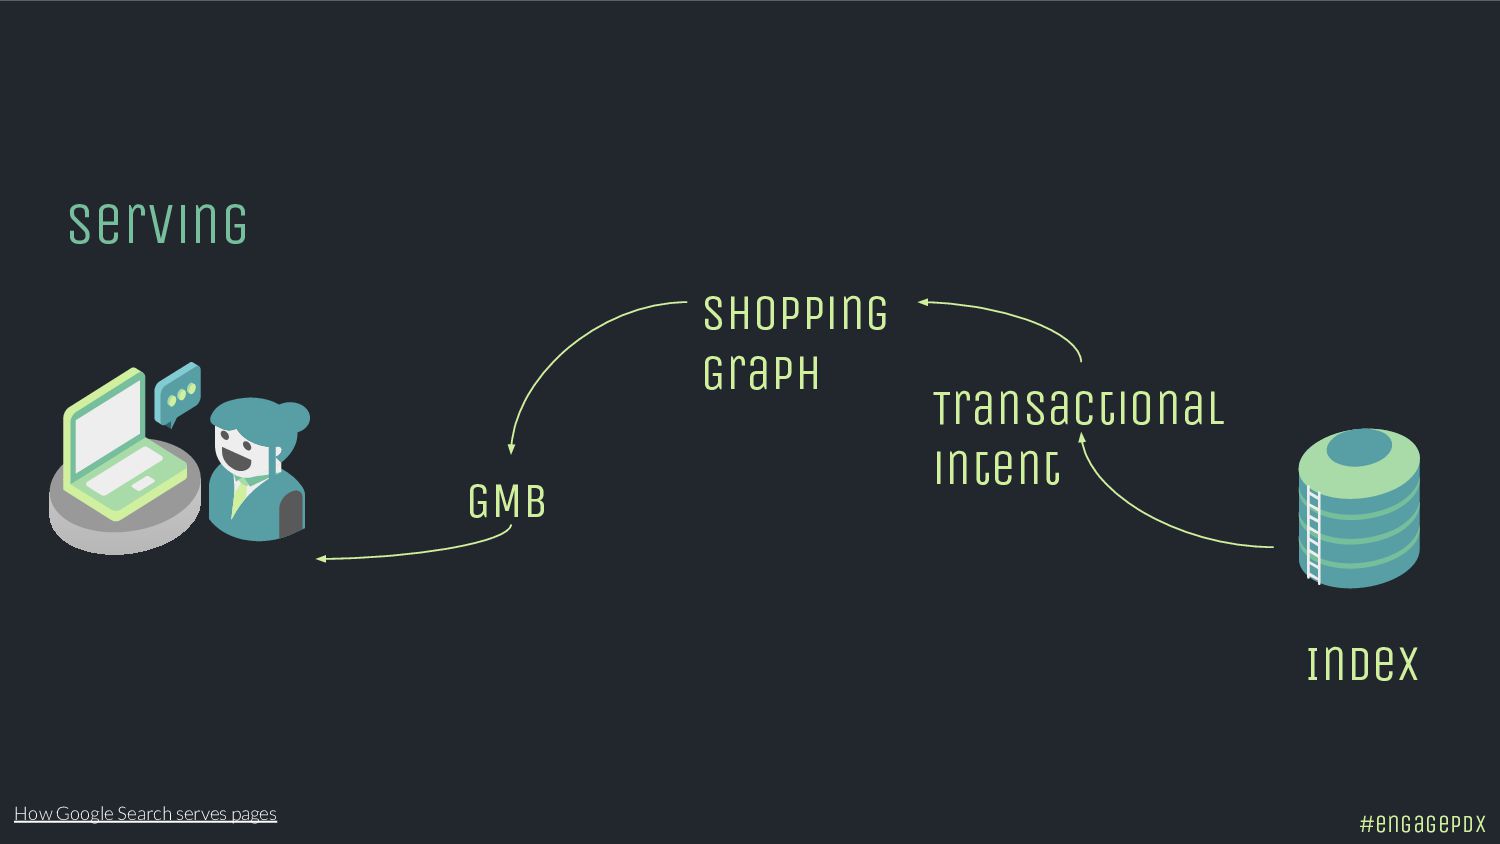
Serving Index How Google Search serves pages Transactional intent Shopping
Graph GMB #engagePDX -
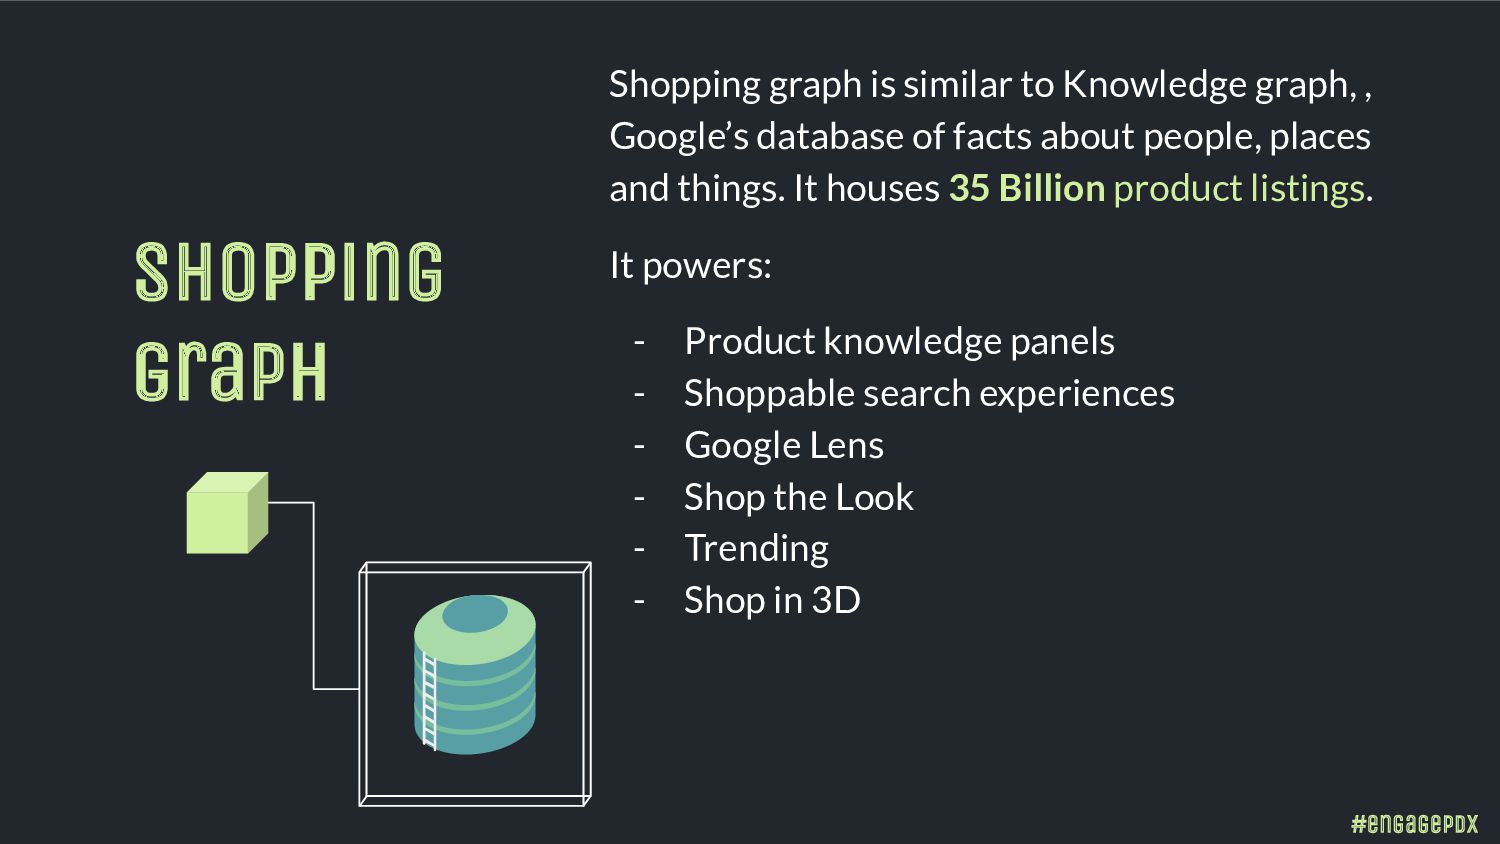
Shopping graph Shopping graph is similar to Knowledge graph, ,
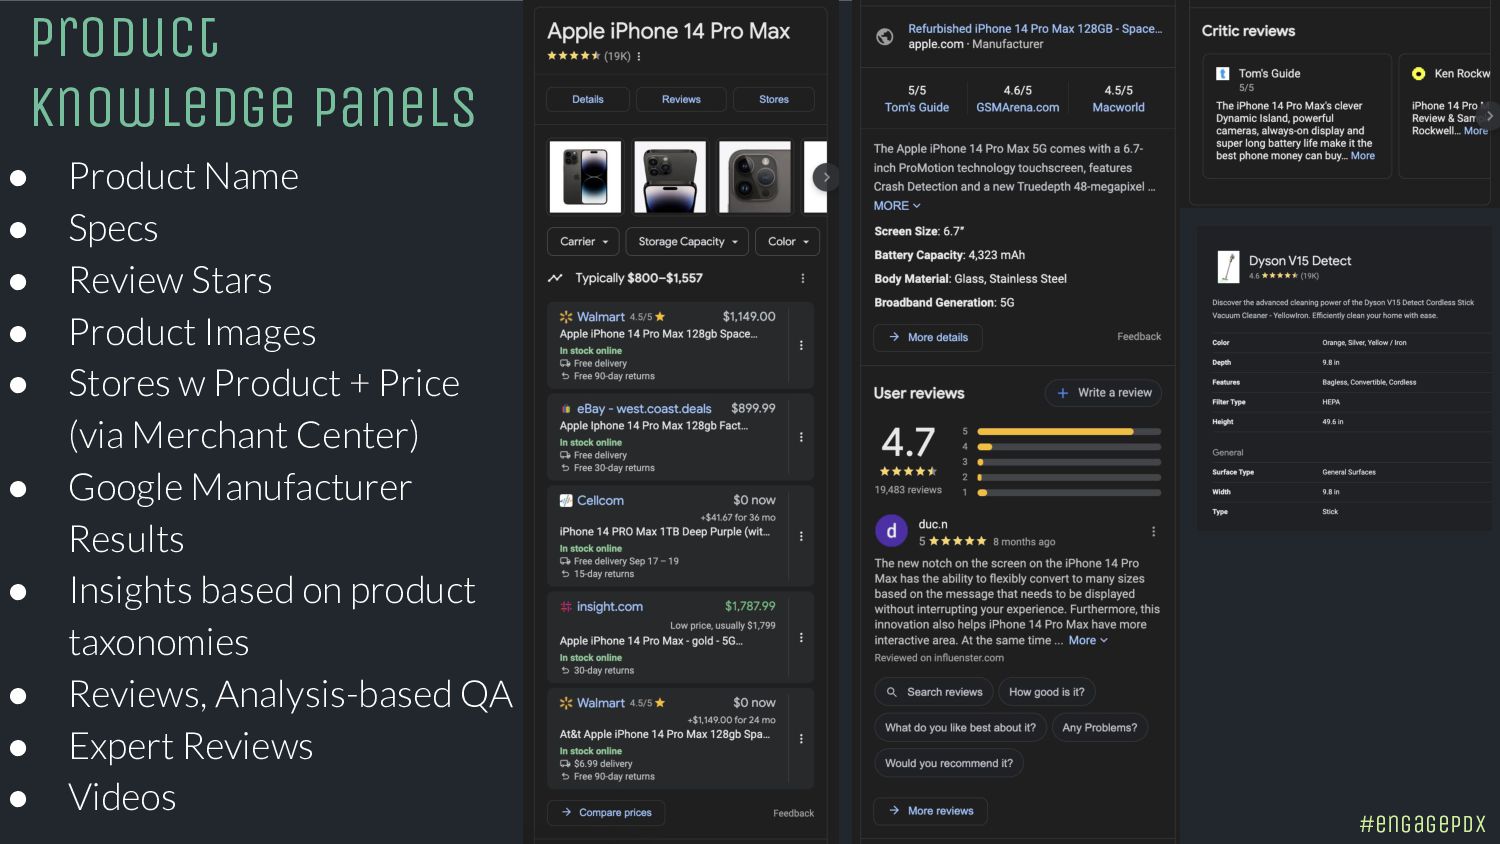
Google’s database of facts about people, places and things. It houses 35 Billion product listings. It powers: - Product knowledge panels - Shoppable search experiences - Google Lens - Shop the Look - Trending - Shop in 3D #engagePDX -
MUM Powered - COVID-19 vaccine information initiative - Shopping Graph
- Things to Know - Multisearch (including Lens) - Visually Intuitive SERP Initiative - Shop the Look - Trending - Shop in 3D #engagePDX -
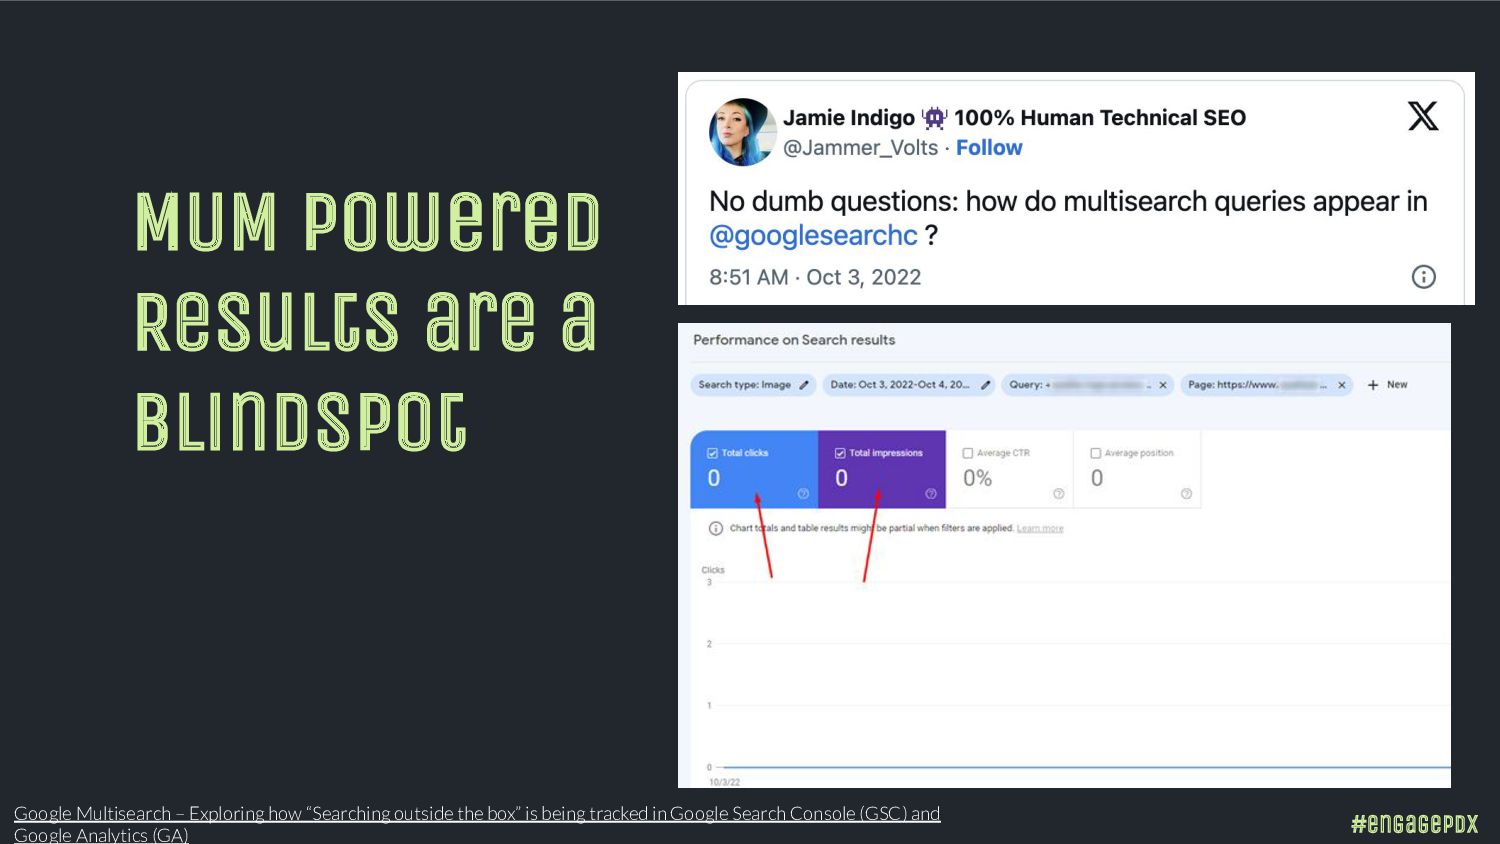
MUM Powered Results are a blindspot Google Multisearch – Exploring
how “Searching outside the box” is being tracked in Google Search Console (GSC) and Google Analytics (GA) #engagePDX -
• Product Name • Specs • Review Stars • Product
Images • Stores w Product + Price (via Merchant Center) • Google Manufacturer Results • Insights based on product taxonomies • Reviews, Analysis-based QA • Expert Reviews • Videos Product Knowledge Panels #engagePDX -
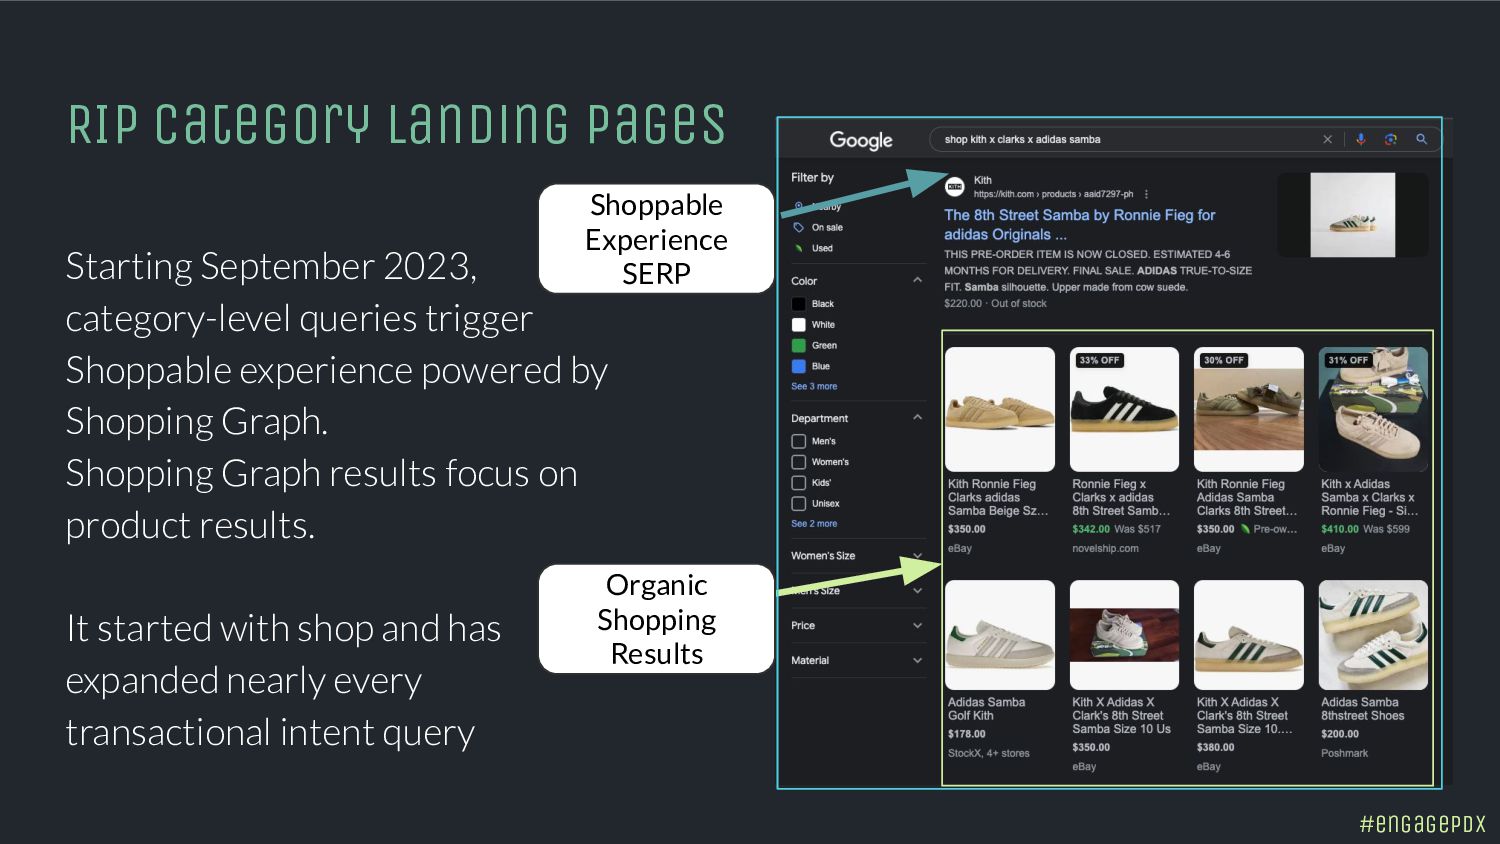
RIP Category Landing Pages Starting September 2023, category-level queries trigger
Shoppable experience powered by Shopping Graph. Shopping Graph results focus on product results. It started with shop and has expanded nearly every transactional intent query Shoppable Experience SERP Organic Shopping Results #engagePDX -
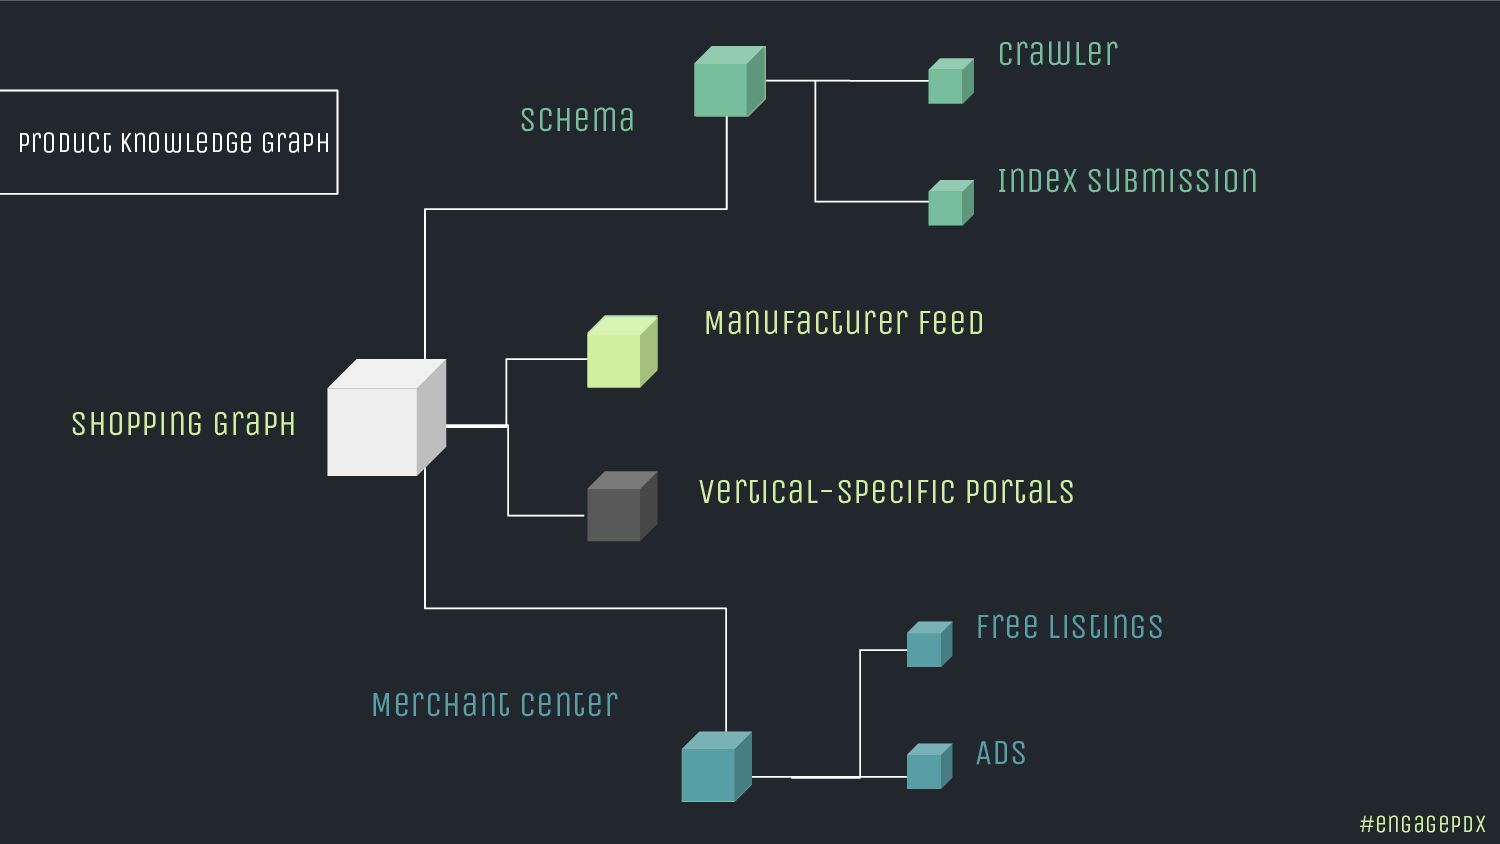
Product Knowledge Graph Merchant Center Crawler Index submission Free Listings
Ads Schema Vertical-specific portals Manufacturer Feed Shopping Graph #engagePDX -
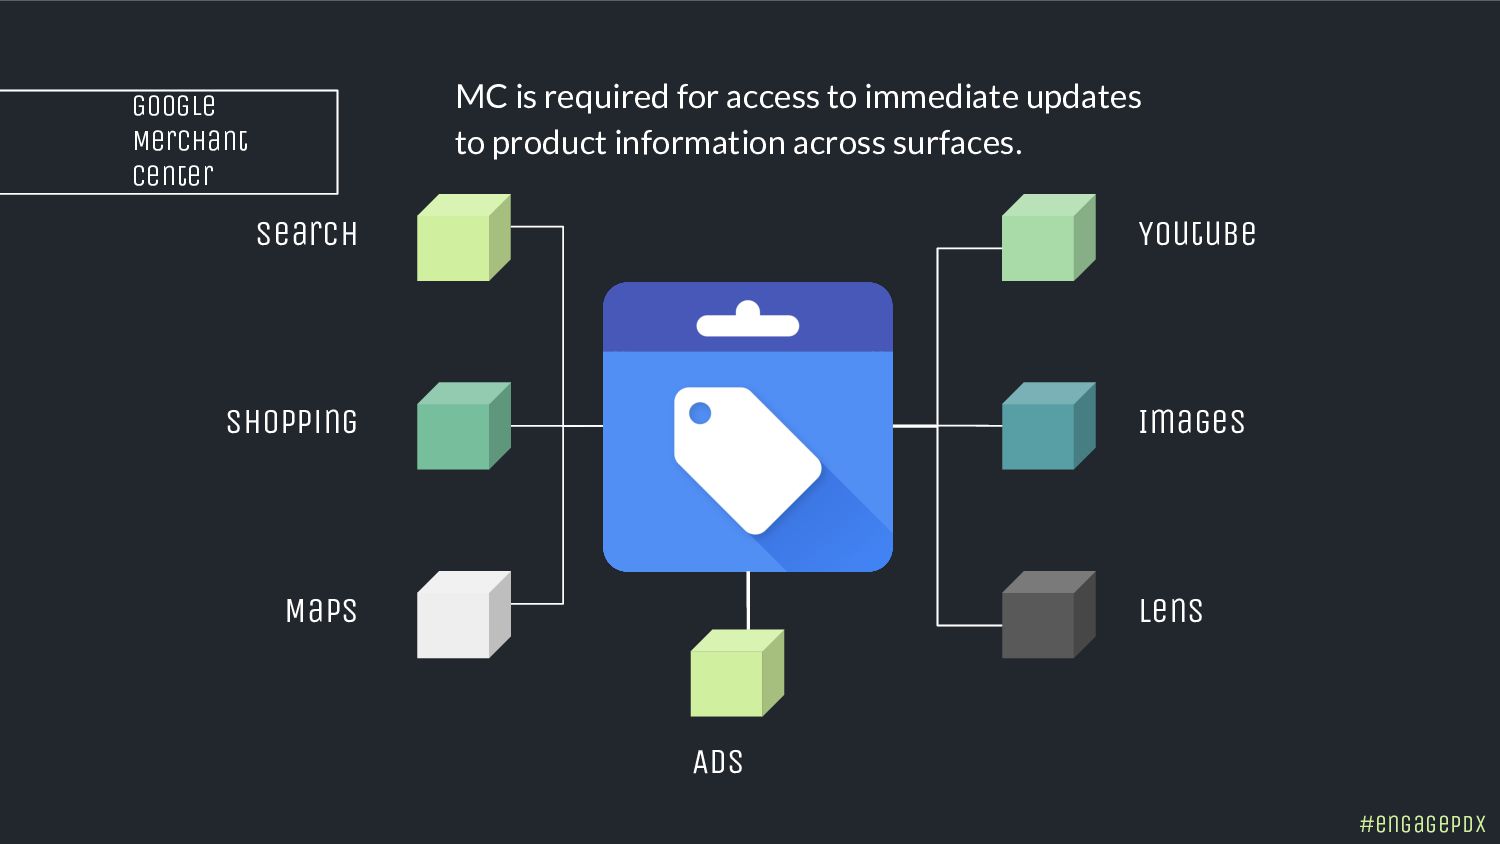
Google Merchant Center Search Shopping Maps Youtube Images Lens Ads
#engagePDX MC is required for access to immediate updates to product information across surfaces. -
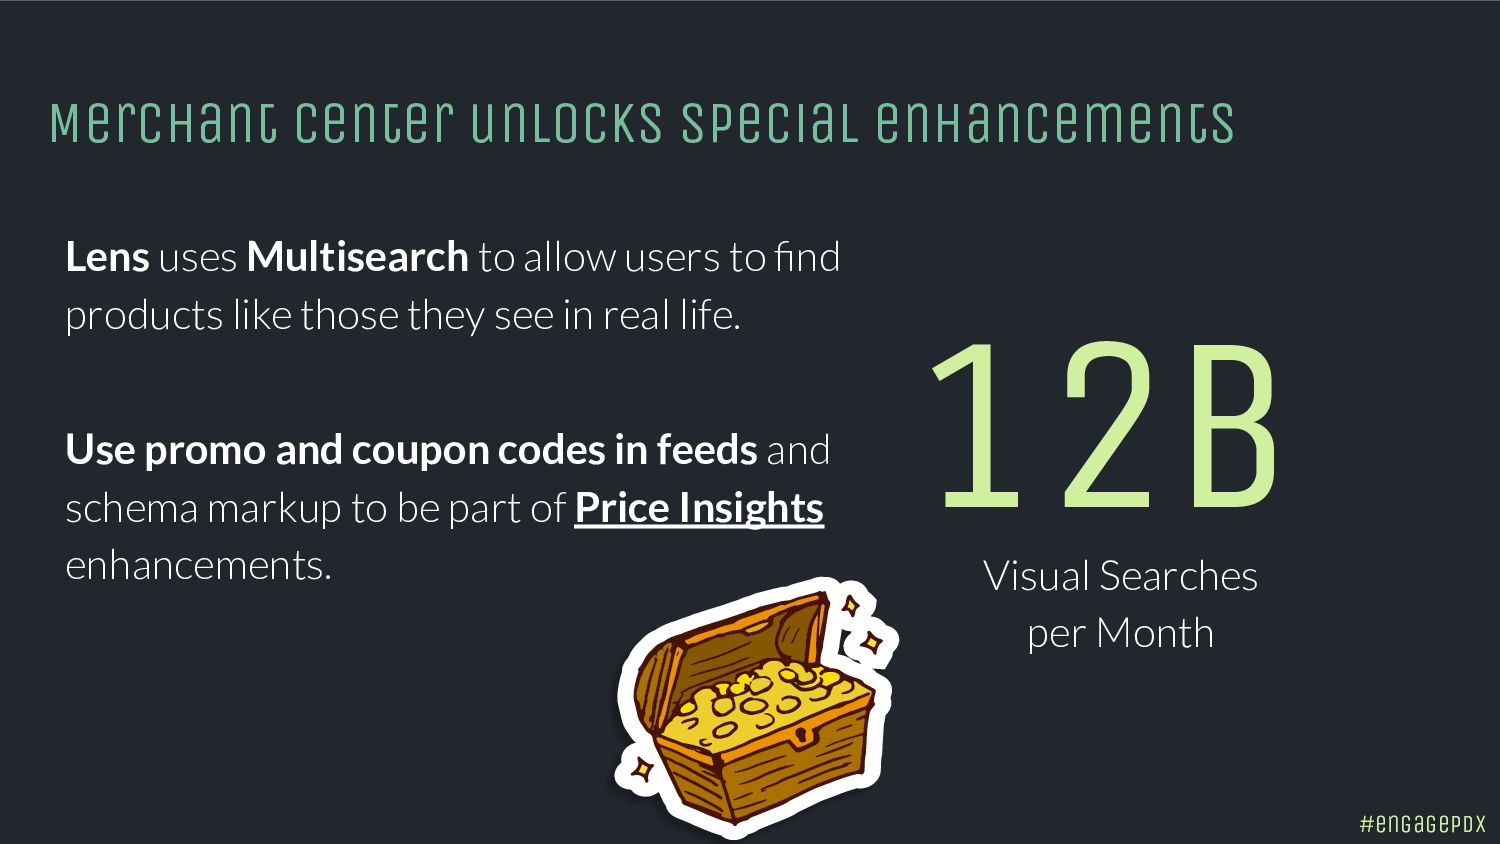
Lens uses Multisearch to allow users to find products like
those they see in real life. Use promo and coupon codes in feeds and schema markup to be part of Price Insights enhancements. 12B Visual Searches per Month Merchant Center unlocks special enhancements #engagePDX -
Merchant Center Feed optimization is your time to shine Merchant
Center Feeds are a consistent reliable source of data for Google that does not require them to crawl to find products. Here are some ways for you to use that AI for good: 1. Data completeness and accuracy 2. Highlight important product details 3. Use high-quality images (these can be generated in Google Product Studio when not readily available to seller) 4. Enhanced product data accuracy (train your data) 5. Analyzing product data to landing pages trends/accuracy #engagePDX -
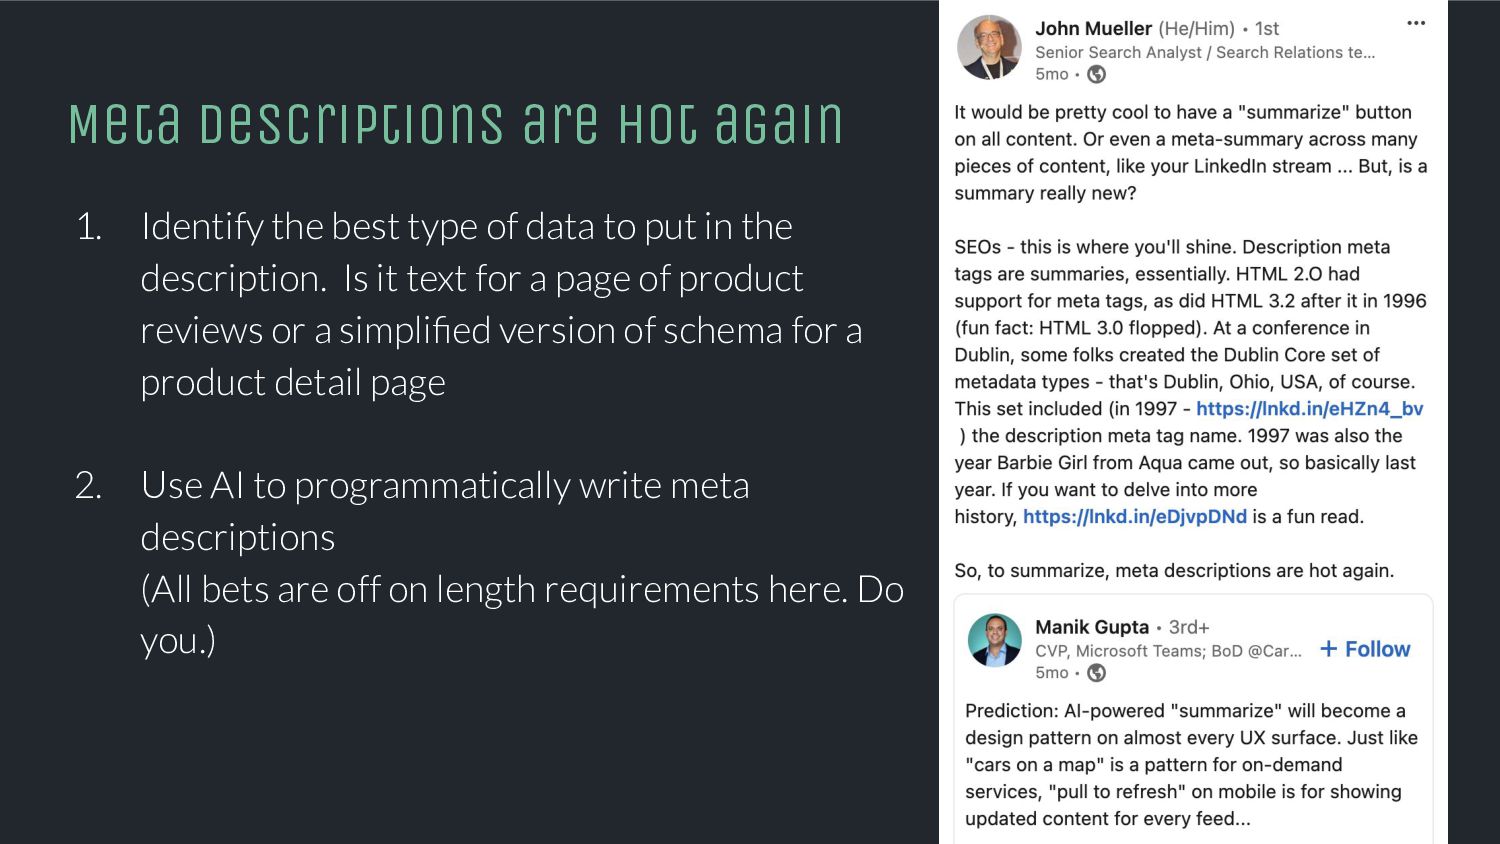
Meta Descriptions are hot again 1. Identify the best type
of data to put in the description. Is it text for a page of product reviews or a simplified version of schema for a product detail page 2. Use AI to programmatically write meta descriptions (All bets are off on length requirements here. Do you.) -
nothing a I says is true it s just probable
#engagePDX -
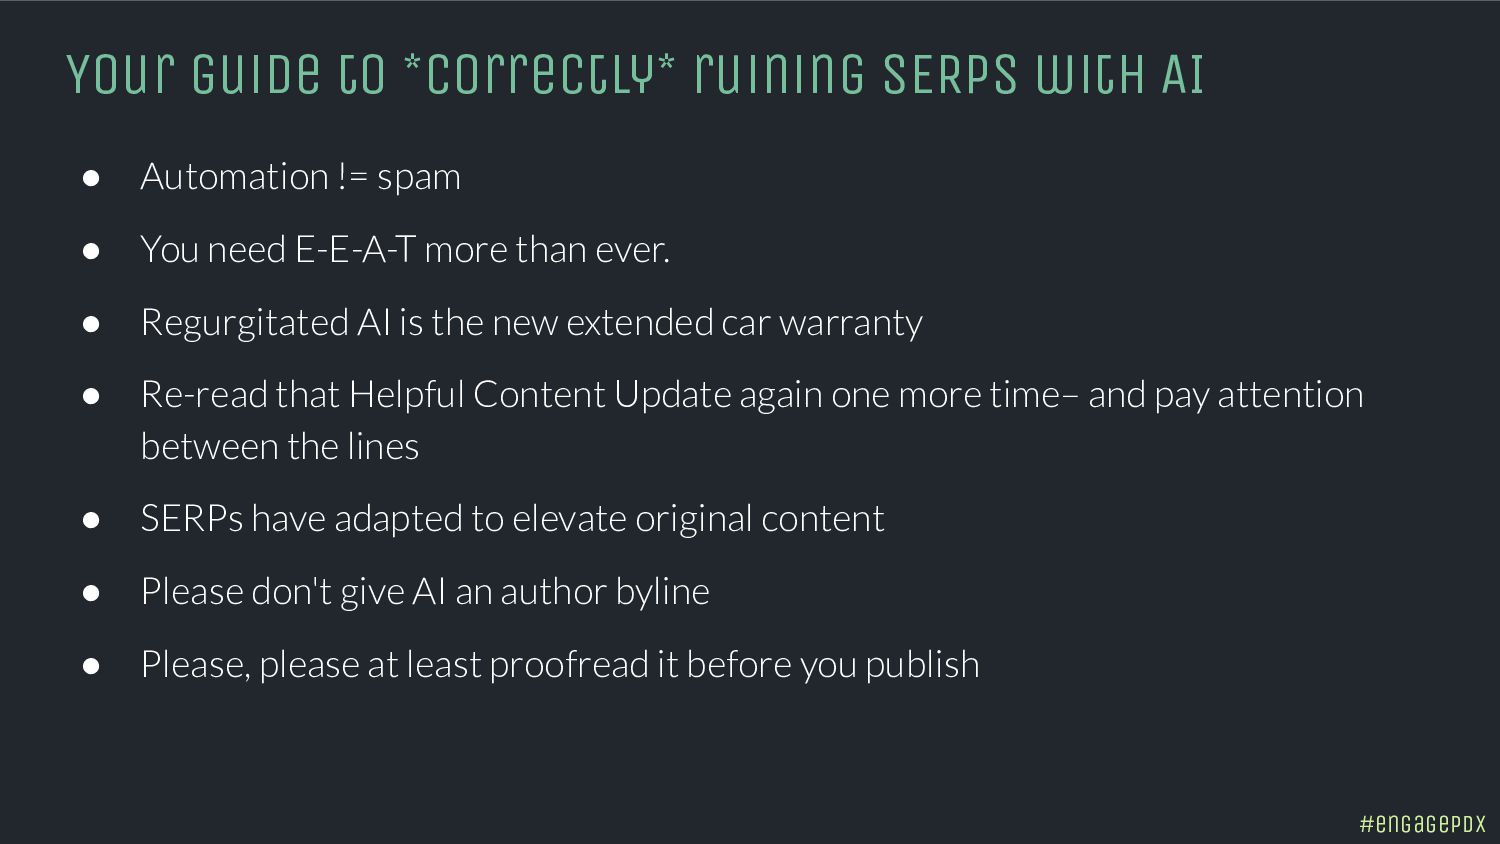
Your guide to *correctly* ruining SERPs with AI • Automation
!= spam • You need E-E-A-T more than ever. • Regurgitated AI is the new extended car warranty • Re-read that Helpful Content Update again one more time– and pay attention between the lines • SERPs have adapted to elevate original content • Please don't give AI an author byline • Please, please at least proofread it before you publish #engagePDX -
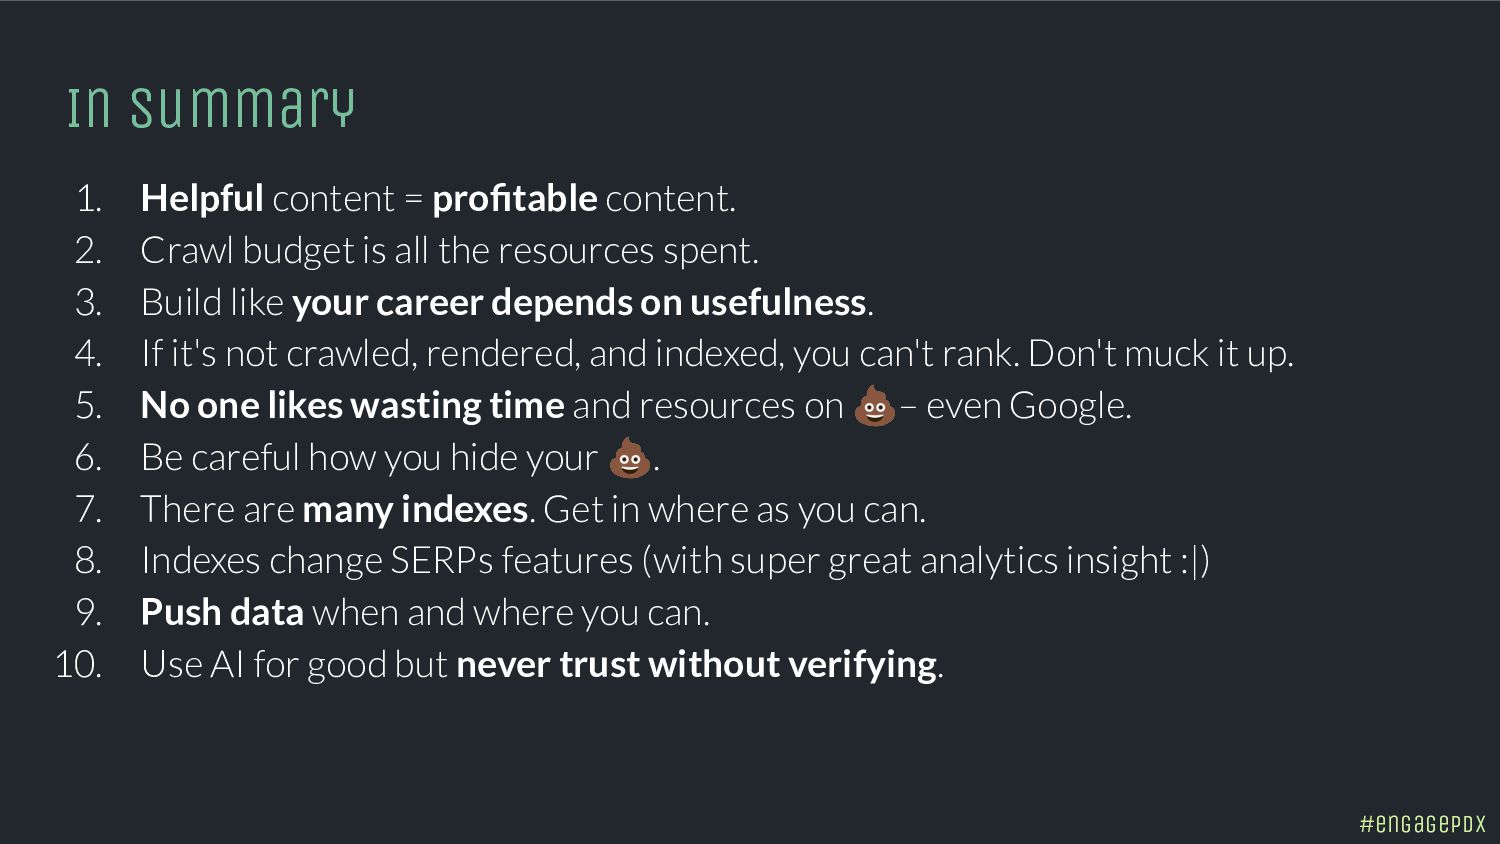
In summary 1. Helpful content = profitable content. 2. Crawl
budget is all the resources spent. 3. Build like your career depends on usefulness. 4. If it's not crawled, rendered, and indexed, you can't rank. Don't muck it up. 5. No one likes wasting time and resources on 💩– even Google. 6. Be careful how you hide your 💩. 7. There are many indexes. Get in where as you can. 8. Indexes change SERPs features (with super great analytics insight :|) 9. Push data when and where you can. 10. Use AI for good but never trust without verifying. #engagePDX -
| ̄ ̄ ̄ ̄ ̄ ̄ ̄ ̄ ̄ ̄ ̄ ̄| it's chaos be kind |____________| (\__/) || (•ㅅ•) ||
/ づ /in/jamie-indigo