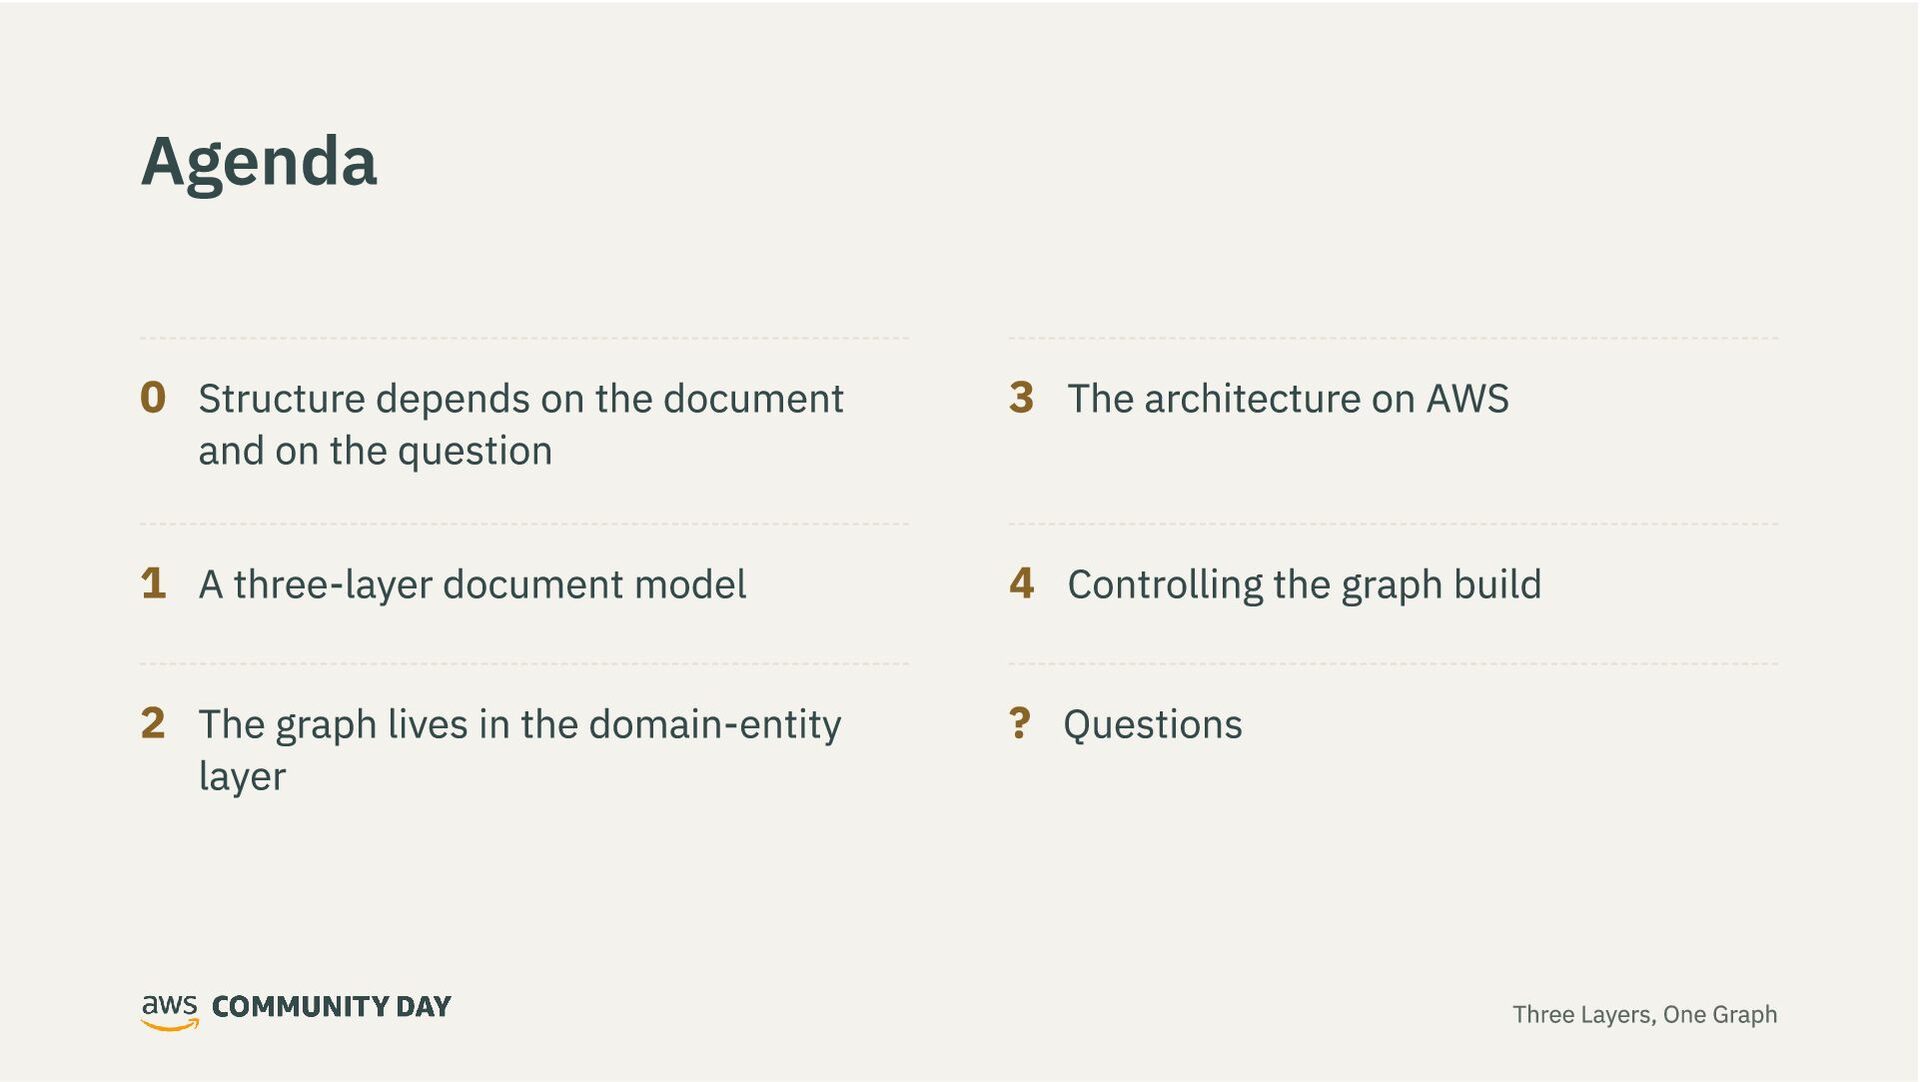
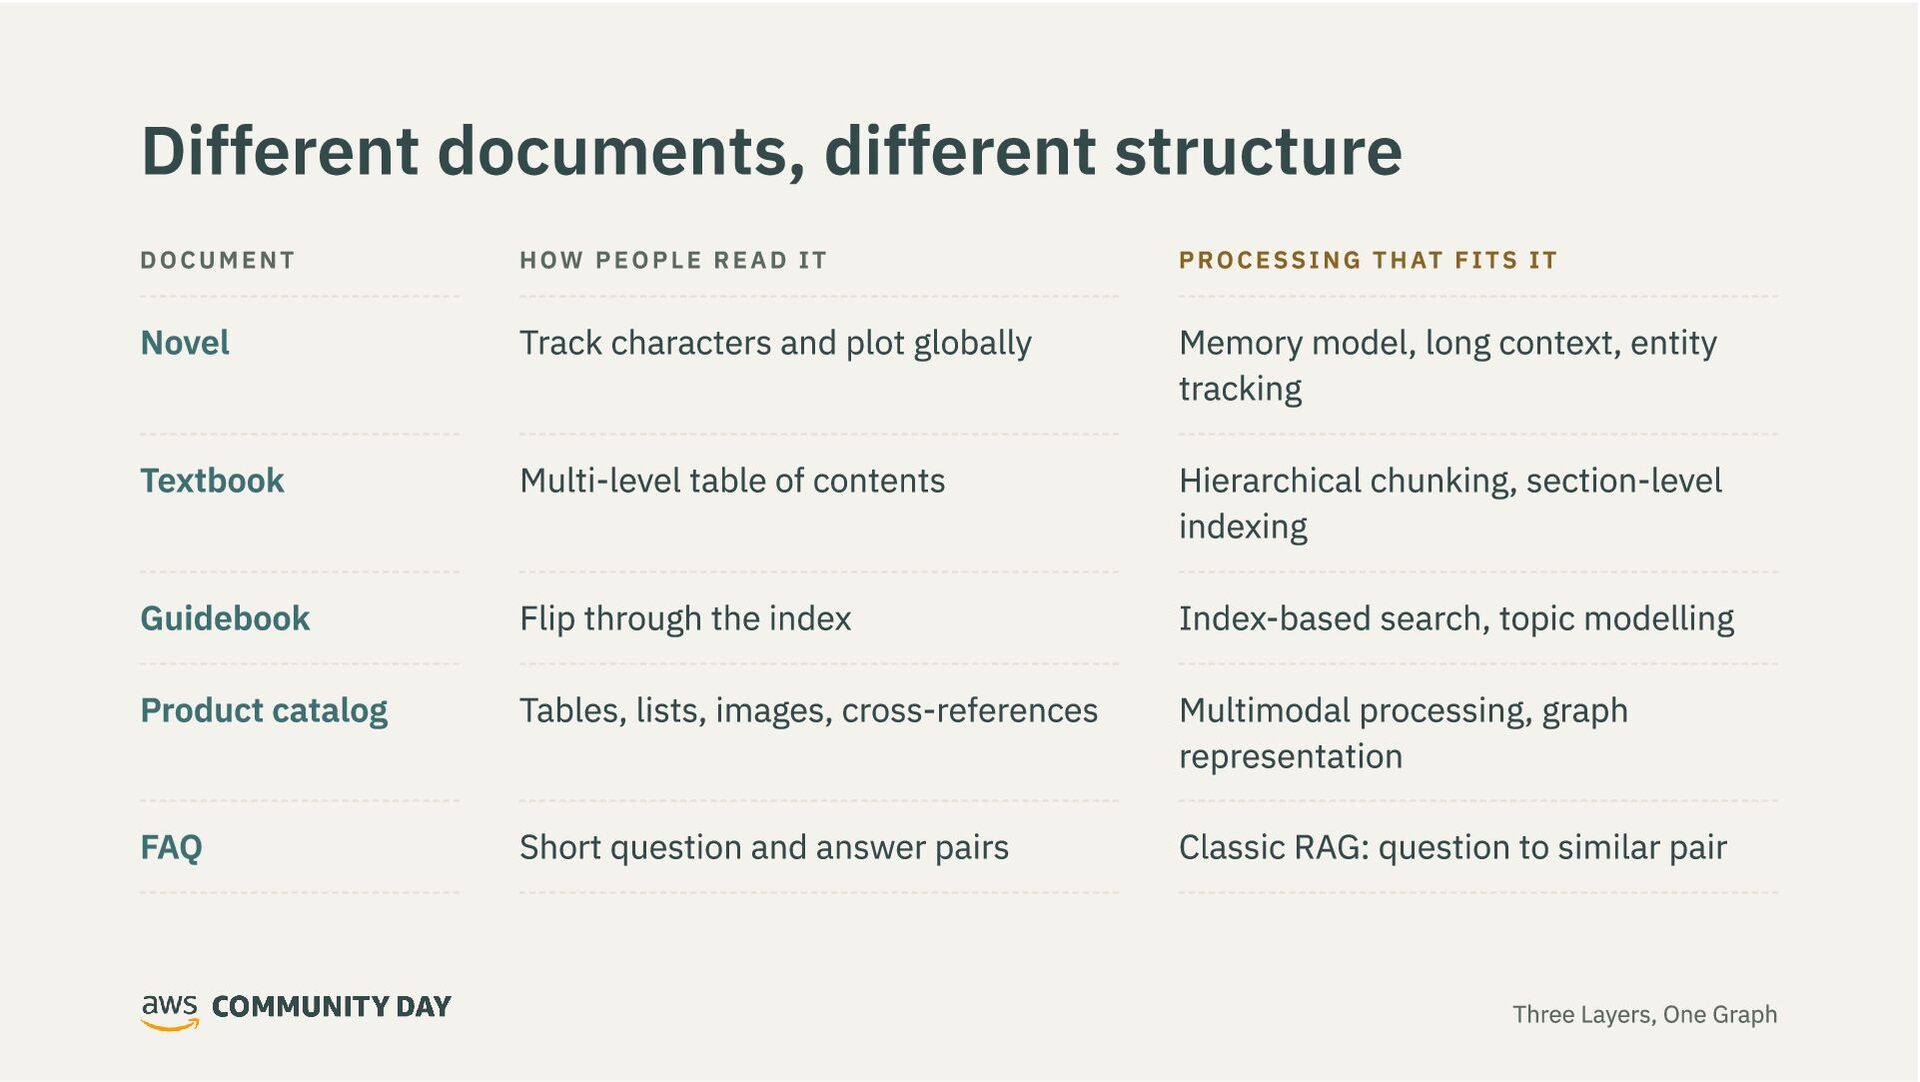
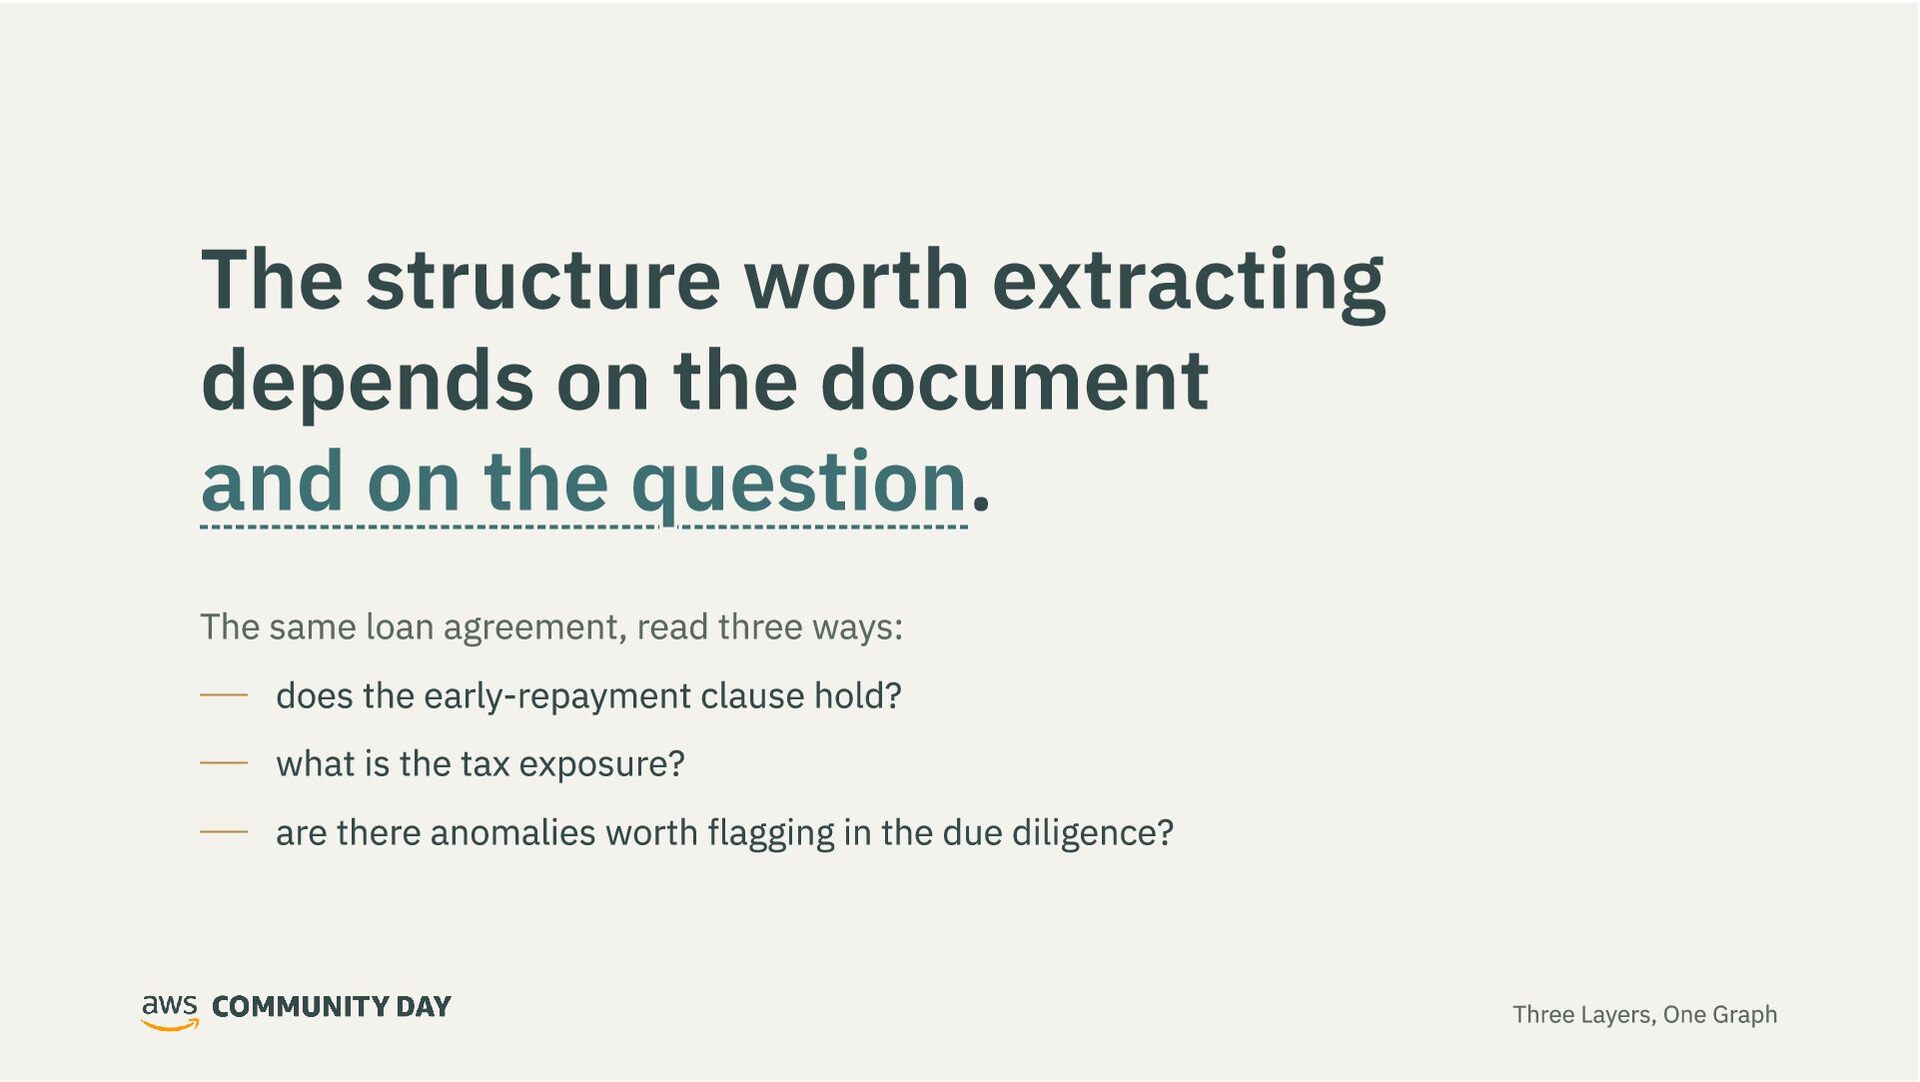
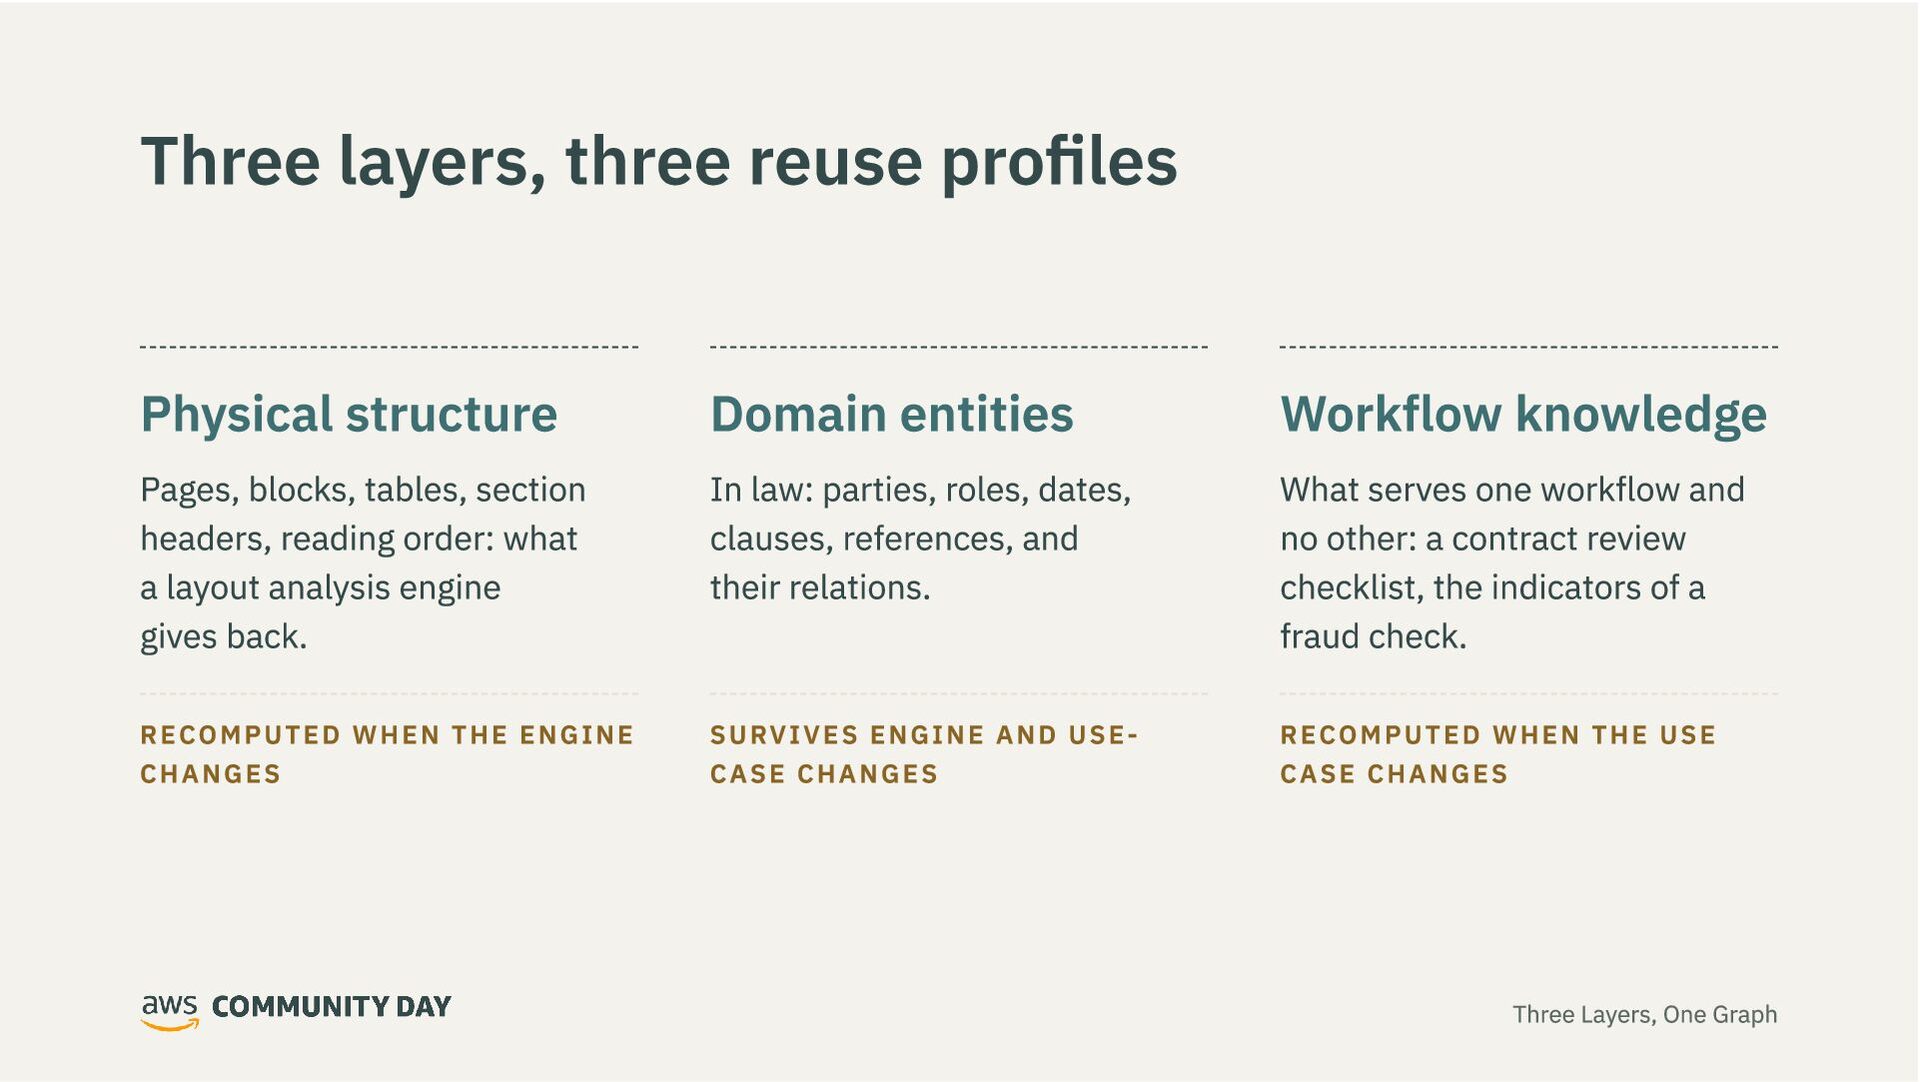
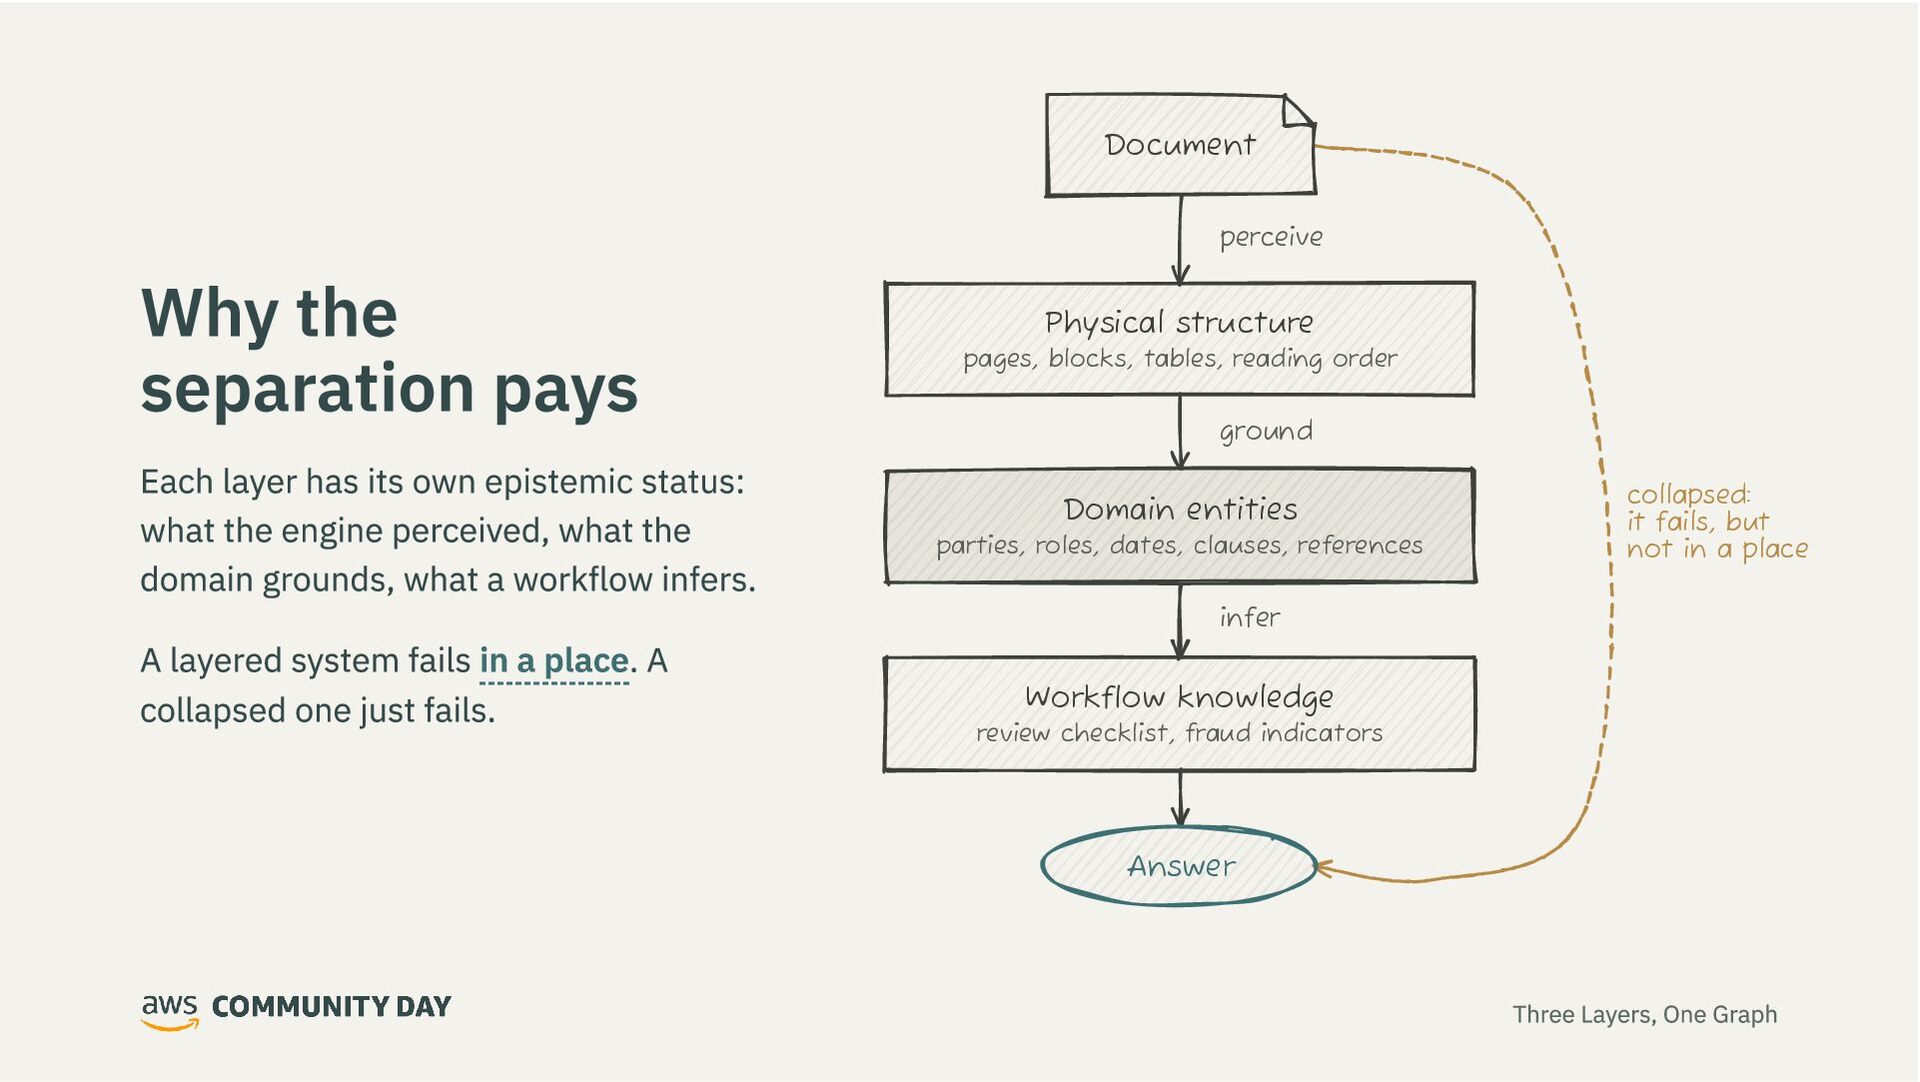
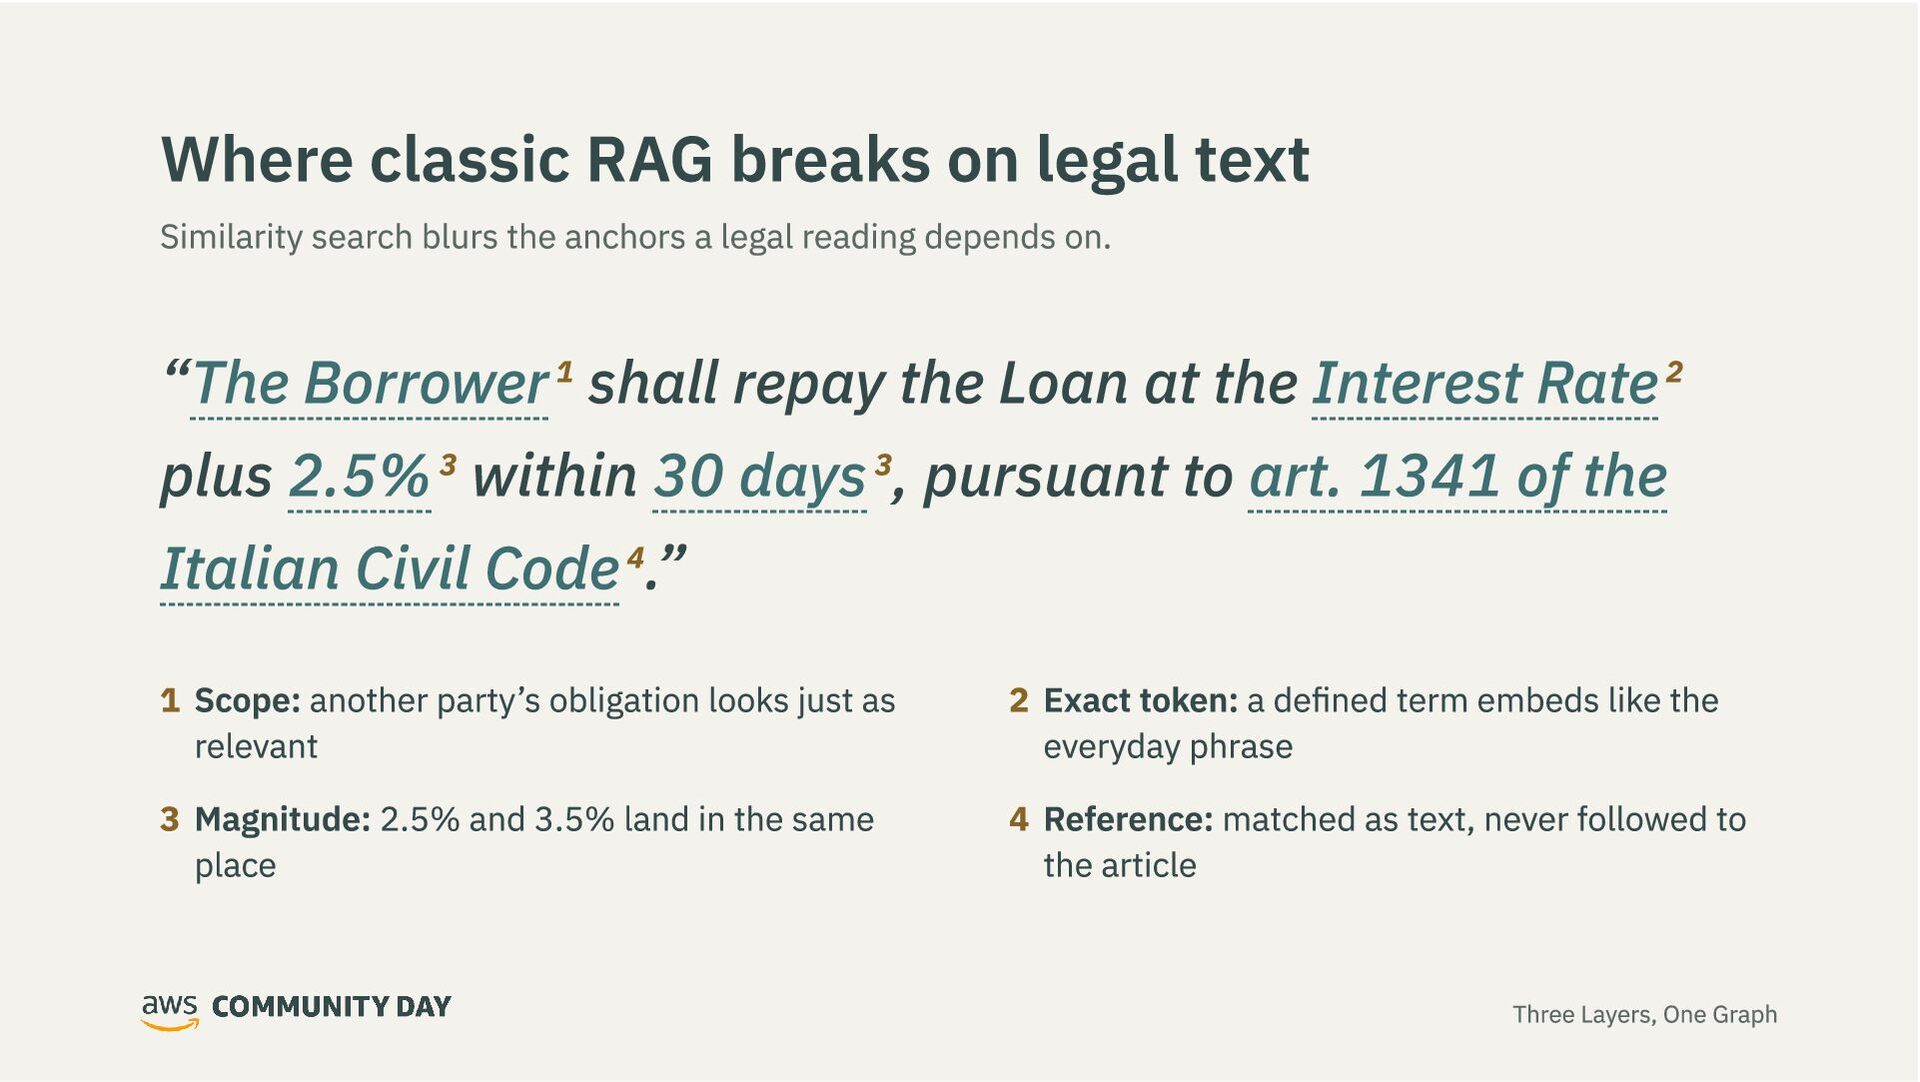
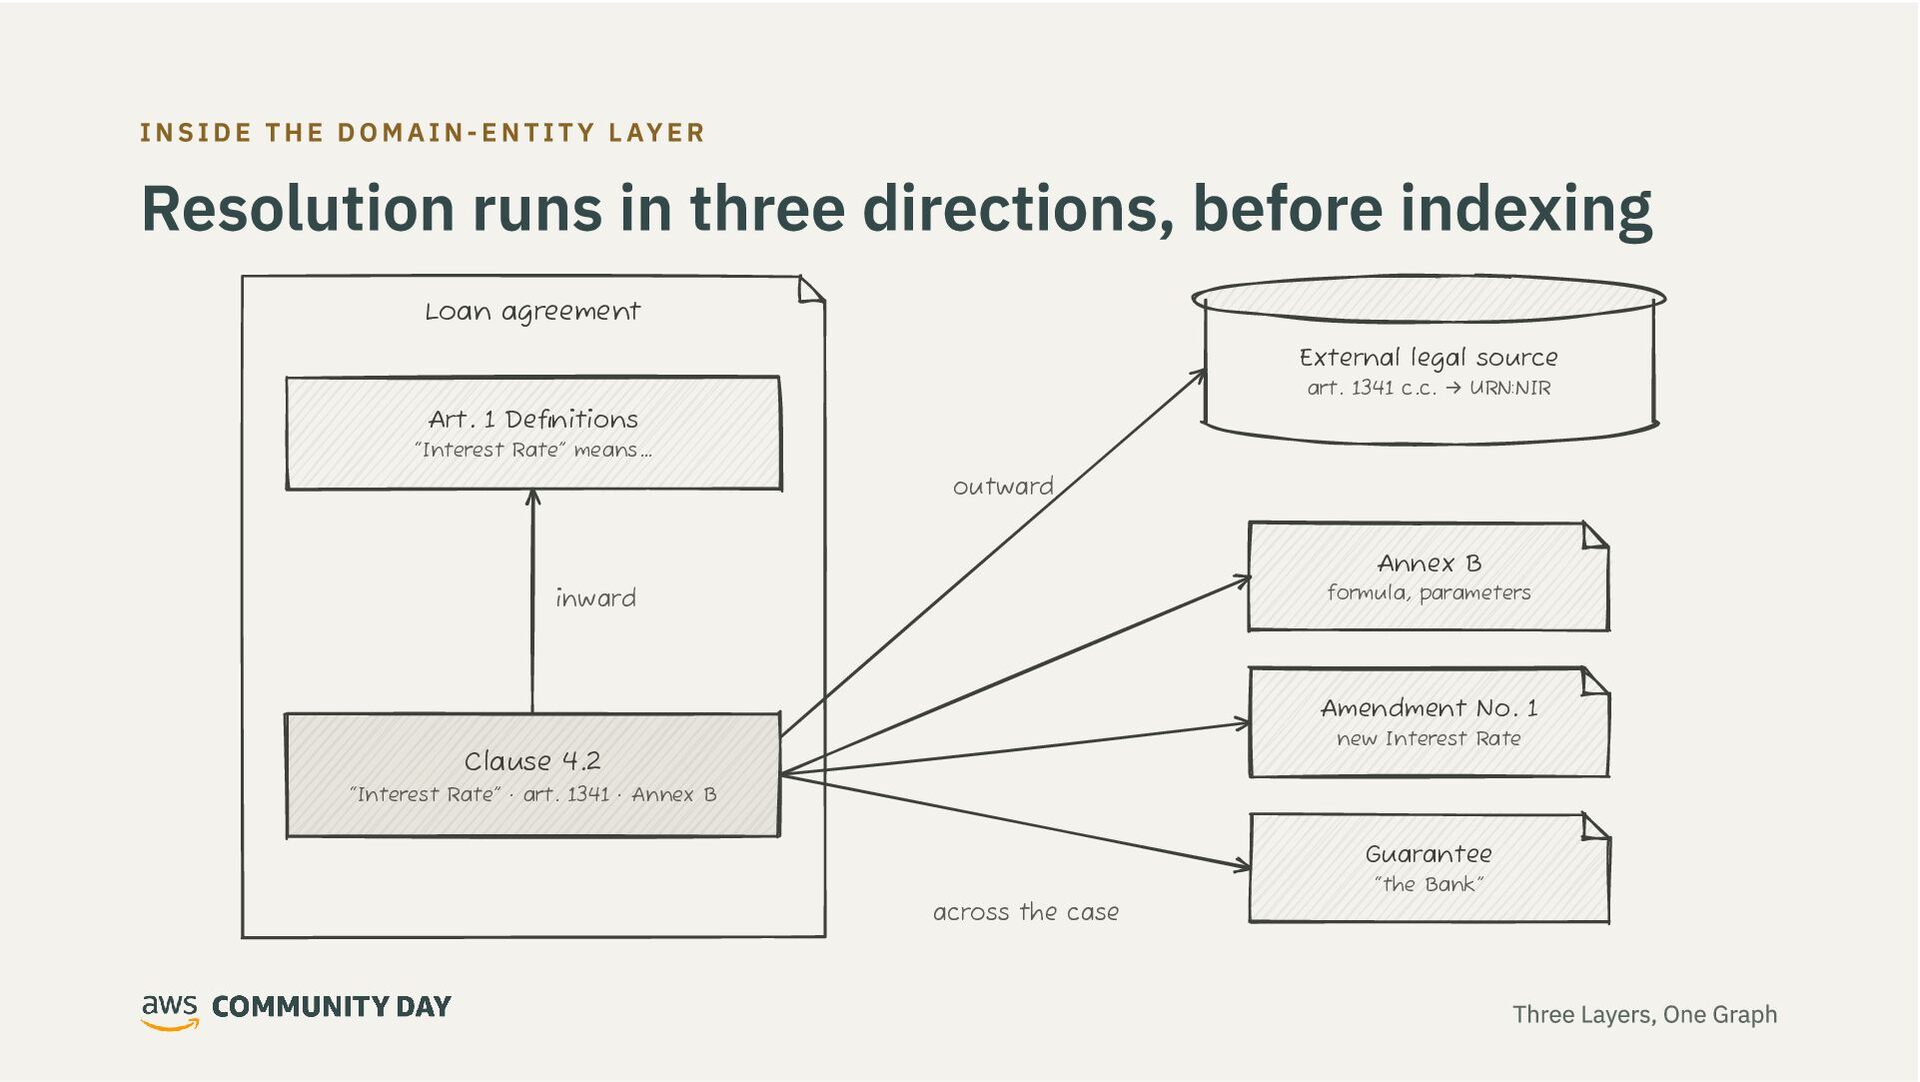
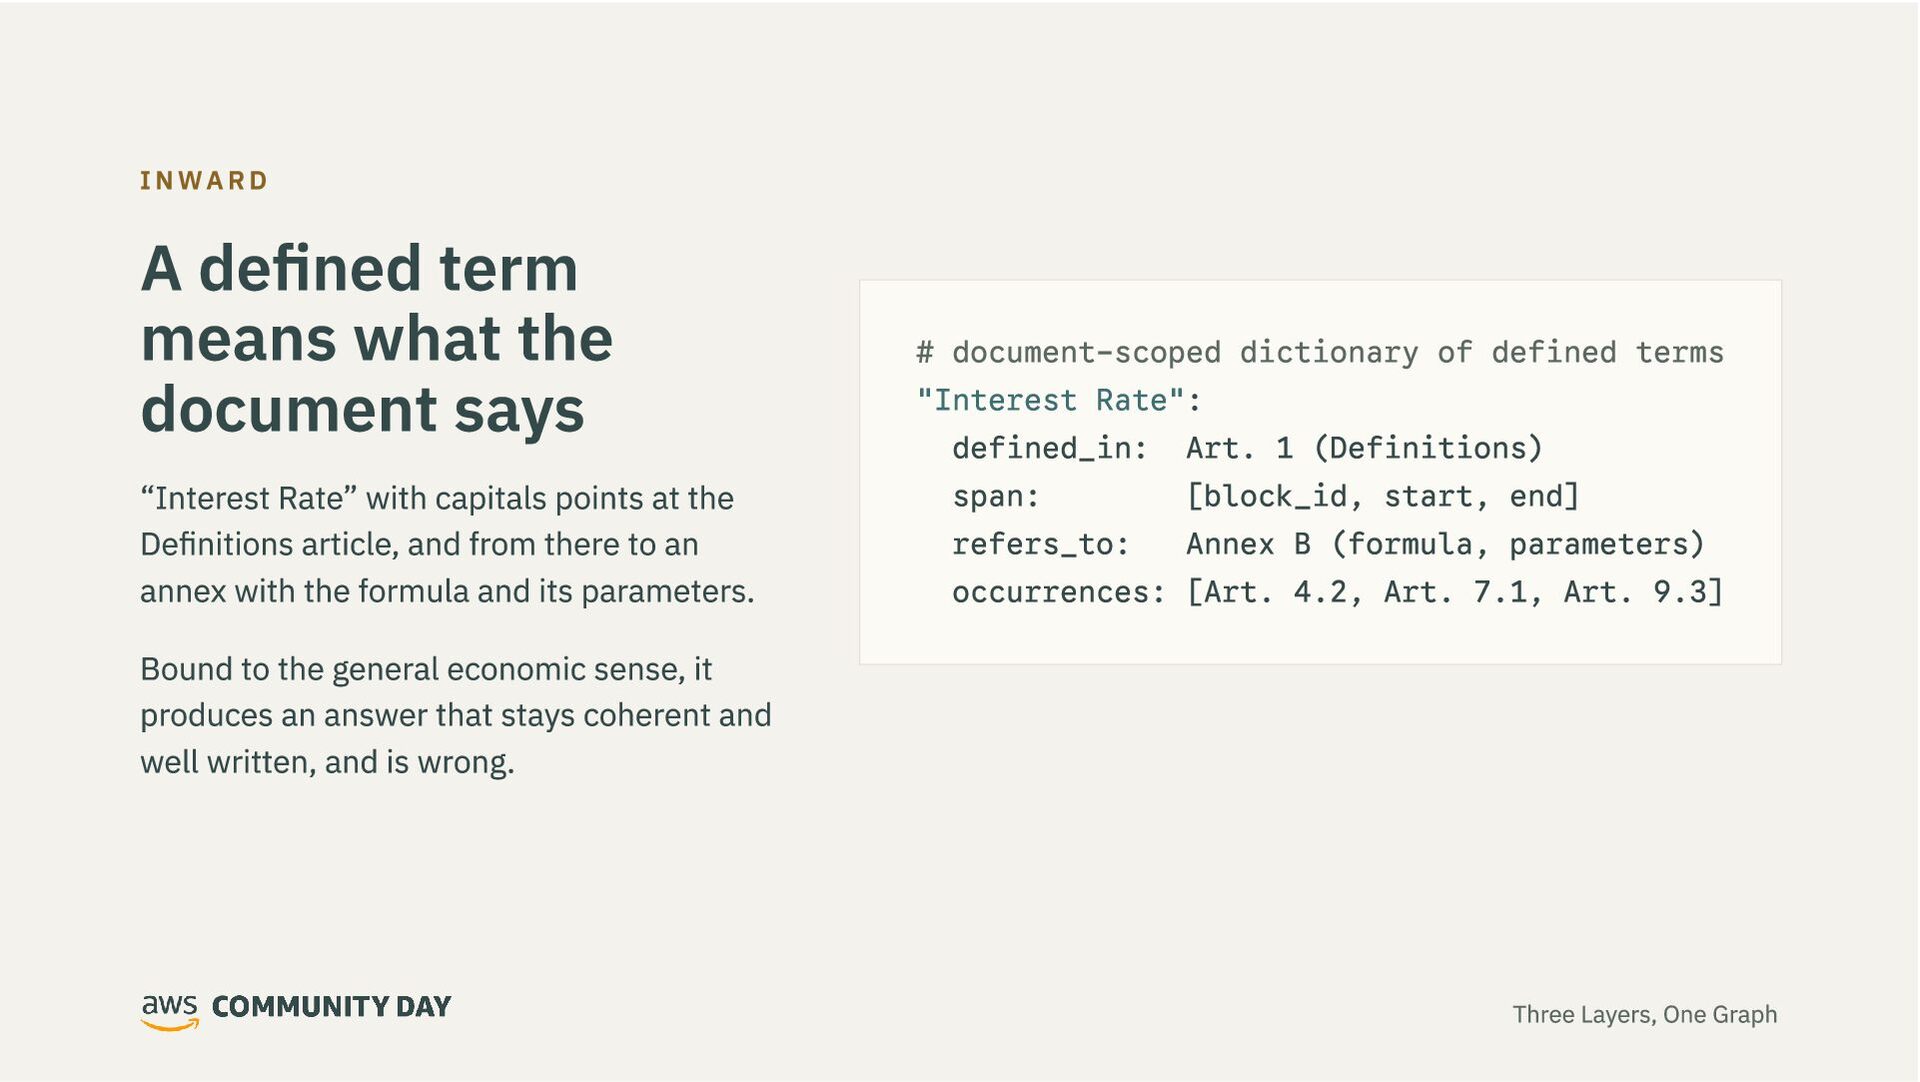
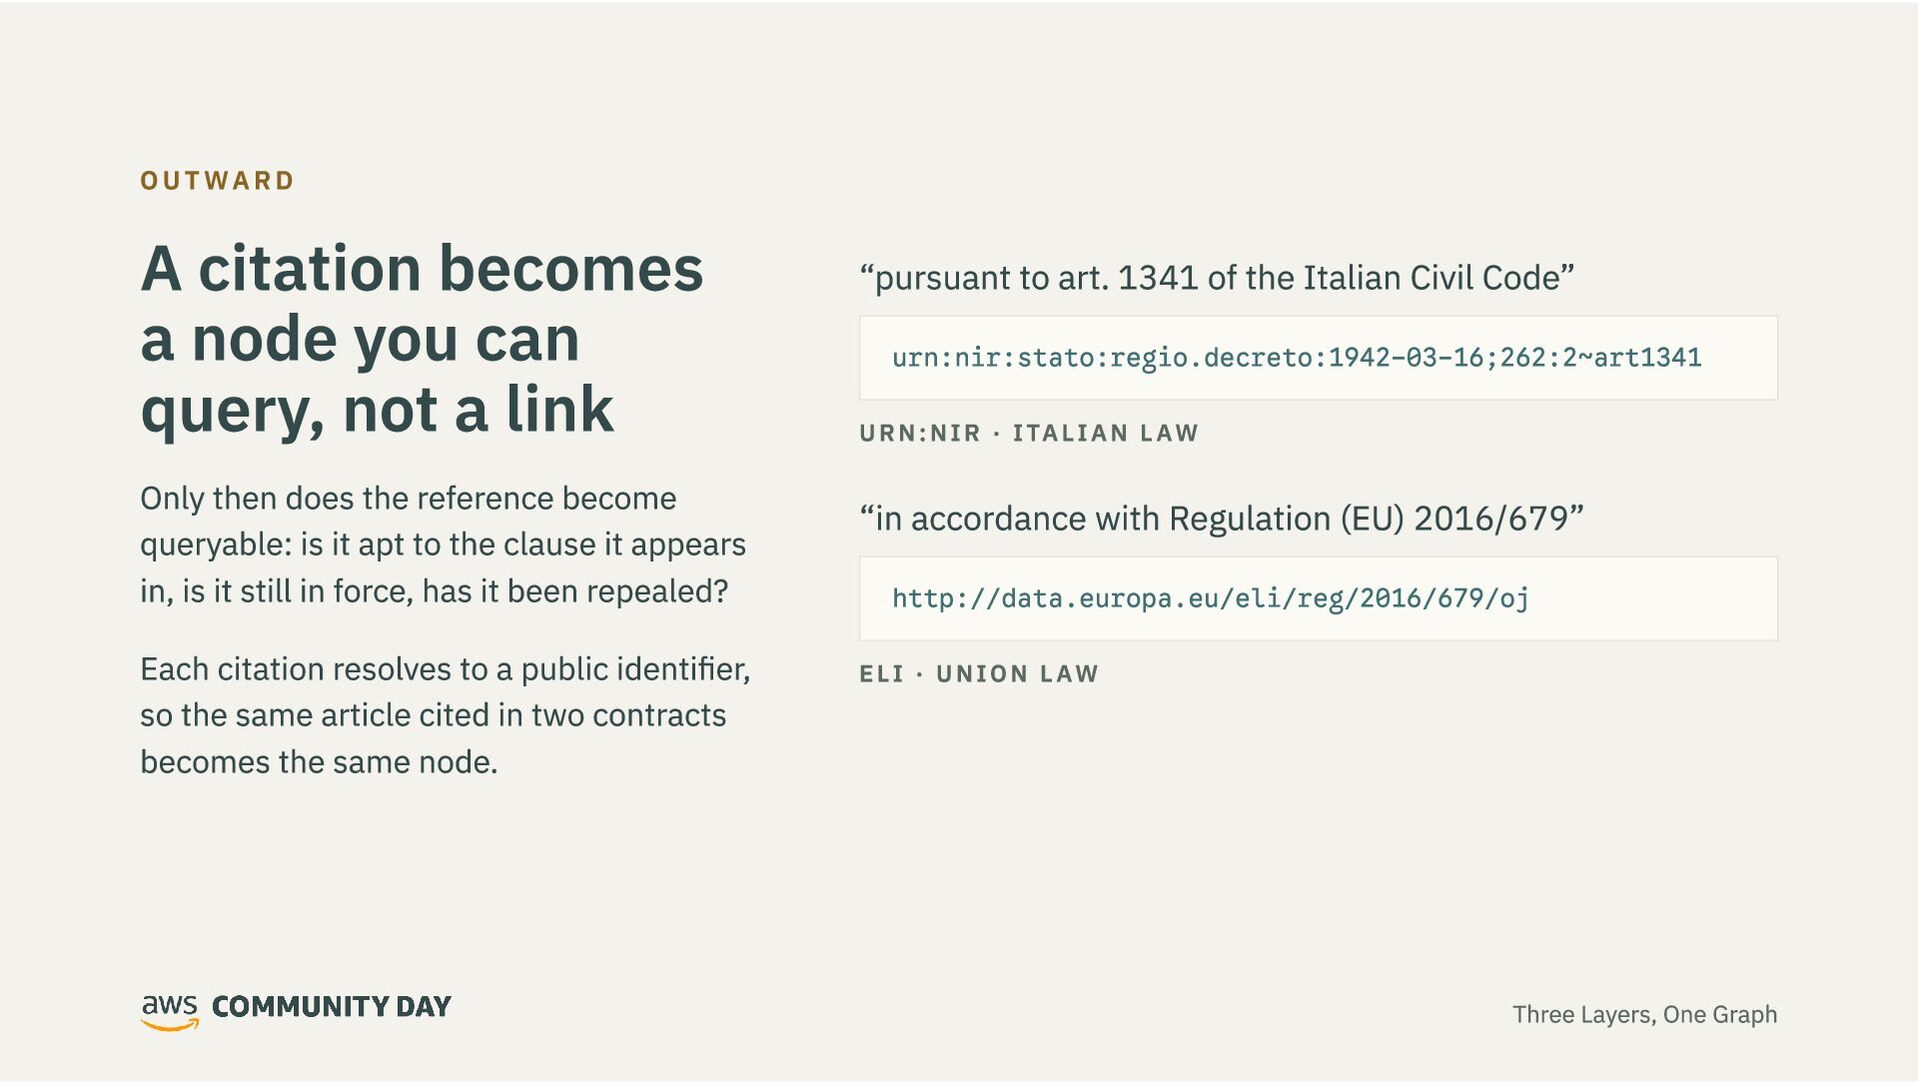
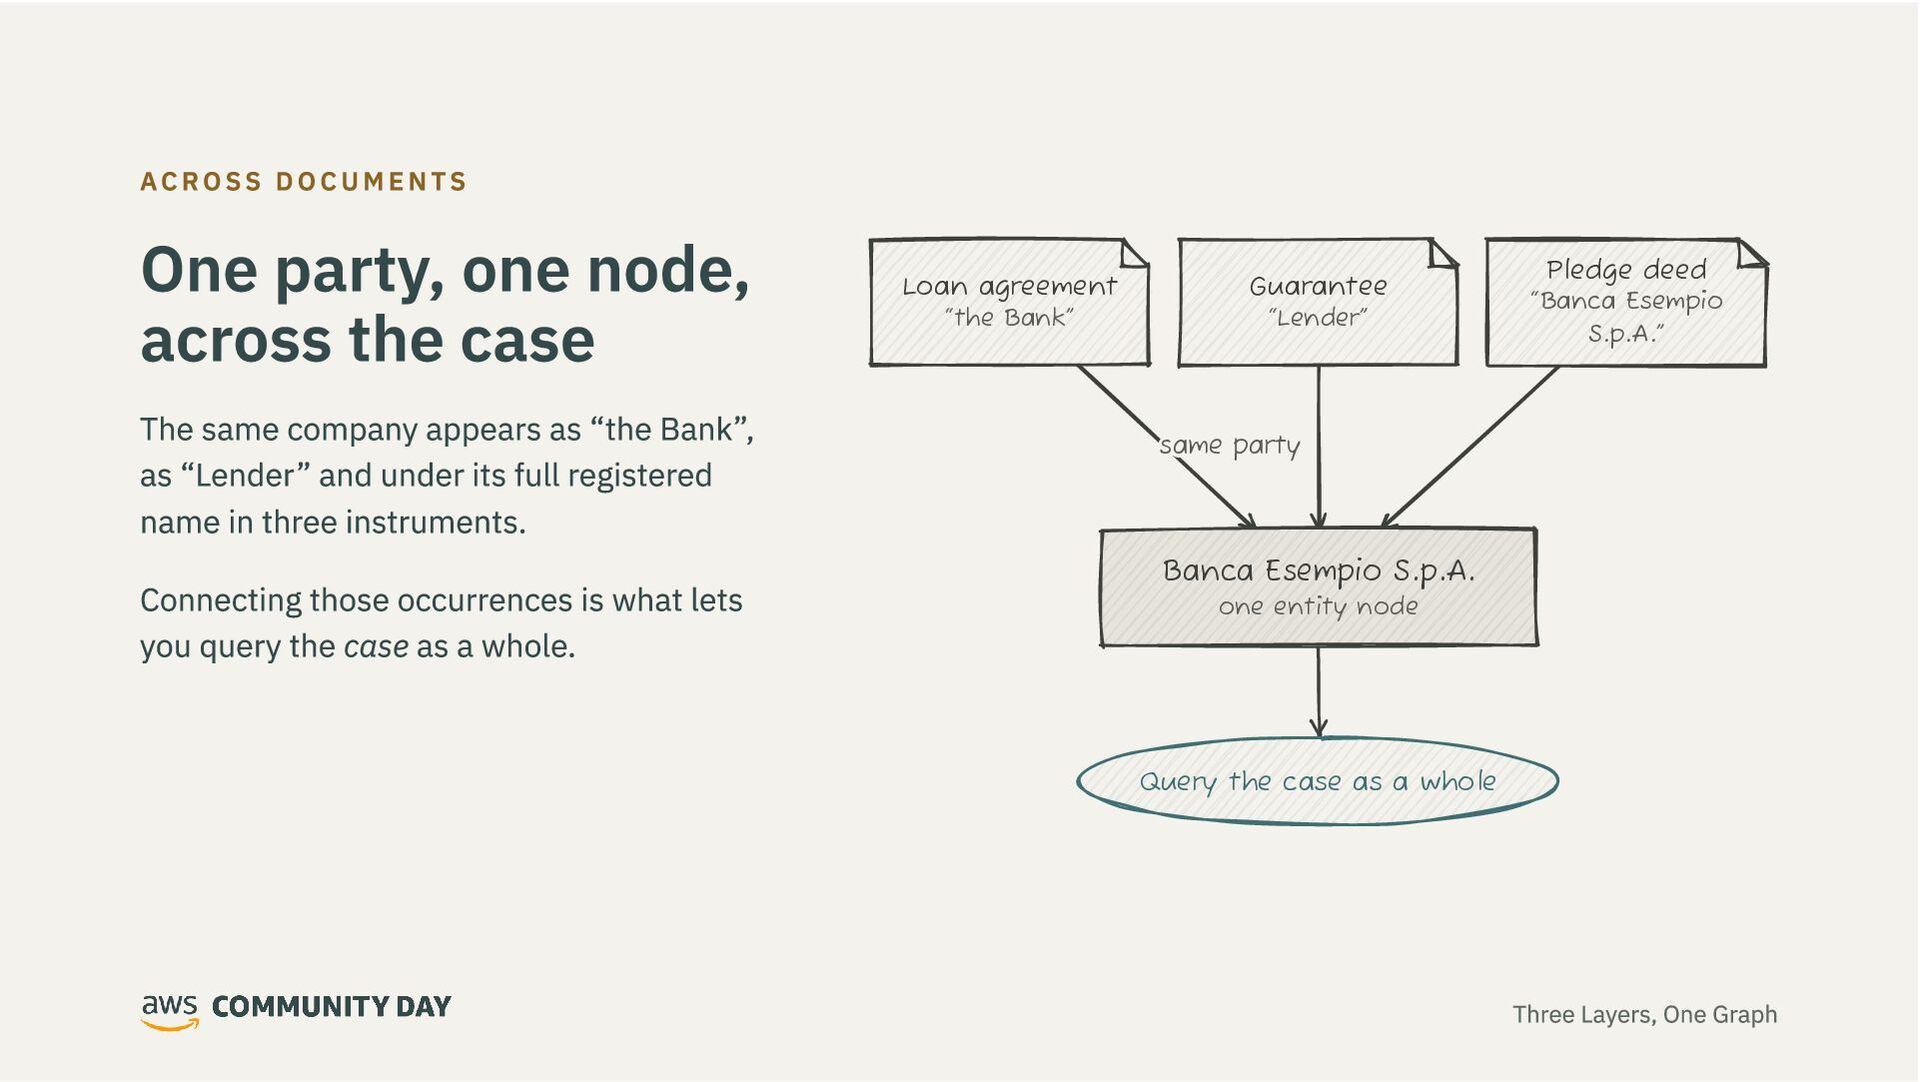
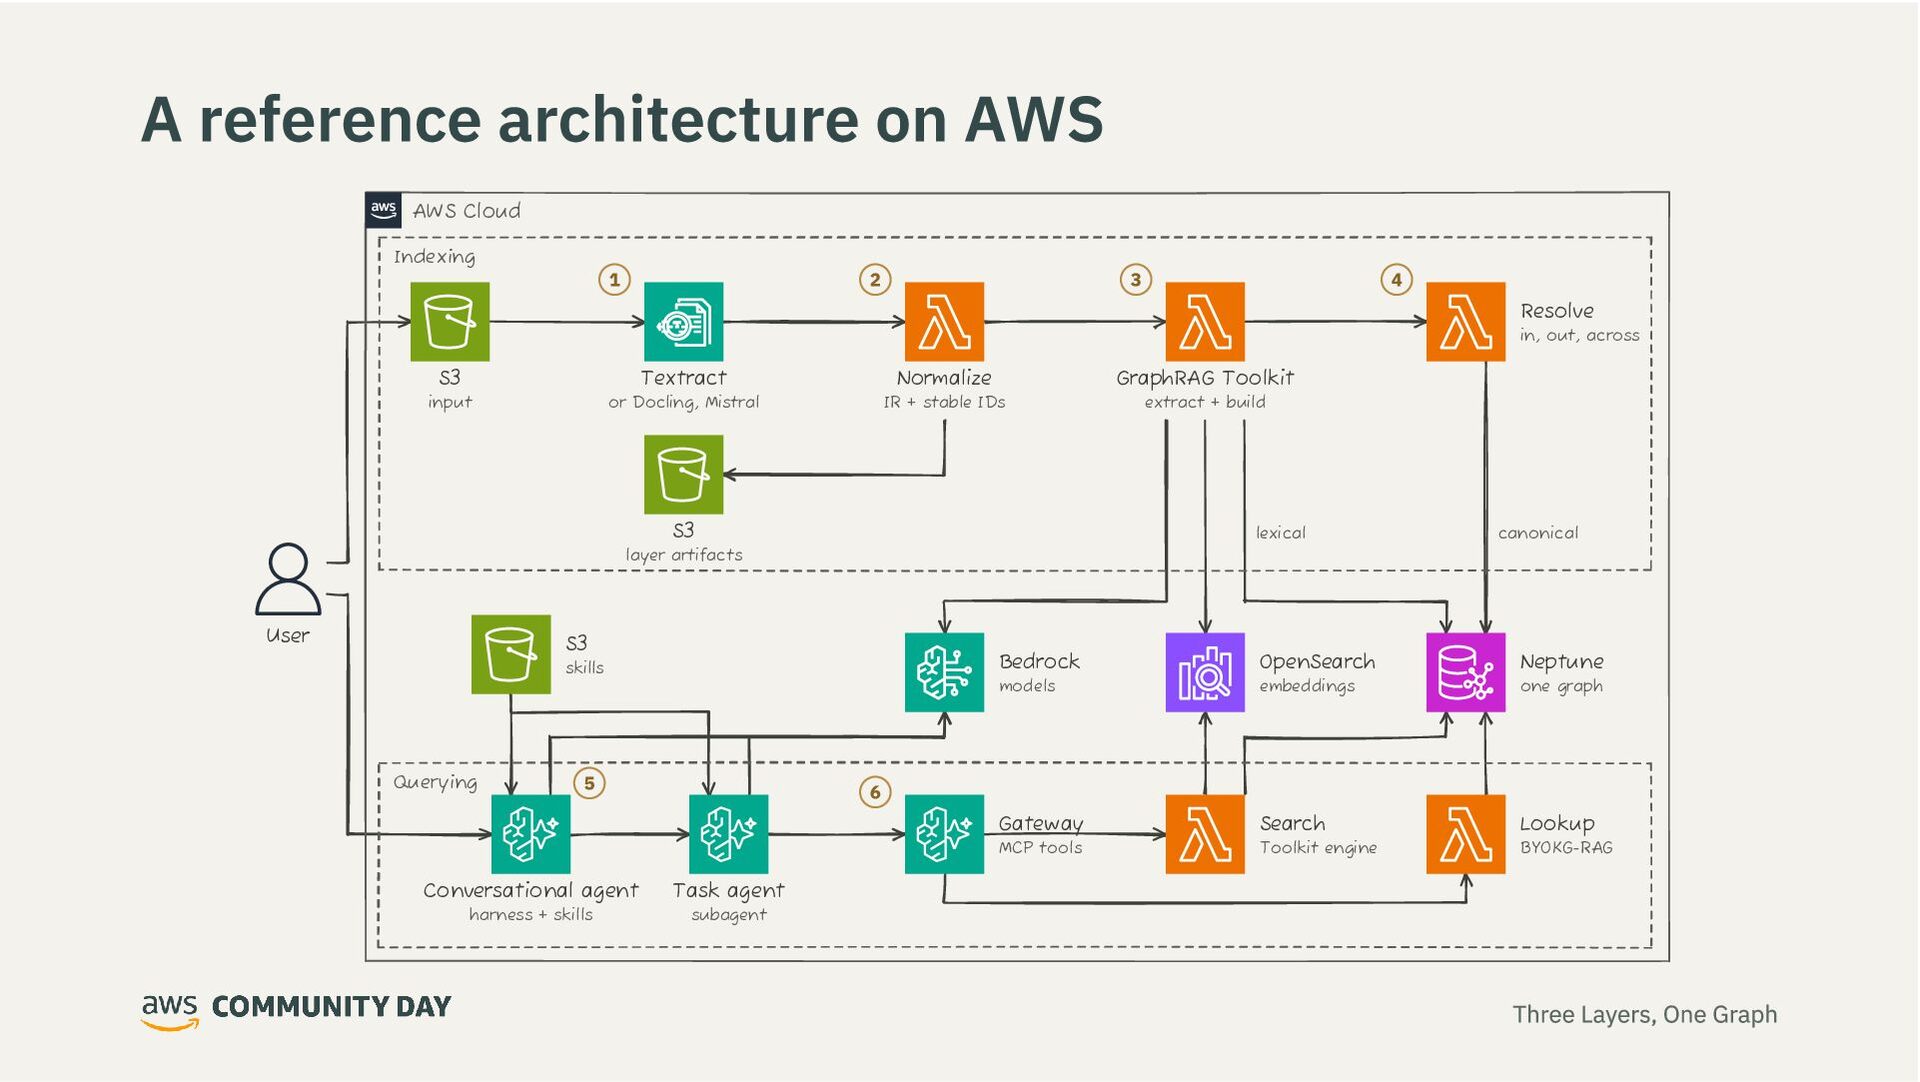
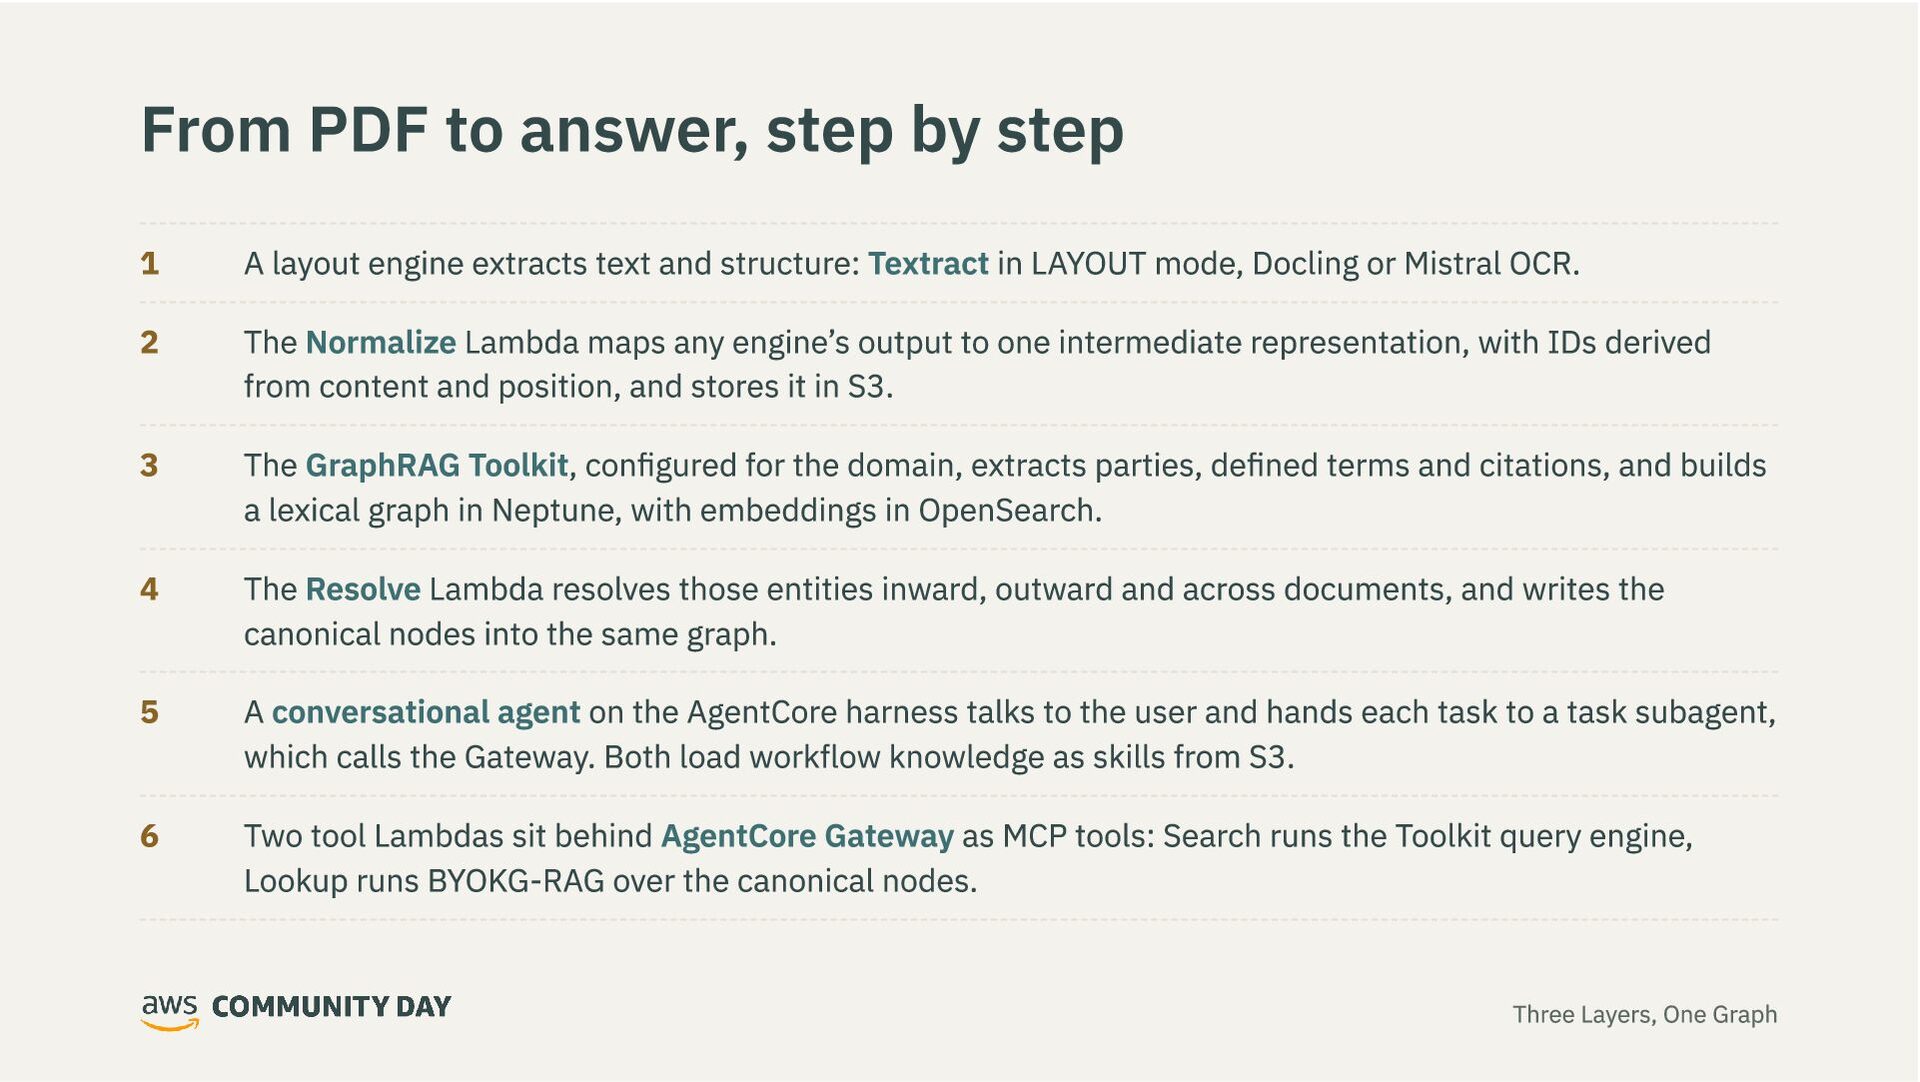
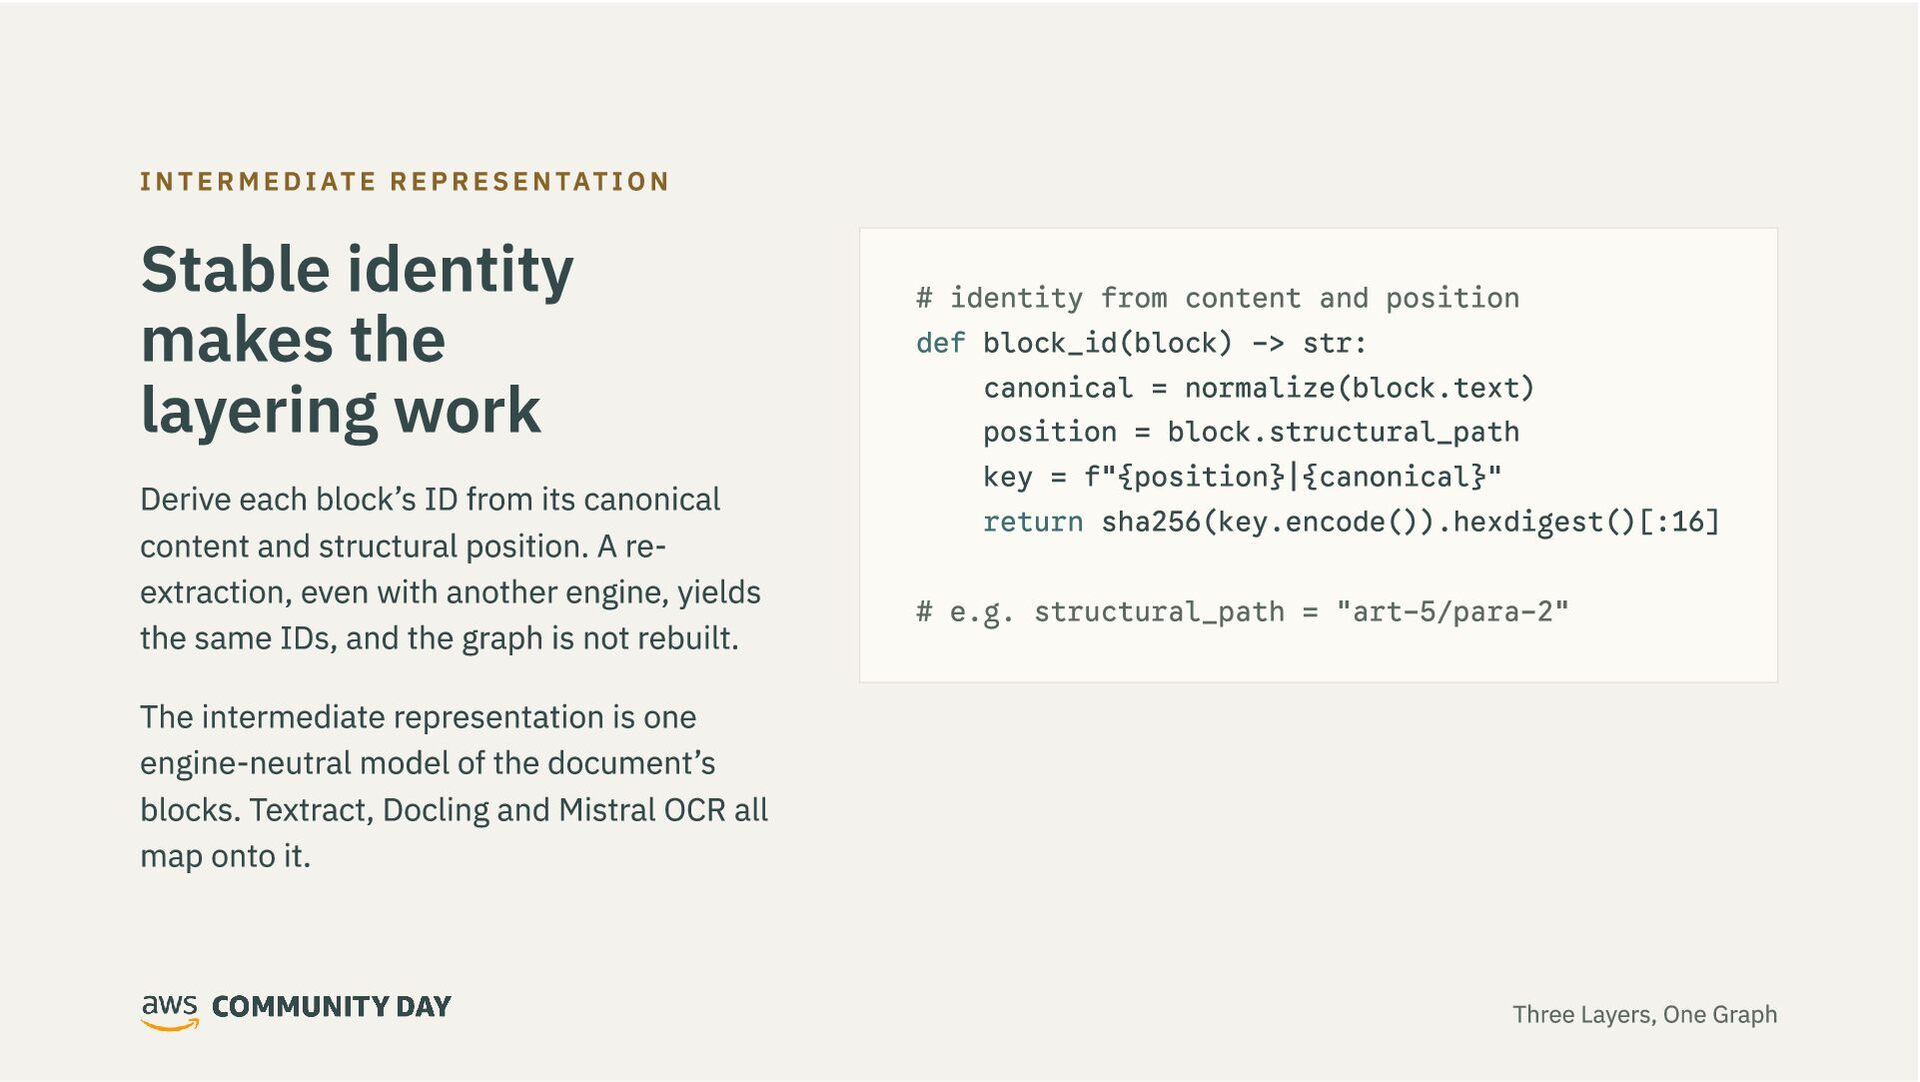
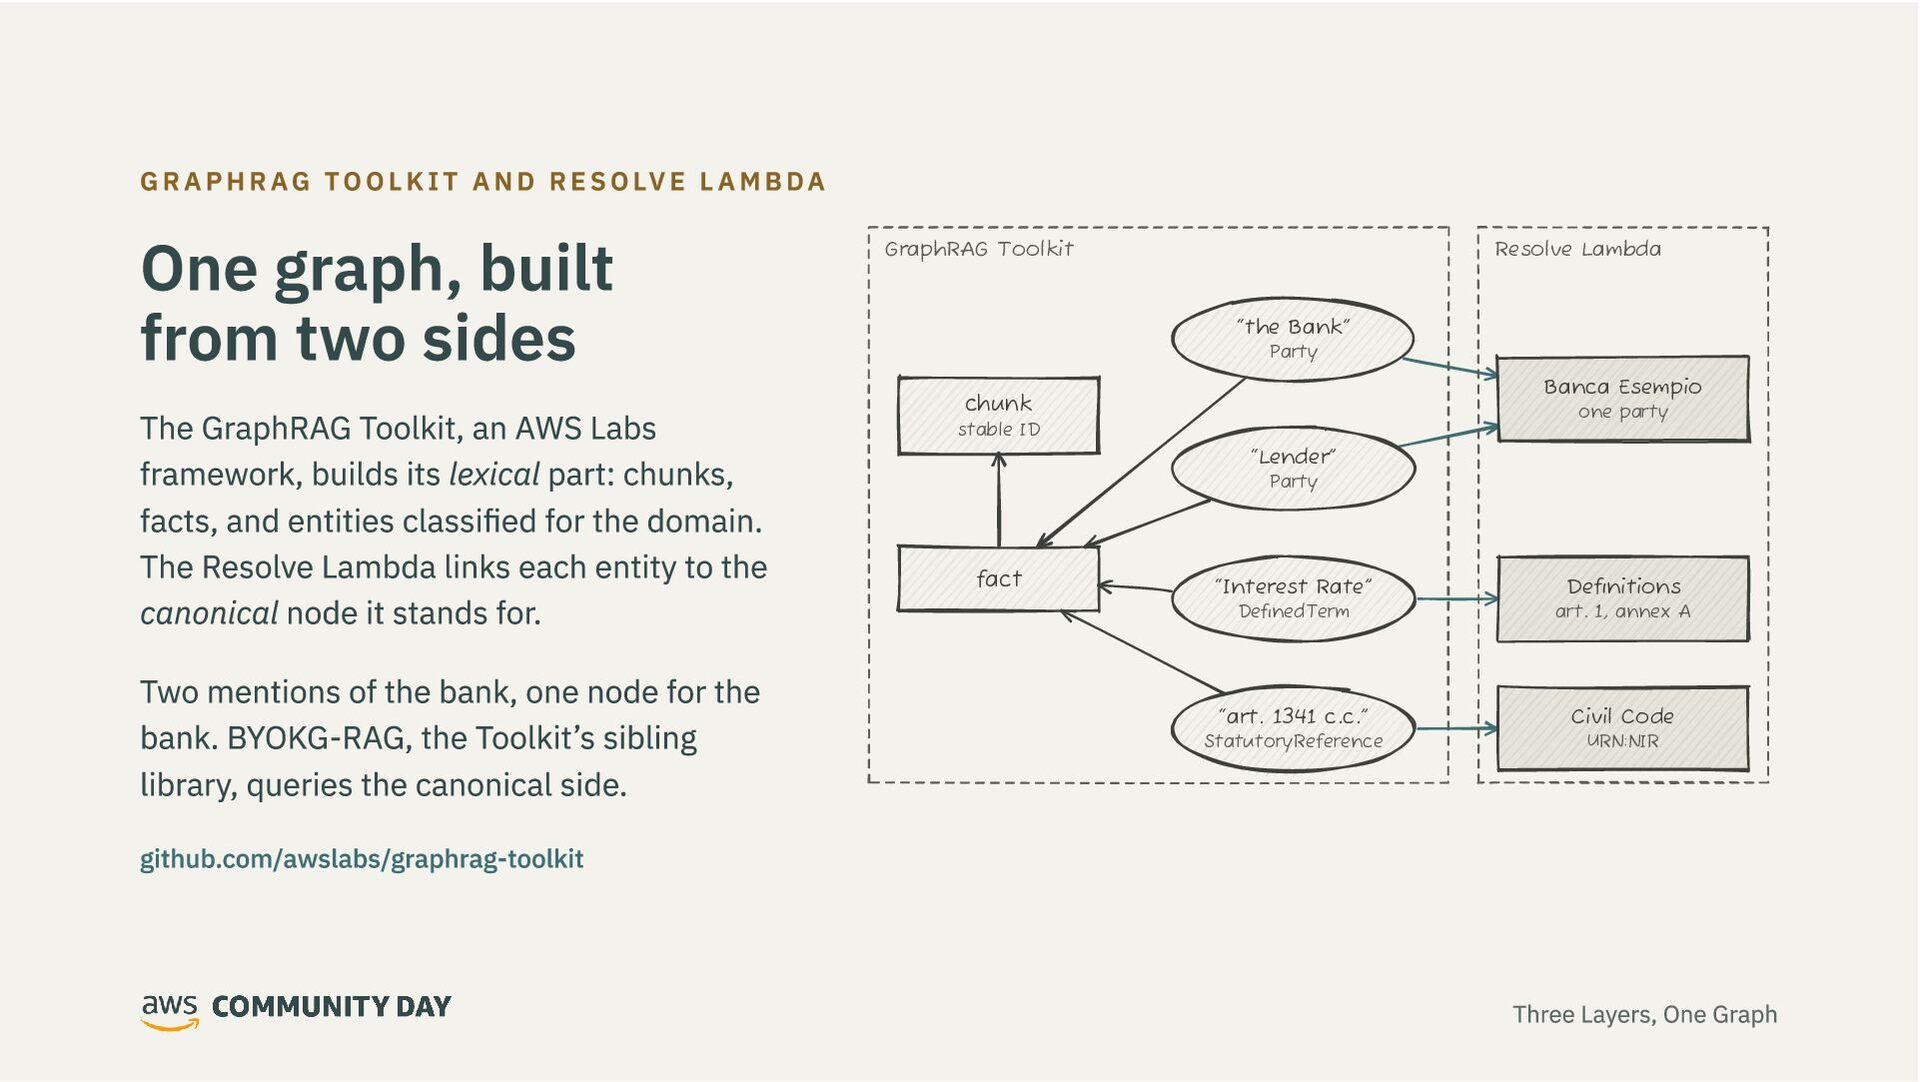
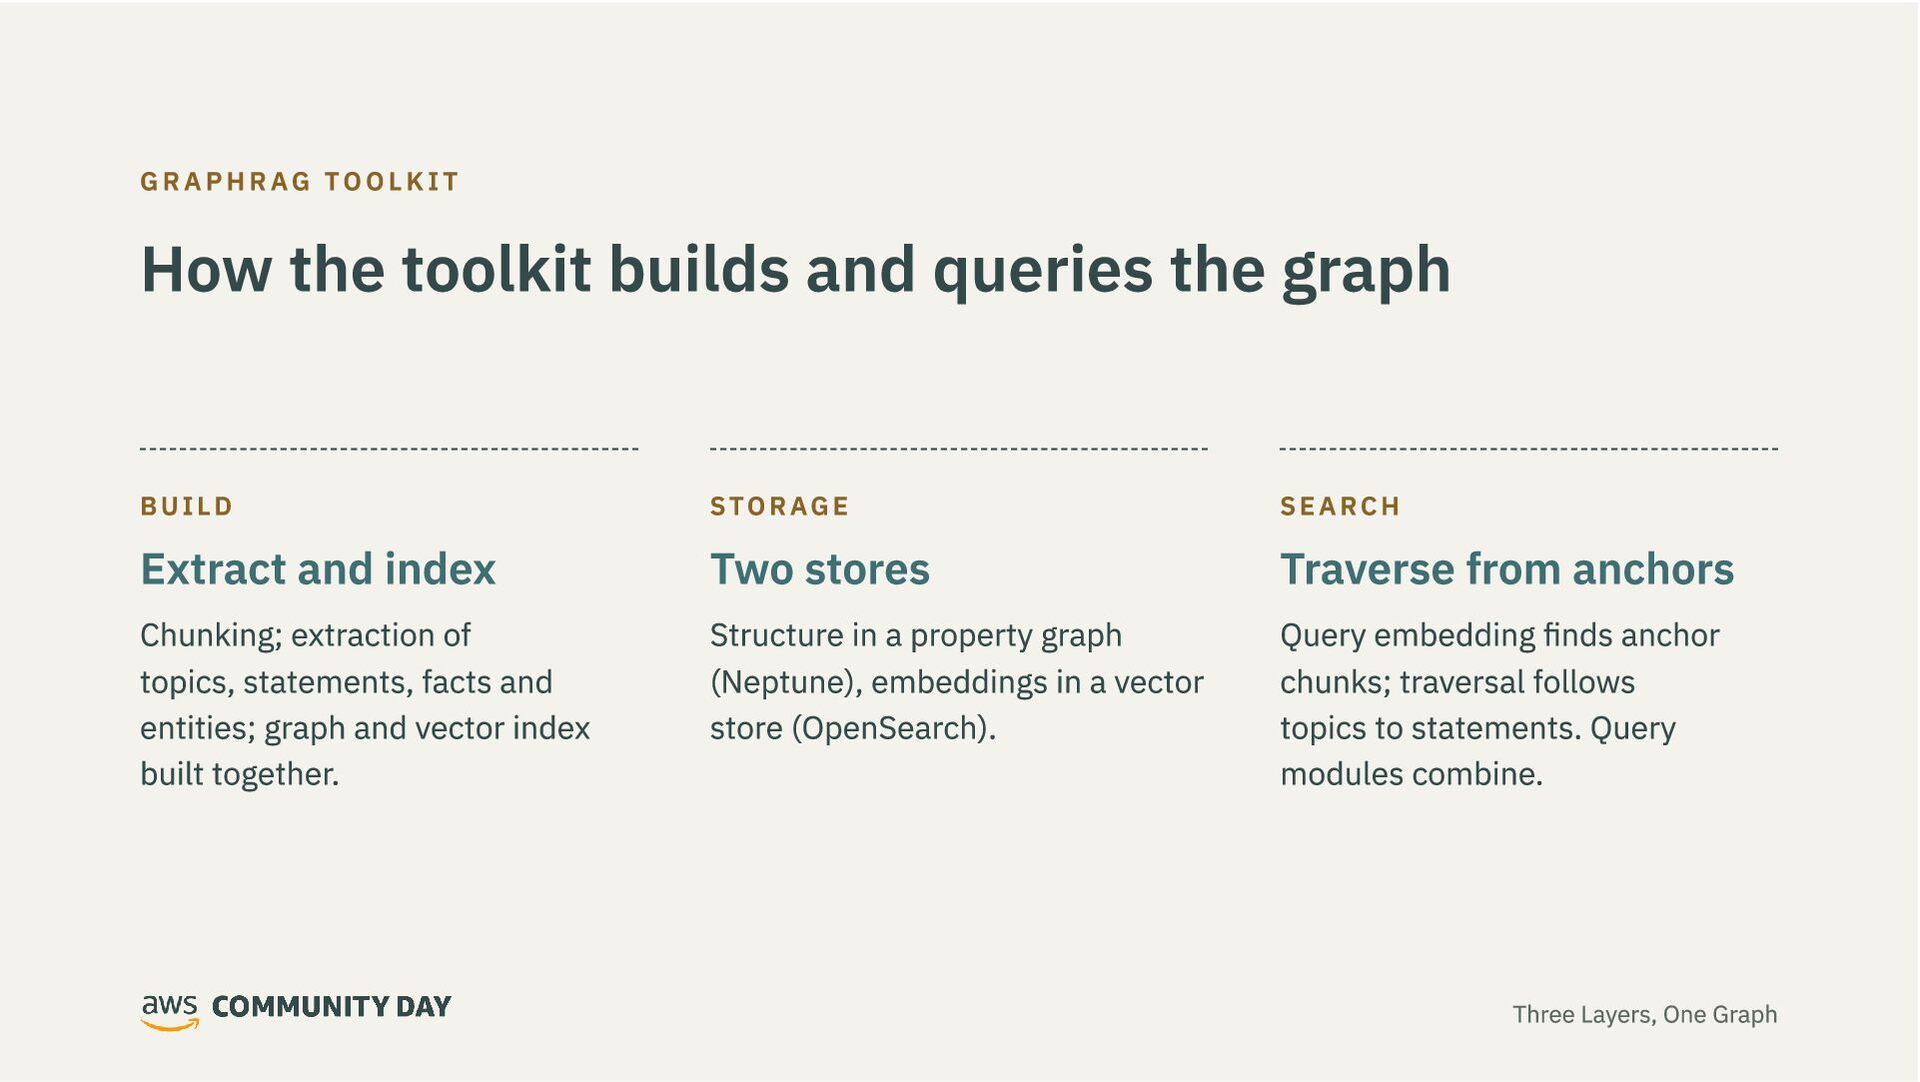
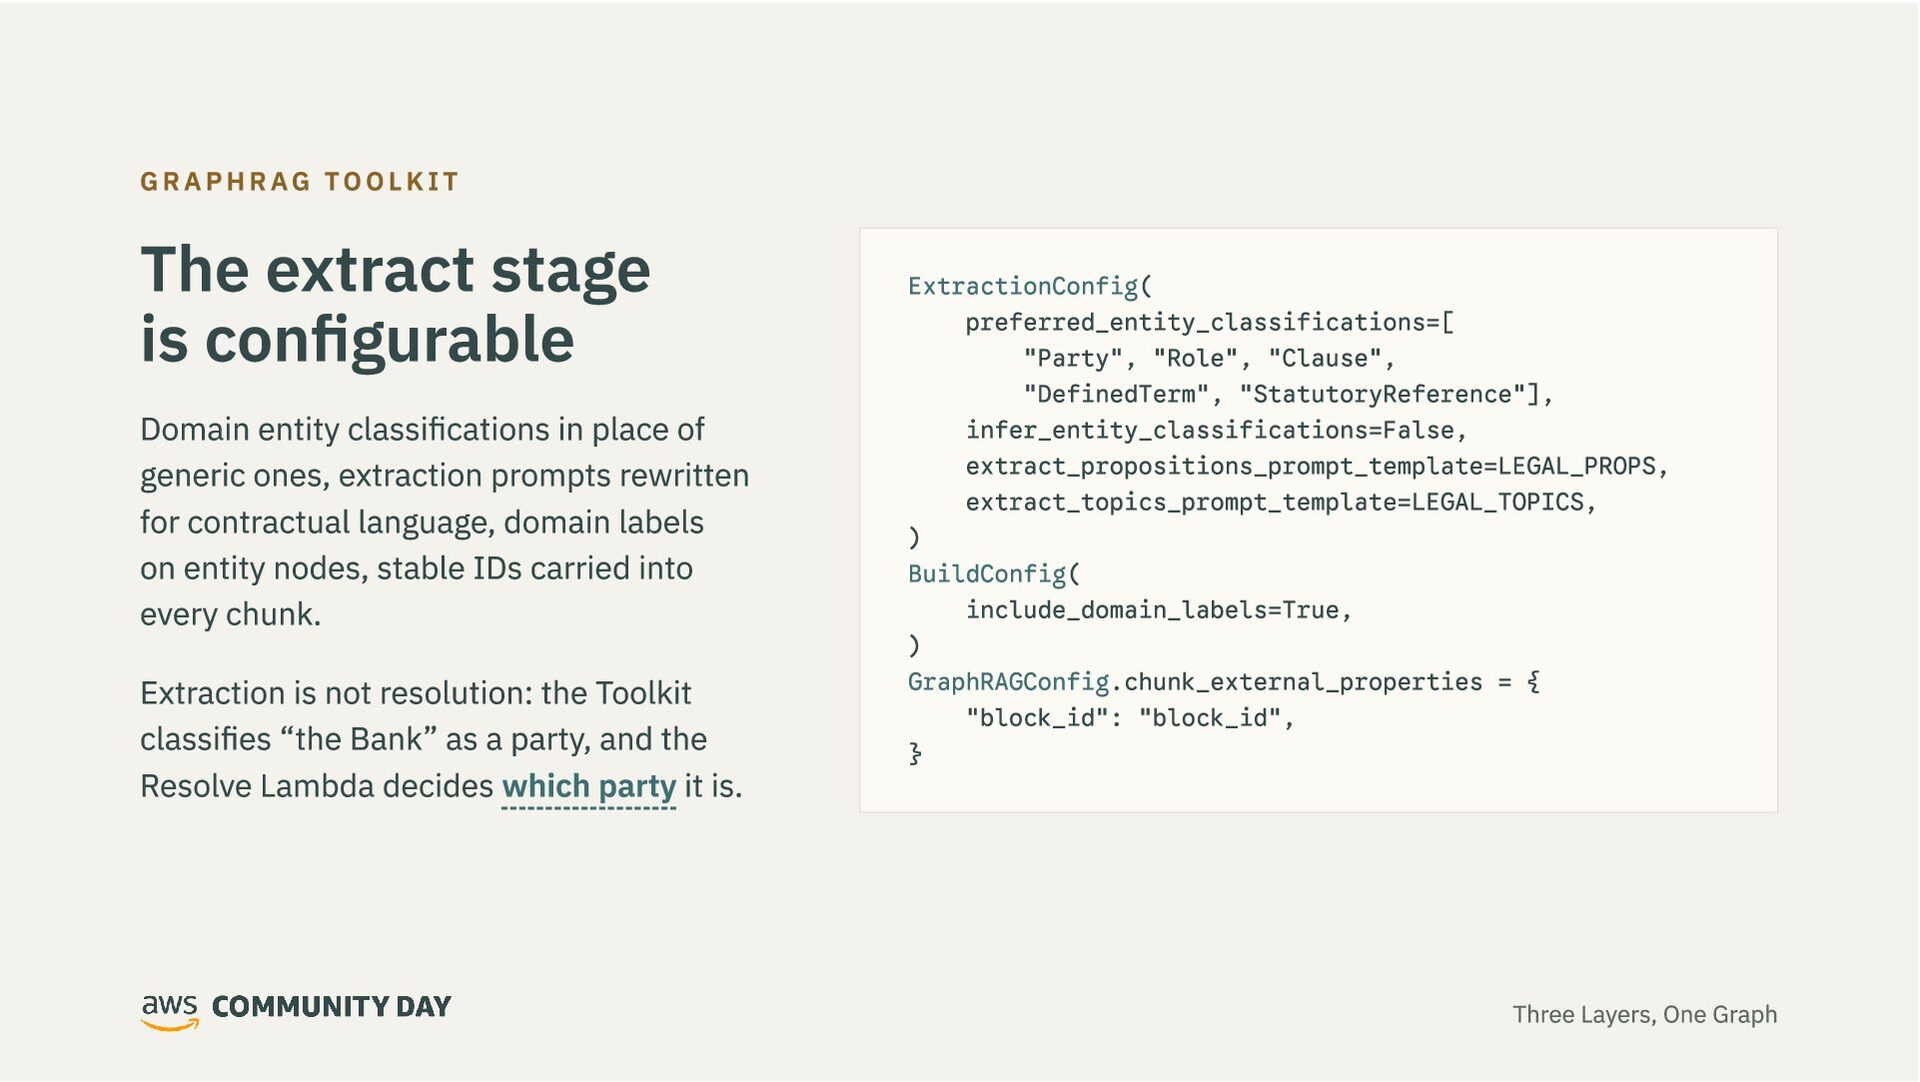
The same contract reads differently depending on what you ask of it, so a document AI system needs more than similarity search. This talk splits what we know about a document into three layers (physical structure, domain entities, workflow knowledge) and builds the graph in the middle one, resolving every defined term, citation and party before anything is indexed. It then shows the reference architecture on AWS: Textract, the GraphRAG Toolkit on Neptune and OpenSearch, and agents on Bedrock AgentCore.


 janostolgyesi
 marcoroth
 kishida
 akihisaikeda
 o0h
 minodriven
 nokomoro3
 optim
 palkan
 lynnswap
 seike460
 uyuki234
 findyinc
 kimpetersen
 varn
 bkeepers
 moore
 afnizarnur
 shpigford
 reverentgeek
 thirion
 marcduiker
 samtorres
 malarkey
 marktimemedia