Share
Embed
Deep Learning with TensorFlow and Keras
An introduction to Deep Learning using TensorFlow and Keras for students at Makerere University
Wesley Kambale
February 29, 2024
Transcript
37 slides
-
• Machine Learning Engineer with 3 years of experience •
Community Builder for 3 years • Explore ML Facilitator with Crowdsource by Google for 2 years • Google Dev Library Author Profile Interests Experience • Research in TinyML, TTS & LLM -
What You Need to Know/Have? - Knowledge of Python, R,
Java, etc - Basic mathematical knowledge (probability and statistics) - Notebook (Google Colab or Jupyter) - Basic data analytics knowledge (MS Excel, Power BI) Pre-requisites -
The libraries you need What next? Pandas* NumPy* Matplotlib &
Seaborn Keras & TensorFlow -
Deep Learning… What is Deep Learning? By learning from large
amounts of labeled data, these networks can identify patterns, classify objects, and make predictions. Deep learning has transformed countless industries such as computer vision, natural language processing, and speech recognition, surpassing the performance of traditional machine learning algorithms in many formerly difficult tasks. -
Image Generation… Generating Images from Natural Language <- “An image
of Wolverine..” “An image of a young man fishing on the shores of Lake Victoria” -> -
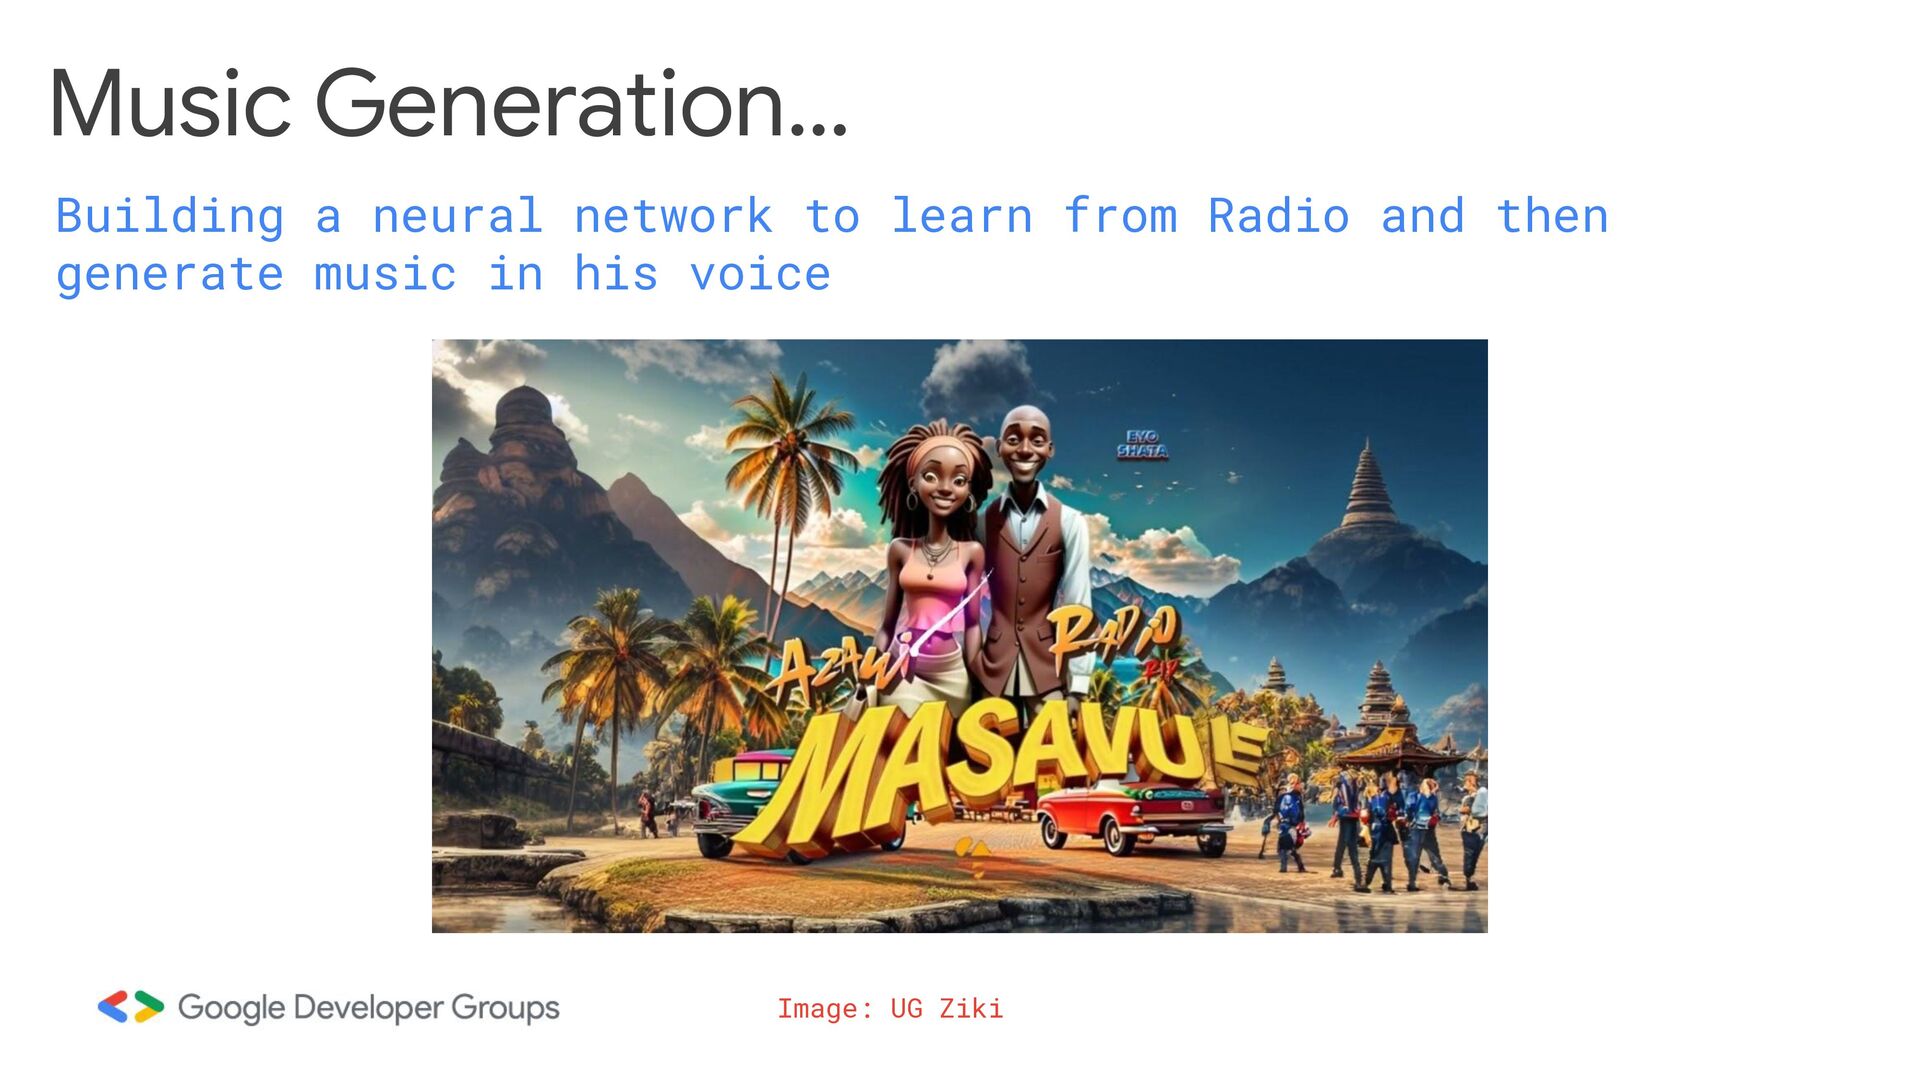
Music Generation… Building a neural network to learn from Radio
and then generate music in his voice Image: UG Ziki -
TensorFlow Image: ResearchGate What is TensorFlow in Deep Learning? TensorFlow
is an open-source deep learning framework developed by the Google Brain team. It offers a vast array of tools, libraries, and resources to create and implement machine learning and deep learning models. -
TensorFlow Core Core API Components Data structures: tf.Tensor, tf.Variable, tf.TensorArray
Primitive APIs: tf.shape, slicing, tf.concat, tf.bitwise Numerical: tf.math, tf.linalg, tf.random Functional components: tf.function, tf.GradientTape Distribution: DTensor Export: tf.saved_model -
Keras Image: Towards Data Science What is Keras in Deep
Learning? Keras is the high-level API for TensorFlow (Keras 3 supports JAX and PyTorch). It provides an approachable, highly-productive interface for solving machine learning (ML) problems, with a focus on modern deep learning. Keras covers every step of the machine learning workflow, from data processing to hyperparameter tuning to deployment. Every TensorFlow user should use the Keras APIs by default. Whether you're an engineer, a researcher, or an ML practitioner, you should start with Keras. -
Keras Image: Towards Data Science Keras API Components Layers: tf.keras.layers.Layer
Models: tf.keras.Model Image: Data Driven Investor -
Keras Keras Model The tf.keras.Model class features built-in training and
evaluation methods: tf.keras.Model.fit: Trains the model for a fixed number of epochs. tf.keras.Model.predict: Generates output predictions for the input samples. tf.keras.Model.evaluate: Returns the loss and metrics values for the model; configured via the tf.keras.Model.compile method. -
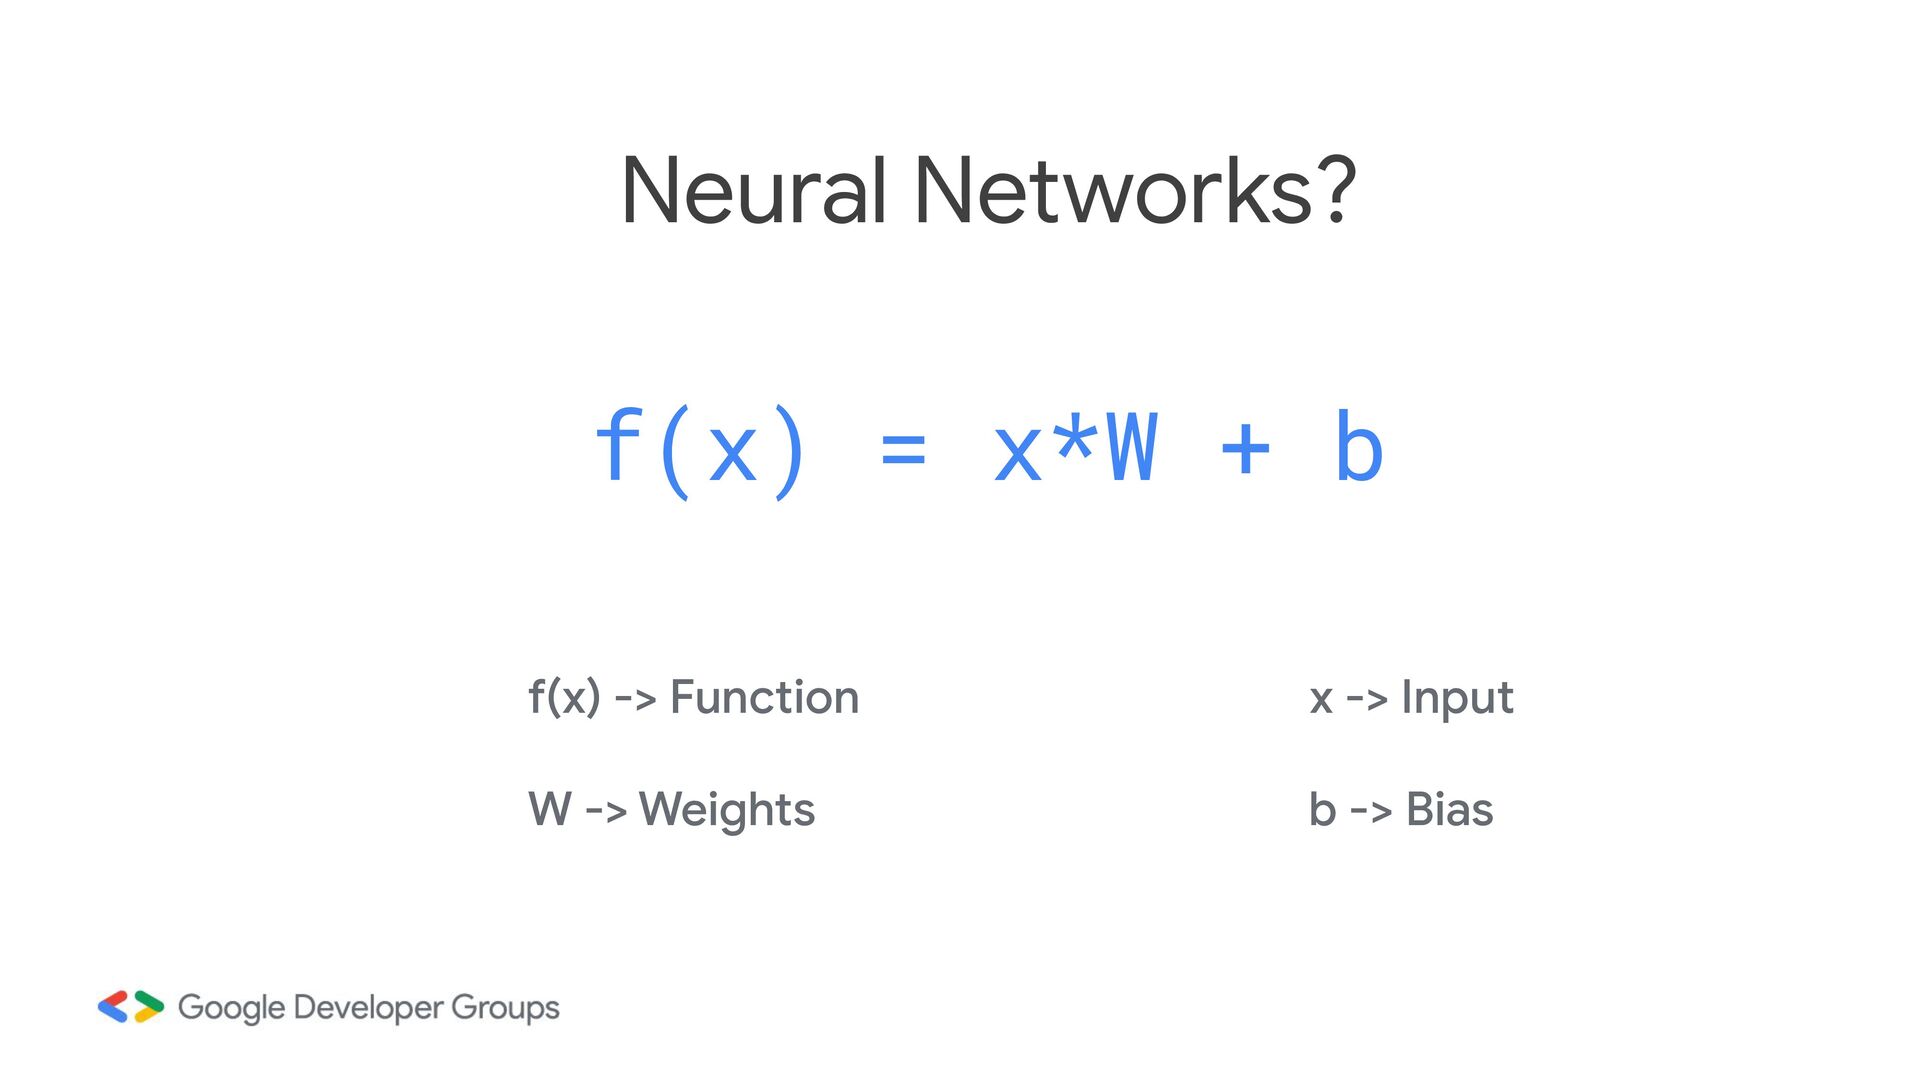
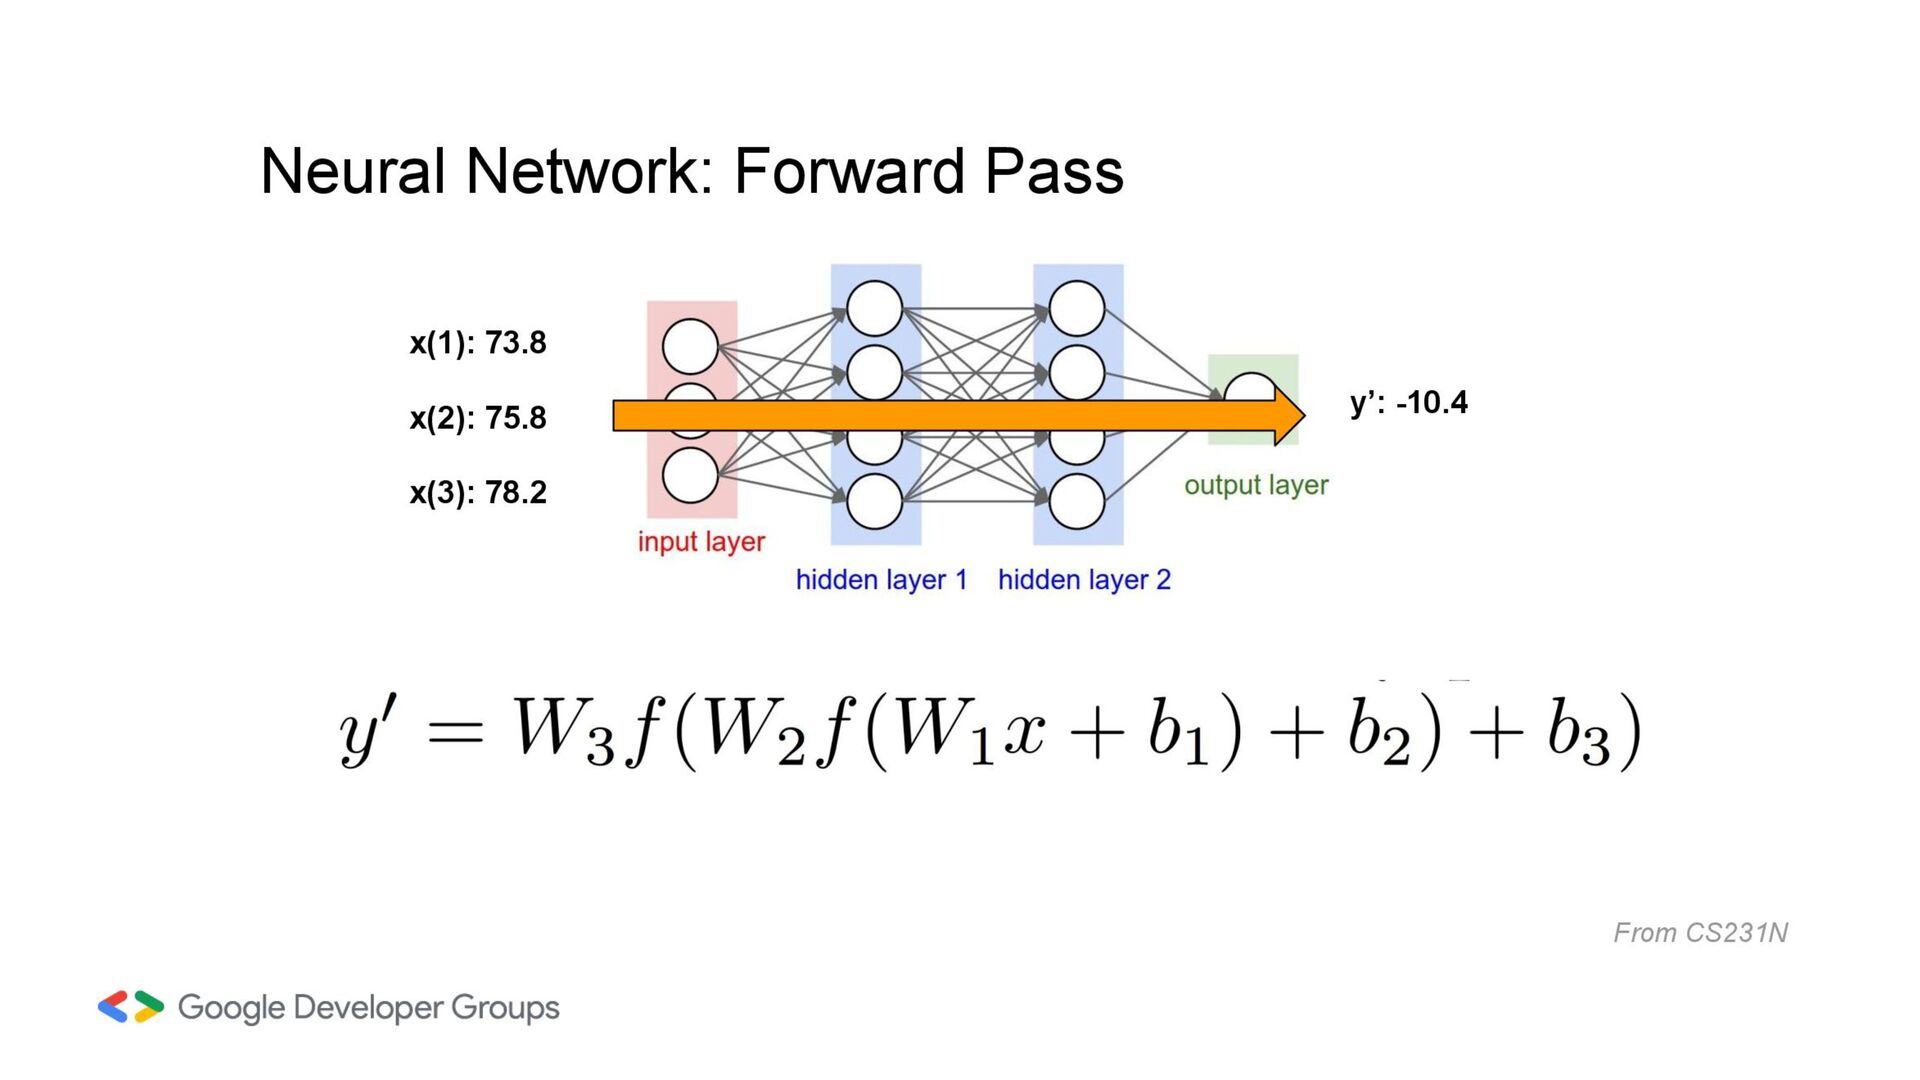
Neural Networks? f(x) = x*W + b f(x) -> Function
x -> Input W -> Weights b -> Bias -
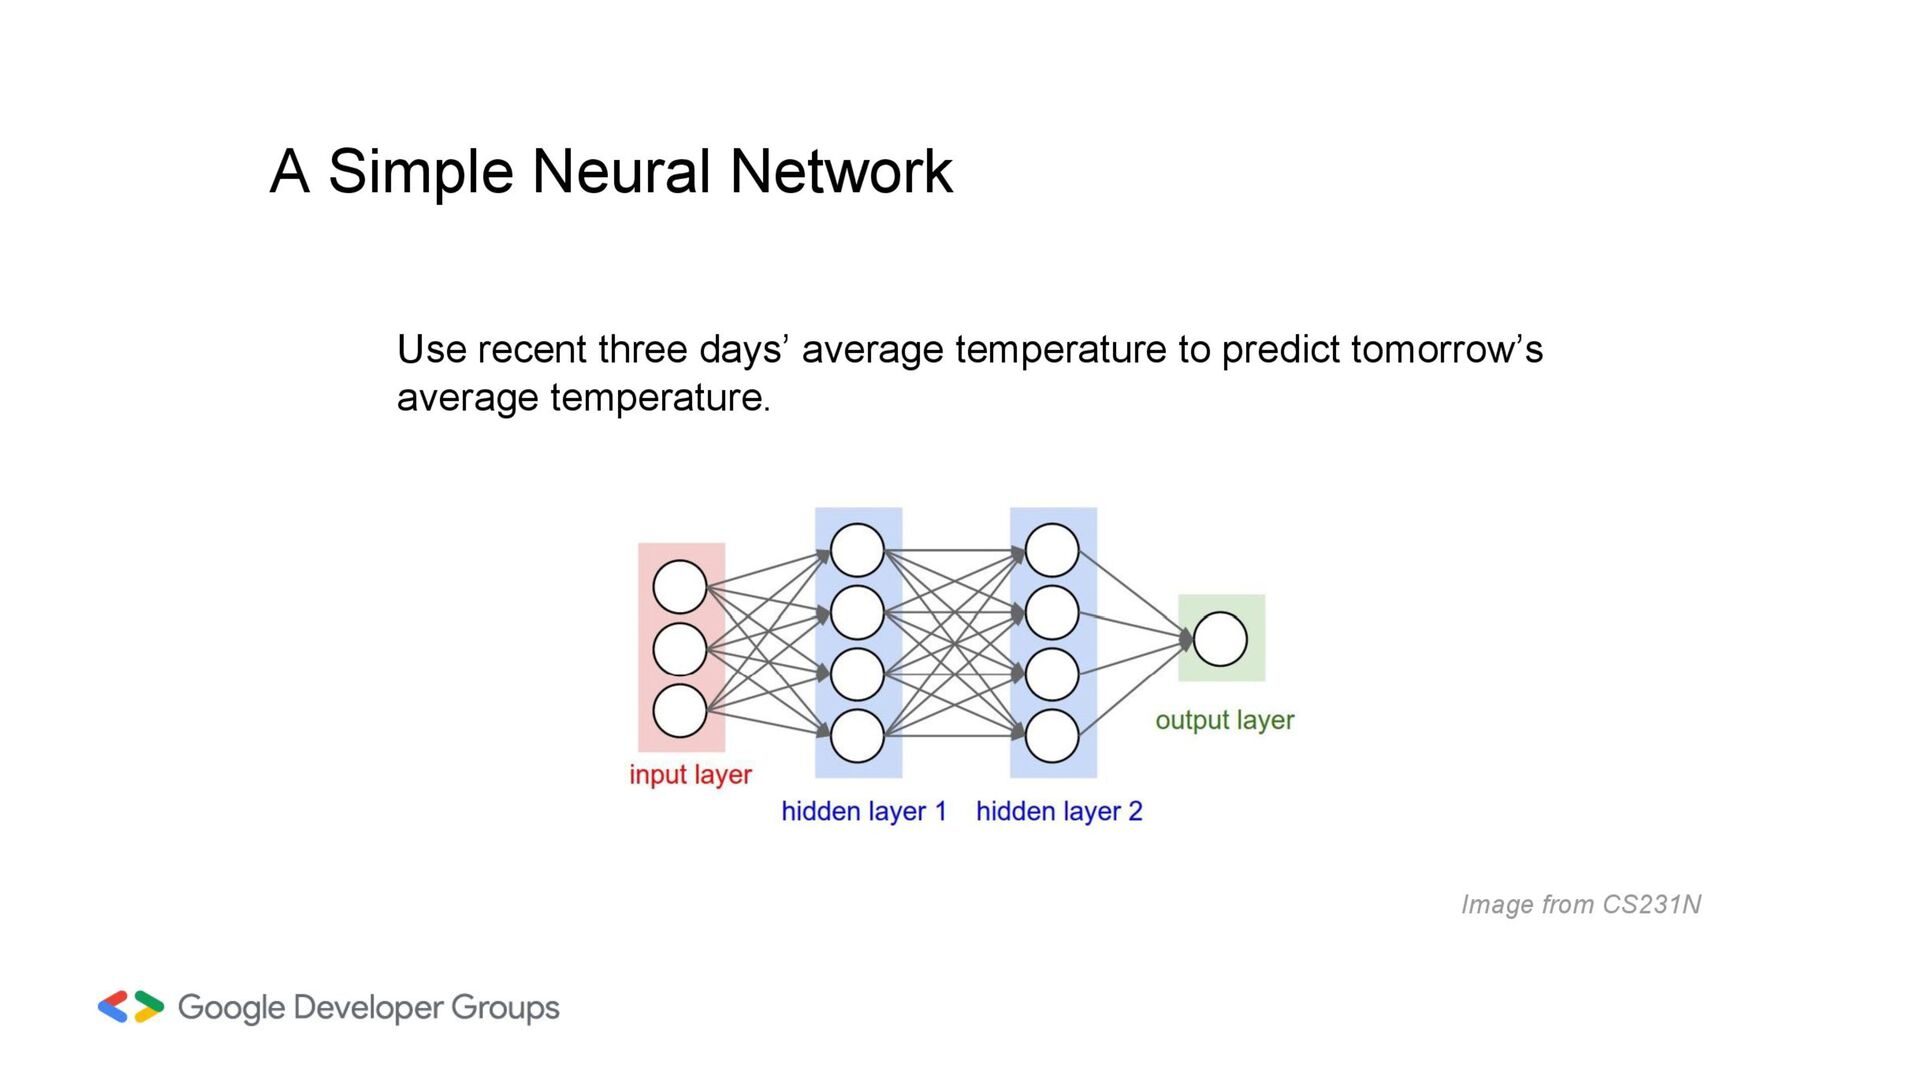
What are Neural Networks? They are computational models inspired by
the human brain's interconnected neurons, utilized in machine learning to process and learn from data, making them capable of complex pattern recognition and decision-making. Neural network layers can have a state (i.e have weights) or be stateless. -
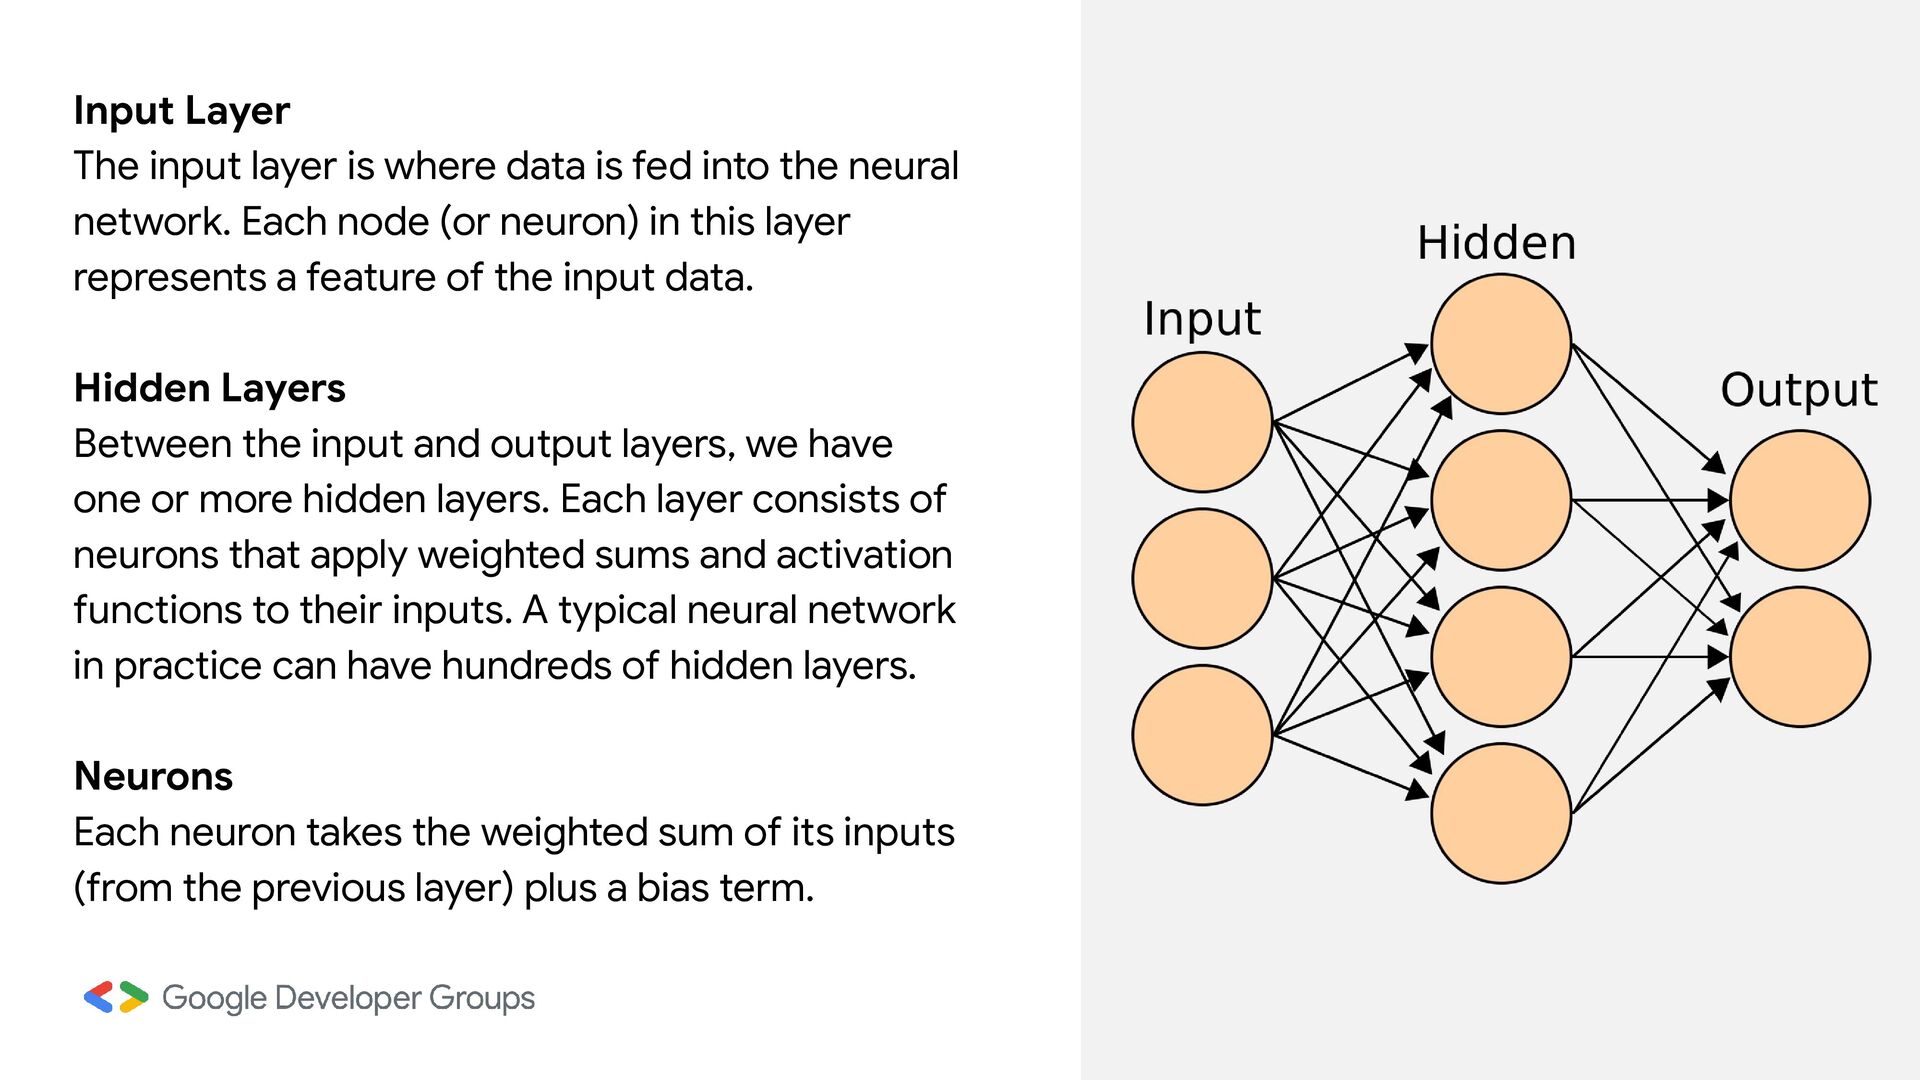
Input Layer The input layer is where data is fed
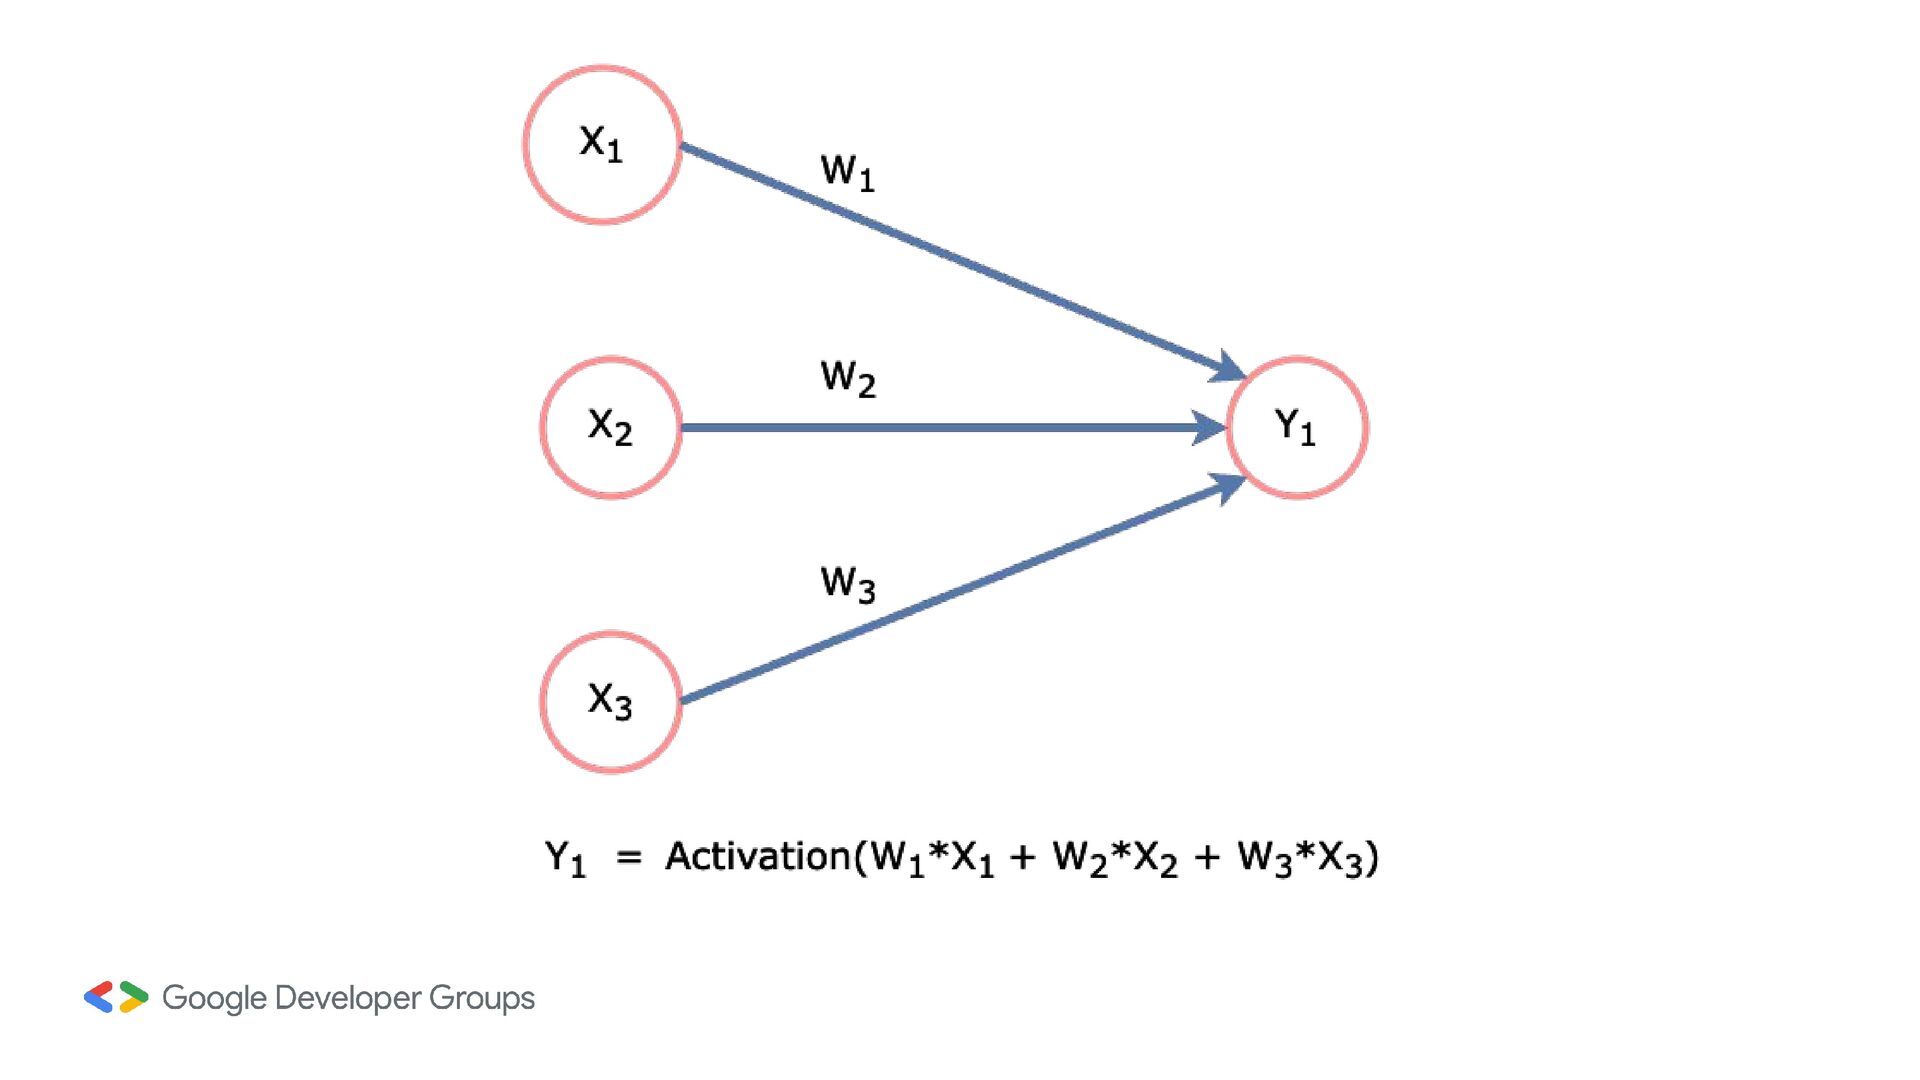
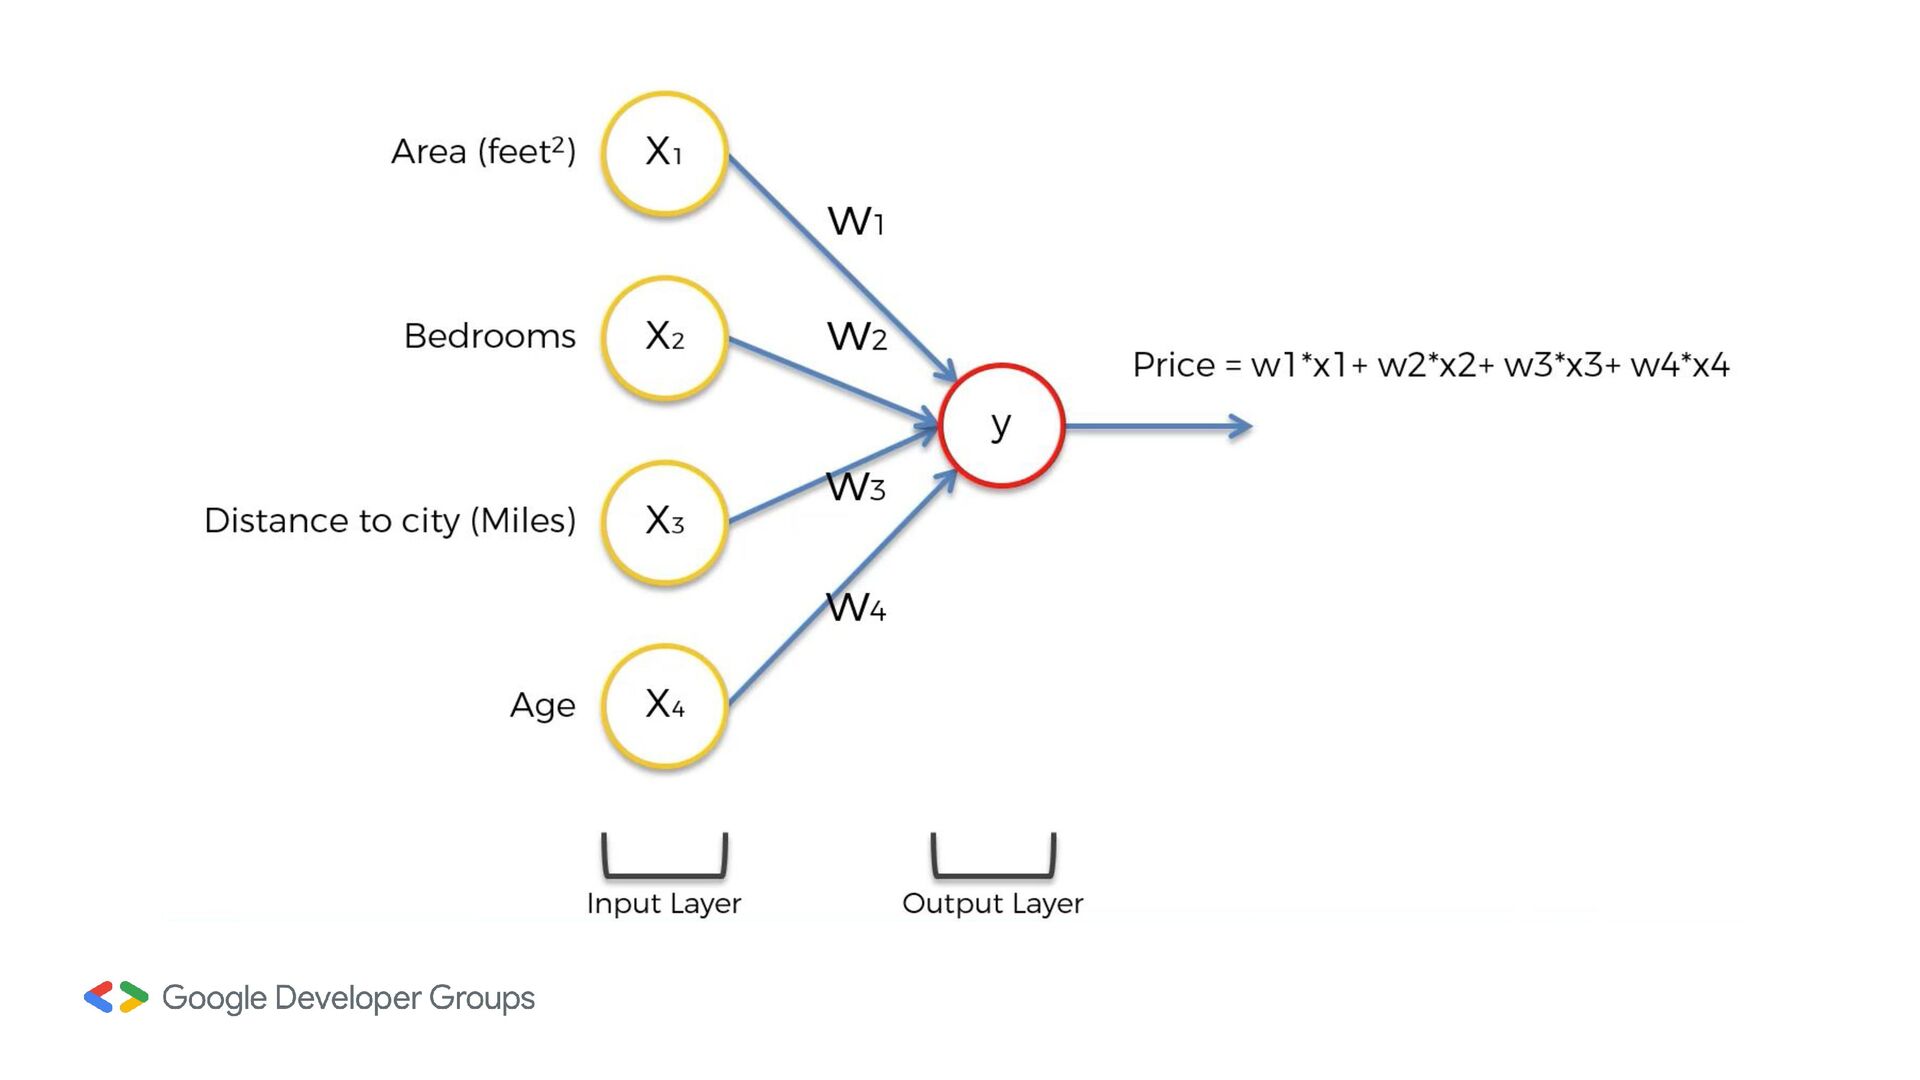
into the neural network. Each node (or neuron) in this layer represents a feature of the input data. Hidden Layers Between the input and output layers, we have one or more hidden layers. Each layer consists of neurons that apply weighted sums and activation functions to their inputs. A typical neural network in practice can have hundreds of hidden layers. Neurons Each neuron takes the weighted sum of its inputs (from the previous layer) plus a bias term. -
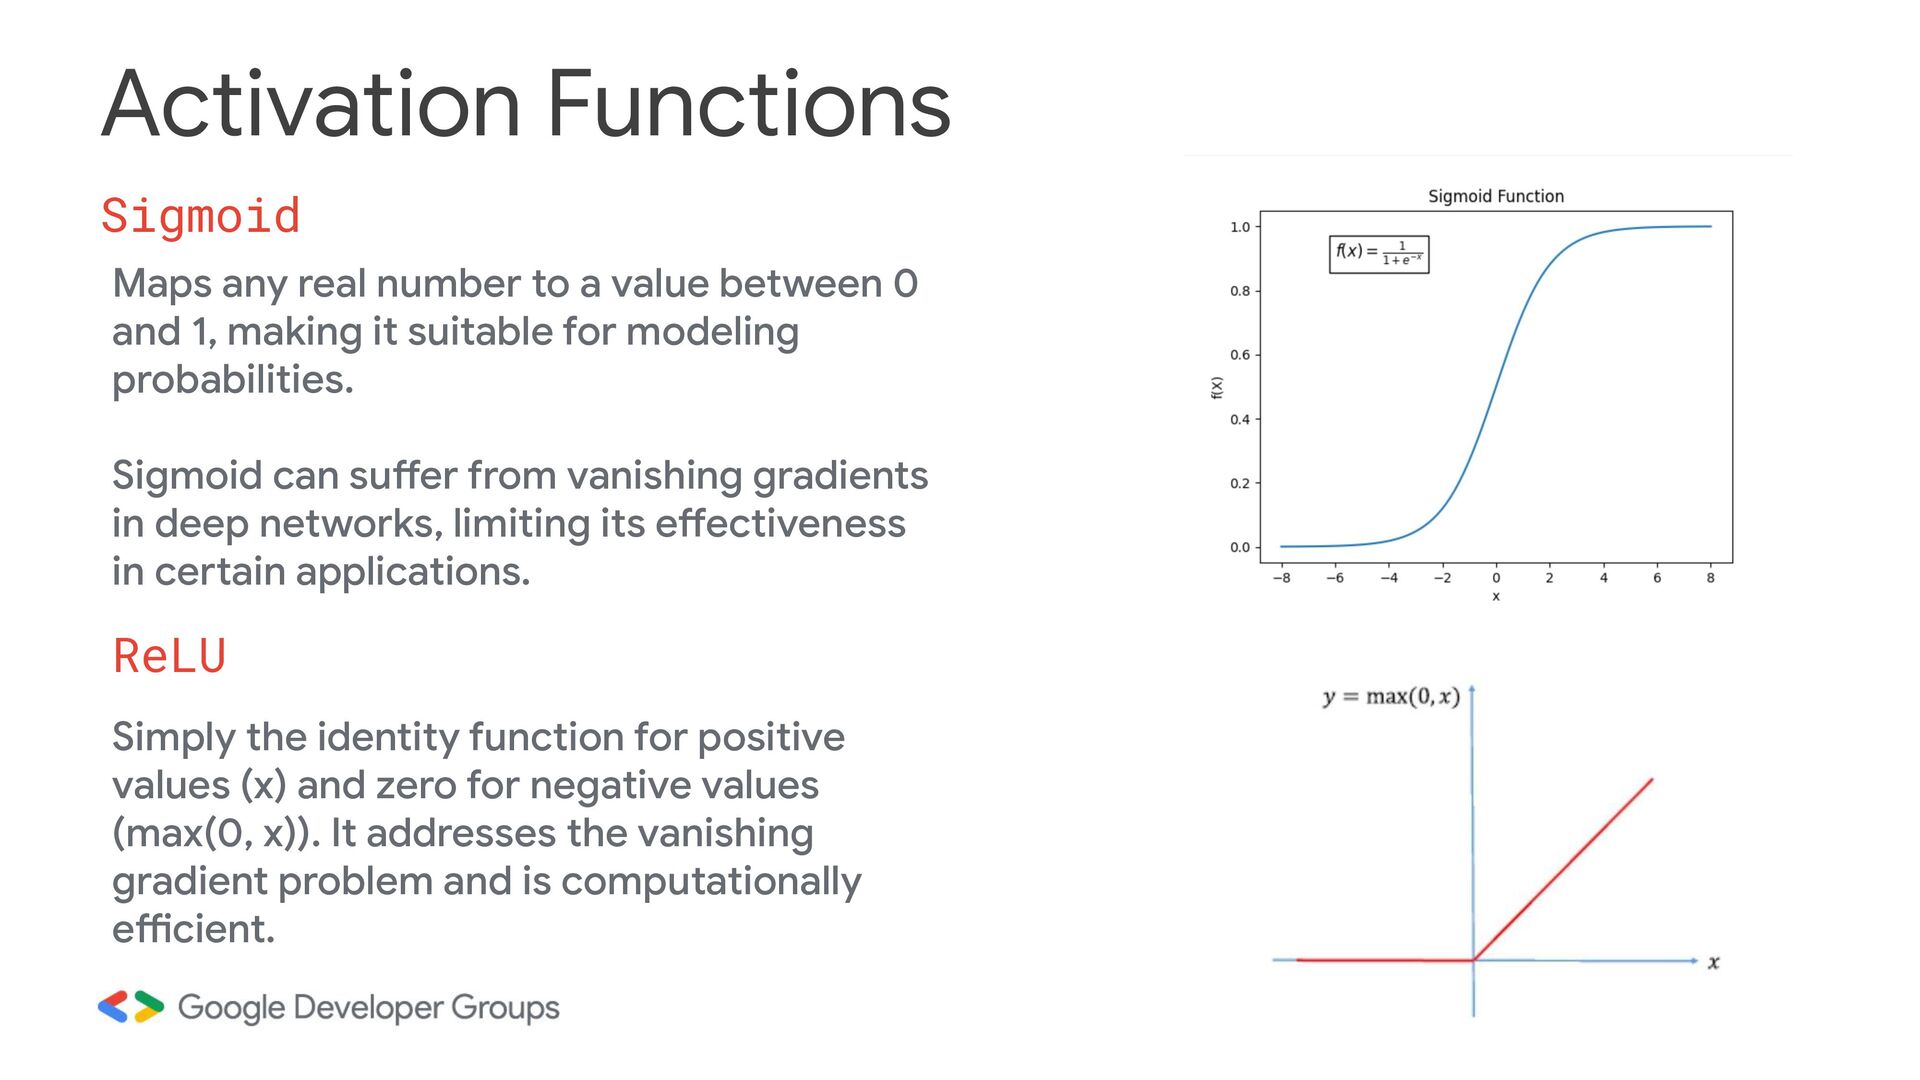
Activation Functions Sigmoid Maps any real number to a value
between 0 and 1, making it suitable for modeling probabilities. Sigmoid can suffer from vanishing gradients in deep networks, limiting its effectiveness in certain applications. ReLU Simply the identity function for positive values (x) and zero for negative values (max(0, x)). It addresses the vanishing gradient problem and is computationally efficient. -
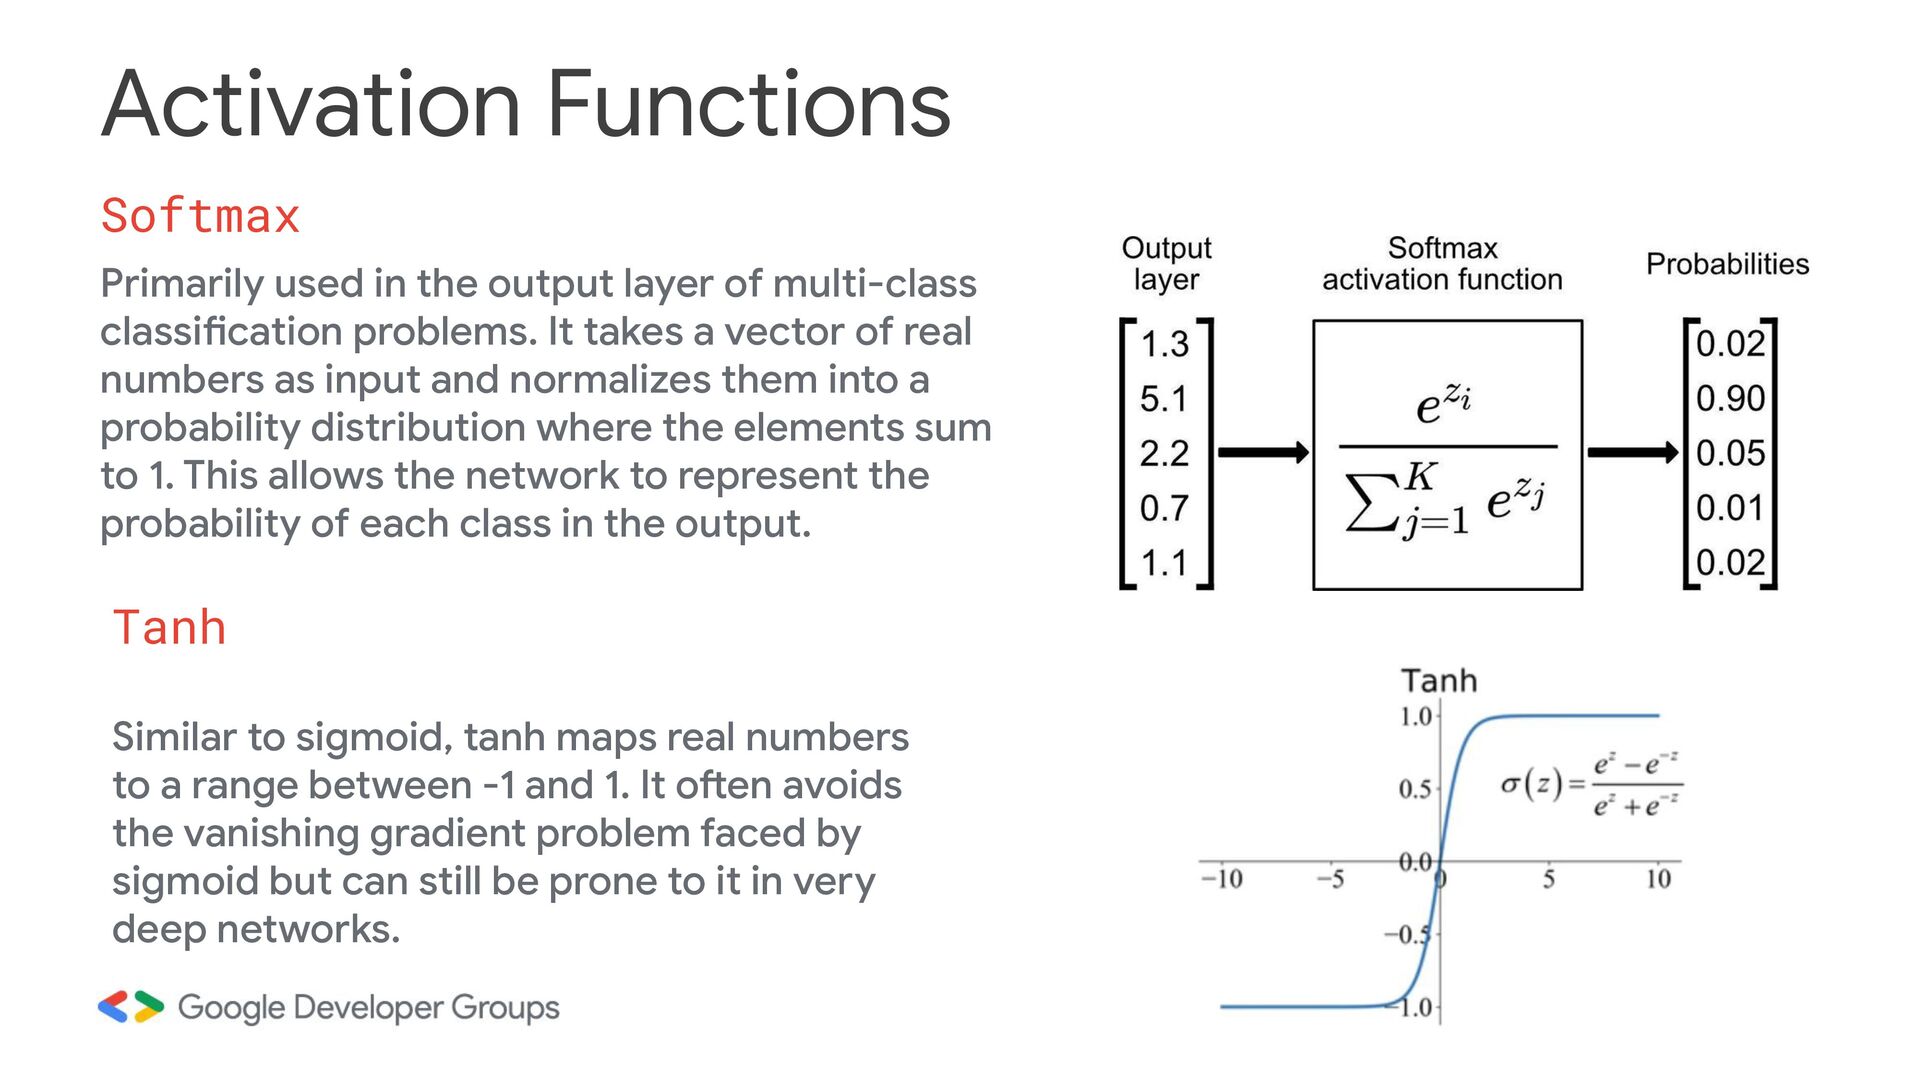
Activation Functions Softmax Primarily used in the output layer of
multi-class classification problems. It takes a vector of real numbers as input and normalizes them into a probability distribution where the elements sum to 1. This allows the network to represent the probability of each class in the output. Tanh Similar to sigmoid, tanh maps real numbers to a range between -1 and 1. It often avoids the vanishing gradient problem faced by sigmoid but can still be prone to it in very deep networks. -
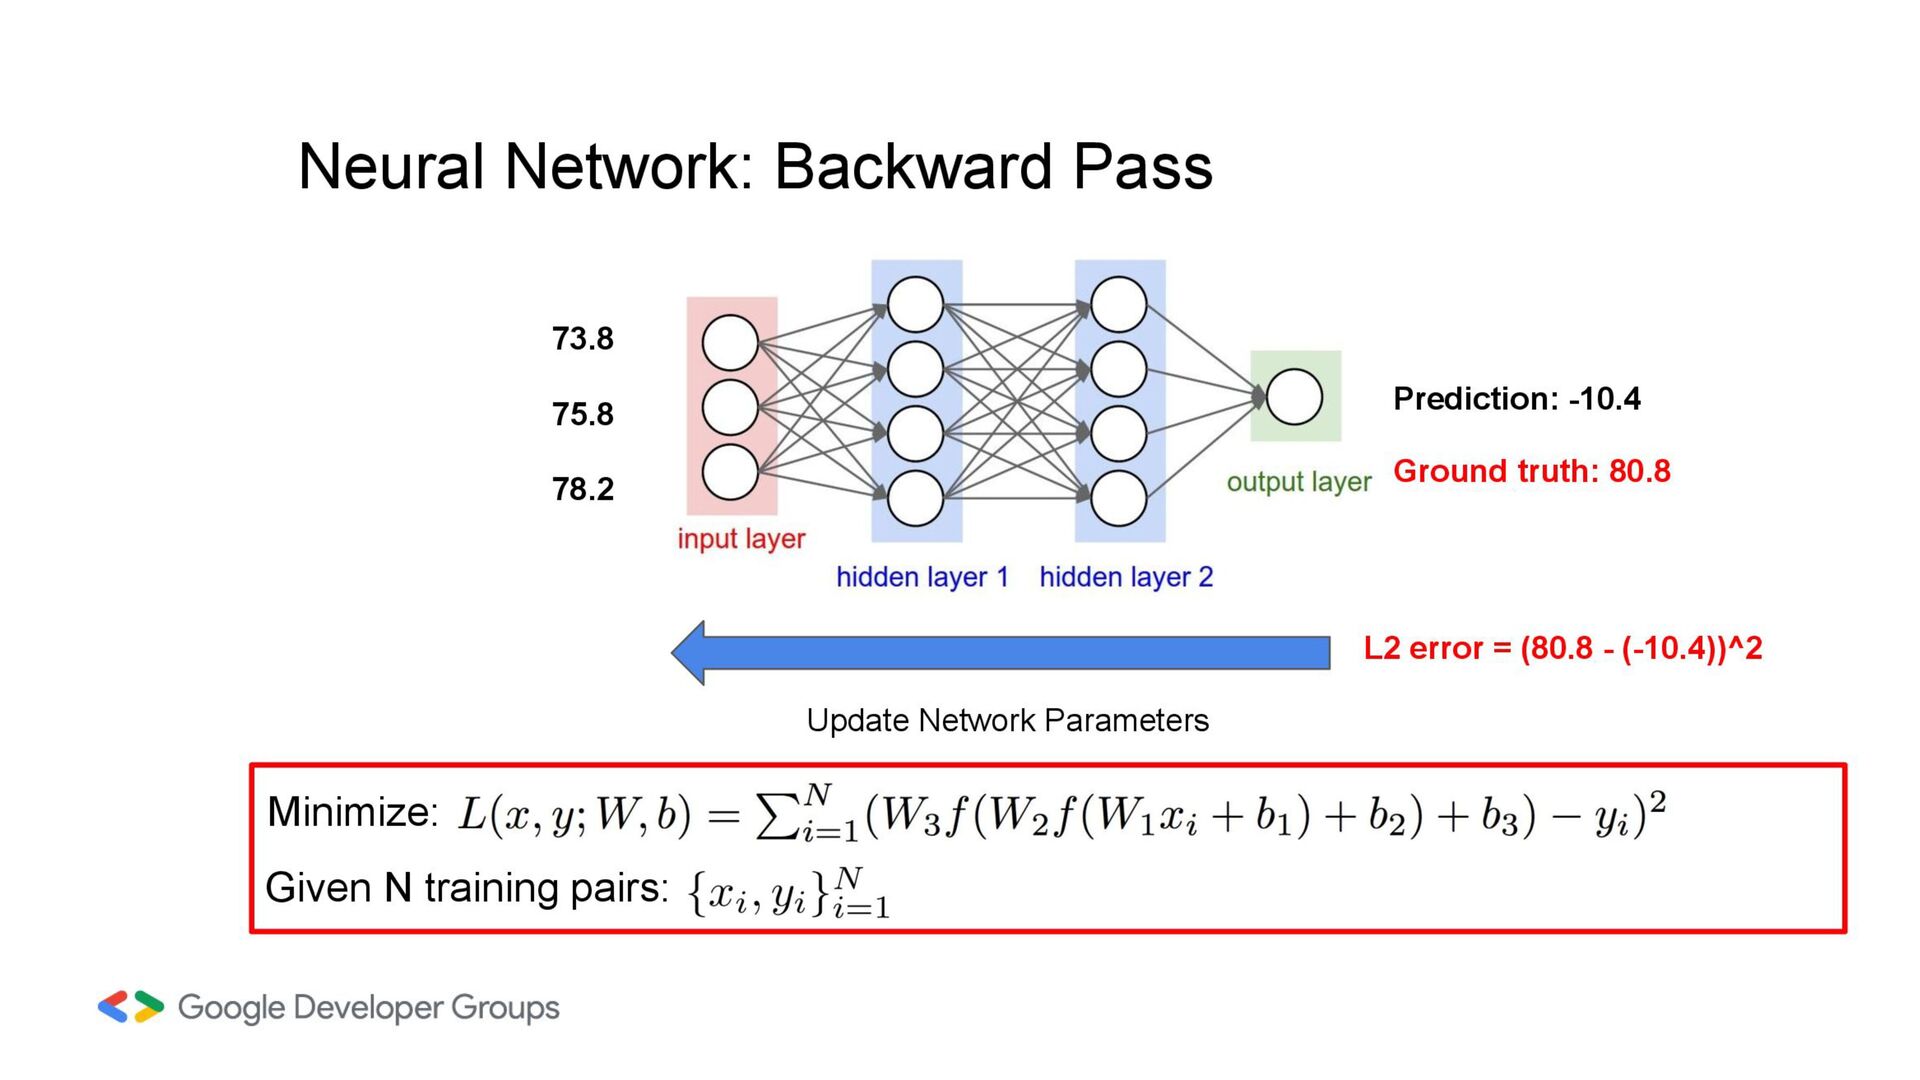
Loss Functions Regression Mean Squared Error (MSE): The average squared
difference between the predicted and actual values. Mean Absolute Error (MAE): The average of the absolute differences between the predicted and actual values. It is less sensitive to outliers compared to MSE. Classification Binary Cross-Entropy Loss (Log Loss): It measures the difference between the predicted probability of the positive class and the actual binary label (0 or 1). Categorical Cross-Entropy Loss: This is an extension of binary cross-entropy for multi-class classification problems (more than two classes). It calculates the average cross-entropy loss across all classes -
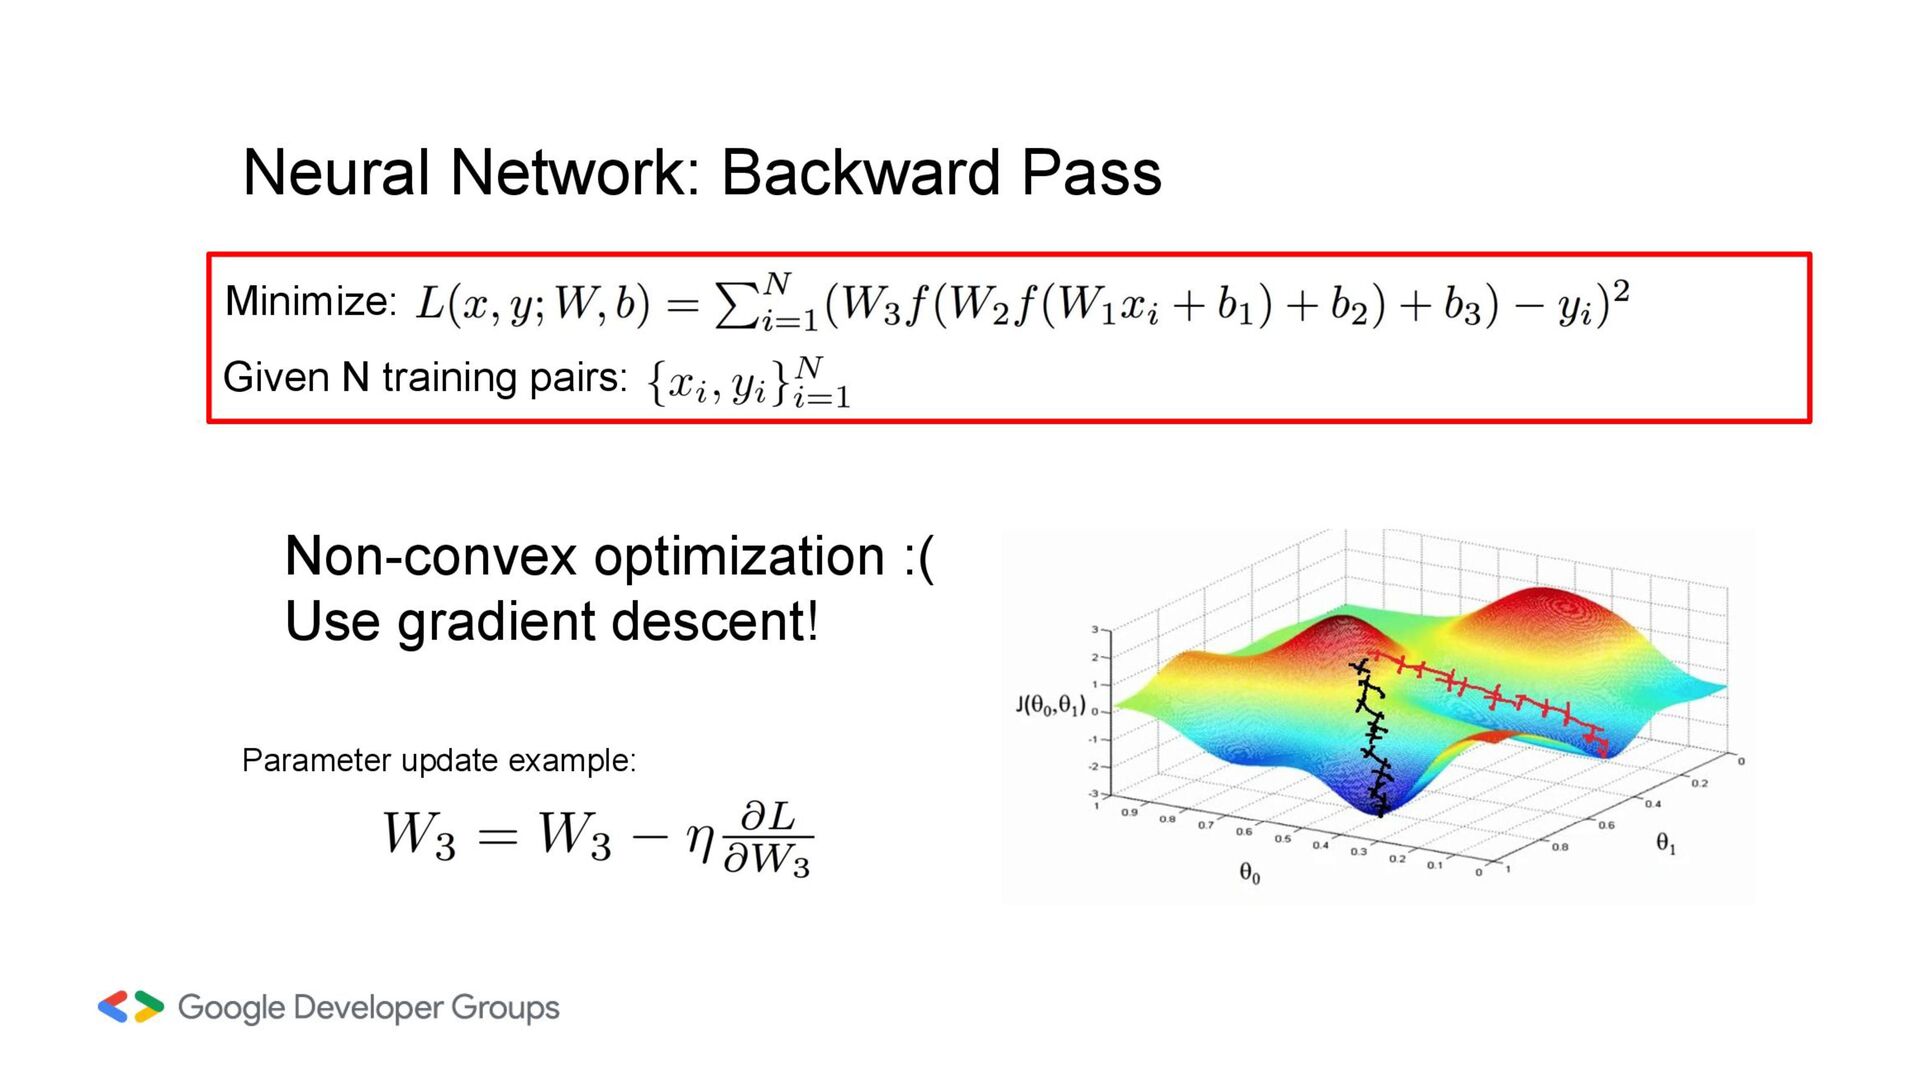
Optimizers Stochastic Gradient Descent (SGD) A fundamental and widely used
optimizer that iteratively updates the model parameters based on the gradient of the loss function with respect to each parameter. It takes a small learning rate step in the direction of the negative gradient, aiming to minimize the loss. RMSprop (Root Mean Square Prop) Adaptively adjusts the learning rate for each parameter based on its historical squared gradients. This helps to address the issue of diminishing learning rates in SGD for parameters with frequently changing gradients. Adam (Adaptive Moment Estimation) Combines the benefits of momentum and RMSprop, incorporating both exponentially decaying averages of past gradients and squared gradients. It is widely used due to its efficiency and effectiveness in various deep learning tasks. -
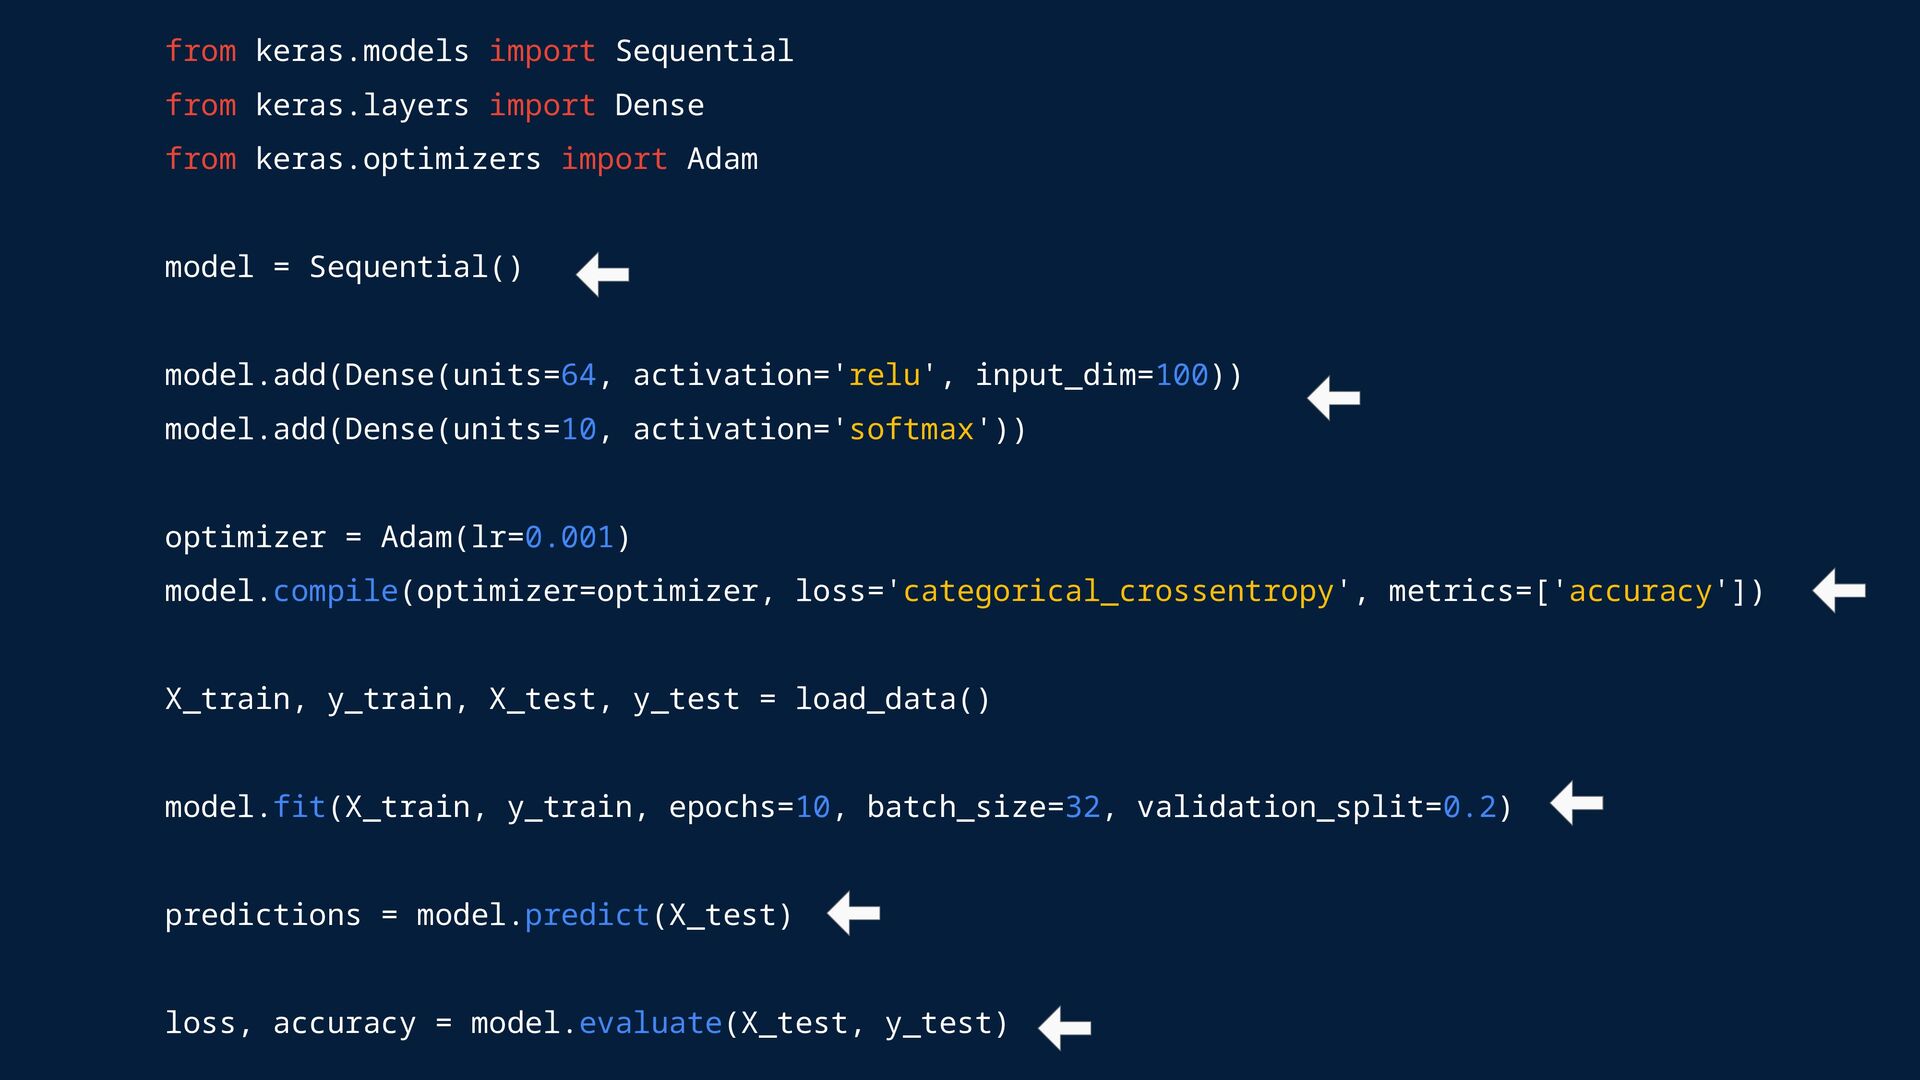
from keras.models import Sequential from keras.layers import Dense from keras.optimizers
import Adam model = Sequential() model.add(Dense(units=64, activation='relu', input_dim=100)) model.add(Dense(units=10, activation='softmax')) optimizer = Adam(lr=0.001) model.compile(optimizer=optimizer, loss='categorical_crossentropy', metrics=['accuracy']) X_train, y_train, X_test, y_test = load_data() model.fit(X_train, y_train, epochs=10, batch_size=32, validation_split=0.2) predictions = model.predict(X_test) loss, accuracy = model.evaluate(X_test, y_test) -
Resources Google Colab Notebook here. (Make a Copy) Access the
Keras Official Documentation: https://keras.io/docs Access the TensorFlow official documentation here: https://www.tensorflow.org/api_docs -
Machine learning is the future - Robert John, GDE -
ML & Google Cloud