Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
Baseline Needs More Love: On Simple Word-Embedd...
Search
Sponsored
·
SiteGround - Reliable hosting with speed, security, and support you can count on.
→
katsutan
April 08, 2019
Technology
260
0
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
Baseline Needs More Love: On Simple Word-Embedding-Based Models and Associated Pooling Mechanisms
文献紹介
長岡技術科学大学
勝田 哲弘
katsutan
April 08, 2019
More Decks by katsutan
See All by katsutan
What does BERT learn about the structure of language?
katsutan
0
280
Simple and Effective Paraphrastic Similarity from Parallel Translations
katsutan
0
240
Simple task-specific bilingual word embeddings
katsutan
0
250
Retrofitting Contextualized Word Embeddings with Paraphrases
katsutan
0
300
Character Eyes: Seeing Language through Character-Level Taggers
katsutan
1
250
Improving Word Embeddings Using Kernel PCA
katsutan
0
250
Better Word Embeddings by Disentangling Contextual n-Gram Information
katsutan
0
370
Rotational Unit of Memory: A Novel Representation Unit for RNNs with Scalable Applications
katsutan
0
300
A robust self-learning method for fully unsupervised cross-lingual mappings of word embeddings
katsutan
0
320
Other Decks in Technology
See All in Technology
Conditional PED-ANOVA: Hyperparameter Importance in Hierarchical & Dynamic Search Spaces
pfn
PRO
0
130
コンテナ運用におけるネットワーク・コンテナコストの削減方法/How to Reduce Network and Container Costs in Container Operations
masakiokuda
1
150
自作バイナリを動かす「入口」8選
puhitaku
2
1.3k
Benchmarking Disaggregated Serving on vLLM + Dynamo with a Real Coding-Agent Workload
nttcom
1
190
Local CI × GitHub Actions
gogutan
2
190
Gemini Intelligence 入門 ― AppFunctions と Gemini Nano
takuroabe
0
250
Getting Started with Google Antigravity
glaforge
0
300
AI × アーキテクト 第1・2章|生成AIの課題とアーキテクトの素養
daidaidai
0
170
無理せず続ける、子育てエンジニアの学び
codmoninc
PRO
0
860
脆弱性診断って、何をしているの? 〜弱点を見つけて、会社の改善につなげるまで〜
keeg
0
920
実体験から学ぶ分析エージェントの開発と運⽤
recruitengineers
PRO
8
2.4k
会社説明資料
persolserverworks
0
9.8k
Featured
See All Featured
Collaborative Software Design: How to facilitate domain modelling decisions
baasie
1
340
Writing Fast Ruby
sferik
630
63k
AI in Enterprises - Java and Open Source to the Rescue
ivargrimstad
0
1.5k
The Cost Of JavaScript in 2023
addyosmani
55
10k
16th Malabo Montpellier Forum Presentation
akademiya2063
PRO
0
410
The MySQL Ecosystem @ GitHub 2015
samlambert
251
13k
30 Presentation Tips
portentint
PRO
1
430
DBのスキルで生き残る技術 - AI時代におけるテーブル設計の勘所
soudai
PRO
68
58k
Organizational Design Perspectives: An Ontology of Organizational Design Elements
kimpetersen
PRO
1
850
<Decoding/> the Language of Devs - We Love SEO 2024
nikkihalliwell
1
360
CoffeeScript is Beautiful & I Never Want to Write Plain JavaScript Again
sstephenson
162
16k
エンジニアに許された特別な時間の終わり
watany
109
250k
Transcript
Baseline Needs More Love: On Simple Word-Embedding-Based Models and Associated
Pooling Mechanisms Proceedings of the 56th Annual Meeting of the Association for Computational Linguistics (Long Papers), pages 440–450 Melbourne, Australia, July 15 - 20, 2018. 文献紹介: 長岡技術科学大学 勝田 哲弘
Abstract • Simple Word-Embedding-based Models (SWEMs)と word-embedding-based RNN/CNN modelsの比較 ◦
SWEMsが多くの場合で同等、優れた精度を示す • Parameter freeのpoolingを活用するモデル ◦ hierarchical pooling ◦ parameter数が少なく済む 2
Introduction • Word embeddingは各単語を固定長のベクトルとして表現し、可変長テキ ストのモデル化によく利用されている ◦ 加算などの簡易的なものからRNN、CNNなど • RNN、CNNはパラメータが多く、計算コストが高い •
SWEMは語順情報が明示的でない、計算コストは低い • 計算コストと表現力はトレードオフ 3
Introduction • 単語分散表現で実行される単純なpooling処理が自然言語処理にいつ、 なぜ有効なのかを調査する • 3つの異なるタスク(17のデータセット)で評価 4
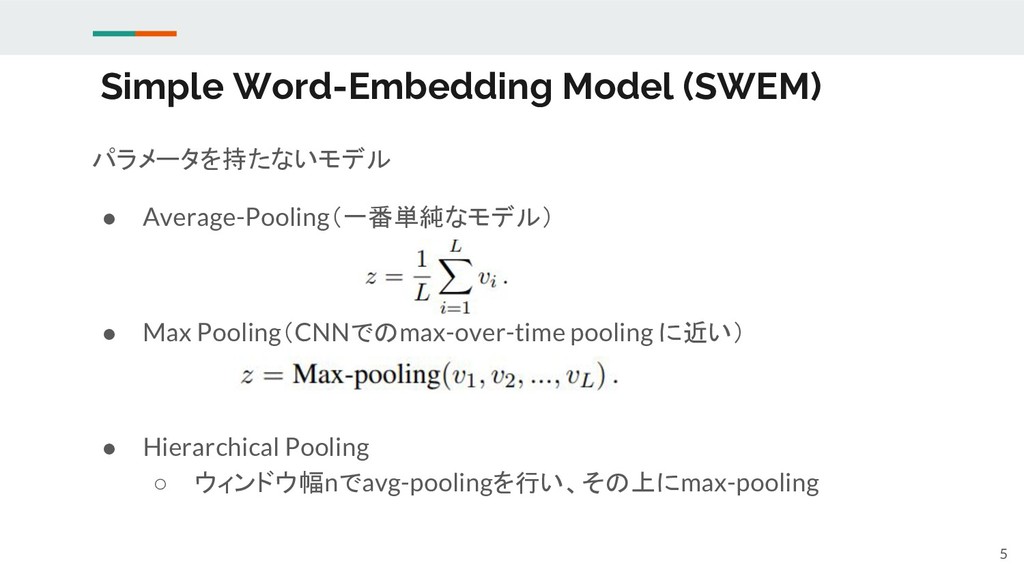
Simple Word-Embedding Model (SWEM) パラメータを持たないモデル • Average-Pooling(一番単純なモデル) • Max Pooling(CNNでのmax-over-time
pooling に近い) • Hierarchical Pooling ◦ ウィンドウ幅nでavg-poolingを行い、その上にmax-pooling 5
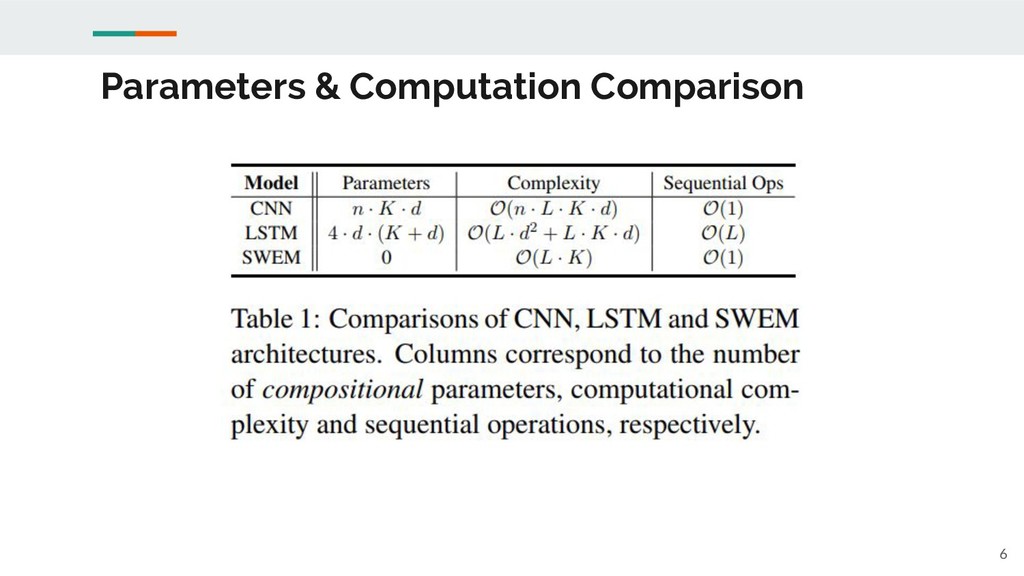
Parameters & Computation Comparison 6
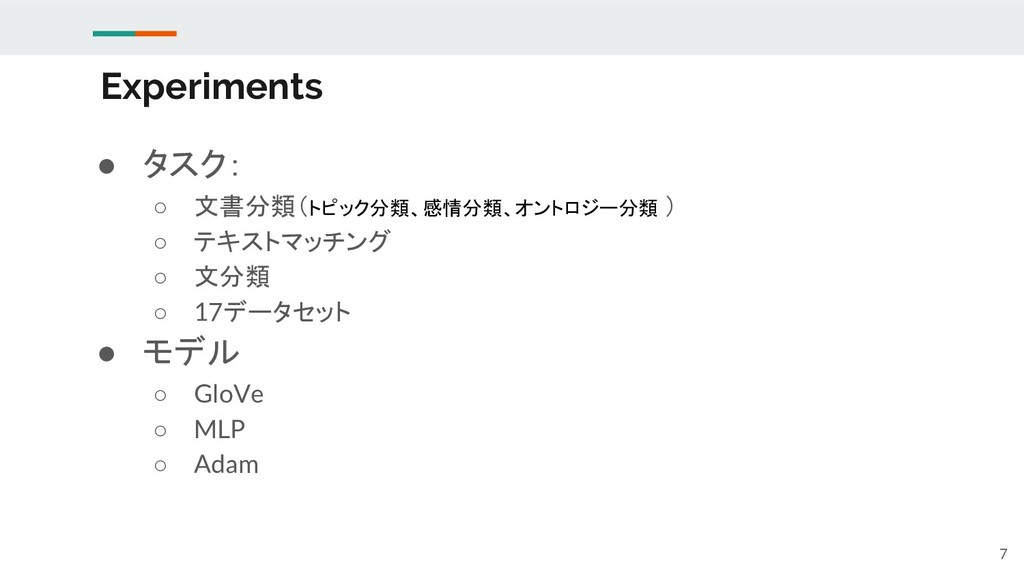
Experiments • タスク: ◦ 文書分類(トピック分類、感情分類、オントロジー分類 ) ◦ テキストマッチング ◦ 文分類
◦ 17データセット • モデル ◦ GloVe ◦ MLP ◦ Adam 7
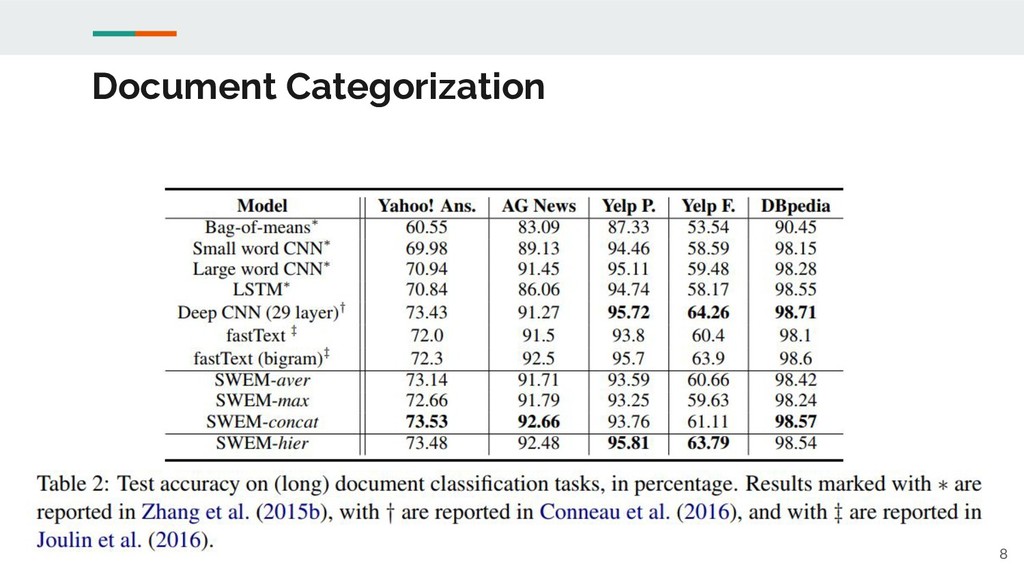
Document Categorization 8
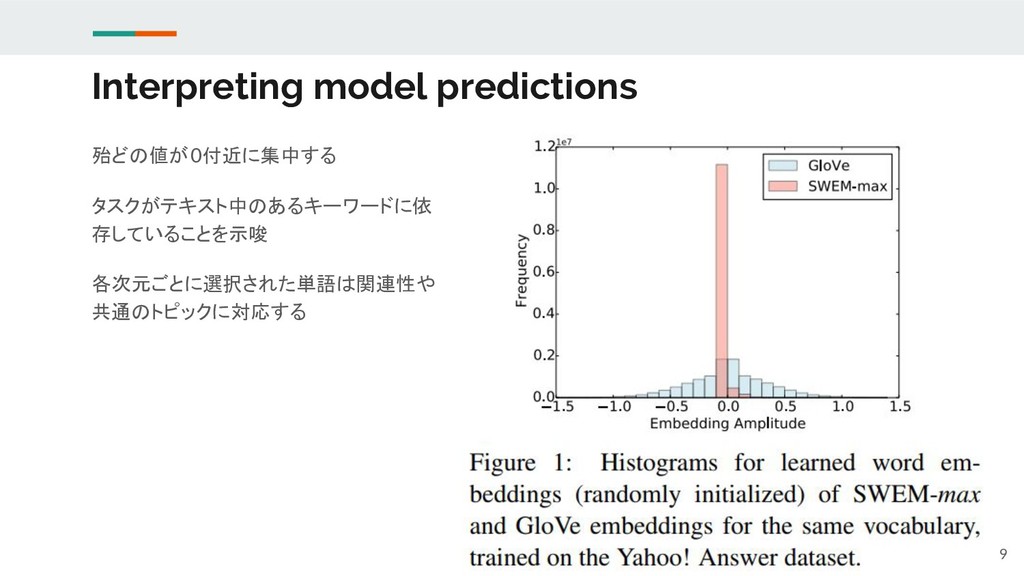
Interpreting model predictions 殆どの値が0付近に集中する タスクがテキスト中のあるキーワードに依 存していることを示唆 各次元ごとに選択された単語は関連性や 共通のトピックに対応する 9
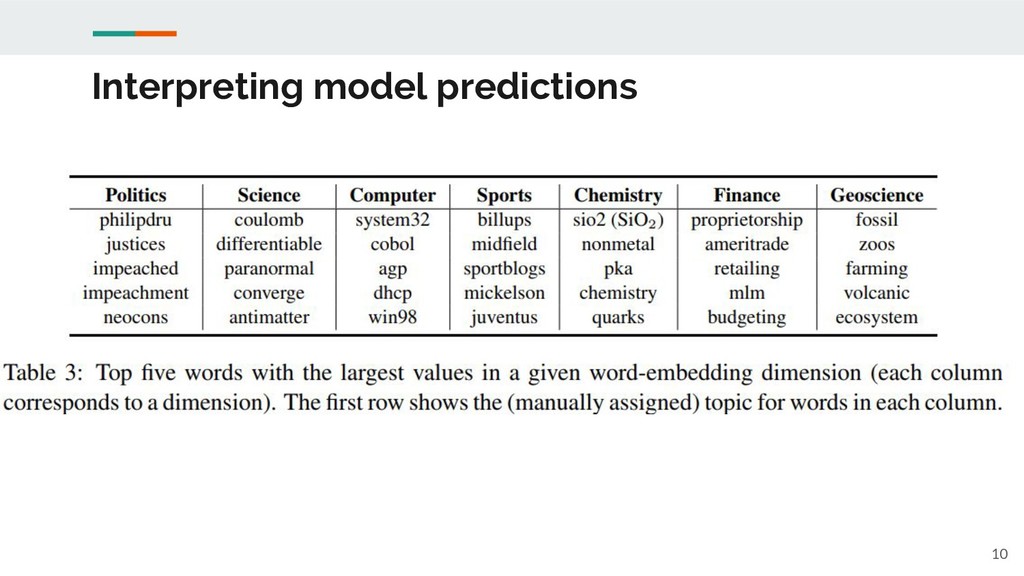
Interpreting model predictions 10
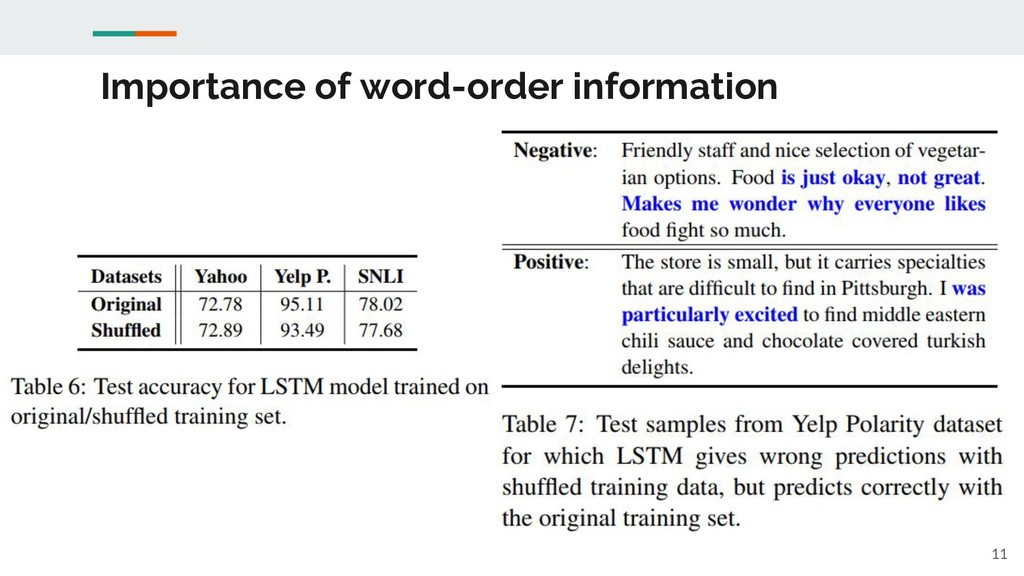
Importance of word-order information 11
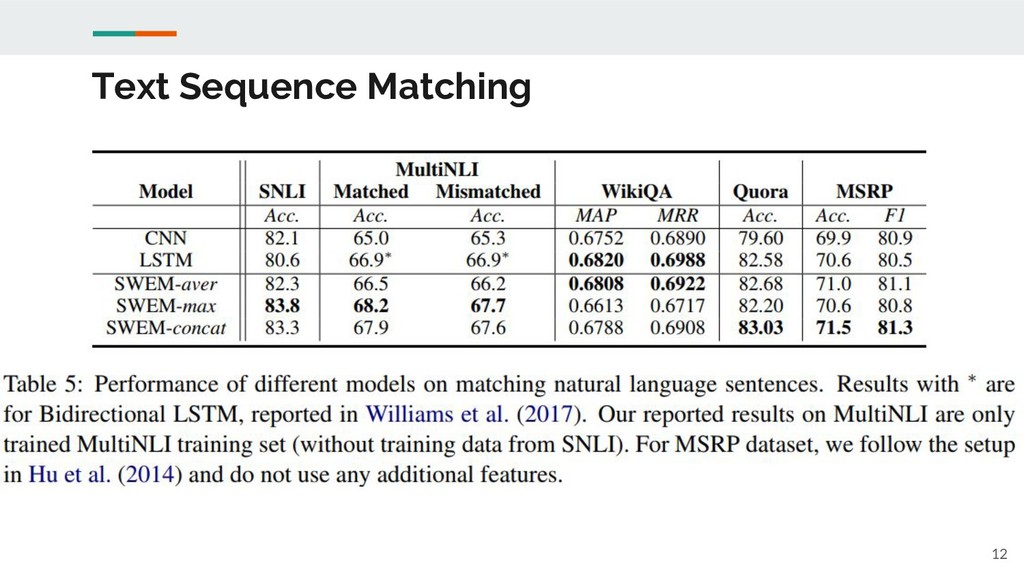
Text Sequence Matching 12
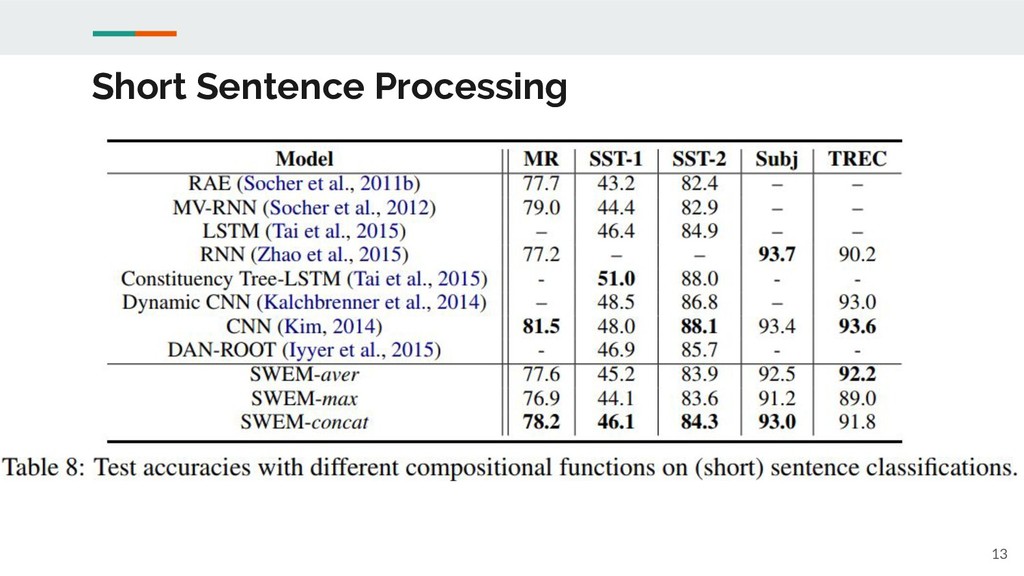
Short Sentence Processing 13
Extension to other languages • Sogou news corpus(a Chinese dataset
represented by Pinyin) ◦ SWEM-concat accuracy : 91.3% ◦ SWEM-hier (window size of 5) accuracy : 96.2% ◦ CNN (95.6%) and LSTM (95.2%) • より語順に敏感な中国語においても最高精度に匹敵する 14
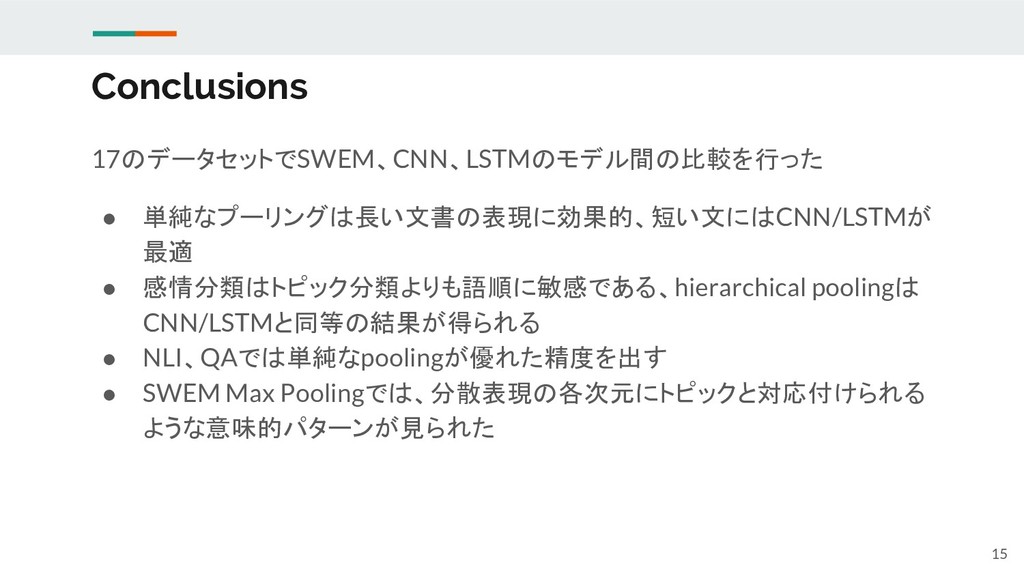
Conclusions 17のデータセットでSWEM、CNN、LSTMのモデル間の比較を行った • 単純なプーリングは長い文書の表現に効果的、短い文にはCNN/LSTMが 最適 • 感情分類はトピック分類よりも語順に敏感である、hierarchical poolingは CNN/LSTMと同等の結果が得られる •
NLI、QAでは単純なpoolingが優れた精度を出す • SWEM Max Poolingでは、分散表現の各次元にトピックと対応付けられる ような意味的パターンが見られた 15

 SiteGround - Reliable hosting with speed, security, and support you can count on.


 katsutan
 pfn
 masakiokuda
 puhitaku
 nttcom
 gogutan
 takuroabe
 glaforge
 daidaidai
 codmoninc
 keeg
 recruitengineers
 persolserverworks
 baasie
 sferik
 ivargrimstad
 addyosmani
 akademiya2063
 samlambert
 portentint
 soudai
 kimpetersen
 nikkihalliwell
 sstephenson
 watany