Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
L1キャッシュ怖い
Search
Hiroki KUMAZAKI
April 10, 2023
Programming
130
0
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
L1キャッシュ怖い
RadixSortを並列化&高速化する話
Hiroki KUMAZAKI
April 10, 2023
Other Decks in Programming
See All in Programming
FactoryBotをやめればRSpecは速くなるのか?
yuta_onishi_97
0
330
Railsのためのパスキー実践入門 〜マルチテナントSaaSでの意思決定〜
utakaha
2
550
[ハンズオン]AIへの指示だけで「五目並べ」を作ってみよう
satoshi256kbyte
1
380
golang-bob.pdf
iwatsukayura
0
130
作れる、でも消せるか?──安全に「枯らして消す」機能削除術 / Drain, Then Delete
chobishiba
2
640
Optunaを作ったときにやりたかったこと、その後 (2026/10/16, Optuna Meetup #3)
iwiwi
1
430
Agentic Software Factoryに、すごく賢いIF文を。 / super smart IF statement into the Agentic Software Factory.
rkaga
8
2.2k
個人開発者よ、Honoを使え(おじさんver)
tanahiro2010
2
260
GemmaをJevのように使ってみる / Use Gemma like Jev
kishida
5
790
AI時代のコードレビューは人に向けるな、仕組みに向けろ
texmeijin
5
3.7k
ソニーのクラウド共通基盤の変遷と AI時代の開発スタイルに合わせた進化 / The Journey of Sony’s Common Cloud Platform and Its Evolution for AI-Native Development
kenjiyoneyama
0
270
ChromeでローカルLLM
ryu1013
0
140
Featured
See All Featured
Ruling the World: When Life Gets Gamed
codingconduct
0
400
Java REST API Framework Comparison - PWX 2021
mraible
34
9.8k
BBQ
matthewcrist
90
10k
Money Talks: Using Revenue to Get Sh*t Done
nikkihalliwell
0
520
Build The Right Thing And Hit Your Dates
maggiecrowley
39
3.5k
How People are Using Generative and Agentic AI to Supercharge Their Products, Projects, Services and Value Streams Today
helenjbeal
2
360
AI: The stuff that nobody shows you
jnunemaker
PRO
10
1.2k
Rails Girls Zürich Keynote
gr2m
96
14k
Why You Should Never Use an ORM
jnunemaker
PRO
61
10k
Test your architecture with Archunit
thirion
2
2.4k
Keith and Marios Guide to Fast Websites
keithpitt
413
23k
Practical Tips for Bootstrapping Information Extraction Pipelines
honnibal
25
2.1k
Transcript
L1キャッシュ怖い 3/23 広域センサネットワークとオーバーレイに関する ワークショップ @kumagi
Radix Sortとは • O(N)なソートアルゴリズム – iwiwi博士「経験上実測で一番速い」 • O(N)のメモリ領域が追加で必要になる – なので多くの場面ではMerge
SortやQuick Sortが 採用されたりする。 – In-PlaceなRadix Sortは最近の研究トピックの一つ • 実装上内部でCounting Sortを使うことが多い – CountingSortに関しては次ページ
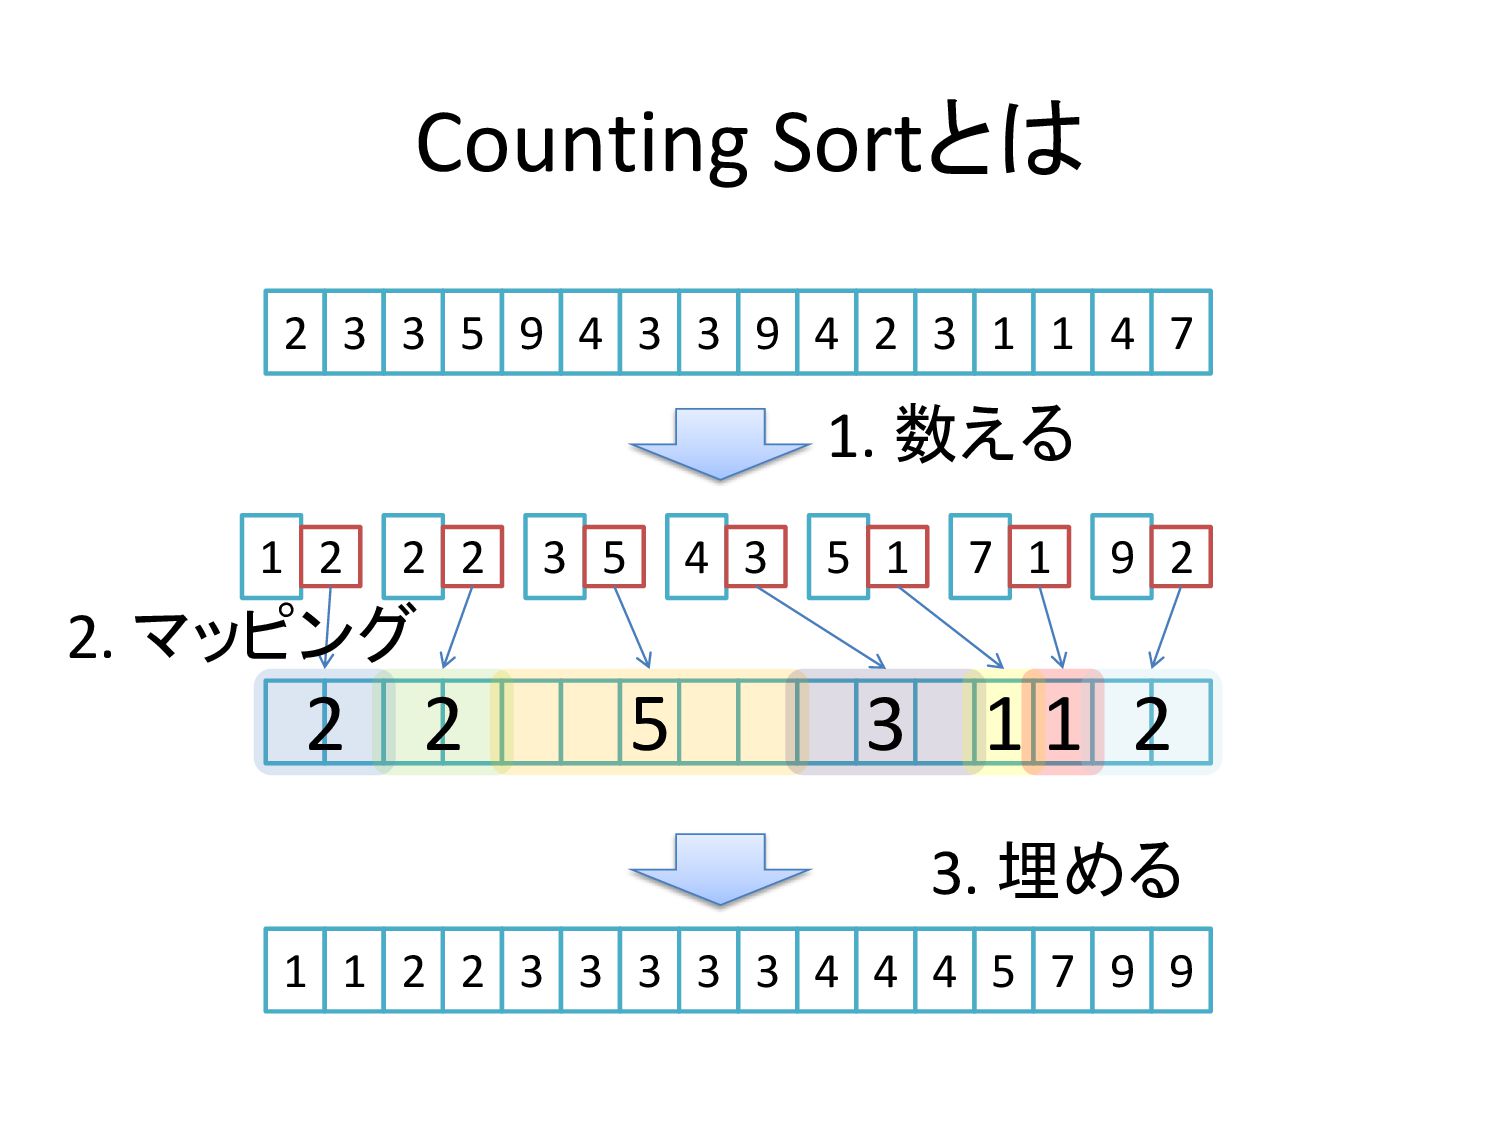
Counting Sortとは 2 3 3 5 9 4 3 3
9 4 2 3 1 1 4 7 1 2 3 4 5 7 9 2 2 5 3 1 1 2 1. 数える 2 2 5 3 1 1 2 2. マッピング 1 1 2 2 3 3 3 3 3 4 4 4 5 7 9 9 3. 埋める
Radix Sort with Counting Sort • CountingSortは値のバリエーションが増えると 死ぬ • 実用上8bit(256種)ずつCounting
Sortする。 • Counting SortはStableなので下8bitから順に Sortする(Least Significant Digit first)。 • 上8bitからSortする事も可能(Most Significant Digit first)こっちはまた後で。
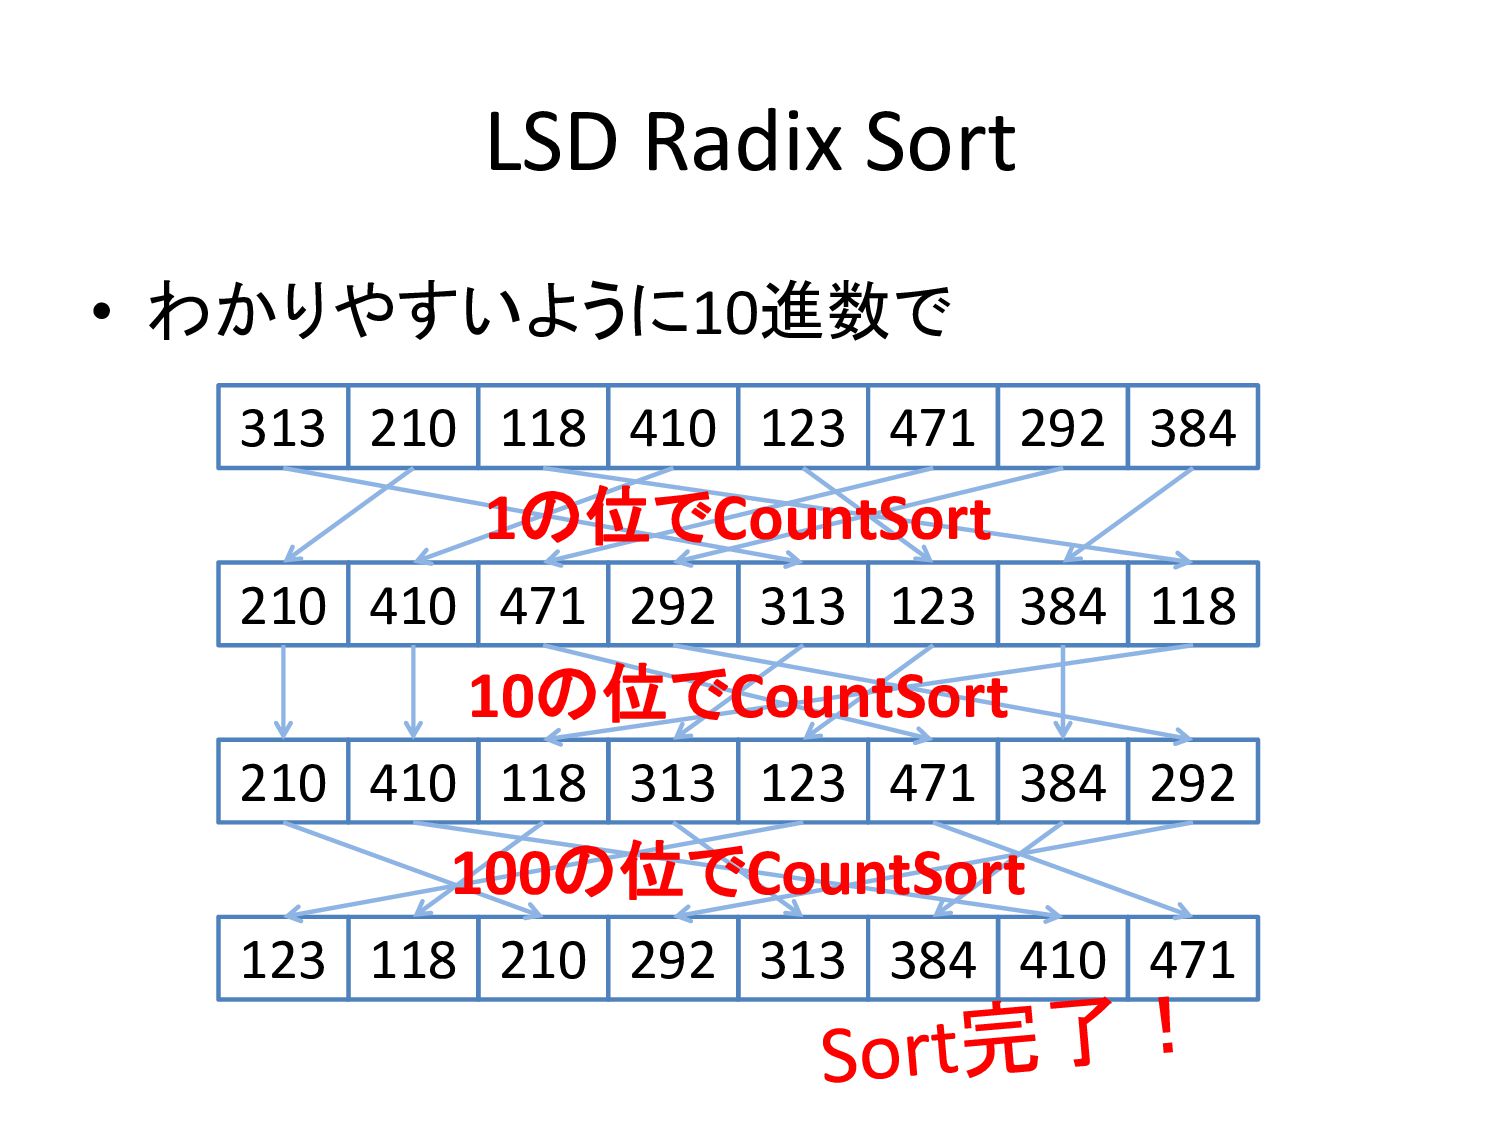
LSD Radix Sort • わかりやすいように10進数で 313 210 118 410 123
471 292 384 313 210 118 410 123 471 292 384 313 210 118 410 123 471 292 384 313 210 118 410 123 471 292 384 1の位でCountSort 10の位でCountSort 100の位でCountSort
LSD Radix Sort https://www.youtube.com/watch?v=kPRA0W1kECg
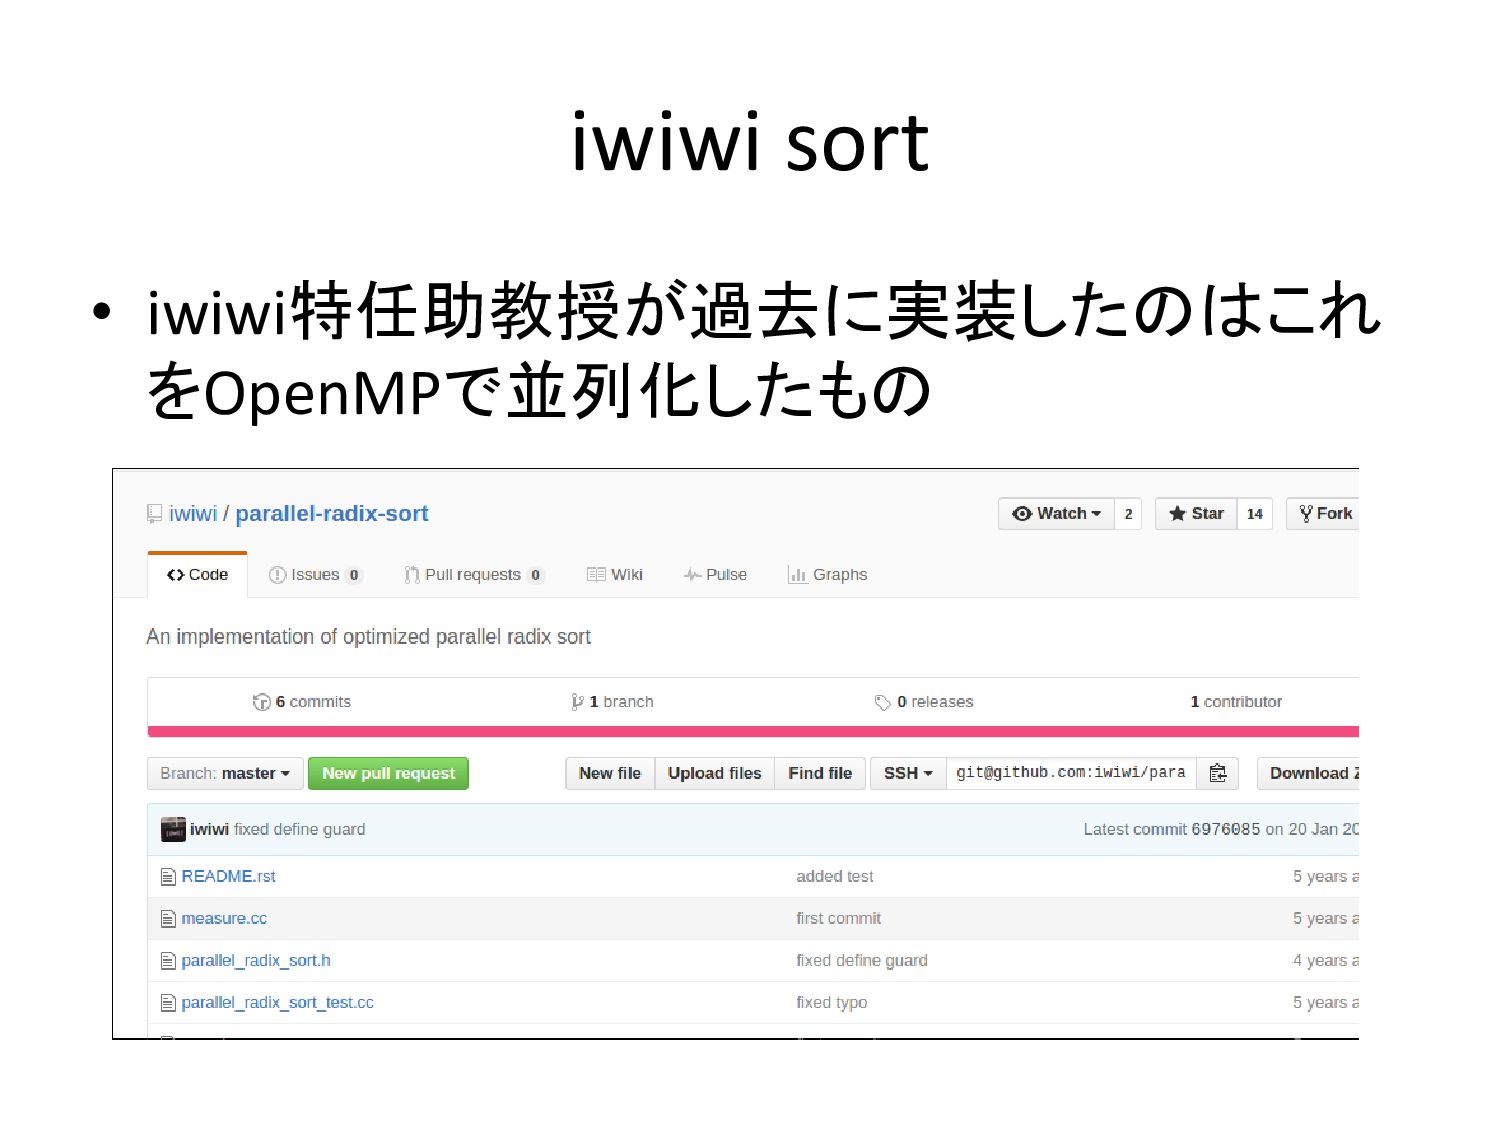
iwiwi sort • iwiwi特任助教授が過去に実装したのはこれ をOpenMPで並列化したもの
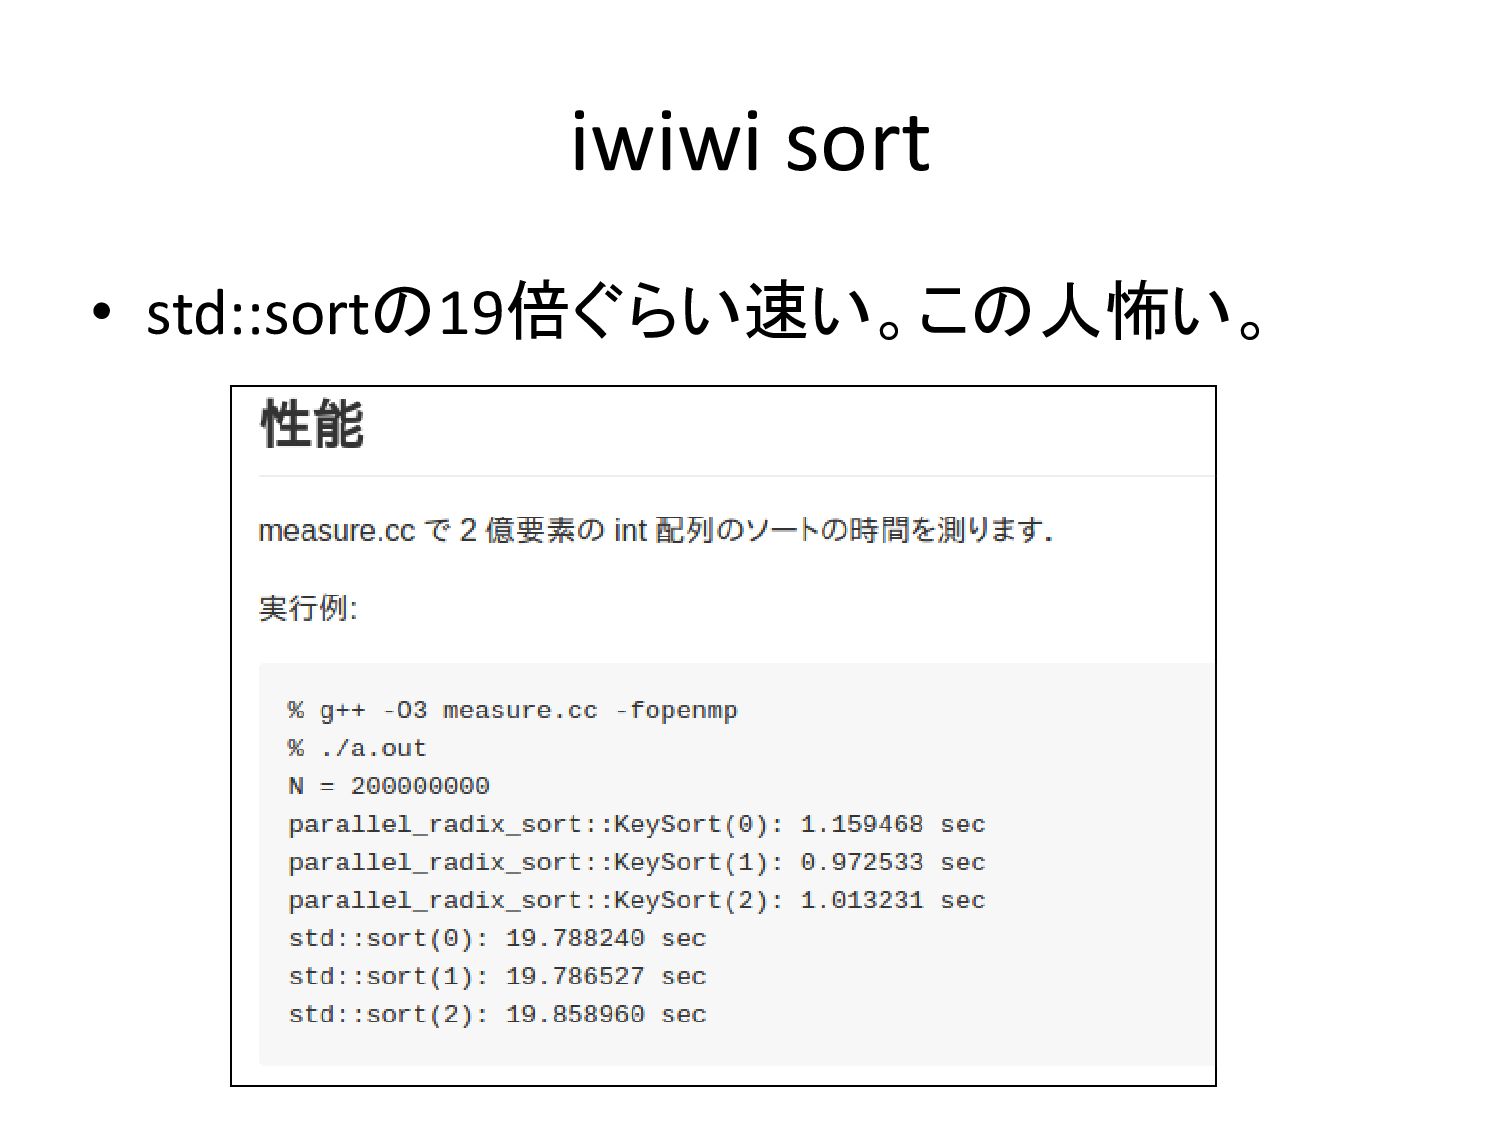
iwiwi sort • std::sortの19倍ぐらい速い。この人怖い。
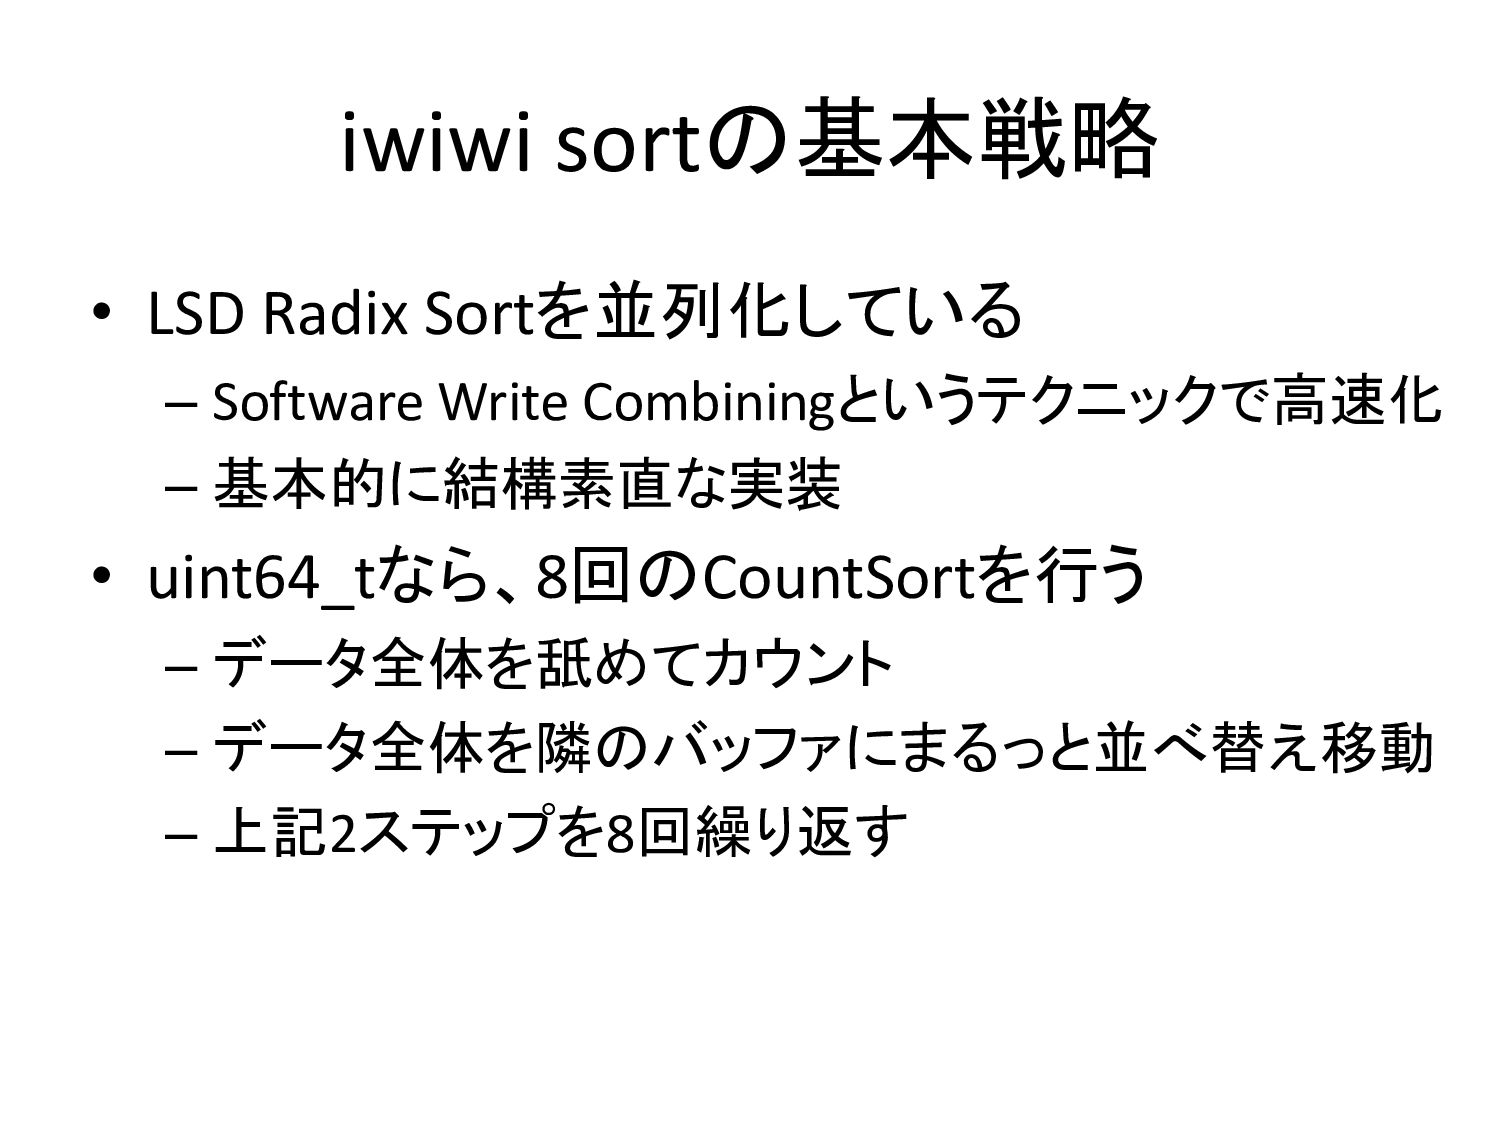
iwiwi sortの基本戦略 • LSD Radix Sortを並列化している – Software Write Combiningというテクニックで高速化
– 基本的に結構素直な実装 • uint64_tなら、8回のCountSortを行う – データ全体を舐めてカウント – データ全体を隣のバッファにまるっと並べ替え移動 – 上記2ステップを8回繰り返す
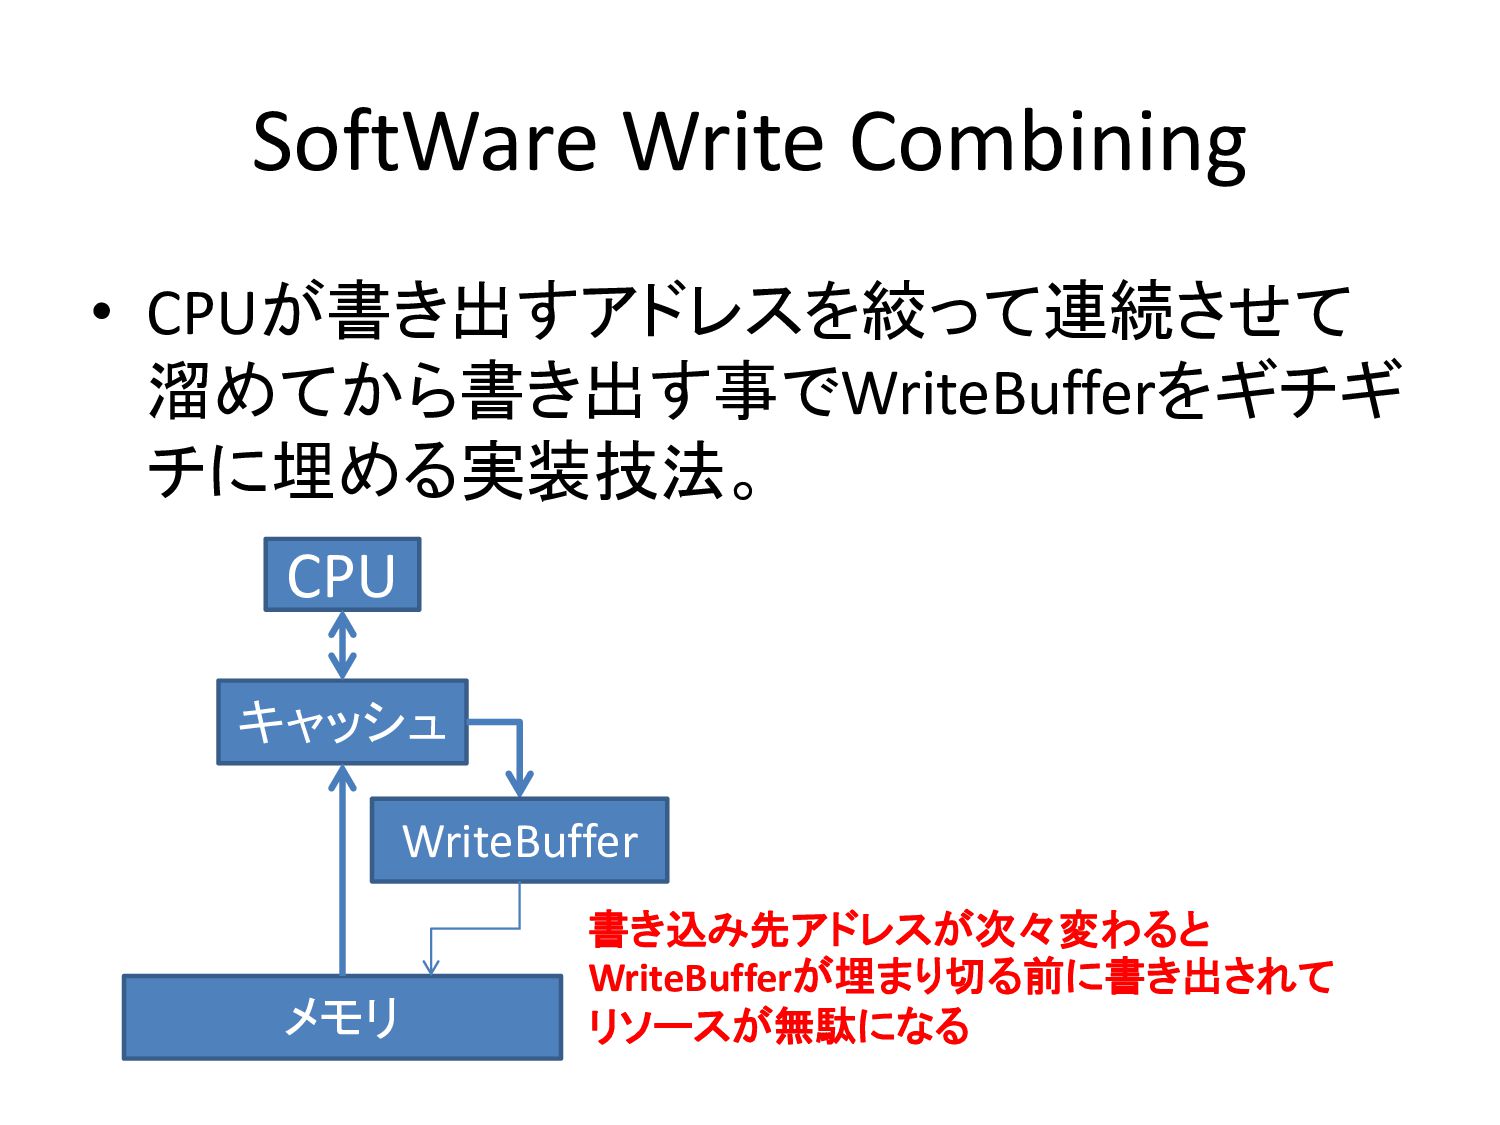
SoftWare Write Combining • CPUが書き出すアドレスを絞って連続させて 溜めてから書き出す事でWriteBufferをギチギ チに埋める実装技法。 CPU キャッシュ メモリ
WriteBuffer 書き込み先アドレスが次々変わると WriteBufferが埋まり切る前に書き出されて リソースが無駄になる
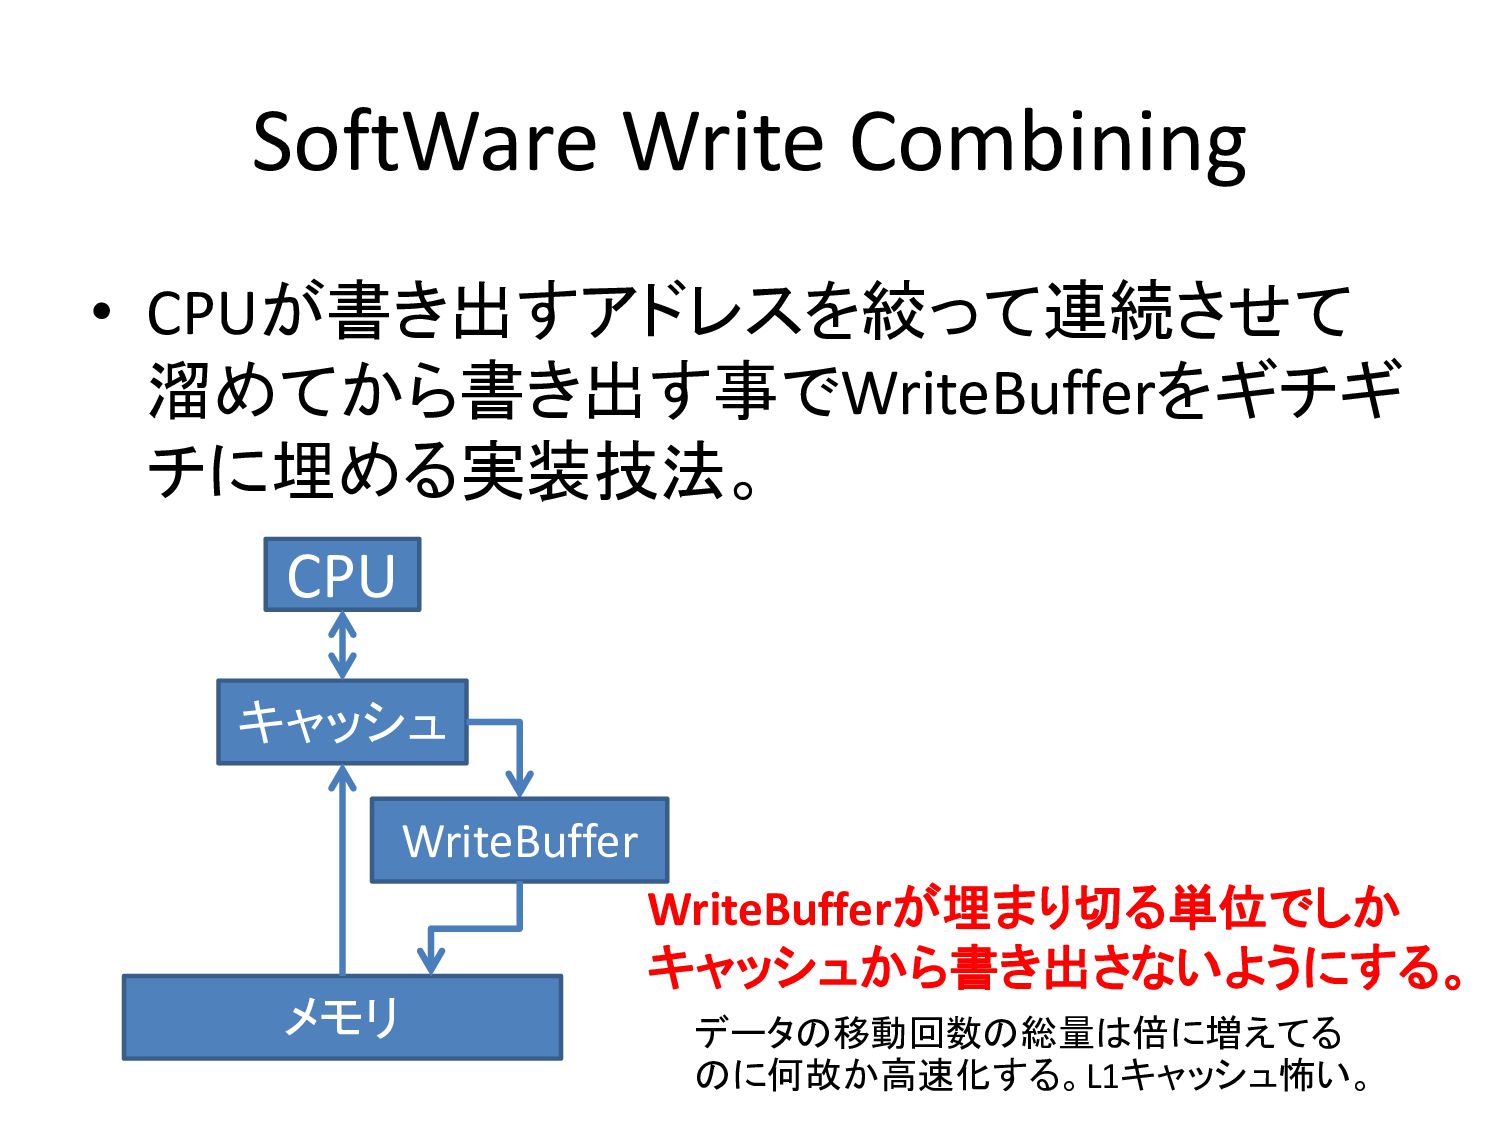
SoftWare Write Combining • CPUが書き出すアドレスを絞って連続させて 溜めてから書き出す事でWriteBufferをギチギ チに埋める実装技法。 CPU キャッシュ メモリ
WriteBuffer WriteBufferが埋まり切る単位でしか キャッシュから書き出さないようにする。 データの移動回数の総量は倍に増えてる のに何故か高速化する。L1キャッシュ怖い。
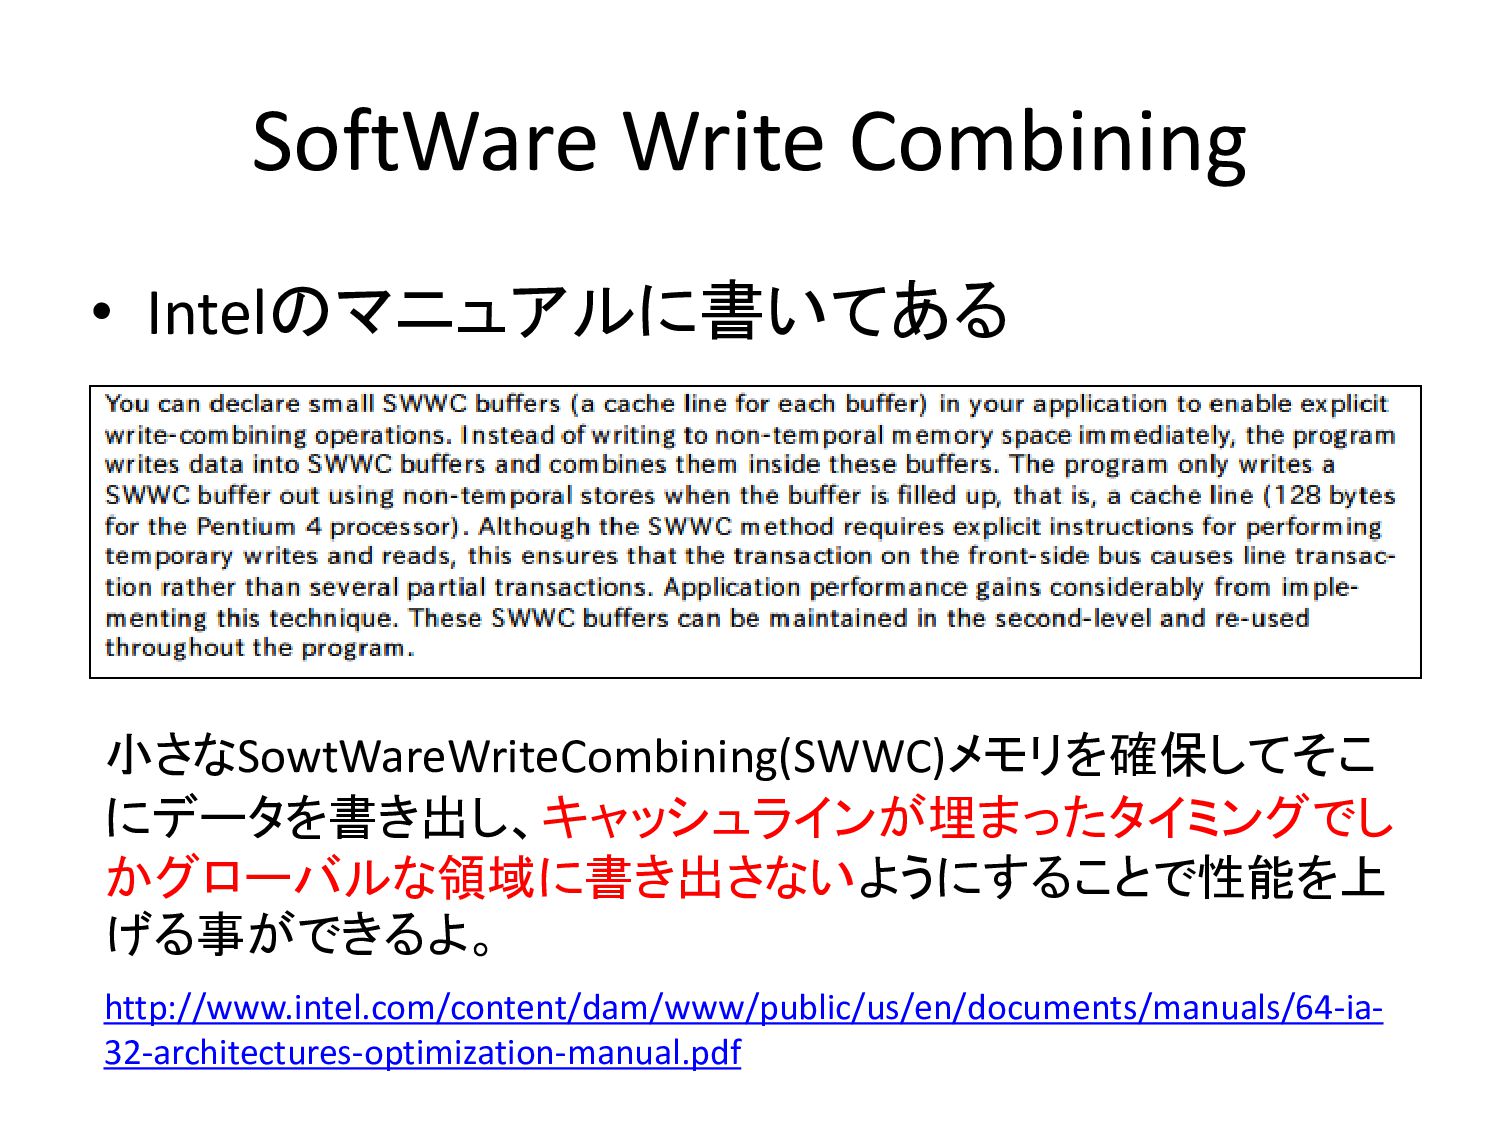
SoftWare Write Combining • Intelのマニュアルに書いてある 小さなSowtWareWriteCombining(SWWC)メモリを確保してそこ にデータを書き出し、キャッシュラインが埋まったタイミングでし かグローバルな領域に書き出さないようにすることで性能を上 げる事ができるよ。 http://www.intel.com/content/dam/www/public/us/en/documents/manuals/64-ia-
32-architectures-optimization-manual.pdf
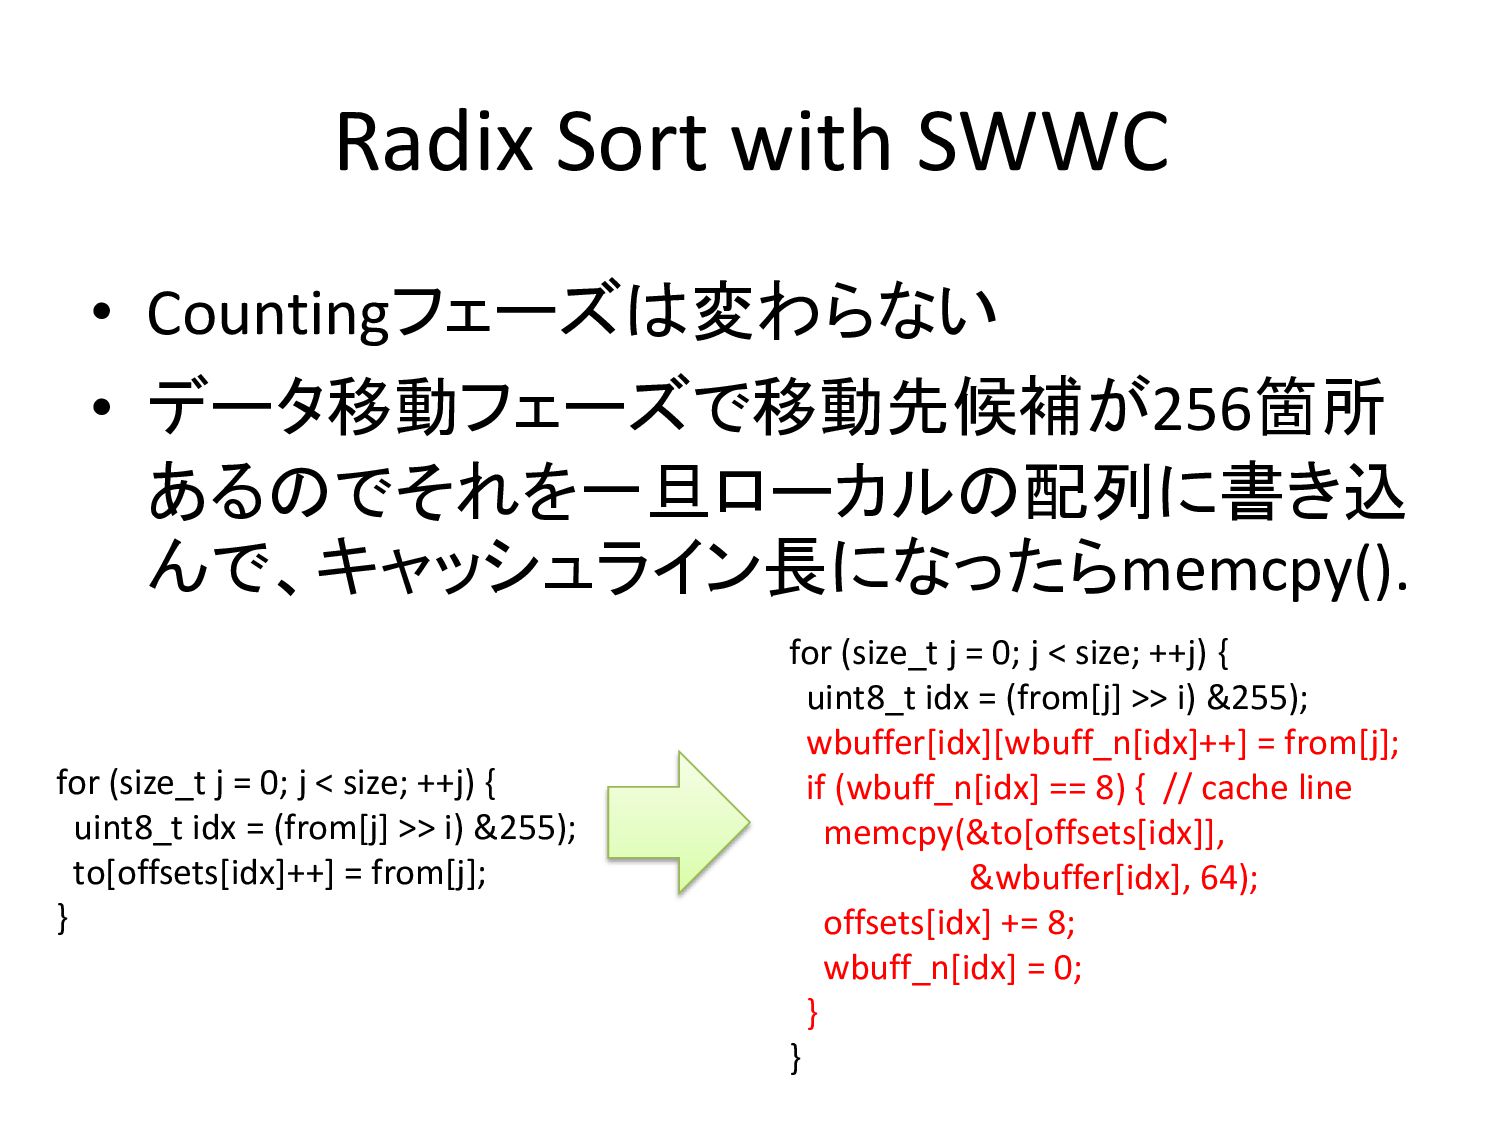
Radix Sort with SWWC • Countingフェーズは変わらない • データ移動フェーズで移動先候補が256箇所 あるのでそれを一旦ローカルの配列に書き込 んで、キャッシュライン長になったらmemcpy().
for (size_t j = 0; j < size; ++j) { uint8_t idx = (from[j] >> i) &255); wbuffer[idx][wbuff_n[idx]++] = from[j]; if (wbuff_n[idx] == 8) { // cache line memcpy(&to[offsets[idx]], &wbuffer[idx], 64); offsets[idx] += 8; wbuff_n[idx] = 0; } } for (size_t j = 0; j < size; ++j) { uint8_t idx = (from[j] >> i) &255); to[offsets[idx]++] = from[j]; }
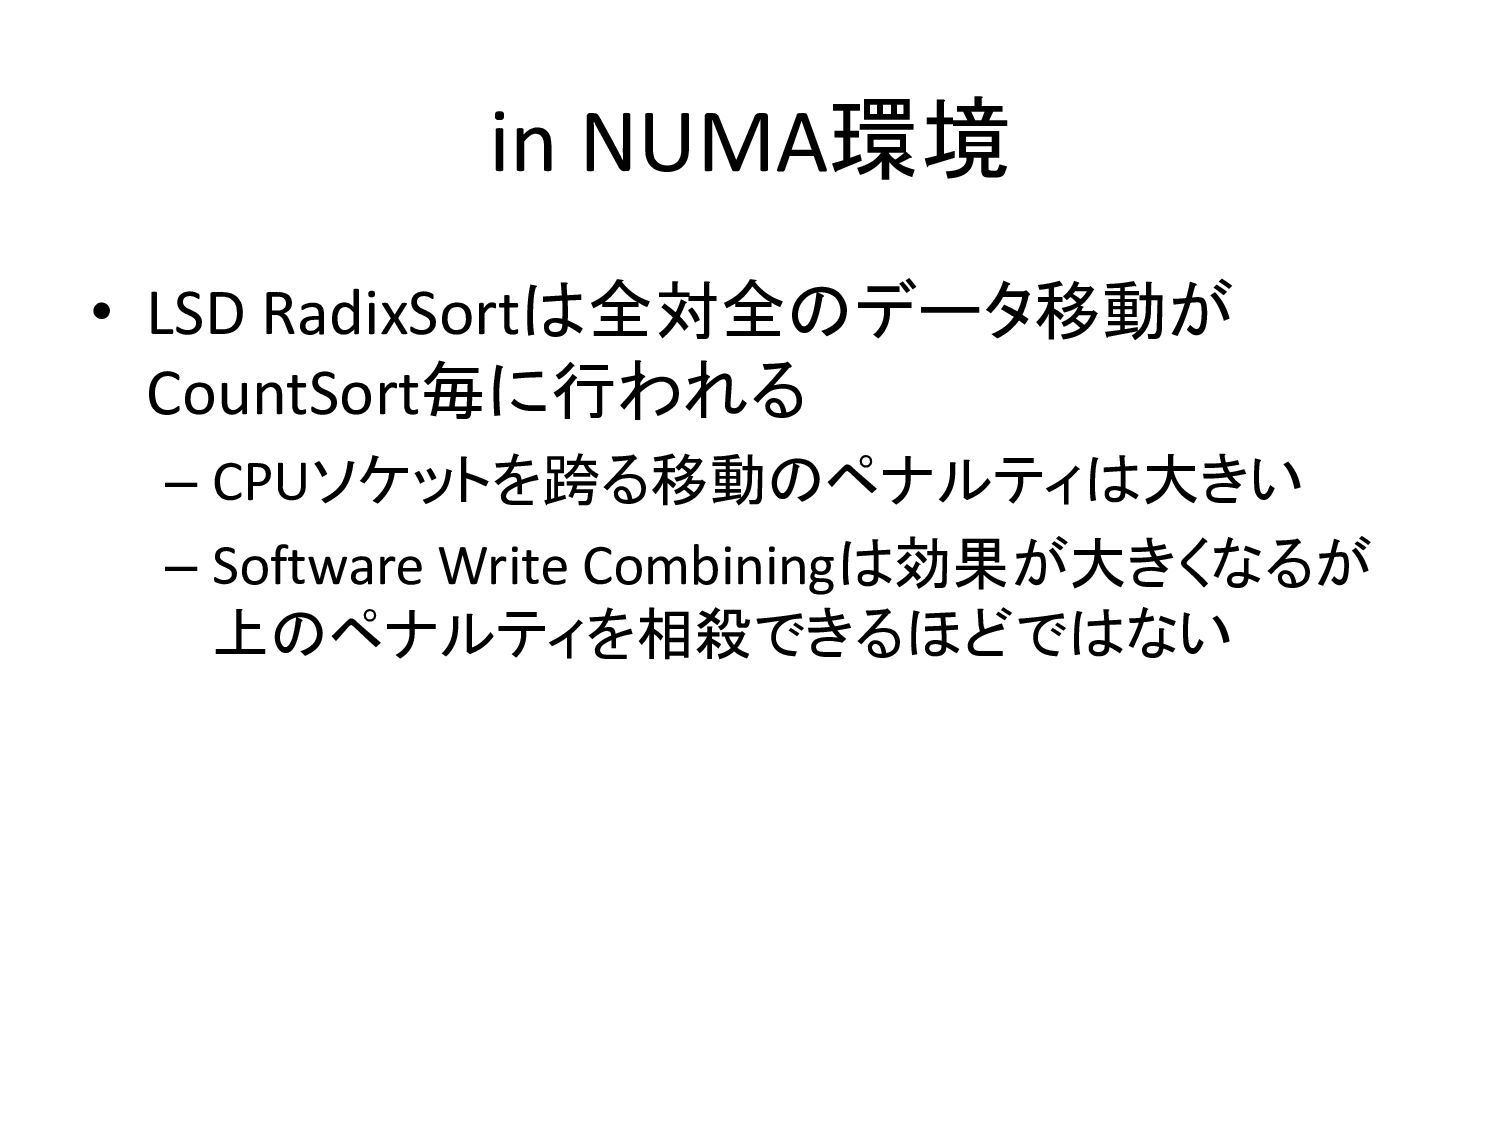
in NUMA環境 • LSD RadixSortは全対全のデータ移動が CountSort毎に行われる – CPUソケットを跨る移動のペナルティは大きい – Software
Write Combiningは効果が大きくなるが 上のペナルティを相殺できるほどではない
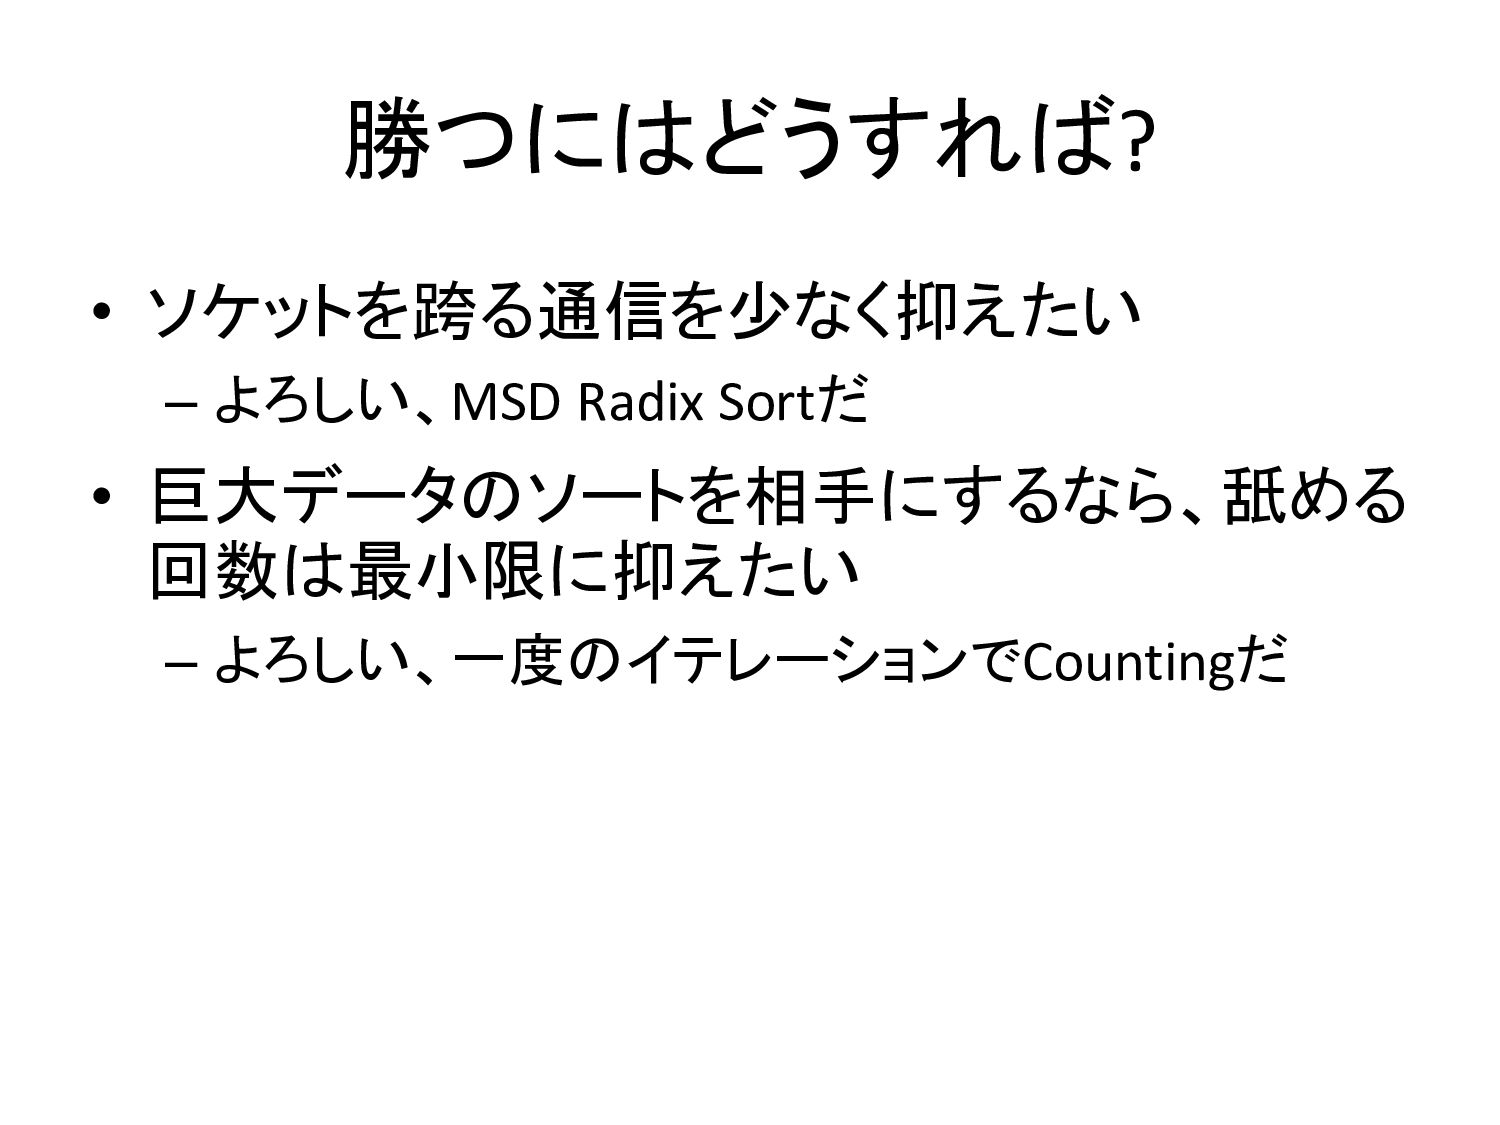
勝つにはどうすれば? • ソケットを跨る通信を少なく抑えたい – よろしい、MSD Radix Sortだ • 巨大データのソートを相手にするなら、舐める 回数は最小限に抑えたい
– よろしい、一度のイテレーションでCountingだ
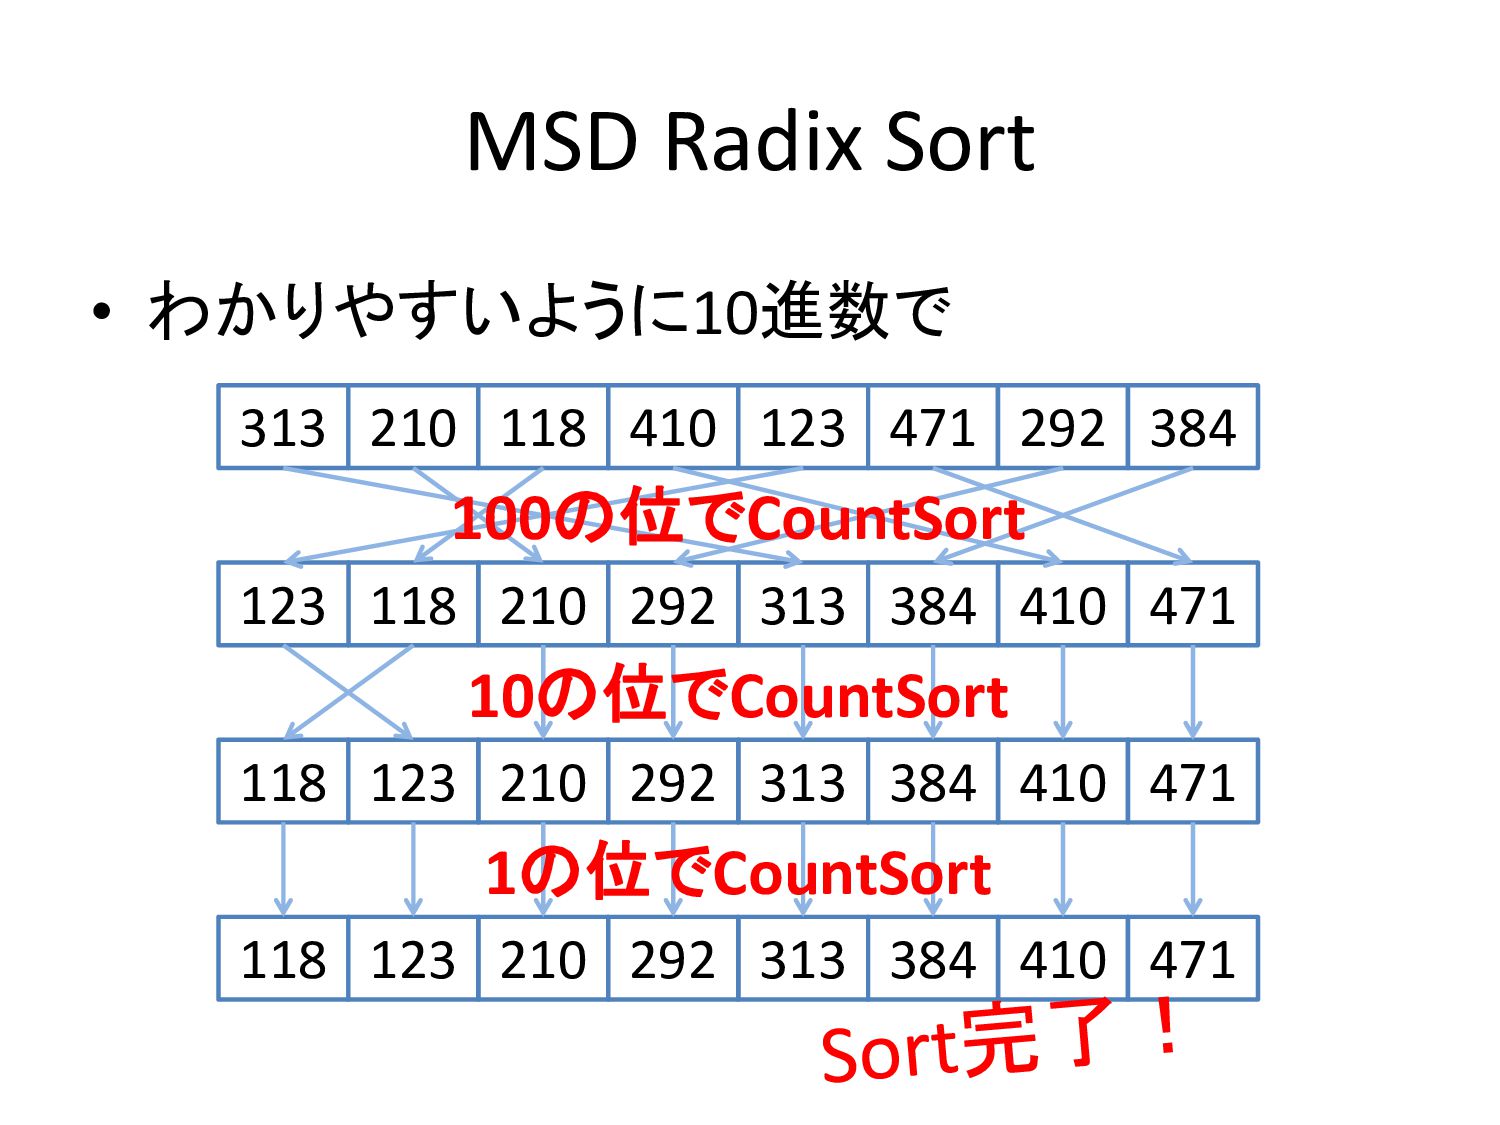
MSD Radix Sort • わかりやすいように10進数で 313 210 118 410 123
471 292 384 313 210 118 410 123 471 292 384 313 210 118 410 123 471 292 384 313 210 118 410 123 471 292 384 100の位でCountSort 10の位でCountSort 1の位でCountSort
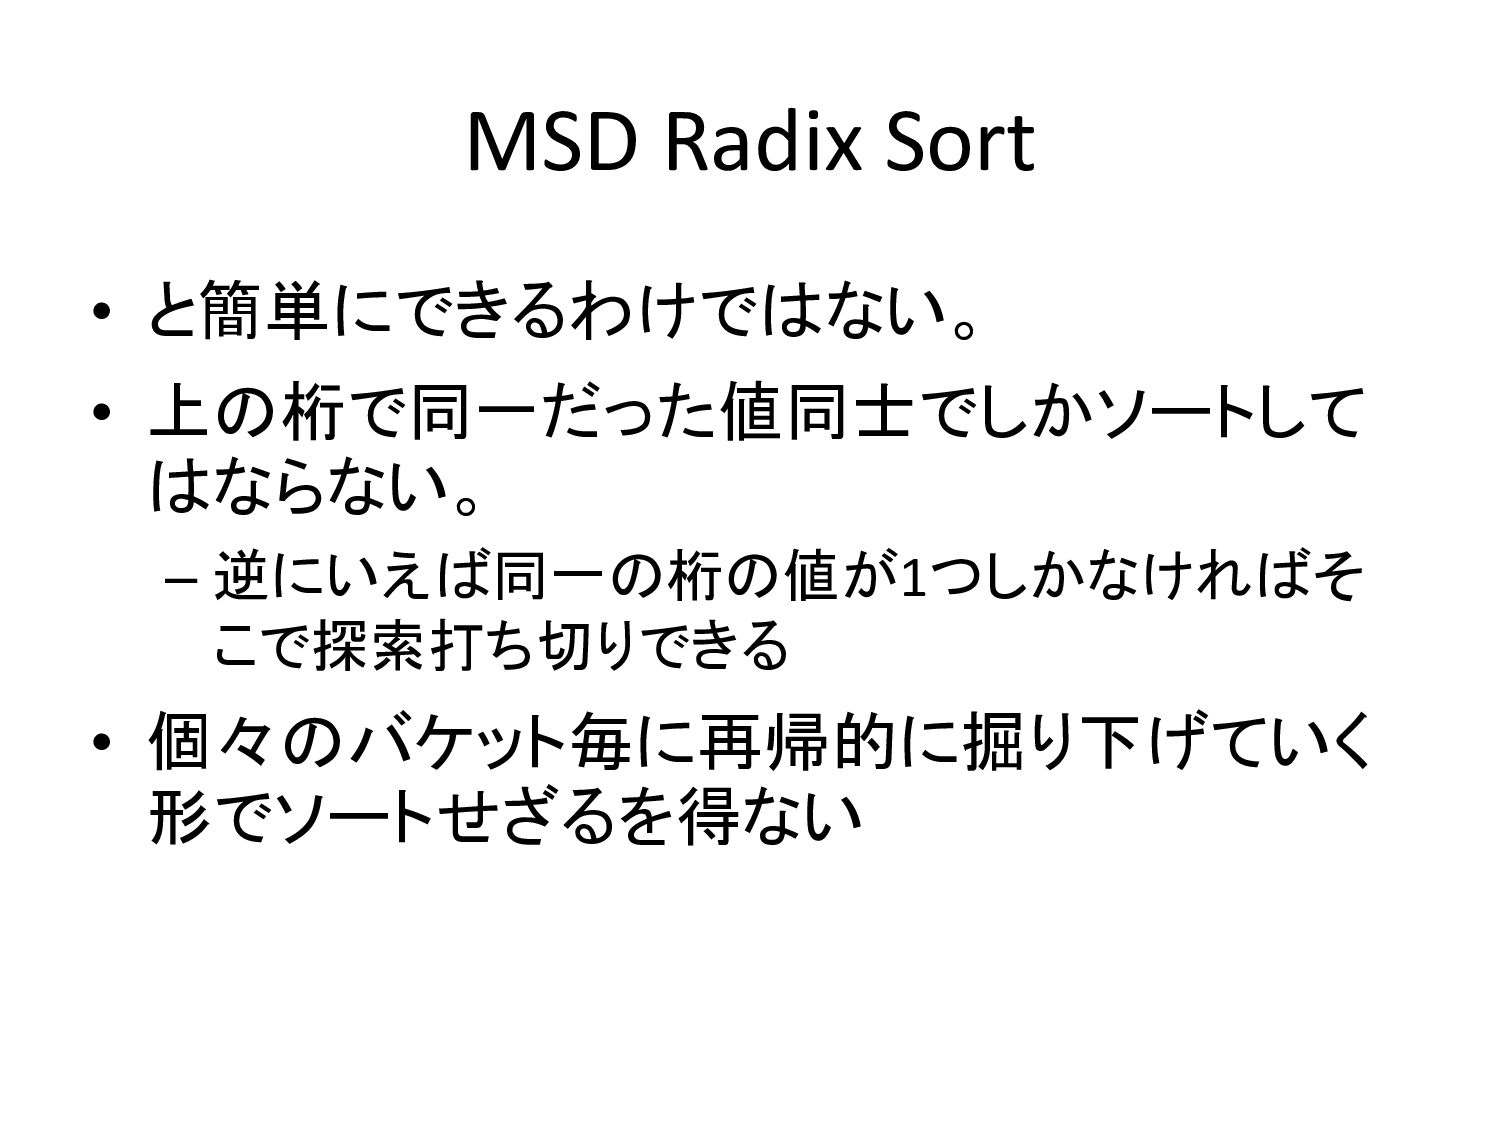
MSD Radix Sort • と簡単にできるわけではない。 • 上の桁で同一だった値同士でしかソートして はならない。 – 逆にいえば同一の桁の値が1つしかなければそ
こで探索打ち切りできる • 個々のバケット毎に再帰的に掘り下げていく 形でソートせざるを得ない
MSD Radix Sort https://www.youtube.com/watch?v=kPRA0W1kECg
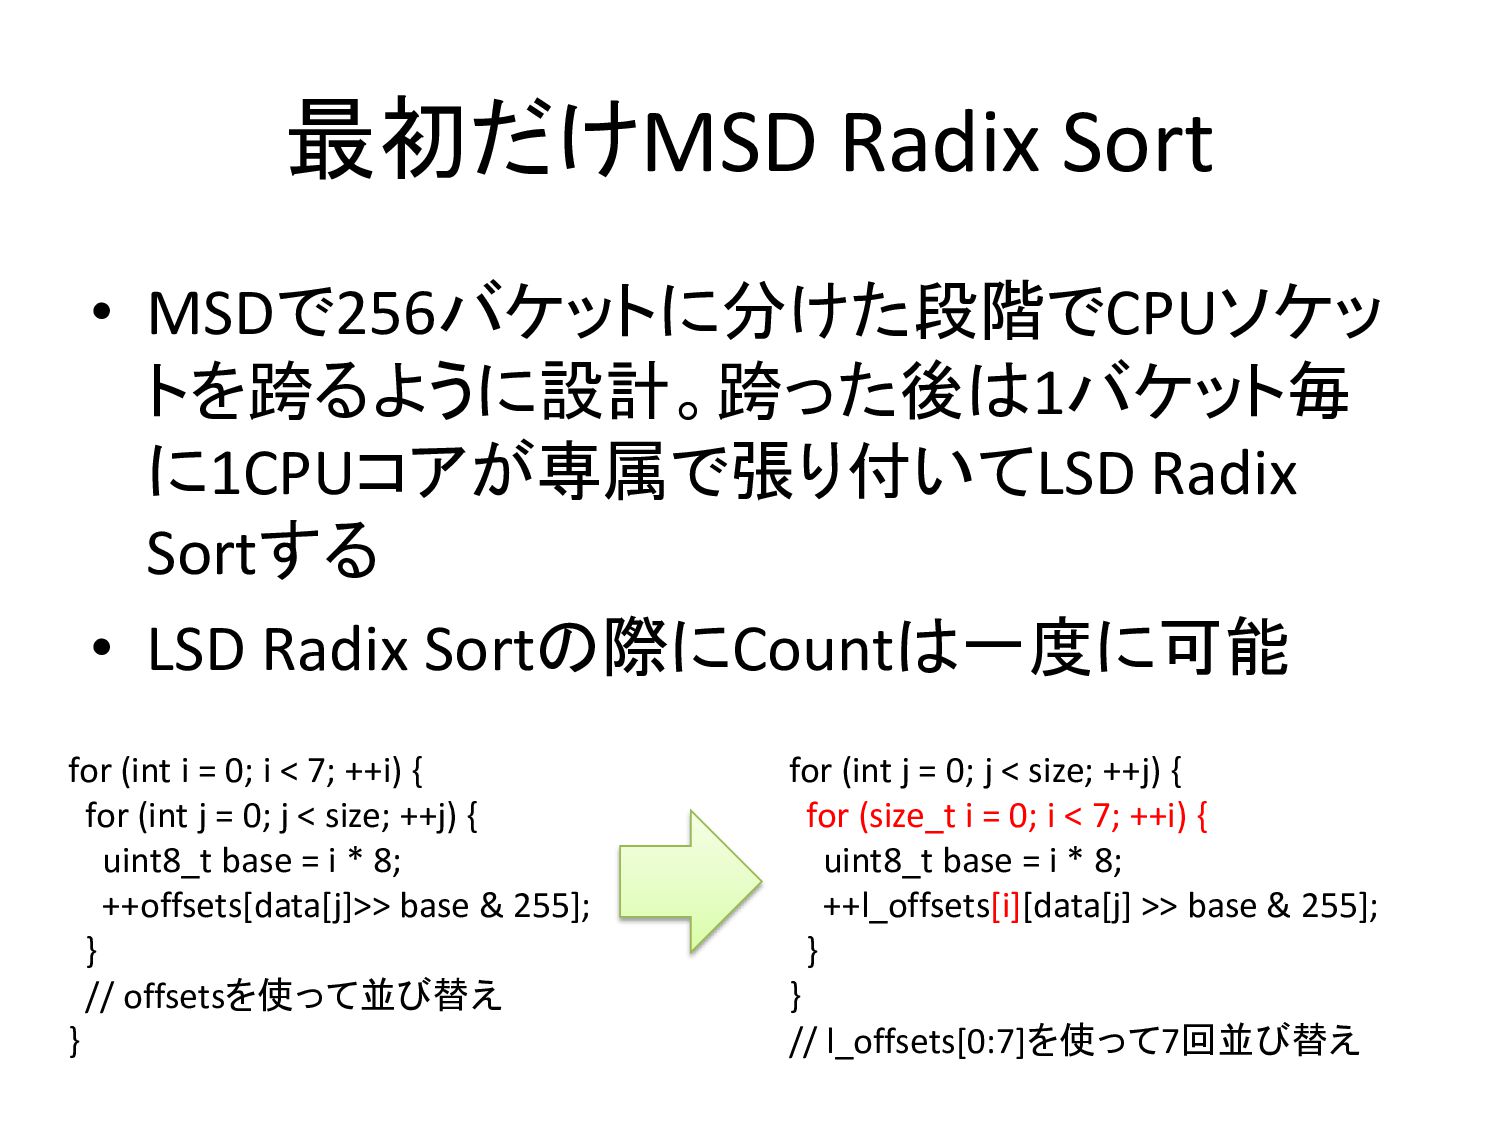
最初だけMSD Radix Sort • MSDで256バケットに分けた段階でCPUソケッ トを跨るように設計。跨った後は1バケット毎 に1CPUコアが専属で張り付いてLSD Radix Sortする •
LSD Radix Sortの際にCountは一度に可能 for (int j = 0; j < size; ++j) { for (size_t i = 0; i < 7; ++i) { uint8_t base = i * 8; ++l_offsets[i][data[j] >> base & 255]; } } // l_offsets[0:7]を使って7回並び替え for (int i = 0; i < 7; ++i) { for (int j = 0; j < size; ++j) { uint8_t base = i * 8; ++offsets[data[j]>> base & 255]; } // offsetsを使って並び替え }
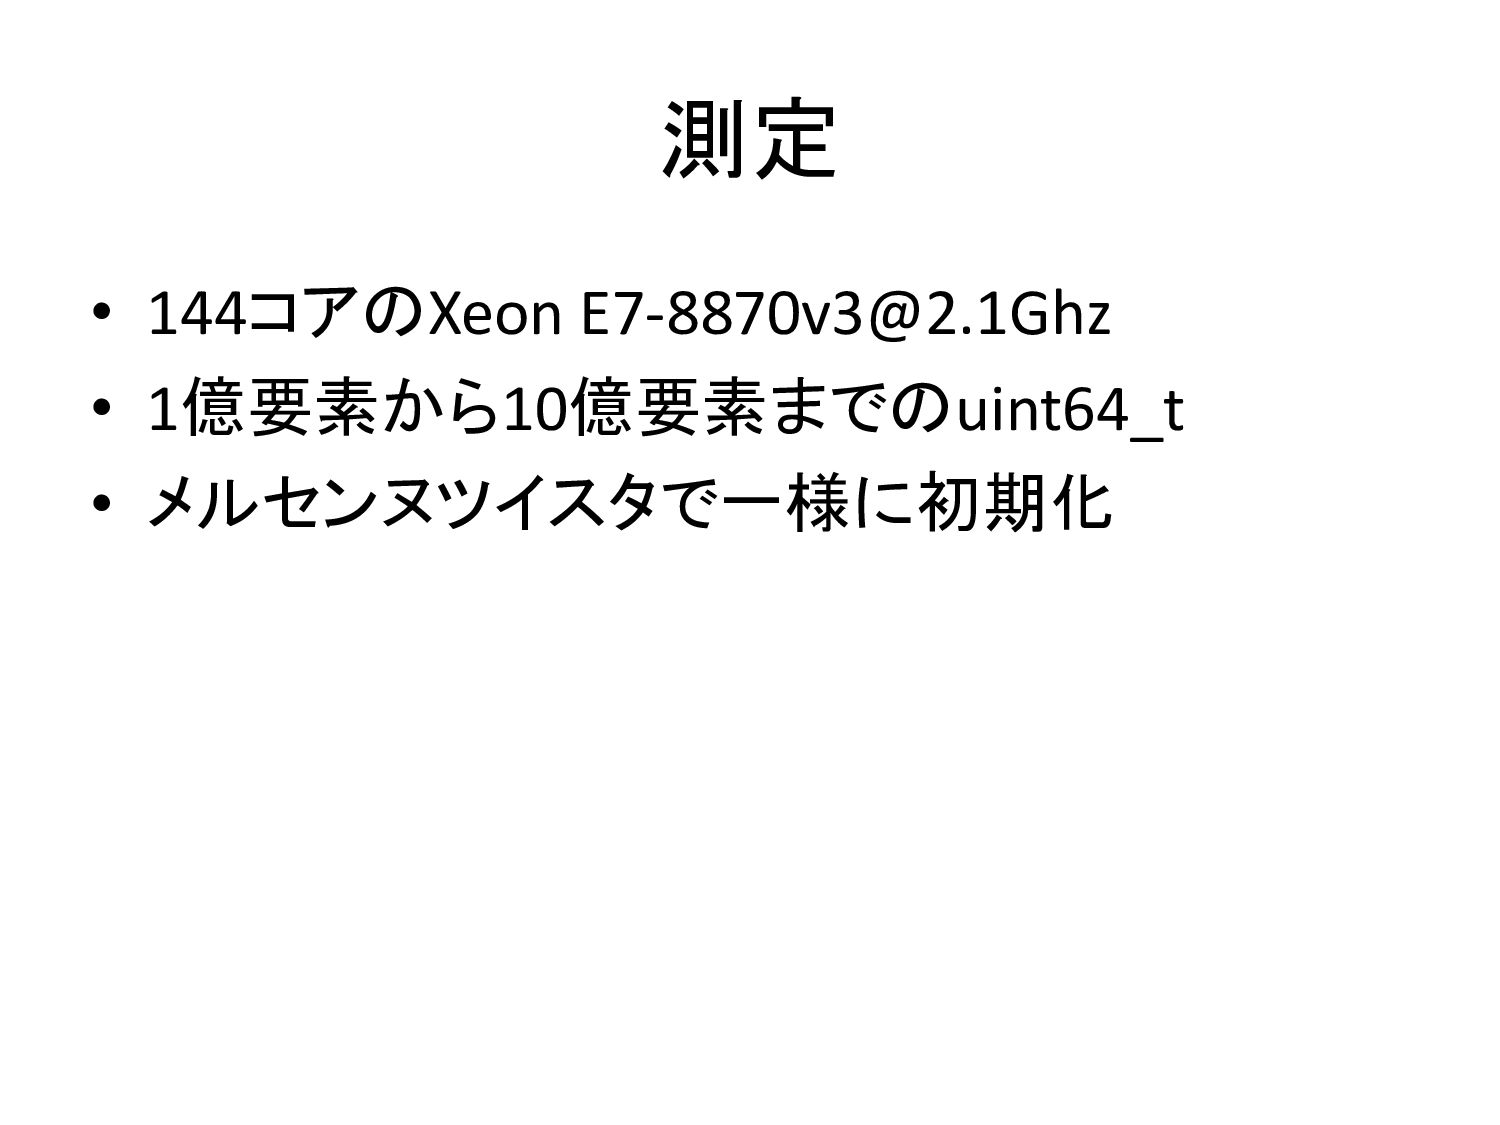
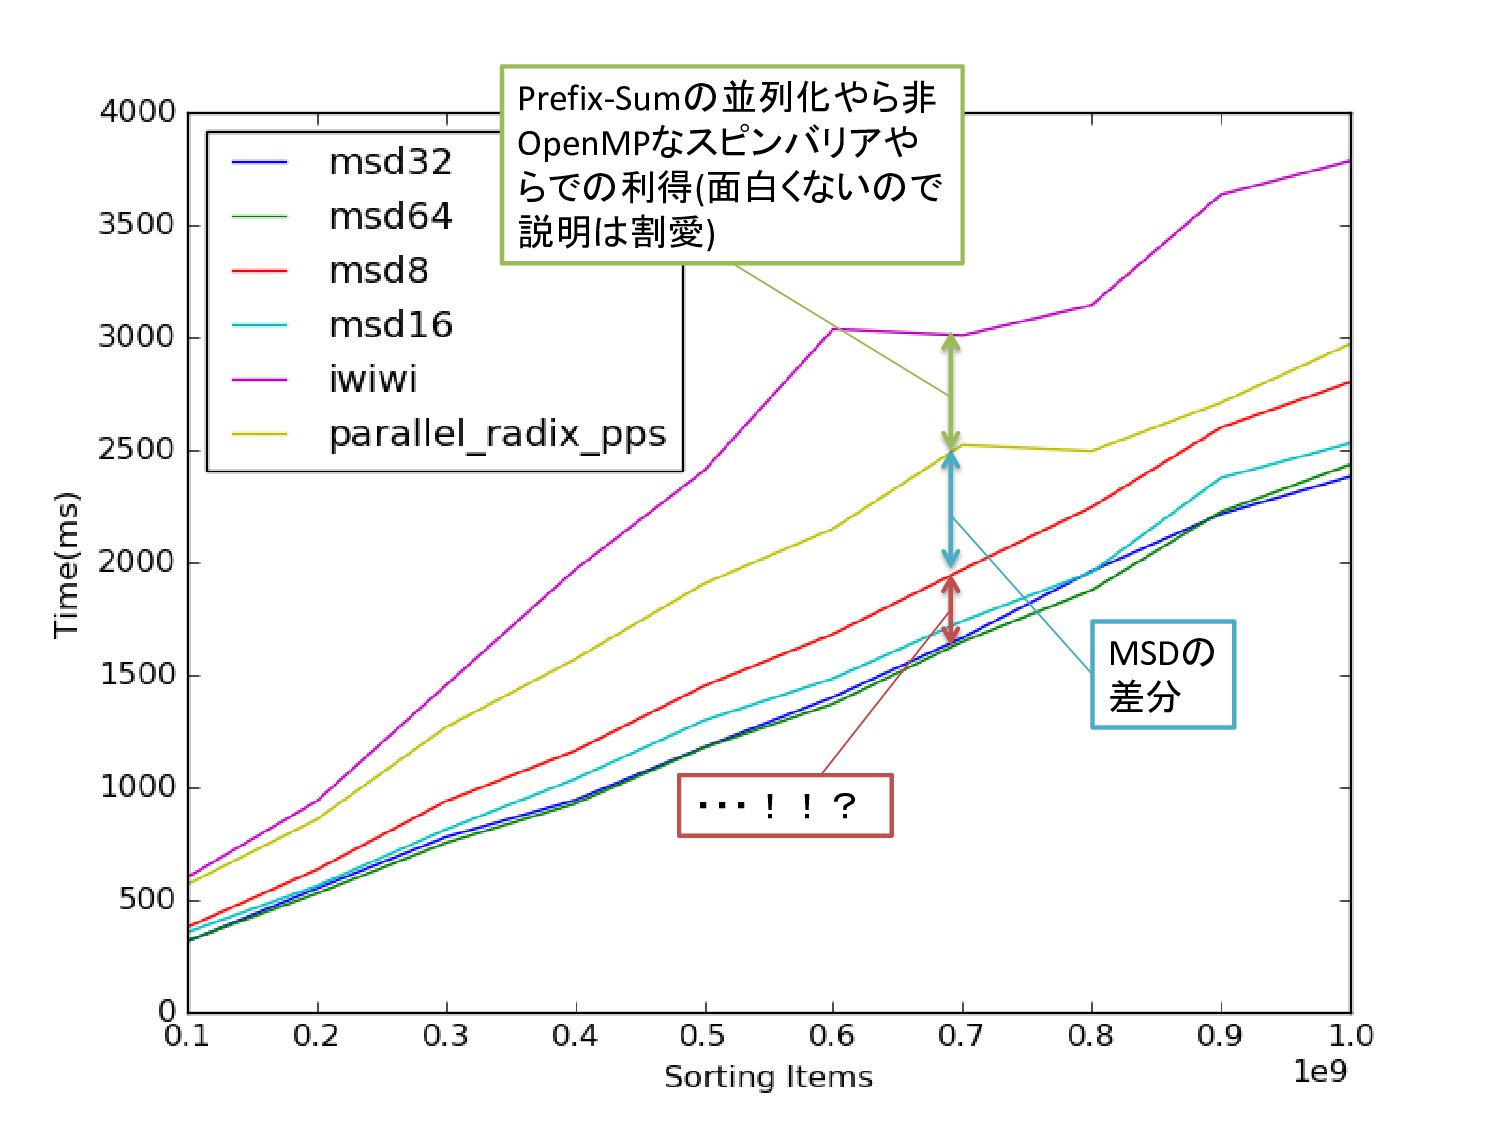
測定 • 144コアのXeon
[email protected]
• 1億要素から10億要素までのuint64_t • メルセンヌツイスタで一様に初期化
MSDの 差分 Prefix-Sumの並列化やら非 OpenMPなスピンバリアや らでの利得(面白くないので 説明は割愛) ・・・!!?
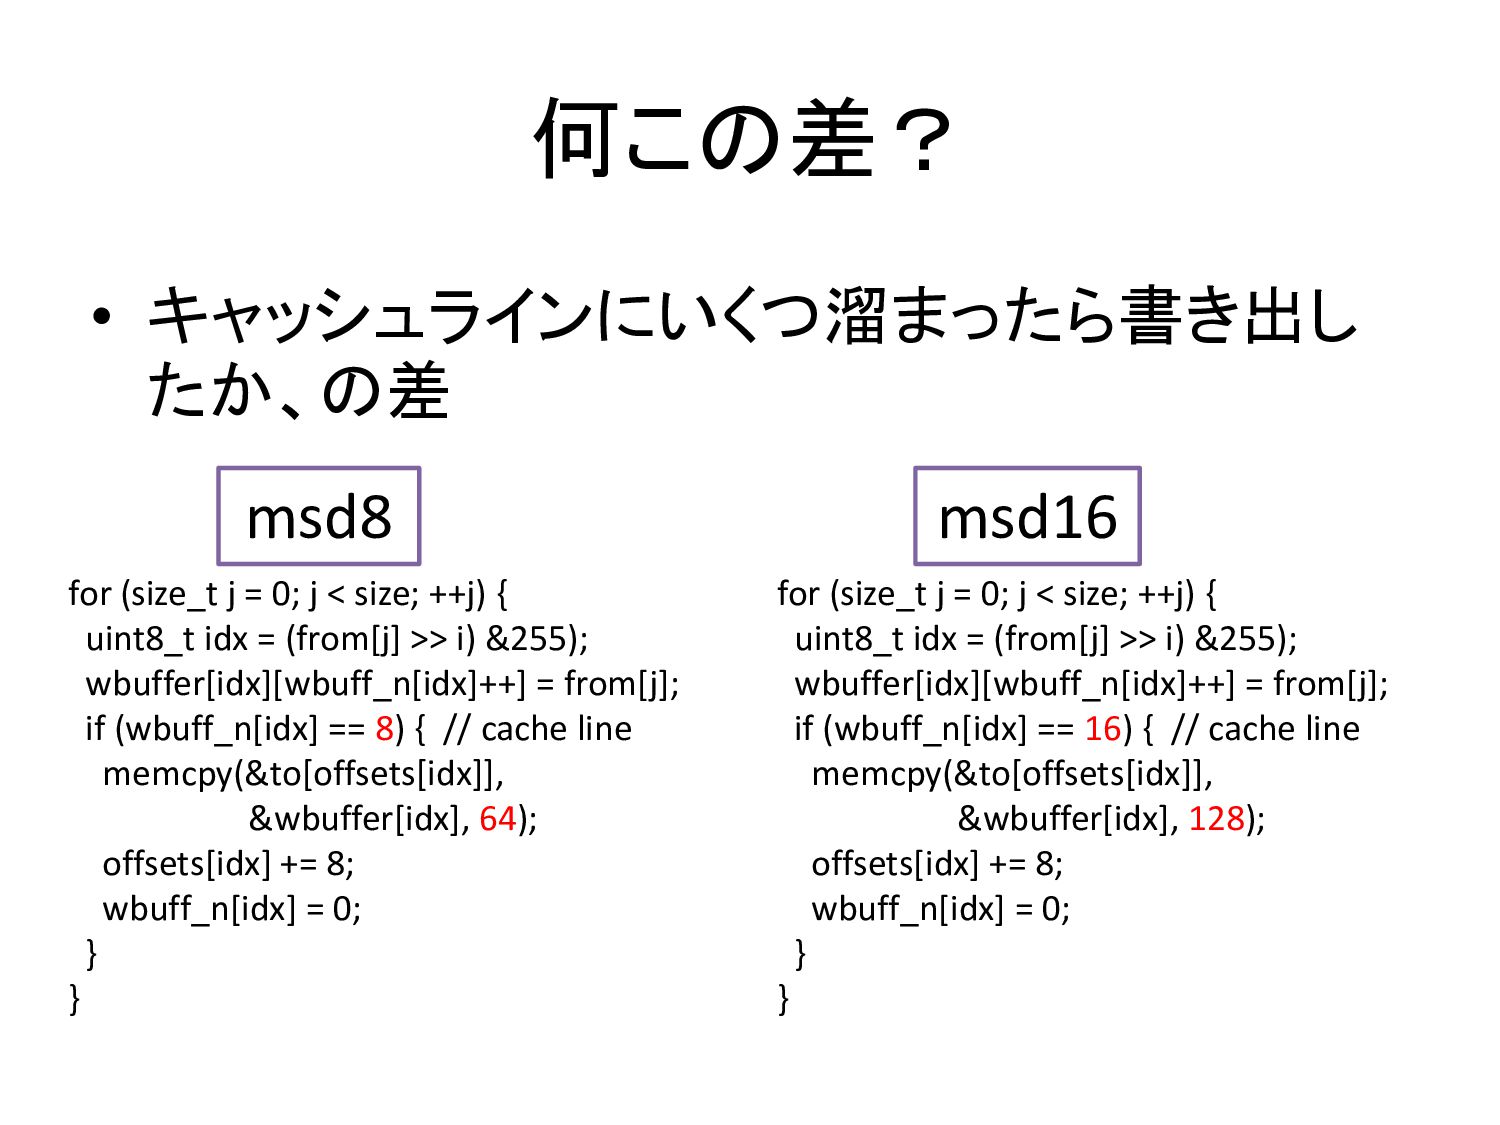
何この差? • キャッシュラインにいくつ溜まったら書き出し たか、の差 for (size_t j = 0; j
< size; ++j) { uint8_t idx = (from[j] >> i) &255); wbuffer[idx][wbuff_n[idx]++] = from[j]; if (wbuff_n[idx] == 8) { // cache line memcpy(&to[offsets[idx]], &wbuffer[idx], 64); offsets[idx] += 8; wbuff_n[idx] = 0; } } for (size_t j = 0; j < size; ++j) { uint8_t idx = (from[j] >> i) &255); wbuffer[idx][wbuff_n[idx]++] = from[j]; if (wbuff_n[idx] == 16) { // cache line memcpy(&to[offsets[idx]], &wbuffer[idx], 128); offsets[idx] += 8; wbuff_n[idx] = 0; } } msd8 msd16
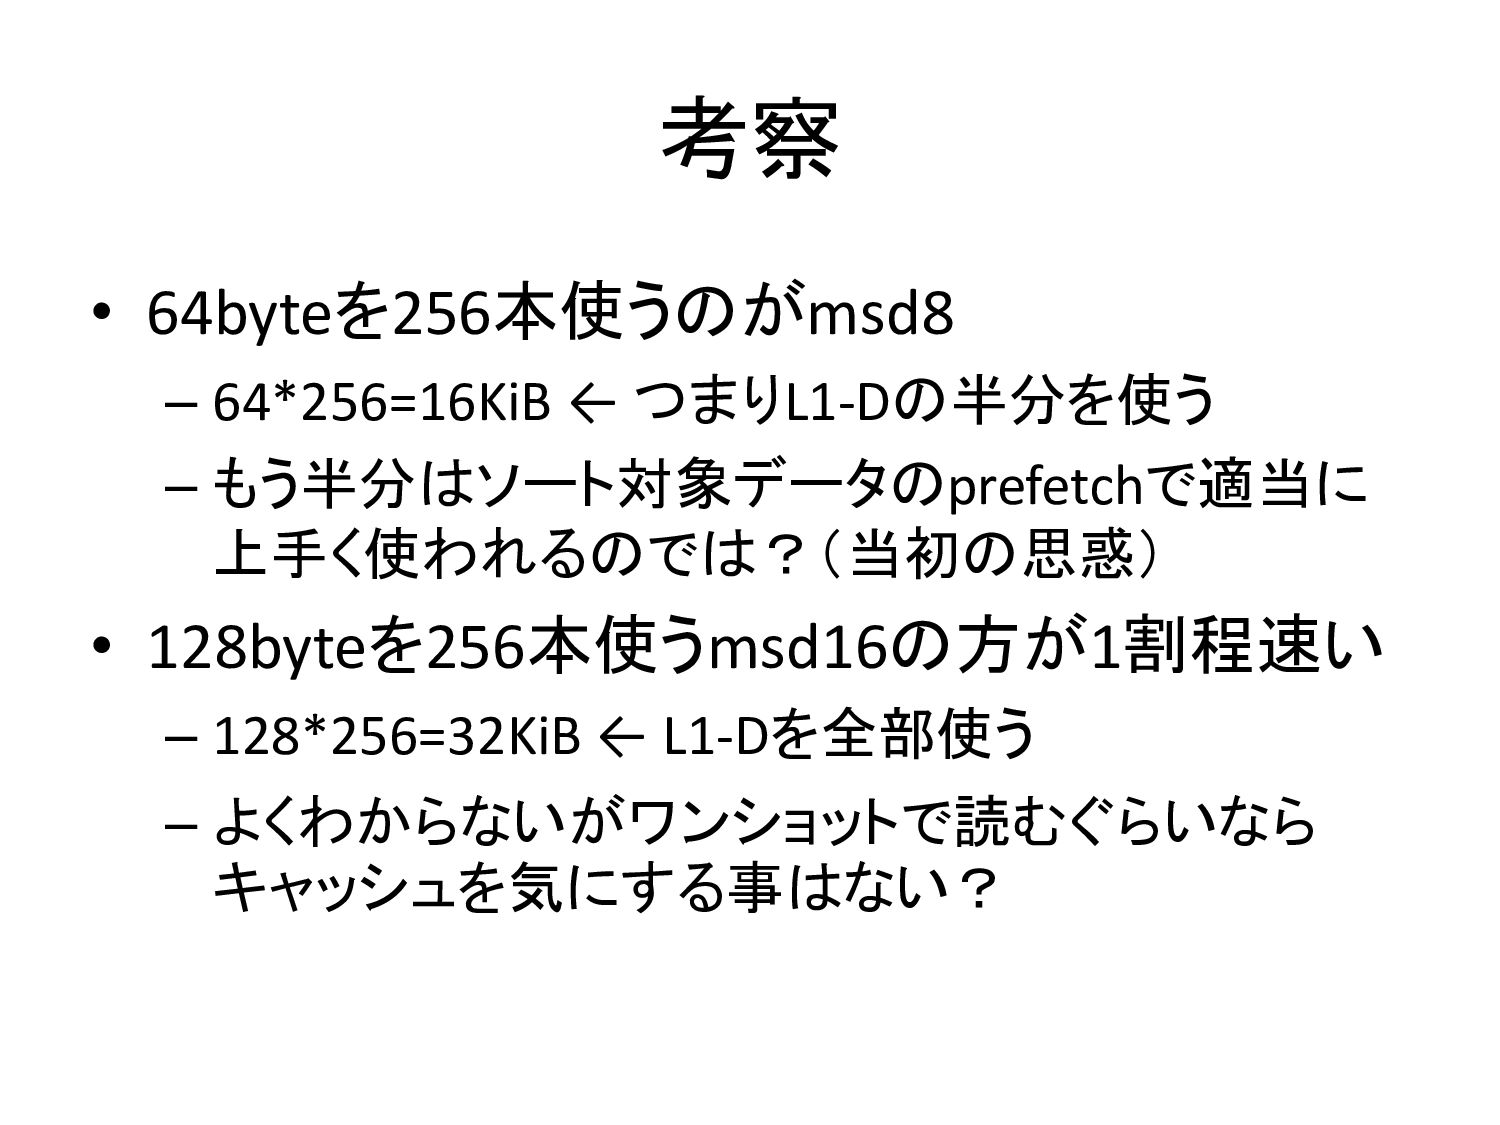
考察 • 64byteを256本使うのがmsd8 – 64*256=16KiB ← つまりL1-Dの半分を使う – もう半分はソート対象データのprefetchで適当に 上手く使われるのでは?(当初の思惑)
• 128byteを256本使うmsd16の方が1割程速い – 128*256=32KiB ← L1-Dを全部使う – よくわからないがワンショットで読むぐらいなら キャッシュを気にする事はない?
None
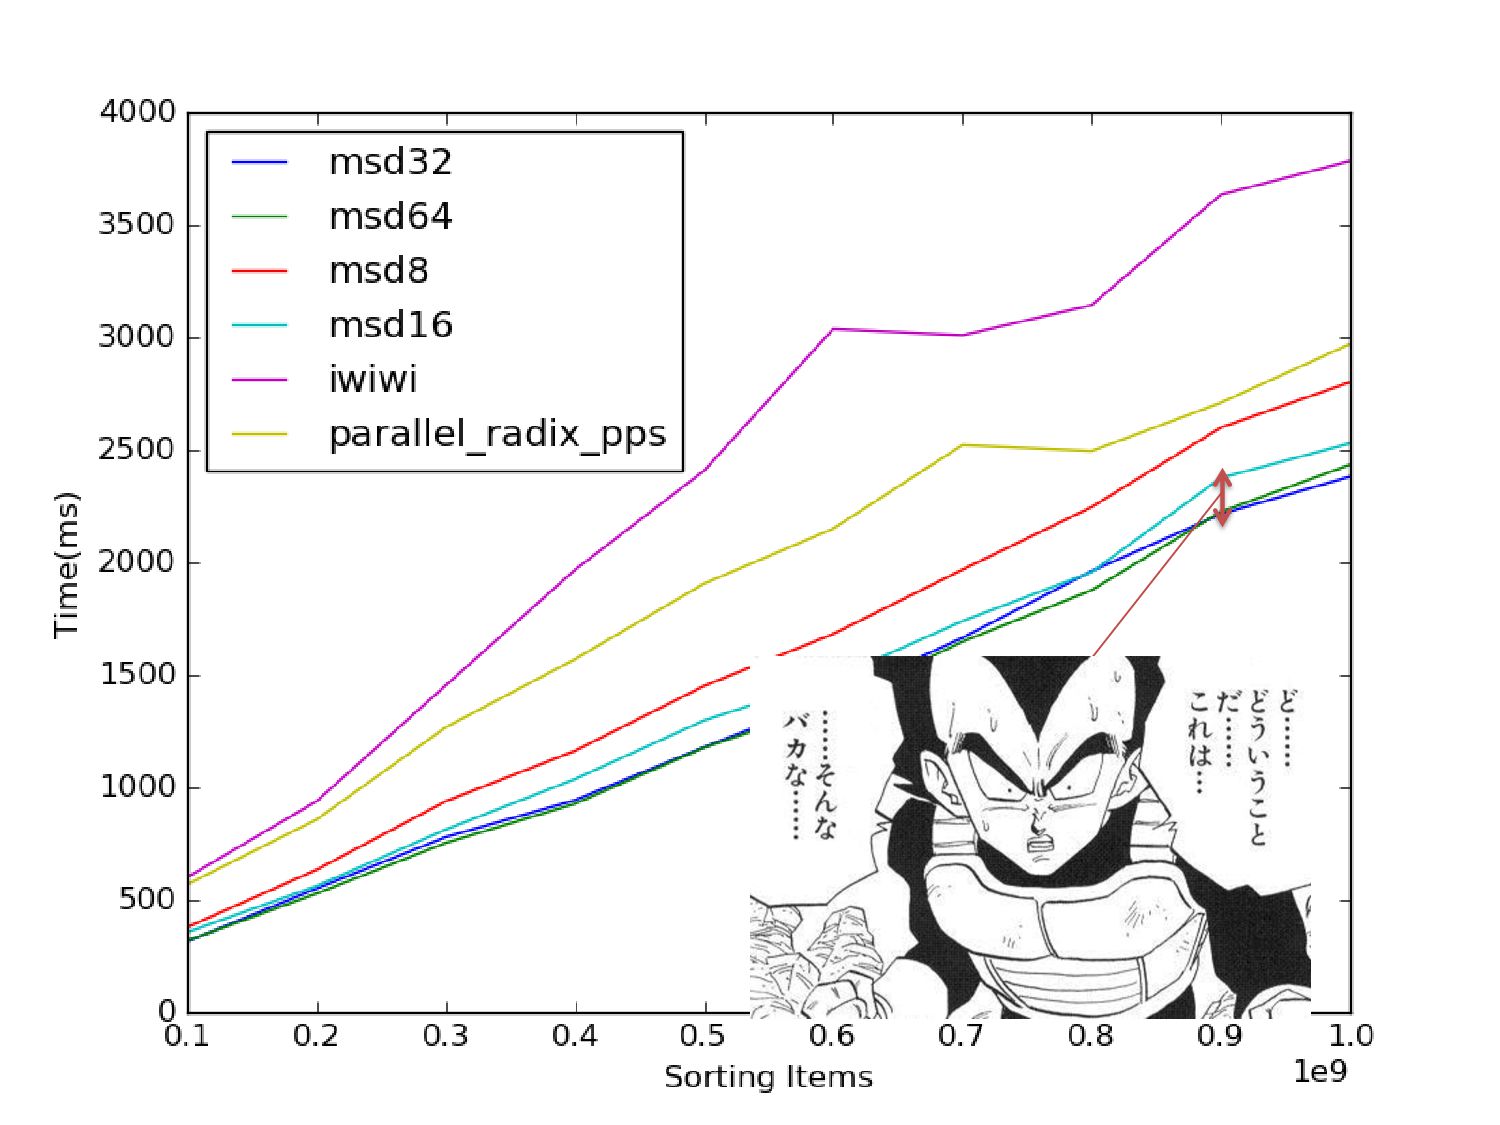
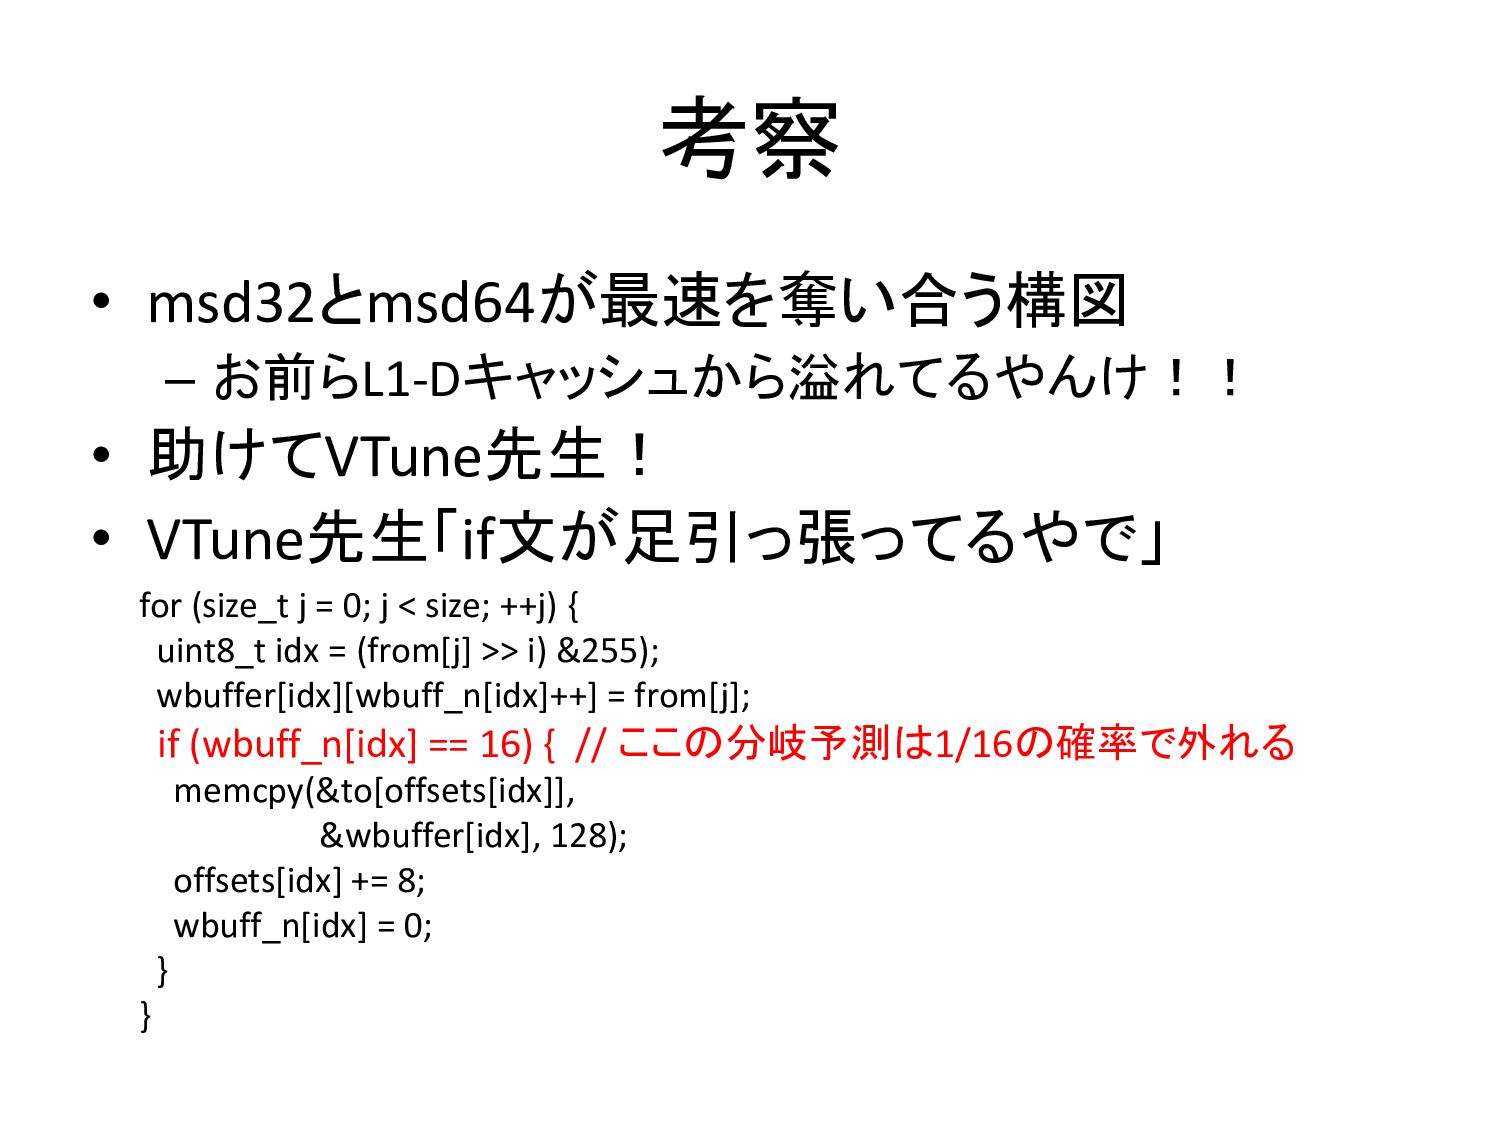
考察 • msd32とmsd64が最速を奪い合う構図 – お前らL1-Dキャッシュから溢れてるやんけ!! • 助けてVTune先生! • VTune先生「if文が足引っ張ってるやで」 for
(size_t j = 0; j < size; ++j) { uint8_t idx = (from[j] >> i) &255); wbuffer[idx][wbuff_n[idx]++] = from[j]; if (wbuff_n[idx] == 16) { // ここの分岐予測は1/16の確率で外れる memcpy(&to[offsets[idx]], &wbuffer[idx], 128); offsets[idx] += 8; wbuff_n[idx] = 0; } }
kumagiさんの次回作にご期待ください!


 yuta_onishi_97
 utakaha
 satoshi256kbyte
 iwatsukayura
 chobishiba
 iwiwi
 rkaga
 tanahiro2010
 kishida
 texmeijin
 kenjiyoneyama
 ryu1013
 codingconduct
 mraible
 matthewcrist
 nikkihalliwell
 maggiecrowley
 helenjbeal
 jnunemaker
 gr2m
 thirion
 keithpitt
 honnibal